You Only Look Once: Unified, Real-Time Object Detection
You Only Look Once: Unified, Real-Time Object Detection
You Only Look Once:统一的实时目标检测
Joseph Redmon * Santosh Divvala Ross Girshick ¶ Ali Farhadi University of Washington * Allen Institute for AI Facebook AI Research ¶ http://pjreddie.com/yolo/
Abstract
摘要
We present YOLO, a new approach to object detection. Prior work on object detection repurposes classifiers to perform detection. Instead, we frame object detection as a regression problem to spatially separated bounding boxes and associated class probabilities. A single neural network predicts bounding boxes and class probabilities directly from full images in one evaluation. Since the whole detection pipeline is a single network, it can be optimized end-to-end directly on detection performance.
我们提出 YOLO,一种新的目标检测思路。此前的目标检测工作多把分类器改造成检测器;我们则把目标检测表述为回归问题:直接回归空间上分离的边界框及其类别概率。单个神经网络从整图一次性评估,直接预测边界框与类别概率。由于整条检测流水线就是一个网络,可以端到端地直接按检测性能优化。
Our unified architecture is extremely fast. Our base YOLO model processes images in real-time at 45 frames per second. A smaller version of the network, Fast YOLO, processes an astounding 155 frames per second while still achieving double the mAP of other real-time detectors. Compared to state-of-the-art detection systems, YOLO makes more localization errors but is less likely to predict false positives on background. Finally, YOLO learns very general representations of objects. It outperforms other detection methods, including DPM and R-CNN, when generalizing from natural images to other domains like artwork.
我们的统一架构极快。基础 YOLO 模型以每秒 45 帧实时处理图像;更小的 Fast YOLO 竟达每秒 155 帧,mAP 仍是其他实时检测器的两倍。相对当时最优检测系统,YOLO 定位误差更多,但更不容易在背景上给出假阳性。最后,YOLO 学到的物体表示很通用:从自然图像泛化到艺术品等其他领域时,它超过 DPM 与 R-CNN 等检测方法。
1 Introduction
1 引言
Humans glance at an image and instantly know what objects are in the image, where they are, and how they interact. The human visual system is fast and accurate, allowing us to perform complex tasks like driving with little conscious thought. Fast, accurate algorithms for object detection would allow computers to drive cars without specialized sensors, enable assistive devices to convey real-time scene information to human users, and unlock the potential for general purpose, responsive robotic systems.
人瞥一眼图像,立刻知道里面有什么物体、在哪里、如何互动。人类视觉系统又快又准,开车这类复杂任务几乎不需刻意思考。若有快速、准确的目标检测算法,计算机就能在没有专用传感器时开车,辅助设备能向用户实时传达场景信息,也能解锁通用、可响应的机器人系统的潜力。
Current detection systems repurpose classifiers to perform detection. To detect an object, these systems take a classifier for that object and evaluate it at various locations and scales in a test image. Systems like deformable parts models (DPM) use a sliding window approach where the classifier is run at evenly spaced locations over the entire image [10].
现有检测系统多把分类器改造成检测器。要检测某物体,就拿该物体的分类器,在测试图的多个位置与尺度上评估。可变形部件模型(DPM)等系统用滑动窗口,在整图均匀间隔的位置上跑分类器 [10]。
More recent approaches like R-CNN use region proposal methods to first generate potential bounding boxes in an image and then run a classifier on these proposed boxes. After classification, post-processing is used to refine the bounding boxes, eliminate duplicate detections, and rescore the boxes based on other objects in the scene [13]. These complex pipelines are slow and hard to optimize because each individual component must be trained separately.
更新近的方法如 R-CNN 先用区域提议在图像中生成候选框,再对这些提议框跑分类器。分类之后还要后处理:精修边界框、消除重复检测,并依据场景中其他物体重新打分 [13]。这些复杂流水线又慢又难优化,因为各组件必须分开训练。
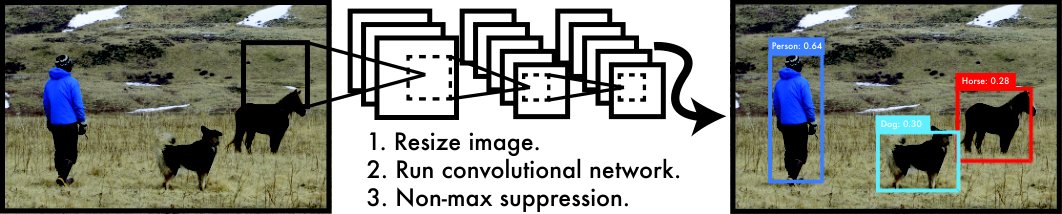
Figure 1: The YOLO Detection System. Processing images with YOLO is simple and straightforward. Our system (1) resizes the input image to , (2) runs a single convolutional network on the image, and (3) thresholds the resulting detections by the model’s confidence.
图 1:YOLO 检测系统。用 YOLO 处理图像简单直接。系统 (1) 把输入图缩放到 ,(2) 在图像上跑单个卷积网络,(3) 按模型置信度对检测结果做阈值。
We reframe object detection as a single regression problem, straight from image pixels to bounding box coordinates and class probabilities. Using our system, you only look once (YOLO) at an image to predict what objects are present and where they are.
我们把目标检测重新表述为单一回归问题:从图像像素直接到边界框坐标与类别概率。用我们的系统,你对图像只需看一次(you only look once,YOLO),就能预测有什么物体、在哪里。
YOLO is refreshingly simple: see Figure 1. A single convolutional network simultaneously predicts multiple bounding boxes and class probabilities for those boxes. YOLO trains on full images and directly optimizes detection performance. This unified model has several benefits over traditional methods of object detection.
YOLO 出奇地简单:见图 1。单个卷积网络同时预测多个边界框及这些框的类别概率。YOLO 在整图上训练,直接优化检测性能。相对传统目标检测方法,这一统一模型有若干好处。
First, YOLO is extremely fast. Since we frame detection as a regression problem we don’t need a complex pipeline. We simply run our neural network on a new image at test time to predict detections. Our base network runs at 45 frames per second with no batch processing on a Titan X GPU and a fast version runs at more than 150 fps. This means we can process streaming video in real-time with less than 25 milliseconds of latency. Furthermore, YOLO achieves more than twice the mean average precision of other real-time systems. For a demo of our system running in real-time on a webcam please see our project webpage: http://pjreddie.com/yolo/.
第一,YOLO 极快。既然把检测表述为回归,就不需要复杂流水线。测试时只需在新图上跑神经网络即可预测检测结果。基础网络在 Titan X GPU 上无批处理时跑 45 帧/秒,快速版超过 150 fps。这意味着我们可以以低于 25 毫秒的延迟实时处理流视频。此外,YOLO 的平均精度均值超过其他实时系统两倍以上。网络摄像头实时演示见项目主页:http://pjreddie.com/yolo/。
Second, YOLO reasons globally about the image when making predictions. Unlike sliding window and region proposal-based techniques, YOLO sees the entire image during training and test time so it implicitly encodes contextual information about classes as well as their appearance. Fast R-CNN, a top detection method [14], mistakes background patches in an image for objects because it can’t see the larger context. YOLO makes less than half the number of background errors compared to Fast R-CNN.
第二,YOLO 做预测时对图像做全局推理。与滑动窗口和基于区域提议的技术不同,YOLO 在训练与测试时都看见整图,因而隐式编码类别及其外观的上下文信息。当时顶尖的 Fast R-CNN [14] 会把图像中的背景块误当成物体,因为它看不见更大上下文。YOLO 的背景错误不到 Fast R-CNN 的一半。
Third, YOLO learns generalizable representations of objects. When trained on natural images and tested on artwork, YOLO outperforms top detection methods like DPM and R-CNN by a wide margin. Since YOLO is highly generalizable it is less likely to break down when applied to new domains or unexpected inputs.
第三,YOLO 学到可泛化的物体表示。在自然图像上训练、在艺术品上测试时,YOLO 大幅超过 DPM、R-CNN 等顶尖检测方法。由于泛化性强,应用到新领域或意外输入时更不容易崩溃。
YOLO still lags behind state-of-the-art detection systems in accuracy. While it can quickly identify objects in images it struggles to precisely localize some objects, especially small ones. We examine these tradeoffs further in our experiments.
YOLO 的精度仍落后于当时最优检测系统。它能快速识别图像中的物体,但精确定位——尤其是小物体——仍吃力。我们在实验中进一步审视这些权衡。
All of our training and testing code is open source. A variety of pretrained models are also available to download.
全部训练与测试代码开源,也可下载多种预训练模型。
2 Unified Detection
2 统一检测
We unify the separate components of object detection into a single neural network. Our network uses features from the entire image to predict each bounding box. It also predicts all bounding boxes across all classes for an image simultaneously. This means our network reasons globally about the full image and all the objects in the image. The YOLO design enables end-to-end training and real-time speeds while maintaining high average precision.
我们把目标检测的各个分离组件统一进单个神经网络。网络用整图特征预测每个边界框,也同时预测图像中所有类别的所有边界框。这意味着网络对整图及其中全部物体做全局推理。YOLO 设计在保持较高平均精度的同时,支持端到端训练与实时速度。
Our system divides the input image into an grid. If the center of an object falls into a grid cell, that grid cell is responsible for detecting that object.
系统把输入图像划分成 网格。若某物体中心落入某网格单元,该单元负责检测该物体。
Each grid cell predicts bounding boxes and confidence scores for those boxes. These confidence scores reflect how confident the model is that the box contains an object and also how accurate it thinks the box is that it predicts. Formally we define confidence as . If no object exists in that cell, the confidence scores should be zero. Otherwise we want the confidence score to equal the intersection over union (IOU) between the predicted box and the ground truth.
每个网格单元预测 个边界框及这些框的置信度分数。置信度既反映模型认为框内含有物体的把握,也反映它认为预测框有多准。形式上,置信度定义为 。若该单元没有物体,置信度应为零;否则我们希望置信度等于预测框与真值的交并比(IOU)。
Each bounding box consists of 5 predictions: , , , , and confidence. The coordinates represent the center of the box relative to the bounds of the grid cell. The width and height are predicted relative to the whole image. Finally the confidence prediction represents the IOU between the predicted box and any ground truth box.
每个边界框含 5 个预测:、、、 与置信度。 表示框中心相对该网格单元边界的位置;宽高相对整图预测;置信度表示预测框与任一真值框的 IOU。
Each grid cell also predicts conditional class probabilities, . These probabilities are conditioned on the grid cell containing an object. We only predict one set of class probabilities per grid cell, regardless of the number of boxes .
每个网格单元还预测 个条件类别概率 。这些概率以该单元含有物体为条件。不论框数 多少,每个网格单元只预测一组类别概率。
At test time we multiply the conditional class probabilities and the individual box confidence predictions,
测试时,我们把条件类别概率与各框置信度预测相乘,
which gives us class-specific confidence scores for each box. These scores encode both the probability of that class appearing in the box and how well the predicted box fits the object.
从而得到每个框的类别相关置信度。这些分数同时编码该类出现在框内的概率,以及预测框与物体的吻合程度。
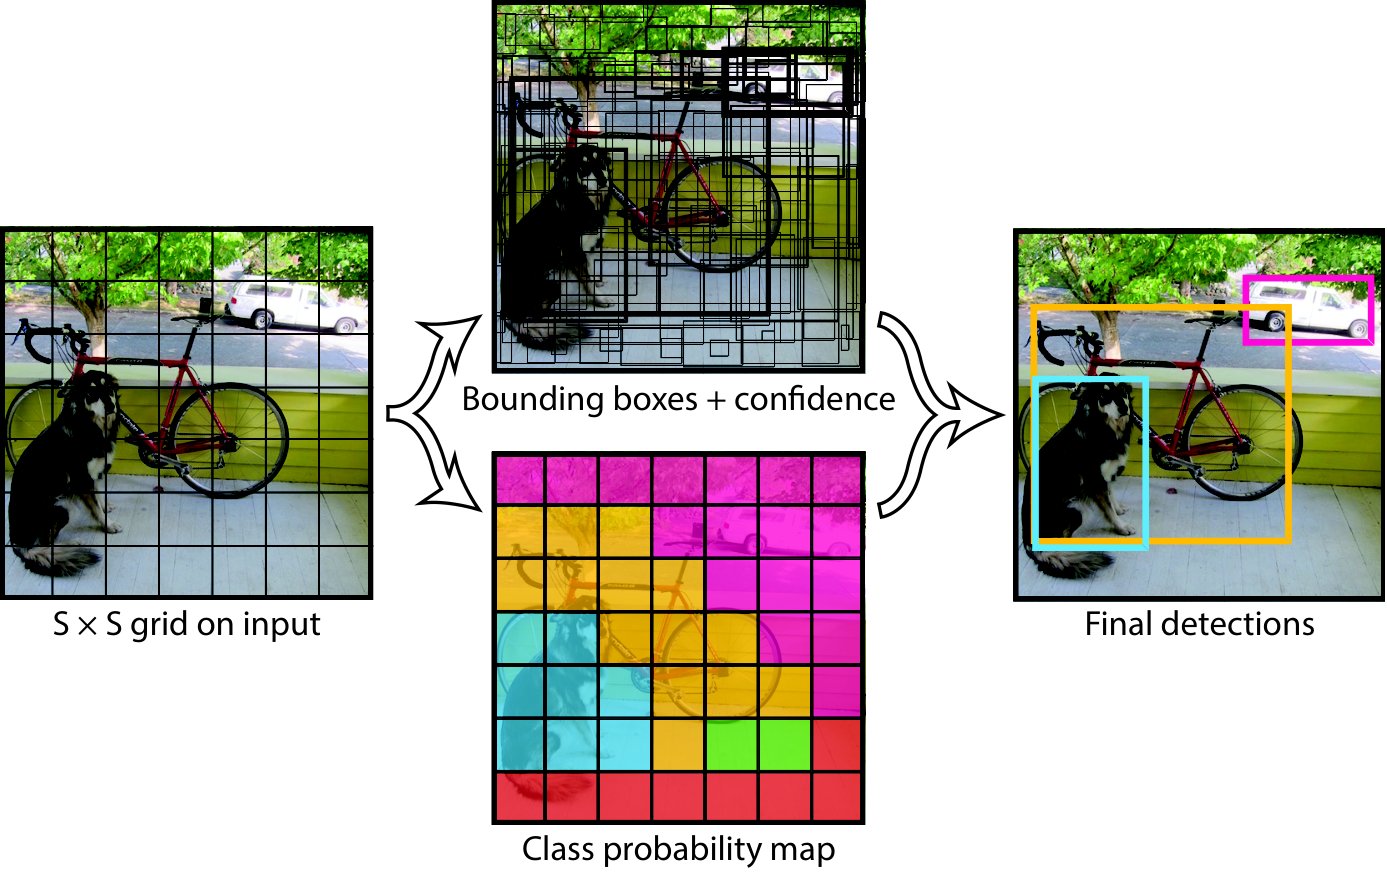
Figure 2: The Model. Our system models detection as a regression problem. It divides the image into an grid and for each grid cell predicts bounding boxes, confidence for those boxes, and class probabilities. These predictions are encoded as an tensor.
图 2:模型。系统把检测建模为回归问题。把图像划分成 网格,对每个网格单元预测 个边界框、这些框的置信度,以及 个类别概率。这些预测编码为 张量。
For evaluating YOLO on Pascal VOC, we use , . Pascal VOC has 20 labelled classes so . Our final prediction is a tensor.
在 Pascal VOC 上评估 YOLO 时,取 、。Pascal VOC 有 20 个标注类别,故 。最终预测是 张量。
2.1 Network Design
2.1 网络设计
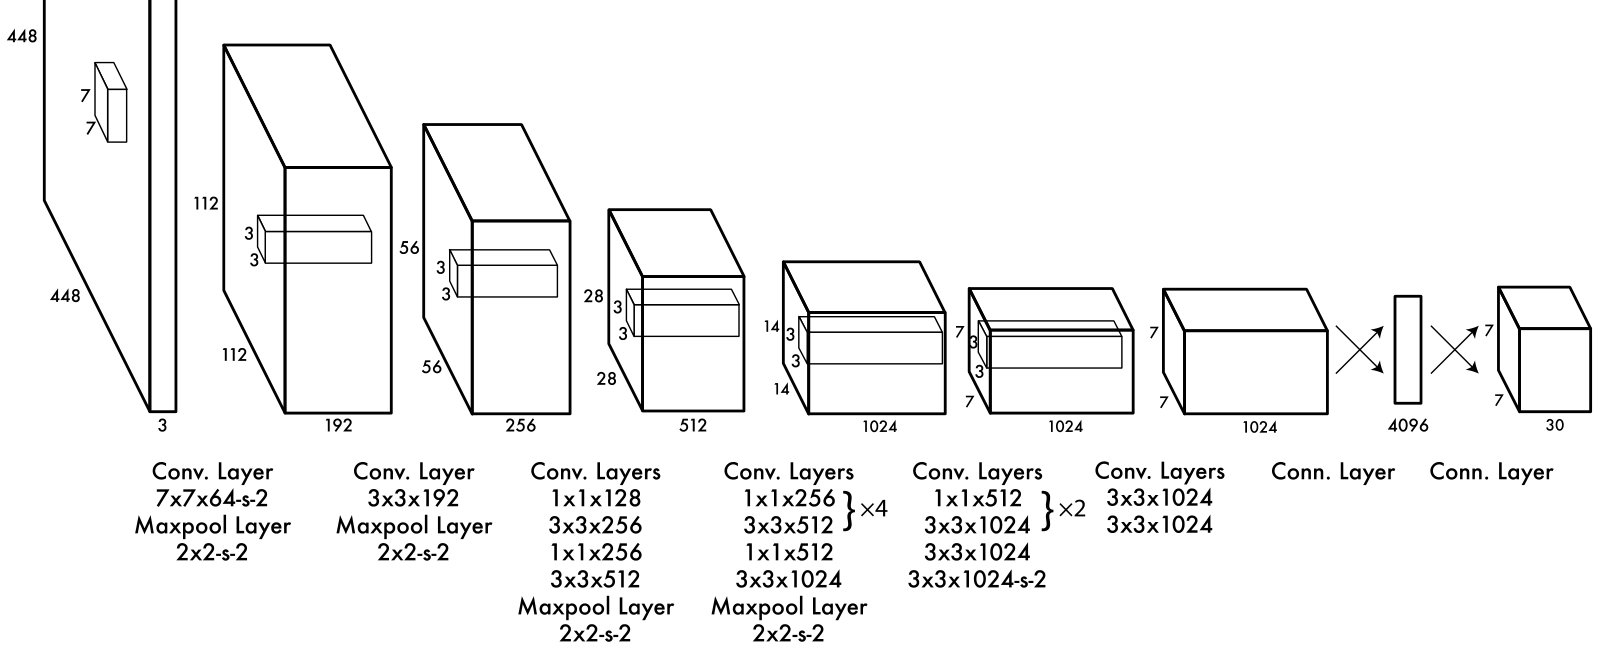
Figure 3: The Architecture. Our detection network has 24 convolutional layers followed by 2 fully connected layers. Alternating convolutional layers reduce the features space from preceding layers. We pretrain the convolutional layers on the ImageNet classification task at half the resolution ( input image) and then double the resolution for detection.
图 3:架构。检测网络有 24 个卷积层,后接 2 个全连接层。交替的 卷积层压缩前层特征空间。我们在 ImageNet 分类任务上以一半分辨率( 输入)预训练卷积层,再把分辨率加倍用于检测。
We implement this model as a convolutional neural network and evaluate it on the Pascal VOC detection dataset [9]. The initial convolutional layers of the network extract features from the image while the fully connected layers predict the output probabilities and coordinates.
我们把该模型实现为卷积神经网络,并在 Pascal VOC 检测数据集 [9] 上评估。网络前部卷积层从图像提取特征,全连接层预测输出概率与坐标。
Our network architecture is inspired by the GoogLeNet model for image classification [34]. Our network has 24 convolutional layers followed by 2 fully connected layers. Instead of the inception modules used by GoogLeNet, we simply use reduction layers followed by convolutional layers, similar to Lin et al [22]. The full network is shown in Figure 3.
网络架构受图像分类的 GoogLeNet [34] 启发:24 个卷积层后接 2 个全连接层。我们不用 GoogLeNet 的 inception 模块,而简单使用 降维层再接 卷积,类似 Lin 等人 [22]。完整网络见图 3。
We also train a fast version of YOLO designed to push the boundaries of fast object detection. Fast YOLO uses a neural network with fewer convolutional layers (9 instead of 24) and fewer filters in those layers. Other than the size of the network, all training and testing parameters are the same between YOLO and Fast YOLO.
我们还训练了面向极速检测的 Fast YOLO:卷积层更少(9 而非 24),层内滤波器也更少。除网络规模外,YOLO 与 Fast YOLO 的训练测试超参相同。
The final output of our network is the tensor of predictions.
网络最终输出是 的预测张量。
2.2 Training
2.2 训练
We pretrain our convolutional layers on the ImageNet 1000-class competition dataset [30]. For pretraining we use the first 20 convolutional layers from Figure 3 followed by a average-pooling layer and a fully connected layer. We train this network for approximately a week and achieve a single crop top-5 accuracy of 88% on the ImageNet 2012 validation set, comparable to the GoogLeNet models in Caffe’s Model Zoo [24]. We use the Darknet framework for all training and inference [26].
我们在 ImageNet 1000 类竞赛数据集 [30] 上预训练卷积层。预训练使用图 3 的前 20 个卷积层,再接平均池化与全连接层。约训练一周,在 ImageNet 2012 验证集上单裁剪 top-5 准确率达 88%,与 Caffe Model Zoo 中的 GoogLeNet 模型相当 [24]。训练与推理均使用 Darknet 框架 [26]。
We then convert the model to perform detection. Ren et al. show that adding both convolutional and connected layers to pretrained networks can improve performance [29]. Following their example, we add four convolutional layers and two fully connected layers with randomly initialized weights. Detection often requires fine-grained visual information so we increase the input resolution of the network from to .
随后把模型改造成做检测。Ren 等人表明:在预训练网络上再加卷积与连接层可提升性能 [29]。我们沿此做法,加入四个卷积层与两个全连接层,权重随机初始化。检测常需细粒度视觉信息,因而把输入分辨率从 提高到 。
Our final layer predicts both class probabilities and bounding box coordinates. We normalize the bounding box width and height by the image width and height so that they fall between 0 and 1. We parametrize the bounding box and coordinates to be offsets of a particular grid cell location so they are also bounded between 0 and 1.
最后一层同时预测类别概率与边界框坐标。我们用图像宽高归一化边界框宽高,使其落在 0 到 1;并把边界框 、 参数化为相对特定网格单元位置的偏移,同样落在 0 到 1。
We use a linear activation function for the final layer and all other layers use the following leaky rectified linear activation:
最后一层用线性激活,其余层用如下 leaky ReLU:
$$\phi(x)=\begin{cases}x,&\text{if }x>0\
0.1x,&\text{otherwise}\end{cases} \tag{2}$$
We optimize for sum-squared error in the output of our model. We use sum-squared error because it is easy to optimize, however it does not perfectly align with our goal of maximizing average precision. It weights localization error equally with classification error which may not be ideal. Also, in every image many grid cells do not contain any object. This pushes the “confidence” scores of those cells towards zero, often overpowering the gradient from cells that do contain objects. This can lead to model instability, causing training to diverge early on.
我们优化模型输出上的平方和误差。选用它是因为容易优化,但它与最大化平均精度的目标并不完全对齐:定位误差与分类误差被同等加权,未必理想。此外,每张图中许多网格单元不含物体,会把这些单元的“置信度”推向零,常压过含物体单元的梯度,导致模型不稳定,训练早期就发散。
To remedy this, we increase the loss from bounding box coordinate predictions and decrease the loss from confidence predictions for boxes that don’t contain objects. We use two parameters, and to accomplish this. We set and .
为此,我们增大边界框坐标预测的损失,减小不含物体框的置信度损失。用两个参数 与 实现,取 、。
Sum-squared error also equally weights errors in large boxes and small boxes. Our error metric should reflect that small deviations in large boxes matter less than in small boxes. To partially address this we predict the square root of the bounding box width and height instead of the width and height directly.
平方和误差还同等加权大框与小框上的误差。误差度量应体现:大框上的小偏差不如小框上重要。为部分解决,我们预测边界框宽高的平方根,而非直接预测宽高。
YOLO predicts multiple bounding boxes per grid cell. At training time we only want one bounding box predictor to be responsible for each object. We assign one predictor to be “responsible” for predicting an object based on which prediction has the highest current IOU with the ground truth. This leads to specialization between the bounding box predictors. Each predictor gets better at predicting certain sizes, aspect ratios, or classes of object, improving overall recall.
YOLO 每个网格单元预测多个边界框。训练时我们只希望一个边界框预测器对每个物体负责。按当前与真值 IOU 最高的预测,指定一个预测器“负责”该物体。这带来边界框预测器之间的特化:各预测器更擅长某些尺寸、宽高比或类别,从而提升整体召回。
During training we optimize the following, multi-part loss function:
训练时我们优化如下多部分损失函数:
$$\lambda_{\textbf{coord}}\sum_{i=0}^{S^{2}}\sum_{j=0}^{B}{\mathbbm{1}}{ij}^{\text{obj}}\left[\left(x{i}-\hat{x}{i}\right)^{2}+\left(y{i}-\hat{y}{i}\right)^{2}\right]\
+\lambda{\textbf{coord}}\sum_{i=0}^{S^{2}}\sum_{j=0}^{B}{\mathbbm{1}}{ij}^{\text{obj}}\left[\left(\sqrt{w{i}}-\sqrt{\hat{w}{i}}\right)^{2}+\left(\sqrt{h{i}}-\sqrt{\hat{h}{i}}\right)^{2}\right]\
+\sum{i=0}^{S^{2}}\sum_{j=0}^{B}{\mathbbm{1}}{ij}^{\text{obj}}\left(C{i}-\hat{C}{i}\right)^{2}\
+\lambda{\textrm{noobj}}\sum_{i=0}^{S^{2}}\sum_{j=0}^{B}{\mathbbm{1}}{ij}^{\text{noobj}}\left(C{i}-\hat{C}{i}\right)^{2}\
+\sum{i=0}^{S^{2}}{\mathbbm{1}}{i}^{\text{obj}}\sum{c\in\textrm{classes}}\left(p_{i}(c)-\hat{p}_{i}(c)\right)^{2} \tag{3}$$
where denotes if object appears in cell and denotes that the th bounding box predictor in cell is “responsible” for that prediction.
其中 表示单元 是否出现物体, 表示单元 中第 个边界框预测器对该预测“负责”。
Note that the loss function only penalizes classification error if an object is present in that grid cell (hence the conditional class probability discussed earlier). It also only penalizes bounding box coordinate error if that predictor is “responsible” for the ground truth box (i.e. has the highest IOU of any predictor in that grid cell).
注意:仅当该网格单元存在物体时,损失函数才惩罚分类误差(故有前文条件类别概率)。也仅当该预测器对真值框“负责”(即在该单元所有预测器中 IOU 最高)时,才惩罚边界框坐标误差。
We train the network for about 135 epochs on the training and validation data sets from Pascal VOC 2007 and 2012. When testing on 2012 we also include the VOC 2007 test data for training. Throughout training we use a batch size of 64, a momentum of and a decay of .
我们在 Pascal VOC 2007 与 2012 的训练与验证集上约训练 135 个 epoch。在 2012 上测试时,训练也纳入 VOC 2007 测试数据。全程 batch size 为 64,动量 ,衰减 。
Our learning rate schedule is as follows: For the first epochs we slowly raise the learning rate from to . If we start at a high learning rate our model often diverges due to unstable gradients. We continue training with for 75 epochs, then for 30 epochs, and finally for 30 epochs.
学习率日程如下:前几个 epoch 把学习率从 缓慢升到 。若一开始就用高学习率,不稳定梯度常使模型发散。随后以 训练 75 个 epoch,再以 训练 30 个 epoch,最后以 训练 30 个 epoch。
To avoid overfitting we use dropout and extensive data augmentation. A dropout layer with rate = .5 after the first connected layer prevents co-adaptation between layers [18]. For data augmentation we introduce random scaling and translations of up to 20% of the original image size. We also randomly adjust the exposure and saturation of the image by up to a factor of in the HSV color space.
为避免过拟合,我们使用 dropout 与大量数据增强。第一个连接层后加 rate=.5 的 dropout,防止层间共适应 [18]。数据增强包括最多原图尺寸 20% 的随机缩放与平移,并在 HSV 空间把曝光与饱和度随机调整至多 倍。
2.3 Inference
2.3 推理
Just like in training, predicting detections for a test image only requires one network evaluation. On Pascal VOC the network predicts 98 bounding boxes per image and class probabilities for each box. YOLO is extremely fast at test time since it only requires a single network evaluation, unlike classifier-based methods.
与训练一样,对测试图预测检测只需一次网络评估。在 Pascal VOC 上,网络每图预测 98 个边界框及每个框的类别概率。YOLO 测试极快,因为只需单次网络评估,不像基于分类器的方法。
The grid design enforces spatial diversity in the bounding box predictions. Often it is clear which grid cell an object falls in to and the network only predicts one box for each object. However, some large objects or objects near the border of multiple cells can be well localized by multiple cells. Non-maximal suppression can be used to fix these multiple detections. While not critical to performance as it is for R-CNN or DPM, non-maximal suppression adds 2-3% in mAP.
网格设计迫使边界框预测具有空间多样性。物体落入哪个网格单元通常很清楚,网络往往每个物体只预测一个框。但有些大物体或靠近多个单元边界的物体,可能被多个单元较好定位。可用非极大值抑制修正这些重复检测。虽不像对 R-CNN 或 DPM 那样关键,非极大值抑制仍可带来 2–3% mAP。
2.4 Limitations of YOLO
2.4 YOLO 的局限
YOLO imposes strong spatial constraints on bounding box predictions since each grid cell only predicts two boxes and can only have one class. This spatial constraint limits the number of nearby objects that our model can predict. Our model struggles with small objects that appear in groups, such as flocks of birds.
YOLO 对边界框预测施加很强的空间约束:每个网格单元只预测两个框,且只能有一个类别。这一约束限制了模型能预测的邻近物体数量。模型对成群出现的小物体(如鸟群)很吃力。
Since our model learns to predict bounding boxes from data, it struggles to generalize to objects in new or unusual aspect ratios or configurations. Our model also uses relatively coarse features for predicting bounding boxes since our architecture has multiple downsampling layers from the input image.
由于模型从数据中学习预测边界框,对新的或异常的宽高比与构型泛化困难。架构从输入图经过多层下采样,用于预测边界框的特征也相对粗糙。
Finally, while we train on a loss function that approximates detection performance, our loss function treats errors the same in small bounding boxes versus large bounding boxes. A small error in a large box is generally benign but a small error in a small box has a much greater effect on IOU. Our main source of error is incorrect localizations.
最后,尽管我们在近似检测性能的损失函数上训练,该损失对小框与大框上的误差一视同仁。大框上的小误差通常无妨,小框上的小误差对 IOU 影响大得多。我们的主要误差来源是定位不准。
3 Comparison to Other Detection Systems
3 与其他检测系统的比较
Object detection is a core problem in computer vision. Detection pipelines generally start by extracting a set of robust features from input images (Haar [25], SIFT [23], HOG [4], convolutional features [6]). Then, classifiers [36, 21, 13, 10] or localizers [1, 32] are used to identify objects in the feature space. These classifiers or localizers are run either in sliding window fashion over the whole image or on some subset of regions in the image [35, 15, 39]. We compare the YOLO detection system to several top detection frameworks, highlighting key similarities and differences.
目标检测是计算机视觉的核心问题。检测流水线通常先从输入图提取稳健特征(Haar [25]、SIFT [23]、HOG [4]、卷积特征 [6]),再用分类器 [36, 21, 13, 10] 或定位器 [1, 32] 在特征空间中识别物体。这些分类器或定位器以滑动窗口跑遍整图,或只跑在图像的某些区域子集上 [35, 15, 39]。我们把 YOLO 与若干顶尖检测框架比较,突出关键异同。
Deformable parts models. Deformable parts models (DPM) use a sliding window approach to object detection [10]. DPM uses a disjoint pipeline to extract static features, classify regions, predict bounding boxes for high scoring regions, etc. Our system replaces all of these disparate parts with a single convolutional neural network. The network performs feature extraction, bounding box prediction, non-maximal suppression, and contextual reasoning all concurrently. Instead of static features, the network trains the features in-line and optimizes them for the detection task. Our unified architecture leads to a faster, more accurate model than DPM.
可变形部件模型。 可变形部件模型(DPM)用滑动窗口做目标检测 [10]。DPM 用割裂的流水线提取静态特征、分类区域、对高分区域预测边界框等。我们的系统用单个卷积神经网络替换所有这些分散部件。网络同时做特征提取、边界框预测、非极大值抑制与上下文推理。特征不是静态的,而是在线训练并为检测任务优化。统一架构带来比 DPM 更快、更准的模型。
R-CNN. R-CNN and its variants use region proposals instead of sliding windows to find objects in images. Selective Search [35] generates potential bounding boxes, a convolutional network extracts features, an SVM scores the boxes, a linear model adjusts the bounding boxes, and non-max suppression eliminates duplicate detections. Each stage of this complex pipeline must be precisely tuned independently and the resulting system is very slow, taking more than 40 seconds per image at test time [14].
R-CNN。 R-CNN 及其变体用区域提议而非滑动窗口在图像中找物体。Selective Search [35] 生成候选框,卷积网络提特征,SVM 给框打分,线性模型调整边界框,非极大值抑制消除重复。复杂流水线的每一阶段都需单独精细调参,系统很慢,测试时每图超过 40 秒 [14]。
YOLO shares some similarities with R-CNN. Each grid cell proposes potential bounding boxes and scores those boxes using convolutional features. However, our system puts spatial constraints on the grid cell proposals which helps mitigate multiple detections of the same object. Our system also proposes far fewer bounding boxes, only 98 per image compared to about 2000 from Selective Search. Finally, our system combines these individual components into a single, jointly optimized model.
YOLO 与 R-CNN 有一些相似:每个网格单元提出潜在边界框,并用卷积特征打分。但我们的系统对网格单元提议施加空间约束,有助于减轻同一物体的多重检测;提议框也少得多——每图仅 98 个,而 Selective Search 约 2000 个。最后,我们把这些组件合成单一、联合优化的模型。
Other Fast Detectors Fast and Faster R-CNN focus on speeding up the R-CNN framework by sharing computation and using neural networks to propose regions instead of Selective Search [14] [28]. While they offer speed and accuracy improvements over R-CNN, both still fall short of real-time performance.
其他快速检测器 Fast 与 Faster R-CNN 通过共享计算、用神经网络代替 Selective Search 做区域提议,来加速 R-CNN 框架 [14][28]。相对 R-CNN 确有速度与精度提升,但仍达不到实时。
Many research efforts focus on speeding up the DPM pipeline [31] [38] [5]. They speed up HOG computation, use cascades, and push computation to GPUs. However, only 30Hz DPM [31] actually runs in real-time.
许多工作聚焦加速 DPM 流水线 [31][38][5]:加快 HOG 计算、用级联、把计算推到 GPU。但真正实时的只有 30Hz DPM [31]。
Instead of trying to optimize individual components of a large detection pipeline, YOLO throws out the pipeline entirely and is fast by design.
YOLO 不试图优化大型检测流水线的各个组件,而是直接扔掉流水线,从设计上就快。
Detectors for single classes like faces or people can be highly optimized since they have to deal with much less variation [37]. YOLO is a general purpose detector that learns to detect a variety of objects simultaneously.
人脸或行人等单类检测器可高度优化,因为变化少得多 [37]。YOLO 是通用检测器,同时学习检测多种物体。
Deep MultiBox. Unlike R-CNN, Szegedy et al. train a convolutional neural network to predict regions of interest [8] instead of using Selective Search. MultiBox can also perform single object detection by replacing the confidence prediction with a single class prediction. However, MultiBox cannot perform general object detection and is still just a piece in a larger detection pipeline, requiring further image patch classification. Both YOLO and MultiBox use a convolutional network to predict bounding boxes in an image but YOLO is a complete detection system.
Deep MultiBox。 与 R-CNN 不同,Szegedy 等人训练卷积神经网络预测感兴趣区域 [8],而非用 Selective Search。MultiBox 也可把置信度预测换成单类预测,做单物体检测。但 MultiBox 不能做通用目标检测,仍只是更大检测流水线中的一块,还需要进一步的图像块分类。YOLO 与 MultiBox 都用卷积网络预测图像中的边界框,但 YOLO 是完整检测系统。
OverFeat. Sermanet et al. train a convolutional neural network to perform localization and adapt that localizer to perform detection [32]. OverFeat efficiently performs sliding window detection but it is still a disjoint system. OverFeat optimizes for localization, not detection performance. Like DPM, the localizer only sees local information when making a prediction. OverFeat cannot reason about global context and thus requires significant post-processing to produce coherent detections.
OverFeat。 Sermanet 等人训练卷积神经网络做定位,再把定位器改造成检测 [32]。OverFeat 高效做滑动窗口检测,但仍是割裂系统;它为定位而非检测性能优化。与 DPM 一样,定位器做预测时只看见局部信息,无法推理全局上下文,因而需要大量后处理才能得到连贯检测。
MultiGrasp. Our work is similar in design to work on grasp detection by Redmon et al [27]. Our grid approach to bounding box prediction is based on the MultiGrasp system for regression to grasps. However, grasp detection is a much simpler task than object detection. MultiGrasp only needs to predict a single graspable region for an image containing one object. It doesn’t have to estimate the size, location, or boundaries of the object or predict it’s class, only find a region suitable for grasping. YOLO predicts both bounding boxes and class probabilities for multiple objects of multiple classes in an image.
MultiGrasp。 我们的工作在设计上类似 Redmon 等人的抓取检测 [27]。边界框预测的网格思路来自 MultiGrasp 对抓取的回归。但抓取检测远比目标检测简单:MultiGrasp 只需为含单个物体的图像预测一个可抓区域,不必估计物体尺寸、位置或边界,也不必预测类别,只要找到适合抓取的区域。YOLO 则为图像中多类多个物体同时预测边界框与类别概率。
4 Experiments
4 实验
First we compare YOLO with other real-time detection systems on Pascal VOC 2007. To understand the differences between YOLO and R-CNN variants we explore the errors on VOC 2007 made by YOLO and Fast R-CNN, one of the highest performing versions of R-CNN [14]. Based on the different error profiles we show that YOLO can be used to rescore Fast R-CNN detections and reduce the errors from background false positives, giving a significant performance boost. We also present VOC 2012 results and compare mAP to current state-of-the-art methods. Finally, we show that YOLO generalizes to new domains better than other detectors on two artwork datasets.
我们先在 Pascal VOC 2007 上把 YOLO 与其他实时检测系统比较。为理解 YOLO 与 R-CNN 变体的差异,我们分析 YOLO 与 Fast R-CNN(R-CNN 表现最好的版本之一 [14])在 VOC 2007 上的误差。基于不同的误差分布,我们展示可用 YOLO 给 Fast R-CNN 检测重新打分,减少背景假阳性带来的误差,从而显著提升性能。我们也给出 VOC 2012 结果,并与当时最优方法比较 mAP。最后,在两个艺术品数据集上展示 YOLO 比其他检测器更能泛化到新领域。
4.1 Comparison to Other Real-Time Systems
4.1 与其他实时系统的比较
Many research efforts in object detection focus on making standard detection pipelines fast. [5] [38] [31] [14] [17] [28] However, only Sadeghi et al. actually produce a detection system that runs in real-time (30 frames per second or better) [31]. We compare YOLO to their GPU implementation of DPM which runs either at 30Hz or 100Hz. While the other efforts don’t reach the real-time milestone we also compare their relative mAP and speed to examine the accuracy-performance tradeoffs available in object detection systems.
目标检测领域许多工作聚焦于把标准检测流水线做快。[5][38][31][14][17][28] 但真正做出实时检测系统(每秒 30 帧或以上)的只有 Sadeghi 等人 [31]。我们把 YOLO 与他们的 GPU 版 DPM 比较,后者跑在 30Hz 或 100Hz。其余工作虽未达实时,我们也比较相对 mAP 与速度,以审视目标检测系统中精度—性能的权衡。
| Real-Time Detectors | Train | mAP | FPS |
|---|---|---|---|
| 100Hz DPM [31] | 2007 | 16.0 | 100 |
| 30Hz DPM [31] | 2007 | 26.1 | 30 |
| Fast YOLO | 2007+2012 | 52.7 | 155 |
| YOLO | 2007+2012 | 63.4 | 45 |
| Less Than Real-Time | |||
| Fastest DPM [38] | 2007 | 30.4 | 15 |
| R-CNN Minus R [20] | 2007 | 53.5 | 6 |
| Fast R-CNN [14] | 2007+2012 | 70.0 | 0.5 |
| Faster R-CNN VGG-16[28] | 2007+2012 | 73.2 | 7 |
| Faster R-CNN ZF [28] | 2007+2012 | 62.1 | 18 |
| YOLO VGG-16 | 2007+2012 | 66.4 | 21 |
Table 1: Real-Time Systems on Pascal VOC 2007. Comparing the performance and speed of fast detectors. Fast YOLO is the fastest detector on record for Pascal VOC detection and is still twice as accurate as any other real-time detector. YOLO is 10 mAP more accurate than the fast version while still well above real-time in speed.
| Real-Time Detectors | Train | mAP | FPS |
|---|---|---|---|
| 100Hz DPM [31] | 2007 | 16.0 | 100 |
| 30Hz DPM [31] | 2007 | 26.1 | 30 |
| Fast YOLO | 2007+2012 | 52.7 | 155 |
| YOLO | 2007+2012 | 63.4 | 45 |
| Less Than Real-Time | |||
| Fastest DPM [38] | 2007 | 30.4 | 15 |
| R-CNN Minus R [20] | 2007 | 53.5 | 6 |
| Fast R-CNN [14] | 2007+2012 | 70.0 | 0.5 |
| Faster R-CNN VGG-16[28] | 2007+2012 | 73.2 | 7 |
| Faster R-CNN ZF [28] | 2007+2012 | 62.1 | 18 |
| YOLO VGG-16 | 2007+2012 | 66.4 | 21 |
表 1:Pascal VOC 2007 上的实时系统。比较快速检测器的性能与速度。Fast YOLO 是 Pascal VOC 检测有记录以来最快的检测器,精度仍是其他实时检测器的两倍。YOLO 比快速版再高 10 mAP,速度仍远超实时。
Fast YOLO is the fastest object detection method on Pascal; as far as we know, it is the fastest extant object detector. With mAP, it is more than twice as accurate as prior work on real-time detection. YOLO pushes mAP to while still maintaining real-time performance.
Fast YOLO 是 Pascal 上最快的目标检测方法;据我们所知,也是现存最快的目标检测器。以 mAP,它比先前实时检测工作准两倍以上。YOLO 把 mAP 推到 ,同时仍保持实时。
We also train YOLO using VGG-16. This model is more accurate but also significantly slower than YOLO. It is useful for comparison to other detection systems that rely on VGG-16 but since it is slower than real-time the rest of the paper focuses on our faster models.
我们还用 VGG-16 训练 YOLO。该模型更准,但也明显更慢。它便于与依赖 VGG-16 的其他检测系统比较;因达不到实时,后文仍聚焦我们的更快模型。
Fastest DPM effectively speeds up DPM without sacrificing much mAP but it still misses real-time performance by a factor of 2 [38]. It also is limited by DPM’s relatively low accuracy on detection compared to neural network approaches.
Fastest DPM 有效加速 DPM 且几乎不牺牲 mAP,但仍差实时约 2 倍 [38]。它也受限于 DPM 相对神经网络方法较低的检测精度。
R-CNN minus R replaces Selective Search with static bounding box proposals [20]. While it is much faster than R-CNN, it still falls short of real-time and takes a significant accuracy hit from not having good proposals.
R-CNN minus R 用静态边界框提议替换 Selective Search [20]。虽比 R-CNN 快得多,仍达不到实时,且因缺少好提议而精度损失明显。
Fast R-CNN speeds up the classification stage of R-CNN but it still relies on selective search which can take around 2 seconds per image to generate bounding box proposals. Thus it has high mAP but at fps it is still far from real-time.
Fast R-CNN 加速了 R-CNN 的分类阶段,但仍依赖 Selective Search,每图生成边界框提议约需 2 秒。因此 mAP 高,但以 fps 仍远离实时。
The recent Faster R-CNN replaces selective search with a neural network to propose bounding boxes, similar to Szegedy et al. [8] In our tests, their most accurate model achieves 7 fps while a smaller, less accurate one runs at 18 fps. The VGG-16 version of Faster R-CNN is 10 mAP higher but is also 6 times slower than YOLO. The Zeiler-Fergus Faster R-CNN is only 2.5 times slower than YOLO but is also less accurate.
近期的 Faster R-CNN 用神经网络代替 Selective Search 做边界框提议,类似 Szegedy 等人 [8]。在我们的测试中,其最准模型达 7 fps,较小、较不准的版本跑 18 fps。VGG-16 版 Faster R-CNN 比 YOLO 高 10 mAP,但也慢 6 倍;Zeiler-Fergus 版 Faster R-CNN 仅慢约 2.5 倍,但精度也更低。
4.2 VOC 2007 Error Analysis
4.2 VOC 2007 误差分析
To further examine the differences between YOLO and state-of-the-art detectors, we look at a detailed breakdown of results on VOC 2007. We compare YOLO to Fast R-CNN since Fast R-CNN is one of the highest performing detectors on Pascal and it’s detections are publicly available.
为进一步审视 YOLO 与当时最优检测器的差异,我们细看 VOC 2007 结果。与 Fast R-CNN 比较——它是 Pascal 上表现最好的检测器之一,且检测结果公开可得。
We use the methodology and tools of Hoiem et al. [19] For each category at test time we look at the top N predictions for that category. Each prediction is either correct or it is classified based on the type of error:
我们采用 Hoiem 等人的方法与工具 [19]。测试时对每个类别看该类别的 top N 预测。每个预测要么正确,要么按误差类型分类:
- • Correct: correct class and
- • Localization: correct class,
- • Similar: class is similar,
- • Other: class is wrong,
- • Background: for any object
- • Correct:类别正确且
- • Localization:类别正确,
- • Similar:类别相近,
- • Other:类别错误,
- • Background:对任何物体
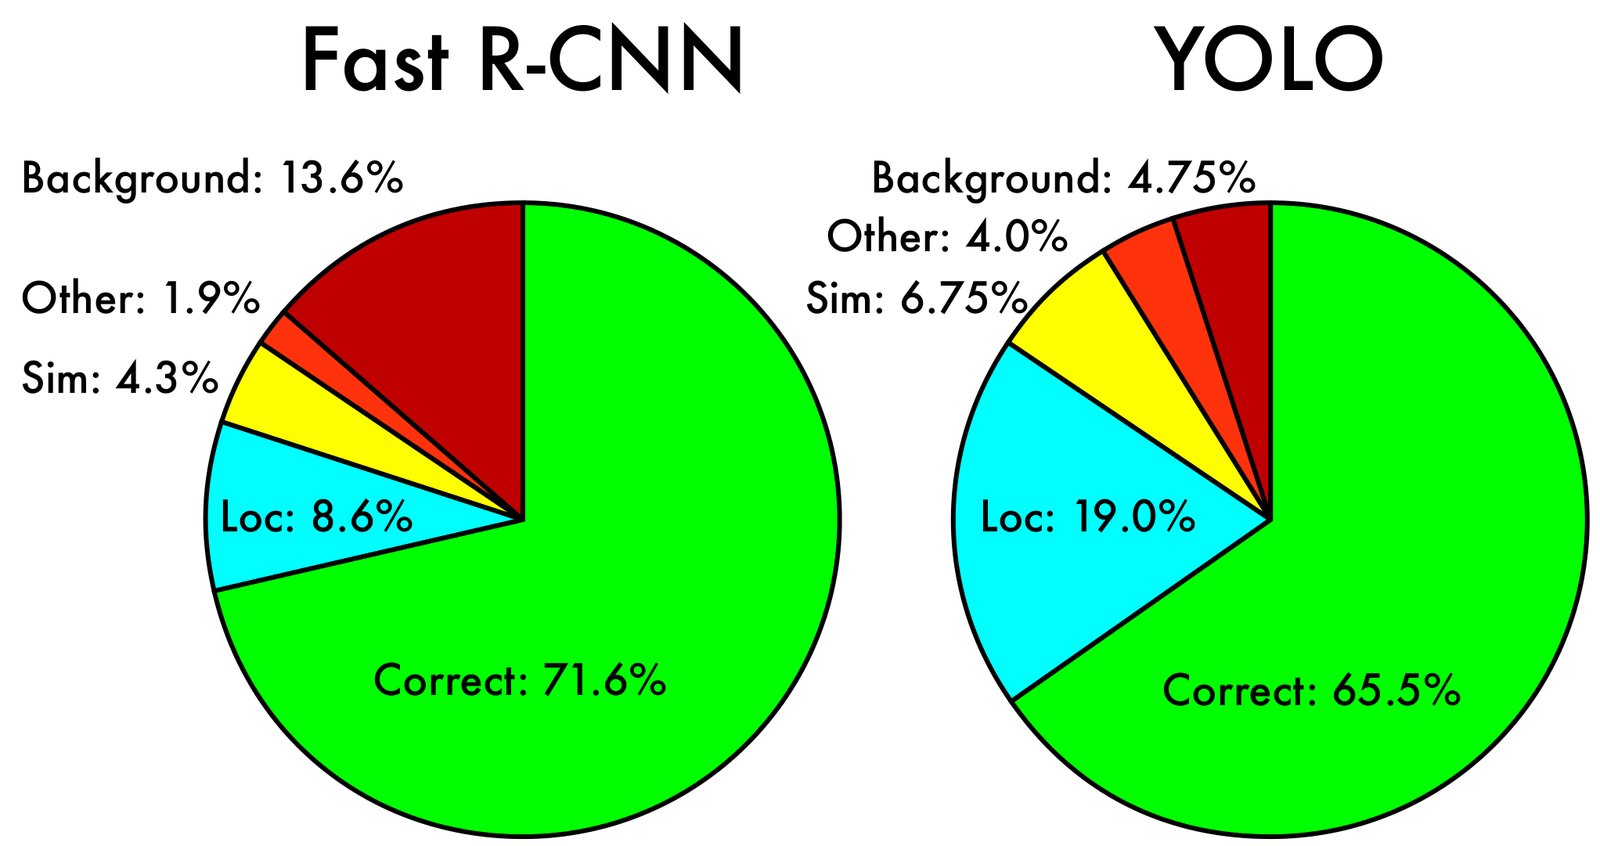
Figure 4 shows the breakdown of each error type averaged across all 20 classes.
图 4 给出在全部 20 类上平均的各误差类型占比。
Figure 4: Error Analysis: Fast R-CNN vs. YOLO These charts show the percentage of localization and background errors in the top N detections for various categories (N = # objects in that category).
图 4:误差分析:Fast R-CNN 对比 YOLO。这些图显示各类别 top N 检测中定位误差与背景误差的百分比(N = 该类物体数)。
YOLO struggles to localize objects correctly. Localization errors account for more of YOLO’s errors than all other sources combined. Fast R-CNN makes much fewer localization errors but far more background errors. 13.6% of it’s top detections are false positives that don’t contain any objects. Fast R-CNN is almost 3x more likely to predict background detections than YOLO.
YOLO 精确定位物体仍吃力。定位误差超过 YOLO 其余误差来源之和。Fast R-CNN 定位误差少得多,但背景误差多得多:其 top 检测中 13.6% 是不含任何物体的假阳性。Fast R-CNN 预测背景检测的概率几乎是 YOLO 的 3 倍。
4.3 Combining Fast R-CNN and YOLO
4.3 结合 Fast R-CNN 与 YOLO
| mAP | Combined | Gain | |
|---|---|---|---|
| Fast R-CNN | 71.8 | - | - |
| Fast R-CNN (2007 data) | 66.9 | 72.4 | .6 |
| Fast R-CNN (VGG-M) | 59.2 | 72.4 | .6 |
| Fast R-CNN (CaffeNet) | 57.1 | 72.1 | .3 |
| YOLO | 63.4 | 75.0 | 3.2 |
Table 2: Model combination experiments on VOC 2007. We examine the effect of combining various models with the best version of Fast R-CNN. Other versions of Fast R-CNN provide only a small benefit while YOLO provides a significant performance boost.
| mAP | Combined | Gain | |
|---|---|---|---|
| Fast R-CNN | 71.8 | - | - |
| Fast R-CNN (2007 data) | 66.9 | 72.4 | .6 |
| Fast R-CNN (VGG-M) | 59.2 | 72.4 | .6 |
| Fast R-CNN (CaffeNet) | 57.1 | 72.1 | .3 |
| YOLO | 63.4 | 75.0 | 3.2 |
表 2:VOC 2007 上的模型组合实验。我们考察把多种模型与最佳 Fast R-CNN 结合的效果。其他版本的 Fast R-CNN 收益很小,而 YOLO 带来显著提升。
| VOC 2012 test | mAP | aero | bike | bird | boat | bottle | bus | car | cat | chair | cow | table | dog | horse | mbike | person | plant | sheep | sofa | train | tv |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| MR_CNN_MORE_DATA [11] | 73.9 | 85.5 | 82.9 | 76.6 | 57.8 | 62.7 | 79.4 | 77.2 | 86.6 | 55.0 | 79.1 | 62.2 | 87.0 | 83.4 | 84.7 | 78.9 | 45.3 | 73.4 | 65.8 | 80.3 | 74.0 |
| HyperNet_VGG | 71.4 | 84.2 | 78.5 | 73.6 | 55.6 | 53.7 | 78.7 | 79.8 | 87.7 | 49.6 | 74.9 | 52.1 | 86.0 | 81.7 | 83.3 | 81.8 | 48.6 | 73.5 | 59.4 | 79.9 | 65.7 |
| HyperNet_SP | 71.3 | 84.1 | 78.3 | 73.3 | 55.5 | 53.6 | 78.6 | 79.6 | 87.5 | 49.5 | 74.9 | 52.1 | 85.6 | 81.6 | 83.2 | 81.6 | 48.4 | 73.2 | 59.3 | 79.7 | 65.6 |
| Fast R-CNN + YOLO | 70.7 | 83.4 | 78.5 | 73.5 | 55.8 | 43.4 | 79.1 | 73.1 | 89.4 | 49.4 | 75.5 | 57.0 | 87.5 | 80.9 | 81.0 | 74.7 | 41.8 | 71.5 | 68.5 | 82.1 | 67.2 |
| MR_CNN_S_CNN [11] | 70.7 | 85.0 | 79.6 | 71.5 | 55.3 | 57.7 | 76.0 | 73.9 | 84.6 | 50.5 | 74.3 | 61.7 | 85.5 | 79.9 | 81.7 | 76.4 | 41.0 | 69.0 | 61.2 | 77.7 | 72.1 |
| Faster R-CNN [28] | 70.4 | 84.9 | 79.8 | 74.3 | 53.9 | 49.8 | 77.5 | 75.9 | 88.5 | 45.6 | 77.1 | 55.3 | 86.9 | 81.7 | 80.9 | 79.6 | 40.1 | 72.6 | 60.9 | 81.2 | 61.5 |
| DEEP_ENS_COCO | 70.1 | 84.0 | 79.4 | 71.6 | 51.9 | 51.1 | 74.1 | 72.1 | 88.6 | 48.3 | 73.4 | 57.8 | 86.1 | 80.0 | 80.7 | 70.4 | 46.6 | 69.6 | 68.8 | 75.9 | 71.4 |
| NoC [29] | 68.8 | 82.8 | 79.0 | 71.6 | 52.3 | 53.7 | 74.1 | 69.0 | 84.9 | 46.9 | 74.3 | 53.1 | 85.0 | 81.3 | 79.5 | 72.2 | 38.9 | 72.4 | 59.5 | 76.7 | 68.1 |
| Fast R-CNN [14] | 68.4 | 82.3 | 78.4 | 70.8 | 52.3 | 38.7 | 77.8 | 71.6 | 89.3 | 44.2 | 73.0 | 55.0 | 87.5 | 80.5 | 80.8 | 72.0 | 35.1 | 68.3 | 65.7 | 80.4 | 64.2 |
| UMICH_FGS_STRUCT | 66.4 | 82.9 | 76.1 | 64.1 | 44.6 | 49.4 | 70.3 | 71.2 | 84.6 | 42.7 | 68.6 | 55.8 | 82.7 | 77.1 | 79.9 | 68.7 | 41.4 | 69.0 | 60.0 | 72.0 | 66.2 |
| NUS_NIN_C2000 [7] | 63.8 | 80.2 | 73.8 | 61.9 | 43.7 | 43.0 | 70.3 | 67.6 | 80.7 | 41.9 | 69.7 | 51.7 | 78.2 | 75.2 | 76.9 | 65.1 | 38.6 | 68.3 | 58.0 | 68.7 | 63.3 |
| BabyLearning [7] | 63.2 | 78.0 | 74.2 | 61.3 | 45.7 | 42.7 | 68.2 | 66.8 | 80.2 | 40.6 | 70.0 | 49.8 | 79.0 | 74.5 | 77.9 | 64.0 | 35.3 | 67.9 | 55.7 | 68.7 | 62.6 |
| NUS_NIN | 62.4 | 77.9 | 73.1 | 62.6 | 39.5 | 43.3 | 69.1 | 66.4 | 78.9 | 39.1 | 68.1 | 50.0 | 77.2 | 71.3 | 76.1 | 64.7 | 38.4 | 66.9 | 56.2 | 66.9 | 62.7 |
| R-CNN VGG BB [13] | 62.4 | 79.6 | 72.7 | 61.9 | 41.2 | 41.9 | 65.9 | 66.4 | 84.6 | 38.5 | 67.2 | 46.7 | 82.0 | 74.8 | 76.0 | 65.2 | 35.6 | 65.4 | 54.2 | 67.4 | 60.3 |
| R-CNN VGG [13] | 59.2 | 76.8 | 70.9 | 56.6 | 37.5 | 36.9 | 62.9 | 63.6 | 81.1 | 35.7 | 64.3 | 43.9 | 80.4 | 71.6 | 74.0 | 60.0 | 30.8 | 63.4 | 52.0 | 63.5 | 58.7 |
| YOLO | 57.9 | 77.0 | 67.2 | 57.7 | 38.3 | 22.7 | 68.3 | 55.9 | 81.4 | 36.2 | 60.8 | 48.5 | 77.2 | 72.3 | 71.3 | 63.5 | 28.9 | 52.2 | 54.8 | 73.9 | 50.8 |
| Feature Edit [33] | 56.3 | 74.6 | 69.1 | 54.4 | 39.1 | 33.1 | 65.2 | 62.7 | 69.7 | 30.8 | 56.0 | 44.6 | 70.0 | 64.4 | 71.1 | 60.2 | 33.3 | 61.3 | 46.4 | 61.7 | 57.8 |
| R-CNN BB [13] | 53.3 | 71.8 | 65.8 | 52.0 | 34.1 | 32.6 | 59.6 | 60.0 | 69.8 | 27.6 | 52.0 | 41.7 | 69.6 | 61.3 | 68.3 | 57.8 | 29.6 | 57.8 | 40.9 | 59.3 | 54.1 |
| SDS [16] | 50.7 | 69.7 | 58.4 | 48.5 | 28.3 | 28.8 | 61.3 | 57.5 | 70.8 | 24.1 | 50.7 | 35.9 | 64.9 | 59.1 | 65.8 | 57.1 | 26.0 | 58.8 | 38.6 | 58.9 | 50.7 |
| R-CNN [13] | 49.6 | 68.1 | 63.8 | 46.1 | 29.4 | 27.9 | 56.6 | 57.0 | 65.9 | 26.5 | 48.7 | 39.5 | 66.2 | 57.3 | 65.4 | 53.2 | 26.2 | 54.5 | 38.1 | 50.6 | 51.6 |
Table 3: Pascal VOC 2012 Leaderboard. YOLO compared with the full comp4 (outside data allowed) public leaderboard as of November 6th, 2015. Mean average precision and per-class average precision are shown for a variety of detection methods. YOLO is the only real-time detector. Fast R-CNN + YOLO is the forth highest scoring method, with a 2.3% boost over Fast R-CNN.
| VOC 2012 test | mAP | aero | bike | bird | boat | bottle | bus | car | cat | chair | cow | table | dog | horse | mbike | person | plant | sheep | sofa | train | tv |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| MR_CNN_MORE_DATA [11] | 73.9 | 85.5 | 82.9 | 76.6 | 57.8 | 62.7 | 79.4 | 77.2 | 86.6 | 55.0 | 79.1 | 62.2 | 87.0 | 83.4 | 84.7 | 78.9 | 45.3 | 73.4 | 65.8 | 80.3 | 74.0 |
| HyperNet_VGG | 71.4 | 84.2 | 78.5 | 73.6 | 55.6 | 53.7 | 78.7 | 79.8 | 87.7 | 49.6 | 74.9 | 52.1 | 86.0 | 81.7 | 83.3 | 81.8 | 48.6 | 73.5 | 59.4 | 79.9 | 65.7 |
| HyperNet_SP | 71.3 | 84.1 | 78.3 | 73.3 | 55.5 | 53.6 | 78.6 | 79.6 | 87.5 | 49.5 | 74.9 | 52.1 | 85.6 | 81.6 | 83.2 | 81.6 | 48.4 | 73.2 | 59.3 | 79.7 | 65.6 |
| Fast R-CNN + YOLO | 70.7 | 83.4 | 78.5 | 73.5 | 55.8 | 43.4 | 79.1 | 73.1 | 89.4 | 49.4 | 75.5 | 57.0 | 87.5 | 80.9 | 81.0 | 74.7 | 41.8 | 71.5 | 68.5 | 82.1 | 67.2 |
| MR_CNN_S_CNN [11] | 70.7 | 85.0 | 79.6 | 71.5 | 55.3 | 57.7 | 76.0 | 73.9 | 84.6 | 50.5 | 74.3 | 61.7 | 85.5 | 79.9 | 81.7 | 76.4 | 41.0 | 69.0 | 61.2 | 77.7 | 72.1 |
| Faster R-CNN [28] | 70.4 | 84.9 | 79.8 | 74.3 | 53.9 | 49.8 | 77.5 | 75.9 | 88.5 | 45.6 | 77.1 | 55.3 | 86.9 | 81.7 | 80.9 | 79.6 | 40.1 | 72.6 | 60.9 | 81.2 | 61.5 |
| DEEP_ENS_COCO | 70.1 | 84.0 | 79.4 | 71.6 | 51.9 | 51.1 | 74.1 | 72.1 | 88.6 | 48.3 | 73.4 | 57.8 | 86.1 | 80.0 | 80.7 | 70.4 | 46.6 | 69.6 | 68.8 | 75.9 | 71.4 |
| NoC [29] | 68.8 | 82.8 | 79.0 | 71.6 | 52.3 | 53.7 | 74.1 | 69.0 | 84.9 | 46.9 | 74.3 | 53.1 | 85.0 | 81.3 | 79.5 | 72.2 | 38.9 | 72.4 | 59.5 | 76.7 | 68.1 |
| Fast R-CNN [14] | 68.4 | 82.3 | 78.4 | 70.8 | 52.3 | 38.7 | 77.8 | 71.6 | 89.3 | 44.2 | 73.0 | 55.0 | 87.5 | 80.5 | 80.8 | 72.0 | 35.1 | 68.3 | 65.7 | 80.4 | 64.2 |
| UMICH_FGS_STRUCT | 66.4 | 82.9 | 76.1 | 64.1 | 44.6 | 49.4 | 70.3 | 71.2 | 84.6 | 42.7 | 68.6 | 55.8 | 82.7 | 77.1 | 79.9 | 68.7 | 41.4 | 69.0 | 60.0 | 72.0 | 66.2 |
| NUS_NIN_C2000 [7] | 63.8 | 80.2 | 73.8 | 61.9 | 43.7 | 43.0 | 70.3 | 67.6 | 80.7 | 41.9 | 69.7 | 51.7 | 78.2 | 75.2 | 76.9 | 65.1 | 38.6 | 68.3 | 58.0 | 68.7 | 63.3 |
| BabyLearning [7] | 63.2 | 78.0 | 74.2 | 61.3 | 45.7 | 42.7 | 68.2 | 66.8 | 80.2 | 40.6 | 70.0 | 49.8 | 79.0 | 74.5 | 77.9 | 64.0 | 35.3 | 67.9 | 55.7 | 68.7 | 62.6 |
| NUS_NIN | 62.4 | 77.9 | 73.1 | 62.6 | 39.5 | 43.3 | 69.1 | 66.4 | 78.9 | 39.1 | 68.1 | 50.0 | 77.2 | 71.3 | 76.1 | 64.7 | 38.4 | 66.9 | 56.2 | 66.9 | 62.7 |
| R-CNN VGG BB [13] | 62.4 | 79.6 | 72.7 | 61.9 | 41.2 | 41.9 | 65.9 | 66.4 | 84.6 | 38.5 | 67.2 | 46.7 | 82.0 | 74.8 | 76.0 | 65.2 | 35.6 | 65.4 | 54.2 | 67.4 | 60.3 |
| R-CNN VGG [13] | 59.2 | 76.8 | 70.9 | 56.6 | 37.5 | 36.9 | 62.9 | 63.6 | 81.1 | 35.7 | 64.3 | 43.9 | 80.4 | 71.6 | 74.0 | 60.0 | 30.8 | 63.4 | 52.0 | 63.5 | 58.7 |
| YOLO | 57.9 | 77.0 | 67.2 | 57.7 | 38.3 | 22.7 | 68.3 | 55.9 | 81.4 | 36.2 | 60.8 | 48.5 | 77.2 | 72.3 | 71.3 | 63.5 | 28.9 | 52.2 | 54.8 | 73.9 | 50.8 |
| Feature Edit [33] | 56.3 | 74.6 | 69.1 | 54.4 | 39.1 | 33.1 | 65.2 | 62.7 | 69.7 | 30.8 | 56.0 | 44.6 | 70.0 | 64.4 | 71.1 | 60.2 | 33.3 | 61.3 | 46.4 | 61.7 | 57.8 |
| R-CNN BB [13] | 53.3 | 71.8 | 65.8 | 52.0 | 34.1 | 32.6 | 59.6 | 60.0 | 69.8 | 27.6 | 52.0 | 41.7 | 69.6 | 61.3 | 68.3 | 57.8 | 29.6 | 57.8 | 40.9 | 59.3 | 54.1 |
| SDS [16] | 50.7 | 69.7 | 58.4 | 48.5 | 28.3 | 28.8 | 61.3 | 57.5 | 70.8 | 24.1 | 50.7 | 35.9 | 64.9 | 59.1 | 65.8 | 57.1 | 26.0 | 58.8 | 38.6 | 58.9 | 50.7 |
| R-CNN [13] | 49.6 | 68.1 | 63.8 | 46.1 | 29.4 | 27.9 | 56.6 | 57.0 | 65.9 | 26.5 | 48.7 | 39.5 | 66.2 | 57.3 | 65.4 | 53.2 | 26.2 | 54.5 | 38.1 | 50.6 | 51.6 |
表 3:Pascal VOC 2012 排行榜。截至 2015 年 11 月 6 日,YOLO 与完整 comp4(允许外部数据)公开排行榜的比较。给出多种检测方法的平均精度均值与每类平均精度。YOLO 是唯一的实时检测器。Fast R-CNN + YOLO 排名第四,相对 Fast R-CNN 提升 2.3%。
YOLO makes far fewer background mistakes than Fast R-CNN. By using YOLO to eliminate background detections from Fast R-CNN we get a significant boost in performance. For every bounding box that R-CNN predicts we check to see if YOLO predicts a similar box. If it does, we give that prediction a boost based on the probability predicted by YOLO and the overlap between the two boxes.
YOLO 的背景错误远少于 Fast R-CNN。用 YOLO 去掉 Fast R-CNN 的背景检测,可显著提升性能。对 R-CNN 预测的每个边界框,我们检查 YOLO 是否预测了相似框;若有,则按 YOLO 预测的概率与两框重叠给该预测加分。
The best Fast R-CNN model achieves a mAP of 71.8% on the VOC 2007 test set. When combined with YOLO, its mAP increases by 3.2% to 75.0%. We also tried combining the top Fast R-CNN model with several other versions of Fast R-CNN. Those ensembles produced small increases in mAP between .3 and .6%, see Table 2 for details.
最佳 Fast R-CNN 模型在 VOC 2007 测试集上 mAP 为 71.8%。与 YOLO 结合后,mAP 提升 3.2% 至 75.0%。我们也尝试把顶级 Fast R-CNN 与其他版本 Fast R-CNN 结合,那些集成仅带来 0.3% 到 0.6% 的小幅提升,见表 2。
The boost from YOLO is not simply a byproduct of model ensembling since there is little benefit from combining different versions of Fast R-CNN. Rather, it is precisely because YOLO makes different kinds of mistakes at test time that it is so effective at boosting Fast R-CNN’s performance.
YOLO 带来的提升并非简单模型集成的副产品——不同版本 Fast R-CNN 结合收益很小。恰恰因为 YOLO 在测试时犯的错误类型不同,才对提升 Fast R-CNN 如此有效。
Unfortunately, this combination doesn’t benefit from the speed of YOLO since we run each model seperately and then combine the results. However, since YOLO is so fast it doesn’t add any significant computational time compared to Fast R-CNN.
可惜,这种组合用不上 YOLO 的速度,因为我们分开跑各模型再合并结果。不过 YOLO 极快,相对 Fast R-CNN 几乎不增加计算时间。
4.4 VOC 2012 Results
4.4 VOC 2012 结果
On the VOC 2012 test set, YOLO scores 57.9% mAP. This is lower than the current state of the art, closer to the original R-CNN using VGG-16, see Table 3. Our system struggles with small objects compared to its closest competitors. On categories like bottle, sheep, and tv/monitor YOLO scores 8-10% lower than R-CNN or Feature Edit. However, on other categories like cat and train YOLO achieves higher performance.
在 VOC 2012 测试集上,YOLO 得到 57.9% mAP。低于当时最优,更接近使用 VGG-16 的原始 R-CNN,见表 3。相对最接近的竞争者,我们的系统对小物体更吃力:在 bottle、sheep、tv/monitor 等类别上,YOLO 比 R-CNN 或 Feature Edit 低 8–10%。但在 cat、train 等类别上,YOLO 表现更高。
Our combined Fast R-CNN + YOLO model is one of the highest performing detection methods. Fast R-CNN gets a 2.3% improvement from the combination with YOLO, boosting it 5 spots up on the public leaderboard.
我们的 Fast R-CNN + YOLO 组合是表现最好的检测方法之一。Fast R-CNN 因与 YOLO 结合获得 2.3% 提升,在公开排行榜上升 5 位。
4.5 Generalizability: Person Detection in Artwork
4.5 泛化性:艺术品中的人检测
| VOC 2007 | Picasso | People-Art | ||
|---|---|---|---|---|
| AP | AP | Best | AP | |
| YOLO | 59.2 | 53.3 | 0.590 | 45 |
| R-CNN | 54.2 | 10.4 | 0.226 | 26 |
| DPM | 43.2 | 37.8 | 0.458 | 32 |
| Poselets [2] | 36.5 | 17.8 | 0.271 | |
| D&T [4] | - | 1.9 | 0.051 |
(a) Picasso Dataset precision-recall curves.
| VOC 2007 | Picasso | People-Art | ||
|---|---|---|---|---|
| AP | AP | Best | AP | |
| YOLO | 59.2 | 53.3 | 0.590 | 45 |
| R-CNN | 54.2 | 10.4 | 0.226 | 26 |
| DPM | 43.2 | 37.8 | 0.458 | 32 |
| Poselets [2] | 36.5 | 17.8 | 0.271 | |
| D&T [4] | - | 1.9 | 0.051 |
(a) Picasso 数据集上的精确率—召回率曲线。
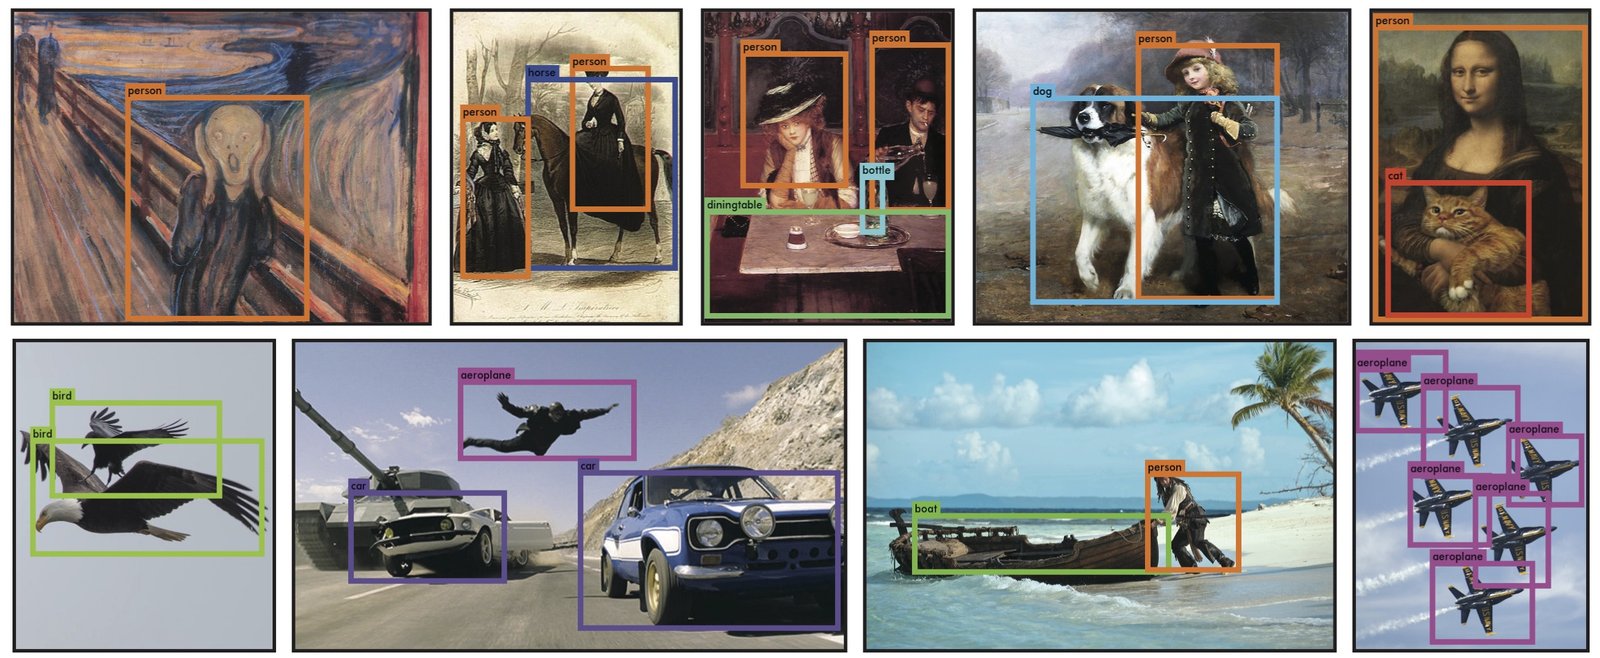
Figure 6: Qualitative Results. YOLO running on sample artwork and natural images from the internet. It is mostly accurate although it does think one person is an airplane.
图 6:定性结果。YOLO 跑在样例艺术品与互联网自然图像上。大体准确,不过有时会把一个人当成飞机。
Academic datasets for object detection draw the training and testing data from the same distribution. In real-world applications it is hard to predict all possible use cases and the test data can diverge from what the system has seen before [3]. We compare YOLO to other detection systems on the Picasso Dataset [12] and the People-Art Dataset [3], two datasets for testing person detection on artwork.
学术目标检测数据集的训练与测试数据往往同分布。现实应用中很难预见所有用例,测试数据可能偏离系统所见 [3]。我们在 Picasso 数据集 [12] 与 People-Art 数据集 [3] 上,把 YOLO 与其他检测系统比较——二者用于测试艺术品中的人检测。
Figure 5 shows comparative performance between YOLO and other detection methods. For reference, we give VOC 2007 detection AP on person where all models are trained only on VOC 2007 data. On Picasso models are trained on VOC 2012 while on People-Art they are trained on VOC 2010.
图 5 给出 YOLO 与其他检测方法的对比表现。作为参考,我们给出仅在 VOC 2007 数据上训练的各模型在 VOC 2007 person 上的检测 AP。Picasso 上模型在 VOC 2012 上训练,People-Art 上在 VOC 2010 上训练。
R-CNN has high AP on VOC 2007. However, R-CNN drops off considerably when applied to artwork. R-CNN uses Selective Search for bounding box proposals which is tuned for natural images. The classifier step in R-CNN only sees small regions and needs good proposals.
R-CNN 在 VOC 2007 上 AP 高,但应用到艺术品时掉得厉害。R-CNN 用 Selective Search 做边界框提议,该法针对自然图像调参;分类步骤只看见小区域,依赖好提议。
DPM maintains its AP well when applied to artwork. Prior work theorizes that DPM performs well because it has strong spatial models of the shape and layout of objects. Though DPM doesn’t degrade as much as R-CNN, it starts from a lower AP.
DPM 应用到艺术品时 AP 保持较好。先前工作认为 DPM 表现好是因为它对物体形状与布局有强空间模型。尽管 DPM 退化不如 R-CNN 严重,但它起点 AP 更低。
YOLO has good performance on VOC 2007 and its AP degrades less than other methods when applied to artwork. Like DPM, YOLO models the size and shape of objects, as well as relationships between objects and where objects commonly appear. Artwork and natural images are very different on a pixel level but they are similar in terms of the size and shape of objects, thus YOLO can still predict good bounding boxes and detections.
YOLO 在 VOC 2007 上表现好,应用到艺术品时 AP 下降也少于其他方法。与 DPM 一样,YOLO 建模物体的尺寸与形状,以及物体之间、物体常见位置的关系。艺术品与自然图像在像素层面差别很大,但在物体尺寸与形状上相似,因而 YOLO 仍能预测较好的边界框与检测。
5 Real-Time Detection In The Wild
5 野外的实时检测
YOLO is a fast, accurate object detector, making it ideal for computer vision applications. We connect YOLO to a webcam and verify that it maintains real-time performance, including the time to fetch images from the camera and display the detections.
YOLO 又快又准,适合计算机视觉应用。我们把 YOLO 接到网络摄像头,验证在包含取图与显示检测的全程下仍保持实时。
The resulting system is interactive and engaging. While YOLO processes images individually, when attached to a webcam it functions like a tracking system, detecting objects as they move around and change in appearance. A demo of the system and the source code can be found on our project website: http://pjreddie.com/yolo/.
所得系统可交互、有吸引力。虽然 YOLO 逐帧处理图像,接到摄像头后表现得像跟踪系统,能检测移动与外观变化中的物体。系统演示与源码见项目网站:http://pjreddie.com/yolo/。
6 Conclusion
6 结论
We introduce YOLO, a unified model for object detection. Our model is simple to construct and can be trained directly on full images. Unlike classifier-based approaches, YOLO is trained on a loss function that directly corresponds to detection performance and the entire model is trained jointly.
我们提出 YOLO,一种统一的目标检测模型。模型构造简单,可直接在整图上训练。与基于分类器的方法不同,YOLO 在直接对应检测性能的损失函数上训练,整模型联合训练。
Fast YOLO is the fastest general-purpose object detector in the literature and YOLO pushes the state-of-the-art in real-time object detection. YOLO also generalizes well to new domains making it ideal for applications that rely on fast, robust object detection.
Fast YOLO 是文献中最快的通用目标检测器,YOLO 则推进了实时目标检测的当时最优。YOLO 也能较好泛化到新领域,适合依赖快速、稳健目标检测的应用。
Acknowledgements: This work is partially supported by ONR N00014-13-1-0720, NSF IIS-1338054, and The Allen Distinguished Investigator Award.
致谢: 本工作部分得到 ONR N00014-13-1-0720、NSF IIS-1338054 与 The Allen Distinguished Investigator Award 支持。
References
参考文献
[1] M. B. Blaschko and C. H. Lampert. Learning to localize objects with structured output regression. In Computer Vision–ECCV 2008 , pages 2--15. Springer, 2008.
[2] L. Bourdev and J. Malik. Poselets: Body part detectors trained using 3d human pose annotations. In International Conference on Computer Vision (ICCV) , 2009.
[3] H. Cai, Q. Wu, T. Corradi, and P. Hall. The cross-depiction problem: Computer vision algorithms for recognising objects in artwork and in photographs. arXiv preprint arXiv:1505.00110 , 2015.
[4] N. Dalal and B. Triggs. Histograms of oriented gradients for human detection. In Computer Vision and Pattern Recognition, 2005. CVPR 2005. IEEE Computer Society Conference on , volume 1, pages 886–893. IEEE, 2005.
[5] T. Dean, M. Ruzon, M. Segal, J. Shlens, S. Vijayanarasimhan, J. Yagnik, et al. Fast, accurate detection of 100,000 object classes on a single machine. In Computer Vision and Pattern Recognition (CVPR), 2013 IEEE Conference on , pages 1814–1821. IEEE, 2013.
[6] J. Donahue, Y. Jia, O. Vinyals, J. Hoffman, N. Zhang, E. Tzeng, and T. Darrell. Decaf: A deep convolutional activation feature for generic visual recognition. arXiv preprint arXiv:1310.1531 , 2013.
[7] J. Dong, Q. Chen, S. Yan, and A. Yuille. Towards unified object detection and semantic segmentation. In Computer Vision–ECCV 2014 , pages 299–314. Springer, 2014.
[8] D. Erhan, C. Szegedy, A. Toshev, and D. Anguelov. Scalable object detection using deep neural networks. In Computer Vision and Pattern Recognition (CVPR), 2014 IEEE Conference on , pages 2155–2162. IEEE, 2014.
[9] M. Everingham, S. M. A. Eslami, L. Van Gool, C. K. I. Williams, J. Winn, and A. Zisserman. The pascal visual object classes challenge: A retrospective. International Journal of Computer Vision , 111(1):98–136, Jan. 2015.
[10] P. F. Felzenszwalb, R. B. Girshick, D. McAllester, and D. Ramanan. Object detection with discriminatively trained part based models. IEEE Transactions on Pattern Analysis and Machine Intelligence , 32(9):1627–1645, 2010.
[11] S. Gidaris and N. Komodakis. Object detection via a multi-region & semantic segmentation-aware CNN model. CoRR , abs/1505.01749, 2015.
[12] S. Ginosar, D. Haas, T. Brown, and J. Malik. Detecting people in cubist art. In Computer Vision-ECCV 2014 Workshops , pages 101–116. Springer, 2014.
[13] R. Girshick, J. Donahue, T. Darrell, and J. Malik. Rich feature hierarchies for accurate object detection and semantic segmentation. In Computer Vision and Pattern Recognition (CVPR), 2014 IEEE Conference on , pages 580–587. IEEE, 2014.
[14] R. B. Girshick. Fast R-CNN. CoRR , abs/1504.08083, 2015.
[15] S. Gould, T. Gao, and D. Koller. Region-based segmentation and object detection. In Advances in neural information processing systems , pages 655–663, 2009.
[16] B. Hariharan, P. Arbeláez, R. Girshick, and J. Malik. Simultaneous detection and segmentation. In Computer Vision–ECCV 2014 , pages 297–312. Springer, 2014.
[17] K. He, X. Zhang, S. Ren, and J. Sun. Spatial pyramid pooling in deep convolutional networks for visual recognition. arXiv preprint arXiv:1406.4729 , 2014.
[18] G. E. Hinton, N. Srivastava, A. Krizhevsky, I. Sutskever, and R. R. Salakhutdinov. Improving neural networks by preventing co-adaptation of feature detectors. arXiv preprint arXiv:1207.0580 , 2012.
[19] D. Hoiem, Y. Chodpathumwan, and Q. Dai. Diagnosing error in object detectors. In Computer Vision–ECCV 2012 , pages 340–353. Springer, 2012.
[20] K. Lenc and A. Vedaldi. R-cnn minus r. arXiv preprint arXiv:1506.06981 , 2015.
[21] R. Lienhart and J. Maydt. An extended set of haar-like features for rapid object detection. In Image Processing. 2002. Proceedings. 2002 International Conference on , volume 1, pages I–900. IEEE, 2002.
[22] M. Lin, Q. Chen, and S. Yan. Network in network. CoRR , abs/1312.4400, 2013.
[23] D. G. Lowe. Object recognition from local scale-invariant features. In Computer vision, 1999. The proceedings of the seventh IEEE international conference on , volume 2, pages 1150–1157. Ieee, 1999.
[24] D. Mishkin. Models accuracy on imagenet 2012 val. https://github.com/BVLC/caffe/wiki/Models-accuracy-on-ImageNet-2012-val . Accessed: 2015-10-2.
[25] C. P. Papageorgiou, M. Oren, and T. Poggio. A general framework for object detection. In Computer vision, 1998. sixth international conference on , pages 555–562. IEEE, 1998.
[26] J. Redmon. Darknet: Open source neural networks in c. http://pjreddie.com/darknet/ , 2013–2016.
[27] J. Redmon and A. Angelova. Real-time grasp detection using convolutional neural networks. CoRR , abs/1412.3128, 2014.
[28] S. Ren, K. He, R. Girshick, and J. Sun. Faster r-cnn: Towards real-time object detection with region proposal networks. arXiv preprint arXiv:1506.01497 , 2015.
[29] S. Ren, K. He, R. B. Girshick, X. Zhang, and J. Sun. Object detection networks on convolutional feature maps. CoRR , abs/1504.06066, 2015.
[30] O. Russakovsky, J. Deng, H. Su, J. Krause, S. Satheesh, S. Ma, Z. Huang, A. Karpathy, A. Khosla, M. Bernstein, A. C. Berg, and L. Fei-Fei. ImageNet Large Scale Visual Recognition Challenge. International Journal of Computer Vision (IJCV) , 2015.
[31] M. A. Sadeghi and D. Forsyth. 30hz object detection with dpm v5. In Computer Vision–ECCV 2014 , pages 65–79. Springer, 2014.
[32] P. Sermanet, D. Eigen, X. Zhang, M. Mathieu, R. Fergus, and Y. LeCun. Overfeat: Integrated recognition, localization and detection using convolutional networks. CoRR , abs/1312.6229, 2013.
[33] Z. Shen and X. Xue. Do more dropouts in pool5 feature maps for better object detection. arXiv preprint arXiv:1409.6911 , 2014.
[34] C. Szegedy, W. Liu, Y. Jia, P. Sermanet, S. Reed, D. Anguelov, D. Erhan, V. Vanhoucke, and A. Rabinovich. Going deeper with convolutions. CoRR , abs/1409.4842, 2014.
[35] J. R. Uijlings, K. E. van de Sande, T. Gevers, and A. W. Smeulders. Selective search for object recognition. International journal of computer vision , 104(2):154–171, 2013.
[36] P. Viola and M. Jones. Robust real-time object detection. International Journal of Computer Vision , 4:34–47, 2001.
[37] P. Viola and M. J. Jones. Robust real-time face detection. International journal of computer vision , 57(2):137–154, 2004.
[38] J. Yan, Z. Lei, L. Wen, and S. Z. Li. The fastest deformable part model for object detection. In Computer Vision and Pattern Recognition (CVPR), 2014 IEEE Conference on , pages 2497–2504. IEEE, 2014.
[39] C. L. Zitnick and P. Dollár. Edge boxes: Locating object proposals from edges. In Computer Vision–ECCV 2014 , pages 391–405. Springer, 2014.