YOLOv3: An Incremental Improvement
YOLOv3: An Incremental Improvement
YOLOv3:一次渐进式改进
Joseph Redmon Ali Farhadi Affiliation: University of Washington
Abstract
摘要
We present some updates to YOLO! We made a bunch of little design changes to make it better. We also trained this new network that’s pretty swell. It’s a little bigger than last time but more accurate. It’s still fast though, don’t worry. At YOLOv3 runs in 22 ms at 28.2 mAP, as accurate as SSD but three times faster. When we look at the old .5 IOU mAP detection metric YOLOv3 is quite good. It achieves AP50 in 51 ms on a Titan X, compared to AP50 in 198 ms by RetinaNet, similar performance but 3.8 faster. As always, all the code is online at https://pjreddie.com/yolo/.
我们给 YOLO 做了一些更新!改了不少小设计,整体更强。还训了一个挺像样的新网络:比上次大一点,也更准,但别担心,速度依旧快。在 上,YOLOv3 跑 22 ms、mAP 28.2,精度与 SSD 相当,却快约三倍。若看旧的 .5 IOU mAP 指标,YOLOv3 表现很好:在 Titan X 上 51 ms 达到 AP50,而 RetinaNet 要 198 ms 才到 AP50,性能接近但快 3.8。代码照例在线:https://pjreddie.com/yolo/。
1 Introduction
1 引言
Sometimes you just kinda phone it in for a year, you know? I didn’t do a whole lot of research this year. Spent a lot of time on Twitter. Played around with GANs a little. I had a little momentum left over from last year [12] [1]; I managed to make some improvements to YOLO. But, honestly, nothing like super interesting, just a bunch of small changes that make it better. I also helped out with other people’s research a little.
有时候一整年就是在混日子,你懂的。今年我没怎么正经做研究,大量时间泡在 Twitter 上,也随便玩了玩 GAN。上一年还剩一点惯性 [12][1],我给 YOLO 做了些改进;老实说没什么特别炸裂的,就是一堆让它更好用的小改动。也帮别人的研究搭过一点手。
Actually, that’s what brings us here today. We have a camera-ready deadline [4] and we need to cite some of the random updates I made to YOLO but we don’t have a source. So get ready for a TECH REPORT!
其实这才是我们今天写这篇的原因。眼下有个相机就绪(camera-ready)截止日 [4],需要引用我对 YOLO 做过的那些零散更新,却没有正式出处。所以——技术报告来了!
The great thing about tech reports is that they don’t need intros, y’all know why we’re here. So the end of this introduction will signpost for the rest of the paper. First we’ll tell you what the deal is with YOLOv3. Then we’ll tell you how we do. We’ll also tell you about some things we tried that didn’t work. Finally we’ll contemplate what this all means.
技术报告的好处是不必正经写引言,大家都知道为什么来。引言末尾给全文指路:先讲 YOLOv3 是怎么回事,再说效果如何,然后列一些我们试过却没成的东西,最后聊聊这一切意味着什么。
2 The Deal
2 怎么回事
So here’s the deal with YOLOv3: We mostly took good ideas from other people. We also trained a new classifier network that’s better than the other ones. We’ll just take you through the whole system from scratch so you can understand it all.
YOLOv3 的路子大致是:好点子多半从别人那儿拿来,另外又训了一个更好的分类骨干。我们会从头把整套系统过一遍,方便你一次看懂。
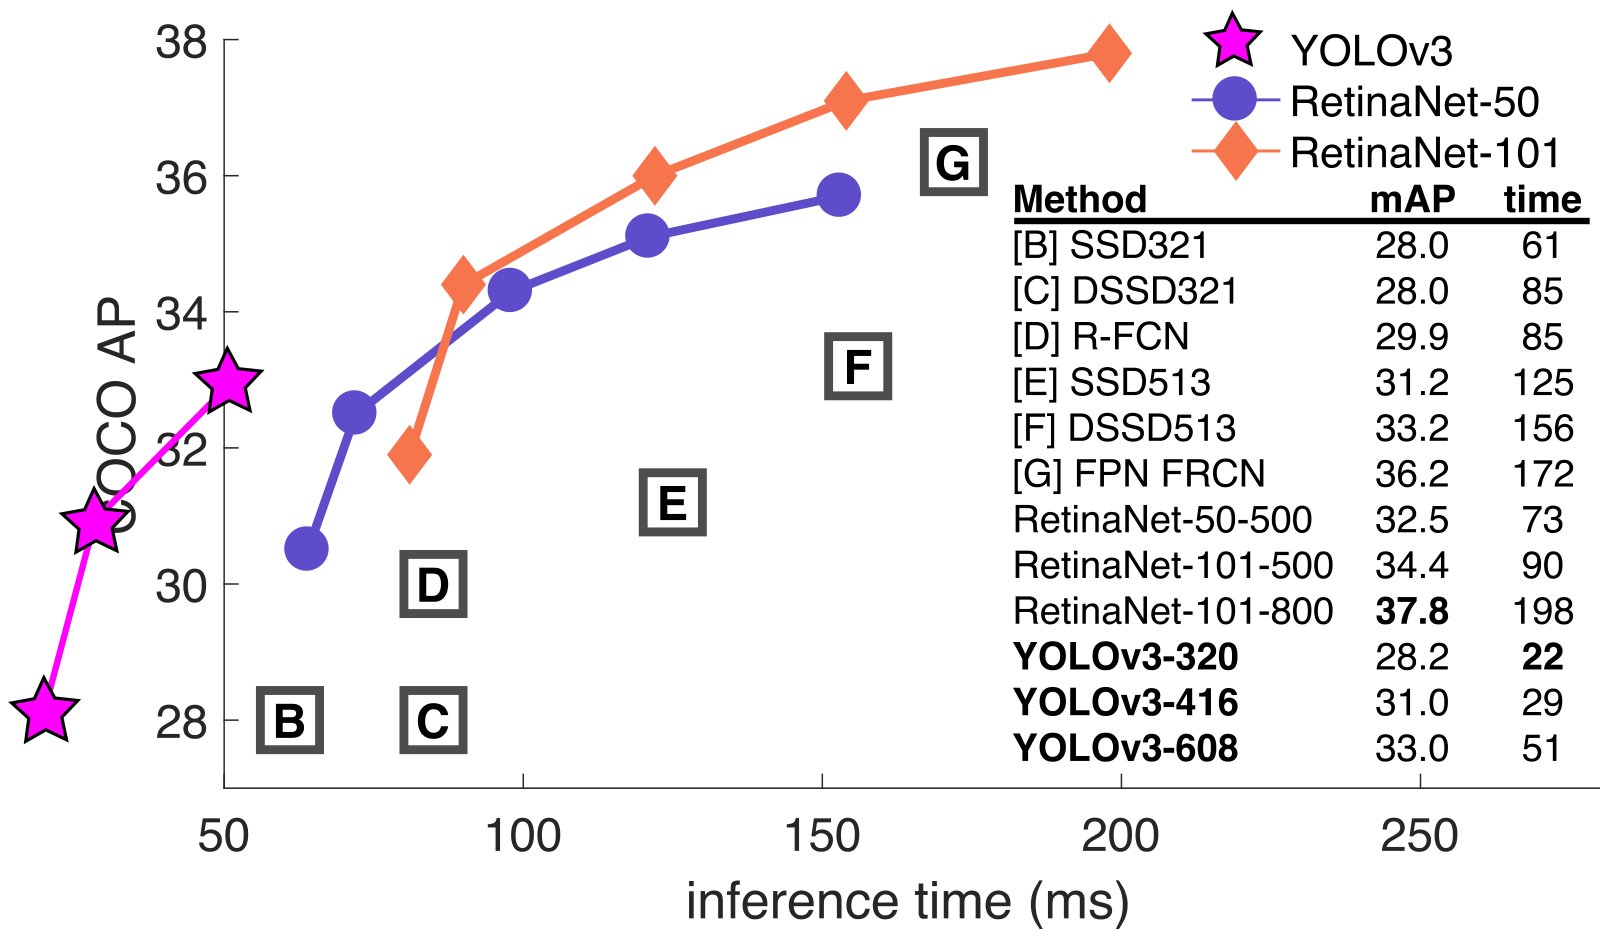
Figure 1: We adapt this figure from the Focal Loss paper [9]. YOLOv3 runs significantly faster than other detection methods with comparable performance. Times from either an M40 or Titan X, they are basically the same GPU.
图 1:改编自 Focal Loss 论文 [9]。在相近精度下,YOLOv3 比多数检测方法快得多。时间测自 M40 或 Titan X,两块卡基本同类。
2.1 Bounding Box Prediction
2.1 边界框预测
Following YOLO9000 our system predicts bounding boxes using dimension clusters as anchor boxes [15]. The network predicts 4 coordinates for each bounding box, , , , . If the cell is offset from the top left corner of the image by and the bounding box prior has width and height , , then the predictions correspond to:
沿用 YOLO9000,我们用维度聚类得到的锚框来预测边界框 [15]。网络为每个边界框预测 4 个坐标 、、、。若该单元格相对图像左上角偏移为 ,锚框先验宽高为 、,则预测对应为:
During training we use sum of squared error loss. If the ground truth for some coordinate prediction is our gradient is the ground truth value (computed from the ground truth box) minus our prediction: . This ground truth value can be easily computed by inverting the equations above.
训练时用平方误差损失。若某坐标预测的真值为 ,梯度就是真值(由真值框反推)减去预测:。真值可由上式反解直接算得。
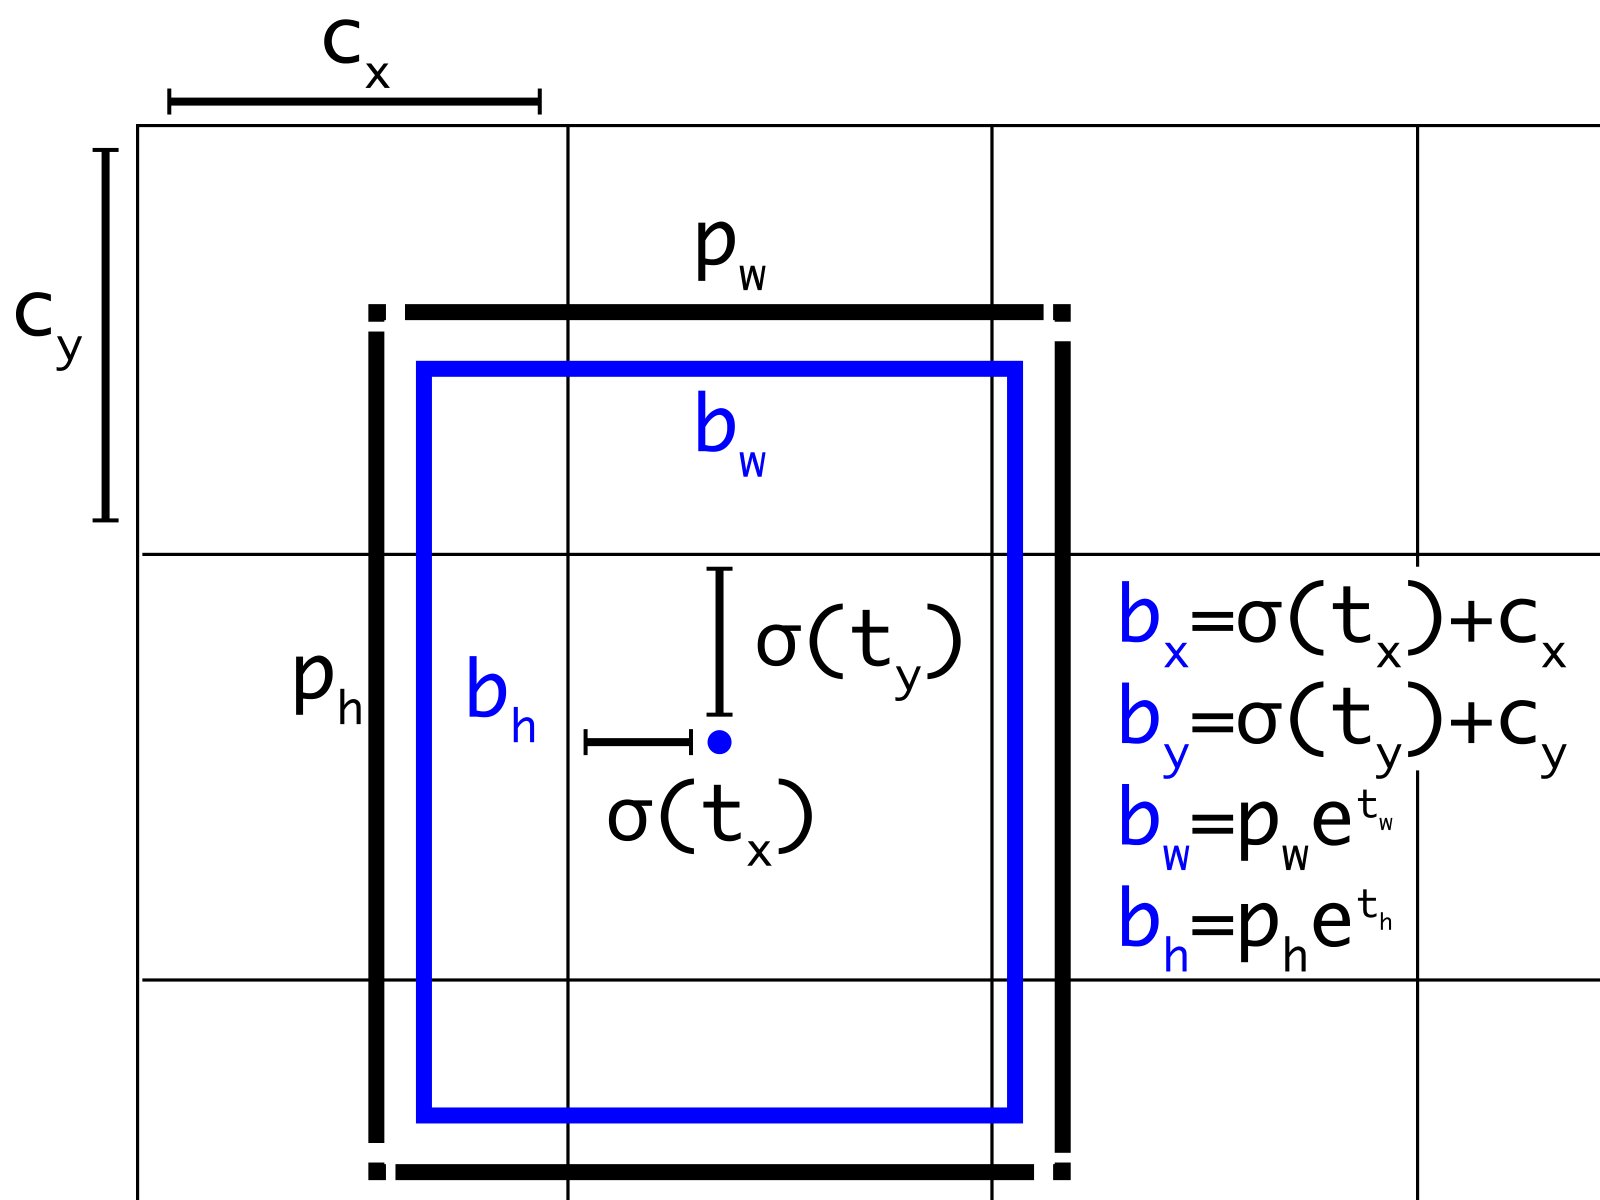
Figure 2: Bounding boxes with dimension priors and location prediction. We predict the width and height of the box as offsets from cluster centroids. We predict the center coordinates of the box relative to the location of filter application using a sigmoid function. This figure blatantly self-plagiarized from [15].
图 2:带维度先验与位置预测的边界框。框的宽高作为相对聚类中心的偏移来预测;框中心相对滤波器作用位置,用 sigmoid 约束。本图公然自剽 [15]。
YOLOv3 predicts an objectness score for each bounding box using logistic regression. This should be 1 if the bounding box prior overlaps a ground truth object by more than any other bounding box prior. If the bounding box prior is not the best but does overlap a ground truth object by more than some threshold we ignore the prediction, following [17]. We use the threshold of . Unlike [17] our system only assigns one bounding box prior for each ground truth object. If a bounding box prior is not assigned to a ground truth object it incurs no loss for coordinate or class predictions, only objectness.
YOLOv3 用逻辑回归为每个边界框预测目标分数(objectness)。若某个边界框先验与真值目标的重叠大于其他任何先验,该分数应为 1。若某先验不是最优、但仍与真值重叠超过某阈值,则按 [17] 忽略该预测;阈值取 。与 [17] 不同,我们每个真值目标只分配一个边界框先验。未分配到真值的先验,不对坐标或类别计损失,只计 objectness。
2.2 Class Prediction
2.2 类别预测
Each box predicts the classes the bounding box may contain using multilabel classification. We do not use a softmax as we have found it is unnecessary for good performance, instead we simply use independent logistic classifiers. During training we use binary cross-entropy loss for the class predictions.
每个框用多标签分类预测可能包含的类别。我们不用 softmax——发现它对好结果并非必要——而是用彼此独立的逻辑分类器。训练时类别预测用二元交叉熵损失。
This formulation helps when we move to more complex domains like the Open Images Dataset [7]. In this dataset there are many overlapping labels (i.e. Woman and Person). Using a softmax imposes the assumption that each box has exactly one class which is often not the case. A multilabel approach better models the data.
这种写法在转向更复杂领域(如 Open Images [7])时更有用。该数据集里标签大量重叠(例如 Woman 与 Person)。softmax 等于假定每个框恰好一类,常常不成立;多标签更能贴合数据。
2.3 Predictions Across Scales
2.3 跨尺度预测
YOLOv3 predicts boxes at 3 different scales. Our system extracts features from those scales using a similar concept to feature pyramid networks [8]. From our base feature extractor we add several convolutional layers. The last of these predicts a 3-d tensor encoding bounding box, objectness, and class predictions. In our experiments with COCO [10] we predict 3 boxes at each scale so the tensor is for the 4 bounding box offsets, 1 objectness prediction, and 80 class predictions.
YOLOv3 在 3 个不同尺度上预测框。特征提取借鉴特征金字塔网络一类思路 [8]。在基础特征提取器上再叠若干卷积层,最后一层预测编码边界框、objectness 与类别的三维张量。在 COCO [10] 实验中,每个尺度预测 3 个框,张量为 ,对应 4 个框偏移、1 个 objectness 与 80 类。
Next we take the feature map from 2 layers previous and upsample it by . We also take a feature map from earlier in the network and merge it with our upsampled features using concatenation. This method allows us to get more meaningful semantic information from the upsampled features and finer-grained information from the earlier feature map. We then add a few more convolutional layers to process this combined feature map, and eventually predict a similar tensor, although now twice the size.
接着取前两层的特征图,上采样 ,再与网络更早层的特征图拼接融合。这样既能从上采样特征拿到更有语义的信息,又能从早期特征图拿到更细粒度的信息。再加几层卷积处理融合特征,最终预测类似张量,尺寸变为两倍。
We perform the same design one more time to predict boxes for the final scale. Thus our predictions for the 3rd scale benefit from all the prior computation as well as fine-grained features from early on in the network.
同样的设计再做一次,得到最后一个尺度的框预测。于是第三尺度的预测既受益于前面全部计算,也吃到网络早期细粒度特征。
We still use k-means clustering to determine our bounding box priors. We just sort of chose 9 clusters and 3 scales arbitrarily and then divide up the clusters evenly across scales. On the COCO dataset the 9 clusters were: .
边界框先验仍用 k-means 聚类确定。我们随意选了 9 个聚类与 3 个尺度,再把聚类均分到各尺度。在 COCO 上 9 个聚类为:。
2.4 Feature Extractor
2.4 特征提取器
We use a new network for performing feature extraction. Our new network is a hybrid approach between the network used in YOLOv2, Darknet-19, and that newfangled residual network stuff. Our network uses successive and convolutional layers but now has some shortcut connections as well and is significantly larger. It has 53 convolutional layers so we call it…. wait for it….. Darknet-53!
特征提取用了一个新网络:把 YOLOv2 的 Darknet-19 与当时流行的残差网络思路混在一起。网络仍是连续的 与 卷积,但加了捷径连接,规模也明显更大。共有 53 个卷积层,我们叫它……等一下……Darknet-53!
Table 1: Darknet-53.
表 1:Darknet-53。
This new network is much more powerful than Darknet-19 but still more efficient than ResNet-101 or ResNet-152. Here are some ImageNet results:
新网络比 Darknet-19 强很多,同时仍比 ResNet-101 或 ResNet-152 更高效。下面是一些 ImageNet 结果:
| Backbone | Top-1 | Top-5 | Bn Ops | BFLOP/s | FPS |
|---|---|---|---|---|---|
| Darknet-19 [15] | 74.1 | 91.8 | 7.29 | 1246 | 171 |
| ResNet-101[5] | 77.1 | 93.7 | 19.7 | 1039 | 53 |
| ResNet-152 [5] | 77.6 | 93.8 | 29.4 | 1090 | 37 |
| Darknet-53 | 77.2 | 93.8 | 18.7 | 1457 | 78 |
Table 2: Comparison of backbones. Accuracy, billions of operations, billion floating point operations per second, and FPS for various networks.
| Backbone | Top-1 | Top-5 | Bn Ops | BFLOP/s | FPS |
|---|---|---|---|---|---|
| Darknet-19 [15] | 74.1 | 91.8 | 7.29 | 1246 | 171 |
| ResNet-101[5] | 77.1 | 93.7 | 19.7 | 1039 | 53 |
| ResNet-152 [5] | 77.6 | 93.8 | 29.4 | 1090 | 37 |
| Darknet-53 | 77.2 | 93.8 | 18.7 | 1457 | 78 |
表 2:骨干对比。 各网络的精度、十亿次运算量、每秒十亿浮点运算与 FPS。
Each network is trained with identical settings and tested at , single crop accuracy. Run times are measured on a Titan X at . Thus Darknet-53 performs on par with state-of-the-art classifiers but with fewer floating point operations and more speed. Darknet-53 is better than ResNet-101 and faster. Darknet-53 has similar performance to ResNet-152 and is faster.
各网络在相同设置下训练,并在 、单裁剪上测试。运行时间在 Titan X、 上测得。因此 Darknet-53 精度可媲美当时顶尖分类器,浮点运算更少、速度更快:优于 ResNet-101 且快 ;与 ResNet-152 相近且快 。
Darknet-53 also achieves the highest measured floating point operations per second. This means the network structure better utilizes the GPU, making it more efficient to evaluate and thus faster. That’s mostly because ResNets have just way too many layers and aren’t very efficient.
Darknet-53 测得的每秒浮点运算也最高,说明网络结构更能吃满 GPU,求值更高效、因而更快。多半因为 ResNet 层数太多、不够高效。
2.5 Training
2.5 训练
We still train on full images with no hard negative mining or any of that stuff. We use multi-scale training, lots of data augmentation, batch normalization, all the standard stuff. We use the Darknet neural network framework for training and testing [14].
我们仍在整图上训练,不做难负例挖掘之类。多尺度训练、大量数据增强、批归一化——都是常规手段。训练与测试用 Darknet 神经网络框架 [14]。
3 How We Do
3 效果如何
| backbone | AP | AP50 | AP75 | APS | APM | APL | |
|---|---|---|---|---|---|---|---|
| Two-stage methods | |||||||
| Faster R-CNN+++ [5] | ResNet-101-C4 | 34.9 | 55.7 | 37.4 | 15.6 | 38.7 | 50.9 |
| Faster R-CNN w FPN [8] | ResNet-101-FPN | 36.2 | 59.1 | 39.0 | 18.2 | 39.0 | 48.2 |
| Faster R-CNN by G-RMI [6] | Inception-ResNet-v2 [21] | 34.7 | 55.5 | 36.7 | 13.5 | 38.1 | 52.0 |
| Faster R-CNN w TDM [20] | Inception-ResNet-v2-TDM | 36.8 | 57.7 | 39.2 | 16.2 | 39.8 | 52.1 |
| One-stage methods | |||||||
| YOLOv2 [15] | DarkNet-19 [15] | 21.6 | 44.0 | 19.2 | 5.0 | 22.4 | 35.5 |
| SSD513 [11, 3] | ResNet-101-SSD | 31.2 | 50.4 | 33.3 | 10.2 | 34.5 | 49.8 |
| DSSD513 [3] | ResNet-101-DSSD | 33.2 | 53.3 | 35.2 | 13.0 | 35.4 | 51.1 |
| RetinaNet [9] | ResNet-101-FPN | 39.1 | 59.1 | 42.3 | 21.8 | 42.7 | 50.2 |
| RetinaNet [9] | ResNeXt-101-FPN | 40.8 | 61.1 | 44.1 | 24.1 | 44.2 | 51.2 |
| YOLOv3 | Darknet-53 | 33.0 | 57.9 | 34.4 | 18.3 | 35.4 | 41.9 |
Table 3: I’m seriously just stealing all these tables from [9] they take soooo long to make from scratch. Ok, YOLOv3 is doing alright. Keep in mind that RetinaNet has like longer to process an image. YOLOv3 is much better than SSD variants and comparable to state-of-the-art models on the AP50 metric.
| backbone | AP | AP50 | AP75 | APS | APM | APL | |
|---|---|---|---|---|---|---|---|
| Two-stage methods | |||||||
| Faster R-CNN+++ [5] | ResNet-101-C4 | 34.9 | 55.7 | 37.4 | 15.6 | 38.7 | 50.9 |
| Faster R-CNN w FPN [8] | ResNet-101-FPN | 36.2 | 59.1 | 39.0 | 18.2 | 39.0 | 48.2 |
| Faster R-CNN by G-RMI [6] | Inception-ResNet-v2 [21] | 34.7 | 55.5 | 36.7 | 13.5 | 38.1 | 52.0 |
| Faster R-CNN w TDM [20] | Inception-ResNet-v2-TDM | 36.8 | 57.7 | 39.2 | 16.2 | 39.8 | 52.1 |
| One-stage methods | |||||||
| YOLOv2 [15] | DarkNet-19 [15] | 21.6 | 44.0 | 19.2 | 5.0 | 22.4 | 35.5 |
| SSD513 [11, 3] | ResNet-101-SSD | 31.2 | 50.4 | 33.3 | 10.2 | 34.5 | 49.8 |
| DSSD513 [3] | ResNet-101-DSSD | 33.2 | 53.3 | 35.2 | 13.0 | 35.4 | 51.1 |
| RetinaNet [9] | ResNet-101-FPN | 39.1 | 59.1 | 42.3 | 21.8 | 42.7 | 50.2 |
| RetinaNet [9] | ResNeXt-101-FPN | 40.8 | 61.1 | 44.1 | 24.1 | 44.2 | 51.2 |
| YOLOv3 | Darknet-53 | 33.0 | 57.9 | 34.4 | 18.3 | 35.4 | 41.9 |
表 3:这些表我基本都从 [9] 搬来,从头做太费时间。好吧,YOLOv3 还行。记住 RetinaNet 处理一张图大约要多花 时间。YOLOv3 明显强于 SSD 变体,在 AP50 上可与当时顶尖模型比肩。
YOLOv3 is pretty good! See table 3. In terms of COCOs weird average mean AP metric it is on par with the SSD variants but is faster. It is still quite a bit behind other models like RetinaNet in this metric though.
YOLOv3 挺不错!见表 3。按 COCO 那种奇怪的平均 mean AP,它与 SSD 变体相当,但快 。在这项指标上仍明显落后于 RetinaNet 一类模型。
However, when we look at the “old” detection metric of mAP at IOU (or AP50 in the chart) YOLOv3 is very strong. It is almost on par with RetinaNet and far above the SSD variants. This indicates that YOLOv3 is a very strong detector that excels at producing decent boxes for objects. However, performance drops significantly as the IOU threshold increases indicating YOLOv3 struggles to get the boxes perfectly aligned with the object.
不过若看「旧」检测指标——IOU 的 mAP(表中 AP50)——YOLOv3 非常强:几乎追平 RetinaNet,并远超 SSD 变体。说明它很擅长给出还不错的目标框。但 IOU 阈值升高后性能掉得厉害,表明框与目标对齐得不够完美。
In the past YOLO struggled with small objects. However, now we see a reversal in that trend. With the new multi-scale predictions we see YOLOv3 has relatively high APS performance. However, it has comparatively worse performance on medium and larger size objects. More investigation is needed to get to the bottom of this.
过去 YOLO 对小目标吃力,现在趋势反过来:多尺度预测下,YOLOv3 的 APS 相对较高;中、大目标反而相对更弱。还需要更多研究才能说清原因。
When we plot accuracy vs speed on the AP50 metric (see figure 5) we see YOLOv3 has significant benefits over other detection systems. Namely, it’s faster and better.
在 AP50 上画精度–速度曲线(见图 5)会发现,YOLOv3 相对其他检测系统优势明显:更快,也更好。
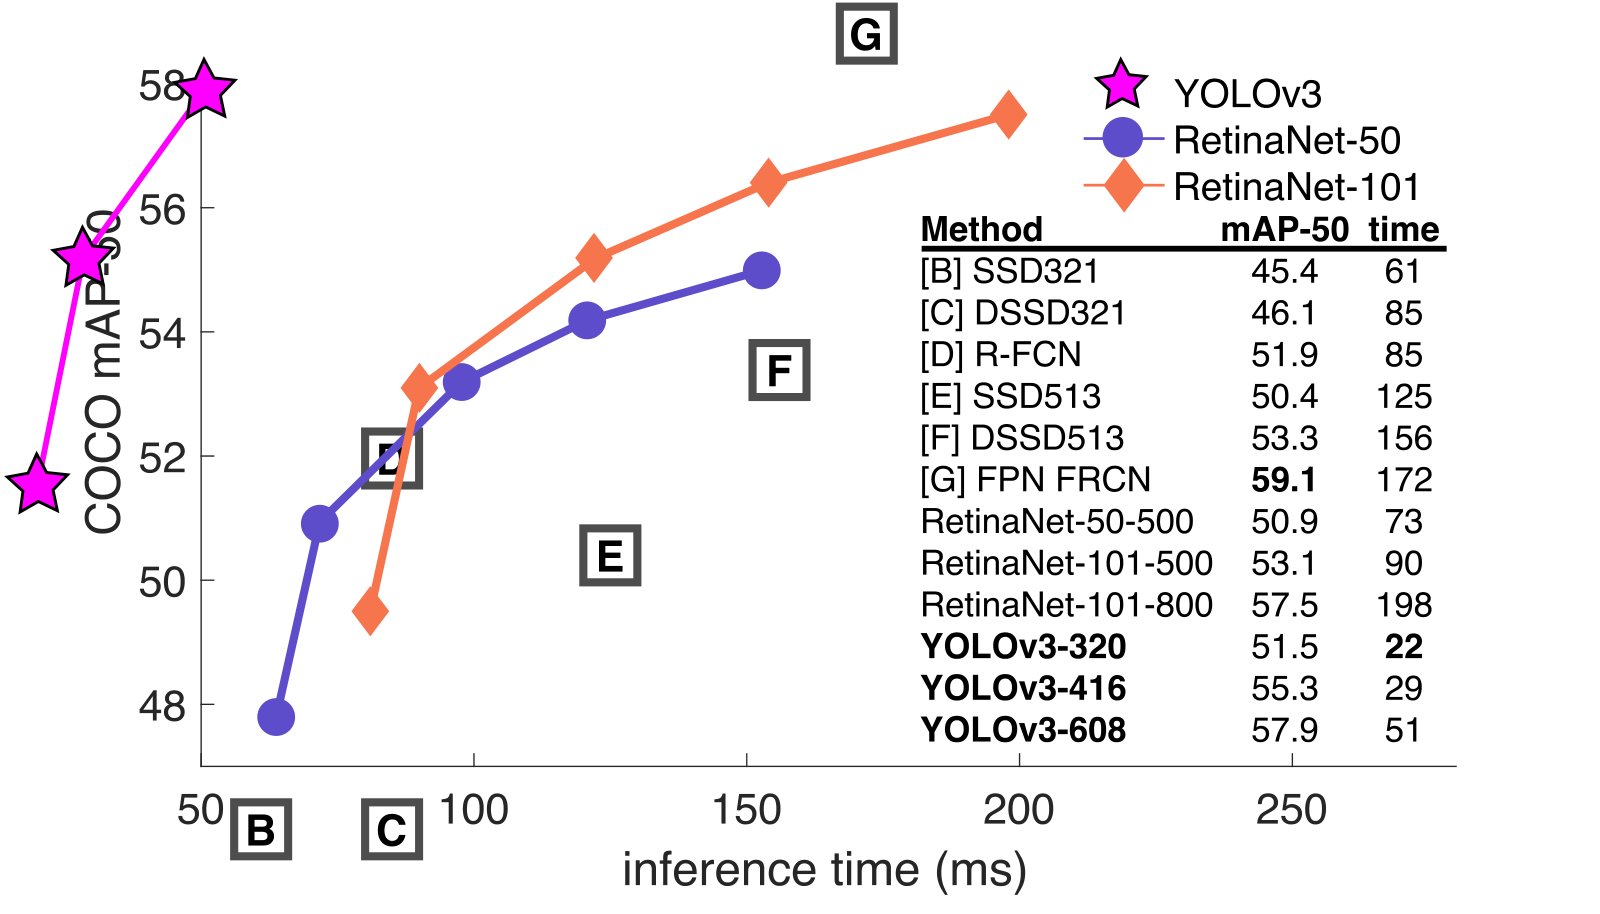
Figure 3: Again adapted from the [9], this time displaying speed/accuracy tradeoff on the mAP at .5 IOU metric. You can tell YOLOv3 is good because it’s very high and far to the left. Can you cite your own paper? Guess who’s going to try, this guy [16]. Oh, I forgot, we also fix a data loading bug in YOLOv2, that helped by like 2 mAP. Just sneaking this in here to not throw off layout.
图 3:再次改编自 [9],展示 .5 IOU mAP 上的速度/精度权衡。YOLOv3 又高又靠左,所以看起来很好。能引用自己的论文吗?猜猜谁准备试试 → [16]。对了,我们还修了 YOLOv2 的一个数据加载 bug,大概抬了 2 mAP。悄悄塞在这儿,免得打乱排版。
4 Things We Tried That Didn’t Work
4 试过却没成的东西
We tried lots of stuff while we were working on YOLOv3. A lot of it didn’t work. Here’s the stuff we can remember.
做 YOLOv3 时试过不少东西,很多没成。下面是还记得的几项。
Anchor box offset predictions. We tried using the normal anchor box prediction mechanism where you predict the offset as a multiple of the box width or height using a linear activation. We found this formulation decreased model stability and didn’t work very well.
锚框 偏移预测。 我们试过常规锚框写法:把 偏移预测成框宽或高的倍数,并用线性激活。结果模型更不稳,效果也不好。
Linear predictions instead of logistic. We tried using a linear activation to directly predict the offset instead of the logistic activation. This led to a couple point drop in mAP.
用线性激活直接预测 ,不用逻辑斯蒂。 这让 mAP 掉了几个点。
Focal loss. We tried using focal loss. It dropped our mAP about 2 points. YOLOv3 may already be robust to the problem focal loss is trying to solve because it has separate objectness predictions and conditional class predictions. Thus for most examples there is no loss from the class predictions? Or something? We aren’t totally sure.
Focal loss。 试了之后 mAP 掉大约 2 点。YOLOv3 或许已经对 focal loss 想解决的问题比较鲁棒——因为 objectness 与条件类别预测是分开的,多数样本上类别预测可能根本没有损失?之类的。我们也不完全确定。
Dual IOU thresholds and truth assignment. Faster R-CNN uses two IOU thresholds during training. If a prediction overlaps the ground truth by .7 it is as a positive example, by it is ignored, less than .3 for all ground truth objects it is a negative example. We tried a similar strategy but couldn’t get good results.
双重 IOU 阈值与真值分配。 Faster R-CNN 训练时用两档 IOU:与真值重叠 ≥.7 为正例, 忽略,对所有真值都 <.3 为负例。我们试过类似策略,效果不好。
We quite like our current formulation, it seems to be at a local optima at least. It is possible that some of these techniques could eventually produce good results, perhaps they just need some tuning to stabilize the training.
我们挺喜欢现在的写法,至少看起来落在某个局部最优。上述技术里或许仍有能成的,也许只是还需要调参稳住训练。
5 What This All Means
5 这一切意味着什么
YOLOv3 is a good detector. It’s fast, it’s accurate. It’s not as great on the COCO average AP between .5 and .95 IOU metric. But it’s very good on the old detection metric of .5 IOU.
YOLOv3 是个好检测器:又快又准。在 COCO 的 .5–.95 IOU 平均 AP 上不算顶尖,但在旧的 .5 IOU 检测指标上非常强。
Why did we switch metrics anyway? The original COCO paper just has this cryptic sentence: “A full discussion of evaluation metrics will be added once the evaluation server is complete”. Russakovsky et al report that that humans have a hard time distinguishing an IOU of .3 from .5! “Training humans to visually inspect a bounding box with IOU of 0.3 and distinguish it from one with IOU 0.5 is surprisingly difficult.” [18] If humans have a hard time telling the difference, how much does it matter?
我们到底为什么要换指标?原始 COCO 论文只有一句含糊的话:「评估服务器完成后,将补充评估指标的完整讨论」。Russakovsky 等人报告说,人很难把 IOU .3 与 .5 的框区分开!「训练人眼去检查 IOU 为 0.3 的框并与 0.5 区分,出乎意料地难。」[18] 若人眼都难分清,这件事又有多重要?
But maybe a better question is: “What are we going to do with these detectors now that we have them?” A lot of the people doing this research are at Google and Facebook. I guess at least we know the technology is in good hands and definitely won’t be used to harvest your personal information and sell it to…. wait, you’re saying that’s exactly what it will be used for?? Oh.
或许更好的问题是:「有了这些检测器,我们接下来拿它们干什么?」很多做这类研究的人在 Google 和 Facebook。至少技术落在靠谱的人手里,绝对不会拿去收割你的个人信息再卖给……等等,你是说恰恰就会这样用?哦。
Well the other people heavily funding vision research are the military and they’ve never done anything horrible like killing lots of people with new technology oh wait.....[^1]
另一头大力资助视觉研究的是军方,他们从来没干过用新技术杀很多人这种可怕的事——哦等等……[^1]
I have a lot of hope that most of the people using computer vision are just doing happy, good stuff with it, like counting the number of zebras in a national park [13], or tracking their cat as it wanders around their house [19]. But computer vision is already being put to questionable use and as researchers we have a responsibility to at least consider the harm our work might be doing and think of ways to mitigate it. We owe the world that much.
我很希望多数用计算机视觉的人只是在做开心、有益的事,比如清点国家公园里有多少斑马 [13],或跟踪自家猫在屋里乱逛 [19]。但计算机视觉已被用到可疑场景;作为研究者,我们至少有责任想想工作可能带来的伤害,并想办法缓解。这是我们欠这个世界的。
In closing, do not @ me. (Because I finally quit Twitter).
最后:别 @ 我。(因为我终于退了 Twitter。)
References
参考文献
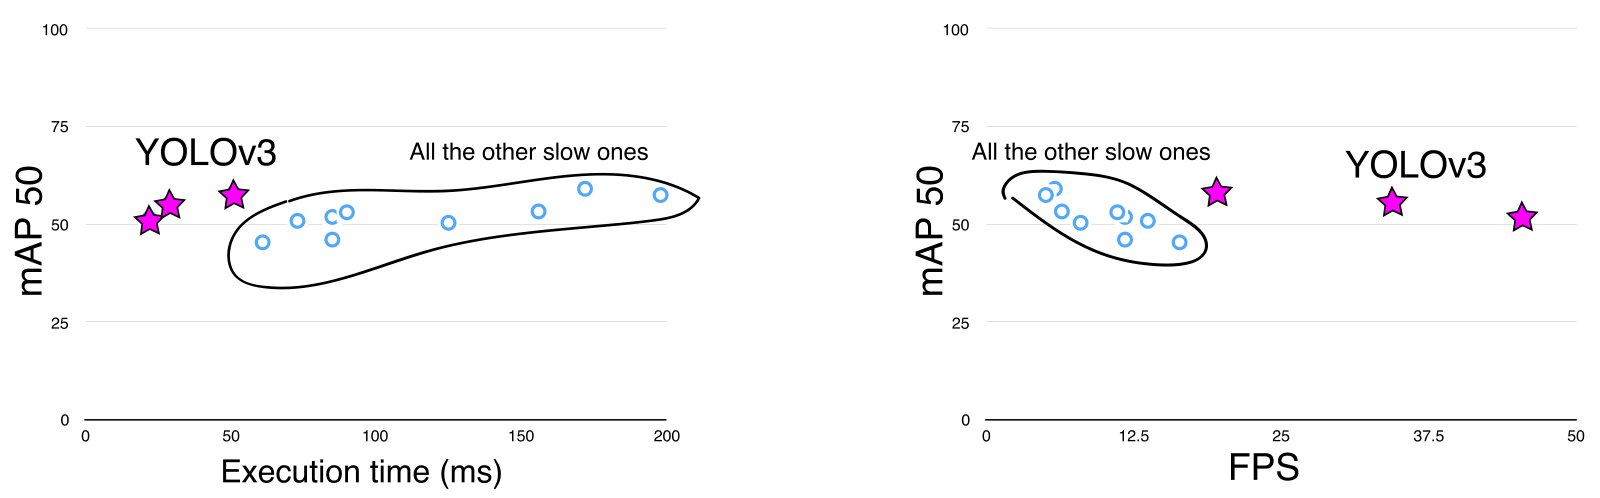
Figure 4: Zero-axis charts are probably more intellectually honest… and we can still screw with the variables to make ourselves look good!
图 4:零轴图表大概更诚实……我们照样还能拧坐标变量,把自己画得好看一点!
(1) Analogy. Wikipedia , Mar 2018.
(2) M. Everingham, L. Van Gool, C. K. Williams, J. Winn, and A. Zisserman. The pascal visual object classes (voc) challenge. International journal of computer vision , 88(2):303–338, 2010.
(3) C.-Y. Fu, W. Liu, A. Ranga, A. Tyagi, and A. C. Berg. Dssd: Deconvolutional single shot detector. arXiv preprint arXiv:1701.06659 , 2017.
(4) D. Gordon, A. Kembhavi, M. Rastegari, J. Redmon, D. Fox, and A. Farhadi. Iqa: Visual question answering in interactive environments. arXiv preprint arXiv:1712.03316 , 2017.
(5) K. He, X. Zhang, S. Ren, and J. Sun. Deep residual learning for image recognition. In Proceedings of the IEEE conference on computer vision and pattern recognition , pages 770–778, 2016.
(6) J. Huang, V. Rathod, C. Sun, M. Zhu, A. Korattikara, A. Fathi, I. Fischer, Z. Wojna, Y. Song, S. Guadarrama, et al. Speed/accuracy trade-offs for modern convolutional object detectors.
(7) I. Krasin, T. Duerig, N. Alldrin, V. Ferrari, S. Abu-El-Haija, A. Kuznetsova, H. Rom, J. Uijlings, S. Popov, A. Veit, S. Belongie, V. Gomes, A. Gupta, C. Sun, G. Chechik, D. Cai, Z. Feng, D. Narayanan, and K. Murphy. Openimages: A public dataset for large-scale multi-label and multi-class image classification. Dataset available from https://github.com/openimages , 2017.
(8) T.-Y. Lin, P. Dollar, R. Girshick, K. He, B. Hariharan, and S. Belongie. Feature pyramid networks for object detection. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pages 2117–2125, 2017.
(9) T.-Y. Lin, P. Goyal, R. Girshick, K. He, and P. Dollár. Focal loss for dense object detection. arXiv preprint arXiv:1708.02002 , 2017.
(10) T.-Y. Lin, M. Maire, S. Belongie, J. Hays, P. Perona, D. Ramanan, P. Dollár, and C. L. Zitnick. Microsoft coco: Common objects in context. In European conference on computer vision , pages 740–755. Springer, 2014.
(11) W. Liu, D. Anguelov, D. Erhan, C. Szegedy, S. Reed, C.-Y. Fu, and A. C. Berg. Ssd: Single shot multibox detector. In European conference on computer vision , pages 21–37. Springer, 2016.
(12) I. Newton. Philosophiae naturalis principia mathematica . William Dawson & Sons Ltd., London, 1687.
(13) J. Parham, J. Crall, C. Stewart, T. Berger-Wolf, and D. Rubenstein. Animal population censusing at scale with citizen science and photographic identification. 2017.
(14) J. Redmon. Darknet: Open source neural networks in c. http://pjreddie.com/darknet/ , 2013–2016.
(15) J. Redmon and A. Farhadi. Yolo9000: Better, faster, stronger. In Computer Vision and Pattern Recognition (CVPR), 2017 IEEE Conference on , pages 6517–6525. IEEE, 2017.
(16) J. Redmon and A. Farhadi. Yolov3: An incremental improvement. arXiv , 2018.
(17) S. Ren, K. He, R. Girshick, and J. Sun. Faster r-cnn: Towards real-time object detection with region proposal networks. arXiv preprint arXiv:1506.01497 , 2015.
(18) O. Russakovsky, L.-J. Li, and L. Fei-Fei. Best of both worlds: human-machine collaboration for object annotation. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pages 2121–2131, 2015.
(19) M. Scott. Smart camera gimbal bot – scanlime:027, Dec 2017.
(20) A. Shrivastava, R. Sukthankar, J. Malik, and A. Gupta. Beyond skip connections: Top-down modulation for object detection. arXiv preprint arXiv:1612.06851 , 2016.
(21) C. Szegedy, S. Ioffe, V. Vanhoucke, and A. A. Alemi. Inception-v4, inception-resnet and the impact of residual connections on learning. 2017.
Rebuttal
答辩
We would like to thank the Reddit commenters, labmates, emailers, and passing shouts in the hallway for their lovely, heartfelt words. If you, like me, are reviewing for ICCV then we know you probably have 37 other papers you could be reading that you’ll invariably put off until the last week and then have some legend in the field email you about how you really should finish those reviews execept it won’t entirely be clear what they’re saying and maybe they’re from the future? Anyway, this paper won’t have become what it will in time be without all the work your past selves will have done also in the past but only a little bit further forward, not like all the way until now forward. And if you tweeted about it I wouldn’t know. Just sayin.
感谢 Reddit 评论者、实验室同事、写信的人和走廊里喊一声的人,那些真心话很暖。如果你像我一样在审 ICCV,大概手里还有 37 篇别的论文,最后一周才赶着写意见,然后领域大佬给你发邮件催你赶紧审完——措辞又不太清楚,说不定还是从未来发来的?总之,这篇论文之所以能长成它将来的样子,离不开你们过去的自己在过去(只是比现在稍早一点,不是一路推到现在)已经做过的那些工作。至于你有没有推特提到它,我反正不知道。就说这么多。
Reviewer #2 AKA Dan Grossman (lol blinding who does that) insists that I point out here that our graphs have not one but two non-zero origins. You’re absolutely right Dan, that’s because it looks way better than admitting to ourselves that we’re all just here battling over 2-3% mAP. But here are the requested graphs. I threw in one with FPS too because we look just like super good when we plot on FPS.
审稿人 #2 又名 Dan Grossman(盲审?谁信啊哈哈)坚持要我指出:我们的图不止一个、而是两个非零原点。你说得对 Dan,因为那样看起来好看多了,总好过承认我们其实在为 2–3% mAP 互掐。按要求把图画在这儿。我还加了一张 FPS 的,因为画在 FPS 上我们看起来特别强。
Reviewer #4 AKA JudasAdventus on Reddit writes “Entertaining read but the arguments against the MSCOCO metrics seem a bit weak”. Well, I always knew you would be the one to turn on me Judas. You know how when you work on a project and it only comes out alright so you have to figure out some way to justify how what you did actually was pretty cool? I was basically trying to do that and I lashed out at the COCO metrics a little bit. But now that I’ve staked out this hill I may as well die on it.
审稿人 #4 又名 Reddit 上的 JudasAdventus 写道:「读着挺逗,但对 MSCOCO 指标的批评有点弱。」我一直知道会是你背叛我,Judas。你知道那种感觉:项目只做成「还行」,于是你得找理由证明自己其实挺酷——我大概就在干这事,顺便对 COCO 指标发泄了一下。既然已经站上这座山,不如死守到底。
See here’s the thing, mAP is already sort of broken so an update to it should maybe address some of the issues with it or at least justify why the updated version is better in some way. And that’s the big thing I took issue with was the lack of justification. For Pascal VOC, the IOU threshold was ”set deliberately low to account for inaccuracies in bounding boxes in the ground truth data“ [2]. Does COCO have better labelling than VOC? This is definitely possible since COCO has segmentation masks maybe the labels are more trustworthy and thus we aren’t as worried about inaccuracy. But again, my problem was the lack of justification.
问题在于:mAP 本身就有点别扭,更新它时至少该处理一些问题,或说明新版为何更好。我真正不爽的是缺少论证。Pascal VOC 里 IOU 阈值「故意设得较低,以容纳真值框标注不准」[2]。COCO 的标注比 VOC 更好吗?有可能——COCO 有分割掩码,标签或许更可信,因而更不担心不准。但我的问题仍然是:缺少论证。
The COCO metric emphasizes better bounding boxes but that emphasis must mean it de-emphasizes something else, in this case classification accuracy. Is there a good reason to think that more precise bounding boxes are more important than better classification? A miss-classified example is much more obvious than a bounding box that is slightly shifted.
COCO 指标强调更准的边界框,那必然就弱化了别的东西,这里是分类精度。有充分理由认为「更准的框」比「更好的分类」更重要吗?错分类比框稍微偏一点要显眼得多。
mAP is already screwed up because all that matters is per-class rank ordering. For example, if your test set only has these two images then according to mAP two detectors that produce these results are JUST AS GOOD:
mAP 已经有问题,因为真正要紧的是每类排序。举例:若测试集只有下面两张图,按 mAP,给出这两种结果的两个检测器「一样好」:
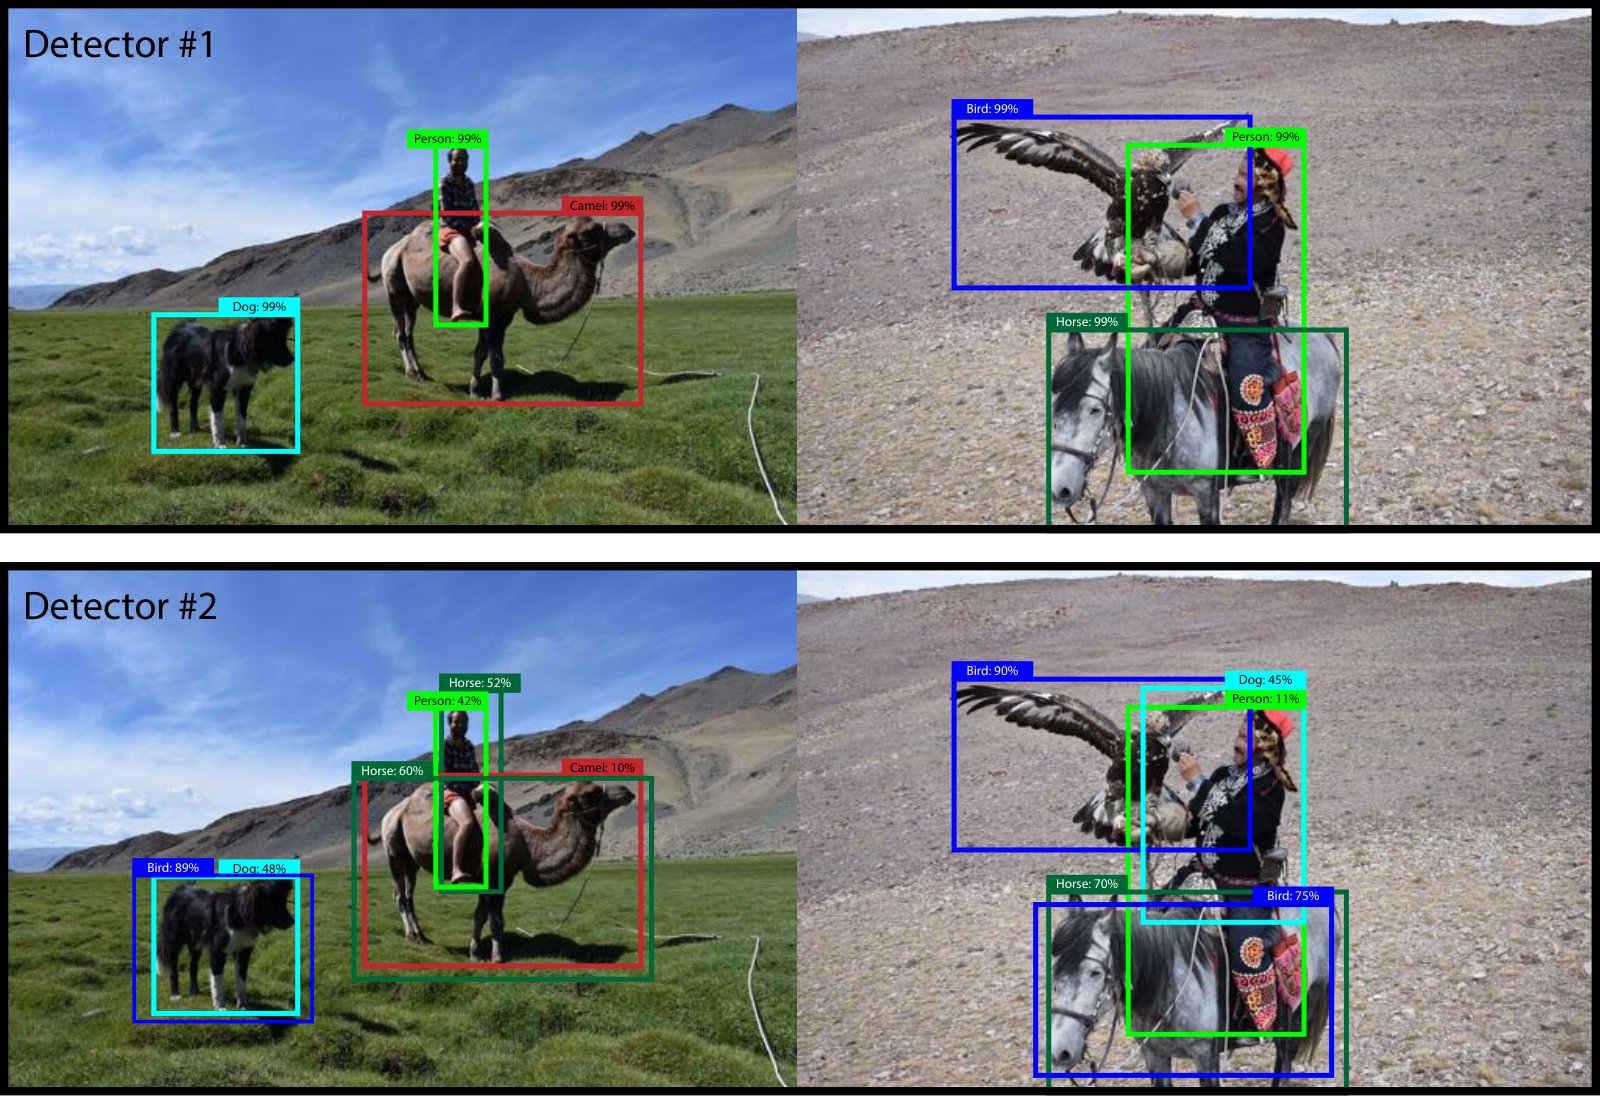
Figure 5: These two hypothetical detectors are perfect according to mAP over these two images. They are both perfect. Totally equal.
图 5:按这两张图上的 mAP,这两个假想检测器都完美。两者都完美。完全等价。
Now this is OBVIOUSLY an over-exaggeration of the problems with mAP but I guess my newly retconned point is that there are such obvious discrepancies between what people in the “real world” would care about and our current metrics that I think if we’re going to come up with new metrics we should focus on these discrepancies. Also, like, it’s already mean average precision, what do we even call the COCO metric, average mean average precision?
这当然是对 mAP 问题的夸张,但我事后补丁式的观点是:现实世界真正在意的,与现有指标之间差距已经很明显;要搞新指标,就该盯着这些差距。还有,已经叫 mean average precision 了,COCO 指标到底叫什么——average mean average precision?
Here’s a proposal, what people actually care about is given an image and a detector, how well will the detector find and classify objects in the image. What about getting rid of the per-class AP and just doing a global average precision? Or doing an AP calculation per-image and averaging over that?
提个方案:人们真正关心的是,给定一张图和一个检测器,它找目标、分类有多好。要不取消按类 AP,改做全局平均精度?或者按图算 AP 再平均?
Boxes are stupid anyway though, I’m probably a true believer in masks except I can’t get YOLO to learn them.
框这东西本来就蠢。我大概更信掩码——只是 YOLO 还学不会它们。