YOLO9000: Better, Faster, Stronger
YOLO9000: Better, Faster, Stronger
YOLO9000:更好、更快、更强(YOLO9000: Better, Faster, Stronger)
Joseph Redmon Ali Farhadi University of Washington * Allen Institute for AI http://pjreddie.com/yolo9000/
Abstract
摘要
We introduce YOLO9000, a state-of-the-art, real-time object detection system that can detect over 9000 object categories. First we propose various improvements to the YOLO detection method, both novel and drawn from prior work. The improved model, YOLOv2, is state-of-the-art on standard detection tasks like Pascal VOC and COCO. Using a novel, multi-scale training method the same YOLOv2 model can run at varying sizes, offering an easy tradeoff between speed and accuracy. At 67 FPS, YOLOv2 gets 76.8 mAP on VOC 2007. At 40 FPS, YOLOv2 gets 78.6 mAP, outperforming state-of-the-art methods like Faster R-CNN with ResNet and SSD while still running significantly faster. Finally we propose a method to jointly train on object detection and classification. Using this method we train YOLO9000 simultaneously on the COCO detection dataset and the ImageNet classification dataset. Our joint training allows YOLO9000 to predict detections for object classes that don’t have labelled detection data. We validate our approach on the ImageNet detection task. YOLO9000 gets 19.7 mAP on the ImageNet detection validation set despite only having detection data for 44 of the 200 classes. On the 156 classes not in COCO, YOLO9000 gets 16.0 mAP. But YOLO can detect more than just 200 classes; it predicts detections for more than 9000 different object categories. And it still runs in real-time.
我们提出 YOLO9000,一套可检测九千多种物体类别的先进实时目标检测系统。首先对 YOLO 检测方法做了一系列改进,其中既有新设计,也有借鉴已有工作之处。改进后的模型 YOLOv2 在 PASCAL VOC、COCO 等标准检测任务上达到当时领先水平。借助新颖的多尺度训练方法,同一套 YOLOv2 权重可在不同输入尺寸下运行,便于在速度与精度之间权衡。在 67 FPS 时,YOLOv2 在 VOC 2007 上达到 76.8 mAP;在 40 FPS 时达到 78.6 mAP,精度超过当时用 ResNet 的 Faster R-CNN 与 SSD,同时速度仍明显更快。最后提出一种在检测与分类数据上联合训练模型的方法。用该方法训练出的 YOLO9000 可实时检测超过 9000 种物体类别。我们在 ImageNet 检测验证集上得到 19.7 mAP;即使仅对 COCO 中未出现的 200 类做评估,仍有 16.0 mAP。
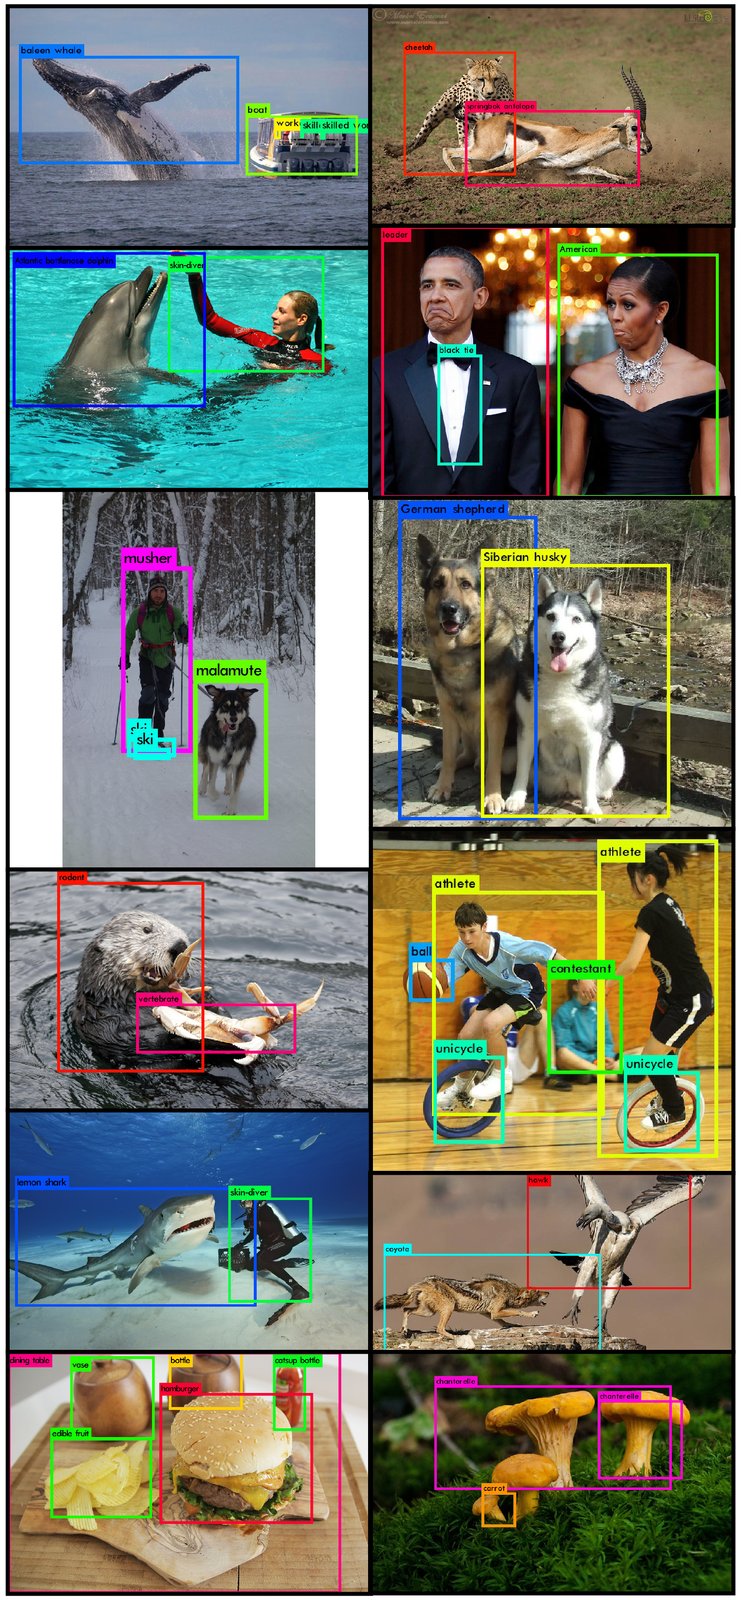
Figure 1: YOLO9000. YOLO9000 can detect a wide variety of object classes in real-time.
图 1:YOLO9000。YOLO9000 能实时检测多种物体类别。
1 Introduction
1 引言
General purpose object detection should be fast, accurate, and able to recognize a wide variety of objects. Since the introduction of neural networks, detection frameworks have become increasingly fast and accurate. However, most detection methods are still constrained to a small set of objects.
一般用途物体的探测速度应当快,准确,能够识别各种各样的物体. 自引入神经网络以来,检测框架越来越迅速和准确. 然而,大多数检测方法仍然受限于一小组物体.
Current object detection datasets are limited compared to datasets for other tasks like classification and tagging. The most common detection datasets contain thousands to hundreds of thousands of images with dozens to hundreds of tags [3] [10] [2]. Classification datasets have millions of images with tens or hundreds of thousands of categories [20] [2].
当前对象检测数据集与分类和标记等其他任务的数据集相比是有限的. 最常见的检测数据集包含数千至数十万的图像,并有数十至数百个标记[3][10][2]. 分类数据集拥有成百上千万的图像,包含数万或数十万个类别[20] [2].
We would like detection to scale to level of object classification. However, labelling images for detection is far more expensive than labelling for classification or tagging (tags are often user-supplied for free). Thus we are unlikely to see detection datasets on the same scale as classification datasets in the near future.
我们希望检测能达到物体分类的水平。 然而,用于检测的标签图像远比用于分类或标记的标签昂贵(标杆通常是免费用户提供的)。 因此,我们不大可能在近期看到与分类数据集相同的检测数据集。
We propose a new method to harness the large amount of classification data we already have and use it to expand the scope of current detection systems. Our method uses a hierarchical view of object classification that allows us to combine distinct datasets together.
我们提出一种新方法来利用我们已经掌握的大量分类数据,并利用它来扩大现有探测系统的范围。 我们的方法使用对物体分类的分级视图,使我们能够将不同的数据集合并在一起.
We also propose a joint training algorithm that allows us to train object detectors on both detection and classification data. Our method leverages labeled detection images to learn to precisely localize objects while it uses classification images to increase its vocabulary and robustness.
我们还提出一个联合训练算法,使我们能够对物体检测器进行探测和分类数据方面的训练。 我们的方法利用标注的检测图像来学习准确定位对象,同时使用分类图像来增加其词汇和坚固性.
Using this method we train YOLO9000, a real-time object detector that can detect over 9000 different object categories. First we improve upon the base YOLO detection system to produce YOLOv2, a state-of-the-art, real-time detector. Then we use our dataset combination method and joint training algorithm to train a model on more than 9000 classes from ImageNet as well as detection data from COCO.
使用这种方法,我们训练YOLO9000,一个实时的物体检测器,可以探测到9000多个不同的物体类别. 首先改进基底YOLO探测系统,以生产YOLOv2,一种最先进的实时探测器. 然后我们用我们的数据集组合方法和联合训练算法,从ImageNet以及COCO的检测数据中,在9000多个课程上训练一个模型.
All of our code and pre-trained models are available online at http://pjreddie.com/yolo9000/.
我们的所有代码和经过预先训练的模型均可在网上查阅:http://pjreddie.com/yolo9000/。
2 Better
2 更好(Better)
YOLO suffers from a variety of shortcomings relative to state-of-the-art detection systems. Error analysis of YOLO compared to Fast R-CNN shows that YOLO makes a significant number of localization errors. Furthermore, YOLO has relatively low recall compared to region proposal-based methods. Thus we focus mainly on improving recall and localization while maintaining classification accuracy.
YOLO相对于最先进的检测系统存在各种缺陷. 对YOLO与Fast R-CNN相比的错误分析显示,YOLO制造了大量定位误差. 此外,与基于区域提议的方法相比,YOLO的召回率相对较低。 因此,我们主要侧重于改进召回和本地化,同时保持分类的准确性。
Computer vision generally trends towards larger, deeper networks [6] [18] [17]. Better performance often hinges on training larger networks or ensembling multiple models together. However, with YOLOv2 we want a more accurate detector that is still fast. Instead of scaling up our network, we simplify the network and then make the representation easier to learn. We pool a variety of ideas from past work with our own novel concepts to improve YOLO’s performance. A summary of results can be found in Table 2.
计算机视觉一般趋向于更大,更深的网络[6] [18] [17]. 更好的表现往往取决于训练更大的网络或将多个模型组合在一起。 然而,随着YOLOv2,我们想要一个更精确的探测器,它仍然很快. 与其扩大我们的网络,不如简化网络,然后让代表更容易学习. 我们把过去工作中的各种想法与我们自己的新概念结合起来,以提高青年组织的业绩。 结果摘要见表2。
Batch Normalization. Batch normalization leads to significant improvements in convergence while eliminating the need for other forms of regularization [7]. By adding batch normalization on all of the convolutional layers in YOLO we get more than 2% improvement in mAP. Batch normalization also helps regularize the model. With batch normalization we can remove dropout from the model without overfitting.
批归一化。 批归一化能显著改善收敛,并减少对其他正则手段的依赖 [7]。在 YOLO 的全部卷积层上加入批归一化后,mAP 提升超过 2%。批归一化也有助于正则化模型:加入后我们可去掉 dropout 而不过拟合。
High Resolution Classifier. All state-of-the-art detection methods use classifier pre-trained on ImageNet [16]. Starting with AlexNet most classifiers operate on input images smaller than [8]. The original YOLO trains the classifier network at and increases the resolution to for detection. This means the network has to simultaneously switch to learning object detection and adjust to the new input resolution.
高分辨率分类器。 当时领先的检测方法都使用在 ImageNet 上预训练的分类器 [16]。自 AlexNet 以来,多数分类器在小于 的输入上运行 [8]。原版 YOLO 以 训练分类网络,再升到 做检测。这意味着网络必须同时适应目标检测与新的输入分辨率。
For YOLOv2 we first fine tune the classification network at the full resolution for 10 epochs on ImageNet. This gives the network time to adjust its filters to work better on higher resolution input. We then fine tune the resulting network on detection. This high resolution classification network gives us an increase of almost 4% mAP.
对于YOLOv2,我们首先微调分类网络,以完整的分辨率为图像网上的10个纪元. 这使得网络有时间调整其过滤器,以更好地进行更高的分辨率输入. 然后,我们精准地调整 由此产生的网络在检测。 这个高分辨率的分类网络让我们增加了近4%的mAP.
Convolutional With Anchor Boxes. YOLO predicts the coordinates of bounding boxes directly using fully connected layers on top of the convolutional feature extractor. Instead of predicting coordinates directly Faster R-CNN predicts bounding boxes using hand-picked priors [15]. Using only convolutional layers the region proposal network (RPN) in Faster R-CNN predicts offsets and confidences for anchor boxes. Since the prediction layer is convolutional, the RPN predicts these offsets at every location in a feature map. Predicting offsets instead of coordinates simplifies the problem and makes it easier for the network to learn.
带锚框的卷积。 YOLO 在卷积特征提取器之上用全连接层直接预测边框坐标。Faster R-CNN 则不直接预测坐标,而是用手选先验(锚框)回归边框 [15]。RPN 仅用卷积层预测锚框的偏移与置信度,由于预测头是卷积的,RPN 预测会平移不变。用锚框后,YOLOv2 的召回上升,也为后续改进留出空间。
We remove the fully connected layers from YOLO and use anchor boxes to predict bounding boxes. First we eliminate one pooling layer to make the output of the network’s convolutional layers higher resolution. We also shrink the network to operate on input images instead of . We do this because we want an odd number of locations in our feature map so there is a single center cell. Objects, especially large objects, tend to occupy the center of the image so it’s good to have a single location right at the center to predict these objects instead of four locations that are all nearby. YOLO’s convolutional layers downsample the image by a factor of 32 so by using an input image of we get an output feature map of .
我们从YOLO中移除了完全连接的层,并使用锚框来预测边框. 首先,我们取消了一个集合层,以使网络的卷积层的输出分辨率更高。 我们还缩小网络以运行在输入图像上,而不是. 我们这样做是因为我们希望在特征图中找到一个奇数的位置,所以有一个单一的中心单元格。 物体,尤其是大型物体,往往占据图像的中心,因此,在中心有一个单一的位置来预测这些物体,而不是四个都位于附近的位置是好的。 YOLO的卷积层以32的系数对图像进行取样,
When we move to anchor boxes we also decouple the class prediction mechanism from the spatial location and instead predict class and objectness for every anchor box. Following YOLO, the objectness prediction still predicts the IOU of the ground truth and the proposed box and the class predictions predict the conditional probability of that class given that there is an object.
当我们移动到锚框时,我们还将类预测机制从空间位置中解开,而是预测每个锚框的类和对象。 在YOLO之后,对象预测仍然预测真值的IOU和拟议中的框,以及类预测预测该类的有条件概率,因为有物体存在.
Using anchor boxes we get a small decrease in accuracy. YOLO only predicts 98 boxes per image but with anchor boxes our model predicts more than a thousand. Without anchor boxes our intermediate model gets mAP with a recall of . With anchor boxes our model gets mAP with a recall of . Even though the mAP decreases, the increase in recall means that our model has more room to improve.
使用锚框,精度会小幅下降。 YOLO只预测每幅图像98盒,但用锚框,我们的模型预测超过一千盒. 没有锚框,我们的中间型号 得到 mAP 与召回 。 有了锚框,我们的模型得到mAP 与召回 。 尽管mAP减少,但召回的增加意味着我们的模式有更大的改进余地.
Dimension Clusters. We encounter two issues with anchor boxes when using them with YOLO. The first is that the box dimensions are hand picked. The network can learn to adjust the boxes appropriately but if we pick better priors for the network to start with we can make it easier for the network to learn to predict good detections.
** Dimension 集群。 ** 在YOLO使用锚框时遇到两个问题. 首先是盒子的尺寸是手工挑选的。 网络可以学习适当调整框,但如果我们选择更好的前科,让网络从开始,就可以让网络更容易学习预测好的检测结果.
Instead of choosing priors by hand, we run k-means clustering on the training set bounding boxes to automatically find good priors. If we use standard k-means with Euclidean distance larger boxes generate more error than smaller boxes. However, what we really want are priors that lead to good IOU scores, which is independent of the size of the box. Thus for our distance metric we use:
我们不是用手选择前科,而是在训练集的边框上进行k-意指集群,以自动找到好的前科. 如果我们使用标准k-表示与欧几利得距离较大的框产生比较小的框更多的错误. 然而,我们真正想要的是导致良好IOU分数的前科,这与盒子大小无关. 因此,对于我们的距离测量,我们使用:
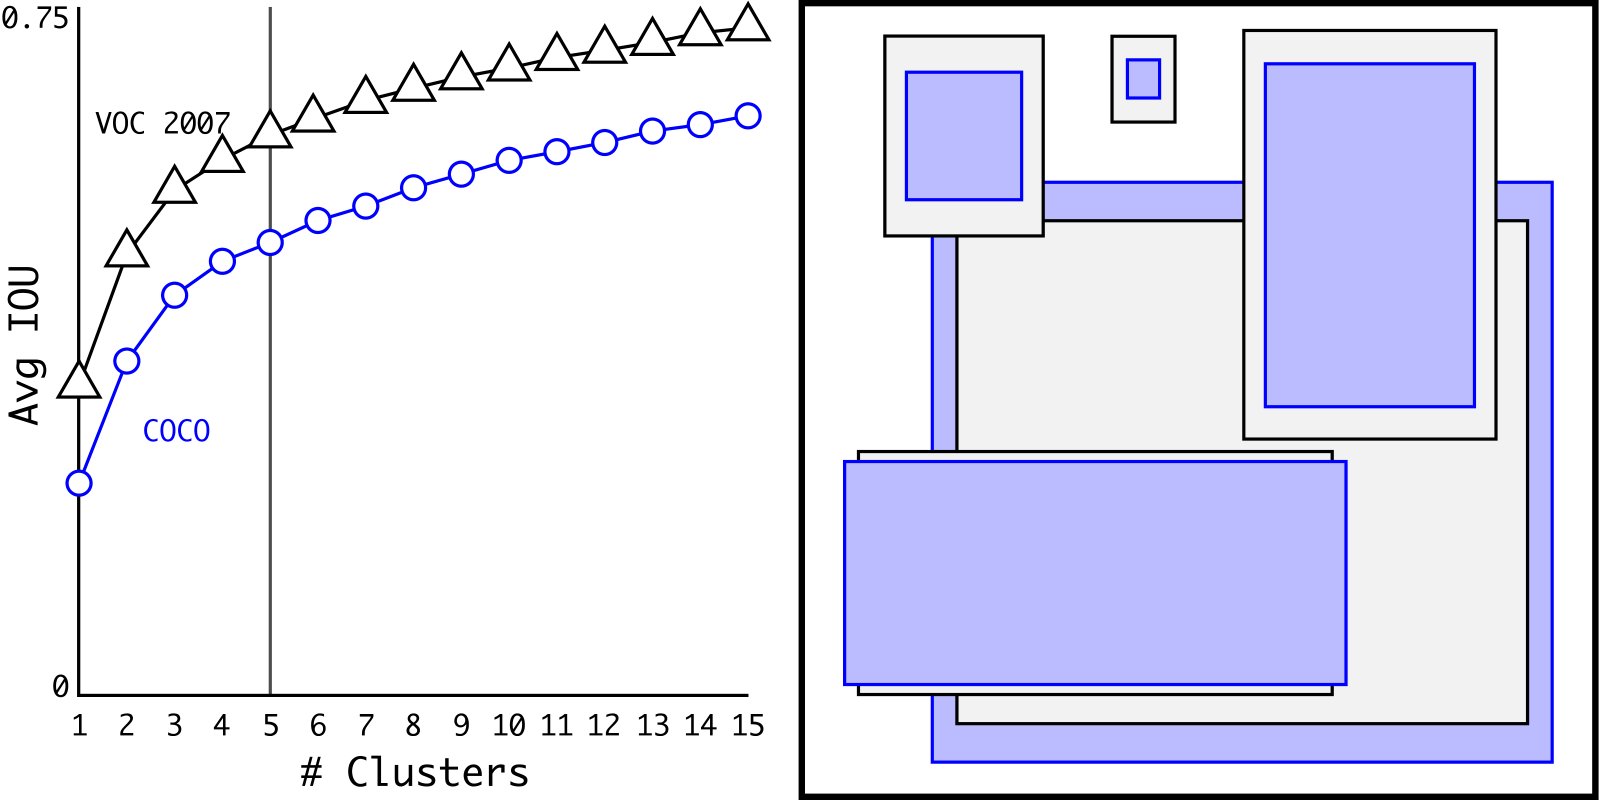
Figure 2: Clustering box dimensions on VOC and COCO. We run k-means clustering on the dimensions of bounding boxes to get good priors for our model. The left image shows the average IOU we get with various choices for . We find that gives a good tradeoff for recall vs. complexity of the model. The right image shows the relative centroids for VOC and COCO. Both sets of priors favor thinner, taller boxes while COCO has greater variation in size than VOC.
图2:**VOC和COCO上的组合框尺寸。 我们运行的k -意指 组合的尺寸 边框的尺寸 得到好的前科 我们的模型。 左侧图像显示我们获得的的各种选择的平均值 。 我们认为,在召回模型与模型复杂性之间作出了很好的权衡。 正确的图像显示了VOC和COCO的相对中心机器人. 两套前科都倾向于更薄、更高的箱子,而COCO的大小比VOC大。 **
We run k-means for various values of and plot the average IOU with closest centroid, see Figure 2. We choose as a good tradeoff between model complexity and high recall. The cluster centroids are significantly different than hand-picked anchor boxes. There are fewer short, wide boxes and more tall, thin boxes.
我们运行各种值为的 k 表示值, 并用最接近的中间机器人绘制平均 IOU, 见图2。 我们选择作为模型复杂度和高召回度之间的良好权衡. 集群的中间体与手摘锚箱有很大不同. 短,宽的盒子较少,而且更高,更薄的盒子.
We compare the average IOU to closest prior of our clustering strategy and the hand-picked anchor boxes in Table 1. At only 5 priors the centroids perform similarly to 9 anchor boxes with an average IOU of 61.0 compared to 60.9. If we use 9 centroids we see a much higher average IOU. This indicates that using k-means to generate our bounding box starts the model off with a better representation and makes the task easier to learn.
我们比较了平均IOU与我们集群战略之前最接近的IOU和表1中手选的锚框. 仅在5个前期,百人机器人的性能与9个锚框相似,平均IOU为61.0,而60.9. 如果我们使用9厘米的机器人, 我们可以看到一个更高的平均IOU。 这表明,使用 k 表示来生成我们的边框,启动模型时会有一个更好的表现,使任务更容易学习.
| Box Generation | Avg IOU | |
|---|---|---|
| Cluster SSE | 5 | 58.7 |
| Cluster IOU | 5 | 61.0 |
| Anchor Boxes [15] | 9 | 60.9 |
| Cluster IOU | 9 | 67.2 |
Table 1: Average IOU of boxes to closest priors on VOC 2007. The average IOU of objects on VOC 2007 to their closest, unmodified prior using different generation methods. Clustering gives much better results than using hand-picked priors.
| 框生成 | Avg IOU (英语). | |
|---|---|---|
| 集群 偃师 | 5 | 58.7 |
| 分组 IOU | 5 | 61.0 |
| 锚框 [15] | 9 | 60.9 |
| 分组 IOU | 9 | 67.2 |
表1:** 2007年VOC最接近的前身的盒式IOU。 VOC 2007上对象的平均IOU到其最接近,未经修改的前使用不同的生成方法. 分组比使用手工挑选的前科结果好得多。 **
Direct location prediction. When using anchor boxes with YOLO we encounter a second issue: model instability, especially during early iterations. Most of the instability comes from predicting the locations for the box. In region proposal networks the network predicts values and and the center coordinates are calculated as:
** 直接位置预测。 ** 当使用与YOLO的锚框时,我们遇到第二个问题:模型不稳定,特别是在早期迭代期间. 不稳定因素大多来自对盒子的位置的预测. 在区域提议网络中,网络预测值为和,计算值为:
For example, a prediction of would shift the box to the right by the width of the anchor box, a prediction of would shift it to the left by the same amount.
例如,对的预测将按锚框的宽度向右移动,对的预测将按相同数量向左移动.
This formulation is unconstrained so any anchor box can end up at any point in the image, regardless of what location predicted the box. With random initialization the model takes a long time to stabilize to predicting sensible offsets.
这种配方不受限制,因此任何锚框都可以最终出现在图像的任意一点上,无论盒子的预测位置是什么. 随着随机初始化,模型需要很长的时间来稳定,以预测合理的抵消.
Instead of predicting offsets we follow the approach of YOLO and predict location coordinates relative to the location of the grid cell. This bounds the ground truth to fall between and . We use a logistic activation to constrain the network’s predictions to fall in this range.
而不是预测抵消,我们遵循YOLO的方法,预测相对于网格细胞位置的位置坐标. 这将地面真相限制在和之间。 我们利用后勤激活来限制网络的预测,
The network predicts 5 bounding boxes at each cell in the output feature map. The network predicts 5 coordinates for each bounding box, , , , , and . If the cell is offset from the top left corner of the image by and the bounding box prior has width and height , , then the predictions correspond to:
网络预测输出特征图中每个单元格有5个边框. 没问题,网络预测每个边框有5个坐标,,,,,和. 如果单元格从图像左上角被抵消,且前面的边框有宽度和高度 ,, 那么预测值对应:
Since we constrain the location prediction the parametrization is easier to learn, making the network more stable. Using dimension clusters along with directly predicting the bounding box center location improves YOLO by almost 5% over the version with anchor boxes.
由于我们制约了位置预测 瘫痪更容易学习,使网络更加稳定。 使用维度集群以及直接预测边框中心位置,用锚框比版本提高了近5%的YOLO.
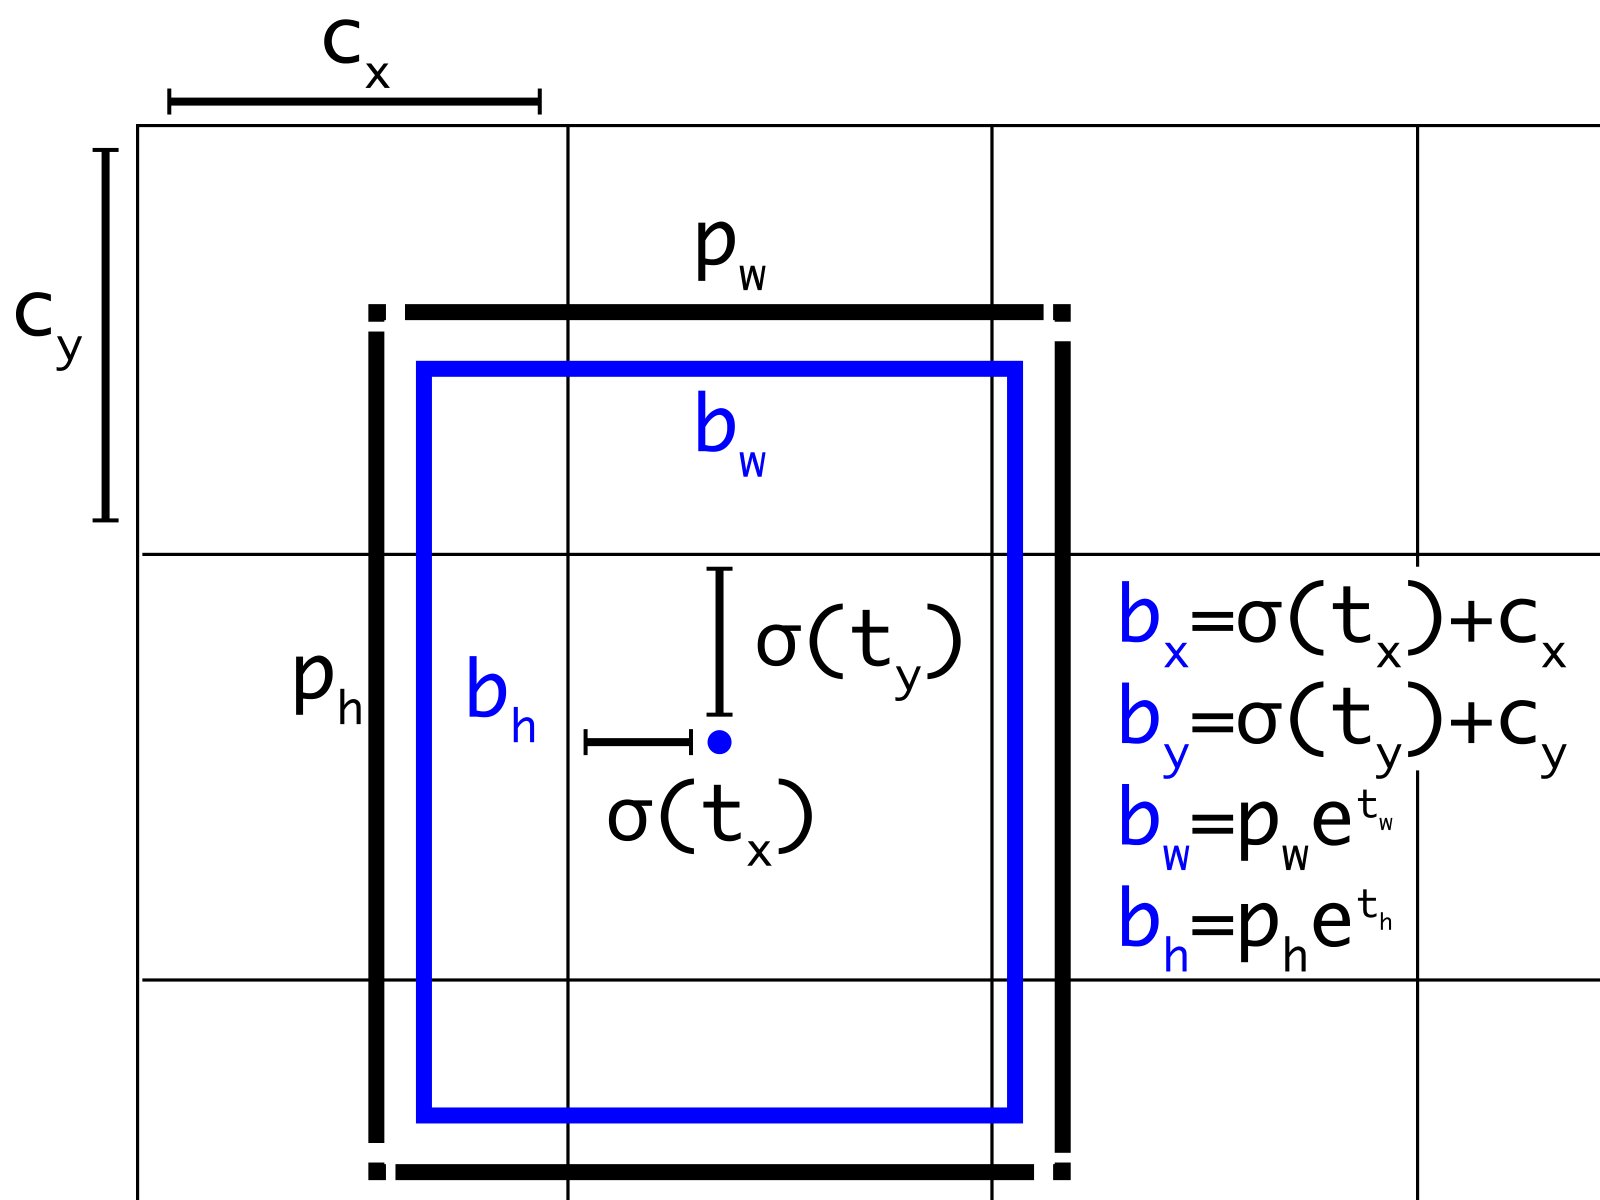
Figure 3: Bounding boxes with dimension priors and location prediction. We predict the width and height of the box as offsets from cluster centroids. We predict the center coordinates of the box relative to the location of filter application using a sigmoid function.
图3:**带尺寸前兆和位置预测的圆框。 我们预测这个盒子的宽度和高度 与组群中间行星相抵消 我们利用sigmoid函数预测箱的中心坐标相对于过滤器应用的位置。 **
**Fine-Grained Features.**This modified YOLO predicts detections on a feature map. While this is sufficient for large objects, it may benefit from finer grained features for localizing smaller objects. Faster R-CNN and SSD both run their proposal networks at various feature maps in the network to get a range of resolutions. We take a different approach, simply adding a passthrough layer that brings features from an earlier layer at resolution.
** Fine-Grained Features**. 这个经过修改的YOLO预测在特性图上检测. 虽然这对大型物体来说是足够的,但对于较小物体的定位来说,它可能得益于更细的谷物特征。 更快的R-CNN和SSD都在网络中的各种专题地图上运行其建议网络,以获得一系列分辨率. 我们采取了一种不同的做法,只是增加了一个通过层,它从早期的一层带入分辨率的特征。
The passthrough layer concatenates the higher resolution features with the low resolution features by stacking adjacent features into different channels instead of spatial locations, similar to the identity mappings in ResNet. This turns the feature map into a feature map, which can be concatenated with the original features. Our detector runs on top of this expanded feature map so that it has access to fine grained features. This gives a modest 1% performance increase.
传承层通过将相邻的特征堆放在不同的通道而不是空间位置,使分辨率较高的特征与分辨率较低的特征相连,类似于ResNet中的身份映射. 这使得特征图变成了特征图,可以与原始特征相配合. 我们的探测器 运行在这个扩展的特征图之上 这样它可以访问 精细的颗粒特征。 这表明业绩略有1%的增长。
Multi-Scale Training. The original YOLO uses an input resolution of . With the addition of anchor boxes we changed the resolution to . However, since our model only uses convolutional and pooling layers it can be resized on the fly. We want YOLOv2 to be robust to running on images of different sizes so we train this into the model.
** 多层面训练。 ** 最初的YOLO使用的输入分辨率. 随着锚框的增加,我们把分辨率改为。 然而,由于我们的模型只使用进化层和集合层,它可以在苍蝇上调整大小. 我们希望YOLOv2 强壮地运行在 不同大小的图像上 因此我们把它训练到模型。
Instead of fixing the input image size we change the network every few iterations. Every 10 batches our network randomly chooses a new image dimension size. Since our model downsamples by a factor of 32, we pull from the following multiples of 32: . Thus the smallest option is and the largest is . We resize the network to that dimension and continue training.
而不是固定输入图像大小,我们每隔几个迭代就改变网络. 每10批我们的网络随机选择一个新的图像尺寸大小. 由于我们的模型降标系数为32, 我们从以下32的倍数中抽取: 。 因此,最小的选择是,最大的选择是。 我们把网络调整到这一层面,并继续训练。
This regime forces the network to learn to predict well across a variety of input dimensions. This means the same network can predict detections at different resolutions. The network runs faster at smaller sizes so YOLOv2 offers an easy tradeoff between speed and accuracy.
这一制度迫使网络学习如何在各种投入层面作出良好的预测。 这意味着同一个网络可以预测不同分辨率的检测. 网络运行速度较快,体积较小,因此YOLOv2在速度和精度之间提供了轻松的权衡.
At low resolutions YOLOv2 operates as a cheap, fairly accurate detector. At it runs at more than 90 FPS with mAP almost as good as Fast R-CNN. This makes it ideal for smaller GPUs, high framerate video, or multiple video streams.
低分辨率的YOLOv2作为廉价,相当准确的探测器运行. 在XX 祝你好运 在XXMATH应给予90多个FPS,MAP几乎和快速R-CNN一样好。 这使得它对于更小的GPU,高帧率的视频,或者多个视频流来说是理想的.
At high resolution YOLOv2 is a state-of-the-art detector with 78.6 mAP on VOC 2007 while still operating above real-time speeds. See Table 3 for a comparison of YOLOv2 with other frameworks on VOC 2007. Figure 4
高分辨率的YOLOv2是一台在VOC 2007上装有78.6mAP的先进探测器,同时仍在实时速度上运行. 关于YOLOv2与VOC 2007的其他框架的比较见表3。 图4
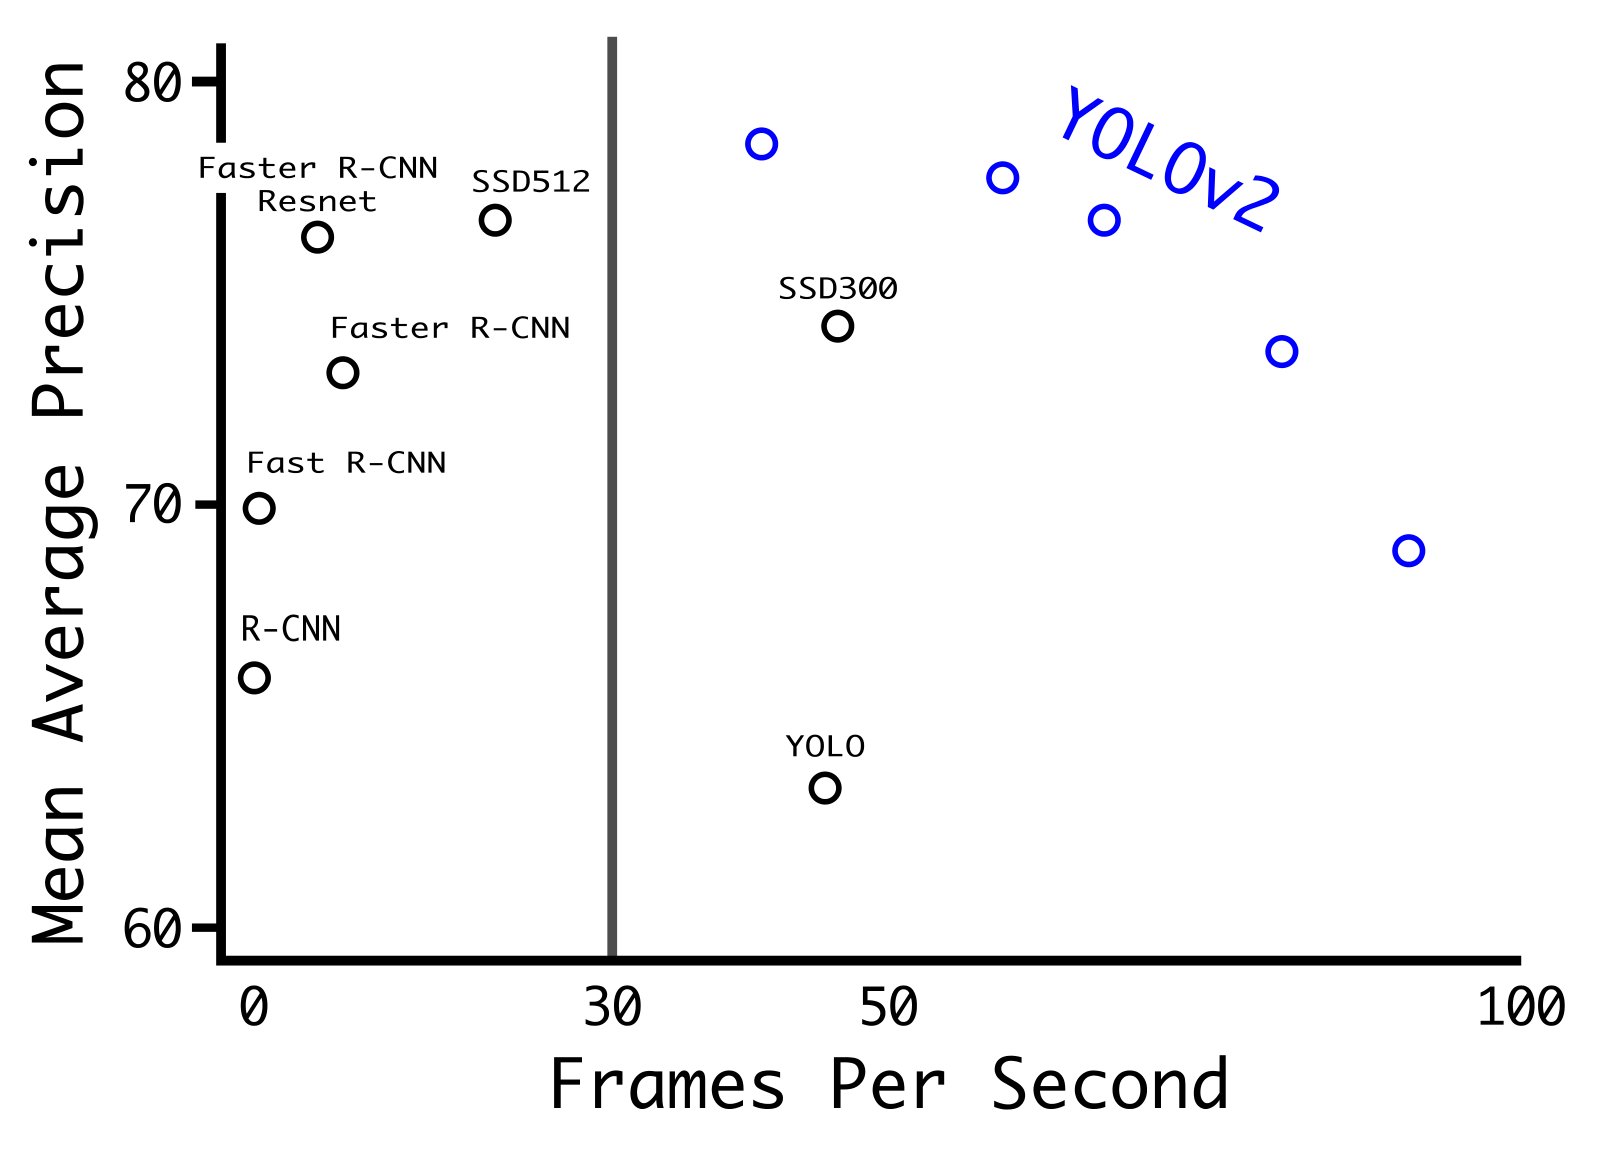
Figure 4: Accuracy and speed on VOC 2007.
图4:** VOC 2007的准确性和速度**
Further Experiments. We train YOLOv2 for detection on VOC 2012. Table 4 shows the comparative performance of YOLOv2 versus other state-of-the-art detection systems. YOLOv2 achieves 73.4 mAP while running far faster than competing methods. We also train on COCO and compare to other methods in Table 5. On the VOC metric (IOU = .5) YOLOv2 gets 44.0 mAP, comparable to SSD and Faster R-CNN.
** 进一步的实验。 ** 我们训练YOLOv2在VOC 2012进行检测. 表4显示YOLOv2与其他最新探测系统的比较性能. YOLOv2实现了73.4 mAP,同时运行远快于竞技方法. 我们还对COCO进行训练,并与表5中的其他方法进行比较。 在VOC度量(IOU = 5)上,YOLOv2得到44.0 mAP,与SSD和更快的R-CNN相当.
| YOLO | YOLOv2 | ||||||||
|---|---|---|---|---|---|---|---|---|---|
| batch norm? | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | |
| hi-res classifier? | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ||
| convolutional? | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | |||
| anchor boxes? | ✓ | ✓ | |||||||
| new network? | ✓ | ✓ | ✓ | ✓ | ✓ | ||||
| dimension priors? | ✓ | ✓ | ✓ | ✓ | |||||
| location prediction? | ✓ | ✓ | ✓ | ✓ | |||||
| passthrough? | ✓ | ✓ | ✓ | ||||||
| multi-scale? | ✓ | ✓ | |||||||
| hi-res detector? | ✓ | ||||||||
| VOC2007 mAP | 63.4 | 65.8 | 69.5 | 69.2 | 69.6 | 74.4 | 75.4 | 76.8 | 78.6 |
Table 2: The path from YOLO to YOLOv2. Most of the listed design decisions lead to significant increases in mAP. Two exceptions are switching to a fully convolutional network with anchor boxes and using the new network. Switching to the anchor box style approach increased recall without changing mAP while using the new network cut computation by 33%.
| YOLO | YOLOv2 | ||||||||
|---|---|---|---|---|---|---|---|---|---|
| 批归一化? | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | |
| 高分辨率分类器? | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ||
| 卷积化? | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | |||
| 锚框? | ✓ | ✓ | |||||||
| 新网络? | ✓ | ✓ | ✓ | ✓ | ✓ | ||||
| 维度先验? | ✓ | ✓ | ✓ | ✓ | |||||
| 位置预测? | ✓ | ✓ | ✓ | ✓ | |||||
| passthrough? | ✓ | ✓ | ✓ | ||||||
| 多尺度? | ✓ | ✓ | |||||||
| 高分辨率检测器? | ✓ | ||||||||
| VOC2007 mAP | 63.4 | 65.8 | 69.5 | 69.2 | 69.6 | 74.4 | 75.4 | 76.8 | 78.6 |
Table 2: The path from YOLO to YOLOv2. Most of the listed design decisions lead to significant increases in mAP. Two exceptions are switching to a fully convolutional network with anchor boxes and using the new network. Switching to the anchor box style approach increased recall without changing mAP while using the new network cut computation by 33%.
| Detection Frameworks | Train | mAP | FPS |
|---|---|---|---|
| Fast R-CNN [5] | 2007+2012 | 70.0 | 0.5 |
| Faster R-CNN VGG-16[15] | 2007+2012 | 73.2 | 7 |
| Faster R-CNN ResNet[6] | 2007+2012 | 76.4 | 5 |
| YOLO [14] | 2007+2012 | 63.4 | 45 |
| SSD300 [11] | 2007+2012 | 74.3 | 46 |
| SSD500 [11] | 2007+2012 | 76.8 | 19 |
| YOLOv2 | 2007+2012 | 69.0 | 91 |
| YOLOv2 | 2007+2012 | 73.7 | 81 |
| YOLOv2 | 2007+2012 | 76.8 | 67 |
| YOLOv2 | 2007+2012 | 77.8 | 59 |
| YOLOv2 | 2007+2012 | 78.6 | 40 |
Table 3: Detection frameworks on Pascal VOC 2007. YOLOv2 is faster and more accurate than prior detection methods. It can also run at different resolutions for an easy tradeoff between speed and accuracy. Each YOLOv2 entry is actually the same trained model with the same weights, just evaluated at a different size. All timing information is on a Geforce GTX Titan X (original, not Pascal model).
| 检测框架 | 火车 | mAP | FPS |
|---|---|---|---|
| 快速 R-CNN [5] (中文(简体) ). | 2007+2012 | 70.0 | 0.5 |
| 更快的R-CNN VGG-16 [15] | 2007+2012 | 73.2 | 7 |
| 褒贬二类 | 2007+2012 | 76.4 | 5 |
| 约 还有 . [14] | 2007+2012 | 63.4 | 45 |
| SSD300 [11] (英语). | 2007+2012 | 74.3 | 46 |
| SSD500 [11] (英语). | 2007+2012 | 76.8 | 19 |
| YOLOv2(英语). | 2007+2012 | 69.0 | 91 |
| YOLOv2(英语). | 2007+2012 | 73.7 | 81 |
| YOLOv2(英语). | 2007+2012 | 76.8 | 67 |
| YOLOv2(英语). | 2007+2012 | 77.8 | 59 |
| YOLOv2(英语). | 2007+2012 | 页:1 | 40 |
表3:** 2007年Pascal VOC的检测框架。 YOLOv2比先前的检测方法更快,更准确. 它也可以以不同的分辨率运行,以方便的速度和准确性之间的权衡. 每一个YOLOv2条目实际上都是同一个训练有素的型号,重量相同,只是用不同的尺寸来评价. 所有计时信息都使用Geforce GTX Titan X(原型,而非Pascal型号)**.
| Method | data | mAP | aero | bike | bird | boat | bottle | bus | car | cat | chair | cow | table | dog | horse | mbike | person | plant | sheep | sofa | train | tv |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Fast R-CNN [5] | 07++12 | 68.4 | 82.3 | 78.4 | 70.8 | 52.3 | 38.7 | 77.8 | 71.6 | 89.3 | 44.2 | 73.0 | 55.0 | 87.5 | 80.5 | 80.8 | 72.0 | 35.1 | 68.3 | 65.7 | 80.4 | 64.2 |
| Faster R-CNN [15] | 07++12 | 70.4 | 84.9 | 79.8 | 74.3 | 53.9 | 49.8 | 77.5 | 75.9 | 88.5 | 45.6 | 77.1 | 55.3 | 86.9 | 81.7 | 80.9 | 79.6 | 40.1 | 72.6 | 60.9 | 81.2 | 61.5 |
| YOLO [14] | 07++12 | 57.9 | 77.0 | 67.2 | 57.7 | 38.3 | 22.7 | 68.3 | 55.9 | 81.4 | 36.2 | 60.8 | 48.5 | 77.2 | 72.3 | 71.3 | 63.5 | 28.9 | 52.2 | 54.8 | 73.9 | 50.8 |
| SSD300 [11] | 07++12 | 72.4 | 85.6 | 80.1 | 70.5 | 57.6 | 46.2 | 79.4 | 76.1 | 89.2 | 53.0 | 77.0 | 60.8 | 87.0 | 83.1 | 82.3 | 79.4 | 45.9 | 75.9 | 69.5 | 81.9 | 67.5 |
| SSD512 [11] | 07++12 | 74.9 | 87.4 | 82.3 | 75.8 | 59.0 | 52.6 | 81.7 | 81.5 | 90.0 | 55.4 | 79.0 | 59.8 | 88.4 | 84.3 | 84.7 | 83.3 | 50.2 | 78.0 | 66.3 | 86.3 | 72.0 |
| ResNet [6] | 07++12 | 73.8 | 86.5 | 81.6 | 77.2 | 58.0 | 51.0 | 78.6 | 76.6 | 93.2 | 48.6 | 80.4 | 59.0 | 92.1 | 85.3 | 84.8 | 80.7 | 48.1 | 77.3 | 66.5 | 84.7 | 65.6 |
| YOLOv2 | 07++12 | 73.4 | 86.3 | 82.0 | 74.8 | 59.2 | 51.8 | 79.8 | 76.5 | 90.6 | 52.1 | 78.2 | 58.5 | 89.3 | 82.5 | 83.4 | 81.3 | 49.1 | 77.2 | 62.4 | 83.8 | 68.7 |
Table 4: PASCAL VOC2012 test detection results. YOLOv2 performs on par with state-of-the-art detectors like Faster R-CNN with ResNet and SSD512 and is faster.
| 方法 | 数据 | mAP | 飞机 | 自行车 | 鸟 | boat | 瓶装 | 公共汽车 | car | cat | 椅子 | 黄牛 | 页:1 | 狗头 | 马 | 摩托车 | 人员 | 工厂 | 绵羊 | 沙发 | 火车 | 电视 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 快速 R-CNN [5] (中文(简体) ). | 07++12 | 68.4 | 82.3 | 78.4 | 70.8 | 52.3 | 38.7 | 77.8 | 71.6 | 89.3 | 44.2 | 73.0 | 55.0 | 87.5 | 80.5 | 80.8 | 72.0 | 35.1 | 68.3 | 65.7 | 80.4 | 64.2 |
| 更快的R-CNN [15] (中文(简体) ). | 07++12 | 70.4 | 84.9 | 79.8 | 74.3 | 53.9 | 49.8 | 77.5 | 75.9 | 88.5 | 45.6 | 77.1 | 55.3 | 86.9 | 81.7 | 80.9 | 79.6 | 40.1 | 72.6 | 60.9 | 81.2 | 61.5 |
| YOLO [14] (英语). | 07++12 | 57.9 | 77.0 | 67.2 | 57.7 | 38.3 | 22.7 | 68.3 | 55.9 | 81.4 | 36.2 | 60.8 | 48.5 | 77.2 | 72.3 | 71.3 | 63.5 | 28.9 | 52.2 | 54.8 | 73.9 | 50.8 |
| SSD300 [11] (英语). | 07++12 | 72.4 | 85.6 | 80.1 | 70.5 | 57.6 | 46.2 | 79.4 | 76.1 | 89.2 | 53.0 | 77.0 | 60.8 | 87.0 | 83.1 | 82.3 | 79.4 | 45.9 | 75.9 | 69.5 | 81.9 | 67.5 |
| SSD512 [11] (英语). | 07++12 | 74.9 | 87.4 | 82.3 | 75.8 | 59.0 | 52.6 | 81.7 | 81.5 | 90.0 | 55.4 | 79.0 | 59.8 | 88.4 | 84.3 | 84.7 | 83.3 | 50.2 | 78.0 | 66.3 | 86.3 | 72.0 |
| ResNet [6] | 07++12 | 73.8 | 86.5 | 81.6 | 77.2 | 58.0 | 51.0 | 78.6 | 76.6 | 93.2 | 48.6 | 80.4 | 59.0 | 92.1 | 85.3 | 84.8 | 80.7 | 48.1 | 77.3 | 66.5 | 84.7 | 65.6 |
| YOLOv2 | 07++12 | 73.4 | 86.3 | 82.0 | 74.8 | 59.2 | 51.8 | 79.8 | 76.5 | 90.6 | 52.1 | 78.2 | 58.5 | 89.3 | 82.5 | 83.4 | 81.3 | 49.1 | 77.2 | 62.4 | 83.8 | 68.7 |
表4什么东西** PASCAL VOC2012测试检测结果. YOLOv2与最新技术的探测器(如ResNet和SSD512的S更快R-CNN)一样运行,速度更快。 **
| 0.5:0.95 | 0.5 | 0.75 | S | M | L | 1 | 10 | 100 | S | M | L | ||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Fast R-CNN [5] | train | 19.7 | 35.9 | - | - | - | - | - | - | - | - | - | - |
| Fast R-CNN[1] | train | 20.5 | 39.9 | 19.4 | 4.1 | 20.0 | 35.8 | 21.3 | 29.5 | 30.1 | 7.3 | 32.1 | 52.0 |
| Faster R-CNN[15] | trainval | 21.9 | 42.7 | - | - | - | - | - | - | - | - | - | - |
| ION [1] | train | 23.6 | 43.2 | 23.6 | 6.4 | 24.1 | 38.3 | 23.2 | 32.7 | 33.5 | 10.1 | 37.7 | 53.6 |
| Faster R-CNN[10] | trainval | 24.2 | 45.3 | 23.5 | 7.7 | 26.4 | 37.1 | 23.8 | 34.0 | 34.6 | 12.0 | 38.5 | 54.4 |
| SSD300 [11] | trainval35k | 23.2 | 41.2 | 23.4 | 5.3 | 23.2 | 39.6 | 22.5 | 33.2 | 35.3 | 9.6 | 37.6 | 56.5 |
| SSD512 [11] | trainval35k | 26.8 | 46.5 | 27.8 | 9.0 | 28.9 | 41.9 | 24.8 | 37.5 | 39.8 | 14.0 | 43.5 | 59.0 |
| YOLOv2 [11] | trainval35k | 21.6 | 44.0 | 19.2 | 5.0 | 22.4 | 35.5 | 20.7 | 31.6 | 33.3 | 9.8 | 36.5 | 54.4 |
Table 5: Results on COCO test-dev2015. Table adapted from [11]
| 0.5:0.95 (中文(简体) ). | 0.5 | 0.75 | S | 管理人员 | L | 1 | 10 | 100 | S | 管理人员 | L | ||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 快速 R-CNN [5] (中文(简体) ). | 19.7 | 35.9 | - | - | - | - | - | - | - | - | - | - | |
| 快速 R-CNN [1] | 火车 | 20.5 | 39.9 | 19.4 | 4.1 | 20.0 | 35.8 | 21.3 | 29.5 | 30.1 | 7.3 | 32.1 | 52.0 |
| 更快的 R-CNN [15] | 火车 | 21.9 | 42.7 | - | - | - | - | - | - | - | - | - | - |
| 伊ON [1] | 火车 | 23.6 | 43.2 | 23.6 | 6.4 | 24.1 | 38.3 | 23.2 | 32.7 | 33.5 | 10.1 | 37.7 | 53.6 |
| 更快的 R-CNN [10] | 火车 | 24.2 | 45.3 | 23.5 | 7.7 | 26.4 | 37.1 | 23.8 | 34.0 | 34.6 | 12.0 | 38.5 | 54.4 |
| SSD300 [11] (英语). | 列车val35k | 23.2 | 41.2 | 23.4 | 5.3 | 23.2 | 39.6 | 22.5 | 33.2 | 35.3 | 9.6 | 37.6 | 56.5 |
| SSD512 [11] (英语). | 列车val35k | 页:1 | ** 46.5 ** | ** 第27.8段** | 页:1 | 页:1 | 页:1 | 页:1 | ** 第37.5页** | **很快就会收到。 | **芮丝·阿斯马拉(签名) | 页:1 | 家 |
| YOLOv2 [11] (英语). | 列车val35k | 21.6 | 44.0 | 19.2 | 5.0 | 22.4 | 35.5 | 20.7 | 31.6 | 33.3 | 9.8 | 36.5 | 54.4 |
表5:COCO测试结果-2015年。 改编自[11]
3 Faster
3 更快(Faster)
We want detection to be accurate but we also want it to be fast. Most applications for detection, like robotics or self-driving cars, rely on low latency predictions. In order to maximize performance we design YOLOv2 to be fast from the ground up.
我们希望检测准确,但我们也希望快速。 大多数用于检测的应用,如机器人或自驾车,都依赖于低延迟预测. 为了最大限度地发挥性能 我们设计了YOLOv2 从地面上快速。
Most detection frameworks rely on VGG-16 as the base feature extractor [17]. VGG-16 is a powerful, accurate classification network but it is needlessly complex. The convolutional layers of VGG-16 require 30.69 billion floating point operations for a single pass over a single image at resolution.
大多数检测框架都依赖于VGG-16作为底片特征提取器[17]. VGG-16是一个强大,准确的分类网络,但它是不必要的复杂. VGG-16的卷积层需要306.9亿的浮点操作,在分辨率上一个单一的传过一个单一的图像.
The YOLO framework uses a custom network based on the Googlenet architecture [19]. This network is faster than VGG-16, only using 8.52 billion operations for a forward pass. However, it’s accuracy is slightly worse than VGG-16. For single-crop, top-5 accuracy at , YOLO’s custom model gets 88.0% ImageNet compared to 90.0% for VGG-16.
YOLO框架使用基于Googlenet架构的自定义网络[19]. 这个网络比VGG-16更快,只使用85.2亿的操作进行前传. 然而,它的准确性略低于VGG-16. 对于单作物,在的上5精度,YOLO的自定义模型得到88.0%的ImageNet,而VGG-16的则得到90.0%.
Darknet-19. We propose a new classification model to be used as the base of YOLOv2. Our model builds off of prior work on network design as well as common knowledge in the field. Similar to the VGG models we use mostly filters and double the number of channels after every pooling step [17]. Following the work on Network in Network (NIN) we use global average pooling to make predictions as well as filters to compress the feature representation between convolutions [9]. We use batch normalization to stabilize training, speed up convergence, and regularize the model [7].
页:1 我们提出一个新的分类模式,作为YOLOv2的基础. 我们的模式借鉴了先前的网络设计工作以及该领域的共同知识。 与VGG模型类似,我们大多使用滤波器,在每个集合步骤[17]后,通道数量翻一番. 继网络网络(NIN)的工作之后,我们利用全球平均集合来作出预测,并使用滤波器来压缩演化之间的特征表示[9]. 我们用批归一化来稳定训练,加快趋同,使模式规范化[7].
Our final model, called Darknet-19, has 19 convolutional layers and 5 maxpooling layers. For a full description see Table 6. Darknet-19 only requires 5.58 billion operations to process an image yet achieves top-1 accuracy and top-5 accuracy on ImageNet.
我们最后的模型叫做"暗网19",有19个卷积层和5个最大集合层. 详细情况见表6。 Darknet-19只需要55.8亿个操作就可以处理一个图像,然而却在ImageNet上实现了上1的精度和上5的精度.
Training for classification. We train the network on the standard ImageNet 1000 class classification dataset for 160 epochs using stochastic gradient descent with a starting learning rate of , polynomial rate decay with a power of , weight decay of and momentum of using the Darknet neural network framework [13]. During training we use standard data augmentation tricks including random crops, rotations, and hue, saturation, and exposure shifts.
** 分类训练。 ** 我们在标准ImageNet 1000类分类数据集上对160个纪元进行网络训练,使用划时代梯度下降,起始学习率为,多诺速率衰减功率为,重量衰减为,动力为使用暗网神经网络框架[13]. 在训练期间,我们使用标准的数据增强技巧,包括随机作物、旋转、湿度、饱和度和接触变化。
| Type | Filters | Size/Stride | Output |
|---|---|---|---|
| Convolutional | 32 | ||
| Maxpool | |||
| Convolutional | 64 | ||
| Maxpool | |||
| Convolutional | 128 | ||
| Convolutional | 64 | ||
| Convolutional | 128 | ||
| Maxpool | |||
| Convolutional | 256 | ||
| Convolutional | 128 | ||
| Convolutional | 256 | ||
| Maxpool | |||
| Convolutional | 512 | ||
| Convolutional | 256 | ||
| Convolutional | 512 | ||
| Convolutional | 256 | ||
| Convolutional | 512 | ||
| Maxpool | |||
| Convolutional | 1024 | ||
| Convolutional | 512 | ||
| Convolutional | 1024 | ||
| Convolutional | 512 | ||
| Convolutional | 1024 | ||
| Convolutional | 1000 | ||
| Avgpool | Global | ||
| Softmax |
Table 6: Darknet-19.
| 类型 | 过滤器 | 大小/ 速度 | 产出 |
|---|---|---|---|
| 革命主义 | 32 | ||
| 马克斯浦 | |||
| 革命主义 | 64 | ||
| 马克斯浦 | |||
| 革命主义 | 128 | ||
| 革命主义 | 64 | ||
| 革命主义 | 128 | ||
| 马克斯浦 | |||
| 革命主义 | 256 | ||
| 革命主义 | 128 | ||
| 革命主义 | 256 | ||
| 马克斯浦 | |||
| 革命主义 | 512 | ||
| 革命主义 | 256 | ||
| 革命主义 | 512 | ||
| 革命主义 | 256 | ||
| 革命主义 | 512 | ||
| 马克斯浦 | |||
| 革命主义 | 1024 | ||
| 革命主义 | 512 | ||
| 革命主义 | 1024 | ||
| 革命主义 | 512 | ||
| 革命主义 | 1024 | ||
| 革命主义 | 1000 | ||
| 阿夫格普尔 | 全球 | ||
| 软马克 |
表6:**Darknet-19。 **
As discussed above, after our initial training on images at we fine tune our network at a larger size, . For this fine tuning we train with the above parameters but for only 10 epochs and starting at a learning rate of . At this higher resolution our network achieves a top-1 accuracy of and a top-5 accuracy of .
如上所述,经过我们在进行图像初步训练后,我们以更大的规模调整我们的网络,。 对于这个微调,我们用上述参数进行训练,但只有10个世纪,并且开始学习速度为。 在这个更高的分辨率下,我们的网络达到了的最高-1精度和的最高-5精度.
Training for detection. We modify this network for detection by removing the last convolutional layer and instead adding on three convolutional layers with filters each followed by a final convolutional layer with the number of outputs we need for detection. For VOC we predict 5 boxes with 5 coordinates each and 20 classes per box so 125 filters. We also add a passthrough layer from the final layer to the second to last convolutional layer so that our model can use fine grain features.
** 检测训练。 ** 我们修改这个网络进行检测,方法是去掉最后一个转录层,然后在三个转录层上加装了滤波器,每个滤波器后面再加一个最后的转录层,加上我们需要检测的输出数量. 对于VOC,我们预测5个盒子,每个盒子有5个坐标,每个盒子有20个等级,这样125个过滤器。 我们还从最后的层到第二到最后的进化层增加了一个传递层,这样我们的模型就可以使用精细的谷物特征.
We train the network for 160 epochs with a starting learning rate of , dividing it by 10 at 60 and 90 epochs. We use a weight decay of and momentum of . We use a similar data augmentation to YOLO and SSD with random crops, color shifting, etc. We use the same training strategy on COCO and VOC.
我们为160个世纪训练网络,开始学习率为,在60和90个世纪时除以10。 我们使用的重量衰减和的动力。 我们在YOLO和SSD中使用了类似的数据增强,随机作物,色调变化等. 我们使用同样的COCO和VOC训练策略.
4 Stronger
4 更强(Stronger)
We propose a mechanism for jointly training on classification and detection data. Our method uses images labelled for detection to learn detection-specific information like bounding box coordinate prediction and objectness as well as how to classify common objects. It uses images with only class labels to expand the number of categories it can detect.
我们建议建立一个联合训练分类和检测数据的机制。 我们的方法利用标有检测标签的图像来学习诸如边框坐标预测和物体等特定检测信息,以及如何对常见物体进行分类。 它使用只有类标签的图像来扩展它能检测到的类别数量.
During training we mix images from both detection and classification datasets. When our network sees an image labelled for detection we can backpropagate based on the full YOLOv2 loss function. When it sees a classification image we only backpropagate loss from the classification-specific parts of the architecture.
在训练期间,我们混合了来自检测和分类数据集的图像。 当我们的网络看到一个标有检测标签的图像时, 我们可以根据YOLOv2损失的全部功能进行后置。 当它看到一个分类图象时,我们只从建筑中特定分类的部位后支撑损失.
This approach presents a few challenges. Detection datasets have only common objects and general labels, like “dog” or “boat”. Classification datasets have a much wider and deeper range of labels. ImageNet has more than a hundred breeds of dog, including “Norfolk terrier”, “Yorkshire terrier”, and “Bedlington terrier”. If we want to train on both datasets we need a coherent way to merge these labels.
这种办法提出了一些挑战。 检测数据集只有普通对象和一般标签,如“狗”或“船”。 分类数据集的标签范围要广得多,更深. ImageNet有100多种狗品种,包括“Norfolk terrier”、“Yorkshire terrier”和“Bedlington terrier”。 如果我们想在这两个数据集上进行训练,我们需要一个连贯的方法来合并这些标签.
Most approaches to classification use a softmax layer across all the possible categories to compute the final probability distribution. Using a softmax assumes the classes are mutually exclusive. This presents problems for combining datasets, for example you would not want to combine ImageNet and COCO using this model because the classes “Norfolk terrier” and “dog” are not mutually exclusive.
大多数分类方法都使用跨所有可能分类的软马克斯层来计算最终概率分布. 使用软马克思假设这些课程是相互排斥的。 这给合并数据集带来了问题,例如,你不希望将ImageNet和COCO合并使用这一模型,因为“Norfolk terrier”和“dog”两个类别并不相互排斥。
We could instead use a multi-label model to combine the datasets which does not assume mutual exclusion. This approach ignores all the structure we do know about the data, for example that all of the COCO classes are mutually exclusive.
我们可以使用一个多标签模型来合并不假定相互排斥的数据集。 这种方法忽略了我们所知道的数据的所有结构,例如所有COCO类都是相互排斥的.
Hierarchical classification. ImageNet labels are pulled from WordNet, a language database that structures concepts and how they relate [12]. In WordNet, “Norfolk terrier” and “Yorkshire terrier” are both hyponyms of “terrier” which is a type of “hunting dog”, which is a type of “dog”, which is a “canine”, etc. Most approaches to classification assume a flat structure to the labels however for combining datasets, structure is exactly what we need.
** 等级分类。 ** ImageNet的标签从WordNet中抽取出来,WordNet是一个语言数据库,它构建概念及其关联方式[12]. 在WordNet中,“Norfolk terrier”和“Yorkshire terrier”都是“terrier”的缩写,是一种“猎狗”,是一种“狗”,是一种“犬类”,等等。 大多数分类方法都假定标签采用平面结构,但为了合并数据集,结构正是我们需要的。
WordNet is structured as a directed graph, not a tree, because language is complex. For example a “dog” is both a type of “canine” and a type of “domestic animal” which are both synsets in WordNet. Instead of using the full graph structure, we simplify the problem by building a hierarchical tree from the concepts in ImageNet.
WordNet的结构为定向图,而非树,因为语言复杂. 例如,“狗”既是一种“犬类”也是一种“家畜”,它们都是WordNet中的合成物。 我们不使用完整的图表结构,而是通过从ImageNet中的概念中建立一个层次树来简化问题.
To build this tree we examine the visual nouns in ImageNet and look at their paths through the WordNet graph to the root node, in this case “physical object”. Many synsets only have one path through the graph so first we add all of those paths to our tree. Then we iteratively examine the concepts we have left and add the paths that grow the tree by as little as possible. So if a concept has two paths to the root and one path would add three edges to our tree and the other would only add one edge, we choose the shorter path.
为了建立这棵树,我们研究了ImageNet中的视觉名词,并通过WordNet图查看它们通往根节点的路径,在此情况下是“物理对象”。 许多合成器在图中只有一个路径,所以我们首先将所有这些路径都添加到我们的树上. 然后,我们反复研究我们留下的概念, 并尽可能少地增加种树的路径。 所以,如果一个概念有两条通往根的路径,一条路径会给我们的树增加三个边缘,而另一条则只会增加一个边缘,那么我们就选择较短的路径.
The final result is WordTree, a hierarchical model of visual concepts. To perform classification with WordTree we predict conditional probabilities at every node for the probability of each hyponym of that synset given that synset. For example, at the “terrier” node we predict:
最终结果是WordTree,视觉概念的层次模型. 为了与WordTree进行分类,我们预测每个节点的有条件概率,以表示该同位素的每个下位元的概率。 例如,在“更”的节点,我们预测:
If we want to compute the absolute probability for a particular node we simply follow the path through the tree to the root node and multiply to conditional probabilities. So if we want to know if a picture is of a Norfolk terrier we compute:
如果我们想计算某个节点的绝对概率,我们只是沿着树到根节点的路径,乘以有条件的概率. 所以,如果我们想知道 照片是否是诺福克恐怖者 我们计算:
For classification purposes we assume that the the image contains an object: .
为了 现在是分类目的 我们假设图像包含一个对象: 。
To validate this approach we train the Darknet-19 model on WordTree built using the 1000 class ImageNet. To build WordTree1k we add in all of the intermediate nodes which expands the label space from 1000 to 1369. During training we propagate ground truth labels up the tree so that if an image is labelled as a “Norfolk terrier” it also gets labelled as a “dog” and a “mammal”, etc. To compute the conditional probabilities our model predicts a vector of 1369 values and we compute the softmax over all sysnsets that are hyponyms of the same concept, see Figure 5.
为了验证这个方法,我们在WordTree上训练了使用1000级图像网建立的Darknet-19模型. 为了构建WordTree1k,我们在所有中间节点中都添加了将标签空间从1000拓宽到1369拓宽. 在训练期间,我们把真值贴在树上,这样,如果一个图像贴上“Norfolk terrier”的标签,它也贴上“狗”和“哺乳动物”等标签。 为了计算有条件的概率,我们的模型预测的矢量为1369值,我们计算所有同概念的sysnsets的软度,见图5。
Using the same training parameters as before, our hierarchical Darknet-19 achieves top-1 accuracy and top-5 accuracy. Despite adding 369 additional concepts and having our network predict a tree structure our accuracy only drops marginally. Performing classification in this manner also has some benefits. Performance degrades gracefully on new or unknown object categories. For example, if the network sees a picture of a dog but is uncertain what type of dog it is, it will still predict “dog” with high confidence but have lower confidences spread out among the hyponyms.
使用与前作相同的训练参数,我们分级的Darknet-19实现了上1精度和上5精度. 尽管增加了369个新概念,而且我们的网络预测了一个树状结构,但是我们的准确度只是略微下降。 以这种方式进行分类也有一些好处。 性能在新的或未知对象类别上优雅地降解。方面具有高度自信的“狗”仍会预测,
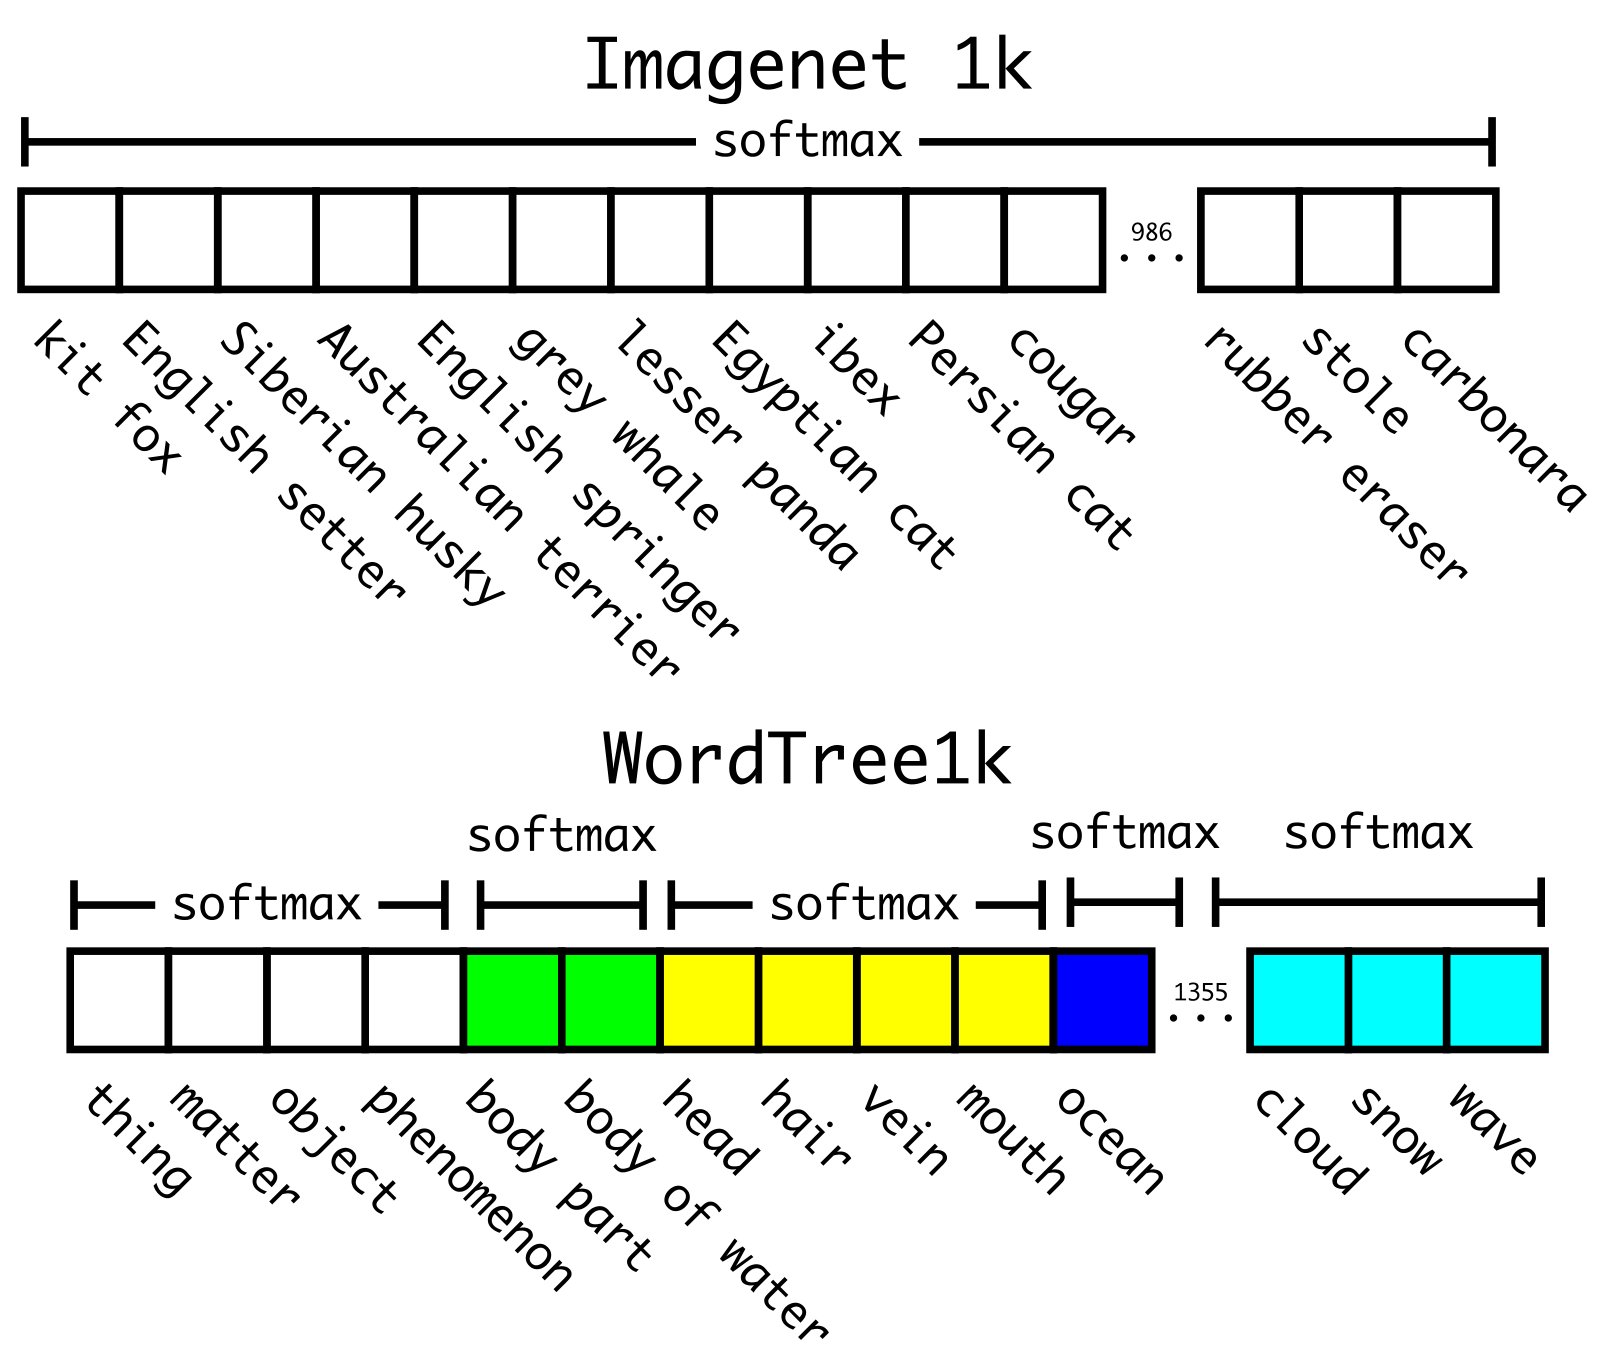
Figure 5: Prediction on ImageNet vs WordTree. Most ImageNet models use one large softmax to predict a probability distribution. Using WordTree we perform multiple softmax operations over co-hyponyms.
图5:** 图像网对WordTree的预测。 大多数ImageNet模型使用一个大软马克来预测概率分布. 使用WordTree,我们执行多个软马克思操作在共音节上**.
This formulation also works for detection. Now, instead of assuming every image has an object, we use YOLOv2’s objectness predictor to give us the value of . The detector predicts a bounding box and the tree of probabilities. We traverse the tree down, taking the highest confidence path at every split until we reach some threshold and we predict that object class.
这种配方也可用于检测。 现在,我们不是假设每个图像都有一个对象,而是使用YOLOv2的对象预测器给出的值。 探测器预测一个边框和概率树. 我们穿过树下,在每个裂缝中走最高的置信路,直到达到一定的阈值,我们预测那个物体类.
Dataset combination with WordTree. We can use WordTree to combine multiple datasets together in a sensible fashion. We simply map the categories in the datasets to synsets in the tree. Figure 6 shows an example of using WordTree to combine the labels from ImageNet and COCO. WordNet is extremely diverse so we can use this technique with most datasets.
** 数据集与 WordTree**. 我们可以使用WordTree将多个数据集以合理的方式组合在一起. 我们只是将数据集中的类别映射到树上的合成。 图6显示了使用WordTree将ImageNet和COCO的标签组合起来的例子. WordNet极其多样,因此我们可以用大多数数据集来使用这一技术.
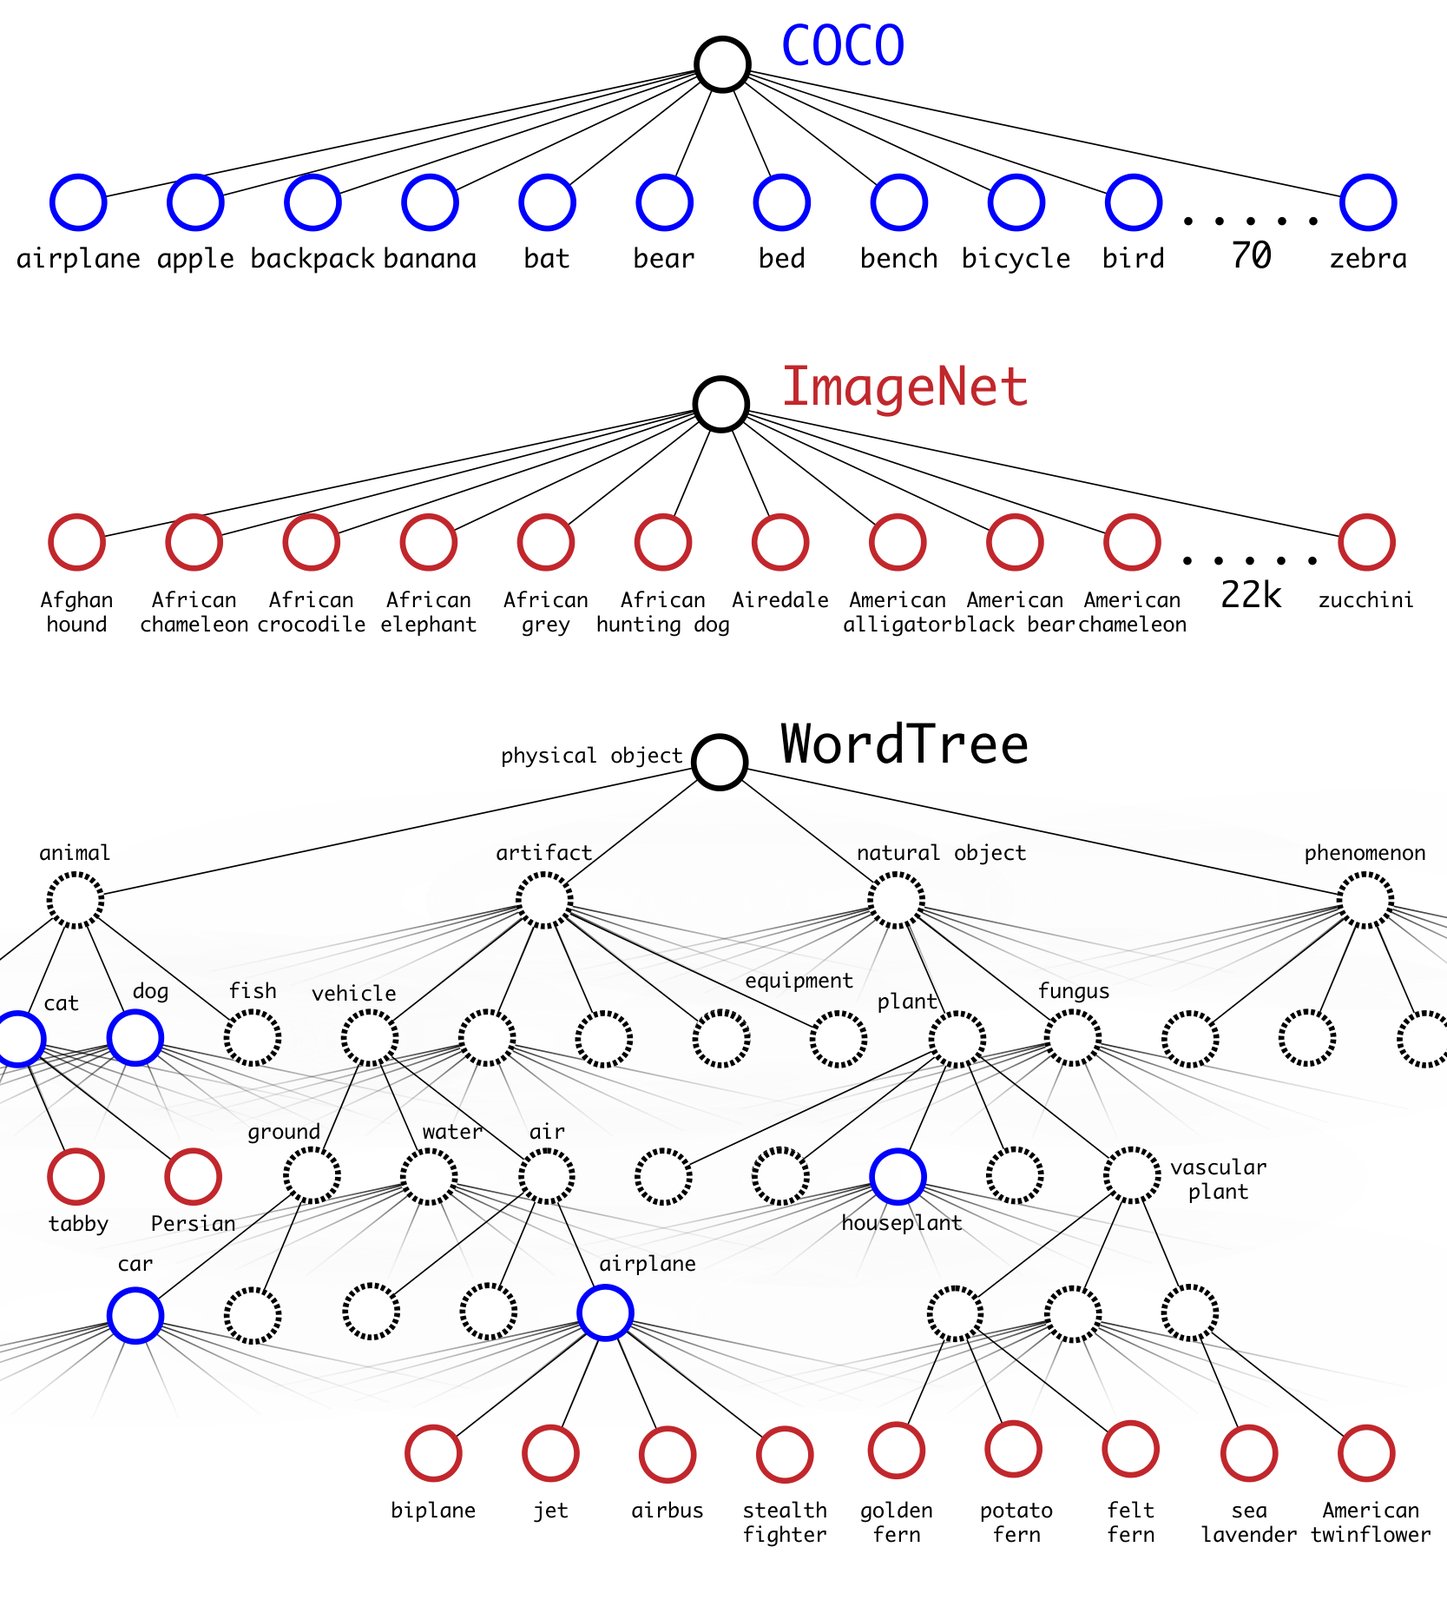
Figure 6: Combining datasets using WordTree hierarchy. Using the WordNet concept graph we build a hierarchical tree of visual concepts. Then we can merge datasets together by mapping the classes in the dataset to synsets in the tree. This is a simplified view of WordTree for illustration purposes.
图6:**使用WordTree分级组合数据集. 使用WordNet概念图,我们构建了视觉概念的层次树. 然后,我们可以通过将数据集中的分类映射到树上的合成来合并数据集. 这是用于插图目的WordTree的简化视图。 **
Joint classification and detection. Now that we can combine datasets using WordTree we can train our joint model on classification and detection. We want to train an extremely large scale detector so we create our combined dataset using the COCO detection dataset and the top 9000 classes from the full ImageNet release. We also need to evaluate our method so we add in any classes from the ImageNet detection challenge that were not already included. The corresponding WordTree for this dataset has 9418 classes. ImageNet is a much larger dataset so we balance the dataset by oversampling COCO so that ImageNet is only larger by a factor of 4:1.
** 联合分类和检测。 ** 现在我们可以用WordTree来合并数据集 我们可以在分类和检测方面训练我们的联合模型. 我们想要训练一个超大尺度的探测器 所以我们用COCO探测数据集 和从ImageNet全版发布的9000类数据来创建我们的综合数据集。 我们还需要评估我们的方法,以便从ImageNet检测挑战中增加尚未包括的类别。 本数据集对应的WordTree有9418类. ImageNet是一个大得多的数据集,所以我们通过对COCO的过度抽样来平衡数据集,这样ImageNet的大小只有4:1的系数.
Using this dataset we train YOLO9000. We use the base YOLOv2 architecture but only 3 priors instead of 5 to limit the output size. When our network sees a detection image we backpropagate loss as normal. For classification loss, we only backpropagate loss at or above the corresponding level of the label. For example, if the label is “dog” we do assign any error to predictions further down in the tree, “German Shepherd” versus “Golden Retriever”, because we do not have that information.
使用这个数据集 我们训练YOLO9000。 我们使用基础的YOLOv2架构,但只使用3个前缀而不是5来限制输出大小. 当我们的网络看到一个检测图像时, 我们背对损失是正常的。 对于分类损失,我们仅在标签的相应级别上或以上进行背推损失. 例如,如果标签是“狗”,我们确实将任何错误分配给在树上进一步下行的预测,即“德国谢泼德”与“黄金利弗”,因为我们没有这种信息。
When it sees a classification image we only backpropagate classification loss. To do this we simply find the bounding box that predicts the highest probability for that class and we compute the loss on just its predicted tree. We also assume that the predicted box overlaps what would be the ground truth label by at least IOU and we backpropagate objectness loss based on this assumption.
当它看到一个分类图像时,我们只会失去后支持分类。 要做到这一点,我们只是找到一个边框, 用来预测这一类中最高的概率, 我们计算出它所预测的树上的损失。 我们还假设,预测的盒子与至少 IOU的地面真象标签重叠,我们根据这一假设支持对象损失。
Using this joint training, YOLO9000 learns to find objects in images using the detection data in COCO and it learns to classify a wide variety of these objects using data from ImageNet.
通过这种联合训练,YOLO9000学习了利用COCO中的检测数据在图像中找到物体,它学习了利用ImageNet的数据对多种多样的这些物体进行分类.
We evaluate YOLO9000 on the ImageNet detection task. The detection task for ImageNet shares on 44 object categories with COCO which means that YOLO9000 has only seen classification data for the majority of the test images, not detection data. YOLO9000 gets 19.7 mAP overall with 16.0 mAP on the disjoint 156 object classes that it has never seen any labelled detection data for. This mAP is higher than results achieved by DPM but YOLO9000 is trained on different datasets with only partial supervision [4]. It also is simultaneously detecting 9000 other object categories, all in real-time.
我们对YOLO9000进行图像网检测任务的评价. ImageNet的检测任务与COCO共享44个对象类别,这意味着YOLO9000只看到了大多数测试图像的分类数据,而不是检测数据. YOLO9000获得19.7 mAP的总和,与16.0 mAP在它从未见过任何标注的检测数据的无关联的156个对象类上. 这个mAP比DPM实现的结果要高,但是YOLO9000在不同的数据集上接受训练,只有部分监督[4]. 它还同时探测到9000个其它对象类别,都是实时的.
| diaper | 0.0 |
|---|---|
| horizontal bar | 0.0 |
| rubber eraser | 0.0 |
| sunglasses | 0.0 |
| swimming trunks | 0.0 |
| … | |
| red panda | 50.7 |
| fox | 52.1 |
| koala bear | 54.3 |
| tiger | 61.0 |
| armadillo | 61.7 |
Table 7: YOLO9000 Best and Worst Classes on ImageNet. The classes with the highest and lowest AP from the 156 weakly supervised classes. YOLO9000 learns good models for a variety of animals but struggles with new classes like clothing or equipment.
| 尿布 | 0.0 |
|---|---|
| 水平栏 | 0.0 |
| 橡胶擦除器 | 0.0 |
| 太阳镜 | 0.0 |
| 提出的申诉 | 0.0 |
| . 尔时. | |
| 红熊猫向妇女提供的 | 50.7 |
| 狐狸队 | 52.1 |
| 科拉熊鱼 | 54.3 |
| 老虎 老虎 老虎 | 61.0 |
| 阿尔马迪略 | 61.7 |
表7:YOLO9000 在ImageNet上最佳和最差等级. 由156个受弱监管的班级中拥有最高和最低AP的班级. YOLO9000为各种动物学习了良好的模型,但与衣物或设备等新阶级挣扎着.
When we analyze YOLO9000’s performance on ImageNet we see it learns new species of animals well but struggles with learning categories like clothing and equipment. New animals are easier to learn because the objectness predictions generalize well from the animals in COCO. Conversely, COCO does not have bounding box label for any type of clothing, only for person, so YOLO9000 struggles to model categories like “sunglasses” or “swimming trunks”.
我们分析YOLO9000在ImageNet上的表现时, 新的动物更容易学习,因为对象预测从COCO中的动物中可以很好地概括. 反之,COCO没有任何类型的服装的边框标签,只针对个人,因此YOLO9000在模拟诸如“日光镜”或“闪烁的树干”等类别方面挣扎。
5 Conclusion
5 结论
We introduce YOLOv2 and YOLO9000, real-time detection systems. YOLOv2 is state-of-the-art and faster than other detection systems across a variety of detection datasets. Furthermore, it can be run at a variety of image sizes to provide a smooth tradeoff between speed and accuracy.
引进YOLOv2和YOLO9000,实时检测系统. YOLOv2是最新技术,并且比跨越各种检测数据集的其他检测系统更快. 此外,它可以以各种图像大小运行,以便在速度和准确性之间提供平稳的权衡。
YOLO9000 is a real-time framework for detection more than 9000 object categories by jointly optimizing detection and classification. We use WordTree to combine data from various sources and our joint optimization technique to train simultaneously on ImageNet and COCO. YOLO9000 is a strong step towards closing the dataset size gap between detection and classification.
YOLO9000是一个通过共同优化检测和分类检测超过9000个对象类别的实时框架. 我们利用WordTree将来自各种来源的数据和我们的联合优化技术结合起来,同时在ImageNet和COCO上训练. YOLO9000是缩小检测和分类之间数据集尺寸差距的有力步骤.
Many of our techniques generalize outside of object detection. Our WordTree representation of ImageNet offers a richer, more detailed output space for image classification. Dataset combination using hierarchical classification would be useful in the classification and segmentation domains. Training techniques like multi-scale training could provide benefit across a variety of visual tasks.
我们的很多技术 一般在物体检测之外。 我们WordTree对ImageNet的表示为图像分类提供了更加丰富,更加详细的输出空间. 采用分级分类法的数据集组合在分类和分区领域将是有益的。 多种规模训练等训练技术可为各种视觉工作提供益处。
For future work we hope to use similar techniques for weakly supervised image segmentation. We also plan to improve our detection results using more powerful matching strategies for assigning weak labels to classification data during training. Computer vision is blessed with an enormous amount of labelled data. We will continue looking for ways to bring different sources and structures of data together to make stronger models of the visual world.
对于今后的工作,我们希望采用类似的技术来进行监督不力的图像分割。 我们还计划改进检测结果,利用更强大的匹配战略,在训练期间为分类数据分配薄弱的标签。 计算机视觉被大量的标注数据所祝福. 我们将继续寻找方法,将不同的数据来源和结构汇集在一起,使视觉世界成为更强大的模型。
References
参考文献
[1] S. Bell, C. L. Zitnick, K. Bala, and R. Girshick. Inside-outside net: Detecting objects in context with skip pooling and recurrent neural networks. arXiv preprint arXiv:1512.04143 , 2015.
[2] J. Deng, W. Dong, R. Socher, L.-J. Li, K. Li, and L. Fei-Fei. Imagenet: A large-scale hierarchical image database. In Computer Vision and Pattern Recognition, 2009. CVPR 2009. IEEE Conference on , pages 248–255. IEEE, 2009.
[3] M. Everingham, L. Van Gool, C. K. Williams, J. Winn, and A. Zisserman. The pascal visual object classes (voc) challenge. International journal of computer vision , 88(2):303–338, 2010.
[4] P. F. Felzenszwalb, R. B. Girshick, and D. McAllester. Discriminatively trained deformable part models, release 4. http://people.cs.uchicago.edu/ pff/latent-release4/.
[5] R. B. Girshick. Fast R-CNN. CoRR , abs/1504.08083, 2015.
[6] K. He, X. Zhang, S. Ren, and J. Sun. Deep residual learning for image recognition. arXiv preprint arXiv:1512.03385 , 2015.
[7] S. Ioffe and C. Szegedy. Batch normalization: Accelerating deep network training by reducing internal covariate shift. arXiv preprint arXiv:1502.03167 , 2015.
[8] A. Krizhevsky, I. Sutskever, and G. E. Hinton. Imagenet classification with deep convolutional neural networks. In Advances in neural information processing systems , pages 1097–1105, 2012.
[9] M. Lin, Q. Chen, and S. Yan. Network in network. arXiv preprint arXiv:1312.4400 , 2013.
[10] T.-Y. Lin, M. Maire, S. Belongie, J. Hays, P. Perona, D. Ramanan, P. Dollár, and C. L. Zitnick. Microsoft coco: Common objects in context. In European Conference on Computer Vision , pages 740–755. Springer, 2014.
[11] W. Liu, D. Anguelov, D. Erhan, C. Szegedy, and S. E. Reed. SSD: single shot multibox detector. CoRR , abs/1512.02325, 2015.
[12] G. A. Miller, R. Beckwith, C. Fellbaum, D. Gross, and K. J. Miller. Introduction to wordnet: An on-line lexical database. International journal of lexicography , 3(4):235–244, 1990.
[13] J. Redmon. Darknet: Open source neural networks in c. http://pjreddie.com/darknet/ , 2013–2016.
[14] J. Redmon, S. Divvala, R. Girshick, and A. Farhadi. You only look once: Unified, real-time object detection. arXiv preprint arXiv:1506.02640 , 2015.
[15] S. Ren, K. He, R. Girshick, and J. Sun. Faster r-cnn: Towards real-time object detection with region proposal networks. arXiv preprint arXiv:1506.01497 , 2015.
[16] O. Russakovsky, J. Deng, H. Su, J. Krause, S. Satheesh, S. Ma, Z. Huang, A. Karpathy, A. Khosla, M. Bernstein, A. C. Berg, and L. Fei-Fei. ImageNet Large Scale Visual Recognition Challenge. International Journal of Computer Vision (IJCV) , 2015.
[17] K. Simonyan and A. Zisserman. Very deep convolutional networks for large-scale image recognition. arXiv preprint arXiv:1409.1556 , 2014.
[18] C. Szegedy, S. Ioffe, and V. Vanhoucke. Inception-v4, inception-resnet and the impact of residual connections on learning. CoRR , abs/1602.07261, 2016.
[19] C. Szegedy, W. Liu, Y. Jia, P. Sermanet, S. Reed, D. Anguelov, D. Erhan, V. Vanhoucke, and A. Rabinovich. Going deeper with convolutions. CoRR , abs/1409.4842, 2014.
[20] B. Thomee, D. A. Shamma, G. Friedland, B. Elizalde, K. Ni, D. Poland, D. Borth, and L.-J. Li. Yfcc100m: The new data in multimedia research. Communications of the ACM , 59(2):64–73, 2016.