XLNet: Generalized Autoregressive Pretraining for Language Understanding
*[inlinelist,1]label=(),
XLNet: Generalized Autoregressive Pretraining for Language Understanding
XLNet:面向语言理解的广义自回归预训练
Zhilin Yang Zihang Dai Yiming Yang Affiliation: Carnegie Mellon University Jaime Carbonell Affiliation: Carnegie Mellon University Ruslan Salakhutdinov, Quoc V. Le Affiliation: Carnegie Mellon University Affiliation: Google AI Brain Team {zhiliny,dzihang,yiming,jgc,rsalakhu}@cs.cmu.edu, qvl@google.com
Abstract
摘要
With the capability of modeling bidirectional contexts, denoising autoencoding based pretraining like BERT achieves better performance than pretraining approaches based on autoregressive language modeling. However, relying on corrupting the input with masks, BERT neglects dependency between the masked positions and suffers from a pretrain-finetune discrepancy. In light of these pros and cons, we propose XLNet, a generalized autoregressive pretraining method that (1) enables learning bidirectional contexts by maximizing the expected likelihood over all permutations of the factorization order and (2) overcomes the limitations of BERT thanks to its autoregressive formulation. Furthermore, XLNet integrates ideas from Transformer-XL, the state-of-the-art autoregressive model, into pretraining. Empirically, under comparable experiment settings, XLNet outperforms BERT on 20 tasks, often by a large margin, including question answering, natural language inference, sentiment analysis, and document ranking.[^1].
借助双向上下文建模能力,像 BERT 这类基于去噪自编码的预训练,整体上优于基于自回归语言建模的预训练。但 BERT 靠掩码破坏输入,既忽略被掩位置之间的依赖,又带来预训练与微调不一致。权衡利弊之后,我们提出 XLNet:一种广义自回归预训练方法,它(1)通过对分解顺序全部排列求期望似然,学到双向上下文;(2)凭借自回归形式避开 BERT 的上述局限。此外,XLNet 把当前最强自回归模型 Transformer-XL 的想法融入预训练。实验上,在可比设定下,XLNet 在 20 项任务上超过 BERT,且往往拉开明显差距,覆盖问答、自然语言推理、情感分析与文档排序等。[^1]。
1 Introduction
1 引言
Unsupervised representation learning has been highly successful in the domain of natural language processing [7, 22, 27, 28, 10]. Typically, these methods first pretrain neural networks on large-scale unlabeled text corpora, and then finetune the models or representations on downstream tasks. Under this shared high-level idea, different unsupervised pretraining objectives have been explored in literature. Among them, autoregressive (AR) language modeling and autoencoding (AE) have been the two most successful pretraining objectives.
无监督表示学习在自然语言处理领域取得了很大成功[7, 22, 27, 28, 10]。这类方法通常先在大规模无标注文本上预训练神经网络,再在下游任务上微调模型或表示。在这一共同思路下,文献探索了多种无监督预训练目标;其中最成功的两类是自回归(AR)语言建模与自编码(AE)。
AR language modeling seeks to estimate the probability distribution of a text corpus with an autoregressive model [7, 27, 28]. Specifically, given a text sequence , AR language modeling factorizes the likelihood into a forward product or a backward one . A parametric model (e.g. a neural network) is trained to model each conditional distribution. Since an AR language model is only trained to encode a uni-directional context (either forward or backward), it is not effective at modeling deep bidirectional contexts. On the contrary, downstream language understanding tasks often require bidirectional context information. This results in a gap between AR language modeling and effective pretraining.
自回归语言建模用自回归模型估计文本语料的概率分布[7, 27, 28]。给定文本序列 ,它把似然分解成前向乘积 ,或后向乘积 ,再用参数模型(如神经网络)拟合每个条件分布。由于 AR 语言模型只学单向上下文(前向或后向),难以刻画深层双向依赖;而下游语言理解任务往往需要双向信息,于是 AR 语言建模与有效预训练之间出现了缺口。
In comparison, AE based pretraining does not perform explicit density estimation but instead aims to reconstruct the original data from corrupted input. A notable example is BERT [10], which has been the state-of-the-art pretraining approach. Given the input token sequence, a certain portion of tokens are replaced by a special symbol [MASK], and the model is trained to recover the original tokens from the corrupted version. Since density estimation is not part of the objective, BERT is allowed to utilize bidirectional contexts for reconstruction. As an immediate benefit, this closes the aforementioned bidirectional information gap in AR language modeling, leading to improved performance. However, the artificial symbols like [MASK] used by BERT during pretraining are absent from real data at finetuning time, resulting in a pretrain-finetune discrepancy. Moreover, since the predicted tokens are masked in the input, BERT is not able to model the joint probability using the product rule as in AR language modeling. In other words, BERT assumes the predicted tokens are independent of each other given the unmasked tokens, which is oversimplified as high-order, long-range dependency is prevalent in natural language [9].
相比之下,基于 AE 的预训练并不显式做密度估计,而是从被破坏的输入重建原始数据。代表性例子是 BERT [10],一度是最强预训练方案。给定输入词元序列后,一部分词元被换成特殊符号 [MASK],模型要从损坏版本恢复原词元。由于目标里不含密度估计,BERT 可以用双向上下文做重建,从而弥补 AR 语言建模的双向信息缺口,表现更好。但预训练里的 [MASK] 一类人工符号在微调真实数据中并不出现,造成预训练–微调不一致。再者,被预测的词元在输入里已被掩掉,BERT 无法像 AR 那样用乘法法则分解联合概率,亦即在给定未掩词元时假设被预测词元彼此独立——对自然语言中普遍的高阶、长程依赖而言,这过于简化 [9]。
Faced with the pros and cons of existing language pretraining objectives, in this work, we propose XLNet, a generalized autoregressive method that leverages the best of both AR language modeling and AE while avoiding their limitations.
面对现有语言预训练目标的优劣,本文提出 XLNet:一种广义自回归方法,尽量兼取 AR 与 AE 之长,同时避开二者的短板。
- • Firstly, instead of using a fixed forward or backward factorization order as in conventional AR models, XLNet maximizes the expected log likelihood of a sequence w.r.t. all possible permutations of the factorization order. Thanks to the permutation operation, the context for each position can consist of tokens from both left and right. In expectation, each position learns to utilize contextual information from all positions, i.e., capturing bidirectional context.
- • Secondly, as a generalized AR language model, XLNet does not rely on data corruption. Hence, XLNet does not suffer from the pretrain-finetune discrepancy that BERT is subject to. Meanwhile, the autoregressive objective also provides a natural way to use the product rule for factorizing the joint probability of the predicted tokens, eliminating the independence assumption made in BERT.
- • 第一,XLNet 不像常规 AR 模型固定前向或后向分解顺序,而是对序列在全部可能的分解顺序排列上最大化期望对数似然。借助排列,每个位置的上下文可以同时来自左右两侧;期望意义下,每个位置都会学会利用所有位置的信息,从而捕获双向上下文。
- • 第二,作为广义 AR 语言模型,XLNet 不依赖数据破坏,因而不会遭受 BERT 那种预训练–微调不一致。同时,自回归目标天然可用乘法法则分解被预测词元的联合概率,消除了 BERT 中的独立性假设。
In addition to a novel pretraining objective, XLNet improves architectural designs for pretraining.
除了新的预训练目标,XLNet 还改进了预训练的结构设计。
- • Inspired by the latest advancements in AR language modeling, XLNet integrates the segment recurrence mechanism and relative encoding scheme of Transformer-XL [9] into pretraining, which empirically improves the performance especially for tasks involving a longer text sequence.
- • Naively applying a Transformer(-XL) architecture to permutation-based language modeling does not work because the factorization order is arbitrary and the target is ambiguous. As a solution, we propose to reparameterize the Transformer(-XL) network to remove the ambiguity.
- • 受 AR 语言建模最新进展启发,XLNet 把 Transformer-XL [9] 的片段循环机制与相对编码方案融入预训练;经验上,这对涉及更长文本序列的任务尤其有帮助。
- • 若把 Transformer(或 Transformer-XL)结构天真地套到基于排列的语言建模上,会因分解顺序任意、目标位置含糊而失效。为此,我们提出对 Transformer(-XL)网络重新参数化,以消除歧义。
Empirically, under comparable experiment setting, XLNet consistently outperforms BERT [10] on a wide spectrum of problems including GLUE language understanding tasks, reading comprehension tasks like SQuAD and RACE, text classification tasks such as Yelp and IMDB, and the ClueWeb09-B document ranking task.
实验上,在可比设定下,XLNet 在广泛问题上持续优于 BERT [10],包括 GLUE 语言理解、SQuAD 与 RACE 等阅读理解、Yelp 与 IMDB 等文本分类,以及 ClueWeb09-B 文档排序。
Related Work The idea of permutation-based AR modeling has been explored in [32, 12], but there are several key differences. Firstly, previous models aim to improve density estimation by baking an “orderless” inductive bias into the model while XLNet is motivated by enabling AR language models to learn bidirectional contexts. Technically, to construct a valid target-aware prediction distribution, XLNet incorporates the target position into the hidden state via two-stream attention while previous permutation-based AR models relied on implicit position awareness inherent to their MLP architectures. Finally, for both orderless NADE and XLNet, we would like to emphasize that “orderless” does not mean that the input sequence can be randomly permuted but that the model allows for different factorization orders of the distribution.
相关工作 基于排列的 AR 建模曾在 [32, 12] 中出现,但有几处关键差异。其一,先前工作多为把「无序」归纳偏置写进模型以改进密度估计,而 XLNet 的动机是让 AR 语言模型学会双向上下文。技术上,为构造有效的目标感知预测分布,XLNet 用双流注意力把目标位置写入隐状态;先前基于排列的 AR 模型则依赖 MLP 结构固有的隐式位置感知。最后,对无序 NADE 与 XLNet,需要强调:「无序」并不是说可以把输入序列随机打乱,而是说模型允许对分布采用不同的分解顺序。
Another related idea is to perform autoregressive denoising in the context of text generation [11], which only considers a fixed order though.
另一相关思路是在文本生成场景做自回归去噪 [11],不过它只考虑固定顺序。
2 Proposed Method
2 方法
2.1 Background
2.1 背景
In this section, we first review and compare the conventional AR language modeling and BERT for language pretraining. Given a text sequence , AR language modeling performs pretraining by maximizing the likelihood under the forward autoregressive factorization:
本节先回顾并比较常规 AR 语言建模与 BERT 在语言预训练中的做法。给定文本序列 ,AR 语言建模通过最大化前向自回归分解下的似然来预训练:
where is a context representation produced by neural models, such as RNNs or Transformers, and denotes the embedding of . In comparison, BERT is based on denoising auto-encoding. Specifically, for a text sequence , BERT first constructs a corrupted version by randomly setting a portion (e.g. 15%) of tokens in to a special symbol [MASK]. Let the masked tokens be . The training objective is to reconstruct from :
其中 是由 RNN 或 Transformer 等神经模型得到的上下文表示, 表示 的嵌入。相比之下,BERT 基于去噪自编码。对文本序列 ,BERT 先随机把一部分(如 15%)词元换成特殊符号 [MASK],得到损坏版 ;记被掩词元为 。训练目标是从 重建 :
where indicates is masked, and is a Transformer that maps a length- text sequence into a sequence of hidden vectors . The pros and cons of the two pretraining objectives are compared in the following aspects:
其中 表示 被掩码, 是把长度 的文本序列 映成隐向量序列 的 Transformer。两类预训练目标可从以下几方面对比:
- • Independence Assumption: As emphasized by the sign in Eq. (2), BERT factorizes the joint conditional probability based on an independence assumption that all masked tokens are separately reconstructed. In comparison, the AR language modeling objective (1) factorizes using the product rule that holds universally without such an independence assumption.
- • Input noise: The input to BERT contains artificial symbols like [MASK] that never occur in downstream tasks, which creates a pretrain-finetune discrepancy. Replacing [MASK] with original tokens as in [10] does not solve the problem because original tokens can be only used with a small probability — otherwise Eq. (2) will be trivial to optimize. In comparison, AR language modeling does not rely on any input corruption and does not suffer from this issue.
- • Context dependency: The AR representation is only conditioned on the tokens up to position (i.e. tokens to the left), while the BERT representation has access to the contextual information on both sides. As a result, the BERT objective allows the model to be pretrained to better capture bidirectional context.
- • 独立性假设:如式 (2) 中 所强调,BERT 在「各被掩词元 分别重建」的独立性假设下分解联合条件概率 。相比之下,AR 语言建模目标 (1) 用普遍成立的乘法法则分解 ,无需该假设。
- • 输入噪声:BERT 的输入含下游任务中不会出现的 [MASK] 等人工符号,造成预训练–微调不一致。像 [10] 那样偶尔用原词元替换 [MASK] 并不能真正解决问题,因为原词元只能以很小概率使用——否则式 (2) 会变得极易优化。AR 语言建模不依赖任何输入破坏,因而没有这一问题。
- • 上下文依赖:AR 表示 只条件于位置 之前的词元(左侧),而 BERT 表示 可同时看到两侧上下文。因此 BERT 目标更利于预训练捕获双向上下文。
2.2 Objective: Permutation Language Modeling
2.2 目标:排列语言模型
According to the comparison above, AR language modeling and BERT possess their unique advantages over the other. A natural question to ask is whether there exists a pretraining objective that brings the advantages of both while avoiding their weaknesses.
由上可见,AR 语言建模与 BERT 各有对方不具备的优势。自然要问:是否存在一种预训练目标,能兼取二者之长、又避开各自的弱点?
Borrowing ideas from orderless NADE [32], we propose the permutation language modeling objective that not only retains the benefits of AR models but also allows models to capture bidirectional contexts. Specifically, for a sequence of length , there are different orders to perform a valid autoregressive factorization. Intuitively, if model parameters are shared across all factorization orders, in expectation, the model will learn to gather information from all positions on both sides.
借鉴无序 NADE [32] 的想法,我们提出排列语言建模目标:既保留 AR 模型的好处,又让模型捕获双向上下文。具体地,对长度 的序列 ,合法的自回归分解共有 种顺序。直观上,若所有分解顺序共享同一组模型参数,则期望意义下模型会学会从两侧所有位置收集信息。
To formalize the idea, let be the set of all possible permutations of the length- index sequence . We use and to denote the -th element and the first elements of a permutation . Then, our proposed permutation language modeling objective can be expressed as follows:
形式化地,令 为长度 的下标序列 的全部排列集合。对排列 ,用 与 分别表示其第 个元素与前 个元素。则提出的排列语言建模目标可写为:
Essentially, for a text sequence , we sample a factorization order at a time and decompose the likelihood according to factorization order. Since the same model parameter is shared across all factorization orders during training, in expectation, has seen every possible element in the sequence, hence being able to capture the bidirectional context. Moreover, as this objective fits into the AR framework, it naturally avoids the independence assumption and the pretrain-finetune discrepancy discussed in Section 2.1.
本质上,对文本序列 ,我们每次采样一个分解顺序 ,并按该顺序分解似然 。由于训练中所有分解顺序共享同一参数 ,期望上 会见到序列中每一个 ,从而能捕获双向上下文。同时,该目标落在 AR 框架内,自然避开了第 2.1 节讨论的独立性假设与预训练–微调不一致。
Remark on Permutation The proposed objective only permutes the factorization order, not the sequence order. In other words, we keep the original sequence order, use the positional encodings corresponding to the original sequence, and rely on a proper attention mask in Transformers to achieve permutation of the factorization order. Note that this choice is necessary, since the model will only encounter text sequences with the natural order during finetuning.
关于排列的说明 所提目标只排列分解顺序,并不打乱序列顺序。换言之,我们保持原始序列顺序,使用对应原始位置的位置编码,并依靠 Transformer 中恰当的注意力掩码来实现分解顺序的排列。这一点是必要的,因为微调时模型只会遇到自然顺序的文本序列。
To provide an overall picture, we show an example of predicting the token given the same input sequence but under different factorization orders in the Appendix A.7 with Figure 4.
为给出整体图景,附录 A.7 的图 4 展示了在同一输入序列 、不同分解顺序下预测词元 的例子。
2.3 Architecture: Two-Stream Self-Attention for Target-Aware Representations
2.3 结构:面向目标表示的双流自注意力
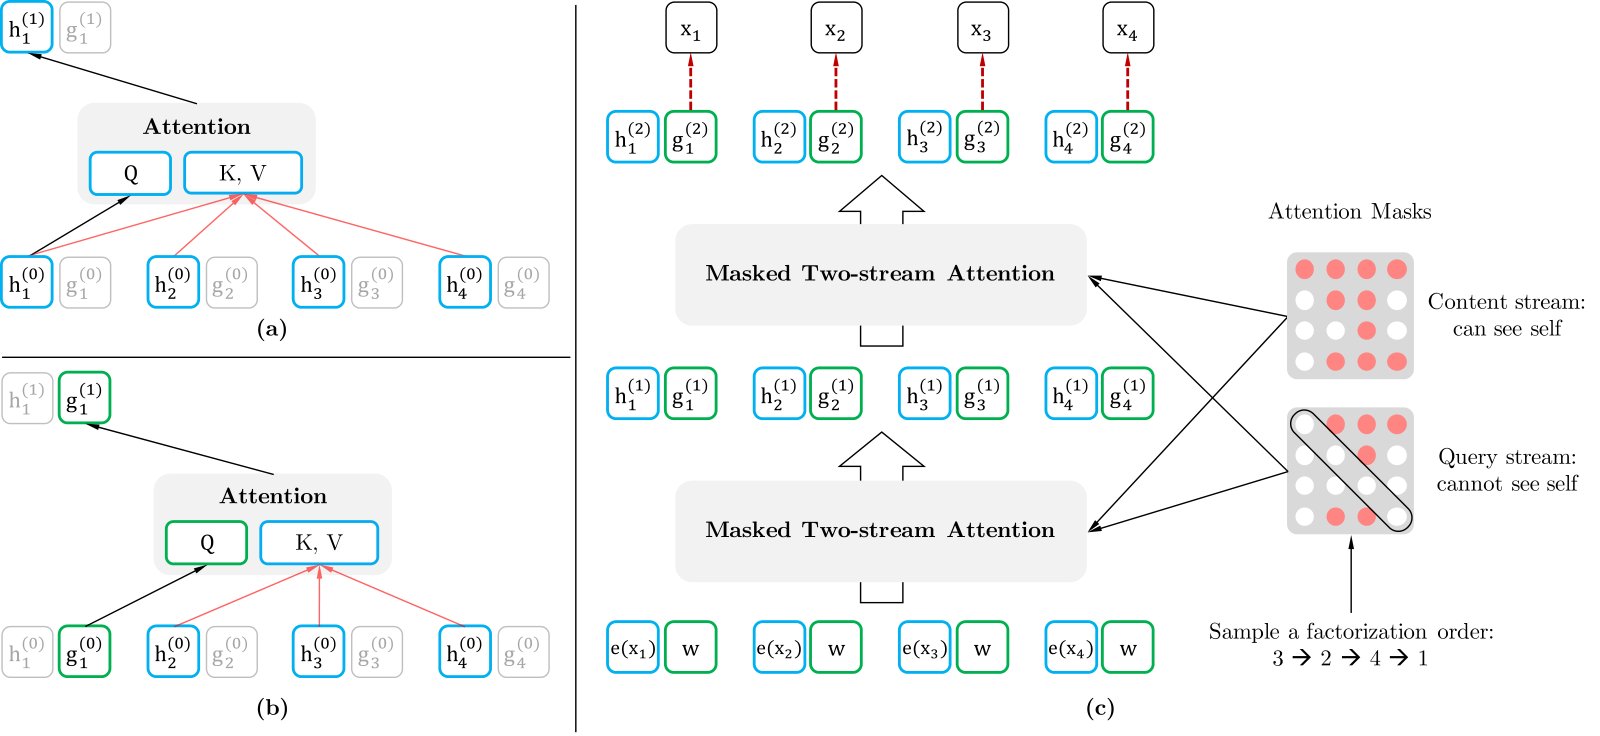
Figure 1: (a): Content stream attention, which is the same as the standard self-attention. (b): Query stream attention, which does not have access information about the content . (c): Overview of the permutation language modeling training with two-stream attention.
图 1:(a) 内容流注意力,与标准自注意力相同。(b) 查询流注意力,无法访问内容 的信息。(c) 带双流注意力的排列语言建模训练总览。
While the permutation language modeling objective has desired properties, naive implementation with standard Transformer parameterization may not work. To see the problem, assume we parameterize the next-token distribution using the standard Softmax formulation, i.e., where denotes the hidden representation of produced by the shared Transformer network after proper masking. Now notice that the representation does not depend on which position it will predict, i.e., the value of . Consequently, the same distribution is predicted regardless of the target position, which is not able to learn useful representations (see Appendix A.1 for a concrete example). To avoid this problem, we propose to re-parameterize the next-token distribution to be target position aware:
尽管排列语言建模目标性质良好,用标准 Transformer 参数化天真实现可能行不通。看问题所在:假设用标准 Softmax 参数化下一词元分布 ,即 ,其中 是共享 Transformer 网络在恰当掩码后得到的 隐表示。注意该表示并不依赖将要预测的位置,即 的取值;于是不论目标位置为何,预测的都是同一分布,无法学到有用表示(附录 A.1 给了具体例子)。为避免这一问题,我们把下一词元分布重新参数化为目标位置感知的形式:
where denotes a new type of representations which additionally take the target position as input.
其中 表示一类新表示,额外把目标位置 作为输入。
Two-Stream Self-Attention While the idea of target-aware representations removes the ambiguity in target prediction, how to formulate remains a non-trivial problem. Among other possibilities, we propose to “stand” at the target position and rely on the position to gather information from the context through attention. For this parameterization to work, there are two requirements that are contradictory in a standard Transformer architecture: (1) to predict the token , should only use the *position* and not the *content* , otherwise the objective becomes trivial; (2) to predict the other tokens with , should also encode the content to provide full contextual information. To resolve such a contradiction, we propose to use two sets of hidden representations instead of one:
双流自注意力 目标感知表示消除了目标预测的歧义,但如何构造 仍非显然。在多种可能中,我们提出「站在」目标位置 ,依靠位置 通过注意力从上下文 收集信息。要使该参数化成立,标准 Transformer 结构里有两个相互矛盾的要求:(1) 预测词元 时, 只能使用*位置* ,不能使用*内容* ,否则目标会变得平凡;(2) 预测 的其他词元 时, 又应编码内容 ,以提供完整上下文。为化解矛盾,我们改用两套隐表示,而非一套:
- • The content representation , or abbreviated as , which serves a similar role to the standard hidden states in Transformer. This representation encodes both the context and itself.
- • The query representation , or abbreviated as , which only has access to the contextual information and the position , but not the content , as discussed above.
- • 内容表示 ,简记 ,作用类似 Transformer 中的标准隐状态,同时编码上下文与 本身。
- • 查询表示 ,简记 ,如上所述,只能访问上下文信息 与位置 ,不能访问内容 。
Computationally, the first layer query stream is initialized with a trainable vector, i.e. , while the content stream is set to the corresponding word embedding, i.e. . For each self-attention layer , the two streams of representations are schematically[^2] updated with a shared set of parameters as follows (illustrated in Figures 1 (a) and (b)):
计算上,第一层查询流初始化为可训练向量,即 ;内容流设为对应词嵌入,即 。对每个自注意力层 ,两套表示用共享参数*示意性地[^2]*按如下更新(见图 1 (a)(b)):
\displaystyle\small g_{z_{t}}^{(m)} \\ \displaystyle\leftarrow\text{Attention}(\text{Q}=g_{z_{t}}^{(m-1)},\text{KV}={\mathbf{h}}_{{\color[rgb]{1,0,1}{\mathbf{z}}_{<t}}}^{(m-1)};\theta), \\ \displaystyle(\text{query stream: use $z_{t}$ but cannot see $x_{z_{t}}$}) \\ \displaystyle h_{z_{t}}^{(m)} \\ \displaystyle\leftarrow\text{Attention}(\text{Q}=h_{z_{t}}^{(m-1)},\text{KV}={\mathbf{h}}_{{\color[rgb]{1,0,1}{\mathbf{z}}_{\leq t}}}^{(m-1)};\theta), \\ \displaystyle(\text{content stream: use both $z_{t}$ and $x_{z_{t}}$}).
where Q, K, V denote the query, key, and value in an attention operation [33]. The update rule of the content representations is exactly the same as the standard self-attention, so during finetuning, we can simply drop the query stream and use the content stream as a normal Transformer(-XL). Finally, we can use the last-layer query representation to compute Eq. (4).
其中 Q、K、V 分别表示注意力中的查询、键与值 [33]。内容表示的更新规则与标准自注意力完全一致,因此微调时可以直接丢掉查询流,把内容流当普通 Transformer(-XL)使用。最后,用最后一层查询表示 计算式 (4)。
Partial Prediction While the permutation language modeling objective (3) has several benefits, it is a much more challenging optimization problem due to the permutation and causes slow convergence in preliminary experiments. To reduce the optimization difficulty, we choose to only predict the last tokens in a factorization order. Formally, we split into a non-target subsequence and a target subsequence , where is the cutting point. The objective is to maximize the log-likelihood of the target subsequence conditioned on the non-target subsequence, i.e.,
部分预测 排列语言建模目标 (3) 虽有多项好处,但因排列而使优化更难,初步实验中收敛偏慢。为降低优化难度,我们只预测分解顺序中靠后的词元。形式化地,把 切成非目标子序列 与目标子序列 ,其中 为切分点。目标是最大化条件于非目标子序列的目标子序列对数似然,即
Note that is chosen as the target because it possesses the longest context in the sequence given the current factorization order . A hyperparameter is used such that about tokens are selected for predictions; i.e., . For unselected tokens, their query representations need not be computed, which saves speed and memory.
注意选择 作为目标,是因为它在当前分解顺序 下拥有序列中最长的上下文。用超参数 使约 的词元被选为预测目标,即 。未选中的词元不必计算查询表示,从而节省速度与显存。
2.4 Incorporating Ideas from Transformer-XL
2.4 融入 Transformer-XL 的想法
Since our objective function fits in the AR framework, we incorporate the state-of-the-art AR language model, Transformer-XL [9], into our pretraining framework, and name our method after it. We integrate two important techniques in Transformer-XL, namely the relative positional encoding scheme and the segment recurrence mechanism. We apply relative positional encodings based on the original sequence as discussed earlier, which is straightforward. Now we discuss how to integrate the recurrence mechanism into the proposed permutation setting and enable the model to reuse hidden states from previous segments. Without loss of generality, suppose we have two segments taken from a long sequence ; i.e., and . Let and be permutations of and respectively. Then, based on the permutation , we process the first segment, and then cache the obtained content representations for each layer . Then, for the next segment , the attention update with memory can be written as
由于目标函数落在 AR 框架内,我们把当前最强 AR 语言模型 Transformer-XL [9] 纳入预训练框架,并以之命名本方法。我们融入 Transformer-XL 的两项重要技术:相对位置编码方案与片段循环机制。相对位置编码按前文所述基于原始序列施加,做法直接。下面讨论如何在所提排列设定下接入循环机制,使模型能复用先前片段的隐状态。不失一般性,设从长序列 取出两段,即 与 。令 与 分别为 与 的排列。先按 处理第一段,并缓存各层 得到的内容表示 。对下一段 ,带记忆的注意力更新可写为
where denotes concatenation along the sequence dimension. Notice that positional encodings only depend on the actual positions in the original sequence. Thus, the above attention update is independent of once the representations are obtained. This allows caching and reusing the memory without knowing the factorization order of the previous segment. In expectation, the model learns to utilize the memory over all factorization orders of the last segment. The query stream can be computed in the same way. Finally, Figure 1 (c) presents an overview of the proposed permutation language modeling with two-stream attention (see Appendix A.7 for more detailed illustration).
其中 表示沿序列维拼接。注意位置编码只依赖原始序列中的实际位置,因此一旦得到表示 ,上述注意力更新就与 无关。这样就可以在不知道前一段分解顺序的情况下缓存并复用记忆。期望上,模型会学会利用上一段所有分解顺序下的记忆。查询流可用同样方式计算。最后,图 1 (c) 给出带双流注意力的排列语言建模总览(更细的图示见附录 A.7)。
2.5 Modeling Multiple Segments
2.5 多段建模
Many downstream tasks have multiple input segments, e.g., a question and a context paragraph in question answering. We now discuss how we pretrain XLNet to model multiple segments in the autoregressive framework. During the pretraining phase, following BERT, we randomly sample two segments (either from the same context or not) and treat the concatenation of two segments as one sequence to perform permutation language modeling. We only reuse the memory that belongs to the same context. Specifically, the input to our model is the same as BERT: [CLS, A, SEP, B, SEP], where “SEP” and “CLS” are two special symbols and “A” and “B” are the two segments. Although we follow the two-segment data format, XLNet-Large does not use the objective of next sentence prediction [10] as it does not show consistent improvement in our ablation study (see Section 3.4).
许多下游任务有多个输入片段,例如问答中的问题与上下文段落。下面讨论如何在自回归框架下预训练 XLNet 以建模多段。预训练阶段仿照 BERT,随机采样两段(可来自同一上下文或否),把两段拼接成一条序列做排列语言建模。我们只复用属于同一上下文的记忆。具体地,模型输入与 BERT 相同:[CLS, A, SEP, B, SEP],其中 “SEP” 与 “CLS” 为特殊符号,“A”“B” 为两段。尽管沿用两段数据格式,XLNet-Large 并不使用下一句预测目标 [10],因为消融中它并未带来稳定收益(见第 3.4 节)。
Relative Segment Encodings Architecturally, different from BERT that adds an absolute segment embedding to the word embedding at each position, we extend the idea of relative encodings from Transformer-XL to also encode the segments. Given a pair of positions and in the sequence, if and are from the same segment, we use a segment encoding or otherwise , where and are learnable model parameters for each attention head. In other words, we only consider whether the two positions are within the same segment, as opposed to considering which specific segments they are from. This is consistent with the core idea of relative encodings; i.e., only modeling the relationships between positions. When attends to , the segment encoding is used to compute an attention weight , where is the query vector as in a standard attention operation and is a learnable head-specific bias vector. Finally, the value is added to the normal attention weight. There are two benefits of using relative segment encodings. First, the inductive bias of relative encodings improves generalization [9]. Second, it opens the possibility of finetuning on tasks that have more than two input segments, which is not possible using absolute segment encodings.
相对片段编码 结构上,不同于 BERT 在每个位置的词嵌入上叠加绝对片段嵌入,我们把 Transformer-XL 的相对编码想法推广到片段。对序列中一对位置 与 ,若二者来自同一片段,用片段编码 ,否则 ,其中 、 是每个注意力头可学习的参数。换言之,我们只关心两位置是否属于同一片段,而不关心它们分别来自哪一个具体片段。这与相对编码的核心一致:只建模位置之间的关系。当 对 做注意力时,用片段编码 计算注意力权重 ,其中 是标准注意力中的查询向量, 是头特定的可学习偏置;最后把 加到普通注意力权重上。相对片段编码有两点好处:其一,相对编码的归纳偏置有利于泛化 [9];其二,它为微调超过两段输入的任务打开可能,而绝对片段编码做不到。
2.6 Discussion
2.6 讨论
Comparing Eq. (2) and (5), we observe that both BERT and XLNet perform partial prediction, i.e., only predicting a subset of tokens in the sequence. This is a necessary choice for BERT because if all tokens are masked, it is impossible to make any meaningful predictions. In addition, for both BERT and XLNet, partial prediction plays a role of reducing optimization difficulty by only predicting tokens with sufficient context. However, the independence assumption discussed in Section 2.1 disables BERT to model dependency between targets.
比较式 (2) 与 (5) 可见,BERT 与 XLNet 都做部分预测,即只预测序列中的一部分词元。对 BERT 这是必要选择:若全部词元都被掩掉,就无法做出有意义的预测。此外,对二者而言,部分预测都通过只预测上下文足够的词元来降低优化难度。但第 2.1 节讨论的独立性假设使 BERT 无法建模目标之间的依赖。
To better understand the difference, let’s consider a concrete example [New, York, is, a, city]. Suppose both BERT and XLNet select the two tokens [New, York] as the prediction targets and maximize . Also suppose that XLNet samples the factorization order [is, a, city, New, York]. In this case, BERT and XLNet respectively reduce to the following objectives:
为更好理解差异,考虑具体例子 [New, York, is, a, city]。假设 BERT 与 XLNet 都选 [New, York] 两个词元作为预测目标,并最大化 ;再假设 XLNet 采样到分解顺序 [is, a, city, New, York]。此时二者分别化为:
\mathcal{J}_{\text{XLNet}}=\log p(\text{New}\mid\text{is a city})+\log p(\text{York}\mid{\color[rgb]{1,0,1}\text{New}},\text{is a city}).
Notice that XLNet is able to capture the dependency between the pair (New, York), which is omitted by BERT. Although in this example, BERT learns some dependency pairs such as (New, city) and (York, city), it is obvious that XLNet always learns more dependency pairs given the same target and contains “denser” effective training signals.
可见 XLNet 能捕获 (New, York) 这对依赖,而 BERT 略去了它。尽管本例中 BERT 也学到 (New, city)、(York, city) 等依赖对,但在相同目标下,XLNet 显然总能学到更多依赖对,训练信号也更「密」。
For more formal analysis and further discussion, please refer to Appendix A.5.
更形式的分析与进一步讨论见附录 A.5。
3 Experiments
3 实验
3.1 Pretraining and Implementation
3.1 预训练与实现
Following BERT [10], we use the BooksCorpus [40] and English Wikipedia as part of our pretraining data, which have 13GB plain text combined. In addition, we include Giga5 (16GB text) [26], ClueWeb 2012-B (extended from [5]), and Common Crawl [6] for pretraining. We use heuristics to aggressively filter out short or low-quality articles for ClueWeb 2012-B and Common Crawl, which results in 19GB and 110GB text respectively. After tokenization with SentencePiece [17], we obtain 2.78B, 1.09B, 4.75B, 4.30B, and 19.97B subword pieces for Wikipedia, BooksCorpus, Giga5, ClueWeb, and Common Crawl respectively, which are 32.89B in total.
仿照 BERT [10],预训练数据的一部分使用 BooksCorpus [40] 与英文维基百科,二者合计约 13GB 纯文本。此外还纳入 Giga5(16GB 文本)[26]、ClueWeb 2012-B(由 [5] 扩展)以及 Common Crawl [6]。对 ClueWeb 2012-B 与 Common Crawl,我们用启发式规则积极滤掉过短或低质文章,分别得到约 19GB 与 110GB 文本。用 SentencePiece [17] 分词后,维基、BooksCorpus、Giga5、ClueWeb、Common Crawl 分别得到 2.78B、1.09B、4.75B、4.30B、19.97B 个子词片段,合计 32.89B。
Our largest model XLNet-Large has the same architecture hyperparameters as BERT-Large, which results in a similar model size. During pretraining, we always use a full sequence length of 512. Firstly, to provide a fair comparison with BERT (section 3.2), we also trained XLNet-Large-wikibooks on BooksCorpus and Wikipedia only, where we reuse all pretraining hyper-parameters as in the original BERT. Then, we scale up the training of XLNet-Large by using all the datasets described above. Specifically, we train on 512 TPU v3 chips for 500K steps with an Adam weight decay optimizer, linear learning rate decay, and a batch size of 8192, which takes about 5.5 days. It was observed that the model still underfits the data at the end of training. Finally, we perform ablation study (section 3.4) based on the XLNet-Base-wikibooks.
最大模型 XLNet-Large 的结构超参与 BERT-Large 相同,因而模型规模相近。预训练时始终使用完整序列长度 512。首先,为与 BERT 公平对比(第 3.2 节),我们还只在 BooksCorpus 与维基上训练了 XLNet-Large-wikibooks,并复用原 BERT 的全部预训练超参。随后用上述全部数据放大训练 XLNet-Large:在 512 块 TPU v3 上训练 500K 步,采用 Adam 权重衰减优化器、线性学习率衰减、批大小 8192,约耗时 5.5 天。观察发现训练结束时模型仍对数据欠拟合。最后,消融(第 3.4 节)基于 XLNet-Base-wikibooks。
Since the recurrence mechanism is introduced, we use a bidirectional data input pipeline where each of the forward and backward directions takes half of the batch size. For training XLNet-Large, we set the partial prediction constant as 6 (see Section 1). Our finetuning procedure follows BERT [10] except otherwise specified[^3]. We employ an idea of span-based prediction, where we first sample a length , and then randomly select a consecutive span of tokens as prediction targets within a context of tokens.
由于引入了循环机制,我们使用双向数据输入管线,前向与后向各占一半批大小。训练 XLNet-Large 时,部分预测常数 取 6(见第 1 节)。微调流程除另有说明外均跟随 BERT [10][^3]。我们采用基于跨度的预测:先采样长度 ,再在长度为 的上下文中随机选取连续 个词元作为预测目标。
We use a variety of natural language understanding datasets to evaluate the performance of our method. Detailed descriptions of the settings for all the datasets can be found in Appendix A.3.
我们用多种自然语言理解数据集评估本方法。各数据集设定详见附录 A.3。
3.2 Fair Comparison with BERT
3.2 与 BERT 的公平对比
| Model | SQuAD1.1 | SQuAD2.0 | RACE | MNLI | QNLI | QQP | RTE | SST-2 | MRPC | CoLA | STS-B |
|---|---|---|---|---|---|---|---|---|---|---|---|
| BERT-Large (Best of 3) | 86.7/92.8 | 82.8/85.5 | 75.1 | 87.3 | 93.0 | 91.4 | 74.0 | 94.0 | 88.7 | 63.7 | 90.2 |
| XLNet-Large-wikibooks | 88.2/94.0 | 85.1/87.8 | 77.4 | 88.4 | 93.9 | 91.8 | 81.2 | 94.4 | 90.0 | 65.2 | 91.1 |
Table 1: Fair comparison with BERT. All models are trained using the same data and hyperparameters as in BERT. We use the best of 3 BERT variants for comparison; i.e., the original BERT, BERT with whole word masking, and BERT without next sentence prediction.
| Model | SQuAD1.1 | SQuAD2.0 | RACE | MNLI | QNLI | QQP | RTE | SST-2 | MRPC | CoLA | STS-B |
|---|---|---|---|---|---|---|---|---|---|---|---|
| BERT-Large (Best of 3) | 86.7/92.8 | 82.8/85.5 | 75.1 | 87.3 | 93.0 | 91.4 | 74.0 | 94.0 | 88.7 | 63.7 | 90.2 |
| XLNet-Large-wikibooks | 88.2/94.0 | 85.1/87.8 | 77.4 | 88.4 | 93.9 | 91.8 | 81.2 | 94.4 | 90.0 | 65.2 | 91.1 |
表 1:与 BERT 的公平对比。所有模型使用与 BERT 相同的数据与超参。对比取三种 BERT 变体中的最佳结果,即原版 BERT、整词掩码 BERT,以及去掉下一句预测的 BERT。
Here, we first compare the performance of BERT and XLNet in a fair setting to decouple the effects of using more data and the improvement from BERT to XLNet. In Table 1, we compare (1) best performance of three different variants of BERT and (2) XLNet trained with the same data and hyperparameters. As we can see, trained on the same data with an almost identical training recipe, XLNet outperforms BERT by a sizable margin on all the considered datasets.
这里先在公平设定下比较 BERT 与 XLNet,以分离「用更多数据」与「从 BERT 到 XLNet 的方法改进」。表 1 对比了(1)三种 BERT 变体的最佳表现,以及(2)用相同数据与超参训练的 XLNet。可见,在几乎同一套训练配方与相同数据上,XLNet 在所考虑的全部数据集上都以可观幅度超过 BERT。
3.3 Comparison with RoBERTa: Scaling Up
3.3 与 RoBERTa 对比:放大训练
| RACE | Accuracy | Middle | High | Model | NDCG@20 | ERR@20 |
|---|---|---|---|---|---|---|
| GPT [28] | 59.0 | 62.9 | 57.4 | DRMM [13] | 24.3 | 13.8 |
| BERT [25] | 72.0 | 76.6 | 70.1 | KNRM [8] | 26.9 | 14.9 |
| BERT+DCMN∗ [38] | 74.1 | 79.5 | 71.8 | Conv [8] | 28.7 | 18.1 |
| RoBERTa [21] | 83.2 | 86.5 | 81.8 | BERT† | 30.53 | 18.67 |
| XLNet | 85.4 | 88.6 | 84.0 | XLNet | 31.10 | 20.28 |
Table 2: Comparison with state-of-the-art results on the test set of RACE, a reading comprehension task, and on ClueWeb09-B, a document ranking task. indicates using ensembles. indicates our implementations. “Middle” and “High” in RACE are two subsets representing middle and high school difficulty levels. All BERT, RoBERTa, and XLNet results are obtained with a 24-layer architecture with similar model sizes (aka BERT-Large).
| RACE | Accuracy | Middle | High | Model | NDCG@20 | ERR@20 |
|---|---|---|---|---|---|---|
| GPT [28] | 59.0 | 62.9 | 57.4 | DRMM [13] | 24.3 | 13.8 |
| BERT [25] | 72.0 | 76.6 | 70.1 | KNRM [8] | 26.9 | 14.9 |
| BERT+DCMN∗ [38] | 74.1 | 79.5 | 71.8 | Conv [8] | 28.7 | 18.1 |
| RoBERTa [21] | 83.2 | 86.5 | 81.8 | BERT† | 30.53 | 18.67 |
| XLNet | 85.4 | 88.6 | 84.0 | XLNet | 31.10 | 20.28 |
表 2:在阅读理解任务 RACE 测试集,以及文档排序任务 ClueWeb09-B 上与当时最优结果的对比。 表示集成; 表示我们的实现。RACE 中 “Middle”“High” 分别为初中、高中难度子集。BERT、RoBERTa 与 XLNet 均为约 BERT-Large 规模的 24 层结构。
| SQuAD2.0 | EM | F1 | SQuAD1.1 | EM | F1 |
|---|---|---|---|---|---|
| Dev set results (single model) | |||||
| BERT [10] | 78.98 | 81.77 | BERT [10] | 84.1 | 90.9 |
| RoBERTa [21] | 86.5 | 89.4 | RoBERTa [21] | 88.9 | 94.6 |
| XLNet | 87.9 | 90.6 | XLNet | 89.7 | 95.1 |
| Test set results on leaderboard (single model, as of Dec 14, 2019) | |||||
| BERT [10] | 80.005 | 83.061 | BERT [10] | 85.083 | 91.835 |
| RoBERTa [21] | 86.820 | 89.795 | BERT∗ [10] | 87.433 | 93.294 |
| XLNet | 87.926 | 90.689 | XLNet | 89.898 | 95.080 |
Table 3: Results on SQuAD, a reading comprehension dataset. marks our runs with the official code. indicates ensembles. : We are not able to obtain the test results of our latest model on SQuAD1.1 from the organizers after submitting our result for more than one month, and thus report the results of an older version for the SQuAD1.1 test set.
| SQuAD2.0 | EM | F1 | SQuAD1.1 | EM | F1 |
|---|---|---|---|---|---|
| Dev set results (single model) | |||||
| BERT [10] | 78.98 | 81.77 | BERT [10] | 84.1 | 90.9 |
| RoBERTa [21] | 86.5 | 89.4 | RoBERTa [21] | 88.9 | 94.6 |
| XLNet | 87.9 | 90.6 | XLNet | 89.7 | 95.1 |
| Test set results on leaderboard (single model, as of Dec 14, 2019) | |||||
| BERT [10] | 80.005 | 83.061 | BERT [10] | 85.083 | 91.835 |
| RoBERTa [21] | 86.820 | 89.795 | BERT∗ [10] | 87.433 | 93.294 |
| XLNet | 87.926 | 90.689 | XLNet | 89.898 | 95.080 |
表 3:阅读理解数据集 SQuAD 上的结果。 为我们用官方代码复现; 表示集成。:最新模型在 SQuAD1.1 上的测试结果提交逾一个月仍未能从主办方取得,故该测试集报告的是较旧版本结果。
| Model | IMDB | Yelp-2 | Yelp-5 | DBpedia | AG | Amazon-2 | Amazon-5 |
|---|---|---|---|---|---|---|---|
| CNN [15] | - | 2.90 | 32.39 | 0.84 | 6.57 | 3.79 | 36.24 |
| DPCNN [15] | - | 2.64 | 30.58 | 0.88 | 6.87 | 3.32 | 34.81 |
| Mixed VAT [31, 23] | 4.32 | - | - | 0.70 | 4.95 | - | - |
| ULMFiT [14] | 4.6 | 2.16 | 29.98 | 0.80 | 5.01 | - | - |
| BERT [35] | 4.51 | 1.89 | 29.32 | 0.64 | - | 2.63 | 34.17 |
| XLNet | 3.20 | 1.37 | 27.05 | 0.60 | 4.45 | 2.11 | 31.67 |
Table 4: Comparison with state-of-the-art error rates on the test sets of several text classification datasets. All BERT and XLNet results are obtained with a 24-layer architecture with similar model sizes (aka BERT-Large).
| Model | IMDB | Yelp-2 | Yelp-5 | DBpedia | AG | Amazon-2 | Amazon-5 |
|---|---|---|---|---|---|---|---|
| CNN [15] | - | 2.90 | 32.39 | 0.84 | 6.57 | 3.79 | 36.24 |
| DPCNN [15] | - | 2.64 | 30.58 | 0.88 | 6.87 | 3.32 | 34.81 |
| Mixed VAT [31, 23] | 4.32 | - | - | 0.70 | 4.95 | - | - |
| ULMFiT [14] | 4.6 | 2.16 | 29.98 | 0.80 | 5.01 | - | - |
| BERT [35] | 4.51 | 1.89 | 29.32 | 0.64 | - | 2.63 | 34.17 |
| XLNet | 3.20 | 1.37 | 27.05 | 0.60 | 4.45 | 2.11 | 31.67 |
表 4:若干文本分类数据集测试集上的错误率与当时最优结果对比。BERT 与 XLNet 均为约 BERT-Large 规模的 24 层结构。
| Model | MNLI | QNLI | QQP | RTE | SST-2 | MRPC | CoLA | STS-B | WNLI |
|---|---|---|---|---|---|---|---|---|---|
| Single-task single models on dev | |||||||||
| BERT [2] | 86.6/- | 92.3 | 91.3 | 70.4 | 93.2 | 88.0 | 60.6 | 90.0 | - |
| RoBERTa [21] | 90.2/90.2 | 94.7 | 92.2 | 86.6 | 96.4 | 90.9 | 68.0 | 92.4 | - |
| XLNet | 90.8/90.8 | 94.9 | 92.3 | 85.9 | 97.0 | 90.8 | 69.0 | 92.5 | - |
| Multi-task ensembles on test (from leaderboard as of Oct 28, 2019) | |||||||||
| MT-DNN∗ [20] | 87.9/87.4 | 96.0 | 89.9 | 86.3 | 96.5 | 92.7 | 68.4 | 91.1 | 89.0 |
| RoBERTa∗ [21] | 90.8/90.2 | 98.9 | 90.2 | 88.2 | 96.7 | 92.3 | 67.8 | 92.2 | 89.0 |
| XLNet∗ | 90.9/90.9† | 99.0† | 90.4† | 88.5 | 97.1† | 92.9 | 70.2 | 93.0 | 92.5 |
Table 5: Results on GLUE. indicates using ensembles, and denotes single-task results in a multi-task row. All dev results are the median of 10 runs. The upper section shows direct comparison on dev data and the lower section shows comparison with state-of-the-art results on the public leaderboard.
| Model | MNLI | QNLI | QQP | RTE | SST-2 | MRPC | CoLA | STS-B | WNLI |
|---|---|---|---|---|---|---|---|---|---|
| Single-task single models on dev | |||||||||
| BERT [2] | 86.6/- | 92.3 | 91.3 | 70.4 | 93.2 | 88.0 | 60.6 | 90.0 | - |
| RoBERTa [21] | 90.2/90.2 | 94.7 | 92.2 | 86.6 | 96.4 | 90.9 | 68.0 | 92.4 | - |
| XLNet | 90.8/90.8 | 94.9 | 92.3 | 85.9 | 97.0 | 90.8 | 69.0 | 92.5 | - |
| Multi-task ensembles on test (from leaderboard as of Oct 28, 2019) | |||||||||
| MT-DNN∗ [20] | 87.9/87.4 | 96.0 | 89.9 | 86.3 | 96.5 | 92.7 | 68.4 | 91.1 | 89.0 |
| RoBERTa∗ [21] | 90.8/90.2 | 98.9 | 90.2 | 88.2 | 96.7 | 92.3 | 67.8 | 92.2 | 89.0 |
| XLNet∗ | 90.9/90.9† | 99.0† | 90.4† | 88.5 | 97.1† | 92.9 | 70.2 | 93.0 | 92.5 |
表 5:GLUE 结果。 表示集成, 表示多任务行中的单任务结果。开发集结果均为 10 次运行的中位数。上半部分直接在开发集对比,下半部分与公开排行榜上的当时最优结果对比。
After the initial publication of our manuscript, a few other pretrained models were released such as RoBERTa [21] and ALBERT [19]. Since ALBERT involves increasing the model hidden size from 1024 to 2048/4096 and thus substantially increases the amount of computation in terms of FLOPs, we exclude ALBERT from the following results as it is hard to lead to scientific conclusions. To obtain relatively fair comparison with RoBERTa, the experiment in this section is based on full data and reuses the hyper-parameters of RoBERTa, as described in section 3.1.
初稿发表后,又有 RoBERTa [21]、ALBERT [19] 等预训练模型发布。由于 ALBERT 把隐藏维从 1024 提到 2048/4096,FLOPs 大幅增加,难以得出科学结论,故下文结果不纳入 ALBERT。为与 RoBERTa 相对公平对比,本节实验基于全量数据,并复用 RoBERTa 的超参(见第 3.1 节)。
The results are presented in Tables 2 (reading comprehension & document ranking), 3 (question answering), 4 (text classification) and 5 (natural language understanding), where XLNet generally outperforms BERT and RoBERTa. In addition, we make two more interesting observations:
结果见表 2(阅读理解与文档排序)、表 3(问答)、表 4(文本分类)与表 5(自然语言理解);总体而言 XLNet 优于 BERT 与 RoBERTa。另外有两点值得注意:
- • For explicit reasoning tasks like SQuAD and RACE that involve longer context, the performance gain of XLNet is usually larger. This superiority at dealing with longer context could come from the Transformer-XL backbone in XLNet.
- • For classification tasks that already have abundant supervised examples such as MNLI (>390K), Yelp (>560K) and Amazon (>3M), XLNet still lead to substantial gains.
- • 对 SQuAD、RACE 这类涉及更长上下文、需要显式推理的任务,XLNet 的收益通常更大;处理长上下文的优势可能来自 XLNet 中的 Transformer-XL 骨干。
- • 对已有充足监督样本的分类任务,如 MNLI(>390K)、Yelp(>560K)、Amazon(>3M),XLNet 仍能带来可观提升。
3.4 Ablation Study
3.4 消融实验
We perform an ablation study to understand the importance of each design choice based on four datasets with diverse characteristics. Specifically, there are three main aspects we hope to study:
我们基于四个特性各异的数据集做消融,以理解各项设计选择的重要性。具体希望弄清三方面:
- • The effectiveness of the permutation language modeling objective alone, especially compared to the denoising auto-encoding objective used by BERT.
- • The importance of using Transformer-XL as the backbone neural architecture.
- • The necessity of some implementation details including span-based prediction, the bidirectional input pipeline, and next-sentence prediction.
- • 单独使用排列语言建模目标的效果,尤其是相对 BERT 所用去噪自编码目标。
- • 以 Transformer-XL 作为骨干神经结构的重要性。
- • 若干实现细节的必要性,包括基于跨度的预测、双向输入管线,以及下一句预测。
With these purposes in mind, in Table 6, we compare 6 XLNet-Base variants with different implementation details (rows 3 - 8), the original BERT-Base model (row 1), and an additional Transformer-XL baseline trained with the denoising auto-encoding (DAE) objective used in BERT but with the bidirectional input pipeline (row 2). For fair comparison, all models are based on a 12-layer architecture with the same model hyper-parameters as BERT-Base and are trained on only Wikipedia and the BooksCorpus. All results reported are the median of 5 runs.
据此,表 6 比较了 6 个实现细节不同的 XLNet-Base 变体(第 3–8 行)、原版 BERT-Base(第 1 行),以及一个额外的 Transformer-XL 基线:它用 BERT 的去噪自编码(DAE)目标训练,但配上双向输入管线(第 2 行)。为公平对比,所有模型均为 12 层,超参与 BERT-Base 相同,且只在维基与 BooksCorpus 上训练。所报结果均为 5 次运行的中位数。
| # | Model | RACE | SQuAD2.0 | MNLI | SST-2 | |
|---|---|---|---|---|---|---|
| F1 | EM | m/mm | ||||
| 1 | BERT-Base | 64.3 | 76.30 | 73.66 | 84.34/84.65 | 92.78 |
| 2 | DAE + Transformer-XL | 65.03 | 79.56 | 76.80 | 84.88/84.45 | 92.60 |
| 3 | XLNet-Base () | 66.05 | 81.33 | 78.46 | 85.84/85.43 | 92.66 |
| 4 | XLNet-Base () | 66.66 | 80.98 | 78.18 | 85.63/85.12 | 93.35 |
| 5 | - memory | 65.55 | 80.15 | 77.27 | 85.32/85.05 | 92.78 |
| 6 | - span-based pred | 65.95 | 80.61 | 77.91 | 85.49/85.02 | 93.12 |
| 7 | - bidirectional data | 66.34 | 80.65 | 77.87 | 85.31/84.99 | 92.66 |
| 8 | + next-sent pred | 66.76 | 79.83 | 76.94 | 85.32/85.09 | 92.89 |
Table 6: The results of BERT on RACE are taken from [38]. We run BERT on the other datasets using the official implementation and the same hyperparameter search space as XLNet. is a hyperparameter to control the optimization difficulty (see Section 1).
| # | Model | RACE | SQuAD2.0 | MNLI | SST-2 | |
|---|---|---|---|---|---|---|
| F1 | EM | m/mm | ||||
| 1 | BERT-Base | 64.3 | 76.30 | 73.66 | 84.34/84.65 | 92.78 |
| 2 | DAE + Transformer-XL | 65.03 | 79.56 | 76.80 | 84.88/84.45 | 92.60 |
| 3 | XLNet-Base () | 66.05 | 81.33 | 78.46 | 85.84/85.43 | 92.66 |
| 4 | XLNet-Base () | 66.66 | 80.98 | 78.18 | 85.63/85.12 | 93.35 |
| 5 | - memory | 65.55 | 80.15 | 77.27 | 85.32/85.05 | 92.78 |
| 6 | - span-based pred | 65.95 | 80.61 | 77.91 | 85.49/85.02 | 93.12 |
| 7 | - bidirectional data | 66.34 | 80.65 | 77.87 | 85.31/84.99 | 92.66 |
| 8 | + next-sent pred | 66.76 | 79.83 | 76.94 | 85.32/85.09 | 92.89 |
表 6:BERT 在 RACE 上的结果取自 [38]。其余数据集上我们用官方实现、并与 XLNet 相同的超参搜索空间跑 BERT。 是控制优化难度的超参(见第 1 节)。
Examining rows 1 - 4 of Table 6, we can see both Transformer-XL and the permutation LM clearly contribute the superior performance of XLNet over BERT. Moreover, if we remove the memory caching mechanism (row 5), the performance clearly drops, especially for RACE which involves the longest context among the 4 tasks. In addition, rows 6 - 7 show that both span-based prediction and the bidirectional input pipeline play important roles in XLNet. Finally, we unexpectedly find the the next-sentence prediction objective proposed in the original BERT does not necessarily lead to an improvement in our setting. Hence, we exclude the next-sentence prediction objective from XLNet.
观察表 6 第 1–4 行可见,Transformer-XL 与排列 LM 都明确贡献了 XLNet 相对 BERT 的优势。若去掉记忆缓存机制(第 5 行),表现明显下降,尤其在四个任务中上下文最长的 RACE 上。第 6–7 行表明,基于跨度的预测与双向输入管线对 XLNet 都很重要。最后我们意外发现,原 BERT 提出的下一句预测目标在本设定下并不必然带来提升,因此 XLNet 不采用该目标。
Finally, we also perform a qualitative study of the attention patterns, which is included in Appendix A.6 due to page limit.
我们还对注意力模式做了定性分析,因篇幅限制放在附录 A.6。
4 Conclusions
4 结论
XLNet is a generalized AR pretraining method that uses a permutation language modeling objective to combine the advantages of AR and AE methods. The neural architecture of XLNet is developed to work seamlessly with the AR objective, including integrating Transformer-XL and the careful design of the two-stream attention mechanism. XLNet achieves substantial improvement over previous pretraining objectives on various tasks.
XLNet 是一种广义 AR 预训练方法,用排列语言建模目标兼取 AR 与 AE 之长。其网络结构为配合 AR 目标而设计,包括融入 Transformer-XL,以及精心设计的双流注意力机制。XLNet 在多种任务上相对先前预训练目标取得了实质改进。
Acknowledgments
The authors would like to thank Qizhe Xie and Adams Wei Yu for providing useful feedback on the project, Jamie Callan for providing the ClueWeb dataset, Youlong Cheng, Yanping Huang and Shibo Wang for providing ideas to improve our TPU implementation, Chenyan Xiong and Zhuyun Dai for clarifying the setting of the document ranking task. ZY and RS were supported by the Office of Naval Research grant N000141812861, the National Science Foundation (NSF) grant IIS1763562, the Nvidia fellowship, and the Siebel scholarship. ZD and YY were supported in part by NSF under the grant IIS-1546329 and by the DOE-Office of Science under the grant ASCR #KJ040201.
致谢
作者感谢 Qizhe Xie 与 Adams Wei Yu 对项目的有益反馈,Jamie Callan 提供 ClueWeb 数据,Youlong Cheng、Yanping Huang 与 Shibo Wang 提出改进 TPU 实现的想法,以及 Chenyan Xiong 与 Zhuyun Dai 澄清文档排序任务设定。ZY 与 RS 得到海军研究办公室资助 N000141812861、美国国家科学基金会(NSF)资助 IIS1763562、Nvidia 奖学金与 Siebel 奖学金支持。ZD 与 YY 部分得到 NSF 资助 IIS-1546329,以及能源部科学办公室资助 ASCR #KJ040201。
References
参考文献
[1] Rami Al-Rfou, Dokook Choe, Noah Constant, Mandy Guo, and Llion Jones. Character-level language modeling with deeper self-attention. arXiv preprint arXiv:1808.04444 , 2018.
[2] Anonymous. Bam! born-again multi-task networks for natural language understanding. anonymous preprint under review, 2018.
[3] Alexei Baevski and Michael Auli. Adaptive input representations for neural language modeling. arXiv preprint arXiv:1809.10853 , 2018.
[4] Yoshua Bengio and Samy Bengio. Modeling high-dimensional discrete data with multi-layer neural networks. In Advances in Neural Information Processing Systems , pages 400–406, 2000.
[5] Jamie Callan, Mark Hoy, Changkuk Yoo, and Le Zhao. Clueweb09 data set, 2009.
[6] Common Crawl. Common crawl. URl: http://http://commoncrawl. org , 2019.
[7] Andrew M Dai and Quoc V Le. Semi-supervised sequence learning. In Advances in neural information processing systems , pages 3079–3087, 2015.
[8] Zhuyun Dai, Chenyan Xiong, Jamie Callan, and Zhiyuan Liu. Convolutional neural networks for soft-matching n-grams in ad-hoc search. In Proceedings of the eleventh ACM international conference on web search and data mining , pages 126–134. ACM, 2018.
[9] Zihang Dai, Zhilin Yang, Yiming Yang, William W Cohen, Jaime Carbonell, Quoc V Le, and Ruslan Salakhutdinov. Transformer-xl: Attentive language models beyond a fixed-length context. arXiv preprint arXiv:1901.02860 , 2019.
[10] Jacob Devlin, Ming-Wei Chang, Kenton Lee, and Kristina Toutanova. Bert: Pre-training of deep bidirectional transformers for language understanding. arXiv preprint arXiv:1810.04805 , 2018.
[11] William Fedus, Ian Goodfellow, and Andrew M Dai. Maskgan: better text generation via filling in the_. arXiv preprint arXiv:1801.07736 , 2018.
[12] Mathieu Germain, Karol Gregor, Iain Murray, and Hugo Larochelle. Made: Masked autoencoder for distribution estimation. In International Conference on Machine Learning , pages 881–889, 2015.
[13] Jiafeng Guo, Yixing Fan, Qingyao Ai, and W Bruce Croft. A deep relevance matching model for ad-hoc retrieval. In Proceedings of the 25th ACM International on Conference on Information and Knowledge Management , pages 55–64. ACM, 2016.
[14] Jeremy Howard and Sebastian Ruder. Universal language model fine-tuning for text classification. arXiv preprint arXiv:1801.06146 , 2018.
[15] Rie Johnson and Tong Zhang. Deep pyramid convolutional neural networks for text categorization. In Proceedings of the 55th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) , pages 562–570, 2017.
[16] Vid Kocijan, Ana-Maria Cretu, Oana-Maria Camburu, Yordan Yordanov, and Thomas Lukasiewicz. A surprisingly robust trick for winograd schema challenge. arXiv preprint arXiv:1905.06290 , 2019.
[17] Taku Kudo and John Richardson. Sentencepiece: A simple and language independent subword tokenizer and detokenizer for neural text processing. arXiv preprint arXiv:1808.06226 , 2018.
[18] Guokun Lai, Qizhe Xie, Hanxiao Liu, Yiming Yang, and Eduard Hovy. Race: Large-scale reading comprehension dataset from examinations. arXiv preprint arXiv:1704.04683 , 2017.
[19] Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, and Radu Soricut. Albert: A lite bert for self-supervised learning of language representations. arXiv preprint arXiv:1909.11942 , 2019.
[20] Xiaodong Liu, Pengcheng He, Weizhu Chen, and Jianfeng Gao. Multi-task deep neural networks for natural language understanding. arXiv preprint arXiv:1901.11504 , 2019.
[21] Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, and Veselin Stoyanov. Roberta: A robustly optimized bert pretraining approach. arXiv preprint arXiv:1907.11692 , 2019.
[22] Bryan McCann, James Bradbury, Caiming Xiong, and Richard Socher. Learned in translation: Contextualized word vectors. In Advances in Neural Information Processing Systems , pages 6294–6305, 2017.
[23] Takeru Miyato, Andrew M Dai, and Ian Goodfellow. Adversarial training methods for semi-supervised text classification. arXiv preprint arXiv:1605.07725 , 2016.
[24] Aaron van den Oord, Nal Kalchbrenner, and Koray Kavukcuoglu. Pixel recurrent neural networks. arXiv preprint arXiv:1601.06759 , 2016.
[25] Xiaoman Pan, Kai Sun, Dian Yu, Heng Ji, and Dong Yu. Improving question answering with external knowledge. arXiv preprint arXiv:1902.00993 , 2019.
[26] Robert Parker, David Graff, Junbo Kong, Ke Chen, and Kazuaki Maeda. English gigaword fifth edition, linguistic data consortium. Technical report, Technical Report. Linguistic Data Consortium, Philadelphia, Tech. Rep. , 2011.
[27] Matthew E Peters, Mark Neumann, Mohit Iyyer, Matt Gardner, Christopher Clark, Kenton Lee, and Luke Zettlemoyer. Deep contextualized word representations. arXiv preprint arXiv:1802.05365 , 2018.
[28] Alec Radford, Karthik Narasimhan, Tim Salimans, and Ilya Sutskever. Improving language understanding by generative pre-training. URL https://s3-us-west-2. amazonaws. com/openai-assets/research-covers/languageunsupervised/language understanding paper. pdf , 2018.
[29] Pranav Rajpurkar, Robin Jia, and Percy Liang. Know what you don’t know: Unanswerable questions for squad. arXiv preprint arXiv:1806.03822 , 2018.
[30] Pranav Rajpurkar, Jian Zhang, Konstantin Lopyrev, and Percy Liang. Squad: 100,000+ questions for machine comprehension of text. arXiv preprint arXiv:1606.05250 , 2016.
[31] Devendra Singh Sachan, Manzil Zaheer, and Ruslan Salakhutdinov. Revisiting lstm networks for semi-supervised text classification via mixed objective function. 2018.
[32] Benigno Uria, Marc-Alexandre Côté, Karol Gregor, Iain Murray, and Hugo Larochelle. Neural autoregressive distribution estimation. The Journal of Machine Learning Research , 17(1):7184–7220, 2016.
[33] Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Łukasz Kaiser, and Illia Polosukhin. Attention is all you need. In Advances in neural information processing systems , pages 5998–6008, 2017.
[34] Alex Wang, Amanpreet Singh, Julian Michael, Felix Hill, Omer Levy, and Samuel R. Bowman. GLUE: A multi-task benchmark and analysis platform for natural language understanding. 2019. In the Proceedings of ICLR.
[35] Qizhe Xie, Zihang Dai, Eduard Hovy, Minh-Thang Luong, and Quoc V. Le. Unsupervised data augmentation. arXiv preprint arXiv:1904.12848 , 2019.
[36] Chenyan Xiong, Zhuyun Dai, Jamie Callan, Zhiyuan Liu, and Russell Power. End-to-end neural ad-hoc ranking with kernel pooling. In Proceedings of the 40th International ACM SIGIR conference on research and development in information retrieval , pages 55–64. ACM, 2017.
[37] Zhilin Yang, Zihang Dai, Ruslan Salakhutdinov, and William W Cohen. Breaking the softmax bottleneck: A high-rank rnn language model. arXiv preprint arXiv:1711.03953 , 2017.
[38] Shuailiang Zhang, Hai Zhao, Yuwei Wu, Zhuosheng Zhang, Xi Zhou, and Xiang Zhou. Dual co-matching network for multi-choice reading comprehension. arXiv preprint arXiv:1901.09381 , 2019.
[39] Xiang Zhang, Junbo Zhao, and Yann LeCun. Character-level convolutional networks for text classification. In Advances in neural information processing systems , pages 649–657, 2015.
[40] Yukun Zhu, Ryan Kiros, Rich Zemel, Ruslan Salakhutdinov, Raquel Urtasun, Antonio Torralba, and Sanja Fidler. Aligning books and movies: Towards story-like visual explanations by watching movies and reading books. In Proceedings of the IEEE international conference on computer vision , pages 19–27, 2015.
Appendix A Target-Aware Representation via Two-Stream Self-Attention
附录 A 经双流自注意力得到的目标感知表示
A.1 A Concrete Example of How Standard LM Parameterization Fails
A.1 标准语言模型参数化为何失效:一个具体例子
In this section, we provide a concrete example to show how the standard language model parameterization fails under the permutation objective, as discussed in Section 1. Specifically, let’s consider two different permutations and satisfying the following relationship
本节给一个具体例子,说明在排列目标下标准语言模型参数化如何失效(见第 1 节讨论)。具体考虑两个不同排列 与 ,满足
Then, substituting the two permutations respectively into the naive parameterization, we have
分别代入天真参数化,得到
Effectively, two different target positions and share exactly the same model prediction. However, the ground-truth distribution of two positions should certainly be different.
效果上,两个不同目标位置 与 共享完全相同的模型预测;但两位置的真实分布理应不同。
A.2 Two-Stream Attention
A.2 双流注意力
Here, we provide the implementation details of the two-stream attention with a Transformer-XL backbone.
这里给出以 Transformer-XL 为骨干的双流注意力实现细节。
A.3 Datasets
A.3 数据集
A.3.1 RACE Dataset
The RACE dataset [18] contains near 100K questions taken from the English exams for middle and high school Chinese students in the age range between 12 to 18, with the answers generated by human experts. This is one of the most difficult reading comprehension datasets that involve challenging reasoning questions. Moreover, the average length of the passages in RACE are longer than 300, which is significantly longer than other popular reading comprehension datasets such as SQuAD [29]. As a result, this dataset serves as a challenging benchmark for long text understanding. We use a sequence length of 512 during finetuning.
A.3.1 RACE 数据集
RACE 数据集 [18] 收录近 10 万道取自中国 12–18 岁初高中英语考试的题目,答案由人类专家给出。这是最具难度的阅读理解数据集之一,包含需要挑战性推理的问题。此外,RACE 篇章平均长度超过 300,显著长于 SQuAD [29] 等常见阅读理解数据,因此可作为长文本理解的苛刻基准。微调时我们使用序列长度 512。
A.3.2 SQuAD
SQuAD is a large-scale reading comprehension dataset with two tasks. SQuAD1.1 [30] contains questions that always have a corresponding answer in the given passages, while SQuAD2.0 [29] introduces unanswerable questions. To finetune an XLNet on SQuAD2.0, we jointly apply a logistic regression loss for answerability prediction similar to classification tasks and a standard span extraction loss for question answering [10].
A.3.2 SQuAD
SQuAD 是大规模阅读理解数据集,含两项任务。SQuAD1.1 [30] 中问题在给定篇章里总有对应答案;SQuAD2.0 [29] 则引入不可回答问题。在 SQuAD2.0 上微调 XLNet 时,我们联合使用类似分类任务的可回答性逻辑回归损失,以及问答常用的标准跨度抽取损失 [10]。
A.3.3 Text classification Datasets
Following previous work on text classification [39, 23], we evaluate XLNet on the following benchmarks: IMDB, Yelp-2, Yelp-5, DBpedia, AG, Amazon-2, and Amazon-5.
A.3.3 文本分类数据集
沿用先前文本分类工作 [39, 23],我们在以下基准上评估 XLNet:IMDB、Yelp-2、Yelp-5、DBpedia、AG、Amazon-2 与 Amazon-5。
A.3.4 GLUE Dataset
The GLUE dataset [34] is a collection of 9 natural language understanding tasks. The test set labels are removed from the publicly released version, and all the practitioners must submit their predictions on the evaluation server to obtain test set results. In Table 5, we present results of multiple settings, including single-task and multi-task, as well as single models and ensembles. In the multi-task setting, we jointly train an XLNet on the four largest datasets—MNLI, SST-2, QNLI, and QQP—and finetune the network on the other datasets. Only single-task training is employed for the four large datasets. For QNLI, we employed a pairwise relevance ranking scheme as in [20] for our test set submission. However, for fair comparison with BERT, our result on the QNLI dev set is based on a standard classification paradigm. For WNLI, we use the loss described in [16].
A.3.4 GLUE 数据集
GLUE 数据集 [34] 汇集 9 项自然语言理解任务。公开版本已去掉测试集标签,从业者须向评测服务器提交预测才能得到测试结果。表 5 给出多种设定下的结果,包括单任务与多任务、单模型与集成。多任务设定下,我们在四个最大数据集——MNLI、SST-2、QNLI、QQP——上联合训练 XLNet,再在其余数据集上微调;四个大数据集本身只做单任务训练。QNLI 测试提交采用与 [20] 类似的成对相关性排序方案;但为与 BERT 公平对比,QNLI 开发集结果基于标准分类范式。WNLI 使用 [16] 所述损失。
A.3.5 ClueWeb09-B Dataset
Following the setting in previous work [8], we use the ClueWeb09-B dataset to evaluate the performance on document ranking. The queries were created by the TREC 2009-2012 Web Tracks based on 50M documents and the task is to rerank the top 100 documents retrieved using a standard retrieval method. Since document ranking, or ad-hoc retrieval, mainly concerns the low-level representations instead of high-level semantics, this dataset serves as a testbed for evaluating the quality of word embeddings. We use a pretrained XLNet to extract word embeddings for the documents and queries without finetuning, and employ a kernel pooling network [36] to rank the documents.
A.3.5 ClueWeb09-B 数据集
沿用先前工作设定 [8],我们用 ClueWeb09-B 评估文档排序。查询来自 TREC 2009–2012 Web Tracks,基于约 5000 万文档;任务是对用标准检索方法取出的前 100 篇文档重排序。文档排序(或 ad-hoc 检索)主要关心低层表示而非高层语义,因而适合检验词嵌入质量。我们用预训练 XLNet 抽取文档与查询的词嵌入(不做微调),再用核池化网络 [36] 排序。
A.4 Hyperparameters
A.4 超参数
A.4.1 Pretraining Hyperparameters
| Hparam | Value |
|---|---|
| Number of layers | 24 |
| Hidden size | 1024 |
| Number of attention heads | 16 |
| Attention head size | 64 |
| FFN inner hidden size | 4096 |
| Hidden Dropout | 0.1 |
| GeLU Dropout | 0.0 |
| Attention dropout | 0.1 |
| Partial prediction | 6 |
| Max sequence length | 512 |
| Batch size | 8192 |
| Learning rate | 4e-4 |
| Number of steps | 500K |
| Warmup steps | 40,000 |
| Learning rate decay | linear |
| Adam epsilon | 1e-6 |
| Weight decay | 0.01 |
Table 7: Hyperparameters for pretraining.
A.4.1 预训练超参数
| Hparam | Value |
|---|---|
| Number of layers | 24 |
| Hidden size | 1024 |
| Number of attention heads | 16 |
| Attention head size | 64 |
| FFN inner hidden size | 4096 |
| Hidden Dropout | 0.1 |
| GeLU Dropout | 0.0 |
| Attention dropout | 0.1 |
| Partial prediction | 6 |
| Max sequence length | 512 |
| Batch size | 8192 |
| Learning rate | 4e-4 |
| Number of steps | 500K |
| Warmup steps | 40,000 |
| Learning rate decay | linear |
| Adam epsilon | 1e-6 |
| Weight decay | 0.01 |
表 7:预训练超参数。
The hyperparameters used for pretraining XLNet are shown in Table 7.
预训练 XLNet 所用超参数见表 7。
A.4.2 Hyperparameters for Finetuning
| Hparam | RACE | SQuAD | MNLI | Yelp-5 |
|---|---|---|---|---|
| Dropout | 0.1 | |||
| Attention dropout | 0.1 | |||
| Max sequence length | 512 | 512 | 128 | 512 |
| Batch size | 32 | 48 | 128 | 128 |
| Learning rate | 2e-5 | 3e-5 | 2e-5 | 1e-5 |
| Number of steps | 12K | 8K | 10K | 10K |
| Learning rate decay | linear | |||
| Weight decay | 0.01 | |||
| Adam epsilon | 1e-6 | 1e-6 | 1e-6 | 1e-6 |
| Layer-wise lr decay | 1.0 | 0.75 | 1.0 | 1.0 |
Table 8: Hyperparameters for finetuning.
A.4.2 微调超参数
| Hparam | RACE | SQuAD | MNLI | Yelp-5 |
|---|---|---|---|---|
| Dropout | 0.1 | |||
| Attention dropout | 0.1 | |||
| Max sequence length | 512 | 512 | 128 | 512 |
| Batch size | 32 | 48 | 128 | 128 |
| Learning rate | 2e-5 | 3e-5 | 2e-5 | 1e-5 |
| Number of steps | 12K | 8K | 10K | 10K |
| Learning rate decay | linear | |||
| Weight decay | 0.01 | |||
| Adam epsilon | 1e-6 | 1e-6 | 1e-6 | 1e-6 |
| Layer-wise lr decay | 1.0 | 0.75 | 1.0 | 1.0 |
表 8:微调超参数。
The hyperparameters used for finetuning XLNet on various tasks are shown in Table 8. “Layer-wise decay” means exponentially decaying the learning rates of individual layers in a top-down manner. For example, suppose the -th layer uses a learning rate , and the Layer-wise decay rate is , then the learning rate of layer is .
各任务微调 XLNet 的超参数见表 8。「逐层衰减」指自上而下对各层学习率做指数衰减。例如,若第 层学习率为 、逐层衰减率为 ,则第 层学习率为 。
A.5 Discussion and Analysis
A.5 讨论与分析
A.5.1 Comparison with BERT
To prove a general point beyond one example, we now turn to more formal expressions. Inspired by previous work [37], given a sequence , we define a set of target-context pairs of interest, , where is a set of tokens in that form a context of . Intuitively, we want the model to learn the dependency of on through a pretraining loss term . For example, given the above sentence, the pairs of interest could be instantiated as:
A.5.1 与 BERT 的比较
为把论点推到单一例子之外,下面转向更形式的表述。受先前工作 [37] 启发,给定序列 ,定义一组关心的目标–上下文对 ,其中 是 中构成 上下文的一组词元。直观上,希望模型通过预训练损失项 学到 对 的依赖。例如,对上面那句句子, 可实例化为:
Note that is merely a virtual notion without unique ground truth, and our analysis will hold regardless of how is instantiated.
注意 只是虚拟概念、并无唯一真值;无论如何实例化 ,下文分析都成立。
Given a set of target tokens and a set of non-target tokens , BERT and XLNet both maximize but with different formulations:
给定目标词元集合 与非目标集合 ,BERT 与 XLNet 都最大化 ,但形式不同:
where denote tokens in that have a factorization order prior to . Both objectives consist of multiple loss terms in the form of . Intuitively, if there exists a target-context pair such that , then the loss term provides a training signal to the dependency between and . For convenience, we say a target-context pair is covered by a model (objective) if .
其中 表示 中分解顺序排在 之前的词元。两个目标都由形如 的多个损失项组成。直观上,若存在目标–上下文对 满足 ,则损失项 为 与 之间的依赖提供训练信号。为方便起见,若 ,称模型(目标)覆盖了 。
Given the definition, let’s consider two cases:
在该定义下,考虑两种情形:
- • If , the dependency is covered by both BERT and XLNet.
- • If and , the dependency can only be covered by XLNet but not BERT. As a result, XLNet is able to cover more dependencies than BERT. In other words, the XLNet objective contains more effective training signals, which empirically leads to better performance in Section 3.
- • 若 ,则依赖 被 BERT 与 XLNet 同时覆盖。
- • 若 且 ,则该依赖只能被 XLNet 覆盖、不能被 BERT 覆盖。因此 XLNet 能覆盖比 BERT 更多的依赖;换言之,XLNet 目标含有更有效的训练信号,这也与第 3 节经验上更好的表现相一致。
A.5.2 Comparison with Language Modeling
Borrowing examples and notations from Section A.5.1, a standard AR language model like GPT [28] is only able to cover the dependency but not . XLNet, on the other hand, is able to cover both in expectation over all factorization orders. Such a limitation of AR language modeling can be critical in real-world applications. For example, consider a span extraction question answering task with the context “Thom Yorke is the singer of Radiohead” and the question “Who is the singer of Radiohead”. The representations of “Thom Yorke” are not dependent on “Radiohead” with AR language modeling and thus they will not be chosen as the answer by the standard approach that employs softmax over all token representations. More formally, consider a context-target pair :
A.5.2 与语言模型的比较
沿用 A.5.1 的例子与记号,像 GPT [28] 这类标准 AR 语言模型只能覆盖依赖 ,而不能覆盖 。XLNet 则在对所有分解顺序取期望时两者都能覆盖。AR 语言建模的这一局限在实际应用中可能很关键。例如,跨度抽取问答的上下文为 “Thom Yorke is the singer of Radiohead”、问题为 “Who is the singer of Radiohead” 时,在 AR 语言建模下 “Thom Yorke” 的表示并不依赖 “Radiohead”,因而不会被「对所有词元表示做 softmax」的标准做法选为答案。更形式地,考虑上下文–目标对 :
- • If , where denotes the tokens prior to in the original sequence, AR language modeling is not able to cover the dependency.
- • In comparison, XLNet is able to cover all dependencies in expectation.
- • 若 ( 为原始序列中位于 之前的词元),AR 语言建模无法覆盖该依赖。
- • 相比之下,XLNet 在期望意义下能覆盖全部依赖。
Approaches like ELMo [27] concatenate forward and backward language models in a shallow manner, which is not sufficient for modeling deep interactions between the two directions.
ELMo [27] 一类方法以前后向语言模型浅层拼接,不足以建模两个方向之间的深层交互。
A.5.3 Bridging the Gap Between Language Modeling and Pretraining
With a deep root in density estimation[^4] [4, 32, 24], language modeling has been a rapidly-developing research area [9, 1, 3]. However, there has been a gap between language modeling and pretraining due to the lack of the capability of bidirectional context modeling, as analyzed in Section A.5.2. It has even been challenged by some machine learning practitioners whether language modeling is a meaningful pursuit if it does not directly improve downstream tasks [^5]. XLNet generalizes language modeling and bridges such a gap. As a result, it further “justifies” language modeling research. Moreover, it becomes possible to leverage the rapid progress of language modeling research for pretraining. As an example, we integrate Transformer-XL into XLNet to demonstrate the usefulness of the latest language modeling progress.
A.5.3 弥合语言模型与预训练之间的差距
语言模型深植于密度估计[^4] [4, 32, 24],一直是快速发展的研究领域 [9, 1, 3]。但由于缺乏双向上下文建模能力(见 A.5.2 分析),语言模型与预训练之间长期存在缺口。甚至有机器学习从业者质疑:若语言模型不能直接改进下游任务,研究它是否还有意义[^5]。XLNet 推广了语言建模并弥合了这一缺口,从而进一步「正当化」语言建模研究;同时,也使预训练可以吸收语言建模的快速进展。例如,我们把 Transformer-XL 融入 XLNet,以展示最新语言建模进展的效用。
A.6 Qualitative Analysis of Attention Patterns
A.6 注意力模式的定性分析
We compare the attention pattern of BERT and XLNet without finetuning. Firstly, we found 4 typical patterns shared by both, as shown in Fig. 2.
我们在不做微调的情况下比较 BERT 与 XLNet 的注意力模式。首先发现两者共享 4 种典型模式,见图 2。
(a) Content stripes
(a) 内容条纹
More interestingly, in Fig. 3, we present 3 patterns that only appear in XLNet but not BERT: (a) The self-exclusion pattern attends to all other tokens but itself, probably offering a fast way to gather global information; (b) The relative-stride pattern attends to positions every a few stride apart relative to the query position; (c) The one-side masked pattern is very similar to the lower-left part of Fig. 1-(d), with the upper-right triangle masked out. It seems that the model learns not to attend the relative right half. Note that all these three unique patterns involve the relative positions rather than absolute ones, and hence are likely enabled by the “relative attention” mechanism in XLNet. We conjecture these unique patterns contribute to the performance advantage of XLNet. On the other hand, the proposed permutation LM objective mostly contributes to a better data efficiency, whose effects may not be obvious from qualitative visualization.
更有意思的是,图 3 给出 3 种只出现在 XLNet、而不出现在 BERT 中的模式:(a) 自排除模式关注除自身外的所有其他词元,可能提供快速汇聚全局信息的路径;(b) 相对步幅模式相对查询位置每隔若干步关注一次;(c) 单侧掩码模式很像图 1-(d) 的左下部分,右上三角被掩掉,模型似乎学会不去关注相对右半侧。注意这三种独特模式都涉及相对位置而非绝对位置,因而很可能由 XLNet 中的「相对注意力」机制促成。我们推测这些独特模式有助于 XLNet 的表现优势。另一方面,所提排列 LM 目标主要贡献于更好的数据效率,其效果未必能从定性可视化中一眼看出。
(a) Self exclusion
(a) 自排除
A.7 Visualizing Memory and Permutation
A.7 可视化记忆与排列
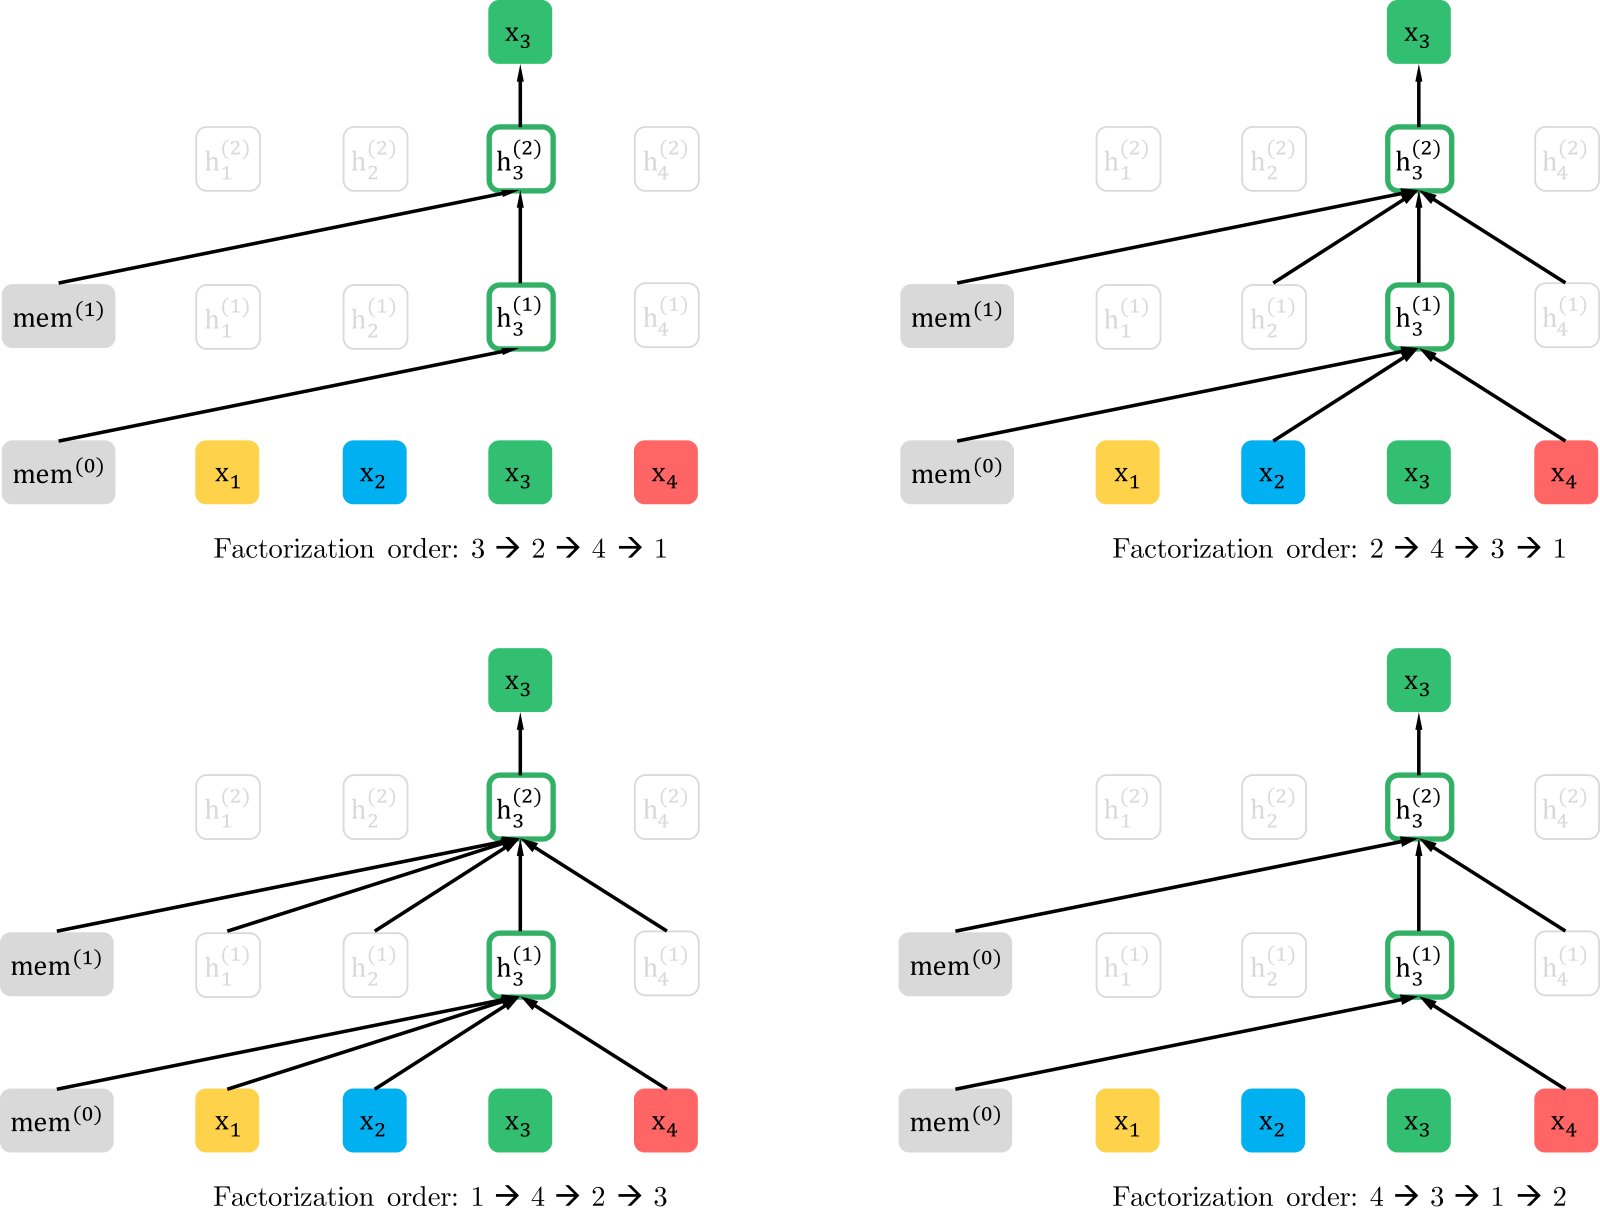
Figure 4: Illustration of the permutation language modeling objective for predicting given the same input sequence but with different factorization orders.
图 4:在同一输入序列 、不同分解顺序下,排列语言建模目标预测 的示意。
In this section, we provide a detailed visualization of the proposed permutation language modeling objective, including the mechanism of reusing memory (aka the recurrence mechanism), how we use attention masks to permute the factorization order, and the difference of the two attention streams.
本节详细可视化所提排列语言建模目标,包括复用记忆(即循环机制)的方式、如何用注意力掩码排列分解顺序,以及两路注意力流的差异。
As shown in Figure 5 and 6, given the current position , the attention mask is decided by the permutation (or factorization order) such that only tokens the occur before in the permutation can be attended; i.e., positions with . Moreover, comparing Figure 5 and 6, we can see how the query stream and the content stream work differently with a specific permutation through attention masks. The main difference is that the query stream cannot do self-attention and does not have access to the token at the position, while the content stream performs normal self-attention.
如图 5、6 所示,给定当前位置 ,注意力掩码由排列(或分解顺序) 决定,使得只有排列中位于 之前的词元可被关注,即满足 的位置 。再比较图 5 与图 6,可以看到在具体排列下查询流与内容流如何通过注意力掩码以不同方式工作。主要差别在于:查询流不能做自注意力,也无法访问该位置的词元;内容流则执行正常自注意力。
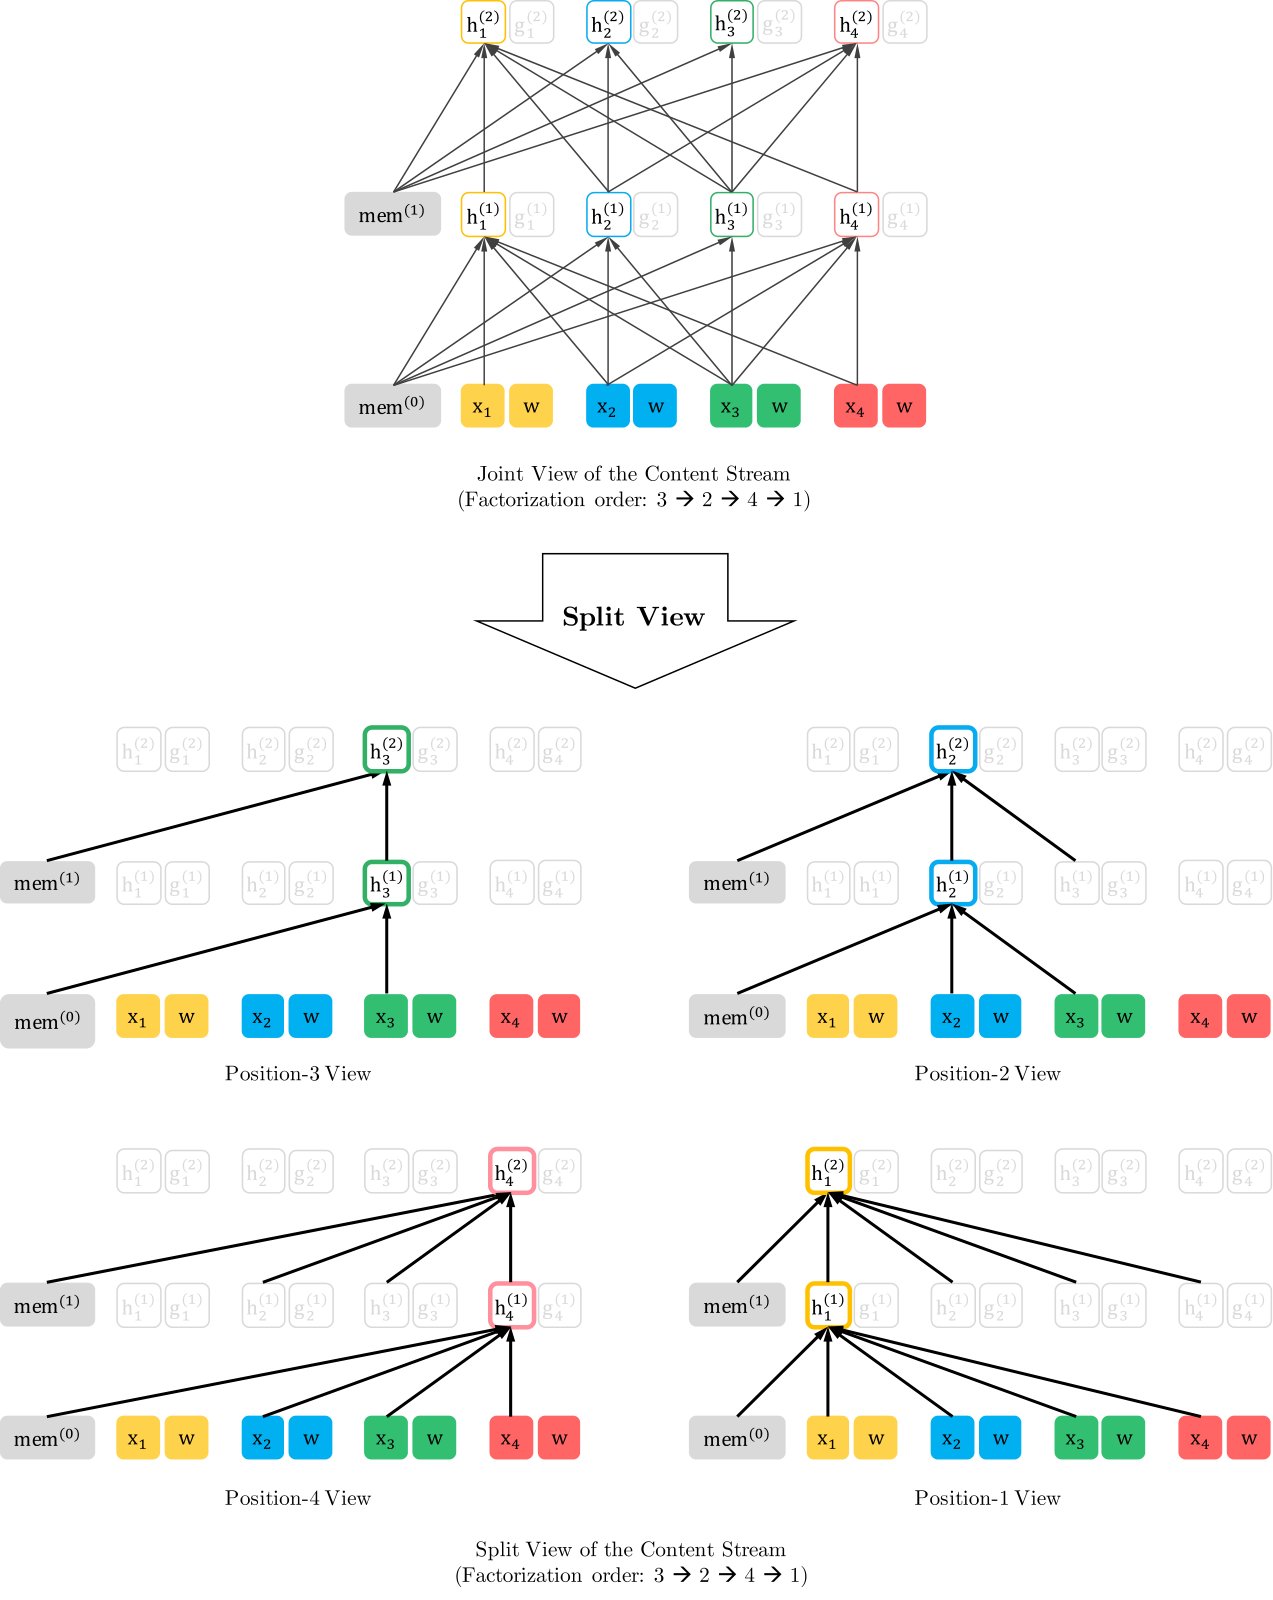
Figure 5: A detailed illustration of the content stream of the proposed objective with both the joint view and split views based on a length-4 sequence under the factorization order [3, 2, 4, 1]. Note that if we ignore the query representation, the computation in this figure is simply the standard self-attention, though with a particular attention mask.
图 5:在分解顺序 [3, 2, 4, 1] 下、基于长度 4 序列,所提目标内容流的详细示意(含联合视图与拆分视图)。注意若忽略查询表示,本图计算就是带特定注意力掩码的标准自注意力。
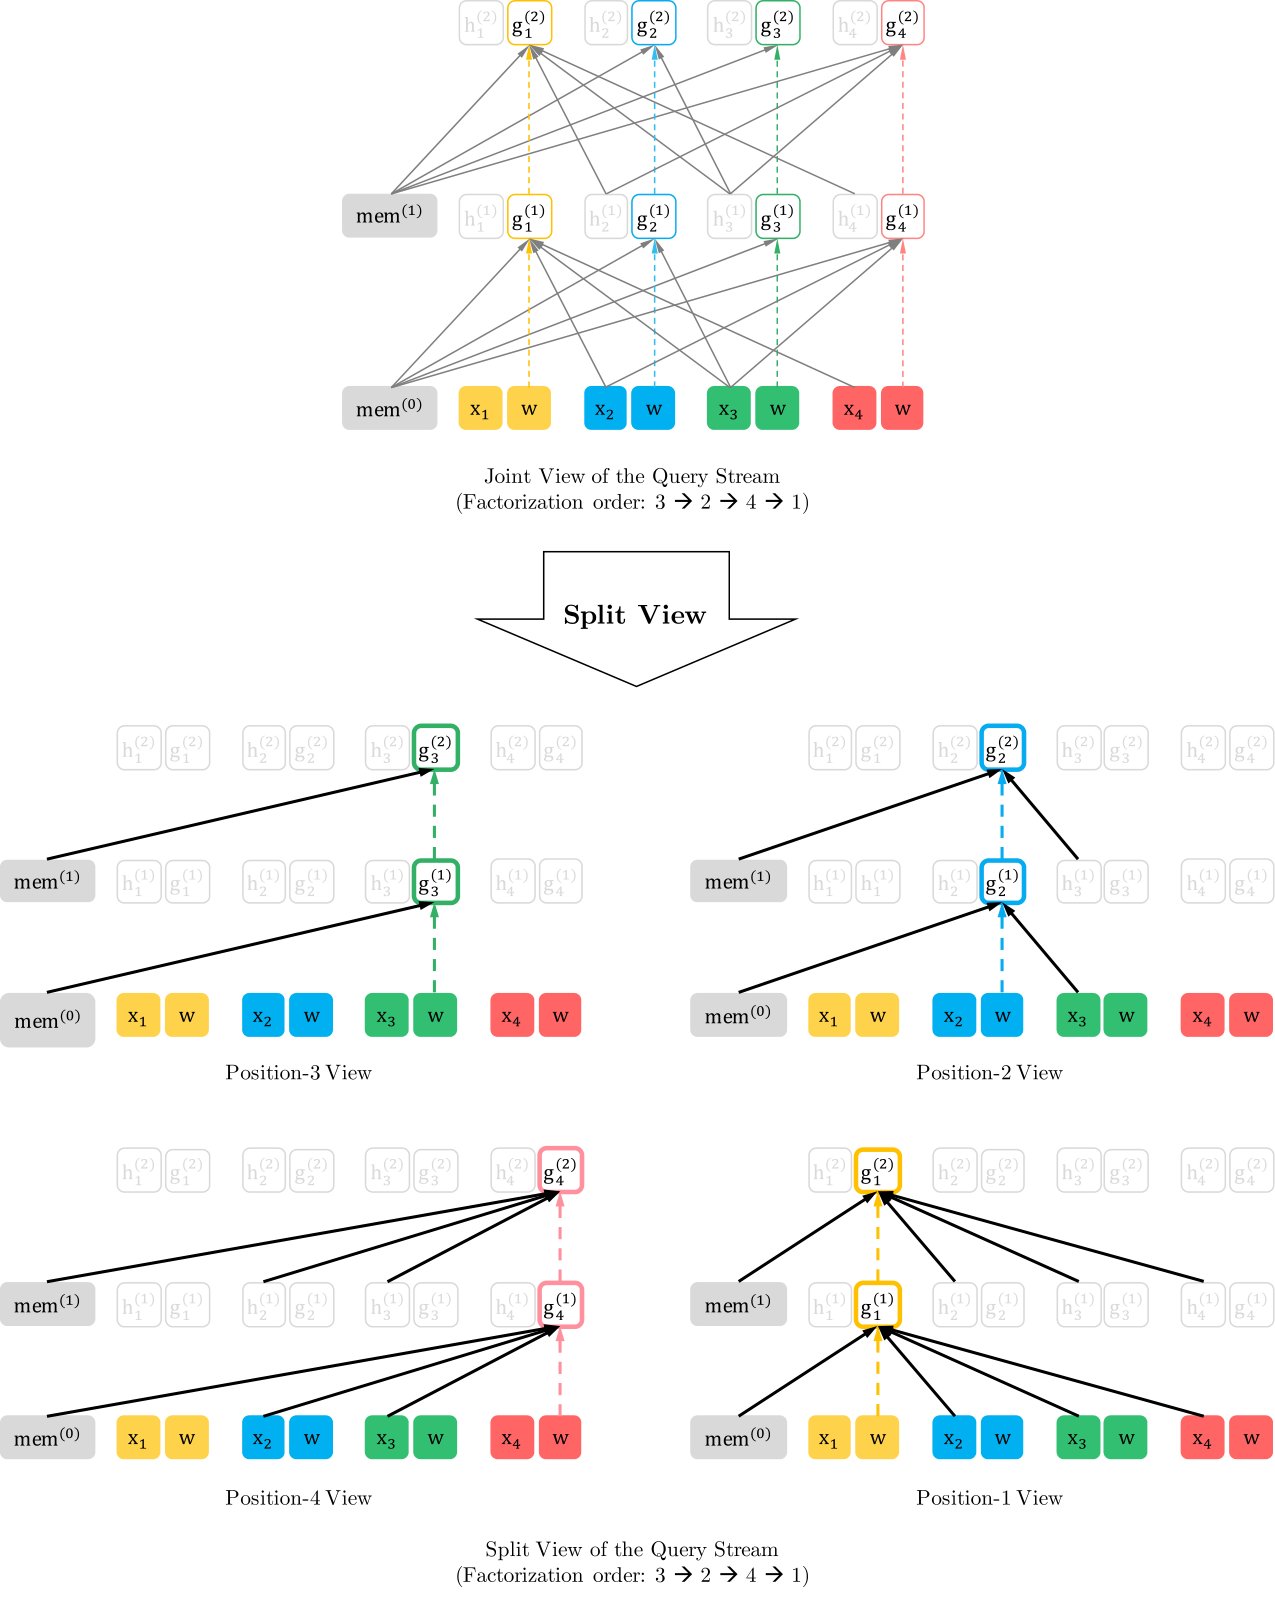
Figure 6: A detailed illustration of the query stream of the proposed objective with both the joint view and split views based on a length-4 sequence under the factorization order [3, 2, 4, 1]. The dash arrows indicate that the query stream cannot access the token (content) at the same position, but only the location information.
图 6:在分解顺序 [3, 2, 4, 1] 下、基于长度 4 序列,所提目标查询流的详细示意(含联合视图与拆分视图)。虚线箭头表示查询流不能访问同位置的词元(内容),只能使用位置信息。