World Models
World Models
世界模型
David Ha Affiliation: Google Brain Jürgen Schmidhuber Affiliation: NNAISENSE Affiliation: Swiss AI Lab, IDSIA (USI & SUPSI)
Abstract
摘要
We explore building generative neural network models of popular reinforcement learning environments. Our world model can be trained quickly in an unsupervised manner to learn a compressed spatial and temporal representation of the environment. By using features extracted from the world model as inputs to an agent, we can train a very compact and simple policy that can solve the required task. We can even train our agent entirely inside of its own hallucinated dream generated by its world model, and transfer this policy back into the actual environment. An interactive version of this paper is available at https://worldmodels.github.io
我们探索为流行的强化学习环境构建生成式神经网络模型。许多先前强化学习研究使用的特征,要么由人类专家手工制作,要么与智能体的策略网络联合训练。我们复现生成式环境模型,并用它训练一个能在该环境中独自运作的智能体。所提智能体可以完全在其自身环境模型生成的幻觉中训练,并把这些策略迁移回实际环境。结合进化策略一类策略搜索方法,我们展示能应对多种视频游戏与机器人任务的实用智能体。例如,智能体成功完成赛车仿真游戏;在 VizDoom 环境中,它甚至可以在不使用任何实际经验、仅在环境模型里训练的情况下击败同行。
1 Introduction
1 引言
Keywords:
Humans develop a mental model of the world based on what they are able to perceive with their limited senses. The decisions and actions we make are based on this internal model. Jay Wright Forrester, the father of system dynamics, described a mental model as:
关键词:
人类根据自己的感知体验,形成关于世界的心智模型。在训练智能体完成任务之前,我们先让它学习自身环境的模型。
The image of the world around us, which we carry in our head, is just a model. Nobody in his head imagines all the world, government or country. He has only selected concepts, and relationships between them, and uses those to represent the real system. (Forrester, 1971)
「我们头脑中携带的周围世界图像,只不过是一个模型。凡是在头脑里操作这个模型时出现的概念,都是预测:用头脑中的模型做的思想实验。」
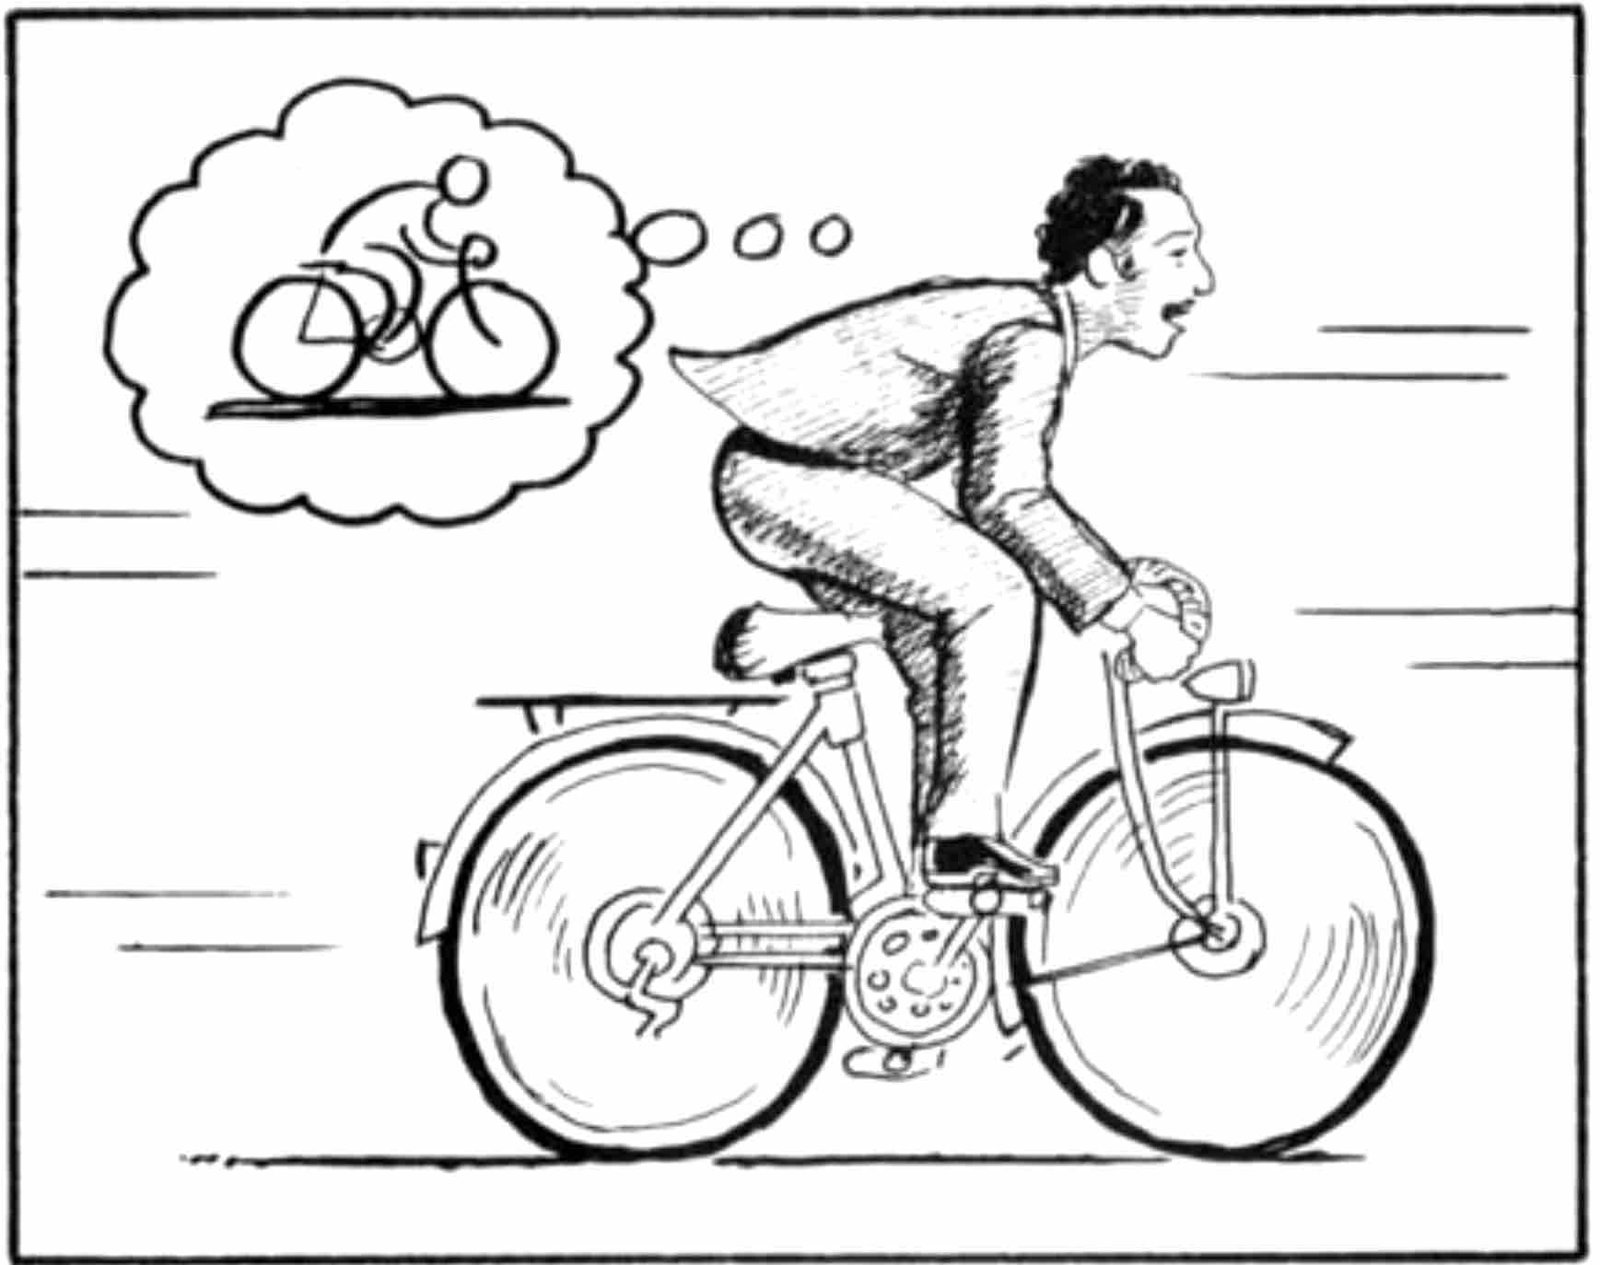
Figure 1: A World Model, from Scott McCloud’s Understanding Comics. (McCloud, 1993; E, 2012)
图 1:世界模型,取自 Scott McCloud 的《理解漫画》。
To handle the vast amount of information that flows through our daily lives, our brain learns an abstract representation of both spatial and temporal aspects of this information. We are able to observe a scene and remember an abstract description thereof (Cheang & Tsao, 2017; Quiroga et al., 2005). Evidence also suggests that what we perceive at any given moment is governed by our brain’s prediction of the future based on our internal model (Nortmann et al., 2015; Gerrit et al., 2013).
为处理每日涌入感官的海量信息,我们的大脑学会复杂的抽象,把信息压缩成并选择性地忽略感知输入。我们的大脑也构建环境的动力学模型,用以推理并预测未来事件的展开。我们作为智能体,由大脑习得的世界模型所引导,并有机会采取将使我们实现目标的行动。
One way of understanding the predictive model inside of our brains is that it might not be about just predicting the future in general, but predicting future sensory data given our current motor actions (Keller et al., 2012; Leinweber et al., 2017). We are able to instinctively act on this predictive model and perform fast reflexive behaviours when we face danger (Mobbs et al., 2015), without the need to consciously plan out a course of action.
理解我们大脑内部预测模型的一种方式是:把它当作生成式模型,受训以模拟我们周围的世界空间。
Take baseball for example. A batter has milliseconds to decide how they should swing the bat – shorter than the time it takes for visual signals to reach our brain. The reason we are able to hit a 100 mph fastball is due to our ability to instinctively predict when and where the ball will go. For professional players, this all happens subconsciously. Their muscles reflexively swing the bat at the right time and location in line with their internal models’ predictions (Gerrit et al., 2013). They can quickly act on their predictions of the future without the need to consciously roll out possible future scenarios to form a plan (Hirshon, 2013).
以棒球为例。击球手只有数毫秒决定如何挥棒,这比视觉信号传到大脑所需时间还短。击球依靠的是大脑对未来的预测,而非直接的感官输入。
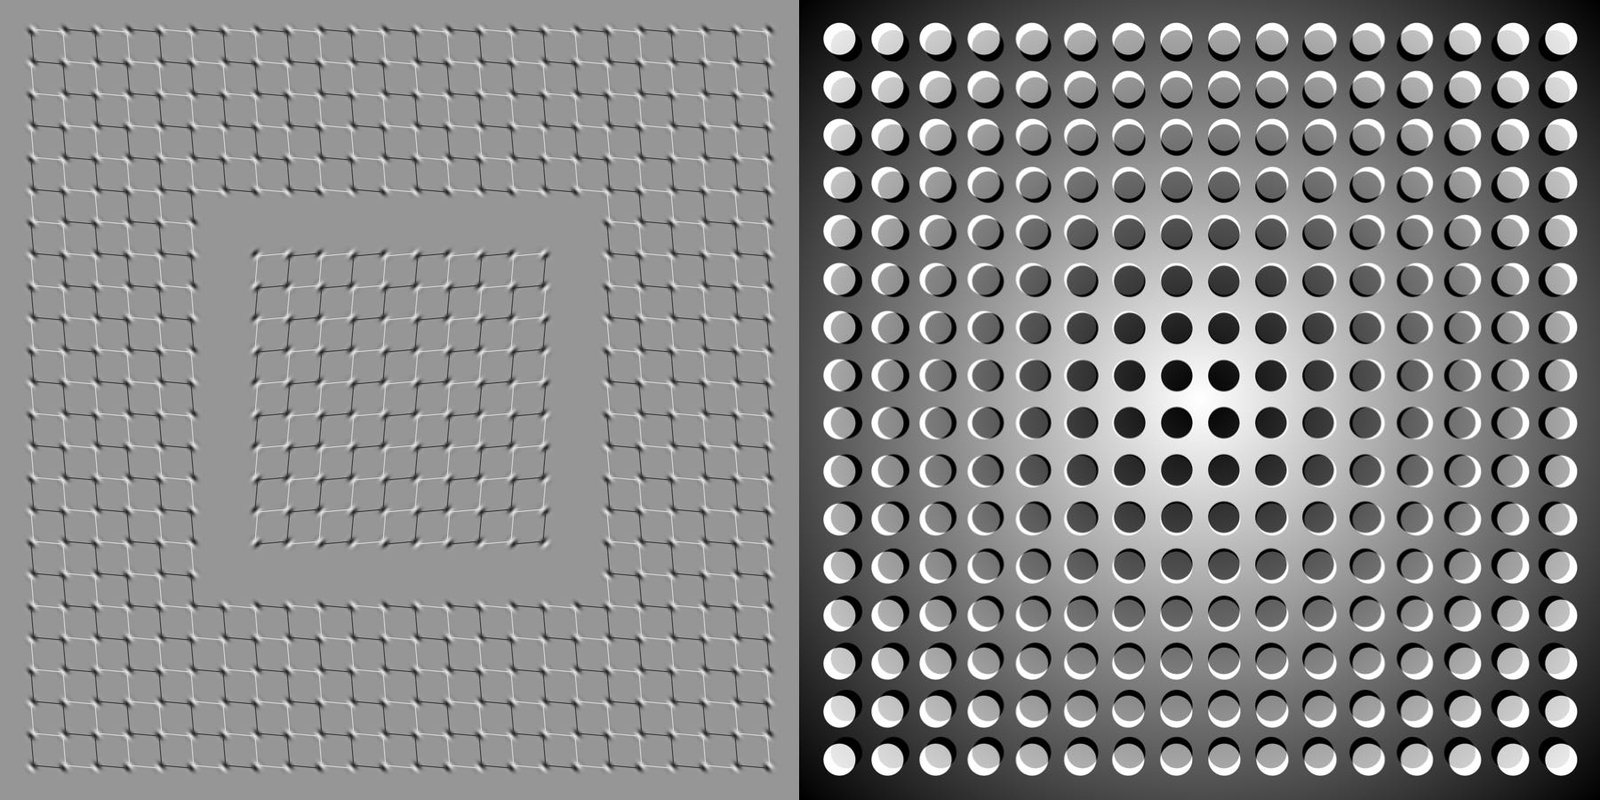
Figure 2: What we see is based on our brain’s prediction of the future (Kitaoka, 2002; Watanabe et al., 2018).
图 2:我们所「看见」的,基于大脑对未来的预测。
In many reinforcement learning (RL) problems (Kaelbling et al., 1996; Sutton & Barto, 1998; Wiering & van Otterlo, 2012), an artificial agent also benefits from having a good representation of past and present states, and a good predictive model of the future (Werbos, 1987; Silver, 2017), preferably a powerful predictive model implemented on a general purpose computer such as a recurrent neural network (RNN) (Schmidhuber, 1990a; Schmidhuber, 1990b; Schmidhuber, 1991a).
在许多强化学习(RL)问题中(Kaelbling 等,1996;Sutton & Barto,1998),智能体同样被限制为一次只接收环境的一次观察,因而必须学习一个内部模型以捕获环境中重要信息。在 RL 文献中,这种内部模型通常是与策略网络联合训练的状态表示。
Figure 3: In this work, we build probabilistic generative models of OpenAI Gym environments. The RNN-based world models are trained using collected observations recorded from the actual game environment. After training the world models, we can use them mimic the complete environment and train agents using them.
图 3:本工作中,我们为 OpenAI Gym 环境构建概率生成模型。
Large RNNs are highly expressive models that can learn rich spatial and temporal representations of data. However, many model-free RL methods in the literature often only use small neural networks with few parameters. The RL algorithm is often bottlenecked by the credit assignment problem, which makes it hard for traditional RL algorithms to learn millions of weights of a large model, hence in practice, smaller networks are used as they iterate faster to a good policy during training.
大型 RNN 是极具表达力的模型,能学习丰富的空间与时间依赖。若我们能训练大型 RNN 来预测 RL 环境中下一步会发生什么,就能把该模型当作虚拟环境,在其中训练智能体。
Ideally, we would like to be able to efficiently train large RNN-based agents. The backpropagation algorithm (Linnainmaa, 1970; Kelley, 1960; Werbos, 1982) can be used to train large neural networks efficiently. In this work we look at training a large neural network[^1] to tackle RL tasks, by dividing the agent into a large world model and a small controller model. We first train a large neural network to learn a model of the agent’s world in an unsupervised manner, and then train the smaller controller model to learn to perform a task using this world model. A small controller lets the training algorithm focus on the credit assignment problem on a small search space, while not sacrificing capacity and expressiveness via the larger world model. By training the agent through the lens of its world model, we show that it can learn a highly compact policy to perform its task.
理想情况下,我们希望高效训练基于大型 RNN 的世界模型,并利用它们作为模拟器去训练策略。这样,实际环境中的样本效率就会提高,因为多数策略训练可在世界模型内完成。
Although there is a large body of research relating to model-based reinforcement learning, this article is not meant to be a review (Arulkumaran et al., 2017; Schmidhuber, 2015b) of the current state of the field. Instead, the goal of this article is to distill several key concepts from a series of papers 1990–2015 on combinations of RNN-based world models and controllers (Schmidhuber, 1990a; Schmidhuber, 1990b; Schmidhuber, 1991a; Schmidhuber, 1990c; Schmidhuber, 2015a). We will also discuss other related works in the literature that share similar ideas of learning a world model and training an agent using this model.
尽管与模型基强化学习相关的研究很多,但先前多数工作并未利用大型生成式神经网络模型的全部表达力。
In this article, we present a simplified framework that we can use to experimentally demonstrate some of the key concepts from these papers, and also suggest further insights to effectively apply these ideas to various RL environments. We use similar terminology and notation as On Learning to Think: Algorithmic Information Theory for Novel Combinations of RL Controllers and RNN World Models (Schmidhuber, 2015a) when describing our methodology and experiments.
本文提出一个简化框架,用以训练大型生成式神经网络模型作为世界模型,并用以训练能在实际环境中运作的智能体。我们把世界模型与控制器分开,先训世界模型,再在其中训控制器。该方法的简单性使我们能把更多算力花在训练更大的世界模型上。
2 Agent Model
2 智能体模型
We present a simple model inspired by our own cognitive system. In this model, our agent has a visual sensory component that compresses what it sees into a small representative code. It also has a memory component that makes predictions about future codes based on historical information. Finally, our agent has a decision-making component that decides what actions to take based only on the representations created by its vision and memory components.
我们提出一个受自身认知系统启发的简单模型。该框架中,智能体有一个视觉感官组件 V,把原始观察压缩成低维隐表示;一个记忆组件 M,做基于历史的预测;以及一个决策组件 C,决定行动。
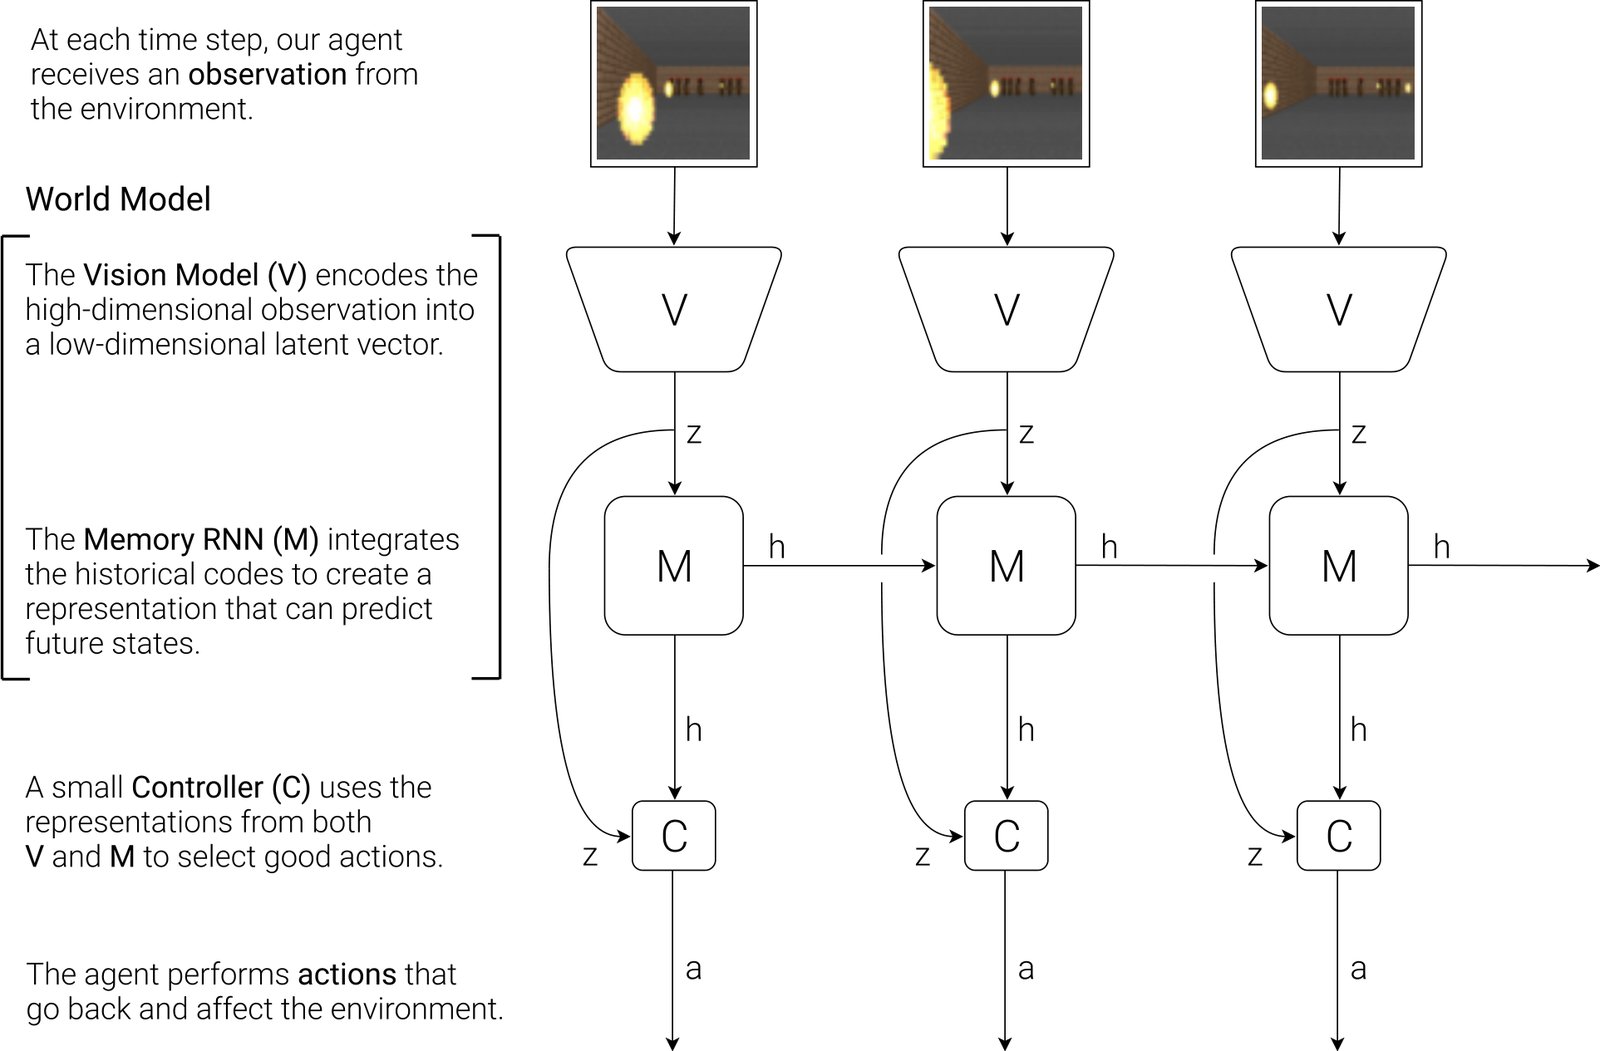
Figure 4: Our agent consists of three components that work closely together: Vision (V), Memory (M), and Controller (C)
图 4:我们的智能体由紧密协作的三个组件构成:视觉模型(V)、记忆模型(M)与控制器(C)。
2.1 VAE (V) Model
2.1 VAE(V)模型
The environment provides our agent with a high dimensional input observation at each time step. This input is usually a 2D image frame that is part of a video sequence. The role of the V model is to learn an abstract, compressed representation of each observed input frame.
环境向智能体提供高维输入观察空间。在本工作中,观察是图像帧。视觉组件的任务是学习压缩所看到内容的抽象表示。
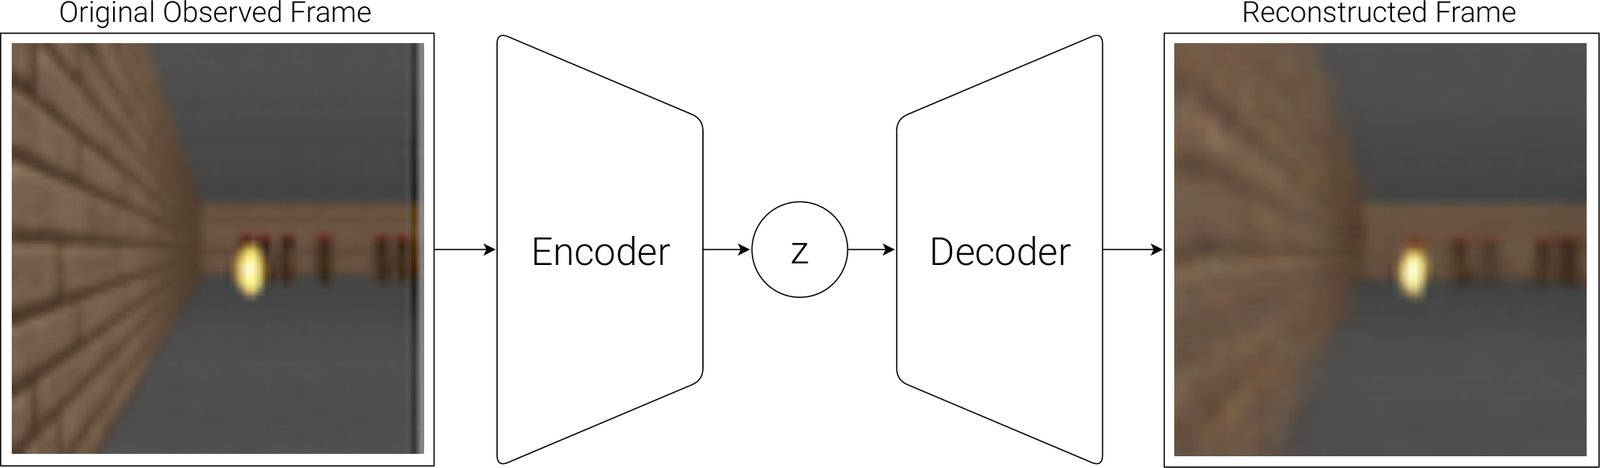
Figure 5: Flow diagram of a Variational Autoencoder (VAE).
图 5:变分自编码器(VAE)流程图。
Here, we use a simple Variational Autoencoder (Kingma & Welling, 2013; Rezende et al., 2014) as our V model to compress each image frame into a small latent vector .
此处我们使用简单的变分自编码器(Kingma & Welling,2013;Rezende 等,2014),把每个图像帧编码成低维隐向量 。
2.2 MDN-RNN (M) Model
2.2 MDN-RNN(M)模型
While it is the role of the V model to compress what the agent sees at each time frame, we also want to compress what happens over time. For this purpose, the role of the M model is to predict the future. The M model serves as a predictive model of the future vectors that V is expected to produce. Since many complex environments are stochastic in nature, we train our RNN to output a probability density function instead of a deterministic prediction of .
V 模型的作用是压缩智能体在每一时刻看到的内容,而 M 模型的作用是从所看到的内容做预测。更具体地,M 模型作为预测模型,估计未来 的概率分布。
Figure 6: RNN with a Mixture Density Network output layer. The MDN outputs the parameters of a mixture of Gaussian distribution used to sample a prediction of the next latent vector .
图 6:带混合密度网络输出层的 RNN。MDN 输出下一隐向量的概率分布参数。
In our approach, we approximate as a mixture of Gaussian distribution, and train the RNN to output the probability distribution of the next latent vector given the current and past information made available to it.
我们的方法中,把 近似为高斯分布的混合,因而可从该分布采样。这使我们能把不确定性与随机性纳入对未来的预测。
More specifically, the RNN will model , where is the action taken at time and is the hidden state of the RNN at time . During sampling, we can adjust a temperature parameter to control model uncertainty, as done in (Ha & Eck, 2017) – we will find adjusting to be useful for training our controller later on.
更具体地,RNN 将建模 ,其中 是智能体在时间 采取的动作, 是 RNN 在时间 的隐状态。
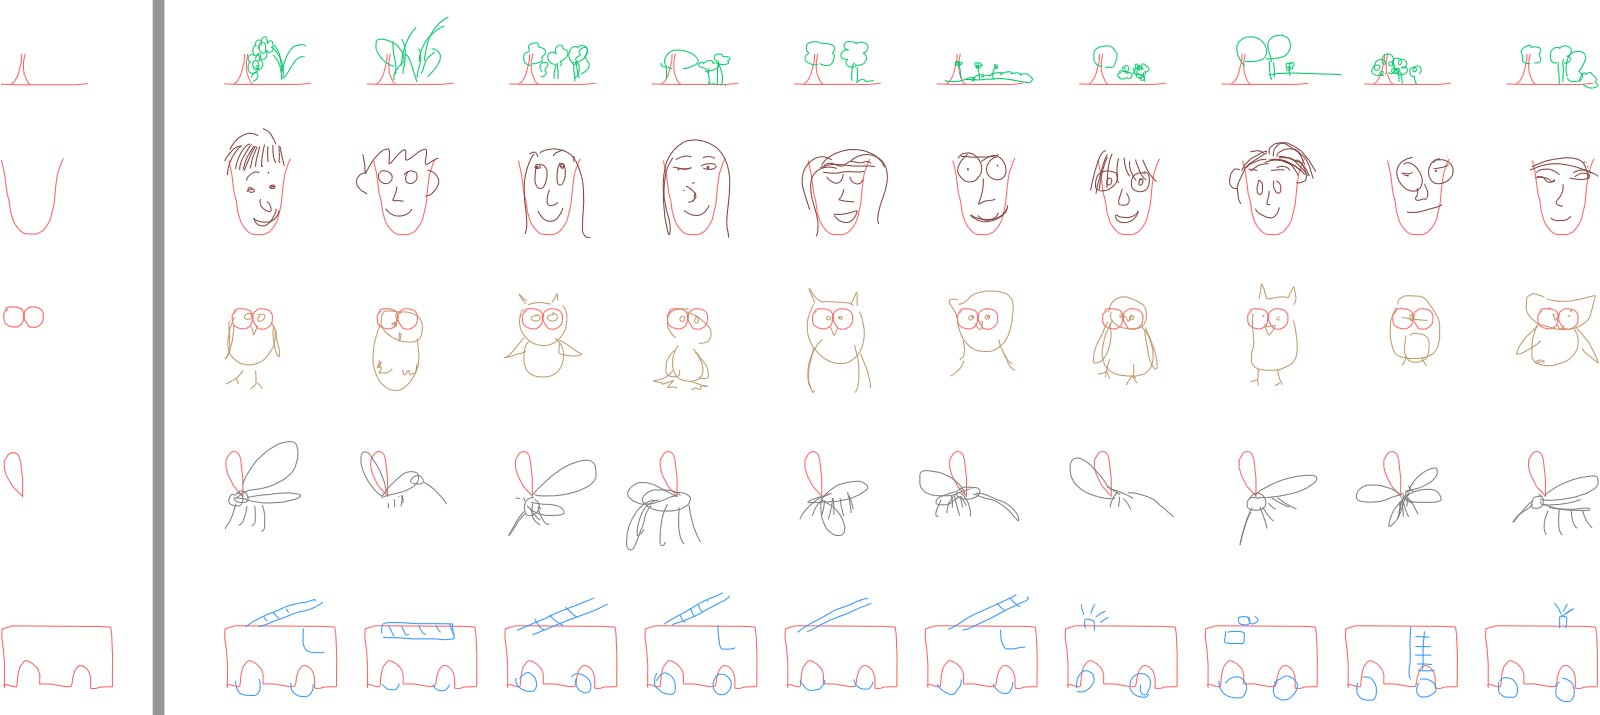
Figure 7: SketchRNN (Ha & Eck, 2017) is an example of a MDN-RNN used to predict the next pen strokes of a sketch drawing. We use a similar model to predict the next latent vector .
图 7:SketchRNN(Ha & Eck,2017)是用 MDN-RNN 生成笔画序列的例子。
This approach is known as a Mixture Density Network (Bishop, 1994) combined with a RNN (MDN-RNN) (Graves, 2013; Ha, 2017a), and has been applied in the past for sequence generation problems such as generating handwriting (Graves, 2013) and sketches (Ha & Eck, 2017).
该方法被称为与 RNN 结合的混合密度网络(Bishop,1994),并已成功用于生成手写与草图一类序列。
2.3 Controller (C) Model
2.3 控制器(C)模型
The Controller (C) model is responsible for determining the course of actions to take in order to maximize the expected cumulative reward of the agent during a rollout of the environment. In our experiments, we deliberately make C as simple and small as possible, and trained separately from V and M, so that most of our agent’s complexity resides in the world model (V and M).
控制器(C)模型负责决定智能体行动的进程。与 V 和 M 不同,C 模型尽可能小且简单。
C is a simple single layer linear model that maps and directly to action at each time step:
C 是简单的单层线性模型,把 与 直接映射为动作 :
In this linear model, and are the weight matrix and bias vector that maps the concatenated input vector to the output action vector .
在该线性模型中, 与 是权重矩阵与偏置向量,也是 C 中仅有的可训练参数。
2.4 Putting V, M, and C Together
2.4 把 V、M 与 C 放在一起
The following flow diagram illustrates how V, M, and C interacts with the environment:
下面的流程图说明 V、M、C 如何与环境交互:
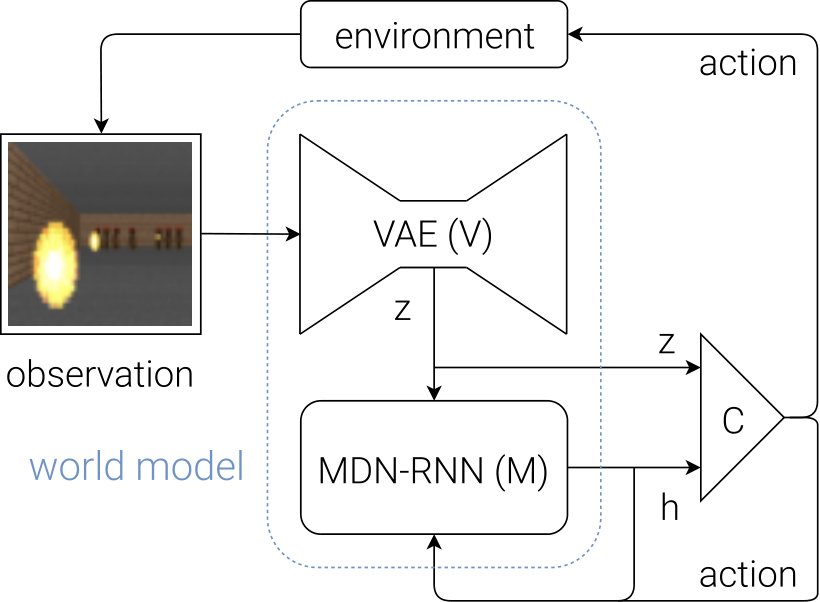
Figure 8: Flow diagram of our Agent model. The raw observation is first processed by V at each time step to produce . The input into C is this latent vector concatenated with M’s hidden state at each time step. C will then output an action vector for motor control, and will affect the environment. M will then take the current and action as an input to update its own hidden state to produce to be used at time .
图 8:智能体模型流程图。原始观察先经 V 编码为 ,再与 M 的隐状态 一并送入 C 以选择动作 。M 用 与 更新其隐状态。
Below is the pseudocode for how our agent model is used in the OpenAI Gym (Brockman et al., 2016) environment:
下面是智能体模型在 OpenAI Gym(Brockman 等,2016)环境中使用方式的伪代码:
Running this function on a given controller C will return the cumulative reward during a rollout.
在给定控制器 C 上运行该函数,将返回累计奖励,用作进化算法的适应度函数。
This minimal design for C also offers important practical benefits. Advances in deep learning provided us with the tools to train large, sophisticated models efficiently, provided we can define a well-behaved, differentiable loss function. Our V and M models are designed to be trained efficiently with the backpropagation algorithm using modern GPU accelerators, so we would like most of the model’s complexity, and model parameters to reside in V and M. The number of parameters of C, a linear model, is minimal in comparison. This choice allows us to explore more unconventional ways to train C – for example, even using evolution strategies (ES) (Rechenberg, 1973; Schwefel, 1977) to tackle more challenging RL tasks where the credit assignment problem is difficult.
C 的极简设计还带来重要实践好处。深度网络训练的进展,以及更大规模数据集与算力,可用于训练更大的世界模型 V 与 M,而不会影响控制器的训练过程。把世界模型与控制器解耦,使我们能把更多算力投入训练更大的世界模型。
To optimize the parameters of C, we chose the Covariance-Matrix Adaptation Evolution Strategy (CMA-ES) (Hansen, 2016; Hansen & Ostermeier, 2001) as our optimization algorithm since it is known to work well for solution spaces of up to a few thousand parameters. We evolve parameters of C on a single machine with multiple CPU cores running multiple rollouts of the environment in parallel.
为优化 C 的参数,我们选择协方差矩阵自适应进化策略(CMA-ES;Hansen,2016)作为我们的优化算法。CMA-ES 是一种流行的基于种群的黑盒优化算法,适合求解困难的优化问题。
For more specific information about the models, training procedures, and environments used in our experiments, please refer to the Appendix section.
关于模型、训练流程与环境的更具体信息,请参阅附录。
3 Car Racing Experiment
3 赛车实验
In this section, we describe how we can train the Agent model described earlier to solve a car racing task. To our knowledge, our agent is the first known solution to achieve the score required to solve this task.[^2]
本节描述如何训练前文所述的智能体模型,以解决 OpenAI Gym 中的 CarRacing-v0 任务(Klimov,2016)。
3.1 World Model for Feature Extraction
3.1 用于特征提取的世界模型
A predictive world model can help us extract useful representations of space and time. By using these features as inputs of a controller, we can train a compact and minimal controller to perform a continuous control task, such as learning to drive from pixel inputs for a top-down car racing environment called CarRacing-v0 (Klimov, 2016).
预测性世界模型可以帮助我们提取关于空间与时间的有用表示。
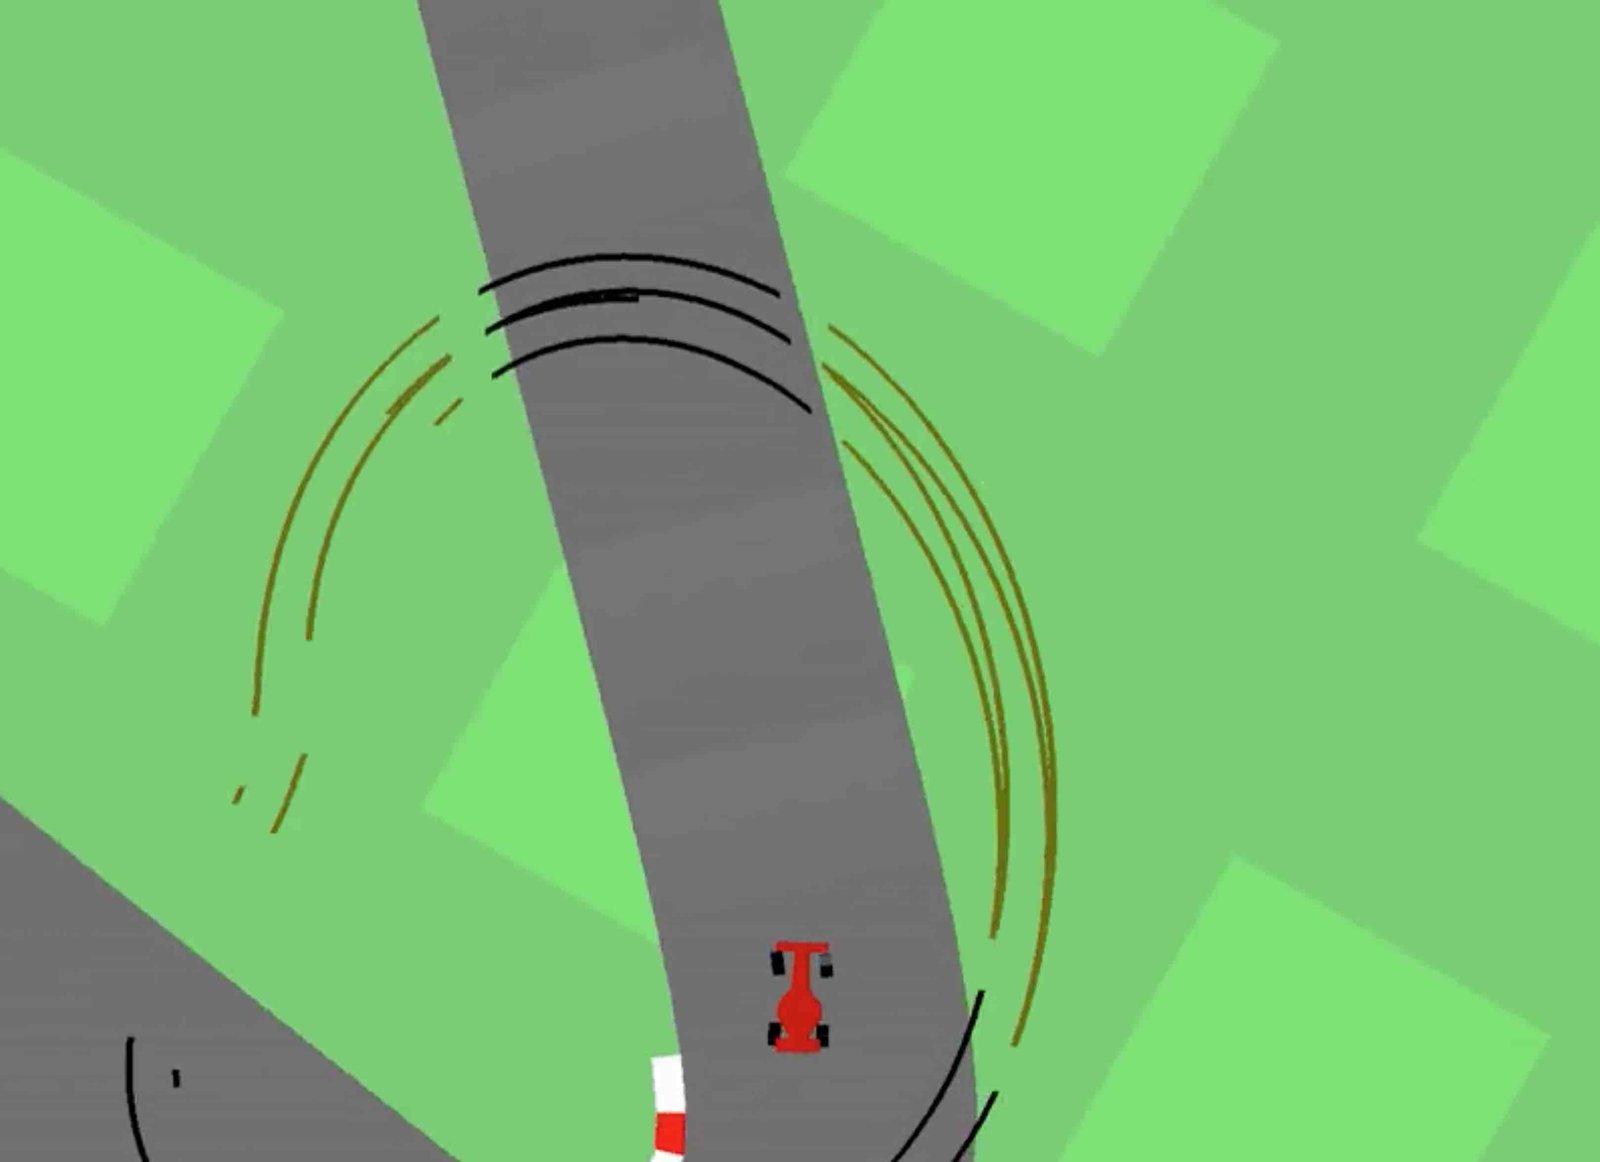
Figure 9: Our agent learning to navigate in CarRacing-v0.
图 9:我们的智能体学习在 CarRacing-v0 中导航。
In this environment, the tracks are randomly generated for each trial, and our agent is rewarded for visiting as many tiles as possible in the least amount of time. The agent controls three continuous actions: steering left/right, acceleration, and brake.
在该环境中,每局赛道随机生成,智能体必须学会从像素输入驾驶汽车。智能体的动作是连续的:转向方向、加速与刹车。
To train our V model, we first collect a dataset of 10,000 random rollouts of the environment. We have first an agent acting randomly to explore the environment multiple times, and record the random actions taken and the resulting observations from the environment. We use this dataset to train V to learn a latent space of each frame observed. We train our VAE to encode each frame into low dimensional latent vector by minimizing the difference between a given frame and the reconstructed version of the frame produced by the decoder from .
为训练 V 模型,我们先收集该环境上 10,000 条随机策略的 rollout。我们把每帧缩放为 64×64 像素,并用这些帧训练 VAE。
We can now use our trained V model to pre-process each frame at time into to train our M model. Using this pre-processed data, along with the recorded random actions taken, our MDN-RNN can now be trained to model as a mixture of Gaussians.[^3]
现在可用训练好的 V 模型,把每一时刻 的帧预处理成 ,并用以训练 M 模型。
In this experiment, the world model (V and M) has no knowledge about the actual reward signals from the environment. Its task is simply to compress and predict the sequence of image frames observed. Only the Controller (C) Model has access to the reward information from the environment. Since there are a mere 867 parameters inside the linear controller model, evolutionary algorithms such as CMA-ES are well suited for this optimization task.
本实验中,世界模型(V 与 M)对实际奖励函数一无所知,只受训去建模环境的观测空间。
We can use the VAE to reconstruct each frame using at each time step to visualize the quality of the information the agent actually sees during a rollout. The figure below is a VAE model trained on screenshots from CarRacing-v0.
我们可用 VAE 在每一步用 重建每一帧,以直观感受压缩过程中损失了哪些信息:
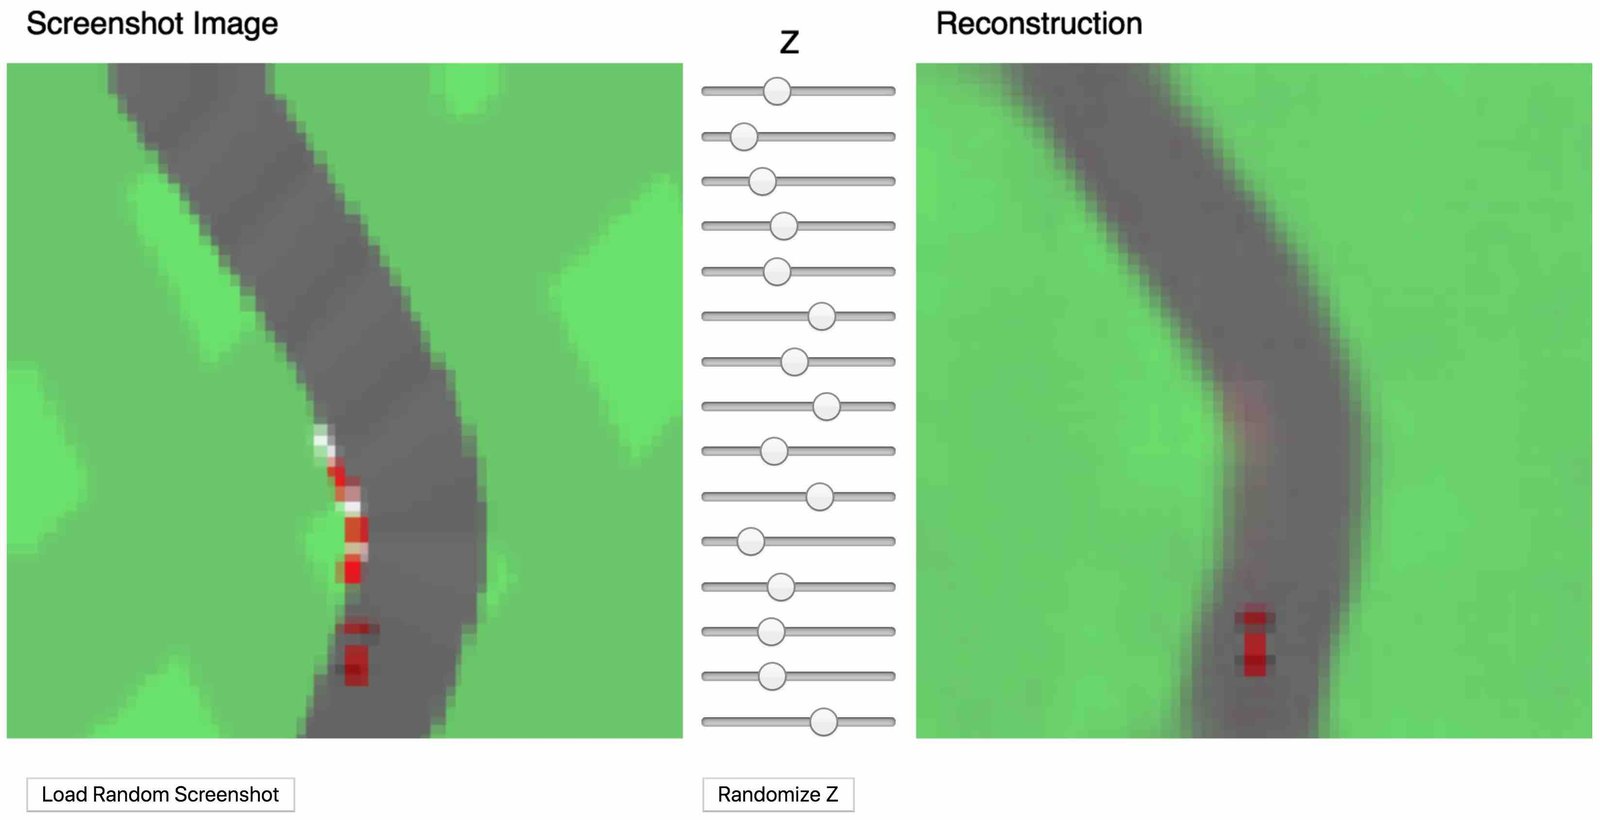
Figure 10: Despite losing details during this lossy compression process, latent vector captures the essence of each image frame.
图 10:尽管有损压缩会丢失细节,隐向量 仍捕获了驾驶所需的本质要素,例如赛道位置与汽车朝向。
In the online version of this article, one can load randomly chosen screenshots to be encoded into a small latent vector , which is used to reconstruct the original screenshot. One can also experiment with adjusting the values of the vector using the slider bars to see how it affects the reconstruction, or randomize to observe the space of possible screenshots.
在本文的在线版本中,可以加载随机选取的游戏截图,并互动探索 VAE 的隐空间。
3.2 Procedure
3.2 流程
To summarize the Car Racing experiment, below are the steps taken:
概括赛车实验,步骤如下:
- Collect 10,000 rollouts from a random policy.
- 从随机策略收集 10,000 条 rollout。
- Train VAE (V) to encode frames into .
- 训练 VAE(V)把帧编码为 。
- Train MDN-RNN (M) to model .
- 训练 MDN-RNN(M)以建模 。
- Define Controller (C) as .
- 定义控制器(C)为 。
- Use CMA-ES to solve for a and that maximizes the expected cumulative reward.
- 用 CMA-ES 求解使期望累计奖励最大的 与 。
| Model | Parameter Count |
|---|---|
| VAE | 4,348,547 |
| MDN-RNN | 422,368 |
| Controller | 867 |
| 模型 | 参数量 |
|---|---|
| VAE | 4,348,547 |
| MDN-RNN | 422,368 |
| Controller | 867 |
3.3 Experiment Results
3.3 实验结果
V Model Only
仅 V 模型
Training an agent to drive is not a difficult task if we have a good representation of the observation. Previous works (Hünermann, 2017; Bling, 2015; Lau, 2016) have shown that with a good set of hand-engineered information about the observation, such as LIDAR information, angles, positions and velocities, one can easily train a small feed-forward network to take this hand-engineered input and output a satisfactory navigation policy. For this reason, we first want to test our agent by handicapping C to only have access to V but not M, so we define our controller as .
若有赛道的良好表示,训练智能体驾驶并不困难。作为对照,我们先在仅用 、不用 的设置下训练智能体。
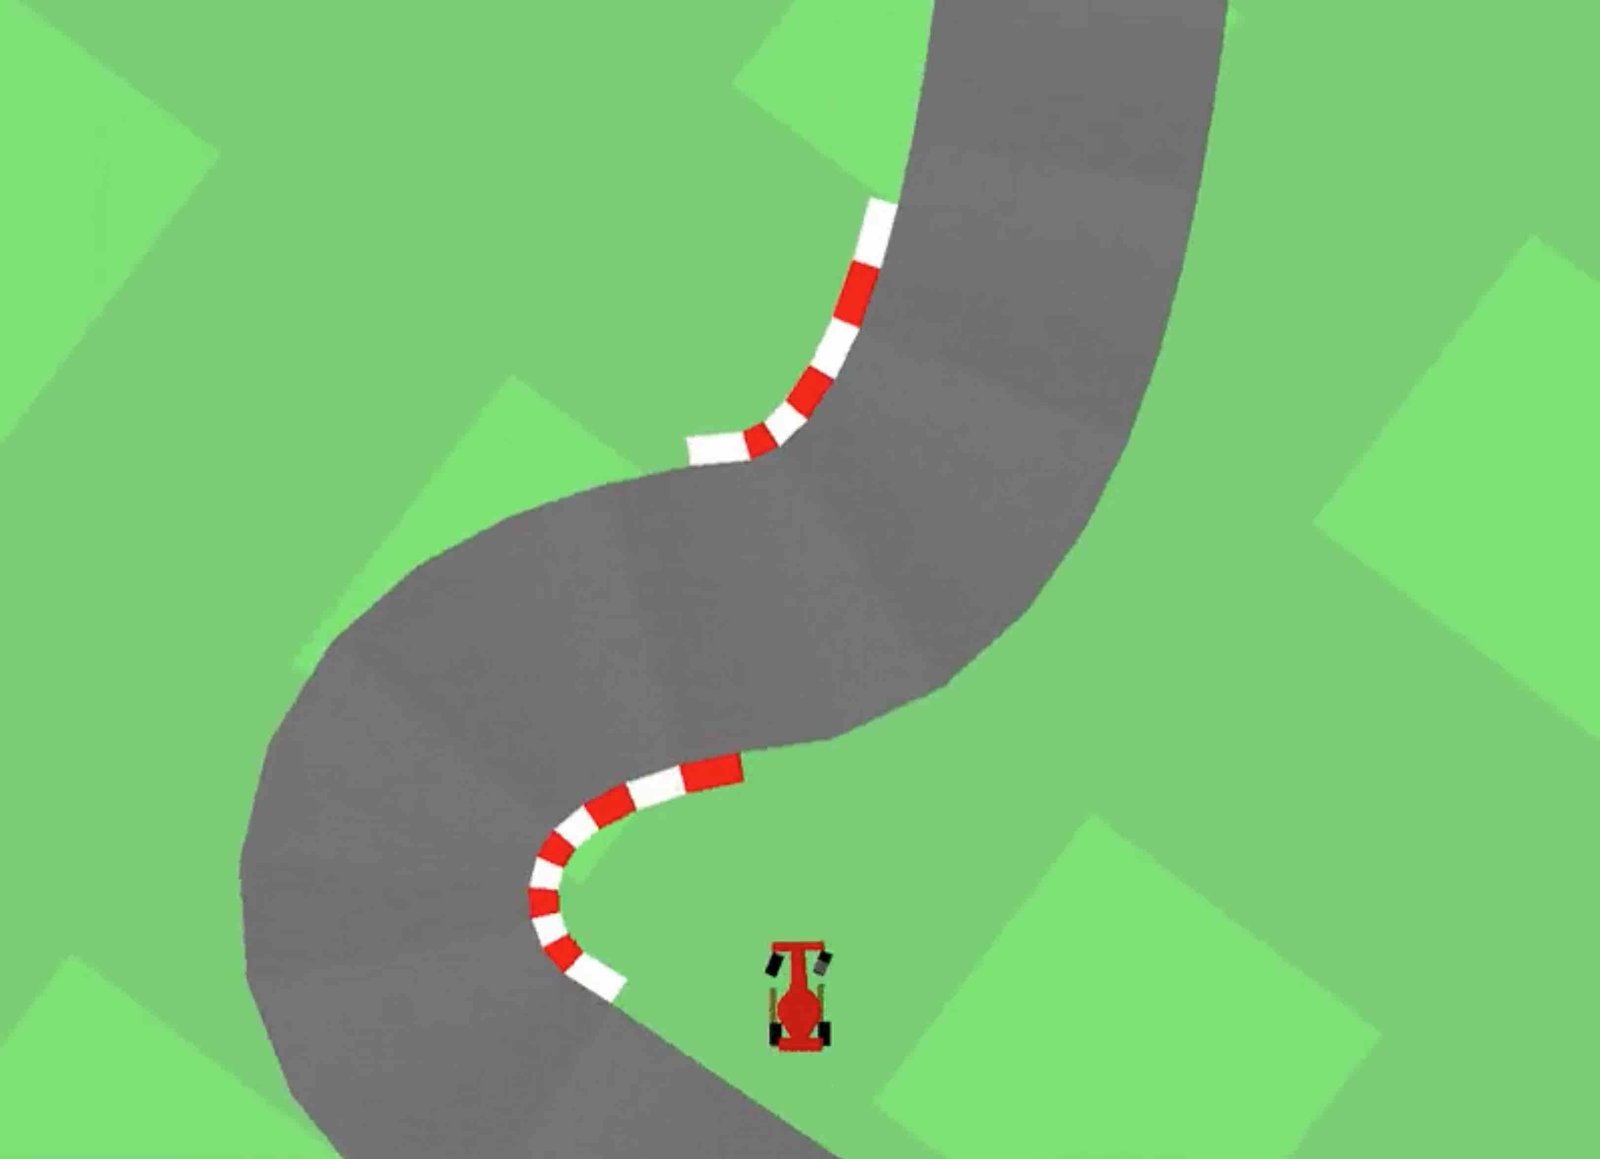
Figure 11: Limiting our controller to see only , but not results in wobbly and unstable driving behaviours.
图 11:把控制器限制为只看 、不看 ,会导致不稳定驾驶。
Although the agent is still able to navigate the race track in this setting, we notice it wobbles around and misses the tracks on sharper corners. This handicapped agent achieved an average score of 632 251 over 100 random trials, in line with the performance of other agents on OpenAI Gym’s leaderboard (Klimov, 2016) and traditional Deep RL methods such as A3C (Khan & Elibol, 2016; Jang et al., 2017). Adding a hidden layer to C’s policy network helps to improve the results to 788 141, but not quite enough to solve this environment.
尽管该设置下智能体仍能在赛道上导航,我们注意到驾驶不稳定,智能体常在弯道处打滑。
Full World Model (V and M)
完整世界模型(V 与 M)
The representation provided by our V model only captures a representation at a moment in time and does not have much predictive power. In contrast, M is trained to do one thing, and to do it really well, which is to predict . Since M’s prediction of is produced from the RNN’s hidden state at time , this vector is a good candidate for the set of learned features we can give to our agent. Combining with gives our controller C a good representation of both the current observation, and what to expect in the future.
V 模型提供的表示 只捕获每一帧的空间信息。若把 M 模型的隐状态 一并交给控制器,智能体就能获得随时间演化的信息。
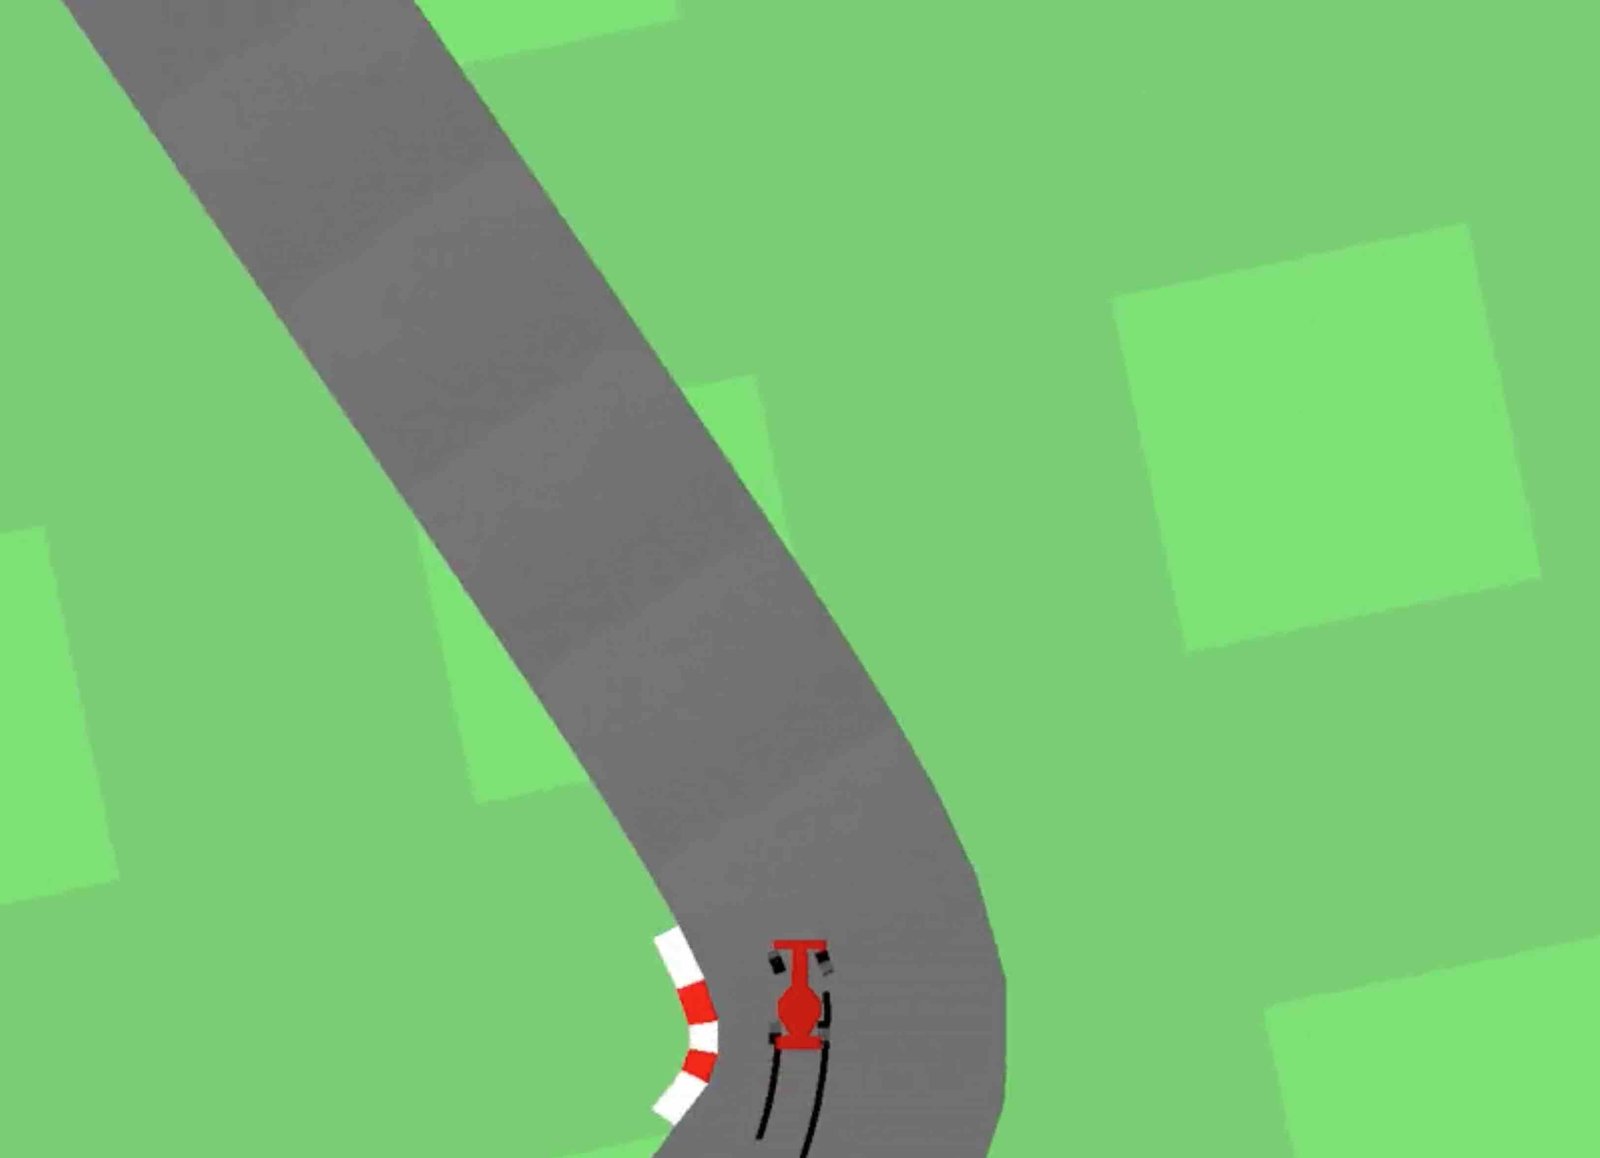
Figure 12: Driving is more stable if we give our controller access to both and .
图 12:若让控制器同时访问 与 ,驾驶更稳定。
We see that allowing the agent to access the both and greatly improves its driving capability. The driving is more stable, and the agent is able to seemingly attack the sharp corners effectively. Furthermore, we see that in making these fast reflexive driving decisions during a car race, the agent does not need to plan ahead and roll out hypothetical scenarios of the future. Since contain information about the probability distribution of the future, the agent can just query the RNN instinctively to guide its action decisions. Like a seasoned Formula One driver or the baseball player discussed earlier, the agent can instinctively predict when and where to navigate in the heat of the moment.
我们看到,让智能体同时访问 与 显著改善了驾驶表现。
| Method | Avg. Score |
|---|---|
| DQN (Prieur, 2017) | 343 18 |
| A3C (continuous) (Jang et al., 2017) | 591 45 |
| A3C (discrete) (Khan & Elibol, 2016) | 652 10 |
| ceobillionaire (Gym Leaderboard) | 838 11 |
| V model | 632 251 |
| V model with hidden layer | 788 141 |
| Full World Model | 906 21 |
Table 1: CarRacing-v0 scores achieved using various methods.
| 方法 | 平均得分 |
|---|---|
| DQN(Prieur,2017) | 343 18 |
| A3C(连续) | 591 45 |
| A3C(离散) | 652 10 |
| 本工作 | 906 21 |
Our agent is able to achieve a score of 906 21 over 100 random trials, effectively solving the task and obtaining new state of the art results. Previous attempts (Khan & Elibol, 2016; Jang et al., 2017) using Deep RL methods obtained average scores of 591–652 range, and the best reported solution on the leaderboard obtained an average score of 838 11 over 100 random trials. Traditional Deep RL methods often require pre-processing of each frame, such as employing edge-detection (Jang et al., 2017), in addition to stacking a few recent frames (Khan & Elibol, 2016; Jang et al., 2017) into the input. In contrast, our world model takes in a stream of raw RGB pixel images and directly learns a spatial-temporal representation. To our knowledge, our method is the first reported solution to solve this task.
我们的智能体在 100 次随机试验上取得 906 21 的得分,有效解决了该任务。据我们所知,这是首次有人用纯视觉输入解决 CarRacing-v0 任务。
3.4 Car Racing Dreams
3.4 赛车梦境
Since our world model is able to model the future, we are also able to have it come up with hypothetical car racing scenarios on its own. We can ask it to produce the probability distribution of given the current states, sample a and use this sample as the real observation. We can put our trained C back into this hallucinated environment generated by M. The following image from an interactive demo in the online version of this article shows how our world model can be used to hallucinate the car racing environment:
由于世界模型能够建模未来,我们也可以让它生成完整的梦境轨迹,并在其中部署策略。
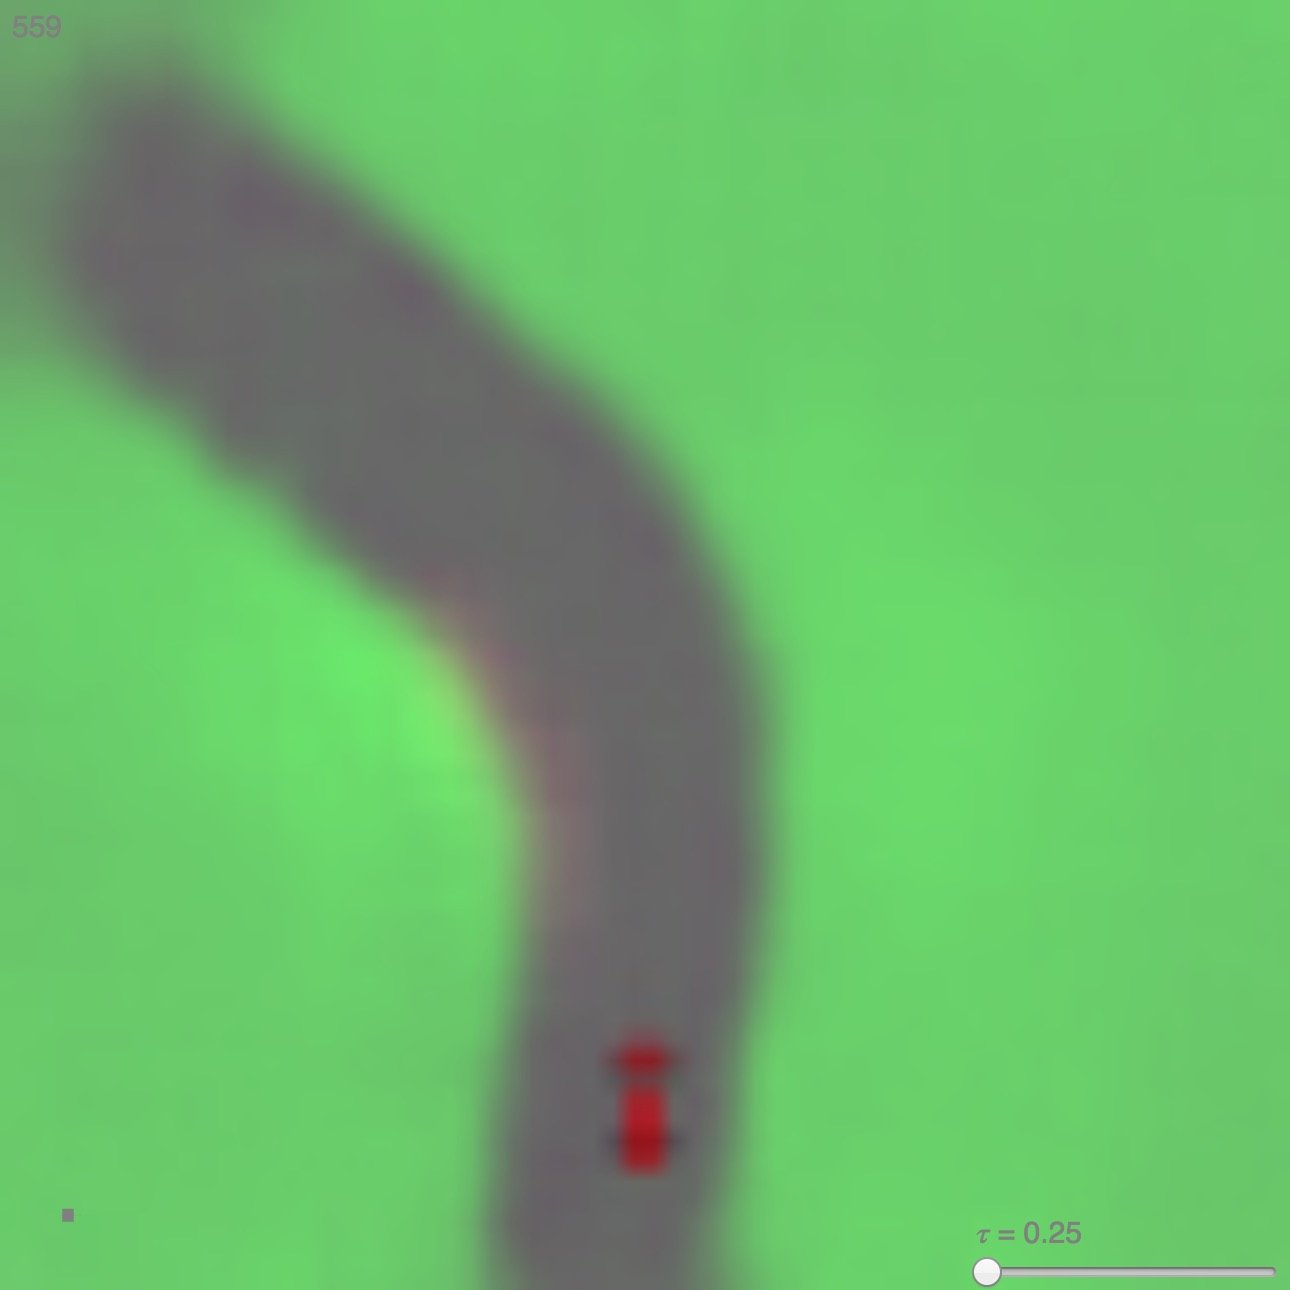
Figure 13: Our agent driving inside of its own dream world. Here, we deploy our trained policy into a fake environment generated by the MDN-RNN, and rendered using the VAE’s decoder. In the demo, one can override the agent’s actions as well as adjust to control the uncertainty of the environment generated by M.
图 13:我们的智能体在自己的梦境世界中驾驶。这里我们把训练好的控制器部署在由 M 模型生成的轨迹上。
4 VizDoom Experiment
4 VizDoom 实验
4.1 Learning Inside of a Dream
4.1 在梦中学习
We have just seen that a policy learned inside of the real environment appears to somewhat function inside of the dream environment. This begs the question – can we train our agent to learn inside of its own dream, and transfer this policy back to the actual environment?
我们刚刚看到,在真实环境中学到的策略,似乎也能在世界模型生成的梦境中运行。那么反过来是否也成立?
If our world model is sufficiently accurate for its purpose, and complete enough for the problem at hand, we should be able to substitute the actual environment with this world model. After all, our agent does not directly observe the reality, but only sees what the world model lets it see. In this experiment, we train an agent inside the hallucination generated by its world model trained to mimic a VizDoom (Kempka et al., 2016) environment.
若世界模型对其用途足够准确,并且完整到足以让智能体在其中实现目标,我们或许能完全在世界模型内部训练智能体,再把策略迁移到实际环境。
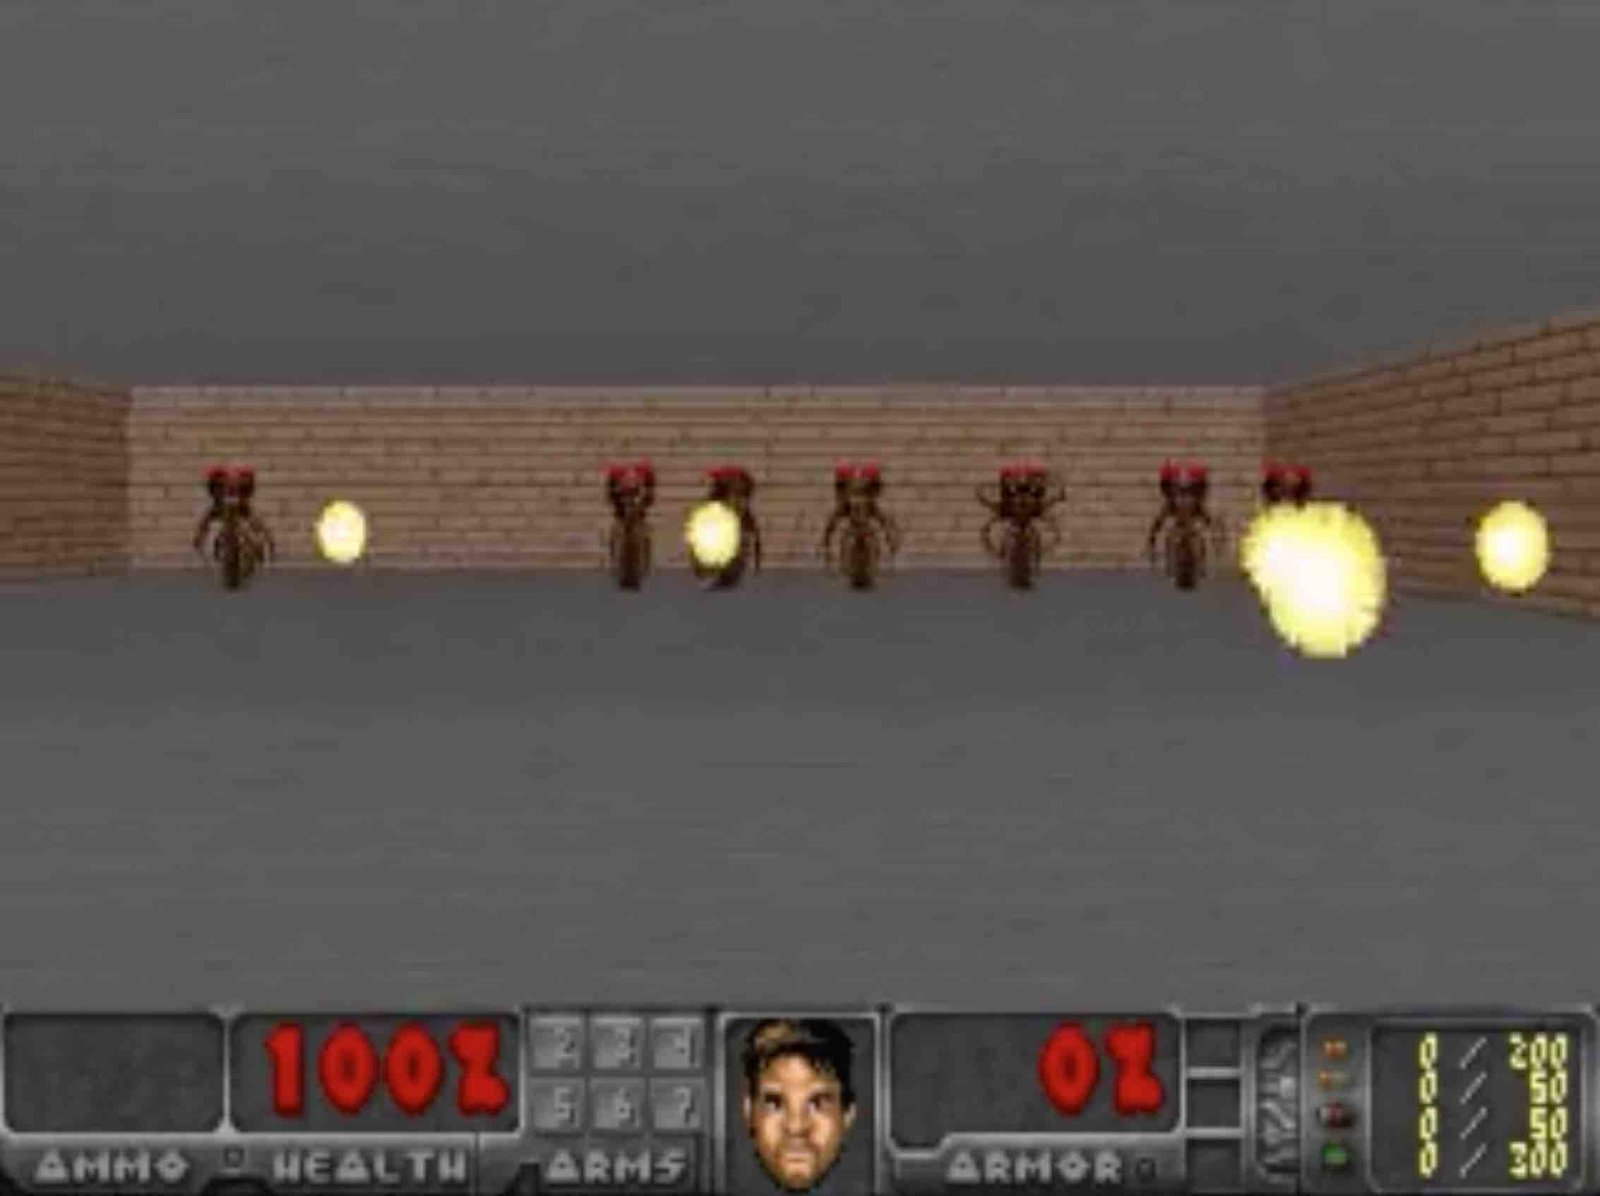
Figure 14: Our final agent solving VizDoom: Take Cover.
图 14:我们的最终智能体在求解 VizDoom: Take Cover。
The agent must learn to avoid fireballs shot by monsters from the other side of the room with the sole intent of killing the agent. There are no explicit rewards in this environment, so to mimic natural selection, the cumulative reward can be defined to be the number of time steps the agent manages to stay alive during a rollout. Each rollout of the environment runs for a maximum of 2100 time steps ( 60 seconds), and the task is considered solved if the average survival time over 100 consecutive rollouts is greater than 750 time steps ( 20 seconds) (Paquette, 2016).
智能体必须学会躲避另一侧怪物射出的火球。智能体每多存活一个时间步就获得奖励,因此必须学习生存策略。
4.2 Procedure
4.2 流程
The setup of our VizDoom experiment is largely the same as the Car Racing task, except for a few key differences. In the Car Racing task, M is only trained to model the next . Since we want to build a world model we can train our agent in, our M model here will also predict whether the agent dies in the next frame (as a binary event , or for short), in addition to the next frame .
VizDoom 实验的设置与赛车任务大体相同,但有若干关键改动。
Since the M model can predict the state in addition to the next observation, we now have all of the ingredients needed to make a full RL environment. We first build an OpenAI Gym environment interface by wrapping a gym.Env interface over our M if it were a real Gym environment, and then train our agent inside of this virtual environment instead of using the actual environment.
由于 M 模型除了下一观测还能预测 状态,我们可以把世界模型当作完整的虚拟环境来训练控制器。
In this simulation, we do not need the V model to encode any real pixel frames during the hallucination process, so our agent will therefore only train entirely in a latent space environment. This has many advantages as we will see.
在该仿真中,训练控制器期间我们不需要 V 模型编码任何真实像素帧——智能体完全在自己的梦境中运行。
This virtual environment has an identical interface to the real environment, so after the agent learns a satisfactory policy in the virtual environment, we can easily deploy this policy back into the actual environment to see how well the policy transfers over.
该虚拟环境与真实环境接口相同,因此我们能用同一套代码在梦境或实际环境中训练与测试策略。
To summarize the Take Cover experiment, below are the steps taken:
概括 Take Cover 实验,步骤如下:
- Collect 10,000 rollouts from a random policy.
- 从随机策略收集 10,000 条 rollout。
- Train VAE (V) to encode each frame into a latent vector , and use V to convert the images collected from (1) into the latent space representation.
- 训练 VAE(V)把每帧编码为隐向量 。
- Train MDN-RNN (M) to model .
- 训练 MDN-RNN(M)以建模 。
- Define Controller (C) as .
- 定义控制器(C)为 。
- Use CMA-ES to solve for a that maximizes the expected survival time inside the virtual environment.
- 用 CMA-ES 求解使梦境中期望存活时间最大的 。
- Use learned policy from (5) on actual environment.
- 把(5)中学到的策略用到实际环境。
| Model | Parameter Count |
|---|---|
| VAE | 4,446,915 |
| MDN-RNN | 1,678,785 |
| Controller | 1,088 |
| 模型 | 参数量 |
|---|---|
| VAE | 4,446,915 |
| MDN-RNN | 1,678,785 |
| Controller | 1,088 |
4.3 Training Inside of the Dream
4.3 在梦境中训练
After some training, our controller learns to navigate around the dream environment and escape from deadly fireballs launched by monsters generated by M. Our agent achieved a score of 900 time steps in the virtual environment.
经过一段时间训练后,我们的控制器学会在梦境环境中导航,并躲避虚拟怪物发射的火球。
Figure 15: Our agent discovers a policy to avoid hallucinated fireballs. In the online version of this article, the reader can interact with the environment inside this demo.
图 15:我们的智能体发现躲避幻觉火球的策略。在线版本中可观看智能体在梦境中游玩。
Here, our RNN-based world model is trained to mimic a complete game environment designed by human programmers. By learning only from raw image data collected from random episodes, it learns how to simulate the essential aspects of the game – such as the game logic, enemy behaviour, physics, and also the 3D graphics rendering.
在这里,基于 RNN 的世界模型受训去模仿由人类设计的完整游戏环境。因此,像实际游戏一样,它必须学会隐含地建模游戏物理、敌人行为,甚至游戏逻辑。
For instance, if the agent selects the left action, the M model learns to move the agent to the left and adjust its internal representation of the game states accordingly. It also learns to block the agent from moving beyond the walls on both sides of the level if the agent attempts to move too far in either direction. Occasionally, the M model needs to keep track of multiple fireballs being shot from several different monsters and coherently move them along in their intended directions. It must also detect whether the agent has been killed by one of these fireballs.
例如,若智能体选择向左的动作,M 模型会学会把智能体移向左侧,并相应调整场景。
Unlike the actual game environment, however, we note that it is possible to add extra uncertainty into the virtual environment, thus making the game more challenging in the dream environment. We can do this by increasing the temperature parameter during the sampling process of . By increasing the uncertainty, our dream environment becomes more difficult compared to the actual environment. The fireballs may move more randomly in a less predictable path compared to the actual game. Sometimes the agent may even die due to sheer misfortune, without explanation.
然而与实际游戏环境不同,我们注意到可以为 M 模型生成的观测分布添加额外不确定性。通过调节温度参数 ,我们可控制梦境中的随机性程度。
We find agents that perform well in higher temperature settings generally perform better in the normal setting. In fact, increasing helps prevent our controller from taking advantage of the imperfections of our world model – we will discuss this in more depth later on.
我们发现,在更高温度设置下表现良好的智能体,通常在实际环境中也表现更好。
4.4 Transfer Policy to Actual Environment
4.4 把策略迁移到实际环境
Figure 16: Deploying our policy learned inside of the dream RNN environment back into the actual VizDoom environment.
图 16:把在梦境 RNN 环境中学到的策略部署回实际 Doom 环境。
We took the agent trained inside of the virtual environment and tested its performance on the original VizDoom scenario. The score over 100 random consecutive trials is 1100 time steps, far beyond the required score of 750 time steps, and also much higher than the score obtained inside the more difficult virtual environment.
我们把在虚拟环境中训练的智能体拿到实际环境上测试其表现,发现策略能够成功迁移。
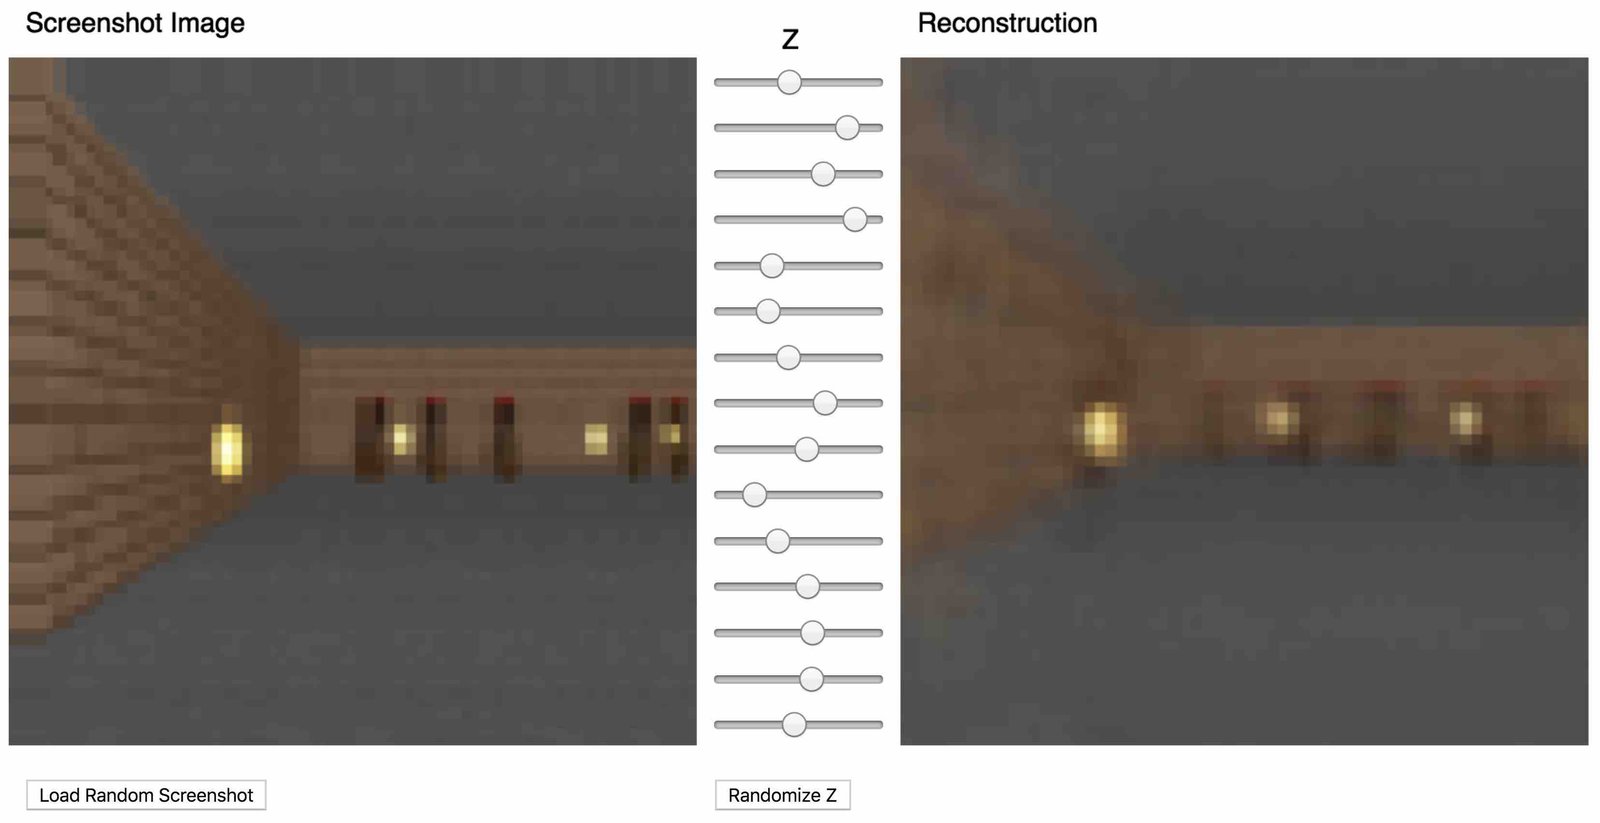
Figure 17: An interactive VAE of Doom in the online article.
图 17:在线文章中的可交互 Doom VAE。
We see that even though the V model is not able to capture all of the details of each frame correctly, for instance, getting the number of monsters correct, the agent is still able to use the learned policy to navigate in the real environment. As the virtual environment cannot even keep track of the exact number of monsters in the first place, an agent that is able to survive the noisier and uncertain virtual nightmare environment will thrive in the original, cleaner environment.
我们看到,尽管 V 模型无法捕获每帧的全部细节,隐空间表示对智能体学会在实际环境中生存已经足够。
4.5 Cheating the World Model
4.5 钻世界模型的空子
In our childhood, we may have encountered ways to exploit video games in ways that were not intended by the original game designer (Wikipedia, 2017). Players discover ways to collect unlimited lives or health, and by taking advantage of these exploits, they can easily complete an otherwise difficult game. However, in the process of doing so, they may have forfeited the opportunity to learn the skill required to master the game as intended by the game designer.
童年时,我们可能遇到过以设计者未曾料到的方式利用电子游戏漏洞的情形。
For instance, in our initial experiments, we noticed that our agent discovered an adversarial policy to move around in such a way so that the monsters in this virtual environment governed by the M model never shoots a single fireball during some rollouts. Even when there are signs of a fireball forming, the agent will move in a way to extinguish the fireballs magically as if it has superpowers in the environment.
例如,在初始实验中,我们注意到智能体发现了一种对抗性策略:让怪物朝某个方向射击,使火球互相碰撞并消失。
Because our world model is only an approximate probabilistic model of the environment, it will occasionally generate trajectories that do not follow the laws governing the actual environment. As we saw previously, even the number of monsters on the other side of the room in the actual environment is not exactly reproduced by the world model. Like a child who learns that objects in the air usually fall to the ground, the child might also imagine unrealistic superheroes who fly across the sky. For this reason, our world model will be exploitable by the controller, even if in the actual environment such exploits do not exist.
因为世界模型只是环境的近似概率模型,它必然有缺陷。智能体有动力去探索并利用这些缺陷,从而在虚拟环境中获得更高分数。
And since we are using the M model to generate a virtual dream environment for our agent, we are also giving the controller access to all of the hidden states of M. This is essentially granting our agent access to all of the internal states and memory of the game engine, rather than only the game observations that the player gets to see. Therefore our agent can efficiently explore ways to directly manipulate the hidden states of the game engine in its quest to maximize its expected cumulative reward. The weakness of this approach of learning a policy inside a learned dynamics model is that our agent can easily find an adversarial policy that can fool our dynamics model – it’ll find a policy that looks good under our dynamics model, but will fail in the actual environment, usually because it visits states where the model is wrong because they are away from the training distribution.
又因为我们用 M 模型为智能体生成虚拟梦境环境,若智能体能利用 M 的缺陷,它就能在梦境中获得很高分数,却无法把策略迁移到实际环境。
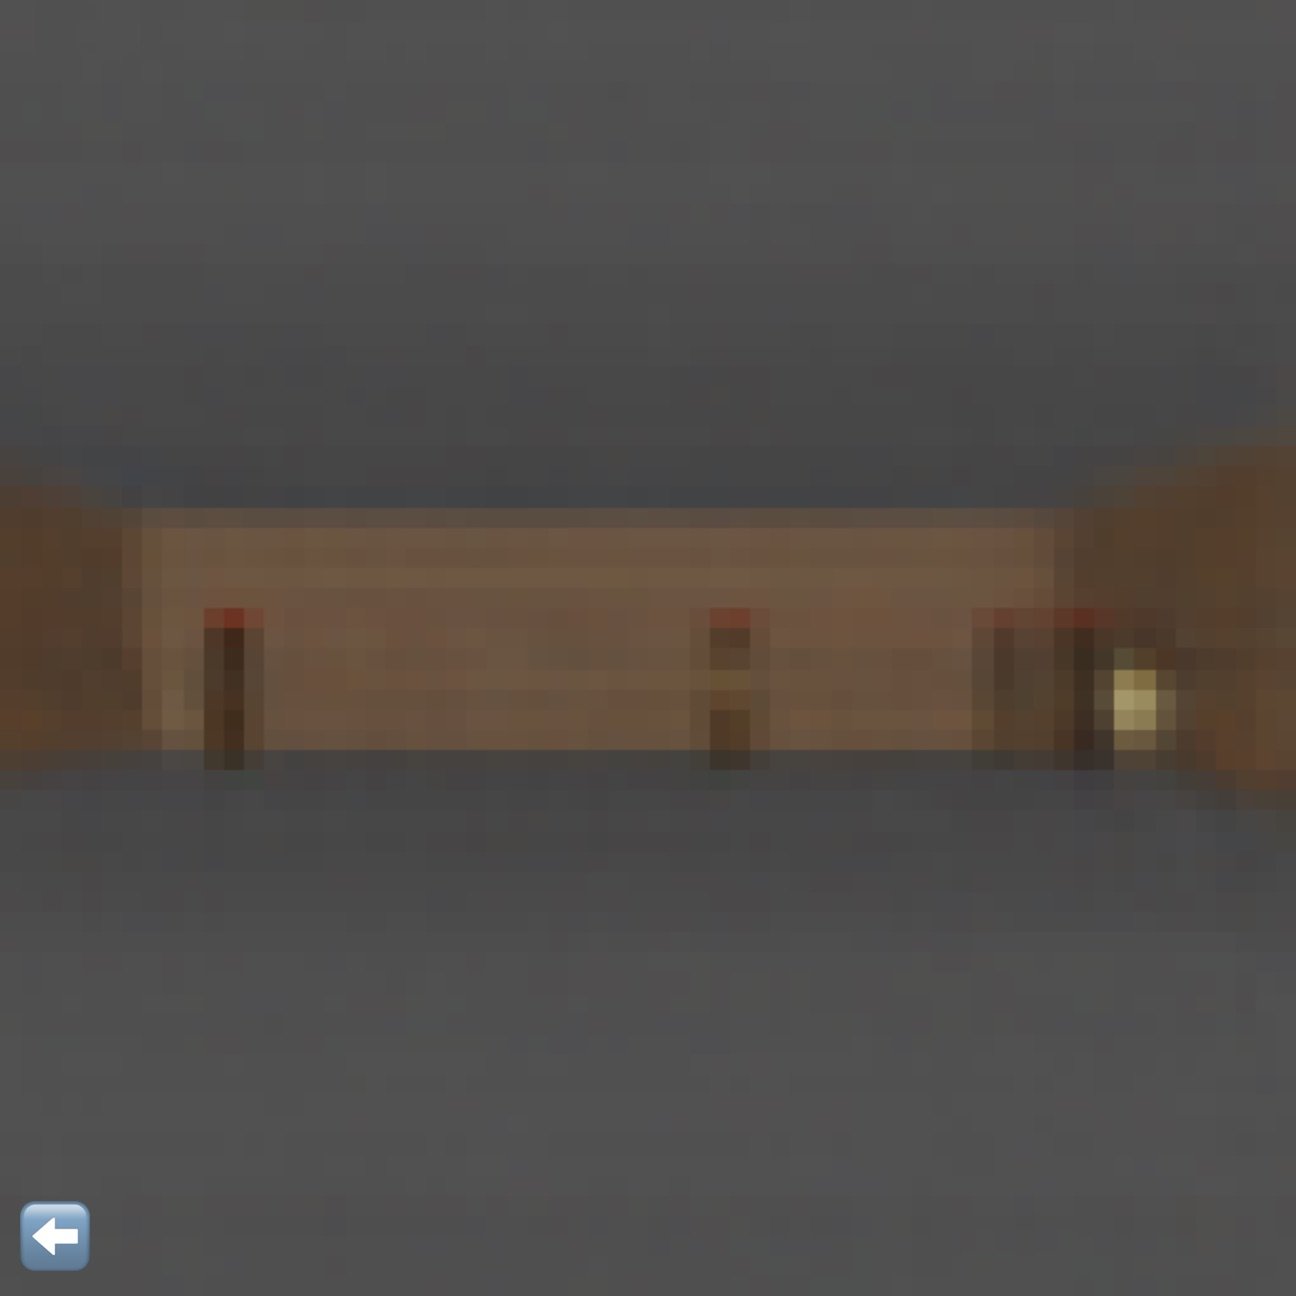
Figure 18: Agent discovers an adversarial policy to automatically extinguish fireballs after they are fired during some rollouts.
图 18:智能体发现对抗性策略,在被怪物看见后自动熄灭火球。
This weakness could be the reason that many previous works that learn dynamics models of RL environments but do not actually use those models to fully replace the actual environments (Oh et al., 2015; Chiappa et al., 2017). Like in the M model proposed in (Schmidhuber, 1990a; Schmidhuber, 1990b; Schmidhuber, 1991a), the dynamics model is a deterministic model, making the model easily exploitable by the agent if it is not perfect. Using Bayesian models, as in PILCO (Deisenroth & Rasmussen, 2011), helps to address this issue with the uncertainty estimates to some extent, however, they do not fully solve the problem. Recent work (Nagabandi et al., 2017) combines the model-based approach with traditional model-free RL training by first initializing the policy network with the learned policy, but must subsequently rely on model-free methods to fine-tune this policy in the actual environment.
这一弱点或许正是许多先前学习 RL 环境动力学模型、并仅用该模型训练策略的工作,难以把策略迁移回实际环境的原因。
In Learning to Think (Schmidhuber, 2015a), it is acceptable that the RNN M is not always a reliable predictor. A (potentially evolution-based) RNN C can in principle learn to ignore a flawed M, or exploit certain useful parts of M for arbitrary computational purposes including hierarchical planning etc. This is not what we do here though – our present approach is still closer to some of the older systems (Schmidhuber, 1990a; Schmidhuber, 1990b; Schmidhuber, 1991a), where a RNN M is used to predict and plan ahead step by step. Unlike this early work, however, we use evolution for C (like in Learning to Think) rather than traditional RL combined with RNNs, which has the advantage of both simplicity and generality.
在 Learning to Think(Schmidhuber,2015a)中,可以接受 RNN M 并不总是完美的,因为控制器 C 是在真实环境中训练的,只把 M 当作可查询的内部模型。
To make it more difficult for our C model to exploit deficiencies of the M model, we chose to use the MDN-RNN as the dynamics model, which models the distribution of possible outcomes in the actual environment, rather than merely predicting a deterministic future. Even if the actual environment is deterministic, the MDN-RNN would in effect approximate it as a stochastic environment. This has the advantage of allowing us to train our C model inside a more stochastic version of any environment – we can simply adjust the temperature parameter to control the amount of randomness in the M model, hence controlling the tradeoff between realism and exploitability.
为使 C 模型更难利用 M 模型的缺陷,我们选择在梦境中使用较高的温度参数,使预测分布更随机、更难利用。
Using a mixture of Gaussian model may seem like overkill given that the latent space encoded with the VAE model is just a single diagonal Gaussian distribution. However, the discrete modes in a mixture density model is useful for environments with random discrete events, such as whether a monster decides to shoot a fireball or stay put. While a single diagonal Gaussian might be sufficient to encode individual frames, a RNN with a mixture density output layer makes it easier to model the logic behind a more complicated environment with discrete random states.
鉴于 VAE 编码的隐空间已近似服从高斯先验,使用高斯混合模型看似小题大做;但我们发现混合密度输出对建模随机环境很有用。
For instance, if we set the temperature parameter to a very low value of , effectively training our C model with a M model that is almost identical to a deterministic LSTM, the monsters inside this dream environment fail to shoot fireballs, no matter what the agent does, due to mode collapse. The M model is not able to jump to another mode in the mixture of Gaussian model where fireballs are formed and shot. Whatever policy learned inside of this dream will achieve a perfect score of 2100 most of the time, but will obviously fail when unleashed into the harsh reality of the actual world, underperforming even a random policy.
例如,若把温度参数设为极低的 ,使梦境几乎变为确定性,智能体就容易发现对抗策略,在梦境中拿到高分,却无法迁移到实际环境。
Note again, however, that the simpler and more robust approach in Learning to Think does not insist on using M for step by step planning. Instead, C can learn to use M’s subroutines (parts of M’s weight matrix) for arbitrary computational purposes but can also learn to ignore M when M is useless and when ignoring M yields better performance. Nevertheless, at least in our present C–M variant, M’s predictions are essential for teaching C, more like in some of the early C–M systems (Schmidhuber, 1990a; Schmidhuber, 1990b; Schmidhuber, 1991a), but combined with evolution or black box optimization.
不过同样要注意,Learning to Think 中更简单且更稳健的做法并不要求温度调节,因为策略是在真实环境中训练的。
By making the temperature an adjustable parameter of the M model, we can see the effect of training the C model on hallucinated virtual environments with different levels of uncertainty, and see how well they transfer over to the actual environment. We experimented with varying the temperature of the virtual environment and observing the resulting average score over 100 random rollouts of the actual environment after training the agent inside of the virtual environment with a given temperature:
通过把温度 设为 M 模型的可调参数,我们可以看到它如何影响策略迁移:
| Temperature | Virtual Score | Actual Score |
|---|---|---|
| 0.10 | 2086 140 | 193 58 |
| 0.50 | 2060 277 | 196 50 |
| 1.00 | 1145 690 | 868 511 |
| 1.15 | 918 546 | 1092 556 |
| 1.30 | 732 269 | 753 139 |
| Random Policy | N/A | |
| Gym Leader | N/A |
Table 2: Take Cover scores at various temperature settings.
| 温度 | 虚拟得分 | 实际得分 |
|---|---|---|
| 0.10 | 2086 140 | 193 58 |
| 0.15 | 2060 282 | 170 67 |
| 0.50 | 1565 529 | 368 173 |
| 1.00 | 1092 556 | 868 511 |
| 1.15 | 933 505 | 1092 556 |
| 1.30 | 756 270 | 753 139 |
We see that while increasing the temperature of the M model makes it more difficult for the C model to find adversarial policies, increasing it too much will make the virtual environment too difficult for the agent to learn anything, hence in practice it is a hyperparameter we can tune. The temperature also affects the types of strategies the agent discovers. For example, although the best score obtained is 1092 556 with , increasing a notch to 1.30 results in a lower score but at the same time a less risky strategy with a lower variance of returns. For comparison, the best score on the OpenAI Gym leaderboard (Paquette, 2016) is 820 58.
我们看到,提高 M 模型的温度会使控制器更难在梦境中获得高分,但学到的策略通常能更好地迁移到实际环境。
5 Iterative Training Procedure
5 迭代训练流程
In our experiments, the tasks are relatively simple, so a reasonable world model can be trained using a dataset collected from a random policy. But what if our environments become more sophisticated? In any difficult environment, only parts of the world are made available to the agent only after it learns how to strategically navigate through its world.
在我们的实验中,任务相对简单,因此用随机策略收集的数据就能训练出合理的世界模型。
For more complicated tasks, an iterative training procedure is required. We need our agent to be able to explore its world, and constantly collect new observations so that its world model can be improved and refined over time. An iterative training procedure (Schmidhuber, 2015a) is as follows:
对于更复杂的任务,需要迭代训练流程。我们需要智能体探索实际环境的更多区域,才能改进世界模型。
- Initialize M, C with random model parameters.
- 用随机模型参数初始化 M、C。
- Rollout to actual environment times. Save all actions and observations during rollouts to storage.
- 在实际环境中 rollout 次。保存所有动作 与观测 。
- Train M to model and train C to optimize expected rewards inside of M.
- 训练 M 以建模 ,并训练 C 以最大化累计奖励。
- Go back to (2) if task has not been completed.
- 若任务尚未完成,回到(2)。
We have shown that one iteration of this training loop was enough to solve simple tasks. For more difficult tasks, we need our controller in Step 2 to actively explore parts of the environment that is beneficial to improve its world model. An exciting research direction is to look at ways to incorporate artificial curiosity and intrinsic motivation (Schmidhuber, 2010; Schmidhuber, 2006; Schmidhuber, 1991b; Pathak et al., 2017; Oudeyer et al., 2007) and information seeking (Schmidhuber et al., 1994; Gottlieb et al., 2013) abilities in an agent to encourage novel exploration (Lehman & Stanley, 2011). In particular, we can augment the reward function based on improvement in compression quality (Schmidhuber, 2010; Schmidhuber, 2006; Schmidhuber, 1991b; Schmidhuber, 2015a).
我们已经表明,对该类简单任务,训练环路迭代一次就够。对更难的任务,我们相信需要更多轮迭代。
In the present approach, since M is a MDN-RNN that models a probability distribution for the next frame, if it does a poor job, then it means the agent has encountered parts of the world that it is not familiar with. Therefore we can adapt and reuse M’s training loss function to encourage curiosity. By flipping the sign of M’s loss function in the actual environment, the agent will be encouraged to explore parts of the world that it is not familiar with. The new data it collects may improve the world model.
在当前方法中,由于 M 是为下一观测建模概率分布的 MDN-RNN,我们可以用它生成额外的梦境轨迹,甚至在实际环境的 rollout 之外增强训练数据。
The iterative training procedure requires the M model to not only predict the next observation and , but also predict the action and reward for the next time step. This may be required for more difficult tasks. For instance, if our agent needs to learn complex motor skills to walk around its environment, the world model will learn to imitate its own C model that has already learned to walk. After difficult motor skills, such as walking, is absorbed into a large world model with lots of capacity, the smaller C model can rely on the motor skills already absorbed by the world model and focus on learning more higher level skills to navigate itself using the motor skills it had already learned.
迭代训练流程要求 M 模型不仅预测下一观测,还预测奖励、动作与终止信号,使梦境环境更完整。
Figure 19: How information becomes memory.
图 19:信息如何成为记忆。
An interesting connection to the neuroscience literature is the work on hippocampal replay that examines how the brain replays recent experiences when an animal rests or sleeps. Replaying recent experiences plays an important role in memory consolidation (Foster, 2017) – where hippocampus-dependent memories become independent of the hippocampus over a period of time. As (Foster, 2017) puts it, replay is less like dreaming and more like thought. We invite readers to read Replay Comes of Age (Foster, 2017) for a detailed overview of replay from a neuroscience perspective with connections to theoretical reinforcement learning.
与神经科学文献的一个有趣联系是关于海马回放的研究:动物在睡眠或休息时会在海马中重放近期经历,据信这有助于记忆巩固与学习。
Iterative training could allow the C–M model to develop a natural hierarchical way to learn. Recent works about self-play in RL (Sukhbaatar et al., 2017; Bansal et al., 2017; Al-Shedivat et al., 2017) and PowerPlay (Schmidhuber, 2013; Srivastava et al., 2012) also explores methods that lead to a natural curriculum learning (Schmidhuber, 2002), and we feel this is one of the more exciting research areas of reinforcement learning.
迭代训练可能使 C–M 模型发展出学习复杂任务的自然层次方式,先学局部技能,再组合成更复杂行为。
6 Related Work
6 相关工作
There is extensive literature on learning a dynamics model, and using this model to train a policy. Many concepts first explored in the 1980s for feed-forward neural networks (FNNs) (Werbos, 1987; Munro, 1987; Robinson & Fallside, 1989; Werbos, 1989; Nguyen & Widrow, 1989) and in the 1990s for RNNs (Schmidhuber, 1990a; Schmidhuber, 1990b; Schmidhuber, 1991a; Schmidhuber, 1990c) laid some of the groundwork for Learning to Think (Schmidhuber, 2015a). The more recent PILCO (Deisenroth & Rasmussen, 2011; Duvenaud, 2016; McAllister & Rasmussen, 2016) is a probabilistic model-based search policy method designed to solve difficult control problems. Using data collected from the environment, PILCO uses a Gaussian process (GP) model to learn the system dynamics, and then uses this model to sample many trajectories in order to train a controller to perform a desired task, such as swinging up a pendulum, or riding a unicycle.
学习动力学模型并用该模型训练策略的文献非常丰富。
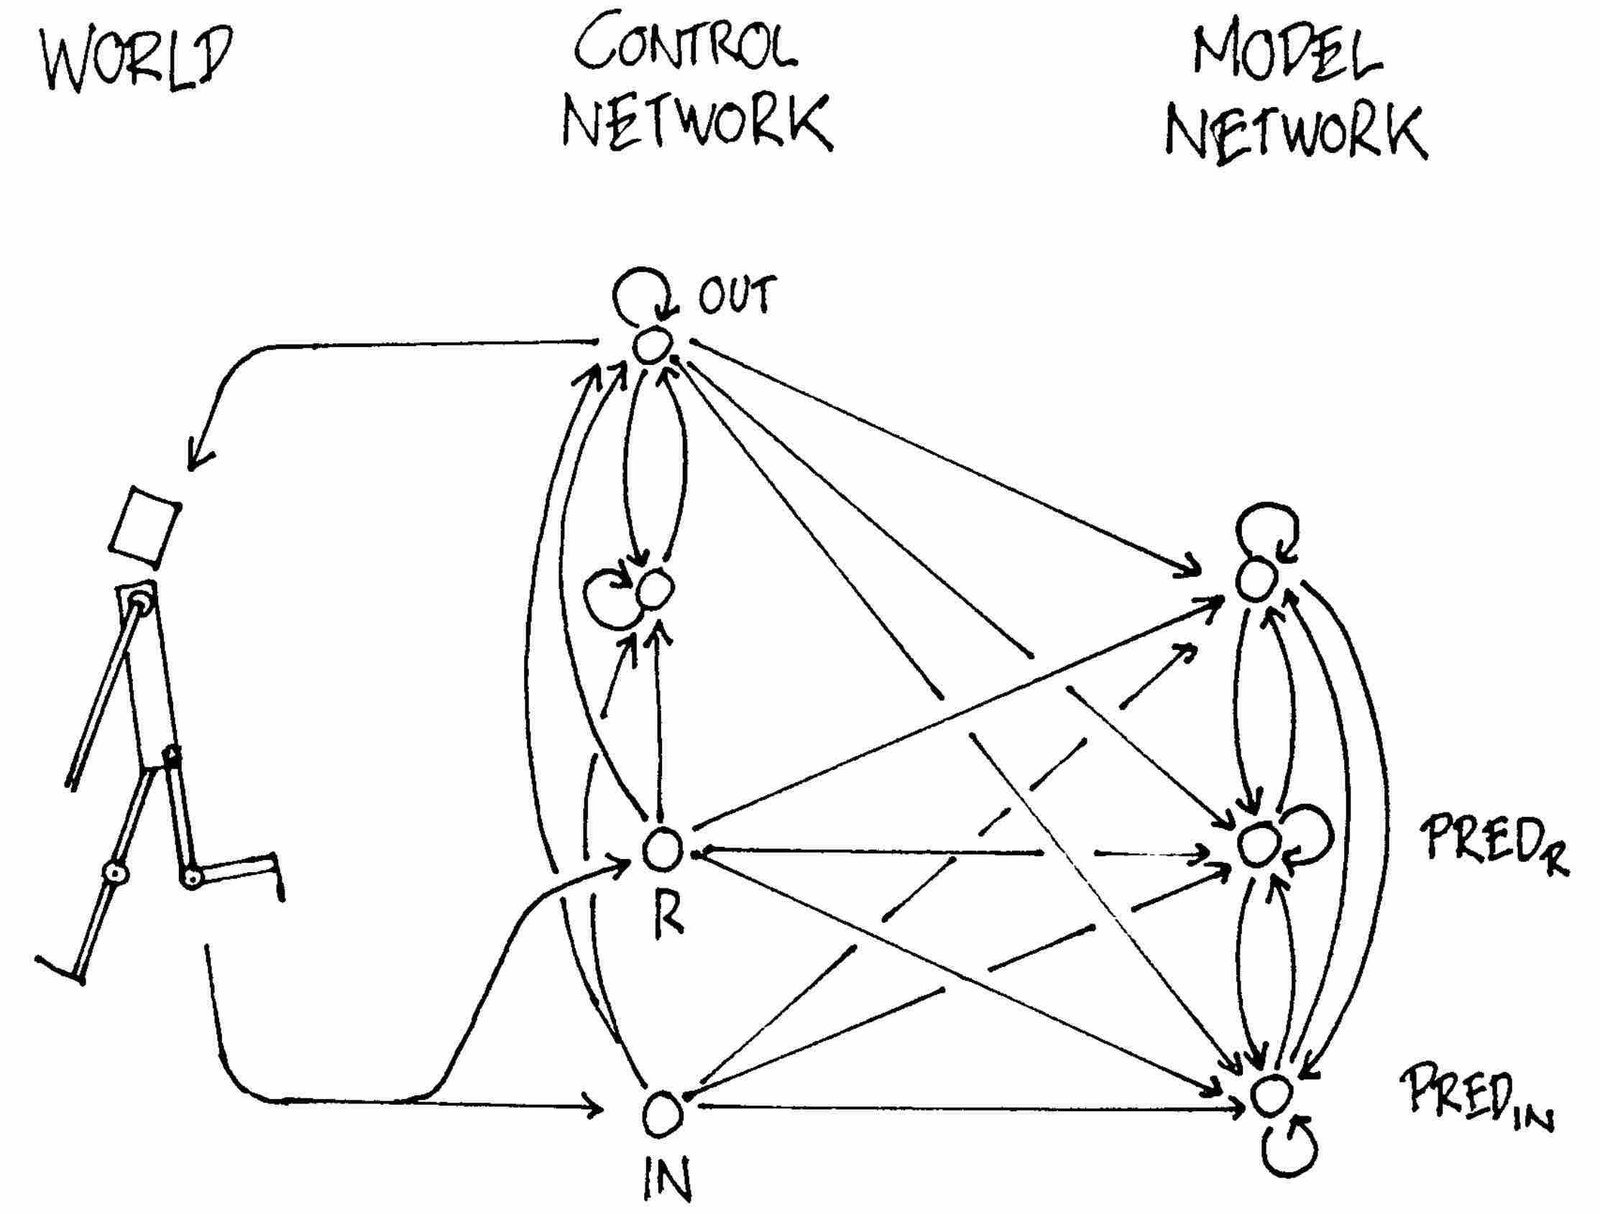
Figure 20: A controller with internal RNN model of the world (Schmidhuber, 1990a).
图 20:带有内部 RNN 世界模型的控制器(Schmidhuber,1990a)。
While Gaussian processes work well with a small set of low dimension data, their computational complexity makes them difficult to scale up to model a large history of high dimensional observations. Other recent works (Gal et al., 2016; Depeweg et al., 2016) use Bayesian neural networks instead of GPs to learn a dynamics model. These methods have demonstrated promising results on challenging control tasks (Hein et al., 2017), where the states are known and well defined, and the observation is relatively low dimensional. Here we are interested in modelling dynamics observed from high dimensional visual data where our input is a sequence of raw pixel frames.
高斯过程在小规模、低维数据上表现良好,但计算成本随数据点数量三次方增长,因而难以扩展到大型视频游戏环境一类高维问题。
In robotic control applications, the ability to learn the dynamics of a system from observing only camera-based video inputs is a challenging but important problem. Early work on RL for active vision trained an FNN to take the current image frame of a video sequence to predict the next frame (Schmidhuber & Huber, 1991), and use this predictive model to train a fovea-shifting control network trying to find targets in a visual scene. To get around the difficulty of training a dynamical model to learn directly from high-dimensional pixel images, researchers explored using neural networks to first learn a compressed representation of the video frames. Recent work along these lines (Wahlström et al., 2014; Wahlström et al., 2015) was able to train controllers using the bottleneck hidden layer of an autoencoder as low-dimensional feature vectors to control a pendulum from pixel inputs. Learning a model of the dynamics from a compressed latent space enable RL algorithms to be much more data-efficient (Finn et al., 2015; Watter et al., 2015; Finn, 2017). We invite readers to watch Finn’s lecture on Model-Based RL (Finn, 2017) to learn more.
在机器人控制应用中,从观测数据学习系统动力学的能力很有价值,因为它能降低在真实硬件上训练策略所需的试验次数。
Video game environments are also popular in model-based RL research as a testbed for new ideas. (Matthew Guzdial, 2017) used a feed-forward convolutional neural network (CNN) to learn a forward simulation model of a video game. Learning to predict how different actions affect future states in the environment is useful for game-play agents, since if our agent can predict what happens in the future given its current state and action, it can simply select the best action that suits its goal. This has been demonstrated not only in early work (Nguyen & Widrow, 1989; Schmidhuber & Huber, 1991) (when compute was a million times more expensive than today) but also in recent studies (Dosovitskiy & Koltun, 2016) on several competitive VizDoom environments.
电子游戏环境也是模型基 RL 研究中流行的新想法试验场。
The works mentioned above use FNNs to predict the next video frame. We may want to use models that can capture longer term time dependencies. RNNs are powerful models suitable for sequence modelling (Graves, 2013). In a lecture called Hallucination with RNNs (Graves, 2015), Graves demonstrated the ability of RNNs to learn a probabilistic model of Atari game environments. He trained RNNs to learn the structure of such a game and then showed that they can hallucinate similar game levels on its own.
上述工作使用前馈网络预测下一视频帧。我们可能希望使用能捕获更长时间依赖的模型。
Using RNNs to develop internal models to reason about the future has been explored as early as 1990 in a paper called Making the World Differentiable (Schmidhuber, 1990a), and then further explored in (Schmidhuber, 1990b; Schmidhuber, 1991a; Schmidhuber, 1990c). A more recent paper called Learning to Think (Schmidhuber, 2015a) presented a unifying framework for building a RNN-based general problem solver that can learn a world model of its environment and also learn to reason about the future using this model. Subsequent works have used RNN-based models to generate many frames into the future (Chiappa et al., 2017; Oh et al., 2015; Denton & Birodkar, 2017), and also as an internal model to reason about the future (Silver et al., 2016; Weber et al., 2017; Watters et al., 2017).
用 RNN 发展内部模型以推理未来,早在二十多年前就被探索过(Schmidhuber,1990a;Schmidhuber,1990b;Schmidhuber,1991a)。
In this work, we used evolution strategies to train our controller, as it offers many benefits. For instance, we only need to provide the optimizer with the final cumulative reward, rather than the entire history. ES is also easy to parallelize – we can launch many instances of rollout with different solutions to many workers and quickly compute a set of cumulative rewards in parallel. Recent works (Fernando et al., 2017; Salimans et al., 2017; Ha, 2017b; Stanley & Clune, 2017) have confirmed that ES is a viable alternative to traditional Deep RL methods on many strong baselines.
本工作中我们用进化策略训练控制器,因为它有诸多好处:易于并行、无需反向传播通过时间,并能优化不可微目标。
Before the popularity of Deep RL methods (Mnih et al., 2013), evolution-based algorithms have been shown to be effective at solving RL tasks (Stanley & Miikkulainen, 2002; Gomez et al., 2008; Gomez & Schmidhuber, 2005; Gauci & Stanley, 2010; Sehnke et al., 2010; Miikkulainen, 2013). Evolution-based algorithms have even been able to solve difficult RL tasks from high dimensional pixel inputs (Koutnik et al., 2013; Hausknecht et al., 2013; Parker & Bryant, 2012). More recent works (Alvernaz & Togelius, 2017) combine VAE and ES, which is similar to our approach.
在深度 RL 方法(Mnih 等,2013)流行之前,基于进化的算法已广泛用于训练神经网络策略。
7 Discussion
7 讨论
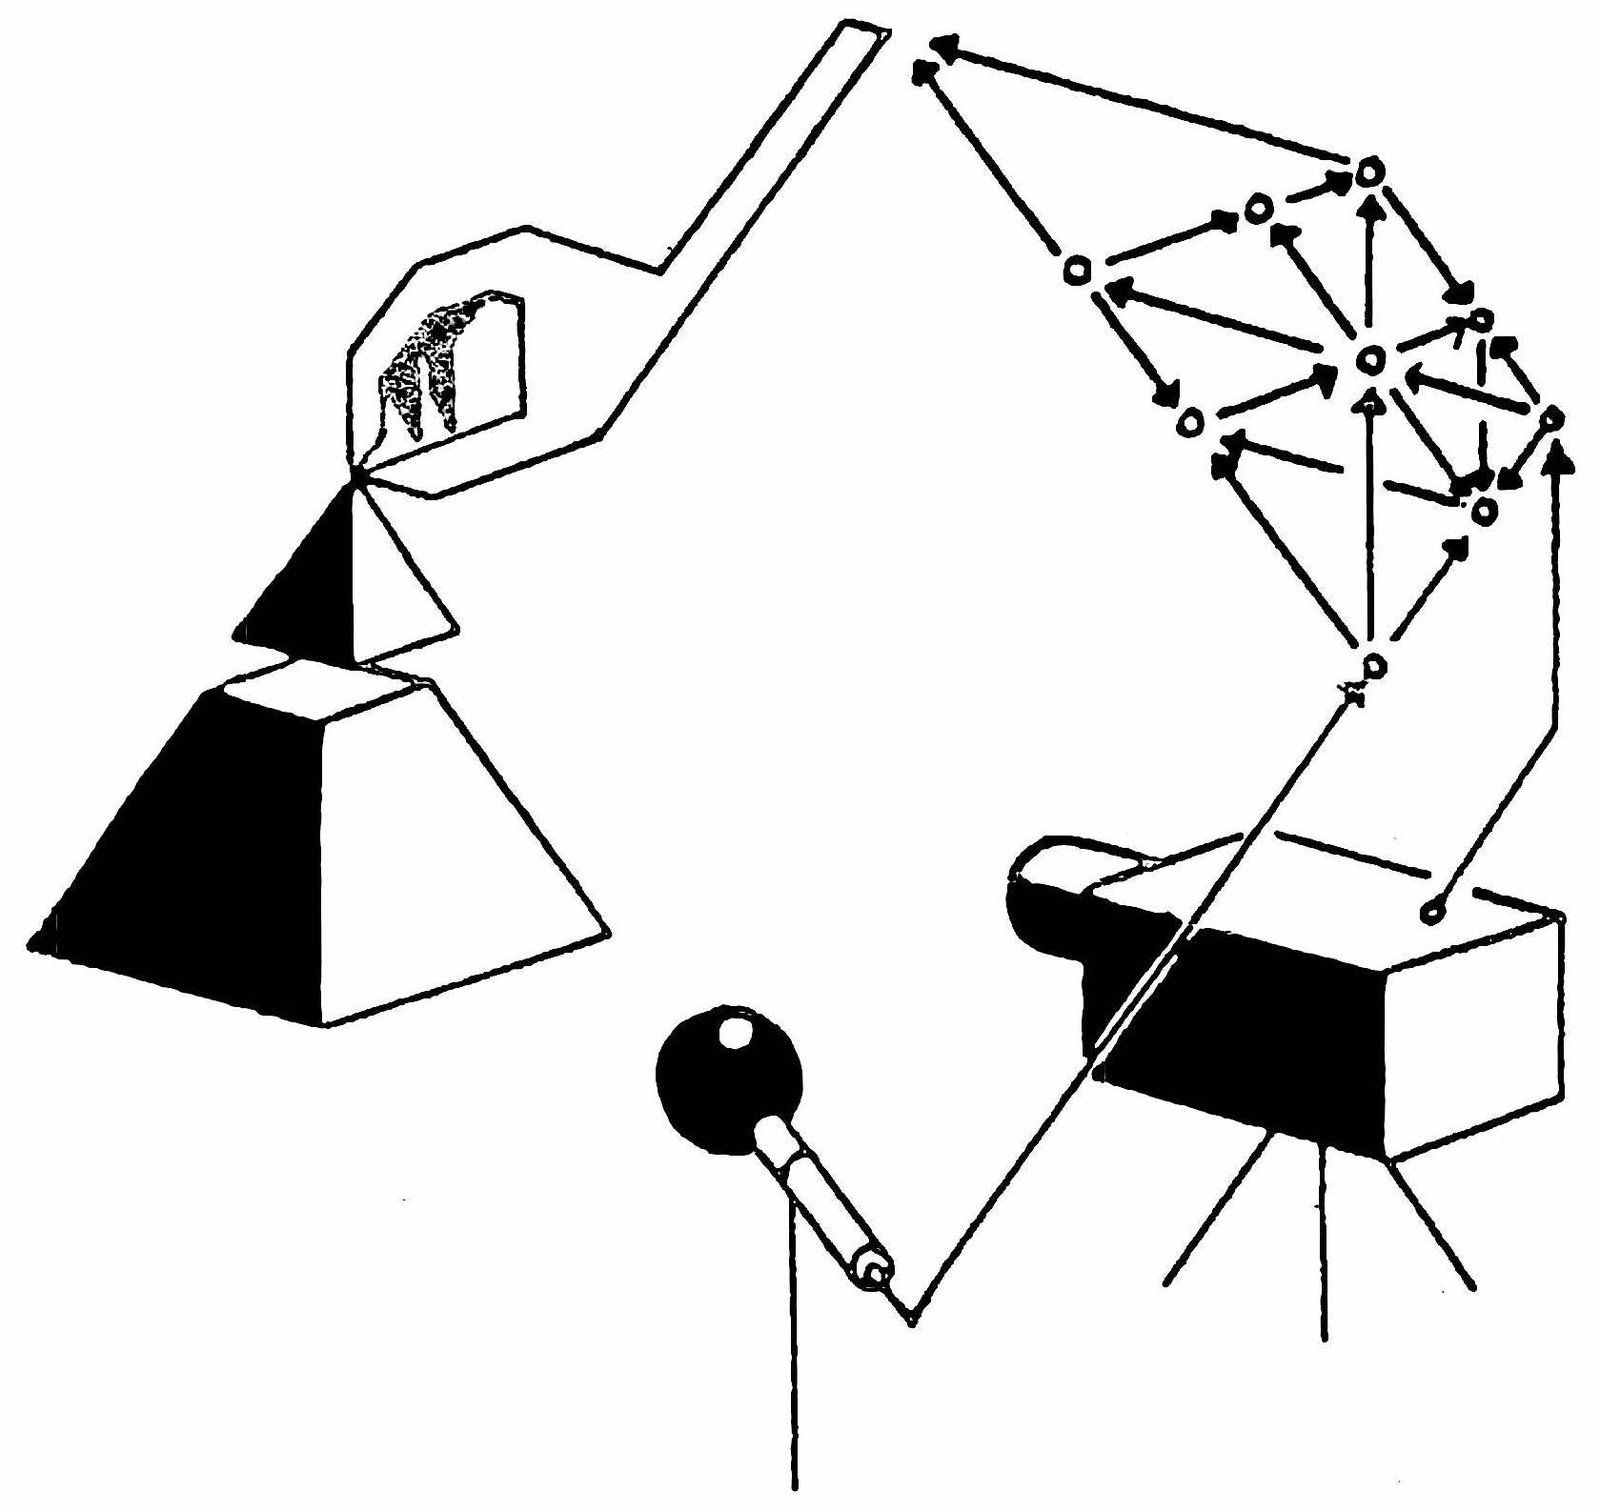
Figure 21: Ancient drawing (1990) of a RNN-based controller interacting with an environment (Schmidhuber, 1990a).
图 21:早期(1990)绘制的、与环境交互的基于 RNN 的控制器示意图。
We have demonstrated the possibility of training an agent to perform tasks entirely inside of its simulated latent space dream world. This approach offers many practical benefits. For instance, running computationally intensive game engines require using heavy compute resources for rendering the game states into image frames, or calculating physics not immediately relevant to the game. We may not want to waste cycles training an agent in the actual environment, but instead train the agent as many times as we want inside its simulated environment. Training agents in the real world is even more expensive, so world models that are trained incrementally to simulate reality may prove to be useful for transferring policies back to the real world. Our approach may complement sim2real approaches outlined in (Bousmalis et al., 2017; Higgins et al., 2017).
我们已经证明:有可能完全在智能体自身的世界模型内部训练它完成任务,并把这些策略迁移到实际环境。
Furthermore, we can take advantage of deep learning frameworks to accelerate our world model simulations using GPUs in a distributed environment. The benefit of implementing the world model as a fully differentiable recurrent computation graph also means that we may be able to train our agents in the dream directly using the backpropagation algorithm to fine-tune its policy to maximize an objective function (Schmidhuber, 1990a; Schmidhuber, 1990b; Schmidhuber, 1991a).
此外,我们可以利用深度学习框架加速世界模型训练,并把更多计算资源投入更大、更有表达力的生成模型。
The choice of using a VAE for the V model and training it as a standalone model also has its limitations, since it may encode parts of the observations that are not relevant to a task. After all, unsupervised learning cannot, by definition, know what will be useful for the task at hand. For instance, it reproduced unimportant detailed brick tile patterns on the side walls in the Doom environment, but failed to reproduce task-relevant tiles on the road in the Car Racing environment. By training together with a M model that predicts rewards, the VAE may learn to focus on task-relevant areas of the image, but the tradeoff here is that we may not be able to reuse the VAE effectively for new tasks without retraining.
选择用 VAE 作为 V 模型并作为独立模型训练,也有其局限性。VAE 可能把对任务有用的信息丢弃,因为它只优化重建目标。
Learning task-relevant features has connections to neuroscience as well. Primary sensory neurons are released from inhibition when rewards are received, which suggests that they generally learn task-relevant features, rather than just any features, at least in adulthood (Pi et al., 2013).
学习与任务相关的特征也与神经科学有联系。初级感觉神经元据信会形成对统计上常见输入模式高效的表示。
Another concern is the limited capacity of our world model. While modern storage devices can store large amounts of historical data generated using the iterative training procedure, our LSTM (Hochreiter & Schmidhuber, 1997; Gers et al., 2000)-based world model may not be able to store all of the recorded information inside its weight connections. While the human brain can hold decades and even centuries of memories to some resolution (Bartol et al., 2015), our neural networks trained with backpropagation have more limited capacity and suffer from issues such as catastrophic forgetting (Ratcliff, 1990; French, 1994; Kirkpatrick et al., 2016). Future work may explore replacing the small MDN-RNN network with higher capacity models (Shazeer et al., 2017; Ha et al., 2016; Suarez, 2017; van den Oord et al., 2016; Vaswani et al., 2017), or incorporating an external memory module (Gemici et al., 2017), if we want our agent to learn to explore more complicated worlds.
另一个担忧是世界模型的容量有限。尽管现代存储设备能保存大量经验,神经网络世界模型必须把这些经验压缩成有限的权集。
Like early RNN-based C–M systems (Schmidhuber, 1990a; Schmidhuber, 1990b; Schmidhuber, 1991a; Schmidhuber, 1990c), ours simulates possible futures time step by time step, without profiting from human-like hierarchical planning or abstract reasoning, which often ignores irrelevant spatial-temporal details. However, the more general Learning To Think (Schmidhuber, 2015a) approach is not limited to this rather naive approach. Instead it allows a recurrent C to learn to address subroutines of the recurrent M, and reuse them for problem solving in arbitrary computable ways, e.g., through hierarchical planning or other kinds of exploiting parts of M’s program-like weight matrix. A recent One Big Net (Schmidhuber, 2018) extension of the C–M approach collapses C and M into a single network, and uses PowerPlay-like (Schmidhuber, 2013; Srivastava et al., 2012) behavioural replay (where the behaviour of a teacher net is compressed into a student net (Schmidhuber, 1992)) to avoid forgetting old prediction and control skills when learning new ones. Experiments with those more general approaches are left for future work.
与早期基于 RNN 的 C–M 系统(Schmidhuber,1990a;Schmidhuber,1990b;Schmidhuber,1991a)一样,我们的方法把世界模型与控制器分开,使各自能用最适合的方法训练。
Acknowledgements
致谢
We would like to thank Blake Richards, Kai Arulkumaran, Ankur Handa, Kory Mathewson, Kyle McDonald, Denny Britz, Elwin Ha and Natasha Jaques for their thoughtful feedback on this article, and for offering their valuable perspectives and insights from their areas of expertise.
我们感谢 Blake Richards、Kai Arulkumaran、Ankur Handa、Kory Mathewson、Kyle McDonald、Denny Britz、Elwin Ha 与 Natasha Jaques 对本稿的认真反馈,以及他们从各自专长领域提供的宝贵视角与洞见。
The interactive online version of this article was built using distill.pub’s web technology. We would like to thank Chris Olah and the rest of the Distill editorial team for their valuable feedback and generous editorial support, in addition to supporting the use of their Distill technology.
本文的可交互在线版使用 distill.pub 的网页技术构建。我们感谢 Chris Olah 与 Distill 编辑团队其余成员的宝贵反馈与慷慨的编辑支持,以及他们支持我们使用 Distill 技术。
The interative demos on worldmodels.github.io were all built using p5.js. Deploying all of these machine learning models in a web browser was made possible with deeplearn.js, a hardware-accelerated machine learning framework for the browser, developed by the People+AI Research Initiative (PAIR) team at Google. A special thanks goes to Nikhil Thorat and Daniel Smilkov for their help during the development process.
worldmodels.github.io 上的可交互演示均用 p5.js 构建。把这些机器学习模型部署到浏览器中,得益于 Google People+AI Research Initiative(PAIR)团队开发的浏览器端硬件加速机器学习框架 deeplearn.js。特别感谢 Nikhil Thorat 与 Daniel Smilkov 在开发过程中的帮助。
We would to extend our thanks to Alex Graves, Douglas Eck, Mike Schuster, Rajat Monga, Vincent Vanhoucke, Jeff Dean and the Google Brain team for helpful feedback and for encouraging us to explore this area of research. Experiments were performed on Ubuntu virtual machines provided by Google Cloud Platform. Any errors here are our own and do not reflect opinions of our proofreaders and colleagues.
我们还要感谢 Alex Graves、Douglas Eck、Mike Schuster、Rajat Monga、Vincent Vanhoucke、Jeff Dean 与 Google Brain 团队的有益反馈,以及鼓励我们探索这一研究方向。实验在 Google Cloud Platform 提供的 Ubuntu 虚拟机上完成。文中若有任何错误,责任在我们,并不代表校对者与同事的意见。
Appendix A Appendix
附录 A
In this section we will describe in more details the models and training methods used in this work.
本节将更详细描述本工作使用的模型与训练方法。
A.1 Variational Autoencoder
A.1 变分自编码器
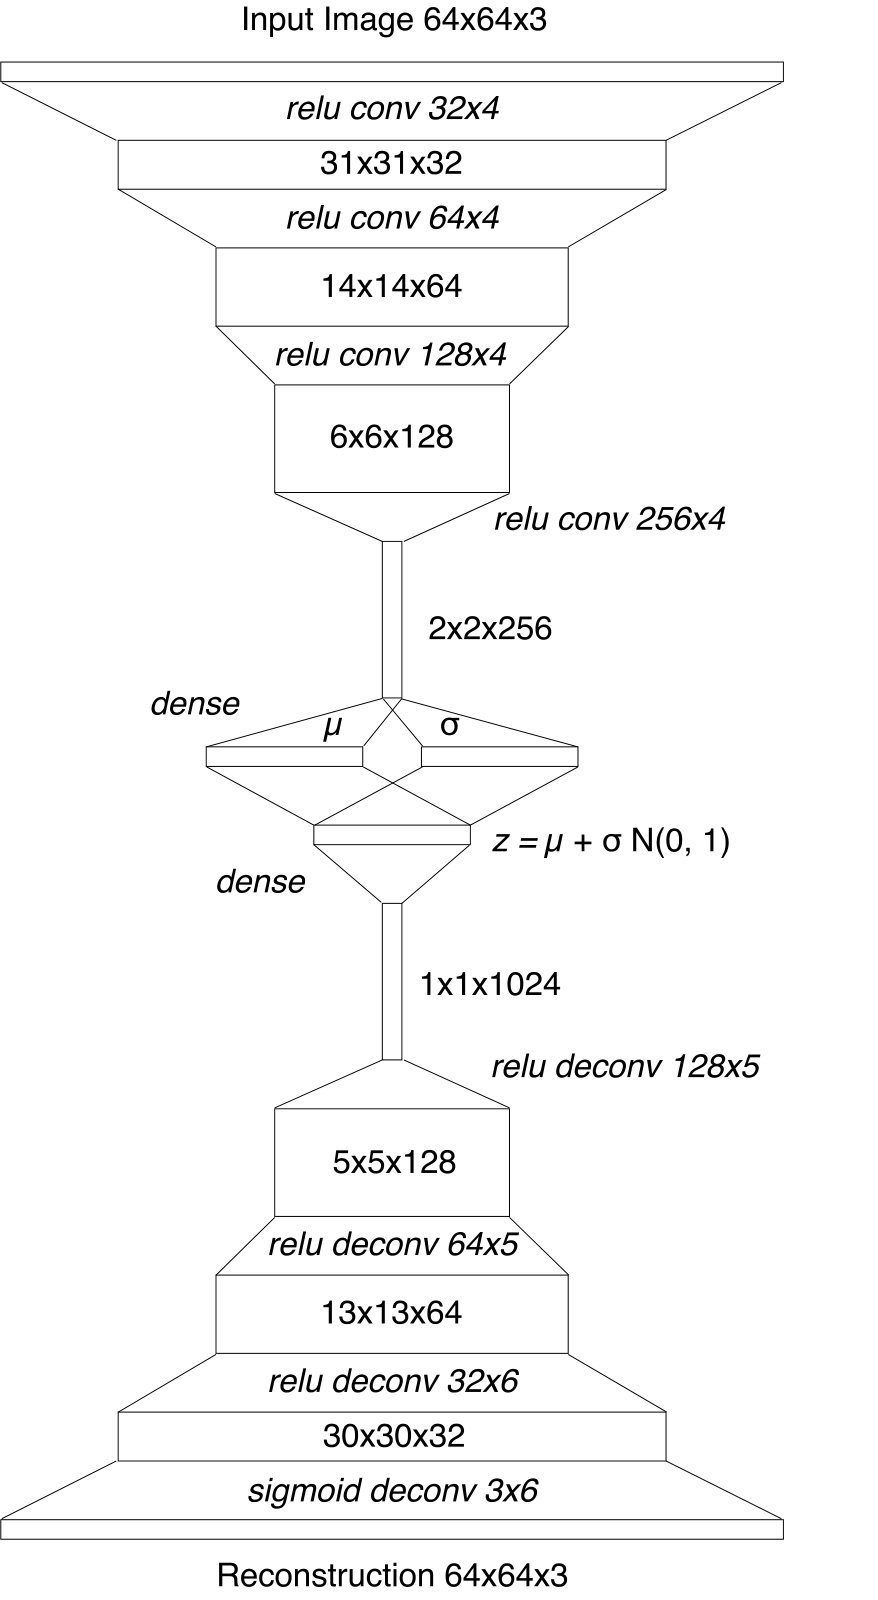
Figure 22: Description of tensor shapes at each layer of ConvVAE.
图 22:ConvVAE 各层张量形状说明。
We trained a Convolutional Variational Autoencoder (ConvVAE) model as the V Model of our agent. Unlike vanilla autoencoders, enforcing a Gaussian prior over the latent vector also limits the amount of information capacity for compressing each frame, but this Gaussian prior also makes the world model more robust to unrealistic vectors generated by the M Model.
我们训练卷积变分自编码器(ConvVAE)作为智能体的 V 模型。与普通自编码器不同,对隐向量 施加高斯先验会限制压缩每帧的信息容量,但该高斯先验也使世界模型对 M 模型生成的不真实 向量更稳健。
As the environment may give us observations as high dimensional pixel images, we first resize each image to 64x64 pixels before and use this resized image as the V Model’s observation. Each pixel is stored as three floating point values between 0 and 1 to represent each of the RGB channels. The ConvVAE takes in this 64x64x3 input tensor and passes this data through 4 convolutional layers to encode it into low dimension vectors and , each of size . The latent vector is sampled from the Gaussian prior . In the Car Racing task, is 32 while for the Doom task is 64. The latent vector is passed through 4 of deconvolution layers used to decode and reconstruct the image.
由于环境可能给出高维像素图像观测,我们先把每张图像缩放到 64×64 像素,再把缩放后的图像作为 V 模型的观测。每个像素存为 0 到 1 之间的三个浮点值,分别表示 RGB 通道。ConvVAE 接收该 64×64×3 输入张量,经 4 个卷积层把数据编码为低维向量 与 ,各长度为 。隐向量 从高斯先验 采样。赛车任务中 为 32,Doom 任务中 为 64。隐向量 再经 4 个反卷积层解码并重建图像。
Each convolution and deconvolution layer uses a stride of 2. The layers are indicated in the diagram in Italics as Activation-type Output Channels x Filter Size. All convolutional and deconvolutional layers use relu activations except for the output layer as we need the output to be between 0 and 1. We trained the model for 1 epoch over the data collected from a random policy, using distance between the input image and the reconstruction to quantify the reconstruction loss we optimize for, in addition to KL loss.
每个卷积与反卷积层步幅为 2。图中以斜体标出的层形如激活类型 输出通道 × 滤波器尺寸。除输出层外,所有卷积与反卷积层使用 relu 激活,因为我们需要输出落在 0 到 1 之间。我们用随机策略收集的数据训练模型 1 个 epoch,优化输入图像与重建之间的 距离作为重建损失,并加上 KL 损失。
A.2 Recurrent Neural Network
A.2 循环神经网络
For the M Model, we use an LSTM (Hochreiter & Schmidhuber, 1997) recurrent neural network combined with a Mixture Density Network (Bishop, 1994) as the output layer. We use this network to model the probability distribution of the next in the next time step as a Mixture of Gaussian distribution. This approach is very similar to (Graves, 2013) in the Unconditional Handwriting Generation section and also the decoder-only section of SketchRNN (Ha & Eck, 2017). The only difference in the approach used is that we did not model the correlation parameter between each element of , and instead had the MDN-RNN output a diagonal covariance matrix of a factored Gaussian distribution.
对 M 模型,我们使用 LSTM(Hochreiter & Schmidhuber,1997)循环神经网络,并结合混合密度网络(Bishop,1994)作为输出层。我们用该网络把下一时间步下一个 的概率分布建模为高斯混合分布。该方法与 Graves(2013)在无条件手写生成一节中的做法非常相似。
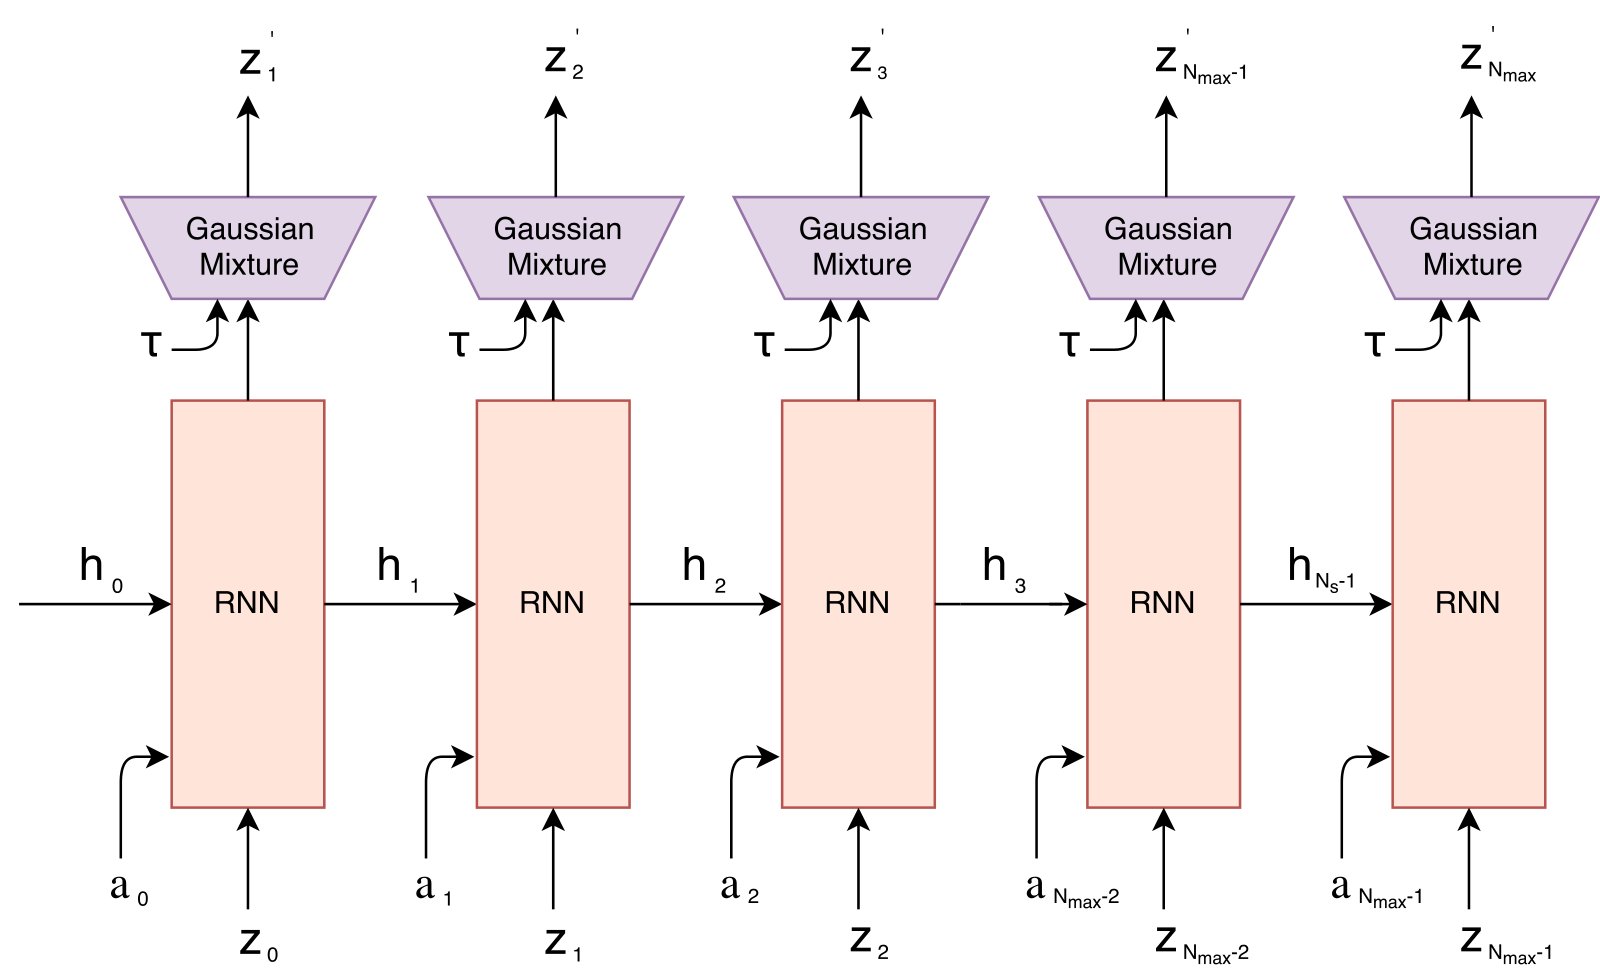
Figure 23: MDN-RNN decoder similar to (Graves, 2013; Ha & Eck, 2017)
图 23:类似于(Graves,2013;Ha & Eck,2017)的 MDN-RNN 解码器
Unlike the handwriting and sketch generation works, rather than using the MDN-RNN to model the pdf of the next pen stroke, we model instead the pdf of the next latent vector . We would sample from this pdf at each time step to generate the hallucinated environments. In the Doom task, we also also use the MDN-RNN to predict the probability of whether the agent has died in this frame. If that probability is above 50%, then we set done to be true in the virtual environment. Given that death is a low probability event at each time step, we find the cutoff approach to more stable compared to sampling from the Bernoulli distribution.
与手写和草图生成工作不同,我们不是用 MDN-RNN 建模下一笔触的概率密度,而是建模下一隐向量 的概率密度。我们在每一步从该密度采样,以生成幻觉环境。在 Doom 任务中,我们还用 MDN-RNN 预测智能体是否在这一帧死亡。若该概率超过 0.5,就结束幻觉回合。
The MDN-RNNs were trained for 20 epochs on the data collected from a random policy agent. In the Car Racing task, the LSTM used 256 hidden units, while the Doom task used 512 hidden units. In both tasks, we used 5 Gaussian mixtures and did not model the correlation parameter, hence is sampled from a factored mixture of Gaussian distribution.
MDN-RNN 在随机策略智能体收集的数据上训练 20 个 epoch。赛车任务中 LSTM 使用 256 个隐单元,Doom 任务使用 512 个隐单元。两个任务都使用 5 个高斯混合,且不建模相关参数 ,因此 从分解的高斯混合分布中采样。
When training the MDN-RNN using teacher forcing from the recorded data, we store a pre-computed set of and for each of the frames, and sample an input each time we construct a training batch, to prevent overfitting our MDN-RNN to a specific sampled .
在用记录数据做 teacher forcing 训练 MDN-RNN 时,我们为每一帧存储预计算的 与 集合,并在每次构造训练 batch 时采样输入 ,以防 MDN-RNN 过拟合到某个特定采样的 。
A.3 Controller
A.3 控制器
For both environments, we applied nonlinearities to clip and bound the action space to the appropriate ranges. For instance, in the Car Racing task, the steering wheel has a range from -1 to 1, the acceleration pedal from 0 to 1, and the brakes from 0 to 1. In the Doom environment, we converted the discrete actions into a continuous action space between -1 to 1, and divided this range into thirds to indicate whether the agent is moving left, staying where it is, or moving to the right. We would give the C Model a feature vector as its input, consisting of and the hidden state of the MDN-RNN. In the Car Racing task, this hidden state is the output vector of the LSTM, while for the Doom task it is both the cell vector and the output vector of the LSTM.
对两个环境,我们都施加 非线性,以把动作空间裁剪并限制在合适范围。例如在赛车任务中,方向盘范围是 -1 到 1,油门踏板是 0 到 1,刹车是 0 到 1。在 Doom 环境中,我们把离散动作转换成 -1 到 1 的连续动作空间,并把该范围三等分,分别表示智能体左移、原地不动或右移。我们给 C 模型的输入是由 与 MDN-RNN 隐状态组成的特征向量。赛车任务中该隐状态是 LSTM 的输出向量 ,Doom 任务中则同时包括 LSTM 的细胞向量 与输出向量 。
A.4 Evolution Strategies
A.4 进化策略
We used Covariance-Matrix Adaptation Evolution Strategy (CMA-ES) (Hansen, 2016) to evolve the weights for our C Model. Following the approach described in Evolving Stable Strategies (Ha, 2017b), we used a population size of 64, and had each agent perform the task 16 times with different initial random seeds. The fitness value for the agent is the average cumulative reward of the 16 random rollouts. The diagram below charts the best performer, worst performer, and mean fitness of the population of 64 agents at each generation:
我们使用协方差矩阵自适应进化策略(CMA-ES)(Hansen,2016)进化 C 模型的权重。遵循 Evolving Stable Strategies(Ha,2017b)所述方法,我们使用种群大小 64,并让每个智能体以不同初始随机种子执行任务 16 次。智能体的适应度值是这 16 次随机 rollout 的平均累计奖励。
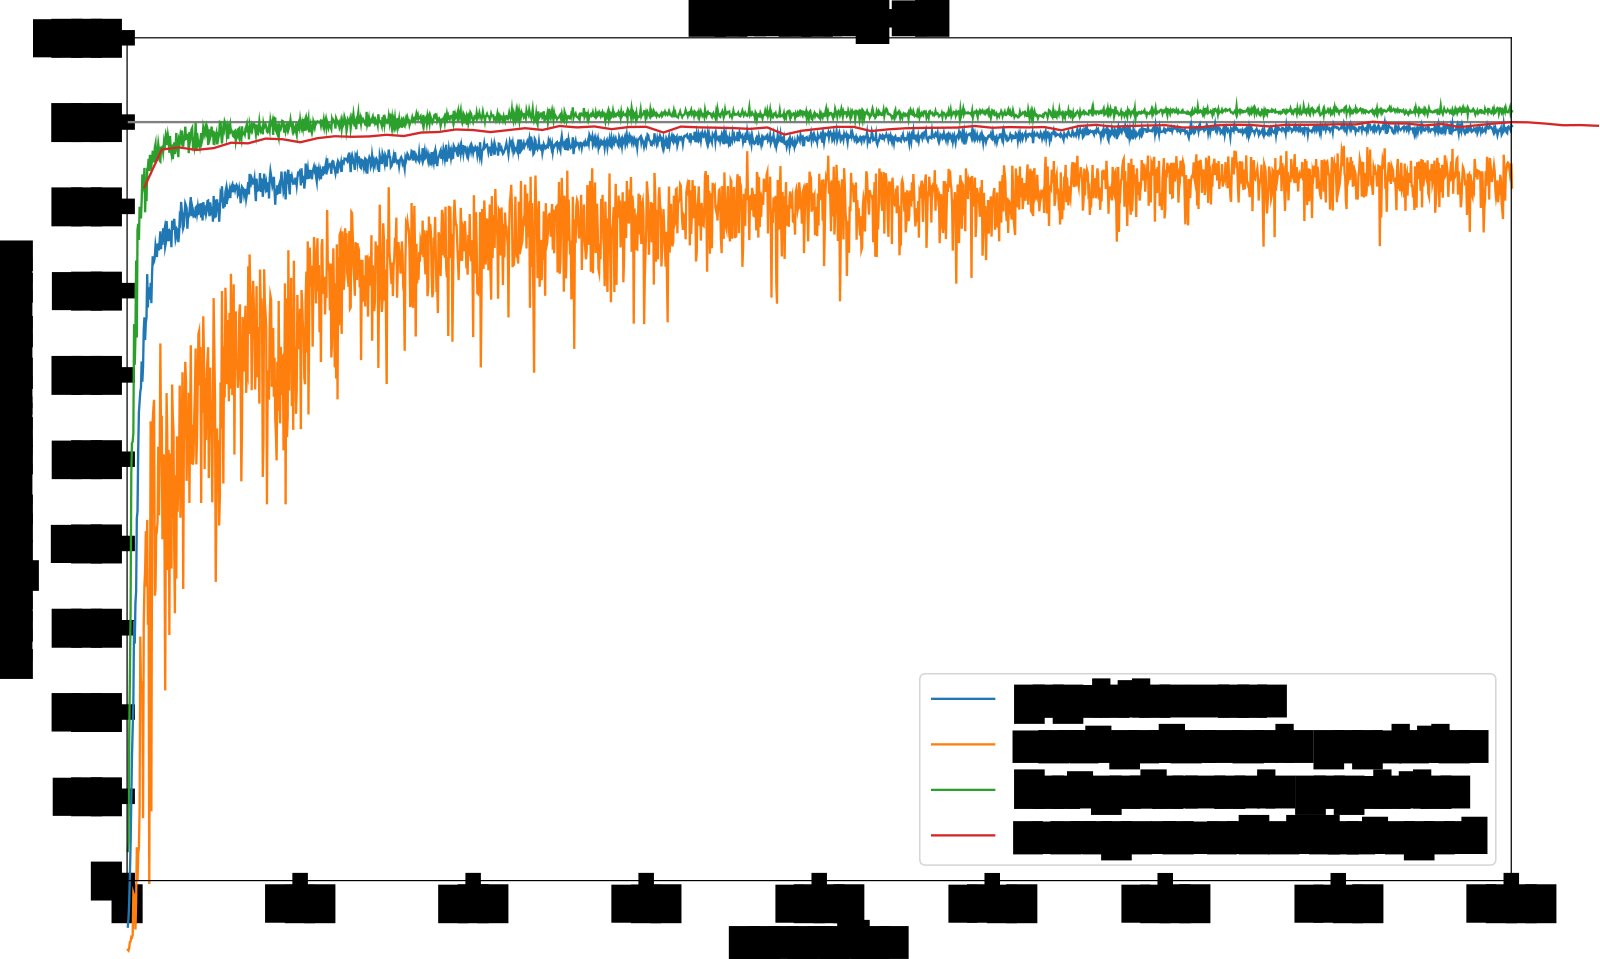
Figure 24: Training of CarRacing-v0
图 24:CarRacing-v0 的训练过程
Since the requirement of this environment is to have an agent achieve an average score above 900 over 100 random rollouts, we took the best performing agent at the end of every 25 generations, and tested that agent over 1024 random rollout scenarios to record this average on the red line. After 1800 generations, an agent was able to achieve an average score of 900.46 over 1024 random rollouts. We used 1024 random rollouts rather than 100 because each process of the 64 core machine had been configured to run 16 times already, effectively using a full generation of compute after every 25 generations to evaluate the best agent 1024 times. Below, we plot the results of same agent evaluated over 100 rollouts:
由于该环境要求智能体在 100 次随机 rollout 上平均得分超过 900,我们每隔 25 代取表现最好的智能体,并在 1024 个随机 rollout 场景上测试,把该平均值记在红线上。经过 1800 代后,某智能体在 1024 次随机 rollout 上平均得分 900.46。我们用 1024 次而非 100 次,是因为 64 核机器上每个进程已配置运行 16 次,相当于每隔 25 代用整整一代算力把最佳智能体评估 1024 次。下面我们画出同一智能体在 100 次 rollout 上的评估结果:
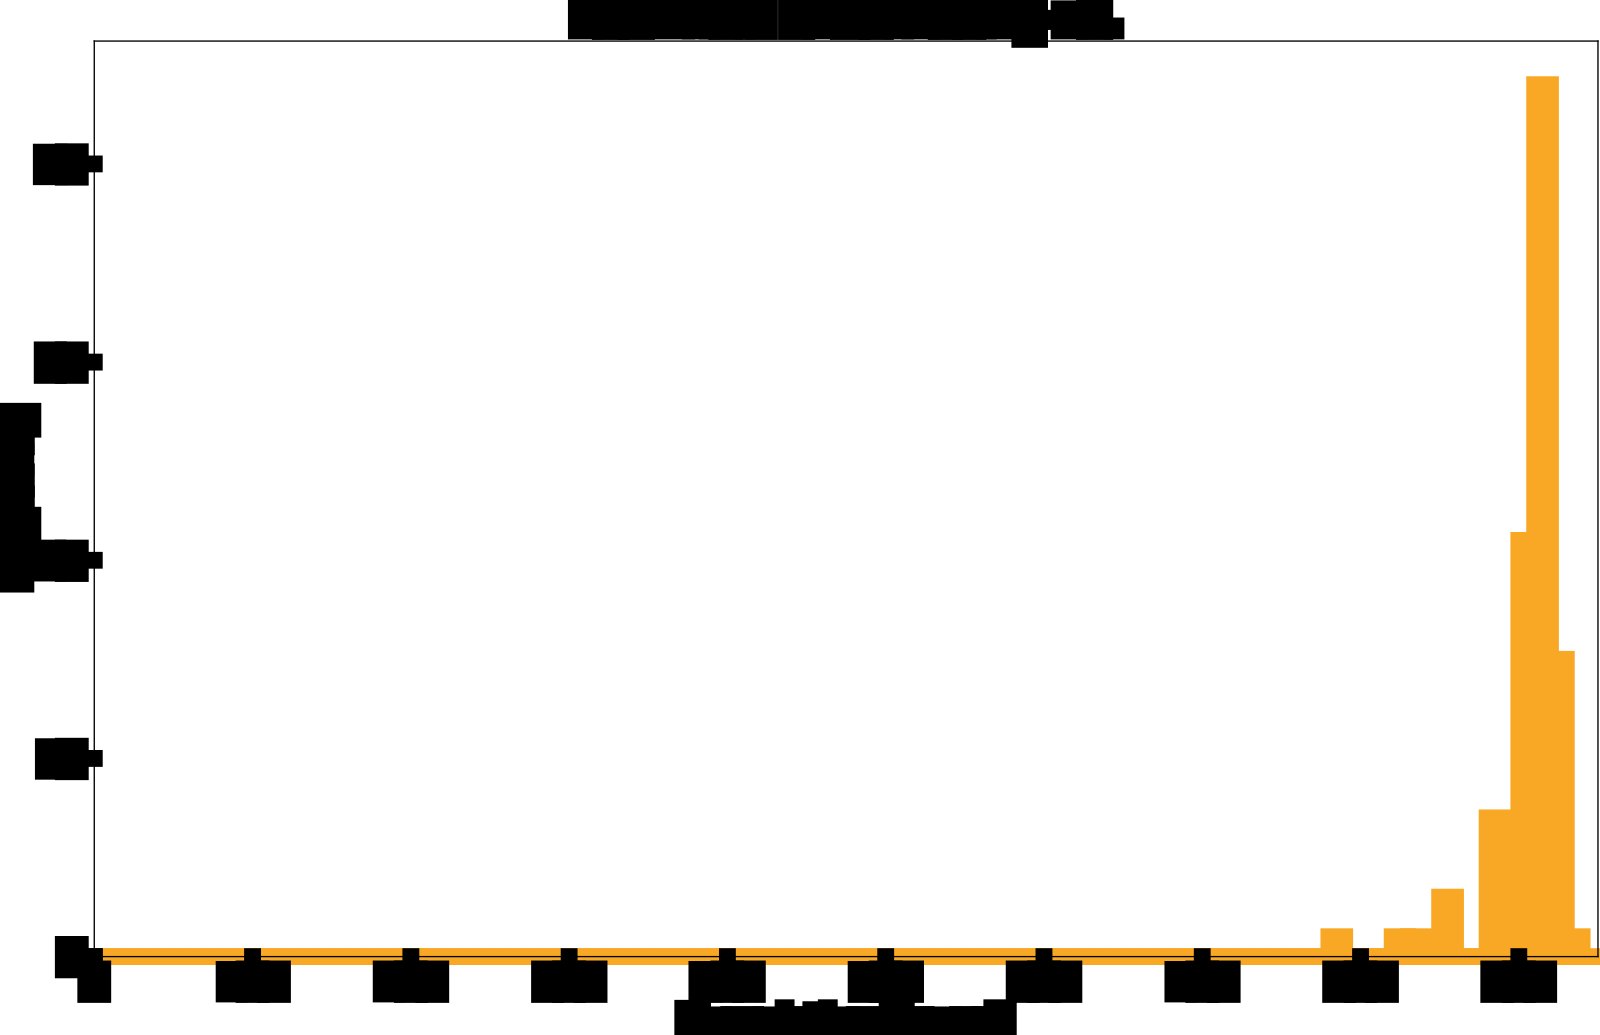
Figure 25: Histogram of cumulative rewards. Score is 906 21.
图 25:累计奖励直方图。得分为 906 21。
We also experimented with an agent that has access to only the vector from the VAE, and not letting it see the RNN’s hidden states. We tried 2 variations, where in the first variation, the C Model mapped directly to the action space . In second variation, we attempted to add a hidden layer with 40 activations between and , increasing the number of model parameters of the C Model to 1443, making it more comparable with the original setup.
我们还实验了只让智能体访问 VAE 的 向量、不看 RNN 隐状态的设置。我们尝试了两种变体:第一种变体中,C 模型把 直接映射到动作空间 ;第二种变体中,我们在 与 之间加入带 40 个 激活的隐层,从而增加 C 模型的参数量。
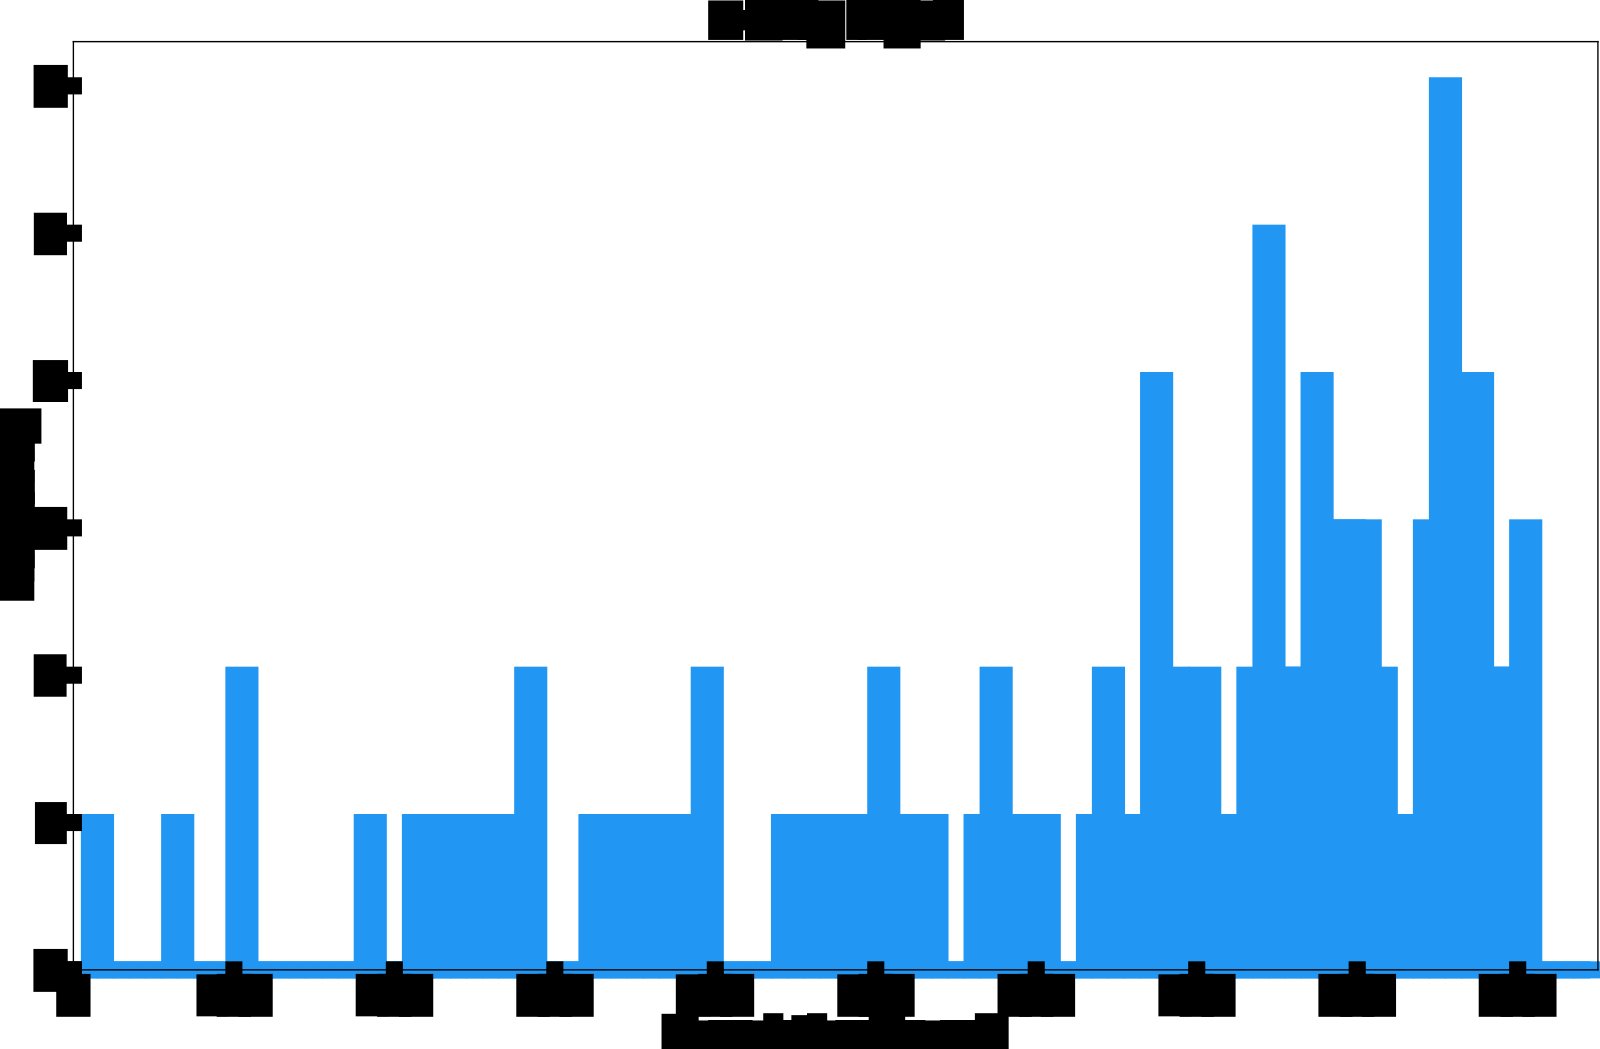
Figure 26: When agent sees only , score is 632 251.
图 26:智能体只看 时,得分为 632 251。
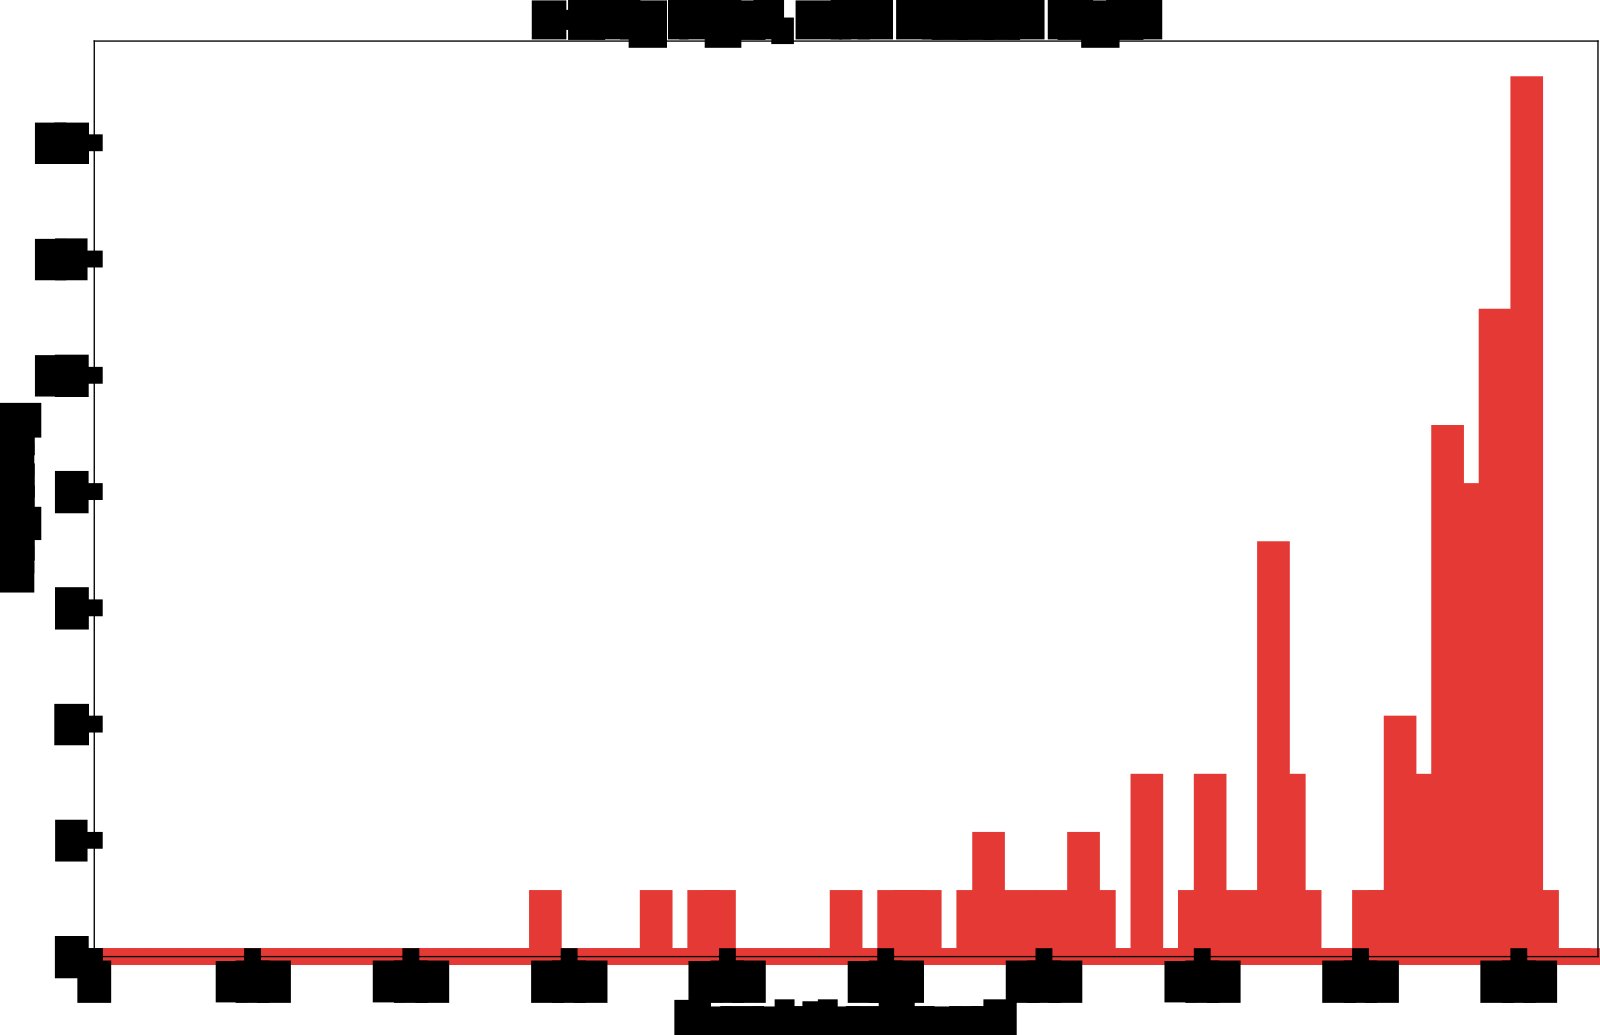
Figure 27: When agent sees only , with a hidden layer, score is 788 141.
图 27:智能体只看 且带隐层时,得分为 788 141。
A.5 DoomRNN
We conducted a similar experiment on the hallucinated Doom environment we called DoomRNN. Please note that we have not actually attempted to train our agent on the actual VizDoom environment, and had only used VizDoom for the purpose of collecting training data using a random policy. DoomRNN is more computationally efficient compared to VizDoom as it only operates in latent space without the need to render a screenshot at each time step, and does not require running the actual Doom game engine.
我们在名为 DoomRNN 的幻觉 Doom 环境上做了类似实验。请注意,我们实际上并未尝试在真实 VizDoom 环境中训练智能体,而只把 VizDoom 用于用随机策略收集训练数据。DoomRNN 比 VizDoom 计算更高效,因为它只在隐空间运行,无需渲染实际像素帧。
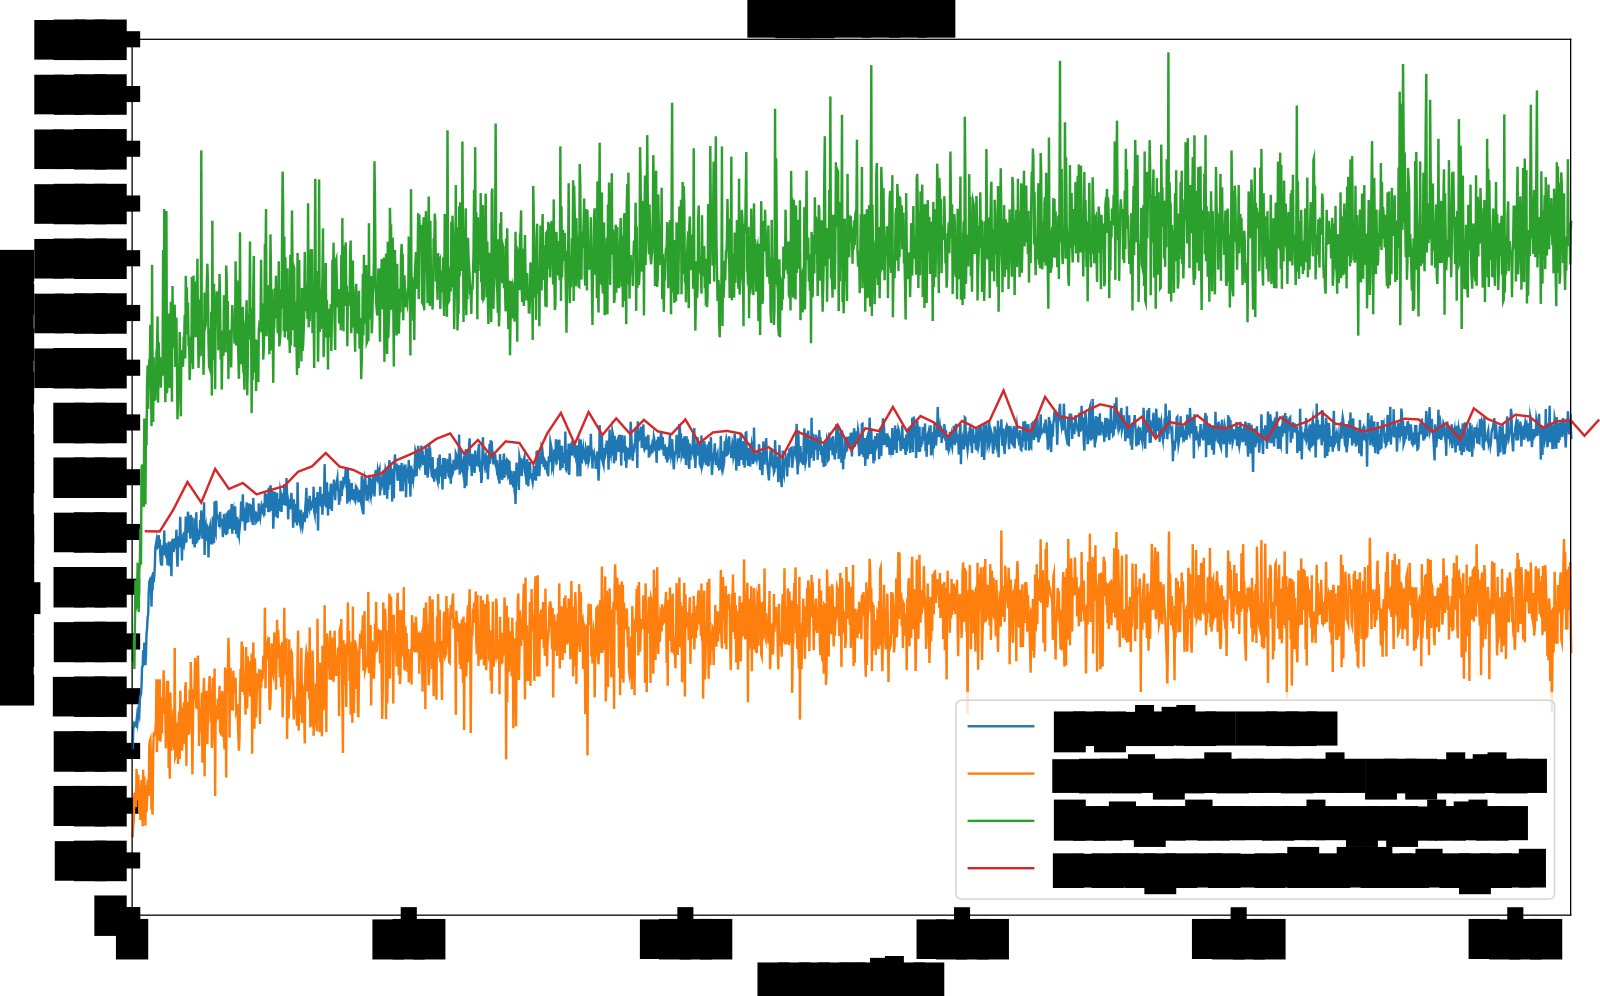
Figure 28: Training of DoomRNN.
图 28:DoomRNN 的训练过程。
In the virtual DoomRNN environment we constructed, we increased the temperature slightly and used to make the agent learn in a more challenging environment. The best agent managed to obtain an average score of 959 over 1024 random rollouts (the highest score of the red line in the diagram). This same agent achieved an average score of 1092 556 over 100 random rollouts when deployed to the actual DoomTakeCover-v0 (Paquette, 2016) environment.
在我们构建的虚拟 DoomRNN 环境中,我们略微提高温度并使用 ,使智能体在更具挑战性的环境中学习。最好的智能体在 1024 次随机 rollout 上平均得分 959(图中红线最高点)。同一智能体部署到实际 VizDoom 环境时,在 100 次随机 rollout 上平均得分 1092 556。
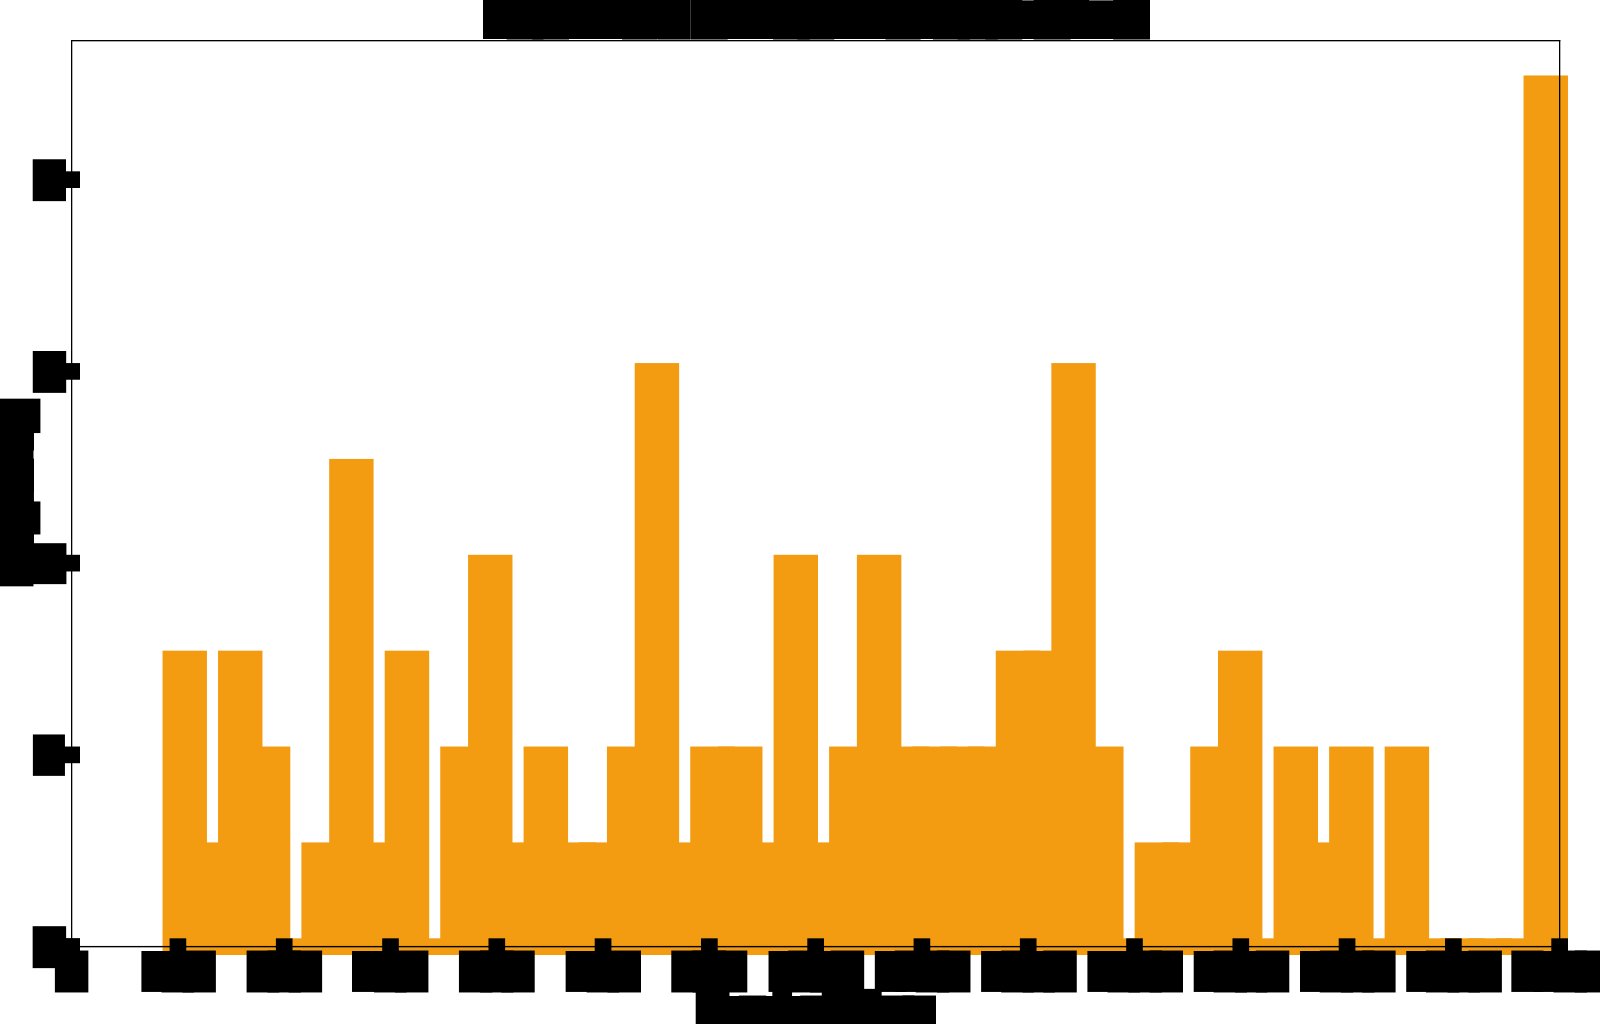
Figure 29: Histogram of time steps survived in the actual VizDoom environment over 100 consecutive trials. Score is 1092 556.
图 29:在实际 VizDoom 环境中连续 100 次试验存活时间步的直方图。得分为 1092 556。
References
参考文献
Al-Shedivat et al. (2017) Al-Shedivat, M., Bansal, T., Burda, Y., Sutskever, I., Mordatch, I., and Abbeel, P. Continuous adaptation via meta-learning in nonstationary and competitive environments. ArXiv preprint , October 2017. URL https://arxiv.org/abs/1710.03641 .
Alvernaz & Togelius (2017) Alvernaz, S. and Togelius, J. Autoencoder-augmented neuroevolution for visual doom playing. ArXiv preprint , July 2017. URL https://arxiv.org/abs/1707.03902 .
Arulkumaran et al. (2017) Arulkumaran, K., Deisenroth, M. P., Brundage, M., and Bharath, A. A. Deep reinforcement learning: A brief survey. IEEE Signal Processing Magazine , 34(6):26–38, Nov 2017. ISSN 1053-5888. doi: 10.1109/MSP.2017.2743240 . URL https://arxiv.org/abs/1708.05866 .
Bansal et al. (2017) Bansal, T., Pachocki, J., Sidor, S., Sutskever, I., and Mordatch, I. Emergent complexity via multi-agent competition. ArXiv preprint , October 2017. URL https://arxiv.org/abs/1710.03748 .
Bartol et al. (2015) Bartol, Thomas M, Jr, Bromer, Cailey, Kinney, Justin, Chirillo, Michael A, Bourne, Jennifer N, Harris, Kristen M, and Sejnowski, Terrence J. Nanoconnectomic upper bound on the variability of synaptic plasticity. eLife Sciences Publications, Ltd , 2015. doi: 10.7554/eLife.10778 . URL https://doi.org/10.7554/eLife.10778 .
Bishop (1994) Bishop, Christopher M. Mixture density networks. Technical Report , 1994. URL http://publications.aston.ac.uk/373/ .
Bling (2015) Bling, Seth. Mar i/o kart, 2015. URL https://youtu.be/S9Y_I9vY8Qw .
Bousmalis et al. (2017) Bousmalis, K., Irpan, A., Wohlhart, P., Bai, Y., Kelcey, M., Kalakrishnan, M., Downs, L., Ibarz, J., Pastor, P., Konolige, K., Levine, S., and Vanhoucke, V. Using simulation and domain adaptation to improve efficiency of deep robotic grasping. ArXiv e-prints , September 2017. URL https://arxiv.org/abs/1709.07857 .
Brockman et al. (2016) Brockman, G., Cheung, V., Pettersson, L., Schneider, J., Schulman, J., Tang, J., and Zaremba, W. Openai gym. ArXiv preprint , June 2016. URL https://arxiv.org/abs/1606.01540 .
Cheang & Tsao (2017) Cheang, L. and Tsao, D. The code for facial identity in the primate brain. Cell , 2017. doi: 10.1016/j.cell.2017.05.011 . URL http://www.cell.com/cell/fulltext/S0092-8674%2817%2930538-X .
Chiappa et al. (2017) Chiappa, S., Racaniere, S., Wierstra, D., and Mohamed, S. Recurrent environment simulators. ArXiv preprint , April 2017. URL https://arxiv.org/abs/1704.02254 .
Deisenroth & Rasmussen (2011) Deisenroth, M. and Rasmussen, C. Pilco: A model-based and data-efficient approach to policy search. 2011. URL http://mlg.eng.cam.ac.uk/pub/pdf/DeiRas11.pdf .
Denton & Birodkar (2017) Denton, E. and Birodkar, V. Unsupervised learning of disentangled representations from video. ArXiv preprint , May 2017. URL https://arxiv.org/abs/1705.10915 .
Depeweg et al. (2016) Depeweg, S., Hernandez-Lobato, J, Doshi-Velez, F., and Udluft, S. Learning and policy search in stochastic dynamical systems with bayesian neural networks. ArXiv preprint , May 2016. URL https://arxiv.org/abs/1605.07127 .
Dosovitskiy & Koltun (2016) Dosovitskiy, A. and Koltun, V. Learning to act by predicting the future. ArXiv preprint , November 2016. URL https://arxiv.org/abs/1611.01779 .
Duvenaud (2016) Duvenaud, David. Lecture slides on pilco. CSC 2541 Course at University of Toronto , 2016. URL https://www.cs.toronto.edu/~duvenaud/courses/csc2541/slides/pilco.pdf .
E (2012) E, M. More thoughts from understanding comics by scott mccloud, 2012. URL https://goo.gl/5Tndi4 .
Fernando et al. (2017) Fernando, C., Banarse, D., Blundell, C., Zwols, Y., Ha, D., Rusu, A., Pritzel, A., and Wierstra, D. Pathnet: Evolution channels gradient descent in super neural networks. ArXiv preprint , January 2017. URL https://arxiv.org/abs/1701.08734 .
Finn et al. (2015) Finn, C., Tan, X., Duan, Y., Darrell, T., Levine, S., and Abbeel, P. Deep spatial autoencoders for visuomotor learning. ArXiv preprint , September 2015. URL https://arxiv.org/abs/1509.06113 .
Finn (2017) Finn, Chelsea. Model-based rl lecture at deep rl bootcamp 2017, 2017. URL https://youtu.be/iC2a7M9voYU?t=44m35s .
Forrester (1971) Forrester, Jay Wright. Counterintuitive behavior of social systems, 1971. URL https://en.wikipedia.org/wiki/Mental_model . [Online; accessed 01-Nov-2017].
Foster (2017) Foster, David J. Replay comes of age. Annual Review of Neuroscience , 40(1):581–602, 2017. doi: 10.1146/annurev-neuro-072116-031538 . URL https://doi.org/10.1146/annurev-neuro-072116-031538 .
French (1994) French, Robert M. Catastrophic interference in connectionist networks: Can it be predicted, can it be prevented? In Cowan, J. D., Tesauro, G., and Alspector, J. (eds.), Advances in Neural Information Processing Systems 6 , pp. 1176–1177. Morgan-Kaufmann, 1994. URL https://goo.gl/jwpLsk .
Gal et al. (2016) Gal, Y., McAllister, R., and Rasmussen, C. Improving pilco with bayesian neural network dynamics models. April 2016. URL http://mlg.eng.cam.ac.uk/yarin/PDFs/DeepPILCO.pdf .
Gauci & Stanley (2010) Gauci, Jason and Stanley, Kenneth O. Autonomous evolution of topographic regularities in artificial neural networks. Neural Computation , 22(7):1860–1898, July 2010. ISSN 0899-7667. doi: 10.1162/neco.2010.06-09-1042 . URL http://eplex.cs.ucf.edu/papers/gauci_nc10.pdf .
Gemici et al. (2017) Gemici, M., Hung, C., Santoro, A., Wayne, G., Mohamed, S., Rezende, D., Amos, D., and Lillicrap, T. Generative temporal models with memory. ArXiv preprint , February 2017. URL https://arxiv.org/abs/1702.04649 .
Gerrit et al. (2013) Gerrit, M., Fischer, J., and Whitney, D. Motion-dependent representation of space in area mt+. Neuron , 2013. doi: 10.1016/j.neuron.2013.03.010 . URL http://dx.doi.org/10.1016/j.neuron.2013.03.010 .
Gers et al. (2000) Gers, F., Schmidhuber, J., and Cummins, F. Learning to forget: Continual prediction with lstm. Neural Computation , 12(10):2451–2471, October 2000. ISSN 0899-7667. doi: 10.1162/089976600300015015 . URL ftp://ftp.idsia.ch/pub/juergen/FgGates-NC.pdf .
Gomez & Schmidhuber (2005) Gomez, F. and Schmidhuber, J. Co-evolving recurrent neurons learn deep memory pomdps. Proceedings of the 7th Annual Conference on Genetic and Evolutionary Computation , pp. 491–498, 2005. doi: 10.1145/1068009.1068092 . URL ftp://ftp.idsia.ch/pub/juergen/gecco05gomez.pdf .
Gomez et al. (2008) Gomez, F., Schmidhuber, J., and Miikkulainen, R. Accelerated neural evolution through cooperatively coevolved synapses. Journal of Machine Learning Research , 9:937–965, June 2008. ISSN 1532-4435. URL http://people.idsia.ch/~juergen/gomez08a.pdf .
Gottlieb et al. (2013) Gottlieb, J., Oudeyer, P., Lopes, M., and Baranes, A. Information-seeking, curiosity, and attention: computational and neural mechanisms. Cell , September 2013. doi: 10.1016/j.tics.2013.09.001 . URL http://www.pyoudeyer.com/TICSCuriosity2013.pdf .
Graves (2013) Graves, Alex. Generating sequences with recurrent neural networks. ArXiv preprint , 2013. URL https://arxiv.org/abs/1308.0850 .
Graves (2015) Graves, Alex. Hallucination with recurrent neural networks, 2015. URL https://www.youtube.com/watch?v=-yX1SYeDHbg&t=49m33s .
Ha (2017a) Ha, D. Recurrent neural network tutorial for artists. blog.otoro.net , 2017a. URL http://blog.otoro.net/2017/01/01/recurrent-neural-network-artist/ .
Ha (2017b) Ha, D. Evolving stable strategies. blog.otoro.net , 2017b. URL http://blog.otoro.net/2017/11/12/evolving-stable-strategies/ .
Ha & Eck (2017) Ha, D. and Eck, D. A neural representation of sketch drawings. ArXiv preprint , April 2017. URL https://magenta.tensorflow.org/sketch-rnn-demo .
Ha et al. (2016) Ha, D., Dai, A., and Le, Q. Hypernetworks. ArXiv preprint , September 2016. URL https://arxiv.org/abs/1609.09106 .
Hansen (2016) Hansen, N. The cma evolution strategy: A tutorial. ArXiv preprint , 2016. URL https://arxiv.org/abs/1604.00772 .
Hansen & Ostermeier (2001) Hansen, Nikolaus and Ostermeier, Andreas. Completely derandomized self-adaptation in evolution strategies. Evolutionary Computation , 9(2):159–195, June 2001. ISSN 1063-6560. doi: 10.1162/106365601750190398 . URL http://www.cmap.polytechnique.fr/~nikolaus.hansen/cmaartic.pdf .
Hausknecht et al. (2013) Hausknecht, M., Lehman, J., Miikkulainen, R., and Stone, P. A neuroevolution approach to general atari game playing. IEEE Transactions on Computational Intelligence and AI in Games , 2013. URL http://www.cs.utexas.edu/~ai-lab/?atari .
Hein et al. (2017) Hein, D., Depeweg, S., Tokic, M., Udluft, S., Hentschel, A., Runkler, T., and Sterzing, V. A benchmark environment motivated by industrial control problems. ArXiv preprint , September 2017. URL https://arxiv.org/abs/1709.09480 .
Higgins et al. (2017) Higgins, I., Pal, A., Rusu, A., Matthey, L., Burgess, C., Pritzel, A., Botvinick, M., Blundell, C., and Lerchner, A. Darla: Improving zero-shot transfer in reinforcement learning. ArXiv e-prints , July 2017. URL https://arxiv.org/abs/1707.08475 .
Hirshon (2013) Hirshon, B. Tracking fastballs, 2013. URL http://sciencenetlinks.com/science-news/science-updates/tracking-fastballs/ .
Hochreiter & Schmidhuber (1997) Hochreiter, Sepp and Schmidhuber, Juergen. Long short-term memory. Neural Computation , 1997. URL ftp://ftp.idsia.ch/pub/juergen/lstm.pdf .
Hünermann (2017) Hünermann, Jan. Self-driving cars in the browser, 2017. URL http://janhuenermann.com/projects/learning-to-drive .
Jang et al. (2017) Jang, S., Min, J., and Lee, C. Reinforcement car racing with a3c. 2017. URL https://www.scribd.com/document/358019044/Reinforcement-Car-Racing-with-A3C .
Kaelbling et al. (1996) Kaelbling, L. P., Littman, M. L., and Moore, A. W. Reinforcement learning: a survey. Journal of AI research , 4:237–285, 1996.
Keller et al. (2012) Keller, Georg B., Bonhoeffer, Tobias, and Hübener, Mark. Sensorimotor mismatch signals in primary visual cortex of the behaving mouse. Neuron , 74(5):809 – 815, 2012. ISSN 0896-6273. doi: https://doi.org/10.1016/j.neuron.2012.03.040 . URL http://www.sciencedirect.com/science/article/pii/S0896627312003844 .
Kelley (1960) Kelley, H. J. Gradient theory of optimal flight paths. ARS Journal , 30(10):947–954, 1960.
Kempka et al. (2016) Kempka, Michael, Wydmuch, Marek, Runc, Grzegorz, Toczek, Jakub, and Jaskowski, Wojciech. Vizdoom: A doom-based ai research platform for visual reinforcement learning. In IEEE Conference on Computational Intelligence and Games , pp. 341–348, Santorini, Greece, Sep 2016. IEEE. URL http://arxiv.org/abs/1605.02097 . The best paper award.
Khan & Elibol (2016) Khan, M. and Elibol, O. Car racing using reinforcement learning. 2016. URL https://web.stanford.edu/class/cs221/2017/restricted/p-final/elibol/final.pdf .
Kingma & Welling (2013) Kingma, D. and Welling, M. Auto-encoding variational bayes. ArXiv preprint , 2013. URL https://arxiv.org/abs/1312.6114 .
Kirkpatrick et al. (2016) Kirkpatrick, J., Pascanu, R., Rabinowitz, N., Veness, J., Desjardins, G., Rusu, A.and Milan, K., Quan, J., Ramalho, T., Grabska-Barwinska, A., Hassabis, D., Clopath, C., Kumaran, D., and Hadsell, R. Overcoming catastrophic forgetting in neural networks. ArXiv preprint , December 2016. URL https://arxiv.org/abs/1612.00796 .
Kitaoka (2002) Kitaoka, Akiyoshi. Akiyoshi’s illusion pages, 2002. URL http://www.ritsumei.ac.jp/~akitaoka/index-e.html .
Klimov (2016) Klimov, Oleg. Carracing-v0, 2016. URL https://gym.openai.com/envs/CarRacing-v0/ .
Koutnik et al. (2013) Koutnik, J., Cuccu, G., Schmidhuber, J., and Gomez, F. Evolving large-scale neural networks for vision-based reinforcement learning. Proceedings of the 15th Annual Conference on Genetic and Evolutionary Computation , pp. 1061–1068, 2013. doi: 10.1145/2463372.2463509 . URL http://people.idsia.ch/~juergen/compressednetworksearch.html .
Lau (2016) Lau, Ben. Using keras and deep deterministic policy gradient to play torcs, 2016. URL https://yanpanlau.github.io/2016/10/11/Torcs-Keras.html .
Lehman & Stanley (2011) Lehman, Joel and Stanley, Kenneth. Abandoning objectives: Evolution through the search for novelty alone. Evolutionary Computation , 19(2):189–223, 2011. ISSN 1063-6560. URL http://eplex.cs.ucf.edu/noveltysearch/userspage/ .
Leinweber et al. (2017) Leinweber, Marcus, Ward, Daniel R., Sobczak, Jan M., Attinger, Alexander, and Keller, Georg B. A sensorimotor circuit in mouse cortex for visual flow predictions. Neuron , 95(6):1420 – 1432.e5, 2017. ISSN 0896-6273. doi: https://doi.org/10.1016/j.neuron.2017.08.036 . URL http://www.sciencedirect.com/science/article/pii/S0896627317307791 .
Linnainmaa (1970) Linnainmaa, S. The representation of the cumulative rounding error of an algorithm as a taylor expansion of the local rounding errors. Master’s thesis, Univ. Helsinki, 1970.
Matthew Guzdial (2017) Matthew Guzdial, Boyang Li, Mark O. Riedl. Game engine learning from video. In Proceedings of the Twenty-Sixth International Joint Conference on Artificial Intelligence, IJCAI-17 , pp. 3707–3713, 2017. doi: 10.24963/ijcai.2017/518 . URL https://doi.org/10.24963/ijcai.2017/518 .
McAllister & Rasmussen (2016) McAllister, R. and Rasmussen, C. Data-efficient reinforcement learning in continuous-state pomdps. ArXiv preprint , February 2016. URL https://arxiv.org/abs/1602.02523 .
McCloud (1993) McCloud, Scott. Understanding Comics: The Invisible Art . Tundra Publishing, 1993. URL https://en.wikipedia.org/wiki/Understanding_Comics .
Miikkulainen (2013) Miikkulainen, R. Evolving neural networks. IJCNN , August 2013. URL http://nn.cs.utexas.edu/downloads/slides/miikkulainen.ijcnn13.pdf .
Mnih et al. (2013) Mnih, V., Kavukcuoglu, K., Silver, D., Graves, A., Antonoglou, I., Wierstra, D., and Riedmiller, M. Playing atari with deep reinforcement learning. ArXiv preprint , December 2013. URL https://arxiv.org/abs/1312.5602 .
Mobbs et al. (2015) Mobbs, Dean, Hagan, Cindy C., Dalgleish, Tim, Silston, Brian, and Prévost, Charlotte. The ecology of human fear: survival optimization and the nervous system., 2015. URL https://www.frontiersin.org/article/10.3389/fnins.2015.00055 .
Munro (1987) Munro, P. W. A dual back-propagation scheme for scalar reinforcement learning. Proceedings of the Ninth Annual Conference of the Cognitive Science Society, Seattle, WA , pp. 165–176, 1987.
Nagabandi et al. (2017) Nagabandi, A., Kahn, G., Fearing, R., and Levine, S. Neural network dynamics for model-based deep reinforcement learning with model-free fine-tuning. ArXiv preprint , August 2017. URL https://arxiv.org/abs/1708.02596 .
Nguyen & Widrow (1989) Nguyen, N. and Widrow, B. The truck backer-upper: An example of self learning in neural networks. In Proceedings of the International Joint Conference on Neural Networks , pp. 357–363. IEEE Press, 1989.
Nortmann et al. (2015) Nortmann, Nora, Rekauzke, Sascha, Onat, Selim, König, Peter, and Jancke, Dirk. Primary visual cortex represents the difference between past and present. Cerebral Cortex , 25(6):1427–1440, 2015. doi: 10.1093/cercor/bht318 . URL http://dx.doi.org/10.1093/cercor/bht318 .
Oh et al. (2015) Oh, J., Guo, X., Lee, H., Lewis, R., and Singh, S. Action-conditional video prediction using deep networks in atari games. ArXiv preprint , July 2015. URL https://arxiv.org/abs/1507.08750 .
Oudeyer et al. (2007) Oudeyer, P., Kaplan, F., and Hafner, V. Intrinsic motivation systems for autonomous mental development. Trans. Evol. Comp , apr 2007. doi: 10.1109/TEVC.2006.890271 . URL http://www.pyoudeyer.com/ims.pdf .
Paquette (2016) Paquette, Philip. Doomtakecover-v0, 2016. URL https://gym.openai.com/envs/DoomTakeCover-v0/ .
Parker & Bryant (2012) Parker, M. and Bryant, B. Neuro-visual control in the quake ii environment. IEEE Transactions on Computational Intelligence and AI in Games , 2012. URL https://www.cse.unr.edu/~bdbryant/papers/parker-2012-tciaig.pdf .
Pathak et al. (2017) Pathak, D., Agrawal, P., A., Efros, and Darrell, T. Curiosity-driven exploration by self-supervised prediction. ArXiv preprint , May 2017. URL https://pathak22.github.io/noreward-rl/ .
Pi et al. (2013) Pi, H., Hangya, B., Kvitsiani, D., Sanders, J., Huang, Z., and Kepecs, A. Cortical interneurons that specialize in disinhibitory control. Nature , November 2013. doi: 10.1038/nature12676 . URL http://dx.doi.org/10.1038/nature12676 .
Prieur (2017) Prieur, Luc. Deep-q learning for box2d racecar rl problem., 2017. URL https://goo.gl/VpDqSw .
Quiroga et al. (2005) Quiroga, R., Reddy, L., Kreiman, G., Koch, C., and Fried, I. Invariant visual representation by single neurons in the human brain. Nature , 2005. doi: 10.1038/nature03687 . URL http://www.nature.com/nature/journal/v435/n7045/abs/nature03687.html .
Ratcliff (1990) Ratcliff, Rodney Mark. Connectionist models of recognition memory: constraints imposed by learning and forgetting functions. Psychological review , 97 2:285–308, 1990.
Rechenberg (1973) Rechenberg, I. Evolutionsstrategie: optimierung technischer systeme nach prinzipien der biologischen evolution . Frommann-Holzboog, 1973. URL https://en.wikipedia.org/wiki/Ingo_Rechenberg .
Rezende et al. (2014) Rezende, D., Mohamed, S., and Wierstra, D. Stochastic backpropagation and approximate inference in deep generative models. ArXiv preprint , 2014. URL https://arxiv.org/abs/1401.4082 .
Robinson & Fallside (1989) Robinson, T. and Fallside, F. Dynamic reinforcement driven error propagation networks with application to game playing. In CogSci 89 , 1989.
Salimans et al. (2017) Salimans, T., Ho, J., Chen, X., Sidor, S., and Sutskever, I. Evolution strategies as a scalable alternative to reinforcement learning. ArXiv preprint , 2017. URL https://arxiv.org/abs/1703.03864 .
Schmidhuber (1990a) Schmidhuber, J. Making the world differentiable: On using self-supervised fully recurrent neural networks for dynamic reinforcement learning and planning in non-stationary environments. 1990a. URL http://people.idsia.ch/~juergen/FKI-126-90_(revised)bw_ocr.pdf .
Schmidhuber (1990b) Schmidhuber, J. An on-line algorithm for dynamic reinforcement learning and planning in reactive environments. 1990 IJCNN International Joint Conference on Neural Networks , pp. 253–258 vol.2, June 1990b. doi: 10.1109/IJCNN.1990.137723 . URL ftp://ftp.idsia.ch/pub/juergen/ijcnn90.ps.gz .
Schmidhuber (1990c) Schmidhuber, J. A possibility for implementing curiosity and boredom in model-building neural controllers. Proceedings of the First International Conference on Simulation of Adaptive Behavior on From Animals to Animats , pp. 222–227, 1990c. URL ftp://ftp.idsia.ch/pub/juergen/curiositysab.pdf .
Schmidhuber (1991a) Schmidhuber, J. Reinforcement learning in markovian and non-markovian environments. Advances in Neural Information Processing Systems 3 , pp. 500–506, 1991a. URL https://goo.gl/ij1uYQ .
Schmidhuber (1991b) Schmidhuber, J. Curious model-building control systems. In Proc. International Joint Conference on Neural Networks, Singapore , pp. 1458–1463, 1991b.
Schmidhuber (1992) Schmidhuber, J. Learning complex, extended sequences using the principle of history compression. Neural Computation , 4(2):234–242, 1992. (Based on TR FKI-148-91, TUM, 1991).
Schmidhuber (2002) Schmidhuber, J. Optimal ordered problem solver. ArXiv preprint , July 2002. URL https://arxiv.org/abs/cs/0207097 .
Schmidhuber (2006) Schmidhuber, J. Developmental robotics, optimal artificial curiosity, creativity, music, and the fine arts. Connection Science , 18(2):173–187, 2006.
Schmidhuber (2010) Schmidhuber, J. Formal theory of creativity, fun, and intrinsic motivation (1990-2010). IEEE Trans. Autonomous Mental Development , 2010. URL http://people.idsia.ch/~juergen/creativity.html .
Schmidhuber (2013) Schmidhuber, J. Powerplay: Training an increasingly general problem solver by continually searching for the simplest still unsolvable problem. Frontiers in Psychology , 4:313, 2013. ISSN 1664-1078. doi: 10.3389/fpsyg.2013.00313 . URL https://www.frontiersin.org/article/10.3389/fpsyg.2013.00313 .
Schmidhuber (2015a) Schmidhuber, J. On learning to think: Algorithmic information theory for novel combinations of reinforcement learning controllers and recurrent neural world models. ArXiv preprint , 2015a. URL https://arxiv.org/abs/1511.09249 .
Schmidhuber (2015b) Schmidhuber, J. Deep learning in neural networks: An overview. Neural Networks , 61:85–117, 2015b. doi: 10.1016/j.neunet.2014.09.003 . Published online 2014; based on TR arXiv:1404.7828 [cs.NE].
Schmidhuber (2018) Schmidhuber, J. One big net for everything. Preprint arXiv:1802.08864 [cs.AI] , February 2018. URL https://arxiv.org/abs/1802.08864 .
Schmidhuber & Huber (1991) Schmidhuber, J. and Huber, R. Learning to generate artificial fovea trajectories for target detection. International Journal of Neural Systems , 2(1-2):125–134, 1991. doi: 10.1142/S012906579100011X . URL ftp://ftp.idsia.ch/pub/juergen/attention.pdf .
Schmidhuber et al. (1994) Schmidhuber, J., Storck, J., and Hochreiter, S. Reinforcement driven information acquisition in nondeterministic environments. Technical Report FKI- -94, TUM Department of Informatics, 1994.
Schwefel (1977) Schwefel, H. Numerical Optimization of Computer Models . John Wiley and Sons, Inc., New York, NY, USA, 1977. ISBN 0471099880. URL https://en.wikipedia.org/wiki/Hans-Paul_Schwefel .
Sehnke et al. (2010) Sehnke, F., Osendorfer, C., Ruckstieb, T., Graves, A., Peters, J., and Schmidhuber, J. Parameter-exploring policy gradients. Neural Networks , 23(4):551–559, 2010. doi: 10.1016/j.neunet.2009.12.004 . URL http://citeseerx.ist.psu.edu/viewdoc/download;jsessionid=A64D1AE8313A364B814998E9E245B40A?doi=10.1.1.180.7104&rep=rep1&type=pdf .
Shazeer et al. (2017) Shazeer, N., Mirhoseini, A., Maziarz, K., Davis, A., Le, Q., Hinton, G., and Dean, J. Outrageously large neural networks: The sparsely-gated mixture-of-experts layer. ArXiv preprint , January 2017. URL https://arxiv.org/abs/1701.06538 .
Silver et al. (2016) Silver, D., van Hasselt, H., Hessel, M., Schaul, T., Guez, A., Harley, T., Dulac-Arnold, G., Reichert, D., Rabinowitz, N., Barreto, A., and Degris, T. The predictron: End-to-end learning and planning. ArXiv preprint , December 2016. URL https://arxiv.org/abs/1612.08810 .
Silver (2017) Silver, David. David silver’s lecture on integrating learning and planning, 2017. URL http://www0.cs.ucl.ac.uk/staff/d.silver/web/Teaching_files/dyna.pdf .
Srivastava et al. (2012) Srivastava, R., Steunebrink, B., and Schmidhuber, J. First experiments with powerplay. ArXiv preprint , October 2012. URL https://arxiv.org/abs/1210.8385 .
Stanley & Clune (2017) Stanley, Kenneth and Clune, Jeff. Welcoming the era of deep neuroevolution, 2017. URL https://eng.uber.com/deep-neuroevolution/ .
Stanley & Miikkulainen (2002) Stanley, Kenneth O. and Miikkulainen, Risto. Evolving neural networks through augmenting topologies. Evolutionary Computation , 10(2):99–127, 2002. URL http://nn.cs.utexas.edu/?stanley:ec02 .
Suarez (2017) Suarez, Joseph. Language modeling with recurrent highway hypernetworks. In Guyon, I., Luxburg, U. V., Bengio, S., Wallach, H., Fergus, R., Vishwanathan, S., and Garnett, R. (eds.), Advances in Neural Information Processing Systems 30 , pp. 3269–3278. Curran Associates, Inc., 2017. URL https://goo.gl/4nqHXw .
Sukhbaatar et al. (2017) Sukhbaatar, S., Lin, Z., Kostrikov, I., Synnaeve, G., Szlam, A., and Fergus, R. Intrinsic motivation and automatic curricula via asymmetric self-play. ArXiv preprint , October 2017. URL https://arxiv.org/abs/1703.05407 .
Sutton & Barto (1998) Sutton, Richard S. and Barto, Andrew G. Introduction to Reinforcement Learning . MIT Press, Cambridge, MA, USA, 1st edition, 1998. ISBN 0262193981. URL http://ufal.mff.cuni.cz/~straka/courses/npfl114/2016/sutton-bookdraft2016sep.pdf .
van den Oord et al. (2016) van den Oord, A., Dieleman, S., Zen, H., Simonyan, K., Vinyals, O., Graves, A., Kalchbrenner, N., Senior, A., and Kavukcuoglu, K. Wavenet: A generative model for raw audio. ArXiv preprint , September 2016. URL https://arxiv.org/abs/1609.03499 .
Vaswani et al. (2017) Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A, Kaiser, L., and Polosukhin, I. Attention is all you need. ArXiv preprint , June 2017. URL https://arxiv.org/abs/1706.03762 .
Wahlström et al. (2014) Wahlström, N., Schön, T., and Deisenroth, M. Learning deep dynamical models from image pixels. ArXiv preprint , October 2014. URL https://arxiv.org/abs/1410.7550 .
Wahlström et al. (2015) Wahlström, N., Schön, T., and Deisenroth, M. From pixels to torques: Policy learning with deep dynamical models. ArXiv preprint , June 2015. URL https://arxiv.org/abs/1502.02251 .
Watanabe et al. (2018) Watanabe, Eiji, Kitaoka, Akiyoshi, Sakamoto, Kiwako, Yasugi, Masaki, and Tanaka, Kenta. Illusory motion reproduced by deep neural networks trained for prediction. Frontiers in Psychology , 9:345, 2018. ISSN 1664-1078. doi: 10.3389/fpsyg.2018.00345 . URL https://www.frontiersin.org/article/10.3389/fpsyg.2018.00345 .
Watter et al. (2015) Watter, M., Springenberg, J., Boedecker, J., and Riedmiller, M. Embed to control: A locally linear latent dynamics model for control from raw images. ArXiv preprint , June 2015. URL https://arxiv.org/abs/1506.07365 .
Watters et al. (2017) Watters, N., Tacchetti, A., Weber, T., Pascanu, R., Battaglia, P., and Zoran, D. Visual interaction networks. ArXiv preprint , June 2017. URL https://arxiv.org/abs/1706.01433 .
Weber et al. (2017) Weber, T., Racanière, S., Reichert, D., Buesing, L., Guez, A., Rezende, D., Badia, A., Vinyals, O., Heess, N., Li, Y., Pascanu, R., Battaglia, P., Silver, D., and Wierstra, D. Imagination-augmented agents for deep reinforcement learning. ArXiv preprint , July 2017. URL https://arxiv.org/abs/1707.06203 .
Werbos (1987) Werbos, P. J. Learning how the world works: Specifications for predictive networks in robots and brains. In Proceedings of IEEE International Conference on Systems, Man and Cybernetics, N.Y. , 1987.
Werbos (1989) Werbos, P. J. Neural networks for control and system identification. In Proceedings of IEEE/CDC Tampa, Florida , 1989.
Werbos (1982) Werbos, Paul J. Applications of advances in nonlinear sensitivity analysis. In System modeling and optimization , pp. 762–770. Springer, 1982.
Wiering & van Otterlo (2012) Wiering, Marco and van Otterlo, Martijn. Reinforcement Learning . Springer, 2012.
Wikipedia (2017) Wikipedia, Authors. Video game exploits, 2017. URL https://en.wikipedia.org/wiki/Video_game_exploits . [Online; accessed 01-Nov-2017].