Why Diffusion Models Don’t Memorize: The Role of Implicit Dynamical Regularization in Training
Why Diffusion Models Don’t Memorize: The Role of Implicit Dynamical Regularization in Training
扩散模型为何不记忆:训练中的隐式动力学正则
Tony Bonnaire † Affiliation: LPENS Affiliation: Université PSL, Paris Email: tony.bonnaire@phys.ens.fr Raphaël Urfin † Affiliation: LPENS Affiliation: Université PSL, Paris Email: raphael.urfin@phys.ens.fr Giulio Biroli Affiliation: LPENS Affiliation: Université PSL, Paris Email: giulio.biroli@phys.ens.fr Marc Mézard Affiliation: Department of Computing Sciences Affiliation: Bocconi University, Milano Email: marc.mezard@unibocconi.it
Tony Bonnaire †(LPENS / Université PSL, Paris) Raphaël Urfin †(LPENS / Université PSL, Paris) Giulio Biroli(LPENS / Université PSL, Paris) Marc Mézard(Bocconi University, Milano)
Abstract
摘要
Diffusion models have achieved remarkable success across a wide range of generative tasks. A key challenge is understanding the mechanisms that prevent their memorization of training data and allow generalization. In this work, we investigate the role of the training dynamics in the transition from generalization to memorization. Through extensive experiments and theoretical analysis, we identify two distinct timescales: an early time at which models begin to generate high-quality samples, and a later time beyond which memorization emerges. Crucially, we find that increases linearly with the training set size , while remains constant. This creates a growing window of training times with where models generalize effectively, despite showing strong memorization if training continues beyond it. It is only when becomes larger than a model-dependent threshold that overfitting disappears at infinite training times. These findings reveal a form of implicit dynamical regularization in the training dynamics, which allow to avoid memorization even in highly overparameterized settings. Our results are supported by numerical experiments with standard U-Net architectures on realistic and synthetic datasets, and by a theoretical analysis using a tractable random features model studied in the high-dimensional limit.
扩散模型在各类生成任务上取得了显著成功。关键挑战之一是理解是什么机制阻止它们记忆训练数据、并允许泛化。本文研究训练动力学在从泛化转向记忆中的作用。通过大量实验与理论分析,我们识别出两个不同的时间尺度:较早的 ,模型开始生成高质量样本;较晚的 ,此后记忆开始出现。关键地, 随训练集大小 线性增长,而 基本保持不变。这使随 增大出现一段不断扩大的训练时间窗口,模型在其中有效泛化;若继续训练超过该窗口,则会表现出强烈记忆。它源于梯度下降训练神经网络得分函数时的隐式动力学正则。我们在 CelebA 上的 U-Net、随机特征模型与高斯混合等设定中验证了这一图像,并给出解析结果支持。
1 Introduction
1 引言
Diffusion Models [49, 20, 54, 55] achieve state-of-the-art performance in a wide variety of AI tasks such as the generation of images [45], audios [64], videos [33], and scientific data [31, 40]. This class of generative models, inspired by out-of-equilibrium thermodynamics [49], corresponds to a two-stage process: the first one, called forward, gradually adds noise to a data, whereas the second one, called backward, generates new data by denoising Gaussian white noise samples. In DMs, the reverse process typically involves solving a stochastic differential equation (SDE) with a force field called score. However, it is also possible to define a deterministic transport through an ordinary differential equation (ODE), treating the score as a velocity field, an approach that is for instance followed in flow matching [32].
扩散模型(Diffusion Models)[49, 20, 54, 55] 在图像[45]、音频[64]、视频[33] 与科学数据[31, 40] 等广泛 AI 任务上达到最先进水平。这类生成模型受非平衡热力学启发[49],对应两阶段过程:前向过程逐步向数据加噪,后向过程通过对高斯白噪声样本去噪来生成新数据。在扩散模型中,反向动力学由得分函数(score) 驱动。
Understanding the generalization properties of score-based generative methods is a central issue in machine learning, and a particularly important question is how memorization of the training set is avoided in practice. A model without regularization achieving zero training loss only learns the empirical score, and is bound to reproduce samples of the training dataset at the end of the backward process. This memorization regime [30, 6] is empirically observed when the training set is small and disappears when it increases beyond a model-dependent threshold [24]. Understanding the mechanisms controlling this change of regimes from memorization to generalization is a central challenge for both theory and applications. Model regularization and inductive biases imposed by the network architecture were shown to play a role [25, 47], as well as a dynamical regularization due to the finiteness of the learning rate [62]. However, the regime shift described above is consistently observed even in models where all these regularization mechanisms are present. This suggests that the core mechanism behind the transition from memorization to generalization lies elsewhere. In this work, we demonstrate – first through numerical experiments, and then via the theoretical analysis of a simplified model – that this transition is driven by an implicit dynamical bias towards generalizing solutions emerging in the training, which allows to avoid the memorization phase.
理解基于得分的生成方法的泛化性质是机器学习的中心问题之一,尤其重要的是:实践中如何避免对训练集的记忆。一个没有正则、把训练损失降到零的模型只会学到经验得分,并在后向过程结束时复现训练样本。这种记忆机制[30, 6] 在训练集较小、维度较高时会被经验观察到;但在大规模设定中,记忆往往在 远未指数级增长于维度 之前就消失了。
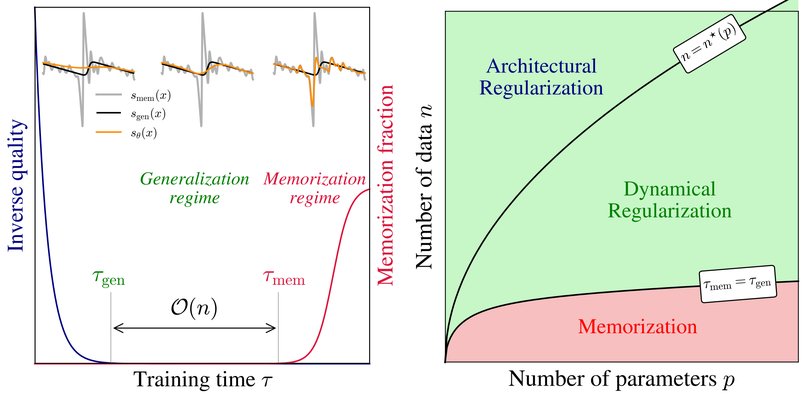
Figure 1: Qualitative summary of our contributions. (Left) Illustration of the training dynamics of a diffusion model. Depending on the training time , we identify three regimes measured by the inverse quality of the generated samples (blue curve) and their memorization fraction (red curve). The generalization regime extends over a large window of training times which increases with the training set size . On top, we show a one dimensional example of the learned score function during training (orange). The gray line gives the exact empirical score, at a given noise level, while the black dashed line corresponds to the true (population) score. (Right) Phase diagram in the plane illustrating three regimes of diffusion models: Memorization when is sufficiently small at fixed , Architectural Regularization for (which is model and dataset dependent, as discussed in [15, 25]), and Dynamical Regularization, corresponding to a large intermediate generalization regime obtained when the training dynamics is stopped early, i.e. .
图1:我们的贡献的定性摘要。 **(左)* 介绍推广模式的培训动态。 根据训练时间,我们确定了三种由生成样品(蓝色曲线)的反向质量及其记忆分数(红色曲线)测量的制度。 通用制度覆盖了培训时间的大窗口,随着培训设置的大小的增加。 在顶部,我们傀儡在训练期间(橙色)展示一个驯服时学习得分功能的一雌性例子畸形.侬. 灰色线给出精确的经验正在进行得分 这就是 天呐 当一个噪声级别上 黑色破 我来对应真实的(人口)分数 (权利) XXMAdong2XX平面中的相位都有权显示有代表性的三种扩散模式:XXMA的人民币在固定的时足够小的纪念物;的建筑规范化(这是模型在上述[15,25]中所讨论的橱窗和数据集的依赖物);动态规范化,相当于早期停止培训动力学时获得的大型中间泛化制度,即XX参与了.
Contributions and theoretical picture.
We investigate the dynamics of score learning using gradient descent, both numerically and analytically, and study the generation properties of the score depending on the time at which the training is stopped. The theoretical picture built from our results and combining several findings from the recent literature is illustrated in Fig. 1. The two main parameters are the size of the training set and the expressivity of the class of score functions on which one trains the model, characterized by a number of parameters ; when both and are large one can identify three main regimes. Given , if is larger than (which depends on the training set and on the class of scores), the score model is not expressive enough to represent the empirical score associated to data, and instead provides a smooth interpolation, approximately independent of the training set. In this regime, even with a very large training time , memorization does not occur because the model is regularized by its architecture and the finite number of parameters. When the model is expressive enough to memorize, and two timescales emerge during training: one, , is the minimum training time required to achieve high-quality data generation; the second, , signals when further training induces memorization, and causes the model to increasingly reproduce the training samples (left panel). The first timescale, , is found independent of , whereas the second, , grows approximately linearly with , thus opening a large window of training times during which the model generalizes if early stopped when . Our results shows that implicit dynamical regularization in training plays a crucial role in score-based generative models, substantially enlarging the generalization regime (see right panel of Fig. 1), and hence allowing to avoid memorization even in highly overparameterized settings. We find that the key mechanism behind the widening gap between and is the irregularity of the empirical score at low noise level and large . In this regime the models used to approximate the score provide a smooth interpolation that remains stable for a long period of training times and closely approximates the population score, a behavior likely rooted in the spectral bias of neural networks [42]. Only at very long training times do the dynamics converge to the low lying minimum corresponding to the empirical score, leading to memorization (as illustrated in the one-dimensional examples in the left panel of Fig. 1).
贡献与理论图景。
我们用梯度下降从数值与解析两方面研究得分学习动力学,并考察训练停止时刻 对生成性质的影响。综合本文结果与近期文献若干发现所形成的理论图景见图 1。两个主要参数是训练集大小 ,以及所训练得分函数类的表达能力(以参数量 刻画);当 与 都很大时,可以区分三种主要机制。给定 ,若 大于 (依赖于训练集与得分函数类),得分模型不足以表示与 个数据对应的经验得分,而会给出近似不依赖训练集的平滑插值。在此机制下,即便训练时间 很长,记忆也不会发生,因为架构与有限参数量本身构成正则。当 时模型足以记忆,训练中出现两个时间尺度: 是达到高质量数据生成所需的最短训练时间; 标志着继续训练会诱发记忆,使模型越来越多地复现训练样本(左图)。第一个时间尺度 与 无关,第二个 近似随 线性增长,从而在早停于 时打开一大段泛化窗口。结果表明,训练中的隐式动力学正则对基于得分的生成模型至关重要,显著扩大了泛化区间(见图 1 右),即便在高度过参数化设定下也能避免记忆。我们发现 与 间距拉大的关键机制,是低噪声、大 下经验得分的不规则性。此时用于近似得分的模型给出平滑插值,在很长一段训练时间内保持稳定,并紧密逼近总体得分,这一行为很可能源于神经网络的频谱偏置 [42]。只有在极长训练时间后,动力学才收敛到对应经验得分的低洼极小,从而导致记忆(如图 1 左的一维示例所示)。
The theoretical picture described above is based on our numerical and analytical results, and builds up on previous works, in particular numerical analysis characterizing the memorization–generalization transition [18, 63], analytical works on memorization of DMs [15, 25, 24], and studies on the spectral bias of deep neural networks [42]. Our numerical experiments use a class of scores based on a realistic U-Net [46] trained on downscaled images of the CelebA dataset [34]. By varying and , we measure the evolution of the sample quality (through FID) and the fraction of memorization during learning, which support the theoretical scenario presented in Fig. 1. Additional experimental results on synthetic data are provided in Supplemental Material (SM, Sects. A and B). On the analytical side, we focus on a class of scores constructed from random features and simplified models of data, following [15]. In this setting, the timescales of training dynamics correspond directly to the inverse eigenvalues of the random feature correlation matrix. Leveraging tools from random matrix theory, we compute the spectrum in the limit of large datasets, high-dimensional data, and overparameterized models. This analysis reveals, in a fully tractable way, how the theoretical picture of Fig. 1 emerges within the random feature framework.
以上描述的理论画面以我们的数值和分析结果为基础,并借鉴了以往的著作,尤其是描述记忆-泛化过渡的数值分析[18,63],关于DMs的记忆分析作品[15,25,24],关于深神经网络光谱偏差的研究[42]. 我们的数字实验使用基于一个现实的U-Net的分数等级[46],训练了CelebA数据集的降级图像[34]. 通过不同的和,我们测量样本质量的演变(通过FID)和学习过程中的记忆的一小部分,这支持了Fig中提出的理论情景. 1. 关于合成数据的其他实验结果载于补充材料(SM、Sects)。 页:1 在分析方面,我们侧重于从随机特征和简化的数据模型中构建的分数类别,遵循[15]. 在此设定中,训练动力学的时间尺度直接对应随机特征相关性矩阵的反义值. 从随机矩阵理论中利用工具,我们计算出大数据集,高维数据和超参数模型的极限光谱. 这一分析以完全可拉动的方式揭示了图1的理论画面是如何在随机特征框架内出现的.
Related works.
- • The memorization transition in DMs has been the subject of several recent empirical investigations [9, 50, 51] which have demonstrated that state-of-the-art image DMs – including Stable Diffusion and DALL·E – can reproduce a non-negligible portion of their training data, indicating a form of memorization. Several additional works [18, 63] examined how this phenomenon is influenced by factors such as data distribution, model configuration, and training procedure, and provide a strong basis for the numerical part of our work.
- • A series of theoretical studies in the high-dimensional regime have analyzed the memorization–generalization transition during the generative dynamics under the empirical score assumption [6, 1, 57], showing how trajectories are attracted to the training samples. Within this high-dimensional framework, [11, 12, 60, 15] study the score learning for various model classes. In particular, [15] uses a Random Feature Neural Network [43]. The authors compute the asymptotic training and test losses for and relate it to memorization. The theoretical part of our work generalizes this approach to study the role of training dynamics and early stopping in the memorization–generalization transition.
- • Recent works have also uncovered complementary sources of implicit regularization explaining how DMs avoid memorization. Architectural biases and limited network capacity were for instance shown to constrain memorization in [25, 24], and finiteness of the learning rate prevents the model from learning the empirical score in [62]. Also related to our analysis, [29] provides general bounds showing the beneficial role of early stopping the training dynamics to enhance generalization for finitely supported target distributions, as well as a study of its effect for one-dimensional gaussian mixtures.
- • Finally, previous studies on supervised learning [42, 65], and more recently on DMs [59], have shown that deep neural networks display a frequency-dependent learning speed, and hence a learning bias towards low frequency functions. This fact plays an important role in the results we present since the empirical score contains a low frequency part that is close to the population score, and a high-frequency part that is dataset-dependent. To the best of our knowledge, the training time to learn the high-frequency part and hence memorize, that we find to scale with , has not been studied from this perspective in the context of score-based generative methods.
相关作品。
- 模式草案的记忆过渡是最近几次经验调查[9、50、51]的主题,这些调查表明,最先进的模式草案 --灿烂的图像,包括稳定扩散和DALL-E -- -- 可以复制其培训数据中不可忽略的部分,表明一种记忆形式。 另有几部著作[18,63]研究了这一现象如何受到数据分布、模型配置和培训程序等因素的影响,并为我们工作的数字部分提供了坚实的基础。
- 高维度制度的一系列理论研究分析了经验分数假设[6,1,57]下基因动力学期间的记忆-通用过渡,显示了轨迹如何被训练样本所吸引. 在这个高维度框架内,[11,12,60,15]为各种模范班学习分数学习. 特别是[15]使用随机特征神经网络[43]. 作者计算的不对称培训和测试损失,并将其与记忆联系起来。 我们工作的理论部分概括了这一方法,以研究培训动态和早期停止记忆-普遍化过渡的作用。
- 最近的工作还发现了间接正规化的补充来源,解释模式草案如何避免记忆。 例如,在[25、24]中,建筑偏见和有限的网络能力被证明制约了记忆,学习率的有限性使模型无法学习[62]中的经验分数。 与我们的分析同样相关的是,[29] 提供了一般性的界限,说明及早停止培训动态对加强有限支持的目标分布的概括性的益处,以及研究其对一维加乌西混合物的影响。
- 最后,以前关于监督学习的研究表明[42、65],最近关于DMs[59]的研究表明,深神经网络显示一个依赖频率的学习速度,因此对低频率功能的学习偏向。 这一事实在我们目前的成果中发挥着重要作用,因为经验分数包含一个接近人口分数的低频部分,以及一个依赖数据集的高频部分. 就我们所知,我们发现使用进行高频部分并因此记住的训练时间,还没有从这一角度在基于分数的基因方法中加以研究。
Setting: generative diffusion and score learning.
Standard DMs define a transport from a target distribution in to a Gaussian white noise through a forward process defined as an Ornstein-Uhlenbeck (OU) stochastic differential equation (SDE):
- 设定:基因传播和分数学习姻缘。
标准DMs定义从中的目标分布到高斯白噪 ,通过一个向前过程定义为Ornstein-Uhlenbeck(OU)斜差方程(SDE):
where is square root of two times a Wiener process. Generation is performed by time-reversing the SDE (1) using the score function ,
其中是双倍维纳过程的平方根. 生成是通过使用分数函数的SDE (1) 时间反转实现的,
where is the probability density at time along the forward process, and the noise is also the square root of two times a Wiener process. As shown in the seminal works [23, 58], can be obtained by minimizing the score matching loss
其中是沿前进过程的时间的概率密度,噪声也是双倍维纳过程的平方根. 如开创性作品[23,58]所示,可以通过最小化比分损失获得.
where . In practice, the optimization problem is restricted to a parametrized class of functions defined, for example, by a neural network with parameters . The expectation over is replaced by the empirical average over the training set ( iid samples drawn from ),
第号 在实际操作中,优化问题被限制在被参数的神经网络所定义的功能的准化类. 对XXMA 这方面的期望被培训组的经验平均值所取代( iid样本 来自),
where . The loss in (4) can be minimized with standard optimizers, such as stochastic gradient descent [44] or Adam [28]. In practice, a single model conditioned on the diffusion time is trained by integrating (4) over time [26]. The solution of the minimization of (4) is the so-called empirical score (e.g. [6, 30]), defined as , with
第号 (4)中的损失可以用标准优化器最小化,如斜坡梯度下降[44]或亚当[28]. 在实践中,一个以传播时间为条件的单一模型通过集成(4)在一段时间[26]进行训练. 最小化(4)的解决方案是所谓的经验得分(如[6,30]),定义为,与.
This solution is known to inevitably recreate samples of the training set at the end of the generative process (i.e., it perfectly memorizes), unless grows exponentially with the dimension [6]. However, this is not the case in many practical applications where memorization is only observed for relatively small values of , and disappears well before becomes exponentially large in . The empirical minimization performed in practice, within a given class of models and a given minimization procedure, does not drive the optimization to the global minimum of (4), but instead to a smoother estimate of the score that is independent of the training set with good generalization properties [24], as the global minimum of (3) would do. Understanding how it is possible, and in particular the role played by the training dynamics to avoid memorization, is the central aim of the present work.
众所周知,除非与维度[6]成指数增长,否则这种解决方案将不可避免地重现基因过程末端设定的训练样本(即完全记忆). 然而,在许多实际应用中,情况并非如此,因为人们只观察到纪念值相对较小的,而且早在在成指数大之前就已消失。 在实践中,在一定的模型类别和特定最小化程序内进行的经验最小化并不* 推动优化到全球最低(4),而是像全球最低(3)那样,更平稳地估计独立于具有良好一般化特性的培训集的得分[24]。 了解如何做到这一点,特别是了解培训动态在避免记忆方面的作用,是目前工作的核心目标。
2 Generalization and memorization during training of diffusion models
2 扩散模型训练中的泛化与记忆
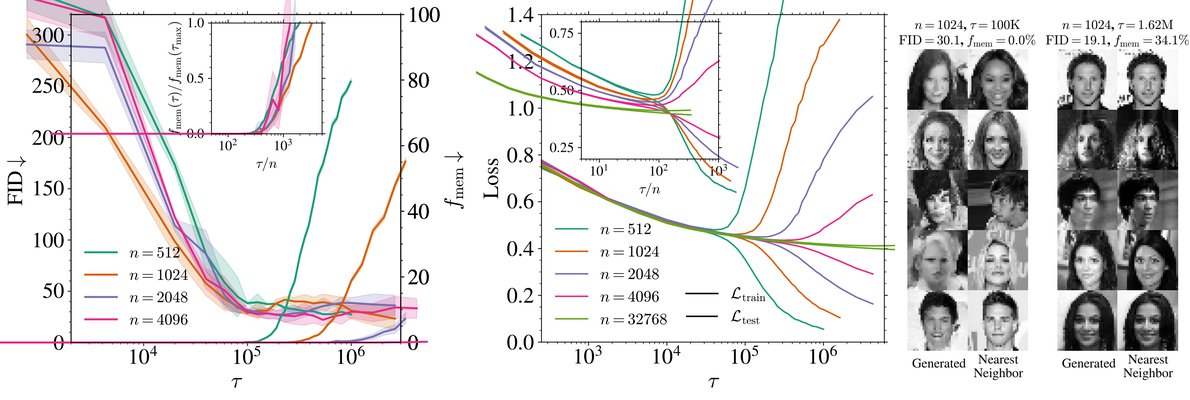
Figure 2: Memorization transition as a function of the training set size for U-Net score models on CelebA. (Left) FID (solid lines, left axis) and memorization fraction (dashed lines, right axis) against training time for various . Inset: normalized memorization fraction with the rescaled time . (Middle) Training (solid lines) and test (dashed lines) loss with for several at fixed . Inset: both losses plotted against . Error bars on the losses are imperceptible. (Right) Generated samples from the model trained with for K or M steps, along with their nearest neighbors in the training set.
图2:** 记忆过渡作为培训设置大小用于CelebA上的U-Net分数模型 *(Left) * FID(固态线,左轴)和记忆分数 (dashed line,右轴) 相对于培训时间用于各种 . 套期: 普通的记分与重定时间 . *(中) * 在固定的中,若干的培训(固线)和试验(干线)损失为。 套期:两项损失均与相对应。 损失上的错误栏是无法察觉的。 (权利) 用为 K或 M级台阶培训的模型生成样本,以及培训组中最近的邻居。 **
Data & architecture.
We conduct our experiments on the CelebA face dataset [34], which we convert to grayscale downsampled images of size , and vary the training set size from 128 up to 32768. Our score model has a U-Net architecture [46] with three resolution levels and a base channel width of with multipliers 1, 2 and 3 respectively. All our networks are DDPMs [20] trained to predict the injected noise at diffusion time using SGD with momentum at fixed batch size . The models are all conditioned on , i.e. a single model approximates the score at all times, and make use of a standard sinusoidal position embedding [56] that is added to the features of each resolution. More details about the numerical setup can be found in SM (Sect. A).
QQ 数据架构( A).
我们在CelebA面部数据集上进行实验[34],我们将其转换成灰度下取样的大小为的图像,并将训练集大小从128到32768. 我们的分数模型有一个U-Net架构[46],分辨度分为三个级别,基信道宽度为,乘数分别为1,2和3. 我们所有的网络都是DDPMs [20] ,在扩散时间使用具有固定批量大小的的SGD来预测注入的噪音。 这些模型都以为条件,即一个单一模型在任何时候都大致比分,并使用嵌入每个分辨率特征的标准sinoidal位置[56]. 关于数字设置的更多细节,请参见SM(A节).
Evaluation metrics.
To study the transition from generalization to memorization during training, we monitor the loss (4) during training using a fixed diffusion time . At various numbers of SGD updates , we compute the loss on all training examples (training loss) and on a held-out test set of 2048 images (test loss). To characterize the score obtained after a training time , we assess the originality and quality of samples by generating 10K samples using a DDIM accelerated sampling [52]. We compute (i) the Fréchet-Inception Distance [19] against 10K test samples which we use to identify the generalization time ; and (ii) the fraction of memorized generated samples granting access to , the memorization time. Following previous numerical studies [63, 18], a generated sample is considered memorized if
- 评价尺度。
为了研究培训期间从一般化向记忆化的过渡,我们利用固定传播时间监测培训期间的损失(4)。 在各种编号的SGD更新中,我们计算所有培训实例的损失(培训损失)和由2048个图像(测试损失)组成的搁置测试集的损失。 为了描述训练时间之后获得的分数,我们通过使用DDIM加速采样生成10K样品,评估样品的原生性和质量[52]. 我们计算(一) Fréchet-Inception District [19] 相对于10K测试样本,我们用来确定通用时间;和(二) 记忆生成的样本的一小部分,允许访问,即纪念时间。 经过以前的数值研究[63, 18],生成的样本如果
where and are the nearest and second nearest neighbors of in the training set in the sense. In what follows, we choose to work with [63, 18], but we checked that varying to or does not impact the claims about the scaling. Error bars in the figures correspond to twice the standard deviation over 5 different test sets for FIDs, and 5 noise realizations for and . For , we report the 95% CIs on the mean evaluated with 1,000 bootstrap samples.
其中和是在意义上的训练集中距离最近和次近的邻居. 在下文中,我们选择与 [63, 18] 合作,但我们检查了不同的至或不会影响关于缩放的索赔. 数字中的错误栏对应于5个不同测试集上的标准偏差的两倍,对和的5个噪声实现. 对于 ,我们报告95%的CI 在平均评估 1,000靴子样本。
Role of training set size on the learning dynamics.
At fixed model capacity (, base width ), we investigate how the training set size impacts the previous metrics. In the left panel of Fig. 2, we first report the FID (solid lines) and (dashed lines) for various . All trainings dynamics exhibit two phases. First, the FID quickly decreases to reach a minimum value on a timescale (K) that does not depend on . In the right panel, the generated samples at K clearly differ from their nearest neighbors in the training set, indicating that the model generalizes correctly. Beyond this time, the FID remains flat. is zero until a later time after which it increases, clearly signaling the entrance into a memorization regime, as illustrated by the generated samples in the right-most panel of Fig. 2, very close to their nearest neighbors. Both the transition time and the value of the final fraction (with being one to four million SGD steps) vary with . The inset plot shows the normalized memorization fraction against the rescaled time , making all curves collapse and increase at around , showing that , and demonstrating the existence of a generalization window for that widens linearly with , as illustrated in the left panel of Fig. 1.
训练集大小对学习动力学的影响。
在固定模型容量(,基宽度 )下,我们考察训练集大小 如何影响上述指标。图 2 左图给出不同 下的 FID(实线)与 (虚线)。所有训练动力学都呈现两阶段:首先 FID 迅速下降,在与 无关的时间尺度 (约 K)上达到最小值。右图显示,K 时生成样本与训练集最近邻明显不同,说明模型正确泛化。此后 FID 保持平台; 在更晚的 之前为零,之后上升,明确进入记忆机制。
As highlighted in the introduction, memorization in DMs is ultimately driven by the overfitting of the empirical score . The evolution of and at fixed are shown in the middle panel of Fig. 2 for ranging from 512 to 32768. Initially, the two losses remain nearly indistinguishable, indicating that the learned score does not depend on the training set. Beyond a critical time, continues to decrease while increases, leading to a nonzero generalization loss whose magnitude depends on . As increases, this critical time also increases and, eventually, the training and test loss gap shrinks: for , the test loss remains close to the training loss, even after 11 million SGD steps. The inset shows the evolution of both losses with , demonstrating that the overfitting time scales linearly with the training set size , just like identified in the left panel. Moreover, there is a consistent lag between the overfitting time and at fixed , reflecting the additional training required for the model to overfit the empirical score sufficiently to reproduce the training samples, and therefore to impact the memorization fraction.
正如导言中所强调的那样,模式草案中的纪念最终是由经验得分的过度匹配所推动的。 和在固定的的演化过程在图2的中间面板中显示,的演化范围从512到32768. 最初,这两种损失仍然几乎无法区分,表明所学得分并不取决于训练集. 在关键时刻之后,继续减少,而则增加,导致非零一般化损失,其程度取决于。 随着的增加,这一关键时间也增加了,最终培训和测试损失差距缩小:对于来说,即使经过1100万SGD步骤,测试损失仍然接近培训损失. 套件显示这两种损失与的演化,表明时间尺度与训练设置大小的线性比过大,与左面面板确定的一样. 此外,在固定的中,过度适应的时间和之间一直存在滞后,这反映了模型需要额外培训,以过度适应经验得分,足以复制培训样本,从而影响记忆分数。
Memorization is not due to data repetition.
We must stress that this delayed memorization with is not due to the mere repetition of training samples, as a first intuition could suggest. In SM Sects. A and B, we show that full-batch updates still yield . In other words, even if at fixed all models have processed each sample equally often, larger consistently postpone memorization. This confirms that memorization in DMs is driven by a fundamental -dependent change in the loss landscape – not by a sample repetition during training.
记忆并非来自数据重复。
必须强调:随 推迟的记忆不是仅因训练样本被看到的次数更少——尽管直觉上容易这么想。附录 A、B 表明,即便采用全 batch 更新, 仍然成立。换言之,在固定 下各模型已同等次数地处理每个样本时,更大的 仍一致地推迟记忆。这说明扩散模型中的记忆由损失地貌随 的根本变化驱动,而非训练中的样本重复。
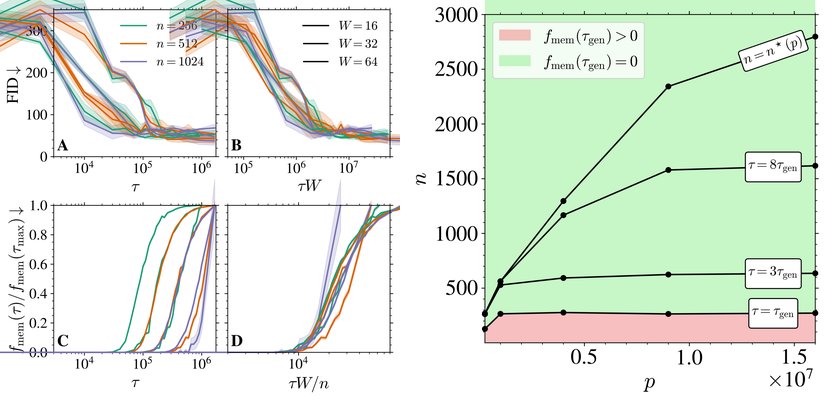
Figure 3: Effect of the number of parameters in the U-Net architecture on the timescales of the training dynamics. (Left) FID (panels A, B) and normalized memorization fraction (panels C, D) for various and during training. In panels B and D, time is rescaled such that all curves collapse. (Right) phase diagram of generalization vs memorization for U-Nets trained on CelebA. Curves show, for , the minimal dataset size satisfying . The shaded background indicates the memorization–generalization boundary for .
图3:** U-Net架构参数数对培训动态时限的影响。 *(左) * FID(A、B小组)和在培训期间用于各种和的普通纪念分数(C、D小组)。 在B面板和D面板中,时间被调整到所有曲线都崩溃。 *(右) *相位图 泛化图与关于CelebA培训的U-Net的纪念图。 曲线显示,对于,最小数据集大小满足. 阴影背景表示的纪念-通用边界。 **
Effect of the model capacity.
To study more precisely the role of the model capacity on the memorization–generalization transition, we vary the number of parameters by changing the U-Nets base width , resulting in a total of parameters. In the left panel of Fig. 3, we plot both the FID (top row) and the normalized memorization fraction (bottom row) as functions of for several width and training set sizes . Panels A and C demonstrate that higher-capacity networks (larger ) achieve high-quality generation and begin to memorize earlier than smaller ones. Panels B and D show that the two characteristic timescales simply scale as and . In particular, this implies that, for , the critical training set size at which is approximately independent of (at least on the limited values of we focused on). When , the interval opens up, so that early stopping within this window yields high quality samples without memorization. In the right panel of Fig. 3, we display this boundary (solid line) in the plane by fixing the training time to , that we identify numerically using the collapse of all FIDs at around (see panel B), and computing the smallest such that . The resulting solid curve delineates two regimes: below the curve, memorization already starts at ; above the curve, the models generalize perfectly under early stopping. We repeat this experiment for and , showing saturation to larger and larger as increases. Eventually, for , we expect these successive boundaries to converge to the architectural regularization threshold , i.e. the point beyond which the network avoids memorization because it is not expressive enough, as found in [15] and highlighted in the right panel of Fig. 1. In order to estimate , we measure for a given the largest yielding . The curve approaches for large . We therefore estimate by measuring the asymptotic values of , which in practice is reached already at M updates for the values of we focus on.
模型容量的影响。
为更精确研究容量对记忆–泛化转变的作用,我们通过改变 U-Net 基宽度 来改变参数量 ,得到 。图 3 左图给出若干 与 下 FID(上行)与归一化记忆比例(下行)随 的变化。面板 A、C 表明更高容量网络(更大 )更早达到高质量生成,也更早开始记忆。面板 B、D 显示两个特征时间尺度简单标度为 、。
3 Training dynamics of a Random Features Network
3 随机特征网络的训练动力学
Notations.
We use bold symbols for vectors and matrices. The norm of a vector is denoted by . We write to mean that in the limit , there exists a constant such that .
注释。
我们在向量和矩阵中使用粗体符号. 矢量的规范由表示. 我们将写为:在极限中,存在一个恒定的,即.
Setting.
We study analytically a model introduced in [15], where the data lie in dimensions. We parametrize the score with a Random Features Neural Network [43]
准备
我们从分析角度研究了[15]中引入的模型,其中的数据是维度。 我们用随机功能神经网络来压平得分 [43]
An RFNN, illustrated in Fig. 4 (left), is a two-layer neural-network whose first layer weights () are drawn from a Gaussian distribution and remain frozen while the second layer weights () are learned during training. This model has already served as theoretical framework for studying several behaviors of deep neural network such as the double descent phenomenon [35, 13]. is an element-wise non-linear activation function. We consider a training set of iid samples for and we focus on the high-dimensional limit with the ratios kept fixed. We study the training dynamics associated to the minimization of the empirical score matching loss defined in (4) at a fixed diffusion time . This is a simplification compared to practical methods, which use a single model for all . It has been already studied in previous theoretical works [11, 15]. The loss (4) is rescaled by a factor in order to ensure a finite limit at large . We also study the evolution of the test loss evaluated on test points and the distance to the exact score ,
图4(左)所示的RFNN是一种双层神经网络,其第一层重量()来自高斯分布,在训练期间学习到第二层重量()时保持冷冻. 这个模型已经作为研究深神经网络的几种行为,如双向下降现象的理论框架[35,13]. 是一种元素明智的非线性激活功能. 我们考虑为提供一套由 iid样本组成的训练集,我们侧重于高维限的,保持的比例不变。 我们研究了与在的固定传播时间尽量减少(4)中定义的实证分数匹配损失有关的培训动态。 与实用方法相比,这是一种简化,对所有使用单一模式。 在之前的理论著作中已经研究过[11,15]. 损失(4)按因数调整,以确保在大范围内有限度。 我们还研究测试点评估的测试损失的演变情况,以及准确得分的距离。
where the expectations are computed over and . The generalization loss, defined as , indicates the degree of overfitting in the model while the distance to the exact score measures the quality of the generation as it is an upper bound on the Kullback–Leibler divergence between the target and generated distributions [53, 8]. The weights are updated via gradient descent
第和之间计算的期望值。 泛化损失被定义为,表示模型中过度适应的程度,而与精确分数的距离则测量生成质量,因为它是Kullback - Leibleer在目标与生成分布之间的上方界限[53,8].通过梯度下降更新加权数
where is the learning rate. In the high-dimensional limit, as the learning rate , and after rescaling time as , the discrete-time dynamics converges to the following continuous-time gradient flow:
其中为学习率. 在高维限中,作为学习速率,在将时间调整为后,离散时间动态会趋同到以下连续时间梯度流: 1.
with
与
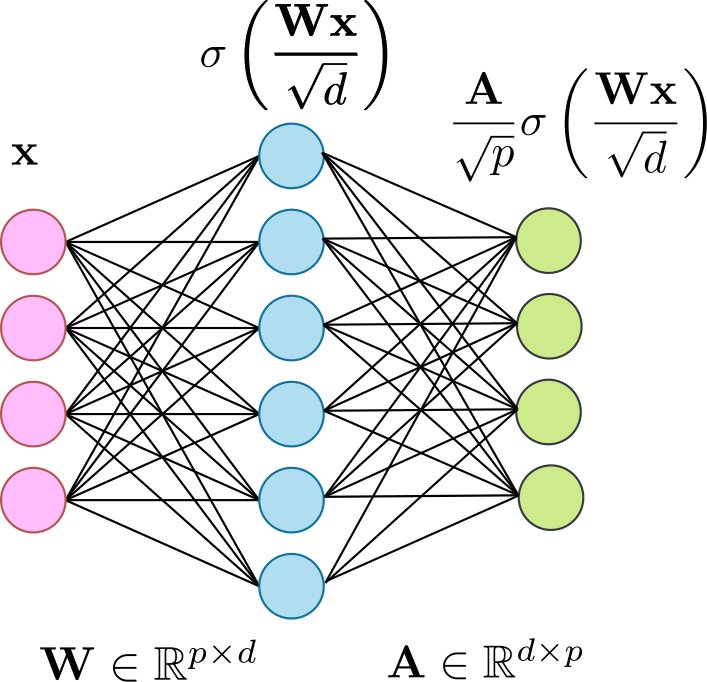
Figure 4: (Left) Illustration of an RFNN. (Middle/Right) Spectrum of . Density from Theorem 3.1 in the overparameterized Regime I described in Theorem 3.2, with , , , and . The bulk of the spectrum (orange) is between and . The histogram shows the eigenvalues from a single realization of at . Inset: zoom near (in blue) showing the first bulk and the delta peak at . (Right) Same as (Middle), but with . The first bulk in blue remains unchanged, as it depends only on in both cases, while the second bulk varies with .
图4:(左)** RFNN说明**(中/右) ** 第号决议。 ** 密度 来自定理3.2所述超参数化制度I中的定理3.1,其中,,,和. 大部分频谱(橙色)介于和之间. 直方图显示了在的单一实现中得出的eigen值. inset:在附近放大(蓝色)显示第一批和位于的三角洲峰. (*Right *) 与(中)相同,但与相同。 以蓝色为单位的第一批没有变化,因为这两种情况只取决于,而第二批则与不同。
Assumptions.
For our analytical results to hold, we make the following mathematical assumptions which are standard when studying Random Features [41, 17, 22] namely (i) the activation function admits a Hermite polynomial expansion ; and (ii) the data distribution has sub-Gaussian tails and a covariance with bounded spectrum. We assume that the empirical distribution of eigenvalues of converges weakly in the high dimensional limit to a deterministic density and that converges to a finite limit (for a more precise mathematical statement see SM Sect. C.3). Moreover, we make additional assumptions that are not essential to the proofs but which simplify the analysis: (iii) the activation function verifies ; and (iv) the second layer is initialized with zero weights . In numerical applications, unless specified, we use and .
- 假设。
为了维持分析结果,我们提出下列数学假设,这些假设在研究随机特征[41、17、22]时是标准的,即(一) 激活函数 承认一种赫米特聚体膨胀 ;和(二) 数据分布 具有亚古西尾部和具有定频谱的共变。 我们假设,的基值经验分布在高维度限度中弱化为确定密度,趋同为有限限度(更精确的数学说明见SM Sect. C.3). 此外,我们还作出一些对证明并非必不可少的、但可简化分析的其他假设:(三) 激活函数验证;和(四) 第二层初始化为零重量。 在数字应用中,除非具体说明,我们使用和。
A
A级
Emergence of the two timescales during training.
We first show in Fig. 5 that the behavior of training and test losses in the RF model mirrors the one found in realistic cases in Sect. 2, with a separation of timescales and which increases with . Equation (10) is linear in and hence it can be solved exactly (see SM). The timescales of the training dynamics are given by the inverse eigenvalues of the matrix . Building on the Gaussian Equivalence Principle [16, 17, 36] and the theory of linear pencils [7], [15] (2025) derive a coupled system of equations characterizing the Stieltjes transform of the eigenvalue density of for isotropic Gaussian data that lie in a -dimensional subspace with and . We offer an alternative derivation presented in SM for general variance using the replica method [37] – a heuristic method from the statistical physics of disordered systems – yielding the more compact formulation for obtaining the spectrum stated in Theorem 3.1. Before stating the theorem, we introduce
训练期间两个时标的出现.
我们首先在图5中显示,RF模型中的培训和测试损失行为与第2节中现实案例中发现的行为相仿,时间尺度为和,它们随着的增加而增加。 方程(10)在中是线性的,因此可以精确解决(见SM)。 训练动力学的时间尺度由矩阵的反正值给出. 基于高斯等值原理[16,17,36]和线性铅笔理论[7],15,衍生出一个结合的方程系统,其特征是的基值密度的Stieltjes变换,用于位于的异地高斯数据 - 带有和的维次空间. 我们用复制法[37],即无序系统统计物理学中的一种热度法,在SM中为一般差异提出一种备选推论,从而得出更紧凑的公式,以获得定理3.1所述频谱。 在陈述定理之前,我们先介绍一下
where , and the expectation is over the random variables which are independent standard Gaussian .
其中,和期望值大于随机变量,这些变量是独立的标准高斯.
Theorem 3.1.
Let , and , with . Let
** 定 义 3.1****。 **
- 让、和与。 让*
Then and satisfy the following set of three equations:
- 然后和满足以下一组三个方程:*
The eigenvalue distribution of , , can then be obtained using the Sokhotski–Plemelj inversion formula .
- ,的等值分布,然后可以使用Sokhotski-Plemelj反演公式获得.
We now focus on the asymptotic regime , typical for strongly over-parameterized models trained on large data sets. In this limit, the spectrum of can be described analytically by the following Theorem 3.2.
峦 我们现在着重注意 Glentimotic system ,这是在大型数据集方面训练的高度超参数化模型的典型。 在这个限制中,的频谱可以通过以下定理3.2来分析描述.
Theorem 3.2(Informal).
Let denote the spectral density of .
** 定理3.2**(非正式)**。 **
- 让表示的光谱密度。
Regime I (overparametrized): .
Regime II (underparametrized): .
- 制度一(超标):。
- II号制度(不足):。 *
where is an atomless measure with support
是一种有支持的无原子措施
and coincides with the asymptotic eigenvalue bulk density of the population covariance ; is independent of and its support is on the scale . The eigenvectors associated with leave both training and test losses unchanged and are therefore irrelevant. In the limit , the supports of and are respectively on the scales and , i.e. they are well separated.
*和与人口共变的不对称二原值块密度相吻合;独立于,其支持规模为. 与有关的编辑人员使培训和测试损失保持不变,因此无关紧要。 在限值中,和的支持分别位于尺度和上,即它们已经很好地分离. *.
The proofs of both theorems are shown in SM (Sect. C). We recall that training timescales are directly related to eigenvalues via the relation . Theorem 3.2 therefore demonstrates the emergence of the two training timescales and in the overparametrized regime of the RFNN model. They are respectively associated to the measures and , which are well separated in regime I, for , as shown in Fig. 4. Generalization: The timescale on which the first relaxation takes place is associated to the formation of the generalization regime. It is related to the bulk and is or order . This regime only depends on the population covariance of the data and is independent of the specific realization of the dataset. On this timescale, which is of order one, both the training and test losses decrease. The generalization loss is zero, and tends to a value that we find to scale as with numerically (see Fig. 5). Memorization: The timescale , on which the second stage of the dynamics takes place, is associated to overfitting and memorization. It is related to the bulk , and scales as , where is the left edge of . In the overparameterized regime , becomes large and of order , thus implying a scaling of with . On this timescale, the training loss decreases while the test loss increases, converging to their respective asymptotic values as computed in [15]. Fig. 5 indeed shows that all training and test curves separate, correspondingly the generalization loss increases, at a time that scales with , as shown in the inset. As increases, the asymptotic () generalization loss decreases, indicating a reduced overfitting. For , although some overfitting remains (i.e., ), the value of is sensibly reduced, and the model is no longer expressive enough to memorize the training data, as shown in [15]. This regime corresponds to the Architectural Regularization phase in Fig. 1. We show in Fig. 5 (panel C) how the generalization loss varies in the plane depending on the time at which training is stopped. In agreement with the above results, we find that the generalization–memorization transition line depends on and moves upward for larger values of , similarly to the numerical results exposed in Fig. 3 and the illustration in Fig. 1.
两个定理的证明在SM(C节)中显示. 我们回顾,通过的关系,培训时间尺度与egenvalus 直接相关。 因此,定理3.2表明,在RFNN模式的超参数制度中出现了和两个培训时间尺度。 如图4所示,它们分别与第号和第号措施有关,这些措施在第号制度I中已完全分开。 ** 第一次放松所依据的时间尺度与一般化制度的形成有关. 它与批量有关,是或订购. 这一制度仅依赖于数据中的人口共性,独立于数据集的具体实现. 在这一按顺序排列的时间尺度上,培训和测试损失都减少了。 一般化损失为零,倾向于用数字来标定一个我们发现的的数值(见图5)。 ** 记忆:** 动力学第二阶段发生的时间尺度与过度适应和记忆有关. 它与大宗有关,尺度为,其中是的左边缘. 在超参数化制度中,变大,排列顺序为,因此表示用缩放. 在这个时间尺度上,培训损失减少,同时测试损失增加,与在[15]中计算的各自不对称值趋同。 图5确实表明,所有训练和试验曲线都分开,相应的是的一般化损失增加,其时间与的尺度相同,如套件所示。 随着的增加,不对称性()一般化损失减少,表明过度适应性降低. 对于,虽然有些偏差仍然存在(即),但的值被敏锐地降低,模型不再足够表达来记住训练数据,如[15]所示. 这个制度与图中的Architectural regularation阶段相对应. 1. 我们在图5(C小组)中显示,通用损失在飞机中因停止培训的时间的不同而有所不同。 与上述结果一致,我们发现,一般化-模拟过渡线取决于,对于更大的值为,向上移动,类似于图3中披露的数字结果和图1中的插图。
4 Conclusions
4 结论
We have shown that the training dynamics of neural network-based score functions display a form of implicit regularization that prevents memorization even in highly overparameterized diffusion models. Specifically, we have identified two well-separated timescales in the learning: , at which models begins to generate high-quality, novel samples, and , beyond which they start to memorize the training data. The gap between these timescales grows with the size of the training set, leading to a broad window where early stopped models generate novel samples of high-quality. We have demonstrated that this phenomenon happens in realistic settings, for controlled synthetic data, and in analytically tractable models. Although our analysis focuses on DMs, the underlying score-learning mechanism we uncover is common to all score-based generative models such as stochastic interpolants [3] or flow matching [32]; we therefore expect our results to generalize to this broader class.
我们已经表明,基于神经网络的得分函数在训练动力学中表现出一种隐式正则,即使在高度过参数化的扩散模型中也能阻止记忆。具体而言,学习过程中存在两个清晰分离的时间尺度:,模型开始生成高质量、新颖的样本;,此后开始记忆训练数据。二者间距随训练集增大而变宽,从而留下一大段早停即可得到高质量新颖样本的窗口。我们在现实设定、可控合成数据与可解析模型中都验证了这一现象。尽管分析聚焦于扩散模型,所揭示的得分学习机制也适用于其他基于得分的生成模型。
Limitations and future works.
- • While we derived our results under SGD optimization, most DMs are trained in practice with Adam [28]. In SM Sects. A and D, we show that the two key timescales still arise using Adam, although with much fewer optimization steps. Studying how different optimizers shift these timescales would be valuable for practical usage.
- • All experiments in Sect. 2 are conducted with unconditional DMs. We additionally verify in SM Sect. B, using a toy Gaussian mixture dataset and classifier-free guidance [21], that the same scaling of with holds in the conditional settings. Understanding precisely how the absolute timescales and depend on the conditioning remains an open question.
- • Our numerical experiments cover a range of between 1M and 16M. Exploring a wider range is essential to map the full phase diagram sketched in Fig. 1 and understand the precise effect of expressivity on dynamical regularization.
- • Finally, our theoretical analysis rely on well-controlled data and score models that reproduce the core effects. Extending these analytical frameworks to richer data distributions (such as Gaussian mixtures or data from the hidden manifold model) and to structured architectures would be valuable to further characterize the implicit dynamical regularization of training score-functions. In particular investigating how heavy-tailed data distribution [2] affect the picture described here could be valuable.
- • Although DMs trained on large and diverse datasets likely avoid the memorization regime we study here, some industrial models were shown to exhibit partial memorization [9, 50]. Our results provide practical guidelines (early-stopping, control the network capacity) to train DMs robustly and hence avoid memorization, which can be especially helpful in data-scarce domains (e.g., physical sciences).
- 限制和未来的工作。
- 虽然我们在战略发展司优化下得出了成果,但大多数模式草案都与亚当[28]进行了实践培训。 在SM部门。 A和D,我们显示这两个关键的时间尺度仍然用亚当出现,虽然优化步骤要少得多. 研究不同的优化者如何改变这些时间尺度对于实际使用是有价值的。
- 第2款的所有试验都是无条件的。 在SM Sect. B中,我们使用一个玩具高斯混合数据集和无分解器制导[21],进一步核实与相同的的缩放在有条件的环境下。 准确理解和的绝对时标如何取决于条件,仍然是一个未决问题。
- 我们的数值实验涵盖1M至16M之间的范围。 探索范围更广,对于图1中描绘的阶段图全图的绘制和理解表达对动态正规化的确切影响至关重要。
- 最后,我们的理论分析依赖于控制良好的数据和复制核心效应的得分模型。 将这些分析框架扩展至更丰富的数据分布(如高斯混合物或隐藏多面模型中的数据)和结构化结构,对于进一步说明培训分数功能的内在动态正规化具有价值。 特别是调查重尾数据分布如何影响本文描述的画面可能是有价值的.
- 虽然就大型和多样化数据集培训的模式草案可能避免我们在此研究的记忆制度,但一些工业模型显示出部分记忆[9、50]。 我们的成果提供了实用的准则(早期制止、控制网络能力),以大力培训模式模式,从而避免记忆化,这在数据稀缺领域(如物理科学)特别有用。
Acknowledgments and Disclosure of Funding
致谢与资助披露
The authors thank Valentin De Bortoli for initial motivating discussions on memorization–generalization transitions. RU thanks Beatrice Achilli, Jérome Garnier-Brun, Carlo Lucibello and Enrico Ventura for insightful discussions. RU is grateful to Bocconi University for its hospitality during his stay, during which part of this work was conducted. This work was performed using HPC resources from GENCI-IDRIS (Grant 2025-AD011016319). GB acknowledges support from the French government under the management of the Agence Nationale PR[AI]RIE-PSAI (ANR-23-IACL-0008). MM acknowledges the support of the PNRR-PE-AI FAIR project funded by the NextGeneration EU program. After completing this work, we became aware that A. Favero, A. Sclocchi, and M. Wyart [14] had also been investigating the memorization–generalization transition from a similar perspective.
作者们感谢瓦伦丁·德·博尔托利(Valentin De Bortoli), RU感谢Beatrice Achilli、Jérome Garnier-Brun、Carlo Lucibello和Enrico Ventura进行了有见地的讨论。 路运联盟感谢博科尼大学在他逗留期间给予的盛情款待,在此期间开展了部分工作。 这项工作是利用GENCI-IDRIS(Grant 2025-AD011016319)的HPC资源进行的。 GB感谢法国政府在国家情报机构管理下的支援[AI]RIE-PSAI(ANR-23-IACL-0008). MM感谢由下一代欧盟方案资助的PNRR-PE-AI FAIR项目的支持. 在完成这项工作后,我们意识到A. Favero、A. Sclocchi和M. Wyart [14] 也从类似的角度调查了纪念-普遍化过渡。
References
参考文献
Why Diffusion Models Don’t Memorize: The Role of Implicit Dynamical Regularization in Training
为什么传播模式不记住:隐性动态规范化在培训中的作用
Supplementary Material (SM)
** 补充材料(SM)**
Tony Bonnaire†, Raphaël Urfin†, Giulio Biroli, Marc Mézard
托尼·博奈尔、拉法埃尔·乌尔芬、朱利奥·比罗利、马克·梅扎德
This document provides detailed derivations and additional experiments supporting the main text (MT). In Sect. A, we give details about the numerical experiments carried out in Sect. 2. In Sect. B we provide additional numerical experiments on simplified score and data models. Sect. C gives formal proofs of the main theorems of Sect. 3. Finally, Sect. D exposes more details on the numerical experiments of Sect. 3.
本文件提供了详细的推论和补充实验,支持主要案文(MT)。 内科. A,我们详细介绍了在部门进行的数值实验。 2. 第2款。 B 我们对简化分数和数据模型提供额外的数字实验。 节 C给出了正式的证明,证明教派的主要定理. 3. 最后,D节披露了第3节数字实验的更多细节。
[1] Achilli, B., Ventura, E., Silvestri, G., Pham, B., Raya, G., Krotov, D., Lucibello, C., and Ambrogioni, L. (2024). Losing dimensions: Geometric memorization in generative diffusion.
[2] Adomaityte, U., Defilippis, L., Loureiro, B., and Sicuro, G. (2024). High-dimensional robust regression under heavy-tailed data: asymptotics and universality. Journal of Statistical Mechanics: Theory and Experiment , 2024(11):114002.
[3] Albergo, M. S., Boffi, N. M., and Vanden-Eijnden, E. (2023). Stochastic interpolants: A unifying framework for flows and diffusions.
[4] Bach, F. (2023). Polynomial magic iii: Hermite polynomials. https://francisbach.com/hermite-polynomials/ . Accessed: 2025-10-09.
[5] Bai, Z. and Zhou, W. (2008). Large sample covariance matrices without independence structures in columns. Statistica Sinica , 18(2):425–442.
[6] Biroli, G., Bonnaire, T., de Bortoli, V., and Mézard, M. (2024). Dynamical regimes of diffusion models. Nature Communications , 15(9957). Open access.
[7] Bodin, A. P. M. (2024). Random Matrix Methods for High-Dimensional Machine Learning Models . Phd thesis, École Polytechnique Fédérale de Lausanne (EPFL), Lausanne, Switzerland.
[8] Bortoli, V. D. (2022). Convergence of denoising diffusion models under the manifold hypothesis. Transactions on Machine Learning Research . Expert Certification.
[9] Carlini, N., Hayes, J., Nasr, M., Jagielski, M., Sehwag, V., Tramèr, F., Balle, B., Ippolito, D., and Wallace, E. (2023). Extracting training data from diffusion models. In Proceedings of the 32nd USENIX Conference on Security Symposium , SEC ’23, USA. USENIX Association.
[10] Chen, C., Liu, D., and Xu, C. (2024). Towards memorization-free diffusion models.
[11] Cui, H., Krzakala, F., Vanden-Eijnden, E., and Zdeborova, L. (2024). Analysis of learning a flow-based generative model from limited sample complexity. In The Twelfth International Conference on Learning Representations .
[12] Cui, H., Pehlevan, C., and Lu, Y. M. (2025). A precise asymptotic analysis of learning diffusion models: theory and insights.
[13] D’Ascoli, S., Refinetti, M., Biroli, G., and Krzakala, F. (2020). Double trouble in double descent: Bias and variance(s) in the lazy regime. In III, H. D. and Singh, A., editors, Proceedings of the 37th International Conference on Machine Learning , volume 119 of Proceedings of Machine Learning Research , pages 2280–2290. PMLR.
[14] Favero, A., Sclocchi, A., and Wyart, M. (2025). Bigger isn’t always memorizing: Early stopping overparameterized diffusion models.
[15] George, A. J., Veiga, R., and Macris, N. (2025). Denoising score matching with random features: Insights on diffusion models from precise learning curves.
[16] Gerace, F., Loureiro, B., Krzakala, F., Mezard, M., and Zdeborova, L. (2020). Generalisation error in learning with random features and the hidden manifold model. In III, H. D. and Singh, A., editors, Proceedings of the 37th International Conference on Machine Learning , volume 119 of Proceedings of Machine Learning Research , pages 3452–3462. PMLR.
[17] Goldt, S., Loureiro, B., Reeves, G., Krzakala, F., Mézard, M., and Zdeborová, L. (2021). The gaussian equivalence of generative models for learning with shallow neural networks.
[18] Gu, X., Du, C., Pang, T., Li, C., Lin, M., and Wang, Y. (2023). On memorization in diffusion models.
[19] Heusel, M., Ramsauer, H., Unterthiner, T., Nessler, B., and Hochreiter, S. (2017). Gans trained by a two time-scale update rule converge to a local nash equilibrium.
[20] Ho, J., Jain, A., and Abbeel, P. (2020). Denoising diffusion probabilistic models.
[21] Ho, J. and Salimans, T. (2022). Classifier-free diffusion guidance.
[22] Hu, H. and Lu, Y. M. (2023). Universality laws for high-dimensional learning with random features. IEEE Transactions on Information Theory , 69(3):1932–1964.
[23] Hyvärinen, A. (2005). Estimation of non-normalized statistical models by score matching. Journal of Machine Learning Research , 6(24):695–709.
[24] Kadkhodaie, Z., Guth, F., Simoncelli, E. P., and Mallat, S. (2024). Generalization in diffusion models arises from geometry-adaptive harmonic representations. In The Twelfth International Conference on Learning Representations .
[25] Kamb, M. and Ganguli, S. (2024). An analytic theory of creativity in convolutional diffusion models.
[26] Karras, T., Aittala, M., Aila, T., and Laine, S. (2022). Elucidating the design space of diffusion-based generative models.
[27] Kibble, W. F. (1945). An extension of a theorem of mehler’s on hermite polynomials. Mathematical Proceedings of the Cambridge Philosophical Society , 41(1):12–15.
[28] Kingma, D. P. and Ba, J. (2015). Adam: A method for stochastic optimization. In Bengio, Y. and LeCun, Y., editors, ICLR (Poster) .
[29] Li, P., Li, Z., Zhang, H., and Bian, J. (2025). On the generalization properties of diffusion models.
[30] Li, S., Chen, S., and Li, Q. (2024a). A good score does not lead to a good generative model.
[31] Li, T., Biferale, L., Bonaccorso, F., and et al. (2024b). Synthetic lagrangian turbulence by generative diffusion models. Nat Mach Intell , 6:393–403.
[32] Lipman, Y., Chen, R. T. Q., Ben-Hamu, H., Nickel, M., and Le, M. (2023). Flow matching for generative modeling. In The Eleventh International Conference on Learning Representations .
[33] Liu, Y., Zhang, K., Li, Y., Yan, Z., Gao, C., Chen, R., Yuan, Z., Huang, Y., Sun, H., Gao, J., He, L., and Sun, L. (2024). Sora: A review on background, technology, limitations, and opportunities of large vision models.
[34] Liu, Z., Luo, P., Wang, X., and Tang, X. (2015). Deep learning face attributes in the wild. In Proceedings of International Conference on Computer Vision (ICCV) .
[35] Mei, S., Misiakiewicz, T., and Montanari, A. (2019). Mean-field theory of two-layers neural networks: dimension-free bounds and kernel limit. In Beygelzimer, A. and Hsu, D., editors, Proceedings of the Thirty-Second Conference on Learning Theory , volume 99 of Proceedings of Machine Learning Research , pages 2388–2464. PMLR.
[36] Mei, S. and Montanari, A. (2020). The generalization error of random features regression: Precise asymptotics and double descent curve.
[37] Mézard, M., Parisi, G., and Virasoro, M. A. (1987). Spin Glass Theory and Beyond: An Introduction to the Replica Method and Its Applications , volume 9 of Lecture Notes in Physics . World Scientific Publishing Company, Singapore.
[38] Paszke, A., Gross, S., Massa, F., Lerer, A., Bradbury, J., Chanan, G., Killeen, T., Lin, Z., Gimelshein, N., Antiga, L., Desmaison, A., Kopf, A., Yang, E., DeVito, Z., Raison, M., Tejani, A., Chilamkurthy, S., Steiner, B., Fang, L., Bai, J., and Chintala, S. (2019). Pytorch: An imperative style, high-performance deep learning library. In Advances in Neural Information Processing Systems , volume 32, pages 8024–8035. Curran Associates, Inc.
[39] Potters, M. and Bouchaud, J.-P. (2020). A First Course in Random Matrix Theory: for Physicists, Engineers and Data Scientists . Cambridge University Press.
[40] Price, I., Sanchez-Gonzalez, A., Alet, F., and et al. (2025). Probabilistic weather forecasting with machine learning. Nature , 637:84–90.
[41] Péché, S. (2019). A note on the pennington-worah distribution. Electronic Communications in Probability , 24:1–7.
[42] Rahaman, N., Baratin, A., Arpit, D., Draxler, F., Lin, M., Hamprecht, F., Bengio, Y., and Courville, A. (2019). On the spectral bias of neural networks. In International conference on machine learning , pages 5301–5310. PMLR.
[43] Rahimi, A. and Recht, B. (2007). Random features for large-scale kernel machines. In Platt, J., Koller, D., Singer, Y., and Roweis, S., editors, Advances in Neural Information Processing Systems , volume 20. Curran Associates, Inc.
[44] Robbins, H. and Monro, S. (1951). A stochastic approximation method. The annals of mathematical statistics , pages 400–407.
[45] Rombach, R., Blattmann, A., Lorenz, D., Esser, P., and Ommer, B. (2021). High-resolution image synthesis with latent diffusion models.
[46] Ronneberger, O., Fischer, P., and Brox, T. (2015). U-net: Convolutional networks for biomedical image segmentation. In Navab, N., Hornegger, J., Wells, W. M., and Frangi, A. F., editors, Medical Image Computing and Computer-Assisted Intervention – MICCAI 2015 , pages 234–241, Cham. Springer International Publishing.
[47] Shah, K., Kalavasis, A., Klivans, A. R., and Daras, G. (2025). Does generation require memorization? creative diffusion models using ambient diffusion.
[48] Silverstein, J. and Bai, Z. (1995). On the empirical distribution of eigenvalues of a class of large dimensional random matrices. Journal of Multivariate Analysis , 54(2):175–192.
[49] Sohl-Dickstein, J., Weiss, E., Maheswaranathan, N., and Ganguli, S. (2015). Deep unsupervised learning using nonequilibrium thermodynamics. In Bach, F. and Blei, D., editors, Proceedings of the 32nd International Conference on Machine Learning , volume 37 of Proceedings of Machine Learning Research , pages 2256–2265, Lille, France. PMLR.
[50] Somepalli, G., Singla, V., Goldblum, M., Geiping, J., and Goldstein, T. (2023a). Diffusion art or digital forgery? investigating data replication in diffusion models. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition .
[51] Somepalli, G., Singla, V., Goldblum, M., Geiping, J., and Goldstein, T. (2023b). Understanding and mitigating copying in diffusion models. Advances in Neural Information Processing Systems , 36:47783–47803.
[52] Song, J., Meng, C., and Ermon, S. (2022). Denoising diffusion implicit models.
[53] Song, Y., Durkan, C., Murray, I., and Ermon, S. (2021a). Maximum likelihood training of score-based diffusion models.
[54] Song, Y. and Ermon, S. (2019). Generative modeling by estimating gradients of the data distribution. In Wallach, H., Larochelle, H., Beygelzimer, A., d'Alché-Buc, F., Fox, E., and Garnett, R., editors, Advances in Neural Information Processing Systems , volume 32. Curran Associates, Inc.
[55] Song, Y., Sohl-Dickstein, J., Kingma, D. P., Kumar, A., Ermon, S., and Poole, B. (2021b). Score-based generative modeling through stochastic differential equations.
[56] Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L. u., and Polosukhin, I. (2017). Attention is all you need. In Guyon, I., Luxburg, U. V., Bengio, S., Wallach, H., Fergus, R., Vishwanathan, S., and Garnett, R., editors, Advances in Neural Information Processing Systems , volume 30. Curran Associates, Inc.
[57] Ventura, E., Achilli, B., Silvestri, G., Lucibello, C., and Ambrogioni, L. (2025). Manifolds, random matrices and spectral gaps: The geometric phases of generative diffusion.
[58] Vincent, P. (2011). A connection between score matching and denoising autoencoders. Neural Computation , 23(7):1661–1674.
[59] Wang, B. (2025). An analytical theory of power law spectral bias in the learning dynamics of diffusion models.
[60] Wang, P., Zhang, H., Zhang, Z., Chen, S., Ma, Y., and Qu, Q. (2024). Diffusion models learn low-dimensional distributions via subspace clustering.
[61] Wen, Y., Liu, Y., Chen, C., and Lyu, L. (2024). Detecting, explaining, and mitigating memorization in diffusion models.
[62] Wu, Y.-H., Marion, P., Biau, G., and Boyer, C. (2025). Taking a big step: Large learning rates in denoising score matching prevent memorization.
[63] Yoon, T., Choi, J. Y., Kwon, S., and Ryu, E. K. (2023). Diffusion probabilistic models generalize when they fail to memorize. In ICML 2023 Workshop on Structured Probabilistic Inference & Generative Modeling .
[64] Zhang, C., Zhang, C., Zheng, S., Zhang, M., Qamar, M., Bae, S.-H., and Kweon, I. S. (2023). A survey on audio diffusion models: Text to speech synthesis and enhancement in generative ai.
[65] Zhi-Qin John Xu, Z.-Q. J. X., Yaoyu Zhang, Y. Z., Tao Luo, T. L., Yanyang Xiao, Y. X., and Zheng Ma, Z. M. (2020). Frequency principle: Fourier analysis sheds light on deep neural networks. Communications in Computational Physics , 28(5):1746–1767.
Appendix A Numerical experiments on CelebA
附录 A CelebA 上的数值实验
A.1 Details on the numerical setup
A.1 数值设置细节
Dataset.
All numerical experiments in Sect. 2 of the MT use the CelebA face dataset [34]. We center-crop each RGB image to pixels and convert to grayscale images in order to accelerate the training of our Diffusion Models (DMs). To precisely control the samples seen by a model, no data augmentation is applied, and we vary the training set size in the window . Examples of training samples are shown in the left-most block of Fig. 6.
QQ 数据集.
MT第2节中的所有数值实验都使用CelebA面值数据集[34]. 我们把每个 RGB 的图像中rop 到像素, 并转换成灰度的图像, 以加速对 CDM 的训练。 为了精确控制模型所看到的样本,没有应用数据增强,我们改变了窗口中的训练集大小. 培训样本的例子见图6最左边的区块。
Architecture.
As commonly done in DDPMs implementations [20, 55], the network approximating the score function is a U-Net [46] made of three resolution levels, each containing two residual blocks with channel multipliers respectively. We apply attention to the two coarsest resolutions, and embed the diffusion time via sinusoidal position embedding [56]. The base channel width varies from to depending on the experiment, resulting in a total of to million trainable parameters.
建筑学.
与DDPMs执行中常见的[20,55]一样,近似分数函数的网络是一个由三个分辨率级组成的U-Net [46],每个分辨率级中分别包含两个带通道乘数的剩余块. 我们注意两个最窄的分辨率,通过嵌入的sinusoidal位置嵌入扩散时间[56]。 基础通道宽度因实验不同而从到不等,共形成到百万列车参数.
Time reparameterization.
Compared to the framework presented in the MT, the DDPMs we train make use of a time reparameterization of the forward and backward processes with a variance schedule , where is the time horizon given as a number of steps, fixed to 1000 in our experiments. The variance is evolving linearly from to . A sample at time , denoted , can be expressed from as the following interpolation
- 时间调整。
与 MT 中呈现的框架相比,我们列车使用一个时间调整法,对前向和后向过程进行时间调整,并采用差异表,其中是作为若干步骤给出的时间范围,在我们的实验中固定到1000个. 差异从到呈线性演变. 在时的样本表示,可以从表示如下插值.
where , and is a standard and centered Gaussian noise. This is a reparameterization of the Ornstein-Uhlenbeck process from Eq. 1 defined through time in the MT, with
其中,和是一种标准且中心化的高斯噪音. 这是通过时间在MT中定义的Ornstein-Uhlenbeck过程从Eq. 1中重新参数化的,使用
Training.
All DMs are trained with Stochastic Gradient Descent (SGD) at fixed learning rate , fixed momentum and batch size . We focus on SGD to facilitate the analysis of time scaling, avoiding problems that may cause alternative adaptive optimization schemes like Adam [28]. We train each model for at least 2M SGD steps, sometimes more for large values of displaying memorization only later. We do not employ exponential moving average or learning-rate warm-up.
培训。
所有模式模式都按照固定学习率、固定动力和批量大小接受Stochastic Gradient Egency(SGD)培训。 我们侧重于SGD,以便于分析时间缩放,避免像Adam[28]这样的可能导致替代性适应优化计划的问题. 我们至少为2M SGD步骤培训每个模型,有时更多的是用于在以后展示记忆的的大型值. 我们没有使用指数移动平均或学习率的热身。
Generation.
To accelerate sampling while preserving FID, we employ the DDIM sampler of [52] (2022) which replaces the Markovian reverse SDE with a deterministic, non-Markovian update. Given a trained denoiser , we iterate for
-轩然大波
求助于DDIM采样器52, 鉴于一个训练有素的 ,我们为
with . During training, we generate at 40 milestones a set of 10,000 samples to assess generalization and memorization. Examples of samples obtained from a model trained on samples with base width are shown in the middle and right blocks from Fig. 6 for two training times, K and M. At K the model generalizes () and achieve a test FID of 35.1. After too much training, memorization sets in and, by M steps, nearly half the generated samples reproduce training images ().
与合并。 在培训期间,我们以40个里程碑生成一套10 000个样本,以评估一般化和记忆化。 从样本培训的模型中提取的样本样本实例显示在图6的中间和右块中,两个培训时间为 K和 M。 在 K,模型一般化(),并实现35.1的测试FID。 经过过多的培训后,记忆设定在 M步骤中,产生的样本几乎有一半复制了培训图像()。
Statistical evaluation.
FIDs [19] are computed[^† †\dagger] using 10,000 generated samples and 10,000 test samples, averaged over 5 independent runs with disjoint test sets. Error bars in the MT denote twice the standard deviation. Training and test losses are estimated similarly over 5 repeated evaluation on training samples and 2048 test samples, and give negligible confidence intervals. For the memorization fraction , we report the standard error on the mean obtained via bootstrap resampling of the 10,000 generated samples. We also verified that the scaling in the memorization time is insensitive to the choice of the threshold used to define in Eq. 6 by testing larger and lower values.
FID[19]是使用10 000个生成的样品和10 000个测试样品计算出来的,平均有5个以上的独立运行,测试组不相连。 MT中的错误栏表示标准偏差的两倍. 对培训样本和2048测试样本的5次重复评价同样估计了培训和测试损失,其置信间隔可忽略不计。 对于的记忆分数,我们报告通过重新取样10 000个生成样本的靴子圈获得的平均值的标准错误。 我们还证实,在本着纪念时间的缩放,对选择在Eq. 6中定义所使用的阈值不敏感,通过测试更大和较低的值.
Computing resources.
Most trainings were performed on Nvidia H100 GPUs (80GB of memory). A typical run of 2M steps takes approximately 50 hours on two GPUs and vary with the model size (defined through its base width ). In total, we train 18 distinct models for the several configurations of the MT. The longest training ( and in Fig. 2) ran for 11M steps. The generation of samples over 40 training times takes around an additional hour per model on the same hardware support.
- 计算资源。
大多数训练都是在Nvidia H100 GPU(80GB of memory)上进行的. 2M步骤的典型运行在两个GPU上需要约50小时,并随模型大小(通过它的基宽来定义)而变化. 我们总共为MT的几个配置培训了18种不同的型号. 最长的训练(图2中的和)跑了11M步. 生成样本超过40个训练时间,需要在同一硬件支持上每个模型额外一个小时左右.
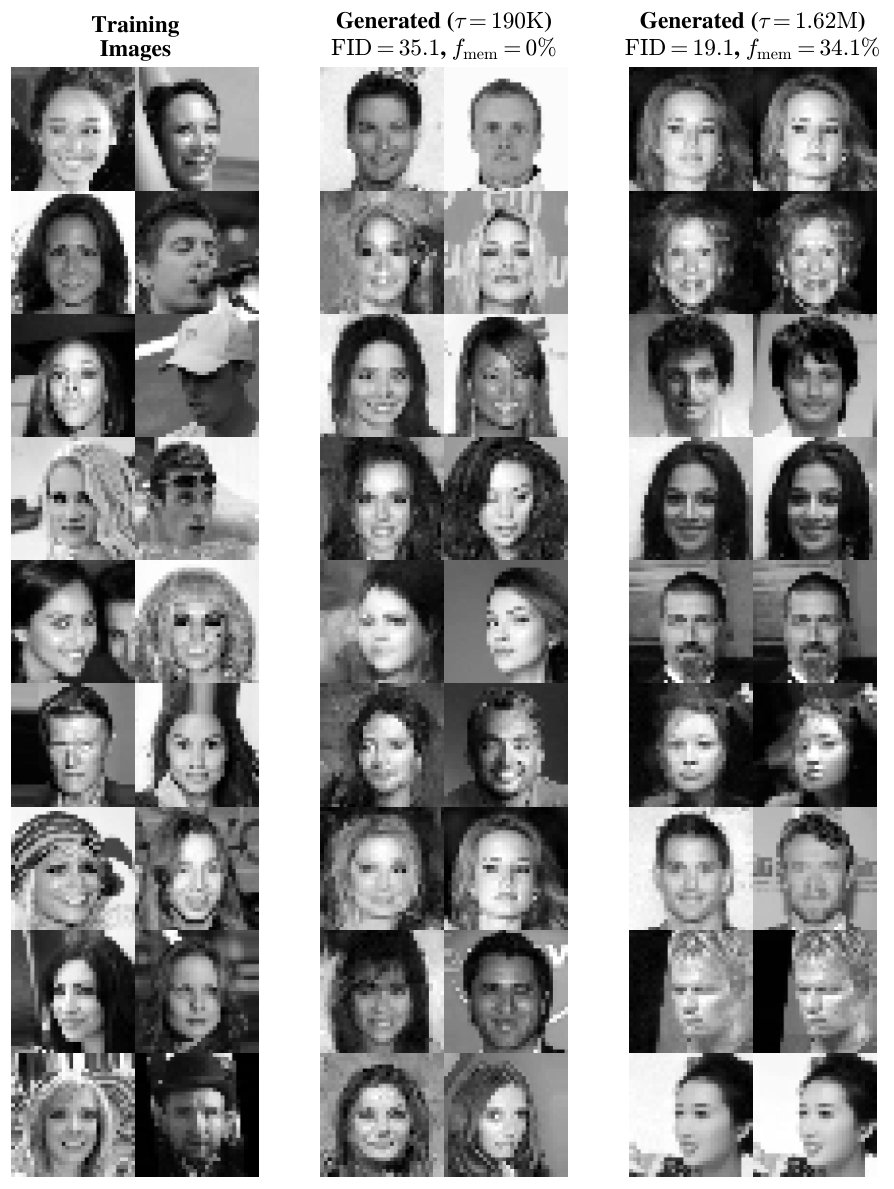
Figure 6: Training and generation on CelebA. The left-most block shows random training images. Middle and right blocks show generated samples in the left column (after K and M SGD updates respectively), alongside each sample’s nearest neighbor in the training set in the right column. All generated images come from model trained on with base width .
图6:** CelebA上的培训和一代。 最左边的块显示随机训练图像. 中块和右块在左栏(分别是 K和 M SGD更新之后)显示生成的样本,与每个样本在右栏的训练集中最接近的邻居并列. 所有生成的图像都来自在上训练的模型,基宽为**.
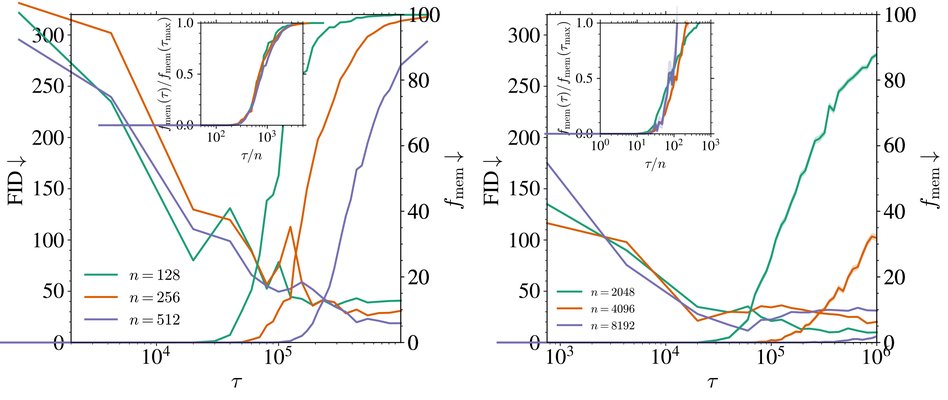
Figure 7: Impact of batch size and optimizer on the scaling of . FID (solid lines, left axis) and memorization fraction (in %, dashed lines, right axis) against training time for various . Inset: normalized memorization fraction with the rescaled time . (Left) Memorization scaling for . (Right) Generalization–Memorization transition with Adam optimizer for .
图7: 批量大小和优化器对缩放. FID(固态线,左轴)和记忆分数(以%,破折线,右轴计)对各种训练时间的影响. 套期: 普通的记分与调整的时间 . *(Left) * 的记忆缩放 。 *(右) * 通用 - 与 Adam 优化器的记忆过渡 。 **
A.2 Batch-size effect: repetition vs. memorization
A.2 batch 大小效应:重复与记忆
All the experiments in the MT use a fixed batch size , and in Sect 2 we emphasize that the observed scaling of cannot be explained by repetition over training samples. To validate this statement, the left panel of Fig. 7 shows FID and memorization fraction curves when we train the models with full-batch updates () for . At any fixed , every sample has been seen exactly times. Yet continues to grow linearly with , as shown in the inset. This demonstrates that larger datasets reshape the loss landscape – requiring proportionally more updates to overfit – rather than simply increasing memorization through repeated exposure of training samples.
在MT中的所有实验都使用一个固定批量大小的,在第2节中,我们强调,所观察到的的缩放不能用重复训练样本来解释。 为了验证这一语句,Fig. 7的左面面板显示FID和记忆分数曲线,当我们为()训练带有完整批次更新的模型时. 在任何固定的中,每个样本都曾被看到过准确的. 然而,与继续线性增长,如插图所示。 这表明,更大的数据集重塑了损失的地貌 — — 需要按比例进行更多的更新以适应过度 — — 而不是仅仅通过反复接触培训样本来增加记忆。
A.3 What about Adam?
A.3 Adam 呢?
We conclude this section by repeating our analysis at fixed using the Adam optimizer [28] instead of SGD with momentum. The learning rate is , gradient averages take values , and batch size . We keep all other settings and evaluation metrics as above. As shown in the right panel of Fig. 7, Adam yields the same two-phase training dynamics with first a generalization regime with and good performances (small FID), and later a memorization phase at , as shown in the inset. The only difference is that both and occur after much fewer steps compared to SGD. This also points out that the emergence of the two well-separated timescales and their scaling is a fundamental property of the loss landscape.
在结束本节时,我们重复我们在固定的的分析,使用Adam优化器[28],而不是具有动力的SGD。 学习率为,梯度平均值为,批量大小为. 我们保留所有其他设置和评价指标如上。 如图7右面板所示,亚当产生相同的两阶段训练动力学,先是具有的通化制度和良好的性能(小FID),后是位于的纪念阶段,如插图所示. 唯一的区别是,与SGD相比,和都是经过少得多的步骤才出现的. 这也指出,两个分离良好的时标的出现及其缩放是损失地貌的基本财产.
Appendix B Generalization–memorization transition in the Gaussian Mixture Model
附录 B 高斯混合模型中的泛化–记忆转变
The aim of this section is to show our results hold for other data distributions than natural images, and alternative score model that U-Net architectures.
本节旨在显示我们对于自然图像之外的其他数据分布的结果,以及U-Net架构的替代分数模型。
B.1 Settings
B.1 设定
Data distribution.
We focus on data iid sampled from a -dimensional Gaussian Mixture Model (GMM) made of two balanced Gaussians centered on with unit covariance, i.e.,
数据分布。
我们侧重于从一个以-维度高斯混合模型(GMM)为样本的数据二维数据,该模型由两个平衡的高斯人组成,以为中心,单位共变,即,,
In what follows, we choose to work with , with . In this controlled setup, the generalization score can be computed analytically from and reads
在下文中,我们选择与合作,与合作。 在这种可控设置中,一般化分数可以从分析计算,并读作:
Score model.
The denoise is implemented as a lightweight residual multi-layer neural network (see Fig. 8): an input layer projecting , followed by three identical residual blocks and an output layer projecting back to . Each block consists of two fully connected layers of width , a skip connection, and a layer normalization. We encode the diffusion time via sinusoidal position embedding and add it to the first feature of each block. The total number of parameter in the network is . For , and , the reference setting of this section, this yields trainable parameters.
QQ得分模式.
denoise 作为轻量级残基多层神经网络(参见图8):一个输入层投影,然后是三个相同的残基块和一个输出层投影返回. 每个区块由两层全连接的宽度,跳过连接,层层正常化组成. 我们通过sinusoidal位置嵌入来编码传播时间,并将其添加到每个区块的第一个特性中. 网络中的参数总数为. 对于和,本节的参考设置,此值得出可训练参数.
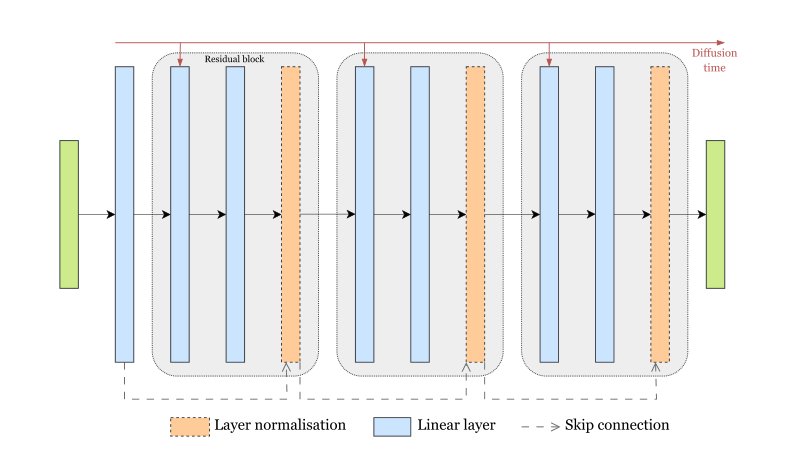
Figure 8: Basic ResNet architecture of the GMM numerical experiments. Residual network with three residual blocks, each made of two fully-connected layers followed by a layer normalization. The width of the network is , and the input and output sizes are .
图8:**GMM数字实验的基本ResNet架构. 残存的网络有3个残块,每个残块由两个完全连接的地层组成,然后是地层正常化. 网络宽度为,输入和输出大小为. **
Training and computing resources.
Unless otherwise specified, we train every model of this section with SGD at fixed learning rate and momentum using full-batch updates for , running for up to 4M updates. All experiments are executed on an Nvidia RTX 2080 Ti, with the largest requiring around 10 hours to complete.
- 培训和计算资源。
除非另有说明,否则我们用固定学习速率的和动力的来训练本节的每一个型号,使用的全批更新,运行时间可达4M更新. 所有实验均在Nvidia RTX 2080 Ti上进行,最大的需要约10小时完成.
Generalization and memorization metrics.
In addition to the memorization fraction , we exploit this controlled setting where we know the true data distribution to directly measure how closely it matches the generated distribution via the Kullback-Leibler (KL) divergence
- 一般化和记忆度量衡。
除了计算分数外, 我们利用这个控制设置, 在知道真实数据分布的地方, 通过 Kullback - Leibler (KL) 差异, 直接测量它与生成的分布相匹配的程度 。
The cross-entropy term is easy to estimate using Monte Carlo,
跨内涵术语 很容易使用蒙特卡洛来估计,
where are samples drawn from the model with parameters at training time . Estimating the negative entropy term is more challenging, since DMs only give access to the score function and not the underlying probability distribution . We can however employ time integration to express it as a function of the score only,
其中是从模型中抽取的样本,在培训时间为. 对蓓目负值术语进行估计更具挑战性,因为DMs只允许访问分数函数,而不是基础概率分布. 然而,我们可以利用时间整合来表达它只是比分的函数,
with
与
This expression assumes that the model learns an accurate representation of the score function. It is noteworthy to mention that samples are generated using standard Euler-Maruyama discretization of the backward process 2 of the MT over timesteps.
这种表达方式假设模型学习到准确的分数函数. 值得一提的是,样品是在时间步骤中利用MT的落后过程2的标准Euler-Maruyama光碟化生成的。
B.2 Scaling of and with and
B.2 与 对 和 的标度
In Fig. 9, the left panel shows how the KL divergence and memorization fraction evolve with training time for different training set sizes at fixed width , while the right panel fixes and varies . In both cases, we observe two distinct phases. First, the KL divergence decreases to near zero on a timescale independent of during which the model fully generalizes (). Beyond , both and begin to rise at a time that scales linearly with , as highlighted by the inset of the left panel. In contrast, scales with , as shown in the inset of the right panel. While the precise dependence of with remains inconclusive in this setting and require a more careful analysis, these results on the GMM mirror the main findings of the MT: the training dynamics of DMs unfolds first in a generalization phase and only later – at – memorization begins.
在图9中,左面面板显示KL差异和记忆分数如何随着训练时间的不同训练设置大小的在固定宽度的上演化,而右面面板则修正,并改变. 在这两种情况下,我们观察到两个不同的阶段。 首先,在独立于的时间尺度上,KL差异降至接近于零,在这段时间里,模型完全通用(.). 在以外,和在开始上升,与呈线性比例,左面面板的插图突出显示了这一点. 与此相对照,的尺度为,如右面板的插图所示. 虽然第与第的精确依赖性在此背景下仍无定论,需要更仔细的分析,但GMMM上的这些结果反映了MT的主要结论:DMs的培训动态首先在概括阶段展开,直到后来 — — 在第 — 记忆开始.
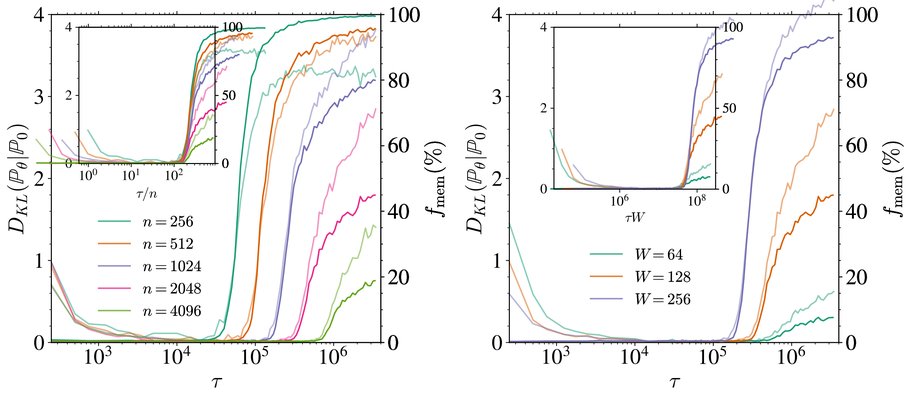
Figure 9: Generalization–Memorization transition as a function of the training set size and width for ResNet score models on GMM (). KL divergences (solid lines, left axis) and memorization fraction (in %, dashed lines, right axis) against training time for various (Left) at fixed . (Right) at fixed . Insets: and against the rescaled time (left) and (right).
图9:** 通用 - 记忆过渡作为训练设置大小和宽度在GMM()上的ResNet评分模型的一种函数. KL差值(实线,左轴)和记分数(以%,虚线,右轴计)相对于训练时间在各种*(左) *(右) 在固定的. *(右) 在固定的. 套数:和在调整的时间(左)和(右)**。
B.3 Discussion on conditional diffusion models
B.3 关于条件扩散模型的讨论
Conditional generation aims to sample from distributions of the form , where denotes a conditioning variable such as a class label, a text embedding, or any other contextual information. DMs can naturally be extended to this setting using for instance classifier-free guidance [21]. Although conditioning often improves sample quality in practice, memorization effects have also been observed in models trained conditionally [51, 61, 10]. Our analysis does not rely on the model being unconditional since these variables typically enter the model as additional inputs and we expect our result to hold in this setting as well. To investigate it, we train a classifier-free guidance model to generate sample from our Gaussian mixture conditionally on the class label, and compute the memorized fraction as a function of that we report in Fig. 10. In the inset, when rescaling the training time by , the curves for all collapse perfectly, confirming that the phenomenon persists in the conditional setting. For more complex datasets, and may in fact depend on the conditioning variable and intermediate regimes could exist where certain classes have already entered the generalization (or memorization) phase while others have not yet.
有条件生成旨在从的形态分布中进行采样,其中表示一个条件变量,如类标签,文本嵌入,或任何其他背景信息. 模式草案可以自然地扩展至此设置,例如使用无分类器的制导[21]. 虽然在实际操作中,调理往往能提高样本质量,但在有条件训练的模型中也观察到了记忆效应[51,61,10]. 我们的分析并不依赖于模型是无条件的,因为这些变量通常作为补充投入进入模型,我们期望我们的结果也能够在此背景下保持下去。 为了调查,我们训练一个无分类器的制导模型,在类标签上有条件地从我们的高斯混合物中生成样品,并计算被记住的分数,作为我们在图10中报告的的一个函数. 在设置中,当调整培训时间时,的曲线全部完全崩溃,证实现象在条件环境下持续存在. 对于更复杂的数据集,XXMA歌手TH5XX和事实上可能依赖于条件变量和中间态,如果某些类别已经进入概括(或记忆)阶段,而其他类别尚未进入,则可能存在.
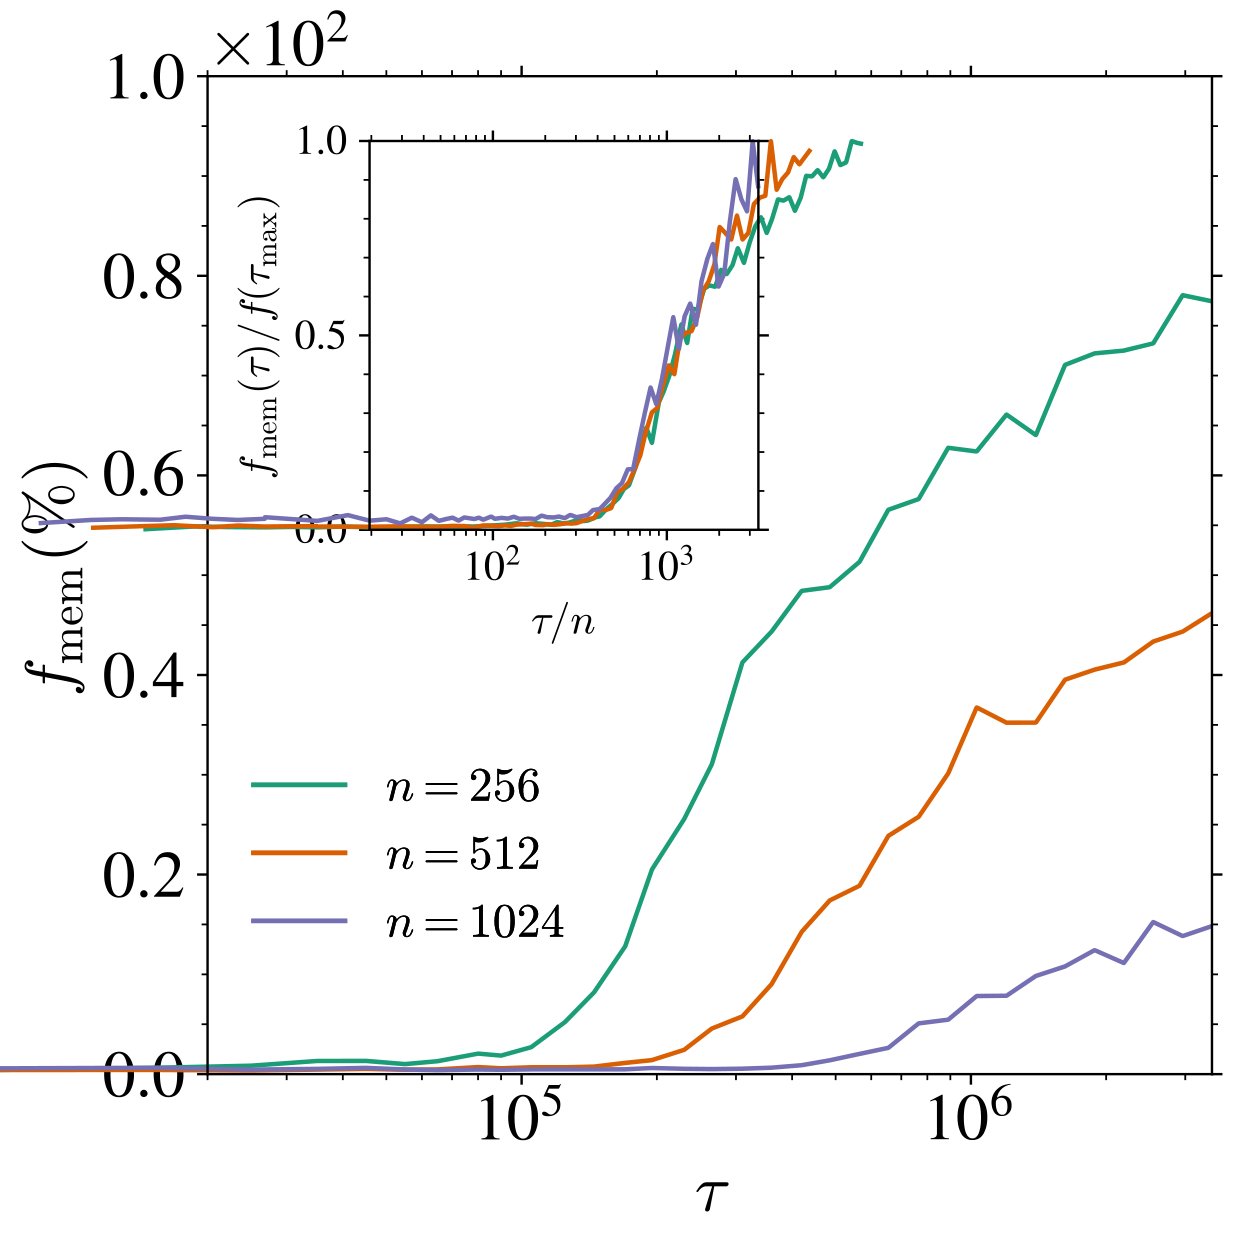
Figure 10: Effect of guidance on . Evolution of as a function of for at fixed .
图10:** 指导对 的影响 作为 在固定值中的函数的演变。 **
Appendix C Proofs of the analytical results
附录 C 解析结果的证明
In the following we provide the mathematical arguments and the proofs for the statement in the MT. The section using the replica method is not mathematically rigorous but uses a well established method of theoretical physics, which has been already shown to provide correct results in several cases. The final result is rigorous, since it can alternatively be obtained from the rigorous free random matrix approach of [15], as shown in Sect. C.4.
在下文中,我们提供了数学论证和MT中陈述的证明. 供其相互联系的彗星,使用复制方法的这个部分在数学上并不严格,而是采用了一种公认的理论物理方法,已经证明在几个案例中提供了正确的结果. 如C.4节所示,最后的结果是严格的,因为也可以从严格的自由随机矩阵法[15]中获取。
C.1 Notations
C.1 记号
We recall here the notations used throughout Sect. 3 of the MT and Sect. C of the SM.
我们在此回顾整个MT第3节和SM第C节所用的说明。
Unless specified, all the expectation values are taken for standard Gaussian variables. We will denote
除非指定,所有期望值都用于标准高斯变量. 我们会表示
the matrix whose columns are the data point vectors and likewise we decompose as
矩阵,其列是数据点向量,我们同样将分解为
$$\displaystyle\bm{\mathrm{W}}=\begin{bmatrix}(\bm{\mathrm{W}}{1})^{!\top}\
\vdots\
(\bm{\mathrm{W}}{p})^{!\top}\end{bmatrix}\in\mathbb{R}^{p\times d}, \tag{50}$$
where denotes the th row of . We recall the definitions of the matrices and
其中表示第2行的. 我们回顾矩阵和的定义。
C.2 Closed form of the learning dynamics
C.2 学习动力学的闭式解
Proposition C.1.
Let be the solution of the gradient flow (10) defined in the MT with initial conditions , then
** 提案C.1*****。 **
- 让作为MT中定义的具有初始条件的梯度流的解决方案(10),然后是, *
with
- 与 *
Proof.
We expand the square in the training loss
证明
在训练损失中扩大广场
and compute the gradient
并计算梯度
Solving this ordinary differential equation yields the desired result. Consequently, the timescales of the dynamics of is determined by the inverse of the eigenvalues of . ∎
解决这个普通的微分方程会产生预期的结果. 因此,XXMA有责任确保20XX的动态 我想用的 但我们的正反值来决定
C.3 Gaussian Equivalence Principle
C.3 高斯等价原理
As explained in [41, 17, 22], the Gaussian Equivalence Principle which applies in the high dimensional setting considered here establishes an equivalence between the spectral properties of the original model and those of a Gaussian covariate model in which the nonlinear activation function is replaced by a linear term and a nonlinear term that acting as noise,
如[41, 17, 22] 所述,高斯等效原理适用于此处考虑的高维环境,确立了原始模型的光谱特性与高斯等效模型的光谱特性的等效性,其中非线性激活功能被一个线性术语和一个作为噪声的非线性术语所取代,
where are constants that depend on the distribution of the data and on the activation function whose formula we recall
其中是常数,取决于数据的分布和激活函数,我们记得其公式
The expectation function are with respect to and . The Gaussian Equivalence Principle (GEP) holds if the distribution of the vector verifies
预期职能涉及和。 如果矢量 \bm{\mathrm{P_{\bm{\mathrm{x}}}$ATH2 XX 的分布得到验证,高斯等效原理(GEP)将持有
(i) has sub-Gaussian tails: there exists a constant such that for all and each entry , (60)
(ii) The data covariance matrix is bounded: there exists a constant independent of such that and where denotes the spectral norm of .
(一)有次古斯底:存在一个恒定的,对于所有和每个条目,(60).
(二)数据共变矩阵是受约束的:存在独立于的常数,即和,其中表示的光谱规范.
In this section, we outline the derivation of the Gaussian Equivalence Principle (GEP) for the matrices and under arbitrary input covariance. This generalizes the approach developed in [15], which considered only the case of data drawn from . A more rigorous approach, which would consist in following [36], is left for future works. We will make use of the Mehler kernel formula [27] which states that for a test function defined on ,
在本节中,我们概述了在任意输入共性下对矩阵和矩阵提出的高斯等效原则。 这概括了在[15]中制定的办法,其中只考虑了从中提取的数据。 今后的工作将采用更为严格的做法,即遵循[36]。 我们将使用Mehler内核公式[27],该公式指出,对于,一个在上定义的测试函数,
where the expectation on the left-hand side is taken over jointly Gaussian random variables and with zero mean, unit variance, and correlation , while on the right-hand side the expectation is taken over independent standard Gaussian variables. denotes the -th Hermite polynomial. We recall some useful properties of the Hermite polynomials [4]:
其中左侧的预期值被联合接管高斯随机变量和,并带有零平均值,单位差异,以及关联性,而右侧的预期值被接管独立的标准高斯变量. 表示-第2次赫尔米特多诺米亚. 我们回顾赫米特人多诺米亚人的一些有用特性[4]:
- • They form an orthogonal base of .
- • The first Hermite polynomials are .
• 它们构成的正交基。
• 第一种赫米特多诺米是。
Lemma C.1(Gaussian Equivalence Principle for ).
In the limit with and with a dataset sampled from a distribution which verifies assumptions (i) and (ii) with , the matrix
** Lemma C.1**(第号的格鲁士等价原则)**。
在限值中,与并用从分配中抽取的数据集对假设(一)和(二)与进行验证,矩阵*
has the same spectrum as its Gaussian equivalent
- 其谱系与其高斯等同*
where
- 在哪里 * * Where *
is a matrix whose columns are sampled according to and has gaussian entries independent of and .
*是一个矩阵,其栏根据和进行抽样,其加西语条目独立于和.
Proof.
For the sake of clarity, in this proof we explicitly make the covariance of the data appear by writing the data points are written as where the vectors have variance 1. Let us focus on the element of in position
证明
为了明确起见,我们在此证据中明确将数据的共变值通过写作来显示,数据点被写成,其中矢量有差异1. 让我们集中谈谈第号阵地的内容。
where repeated indices mean that there is a hidden sum. We introduce the random variable . In the high dimensional limit it converges to a Gaussian random variable by the Central Limit Theorem (since the tails of the data distribution are sub-Gaussian). If , the diagonal terms concentrate with respect to the data points and we can thus replace the sum by an average
重复的指数表示有隐藏的总和。 我们介绍随机变量 。 在高维限中,它通过中限定理(因为数据分布的尾部是次古西安)与高斯随机变量汇合. 如果,对角术语集中在数据点上,因此我们可以用平均值取代总和。
The finite corrections can be discarded because they cannot change the spectrum of . can be taken Gaussian with mean 0 and covariance hence
有限的更正可以放弃,因为它们不能改变的频谱.可以用平均值 0 和 共变值取下
If , we denote . For now we consider and the fixed and look at . We use the Mehler Kernel formula for the random variables and that have correlation
如果,我们表示. 现在,我们考虑第和第定型,看看第. 我们使用Mehler Kernel公式来计算具有关联性的和的随机变量
We truncate at order since the corrections are order .
由于更正为号,我们按第号顺序缩短。
by neglecting corrections and where the law of can be considered Gaussian with zero mean correlation . The coefficient in front of is therefore
由于忽略了更正,因此可以认为的定律是零正相关值. 因此,之前的系数是:
Denote . We now focus on
注释. 我们现在专注于
We use the GEP on
我们用GEP 在
with and . Hence the truncated expansion yields for
与和合并. 因此,第号的减速扩展产量
Now we need to deal with the diagonal term. We need to substract
现在我们需要处理对角术语。 我们需要减法
The Gaussian equivalent of reads
第的高斯等值读作
with .
与合并。
∎
Lemma C.2(GEP for ).
Let
** Lemma分区**(第 GEP)**。 **
让
where the expectation value is taken . Then the GEP of reads
- 以为预期值。 然后,的GEP读作*
where and are defined in Sect. C.1.
- C.1节界定了和的定义。
Proof.
For a vector sampled from , the are asymptotically Gaussian with 0 mean, variance and correlation . We apply Mehler Kernel formula to
证明
对于从中抽取的矢量,是不对称的高斯语,其平均值为0,差异值为,相关值为. 我们在中应用梅勒克内尔公式
where the expectation on and is standard Gaussian. We keep only terms at order . If we keep the terms up to order .
其中对和的期望是标准高斯语. 我们只按的顺序 如果,我们保留条件 一直到。
For we cannot truncate because all terms are . Hence the diagonals terms are asymptotically
对来说,我们不能截断,因为所有术语都是。 因此,对角词是不对称的
Taking care of the diagonal terms, the Gaussian Equivalent matrix reads
跛着对角术语,高斯等值矩阵读作
where .
第号
∎
Building on the GEP of , we prove the following lemma on the scaling of the eigenvalues in the bulk.
在的GEP的基础上,我们证明了以下的莱玛在量产值上的比例。
Lemma C.3(Scaling of the bulk of ).
We assume that is positive definite and that the spectral norm stays . In the high dimensional limit , the spectrum of is asymptotically equal to
** Lemma C.3**(扩大第号决议的大部分内容)**。
- 我们假定是肯定的,光谱规范保持. 在高维限中,的频谱在不对称上等于 *
where is an atomless measure whose support is of order .
- 是一种无原子措施,其支持是命令。
Proof.
Since and and , the spectrum admits a Dirac mass at with weight . For the order of magnitude of the eigenvalues in the bulk, let us first observe that the bulk of is the same as the one of . We can bound the spectral norm of the product by the product of the spectral norms
证明
自和和以来,光谱在接受一个具有重量的Dirac质量 . 关于大宗中元值的量级,让我们首先指出,的量级与的量级相同。 我们可以用光谱规范的产物 来约束产品的光谱规范
since we assumed that and since is given by the Marchenko-Pastur law [39]. To bound the norm from below we use the following inequality
既然我们假设和是由马琴科-巴斯图尔法给予的[39]. 为了将规范从下面绑起来 我们利用以下不平等
Since is positive definite, the bound is also of order . This concludes that the support of the bulk is of order . ∎
由于是肯定的,约束也是命令. 由此得出结论,批量支持是命令。
Lemma C.4(GEP for and ).
Let
** Lemma C.4**(第和第 GEP)**。 **
让
They can be replaced by their Gaussian Equivalence Principle in the train and test losses.
- 它们可由它们在火车和试验损失中的高斯等值原则所取代。 *
Proof.
The two matrices only differ element-wise by quantity of order and therefore have the same Gaussian Equivalent matrix. We focus on . Introduce the random variable . Its has 0 mean, covariance and correlation with . We apply the Mehler Kernel formula
证明
这两种矩阵仅因量值而异,因此具有相同的高斯等价矩阵. 我们把重点放在上。 引入随机变量。 它有0平均,共变的和与 的相关性. 我们采用梅勒核心公式
∎
C.4 Proof of Theorem 3.1
C.4 定理 3.1 的证明
We recall the Theorem 3.1 of the MT.
我们回顾MT定理3.1。
Theorem C.1.
Let , and , with . Let
** 定 义 C.1******。 **
- 让、和与。 让*
Then and satisfy the following set of three equations:
- 然后和满足以下一组三个方程:*
The eigenvalue distribution of , , can then be obtained using the Sokhotski–Plemelj inversion formula .
- ,的等值分布,然后可以使用Sokhotski-Plemelj反演公式获得.
We first show that the equations of the Stieltjes transform of found in Ref. [15] with linear pencils [7] in the case i.e. can be reduced to the equations of Theorem 3.1 with our definitions of and . The equations of [15] read
我们首先表明,在参考文献[15]中发现的使用线性铅笔的即的Stieltjes变换方程,可与我们关于和的定义简化为定理3.1的方程. [15]的等式为:
with and auxiliary variables. We make the following change of variables . The second equations relates to and
带有和辅助变量. 我们对变量作如下修改。 第二个方程式涉及和
Injecting this into the second equations gives the second equation of Theorem 3.1. The fourth equation gives
将此注入第二方程中,给出了定理3.1的第二方程. 第四个方程式
Injecting this into the first equation gives
输入到第一个方程式中
After some massaging we find back the first equation of Theorem 3.1. We now prove Theorem 3.1 using a replica computation, inspired by the calculation done in Ref. [13].
经过一些按摩后,我们发现回 第一级方程式定理3.1。 我们现在通过参照参考文献[13]中的计算,用复制计算来证明定理3.1。
Proof.
Our goal is to compute the Stieltjes transform of the matrix .
证明
我们的目标是计算Stieltjes 变换的矩阵 。
The so-called replica trick consists of replacing the by . Applying this identity, we obtain
所谓的replica trick包括将替换为. 使用这个身份,我们获得
where as usual with replica computations we have inverted the order of the limits and . We define the partition function as
与往常一样,我们用复制计算法颠倒了限值和的顺序。 我们定义分区函数为
We replace by its Gaussian equivalent proved in Lemma C.1 and write the partition function for an arbitrary integer
我们用在Lemma C.1中证明的代替,并为任意整数写入分区函数
We first perform the computation for integer values of , and then analytically continue the result to the limit . To compute the expectation over , , and , we need the following standard result from Gaussian integration
我们首先对的整数进行计算,然后在分析上将结果延续到极限. 为了计算对、和的期望值,我们需要高斯一体化的以下标准结果:
where is a square matrix and a vector.
其中是一个平方矩阵,是一个矢量.
Averaging over the data set.
The dataset dependence enters through
QQ 浏览数据集。
数据集依赖性通过
We introduce for each replica a Fourier transform of the delta function by using the auxiliary variables as[^† †\dagger]
通过使用辅助变量作为[XXXDagger],我们为每件复制品引入了三角洲函数的傅里叶变换.
In the following, we do the change of variable with a dimensional Gaussian random variable with unit variance.
在以下中,我们用来做变异的的变异,一个的维度高斯随机变量,单位差异.
Denote and , then
注释和,然后
where repeated indices mean that there is an implicit summation.
重复的指数意味着有隐含的汇总。
Averaging over .
The terms that depend on are
在上空飞行。
依赖的术语是:
with
与
We are left with
我们只剩下了
Averaging over the random features .
only appears through .
在随机特性上进行反射 .
仅通过出现.
We end up with
我们最终会
Averaging over the .
We can integrate with respect to . The only terms that appear with it are
{\fn黑体\fs22\bord1\shad0\3aHBE\4aH00\fscx67\fscy66\2cHFFFFFF\3cH808080}在第号上空欢呼
我们可以在方面进行整合。 它出现的唯一条件就是
Denote and , then the integral is of the form
说明和,然后构成
This gives
这给
Introducing the order parameters.
We define the order parameters as and . To enforce these constraints, we use the following delta function representations
介绍顺序参数。
我们把顺序参数定义为和. 为了执行这些限制,我们使用以下三角洲函数表示
We also introduce .
我们还介绍。
The integration over and gives
与和的融合
We need to combine and ,
我们需要把和结合起来,
Then for , we can introduce the density of eigenvalues of
然后,对于, 我们可以引入 的 eigen值密度为
We end up with
我们最终会
where the action reads
动作读作
In the high dimensional limit, the partition function is dominated by the saddle point. By derivating with respect to we get
在高维限中,分区功能以鞍点为主. 关于,我们得到
which yields
产量
As a sanity check, if , differentiation with respect to and yields
作为疗理检查,如果,则对和的产量进行区分。
and we find back the same action as before.
我们又找到和以前一样的动作
RS Ansatz.
As before we introduce a RS ansatz for all the the matrices and moreover suppose that only the diagonal terms are non vanishing i.e. they are of the form . This ansatz yields
(原始内容存档于2019-09-22). RS Ansatz.
正如我们对所有矩阵采用RS ansatz之前一样,此外,我们假设只有对角词是不会消失的,即它们属于。 这个Ansatz的产量
Let us differentiate with respect to the 5 variables
让我们就5个变量作出区分
Hence the saddle point equations read
因此,鞍点方程读作
Finally, we observe that the solution to the saddle point equations corresponds to the Stieltjes transform of .
最后,我们看到,到鞍点方程的溶液与的Stieltjes变换相对应.
∎
C.5 Proof of Theorem 3.2
C.5 定理 3.2 的证明
We recall Theorem 3.2 of the MT.
我们回顾MT定理3.2.
Theorem C.2(Informal).
Let denote the spectral density of .
** C.2**(非正式)**。 **
- 让表示的光谱密度。
Regime I (overparametrized): .
Regime II (underparametrized): .
- 制度一(超标):。
- II号制度(不足):。 *
where is a atomless measure with support
其中是一种有支持的无原子措施
and coincides with the asymptotic eigenvalue bulk density of the population covariance ; is independent of and its support is on the scale . The eigenvectors associated with leave both training and test losses unchanged and are therefore irrelevant. In the limit , the supports of and are respectively on the scales and , i.e. they are well separated.
*和与人口共变的不对称二原值块密度相吻合;独立于,其支持规模为. 与有关的编辑人员使培训和测试损失保持不变,因此无关紧要。 在限值中,和的支持分别位于尺度和上,即它们已经很好地分离. *.
We now proceed to prove Theorem 3.2.
我们现在着手证明定理3.2。
Proof.
Delta peak. We first account for the delta peak in the spectrum. We use the Gaussian equivalence for computed in Lemma C.1. Let be the th column of and the th row of . Suppose a vector lies in the kernel of all these
证明
** 德尔塔峰 建议。 我们首先说明三角洲 建议在光谱中。 我们使用高斯等值法计算出在Lemma C.1中的。 让成为的第XX列,让成为的第XX列. 如果矢量位于所有这些的内核**
then . These are linear constraints on a vector of size hence there are non trivial solutions for . Hence a delta-peak at appears as soon as . Next, we extract its weight. Recall that the Stieltjes transform satisfies
然后是。 这些是对大小的矢量的线性约束 ,因此,有非细微的解决方案. 因此,在出现三角峰时,即为。 接下来,我们提取它的重量。 记得斯提尔捷斯的转变满足了
and a point mass of weight at contributes as . Meanwhile
在时,一个重量的点质量为。 同时
remain finite in that limit, since the corresponding eigenvectors satisfy . We substitute this Ansatz into the equations of Theorem 3.1. The first equation reads
由于相应的编辑者满足的要求,该限额仍为有限。 我们用这个安萨兹来代替定理3.1的方程式. 第一个方程式是
and simplifies to
并简化为
It readily gives
它很容易给
Thus the point mass at has weight , in agreement with the counting of degrees of freedom presented above. Finally, one checks that these isolated eigenvalues do not contribute to the train and test losses. After expanding the square they read
百度百科 百度百科 百度百科 百度百科 百度百科 百度百科 百度百科 百度百科 最后,有一次检查,这些孤立的eigen价值不会造成列车和测试损失. 在扩大广场后,他们读到
The terms that appear in the loss are of the form and . The trace can be decomposed on the basis of eigenvectors of . The eigenvectors associated with the delta peak satisfy . Looking at the expression of the matrix , one can easily see that, for initial conditions , one has and the subspace corresponding to these isolated eigenvalues does not contribute to the loss. First bulk. Using the expression for and we make the following Ansatz in the large limit:
损失中出现的术语为和。 痕量可根据的eigenvectors分解. 与三角洲峰相关的精子满足. 从矩阵的表达方式来看,人们可以很容易地看到,在初始条件中,一个人拥有,与这些孤立的eigen值对应的子空间不会造成损失. ** 第一批。 ** 使用和的表达式,我们在的大型限制中做了以下 Ansatz:
In this limit the saddle point equations becomes at leading order in
在这个限制中,鞍点方程在中成为领先顺序
We can focus only on the last equation on only. This is a quadratic polynomial in . If its discriminant is negative then the solutions are imaginary and thus the density of eigenvalues is non-zero. The edge of the bulk are where the discriminant vanishes
我们只能把注意力集中在上一个方程式上。 这是中的一种四倍体多元体. 如果它的歧视性是负的,那么溶液就是想象的,因此,基值的密度是非零的. 大部分的边缘是歧视者消失的地方
It vanishes for
它消失为
which are the edges of the first bulk . We have checked this result, and hence validated the Ansatz solving numerically the equations on . Interestingly at leading order the expression of the first bulk is independent of . Second Bulk. We scale and . The equations on and lead to
它们是第一批的的边缘。 我们的关键要素是,安萨兹以数字方式解决了的方程式。 有趣的是,第一批的表示独立于。 ** 第二批。 ** 我们的尺度是和。 和上的方程式导致:
This yields the following equation on
在上得出以下公式
We denote the shifted variable . This yields
我们表示变位变量。 这个产量
We decompose the integral
我们分解整体
By plugging this back in the equation we find
把这个塞回方程式里
We do the change of variable . This yields
我们做变异的。 这个产量
An integration by parts give that . We thus realize that the integral is over the eigenvalue distribution of ,
各个部分的整合使 . 因此,我们意识到,组成部分超越了第的元值分配,
We recognize the Bai-Silverstein equations [48, 5] for the eigenvalue density of the matrix
我们认清了Bai-Silverstein方程 [48, 5] 基质的等值密度
which is the population version of and is thus independent of . Lemma C.3 concludes on the order of the eigenvalues in the bulk of .
这是的人口版本,因此独立于. Lemma C.3在的批量中以eigen值的顺序得出结论.
∎
C.6 Dynamics on the fast timescales
C.6 快时间尺度上的动力学
In the following we denote for a matrix ,
在下文中,我们表示一个矩阵,
the operator norm and
操作者规范以及
the Frobenius norm. Before deriving the fast-time behavior, we need the following lemma.
弗罗贝尼乌斯规范。 在产生快速行为之前 我们需要以下的lemma。
Lemma C.5.
The operator norm of satisfies
** 莱玛 C.5******。 **
操作规范满足
when .
- 当.
Proof.
On the one hand,
证明
′′′′′N 有没有搞错?
and on the other hand,
另一方面,
We also note the identities and .
我们还注意到和的身份。
We can bound its operator norm
我们可以约束它的操作规范
where are constants independent of . We bound each of the three terms on the right hand side. We will use the fact that for a symmetric matrix, the operator norm is equal to its largest eigenvalue.
其中是独立于的常数. 我们把三个术语都绑在右手边 我们将利用这样一个事实,即对于一个对称的矩阵,操作规范等于其最大的eigen值.
First term.
We observe that and have the same eigenvalues up to the multiplicity of 0[^† †\dagger]. We then use the sub-multiplicativity of the operator norm
我们观察到,和具有相同的等元值,最多为0[XXXDagger]的多重值. 然后我们使用操作规范的分倍性
We can do the same operation by introducing with with standard Gaussian entries,
我们可以通过引入 与 与标准高斯条目,
Among our assumptions, we had . The spectrum of is the Marchenko-Pastur law whose largest eigenvalue is of order while for it is order . The bound reads
在我们的假设中,我们有。 的谱系是Marchenko-Pastur定律,其最大eigen值为令,而对于则为令. 约束为:
Second term.
We observe that the spectrum of is Marchenko-Pastur and thus its largest eigenvalue is order yielding
我们注意到,的谱系为·马延科-帕斯图尔,因此其最大的基值是命令。
Third term.
We first bound the operator norm by the Frobenius norm.
我们首先按照弗罗贝尼乌斯的规范来约束操作者规范.
We expand the square
我们扩大广场
The Central Limit Theorem yields
中央限制定理产量
hence
因此,
Putting all the contributions together yields
将所有贡献合并起来
∎
Proposition C.2(Informal).
On timescales , both the train and test losses satisfy
** 提案C.2**(非正式)**。 **
在时标上,列车和试验损失都满足
Proof.
According to the spectral analysis of conducted previously, there are two bulks in the spectrum that contribute to the dynamics: a first bulk with eigenvalues of order and a second bulk with eigenvalues of order in the limit. Hence, in the regime , if is in the second bulk and is if is in the first bulk. We remind the expressions of the train and test loss
证明
根据以前对进行的光谱分析,光谱中有两批有助于动力学:第一批具有定序的eigen值,第二批具有定序的eigen值. 因此,在制度中,如果属于第二批,如果属于第一批,则为。 我们提醒火车的表达和测试损失
and use the expression of in Proposition C.1 that we expand on the basis of eigenvectors of .
并使用在的 eigenvectors的基础上扩展的的表达.
where means that the eigenvalue belongs to the second bulk. We also have that and have the same GEP and they thus cancel each other when computing the generalization loss . It reads
其中表示 eigenvalue属于第二批. 我们还发现,和具有相同的GEP ,因此在计算的通用化损失时,它们相互取消了. 写着
We then use Lemma C.5 — which states that the operator norm of in the subspace spanned by the eigenvectors of the second bulk is bounded by — to bound ,
然后,我们使用Lemma C.5——该标准规定,在第二批的精算器跨越的子空间中,的操作规范以为界——将,
We also used the fact that the sums contain terms — the only terms that matter are the diagonal ones — and that the eigenvalues scale as . The bound yield that vanishes asymptotically in the large number of data and large number of parameters regime. Therefore, on the fast timescale we find . Let us now focus on
我们还使用了这样的事实,即这些金额中包含术语——唯一重要的术语是对角术语——以及作为的等值尺度。 第号卫星在大量数据和大量参数制度下无节制地消失。 因此,在快速的时间尺度上,我们发现。 让我们现在集中谈第号决议
There are values in the sum and the eigenvalues of and are both order hence the sum divided by is a positive quantity thus in this training time regime, , we obtain:
在总和中存在和的等值,两者的等值均为,因此,除以的等值是的正值,因此,在这个培训时间制度中,我们得到:
∎
Appendix D Numerical experiments for Random Features
附录 D 随机特征的数值实验
Details on the numerical experiments.
All the numerical experiments for the RFNN were conducted using and unless specified. At each step, the gradient of the loss was computed using the full batch of data points. The train loss was estimated by adding noise to each data point times. The test loss was computed by drawing new points from the data distribution and noising each one times. The error on the score was evaluated by drawing 10,000 points from the noisy distribution .
数字实验的细节。
除非另有说明,区域网的所有数值试验均使用和进行。 在每一步骤,损失的梯度都是用全部数据点计算的。 列车损失是通过在每个数据点上增加噪音来估计的. 计算测试损失的方法是从数据分配中抽取新点,并点头一次。 通过从吵闹的分发中抽取10,000分来评价得分错误.
Effect of .
Figure 11: Generalization loss for different diffusion times . Generalization loss against (Left) training time and (Right) rescaled training time for different and different and .
效应.
图11:不同传播时间的一般化损失 . 相对于(Left)培训时间 和(Right)调整培训时间 对于不同的和不同的和.
We present plots for different diffusion times in Fig. 11 and show that the rescaling of the training times by also makes the loss curves collapse. Of particular interest is the behavior of , and more specifically the ratio , at small . Recall that
我们在图11中提出了不同传播时间的地块,并表明将的训练时间调整为也使损失曲线崩溃。 特别令人感兴趣的是的行为,更具体地说是的比例,在小. 回顾
In the overparameterized regime , this ratio is independent of since and . However, when , a nontrivial scaling emerges: since , it follows that
在超参数化制度中,这个比率独立于,自和. 然而,当 出现非三角缩放时:自 以来,该缩放如下:
implying that the two timescales become increasingly separated. It is unclear whether this behavior is related to specific properties of the learned score function, and is related to the approach of the interpolation threshold. We leave this question for future investigation.
意味着两个时标越来越分离. 目前尚不清楚这种行为是否与所学得分函数的特定属性相关,也与插值阈值的方法相关. 这个问题留待将来调查。
Experiments with .
In Fig. 12, we present train and test loss curves for . We see that our prediction of the timescale of memorization computed in the MT holds for general data variance.
与进行实验.
在图12中,我们提出了的列车和测试损失曲线。 我们看到,我们预测在MT中计算到的记忆时间尺度对一般数据差异有利。
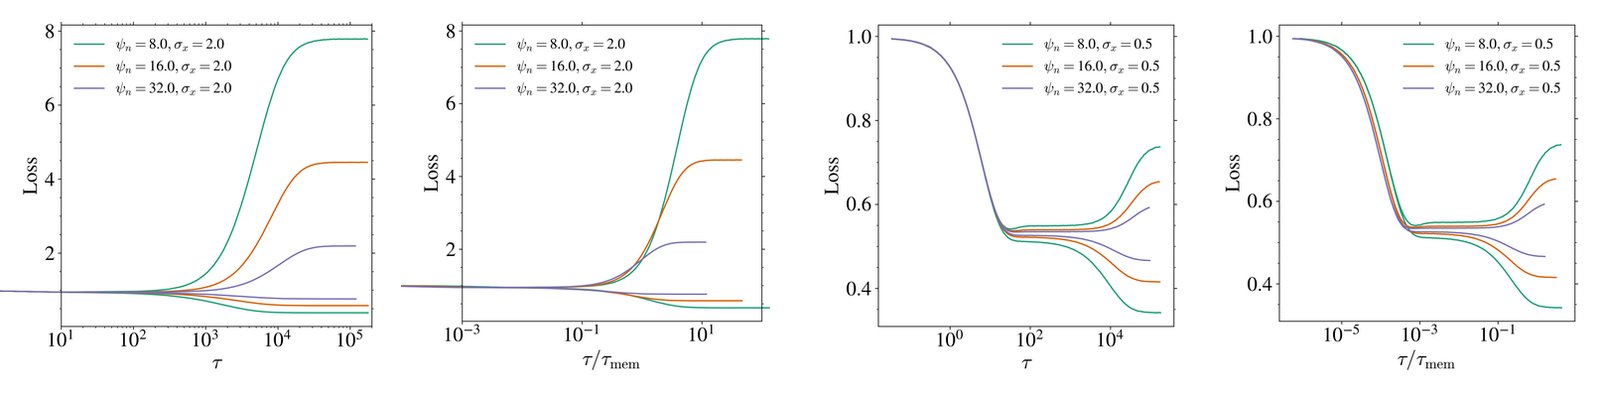
Figure 12: Different . Train loss (solid line) and test loss (dotted line) for , different and (top) and (bottom) against the training time and the rescaled training time .
图12:** 不同的. 、不同的和(上)和(下)的列车损失(实线)和试验损失(虚线)与培训时间的对比
Scaling of with .
In the RF model, the error with respect to the true score, as defined in the main text,
- 将与相适应。
在RF模型中,正文中定义的真实分数错误,
serves as a measure of the generalization capability of the generative process. As shown in [53], the Kullback–Leibler divergence between the true data distribution and the generated distribution can be upper bounded
成为衡量基因过程一般化能力的一个尺度。 如[53]所示,Kullback–Leibler在真实数据分布和生成的分布之间的差值可以被上方限定.
where the integral is taken over all estimations of the parameter matrix at all diffusion times . This bound assumes that the reverse dynamics are integrated exactly, starting from infinite time. In practical settings, however, one typically relies on an approximate scheme and initiates the reverse process at a large but finite time . A generalization of this bound under such conditions can be found in [8]. We have numerically investigate the behaviour of on Fig. 13. On the fast timescale , it decreases until a minimal value that depends only on with a power-law with . We leave for future work performing an accurate numerical estimate of and a developing a theory for it.
,其组成部分在任何传播时间的 中,均接管参数矩阵的所有估计值。 这个约束假设反向动力是完全融合的,从无限时间开始. 然而,在实际环境中,人们通常依赖一种近似办法,并在一个大而有限的时间启动反向进程。 可在[8]中发现在这种条件下这一约束的概括。 我们对图13上的的行为进行了数字调查。 在快速时间尺度的上,它下降至一个最小值的,它仅依赖于拥有电源法的和. 我们留给今后的工作,对进行准确的数字估计,并为它制定理论。
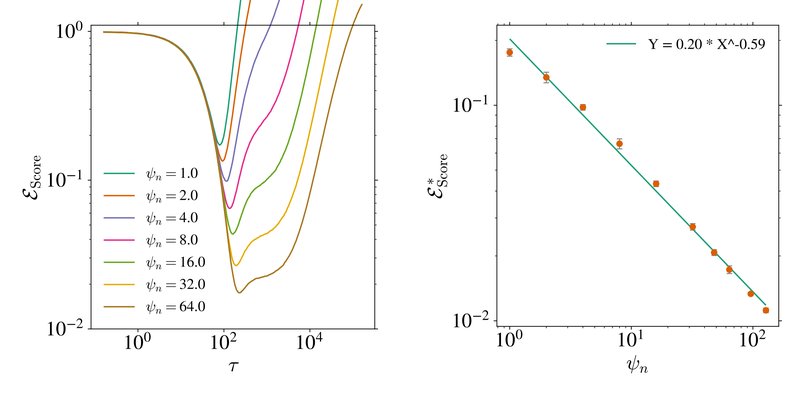
Figure 13: Effect of on . (Left) Error between the learned score and the true score for , , and various values of . (Right) Minimum score error as a function of , showing a power-law decay with exponent approximately . The error bars correspond to thrice the standard deviation over 10 runs with new initial conditions.
图13:**对的影响 (Left) 学习得分与,的真实得分之间的错误,以及各种值为. (Right) 最小得分错误为作为的一种函数,显示功率-法衰减,主动力约为. 误差栏对应10个以上的标准偏差的三倍,并附有新的初始条件。 **
Spectrum of .
In Fig. 14, we compare the solutions of the equations of Theorem 3.1 to the histogram of finite size realizations of .
的谱系.
在图14中,我们比较了定理3.1等式的解决方案与有限尺寸实现的直方图.
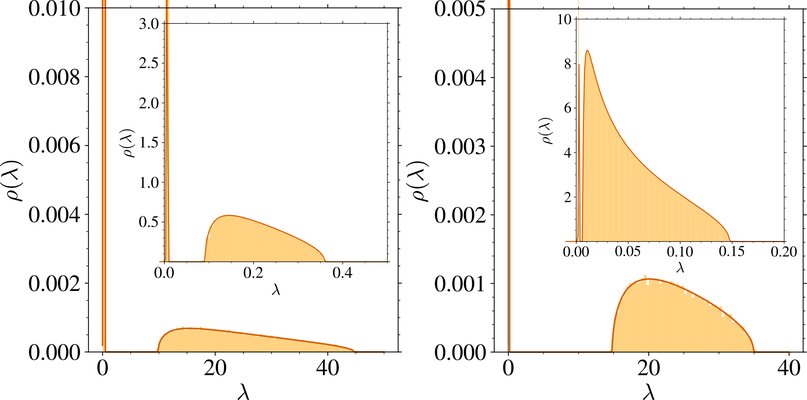
Figure 14: Spectrum of . Solutions of the equations in Theorem 3.1. (solid lines) and empirical spectrum for and (histogram). (Left) , , . (Right) , , .
图14:** 的示意图. 定理3.1.(固线)中的方程解决方案和和(历史图)的经验谱. (左),,. (右),,. **
Effect of Adam optimization.
Numerical experiments with RFNN on Gaussian data show that the linear scaling of the memorization time with holds also for the Adam optimizer as shown in Fig.15.
亚当优化的效果。
在高斯数据上与RFNN进行的数字实验表明,用计时时间的线性缩放也为亚当优化器所持有,如图15所示.
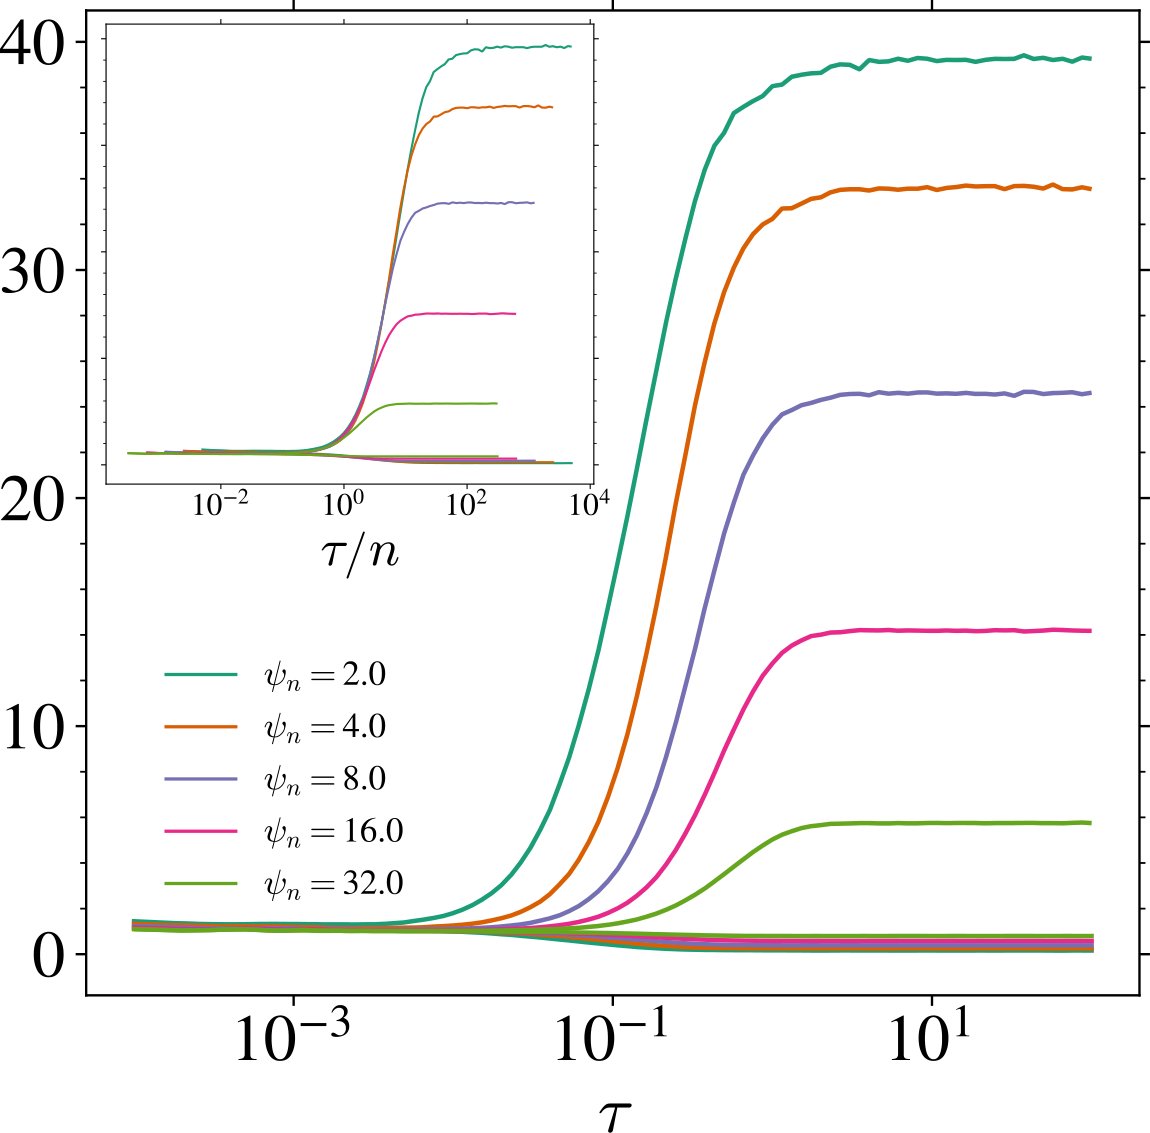
Figure 15: Adam. Train loss (solid line) and test loss (dotted line) at for several with the Pytorch [38] implementation of Adam. The inset shows the effect of a rescaling of the training time by .
图15:**亚当。 列车损耗(实线)和试验损耗(虚线)在,与Pytorch[38] Adam一起执行若干 . 套件显示调整培训时间的效果。 **