An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale
An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale
一张图抵得上 16×16 个词:规模化图像识别中的 Transformer
Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Affiliation: equal technical contribution, equal advising Google Research, Brain Team {adosovitskiy, neilhoulsby}@google.com Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby Affiliation: equal technical contribution, equal advising Google Research, Brain Team {adosovitskiy, neilhoulsby}@google.com
Abstract
摘要
While the Transformer architecture has become the de-facto standard for natural language processing tasks, its applications to computer vision remain limited. In vision, attention is either applied in conjunction with convolutional networks, or used to replace certain components of convolutional networks while keeping their overall structure in place. We show that this reliance on CNNs is not necessary and a pure transformer applied directly to sequences of image patches can perform very well on image classification tasks. When pre-trained on large amounts of data and transferred to multiple mid-sized or small image recognition benchmarks (ImageNet, CIFAR-100, VTAB, etc.), Vision Transformer (ViT) attains excellent results compared to state-of-the-art convolutional networks while requiring substantially fewer computational resources to train.[^1]
尽管 Transformer 架构已成为自然语言处理任务的事实标准,它在计算机视觉中的应用仍然有限。在视觉中,注意力要么与卷积网络结合使用,要么用来替换卷积网络的某些组件而保持其整体结构不变。我们表明,这种对 CNN 的依赖并非必要:把纯 Transformer 直接作用于图像块序列,即可在图像分类任务上表现很好。当在大量数据上预训练并迁移到多个中等或小型图像识别基准(ImageNet、CIFAR-100、VTAB 等)时,Vision Transformer(ViT)相对先进卷积网络取得优异结果,同时训练所需计算资源显著更少。[^1]
1 Introduction
1 引言
Self-attention-based architectures, in particular Transformers (Vaswani et al. 2017), have become the model of choice in natural language processing (NLP). The dominant approach is to pre-train on a large text corpus and then fine-tune on a smaller task-specific dataset (Devlin et al. 2019). Thanks to Transformers’ computational efficiency and scalability, it has become possible to train models of unprecedented size, with over 100B parameters (Brown et al. 2020; Lepikhin et al. 2020). With the models and datasets growing, there is still no sign of saturating performance.
基于自注意力的架构,尤其是 Transformer (Vaswani et al. 2017),已成为自然语言处理(NLP)中的首选模型。主流做法是在大规模文本语料上预训练,再在较小的任务特定数据集上微调 (Devlin et al. 2019)。得益于 Transformer 的计算效率与可扩展性,训练前所未有规模的模型成为可能,参数超过 100B (Brown et al. 2020;Lepikhin et al. 2020)。随着模型与数据集增大,性能仍未见饱和迹象。
In computer vision, however, convolutional architectures remain dominant (LeCun et al. 1989; Krizhevsky et al. 2012; He et al. 2016). Inspired by NLP successes, multiple works try combining CNN-like architectures with self-attention (Wang et al. 2018; Carion et al. 2020), some replacing the convolutions entirely (Ramachandran et al. 2019; Wang et al. 2020a). The latter models, while theoretically efficient, have not yet been scaled effectively on modern hardware accelerators due to the use of specialized attention patterns. Therefore, in large-scale image recognition, classic ResNet-like architectures are still state of the art (Mahajan et al. 2018; Xie et al. 2020; Kolesnikov et al. 2020).
然而在计算机视觉中,卷积架构仍然主导 (LeCun et al. 1989;Krizhevsky et al. 2012;He et al. 2016)。受 NLP 成功启发,多项工作尝试把类 CNN 架构与自注意力结合 (Wang et al. 2018;Carion et al. 2020),有的甚至完全替换卷积 (Ramachandran et al. 2019;Wang et al. 2020a)。后一类模型虽在理论上高效,但由于使用专门的注意力模式,尚未在现代硬件加速器上有效扩展。因此,在大规模图像识别中,经典类 ResNet 架构仍是先进水平 (Mahajan et al. 2018;Xie et al. 2020;Kolesnikov et al. 2020)。
Inspired by the Transformer scaling successes in NLP, we experiment with applying a standard Transformer directly to images, with the fewest possible modifications. To do so, we split an image into patches and provide the sequence of linear embeddings of these patches as an input to a Transformer. Image patches are treated the same way as tokens (words) in an NLP application. We train the model on image classification in supervised fashion.
受 NLP 中 Transformer 扩展成功的启发,我们实验把标准 Transformer 直接应用于图像,并尽可能少做修改。为此,我们把图像切成块,并把这些块的线性嵌入序列作为 Transformer 的输入。图像块的处理方式与 NLP 应用中的记号(词)相同。我们以监督方式在图像分类上训练模型。
When trained on mid-sized datasets such as ImageNet without strong regularization, these models yield modest accuracies of a few percentage points below ResNets of comparable size. This seemingly discouraging outcome may be expected: Transformers lack some of the inductive biases inherent to CNNs, such as translation equivariance and locality, and therefore do not generalize well when trained on insufficient amounts of data.
当在 ImageNet 这类中等规模数据集上训练且没有强正则时,这些模型只能得到比同规模 ResNet 低几个百分点的一般精度。这一看似令人沮丧的结果或许在预期之中:Transformer 缺少 CNN 固有的某些归纳偏置,例如平移等变性与局部性,因此在数据不足时泛化不好。
However, the picture changes if the models are trained on larger datasets (14M-300M images). We find that large scale training trumps inductive bias. Our Vision Transformer (ViT) attains excellent results when pre-trained at sufficient scale and transferred to tasks with fewer datapoints. When pre-trained on the public ImageNet-21k dataset or the in-house JFT-300M dataset, ViT approaches or beats state of the art on multiple image recognition benchmarks. In particular, the best model reaches the accuracy of on ImageNet, on ImageNet-ReaL, on CIFAR-100, and on the VTAB suite of 19 tasks.
然而,当模型在更大数据集(14M–300M 图像)上训练时,图景会改变。我们发现大规模训练胜过归纳偏置。我们的 Vision Transformer(ViT)在足够规模上预训练并迁移到数据点更少的任务时,取得优异结果。当在公开 ImageNet-21k 数据集或内部 JFT-300M 数据集上预训练时,ViT 在多个图像识别基准上接近或超过先进水平。特别是,最好的模型在 ImageNet 上达到 精度,在 ImageNet-ReaL 上 ,在 CIFAR-100 上 ,在含 19 个任务的 VTAB 套件上 。
2 Related Work
2 相关工作
Transformers were proposed by Vaswani et al. 2017 for machine translation, and have since become the state of the art method in many NLP tasks. Large Transformer-based models are often pre-trained on large corpora and then fine-tuned for the task at hand: BERT (Devlin et al. 2019) uses a denoising self-supervised pre-training task, while the GPT line of work uses language modeling as its pre-training task (Radford et al. 2018; Radford et al. 2019; Brown et al. 2020).
Transformer 由 Vaswani et al. 2017 为机器翻译提出,此后成为许多 NLP 任务的先进方法。大型基于 Transformer 的模型常在大规模语料上预训练,再针对手头任务微调:BERT (Devlin et al. 2019)使用去噪自监督预训练任务,而 GPT 系列以语言建模作为预训练任务 (Radford et al. 2018;Radford et al. 2019;Brown et al. 2020)。
Naive application of self-attention to images would require that each pixel attends to every other pixel. With quadratic cost in the number of pixels, this does not scale to realistic input sizes. Thus, to apply Transformers in the context of image processing, several approximations have been tried in the past. Parmar et al. 2018 applied the self-attention only in local neighborhoods for each query pixel instead of globally. Such local multi-head dot-product self attention blocks can completely replace convolutions (Hu et al. 2019; Ramachandran et al. 2019; Zhao et al. 2020). In a different line of work, Sparse Transformers (Child et al. 2019) employ scalable approximations to global self-attention in order to be applicable to images. An alternative way to scale attention is to apply it in blocks of varying sizes (Weissenborn et al. 2019), in the extreme case only along individual axes (Ho et al. 2019; Wang et al. 2020a). Many of these specialized attention architectures demonstrate promising results on computer vision tasks, but require complex engineering to be implemented efficiently on hardware accelerators.
把自注意力朴素应用于图像,会要求每个像素关注其他每个像素。代价相对像素数二次,无法扩展到现实输入尺寸。因此,为在图像处理语境中应用 Transformer,过去尝试了若干近似。Parmar et al. 2018 对每个查询像素只在局部邻域而非全局施加自注意力。这类局部多头点积自注意力块可以完全替换卷积 (Hu et al. 2019;Ramachandran et al. 2019;Zhao et al. 2020)。另一条线中,Sparse Transformers (Child et al. 2019)采用可扩展的全局自注意力近似以便用于图像。扩展注意力的另一种方式是在不同大小的块中施加(Weissenborn et al. 2019),极端情形下仅沿单个轴 (Ho et al. 2019;Wang et al. 2020a)。这些专门注意力架构中有许多在计算机视觉任务上展示出有希望的结果,但要在硬件加速器上高效实现需要复杂工程。
Most related to ours is the model of Cordonnier et al. 2020, which extracts patches of size from the input image and applies full self-attention on top. This model is very similar to ViT, but our work goes further to demonstrate that large scale pre-training makes vanilla transformers competitive with (or even better than) state-of-the-art CNNs. Moreover, Cordonnier et al. 2020 use a small patch size of pixels, which makes the model applicable only to small-resolution images, while we handle medium-resolution images as well.
与我们最相关的是 Cordonnier et al. 2020 的模型:它从输入图像提取 大小的块,并在其上施加完整自注意力。该模型与 ViT 非常相似,但我们的工作更进一步,表明大规模预训练使原版 Transformer 能与(甚至优于)先进 CNN 竞争。此外,Cordonnier et al. 2020 使用 像素的小块尺寸,使模型仅适用于小分辨率图像,而我们也能处理中等分辨率图像。
There has also been a lot of interest in combining convolutional neural networks (CNNs) with forms of self-attention, e.g. by augmenting feature maps for image classification (Bello et al. 2019) or by further processing the output of a CNN using self-attention, e.g. for object detection (Hu et al. 2018; Carion et al. 2020), video processing (Wang et al. 2018; Sun et al. 2019), image classification (Wu et al. 2020), unsupervised object discovery (Locatello et al. 2020), or unified text-vision tasks (Chen et al. 2020c; Lu et al. 2019; Li et al. 2019).
把卷积神经网络(CNN)与各种形式的自注意力结合也引起大量兴趣,例如通过增强特征图做图像分类 (Bello et al. 2019),或用自注意力进一步处理 CNN 输出,例如用于目标检测 (Hu et al. 2018;Carion et al. 2020)、视频处理 (Wang et al. 2018;Sun et al. 2019)、图像分类 (Wu et al. 2020)、无监督目标发现 (Locatello et al. 2020),或统一的文本-视觉任务 (Chen et al. 2020c;Lu et al. 2019;Li et al. 2019)。
Another recent related model is image GPT (iGPT) (Chen et al. 2020a), which applies Transformers to image pixels after reducing image resolution and color space. The model is trained in an unsupervised fashion as a generative model, and the resulting representation can then be fine-tuned or probed linearly for classification performance, achieving a maximal accuracy of 72% on ImageNet.
另一个近期相关模型是 image GPT(iGPT) (Chen et al. 2020a),它在降低图像分辨率与颜色空间后把 Transformer 应用于图像像素。模型以无监督方式作为生成模型训练,所得表征随后可微调或以线性探测评估分类表现,在 ImageNet 上最高达到 72% 精度。
Our work adds to the increasing collection of papers that explore image recognition at larger scales than the standard ImageNet dataset. The use of additional data sources allows to achieve state-of-the-art results on standard benchmarks (Mahajan et al. 2018; Touvron et al. 2019; Xie et al. 2020). Moreover, Sun et al. 2017 study how CNN performance scales with dataset size, and Kolesnikov et al. 2020; Djolonga et al. 2020 perform an empirical exploration of CNN transfer learning from large scale datasets such as ImageNet-21k and JFT-300M. We focus on these two latter datasets as well, but train Transformers instead of ResNet-based models used in prior works.
我们的工作加入日益增多的、在比标准 ImageNet 更大尺度上探索图像识别的论文行列。使用额外数据源可在标准基准上取得先进结果 (Mahajan et al. 2018;Touvron et al. 2019;Xie et al. 2020)。此外,Sun et al. 2017 研究 CNN 表现如何随数据集规模扩展,Kolesnikov et al. 2020;Djolonga et al. 2020 对从 ImageNet-21k 与 JFT-300M 等大规模数据集做 CNN 迁移学习进行了经验探索。我们也聚焦这两个数据集,但训练的是 Transformer 而非先前工作中的基于 ResNet 的模型。
3 Method
3 方法
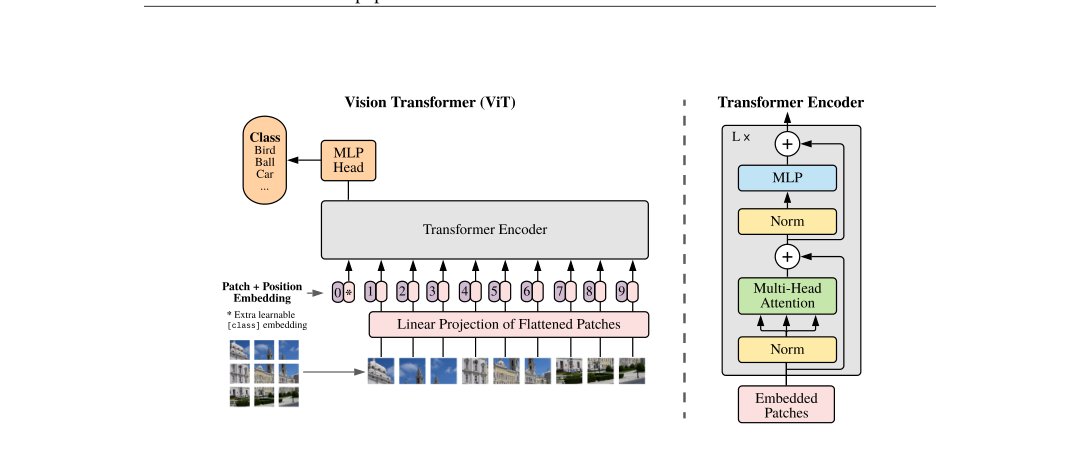
Figure 1: Model overview. We split an image into fixed-size patches, linearly embed each of them, add position embeddings, and feed the resulting sequence of vectors to a standard Transformer encoder. In order to perform classification, we use the standard approach of adding an extra learnable “classification token” to the sequence. The illustration of the Transformer encoder was inspired by Vaswani et al. 2017.
图 1:模型概览。我们把图像切成固定大小的块,对每个块做线性嵌入,加入位置嵌入,并把所得向量序列送入标准 Transformer 编码器。为做分类,我们采用标准做法:向序列添加一个额外的可学习「分类记号」。Transformer 编码器示意图受 Vaswani et al. 2017 启发。
In model design we follow the original Transformer (Vaswani et al. 2017) as closely as possible. An advantage of this intentionally simple setup is that scalable NLP Transformer architectures – and their efficient implementations – can be used almost out of the box.
在模型设计上,我们尽可能贴近原始 Transformer(Vaswani et al. 2017)。这一有意保持简单的设定的优势是:可扩展的 NLP Transformer 架构——及其高效实现——几乎开箱即用。
3.1 Vision Transformer (ViT)
3.1 Vision Transformer(ViT)
An overview of the model is depicted in Figure 1. The standard Transformer receives as input a 1D sequence of token embeddings. To handle 2D images, we reshape the image into a sequence of flattened 2D patches , where is the resolution of the original image, is the number of channels, is the resolution of each image patch, and is the resulting number of patches, which also serves as the effective input sequence length for the Transformer. The Transformer uses constant latent vector size through all of its layers, so we flatten the patches and map to dimensions with a trainable linear projection (Eq. 1). We refer to the output of this projection as the patch embeddings.
模型概览见图 1。标准 Transformer 接收一维记号嵌入序列作为输入。为处理二维图像,我们把图像 重塑为展平的二维块序列 ,其中 是原始图像分辨率, 是通道数, 是每个图像块的分辨率, 是所得块数,也作为 Transformer 的有效输入序列长度。Transformer 在所有层使用恒定潜向量尺寸 ,因此我们展平这些块并用可训练线性投影映射到 维(式 1)。我们把该投影的输出称为块嵌入。
Similar to BERT’s [class] token, we prepend a learnable embedding to the sequence of embedded patches (), whose state at the output of the Transformer encoder () serves as the image representation (Eq. 4). Both during pre-training and fine-tuning, a classification head is attached to . The classification head is implemented by a MLP with one hidden layer at pre-training time and by a single linear layer at fine-tuning time.
类似 BERT 的 [class] 记号,我们在嵌入块序列前添加一个可学习嵌入(),其在 Transformer 编码器输出处的状态()作为图像表征 (式 4)。预训练与微调期间,分类头都接到 。分类头在预训练时由带一个隐层的 MLP 实现,微调时由单线性层实现。
Position embeddings are added to the patch embeddings to retain positional information. We use standard learnable 1D position embeddings, since we have not observed significant performance gains from using more advanced 2D-aware position embeddings (Appendix D.4). The resulting sequence of embedding vectors serves as input to the encoder.
位置嵌入被加到块嵌入上以保留位置信息。我们使用标准可学习一维位置嵌入,因为我们未观察到使用更先进的二维感知位置嵌入有显著性能增益(附录 D.4)。所得嵌入向量序列作为编码器输入。
The Transformer encoder (Vaswani et al. 2017) consists of alternating layers of multiheaded self-attention (MSA, see Appendix A) and MLP blocks (Eq. 2, 3). Layernorm (LN) is applied before every block, and residual connections after every block (Wang et al. 2019; Baevski & Auli 2019). The MLP contains two layers with a GELU non-linearity.
Transformer 编码器(Vaswani et al. 2017)由交替的多头自注意力(MSA,见附录 A)与 MLP 块组成(式 2、3)。每个块前施加 Layernorm(LN),每个块后有残差连接(Wang et al. 2019;Baevski & Auli 2019)。MLP 含两层并带 GELU 非线性。
Inductive bias.
We note that Vision Transformer has much less image-specific inductive bias than CNNs. In CNNs, locality, two-dimensional neighborhood structure, and translation equivariance are baked into each layer throughout the whole model. In ViT, only MLP layers are local and translationally equivariant, while the self-attention layers are global. The two-dimensional neighborhood structure is used very sparingly: in the beginning of the model by cutting the image into patches and at fine-tuning time for adjusting the position embeddings for images of different resolution (as described below). Other than that, the position embeddings at initialization time carry no information about the 2D positions of the patches and all spatial relations between the patches have to be learned from scratch.
归纳偏置。
我们指出,Vision Transformer 比 CNN 少得多图像特定归纳偏置。在 CNN 中,局部性、二维邻域结构与平移等变性被烘焙进整个模型的每一层。在 ViT 中,只有 MLP 层是局部且平移等变的,而自注意力层是全局的。二维邻域结构用得非常节省:在模型开头把图像切成块,以及在微调时为不同分辨率图像调整位置嵌入(如下所述)。除此之外,初始化时的位置嵌入不携带关于块二维位置的信息,块之间的所有空间关系都必须从头学习。
Hybrid Architecture.
As an alternative to raw image patches, the input sequence can be formed from feature maps of a CNN (LeCun et al. 1989). In this hybrid model, the patch embedding projection (Eq. 1) is applied to patches extracted from a CNN feature map. As a special case, the patches can have spatial size 1x1, which means that the input sequence is obtained by simply flattening the spatial dimensions of the feature map and projecting to the Transformer dimension. The classification input embedding and position embeddings are added as described above.
混合架构。
作为原始图像块的替代,输入序列可由 CNN 的特征图形成 (LeCun et al. 1989)。在这一混合模型中,块嵌入投影 (式 1)施加于从 CNN 特征图提取的块。作为一种特殊情形,块的空间尺寸可为 1×1,这意味着输入序列只需展平特征图的空间维并投影到 Transformer 维即可得到。分类输入嵌入与位置嵌入按上文所述添加。
3.2 Fine-tuning and Higher Resolution
3.2 微调与更高分辨率
Typically, we pre-train ViT on large datasets, and fine-tune to (smaller) downstream tasks. For this, we remove the pre-trained prediction head and attach a zero-initialized feedforward layer, where is the number of downstream classes. It is often beneficial to fine-tune at higher resolution than pre-training (Touvron et al. 2019; Kolesnikov et al. 2020). When feeding images of higher resolution, we keep the patch size the same, which results in a larger effective sequence length. The Vision Transformer can handle arbitrary sequence lengths (up to memory constraints), however, the pre-trained position embeddings may no longer be meaningful. We therefore perform 2D interpolation of the pre-trained position embeddings, according to their location in the original image. Note that this resolution adjustment and patch extraction are the only points at which an inductive bias about the 2D structure of the images is manually injected into the Vision Transformer.
通常,我们在大数据集上预训练 ViT,再微调到(较小的)下游任务。为此,我们去掉预训练预测头,并接上一个零初始化的 前馈层,其中 是下游类别数。以高于预训练的分辨率微调往往有益 (Touvron et al. 2019;Kolesnikov et al. 2020)。喂入更高分辨率图像时,我们保持块尺寸不变,这导致更大的有效序列长度。Vision Transformer 可处理任意序列长度(直到内存限制),但预训练位置嵌入可能不再有意义。因此,我们按预训练位置嵌入在原始图像中的位置做二维插值。注意,这一分辨率调整与块提取,是手动向 Vision Transformer 注入关于图像二维结构的归纳偏置的仅有两处。
4 Experiments
4 实验
We evaluate the representation learning capabilities of ResNet, Vision Transformer (ViT), and the hybrid. To understand the data requirements of each model, we pre-train on datasets of varying size and evaluate many benchmark tasks. When considering the computational cost of pre-training the model, ViT performs very favourably, attaining state of the art on most recognition benchmarks at a lower pre-training cost. Lastly, we perform a small experiment using self-supervision, and show that self-supervised ViT holds promise for the future.
我们评估 ResNet、Vision Transformer(ViT)与混合模型的表征学习能力。为理解各模型的数据需求,我们在不同规模的数据集上预训练,并评估许多基准任务。在考虑预训练模型的计算代价时,ViT 表现非常有利:在多数识别基准上以更低预训练代价达到先进水平。最后,我们做了一个使用自监督的小实验,表明自监督 ViT 对未来有希望。
4.1 Setup
4.1 设置
Datasets. To explore model scalability, we use the ILSVRC-2012 ImageNet dataset with 1k classes and 1.3M images (we refer to it as ImageNet in what follows), its superset ImageNet-21k with 21k classes and 14M images (Deng et al. 2009), and JFT (Sun et al. 2017) with 18k classes and 303M high-resolution images. We de-duplicate the pre-training datasets w.r.t. the test sets of the downstream tasks following Kolesnikov et al. 2020. We transfer the models trained on these dataset to several benchmark tasks: ImageNet on the original validation labels and the cleaned-up ReaL labels (Beyer et al. 2020), CIFAR-10/100 (Krizhevsky 2009), Oxford-IIIT Pets (Parkhi et al. 2012), and Oxford Flowers-102 (Nilsback & Zisserman 2008). For these datasets, pre-processing follows Kolesnikov et al. 2020.
数据集。 为探索模型可扩展性,我们使用含 1k 类、1.3M 图像的 ILSVRC-2012 ImageNet 数据集(下文称为 ImageNet)、其超集 ImageNet-21k(21k 类、14M 图像) (Deng et al. 2009),以及含 18k 类、303M 高分辨率图像的 JFT (Sun et al. 2017)。我们按 Kolesnikov et al. 2020 相对下游任务测试集对预训练数据集去重。我们把在这些数据集上训练的模型迁移到若干基准任务:原始验证标签与清洗后 ReaL 标签上的 ImageNet (Beyer et al. 2020)、CIFAR-10/100 (Krizhevsky 2009)、Oxford-IIIT Pets (Parkhi et al. 2012)以及 Oxford Flowers-102 (Nilsback & Zisserman 2008)。对这些数据集,预处理遵循 Kolesnikov et al. 2020。
We also evaluate on the 19-task VTAB classification suite (Zhai et al. 2019b). VTAB evaluates low-data transfer to diverse tasks, using 1 000 training examples per task. The tasks are divided into three groups: Natural – tasks like the above, Pets, CIFAR, etc. Specialized – medical and satellite imagery, and Structured – tasks that require geometric understanding like localization.
我们还在含 19 个任务的 VTAB 分类套件上评估 (Zhai et al. 2019b)。VTAB 评估向多样任务的低数据迁移,每任务使用 1 000 个训练样本。任务分为三组:Natural——类似上述的 Pets、CIFAR 等任务;Specialized——医学与卫星影像;Structured——需要几何理解(如定位)的任务。
Model Variants. We base ViT configurations on those used for BERT (Devlin et al. 2019), as summarized in Table 1. The “Base” and “Large” models are directly adopted from BERT and we add the larger “Huge” model. In what follows we use brief notation to indicate the model size and the input patch size: for instance, ViT-L/16 means the “Large” variant with input patch size. Note that the Transformer’s sequence length is inversely proportional to the square of the patch size, thus models with smaller patch size are computationally more expensive.
模型变体。 我们以 BERT (Devlin et al. 2019)所用配置为基础设定 ViT,汇总于表 1。「Base」与「Large」模型直接取自 BERT,我们再加入更大的「Huge」模型。下文用简记表示模型规模与输入块尺寸:例如 ViT-L/16 表示带 输入块尺寸的「Large」变体。注意 Transformer 的序列长度与块尺寸的平方成反比,因此块更小的模型计算更昂贵。
For the baseline CNNs, we use ResNet (He et al. 2016), but replace the Batch Normalization layers (Ioffe & Szegedy 2015) with Group Normalization (Wu & He 2018), and used standardized convolutions (Qiao et al. 2019). These modifications improve transfer (Kolesnikov et al. 2020), and we denote the modified model “ResNet (BiT)”. For the hybrids, we feed the intermediate feature maps into ViT with patch size of one “pixel”. To experiment with different sequence lengths, we either (i) take the output of stage 4 of a regular ResNet50 or (ii) remove stage 4, place the same number of layers in stage 3 (keeping the total number of layers), and take the output of this extended stage 3. Option (ii) results in a 4x longer sequence length, and a more expensive ViT model.
对基线 CNN,我们使用 ResNet (He et al. 2016),但把批归一化层 (Ioffe & Szegedy 2015)替换为组归一化 (Wu & He 2018),并使用标准化卷积 (Qiao et al. 2019)。这些修改改善迁移 (Kolesnikov et al. 2020),我们把修改后的模型记为「ResNet(BiT)」。对混合模型,我们把中间特征图以「像素」块尺寸为一喂入 ViT。为试验不同序列长度,我们要么 (i) 取常规 ResNet50 第 4 阶段的输出,要么 (ii) 去掉第 4 阶段,把同等层数放进第 3 阶段(保持总层数),并取这一扩展第 3 阶段的输出。选项 (ii) 使序列长度长 4 倍,ViT 模型也更贵。
| Model | Layers | Hidden size | MLP size | Heads | Params |
|---|---|---|---|---|---|
| ViT-Base | 12 | 768 | 3072 | 12 | 86M |
| ViT-Large | 24 | 1024 | 4096 | 16 | 307M |
| ViT-Huge | 32 | 1280 | 5120 | 16 | 632M |
Table 1: Details of Vision Transformer model variants.
| 模型 | 层数 | 隐尺寸 | MLP 尺寸 | 头数 | 参数 |
|---|---|---|---|---|---|
| ViT-Base | 12 | 768 | 3072 | 12 | 86M |
| ViT-Large | 24 | 1024 | 4096 | 16 | 307M |
| ViT-Huge | 32 | 1280 | 5120 | 16 | 632M |
表 1:Vision Transformer 模型变体细节。
Training & Fine-tuning. We train all models, including ResNets, using Adam (Kingma & Ba 2015) with , , a batch size of 4096 and apply a high weight decay of , which we found to be useful for transfer of all models (Appendix D.1 shows that, in contrast to common practices, Adam works slightly better than SGD for ResNets in our setting). We use a linear learning rate warmup and decay, see Appendix B.1 for details. For fine-tuning we use SGD with momentum, batch size 512, for all models, see Appendix B.1.1. For ImageNet results in Table 2, we fine-tuned at higher resolution: for ViT-L/16 and for ViT-H/14, and also used Polyak & Juditsky 1992 averaging with a factor of (Ramachandran et al. 2019; Wang et al. 2020b).
训练与微调。 我们用 Adam (Kingma & Ba 2015)训练所有模型(含 ResNet),,,批量 4096,并施加较高的权重衰减 ——我们发现这对所有模型的迁移都有用(附录 D.1 表明,与常见做法相反,在我们的设定中 Adam 对 ResNet 略优于 SGD)。我们使用线性学习率预热与衰减,细节见附录 B.1。微调时对所有模型使用带动量的 SGD,批量 512,见附录 B.1.1。对表 2 中的 ImageNet 结果,我们以更高分辨率微调:ViT-L/16 为 ,ViT-H/14 为 ,并使用因子 的 Polyak & Juditsky 1992 平均 (Ramachandran et al. 2019;Wang et al. 2020b)。
Metrics. We report results on downstream datasets either through few-shot or fine-tuning accuracy. Fine-tuning accuracies capture the performance of each model after fine-tuning it on the respective dataset. Few-shot accuracies are obtained by solving a regularized least-squares regression problem that maps the (frozen) representation of a subset of training images to target vectors. This formulation allows us to recover the exact solution in closed form. Though we mainly focus on fine-tuning performance, we sometimes use linear few-shot accuracies for fast on-the-fly evaluation where fine-tuning would be too costly.
指标。 我们通过少样本或微调精度在下游数据集上报告结果。微调精度刻画各模型在相应数据集上微调后的表现。少样本精度通过求解正则化最小二乘回归得到:把训练图像子集的(冻结)表征映射到 目标向量。这一表述使我们能以闭式恢复精确解。尽管我们主要关注微调表现,有时也用线性少样本精度做快速即时评估——此时微调代价过高。
4.2 Comparison to State of the Art
4.2 与先进方法比较
We first compare our largest models – ViT-H/14 and ViT-L/16 – to state-of-the-art CNNs from the literature. The first comparison point is Big Transfer (BiT) (Kolesnikov et al. 2020), which performs supervised transfer learning with large ResNets. The second is Noisy Student (Xie et al. 2020), which is a large EfficientNet trained using semi-supervised learning on ImageNet and JFT-300M with the labels removed. Currently, Noisy Student is the state of the art on ImageNet and BiT-L on the other datasets reported here. All models were trained on TPUv3 hardware, and we report the number of TPUv3-core-days taken to pre-train each of them, that is, the number of TPU v3 cores (2 per chip) used for training multiplied by the training time in days.
我们首先把最大模型——ViT-H/14 与 ViT-L/16——与文献中的先进 CNN 比较。第一个对照点是 Big Transfer(BiT) (Kolesnikov et al. 2020),它用大型 ResNet 做监督迁移学习。第二个是 Noisy Student (Xie et al. 2020),这是一个在 ImageNet 与去掉标签的 JFT-300M 上用半监督学习训练的大型 EfficientNet。当前 Noisy Student 是 ImageNet 上的先进水平,BiT-L 是此处报告的其他数据集上的先进水平。所有模型都在 TPUv3 硬件上训练,我们报告预训练各模型所用的 TPUv3-core-days,即训练所用 TPU v3 核数(每芯片 2 核)乘以训练天数。
| Ours-JFT | Ours-JFT | Ours-I21k | BiT-L | Noisy Student | |
|---|---|---|---|---|---|
| (ViT-H/14) | (ViT-L/16) | (ViT-L/16) | (ResNet152x4) | (EfficientNet-L2) | |
| ImageNet | |||||
| ImageNet ReaL | |||||
| CIFAR-10 | |||||
| CIFAR-100 | |||||
| Oxford-IIIT Pets | |||||
| Oxford Flowers-102 | |||||
| VTAB (19 tasks) | |||||
| TPUv3-core-days | k | k | k | k | k |
Table 2: Comparison with state of the art on popular image classification benchmarks. We report mean and standard deviation of the accuracies, averaged over three fine-tuning runs. Vision Transformer models pre-trained on the JFT-300M dataset outperform ResNet-based baselines on all datasets, while taking substantially less computational resources to pre-train. ViT pre-trained on the smaller public ImageNet-21k dataset performs well too. ∗Slightly improved result reported in Touvron et al. 2020.
| 本文-JFT | 本文-JFT | 本文-I21k | BiT-L | Noisy Student | |
|---|---|---|---|---|---|
| (ViT-H/14) | (ViT-L/16) | (ViT-L/16) | (ResNet152x4) | (EfficientNet-L2) | |
| ImageNet | |||||
| ImageNet ReaL | |||||
| CIFAR-10 | |||||
| CIFAR-100 | |||||
| Oxford-IIIT Pets | |||||
| Oxford Flowers-102 | |||||
| VTAB (19 tasks) | |||||
| TPUv3-core-days | k | k | k | k | k |
表 2:在流行图像分类基准上与先进方法比较。我们报告三次微调运行的精度均值与标准差。在 JFT-300M 数据集上预训练的 Vision Transformer 模型在所有数据集上超过基于 ResNet 的基线,同时预训练计算资源显著更少。在较小的公开 ImageNet-21k 数据集上预训练的 ViT 也表现良好。∗Touvron et al. 2020 报告的略有改善的 结果。
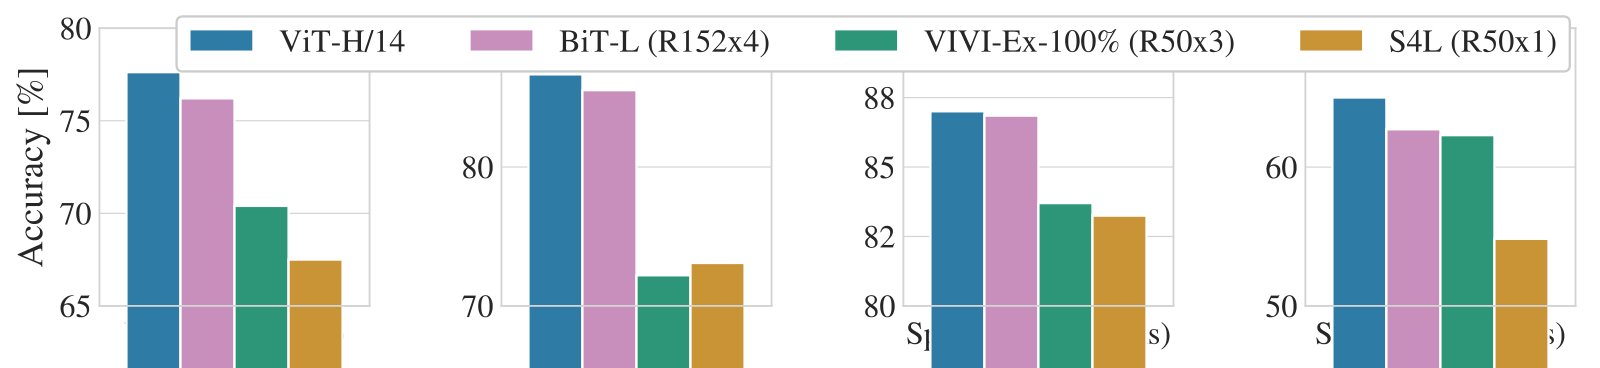
Figure 2: Breakdown of VTAB performance in Natural, Specialized, and Structured task groups.
图 2:VTAB 在 Natural、Specialized 与 Structured 任务组上的表现分解。
Table 2 shows the results. The smaller ViT-L/16 model pre-trained on JFT-300M outperforms BiT-L (which is pre-trained on the same dataset) on all tasks, while requiring substantially less computational resources to train. The larger model, ViT-H/14, further improves the performance, especially on the more challenging datasets – ImageNet, CIFAR-100, and the VTAB suite. Interestingly, this model still took substantially less compute to pre-train than prior state of the art. However, we note that pre-training efficiency may be affected not only by the architecture choice, but also other parameters, such as training schedule, optimizer, weight decay, etc. We provide a controlled study of performance vs. compute for different architectures in Section 4.4. Finally, the ViT-L/16 model pre-trained on the public ImageNet-21k dataset performs well on most datasets too, while taking fewer resources to pre-train: it could be trained using a standard cloud TPUv3 with 8 cores in approximately 30 days.
表 2 给出结果。在 JFT-300M 上预训练的较小 ViT-L/16 模型在所有任务上超过 BiT-L(在同一数据集上预训练),同时训练所需计算资源显著更少。更大的模型 ViT-H/14 进一步提升表现,尤其在更具挑战的数据集——ImageNet、CIFAR-100 与 VTAB 套件——上。有趣的是,该模型预训练所需计算仍显著少于此前先进方法。但我们指出,预训练效率可能不仅受架构选择影响,也受训练日程、优化器、权重衰减等其他参数影响。第 4.4 节给出不同架构表现对计算的受控研究。最后,在公开 ImageNet-21k 数据集上预训练的 ViT-L/16 在多数数据集上也表现良好,且预训练资源更少:大约可用带 8 核的标准云 TPUv3 训练约 30 天。
Figure 2 decomposes the VTAB tasks into their respective groups, and compares to previous SOTA methods on this benchmark: BiT, VIVI – a ResNet co-trained on ImageNet and Youtube (Tschannen et al. 2020), and S4L – supervised plus semi-supervised learning on ImageNet (Zhai et al. 2019a). ViT-H/14 outperforms BiT-R152x4, and other methods, on the Natural and Structured tasks. On the Specialized the performance of the top two models is similar.
图 2 把 VTAB 任务分解到各自组别,并与该基准上此前 SOTA 方法比较:BiT、VIVI——在 ImageNet 与 Youtube 上共训的 ResNet (Tschannen et al. 2020),以及 S4L——ImageNet 上的监督加半监督学习 (Zhai et al. 2019a)。ViT-H/14 在 Natural 与 Structured 任务上超过 BiT-R152x4 及其他方法。在 Specialized 上,前两名模型表现相近。
4.3 Pre-training Data Requirements
4.3 预训练数据需求
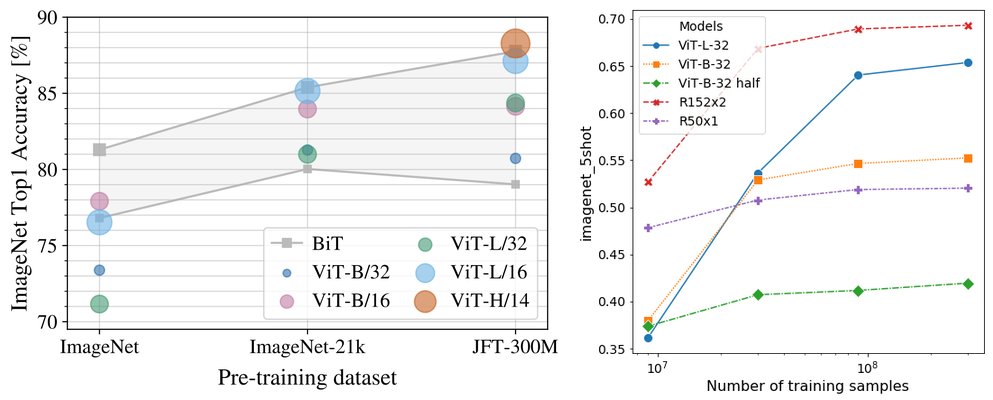
Figure 3: Transfer to ImageNet. While large ViT models perform worse than BiT ResNets (shaded area) when pre-trained on small datasets, they shine when pre-trained on larger datasets. Similarly, larger ViT variants overtake smaller ones as the dataset grows.
图 3:迁移到 ImageNet。当在小数据集上预训练时,大型 ViT 模型表现弱于 BiT ResNet(阴影区域);当在更大数据集上预训练时,它们大放异彩。类似地,随数据集增大,更大的 ViT 变体超过较小变体。
The Vision Transformer performs well when pre-trained on a large JFT-300M dataset. With fewer inductive biases for vision than ResNets, how crucial is the dataset size? We perform two series of experiments.
Vision Transformer 在大规模 JFT-300M 数据集上预训练时表现良好。相对 ResNet,它对视觉的归纳偏置更少,数据集规模有多关键?我们做两组实验。
First, we pre-train ViT models on datasets of increasing size: ImageNet, ImageNet-21k, and JFT-300M. To boost the performance on the smaller datasets, we optimize three basic regularization parameters – weight decay, dropout, and label smoothing. Figure 4 shows the results after fine-tuning to ImageNet (results on other datasets are shown in Table 5)[^2]. When pre-trained on the smallest dataset, ImageNet, ViT-Large models underperform compared to ViT-Base models, despite (moderate) regularization. With ImageNet-21k pre-training, their performances are similar. Only with JFT-300M, do we see the full benefit of larger models. Figure 4 also shows the performance region spanned by BiT models of different sizes. The BiT CNNs outperform ViT on ImageNet, but with the larger datasets, ViT overtakes.
首先,我们在规模递增的数据集上预训练 ViT 模型:ImageNet、ImageNet-21k 与 JFT-300M。为提升在较小数据集上的表现,我们优化三个基本正则参数——权重衰减、dropout 与标签平滑。图 4 给出微调到 ImageNet 后的结果(其他数据集结果见表 5)[^2]。当在最小数据集 ImageNet 上预训练时,尽管有(适度)正则,ViT-Large 模型仍弱于 ViT-Base 模型。用 ImageNet-21k 预训练时,二者表现相近。只有用 JFT-300M,我们才看到更大模型的全部收益。图 4 还给出不同规模 BiT 模型覆盖的表现区域。BiT CNN 在 ImageNet 上超过 ViT,但在更大数据集上 ViT 反超。
Second, we train our models on random subsets of 9M, 30M, and 90M as well as the full JFT-300M dataset. We do not perform additional regularization on the smaller subsets and use the same hyper-parameters for all settings. This way, we assess the intrinsic model properties, and not the effect of regularization. We do, however, use early-stopping, and report the best validation accuracy achieved during training. To save compute, we report few-shot linear accuracy instead of full fine-tuning accuracy. Figure 4 contains the results. Vision Transformers overfit more than ResNets with comparable computational cost on smaller datasets. For example, ViT-B/32 is slightly faster than ResNet50; it performs much worse on the 9M subset, but better on 90M+ subsets. The same is true for ResNet152x2 and ViT-L/16. This result reinforces the intuition that the convolutional inductive bias is useful for smaller datasets, but for larger ones, learning the relevant patterns directly from data is sufficient, even beneficial.
其次,我们在 JFT-300M 的随机子集 9M、30M、90M 以及全集上训练模型。我们不在较小子集上做额外正则,并对所有设定使用相同超参数。这样评估的是内在模型属性,而非正则效应。但我们使用早停,并报告训练期间达到的最佳验证精度。为节省计算,我们报告少样本线性精度而非完整微调精度。图 4 含结果。在较小数据集上,计算代价可比的情形下,Vision Transformer 比 ResNet 更容易过拟合。例如,ViT-B/32 略快于 ResNet50;它在 9M 子集上差很多,但在 90M+ 子集上更好。ResNet152x2 与 ViT-L/16 也是如此。这一结果强化了直觉:卷积归纳偏置对较小数据集有用,但对较大数据集,直接从数据学习相关模式已足够,甚至更有益。
Overall, the few-shot results on ImageNet (Figure 4), as well as the low-data results on VTAB (Table 2) seem promising for very low-data transfer. Further analysis of few-shot properties of ViT is an exciting direction of future work.
总体而言,ImageNet 上的少样本结果(图 4)以及 VTAB 上的低数据结果(表 2)对极低数据迁移显得有希望。进一步分析 ViT 的少样本性质是令人兴奋的未来工作方向。
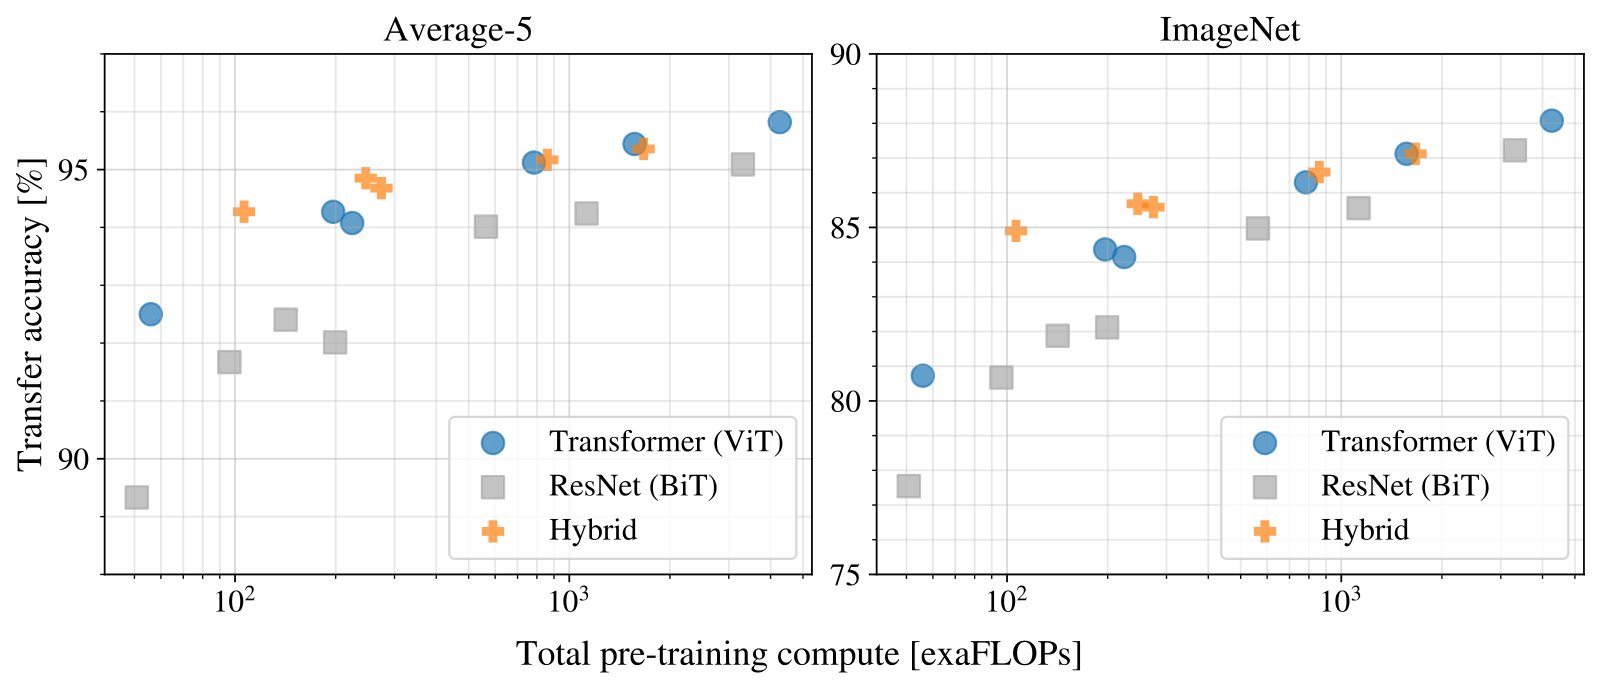
Figure 5: Performance versus pre-training compute for different architectures: Vision Transformers, ResNets, and hybrids. Vision Transformers generally outperform ResNets with the same computational budget. Hybrids improve upon pure Transformers for smaller model sizes, but the gap vanishes for larger models.
图 5:不同架构的表现对预训练计算:Vision Transformer、ResNet 与混合模型。在相同计算预算下,Vision Transformer 通常超过 ResNet。混合模型在较小模型规模上改进纯 Transformer,但差距在较大模型上消失。
4.4 Scaling Study
4.4 扩展研究
We perform a controlled scaling study of different models by evaluating transfer performance from JFT-300M. In this setting data size does not bottleneck the models’ performances, and we assess performance versus pre-training cost of each model. The model set includes: 7 ResNets, R50x1, R50x2 R101x1, R152x1, R152x2, pre-trained for 7 epochs, plus R152x2 and R200x3 pre-trained for 14 epochs; 6 Vision Transformers, ViT-B/32, B/16, L/32, L/16, pre-trained for 7 epochs, plus L/16 and H/14 pre-trained for 14 epochs; and 5 hybrids, R50+ViT-B/32, B/16, L/32, L/16 pre-trained for 7 epochs, plus R50+ViT-L/16 pre-trained for 14 epochs (for hybrids, the number at the end of the model name stands not for the patch size, but for the total dowsampling ratio in the ResNet backbone).
我们通过评估从 JFT-300M 出发的迁移表现,对不同模型做受控扩展研究。在这一设定中数据规模不构成模型表现瓶颈,我们评估各模型表现对预训练代价。模型集合包括:7 个 ResNet——R50x1、R50x2、R101x1、R152x1、R152x2(预训练 7 个 epoch),外加预训练 14 个 epoch 的 R152x2 与 R200x3;6 个 Vision Transformer——ViT-B/32、B/16、L/32、L/16(预训练 7 个 epoch),外加预训练 14 个 epoch 的 L/16 与 H/14;以及 5 个混合模型——R50+ViT-B/32、B/16、L/32、L/16(预训练 7 个 epoch),外加预训练 14 个 epoch 的 R50+ViT-L/16(对混合模型,名称末尾数字不表示块尺寸,而表示 ResNet 骨干中的总下采样比)。
Figure 5 contains the transfer performance versus total pre-training compute (see Appendix D.5 for details on computational costs). Detailed results per model are provided in Table 6 in the Appendix. A few patterns can be observed. First, Vision Transformers dominate ResNets on the performance/compute trade-off. ViT uses approximately less compute to attain the same performance (average over 5 datasets). Second, hybrids slightly outperform ViT at small computational budgets, but the difference vanishes for larger models. This result is somewhat surprising, since one might expect convolutional local feature processing to assist ViT at any size. Third, Vision Transformers appear not to saturate within the range tried, motivating future scaling efforts.
图 5 给出迁移表现对总预训练计算(计算代价细节见附录 D.5)。各模型详细结果见附录表 6。可观察到若干模式。第一,在表现/计算权衡上,Vision Transformer 主导 ResNet。ViT 大约用 更少计算达到相同表现(5 个数据集平均)。第二,混合模型在小计算预算上略优于 ViT,但对更大模型差距消失。这一结果有些出人意料,因为人们可能期望卷积局部特征处理在任意规模上都能帮助 ViT。第三,在所尝试范围内 Vision Transformer 似乎未饱和,这激励未来的扩展努力。
4.5 Inspecting Vision Transformer
4.5 审视 Vision Transformer
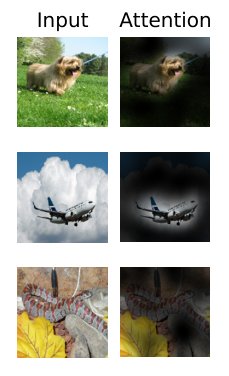
Figure 6: Representative examples of attention from the output token to the input space. See Appendix D.7 for details.
图 6:从输出记号到输入空间的注意力代表性例子。细节见附录 D.7。
To begin to understand how the Vision Transformer processes image data, we analyze its internal representations. The first layer of the Vision Transformer linearly projects the flattened patches into a lower-dimensional space (Eq. 1). Figure 7 (left) shows the top principal components of the the learned embedding filters. The components resemble plausible basis functions for a low-dimensional representation of the fine structure within each patch.
为开始理解 Vision Transformer 如何处理图像数据,我们分析其内部表征。Vision Transformer 的第一层把展平块线性投影到较低维空间(式 1)。图 7(左)展示所学嵌入滤波器的顶部主成分。这些分量类似每个块内精细结构的低维表示的合理基函数。
After the projection, a learned position embedding is added to the patch representations. Figure 7 (center) shows that the model learns to encode distance within the image in the similarity of position embeddings, i.e. closer patches tend to have more similar position embeddings. Further, the row-column structure appears; patches in the same row/column have similar embeddings. Finally, a sinusoidal structure is sometimes apparent for larger grids (Appendix D). That the position embeddings learn to represent 2D image topology explains why hand-crafted 2D-aware embedding variants do not yield improvements (Appendix D.4).
投影之后,把学到的位置嵌入加到块表征上。图 7(中)表明模型学会在位置嵌入的相似度中编码图像内距离,即更近的块往往有更相似的位置嵌入。此外,行列结构出现;同一行/列中的块有相似嵌入。最后,对更大网格有时可见正弦结构(附录 D)。位置嵌入学会表示二维图像拓扑,这解释了为何手工设计的二维感知嵌入变体不带来改进(附录 D.4)。
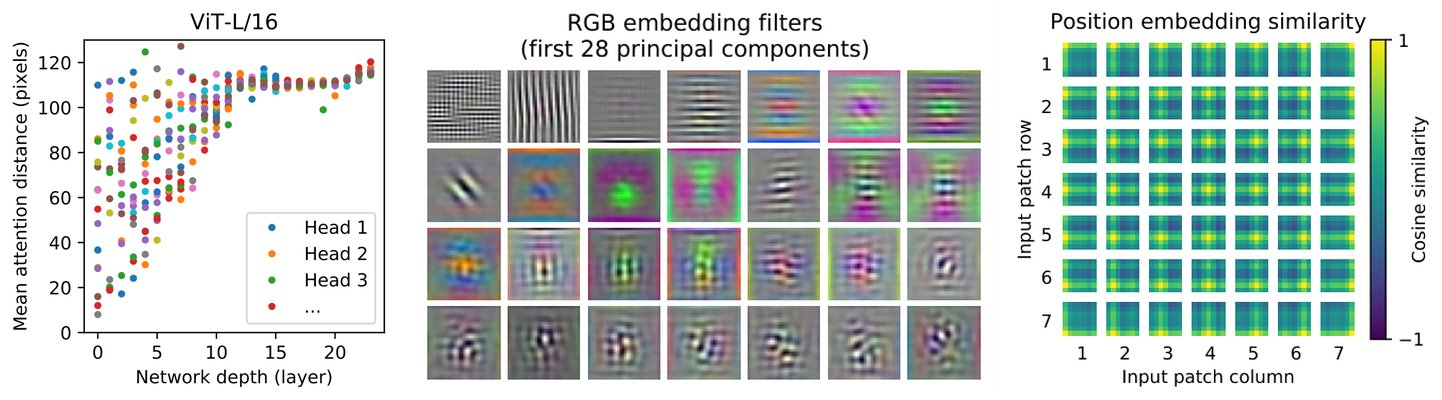
Figure 7: Left: Filters of the initial linear embedding of RGB values of ViT-L/32. Center: Similarity of position embeddings of ViT-L/32. Tiles show the cosine similarity between the position embedding of the patch with the indicated row and column and the position embeddings of all other patches. Right: Size of attended area by head and network depth. Each dot shows the mean attention distance across images for one of 16 heads at one layer. See Appendix D.7 for details.
图 7:左: ViT-L/32 对 RGB 值初始线性嵌入的滤波器。中: ViT-L/32 位置嵌入的相似度。各瓦片展示所指行列块的位置嵌入与所有其他块位置嵌入之间的余弦相似度。右: 按头与网络深度的注意力区域大小。每个点表示某一层 16 个头之一跨图像的平均注意力距离。细节见附录 D.7。
Self-attention allows ViT to integrate information across the entire image even in the lowest layers. We investigate to what degree the network makes use of this capability. Specifically, we compute the average distance in image space across which information is integrated, based on the attention weights (Figure 7, right). This “attention distance” is analogous to receptive field size in CNNs. We find that some heads attend to most of the image already in the lowest layers, showing that the ability to integrate information globally is indeed used by the model. Other attention heads have consistently small attention distances in the low layers. This highly localized attention is less pronounced in hybrid models that apply a ResNet before the Transformer (Figure 7, right), suggesting that it may serve a similar function as early convolutional layers in CNNs. Further, the attention distance increases with network depth. Globally, we find that the model attends to image regions that are semantically relevant for classification (Figure 6).
自注意力使 ViT 即使在最低层也能跨整幅图像整合信息。我们考察网络在多大程度上利用这一能力。具体地,我们基于注意力权重计算信息被整合所跨越的图像空间平均距离(图 7,右)。这一「注意力距离」类似于 CNN 中的感受野大小。我们发现:某些头在最低层就已关注图像的大部分,表明模型确实使用了全局整合信息的能力。其他注意力头在低层始终保持较小的注意力距离。这种高度局部的注意力在先施加 ResNet 再接 Transformer 的混合模型中不那么显著(图 7,右),表明它可能服务与 CNN 早期卷积层类似的功能。此外,注意力距离随网络深度增加。全局来看,我们发现模型关注对分类语义相关的图像区域(图 6)。
4.6 Self-supervision
4.6 自监督
Transformers show impressive performance on NLP tasks. However, much of their success stems not only from their excellent scalability but also from large scale self-supervised pre-training (Devlin et al. 2019; Radford et al. 2018). We also perform a preliminary exploration on masked patch prediction for self-supervision, mimicking the masked language modeling task used in BERT. With self-supervised pre-training, our smaller ViT-B/16 model achieves 79.9% accuracy on ImageNet, a significant improvement of 2% to training from scratch, but still 4% behind supervised pre-training. Appendix B.1.2 contains further details. We leave exploration of contrastive pre-training (Chen et al. 2020b; He et al. 2020; Bachman et al. 2019; Hénaff et al. 2020) to future work.
Transformer 在 NLP 任务上表现出色。但其成功很大程度上不仅来自优异的可扩展性,也来自大规模自监督预训练(Devlin et al. 2019;Radford et al. 2018)。我们也对自监督的掩蔽块预测做了初步探索,模仿 BERT 使用的掩蔽语言建模任务。借助自监督预训练,我们较小的 ViT-B/16 模型在 ImageNet 上达到 79.9% 精度,相对从零训练显著提升 2%,但仍落后监督预训练 4%。进一步细节见附录 B.1.2。对比预训练的探索(Chen et al. 2020b;He et al. 2020;Bachman et al. 2019;Hénaff et al. 2020)留作未来工作。
5 Conclusion
5 结论
We have explored the direct application of Transformers to image recognition. Unlike prior works using self-attention in computer vision, we do not introduce image-specific inductive biases into the architecture apart from the initial patch extraction step. Instead, we interpret an image as a sequence of patches and process it by a standard Transformer encoder as used in NLP. This simple, yet scalable, strategy works surprisingly well when coupled with pre-training on large datasets. Thus, Vision Transformer matches or exceeds the state of the art on many image classification datasets, whilst being relatively cheap to pre-train.
我们探索了把 Transformer 直接应用于图像识别。与先前在计算机视觉中使用自注意力的工作不同,除初始块提取步骤外,我们不向架构引入图像特定归纳偏置。相反,我们把图像解释为块序列,并用 NLP 中使用的标准 Transformer 编码器处理它。这一简单却可扩展的策略在与大规模数据集预训练结合时出人意料地有效。因此,Vision Transformer 在许多图像分类数据集上达到或超过先进水平,同时预训练相对便宜。
While these initial results are encouraging, many challenges remain. One is to apply ViT to other computer vision tasks, such as detection and segmentation. Our results, coupled with those in Carion et al. 2020, indicate the promise of this approach. Another challenge is to continue exploring self-supervised pre-training methods. Our initial experiments show improvement from self-supervised pre-training, but there is still large gap between self-supervised and large-scale supervised pre-training. Finally, further scaling of ViT would likely lead to improved performance.
尽管这些初步结果令人鼓舞,仍有许多挑战。其一是把 ViT 应用于其他计算机视觉任务,如检测与分割。我们的结果与 Carion et al. 2020 的结果一起,表明这一路线有希望。另一挑战是继续探索自监督预训练方法。我们的初步实验显示自监督预训练有改进,但自监督与大规模监督预训练之间仍有较大差距。最后,进一步扩展 ViT 很可能带来更好表现。
Acknowledgements
致谢
The work was performed in Berlin, Zürich, and Amsterdam. We thank many colleagues at Google for their help, in particular Andreas Steiner for crucial help with the infrastructure and the open-source release of the code; Joan Puigcerver and Maxim Neumann for help with the large-scale training infrastructure; Dmitry Lepikhin, Aravindh Mahendran, Daniel Keysers, Mario Lučić, Noam Shazeer, Ashish Vaswani, and Colin Raffel for useful discussions.
本工作在柏林、苏黎世与阿姆斯特丹完成。我们感谢 Google 许多同事的帮助,尤其是 Andreas Steiner 在基础设施与代码开源发布上的关键帮助;Joan Puigcerver 与 Maxim Neumann 在大规模训练基础设施上的帮助;Dmitry Lepikhin、Aravindh Mahendran、Daniel Keysers、Mario Lučić、Noam Shazeer、Ashish Vaswani 与 Colin Raffel 的有益讨论。
References
参考文献
Abnar & Zuidema (2020) Samira Abnar and Willem Zuidema. Quantifying attention flow in transformers. In ACL , 2020.
Bachman et al. (2019) Philip Bachman, R Devon Hjelm, and William Buchwalter. Learning representations by maximizing mutual information across views. In NeurIPS , 2019.
Baevski & Auli (2019) Alexei Baevski and Michael Auli. Adaptive input representations for neural language modeling. In ICLR , 2019.
Bello et al. (2019) I. Bello, B. Zoph, Q. Le, A. Vaswani, and J. Shlens. Attention augmented convolutional networks. In ICCV , 2019.
Beyer et al. (2020) Lucas Beyer, Olivier J. Hénaff, Alexander Kolesnikov, Xiaohua Zhai, and Aäron van den Oord. Are we done with imagenet? arXiv , 2020.
Brown et al. (2020) Tom B Brown, Benjamin Mann, Nick Ryder, Melanie Subbiah, Jared Kaplan, Prafulla Dhariwal, Arvind Neelakantan, Pranav Shyam, Girish Sastry, Amanda Askell, et al. Language models are few-shot learners. arXiv , 2020.
Carion et al. (2020) Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, and Sergey Zagoruyko. End-to-end object detection with transformers. In ECCV , 2020.
Chen et al. (2020a) Mark Chen, Alec Radford, Rewon Child, Jeff Wu, and Heewoo Jun. Generative pretraining from pixels. In ICML , 2020a.
Chen et al. (2020b) Ting Chen, Simon Kornblith, Mohammad Norouzi, and Geoffrey E. Hinton. A simple framework for contrastive learning of visual representations. In ICML , 2020b.
Chen et al. (2020c) Yen-Chun Chen, Linjie Li, Licheng Yu, Ahmed El Kholy, Faisal Ahmed, Zhe Gan, Yu Cheng, and Jingjing Liu. UNITER: UNiversal Image-TExt Representation Learning. In ECCV , 2020c.
Child et al. (2019) Rewon Child, Scott Gray, Alec Radford, and Ilya Sutskever. Generating long sequences with sparse transformers. arXiv , 2019.
Cordonnier et al. (2020) Jean-Baptiste Cordonnier, Andreas Loukas, and Martin Jaggi. On the relationship between self-attention and convolutional layers. In ICLR , 2020.
Deng et al. (2009) J. Deng, W. Dong, R. Socher, L. Li, Kai Li, and Li Fei-Fei. Imagenet: A large-scale hierarchical image database. In CVPR , 2009.
Devlin et al. (2019) Jacob Devlin, Ming-Wei Chang, Kenton Lee, and Kristina Toutanova. BERT: Pre-training of deep bidirectional transformers for language understanding. In NAACL , 2019.
Djolonga et al. (2020) Josip Djolonga, Jessica Yung, Michael Tschannen, Rob Romijnders, Lucas Beyer, Alexander Kolesnikov, Joan Puigcerver, Matthias Minderer, Alexander D’Amour, Dan Moldovan, Sylvan Gelly, Neil Houlsby, Xiaohua Zhai, and Mario Lucic. On robustness and transferability of convolutional neural networks. arXiv , 2020.
He et al. (2016) Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recognition. In CVPR , 2016.
He et al. (2020) Kaiming He, Haoqi Fan, Yuxin Wu, Saining Xie, and Ross Girshick. Momentum contrast for unsupervised visual representation learning. In CVPR , 2020.
Ho et al. (2019) Jonathan Ho, Nal Kalchbrenner, Dirk Weissenborn, and Tim Salimans. Axial attention in multidimensional transformers. arXiv , 2019.
Hu et al. (2018) Han Hu, Jiayuan Gu, Zheng Zhang, Jifeng Dai, and Yichen Wei. Relation networks for object detection. In CVPR , 2018.
Hu et al. (2019) Han Hu, Zheng Zhang, Zhenda Xie, and Stephen Lin. Local relation networks for image recognition. In ICCV , 2019.
Huang et al. (2020) Zilong Huang, Xinggang Wang, Yunchao Wei, Lichao Huang, Humphrey Shi, Wenyu Liu, and Thomas S. Huang. Ccnet: Criss-cross attention for semantic segmentation. In ICCV , 2020.
Hénaff et al. (2020) Olivier J. Hénaff, Aravind Srinivas, Jeffrey De Fauw, Ali Razavi, Carl Doersch, S. M. Ali Eslami, and Aaron van den Oord. Data-efficient image recognition with contrastive predictive coding. In ICML , 2020.
Ioffe & Szegedy (2015) Sergey Ioffe and Christian Szegedy. Batch normalization: Accelerating deep network training by reducing internal covariate shift. 2015.
Kingma & Ba (2015) Diederik P. Kingma and Jimmy Ba. Adam: A method for stochastic optimization. In ICLR , 2015.
Kolesnikov et al. (2020) Alexander Kolesnikov, Lucas Beyer, Xiaohua Zhai, Joan Puigcerver, Jessica Yung, Sylvain Gelly, and Neil Houlsby. Big transfer (BiT): General visual representation learning. In ECCV , 2020.
Krizhevsky (2009) Alex Krizhevsky. Learning multiple layers of features from tiny images. Technical report, 2009.
Krizhevsky et al. (2012) Alex Krizhevsky, Ilya Sutskever, and Geoffrey E. Hinton. Imagenet classification with deep convolutional neural networks. In NIPS , 2012.
LeCun et al. (1989) Y. LeCun, B. Boser, J. Denker, D. Henderson, R. Howard, W. Hubbard, and L. Jackel. Backpropagation applied to handwritten zip code recognition. Neural Computation , 1:541–551, 1989.
Lepikhin et al. (2020) Dmitry Lepikhin, HyoukJoong Lee, Yuanzhong Xu, Dehao Chen, Orhan Firat, Yanping Huang, Maxim Krikun, Noam Shazeer, and Zhifeng Chen. Gshard: Scaling giant models with conditional computation and automatic sharding. arXiv , 2020.
Li et al. (2019) Liunian Harold Li, Mark Yatskar, Da Yin, Cho-Jui Hsieh, and Kai-Wei Chang. VisualBERT: A Simple and Performant Baseline for Vision and Language. In Arxiv , 2019.
Locatello et al. (2020) Francesco Locatello, Dirk Weissenborn, Thomas Unterthiner, Aravindh Mahendran, Georg Heigold, Jakob Uszkoreit, Alexey Dosovitskiy, and Thomas Kipf. Object-centric learning with slot attention. arXiv , 2020.
Lu et al. (2019) Jiasen Lu, Dhruv Batra, Devi Parikh, and Stefan Lee. ViLBERT: Pretraining Task-Agnostic Visiolinguistic Representations for Vision-and-Language Tasks. In NeurIPS . 2019.
Mahajan et al. (2018) Dhruv Mahajan, Ross Girshick, Vignesh Ramanathan, Kaiming He, Manohar Paluri, Yixuan Li, Ashwin Bharambe, and Laurens van der Maaten. Exploring the limits of weakly supervised pretraining. In ECCV , 2018.
Nilsback & Zisserman (2008) M. Nilsback and A. Zisserman. Automated flower classification over a large number of classes. In ICVGIP , 2008.
Parkhi et al. (2012) Omkar M. Parkhi, Andrea Vedaldi, Andrew Zisserman, and C. V. Jawahar. Cats and dogs. In CVPR , 2012.
Parmar et al. (2018) Niki Parmar, Ashish Vaswani, Jakob Uszkoreit, Lukasz Kaiser, Noam Shazeer, Alexander Ku, and Dustin Tran. Image transformer. In ICML , 2018.
Polyak & Juditsky (1992) B. T. Polyak and A. B. Juditsky. Acceleration of stochastic approximation by averaging. SIAM Journal on Control and Optimization , 30(4):838–855, 1992. doi: 10.1137/0330046 . URL https://doi.org/10.1137/0330046 .
Qiao et al. (2019) Siyuan Qiao, Huiyu Wang, Chenxi Liu, Wei Shen, and Alan Yuille. Weight standardization. arXiv preprint arXiv:1903.10520 , 2019.
Radford et al. (2018) Alec Radford, Karthik Narasimhan, Tim Salimans, and Ilya Sutskever. Improving language understanding with unsupervised learning. Technical Report , 2018.
Radford et al. (2019) Alec Radford, Jeff Wu, Rewon Child, David Luan, Dario Amodei, and Ilya Sutskever. Language models are unsupervised multitask learners. Technical Report , 2019.
Ramachandran et al. (2019) Prajit Ramachandran, Niki Parmar, Ashish Vaswani, Irwan Bello, Anselm Levskaya, and Jon Shlens. Stand-alone self-attention in vision models. In NeurIPS , 2019.
Sun et al. (2017) Chen Sun, Abhinav Shrivastava, Saurabh Singh, and Abhinav Gupta. Revisiting unreasonable effectiveness of data in deep learning era. In ICCV , 2017.
Sun et al. (2019) Chen Sun, Austin Myers, Carl Vondrick, Kevin Murphy, and Cordelia Schmid. Videobert: A joint model for video and language representation learning. In ICCV , 2019.
Touvron et al. (2019) Hugo Touvron, Andrea Vedaldi, Matthijs Douze, and Herve Jegou. Fixing the train-test resolution discrepancy. In NeurIPS . 2019.
Touvron et al. (2020) Hugo Touvron, Andrea Vedaldi, Matthijs Douze, and Herve Jegou. Fixing the train-test resolution discrepancy: Fixefficientnet. arXiv preprint arXiv:2003.08237 , 2020.
Tschannen et al. (2020) Michael Tschannen, Josip Djolonga, Marvin Ritter, Aravindh Mahendran, Neil Houlsby, Sylvain Gelly, and Mario Lucic. Self-supervised learning of video-induced visual invariances. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) , June 2020.
Vaswani et al. (2017) Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Łukasz Kaiser, and Illia Polosukhin. Attention is all you need. In NIPS , 2017.
Wang et al. (2020a) Huiyu Wang, Yukun Zhu, Bradley Green, Hartwig Adam, Alan Yuille, and Liang-Chieh Chen. Axial-deeplab: Stand-alone axial-attention for panoptic segmentation. In ECCV , 2020a.
Wang et al. (2020b) Huiyu Wang, Yukun Zhu, Bradley Green, Hartwig Adam, Alan Yuille, and Liang-Chieh Chen. Axial-deeplab: Stand-alone axial-attention for panoptic segmentation. arXiv preprint arXiv:2003.07853 , 2020b.
Wang et al. (2019) Qiang Wang, Bei Li, Tong Xiao, Jingbo Zhu, Changliang Li, Derek F. Wong, and Lidia S. Chao. Learning deep transformer models for machine translation. In ACL , 2019.
Wang et al. (2018) Xiaolong Wang, Ross Girshick, Abhinav Gupta, and Kaiming He. Non-local neural networks. In CVPR , 2018.
Weissenborn et al. (2019) Dirk Weissenborn, Oscar Täckström, and Jakob Uszkoreit. Scaling autoregressive video models. In ICLR , 2019.
Wu et al. (2020) Bichen Wu, Chenfeng Xu, Xiaoliang Dai, Alvin Wan, Peizhao Zhang, Masayoshi Tomizuka, Kurt Keutzer, and Peter Vajda. Visual transformers: Token-based image representation and processing for computer vision. arxiv , 2020.
Wu & He (2018) Yuxin Wu and Kaiming He. Group normalization. In ECCV , 2018.
Xie et al. (2020) Qizhe Xie, Minh-Thang Luong, Eduard Hovy, and Quoc V. Le. Self-training with noisy student improves imagenet classification. In CVPR , 2020.
Zhai et al. (2019a) Xiaohua Zhai, Avital Oliver, Alexander Kolesnikov, and Lucas Beyer. S 4 L: Self-Supervised Semi-Supervised Learning. In ICCV , 2019a.
Zhai et al. (2019b) Xiaohua Zhai, Joan Puigcerver, Alexander Kolesnikov, Pierre Ruyssen, Carlos Riquelme, Mario Lucic, Josip Djolonga, Andre Susano Pinto, Maxim Neumann, Alexey Dosovitskiy, et al. A large-scale study of representation learning with the visual task adaptation benchmark. arXiv preprint arXiv:1910.04867 , 2019b.
Zhao et al. (2020) Hengshuang Zhao, Jiaya Jia, and Vladlen Koltun. Exploring self-attention for image recognition. In CVPR , 2020.
Appendix
附录
Appendix A Multihead Self-attention
附录 A 多头自注意力
Standard self-attention (SA, Vaswani et al. 2017) is a popular building block for neural architectures. For each element in an input sequence , we compute a weighted sum over all values in the sequence. The attention weights are based on the pairwise similarity between two elements of the sequence and their respective query and key representations.
标准 自注意力(SA,Vaswani et al. 2017)是神经网络架构的流行积木。对输入序列 中的每个元素,我们计算序列中所有值 的加权和。注意力权重 基于序列中两个元素及其各自查询 与键 表征之间的成对相似度。
Multihead self-attention (MSA) is an extension of SA in which we run self-attention operations, called “heads”, in parallel, and project their concatenated outputs. To keep compute and number of parameters constant when changing , (Eq. 5) is typically set to .
多头自注意力(MSA)是 SA 的扩展:我们并行运行 个称为「头」的自注意力运算,并投影其拼接输出。为在改变 时保持计算与参数量恒定,(式 5)通常设为 。
Appendix B Experiment details
附录 B 实验细节
B.1 Training
B.1 训练
| Models | Dataset | Epochs | Base LR | LR decay | Weight decay | Dropout |
|---|---|---|---|---|---|---|
| ViT-B/{16,32} | JFT-300M | 7 | linear | 0.1 | 0.0 | |
| ViT-L/32 | JFT-300M | 7 | linear | 0.1 | 0.0 | |
| ViT-L/16 | JFT-300M | 7/14 | linear | 0.1 | 0.0 | |
| ViT-H/14 | JFT-300M | 14 | linear | 0.1 | 0.0 | |
| R50x{1,2} | JFT-300M | 7 | linear | 0.1 | 0.0 | |
| R101x1 | JFT-300M | 7 | linear | 0.1 | 0.0 | |
| R152x{1,2} | JFT-300M | 7 | linear | 0.1 | 0.0 | |
| R50+ViT-B/{16,32} | JFT-300M | 7 | linear | 0.1 | 0.0 | |
| R50+ViT-L/32 | JFT-300M | 7 | linear | 0.1 | 0.0 | |
| R50+ViT-L/16 | JFT-300M | 7/14 | linear | 0.1 | 0.0 | |
| ViT-B/{16,32} | ImageNet-21k | 90 | linear | 0.03 | 0.1 | |
| ViT-L/{16,32} | ImageNet-21k | 30/90 | linear | 0.03 | 0.1 | |
| ViT- | ImageNet | 300 | cosine | 0.3 | 0.1 |
Table 3: Hyperparameters for training. All models are trained with a batch size of 4096 and learning rate warmup of 10k steps. For ImageNet we found it beneficial to additionally apply gradient clipping at global norm 1. Training resolution is 224.
| 模型 | 数据集 | Epochs | 基础 LR | LR 衰减 | 权重衰减 | Dropout |
|---|---|---|---|---|---|---|
| ViT-B/{16,32} | JFT-300M | 7 | linear | 0.1 | 0.0 | |
| ViT-L/32 | JFT-300M | 7 | linear | 0.1 | 0.0 | |
| ViT-L/16 | JFT-300M | 7/14 | linear | 0.1 | 0.0 | |
| ViT-H/14 | JFT-300M | 14 | linear | 0.1 | 0.0 | |
| R50x{1,2} | JFT-300M | 7 | linear | 0.1 | 0.0 | |
| R101x1 | JFT-300M | 7 | linear | 0.1 | 0.0 | |
| R152x{1,2} | JFT-300M | 7 | linear | 0.1 | 0.0 | |
| R50+ViT-B/{16,32} | JFT-300M | 7 | linear | 0.1 | 0.0 | |
| R50+ViT-L/32 | JFT-300M | 7 | linear | 0.1 | 0.0 | |
| R50+ViT-L/16 | JFT-300M | 7/14 | linear | 0.1 | 0.0 | |
| ViT-B/{16,32} | ImageNet-21k | 90 | linear | 0.03 | 0.1 | |
| ViT-L/{16,32} | ImageNet-21k | 30/90 | linear | 0.03 | 0.1 | |
| ViT- | ImageNet | 300 | cosine | 0.3 | 0.1 |
表 3:训练超参数。所有模型以批量 4096、学习率预热 10k 步训练。对 ImageNet,我们发现额外施加全局范数 1 的梯度裁剪有益。训练分辨率为 224。
Table 3 summarizes our training setups for our different models. We found strong regularization to be key when training models from scratch on ImageNet. Dropout, when used, is applied after every dense layer except for the the qkv-projections and directly after adding positional- to patch embeddings. Hybrid models are trained with the exact setup as their ViT counterparts. Finally, all training is done on resolution 224.
表 3 汇总不同模型的训练设定。我们发现:在 ImageNet 上从零训练模型时,强正则是关键。使用 dropout 时,它施加于每个稠密层之后(qkv 投影除外),并直接加在位置嵌入与块嵌入相加之后。混合模型用与对应 ViT 完全相同的设定训练。最后,所有训练都在分辨率 224 上进行。
B.1.1 Fine-tuning
| Dataset | Steps | Base LR |
|---|---|---|
| ImageNet | 20 000 | {0.003, 0.01, 0.03, 0.06} |
| CIFAR100 | 10 000 | {0.001, 0.003, 0.01, 0.03} |
| CIFAR10 | 10 000 | {0.001, 0.003, 0.01, 0.03} |
| Oxford-IIIT Pets | 500 | {0.001, 0.003, 0.01, 0.03} |
| Oxford Flowers-102 | 500 | {0.001, 0.003, 0.01, 0.03} |
| VTAB (19 tasks) | 2 500 | 0.01 |
Table 4: Hyperparameters for fine-tuning. All models are fine-tuned with cosine learning rate decay, a batch size of 512, no weight decay, and grad clipping at global norm 1. If not mentioned otherwise, fine-tuning resolution is 384.
B.1.1 微调
| 数据集 | 步数 | 基础 LR |
|---|---|---|
| ImageNet | 20 000 | {0.003, 0.01, 0.03, 0.06} |
| CIFAR100 | 10 000 | {0.001, 0.003, 0.01, 0.03} |
| CIFAR10 | 10 000 | {0.001, 0.003, 0.01, 0.03} |
| Oxford-IIIT Pets | 500 | {0.001, 0.003, 0.01, 0.03} |
| Oxford Flowers-102 | 500 | {0.001, 0.003, 0.01, 0.03} |
| VTAB (19 tasks) | 2 500 | 0.01 |
表 4:微调超参数。所有模型用余弦学习率衰减、批量 512、无权重衰减、全局范数 1 的梯度裁剪微调。除非另有说明,微调分辨率为 384。
We fine-tune all ViT models using SGD with a momentum of 0.9. We run a small grid search over learning rates, see learning rate ranges in Table 4. To do so, we use small sub-splits from the training set (10% for Pets and Flowers, 2% for CIFAR, 1% ImageNet) as development set and train on the remaining data. For final results we train on the entire training set and evaluate on the respective test data. For fine-tuning ResNets and hybrid models we use the exact same setup, with the only exception of ImageNet where we add another value to the learning rate sweep. Additionally, for ResNets we also run the setup of Kolesnikov et al. 2020 and select the best results across this run and our sweep. Finally, if not mentioned otherwise, all fine-tuning experiments run at 384 resolution (running fine-tuning at different resolution than training is common practice (Kolesnikov et al. 2020)).
我们用动量 0.9 的 SGD 微调所有 ViT 模型。我们在学习率上跑小网格搜索,见表 4 中的学习率范围。为此,我们从训练集划出小子集作为开发集(Pets 与 Flowers 为 10%,CIFAR 为 2%,ImageNet 为 1%),并在剩余数据上训练。最终结果在整个训练集上训练,并在相应测试数据上评估。微调 ResNet 与混合模型使用完全相同设定,唯一例外是 ImageNet:我们在学习率扫描中再加一个值 。此外,对 ResNet 我们也跑 Kolesnikov et al. 2020 的设定,并在该运行与我们的扫描中选最佳结果。最后,除非另有说明,所有微调实验在分辨率 384 运行(以不同于训练的分辨率微调是常见做法(Kolesnikov et al. 2020))。
When transferring ViT models to another dataset, we remove the whole head (two linear layers) and replace it by a single, zero-initialized linear layer outputting the number of classes required by the target dataset. We found this to be a little more robust than simply re-initializing the very last layer.
把 ViT 模型迁移到另一数据集时,我们去掉整个头(两个线性层),换成单个零初始化线性层,输出目标数据集所需的类别数。我们发现这比简单重新初始化最后一层稍稳健。
For VTAB we follow the protocol in Kolesnikov et al. 2020, and use the same hyperparameter setting for all tasks. We use a learning rate of and train for steps (Tab. 4). We chose this setting by running a small sweep over two learning rates and two schedules, and selecting the setting with the highest VTAB score on the 200-example validation sets. We follow the pre-processing used in Kolesnikov et al. 2020, except that we do not use task-specific input resolutions. Instead we find that Vision Transformer benefits most from a high resolution () for all tasks.
对 VTAB,我们遵循 Kolesnikov et al. 2020 的协议,并对所有任务使用相同超参数设定。学习率 ,训练 步(表 4)。我们通过在两种学习率与两种日程上跑小扫描,并选取在 200 样本验证集上 VTAB 分数最高的设定来选定。预处理遵循 Kolesnikov et al. 2020,但我们不使用任务特定输入分辨率。相反,我们发现 Vision Transformer 在所有任务上最受益于高分辨率()。
B.1.2 Self-supervision
We employ the masked patch prediction objective for preliminary self-supervision experiments. To do so we corrupt 50% of patch embeddings by either replacing their embeddings with a learnable [mask] embedding (80%), a random other patch embedding (10%) or just keeping them as is (10%). This setup is very similar to the one used for language by Devlin et al. 2019. Finally, we predict the 3-bit, mean color (i.e., 512 colors in total) of every corrupted patch using their respective patch representations.
B.1.2 自监督
我们采用掩蔽块预测目标做初步自监督实验。为此,我们腐蚀 50% 的块嵌入:要么用可学习 [mask] 嵌入替换其嵌入(80%),要么替换为随机其他块嵌入(10%),要么保持原样(10%)。这一设定与 Devlin et al. 2019 用于语言的设定非常相似。最后,我们用各自的块表征预测每个被腐蚀块的 3 比特平均颜色(即共 512 色)。
We trained our self-supervised model for 1M steps (ca. 14 epochs) with batch size 4096 on JFT. We use Adam, with a base learning rate of , warmup of 10k steps and cosine learning rate decay. As prediction targets for pretraining we tried the following settings: 1) predicting only the mean, 3bit color (i.e., 1 prediction of 512 colors), 2) predicting a downsized version of the patch with 3bit colors in parallel (i.e., 16 predictions of 512 colors), 3) regression on the full patch using L2 (i.e., 256 regressions on the 3 RGB channels). Surprisingly, we found that all worked quite well, though L2 was slightly worse. We report final results only for option 1) because it has shown best few-shot performance. We also experimented with 15% corruption rate as used by Devlin et al. 2019 but results were also slightly worse on our few-shot metrics.
我们在 JFT 上以批量 4096 训练自监督模型 1M 步(约 14 个 epoch)。使用 Adam,基础学习率 ,预热 10k 步,余弦学习率衰减。作为预训练预测目标,我们尝试如下设定:1)只预测平均 3 比特颜色(即 1 次 512 色预测);2)并行预测 块的 降采样版本的 3 比特颜色(即 16 次 512 色预测);3)用 L2 对完整块回归(即对 3 个 RGB 通道做 256 次回归)。令人惊讶的是,我们发现三者都相当有效,不过 L2 略差。我们只报告选项 1)的最终结果,因为它少样本表现最好。我们也试验了 Devlin et al. 2019 使用的 15% 腐蚀率,但在我们的少样本指标上结果也略差。
Lastly, we would like to remark that our instantiation of masked patch prediction doesn’t require such an enormous amount of pretraining nor a large dataset such as JFT in order to lead to similar performance gains on ImageNet classification. That is, we observed diminishing returns on downstream performance after 100k pretraining steps, and see similar gains when pretraining on ImageNet.
最后,我们想指出:我们的掩蔽块预测实例化并不需要如此大量的预训练,也不需要 JFT 这样的大数据集,才能在 ImageNet 分类上带来相似增益。也就是说,我们观察到预训练 100k 步之后下游表现收益递减,并在 ImageNet 上预训练时看到相似增益。
Appendix C Additional Results
附录 C 额外结果
We report detailed results corresponding to the figures presented in the paper. Table 5 corresponds to Figure 4 from the paper and shows transfer performance of different ViT models pre-trained on datasets of increasing size: ImageNet, ImageNet-21k, and JFT-300M. Table 6 corresponds to Figure 5 from the paper and shows the transfer performance of ViT, ResNet, and hybrid models of varying size, as well as the estimated computational cost of their pre-training.
我们报告与文中图对应的详细结果。表 5 对应文中图 4,展示在规模递增数据集 ImageNet、ImageNet-21k 与 JFT-300M 上预训练的不同 ViT 模型的迁移表现。表 6 对应文中图 5,展示不同规模 ViT、ResNet 与混合模型的迁移表现,以及其预训练估计计算代价。
| ViT-B/16 | ViT-B/32 | ViT-L/16 | ViT-L/32 | ViT-H/14 | ||
|---|---|---|---|---|---|---|
| ImageNet | CIFAR-10 | 98.13 | 97.77 | 97.86 | 97.94 | - |
| CIFAR-100 | 87.13 | 86.31 | 86.35 | 87.07 | - | |
| ImageNet | 77.91 | 73.38 | 76.53 | 71.16 | - | |
| ImageNet ReaL | 83.57 | 79.56 | 82.19 | 77.83 | - | |
| Oxford Flowers-102 | 89.49 | 85.43 | 89.66 | 86.36 | - | |
| Oxford-IIIT-Pets | 93.81 | 92.04 | 93.64 | 91.35 | - | |
| ImageNet-21k | CIFAR-10 | 98.95 | 98.79 | 99.16 | 99.13 | 99.27 |
| CIFAR-100 | 91.67 | 91.97 | 93.44 | 93.04 | 93.82 | |
| ImageNet | 83.97 | 81.28 | 85.15 | 80.99 | 85.13 | |
| ImageNet ReaL | 88.35 | 86.63 | 88.40 | 85.65 | 88.70 | |
| Oxford Flowers-102 | 99.38 | 99.11 | 99.61 | 99.19 | 99.51 | |
| Oxford-IIIT-Pets | 94.43 | 93.02 | 94.73 | 93.09 | 94.82 | |
| JFT-300M | CIFAR-10 | 99.00 | 98.61 | 99.38 | 99.19 | 99.50 |
| CIFAR-100 | 91.87 | 90.49 | 94.04 | 92.52 | 94.55 | |
| ImageNet | 84.15 | 80.73 | 87.12 | 84.37 | 88.04 | |
| ImageNet ReaL | 88.85 | 86.27 | 89.99 | 88.28 | 90.33 | |
| Oxford Flowers-102 | 99.56 | 99.27 | 99.56 | 99.45 | 99.68 | |
| Oxford-IIIT-Pets | 95.80 | 93.40 | 97.11 | 95.83 | 97.56 |
Table 5: Top1 accuracy (in %) of Vision Transformer on various datasets when pre-trained on ImageNet, ImageNet-21k or JFT300M. These values correspond to Figure 4 in the main text. Models are fine-tuned at 384 resolution. Note that the ImageNet results are computed without additional techniques (Polyak averaging and 512 resolution images) used to achieve results in Table 2.
| ViT-B/16 | ViT-B/32 | ViT-L/16 | ViT-L/32 | ViT-H/14 | ||
|---|---|---|---|---|---|---|
| ImageNet | CIFAR-10 | 98.13 | 97.77 | 97.86 | 97.94 | - |
| CIFAR-100 | 87.13 | 86.31 | 86.35 | 87.07 | - | |
| ImageNet | 77.91 | 73.38 | 76.53 | 71.16 | - | |
| ImageNet ReaL | 83.57 | 79.56 | 82.19 | 77.83 | - | |
| Oxford Flowers-102 | 89.49 | 85.43 | 89.66 | 86.36 | - | |
| Oxford-IIIT-Pets | 93.81 | 92.04 | 93.64 | 91.35 | - | |
| ImageNet-21k | CIFAR-10 | 98.95 | 98.79 | 99.16 | 99.13 | 99.27 |
| CIFAR-100 | 91.67 | 91.97 | 93.44 | 93.04 | 93.82 | |
| ImageNet | 83.97 | 81.28 | 85.15 | 80.99 | 85.13 | |
| ImageNet ReaL | 88.35 | 86.63 | 88.40 | 85.65 | 88.70 | |
| Oxford Flowers-102 | 99.38 | 99.11 | 99.61 | 99.19 | 99.51 | |
| Oxford-IIIT-Pets | 94.43 | 93.02 | 94.73 | 93.09 | 94.82 | |
| JFT-300M | CIFAR-10 | 99.00 | 98.61 | 99.38 | 99.19 | 99.50 |
| CIFAR-100 | 91.87 | 90.49 | 94.04 | 92.52 | 94.55 | |
| ImageNet | 84.15 | 80.73 | 87.12 | 84.37 | 88.04 | |
| ImageNet ReaL | 88.85 | 86.27 | 89.99 | 88.28 | 90.33 | |
| Oxford Flowers-102 | 99.56 | 99.27 | 99.56 | 99.45 | 99.68 | |
| Oxford-IIIT-Pets | 95.80 | 93.40 | 97.11 | 95.83 | 97.56 |
表 5:在 ImageNet、ImageNet-21k 或 JFT300M 上预训练时,Vision Transformer 在各数据集上的 Top1 精度(%)。这些数值对应正文图 4。模型以分辨率 384 微调。注意 ImageNet 结果未使用表 2 中达到结果所用的额外技术(Polyak 平均与 512 分辨率图像)。
| Epochs | ImageNet | ImageNet ReaL | CIFAR-10 | CIFAR-100 | Pets | Flowers | exaFLOPs | |
|---|---|---|---|---|---|---|---|---|
| name | ||||||||
| ViT-B/32 | 7 | 80.73 | 86.27 | 98.61 | 90.49 | 93.40 | 99.27 | 55 |
| ViT-B/16 | 7 | 84.15 | 88.85 | 99.00 | 91.87 | 95.80 | 99.56 | 224 |
| ViT-L/32 | 7 | 84.37 | 88.28 | 99.19 | 92.52 | 95.83 | 99.45 | 196 |
| ViT-L/16 | 7 | 86.30 | 89.43 | 99.38 | 93.46 | 96.81 | 99.66 | 783 |
| ViT-L/16 | 14 | 87.12 | 89.99 | 99.38 | 94.04 | 97.11 | 99.56 | 1567 |
| ViT-H/14 | 14 | 88.08 | 90.36 | 99.50 | 94.71 | 97.11 | 99.71 | 4262 |
| ResNet50x1 | 7 | 77.54 | 84.56 | 97.67 | 86.07 | 91.11 | 94.26 | 50 |
| ResNet50x2 | 7 | 82.12 | 87.94 | 98.29 | 89.20 | 93.43 | 97.02 | 199 |
| ResNet101x1 | 7 | 80.67 | 87.07 | 98.48 | 89.17 | 94.08 | 95.95 | 96 |
| ResNet152x1 | 7 | 81.88 | 87.96 | 98.82 | 90.22 | 94.17 | 96.94 | 141 |
| ResNet152x2 | 7 | 84.97 | 89.69 | 99.06 | 92.05 | 95.37 | 98.62 | 563 |
| ResNet152x2 | 14 | 85.56 | 89.89 | 99.24 | 91.92 | 95.75 | 98.75 | 1126 |
| ResNet200x3 | 14 | 87.22 | 90.15 | 99.34 | 93.53 | 96.32 | 99.04 | 3306 |
| R50x1+ViT-B/32 | 7 | 84.90 | 89.15 | 99.01 | 92.24 | 95.75 | 99.46 | 106 |
| R50x1+ViT-B/16 | 7 | 85.58 | 89.65 | 99.14 | 92.63 | 96.65 | 99.40 | 274 |
| R50x1+ViT-L/32 | 7 | 85.68 | 89.04 | 99.24 | 92.93 | 96.97 | 99.43 | 246 |
| R50x1+ViT-L/16 | 7 | 86.60 | 89.72 | 99.18 | 93.64 | 97.03 | 99.40 | 859 |
| R50x1+ViT-L/16 | 14 | 87.12 | 89.76 | 99.31 | 93.89 | 97.36 | 99.11 | 1668 |
Table 6: Detailed results of model scaling experiments. These correspond to Figure 5 in the main paper. We show transfer accuracy on several datasets, as well as the pre-training compute (in exaFLOPs).
| Epochs | ImageNet | ImageNet ReaL | CIFAR-10 | CIFAR-100 | Pets | Flowers | exaFLOPs | |
|---|---|---|---|---|---|---|---|---|
| 名称 | ||||||||
| ViT-B/32 | 7 | 80.73 | 86.27 | 98.61 | 90.49 | 93.40 | 99.27 | 55 |
| ViT-B/16 | 7 | 84.15 | 88.85 | 99.00 | 91.87 | 95.80 | 99.56 | 224 |
| ViT-L/32 | 7 | 84.37 | 88.28 | 99.19 | 92.52 | 95.83 | 99.45 | 196 |
| ViT-L/16 | 7 | 86.30 | 89.43 | 99.38 | 93.46 | 96.81 | 99.66 | 783 |
| ViT-L/16 | 14 | 87.12 | 89.99 | 99.38 | 94.04 | 97.11 | 99.56 | 1567 |
| ViT-H/14 | 14 | 88.08 | 90.36 | 99.50 | 94.71 | 97.11 | 99.71 | 4262 |
| ResNet50x1 | 7 | 77.54 | 84.56 | 97.67 | 86.07 | 91.11 | 94.26 | 50 |
| ResNet50x2 | 7 | 82.12 | 87.94 | 98.29 | 89.20 | 93.43 | 97.02 | 199 |
| ResNet101x1 | 7 | 80.67 | 87.07 | 98.48 | 89.17 | 94.08 | 95.95 | 96 |
| ResNet152x1 | 7 | 81.88 | 87.96 | 98.82 | 90.22 | 94.17 | 96.94 | 141 |
| ResNet152x2 | 7 | 84.97 | 89.69 | 99.06 | 92.05 | 95.37 | 98.62 | 563 |
| ResNet152x2 | 14 | 85.56 | 89.89 | 99.24 | 91.92 | 95.75 | 98.75 | 1126 |
| ResNet200x3 | 14 | 87.22 | 90.15 | 99.34 | 93.53 | 96.32 | 99.04 | 3306 |
| R50x1+ViT-B/32 | 7 | 84.90 | 89.15 | 99.01 | 92.24 | 95.75 | 99.46 | 106 |
| R50x1+ViT-B/16 | 7 | 85.58 | 89.65 | 99.14 | 92.63 | 96.65 | 99.40 | 274 |
| R50x1+ViT-L/32 | 7 | 85.68 | 89.04 | 99.24 | 92.93 | 96.97 | 99.43 | 246 |
| R50x1+ViT-L/16 | 7 | 86.60 | 89.72 | 99.18 | 93.64 | 97.03 | 99.40 | 859 |
| R50x1+ViT-L/16 | 14 | 87.12 | 89.76 | 99.31 | 93.89 | 97.36 | 99.11 | 1668 |
表 6:模型扩展实验的详细结果。对应正文图 5。我们展示若干数据集上的迁移精度,以及预训练计算(exaFLOPs)。
Appendix D Additional Analyses
附录 D 额外分析
D.1 SGD vs. Adam for ResNets
D.1 ResNet 的 SGD 对 Adam
ResNets are typically trained with SGD and our use of Adam as optimizer is quite unconventional. Here we show the experiments that motivated this choice. Namely, we compare the fine-tuning performance of two ResNets – 50x1 and 152x2 – pre-trained on JFT with SGD and Adam. For SGD, we use the hyperparameters recommended by Kolesnikov et al. 2020. Results are presented in Table 7. Adam pre-training outperforms SGD pre-training on most datasets and on average. This justifies the choice of Adam as the optimizer used to pre-train ResNets on JFT. Note that the absolute numbers are lower than those reported by Kolesnikov et al. 2020, since we pre-train only for epochs, not .
ResNet 通常用 SGD 训练,我们使用 Adam 作为优化器相当非常规。这里展示促使这一选择的实验。具体地,我们比较两个在 JFT 上分别用 SGD 与 Adam 预训练的 ResNet——50x1 与 152x2——的微调表现。对 SGD,我们使用 Kolesnikov et al. 2020 推荐的超参数。结果见表 7。Adam 预训练在多数数据集以及平均上超过 SGD 预训练。这证明了用 Adam 在 JFT 上预训练 ResNet 的选择。注意绝对数字低于 Kolesnikov et al. 2020 报告的数字,因为我们只预训练 个 epoch,而非 。
| ResNet50 | ResNet152x2 | |||
|---|---|---|---|---|
| Dataset | Adam | SGD | Adam | SGD |
| ImageNet | ||||
| CIFAR10 | ||||
| CIFAR100 | ||||
| Oxford-IIIT Pets | ||||
| Oxford Flowers-102 | ||||
| Average |
Table 7: Fine-tuning ResNet models pre-trained with Adam and SGD.
| ResNet50 | ResNet152x2 | |||
|---|---|---|---|---|
| 数据集 | Adam | SGD | Adam | SGD |
| ImageNet | ||||
| CIFAR10 | ||||
| CIFAR100 | ||||
| Oxford-IIIT Pets | ||||
| Oxford Flowers-102 | ||||
| 平均 |
表 7:用 Adam 与 SGD 预训练的 ResNet 模型的微调结果。
D.2 Transformer shape
D.2 Transformer 形状
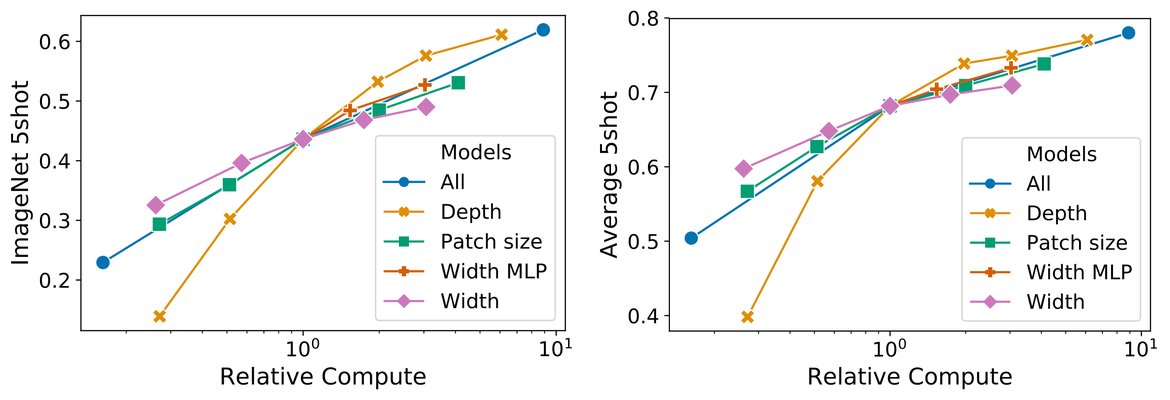
Figure 8: Scaling different model dimensions of the Vision Transformer.
图 8:扩展 Vision Transformer 的不同模型维度。
We ran ablations on scaling different dimensions of the Transformer architecture to find out which are best suited for scaling to very large models. Figure 8 shows 5-shot performance on ImageNet for different configurations. All configurations are based on a ViT model with layers, , and a patch size of , the intersection of all lines. We can see that scaling the depth results in the biggest improvements which are clearly visible up until 64 layers. However, diminishing returns are already visible after 16 layers. Interestingly, scaling the width of the network seems to result in the smallest changes. Decreasing the patch size and thus increasing the effective sequence length shows surprisingly robust improvements without introducing parameters. These findings suggest that compute might be a better predictor of performance than the number of parameters, and that scaling should emphasize depth over width if any. Overall, we find that scaling all dimensions proportionally results in robust improvements.
我们对扩展 Transformer 架构的不同维度做消融,以找出哪些最适于扩展到很大模型。图 8 展示不同配置在 ImageNet 上的 5-shot 表现。所有配置基于 8 层、、、块尺寸 的 ViT 模型——各线交点。可以看到,扩展深度带来最大改进,直到 64 层仍清晰可见。但 16 层之后已可见收益递减。有趣的是,扩展网络宽度似乎带来最小变化。减小块尺寸从而增加有效序列长度,在不引入参数的情况下显示出出人意料稳健的改进。这些发现表明:计算可能比参数量更能预测表现,且扩展应优先强调深度而非宽度。总体而言,我们发现按比例扩展所有维度会带来稳健改进。
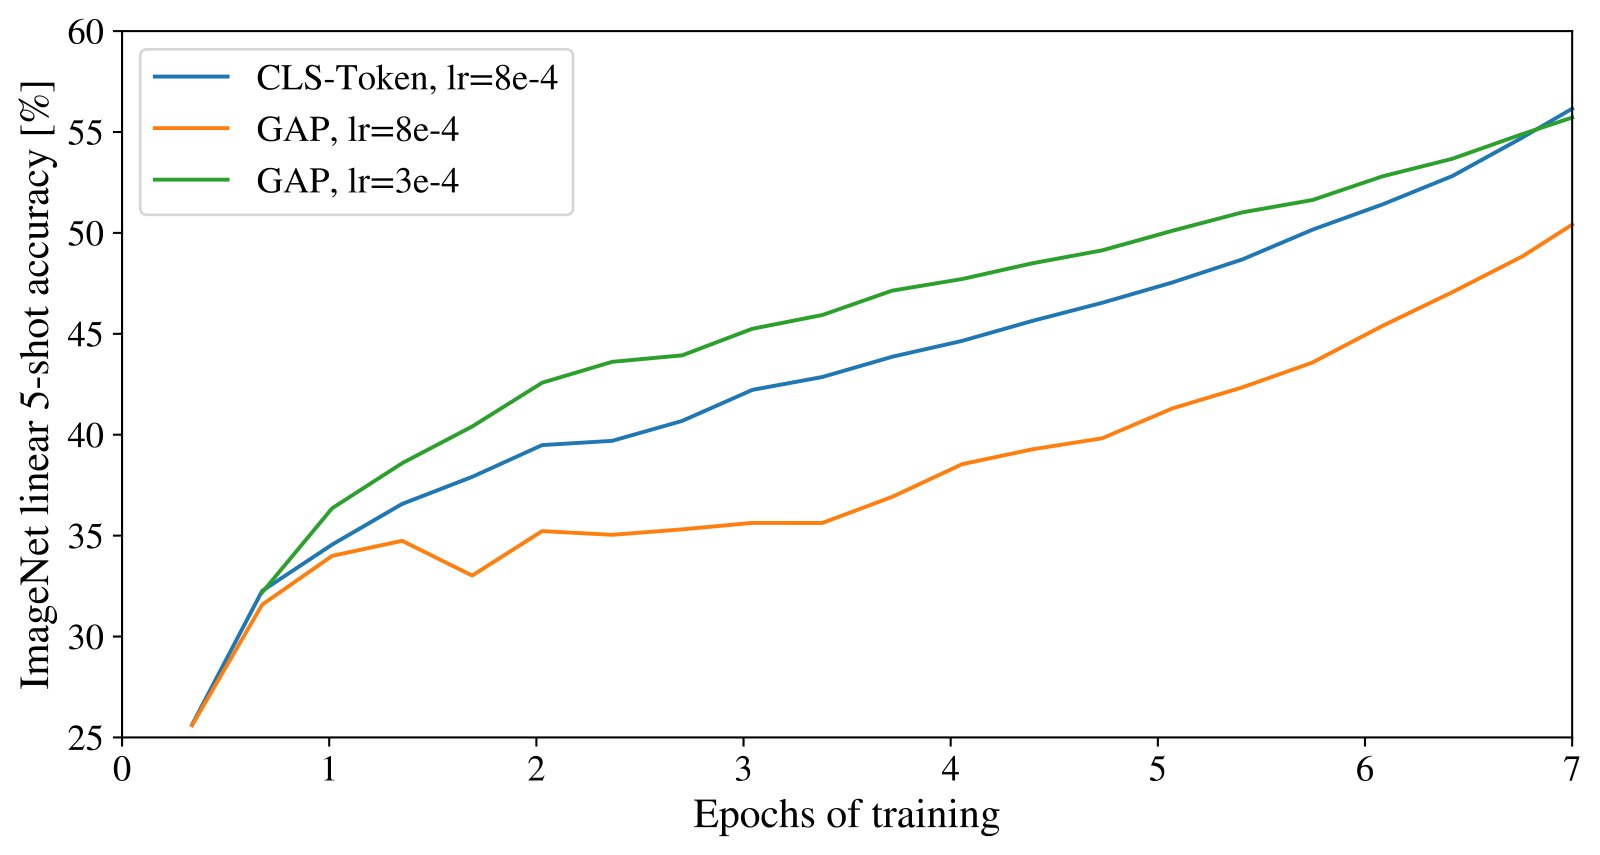
Figure 9: Comparison of class-token and global average pooling classifiers. Both work similarly well, but require different learning-rates.
图 9:分类记号与全局平均池化分类器的比较。二者表现相近,但需要不同学习率。
D.3 Head Type and class token
D.3 头类型与 class 记号
In order to stay as close as possible to the original Transformer model, we made use of an additional [class] token, which is taken as image representation. The output of this token is then transformed into a class prediction via a small multi-layer perceptron (MLP) with as non-linearity in the single hidden layer.
为尽可能贴近原始 Transformer 模型,我们使用额外的 [class] 记号,并将其取为图像表征。该记号的输出再经带 作为单隐层非线性的小型多层感知机(MLP)变换为类别预测。
This design is inherited from the Transformer model for text, and we use it throughout the main paper. An initial attempt at using only image-patch embeddings, globally average-pooling (GAP) them, followed by a linear classifier—just like ResNet’s final feature map—performed very poorly. However, we found that this is neither due to the extra token, nor to the GAP operation. Instead, the difference in performance is fully explained by the requirement for a different learning-rate, see Figure 9.
这一设计继承自用于文本的 Transformer 模型,并贯穿正文使用。最初尝试只使用图像块嵌入、对其做全局平均池化(GAP)、再接线性分类器——就像 ResNet 的最终特征图——表现很差。但我们发现这既不是因为额外记号,也不是因为 GAP 运算。相反,表现差异完全可由对不同学习率的需求解释,见图 9。
D.4 Positional Embedding
D.4 位置嵌入
We ran ablations on different ways of encoding spatial information using positional embedding. We tried the following cases:
我们对用位置嵌入编码空间信息的不同方式做消融。我们尝试如下情形:
- • Providing no positional information: Considering the inputs as a bag of patches.
- • 不提供位置信息:把输入视为块袋。
- • 1-dimensional positional embedding: Considering the inputs as a sequence of patches in the raster order (default across all other experiments in this paper).
- • 一维位置嵌入:把输入视为按光栅次序排列的块序列(本文所有其他实验的默认)。
- • 2-dimensional positional embedding: Considering the inputs as a grid of patches in two dimensions. In this case, two sets of embeddings are learned, each for one of the axes, -embedding, and -embedding, each with size . Then, based on the coordinate on the path in the input, we concatenate the and embedding to get the final positional embedding for that patch.
- • 二维位置嵌入:把输入视为二维块网格。此时学习两套嵌入,各对应一个轴:-嵌入与 -嵌入,各大小为 。然后,根据输入路径上的坐标,拼接 与 嵌入,得到该块的最终位置嵌入。
- • Relative positional embeddings: Considering the relative distance between patches to encode the spatial information as instead of their absolute position. To do so, we use 1-dimensional Relative Attention, in which we define the relative distance all possible pairs of patches. Thus, for every given pair (one as query, and the other as key/value in the attention mechanism), we have an offset , where each offset is associated with an embedding. Then, we simply run extra attention, where we use the original query (the content of query), but use relative positional embeddings as keys. We then use the logits from the relative attention as a bias term and add it to the logits of the main attention (content-based attention) before applying the softmax.
- • 相对位置嵌入:用块之间的相对距离而非绝对位置来编码空间信息。为此,我们使用一维相对注意力,其中定义所有可能块对之间的相对距离。于是,对每一给定对(一个作为查询,另一个作为注意力机制中的键/值),我们有偏移 ,每个偏移关联一个嵌入。然后,我们简单再跑一次额外注意力:使用原始查询(查询内容),但用相对位置嵌入作为键。随后把相对注意力的 logits 用作偏置项,在施加 softmax 前加到主注意力(基于内容的注意力)的 logits 上。
| Pos. Emb. | Default/Stem | Every Layer | Every Layer-Shared |
|---|---|---|---|
| No Pos. Emb. | 0.61382 | N/A | N/A |
| 1-D Pos. Emb. | 0.64206 | 0.63964 | 0.64292 |
| 2-D Pos. Emb. | 0.64001 | 0.64046 | 0.64022 |
| Rel. Pos. Emb. | 0.64032 | N/A | N/A |
Table 8: Results of the ablation study on positional embeddings with ViT-B/16 model evaluated on ImageNet 5-shot linear.
| 位置嵌入 | 默认/Stem | 每层 | 每层共享 |
|---|---|---|---|
| 无位置嵌入 | 0.61382 | N/A | N/A |
| 一维位置嵌入 | 0.64206 | 0.63964 | 0.64292 |
| 二维位置嵌入 | 0.64001 | 0.64046 | 0.64022 |
| 相对位置嵌入 | 0.64032 | N/A | N/A |
表 8:在 ImageNet 5-shot 线性评估的 ViT-B/16 模型上,位置嵌入消融研究结果。
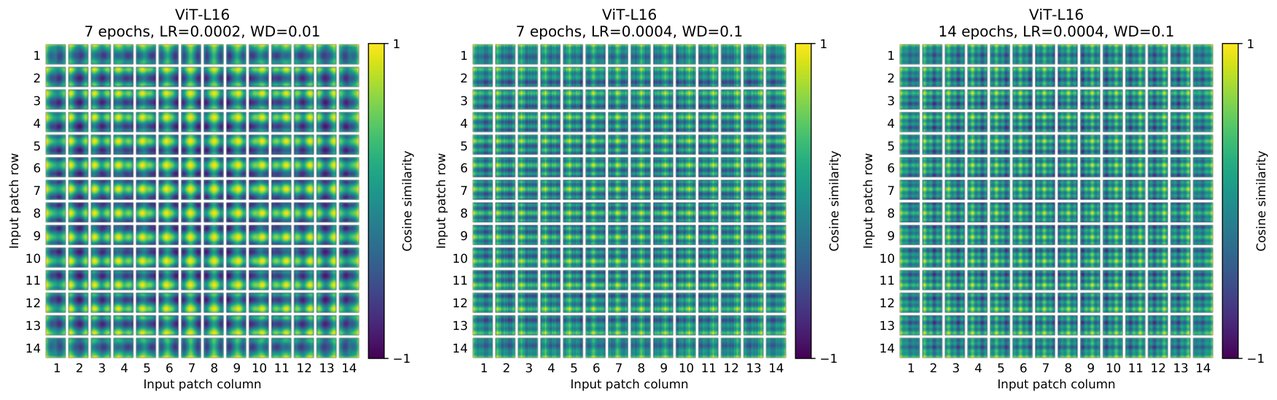
Figure 10: Position embeddings of models trained with different hyperparameters.
图 10:用不同超参数训练的模型的位置嵌入。
In addition to different ways of encoding spatial information, we also tried different ways of incorporating this information in our model. For the 1-dimensional and 2-dimensional positional embeddings, we tried three different cases: (1) add positional embeddings to the inputs right after the stem of them model and before feeding the inputs to the Transformer encoder (default across all other experiments in this paper); (2) learn and add positional embeddings to the inputs at the beginning of each layer; (3) add a learned positional embeddings to the inputs at the beginning of each layer (shared between layers).
除编码空间信息的不同方式外,我们还尝试把该信息纳入模型的不同方式。对一维与二维位置嵌入,我们尝试三种情形:(1) 在模型 stem 之后、把输入喂入 Transformer 编码器之前,把位置嵌入加到输入上(本文所有其他实验的默认);(2) 在每层开头学习并把位置嵌入加到输入上;(3) 在每层开头把学到的位置嵌入加到输入上(层间共享)。
Table 8 summarizes the results from this ablation study on a ViT-B/16 model. As we can see, while there is a large gap between the performances of the model with no positional embedding and models with positional embedding, there is little to no difference between different ways of encoding positional information. We speculate that since our Transformer encoder operates on patch-level inputs, as opposed to pixel-level, the differences in how to encode spatial information is less important. More precisely, in patch-level inputs, the spatial dimensions are much smaller than the original pixel-level inputs, e.g., as opposed to , and learning to represent the spatial relations in this resolution is equally easy for these different positional encoding strategies. Even so, the specific pattern of position embedding similarity learned by the network depends on the training hyperparameters (Figure 10).
表 8 汇总在 ViT-B/16 模型上该消融研究的结果。可以看到,虽然无位置嵌入模型与有位置嵌入模型之间有很大差距,但编码位置信息的不同方式之间几乎没有差别。我们推测:由于我们的 Transformer 编码器在块级输入上运算,而非像素级,如何编码空间信息的差异不那么重要。更精确地说,在块级输入中,空间维远小于原始像素级输入,例如 对 ,以这一分辨率学习表示空间关系对这些不同位置编码策略同样容易。即便如此,网络所学位置嵌入相似度的具体模式仍依赖于训练超参数(图 10)。
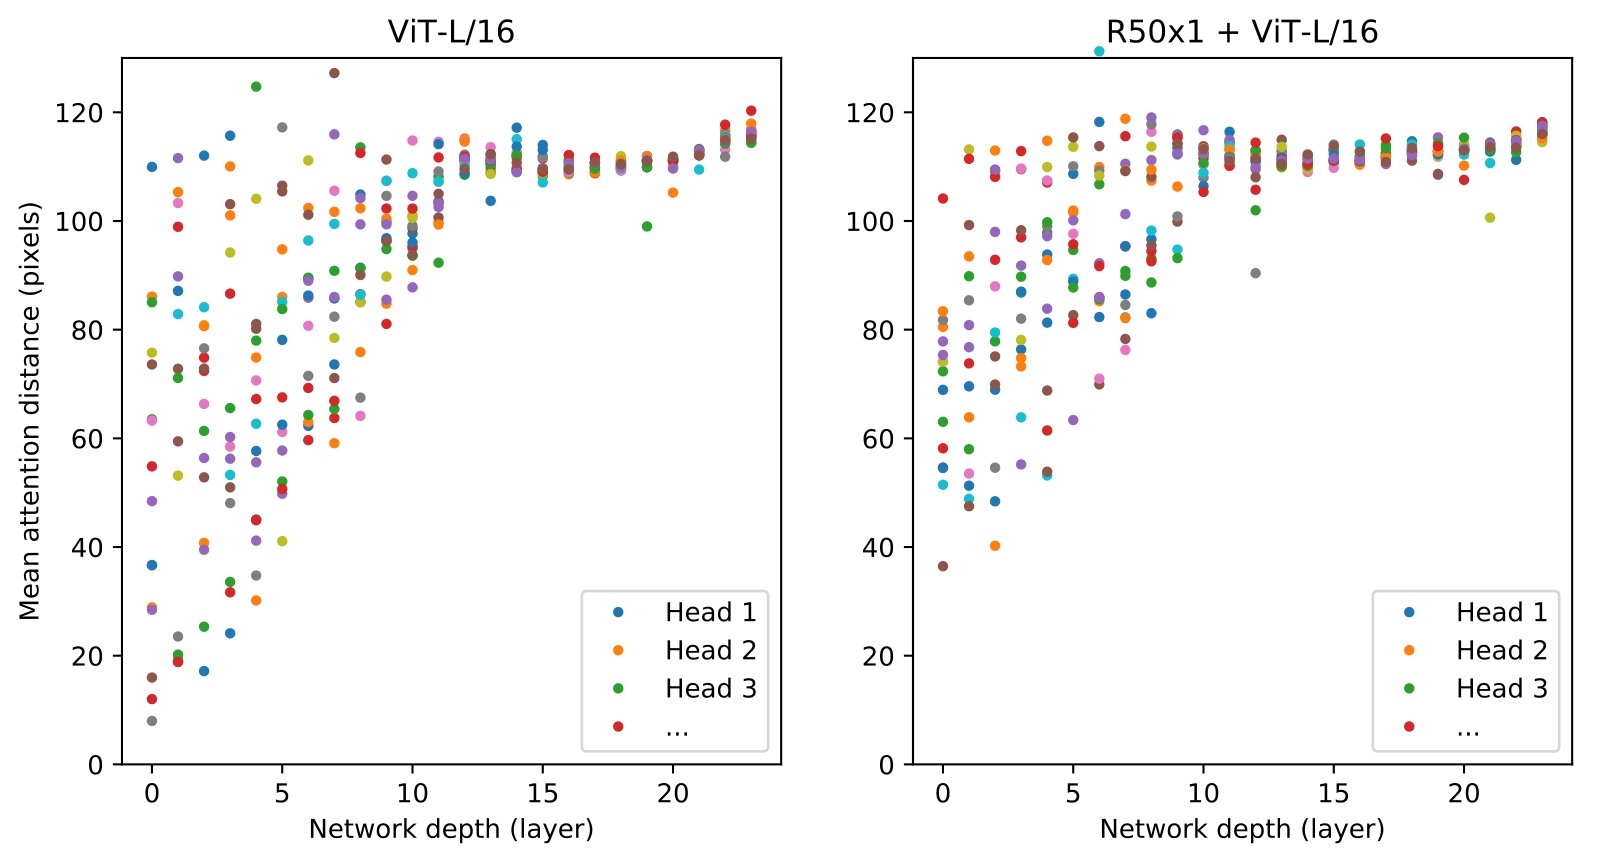
Figure 11: Size of attended area by head and network depth. Attention distance was computed for 128 example images by averaging the distance between the query pixel and all other pixels, weighted by the attention weight. Each dot shows the mean attention distance across images for one of 16 heads at one layer. Image width is 224 pixels.
图 11:按头与网络深度的注意力区域大小。注意力距离对 128 张示例图像计算:查询像素与所有其他像素之间的距离按注意力权重加权平均。每个点表示某一层 16 个头之一跨图像的平均注意力距离。图像宽度为 224 像素。
D.5 Empirical Computational Costs
D.5 经验计算代价
We are also interested in real-world speed of the architectures on our hardware, which is not always well predicted by theoretical FLOPs due to details like lane widths and cache sizes. For this purpose, we perform timing of inference speed for the main models of interest, on a TPUv3 accelerator; the difference between inference and backprop speed is a constant model-independent factor.
我们也关心架构在我们硬件上的真实世界速度,而这并不总是由理论 FLOPs 良好预测,因为还有通道宽度与缓存大小等细节。为此,我们在 TPUv3 加速器上对主要感兴趣模型做推理速度计时;推理与反向传播速度之差是与模型无关的常数因子。
Figure 12 (left) shows how many images one core can handle per second, across various input sizes. Every single point refers to the peak performance measured across a wide range of batch-sizes. As can be seen, the theoretical bi-quadratic scaling of ViT with image size only barely starts happening for the largest models at the largest resolutions.
图 12(左)展示一个核每秒能处理多少图像,覆盖各种输入尺寸。每个点对应在大范围批量上测得的峰值表现。可以看到,ViT 相对图像尺寸的理论双二次扩展,仅在最大模型、最大分辨率时才勉强开始显现。
Another quantity of interest is the largest batch-size each model can fit onto a core, larger being better for scaling to large datasets. Figure 12 (right) shows this quantity for the same set of models. This shows that large ViT models have a clear advantage in terms of memory-efficiency over ResNet models.
另一个感兴趣的量是每个模型能装进一个核的最大批量,越大越利于扩展到大数据集。图 12(右)对同一组模型展示该量。这表明大型 ViT 模型在内存效率上相对 ResNet 模型有明显优势。
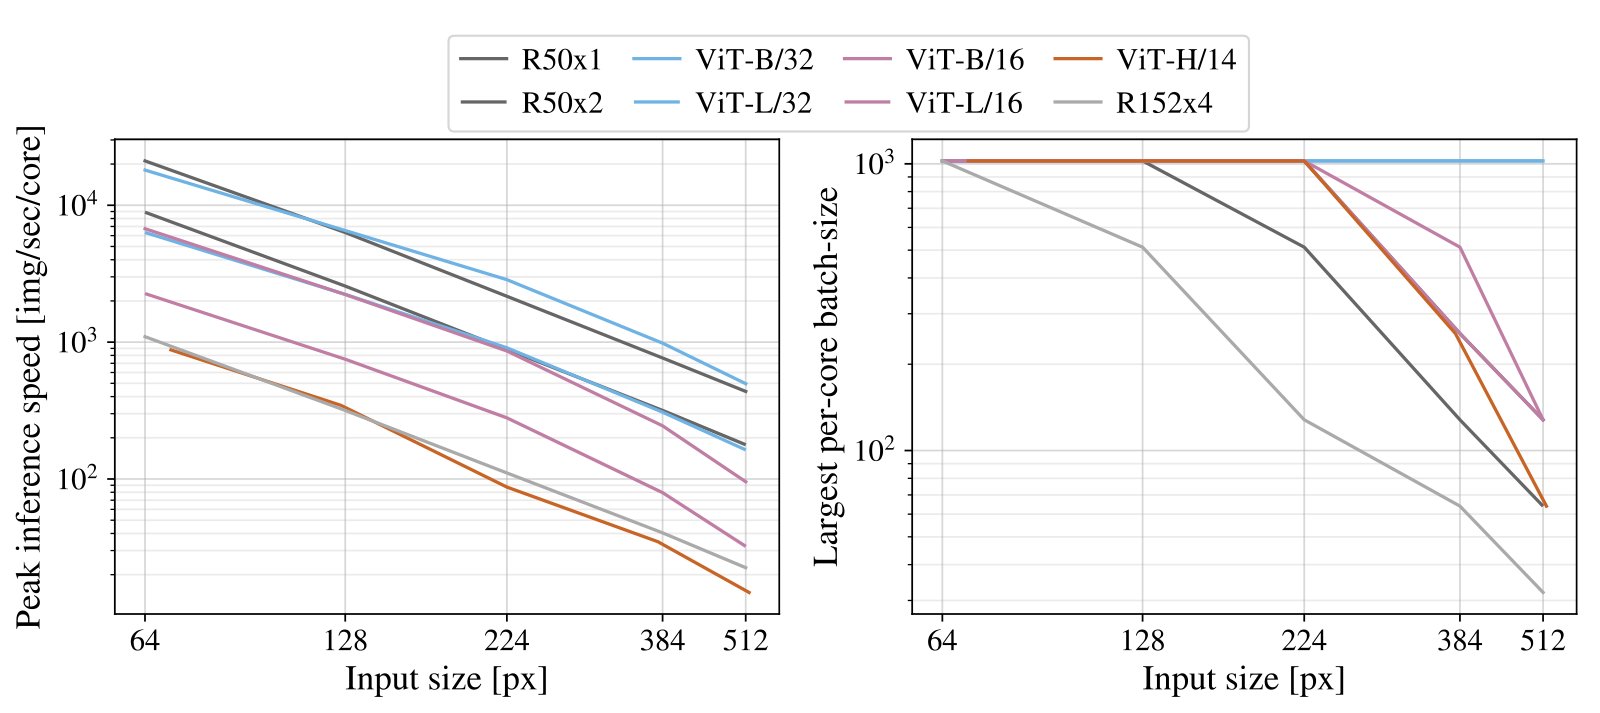
Figure 12: Left: Real wall-clock timings of various architectures across input sizes. ViT models have speed comparable to similar ResNets. Right: Largest per-core batch-size fitting on device with various architectures across input sizes. ViT models are clearly more memory-efficient.
图 12:左: 各架构跨输入尺寸的真实墙钟计时。ViT 模型速度与相似 ResNet 可比。右: 各架构跨输入尺寸时能装入设备的每核最大批量。ViT 模型明显更省内存。
D.6 Axial Attention
D.6 轴向注意力
Axial Attention (Huang et al. 2020; Ho et al. 2019) is a simple, yet effective technique to run self-attention on large inputs that are organized as multidimensional tensors. The general idea of axial attention is to perform multiple attention operations, each along a single axis of the input tensor, instead of applying 1-dimensional attention to the flattened version of the input. In axial attention, each attention mixes information along a particular axis, while keeping information along the other axes independent. Along this line, Wang et al. 2020b proposed the AxialResNet model in which all the convolutions with kernel size in a ResNet50 are replaced by axial self-attention, i.e. a row and column attention, augmented by relative positional encoding. We have implemented AxialResNet as a baseline model.[^3].
轴向注意力 (Huang et al. 2020;Ho et al. 2019)是一种简单却有效的技术,用于在组织为多维张量的大输入上运行自注意力。轴向注意力的一般想法是执行多次注意力运算,每次沿输入张量的单个轴,而不是对输入的展平版本施加一维注意力。在轴向注意力中,每次注意力沿特定轴混合信息,同时保持其他轴上的信息独立。沿这一路线,Wang et al. 2020b 提出 AxialResNet 模型:ResNet50 中所有核大小为 的卷积被轴向自注意力替换,即行与列注意力,并由相对位置编码增强。我们实现了 AxialResNet 作为基线模型。[^3]。
Moreover, we have modified ViT to process inputs in the 2-dimensional shape, instead of a 1-dimensional sequence of patches, and incorporate Axial Transformer blocks, in which instead of a self-attention followed by an MLP, we have a a row-self-attention plus an MLP followed by a column-self-attention plus an MLP.
此外,我们修改 ViT 以二维形状处理输入,而非一维块序列,并纳入轴向 Transformer 块:其中不是自注意力后接 MLP,而是行自注意力加 MLP,再接列自注意力加 MLP。
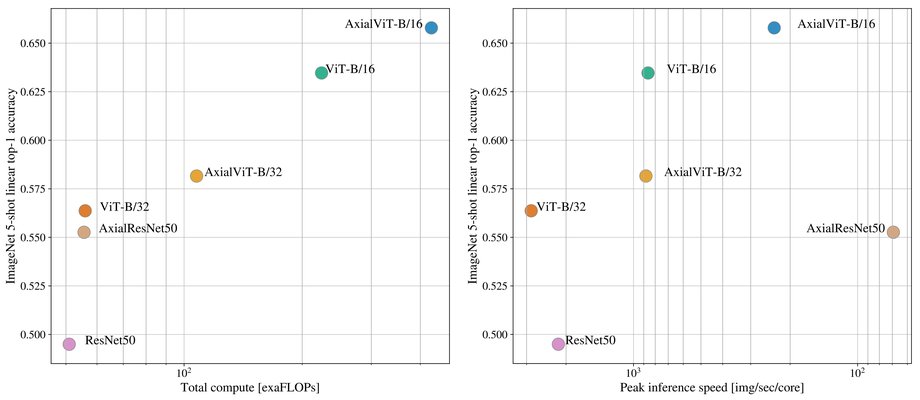
Figure 13: Performance of Axial-Attention based models, in terms of top-1 accuracy on ImageNet 5-shot linear, versus their speed in terms of number of FLOPs (left) and inference time (left).
图 13:基于轴向注意力的模型表现:ImageNet 5-shot 线性的 top-1 精度对 FLOPs 数(左)与推理时间(右)的速度。
Figure 13, present the performance of Axial ResNet, Axial-ViT-B/32 and Axial-ViT-B/16 on ImageNet 5shot linear, when pretrained on JFT dataset, verses the pretraining compute, both in terms of number of FLOPs and inference time (example per seconds). As we can see, both Axial-ViT-B/32 and Axial-ViT-B/16 do better than their ViT-B counterpart in terms of performance, but it comes at the cost of more compute. This is because in Axial-ViT models, each Transformer block with global self-attention is replaced by two Axial Transformer blocks, one with row and one with column self-attention and although the sequence length that self-attention operates on is smaller in axial case, there is a extra MLP per Axial-ViT block. For the AxialResNet, although it looks reasonable in terms of accuracy/compute trade-off (Figure 13, left), the naive implementation is extremely slow on TPUs (Figure 13, right).
图 13 给出 Axial ResNet、Axial-ViT-B/32 与 Axial-ViT-B/16 在 JFT 数据集上预训练后、ImageNet 5shot 线性上的表现,对预训练计算(按 FLOPs 数与推理时间/每秒样本)。可以看到,Axial-ViT-B/32 与 Axial-ViT-B/16 在表现上都优于对应的 ViT-B,但代价是更多计算。这是因为在 Axial-ViT 模型中,每个带全局自注意力的 Transformer 块被两个轴向 Transformer 块替换——一个带行、一个带列自注意力;尽管轴向情形下自注意力运算的序列长度更短,但每个 Axial-ViT 块有额外一个 MLP。对 AxialResNet,尽管在精度/计算权衡上看起来合理(图 13,左),朴素实现在 TPU 上极慢(图 13,右)。
D.7 Attention Distance
D.7 注意力距离
To understand how ViT uses self-attention to integrate information across the image, we analyzed the average distance spanned by attention weights at different layers (Figure 11). This “attention distance” is analogous to receptive field size in CNNs. Average attention distance is highly variable across heads in lower layers, with some heads attending to much of the image, while others attend to small regions at or near the query location. As depth increases, attention distance increases for all heads. In the second half of the network, most heads attend widely across tokens.
为理解 ViT 如何用自注意力跨图像整合信息,我们分析不同层上注意力权重跨越的平均距离(图 11)。这一「注意力距离」类似于 CNN 中的感受野大小。低层中平均注意力距离跨头高度可变:某些头关注图像的大部分,另一些关注查询位置处或附近的小区域。随深度增加,所有头的注意力距离增大。在网络后半部分,多数头广泛跨记号关注。
D.8 Attention Maps
D.8 注意力图
To compute maps of the attention from the output token to the input space (Figures 6 and 14), we used Attention Rollout (Abnar & Zuidema 2020). Briefly, we averaged attention weights of ViT-L/16 across all heads and then recursively multiplied the weight matrices of all layers. This accounts for the mixing of attention across tokens through all layers.
为计算从输出记号到输入空间的注意力图(图 6 与图 14),我们使用 Attention Rollout(Abnar & Zuidema 2020)。简言之,我们跨所有头平均 ViT-L/16 的注意力权重,再递归相乘所有层的权重矩阵。这计入通过所有层跨记号的注意力混合。
Figure 14: Further example attention maps as in Figure 6 (random selection).
图 14:如图 6 的更多注意力图例子(随机选取)。
D.9 ObjectNet Results
D.9 ObjectNet 结果
We also evaluate our flagship ViT-H/14 model on the ObjectNet benchmark following the evaluation setup in Kolesnikov et al. 2020, resulting in 82.1% top-5 accuracy and 61.7% top-1 accuracy.
我们还按 Kolesnikov et al. 2020 的评估设定,在 ObjectNet 基准上评估旗舰 ViT-H/14 模型,得到 82.1% top-5 精度与 61.7% top-1 精度。
D.10 VTAB Breakdown
D.10 VTAB 分解
Table 9 shows the scores attained on each of the VTAB-1k tasks.
表 9 展示在各 VTAB-1k 任务上达到的分数。
| Caltech101 | CIFAR-100 | DTD | Flowers102 | Pets | Sun397 | SVHN | Camelyon | EuroSAT | Resisc45 | Retinopathy | Clevr-Count | Clevr-Dist | DMLab | dSpr-Loc | dSpr-Ori | KITTI-Dist | sNORB-Azim | sNORB-Elev | Mean | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| ViT-H/14 (JFT) | 95.3 | 85.5 | 75.2 | 99.7 | 97.2 | 65.0 | 88.9 | 83.3 | 96.7 | 91.4 | 76.6 | 91.7 | 63.8 | 53.1 | 79.4 | 63.3 | 84.5 | 33.2 | 51.2 | 77.6 |
| ViT-L/16 (JFT) | 95.4 | 81.9 | 74.3 | 99.7 | 96.7 | 63.5 | 87.4 | 83.6 | 96.5 | 89.7 | 77.1 | 86.4 | 63.1 | 49.7 | 74.5 | 60.5 | 82.2 | 36.2 | 51.1 | 76.3 |
| ViT-L/16 (I21k) | 90.8 | 84.1 | 74.1 | 99.3 | 92.7 | 61.0 | 80.9 | 82.5 | 95.6 | 85.2 | 75.3 | 70.3 | 56.1 | 41.9 | 74.7 | 64.9 | 79.9 | 30.5 | 41.7 | 72.7 |
Table 9: Breakdown of VTAB-1k performance across tasks.
| Caltech101 | CIFAR-100 | DTD | Flowers102 | Pets | Sun397 | SVHN | Camelyon | EuroSAT | Resisc45 | Retinopathy | Clevr-Count | Clevr-Dist | DMLab | dSpr-Loc | dSpr-Ori | KITTI-Dist | sNORB-Azim | sNORB-Elev | Mean | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| ViT-H/14 (JFT) | 95.3 | 85.5 | 75.2 | 99.7 | 97.2 | 65.0 | 88.9 | 83.3 | 96.7 | 91.4 | 76.6 | 91.7 | 63.8 | 53.1 | 79.4 | 63.3 | 84.5 | 33.2 | 51.2 | 77.6 |
| ViT-L/16 (JFT) | 95.4 | 81.9 | 74.3 | 99.7 | 96.7 | 63.5 | 87.4 | 83.6 | 96.5 | 89.7 | 77.1 | 86.4 | 63.1 | 49.7 | 74.5 | 60.5 | 82.2 | 36.2 | 51.1 | 76.3 |
| ViT-L/16 (I21k) | 90.8 | 84.1 | 74.1 | 99.3 | 92.7 | 61.0 | 80.9 | 82.5 | 95.6 | 85.2 | 75.3 | 70.3 | 56.1 | 41.9 | 74.7 | 64.9 | 79.9 | 30.5 | 41.7 | 72.7 |
表 9:跨任务的 VTAB-1k 表现分解。