VGGT: Visual Geometry Grounded Transformer
VGGT: Visual Geometry Grounded Transformer
VGGT:视觉几何接地 Transformer
Jianyuan Wang Affiliation: Visual Geometry Group, University of Oxford Affiliation: Meta AI Minghao Chen Affiliation: Visual Geometry Group, University of Oxford Affiliation: Meta AI Nikita Karaev Affiliation: Visual Geometry Group, University of Oxford Affiliation: Meta AI Andrea Vedaldi Affiliation: Visual Geometry Group, University of Oxford Affiliation: Meta AI Christian Rupprecht Affiliation: Visual Geometry Group, University of Oxford David Novotny Affiliation: Meta AI
Jianyuan Wang 单位: Visual Geometry Group, University of Oxford 单位: Meta AI Minghao Chen 单位: Visual Geometry Group, University of Oxford 单位: Meta AI Nikita Karaev 单位: Visual Geometry Group, University of Oxford 单位: Meta AI Andrea Vedaldi 单位: Visual Geometry Group, University of Oxford 单位: Meta AI Christian Rupprecht 单位: Visual Geometry Group, University of Oxford David Novotny 单位: Meta AI
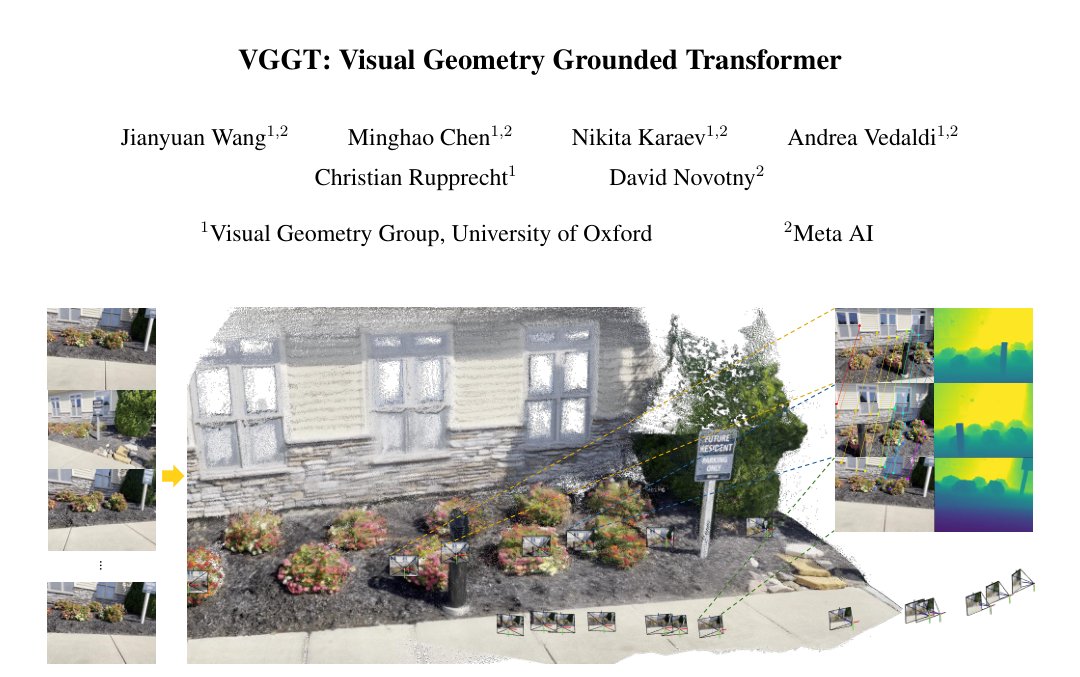
Figure 1: VGGT is a large feed-forward transformer with minimal 3D-inductive biases trained on a trove of 3D-annotated data. It accepts up to hundreds of images and predicts cameras, point maps, depth maps, and point tracks for all images at once in less than a second, which often outperforms optimization-based alternatives without further processing.
图 1:VGGT 是一个大型前馈Transformer,具有最小的 3D 归纳偏置,在大量标注了 3D 数据的数据上进行训练。它最多可接受数百张图像,并在不到一秒的时间内为所有图像预测相机、点图、深度图和点轨迹,这通常在无需进一步处理的情况下就超过了基于优化的替代方法。
Abstract
摘要
We present VGGT, a feed-forward neural network that directly infers all key 3D attributes of a scene, including camera parameters, point maps, depth maps, and 3D point tracks, from one, a few, or hundreds of its views. This approach is a step forward in 3D computer vision, where models have typically been constrained to and specialized for single tasks. It is also simple and efficient, reconstructing images in under one second, and still outperforming alternatives that require post-processing with visual geometry optimization techniques. The network achieves state-of-the-art results in multiple 3D tasks, including camera parameter estimation, multi-view depth estimation, dense point cloud reconstruction, and 3D point tracking. We also show that using pretrained VGGT as a feature backbone significantly enhances downstream tasks, such as non-rigid point tracking and feed-forward novel view synthesis. Code and models are publicly available at https://github.com/facebookresearch/vggt.
我们提出 VGGT,一个前馈神经网络,能从场景的一张、若干张乃至上百张视图中,直接推断该场景的全部关键三维属性,包括相机参数、点图、深度图与三维点轨迹。这是三维计算机视觉的一步前进——以往模型通常被限制在、并专精于单一任务。它也简单高效:重建图像不到一秒,却仍优于需要视觉几何优化后处理的替代方法。该网络在多项三维任务上达到最先进水平,包括相机参数估计、多视图深度估计、稠密点云重建与三维点跟踪。我们还表明,将预训练的 VGGT 用作特征骨干,能显著提升下游任务,例如非刚性点跟踪与前馈新视角合成。代码与模型公开于 https://github.com/facebookresearch/vggt。
1 Introduction
1 引言
We consider the problem of estimating the 3D attributes of a scene, captured in a set of images, utilizing a feed-forward neural network. Traditionally, 3D reconstruction has been approached with visual-geometry methods, utilizing iterative optimization techniques like Bundle Adjustment (BA) [45]. Machine learning has often played an important complementary role, addressing tasks that cannot be solved by geometry alone, such as feature matching and monocular depth prediction. The integration has become increasingly tight, and now state-of-the-art Structure-from-Motion (SfM) methods like VGGSfM [125] combine machine learning and visual geometry end-to-end via differentiable BA. Even so, visual geometry still plays a major role in 3D reconstruction, which increases complexity and computational cost.
我们考虑利用前馈神经网络估计场景的三维属性,该场景被捕获在一组图像中。传统上,三维重建是通过视觉几何方法来实现的,使用像捆绑调整(Bundle Adjustment, BA)[45]这样的迭代优化技术。机器学习通常发挥重要的补充作用,解决仅凭几何无法解决的任务,例如特征匹配和单目深度预测。这两者的结合越来越紧密,现在最先进的基于运动的结构(Structure-from-Motion, SfM)方法,如VGGSfM [125],通过可微的BA将机器学习和视觉几何端到端结合。即便如此,视觉几何在三维重建中仍然起着重要作用,这增加了复杂性和计算成本。
As networks become ever more powerful, we ask if, finally, 3D tasks can be solved directly by a neural network, eschewing geometry post-processing almost entirely. Recent contributions like DUSt3R [129] and its evolution MASt3R [62] have shown promising results in this direction, but these networks can only process two images at once and rely on post-processing to reconstruct more images, fusing pairwise reconstructions.
随着网络变得越来越强大,我们开始问,3D任务是否最终可以被神经网络直接解决,几乎完全不依赖几何后处理。像DUSt3R [129]及其演进版本MASt3R [62]这样的最新研究在这方面显示了有希望的结果,但这些网络一次只能处理两张图像,并且依赖后处理来重建更多图像,通过融合成对的重建结果。
In this paper, we take a further step towards removing the need to optimize 3D geometry in post-processing. We do so by introducing Visual Geometry Grounded Transformer (VGGT), a feed-forward neural network that performs 3D reconstruction from one, a few, or even hundreds of input views of a scene. VGGT predicts a full set of 3D attributes, including camera parameters, depth maps, point maps, and 3D point tracks. It does so in a single forward pass, in seconds. Remarkably, it often outperforms optimization-based alternatives even without further processing. This is a substantial departure from DUSt3R, MASt3R, or VGGSfM, which still require costly iterative post-optimization to obtain usable results.
在本文中,我们进一步迈出了消除后处理优化3D几何需求的一步。我们通过引入视觉几何基础Transformer(VGGT)来实现这一点,这是一种前馈神经网络,可以从场景的单个、少量甚至数百个输入视图中进行3D重建。VGGT预测完整的3D属性,包括相机参数、深度图、点图和3D点轨迹。它在一次前向传递中即可完成,耗时仅几秒。值得注意的是,即使不进行进一步处理,它通常也优于基于优化的替代方法。这与DUSt3R、MASt3R或VGGSfM有显著不同,后者仍需要代价高昂的迭代后优化才能获得可用结果。
We also show that it is unnecessary to design a special network for 3D reconstruction. Instead, VGGT is based on a fairly standard large transformer [119], with no particular 3D or other inductive biases (except for alternating between frame-wise and global attention), but trained on a large number of publicly available datasets with 3D annotations. VGGT is thus built in the same mold as large models for natural language processing and computer vision, such as GPTs [148, 29, 1], CLIP [86], DINO [10, 78], and Stable Diffusion [34]. These have emerged as versatile backbones that can be fine-tuned to solve new, specific tasks. Similarly, we show that the features computed by VGGT can significantly enhance downstream tasks like point tracking in dynamic videos, and novel view synthesis.
我们还展示了设计一个用于3D重建的特殊网络是没有必要的。相反,VGGT 基于一个相当标准的大型Transformer [119],没有特定的3D或其他归纳偏置(除了在帧级注意力和全局注意力之间交替),但在大量公开可用的带有3D标注的数据集上进行了训练。因此,VGGT 是按与自然语言处理和计算机视觉的大型模型相同的模式构建的,比如 GPT 系列 [148, 29, 1]、CLIP [86]、DINO [10, 78] 和 Stable Diffusion [34]。它们已经成为多功能的骨干网络,可以微调以解决新的特定任务。类似地,我们展示了 VGGT 计算的特征可以显著增强下游任务,如动态视频中的点跟踪和新视角合成。
There are several recent examples of large 3D neural networks, including DepthAnything [142], MoGe [128], and LRM [49]. However, these models only focus on a single 3D task, such as monocular depth estimation or novel view synthesis. In contrast, VGGT uses a shared backbone to predict all 3D quantities of interest together. We demonstrate that learning to predict these interrelated 3D attributes enhances overall accuracy despite potential redundancies. At the same time, we show that, during inference, we can derive the point maps from separately predicted depth and camera parameters, obtaining better accuracy compared to directly using the dedicated point map head.
最近有几个大型 3D 神经网络的例子,包括 DepthAnything [142]、MoGe [128] 和 LRM [49]。然而,这些模型只关注单一的 3D 任务,例如单目深度估计或新视图合成。相比之下,VGGT 使用共享的主干网络来共同预测所有感兴趣的 3D 量。我们证明了 学习 预测这些相互关联的 3D 属性可以提高整体准确性,尽管可能存在冗余。同时,我们展示了在 推理 过程中,我们可以通过单独预测的深度和相机参数来推导点图,并且与直接使用专用点图头相比,获得了更好的准确性。
To summarize, we make the following contributions: (1) We introduce VGGT, a large feed-forward transformer that, given one, a few, or even hundreds of images of a scene, can predict all its key 3D attributes, including camera intrinsics and extrinsics, point maps, depth maps, and 3D point tracks, in seconds. (2) We demonstrate that VGGT’s predictions are directly usable, being highly competitive and usually better than those of state-of-the-art methods that use slow post-processing optimization techniques. (3) We also show that, when further combined with BA post-processing, VGGT achieves state-of-the-art results across the board, even when compared to methods that specialize in a subset of 3D tasks, often improving quality substantially.
总而言之,我们做出了以下贡献:(1)我们提出了 VGGT,一种大型前馈Transformer,能够在给定单张、少量甚至数百张场景图像的情况下,在几秒钟内预测其所有关键的三维属性,包括相机内参和外参、点图、深度图和三维点跟踪。(2)我们证明了 VGGT 的预测结果可以直接使用,其性能高度具有竞争力,通常优于那些依赖缓慢后处理优化技术的最先进方法。(3)我们还表明,当进一步结合 BA 后处理时,VGGT 在各方面都能取得最先进的结果,即使与专注于特定三维任务的某些方法相比,也常常显著提高质量。
We make our code and models publicly available at https://github.com/facebookresearch/vggt. We believe that this will facilitate further research in this direction and benefit the computer vision community by providing a new foundation for fast, reliable, and versatile 3D reconstruction.
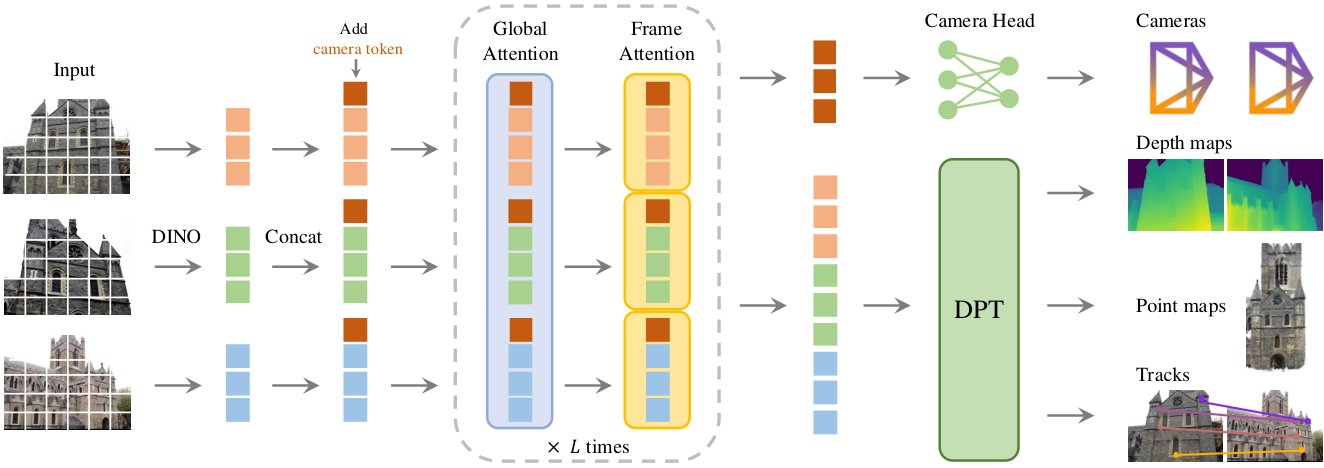
Figure 2: Architecture Overview. Our model first patchifies the input images into tokens by DINO, and appends camera tokens for camera prediction. It then alternates between frame-wise and global self attention layers. A camera head makes the final prediction for camera extrinsics and intrinsics, and a DPT [87] head for any dense output.
图 2:架构概览。我们的模型首先通过 DINO 将输入图像分块为 token,并附加用于相机预测的相机 token。随后,它在帧级自注意力层和全局自注意力层之间交替进行。相机头负责对相机外参和内参进行最终预测,而 DPT [87] 头用于任何密集输出。
2 Related Work
2 相关工作
Structure from Motion
is a classic computer vision problem [45, 80, 77] that involves estimating camera parameters and reconstructing sparse point clouds from a set of images of a static scene captured from different viewpoints. The traditional SfM pipeline [103, 2, 36, 134, 94, 70] consists of multiple stages, including image matching, triangulation, and bundle adjustment. COLMAP [94] is the most popular framework based on the traditional pipeline. In recent years, deep learning has improved many components of the SfM pipeline, with keypoint detection [149, 21, 31, 116] and image matching [92, 11, 99, 67] being two primary areas of focus. Recent methods [160, 118, 109, 131, 122, 112, 113, 5, 102, 125] explored end-to-end differentiable SfM, where VGGSfM [125] started to outperform traditional algorithms on challenging phototourism scenarios.
运动结构
是一个经典的计算机视觉问题 [45, 80, 77],涉及从一组从不同视角拍摄的静态场景图像中估计相机参数和重建稀疏点云。传统的 SfM 流水线 [103, 2, 36, 134, 94, 70] 包括多个阶段,包括图像匹配、三角测量和束调整。COLMAP [94] 是基于传统流水线的最流行框架。近年来,深度学习改善了 SfM 流水线的许多组件,其中关键点检测 [149, 21, 31, 116] 和图像匹配 [92, 11, 99, 67] 是两个主要的关注领域。最近的方法 [160, 118, 109, 131, 122, 112, 113, 5, 102, 125] 探索了端到端可微的 SfM,其中 VGGSfM [125] 开始在具有挑战性的摄影旅游场景中超越传统算法。
Multi-view Stereo
aims to densely reconstruct the geometry of a scene from multiple overlapping images, typically assuming known camera parameters, which are often estimated with SfM. MVS methods can be divided into three categories: traditional handcrafted [38, 39, 96, 130], global optimization [74, 37, 133, 147], and learning-based methods [145, 42, 72, 84, 157]. As in SfM, learning-based MVS approaches have recently seen a lot of progress. Here, DUSt3R [129] and MASt3R [62] directly estimate aligned dense point clouds from a pair of views, similar to MVS but without requiring camera parameters. Some concurrent works [127, 111, 156, 141] explore replacing DUSt3R’s test-time optimization with neural networks, though these attempts achieve only suboptimal or comparable performance to DUSt3R. Instead, VGGT outperforms DUSt3R and MASt3R by a large margin.
多视角立体
旨在从多张重叠图像中密集重建场景的几何结构,通常假设已知摄像机参数,这些参数通常通过SfM估计。MVS方法可以分为三类:传统手工方法 [38, 39, 96, 130]、全局优化方法 [74, 37, 133, 147] 和基于学习的方法 [145, 42, 72, 84, 157]。与SfM一样,基于学习的MVS方法近年来也取得了很大进展。在这里,DUSt3R [129] 和 MASt3R [62] 直接从一对视图估计对齐的密集点云,类似于MVS,但不需要摄像机参数。一些同期工作 [127, 111, 156, 141] 探索用神经网络替代DUSt3R的测试时优化,尽管这些尝试只实现了次优或与DUSt3R相当的性能。相反,VGGT则远超DUSt3R和MASt3R。
Tracking-Any-Point
was first introduced in Particle Video [91] and revived by PIPs [44] during the deep learning era, aiming to track points of interest across video sequences including dynamic motions. Given a video and some 2D query points, the task is to predict 2D correspondences of these points in all other frames. TAP-Vid [23] proposed three benchmarks for this task and a simple baseline method later improved in TAPIR [24]. CoTracker [56, 55] utilized correlations between different points to track through occlusions, while DOT [60] enabled dense tracking through occlusions. Recently, TAPTR [63] proposed an end-to-end transformer for this task, and LocoTrack [13] extended commonly used pointwise features to nearby regions. All of these methods are specialized point trackers. Here, we demonstrate that VGGT’s features yield state-of-the-art tracking performance when coupled with existing point trackers.
跟踪任意点
最早在 Particle Video [91] 中引入,并在深度学习时代由 PIPs [44] 重新提出,旨在跟踪视频序列中感兴趣的点,包括动态运动。给定一个视频和一些二维查询点,任务是预测这些点在所有其他帧中的二维对应关系。TAP-Vid [23] 为该任务提出了三个基准测试,并在 TAPIR [24] 中提出了一个简单的基线方法并进行了改进。CoTracker [56, 55] 利用不同点之间的相关性来实现遮挡中的跟踪,而 DOT [60] 则实现了遮挡中的密集跟踪。最近,TAPTR [63] 提出了一个用于该任务的端到端Transformer,而 LocoTrack [13] 将常用的逐点特征扩展到附近区域。所有这些方法都是专门的点跟踪器。在这里,我们展示了当 VGGT 的特征与现有点跟踪器结合使用时,能够实现最先进的跟踪性能。
3 Method
3 方法
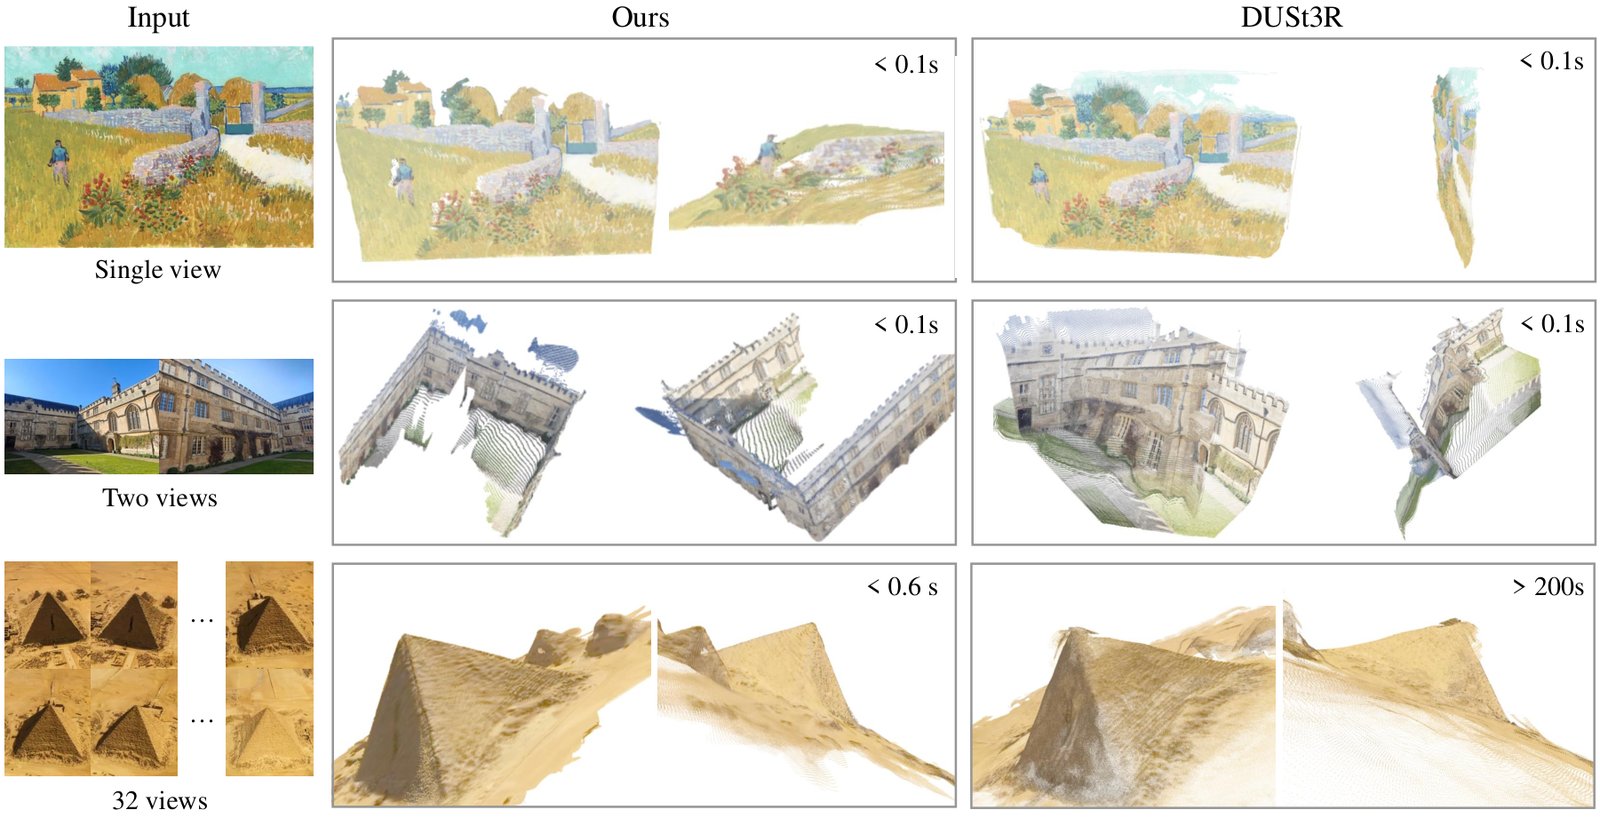
Figure 3: Qualitative comparison of our predicted 3D points to DUSt3R on in-the-wild images. As shown in the top row, our method successfully predicts the geometric structure of an oil painting, while DUSt3R predicts a slightly distorted plane. In the second row, our method correctly recovers a 3D scene from two images with no overlap, while DUSt3R fails. The third row provides a challenging example with repeated textures, while our prediction is still high-quality. We do not include examples with more than 32 frames, as DUSt3R runs out of memory beyond this limit.
图 3:在自然场景图像上,我们预测的 3D 点与 DUSt3R 的定性比较。如上排所示,我们的方法成功预测了一幅油画的几何结构,而 DUSt3R 预测的则是略微扭曲的平面。在第二排中,我们的方法能够正确从两张没有重叠的图像中恢复出 3D 场景,而 DUSt3R 则失败。第三排提供了一个具有重复纹理的挑战性示例,但我们的预测仍然是高质量的。我们未包含超过 32 帧的示例,因为 DUSt3R 超过此限制后会耗尽内存。
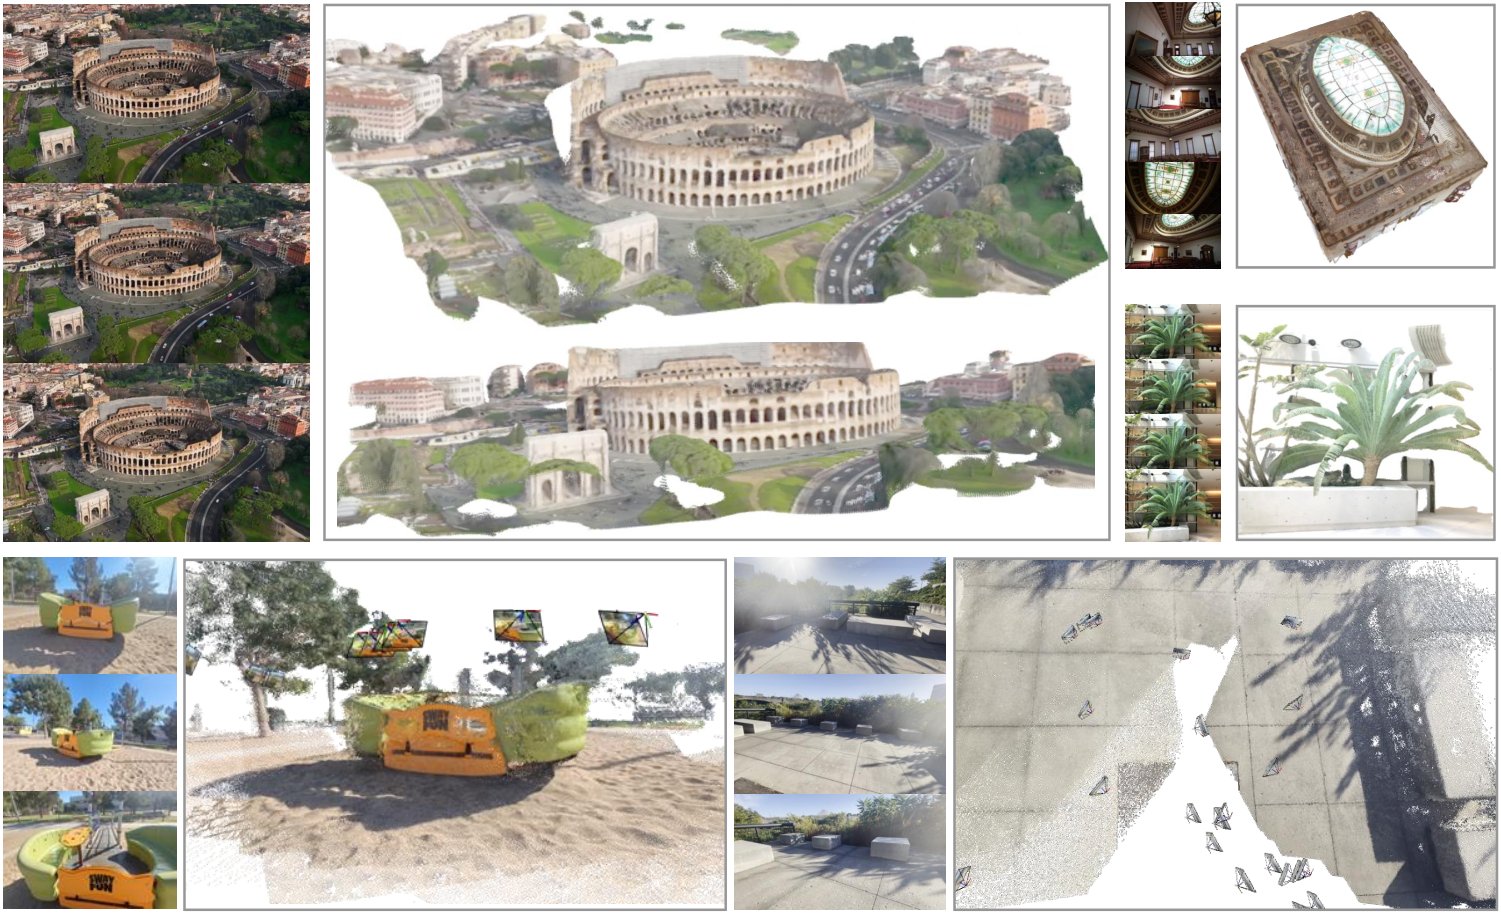
Figure 4: Additional Visualizations of Point Map Estimation. Camera frustums illustrate the estimated camera poses. Explore our interactive demo for better visualization quality.
图 4:点图估计的附加可视化。相机视锥体显示了估计的相机位姿。请探索我们的交互式演示以获得更好的可视化效果。
We introduce VGGT, a large transformer that ingests a set of images as input and produces a variety of 3D quantities as output. We start by introducing the problem in Sec. 3.1, followed by our architecture in Sec. 3.2 and its prediction heads in Sec. 3.3, and finally the training setup in Sec. 3.4.
我们介绍了 VGGT,一种大型Transformer,它将一组图像作为输入,并生成各种 3D 量作为输出。我们首先在第 3.1 节介绍问题,然后在第 3.2 节介绍我们的架构及其在第 3.3 节的预测头,最后在第 3.4 节介绍训练设置。
3.1 Problem definition and notation
3.1 问题定义与记号
The input is a sequence of RGB images observing the same 3D scene. VGGT’s transformer is a function that maps this sequence to a corresponding set of 3D annotations, one per frame:
输入是一个序列的RGB 图像 ,观察同一个 3D 场景。VGGT 的Transformer是一个函数,将该序列映射到相应的一组 3D 注释,每帧一个:
The transformer thus maps each image to its camera parameters (intrinsics and extrinsics), its depth map , its point map , and a grid of -dimensional features for point tracking. We explain next how these are defined.
因此,变压器将每张图像映射到其相机参数 (内参和外参)、其深度图 、其点图 ,以及一个的维特征网格用于点跟踪。接下来我们解释这些是如何定义的。
For the camera parameters , we use the parametrization from [125] and set which is the concatenation of the rotation quaternion , the translation vector , and the field of view . We assume that the camera’s principal point is at the image center, which is common in SfM frameworks [95, 125].
对于相机参数 ,我们使用来自 [125] 的参数化方法,并设置 ,它是旋转四元数 、平移向量和视场的连接。我们假设相机的主点位于图像中心,这在 SfM 框架中很常见 [95, 125]。
We denote the domain of the image with i.e., the set of pixel locations. The depth map associates each pixel location with its corresponding depth value , as observed from the -th camera. Likewise, the point map associates each pixel with its corresponding 3D scene point . Importantly, like in DUSt3R [129], the point maps are viewpoint invariant, meaning that the 3D points are defined in the coordinate system of the first camera , which we take as the world reference frame.
我们用表示图像的域,即像素位置的集合。深度图将每个像素位置与其对应的深度值关联,该深度值由第个相机观测到。类似地,点图将每个像素与其对应的 3D 场景点关联。重要的是,像在 DUSt3R [129] 中一样,点图是视点不变的,这意味着 3D 点在第一台相机的坐标系中定义,我们将其作为世界参考系。
Finally, for keypoint tracking, we follow track-any-point methods such as [57, 25]. Namely, given a fixed query image point in the query image , the network outputs a track formed by the corresponding 2D points in all images .
最后,对于关键点跟踪,我们遵循诸如 [57, 25] 的任意点跟踪方法。也就是说,给定查询图像中的固定查询图像点 ,网络输出由所有图像中对应的 2D 点组成的轨迹 。
Note that the transformer above does not output the tracks directly but instead features , which are used for tracking. The tracking is delegated to a separate module, described in Sec. 3.3, which implements a function It ingests the query point and the dense tracking features output by the transformer and then computes the track. The two networks and are trained jointly end-to-end.
请注意,上述Transformer并不会直接输出轨迹,而是输出用于跟踪的特征 。跟踪任务被委托给一个单独的模块,如第 3.3 节所述,该模块实现了函数 。它接收查询点和由Transformer输出的密集跟踪特征 ,然后计算轨迹。这两个网络和是端到端联合训练的。
Order of Predictions.
The order of the images in the input sequence is arbitrary, except that the first image is chosen as the reference frame. The network architecture is designed to be permutation equivariant for all but the first frame.
预测顺序。
输入序列中图像的顺序是任意的,除了第一张图像被选择为参考帧。网络架构被设计为对除第一帧之外的所有帧具有置换等变性。
Over-complete Predictions.
Notably, not all quantities predicted by VGGT are independent. For example, as shown by DUSt3R [129], the camera parameters can be inferred from the invariant point map , for instance, by solving the Perspective--Point (PnP) problem [61, 35]. Furthermore, the depth maps can be deduced from the point map and the camera parameters. However, as we show in Sec. 4.5, tasking VGGT with explicitly predicting all aforementioned quantities during training brings substantial performance gains, even when these are related by closed-form relationships. Meanwhile, during inference, it is observed that combining independently estimated depth maps and camera parameters produces more accurate 3D points compared to directly employing a specialized point map branch.
过度完整的预测。
值得注意的是,并非 VGGT 预测的所有量都是独立的。例如,正如 DUSt3R [129] 所示,相机参数可以从不变量点图推断出来,例如,通过求解透视--点(PnP)问题 [61, 35]。此外,深度图可以从点图和相机参数中推导出来。然而,正如我们在第 4.5 节中所展示的,即使这些量通过封闭形式的关系相互关联,在训练过程中要求 VGGT 明确预测上述所有量也能带来显著的性能提升。与此同时,在推理阶段,观察到将独立估计的深度图和相机参数结合使用,比直接使用专门的点图分支产生的 3D 点更为精确。
3.2 Feature Backbone
3.2 特征骨干
Following recent works in 3D deep learning [132, 129, 53], we design a simple architecture with minimal 3D inductive biases, letting the model learn from ample quantities of 3D-annotated data. In particular, we implement the model as a large transformer [119]. To this end, each input image is initially patchified into a set of tokens[^1] through DINO [78]. The combined set of image tokens from all frames, i.e., , is subsequently processed through the main network structure, alternating frame-wise and global self-attention layers.
继近期在3D深度学习方面的工作[132, 129, 53]之后,我们设计了一个具有最小3D归纳偏差的简单架构,让模型从大量3D标注数据中学习。具体而言,我们将模型实现为一个大型Transformer[119]。为此,每个输入图像最初通过DINO[78]被切分成一组令牌[^1]。来自所有帧的图像令牌的组合集合,即,随后通过主网络结构处理,在帧级和全局自注意力层之间交替进行。
Alternating-Attention.
We slightly adjust the standard transformer design by introducing Alternating-Attention (AA), making the transformer focus within each frame and globally in an alternate fashion. Specifically, frame-wise self-attention attends to the tokens within each frame separately, and global self-attention attends to the tokens across all frames jointly. This strikes a balance between integrating information across different images and normalizing the activations for the tokens within each image. By default, we employ layers of global and frame-wise attention. In Sec. 4, we demonstrate that our AA architecture brings significant performance gains. Note that our architecture does not employ any cross-attention layers, only self-attention ones.
交替注意力。
我们对标准 Transformer 设计稍作调整,引入交替注意力(Alternating-Attention,AA),使 Transformer 交替地在帧内与全局聚焦。具体而言,帧内自注意力分别关注每帧内的 token ,全局自注意力则联合关注所有帧的 token 。这在跨图像信息融合与各图像内 token 激活归一化之间取得平衡。默认情况下,我们使用 层全局与帧内注意力。第 4 节表明 AA 架构带来显著性能提升。注意我们的架构不使用任何交叉注意力层,仅使用自注意力层。
3.3 Prediction heads
3.3 预测头
Here, we describe how predicts the camera parameters, depth maps, point maps, and point tracks. First, for each input image , we augment the corresponding image tokens with an additional camera token and four register tokens [19] . The concatenation of is then passed to the AA transformer, yielding output tokens . Here, the camera token and register tokens of the first frame (, ) are set to a different set of learnable tokens than those of all other frames (), which are also learnable. This allows the model to distinguish the first frame from the rest, and to represent the 3D predictions in the coordinate frame of the first camera. Note that the refined camera and register tokens now become frame-specific—–this is because our AA transformer contains frame-wise self-attention layers that allow the transformer to match the camera and register tokens with the corresponding tokens from the same image. Following common practice, the output register tokens are discarded while , are used for prediction.
在这里,我们描述如何预测相机参数、深度图、点图和点轨迹。 首先,对于每个输入图像,我们使用额外的相机标记和四个寄存器标记 [19]来增强相应的图像标记。 然后的串联被传递到 AA 变压器,产生输出标记。 这里,第一帧(,)的相机令牌和寄存器令牌被设置为与所有其他帧()不同的一组可学习令牌,这些帧也是可学习的。 这使得模型能够将第一帧与其余帧区分开来,并在第一相机的坐标系中表示 3D 预测。 请注意,精炼的相机和注册标记现在变得特定于帧 - 这是因为我们的 AA 转换器包含逐帧自注意力层,允许转换器将相机和注册标记与同一图像中的相应标记进行匹配。 按照惯例,输出寄存器令牌被丢弃,而、用于预测。
Coordinate Frame.
As noted above, we predict cameras, point maps, and depth maps in the coordinate frame of the first camera . As such, the camera extrinsics output for the first camera are set to the identity, i.e., the first rotation quaternion is and the first translation vector is . Recall that the special camera and register tokens allow the transformer to identify the first camera.
坐标系。
如上所述,我们在第一台相机的坐标系中预测相机、点图和深度图。因此,第一台相机的外参输出设置为单位矩阵,即第一旋转四元数为 ,第一平移向量为 。请注意,特殊相机标记和注册标记允许Transformer识别第一台相机。
Camera Predictions.
The camera parameters are predicted from the output camera tokens using four additional self-attention layers followed by a linear layer. This forms the camera head that predicts the camera intrinsics and extrinsics.
相机预测。
相机参数是使用四个额外的自注意力层后跟一个线性层,从输出的相机令牌预测的。这形成了预测相机内部参数和外部参数的相机头。
Dense Predictions.
The output image tokens are used to predict the dense outputs, i.e., the depth maps , point maps , and tracking features . More specifically, are first converted to dense feature maps with a DPT layer [87]. Each is then mapped with a convolutional layer to the corresponding depth and point maps and . Additionally, the DPT head also outputs dense features , which serve as input to the tracking head. We also predict the aleatoric uncertainty [58, 76] and for each depth and point map, respectively. As described in Sec. 3.4, the uncertainty maps are used in the loss and, after training, are proportional to the model’s confidence in the predictions.
密集预测。
输出图像标记用于预测密集输出,即深度图 、点图和跟踪特征 。更具体地, 首先通过 DPT 层 [87] 转换为密集特征图 。随后,每个都通过一个卷积层映射到对应的深度图和点图和 。此外,DPT 头还输出密集特征 ,作为跟踪头的输入。我们还预测每个深度图和点图分别的偶然不确定性和 。如 3.4 节所述,不确定性图用于损失函数,并在训练结束后与模型对预测的置信度成比例。
Tracking.
In order to implement the tracking module , we use the CoTracker2 architecture [57], which takes the dense tracking features as input. More specifically, given a query point in a query image (during training, we always set , but any other image can be potentially used as a query), the tracking head predicts the set of 2D points in all images that correspond to the same 3D point as . To do so, the feature map of the query image is first bilinearly sampled at the query point to obtain its feature. This feature is then correlated with all other feature maps to obtain a set of correlation maps. These maps are then processed by self-attention layers to predict the final 2D points , which are all in correspondence with . Note that, similar to VGGSfM [125], our tracker does not assume any temporal ordering of the input frames and, hence, can be applied to any set of input images, not just videos.
追踪。
为了实现跟踪模块 ,我们使用 CoTracker2 架构[57],它将密集的跟踪特征作为输入。 更具体地说,给定查询图像中的查询点(在训练期间,我们始终设置,但任何其他图像都可以用作查询),跟踪头预测所有图像中的 2D 点集,这些点对应于与相同的 3D 点。 为此,首先在查询点处对查询图像的特征图进行双线性采样以获得其特征。 然后将该特征与所有其他特征图相关联以获得一组相关图。 然后,这些图通过自注意力层进行处理,以预测最终的 2D 点,这些点都与相对应。 请注意,与 VGGSfM [125] 类似,我们的跟踪器不假设输入帧的任何时间顺序,因此可以应用于任何输入图像集,而不仅仅是视频。
3.4 Training
3.4 训练
Training Losses.
We train the VGGT model end-to-end using a multi-task loss:
训练损失。
我们使用多任务损失对 VGGT 模型进行端到端训练:
We found that the camera (), depth (), and point-map () losses have similar ranges and do not need to be weighted against each other. The tracking loss is down-weighted with a factor of . We describe each loss term in turn.
我们发现相机 ()、深度 () 和点图 () 的损失具有相似的范围,不需要相互加权。跟踪损失被按的系数降低权重。我们依次描述每个损失项。
The camera loss supervises the cameras : comparing the predicted cameras with the ground truth using the Huber loss .
相机损失监督相机: 将预测的相机与真实值进行比较,使用 Huber 损失。
The depth loss follows DUSt3R [129] and implements the aleatoric-uncertainty loss [75, 59] weighing the discrepancy between the predicted depth and the ground-truth depth with the predicted uncertainty map . Differently from DUSt3R, we also apply a gradient-based term, which is widely used in monocular depth estimation. Hence, the depth loss is \mathcal{L}_{\text{depth}}=\sum_{i=1}^{N}\|\Sigma_{i}^{D}\odot(\hat{D}_{i}-D_{i})\|+\|\Sigma_{i}^{D}\odot({\scalebox{0.75}{\nabla}}\hat{D}_{i}-{\scalebox{0.75}{\nabla}}D_{i})\|-\alpha\log\Sigma_{i}^{D}, where is the channel-broadcast element-wise product. The point map loss is defined analogously but with the point-map uncertainty : \mathcal{L}_{\text{pmap}}=\sum_{i=1}^{N}\|\Sigma_{i}^{P}\odot(\hat{P}_{i}-P_{i})\|+\|\Sigma_{i}^{P}\odot({\scalebox{0.75}{\nabla}}\hat{P}_{i}-{\scalebox{0.75}{\nabla}}P_{i})\|-\alpha\log\Sigma_{i}^{P}.
深度损失遵循 DUSt3R [129] 并实现了 aleatoric-uncertainty 损失 [75, 59],该损失使用预测的不确定性图对预测深度与真实深度之间的差异进行加权。与 DUSt3R 不同的是,我们还应用了基于梯度的项,这在单目深度估计中被广泛使用。因此,深度损失为\mathcal{L}_{\text{depth}}=\sum_{i=1}^{N}\|\Sigma_{i}^{D}\odot(\hat{D}_{i}-D_{i})\|+\|\Sigma_{i}^{D}\odot({\scalebox{0.75}{\nabla}}\hat{D}_{i}-{\scalebox{0.75}{\nabla }}D_{i})\|-\alpha\log\Sigma_{i}^{D},其中是通道广播的逐元素乘法。点图损失以类似方式定义,但使用点图不确定性 :\mathcal{L}_{\text{pmap}}=\sum_{i=1}^{N}\|\Sigma_{i}^{P}\odot(\hat{P}_{i}-P_{i})\|+\|\Sigma_{i}^{P}\odot({\scalebox{0.75}{ \nabla}}\hat{P}_{i}-{\scalebox{0.75}{\nabla }}P_{i})\|-\alpha\log\Sigma_{i}^{P}。
Finally, the tracking loss is given by . Here, the outer sum runs over all ground-truth query points in the query image , is ’s ground-truth correspondence in image , and is the corresponding prediction obtained by the application of the tracking module. Additionally, following CoTracker2 [57], we apply a visibility loss (binary cross-entropy) to estimate whether a point is visible in a given frame.
最后,跟踪损失由给出。这里,外层求和遍历查询图像中的所有真实查询点 , 是在图像中的真实对应点, 是通过应用跟踪模块获得的相应预测。此外,遵循 CoTracker2 [57],我们应用可见性损失(二元交叉熵)来估计某个点在给定帧中是否可见。
Ground Truth Coordinate Normalization.
If we scale a scene or change its global reference frame, the images of the scene are not affected at all, meaning that any such variant is a legitimate result of 3D reconstruction. We remove this ambiguity by normalizing the data, thus making a canonical choice and task the transformer to output this particular variant. We follow [129] and, first, express all quantities in the coordinate frame of the first camera . Then, we compute the average Euclidean distance of all 3D points in the point map to the origin and use this scale to normalize the camera translations , the point map , and the depth map . Importantly, unlike [129], we do not apply such normalization to the predictions output by the transformer; instead, we force it to learn the normalization we choose from the training data.
地面真实坐标归一化。
如果我们对一个场景进行缩放或改变其全局参考框架,场景的图像不会受到任何影响,这意味着任何此类变体都是三维重建的合法结果。我们通过对数据进行归一化来消除这种歧义,从而做出规范选择,并让Transformer输出这一特定变体。我们遵循 [129] 的方法,首先,将所有量表示在第一台相机的坐标系中。然后,我们计算点图中所有三维点到原点的平均欧几里得距离,并使用该比例来归一化相机平移、点图和深度图。重要的是,与 [129] 不同,我们 不 将这种归一化应用于Transformer输出的预测结果;相反,我们迫使其从训练数据中学习我们选择的归一化。
Implementation Details.
By default, we employ layers of global and frame-wise attention, respectively. The model consists of approximately 1.2 billion parameters in total. We train the model by optimizing the training loss (2) with the AdamW optimizer for K iterations. We use a cosine learning rate scheduler with a peak learning rate of and a warmup of K iterations. For every batch, we randomly sample – frames from a random training scene. The input frames, depth maps, and point maps are resized to a maximum dimension of pixels. The aspect ratio is randomized between 0.33 and 1.0. We also randomly apply color jittering, Gaussian blur, and grayscale augmentation to the frames. The training runs on 64 A100 GPUs over nine days. We employ gradient norm clipping with a threshold of to ensure training stability. We leverage bfloat16 precision and gradient checkpointing to improve GPU memory and computational efficiency.
实施细节。
默认情况下,我们分别采用层全局和帧级注意力。该模型总共有大约 12 亿个参数。我们使用 AdamW 优化器通过优化训练损失 (2) 来训练模型,训练K 次迭代。我们使用余弦学习率调度器,峰值学习率为 ,并进行K 次迭代的预热。在每个批次中,我们从随机训练场景中随机采样 – 帧。输入帧、深度图和点图的最大尺寸调整为像素。长宽比在 0.33 到 1.0 之间随机变化。我们还会随机对帧应用颜色抖动、高斯模糊和灰度增强。训练在 64 张 A100 GPU 上运行九天。我们使用阈值为的梯度范数裁剪以确保训练稳定性。我们采用 bfloat16 精度和梯度检查点来提高 GPU 内存和计算效率。
Training Data.
The model was trained using a large and diverse collection of datasets, including: Co3Dv2 [88], BlendMVS [146], DL3DV [69], MegaDepth [64], Kubric [41], WildRGB [135], ScanNet [18], HyperSim [89], Mapillary [71], Habitat [107], Replica [104], MVS-Synth [50], PointOdyssey [159], Virtual KITTI [7], Aria Synthetic Environments [82], Aria Digital Twin [82], and a synthetic dataset of artist-created assets similar to Objaverse [20]. These datasets span various domains, including indoor and outdoor environments, and encompass synthetic and real-world scenarios. The 3D annotations for these datasets are derived from multiple sources, such as direct sensor capture, synthetic engines, or SfM techniques [95]. The combination of our datasets is broadly comparable to those of MASt3R [30] in size and diversity.
训练数据。
该模型使用了大量且多样化的数据集进行训练,包括:Co3Dv2 [88]、BlendMVS [146]、DL3DV [69]、MegaDepth [64]、Kubric [41]、WildRGB [135]、ScanNet [18]、HyperSim [89]、Mapillary [71]、Habitat [107]、Replica [104]、MVS-Synth [50]、PointOdyssey [159]、Virtual KITTI [7]、Aria Synthetic Environments [82]、Aria Digital Twin [82],以及类似于 Objaverse [20] 的艺术家创建资产的合成数据集。这些数据集涵盖了各种领域,包括室内和室外环境,并包括合成和现实世界的场景。这些数据集的 3D 标注来源于多种途径,如直接传感器采集、合成引擎或 SfM 技术 [95]。我们的数据集组合在规模和多样性上与 MASt3R [30] 相当。
4 Experiments
4 实验
| Methods | Re10K (unseen) | CO3Dv2 | Time |
|---|---|---|---|
| AUC@30 | AUC@30 | ||
| Colmap+SPSG [92] | 45.2 | 25.3 | 15s |
| PixSfM [66] | 49.4 | 30.1 | 20s |
| PoseDiff [124] | 48.0 | 66.5 | 7s |
| DUSt3R [129] | 67.7 | 76.7 | 7s |
| MASt3R [62] | 76.4 | 81.8 | 9s |
| VGGSfM v2 [125] | 78.9 | 83.4 | 10s |
| MV-DUSt3R [111] ‡ | 71.3 | 69.5 | 0.6s |
| CUT3R [127] ‡ | 75.3 | 82.8 | 0.6s |
| FLARE [156] ‡ | 78.8 | 83.3 | 0.5s |
| Fast3R [141] ‡ | 72.7 | 82.5 | 0.2s |
| Ours (Feed-Forward) | 85.3 | 88.2 | 0.2s |
| Ours (with BA) | 93.5 | 91.8 | 1.8s |
Table 1: Camera Pose Estimation on RealEstate10K [161] and CO3Dv2 [88] with 10 random frames. All metrics the higher the better. None of the methods were trained on the Re10K dataset. Runtime were measured using one H100 GPU. Methods marked with ‡ represent concurrent work.
| 方法 | Re10K (未见) | CO3Dv2 | 时间 |
|---|---|---|---|
| AUC@30 | AUC@30 | ||
| Colmap+SPSG [92] | 45.2 | 25.3 | 15s |
| PixSfM [66] | 49.4 | 30.1 | 20s |
| 姿态差异 [124] | 48.0 | 66.5 | 7s |
| DUSt3R [129] | 67.7 | 76.7 | 7s |
| MASt3R [62] | 76.4 | 81.8 | 9s |
| VGGSfM v2 [125] | 78.9 | 83.4 | 10s |
| MV-DUSt3R [111] ‡ | 71.3 | 69.5 | 0.6s |
| CUT3R [127] ‡ | 75.3 | 82.8 | 0.6s |
| 火焰 [156] ‡ | 78.8 | 83.3 | 0.5s |
| Fast3R [141] ‡ | 72.7 | 82.5 | 0.2s |
| 我们的(前馈) | 85.3 | 88.2 | 0.2s |
| 我们的(带 BA) | 93.5 | 91.8 | 1.8s |
表1:在 RealEstate10K [161] 和 CO3Dv2 [88] 上使用 10 帧随机图像进行的相机位姿估计。所有指标数值越高越好。所有方法均未在 Re10K 数据集上进行训练。运行时间在一块 H100 GPU 上测量。带 ‡ 标记的方法表示同时进行的工作。
| Known GT | Method | Acc. | Comp. | Overall |
|---|---|---|---|---|
| camera | ||||
| ✓ | Gipuma [40] | 0.283 | 0.873 | 0.578 |
| ✓ | MVSNet [144] | 0.396 | 0.527 | 0.462 |
| ✓ | CIDER [139] | 0.417 | 0.437 | 0.427 |
| ✓ | PatchmatchNet [121] | 0.427 | 0.377 | 0.417 |
| ✓ | MASt3R [62] | 0.403 | 0.344 | 0.374 |
| ✓ | GeoMVSNet [157] | 0.331 | 0.259 | 0.295 |
| ✗ | DUSt3R [129] | 2.677 | 0.805 | 1.741 |
| ✗ | Ours | 0.389 | 0.374 | 0.382 |
Table 2: Dense MVS Estimation on the DTU [51] Dataset. Methods operating with known ground-truth camera are in the top part of the table, while the bottom part contains the methods that do not know the ground-truth camera.
| 已知GT | 方法 | Acc. | 计算机 | 总体 |
|---|---|---|---|---|
| camera | ||||
| ✓ | Gipuma [40] | 0.283 | 0.873 | 0.578 |
| ✓ | MVSNet [144] | 0.396 | 0.527 | 0.462 |
| ✓ | 苹果酒 [139] | 0.417 | 0.437 | 0.427 |
| ✓ | PatchmatchNet [121] | 0.427 | 0.377 | 0.417 |
| ✓ | MASt3R [62] | 0.403 | 0.344 | 0.374 |
| ✓ | GeoMVSNet [157] | 0.331 | 0.259 | 0.295 |
| ✗ | DUSt3R [129] | 2.677 | 0.805 | 1.741 |
| ✗ | 我们的 | 0.389 | 0.374 | 0.382 |
表 2:在 DTU [51] 数据集上的密集 MVS 估计。 使用已知真实相机的的方法位于表格的上部分,而底部部分包含不使用真实相机的方法。
| Methods | Acc. | Comp. | Overall | Time |
|---|---|---|---|---|
| DUSt3R | 1.167 | 0.842 | 1.005 | 7s |
| MASt3R | 0.968 | 0.684 | 0.826 | 9s |
| Ours (Point) | 0.901 | 0.518 | 0.709 | 0.2s |
| Ours (Depth + Cam) | 0.873 | 0.482 | 0.677 | 0.2s |
Table 3: Point Map Estimation on ETH3D [97]. DUSt3R and MASt3R use global alignment while ours is feed-forward and, hence, much faster. The row Ours (Point) indicates the results using the point map head directly, while Ours (Depth + Cam) denotes constructing point clouds from the depth map head combined with the camera head.
| 方法 | Acc. | 计算机 | 总体 | 时间 |
|---|---|---|---|---|
| DUSt3R | 1.167 | 0.842 | 1.005 | 7s |
| 大师 | 0.968 | 0.684 | 0.826 | 9s |
| 我们(点) | 0.901 | 0.518 | 0.709 | 0.2s |
| 我们的(深度 + 相机) | 0.873 | 0.482 | 0.677 | 0.2s |
表3:ETH3D 上的点图估计 [97]。 DUSt3R 和 MASt3R 使用全局对齐,而我们的方法是前馈的,因此速度更快。行 Ours (Point) 表示直接使用点图头的结果,而 Ours (Depth + Cam) 表示使用深度图头结合相机头构建点云的结果。
| Method | AUC@5 | AUC@10 | AUC@20 |
|---|---|---|---|
| SuperGlue [92] | 16.2 | 33.8 | 51.8 |
| LoFTR [105] | 22.1 | 40.8 | 57.6 |
| DKM [32] | 29.4 | 50.7 | 68.3 |
| CasMTR [9] | 27.1 | 47.0 | 64.4 |
| Roma [33] | 31.8 | 53.4 | 70.9 |
| Ours | 33.9 | 55.2 | 73.4 |
Table 4: Two-View matching comparison on ScanNet-1500 [18, 92]. Although our tracking head is not specialized for the two-view setting, it outperforms the state-of-the-art two-view matching method Roma. Measured in AUC (higher is better).
| 方法 | AUC@5 | AUC@10 | AUC@20 |
|---|---|---|---|
| 超级胶 [92] | 16.2 | 33.8 | 51.8 |
| LoFTR [105] | 22.1 | 40.8 | 57.6 |
| DKM [32] | 29.4 | 50.7 | 68.3 |
| CasMTR [9] | 27.1 | 47.0 | 64.4 |
| 罗马 [33] | 31.8 | 53.4 | 70.9 |
| 我们的 | 33.9 | 55.2 | 73.4 |
表 4:ScanNet-1500 [18, 92] 上的双视图匹配比较。尽管我们的跟踪头并非专为双视图设置设计,但它的表现优于最新的双视图匹配方法 Roma。以 AUC 衡量(值越高越好)。
This section compares our method to state-of-the-art approaches across multiple tasks to show its effectiveness.
本节将我们的方法与多任务中的最先进方法进行比较,以展示其有效性。
4.1 Camera Pose Estimation
4.1 相机位姿估计
We first evaluate our method on the CO3Dv2 [88] and RealEstate10K [161] datasets for camera pose estimation, as shown in Tab. 1. Following [124], we randomly select 10 images per scene and evaluate them using the standard metric AUC@30, which combines RRA and RTA. RRA (Relative Rotation Accuracy) and RTA (Relative Translation Accuracy) calculate the relative angular errors in rotation and translation, respectively, for each image pair. These angular errors are then thresholded to determine the accuracy scores. AUC is the area under the accuracy-threshold curve of the minimum values between RRA and RTA across varying thresholds. The (learnable) methods in Tab. 1 have been trained on Co3Dv2 and not on RealEstate10K. Our feed-forward model consistently outperforms competing methods across all metrics on both datasets, including those that employ computationally expensive post-optimization steps, such as Global Alignment for DUSt3R/MASt3R and Bundle Adjustment for VGGSfM, typically requiring more than seconds. In contrast, VGGT achieves superior performance while only operating in a feed-forward manner, requiring just seconds on the same hardware. Compared to concurrent works [141, 111, 156, 127] (indicated by ‡), our method demonstrates significant performance advantages, with speed similar to the fastest variant Fast3R [141]. Furthermore, our model’s performance advantage is even more pronounced on the RealEstate10K dataset, which none of the methods presented in Tab. 1 were trained on. This validates the superior generalization of VGGT.
我们首先在 CO3Dv2 [88] 和 RealEstate10K [161] 数据集上评估我们的方法,以进行相机位姿估计,如表 1 所示。 按照[124],我们为每个场景随机选择 10 张图像,并使用结合了 RRA 和 RTA 的标准指标 AUC@30 对其进行评估。 RRA(相对旋转精度)和 RTA(相对平移精度)分别计算每个图像对的旋转和平移相对角度误差。 然后对这些角度误差进行阈值处理以确定准确度分数。 AUC 是不同阈值下 RRA 和 RTA 之间最小值的准确度阈值曲线下的面积。 Tab. 中的(可学习的)方法。 1 人接受过 Co3Dv2 培训,未接受过 RealEstate10K 培训。 我们的前馈模型在两个数据集的所有指标上始终优于竞争方法,包括那些采用计算成本昂贵的后优化步骤的方法,例如 DUSt3R/MASt3R 的全局对齐和 VGGSfM 的捆绑调整,通常需要超过秒。 相比之下,VGGT 仅以前馈方式运行即可实现卓越的性能,在相同硬件上仅需要秒。 与并发工作[141,111,156,127](用*‡*表示)相比,我们的方法表现出显着的性能优势,速度与最快的变体Fast3R[141]相似。 此外,我们的模型的性能优势在 RealEstate10K 数据集上更加明显,这是表 1 中介绍的任何方法都没有的。 1 人接受过培训。 这验证了 VGGT 的卓越泛化能力。
Our results also show that VGGT can be improved even further by combining it with optimization methods from visual geometry optimization like BA. Specifically, refining the predicted camera poses and tracks with BA further improves accuracy. Note that our method directly predicts close-to-accurate point/depth maps, which can serve as a good initialization for BA. This eliminates the need for triangulation and iterative refinement in BA as done by [125], making our approach significantly faster (only around seconds even with BA). Hence, while the feed-forward mode of VGGT outperforms all previous alternatives (whether they are feed-forward or not), there is still room for improvement since post-optimization still brings benefits.
我们的结果还表明,通过将 VGGT 与来自视觉几何优化的方法(如 BA)结合,VGGT 可以进一步改进。具体来说,用 BA 精炼预测的相机位姿和轨迹可以进一步提高精度。请注意,我们的方法直接预测接近准确的点/深度图,这可以作为 BA 的良好初始化。这消除了像 [125] 所做的在 BA 中进行三角测量和迭代优化的需求,使我们的方法显著更快(即使使用 BA 也仅需大约秒)。因此,虽然 VGGT 的前馈模式优于所有之前的方法(无论它们是否是前馈的),但仍有改进空间,因为后期优化仍然带来好处。
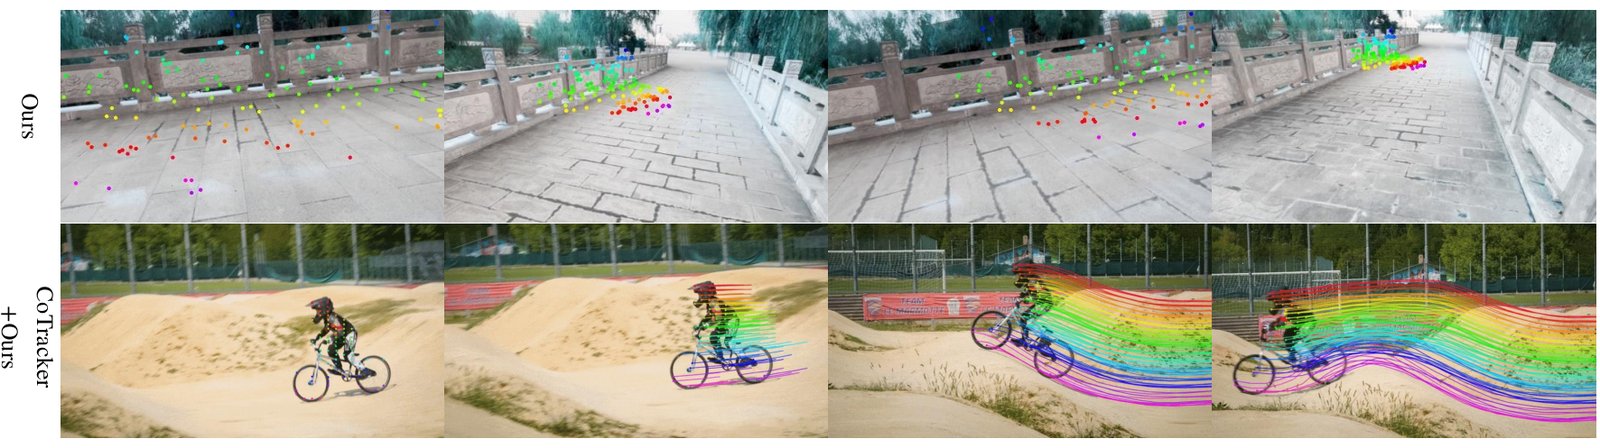
Figure 5: Visualization of Rigid and Dynamic Point Tracking. Top: VGGT’s tracking module outputs keypoint tracks for an unordered set of input images depicting a static scene. Bottom: We finetune the backbone of VGGT to enhance a dynamic point tracker CoTracker [56], which processes sequential inputs.
图5:刚性和动态点跟踪的可视化。上:VGGT 的跟踪模块输出用于一组无序输入图像的关键点轨迹,这些图像描绘了一个静态场景。下:我们微调 VGGT 的主干网络以增强动态点跟踪器 CoTracker [56],该跟踪器处理连续输入。
4.2 Multi-view Depth Estimation
4.2 多视图深度估计
Following MASt3R [62], we further evaluate our multi-view depth estimation results on the DTU [51] dataset. We report the standard DTU metrics, including Accuracy (the smallest Euclidean distance from the prediction to ground truth), Completeness (the smallest Euclidean distance from the ground truth to prediction), and their average Overall (i.e., Chamfer distance). In Tab. 2, DUSt3R and our VGGT are the only two methods operating without the knowledge of ground truth cameras. MASt3R derives depth maps by triangulating matches using the ground truth cameras. Meanwhile, deep multi-view stereo methods like GeoMVSNet use ground truth cameras to construct cost volumes.
继 MASt3R [62] 之后,我们进一步在 DTU [51] 数据集上评估我们的多视图深度估计结果。我们报告标准的 DTU 指标,包括准确率(预测到真实值的最小欧几里得距离)、完整性(真实值到预测的最小欧几里得距离)及其平均值总体(即 Chamfer 距离)。在表 2 中,DUSt3R 和我们的 VGGT 是唯一两个在不使用真实相机信息的情况下操作的方法。MASt3R 使用真实相机通过三角测量匹配来获取深度图。同时,像 GeoMVSNet 这样的深度多视图立体方法使用真实相机来构建代价体积。
Our method substantially outperforms DUSt3R, reducing the Overall score from to . More importantly, it achieves results comparable to methods that know ground-truth cameras at test time. The significant performance gains can likely be attributed to our model’s multi-image training scheme that teaches it to reason about multi-view triangulation natively, instead of relying on ad hoc alignment procedures, such as in DUSt3R, which only averages multiple pairwise camera triangulations.
我们的方法大幅超越了DUSt3R,将整体得分从降低到。更重要的是,它在测试时取得的结果可与那些已知真实相机的方法相比。显著的性能提升很可能归因于我们模型的多图像训练方案,该方案教会模型原生地进行多视图三角测量推理,而不是依赖像DUSt3R中那样的临时对齐程序,后者仅仅是对多次成对相机三角测量结果进行平均。
4.3 Point Map Estimation
4.3 点图估计
We also compare the accuracy of our predicted point cloud to DUSt3R and MASt3R on the ETH3D [97] dataset. For each scene, we randomly sample frames. The predicted point cloud is aligned to the ground truth using the Umeyama [117] algorithm. The results are reported after filtering out invalid points using the official masks. We report Accuracy, Completeness, and Overall (Chamfer distance) for point map estimation. As shown in Tab. 3, although DUSt3R and MASt3R conduct expensive optimization (global alignment–—around 10 seconds per scene), our method still outperforms them significantly in a simple feed-forward regime at only seconds per reconstruction.
我们还将我们预测的点云的精度与 ETH3D [97] 数据集上的 DUSt3R 和 MASt3R 进行了比较。对于每个场景,我们随机采样帧。使用 Umeyama [117] 算法将预测的点云与真实值对齐。在使用官方掩码过滤掉无效点后报告结果。我们报告了点图估计的精度、完整性和总体(Chamfer 距离)。如表 3 所示,尽管 DUSt3R 和 MASt3R 进行耗时的优化(全局对齐——每个场景约 10 秒),我们的方法在仅需秒每次重建的简单前馈模式下仍显著优于它们。
Meanwhile, compared to directly using our estimated point maps, we found that the predictions from our depth and camera heads (i.e., unprojecting the predicted depth maps to 3D using the predicted camera parameters) yield higher accuracy. We attribute this to the benefits of decomposing a complex task (point map estimation) into simpler subproblems (depth map and camera prediction), even though camera, depth maps, and point maps are jointly supervised during training.
同时,与直接使用我们估计的点图相比,我们发现来自我们深度和相机头的预测(即使用预测的相机参数将预测的深度图反投影到 3D)具有更高的准确性。我们将此归因于将一个复杂任务(点图估计)分解为更简单的子问题(深度图和相机预测)的好处,即使在训练过程中相机、深度图和点图是联合监督的。
We present a qualitative comparison with DUSt3R on in-the-wild scenes in Fig. 3 and further examples in Fig. 4. VGGT outputs high-quality predictions and generalizes well, excelling on challenging out-of-domain examples, such as oil paintings, non-overlapping frames, and scenes with repeating or homogeneous textures like deserts.
我们在图 3 中展示了与 DUSt3R 在自然场景下的定性比较,并在图 4 中提供了更多示例。VGGT 输出高质量的预测,并且具有良好的泛化能力,在具有挑战性的域外示例中表现出色,例如油画、非重叠帧以及具有重复或均质纹理的场景,如沙漠。
4.4 Image Matching
4.4 图像匹配
Two-view image matching is a widely-explored topic [93, 68, 105] in computer vision. It represents a specific case of rigid point tracking, which is restricted to only two views, and hence a suitable evaluation benchmark to measure our tracking accuracy, even though our model is not specialized for this task. We follow the standard protocol [33, 93] on the ScanNet dataset [18] and report the results in Tab. 4. For each image pair, we extract the matches and use them to estimate an essential matrix, which is then decomposed to a relative camera pose. The final metric is the relative pose accuracy, measured by AUC. For evaluation, we use ALIKED [158] to detect keypoints, treating them as query points . These are then passed to our tracking branch to find correspondences in the second frame. We adopt the evaluation hyperparameters (e.g., the number of matches, RANSAC thresholds) from Roma [33]. Despite not being explicitly trained for two-view matching, Tab. 4 shows that VGGT achieves the highest accuracy among all baselines.
双视图图像匹配是计算机视觉中广泛探讨的主题 [93,68,105]。 它代表了刚性点跟踪的特定情况,仅限于两个视图,因此是一个合适的评估基准来衡量我们的跟踪精度,即使我们的模型并非专门用于此任务。 我们遵循 ScanNet 数据集 [18] 上的标准协议 [33, 93] 并在选项卡中报告结果。 4. 对于每个图像对,我们提取匹配并使用它们来估计基本矩阵,然后将其分解为相对相机位姿。 最终指标是相对位姿精度,由 AUC 测量。 为了进行评估,我们使用 ALIKED [158] 来检测关键点,将它们视为查询点。 然后将它们传递到我们的跟踪分支以查找第二帧中的对应关系。 我们采用来自 Roma 的评估超参数(例如,匹配数、RANSAC 阈值)[33]。 尽管没有接受过双视图匹配的明确训练,Tab. 图 4 显示 VGGT 在所有基线中实现了最高的准确度。
| ETH3D Dataset | Acc. | Comp. | Overall |
|---|---|---|---|
| Cross-Attention | 1.287 | 0.835 | 1.061 |
| Global Self-Attention Only | 1.032 | 0.621 | 0.827 |
| Alternating-Attention | 0.901 | 0.518 | 0.709 |
Table 5: Ablation Study for Transformer Backbone on ETH3D. We compare our alternating-attention architecture against two variants: one using only global self-attention and another employing cross-attention.
| ETH3D 数据集 | Acc. | 计算机 | 总体 |
|---|---|---|---|
| 交叉注意力 | 1.287 | 0.835 | 1.061 |
| 仅全局自注意力 | 1.032 | 0.621 | 0.827 |
| 交替注意 | 0.901 | 0.518 | 0.709 |
表 5:ETH3D 上 Transformer 主干的消融研究。我们将我们的交替注意力架构与两种变体进行比较:一种仅使用全局自注意力,另一种采用交叉注意力。
| w. | w. | w. | Acc. | Comp. | Overall |
|---|---|---|---|---|---|
| ✗ | ✓ | ✓ | 1.042 | 0.627 | 0.834 |
| ✓ | ✗ | ✓ | 0.920 | 0.534 | 0.727 |
| ✓ | ✓ | ✗ | 0.976 | 0.603 | 0.790 |
| ✓ | ✓ | ✓ | 0.901 | 0.518 | 0.709 |
Table 6: Ablation Study for Multi-task Learning, which shows that simultaneous training with camera, depth and track estimation yields the highest accuracy in point map estimation on ETH3D.
| w. | w. | w. | Acc. | 计算机 | 总体 |
|---|---|---|---|---|---|
| ✗ | ✓ | ✓ | 1.042 | 0.627 | 0.834 |
| ✓ | ✗ | ✓ | 0.920 | 0.534 | 0.727 |
| ✓ | ✓ | ✗ | 0.976 | 0.603 | 0.790 |
| ✓ | ✓ | ✓ | 0.901 | 0.518 | 0.709 |
表6:多任务学习消融研究,显示同时进行相机、深度和轨迹估计的训练在ETH3D上的点图估计中获得了最高的准确率。
4.5 Ablation Studies
4.5 消融实验
Feature Backbone.
We first validate the effectiveness of our proposed Alternating-Attention design by comparing it against two alternative attention architectures: (a) global self-attention only, and (b) cross-attention. To ensure a fair comparison, all model variants maintain an identical number of parameters, using a total of attention layers. For the cross-attention variant, each frame independently attends to tokens from all other frames, maximizing cross-frame information fusion although significantly increasing the runtime, particularly as the number of input frames grows. The hyperparameters such as the hidden dimension and the number of heads are kept the same. Point map estimation accuracy is chosen as the evaluation metric for our ablation study, as it reflects the model’s joint understanding of scene geometry and camera parameters. Results in Tab. 5 demonstrate that our Alternating-Attention architecture outperforms both baseline variants by a clear margin. Additionally, our other preliminary exploratory experiments consistently showed that architectures using cross-attention generally underperform compared to those exclusively employing self-attention.
特征骨干。
我们首先通过将其与两种替代注意力架构进行比较来验证我们提出的交替注意力设计的有效性:(a)仅全局自注意力和(b)交叉注意力。 为了确保公平比较,所有模型变体都使用总共注意力层来维护相同数量的参数。 对于交叉注意力变体,每个帧独立地关注来自所有其他帧的标记,最大化跨帧信息融合,尽管显着增加了运行时间,特别是随着输入帧数量的增长。 隐藏维度和头数等超参数保持不变。 选择点图估计精度作为我们的消融研究的评估指标,因为它反映了模型对场景几何和相机参数的共同理解。 结果在选项卡中。 图 5 表明我们的交替注意力架构明显优于两种基线变体。 此外,我们的其他初步探索性实验一致表明,与仅使用自注意力的架构相比,使用交叉注意力的架构通常表现不佳。
Multi-task Learning.
We also verify the benefit of training a single network to simultaneously learn multiple 3D quantities, even though these outputs may potentially overlap (e.g., depth maps and camera parameters together can produce point maps). As shown in Tab. 6, there is a noticeable decrease in the accuracy of point map estimation when training without camera, depth, or track estimation. Notably, incorporating camera parameter estimation clearly enhances point map accuracy, whereas depth estimation contributes only marginal improvements.
多任务学习。
我们还验证了训练单一网络同时学习多个 3D 量的好处,即使这些输出可能存在潜在重叠(例如,深度图和相机参数一起可以生成点图)。如表 6 所示,当训练时不包含相机、深度或轨迹估计时,点图估计的准确性明显下降。值得注意的是,加入相机参数估计显著提高了点图的准确性,而深度估计仅带来了微小的改进。
4.6 Finetuning for Downstream Tasks
4.6 下游任务微调
We now show that the VGGT pre-trained feature extractor can be reused in downstream tasks. We show this for feed-forward novel view synthesis and dynamic point tracking.
我们现在展示 VGGT 预训练特征提取器可以在下游任务中重复使用。我们在前馈新视角合成和动态点跟踪中展示了这一点。
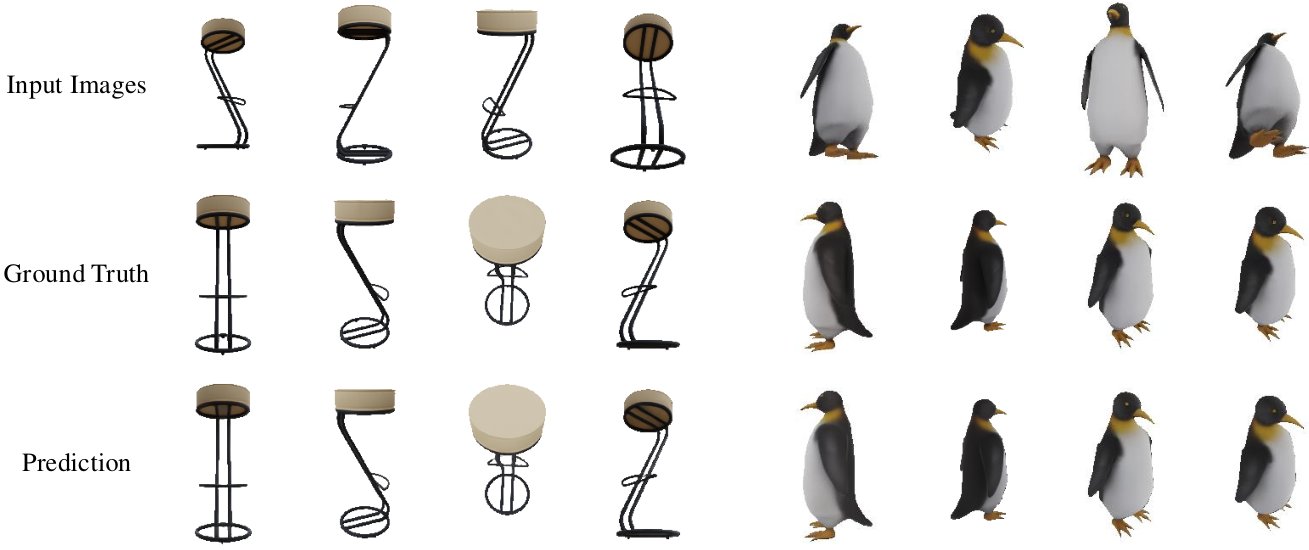
Figure 6: Qualitative Examples of Novel View Synthesis. The top row shows the input images, the middle row displays the ground truth images from target viewpoints, and the bottom row presents our synthesized images.
图6:新视角合成的定性示例。顶部显示输入图像,中间显示目标视角的真实图像,底部显示我们合成的图像。
| Method | Known Input Cam | Size | PSNR | SSIM | LPIPS |
|---|---|---|---|---|---|
| LGM [110] | ✓ | 256 | 21.44 | 0.832 | 0.122 |
| GS-LRM [154] | ✓ | 256 | 29.59 | 0.944 | 0.051 |
| LVSM [53] | ✓ | 256 | 31.71 | 0.957 | 0.027 |
| Ours-NVS∗ | ✗ | 224 | 30.41 | 0.949 | 0.033 |
Table 7: Quantitative comparisons for view synthesis on GSO [28] dataset. Finetuning VGGT for feed-forward novel view synthesis, it demonstrates competitive performance even without knowing camera extrinsic and intrinsic parameters for the input images. Note that ∗ indicates using a small training set (only 20%).
| 方法 | 已知输入摄像头 | 尺寸 | PSNR | SSIM | LPIPS |
|---|---|---|---|---|---|
| LGM [110] | ✓ | 256 | 21.44 | 0.832 | 0.122 |
| GS-LRM [154] | ✓ | 256 | 29.59 | 0.944 | 0.051 |
| LVSM [53] | ✓ | 256 | 31.71 | 0.957 | 0.027 |
| Ours-NVS∗ | ✗ | 224 | 30.41 | 0.949 | 0.033 |
表7:在GSO [28] 数据集上进行视图合成的定量比较。对VGGT进行微调以进行前馈新视图合成,即使在不知道输入图像的相机外参和内参的情况下,也表现出具有竞争力的性能。注意,∗表示使用了一个小训练集(仅20%)。
Feed-forward Novel View Synthesis
is progressing rapidly [49, 126, 8, 140, 155, 108, 43, 53]. Most existing methods take images with known camera parameters as input and predict the target image corresponding to a new camera viewpoint. Instead of relying on an explicit 3D representation, we follow LVSM [53] and modify VGGT to directly output the target image. However, we do not assume known camera parameters for the input frames.
前馈式新视角合成
正在迅速发展 [49, 126, 8, 140, 155, 108, 43, 53]。大多数现有方法以已知相机参数的图像作为输入,并预测对应新相机视角的目标图像。我们没有依赖显式的 3D 表示,而是遵循 LVSM [53] 并修改 VGGT 以直接输出目标图像。然而,我们不假设输入帧的相机参数是已知的。
We follow the training and evaluation protocol of LVSM closely, e.g., using input views and adopting Plücker rays to represent target viewpoints. We make a simple modification to VGGT. As before, the input images are converted into tokens by DINO. Then, for the target views, we use a convolutional layer to encode their Plücker ray images into tokens. These tokens, representing both the input images and the target views, are concatenated and processed by the AA transformer. Subsequently, a DPT head is used to regress the RGB colors for the target views. It is important to note that we do not input the Plücker rays for the source images. Hence, the model is not given the camera parameters for these input frames.
我们严格遵循 LVSM 的训练和评估协议,例如,使用输入视图并采用 Plücker 光线来表示目标视点。我们对 VGGT 进行了一个简单的修改。和之前一样,输入图像通过 DINO 转换为 tokens。然后,对于目标视图,我们使用卷积层将其 Plücker 光线图像编码为 tokens。这些 tokens,同时表示输入图像和目标视图,会被连接并由 AA transformer 处理。随后,使用 DPT 头回归目标视图的 RGB 颜色。需要注意的是,我们不将源图像的 Plücker 光线作为输入。因此,模型不会获得这些输入帧的相机参数。
LVSM was trained on the Objaverse dataset [20]. We use a similar internal dataset of approximately 20% the size of Objaverse. Further details on training and evaluation can be found in [53]. As shown in Tab. 7, despite not requiring the input camera parameters and using less training data than LVSM, our model achieves competitive results on the GSO dataset [28]. We expect that better results would be obtained using a larger training dataset. Qualitative examples are shown in Fig. 6.
LVSM 在 Objaverse 数据集 [20] 上进行了训练。我们使用了一个类似的内部数据集,其规模大约是 Objaverse 的 20%。关于训练和评估的更多细节可以在 [53] 中找到。如表 7 所示,尽管不需要输入相机参数且使用的训练数据少于 LVSM,我们的模型在 GSO 数据集 [28] 上仍取得了有竞争力的结果。我们预计使用更大的训练数据集可以获得更好的结果。定性示例见图 6。
| Method | Kinetics | RGB-S | DAVIS | ||||||
|---|---|---|---|---|---|---|---|---|---|
| AJ | OA | AJ | OA | AJ | OA | ||||
| TAPTR [63] | 49.0 | 64.4 | 85.2 | 60.8 | 76.2 | 87.0 | 63.0 | 76.1 | 91.1 |
| LocoTrack [13] | 52.9 | 66.8 | 85.3 | 69.7 | 83.2 | 89.5 | 62.9 | 75.3 | 87.2 |
| BootsTAPIR [26] | 54.6 | 68.4 | 86.5 | 70.8 | 83.0 | 89.9 | 61.4 | 73.6 | 88.7 |
| CoTracker [56] | 49.6 | 64.3 | 83.3 | 67.4 | 78.9 | 85.2 | 61.8 | 76.1 | 88.3 |
| CoTracker + Ours | 57.2 | 69.0 | 88.9 | 72.1 | 84.0 | 91.6 | 64.7 | 77.5 | 91.4 |
Table 8: Dynamic Point Tracking Results on the TAP-Vid benchmarks. Although our model was not designed for dynamic scenes, simply fine-tuning CoTracker with our pretrained weights significantly enhances performance, demonstrating the robustness and effectiveness of our learned features.
| 方法 | 动力学 | RGB-S | 戴维斯 | ||||||
|---|---|---|---|---|---|---|---|---|---|
| AJ | OA | AJ | OA | AJ | OA | ||||
| TAPTR [63] | 49.0 | 64.4 | 85.2 | 60.8 | 76.2 | 87.0 | 63.0 | 76.1 | 91.1 |
| LocoTrack [13] | 52.9 | 66.8 | 85.3 | 69.7 | 83.2 | 89.5 | 62.9 | 75.3 | 87.2 |
| BootsTAPIR [26] | 54.6 | 68.4 | 86.5 | 70.8 | 83.0 | 89.9 | 61.4 | 73.6 | 88.7 |
| CoTracker [56] | 49.6 | 64.3 | 83.3 | 67.4 | 78.9 | 85.2 | 61.8 | 76.1 | 88.3 |
| CoTracker + 我们的 | 57.2 | 69.0 | 88.9 | 72.1 | 84.0 | 91.6 | 64.7 | 77.5 | 91.4 |
表 8:TAP-Vid 基准上的动态点跟踪结果。尽管我们的模型并非为动态场景设计,但仅仅使用我们的预训练权重对 CoTracker 进行微调就能显著提升性能,这展示了我们所学习特征的鲁棒性和有效性。
Dynamic Point Tracking
has emerged as a highly competitive task in recent years [44, 25, 136, 57], and it serves as another downstream application for our learned features. Following standard practices, we report these point-tracking metrics: Occlusion Accuracy (OA), which comprises the binary accuracy of occlusion predictions; , comprising the mean proportion of visible points accurately tracked within a certain pixel threshold; and Average Jaccard (AJ), measuring tracking and occlusion prediction accuracy together.
动态点跟踪
近年来,动态点跟踪已成为一个高度竞争的任务 [44, 25, 136, 57],同时它也是我们学习特征的另一个下游应用。按照标准做法,我们报告以下点跟踪指标:遮挡准确率 (OA),包括遮挡预测的二元准确率;,包括在特定像素阈值内准确跟踪的可见点的平均比例;以及平均雅卡尔指数 (AJ),用于同时衡量跟踪和遮挡预测的准确性。
We adapt the state-of-the-art CoTracker2 model [57] by substituting its backbone with our pretrained feature backbone. This is necessary because VGGT is trained on unordered image collections instead of sequential videos. Our backbone predicts the tracking features , which replace the outputs of the feature extractor and later enter the rest of the CoTracker2 architecture, that finally predicts the tracks. We finetune the entire modified tracker on Kubric [41]. As illustrated in Tab. 8, the integration of pretrained VGGT significantly enhances CoTracker’s performance on the TAP-Vid benchmark [23]. For instance, VGGT’s tracking features improve the metric from to on the TAP-Vid RGB-S dataset. Despite the TAP-Vid benchmark’s inclusion of videos featuring rapid dynamic motions from various data sources, our model’s strong performance demonstrates the generalization capability of its features, even in scenarios for which it was not explicitly designed.
我们采用最先进的 CoTracker2 模型 [57],用我们预先训练的特征主干替换其主干。 这是必要的,因为 VGGT 是在无序图像集合而不是顺序视频上进行训练的。 我们的主干网预测跟踪特征,它取代特征提取器的输出,然后进入 CoTracker2 架构的其余部分,最终预测轨迹。 我们对 Kubric [41] 上的整个修改后的跟踪器进行了微调。 如表所示。 如图 8 所示,预训练 VGGT 的集成显着增强了 CoTracker 在 TAP-Vid 基准上的性能 [23]。 例如,VGGT 的跟踪功能将 TAP-Vid RGB-S 数据集上的指标从改进为 。 尽管 TAP-Vid 基准测试包含来自各种数据源的具有快速动态运动的视频,但我们的模型的强大性能证明了其特征的泛化能力,即使在未明确设计的场景中也是如此。
5 Discussions
5 讨论
Limitations.
While our method exhibits strong generalization to diverse in-the-wild scenes, several limitations remain. First, the current model does not support fisheye or panoramic images. Additionally, reconstruction performance drops under conditions involving extreme input rotations. Moreover, although our model handles scenes with minor non-rigid motions, it fails in scenarios involving substantial non-rigid deformation.
限制。
虽然我们的方法在各种野外场景中表现出强大的泛化能力,但仍然存在一些限制。首先,当前模型不支持鱼眼或全景图像。此外,在输入图像旋转极端的条件下,重建性能会下降。此外,尽管我们的模型能够处理具有轻微非刚性运动的场景,但在涉及显著非刚性变形的场景中会失败。
However, an important advantage of our approach is its flexibility and ease of adaptation. Addressing these limitations can be straightforwardly achieved by fine-tuning the model on targeted datasets with minimal architectural modifications. This adaptability clearly distinguishes our method from existing approaches, which typically require extensive re-engineering during test-time optimization to accommodate such specialized scenarios.
然而,我们方法的一个重要优势是其灵活性和易于适应性。通过在针对性的 数据集 上对模型进行微调,并进行最少的架构修改,可以轻松地解决这些限制。这种适应性明显区分了我们的方法与现有方法,后者通常在测试时优化过程中需要大量的重新设计,以适应这种特殊的场景。
| Input Frames | 1 | 2 | 4 | 8 | 10 | 20 | 50 | 100 | 200 |
|---|---|---|---|---|---|---|---|---|---|
| Time (s) | 0.04 | 0.05 | 0.07 | 0.11 | 0.14 | 0.31 | 1.04 | 3.12 | 8.75 |
| Mem. (GB) | 1.88 | 2.07 | 2.45 | 3.23 | 3.63 | 5.58 | 11.41 | 21.15 | 40.63 |
Table 9: Runtime and peak GPU memory usage across different numbers of input frames. Runtime is measured in seconds, and GPU memory usage is reported in gigabytes.
| 输入帧 | 1 | 2 | 4 | 8 | 10 | 20 | 50 | 100 | 200 |
|---|---|---|---|---|---|---|---|---|---|
| 时间 (秒) | 0.04 | 0.05 | 0.07 | 0.11 | 0.14 | 0.31 | 1.04 | 3.12 | 8.75 |
| 内存(GB) | 1.88 | 2.07 | 2.45 | 3.23 | 3.63 | 5.58 | 11.41 | 21.15 | 40.63 |
表9:不同输入帧数下的运行时间和峰值GPU显存使用情况。运行时间以秒为单位,GPU显存使用量以吉字节为单位。
Runtime and Memory.
As shown in Tab. 9, we evaluate inference runtime and peak GPU memory usage of the feature backbone when processing varying numbers of input frames. Measurements are conducted using a single NVIDIA H100 GPU with flash attention v3 [98]. Images have a resolution of .
运行时长和内存使用情况。
如表 9 所示,我们评估了特征骨干在处理不同数量的输入帧时的推理运行时间和峰值 GPU 内存使用情况。测量采用单个 NVIDIA H100 GPU 并使用 flash attention v3 [98] 进行。图像分辨率为。
We focus on the cost associated with the feature backbone since users may select different branch combinations depending on their specific requirements and available resources. The camera head is lightweight, typically accounting for approximately of the runtime and about of the GPU memory used by the feature backbone. A DPT head uses an average of seconds and GB GPU memory per frame.
我们关注与特征骨干相关的成本,因为用户可能会根据其具体需求和可用资源选择不同的分支组合。相机头重量轻,通常大约占特征骨干运行时间的 ,以及使用的 GPU 内存的约 。DPT 头平均每帧使用秒和GB GPU 内存。
When GPU memory is sufficient, multiple frames can be processed efficiently in a single forward pass. At the same time, in our model, inter-frame relationships are handled only within the feature backbone, and the DPT heads make independent predictions per frame. Therefore, users constrained by GPU resources may perform predictions frame by frame. We leave this trade-off to the user’s discretion.
当 GPU 内存充足时,可以在一次前向传递中高效处理多帧。同时,在我们的模型中,帧间关系仅在特征骨干网络中处理,而 DPT 头部对每帧独立进行预测。因此,受 GPU 资源限制的用户可以逐帧进行预测。我们将这一权衡留给用户自行决定。
We recognize that a naive implementation of global self-attention can be highly memory-intensive with a large number of tokens. Savings or accelerations can be achieved by employing techniques used in large language model (LLM) deployments. For instance, Fast3R [141] employs Tensor Parallelism to accelerate inference with multiple GPUs, which can be directly applied to our model.
我们认识到,对全局自注意力的天真实现,在大量令牌情况下可能会非常占用内存。通过采用在大语言模型(LLM)部署中使用的技术,可以实现节省或加速。例如,Fast3R [141] 使用张量并行来通过多GPU加速推理,这可以直接应用于我们的模型。
Patchifying.
As discussed in Sec. 3.2, we have explored the method of patchifying images into tokens by utilizing either a convolutional layer or a pretrained DINOv2 model. Empirical results indicate that the DINOv2 model provides better performance; moreover, it ensures much more stable training, particularly in the initial stages. The DINOv2 model is also less sensitive to variations in hyperparameters such as learning rate or momentum. Consequently, we have chosen DINOv2 as the default method for patchifying in our model.
图像分块处理。
如第3.2节所讨论的,我们探索了将图像分块为标记的方法,可以使用卷积层或预训练的 DINOv2 模型。实证结果表明,DINOv2 模型提供了更好的性能;此外,它确保了训练更加稳定,特别是在初始阶段。DINOv2 模型对学习率或动量等超参数的变化也不太敏感。因此,我们选择 DINOv2 作为我们模型中默认的图像分块方法。
Differentiable BA.
We also explored the idea of using differentiable bundle adjustment as in VGGSfM [125]. In small-scale preliminary experiments, differentiable BA demonstrated promising performance. However, a bottleneck is its computational cost during training. Enabling differentiable BA in PyTorch using Theseus [85] typically makes each training step roughly times slower, which is expensive for large-scale training. While customizing a framework to expedite training could be a potential solution, it falls outside the scope of this work. Thus, we opted not to include differentiable BA in this work, but we recognize it as a promising direction for large-scale unsupervised training, as it can serve as an effective supervision signal in scenarios lacking explicit 3D annotations.
可微分BA。
我们还探讨了使用可微分束束调整(differentiable bundle adjustment),如 VGGSfM [125] 中所示。在小规模的初步实验中,可微分 BA 展示出了有希望的性能。然而,其训练过程中的计算成本是一个瓶颈。在 PyTorch 中使用 Theseus [85] 启用可微分 BA 通常会使每个训练步骤大约慢倍,对于大规模训练来说代价高昂。虽然定制一个框架以加速训练可能是一个潜在的解决方案,但这超出了本工作的范围。因此,我们选择不在本工作中包含可微分 BA,但我们认为它是大规模无监督训练的一个有前途的方向,因为它可以在缺乏明确 3D 注释的情况下,作为有效的监督信号。
Single-view Reconstruction.
Unlike systems like DUSt3R and MASt3R that have to duplicate an image to create a pair, our model architecture inherently supports the input of a single image. In this case, global attention simply transitions to frame-wise attention. Although our model was not explicitly trained for single-view reconstruction, it demonstrates surprisingly good results. Some examples can be found in Fig. 3 and Fig. 7. We strongly encourage trying our demo for better visualization.
单视图重建。
与需要复制图像以创建成对输入的系统例如 DUSt3R 和 MASt3R 不同,我们的模型架构本身就支持单张图像的输入。在这种情况下,全局注意力会简单地过渡为逐帧注意力。尽管我们的模型并未专门针对单视图重建进行训练,但它显示出了令人惊讶的良好效果。一些示例可以在图 3 和图 7 中找到。我们强烈建议尝试我们的演示以获得更好的可视化效果。
Normalizing Prediction.
As discussed in Sec. 3.4, our approach normalizes the ground truth using the average Euclidean distance of the 3D points. While some methods, such as DUSt3R, also apply such normalization to network predictions, our findings suggest that it is neither necessary for convergence nor advantageous for final model performance. Furthermore, it tends to introduce additional instability during the training phase.
预测归一化。
如第3.4节所讨论,我们的方法使用3D点的平均欧几里得距离对真实值进行归一化。虽然一些方法(如DUSt3R)也对网络预测应用这种归一化,但我们的研究发现,这既不是收敛所必需的,也不利于最终模型性能。此外,它在训练阶段还容易引入额外的不稳定性。
6 Conclusions
6 结论
We present Visual Geometry Grounded Transformer (VGGT), a feed-forward neural network that can directly estimate all key 3D scene properties for hundreds of input views. It achieves state-of-the-art results in multiple 3D tasks, including camera parameter estimation, multi-view depth estimation, dense point cloud reconstruction, and 3D point tracking. Our simple, neural-first approach departs from traditional visual geometry-based methods, which rely on optimization and post-processing to obtain accurate and task-specific results. The simplicity and efficiency of our approach make it well-suited for real-time applications, which is another benefit over optimization-based approaches.
我们提出了视觉几何基础Transformer(Visual Geometry Grounded Transformer, VGGT),这是一种前馈神经网络,可以直接估计数百个输入视图的所有关键三维场景属性。它在多项三维任务中实现了最先进的结果,包括相机参数估计、多视图深度估计、稠密点云重建和三维点跟踪。我们这种简单的以神经网络为主的方法有别于传统的基于视觉几何的方法,后者依赖优化和后处理来获得准确且任务特定的结果。我们方法的简洁性和高效性使其非常适合实时应用,这是相对于基于优化的方法的另一个优势。
Appendix
附录
In the Appendix, we provide the following:
在附录中,我们提供了以下内容:
- • formal definitions of key terms in Appendix A.
- • comprehensive implementation details, including architecture and training hyperparameters in Appendix B.
- • additional experiments and discussions in Appendix C.
- • qualitative examples of single-view reconstruction in Appendix D.
- • an expanded review of related works in Appendix E.
- • 关键术语的正式定义见附录A。
- • 综合的实现细节,包括架构和训练超参数,见附录B。
- • 额外的实验和讨论见附录C。
- • 单视角重建的定性示例见附录D。
- • 相关工作的扩展综述见附录E。
Appendix A Formal Definitions
附录 A 形式化定义
In this section, we provide additional formal definitions that further ground the method section.
在本节中,我们提供了额外的正式定义,以进一步支持方法部分。
The camera extrinsics are defined in relation to the world reference frame, which we take to be the coordinate system of the first camera. We thus introduce two functions. The first function applies the rigid transformation encoded by to a point in the world reference frame to obtain the corresponding point in the camera reference frame. The second function further applies perspective projection, mapping the 3D point to a 2D image point . We also denote the depth of the point as observed from the camera by .
相机外参是相对于世界参考坐标系定义的,我们将其视为第一个相机的坐标系。因此我们引入两个函数。第一个函数对世界参考系中的点应用由编码的刚体变换,以得到相机参考系中的对应点 。第二个函数进一步应用透视投影,将三维点映射到二维图像点 。我们还将从相机观察到的点的深度记为 。
We model the scene as a collection of regular surfaces . We make this a function of the -th input image as the scene can change over time [151]. The depth at pixel location is defined as the minimum depth of any 3D point in the scene that projects to , i.e., The point at pixel location is then given by , where is the 3D point that minimizes the expression above, i.e., .
我们将场景建模为一组规则的表面 。我们将其作为第张输入图像的函数,因为场景可能随时间变化 [151]。像素位置的深度定义为投影到的场景中任意 3D 点的最小深度,即 。像素位置处的点则由给出,其中是使上述表达式最小化的 3D 点,即 。
Appendix B Implementation Details
附录 B 实现细节
Architecture.
As mentioned in the main paper, VGGT consists of attention blocks, each block equipped with one frame-wise self-attention layer and one global self-attention layer. Following the ViT-L model used in DINOv2 [78], each attention layer is configured with a feature dimension of and employs heads. We use the official implementation of the attention layer from PyTorch, i.e., torch.nn.MultiheadAttention, with flash attention enabled. To stabilize training, we also use QKNorm [48] and LayerScale [115] for each attention layer. The value of LayerScale is initialized with . For image tokenization, we use DINOv2 [78] and add positional embedding. As in [143], we feed the tokens from the -th, -th, -th, and -rd block into DPT [87] for upsampling.
建筑。
如主论文中所述,VGGT 由个注意力模块组成,每个模块配备一个帧级自注意力层和一个全局自注意力层。遵循 DINOv2 [78] 中使用的 ViT-L 模型,每个注意力层的特征维度设置为 ,并使用个头。我们使用来自 PyTorch 的官方注意力层实现,即 torch.nn.MultiheadAttention,并启用闪存注意力(flash attention)。为了稳定训练,我们还对每个注意力层使用 QKNorm [48] 和 LayerScale [115]。LayerScale 的初始值设为 。对于图像分令牌化,我们使用 DINOv2 [78] 并添加位置嵌入。如 [143] 中所示,我们将来自第 、、 和个模块的令牌输入 DPT [87] 进行上采样。
Training.
To form a training batch, we first choose a random training dataset (each dataset has a different yet approximately similar weight, as in [129]), and from the dataset, we then sample a random scene (uniformly). During the training phase, we select between and frames per scene while maintaining the constant total of frames within each batch. For training, we use the respective training sets of each dataset. We exclude training sequences containing fewer than frames. RGB frames, depth maps, and point maps are first isotropically resized, so the longer size has pixels. Then, we crop the shorter dimension (around the principal point) to a size between and pixels while remaining a multiple of the -pixel patch size. It is worth mentioning that we apply aggressive color augmentation independently across each frame within the same scene, enhancing the model’s robustness to varying lighting conditions. We build ground truth tracks following [125, 33, 105], which unprojects depth maps to 3D, reprojects points to target frames, and retains correspondences where reprojected depths match target depth maps. Frames with low similarity to the query frame are excluded during batch sampling. In rare cases with no valid correspondences, the tracking loss is omitted.
训练。
为了形成训练批次,我们首先选择一个随机训练数据集(每个数据集具有不同但大致相似的权重,如[129]中所示),然后从数据集中采样随机场景(均匀)。 在训练阶段,我们在每个场景的和帧之间进行选择,同时保持每批中帧的总数恒定。 对于训练,我们使用每个数据集各自的训练集。 我们排除包含少于帧的训练序列。 RGB 帧、深度图和点图首先进行各向同性调整大小,因此较长的尺寸具有像素。 然后,我们将较短的尺寸(主点周围)裁剪为和像素之间的大小,同时保留像素补丁大小的倍数。 值得一提的是,我们在同一场景中的每个帧上独立地应用积极的色彩增强,增强了模型对不同光照条件的鲁棒性。 我们按照 [125,33,105] 构建地面实况轨迹,将深度图取消投影到 3D,将点重新投影到目标帧,并保留重新投影的深度与目标深度图匹配的对应关系。 在批量采样期间排除与查询帧相似度低的帧。 在没有有效对应关系的极少数情况下,跟踪损失被忽略。
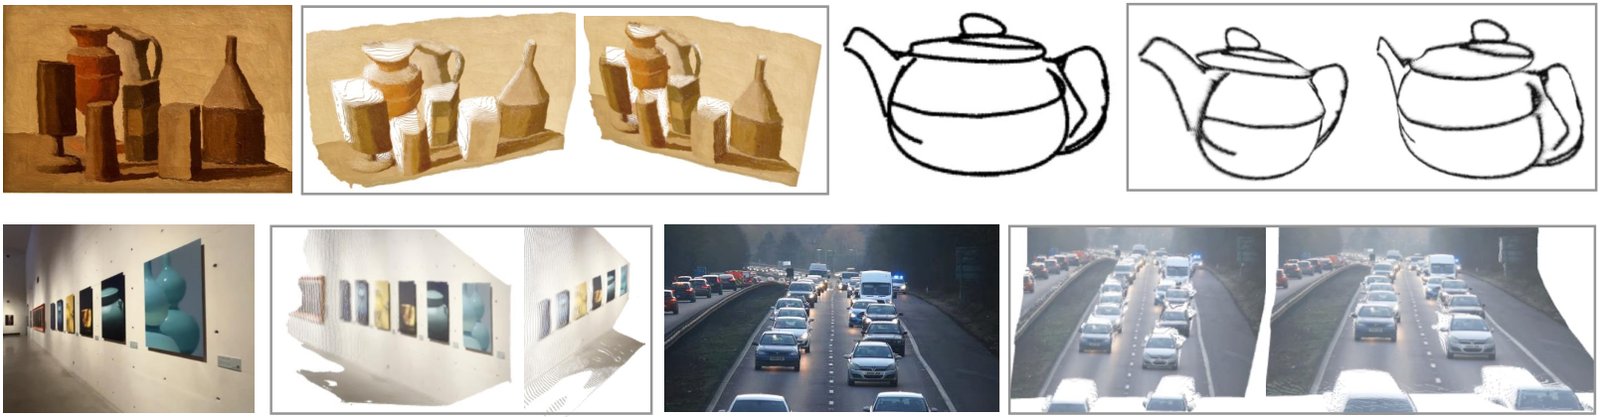
Figure 7: Single-view Reconstruction by Point Map Estimation. Unlike DUSt3R, which requires duplicating an image into a pair, our model can predict the point map from a single input image. It demonstrates strong generalization to unseen real-world images.
图7:通过点图估计进行单视图重建。与需要将图像复制为一对的DUSt3R不同,我们的模型可以从单张输入图像预测点图。它在未见过的真实世界图像上表现出很强的泛化能力。
Appendix C Additional Experiments
附录 C 补充实验
Camera Pose Estimation on IMC
We also evaluate using the Image Matching Challenge (IMC) [54], a camera pose estimation benchmark focusing on phototourism data. Until recently, the benchmark was dominated by classical incremental SfM methods [94].
IMC上的相机位姿估计
我们还使用图像匹配挑战赛(IMC)[54]进行评估,这是一个专注于摄影旅游数据的相机位姿估计基准。直到最近,该基准一直由经典的增量SfM方法[94]主导。
Baselines.
We evaluate two flavors of our model: VGGT and VGGT + BA. VGGT directly outputs camera pose estimates, while VGGT + BA refines the estimates using an additional Bundle Adjustment stage. We compare to the classical incremental SfM methods such as [94, 66] and to recently-proposed deep methods. Specifically, recently VGGSfM [125] provided the first end-to-end trained deep method that outperformed incremental SfM on the challenging phototourism datasets.
基线。
我们评估了模型的两种版本:VGGT 和 VGGT + BA。VGGT 直接输出相机位姿估计,而 VGGT + BA 则通过额外的束调整(Bundle Adjustment)阶段来优化这些估计。我们将其与经典的增量式 SfM 方法(如 [94, 66])以及最近提出的深度方法进行比较。具体来说,最近的 VGGSfM [125] 提出了第一个端到端训练的深度方法,在具有挑战性的摄影旅游数据集上性能超过了增量式 SfM。
Besides VGGSfM, we additionally compare to recently popularized DUSt3R [129] and MASt3R [62]. It is important to note that DUSt3R and MASt3R utilized a substantial portion of the MegaDepth dataset for training, only excluding scenes and . The MegaDepth scenes employed in their training have some overlap with the IMC benchmark, although the images are not identical; the same scenes are present in both datasets. For instance, the MegaDepth scene corresponds to the British Museum, while the British Museum is also a scene in the IMC benchmark. For an apples-to-apples comparison, we adopt the same training split as DUSt3R and MASt3R. In the main paper, to ensure a fair comparison on ScanNet-1500, we exclude the corresponding ScanNet scenes from our training.
除了 VGGSfM,我们还额外对比了最近流行的 DUSt3R [129] 和 MASt3R [62]。值得注意的是,DUSt3R 和 MASt3R 使用了 MegaDepth 数据集的大部分用于训练,仅排除了场景和 。它们训练中使用的 MegaDepth 场景与 IMC 基准有一定的重叠,尽管图像并不完全相同;同样的场景在两个数据集中都存在。例如,MegaDepth 场景对应大英博物馆,而大英博物馆也是 IMC 基准中的一个场景。为了进行公平比较,我们采用与 DUSt3R 和 MASt3R 相同的训练划分。在主文中,为了在 ScanNet-1500 上确保公平比较,我们在训练中排除了相应的 ScanNet 场景。
Results.
Table 10 contains the results of our evaluation. Although phototourism data is the traditional focus of SfM methods, our VGGT’s feed-forward performance is on par with the state-of-the-art VGGSfMv2 with AUC@10 of versus , while being significantly faster (0.2 vs. 10 seconds per scene). Remarkably, VGGT outperforms both MASt3R [62] and DUSt3R [129] significantly across all accuracy thresholds while being much faster. This is because MASt3R’s and DUSt3R’s feed-forward predictions can only process pairs of frames and, hence, require a costly global alignment step. Additionally, with bundle adjustment, VGGT + BA further improves drastically, achieving state-of-the-art performance on IMC, raising AUC@10 from to , and raising AUC@3 from to . Note that our model directly predicts 3D points, which can serve as the initialization for BA. This eliminates the need for triangulation and iterative refinement of BA as in [125]. As a result, VGGT + BA is much faster than [125].
结果。
表 10 包含我们的评估结果。 尽管摄影旅游数据是 SfM 方法的传统焦点,但我们的 VGGT 的前馈性能与最先进的 VGGSfMv2 相当,其中与的 AUC@10 相同,同时速度明显更快(每个场景 0.2 秒与 10 秒)。 值得注意的是,VGGT 在所有精度阈值上均显着优于 MASt3R [62] 和 DUSt3R [129],同时速度更快。 这是因为 MASt3R 和 DUSt3R 的前馈预测只能处理帧对,因此需要昂贵的全局对齐步骤。 此外,通过捆绑调整,VGGT + BA 进一步大幅提高,在 IMC 上实现了最先进的性能,将 AUC@10 从提高到,并将 AUC@3 从提高到。 请注意,我们的模型直接预测 3D 点,这可以作为 BA 的初始化。 这消除了对 BA 的三角测量和迭代细化的需要,如[125]中所示。 因此,VGGT + BA 比 [125] 快得多。
| Method | Test-time Opt. | AUC@3 | AUC@5 | AUC@10 | Runtime |
|---|---|---|---|---|---|
| COLMAP (SIFT+NN) [94] | ✓ | 23.58 | 32.66 | 44.79 | 10s |
| PixSfM (SIFT + NN) [66] | ✓ | 25.54 | 34.80 | 46.73 | 20s |
| PixSfM (LoFTR) [66] | ✓ | 44.06 | 56.16 | 69.61 | 20s |
| PixSfM (SP + SG) [66] | ✓ | 45.19 | 57.22 | 70.47 | 20s |
| DFSfM (LoFTR) [47] | ✓ | 46.55 | 58.74 | 72.19 | 10s |
| DUSt3R [129] | ✓ | 13.46 | 21.24 | 35.62 | 7s |
| MASt3R [62] | ✓ | 30.25 | 46.79 | 57.42 | 9s |
| VGGSfM [125] | ✓ | 45.23 | 58.89 | 73.92 | 6s |
| VGGSfMv2 [125] | ✓ | 59.32 | 67.78 | 76.82 | 10s |
| VGGT (ours) | ✗ | 39.23 | 52.74 | 71.26 | 0.2s |
| VGGT + BA (ours) | ✓ | 66.37 | 75.16 | 84.91 | 1.8s |
Table 10: Camera Pose Estimation on IMC [54]. Our method achieves state-of-the-art performance on the challenging phototropism data, outperforming VGGSfMv2 [125] which ranked first on the latest CVPR’24 IMC Challenge in camera pose (rotation and translation) estimation.
| 方法 | 测试时优化 | AUC@3 | AUC@5 | AUC@10 | 运行时 |
|---|---|---|---|---|---|
| COLMAP(SIFT+NN)[94] | ✓ | 23.58 | 32.66 | 44.79 | 10s |
| PixSfM(SIFT + NN)[66] | ✓ | 25.54 | 34.80 | 46.73 | 20s |
| PixSfM(LoFTR) [66] | ✓ | 44.06 | 56.16 | 69.61 | 20s |
| PixSfM(SP + SG) [66] | ✓ | 45.19 | 57.22 | 70.47 | 20s |
| DFSfM(LoFTR)[47] | ✓ | 46.55 | 58.74 | 72.19 | 10s |
| DUSt3R [129] | ✓ | 13.46 | 21.24 | 35.62 | 7s |
| MASt3R [62] | ✓ | 30.25 | 46.79 | 57.42 | 9s |
| VGGSfM [125] | ✓ | 45.23 | 58.89 | 73.92 | 6s |
| VGGSfMv2 [125] | ✓ | 59.32 | 67.78 | 76.82 | 10s |
| VGGT(我们的) | ✗ | 39.23 | 52.74 | 71.26 | 0.2秒 |
| VGGT + BA(我们的) | ✓ | 66.37 | 75.16 | 84.91 | 1.8s |
表 10:IMC [54] 上的相机位姿估计。我们的方法在具有挑战性的向光性数据上达到了最先进的性能,超过了 VGGSfMv2 [125],后者在最新的 CVPR’24 IMC 挑战赛中在相机位姿(旋转和平移)估计方面排名第一。
Appendix D Qualitative Examples
附录 D 定性示例
We further present qualitative examples of single-view reconstruction in Fig. 7.
我们在图 7 中进一步展示了单视图重建的定性示例。
Appendix E Related Work
附录 E 相关工作
In this section, we discuss additional related works.
在本节中,我们讨论其他相关的工作。
Vision Transformers.
The Transformer architecture was initially proposed for language processing tasks [120, 22, 6]. It was later introduced to the computer vision community by ViT [27], sparking widespread adoption. Vision Transformers and their variants have since become dominant in the design of architectures for various computer vision tasks [4, 83, 12, 137], thanks to their simplicity, high capacity, flexibility, and ability to capture long-range dependencies.
视觉Transformer。
Transformer架构最初是为语言处理任务提出的 [120, 22, 6]。后来由 ViT [27] 引入计算机视觉领域,激发了广泛的应用。得益于其简洁性、高容量、灵活性以及捕捉长程依赖的能力,视觉Transformer及其变体此后已成为各种计算机视觉任务架构设计的主导 [4, 83, 12, 137]。
DeiT [114] demonstrated that Vision Transformers can be effectively trained on datasets like ImageNet using strong data augmentation strategies. DINO [10] revealed intriguing properties of features learned by Vision Transformers in a self-supervised manner. CaiT [115] introduced layer scaling to address the challenges of training deeper Vision Transformers, effectively mitigating gradient-related issues. Further, techniques such as QKNorm [48, 150] have been proposed to stabilize the training process. Additionally, [138] also explores the dynamics between frame-wise and global attention modules in object tracking, though using cross-attention.
DeiT [114] 展示了可以通过强数据增强策略在像 ImageNet 这样的数据集上有效地训练视觉Transformer。DINO [10] 揭示了视觉Transformer以自监督方式学习的特征的有趣属性。CaiT [115] 引入了层归一化来解决训练更深的视觉Transformer的挑战,有效缓解了梯度相关问题。此外,还提出了诸如 QKNorm [48, 150] 的技术以稳定训练过程。此外,[138] 还探讨了在目标跟踪中逐帧与全局注意力模块之间的动态关系,尽管使用了交叉注意力。
Camera Pose Estimation.
Estimating camera poses from multi-view images is a crucial problem in 3D computer vision. Over the last decades, Structure from Motion (SfM) has emerged as the dominant approach [46], whether incremental [103, 2, 36, 134, 94] or global [3, 14, 17, 73, 106, 90, 79, 52, 16, 15, 81]. Recently, a set of methods treat camera pose estimation as a regression problem [160, 118, 109, 131, 122, 112, 113, 152, 100, 123, 65, 153], which show promising results under the sparse-view setting. Ace-Zero [5] further proposes to regress 3D scene coordinates and FlowMap [101] focuses on depth maps, as intermediates for camera prediction. Instead, VGGSfM [125] simplifies the classical SfM pipeline to a differentiable framework, demonstrating exceptional performance, particularly with phototourism datasets. At the same time, DUSt3R [129, 62] introduces an approach to learn pixel-aligned point map, and hence camera poses can be recovered by simple alignment. This paradigm shift has garnered considerable interest as the point map, an over-parameterized representation, offers seamless integration with various downstream applications, such as 3D Gaussian splatting.
相机位姿估计。
从多视图图像中估计相机位姿是 3D 计算机视觉中的一个关键问题。 在过去的几十年里,运动结构(SfM)已成为主导方法[46],无论是增量[103,2,36,134,94]还是全局[3,14,17,73,106,90,79,52,16,15,81]。 最近,一组方法将相机位姿估计视为回归问题[160,118,109,131,122,112,113,152,100,123,65,153],在稀疏视图设置下显示出有希望的结果。 Ace-Zero [5] 进一步建议回归 3D 场景坐标,FlowMap [101] 专注于深度图,作为相机预测的中间体。 相反,VGGSfM [125] 将经典的 SfM 流程简化为可微分框架,展示了卓越的性能,尤其是在摄影旅游数据集上。 同时,DUSt3R [129, 62] 引入了一种学习像素对齐点图的方法,因此可以通过简单的对齐来恢复相机位姿。 这种范式转变引起了相当大的兴趣,因为点图(一种过度参数化的表示)提供了与各种下游应用程序(例如 3D 高斯分布)的无缝集成。
References
参考文献
[1] Josh Achiam, Steven Adler, Sandhini Agarwal, Lama Ahmad, Ilge Akkaya, Florencia Leoni Aleman, Diogo Almeida, Janko Altenschmidt, Sam Altman, Shyamal Anadkat, et al. Gpt-4 technical report. arXiv preprint arXiv:2303.08774 , 2023.
[2] Sameer Agarwal, Yasutaka Furukawa, Noah Snavely, Ian Simon, Brian Curless, Steven M Seitz, and Richard Szeliski. Building rome in a day. Communications of the ACM , 54(10):105–112, 2011.
[3] Mica Arie-Nachimson, Shahar Z Kovalsky, Ira Kemelmacher-Shlizerman, Amit Singer, and Ronen Basri. Global motion estimation from point matches. In 2012 Second international conference on 3D imaging, modeling, processing, visualization & transmission , pages 81–88. IEEE, 2012.
[4] Anurag Arnab, Mostafa Dehghani, Georg Heigold, Chen Sun, Mario Lučić, and Cordelia Schmid. Vivit: A video vision transformer. In Proceedings of the IEEE/CVF international conference on computer vision , pages 6836–6846, 2021.
[5] Eric Brachmann, Jamie Wynn, Shuai Chen, Tommaso Cavallari, Áron Monszpart, Daniyar Turmukhambetov, and Victor Adrian Prisacariu. Scene coordinate reconstruction: Posing of image collections via incremental learning of a relocalizer. In ECCV , 2024.
[6] Tom B Brown. Language models are few-shot learners. arXiv preprint arXiv:2005.14165 , 2020.
[7] Yohann Cabon, Naila Murray, and Martin Humenberger. Virtual kitti 2. arXiv preprint arXiv:2001.10773 , 2020.
[8] Ang Cao, Justin Johnson, Andrea Vedaldi, and David Novotny. Lightplane: Highly-scalable components for neural 3Dfields. In Proceedings of the International Conference on 3D Vision (3DV) , 2025.
[9] Chenjie Cao and Yanwei Fu. Improving transformer-based image matching by cascaded capturing spatially informative keypoints. In Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV) , pages 12129–12139, 2023.
[10] Mathilde Caron, Hugo Touvron, Ishan Misra, Hervé Jégou, Julien Mairal, Piotr Bojanowski, and Armand Joulin. Emerging properties in self-supervised vision transformers. In Proc. ICCV , 2021.
[11] Hongkai Chen, Zixin Luo, Jiahui Zhang, Lei Zhou, Xuyang Bai, Zeyu Hu, Chiew-Lan Tai, and Long Quan. Learning to match features with seeded graph matching network. In Proceedings of the IEEE/CVF International Conference on Computer Vision , pages 6301–6310, 2021.
[12] Bowen Cheng, Ishan Misra, Alexander G Schwing, Alexander Kirillov, and Rohit Girdhar. Masked-attention mask transformer for universal image segmentation. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition , pages 1290–1299, 2022.
[13] Seokju Cho, Jiahui Huang, Jisu Nam, Honggyu An, Seungryong Kim, and Joon-Young Lee. Local all-pair correspondence for point tracking. Proc. ECCV , 2024.
[14] David J Crandall, Andrew Owens, Noah Snavely, and Daniel P Huttenlocher. Sfm with mrfs: Discrete-continuous optimization for large-scale structure from motion. IEEE transactions on pattern analysis and machine intelligence , 35(12):2841–2853, 2012.
[15] Hainan Cui, Xiang Gao, Shuhan Shen, and Zhanyi Hu. Hsfm: Hybrid structure-from-motion. In Proceedings of the IEEE conference on computer vision and pattern recognition , pages 1212–1221, 2017.
[16] Zhaopeng Cui and Ping Tan. Global structure-from-motion by similarity averaging. In Proceedings of the IEEE International Conference on Computer Vision , pages 864–872, 2015.
[17] Zhaopeng Cui, Nianjuan Jiang, Chengzhou Tang, and Ping Tan. Linear global translation estimation with feature tracks. arXiv preprint arXiv:1503.01832 , 2015.
[18] Angela Dai, Angel X Chang, Manolis Savva, Maciej Halber, Thomas Funkhouser, and Matthias Nießner. Scannet: Richly-annotated 3d reconstructions of indoor scenes. In Proceedings of the IEEE conference on computer vision and pattern recognition , pages 5828–5839, 2017.
[19] Timothée Darcet, Maxime Oquab, Julien Mairal, and Piotr Bojanowski. Vision transformers need registers. arXiv preprint arXiv:2309.16588 , 2023.
[20] Matt Deitke, Dustin Schwenk, Jordi Salvador, Luca Weihs, Oscar Michel, Eli VanderBilt, Ludwig Schmidt, Kiana Ehsani, Aniruddha Kembhavi, and Ali Farhadi. Objaverse: A universe of annotated 3d objects. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition , pages 13142–13153, 2023.
[21] Daniel DeTone, Tomasz Malisiewicz, and Andrew Rabinovich. Superpoint: Self-supervised interest point detection and description. In Proceedings of the IEEE conference on computer vision and pattern recognition workshops , pages 224–236, 2018.
[22] Jacob Devlin, Ming-Wei Chang, Kenton Lee, and Kristina Toutanova. Bert: Pre-training of deep bidirectional transformers for language understanding. In North American Chapter of the Association for Computational Linguistics , 2019.
[23] Carl Doersch, Ankush Gupta, Larisa Markeeva, Adrià Recasens, Lucas Smaira, Yusuf Aytar, João Carreira, Andrew Zisserman, and Yi Yang. Tap-vid: A benchmark for tracking any point in a video. arXiv , 2022.
[24] Carl Doersch, Yi Yang, Mel Vecerik, Dilara Gokay, Ankush Gupta, Yusuf Aytar, Joao Carreira, and Andrew Zisserman. TAPIR: Tracking any point with per-frame initialization and temporal refinement. arXiv , 2306.08637, 2023a.
[25] Carl Doersch, Yi Yang, Mel Vecerik, Dilara Gokay, Ankush Gupta, Yusuf Aytar, Joao Carreira, and Andrew Zisserman. TAPIR: tracking any point with per-frame initialization and temporal refinement. In Proc. CVPR , 2023b.
[26] Carl Doersch, Yi Yang, Dilara Gokay, Pauline Luc, Skanda Koppula, Ankush Gupta, Joseph Heyward, Ross Goroshin, João Carreira, and Andrew Zisserman. Bootstap: Bootstrapped training for tracking-any-point. arXiv preprint arXiv:2402.00847 , 2024.
[27] Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, and Neil Houlsby. An image is worth 16 × \times 16 words: Transformers for image recognition at scale. In Proc. ICLR , 2021.
[28] Laura Downs, Anthony Francis, Nate Koenig, Brandon Kinman, Ryan Hickman, Krista Reymann, Thomas B McHugh, and Vincent Vanhoucke. Google scanned objects: A high-quality dataset of 3d scanned household items. In 2022 International Conference on Robotics and Automation (ICRA) , pages 2553–2560. IEEE, 2022.
[29] Abhimanyu Dubey, Abhinav Jauhri, Abhinav Pandey, Abhishek Kadian, Ahmad Al-Dahle, Aiesha Letman, Akhil Mathur, Alan Schelten, Amy Yang, Angela Fan, Anirudh Goyal, Anthony Hartshorn, Aobo Yang, Archi Mitra, Archie Sravankumar, Artem Korenev, Arthur Hinsvark, Arun Rao, Aston Zhang, Aurélien Rodriguez, Austen Gregerson, Ava Spataru, Baptiste Rozière, Bethany Biron, Binh Tang, Bobbie Chern, Charlotte Caucheteux, Chaya Nayak, Chloe Bi, Chris Marra, Chris McConnell, Christian Keller, Christophe Touret, Chunyang Wu, Corinne Wong, Cristian Canton Ferrer, Cyrus Nikolaidis, Damien Allonsius, Daniel Song, Danielle Pintz, Danny Livshits, David Esiobu, Dhruv Choudhary, Dhruv Mahajan, Diego Garcia-Olano, Diego Perino, Dieuwke Hupkes, Egor Lakomkin, Ehab AlBadawy, Elina Lobanova, Emily Dinan, Eric Michael Smith, Filip Radenovic, Frank Zhang, Gabriel Synnaeve, Gabrielle Lee, Georgia Lewis Anderson, Graeme Nail, Grégoire Mialon, Guan Pang, Guillem Cucurell, Hailey Nguyen, Hannah Korevaar, Hu Xu, Hugo Touvron, Iliyan Zarov, Imanol Arrieta Ibarra, Isabel M. Kloumann, Ishan Misra, Ivan Evtimov, Jade Copet, Jaewon Lee, Jan Geffert, Jana Vranes, Jason Park, Jay Mahadeokar, Jeet Shah, Jelmer van der Linde, Jennifer Billock, Jenny Hong, Jenya Lee, Jeremy Fu, Jianfeng Chi, Jianyu Huang, Jiawen Liu, Jie Wang, Jiecao Yu, Joanna Bitton, Joe Spisak, Jongsoo Park, Joseph Rocca, Joshua Johnstun, Joshua Saxe, Junteng Jia, Kalyan Vasuden Alwala, Kartikeya Upasani, Kate Plawiak, Ke Li, Kenneth Heafield, and Kevin Stone. The Llama 3 herd of models. arXiv , 2407.21783, 2024.
[30] Bardienus Duisterhof, Lojze Zust, Philippe Weinzaepfel, Vincent Leroy, Yohann Cabon, and Jerome Revaud. MASt3R-SfM: a fully-integrated solution for unconstrained structure-from-motion. arXiv , 2409.19152, 2024.
[31] Mihai Dusmanu, Ignacio Rocco, Tomas Pajdla, Marc Pollefeys, Josef Sivic, Akihiko Torii, and Torsten Sattler. D2-net: A trainable cnn for joint description and detection of local features. In Proceedings of the ieee/cvf conference on computer vision and pattern recognition , pages 8092–8101, 2019.
[32] Johan Edstedt, Ioannis Athanasiadis, Mårten Wadenbäck, and Michael Felsberg. DKM: Dense kernelized feature matching for geometry estimation. In IEEE Conference on Computer Vision and Pattern Recognition , 2023.
[33] Johan Edstedt, Qiyu Sun, Georg Bökman, Mårten Wadenbäck, and Michael Felsberg. Roma: Robust dense feature matching. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition , pages 19790–19800, 2024.
[34] Patrick Esser, Robin Rombach, and Björn Ommer. Taming transformers for high-resolution image synthesis. In Proc. CVPR , 2021.
[35] Martin A Fischler and Robert C Bolles. Random sample consensus: a paradigm for model fitting with applications to image analysis and automated cartography. Communications of the ACM , 24(6):381–395, 1981.
[36] Jan-Michael Frahm, Pierre Fite-Georgel, David Gallup, Tim Johnson, Rahul Raguram, Changchang Wu, Yi-Hung Jen, Enrique Dunn, Brian Clipp, Svetlana Lazebnik, et al. Building rome on a cloudless day. In Computer Vision–ECCV 2010: 11th European Conference on Computer Vision, Heraklion, Crete, Greece, September 5-11, 2010, Proceedings, Part IV 11 , pages 368–381. Springer, 2010.
[37] Qiancheng Fu, Qingshan Xu, Yew Soon Ong, and Wenbing Tao. Geo-neus: Geometry-consistent neural implicit surfaces learning for multi-view reconstruction. Advances in Neural Information Processing Systems , 35:3403–3416, 2022.
[38] Yasutaka Furukawa, Carlos Hernández, et al. Multi-view stereo: A tutorial. Foundations and Trends® in Computer Graphics and Vision , 9(1-2):1–148, 2015.
[39] Silvano Galliani, Katrin Lasinger, and Konrad Schindler. Massively parallel multiview stereopsis by surface normal diffusion. In Proceedings of the IEEE international conference on computer vision , pages 873–881, 2015a.
[40] Silvano Galliani, Katrin Lasinger, and Konrad Schindler. Massively parallel multiview stereopsis by surface normal diffusion. In ICCV , 2015b.
[41] Klaus Greff, Francois Belletti, Lucas Beyer, Carl Doersch, Yilun Du, Daniel Duckworth, David J Fleet, Dan Gnanapragasam, Florian Golemo, Charles Herrmann, Thomas Kipf, Abhijit Kundu, Dmitry Lagun, Issam Laradji, Hsueh-Ti (Derek) Liu, Henning Meyer, Yishu Miao, Derek Nowrouzezahrai, Cengiz Oztireli, Etienne Pot, Noha Radwan, Daniel Rebain, Sara Sabour, Mehdi S. M. Sajjadi, Matan Sela, Vincent Sitzmann, Austin Stone, Deqing Sun, Suhani Vora, Ziyu Wang, Tianhao Wu, Kwang Moo Yi, Fangcheng Zhong, and Andrea Tagliasacchi. Kubric: a scalable dataset generator. In Proc. CVPR , 2022.
[42] Xiaodong Gu, Zhiwen Fan, Siyu Zhu, Zuozhuo Dai, Feitong Tan, and Ping Tan. Cascade cost volume for high-resolution multi-view stereo and stereo matching. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition , pages 2495–2504, 2020.
[43] Junlin Han, Jianyuan Wang, Andrea Vedaldi, Philip Torr, and Filippos Kokkinos. Flex3d: Feed-forward 3d generation with flexible reconstruction model and input view curation. arXiv preprint arXiv:2410.00890 , 2024.
[44] Adam W Harley, Zhaoyuan Fang, and Katerina Fragkiadaki. Particle video revisited: Tracking through occlusions using point trajectories. In Proc. ECCV , 2022.
[45] Richard Hartley and Andrew Zisserman. Multiple View Geometry in Computer Vision . Cambridge University Press, 2000.
[46] Richard Hartley and Andrew Zisserman. Multiple View Geometry in Computer Vision . Cambridge University Press, ISBN: 0521540518, 2004.
[47] Xingyi He, Jiaming Sun, Yifan Wang, Sida Peng, Qixing Huang, Hujun Bao, and Xiaowei Zhou. Detector-free structure from motion. In arxiv , 2023.
[48] Alex Henry, Prudhvi Raj Dachapally, Shubham Pawar, and Yuxuan Chen. Query-key normalization for transformers. arXiv preprint arXiv:2010.04245 , 2020.
[49] Yicong Hong, Kai Zhang, Jiuxiang Gu, Sai Bi, Yang Zhou, Difan Liu, Feng Liu, Kalyan Sunkavalli, Trung Bui, and Hao Tan. LRM: Large reconstruction model for single image to 3D. In Proc. ICLR , 2024.
[50] Po-Han Huang, Kevin Matzen, Johannes Kopf, Narendra Ahuja, and Jia-Bin Huang. Deepmvs: Learning multi-view stereopsis. In IEEE Conference on Computer Vision and Pattern Recognition (CVPR) , 2018.
[51] Rasmus Jensen, Anders Dahl, George Vogiatzis, Engil Tola, and Henrik Aanæs. Large scale multi-view stereopsis evaluation. In 2014 IEEE Conference on Computer Vision and Pattern Recognition , pages 406–413. IEEE, 2014.
[52] Nianjuan Jiang, Zhaopeng Cui, and Ping Tan. A global linear method for camera pose registration. In Proceedings of the IEEE international conference on computer vision , pages 481–488, 2013.
[53] Haian Jin, Hanwen Jiang, Hao Tan, Kai Zhang, Sai Bi, Tianyuan Zhang, Fujun Luan, Noah Snavely, and Zexiang Xu. LVSM: a large view synthesis model with minimal 3D inductive bias. arXiv , 2410.17242, 2024.
[54] Yuhe Jin, Dmytro Mishkin, Anastasiia Mishchuk, Jiri Matas, Pascal Fua, Kwang Moo Yi, and Eduard Trulls. Image matching across wide baselines: From paper to practice. International Journal of Computer Vision , 129(2):517–547, 2021.
[55] Nikita Karaev, Iurii Makarov, Jianyuan Wang, Natalia Neverova, Andrea Vedaldi, and Christian Rupprecht. Cotracker3: Simpler and better point tracking by pseudo-labelling real videos. arXiv preprint arXiv:2410.11831 , 2024a.
[56] Nikita Karaev, Ignacio Rocco, Benjamin Graham, Natalia Neverova, Andrea Vedaldi, and Christian Rupprecht. Cotracker: It is better to track together. Proc. ECCV , 2024b.
[57] Nikita Karaev, Ignacio Rocco, Ben Graham, Natalia Neverova, Andrea Vedaldi, and Christian Rupprecht. CoTracker: It is better to track together. In Proceedings of the European Conference on Computer Vision (ECCV) , 2024c.
[58] Alex Kendall and Roberto Cipolla. Modelling uncertainty in deep learning for camera relocalization. In Proc. ICRA . IEEE, 2016.
[59] Alex Kendall and Yarin Gal. What uncertainties do we need in Bayesian deep learning for computer vision? Proc. NeurIPS , 2017.
[60] Guillaume Le Moing, Jean Ponce, and Cordelia Schmid. Dense optical tracking: Connecting the dots. In CVPR , 2024.
[61] Vincent Lepetit, Francesc Moreno-Noguer, and Pascal Fua. Ep n p: An accurate o (n) solution to the p n p problem. International journal of computer vision , 81:155–166, 2009.
[62] Vincent Leroy, Yohann Cabon, and Jérôme Revaud. Grounding image matching in 3d with mast3r. arXiv preprint arXiv:2406.09756 , 2024.
[63] Hongyang Li, Hao Zhang, Shilong Liu, Zhaoyang Zeng, Tianhe Ren, Feng Li, and Lei Zhang. Taptr: Tracking any point with transformers as detection. arXiv preprint arXiv:2403.13042 , 2024.
[64] Zhengqi Li and Noah Snavely. Megadepth: Learning single-view depth prediction from internet photos. In Proceedings of the IEEE conference on computer vision and pattern recognition , pages 2041–2050, 2018.
[65] Amy Lin, Jason Y Zhang, Deva Ramanan, and Shubham Tulsiani. Relpose++: Recovering 6d poses from sparse-view observations. arXiv preprint arXiv:2305.04926 , 2023.
[66] Philipp Lindenberger, Paul-Edouard Sarlin, Viktor Larsson, and Marc Pollefeys. Pixel-perfect structure-from-motion with featuremetric refinement. arXiv.cs , abs/2108.08291, 2021.
[67] Philipp Lindenberger, Paul-Edouard Sarlin, and Marc Pollefeys. Lightglue: Local feature matching at light speed. arXiv preprint arXiv:2306.13643 , 2023a.
[68] Philipp Lindenberger, Paul-Edouard Sarlin, and Marc Pollefeys. LightGlue: local feature matching at light speed. In Proc. ICCV , 2023b.
[69] Lu Ling, Yichen Sheng, Zhi Tu, Wentian Zhao, Cheng Xin, Kun Wan, Lantao Yu, Qianyu Guo, Zixun Yu, Yawen Lu, et al. Dl3dv-10k: A large-scale scene dataset for deep learning-based 3d vision. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition , pages 22160–22169, 2024.
[70] Shaohui Liu, Yidan Gao, Tianyi Zhang, Rémi Pautrat, Johannes L Schönberger, Viktor Larsson, and Marc Pollefeys. Robust incremental structure-from-motion with hybrid features. In European Conference on Computer Vision , pages 249–269. Springer, 2025.
[71] Manuel Lopez-Antequera, Pau Gargallo, Markus Hofinger, Samuel Rota Bulò, Yubin Kuang, and Peter Kontschieder. Mapillary planet-scale depth dataset. In Proceedings of the European Conference on Computer Vision (ECCV) , 2020.
[72] Zeyu Ma, Zachary Teed, and Jia Deng. Multiview stereo with cascaded epipolar raft. In European Conference on Computer Vision , pages 734–750. Springer, 2022.
[73] Pierre Moulon, Pascal Monasse, and Renaud Marlet. Global fusion of relative motions for robust, accurate and scalable structure from motion. In Proceedings of the IEEE international conference on computer vision , pages 3248–3255, 2013.
[74] Michael Niemeyer, Lars Mescheder, Michael Oechsle, and Andreas Geiger. Differentiable volumetric rendering: Learning implicit 3d representations without 3d supervision. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition , pages 3504–3515, 2020.
[75] David Novotný, Diane Larlus, and Andrea Vedaldi. Learning 3D object categories by looking around them. In Proceedings of the International Conference on Computer Vision (ICCV) , 2017.
[76] David Novotný, Diane Larlus, and Andrea Vedaldi. Capturing the geometry of object categories from video supervision. IEEE Transactions on Pattern Analysis and Machine Intelligence , 2018.
[77] John Oliensis. A critique of structure-from-motion algorithms. Computer Vision and Image Understanding , 80(2):172–214, 2000.
[78] Maxime Oquab, Timothée Darcet, Théo Moutakanni, Huy V. Vo, Marc Szafraniec, Vasil Khalidov, Pierre Fernandez, Daniel HAZIZA, Francisco Massa, Alaaeldin El-Nouby, Mido Assran, Nicolas Ballas, Wojciech Galuba, Russell Howes, Po-Yao Huang, Shang-Wen Li, Ishan Misra, Michael Rabbat, Vasu Sharma, Gabriel Synnaeve, Hu Xu, Herve Jegou, Julien Mairal, Patrick Labatut, Armand Joulin, and Piotr Bojanowski. DINOv2: Learning robust visual features without supervision. Transactions on Machine Learning Research , 2024.
[79] Onur Ozyesil and Amit Singer. Robust camera location estimation by convex programming. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pages 2674–2683, 2015.
[80] Onur Özyeşil, Vladislav Voroninski, Ronen Basri, and Amit Singer. A survey of structure from motion*. Acta Numerica , 26:305–364, 2017.
[81] Linfei Pan, Daniel Barath, Marc Pollefeys, and Johannes Lutz Schönberger. Global Structure-from-Motion Revisited. In European Conference on Computer Vision (ECCV) , 2024.
[82] Xiaqing Pan, Nicholas Charron, Yongqian Yang, Scott Peters, Thomas Whelan, Chen Kong, Omkar Parkhi, Richard Newcombe, and Yuheng (Carl) Ren. Aria digital twin: A new benchmark dataset for egocentric 3d machine perception. In Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV) , pages 20133–20143, 2023.
[83] William Peebles and Saining Xie. Scalable diffusion models with transformers. In Proceedings of the IEEE/CVF International Conference on Computer Vision , pages 4195–4205, 2023.
[84] Rui Peng, Rongjie Wang, Zhenyu Wang, Yawen Lai, and Ronggang Wang. Rethinking depth estimation for multi-view stereo: A unified representation. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition , pages 8645–8654, 2022.
[85] Luis Pineda, Taosha Fan, Maurizio Monge, Shobha Venkataraman, Paloma Sodhi, Ricky TQ Chen, Joseph Ortiz, Daniel DeTone, Austin Wang, Stuart Anderson, et al. Theseus: A library for differentiable nonlinear optimization. Advances in Neural Information Processing Systems , 35:3801–3818, 2022.
[86] Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, and Ilya Sutskever. Learning transferable visual models from natural language supervision. In Proc. ICML , pages 8748–8763, 2021.
[87] René Ranftl, Alexey Bochkovskiy, and Vladlen Koltun. Vision transformers for dense prediction. In Proceedings of the IEEE/CVF international conference on computer vision , pages 12179–12188, 2021.
[88] Jeremy Reizenstein, Roman Shapovalov, Philipp Henzler, Luca Sbordone, Patrick Labatut, and David Novotny. Common Objects in 3D: Large-scale learning and evaluation of real-life 3D category reconstruction. In Proc. ICCV , 2021.
[89] Mike Roberts, Jason Ramapuram, Anurag Ranjan, Atulit Kumar, Miguel Angel Bautista, Nathan Paczan, Russ Webb, and Joshua M. Susskind. Hypersim: A photorealistic synthetic dataset for holistic indoor scene understanding. In International Conference on Computer Vision (ICCV) 2021 , 2021.
[90] Rother. Linear multiview reconstruction of points, lines, planes and cameras using a reference plane. In Proceedings Ninth IEEE International Conference on Computer Vision , pages 1210–1217. IEEE, 2003.
[91] Peter Sand and Seth Teller. Particle video: Long-range motion estimation using point trajectories. IJCV , 80, 2008.
[92] Paul-Edouard Sarlin, Daniel DeTone, Tomasz Malisiewicz, and Andrew Rabinovich. Superglue: Learning feature matching with graph neural networks. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition , pages 4938–4947, 2020a.
[93] Paul-Edouard Sarlin, Daniel DeTone, Tomasz Malisiewicz, and Andrew Rabinovich. SuperGlue: learning feature matching with graph neural networks. In Proc. CVPR , 2020b.
[94] Johannes Lutz Schönberger and Jan-Michael Frahm. Structure-from-motion revisited. In Conference on Computer Vision and Pattern Recognition (CVPR) , 2016a.
[95] Johannes Lutz Schönberger and Jan-Michael Frahm. Structure-from-motion revisited. In Proc. CVPR , 2016b.
[96] Johannes L Schönberger, Enliang Zheng, Jan-Michael Frahm, and Marc Pollefeys. Pixelwise view selection for unstructured multi-view stereo. In Computer Vision–ECCV 2016: 14th European Conference, Amsterdam, The Netherlands, October 11-14, 2016, Proceedings, Part III 14 , pages 501–518. Springer, 2016.
[97] Thomas Schops, Johannes L Schonberger, Silvano Galliani, Torsten Sattler, Konrad Schindler, Marc Pollefeys, and Andreas Geiger. A multi-view stereo benchmark with high-resolution images and multi-camera videos. In Proceedings of the IEEE conference on computer vision and pattern recognition , pages 3260–3269, 2017.
[98] Jay Shah, Ganesh Bikshandi, Ying Zhang, Vijay Thakkar, Pradeep Ramani, and Tri Dao. Flashattention-3: Fast and accurate attention with asynchrony and low-precision. Advances in Neural Information Processing Systems , 37:68658–68685, 2024.
[99] Yan Shi, Jun-Xiong Cai, Yoli Shavit, Tai-Jiang Mu, Wensen Feng, and Kai Zhang. Clustergnn: Cluster-based coarse-to-fine graph neural network for efficient feature matching. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition , pages 12517–12526, 2022.
[100] Samarth Sinha, Jason Y Zhang, Andrea Tagliasacchi, Igor Gilitschenski, and David B Lindell. Sparsepose: Sparse-view camera pose regression and refinement. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition , pages 21349–21359, 2023.
[101] Cameron Smith, David Charatan, Ayush Tewari, and Vincent Sitzmann. Flowmap: High-quality camera poses, intrinsics, and depth via gradient descent. arXiv preprint arXiv:2404.15259 , 2024a.
[102] Cameron Smith, David Charatan, Ayush Tewari, and Vincent Sitzmann. FlowMap: high-quality camera poses, intrinsics, and depth via gradient descent. arXiv , 2404.15259, 2024b.
[103] Noah Snavely, Steven M Seitz, and Richard Szeliski. Photo tourism: exploring photo collections in 3d. In ACM siggraph 2006 papers , pages 835–846. 2006.
[104] Julian Straub, Thomas Whelan, Lingni Ma, Yufan Chen, Erik Wijmans, Simon Green, Jakob J Engel, Raul Mur-Artal, Carl Ren, Shobhit Verma, et al. The replica dataset: A digital replica of indoor spaces. arXiv preprint arXiv:1906.05797 , 2019.
[105] Jiaming Sun, Zehong Shen, Yuang Wang, Hujun Bao, and Xiaowei Zhou. Loftr: Detector-free local feature matching with transformers. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition , pages 8922–8931, 2021.
[106] Chris Sweeney, Torsten Sattler, Tobias Hollerer, Matthew Turk, and Marc Pollefeys. Optimizing the viewing graph for structure-from-motion. In Proceedings of the IEEE international conference on computer vision , pages 801–809, 2015.
[107] Andrew Szot, Alex Clegg, Eric Undersander, Erik Wijmans, Yili Zhao, John Turner, Noah Maestre, Mustafa Mukadam, Devendra Chaplot, Oleksandr Maksymets, Aaron Gokaslan, Vladimir Vondrus, Sameer Dharur, Franziska Meier, Wojciech Galuba, Angel Chang, Zsolt Kira, Vladlen Koltun, Jitendra Malik, Manolis Savva, and Dhruv Batra. Habitat 2.0: Training home assistants to rearrange their habitat. In Advances in Neural Information Processing Systems (NeurIPS) , 2021.
[108] Stanislaw Szymanowicz, Chrisitian Rupprecht, and Andrea Vedaldi. Splatter image: Ultra-fast single-view 3d reconstruction. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition , pages 10208–10217, 2024.
[109] Chengzhou Tang and Ping Tan. Ba-net: Dense bundle adjustment network. arXiv preprint arXiv:1806.04807 , 2018.
[110] Jiaxiang Tang, Zhaoxi Chen, Xiaokang Chen, Tengfei Wang, Gang Zeng, and Ziwei Liu. Lgm: Large multi-view gaussian model for high-resolution 3d content creation. In European Conference on Computer Vision , pages 1–18. Springer, 2024a.
[111] Zhenggang Tang, Yuchen Fan, Dilin Wang, Hongyu Xu, Rakesh Ranjan, Alexander Schwing, and Zhicheng Yan. Mv-dust3r+: Single-stage scene reconstruction from sparse views in 2 seconds. arXiv preprint arXiv:2412.06974 , 2024b.
[112] Zachary Teed and Jia Deng. Deepv2d: Video to depth with differentiable structure from motion. arXiv preprint arXiv:1812.04605 , 2018.
[113] Zachary Teed and Jia Deng. Droid-slam: Deep visual slam for monocular, stereo, and rgb-d cameras. Advances in neural information processing systems , 34:16558–16569, 2021.
[114] Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, and Hervé Jégou. Training data-efficient image transformers & distillation through attention. In International conference on machine learning , pages 10347–10357. PMLR, 2021a.
[115] Hugo Touvron, Matthieu Cord, Alexandre Sablayrolles, Gabriel Synnaeve, and Hervé Jégou. Going deeper with image transformers. In Proceedings of the IEEE/CVF international conference on computer vision , pages 32–42, 2021b.
[116] Michał Tyszkiewicz, Pascal Fua, and Eduard Trulls. Disk: Learning local features with policy gradient. Advances in Neural Information Processing Systems , 33:14254–14265, 2020.
[117] Shinji Umeyama. Least-squares estimation of transformation parameters between two point patterns. IEEE Trans. Pattern Anal. Mach. Intell. , 13(4), 1991.
[118] Benjamin Ummenhofer, Huizhong Zhou, Jonas Uhrig, Nikolaus Mayer, Eddy Ilg, Alexey Dosovitskiy, and Thomas Brox. Demon: Depth and motion network for learning monocular stereo. In Proceedings of the IEEE conference on computer vision and pattern recognition , pages 5038–5047, 2017.
[119] Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N. Gomez, Lukasz Kaiser, and Illia Polosukhin. Attention is all you need. In Proc. NeurIPS , 2017a.
[120] Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Łukasz Kaiser, and Illia Polosukhin. Attention is all you need. Advances in neural information processing systems , 30, 2017b.
[121] Fangjinhua Wang, Silvano Galliani, Christoph Vogel, Pablo Speciale, and Marc Pollefeys. Patchmatchnet: Learned multi-view patchmatch stereo. In CVPR , pages 14194–14203, 2021a.
[122] Jianyuan Wang, Yiran Zhong, Yuchao Dai, Stan Birchfield, Kaihao Zhang, Nikolai Smolyanskiy, and Hongdong Li. Deep two-view structure-from-motion revisited. In Proceedings of the IEEE/CVF conference on Computer Vision and Pattern Recognition , pages 8953–8962, 2021b.
[123] Jianyuan Wang, Christian Rupprecht, and David Novotny. Posediffusion: Solving pose estimation via diffusion-aided bundle adjustment. In Proceedings of the IEEE/CVF International Conference on Computer Vision , pages 9773–9783, 2023a.
[124] Jianyuan Wang, Christian Rupprecht, and David Novotny. PoseDiffusion: solving pose estimation via diffusion-aided bundle adjustment. In Proc. ICCV , 2023b.
[125] Jianyuan Wang, Nikita Karaev, Christian Rupprecht, and David Novotny. VGGSfM: visual geometry grounded deep structure from motion. In Proc. CVPR , 2024a.
[126] Peng Wang, Hao Tan, Sai Bi, Yinghao Xu, Fujun Luan, Kalyan Sunkavalli, Wenping Wang, Zexiang Xu, and Kai Zhang. PF-LRM: pose-free large reconstruction model for joint pose and shape prediction. arXiv.cs , abs/2311.12024, 2023c.
[127] Qianqian Wang, Yifei Zhang, Aleksander Holynski, Alexei A. Efros, and Angjoo Kanazawa. Continuous 3d perception model with persistent state, 2025.
[128] Ruicheng Wang, Sicheng Xu, Cassie Dai, Jianfeng Xiang, Yu Deng, Xin Tong, and Jiaolong Yang. MoGe: unlocking accurate monocular geometry estimation for open-domain images with optimal training supervision. arXiv , 2410.19115, 2024b.
[129] Shuzhe Wang, Vincent Leroy, Yohann Cabon, Boris Chidlovskii, and Jerome Revaud. DUSt3R: Geometric 3D vision made easy. In Proc. CVPR , 2024c.
[130] Yuesong Wang, Zhaojie Zeng, Tao Guan, Wei Yang, Zhuo Chen, Wenkai Liu, Luoyuan Xu, and Yawei Luo. Adaptive patch deformation for textureless-resilient multi-view stereo. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) , pages 1621–1630, 2023d.
[131] Xingkui Wei, Yinda Zhang, Zhuwen Li, Yanwei Fu, and Xiangyang Xue. Deepsfm: Structure from motion via deep bundle adjustment. In Computer Vision–ECCV 2020: 16th European Conference, Glasgow, UK, August 23–28, 2020, Proceedings, Part I 16 , pages 230–247. Springer, 2020.
[132] Xinyue Wei, Kai Zhang, Sai Bi, Hao Tan, Fujun Luan, Valentin Deschaintre, Kalyan Sunkavalli, Hao Su, and Zexiang Xu. MeshLRM: large reconstruction model for high-quality mesh. arXiv , 2404.12385, 2024.
[133] Yi Wei, Shaohui Liu, Yongming Rao, Wang Zhao, Jiwen Lu, and Jie Zhou. Nerfingmvs: Guided optimization of neural radiance fields for indoor multi-view stereo. In Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV) , pages 5610–5619, 2021.
[134] Changchang Wu. Towards linear-time incremental structure from motion. In 2013 International Conference on 3D Vision-3DV 2013 , pages 127–134. IEEE, 2013.
[135] Hongchi Xia, Yang Fu, Sifei Liu, and Xiaolong Wang. Rgbd objects in the wild: Scaling real-world 3d object learning from rgb-d videos, 2024.
[136] Yuxi Xiao, Qianqian Wang, Shangzhan Zhang, Nan Xue, Sida Peng, Yujun Shen, and Xiaowei Zhou. Spatialtracker: Tracking any 2d pixels in 3d space. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition , pages 20406–20417, 2024.
[137] Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M Alvarez, and Ping Luo. Segformer: Simple and efficient design for semantic segmentation with transformers. Advances in neural information processing systems , 34:12077–12090, 2021.
[138] Fei Xie, Chunyu Wang, Guangting Wang, Yue Cao, Wankou Yang, and Wenjun Zeng. Correlation-aware deep tracking. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition , pages 8751–8760, 2022.
[139] Qingshan Xu and Wenbing Tao. Learning inverse depth regression for multi-view stereo with correlation cost volume. In AAAI , 2020.
[140] Yinghao Xu, Zifan Shi, Wang Yifan, Hansheng Chen, Ceyuan Yang, Sida Peng, Yujun Shen, and Gordon Wetzstein. GRM: Large gaussian reconstruction model for efficient 3D reconstruction and generation. arXiv , 2403.14621, 2024.
[141] Jianing Yang, Alexander Sax, Kevin J Liang, Mikael Henaff, Hao Tang, Ang Cao, Joyce Chai, Franziska Meier, and Matt Feiszli. Fast3r: Towards 3d reconstruction of 1000+ images in one forward pass. arXiv preprint arXiv:2501.13928 , 2025.
[142] Lihe Yang, Bingyi Kang, Zilong Huang, Xiaogang Xu, Jiashi Feng, and Hengshuang Zhao. Depth anything: Unleashing the power of large-scale unlabeled data. In Proc. CVPR , 2024a.
[143] Lihe Yang, Bingyi Kang, Zilong Huang, Zhen Zhao, Xiaogang Xu, Jiashi Feng, and Hengshuang Zhao. Depth anything v2. arXiv:2406.09414 , 2024b.
[144] Yao Yao, Zixin Luo, Shiwei Li, Tian Fang, and Long Quan. Mvsnet: Depth inference for unstructured multi-view stereo. In ECCV , 2018a.
[145] Yao Yao, Zixin Luo, Shiwei Li, Tian Fang, and Long Quan. Mvsnet: Depth inference for unstructured multi-view stereo. In Proceedings of the European conference on computer vision (ECCV) , pages 767–783, 2018b.
[146] Yao Yao, Zixin Luo, Shiwei Li, Jingyang Zhang, Yufan Ren, Lei Zhou, Tian Fang, and Long Quan. Blendedmvs: A large-scale dataset for generalized multi-view stereo networks. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition , pages 1790–1799, 2020.
[147] Lior Yariv, Yoni Kasten, Dror Moran, Meirav Galun, Matan Atzmon, Basri Ronen, and Yaron Lipman. Multiview neural surface reconstruction by disentangling geometry and appearance. Advances in Neural Information Processing Systems , 33:2492–2502, 2020.
[148] Gokul Yenduri, Ramalingam M, Chemmalar Selvi G., Supriya Y, Gautam Srivastava, Praveen Kumar Reddy Maddikunta, Deepti Raj G, Rutvij H. Jhaveri, Prabadevi B, Weizheng Wang, Athanasios V. Vasilakos, and Thippa Reddy Gadekallu. Generative pre-trained transformer: A comprehensive review on enabling technologies, potential applications, emerging challenges, and future directions. arXiv.cs , abs/2305.10435, 2023.
[149] Kwang Moo Yi, Eduard Trulls, Vincent Lepetit, and Pascal Fua. LIFT: Learned Invariant Feature Transform. In Proc. ECCV , 2016.
[150] Shuangfei Zhai, Tatiana Likhomanenko, Etai Littwin, Dan Busbridge, Jason Ramapuram, Yizhe Zhang, Jiatao Gu, and Joshua M Susskind. Stabilizing transformer training by preventing attention entropy collapse. In International Conference on Machine Learning , pages 40770–40803. PMLR, 2023.
[151] Junyi Zhang, Charles Herrmann, Junhwa Hur, Varun Jampani, Trevor Darrell, Forrester Cole, Deqing Sun, and Ming-Hsuan Yang. MonST3R: a simple approach for estimating geometry in the presence of motion. arXiv , 2410.03825, 2024a.
[152] Jason Y Zhang, Deva Ramanan, and Shubham Tulsiani. Relpose: Predicting probabilistic relative rotation for single objects in the wild. In ECCV , pages 592–611. Springer, 2022.
[153] Jason Y Zhang, Amy Lin, Moneish Kumar, Tzu-Hsuan Yang, Deva Ramanan, and Shubham Tulsiani. Cameras as rays: Pose estimation via ray diffusion. In International Conference on Learning Representations (ICLR) , 2024b.
[154] Kai Zhang, Sai Bi, Hao Tan, Yuanbo Xiangli, Nanxuan Zhao, Kalyan Sunkavalli, and Zexiang Xu. Gs-lrm: Large reconstruction model for 3d gaussian splatting. In European Conference on Computer Vision , pages 1–19. Springer, 2024c.
[155] Kai Zhang, Sai Bi, Hao Tan, Yuanbo Xiangli, Nanxuan Zhao, Kalyan Sunkavalli, and Zexiang Xu. GS-LRM: large reconstruction model for 3D Gaussian splatting. arXiv , 2404.19702, 2024d.
[156] Shangzhan Zhang, Jianyuan Wang, Yinghao Xu, Nan Xue, Christian Rupprecht, Xiaowei Zhou, Yujun Shen, and Gordon Wetzstein. Flare: Feed-forward geometry, appearance and camera estimation from uncalibrated sparse views, 2025.
[157] Zhe Zhang, Rui Peng, Yuxi Hu, and Ronggang Wang. Geomvsnet: Learning multi-view stereo with geometry perception. In CVPR , 2023.
[158] Xiaoming Zhao, Xingming Wu, Weihai Chen, Peter CY Chen, Qingsong Xu, and Zhengguo Li. Aliked: A lighter keypoint and descriptor extraction network via deformable transformation. IEEE Transactions on Instrumentation and Measurement , 72:1–16, 2023.
[159] Yang Zheng, Adam W. Harley, Bokui Shen, Gordon Wetzstein, and Leonidas J. Guibas. Pointodyssey: A large-scale synthetic dataset for long-term point tracking. In ICCV , 2023.
[160] Tinghui Zhou, Matthew Brown, Noah Snavely, and David G Lowe. Unsupervised learning of depth and ego-motion from video. In Proceedings of the IEEE conference on computer vision and pattern recognition , pages 1851–1858, 2017.
[161] Tinghui Zhou, Richard Tucker, John Flynn, Graham Fyffe, and Noah Snavely. Stereo magnification: Learning view synthesis using multiplane images. arXiv preprint arXiv:1805.09817 , 2018.