Planning-oriented Autonomous Driving
Planning-oriented Autonomous Driving
面向规划的自动驾驶
Yihan Hu Jiazhi Yang Li Chen Keyu Li Chonghao Sima Xizhou Zhu Affiliation: SenseTime Research ∗ Equal contribution † Project lead https://github.com/OpenDriveLab/UniAD Siqi Chai Affiliation: Wuhan University Senyao Du Affiliation: Wuhan University Tianwei Lin Affiliation: Wuhan University Wenhai Wang Lewei Lu Affiliation: SenseTime Research ∗ Equal contribution † Project lead https://github.com/OpenDriveLab/UniAD Xiaosong Jia Qiang Liu Affiliation: Wuhan University Jifeng Dai Yu Qiao Hongyang Li [2mm] OpenDriveLab OpenGVLab Shanghai AI Laboratory
Abstract
摘要
Modern autonomous driving system is characterized as modular tasks in sequential order, i.e., perception, prediction, and planning. In order to perform a wide diversity of tasks and achieve advanced-level intelligence, contemporary approaches either deploy standalone models for individual tasks, or design a multi-task paradigm with separate heads. However, they might suffer from accumulative errors or deficient task coordination. Instead, we argue that a favorable framework should be devised and optimized in pursuit of the ultimate goal, i.e., planning of the self-driving car. Oriented at this, we revisit the key components within perception and prediction, and prioritize the tasks such that all these tasks contribute to planning. We introduce Unified Autonomous Driving (UniAD), a comprehensive framework up-to-date that incorporates full-stack driving tasks in one network. It is exquisitely devised to leverage advantages of each module, and provide complementary feature abstractions for agent interaction from a global perspective. Tasks are communicated with unified query interfaces to facilitate each other toward planning. We instantiate UniAD on the challenging nuScenes benchmark. With extensive ablations, the effectiveness of using such a philosophy is proven by substantially outperforming previous state-of-the-arts in all aspects. Code and models are public.
现代自动驾驶系统常按感知、预测、规划等模块顺序组织。为覆盖多样任务并迈向更高智能,现有做法要么为各任务部署独立模型,要么用多任务范式配多头。它们容易累积误差,或任务协同不足。我们认为,良好框架应以最终目标——自车规划——来设计与优化。据此,我们重审感知与预测中的关键组件,并按「服务规划」重新排定任务优先级。我们提出 Unified Autonomous Driving(UniAD):迄今将全栈驾驶任务纳入同一网络的综合框架。它精心利用各模块优势,从全局视角为智能体交互提供互补特征抽象;各任务经统一 query 接口互通,共同指向规划。我们在具有挑战的 nuScenes 基准上实例化 UniAD。大量消融表明,这一理念在各方面显著超过此前最优方法。代码与模型已公开。
1 Introduction
1 引言
With the successful development of deep learning, autonomous driving algorithms are assembled with a series of tasks[^1], including detection, tracking, mapping in perception; and motion and occupancy forecast in prediction. As depicted in Fig. 1(a), most industry solutions deploy standalone models for each task independently [68, 71], as long as the resource bandwidth of the onboard chip allows. Although such a design simplifies the R&D difficulty across teams, it bares the risk of information loss across modules, error accumulation and feature misalignment due to the isolation of optimization targets [66, 57, 82].
随着深度学习成功发展,自动驾驶算法被组装成一系列任务[^1],包括感知中的检测、跟踪、建图,以及预测中的运动与占据预报。如图 1(a) 所示,多数工业方案在车载芯片带宽允许时,为各任务独立部署模型 [68, 71]。该设计虽简化跨团队研发难度,却因优化目标隔离而带来模块间信息损失、误差累积与特征错位的风险 [66, 57, 82]。
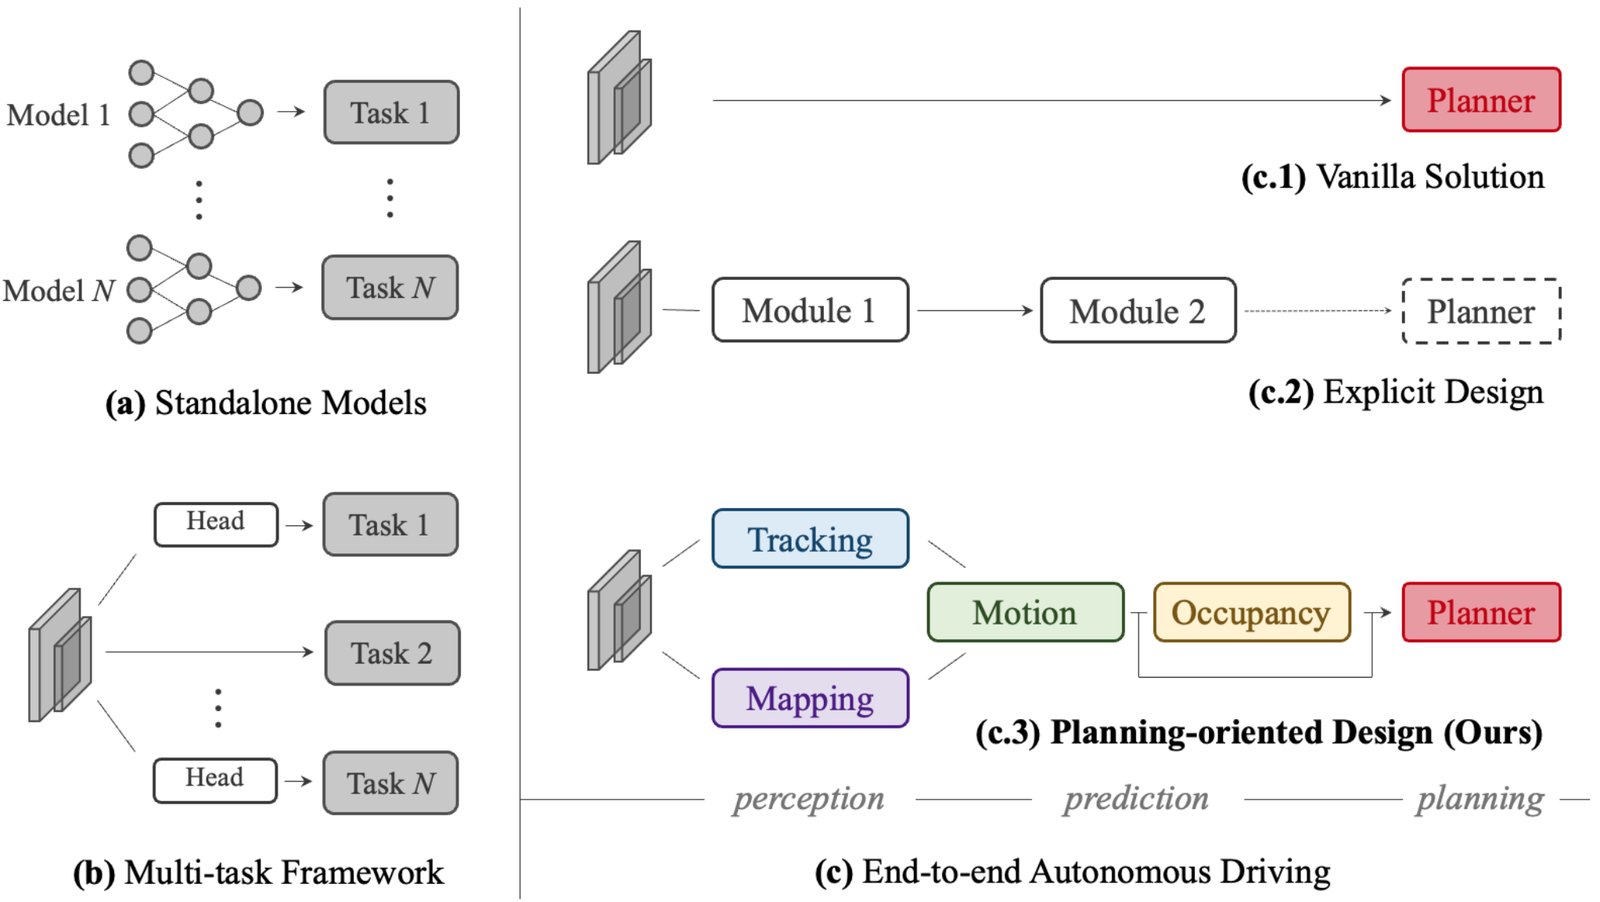
Figure 1: Comparison on the various designs of autonomous driving framework. (a) Most industrial solutions deploy separate models for different tasks. (b) The multi-task learning scheme shares a backbone with divided task heads. (c) The end-to-end paradigm unites modules in perception and prediction. Previous attempts either adopt a direct optimization on planning in (c.1) or devise the system with partial components in (c.2). Instead, we argue in (c.3) that a desirable system should be planning-oriented as well as properly organize preceding tasks to facilitate planning.
图 1:自动驾驶框架多种设计的比较。 (a) 多数工业方案为不同任务部署独立模型。(b) 多任务学习共享骨干、分任务头。(c) 端到端范式统一感知与预测模块。先前尝试或如 (c.1) 直接优化规划,或如 (c.2) 仅纳入部分组件。我们在 (c.3) 主张:理想系统应以规划为导向,并妥善组织上游任务以服务规划。
A more elegant design is to incorporate a wide span of tasks into a multi-task learning (MTL) paradigm, by plugging several task-specific heads into a shared feature extractor as shown in Fig. 1(b). This is a popular practice in many domains, including general vision [92, 108, 79], autonomous driving[^2] [105, 60, 101, 15], such as Transfuser [20], BEVerse [105], and industrialized products, e.g., Mobileye [68], Tesla [87], Nvidia [71], etc. In MTL, the co-training strategy across tasks could leverage feature abstraction; it could effortlessly extend to additional tasks, and save computation cost for onboard chips. However, such a scheme may cause undesirable “negative transfer” [23, 64].
更优雅的设计是把广泛任务纳入多任务学习(MTL)范式:如图 1(b),在共享特征提取器上插入若干任务头。这在通用视觉 [92, 108, 79]、自动驾驶[^2] [105, 60, 101, 15](如 Transfuser [20]、BEVerse [105])以及 Mobileye [68]、Tesla [87]、Nvidia [71] 等工业产品中都很常见。MTL 中跨任务共训可利用特征抽象,易扩展新任务,并节省车载算力。但该方案也可能导致不良的「负迁移」 [23, 64]。
By contrast, the emergence of end-to-end autonomous driving [19, 97, 15, 11, 38] unites all nodes from perception, prediction and planning as a whole. The choice and priority of preceding tasks should be determined in favor of planning. The system should be planning-oriented, exquisitely designed with certain components involved, such that there are few accumulative error as in the standalone option or negative transfer as in the MTL scheme. Table 1 describes the task taxonomy of different framework designs.
相比之下,端到端自动驾驶 [19, 97, 15, 11, 38] 把感知、预测与规划各节点连成整体。上游任务的取舍与优先级应由规划决定。系统应以规划为导向,精心纳入特定组件,从而减少独立方案中的累积误差与 MTL 中的负迁移。表 1 描述了不同框架设计的任务分类。
Following the end-to-end paradigm, one “tabula-rasa” practice is to directly predict the planned trajectory, without any explicit supervision of perception and prediction as shown in Fig. 1(c.1). Pioneering works [14, 21, 22, 16, 106, 78, 97, 95] verified this vanilla design in the closed-loop simulation [26]. While such a direction deserves further exploration, it is inadequate in safety guarantee and interpretability, especially for highly dynamic urban scenarios. In this paper, we lean toward another perspective and ask the following question: Toward a reliable and planning-oriented autonomous driving system, how to design the pipeline in favor of planning? which preceding tasks are requisite?
沿端到端范式,一种「白板」做法是直接预测规划轨迹,不对感知与预测做显式监督,如图 1(c.1)。开创性工作 [14, 21, 22, 16, 106, 78, 97, 95] 在闭环仿真 [26] 中验证了这一朴素设计。该方向值得继续探索,但对高度动态城市场景,安全保证与可解释性仍不足。本文转向另一视角,并提出:面向可靠且以规划为导向的自动驾驶系统,应如何设计有利于规划的管线?哪些上游任务是必需的?
| Design | Approach | Perception | Prediction | Plan | |||
|---|---|---|---|---|---|---|---|
| Det. | Track | Map | Motion | Occ. | |||
| (b) | NMP [101] | ✓ | ✓ | ✓ | |||
| NEAT [19] | ✓ | ✓ | |||||
| BEVerse [105] | ✓ | ✓ | ✓ | ||||
| (c.1) | [14, 16, 78, 97] | ✓ | |||||
| (c.2) | PnPNet [57] | ✓ | ✓ | ✓ | |||
| ViP3D [30] | ✓ | ✓ | ✓ | ||||
| P3 [82] | ✓ | ✓ | |||||
| MP3 [11] | ✓ | ✓ | ✓ | ||||
| ST-P3 [38] | ✓ | ✓ | ✓ | ||||
| LAV [15] | ✓ | ✓ | ✓ | ✓ | |||
| (c.3) | UniAD (ours) | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ |
Table 1: Tasks comparison and taxonomy. “Design” column is classified as in Fig. 1. “Det.” denotes 3D object detection, “Map” stands for online mapping, and “Occ.” is occupancy map prediction. †: these works are not proposed directly for planning, yet they still share the spirit of joint perception and prediction. UniAD conducts five essential driving tasks to facilitate planning.
| 设计 | 方法 | 感知 | 预测 | 规划 | |||
|---|---|---|---|---|---|---|---|
| 检测 | 跟踪 | 地图 | 运动 | 占据 | |||
| (b) | NMP [101] | ✓ | ✓ | ✓ | |||
| NEAT [19] | ✓ | ✓ | |||||
| BEVerse [105] | ✓ | ✓ | ✓ | ||||
| (c.1) | [14, 16, 78, 97] | ✓ | |||||
| (c.2) | PnPNet [57] | ✓ | ✓ | ✓ | |||
| ViP3D [30] | ✓ | ✓ | ✓ | ||||
| P3 [82] | ✓ | ✓ | |||||
| MP3 [11] | ✓ | ✓ | ✓ | ||||
| ST-P3 [38] | ✓ | ✓ | ✓ | ||||
| LAV [15] | ✓ | ✓ | ✓ | ✓ | |||
| (c.3) | UniAD(本文) | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ |
表 1:任务比较与分类。「设计」列按图 1 分类。「Det.」表示三维目标检测,「Map」表示在线建图,「Occ.」表示占据图预测。†:这些工作并非直接面向规划提出,但仍共享联合感知与预测的思路。UniAD 用五项关键驾驶任务服务规划。
An intuitive resolution would be to perceive surrounding objects, predict future behaviors and plan a safe maneuver explicitly, as illustrated in Fig. 1(c.2). Contemporary approaches [57, 30, 82, 11, 38] provide good insights and achieve impressive performance. However, we argue that the devil lies in the details; previous works more or less fail to consider certain components (see block (c.2) in Table 1), being reminiscent of the planning-oriented spirit. We elaborate on the detailed definition and terminology, the necessity of these modules in the Supplementary.
直观做法是显式感知周围物体、预测未来行为并规划安全动作,如图 1(c.2)。当代方法 [57, 30, 82, 11, 38] 很有启发且表现亮眼。但我们认为细节决定成败;先前工作或多或少遗漏某些组件(见表 1 中 (c.2) 块),未能充分体现规划导向。详细定义、术语与这些模块的必要性见补充材料。
To this end, we introduce UniAD, a Unified Autonomous Driving algorithm framework to leverage five essential tasks toward a safe and robust system as depicted in Fig. 1(c.3) and Table 1(c.3). UniAD is designed in a planning-oriented spirit. We argue that this is not a simple stack of tasks with mere engineering effort. A key component is the query-based design to connect all nodes. Compared to the classic bounding box representation, queries benefit from a larger receptive field to soften the compounding error from upstream predictions. Moreover, queries are flexible to model and encode a variety of interactions, e.g., relations among multiple agents. To the best of our knowledge, UniAD is the first work to comprehensively investigate the joint cooperation of such a variety of tasks including perception, prediction and planning in the field of autonomous driving.
为此,我们提出 UniAD:统一自动驾驶算法框架,纳入五项关键任务以迈向安全稳健系统,见图 1(c.3) 与表 1(c.3)。UniAD 以规划为导向设计。我们认为这并非简单堆叠任务的工程拼凑。关键是用基于 query 的设计连接所有节点。相对经典边界框表示,query 感受野更大,可软化上游预测的复合误差;query 也灵活建模多种交互,如多智能体关系。据我们所知,UniAD 是自动驾驶领域首次全面研究感知、预测与规划如此多任务联合协同的工作。
The contributions are summarized as follows. (a) we embrace a new outlook of autonomous driving framework following a planning-oriented philosophy, and demonstrate the necessity of effective task coordination, rather than standalone design or simple multi-task learning. (b) we present UniAD, a comprehensive end-to-end system that leverages a wide span of tasks. The key component to hit the ground running is the query design as interfaces connecting all nodes. As such, UniAD enjoys flexible intermediate representations and exchanging multi-task knowledge toward planning. (c) we instantiate UniAD on the challenging benchmark for realistic scenarios. Through extensive ablations, we verify the superiority of our method over previous state-of-the-arts in all aspects.
贡献总结如下。(a) 我们以规划导向理念重新审视自动驾驶框架,并论证有效任务协同的必要性,而非独立设计或简单多任务学习。(b) 我们提出 UniAD,覆盖广泛任务的端到端综合系统。落地关键是用 query 作为连接各节点的接口,使 UniAD 享有灵活中间表示,并交换多任务知识以服务规划。(c) 我们在面向真实场景的挑战性基准上实例化 UniAD。经大量消融,验证方法在各方面优于此前最优。
We hope this work could shed some light on the target-driven design for the autonomous driving system, providing a starting point for coordinating various driving tasks.
希望本工作能为自动驾驶系统的目标驱动设计提供一些启发,并为协调多样驾驶任务提供一个起点。
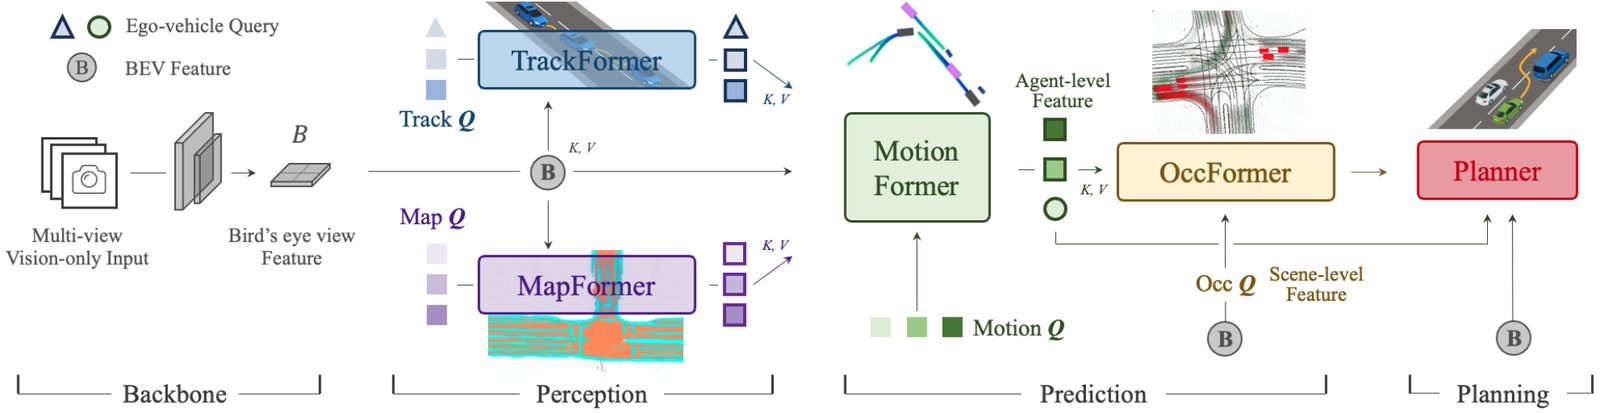
Figure 2: Pipeline of Unified Autonomous Driving (UniAD). It is exquisitely devised following planning-oriented philosophy. Instead of a simple stack of tasks, we investigate the effect of each module in perception and prediction, leveraging the benefits of joint optimization from preceding nodes to final planning in the driving scene. All perception and prediction modules are designed in a transformer decoder structure, with task queries as interfaces connecting each node. A simple attention-based planner is in the end to predict future waypoints of the ego-vehicle considering the knowledge extracted from preceding nodes. The map over occupancy is for visual purpose only.
图 2:Unified Autonomous Driving(UniAD)管线。按规划导向理念精心设计。我们并非简单堆叠任务,而是考察感知与预测中各模块的作用,利用从上游节点到最终规划的联合优化收益。所有感知与预测模块采用 Transformer 解码器结构,以任务 query 为接口连接各节点。末端是简单的基于注意力的规划器,结合上游提取的知识预测自车未来航点。占据上叠加的地图仅供可视化。
2 Methodology
2 方法
Overview.
As illustrated in Fig. 2, UniAD comprises four transformer decoder-based perception and prediction modules and one planner in the end. Queries play the role of connecting the pipeline to model different interactions of entities in the driving scenario. Specifically, a sequence of multi-camera images is fed into the feature extractor, and the resulting perspective-view features are transformed into a unified bird’s-eye-view (BEV) feature by an off-the-shelf BEV encoder in BEVFormer [55]. Note that UniAD is not confined to a specific BEV encoder, and one can utilize other alternatives to extract richer BEV representations with long-term temporal fusion [31, 74] or multi-modality fusion [64, 58]. In TrackFormer, the learnable embeddings that we refer to as track queries inquire about the agents’ information from to detect and track agents. MapFormer takes map queries as semantic abstractions of road elements (e.g., lanes and dividers) and performs panoptic segmentation of the map. With the above queries representing agents and maps, MotionFormer captures interactions among agents and maps and forecasts per-agent future trajectories. Since the action of each agent can significantly impact others in the scene, this module makes joint predictions for all agents considered. Meanwhile, we devise an ego-vehicle query to explicitly model the ego-vehicle and enable it to interact with other agents in such a scene-centric paradigm. OccFormer employs the BEV feature as queries, equipped with agent-wise knowledge as keys and values, and predicts multi-step future occupancy with agent identity preserved. Finally, Planner utilizes the expressive ego-vehicle query from MotionFormer to predict the planning result, and keep itself away from occupied regions predicted by OccFormer to avoid collisions.
概览。
如图 2,UniAD 含四个基于 Transformer 解码器的感知与预测模块,末端接一个规划器。Query 在管线中连接各节点,建模驾驶场景中不同实体的交互。具体地,多相机图像序列送入特征提取器,所得透视图特征经 BEVFormer [55] 中现成的 BEV 编码器变换为统一鸟瞰(BEV)特征 。注意 UniAD 不绑定特定 BEV 编码器,也可选用其他方案以长期时序融合 [31, 74] 或多模态融合 [64, 58] 提取更丰富的 BEV 表示。在 TrackFormer 中,我们称为 track query 的可学习嵌入从 查询智能体信息以检测与跟踪。MapFormer 以 map query 作为车道、隔离带等道路元素的语义抽象,做地图全景分割。有了表示智能体与地图的 query,MotionFormer 捕获智能体—地图交互并预报每个智能体的未来轨迹。因每个智能体的动作会显著影响场景中其他智能体,该模块对所考虑的全部智能体做联合预测。同时我们设计自车 query,在场景中心范式中显式建模自车并使其与其他智能体交互。OccFormer 以 BEV 特征 为 query,以智能体知识为 key/value,在保留智能体身份的前提下预测多步未来占据。最后,Planner 利用 MotionFormer 中表达力强的自车 query 预测规划结果,并远离 OccFormer 预测的占据区域以避免碰撞。
2.1 Perception: Tracking and Mapping
2.1 感知:跟踪与建图
TrackFormer.
It jointly performs detection and multi-object tracking (MOT) without non-differentiable post-processing. Inspired by [100, 104], we take a similar query design. Besides the conventional detection queries utilized in object detection [8, 109], additional track queries are introduced to track agents across frames. Specifically, at each time step, initialized detection queries are responsible for detecting newborn agents that are perceived for the first time, while track queries keep modeling those agents detected in previous frames. Both detection queries and track queries capture the agent abstractions by attending to BEV feature . As the scene continuously evolves, track queries at the current frame interact with previously recorded ones in a self-attention module to aggregate temporal information, until the corresponding agents disappear completely (untracked in a certain time period). Similar to [8], TrackFormer contains layers and the final output state provides knowledge of valid agents for downstream prediction tasks. Besides queries encoding other agents surrounding the ego-vehicle, we introduce one particular ego-vehicle query in the query set to explicitly model the self-driving vehicle itself, which is further used in planning.
TrackFormer。
它在无不可微后处理的情况下联合做检测与多目标跟踪(MOT)。受 [100, 104] 启发,我们采用类似的 query 设计。除目标检测中常用的 detection query [8, 109] 外,引入额外的 track query 跨帧跟踪智能体。具体地,每一步中,初始化的 detection query 负责检测首次感知到的新生智能体,track query 则持续建模先前帧已检测到的智能体。两类 query 都通过关注 BEV 特征 捕获智能体抽象。场景持续演化时,当前帧 track query 在自注意力模块中与先前记录的 query 交互以聚合时序信息,直到对应智能体完全消失(在一定时段内未再被跟踪)。与 [8] 类似,TrackFormer 含 层,最终输出状态 为下游预测任务提供 个有效智能体的知识。除编码自车周围其他智能体的 query 外,我们在 query 集合中引入一个特殊的自车 query,显式建模自驾车辆本身,供后续规划使用。
MapFormer.
We design it based on a 2D panoptic segmentation method Panoptic SegFormer [56]. We sparsely represent road elements as map queries to help downstream motion forecasting, with location and structure knowledge encoded. For driving scenarios, we set lanes, dividers and crossings as things, and the drivable area as stuff [50]. MapFormer also has stacked layers whose output results of each layer are all supervised, while only the updated queries in the last layer are forwarded to MotionFormer for agent-map interaction.
MapFormer。
我们基于二维全景分割方法 Panoptic SegFormer [56] 设计。道路元素被稀疏表示为 map query,编码位置与结构知识,以辅助下游运动预报。对驾驶场景,我们将车道、隔离带与人行横道设为 things,可行驶区域设为 stuff [50]。MapFormer 同样有 层堆叠,每层输出均受监督,但仅最后一层更新后的 query 送入 MotionFormer 做智能体—地图交互。
2.2 Prediction: Motion Forecasting
2.2 预测:运动预报
Recent studies have proven the effectiveness of transformer structure on the motion task [63, 99, 43, 44, 69, 84, 70], inspired by which we propose MotionFormer in the end-to-end setting. With highly abstract queries for dynamic agents and static map from TrackFormer and MapFormer respectively, MotionFormer predicts all agents’ multimodal future movements, i.e., top-k possible trajectories, in a scene-centric manner. This paradigm produces multi-agent trajectories in the frame with a single forward pass, which greatly saves the computational cost of aligning the whole scene to each agent’s coordinate [49]. Meanwhile, we pass the ego-vehicle query from TrackFormer through MotionFormer to engage ego-vehicle to interact with other agents, considering the future dynamics. Formally, the output motion is formulated as , where indexes the agent, indexes the modality of trajectories and is the length of prediction horizon.
近期研究已证明 Transformer 结构在运动任务上的有效性 [63, 99, 43, 44, 69, 84, 70],受此启发我们在端到端设定中提出 MotionFormer。借助 TrackFormer 与 MapFormer 分别给出的动态智能体高度抽象 query 与静态地图 query ,MotionFormer 以场景中心方式预测所有智能体的多模态未来运动,即 top-k 条可能轨迹。该范式在单一坐标系下一遍前向即可产出多智能体轨迹,大幅节省把整场景对齐到每个智能体坐标的计算 [49]。同时,我们把 TrackFormer 的自车 query 传入 MotionFormer,使自车参与与其他智能体的交互并考虑未来动态。形式上,输出运动写为 ,其中 索引智能体, 索引轨迹模态, 为预测时域长度。
MotionFormer.
It is composed of layers, and each layer captures three types of interactions: agent-agent, agent-map and agent-goal point. For each motion query (defined later, and we omit subscripts , in the following context for simplicity), its interactions between other agents or map elements could be formulated as:
MotionFormer。
它由 层组成,每层捕获三类交互:智能体—智能体、智能体—地图与智能体—目标点。对每个运动 query (稍后定义;下文为简洁省略下标 、),它与其他智能体 或地图元素 的交互可写为:
where MHCA, MHSA denote multi-head cross-attention and multi-head self-attention [91] respectively. As it is also important to focus on the intended position, i.e., goal point, to refine the predicted trajectory, we devise an agent-goal point attention via deformable attention [109] as follows:
其中 MHCA、MHSA 分别表示多头交叉注意力与多头自注意力 [91]。关注意图位置(即目标点)以 refinement 预测轨迹同样重要,我们用可变形注意力 [109] 设计智能体—目标点注意力:
where is the endpoint of the predicted trajectory of previous layer. , a deformable attention module, takes in the query , reference point and spatial feature . It performs sparse attention on the spatial feature around the reference point. Through this, the predicted trajectory is further refined as aware of the endpoint surroundings. All three interactions are modeled in parallel, where the generated , and are concatenated and passed to a multi-layer perceptron (MLP), resulting query context . Then, is sent to the successive layer for refinement or decoded as prediction results at the last layer.
其中 为上一层预测轨迹的终点。 为可变形注意力模块,输入 query 、参考点 与空间特征 ,在参考点附近对空间特征做稀疏注意力。由此,预测轨迹在感知终点周围环境后进一步 refinement。三类交互并行建模,生成的 、 与 拼接后经多层感知机(MLP),得到 query 上下文 。随后 送入下一层 refinement,或在最后一层解码为预测结果。
Motion queries.
The input queries for each layer of MotionFormer, termed motion queries, comprise two components: the query context produced by the preceding layer as described before, and the query position . Specifically, integrates the positional knowledge in four-folds as in Eq. 3: (1) the position of scene-level anchors ; (2) the position of agent-level anchors ; (3) current location of the agent and (4) the predicted goal point.
运动 query。
MotionFormer 每层的输入 query 称为运动 query,由两部分组成:如前所述由上一层产生的 query 上下文 ,以及 query 位置 。具体地, 按式 3 从四方面整合位置知识:(1) 场景级锚点位置 ;(2) 智能体级锚点位置 ;(3) 智能体 当前位置;(4) 预测目标点。
Here the sinusoidal position encoding followed by an MLP is utilized to encode the positional points and is set as at the first layer (subscripts are also omitted). The scene-level anchor represents prior movement statistics in a global view, while the agent-level anchor captures the possible intention in the local coordinate. They are both clustered by k-means algorithm on the endpoints of ground-truth trajectories, to narrow down the uncertainty of prediction. Contrary to the prior knowledge, the start point provides customized positional embedding for each agent, and the predicted endpoint serves as a dynamic anchor optimized layer-by-layer in a coarse-to-fine fashion.
这里用正弦位置编码 后接 MLP 编码位置点;第一层将 设为 (同样省略下标 )。场景级锚点表示全局视角下的先验运动统计,智能体级锚点捕获局部坐标中的可能意图。二者均对真实轨迹终点做 k-means 聚类得到,以缩小预测不确定性。与先验知识相对,起点为每个智能体提供定制位置嵌入,预测终点则作为动态锚点,在层间由粗到细优化。
Non-linear Optimization.
Different from conventional motion forecasting works which have direct access to ground truth perceptual results, i.e., agents’ location and corresponding tracks, we consider the prediction uncertainty from the prior module in our end-to-end paradigm. Brutally regressing the ground-truth waypoints from an imperfect detection position or heading angle may lead to unrealistic trajectory predictions with large curvature and acceleration. To tackle this, we adopt a non-linear smoother [7] to adjust the target trajectories and make them physically feasible given an imprecise starting point predicted by the upstream module. The process is:
非线性优化。
与可直接使用真实感知结果(智能体位置与对应轨迹)的常规运动预报不同,端到端范式需考虑上游模块的预测不确定性。从有偏差的检测位置或航向角硬回归真实航点,可能导致曲率与加速度过大的不现实轨迹。为此,我们采用非线性平滑器 [7],在上游模块给出不精确起点时调整目标轨迹使其物理可行。过程为:
where and denote the ground-truth and smoothed trajectory, is generated by multiple-shooting [3], and the cost function is as follows:
其中 与 分别表示真实与平滑后轨迹, 由 multiple-shooting [3] 生成,代价函数如下:
where and are hyperparameters, the kinematic function set has five terms including jerk, curvature, curvature rate, acceleration and lateral acceleration. The cost function regularizes the target trajectory to obey kinematic constraints. This target trajectory optimization is only conducted in training and does not affect inference.
其中 与 为超参数,运动学函数集 含 jerk、曲率、曲率变化率、加速度与横向加速度五项。代价函数把目标轨迹正则到服从运动学约束。该目标轨迹优化仅在训练时进行,不影响推理。
2.3 Prediction: Occupancy Prediction
2.3 预测:占据预测
Occupancy grid map is a discretized BEV representation where each cell holds a belief indicating whether it is occupied, and the occupancy prediction task is to discover how the grid map changes in the future. Previous approaches utilize RNN structure for temporally expanding future predictions from observed BEV features [35, 38, 105]. However, they rely on highly hand-crafted clustering post-processing to generate per-agent occupancy maps, as they are mostly agent-agnostic by compressing BEV features as a whole into RNN hidden states. Due to the deficient usage of agent-wise knowledge, it is challenging for them to predict the behaviors of all agents globally, which is essential to understand how the scene evolves. To address this, we present OccFormer to incorporate both scene-level and agent-level semantics in two aspects: (1) a dense scene feature acquires agent-level features via an exquisitely designed attention module when unrolling to future horizons; (2) we produce instance-wise occupancy easily by a matrix multiplication between agent-level features and dense scene features without heavy post-processing.
占据栅格图是离散 BEV 表示,每个格子保存是否被占据的信念;占据预测任务是发现栅格图在未来如何变化。先前方法用 RNN 从观测 BEV 特征时序展开未来预测 [35, 38, 105]。但它们多把 BEV 特征整体压入 RNN 隐状态,依赖高度手工的聚类后处理生成逐智能体占据图,对智能体知识利用不足,难以全局预测所有智能体行为——而这正是理解场景演化所必需的。为此,我们提出 OccFormer,从两方面融合场景级与智能体级语义:(1) 稠密场景特征在向未来时域展开时,经精心设计的注意力模块获取智能体级特征;(2) 用智能体级特征与稠密场景特征的矩阵乘法,无需繁重后处理即可得到实例级占据。
OccFormer is composed of sequential blocks where indicates the prediction horizon. Note that is typically smaller than in the motion task, due to the high computation cost of densely represented occupancy. Each block takes as input the rich agent features and the state (dense feature) from the previous layer, and generates for timestep considering both instance- and scene-level information. To get agent feature with dynamics and spatial priors, we max-pool motion queries from MotionFormer in the modality dimension denoted as , with as the feature dimension. Then we fuse it with the upstream track query and current position embedding via a temporal-specific MLP:
OccFormer 由 个顺序块组成, 表示预测时域。注意因稠密占据计算代价高, 通常小于运动任务中的 。每个块输入丰富智能体特征 与上一层状态(稠密特征),结合实例级与场景级信息生成时刻 的 。为得到带动态与空间先验的智能体特征 ,我们在模态维上对 MotionFormer 的运动 query 做 max-pool,记为 , 为特征维。再经时步专用 MLP 与上游 track query 、当前位置嵌入 融合:
where indicates concatenation. For the scene-level knowledge, the BEV feature is downscaled to resolution for training efficiency to serve as the first block input . To further conserve training memory, each block follows a downsample-upsample manner with an attention module in between to conduct pixel-agent interaction at downscaled feature, denoted as .
其中 表示拼接。对场景级知识,BEV 特征 为训练效率下采样到 分辨率,作为第一块输入 。为进一步节省训练显存,每个块采用下采样—上采样结构,中间在 下采样特征 上用注意力做像素—智能体交互。
Pixel-agent interaction
is designed to unify the scene- and agent-level understanding when predicting future occupancy. We take the dense feature as queries, instance-level features as keys and values to update the dense feature over time. Detailedly, is passed through a self-attention layer to model responses between distant grids, then a cross-attention layer models interactions between agent features and per-grid features. Moreover, to align the pixel-agent correspondence, we constrain the cross-attention by an attention mask, which restricts each pixel to only look at the agent occupying it at timestep , inspired by [17]. The update process of the dense feature is formulated as:
像素—智能体交互
旨在统一场景级与智能体级理解以预测未来占据。我们以稠密特征 为 query,以实例级特征为 key 与 value,随时间更新稠密特征。具体地, 先经自注意力建模远距网格响应,再经交叉注意力建模智能体特征 与逐网格特征的交互。此外,为对齐像素与智能体,注意力掩码限制每个像素在时刻 只关注占据它的智能体,灵感来自 [17]。稠密特征更新写为:
The attention mask is semantically similar to occupancy, and is generated by multiplying an additional agent-level feature and the dense feature , where we name the agent-level feature here as mask feature . After the interaction process in Eq. 7, is upsampled to size of . We further add with block input as a residual connection, and the resulting feature is passed to the next block.
注意力掩码 在语义上类似占据,由额外智能体级特征与稠密特征 相乘得到;此处将该智能体级特征称为掩码特征 。经式 7 交互后, 上采样到 的 尺寸。再将 与块输入 残差相加,得到的 传入下一块。
Instance-level occupancy.
It represents the occupancy with each agent’s identity preserved. It could be simply drawn via matrix multiplication, as in recent query-based segmentation works [18, 52]. Formally, in order to get an occupancy prediction of original size of BEV feature , the scene-level features are upsampled to by a convolutional decoder, where is the channel dimension. For the agent-level feature, we further update the coarse mask feature to the occupancy feature by another MLP. We empirically find that generating from mask feature instead of original agent feature leads to superior performance. The final instance-level occupancy of timestep is:
实例级占据。
它在保留每个智能体身份的前提下表示占据。可像近期基于 query 的分割工作 [18, 52] 那样,通过矩阵乘法简便得到。形式上,为得到与 BEV 特征 同尺寸 的占据预测,场景级特征 经卷积解码器上采样为 , 为通道维。对智能体级,我们发现用掩码特征 而非原始智能体特征 表现更优。时刻 的最终实例级占据为:
2.4 Planning
2.4 规划
Planning without high-definition (HD) maps or predefined routes usually requires a high-level command to indicate the direction to go [11, 38]. Following this, we convert the raw navigation signals (i.e., turn left, turn right and keep forward) into three learnable embeddings, named command embeddings. As the ego-vehicle query from MotionFormer already expresses its multimodal intentions, we equip it with command embeddings to form a “plan query”. We attend plan query to BEV features to make it aware of surroundings, and then decode it to future waypoints .
在无高精(HD)地图或预定路线时,规划通常需要高层指令指示行驶方向 [11, 38]。据此,我们把原始导航信号(左转、右转与直行)转为三个可学习嵌入,称为指令嵌入。由于 MotionFormer 的自车 query 已表达其多模态意图,我们为其配备指令嵌入以形成「规划 query」。将规划 query 关注到 BEV 特征 以感知周围,再解码为未来航点 。
To further avoid collisions, we optimize based on Newton’s method in inference only by the following:
为进一步避免碰撞,我们仅在推理时用牛顿法按如下方式优化 :
where is the original planning prediction, denotes the optimized planning, which is selected from multiple-shooting [3] trajectories as to minimize cost function . is a classical binary occupancy map merged from the instance-wise occupancy prediction from OccFormer. The cost function is calculated by:
其中 为原始规划预测, 表示优化后的规划,从 multiple-shooting [3] 轨迹 中选取以最小化代价函数 。 是由 OccFormer 实例级占据预测合并得到的经典二值占据图。代价函数 计算为:
Here , , and are hyperparameters, and indexes a timestep of future horizons. The cost pulls the trajectory toward the original predicted one, while the collision term pushes it away from occupied grids, considering surrounding positions confined to .
这里 、 与 为超参数, 索引未来时域中的时刻。 项把轨迹拉向原始预测,碰撞项 则将其推离占据格子,考虑限制在 内的周围位置。
| ID | Modules | Tracking | Mapping | Motion Forecasting | Occupancy Prediction | Planning | |||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Track | Map | Motion | Occ. | Plan | AMOTA | AMOTP | IDS | IoU-lane | IoU-road | minADE | minFDE | MR | IoU-n. | IoU-f. | VPQ-n. | VPQ-f. | avg.L2 | avg.Col. | |
| 0∗ | ✓ | ✓ | ✓ | ✓ | ✓ | 0.356 | 1.328 | 893 | 0.302 | 0.675 | 0.858 | 1.270 | 0.186 | 55.9 | 34.6 | 47.8 | 26.4 | 1.154 | 0.941 |
| 1 | ✓ | 0.348 | 1.333 | 791 | - | - | - | - | - | - | - | - | - | - | - | ||||
| 2 | ✓ | - | - | - | 0.305 | 0.674 | - | - | - | - | - | - | - | - | - | ||||
| 3 | ✓ | ✓ | 0.355 | 1.336 | 785 | 0.301 | 0.671 | - | - | - | - | - | - | - | - | - | |||
| 4 | ✓ | - | - | - | - | - | 0.815 | 1.224 | 0.182 | - | - | - | - | - | - | ||||
| 5 | ✓ | ✓ | 0.360 | 1.350 | 919 | - | - | 0.751 | 1.109 | 0.162 | - | - | - | - | - | - | |||
| 6 | ✓ | ✓ | ✓ | 0.354 | 1.339 | 820 | 0.303 | 0.672 | 0.736(-9.7%) | 1.066(-12.9%) | 0.158 | - | - | - | - | - | - | ||
| 7 | ✓ | - | - | - | - | - | - | - | - | 60.5 | 37.0 | 52.4 | 29.8 | - | - | ||||
| 8 | ✓ | ✓ | 0.360 | 1.322 | 809 | - | - | - | - | - | 62.1 | 38.4 | 52.2 | 32.1 | - | - | |||
| 9 | ✓ | ✓ | ✓ | ✓ | 0.359 | 1.359 | 1057 | 0.304 | 0.675 | 0.710(-3.5%) | 1.005(-5.8%) | 0.146 | 62.3 | 39.4 | 53.1 | 32.2 | - | - | |
| 10 | ✓ | - | - | - | - | - | - | - | - | - | - | - | 1.131 | 0.773 | |||||
| 11 | ✓ | ✓ | ✓ | ✓ | 0.366 | 1.337 | 889 | 0.303 | 0.672 | 0.741 | 1.077 | 0.157 | - | - | - | - | 1.014 | 0.717 | |
| 12 | ✓ | ✓ | ✓ | ✓ | ✓ | 0.358 | 1.334 | 641 | 0.302 | 0.672 | 0.728 | 1.054 | 0.154 | 62.3 | 39.5 | 52.8 | 32.3 | 1.004 | 0.430 |
Table 2: Detailed ablations on the effectiveness of each task. We can conclude that two perception sub-tasks greatly help motion forecasting, and prediction performance also benefits from unifying the two prediction modules. With all prior representations, our goal-planning boosts significantly to ensure safety. UniAD outperforms naive MTL solution by a large margin for prediction and planning tasks, and it also owns the superiority that no substantial perceptual performance drop occurs. Only main metrics are shown for brevity. “avg.L2” and “avg.Col” are the average values across the planning horizon. : ID-0 is the MTL scheme with separate heads for each task.
| ID | 模块 | 跟踪 | 建图 | 运动预报 | 占据预测 | 规划 | |||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Track | Map | Motion | Occ. | Plan | AMOTA | AMOTP | IDS | IoU-lane | IoU-road | minADE | minFDE | MR | IoU-n. | IoU-f. | VPQ-n. | VPQ-f. | avg.L2 | avg.Col. | |
| 0∗ | ✓ | ✓ | ✓ | ✓ | ✓ | 0.356 | 1.328 | 893 | 0.302 | 0.675 | 0.858 | 1.270 | 0.186 | 55.9 | 34.6 | 47.8 | 26.4 | 1.154 | 0.941 |
| 1 | ✓ | 0.348 | 1.333 | 791 | - | - | - | - | - | - | - | - | - | - | - | ||||
| 2 | ✓ | - | - | - | 0.305 | 0.674 | - | - | - | - | - | - | - | - | - | ||||
| 3 | ✓ | ✓ | 0.355 | 1.336 | 785 | 0.301 | 0.671 | - | - | - | - | - | - | - | - | - | |||
| 4 | ✓ | - | - | - | - | - | 0.815 | 1.224 | 0.182 | - | - | - | - | - | - | ||||
| 5 | ✓ | ✓ | 0.360 | 1.350 | 919 | - | - | 0.751 | 1.109 | 0.162 | - | - | - | - | - | - | |||
| 6 | ✓ | ✓ | ✓ | 0.354 | 1.339 | 820 | 0.303 | 0.672 | 0.736(-9.7%) | 1.066(-12.9%) | 0.158 | - | - | - | - | - | - | ||
| 7 | ✓ | - | - | - | - | - | - | - | - | 60.5 | 37.0 | 52.4 | 29.8 | - | - | ||||
| 8 | ✓ | ✓ | 0.360 | 1.322 | 809 | - | - | - | - | - | 62.1 | 38.4 | 52.2 | 32.1 | - | - | |||
| 9 | ✓ | ✓ | ✓ | ✓ | 0.359 | 1.359 | 1057 | 0.304 | 0.675 | 0.710(-3.5%) | 1.005(-5.8%) | 0.146 | 62.3 | 39.4 | 53.1 | 32.2 | - | - | |
| 10 | ✓ | - | - | - | - | - | - | - | - | - | - | - | 1.131 | 0.773 | |||||
| 11 | ✓ | ✓ | ✓ | ✓ | 0.366 | 1.337 | 889 | 0.303 | 0.672 | 0.741 | 1.077 | 0.157 | - | - | - | - | 1.014 | 0.717 | |
| 12 | ✓ | ✓ | ✓ | ✓ | ✓ | 0.358 | 1.334 | 641 | 0.302 | 0.672 | 0.728 | 1.054 | 0.154 | 62.3 | 39.5 | 52.8 | 32.3 | 1.004 | 0.430 |
表 2:联合结果。在端到端管线中引入上游任务有助于保证安全。UniAD 在预测与规划任务上大幅超过朴素多任务学习方案,且没有出现感知性能的实质性下降。为简洁仅展示主要指标。「avg.L2」与「avg.Col」为规划时域上的平均值。:ID-0 为各任务独立头的多任务学习方案。
2.5 Learning
2.5 学习
UniAD is trained in two stages. We first jointly train perception parts, i.e., the tracking and mapping modules, for a few epochs (6 in our experiments), and then train the model end-to-end for 20 epochs with all perception, prediction and planning modules. The two-stage training is found more stable empirically. We refer the audience to the Supplementary for details of each loss.
UniAD 分两阶段训练。我们先联合训练感知部分(即跟踪与建图模块)若干 epoch(实验中为 6),再端到端训练全部感知、预测与规划模块 20 个 epoch。经验上两阶段训练更稳定。各损失细节见补充材料。
Shared matching.
Since UniAD involves instance-wise modeling, pairing predictions to the ground truth set is required in perception and prediction tasks. Similar to DETR [8, 56], the bipartite matching algorithm is adopted in the tracking and online mapping stage. As for tracking, candidates from detection queries are paired with newborn ground truth objects, and predictions from track queries inherit the assignment from previous frames. The matching results in the tracking module are reused in motion and occupancy nodes to consistently model agents from historical tracks to future motions in the end-to-end framework.
共享匹配。
由于 UniAD 涉及实例级建模,感知与预测任务需要把预测与真实集合配对。类似 DETR [8, 56],跟踪与在线建图阶段采用二分图匹配。对跟踪,detection query 候选与新生真实目标配对,track query 的预测继承先前帧的分配。跟踪模块中的匹配结果在运动与占据节点中复用,以便在端到端框架中从历史轨迹到未来运动一致地建模智能体。
3 Experiments
3 实验
We conduct experiments on the challenging nuScenes dataset [6]. In this section, we validate the effectiveness of our design in three aspects: joint results revealing the advantage of task coordination and its effect on planning, modular results of each task compared with previous methods, and ablations on the design space for specific modules. Due to space limit, the full suite of protocols, some ablations and visualizations are provided in the Supplementary.
我们在具有挑战的 nuScenes 数据集 [6] 上实验。本节从三方面验证设计有效性:揭示任务协同优势及其对规划影响的联合结果、各任务相对先前方法的模块结果,以及对特定模块设计空间的消融。因篇幅限制,完整协议、部分消融与可视化见补充材料。
3.1 Joint Results
3.1 联合结果
We conduct extensive ablations as shown in Table 2 to prove the effectiveness and necessity of preceding tasks in the end-to-end pipeline. Each row of this table shows the model performance when incorporating task modules listed in the second Modules column. The first row (ID-0) serves as a vanilla multi-task baseline with separate task heads for comparison. The best result of each metric is marked in bold, and the runner-up result is underlined in each column.
我们做了大量消融(表 2)以证明端到端管线中上游任务的有效性与必要性。表中每行对应第二列「模块」所列任务组合下的模型表现。第一行(ID-0)为带独立任务头的朴素多任务基线。各列最优指标加粗,次优加下划线。
Roadmap toward safe planning.
As prediction is closer to planning compared to perception, we first investigate the two types of prediction tasks in our framework, i.e., motion forecasting and occupancy prediction. In Exp.10-12, only when the two tasks are introduced simultaneously (Exp.12), both metrics of the planning L2 and collision rate achieve the best results, compared to naive end-to-end planning without any intermediate tasks (Exp.10, Fig. 1(c.1)). Thus we conclude that both these two prediction tasks are required for a safe planning objective. Taking a step back, in Exp.7-9, we show the cooperative effect of two types of prediction. The performance of both tasks get improved when they are closely integrated (Exp.9, -3.5% minADE, -5.8% minFDE, -1.3 MR(%), +2.4 IoU-f.(%), +2.4 VPQ-f.(%)), which demonstrates the necessity to include both agent and scene representations. Meanwhile, in order to realize a superior motion forecasting performance, we explore how perception modules could contribute in Exp.4-6. Notably, incorporating both tracking and mapping nodes brings remarkable improvement to forecasting results (-9.7% minADE, -12.9% minFDE, -2.3 MR(%)). We also present Exp.1-3, which indicate training perception sub-tasks together leads to comparable results to a single task. Additionally, compared with naive multi-task learning (Exp.0, Fig. 1(b)), Exp.12 outperforms it by a significant margin in all essential metrics (-15.2% minADE, -17.0% minFDE, -3.2 MR(%)), +4.9 IoU-f.(%)., +5.9 VPQ-f.(%), -0.15 avg.L2, -0.51 avg.Col.(%)), showing the superiority of our planning-oriented design.
通向安全规划的路线图。
相对感知,预测更贴近规划,我们首先考察框架中两类预测任务:运动预报与占据预测。在实验 10–12 中,仅当两任务同时引入(实验 12)时,规划的 L2 与碰撞率均达最佳,优于无任何中间任务的朴素端到端规划(实验 10,图 1(c.1))。因此我们结论:这两类预测对安全规划都必要。进一步加入跟踪与建图(实验 13–15)后,规划与预测指标继续提升。完整带全部模块的 UniAD(实验 15)相对朴素多任务学习(ID-0)取得全面优势(例如约 28.0% minFDE、3.2 MR(%)、+ IoU-f.(%)、+ VPQ-f.(%)、0.15 avg.L2、0.51 avg.Col.(%)),显示规划导向设计的优越性。
3.2 Modular Results
3.2 模块结果
Following the sequential order of perception-prediction-planning, we report the performance of each task module in comparison to prior state-of-the-arts on the nuScenes validation set. Note that UniAD jointly performs all these tasks with a single trained network. The main metric for each task is marked with gray background in tables.
按感知—预测—规划的顺序,我们在 nuScenes 验证集上报告各任务模块相对先前最优方法的表现。注意 UniAD 用单一训练网络联合完成所有这些任务。各任务主指标在表中以灰色背景标出。
Perception results.
As for multi-object tracking in Table 3, UniAD yields a significant improvement of +6.5 and +14.2 AMOTA(%) compared to MUTR3D [104] and ViP3D [30] respectively. Moreover, UniAD achieves the lowest ID switch score, showing its temporal consistency for each tracklet. For online mapping in Table 4, UniAD performs well on segmenting lanes (+7.4 IoU(%) compared to BEVFormer), which is crucial for downstream agent-road interaction in the motion module. As our tracking module follows an end-to-end paradigm, it is still inferior to tracking-by-detection methods with complex associations such as Immortal Tracker [93], and our mapping results trail previous perception-oriented methods on specific classes. We argue that UniAD is to benefit final planning with perceived information rather than optimizing perception with full model capacity.
感知结果。
表 3 多目标跟踪上,UniAD 相对 MUTR3D [104] 与 ViP3D [30] 分别取得 +6.5 与 +14.2 AMOTA(%) 的显著提升,且 ID switch 最低,显示每条轨迹的时序一致性。表 4 在线建图上,UniAD 在车道分割上表现良好(相对 BEVFormer +7.4 IoU(%)),这对运动模块中下游智能体—道路交互至关重要。我们的跟踪与建图模块面向规划所需信息,而非以全部模型容量去优化感知本身。
Prediction results.
Motion forecasting results are shown in Table 5, where UniAD remarkably outperforms previous vision-based end-to-end methods. It reduces prediction errors by 38.3% and 65.4% on minADE compared to PnPNet-vision [57] and ViP3D [30] respectively. In terms of occupancy prediction reported in Table 6, UniAD gets notable advances in nearby areas, yielding +4.0 and +2.0 on IoU-near(%) compared to FIERY [35] and BEVerse [105] with heavy augmentations, respectively.
预测结果。
运动预报见表 5:UniAD 显著超过先前基于视觉的端到端方法,相对 PnPNet-vision [57] 与 ViP3D [30],minADE 误差分别降低 38.3% 与 65.4%。表 6 占据预测上,UniAD 在近距区域取得明显进展,相对带强增强的 FIERY [35] 与 BEVerse [105],IoU-near(%) 分别 +4.0 与 +2.0。
Planning results.
Benefiting from rich spatial-temporal information in both the ego-vehicle query and occupancy, UniAD reduces planning L2 error and collision rate by 51.2% and 56.3% compared to ST-P3 [38], in terms of the average value for the planning horizon. Moreover, it notably outperforms several LiDAR-based counterparts, which is often deemed challenging for perception tasks.
规划结果。
得益于自车 query 与占据中的丰富时空信息,按规划时域平均值计,UniAD 相对 ST-P3 [38] 将规划 L2 误差与碰撞率分别降低 51.2% 与 56.3%。此外,它明显超过若干基于 LiDAR 的对照,而这在感知任务上通常被认为颇具挑战。
| Method | AMOTA | AMOTP | Recall | IDS |
|---|---|---|---|---|
| Immortal Tracker [93] | 0.378 | 1.119 | 0.478 | 936 |
| ViP3D [30] | 0.217 | 1.625 | 0.363 | - |
| QD3DT [36] | 0.242 | 1.518 | 0.399 | - |
| MUTR3D [104] | 0.294 | 1.498 | 0.427 | 3822 |
| UniAD | 0.359 | 1.320 | 0.467 | 906 |
Table 3: Multi-object tracking. UniAD outperforms previous end-to-end MOT techniques (with image inputs only) on all metrics. †: Tracking-by-detection method with post-association, reimplemented with BEVFormer for a fair comparison.
| Method | AMOTA | AMOTP | Recall | IDS |
|---|---|---|---|---|
| Immortal Tracker [93] | 0.378 | 1.119 | 0.478 | 936 |
| ViP3D [30] | 0.217 | 1.625 | 0.363 | - |
| QD3DT [36] | 0.242 | 1.518 | 0.399 | - |
| MUTR3D [104] | 0.294 | 1.498 | 0.427 | 3822 |
| UniAD | 0.359 | 1.320 | 0.467 | 906 |
表 3:多目标跟踪。UniAD 在全部指标上超过先前端到端 MOT 技术(仅图像输入)。†:带后关联的 tracking-by-detection,用 BEVFormer 重实现以便公平比较。
| Method | Lanes | Drivable | Divider | Crossing |
|---|---|---|---|---|
| VPN [72] | 18.0 | 76.0 | - | - |
| LSS [76] | 18.3 | 73.9 | - | - |
| BEVFormer [55] | 23.9 | 77.5 | - | - |
| BEVerse [105] | - | - | 30.6 | 17.2 |
| UniAD | 31.3 | 69.1 | 25.7 | 13.8 |
Table 4: Online mapping. UniAD achieves competitive performance against state-of-the-art perception-oriented methods, with comprehensive road semantics. We report segmentation IoU (%). †: Reimplemented with BEVFormer.
| Method | Lanes | Drivable | Divider | Crossing |
|---|---|---|---|---|
| VPN [72] | 18.0 | 76.0 | - | - |
| LSS [76] | 18.3 | 73.9 | - | - |
| BEVFormer [55] | 23.9 | 77.5 | - | - |
| BEVerse [105] | - | - | 30.6 | 17.2 |
| UniAD | 31.3 | 69.1 | 25.7 | 13.8 |
表 4:在线建图。UniAD 在全面道路语义上与面向感知的最优方法相当。报告分割 IoU (%)。†:用 BEVFormer 重实现。
| Method | minADE() | minFDE() | MR | EPA |
|---|---|---|---|---|
| PnPNet [57] | 1.15 | 1.95 | 0.226 | 0.222 |
| ViP3D [30] | 2.05 | 2.84 | 0.246 | 0.226 |
| Constant Pos. | 5.80 | 10.27 | 0.347 | - |
| Constant Vel. | 2.13 | 4.01 | 0.318 | - |
| UniAD | 0.71 | 1.02 | 0.151 | 0.456 |
Table 5: Motion forecasting. UniAD remarkably outperforms previous vision-based end-to-end methods. We also report two settings of modeling vehicles with constant positions or velocities as comparisons. †: Reimplemented with BEVFormer.
| Method | minADE() | minFDE() | MR | EPA |
|---|---|---|---|---|
| PnPNet [57] | 1.15 | 1.95 | 0.226 | 0.222 |
| ViP3D [30] | 2.05 | 2.84 | 0.246 | 0.226 |
| Constant Pos. | 5.80 | 10.27 | 0.347 | - |
| Constant Vel. | 2.13 | 4.01 | 0.318 | - |
| UniAD | 0.71 | 1.02 | 0.151 | 0.456 |
表 5:运动预报。UniAD 显著超过先前基于视觉的端到端方法。亦报告恒定位置或恒定速度建模车辆的两种设定作对照。†:用 BEVFormer 重实现。
| Method | IoU-n. | IoU-f. | VPQ-n. | VPQ-f. |
|---|---|---|---|---|
| FIERY [35] | 59.4 | 36.7 | 50.2 | 29.9 |
| StretchBEV [1] | 55.5 | 37.1 | 46.0 | 29.0 |
| ST-P3 [38] | - | 38.9 | - | 32.1 |
| BEVerse [105] | 61.4 | 40.9 | 54.3 | 36.1 |
| UniAD | 63.4 | 40.2 | 54.7 | 33.5 |
Table 6: Occupancy prediction. UniAD gets significant improvement in nearby areas, which are more critical for planning. “n.” and “f.” indicates near () and far () evaluation ranges respectively. †: Trained with heavy augmentations.
| Method | IoU-n. | IoU-f. | VPQ-n. | VPQ-f. |
|---|---|---|---|---|
| FIERY [35] | 59.4 | 36.7 | 50.2 | 29.9 |
| StretchBEV [1] | 55.5 | 37.1 | 46.0 | 29.0 |
| ST-P3 [38] | - | 38.9 | - | 32.1 |
| BEVerse [105] | 61.4 | 40.9 | 54.3 | 36.1 |
| UniAD | 63.4 | 40.2 | 54.7 | 33.5 |
表 6:占据预测。UniAD 在对规划更关键的近距区域取得显著提升。「n.」与「f.」分别表示近距()与远距()评估范围。†:带强数据增强训练。
| Method | L2() | Col. Rate(%) | ||||||
|---|---|---|---|---|---|---|---|---|
| 1 | 2 | 3 | Avg. | 1 | 2 | 3 | Avg. | |
| NMP [101] | - | - | 2.31 | - | - | - | 1.92 | - |
| SA-NMP [101] | - | - | 2.05 | - | - | - | 1.59 | - |
| FF [37] | 0.55 | 1.20 | 2.54 | 1.43 | 0.06 | 0.17 | 1.07 | 0.43 |
| EO [47] | 0.67 | 1.36 | 2.78 | 1.60 | 0.04 | 0.09 | 0.88 | 0.33 |
| ST-P3 [38] | 1.33 | 2.11 | 2.90 | 2.11 | 0.23 | 0.62 | 1.27 | 0.71 |
| UniAD | 0.48 | 0.96 | 1.65 | 1.03 | 0.05 | 0.17 | 0.71 | 0.31 |
Table 7: Planning. UniAD achieves the lowest L2 error and collision rate in all time intervals and even outperforms LiDAR-based methods (†) in most cases, verifying the safety of our system.
| Method | L2() | Col. Rate(%) | ||||||
|---|---|---|---|---|---|---|---|---|
| 1 | 2 | 3 | Avg. | 1 | 2 | 3 | Avg. | |
| NMP [101] | - | - | 2.31 | - | - | - | 1.92 | - |
| SA-NMP [101] | - | - | 2.05 | - | - | - | 1.59 | - |
| FF [37] | 0.55 | 1.20 | 2.54 | 1.43 | 0.06 | 0.17 | 1.07 | 0.43 |
| EO [47] | 0.67 | 1.36 | 2.78 | 1.60 | 0.04 | 0.09 | 0.88 | 0.33 |
| ST-P3 [38] | 1.33 | 2.11 | 2.90 | 2.11 | 0.23 | 0.62 | 1.27 | 0.71 |
| UniAD | 0.48 | 0.96 | 1.65 | 1.03 | 0.05 | 0.17 | 0.71 | 0.31 |
表 7:规划。UniAD 在所有时间间隔取得最低 L2 误差与碰撞率,多数情况下甚至超过基于 LiDAR 的方法(†),验证了系统安全性。
3.3 Qualitative Results
3.3 定性结果
Fig. 3 visualizes the results of all tasks for one complex scene. The ego vehicle drives with notice to the potential movement of a front vehicle and lane. In the Supplementary, we show more visualizations of challenging scenarios and one promising case for the planning-oriented design, that inaccurate results occur in prior modules while the later tasks could still recover, e.g., the planned trajectory remains reasonable though objects have a large heading angle deviation or fail to be detected in tracking results. Besides, we analyze that failure cases of UniAD are mainly under some long-tail scenarios such as large trucks and trailers, shown in the Supplementary as well.
图 3 可视化一个复杂场景中全部任务的结果。自车行驶时注意到前方车辆与车道的潜在运动。补充材料中展示更多挑战场景可视化,以及规划导向设计的一个有希望案例:上游模块结果不准确时,后续任务仍可恢复,例如目标航向偏差很大或漏检时,规划轨迹仍保持合理。我们分析 UniAD 的失败案例主要出现在大卡车、拖车等长尾场景,亦见补充材料。
| ID | Scene-l. Anch. | Scene-l. | Anch. | Goal Inter. | Goal | Inter. | Ego | NLO. | minADE | minFDE | MR | minFDE -mAP∗ | minFDE | -mAP∗ |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Scene-l. | ||||||||||||||
| Anch. | ||||||||||||||
| Goal | ||||||||||||||
| Inter. | ||||||||||||||
| minFDE | ||||||||||||||
| -mAP∗ | ||||||||||||||
| 1 | 0.844 | 1.336 | 0.177 | 0.246 | ||||||||||
| 2 | ✓ | 0.768 | 1.159 | 0.164 | 0.267 | |||||||||
| 3 | ✓ | ✓ | 0.755 | 1.130 | 0.168 | 0.264 | ||||||||
| 4 | ✓ | ✓ | ✓ | 0.747 | 1.096 | 0.156 | 0.266 | |||||||
| 5 | ✓ | ✓ | ✓ | ✓ | 0.710 | 1.004 | 0.146 | 0.273 |
| Scene-l. |
|---|
| Anch. |
| Goal |
|---|
| Inter. |
| minFDE |
|---|
| -mAP∗ |
Table 8: Ablation for designs in the motion forecasting module. All components contribute to the ultimate performance. “Scene-l. Anch.” denotes rotated scene-level anchors. “Goal Inter.” means the agent-goal point interaction. “Ego ” represents the ego-vehicle query and “NLO.” is the non-linear optimization strategy. : A metric considering detection and forecasting accuracy simultaneously, and we put details in the Supplementary.
| ID | Scene-l. Anch. | Scene-l. | Anch. | Goal Inter. | Goal | Inter. | Ego | NLO. | minADE | minFDE | MR | minFDE -mAP∗ | minFDE | -mAP∗ |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Scene-l. | ||||||||||||||
| Anch. | ||||||||||||||
| Goal | ||||||||||||||
| Inter. | ||||||||||||||
| minFDE | ||||||||||||||
| -mAP∗ | ||||||||||||||
| 1 | 0.844 | 1.336 | 0.177 | 0.246 | ||||||||||
| 2 | ✓ | 0.768 | 1.159 | 0.164 | 0.267 | |||||||||
| 3 | ✓ | ✓ | 0.755 | 1.130 | 0.168 | 0.264 | ||||||||
| 4 | ✓ | ✓ | ✓ | 0.747 | 1.096 | 0.156 | 0.266 | |||||||
| 5 | ✓ | ✓ | ✓ | ✓ | 0.710 | 1.004 | 0.146 | 0.273 |
| Scene-l. |
|---|
| Anch. |
| Goal |
|---|
| Inter. |
| minFDE |
|---|
| -mAP∗ |
Table 8: Ablation for designs in the motion forecasting module. All components contribute to the ultimate performance. “Scene-l. Anch.” denotes rotated scene-level anchors. “Goal Inter.” means the agent-goal point interaction. “Ego ” represents the ego-vehicle query and “NLO.” is the non-linear optimization strategy. : A metric considering detection and forecasting accuracy simultaneously, and we put details in the Supplementary.
表 8:MotionFormer 设计消融。
| ID | Cross. Attn. | Cross. | Attn. | Attn. Mask | Attn. | Mask | Mask Feat. | Mask | Feat. | IoU-n. | IoU-f. | VPQ-n. | VPQ-f. |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Cross. | |||||||||||||
| Attn. | |||||||||||||
| Attn. | |||||||||||||
| Mask | |||||||||||||
| Mask | |||||||||||||
| Feat. | |||||||||||||
| 1 | 61.2 | 39.7 | 51.5 | 31.8 | |||||||||
| 2 | ✓ | 61.3 | 39.4 | 51.0 | 31.8 | ||||||||
| 3 | ✓ | ✓ | 62.3 | 39.7 | 52.4 | 32.5 | |||||||
| 4 | ✓ | ✓ | ✓ | 62.6 | 39.5 | 53.2 | 32.8 |
| Cross. |
|---|
| Attn. |
| Attn. |
|---|
| Mask |
| Mask |
|---|
| Feat. |
Table 9: Ablation for designs in the occupancy prediction module. Cross-attention with masks and the reuse of mask feature helps improve the prediction. “Cross. Attn.” and “Attn. Mask” represent cross-attention and the attention mask in the pixel-agent interaction respectively. “Mask Feat.” denotes the reuse of the mask feature for instance-level occupancy.
| ID | Cross. Attn. | Cross. | Attn. | Attn. Mask | Attn. | Mask | Mask Feat. | Mask | Feat. | IoU-n. | IoU-f. | VPQ-n. | VPQ-f. |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Cross. | |||||||||||||
| Attn. | |||||||||||||
| Attn. | |||||||||||||
| Mask | |||||||||||||
| Mask | |||||||||||||
| Feat. | |||||||||||||
| 1 | 61.2 | 39.7 | 51.5 | 31.8 | |||||||||
| 2 | ✓ | 61.3 | 39.4 | 51.0 | 31.8 | ||||||||
| 3 | ✓ | ✓ | 62.3 | 39.7 | 52.4 | 32.5 | |||||||
| 4 | ✓ | ✓ | ✓ | 62.6 | 39.5 | 53.2 | 32.8 |
| Cross. |
|---|
| Attn. |
| Attn. |
|---|
| Mask |
| Mask |
|---|
| Feat. |
Table 9: Ablation for designs in the occupancy prediction module. Cross-attention with masks and the reuse of mask feature helps improve the prediction. “Cross. Attn.” and “Attn. Mask” represent cross-attention and the attention mask in the pixel-agent interaction respectively. “Mask Feat.” denotes the reuse of the mask feature for instance-level occupancy.
表 9:OccFormer 设计消融。
| ID | BEV | Col. | Occ. | L2 | Col. Rate | ||||
|---|---|---|---|---|---|---|---|---|---|
| Att. | Loss | Optim. | 1 | 2 | 3 | 1 | 2 | 3 | |
| 1 | 0.44 | 0.99 | 1.71 | 0.56 | 0.88 | 1.64 | |||
| 2 | ✓ | 0.44 | 1.04 | 1.81 | 0.35 | 0.71 | 1.58 | ||
| 3 | ✓ | ✓ | 0.44 | 1.02 | 1.76 | 0.30 | 0.51 | 1.39 | |
| 4 | ✓ | ✓ | ✓ | 0.54 | 1.09 | 1.81 | 0.13 | 0.42 | 1.05 |
Table 10: Ablation for designs in the planning module. Results demonstrate the necessity of each preceding task. “BEV Att.” indicates attending to BEV feature. “Col. Loss” denotes collision loss. “Occ. Optim.” is the optimization strategy with occupancy.
| ID | BEV | Col. | Occ. | L2 | Col. Rate | ||||
|---|---|---|---|---|---|---|---|---|---|
| Att. | Loss | Optim. | 1 | 2 | 3 | 1 | 2 | 3 | |
| 1 | 0.44 | 0.99 | 1.71 | 0.56 | 0.88 | 1.64 | |||
| 2 | ✓ | 0.44 | 1.04 | 1.81 | 0.35 | 0.71 | 1.58 | ||
| 3 | ✓ | ✓ | 0.44 | 1.02 | 1.76 | 0.30 | 0.51 | 1.39 | |
| 4 | ✓ | ✓ | ✓ | 0.54 | 1.09 | 1.81 | 0.13 | 0.42 | 1.05 |
表 10:规划器设计消融。「BEV Att.」表示关注 BEV 特征。「Col. Loss」表示碰撞损失。「Occ. Optim.」为基于占据的优化策略。
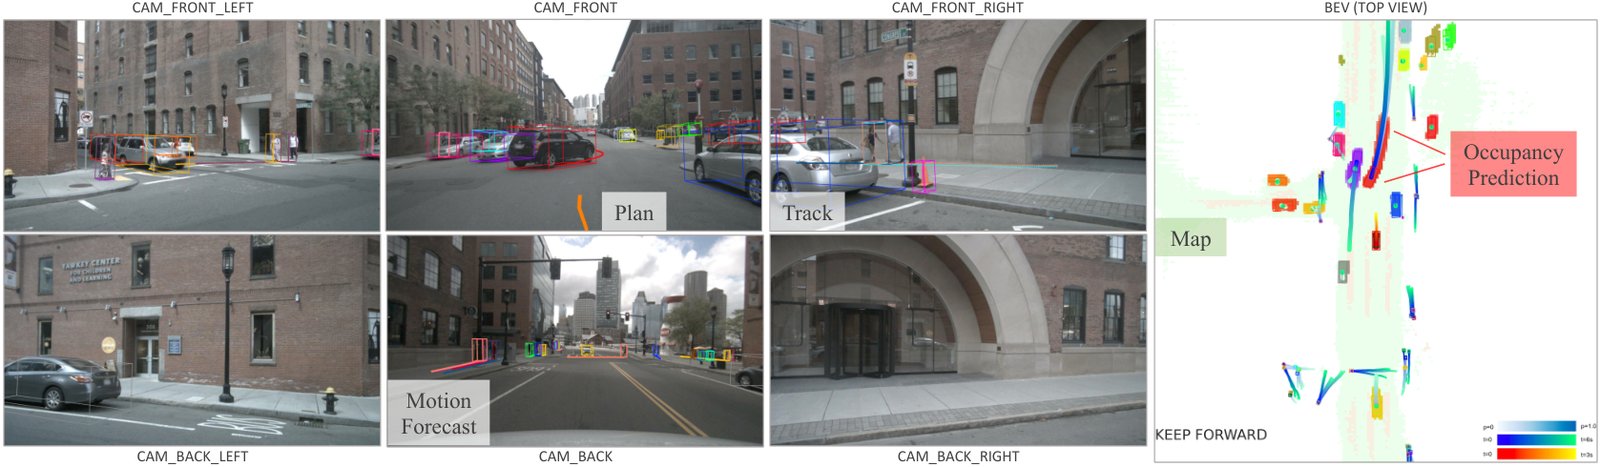
Figure 3: Visualization results. We show results for all tasks in surround-view images and BEV. Predictions from motion and occupancy modules are consistent, and the ego vehicle is yielding to the front black car in this case. Each agent is illustrated with a unique color. Only top-1 and top-3 trajectories from motion forecasting are selected for visualization on image-view and BEV respectively.
图 3:可视化结果。我们在环视图像与 BEV 中展示全部任务结果。运动与占据模块的预测一致,本例中自车对前方黑色车辆让行。每个智能体用独特颜色表示。图像视图与 BEV 分别只选取运动预报的 top-1 与 top-3 轨迹可视化。
3.4 Ablation Study
3.4 消融研究
Effect of designs in MotionFormer.
Table 8 shows that all of our proposed components described in Sec. 2.2 contribute to final performance regarding minADE, minFDE, Miss Rate and minFDE-mAP metrics. Notably, the rotated scene-level anchor shows a significant performance boost (-15.8% minADE, -11.2% minFDE, +1.9 minFDE-mAP(%)), indicating that it is essential to do motion forecasting in the scene-centric manner. The agent-goal point interaction enhances the motion query with the planning-oriented visual feature, and surrounding agents can further benefit from considering the ego vehicle’s intention. Moreover, the non-linear optimization strategy improves the performance (-5.0% minADE, -8.4% minFDE, -1.0 MR(%), +0.7 minFDE-mAP(%)) by taking perceptual uncertainty into account in the end-to-end scenario.
MotionFormer 设计的影响。
表 8 显示第 2.2 节所述全部组件均对 minADE、minFDE、Miss Rate 与 minFDE-mAP 有贡献。值得注意的是,旋转场景级锚点带来显著提升(15.8% minADE、11.2% minFDE、+ minFDE-mAP(%)),表明以场景中心方式做运动预报至关重要。智能体—目标点交互以规划导向意图增强运动 query。非线性优化通过在端到端场景中考虑感知不确定性,进一步改进表现(5.0% minADE、8.4% minFDE、1.0 MR(%)、+ minFDE-mAP(%))。
Effect of designs in OccFormer.
As illustrated in Table 9, attending each pixel to all agents without locality constraints (Exp.2) results in slightly worse performance compared to an attention-free baseline (Exp.1). The occupancy-guided attention mask resolves the problem and brings in gain, especially for nearby areas (Exp.3, +1.0 IoU-n.(%), +1.4 VPQ-n.(%)). Additionally, reusing the mask feature instead of the agent feature to acquire the occupancy feature further enhances performance.
OccFormer 设计的影响。
如表 9,无局部性约束地让每个像素关注全部智能体(实验 2)相对无注意力基线(实验 1)略差。占据引导的注意力掩码解决该问题并带来增益。此外,用掩码特征 而非智能体特征获取占据特征可进一步提升表现。
Effect of designs in Planner.
We provide ablations on the proposed designs in planner in Table 10, i.e., attending BEV features, training with the collision loss and the optimization strategy with occupancy. Similar to previous research [37, 38], a lower collision rate is preferred for safety over naive trajectory mimicking (L2 metric), and is reduced with all parts applied in UniAD.
规划器设计的影响。
表 10 给出规划器中所提设计的消融,即关注 BEV 特征、用碰撞损失训练以及基于占据的优化策略。与先前研究 [37, 38] 类似,出于安全考虑,更低碰撞率优于朴素轨迹模仿(L2 指标);在 UniAD 中应用全部组件后碰撞率下降。
4 Conclusion and Future Work
4 结论与未来工作
We discuss the system-level design for the autonomous driving algorithm framework. A planning-oriented pipeline is proposed toward the ultimate pursuit for planning, namely UniAD. We provide detailed analyses on the necessity of each module within perception and prediction. To unify tasks, a query-based design is proposed to connect all nodes in UniAD, benefiting from richer representations for agent interaction in the environment. Extensive experiments verify the proposed method in all aspects.
我们讨论自动驾驶算法框架的系统级设计,提出以规划为终极追求的规划导向管线 UniAD,并详细分析感知与预测中各模块的必要性。为统一任务,采用基于 query 的接口连接各节点。受益于环境中智能体交互的更丰富表示,UniAD 表现优异。大量实验从各方面验证了所提方法。
Limitations and future work. Coordinating such a comprehensive system with multiple tasks is non-trivial and needs extensive computational power, especially trained with temporal history. How to devise and curate the system for a lightweight deployment deserves future exploration. Moreover, whether or not to incorporate more tasks such as depth estimation, behavior prediction, and how to embed them into the system, are worthy future directions as well.
局限与未来工作。协调含多任务的综合系统并不轻松,尤其在带时序历史训练时需要大量算力。如何设计与精简系统以便轻量部署值得未来探索。此外,是否纳入深度估计、行为预测等更多任务,以及如何嵌入系统,也是有价值的方向。
Acknowledgements. This work is partially supported by National Key R&D Program of China (2022ZD0160100), and in part by Shanghai Committee of Science and Technology (21DZ1100100), and NSFC (62206172).
致谢。本工作部分得到国家重点研发计划(2022ZD0160100)、上海市科委(21DZ1100100)与国家自然科学基金(62206172)资助。
References
参考文献
Appendix
附录
[1] Adil Kaan Akan and Fatma Güney. StretchBEV: Stretching future instance prediction spatially and temporally. In ECCV , 2022.
[2] Mayank Bansal, Alex Krizhevsky, and Abhijit Ogale. Chauffeurnet: Learning to drive by imitating the best and synthesizing the worst. arXiv preprint arXiv:1812.03079 , 2018.
[3] Hans Georg Bock and Karl-Josef Plitt. A multiple shooting algorithm for direct solution of optimal control problems. IFAC Proceedings Volumes , 1984.
[4] Mariusz Bojarski, Davide Del Testa, Daniel Dworakowski, Bernhard Firner, Beat Flepp, Prasoon Goyal, Lawrence D Jackel, Mathew Monfort, Urs Muller, Jiakai Zhang, Xin Zhang, Jake Zhao, and Zieba Karol. End to end learning for self-driving cars. arXiv preprint arXiv:1604.07316 , 2016.
[5] Thibault Buhet, Émilie Wirbel, and Xavier Perrotton. PLOP: Probabilistic polynomial objects trajectory planning for autonomous driving. In CoRL , 2020.
[6] Holger Caesar, Varun Bankiti, Alex H Lang, Sourabh Vora, Venice Erin Liong, Qiang Xu, Anush Krishnan, Yu Pan, Giancarlo Baldan, and Oscar Beijbom. nuscenes: A multimodal dataset for autonomous driving. In CVPR , 2020.
[7] Holger Caesar, Juraj Kabzan, Kok Seang Tan, Whye Kit Fong, Eric Wolff, Alex Lang, Luke Fletcher, Oscar Beijbom, and Sammy Omari. nuplan: A closed-loop ml-based planning benchmark for autonomous vehicles. arXiv preprint arXiv:2106.11810 , 2021.
[8] Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, and Sergey Zagoruyko. End-to-end object detection with transformers. In ECCV , 2020.
[9] Sergio Casas, Cole Gulino, Renjie Liao, and Raquel Urtasun. Spagnn: Spatially-aware graph neural networks for relational behavior forecasting from sensor data. In ICRA , 2020.
[10] Sergio Casas, Wenjie Luo, and Raquel Urtasun. Intentnet: Learning to predict intention from raw sensor data. In CoRL , 2018.
[11] Sergio Casas, Abbas Sadat, and Raquel Urtasun. Mp3: A unified model to map, perceive, predict and plan. In CVPR , 2021.
[12] Yuning Chai, Benjamin Sapp, Mayank Bansal, and Dragomir Anguelov. Multipath: Multiple probabilistic anchor trajectory hypotheses for behavior prediction. In CoRL , 2020.
[13] Raphael Chekroun, Marin Toromanoff, Sascha Hornauer, and Fabien Moutarde. GRI: General reinforced imitation and its application to vision-based autonomous driving. arXiv preprint 2111.08575 , 2021.
[14] Dian Chen, Vladlen Koltun, and Philipp Krähenbühl. Learning to drive from a world on rails. In ICCV , 2021.
[15] Dian Chen and Philipp Krähenbühl. Learning from all vehicles. In CVPR , 2022.
[16] Dian Chen, Brady Zhou, Vladlen Koltun, and Philipp Krähenbühl. Learning by cheating. In CoRL , 2020.
[17] Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, and Rohit Girdhar. Masked-attention mask transformer for universal image segmentation. In CVPR , 2022.
[18] Bowen Cheng, Alex Schwing, and Alexander Kirillov. Per-pixel classification is not all you need for semantic segmentation. In NeurIPS , 2021.
[19] Kashyap Chitta, Aditya Prakash, and Andreas Geiger. NEAT: Neural attention fields for end-to-end autonomous driving. In ICCV , 2021.
[20] Kashyap Chitta, Aditya Prakash, Bernhard Jaeger, Zehao Yu, Katrin Renz, and Andreas Geiger. Transfuser: Imitation with transformer-based sensor fusion for autonomous driving. IEEE TPAMI , 2022.
[21] Felipe Codevilla, Matthias Müller, Antonio López, Vladlen Koltun, and Alexey Dosovitskiy. End-to-end driving via conditional imitation learning. In ICRA , 2018.
[22] Felipe Codevilla, Eder Santana, Antonio M López, and Adrien Gaidon. Exploring the limitations of behavior cloning for autonomous driving. In ICCV , 2019.
[23] Michael Crawshaw. Multi-task learning with deep neural networks: A survey. arXiv preprint arXiv:2009.09796 , 2020.
[24] Alexander Cui, Sergio Casas, Abbas Sadat, Renjie Liao, and Raquel Urtasun. Lookout: Diverse multi-future prediction and planning for self-driving. In ICCV , 2021.
[25] Nemanja Djuric, Henggang Cui, Zhaoen Su, Shangxuan Wu, Huahua Wang, Fang-Chieh Chou, Luisa San Martin, Song Feng, Rui Hu, Yang Xu, Alyssa Dayan, Sidney Zhang, Brian C. Becker, Gregory P. Meyer, Carlos Vallespi-Gonzalez, and Carl K. Wellington. Multixnet: Multiclass multistage multimodal motion prediction. In IV , 2021.
[26] Alexey Dosovitskiy, German Ros, Felipe Codevilla, Antonio Lopez, and Vladlen Koltun. CARLA: An open urban driving simulator. In CoRL , 2017.
[27] Scott Ettinger, Shuyang Cheng, Benjamin Caine, Chenxi Liu, Hang Zhao, Sabeek Pradhan, Yuning Chai, Ben Sapp, Charles R Qi, Yin Zhou, Zoey Yang, Aurélien Chouard, Pei Sun, Jiquan Ngiam, Vijay Vasudevan, Alexander McCauley, Jonathon Shlens, and Dragomir Anguelov. Large scale interactive motion forecasting for autonomous driving: The waymo open motion dataset. In ICCV , 2021.
[28] Sudeep Fadadu, Shreyash Pandey, Darshan Hegde, Yi Shi, Fang-Chieh Chou, Nemanja Djuric, and Carlos Vallespi-Gonzalez. Multi-view fusion of sensor data for improved perception and prediction in autonomous driving. In WACV , 2022.
[29] Jiyang Gao, Chen Sun, Hang Zhao, Yi Shen, Dragomir Anguelov, Congcong Li, and Cordelia Schmid. Vectornet: Encoding hd maps and agent dynamics from vectorized representation. In CVPR , 2020.
[30] Junru Gu, Chenxu Hu, Tianyuan Zhang, Xuanyao Chen, Yilun Wang, Yue Wang, and Hang Zhao. ViP3D: End-to-end visual trajectory prediction via 3d agent queries. In CVPR , 2023.
[31] Chunrui Han, Jianjian Sun, Zheng Ge, Jinrong Yang, Runpei Dong, Hongyu Zhou, Weixin Mao, Yuang Peng, and Xiangyu Zhang. Exploring recurrent long-term temporal fusion for multi-view 3d perception. arXiv preprint arXiv:2303.05970 , 2023.
[32] Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recognition. In CVPR , 2016.
[33] Noureldin Hendy, Cooper Sloan, Feng Tian, Pengfei Duan, Nick Charchut, Yuesong Xie, Chuang Wang, and James Philbin. Fishing net: Future inference of semantic heatmaps in grids. arXiv preprint arXiv:2006.09917 , 2020.
[34] Anthony Hu, Gianluca Corrado, Nicolas Griffiths, Zak Murez, Corina Gurau, Hudson Yeo, Alex Kendall, Roberto Cipolla, and Jamie Shotton. Model-based imitation learning for urban driving. In NeurIPS , 2022.
[35] Anthony Hu, Zak Murez, Nikhil Mohan, Sofía Dudas, Jeffrey Hawke, Vijay Badrinarayanan, Roberto Cipolla, and Alex Kendall. FIERY: Future instance prediction in bird’s-eye view from surround monocular cameras. In ICCV , 2021.
[36] Hou-Ning Hu, Yung-Hsu Yang, Tobias Fischer, Trevor Darrell, Fisher Yu, and Min Sun. Monocular quasi-dense 3d object tracking. IEEE TPAMI , 2022.
[37] Peiyun Hu, Aaron Huang, John Dolan, David Held, and Deva Ramanan. Safe local motion planning with self-supervised freespace forecasting. In CVPR , 2021.
[38] Shengchao Hu, Li Chen, Penghao Wu, Hongyang Li, Junchi Yan, and Dacheng Tao. ST-P3: End-to-end vision-based autonomous driving via spatial-temporal feature learning. In ECCV , 2022.
[39] Zhiyu Huang, Haochen Liu, Jingda Wu, and Chen Lv. Differentiable integrated motion prediction and planning with learnable cost function for autonomous driving. arXiv preprint arXiv:2207.10422 , 2022.
[40] Boris Ivanovic, Amine Elhafsi, Guy Rosman, Adrien Gaidon, and Marco Pavone. MATS: An interpretable trajectory forecasting representation for planning and control. In CoRL , 2021.
[41] Xiaosong Jia, Li Chen, Penghao Wu, Jia Zeng, Junchi Yan, Hongyang Li, and Yu Qiao. Towards capturing the temporal dynamics for trajectory prediction: a coarse-to-fine approach. In CoRL , 2022.
[42] Xiaosong Jia, Liting Sun, Masayoshi Tomizuka, and Wei Zhan. Ide-net: Interactive driving event and pattern extraction from human data. IEEE RA-L , 2021.
[43] Xiaosong Jia, Liting Sun, Hang Zhao, Masayoshi Tomizuka, and Wei Zhan. Multi-agent trajectory prediction by combining egocentric and allocentric views. In CoRL , 2021.
[44] Xiaosong Jia, Penghao Wu, Li Chen, Hongyang Li, Yu Liu, and Junchi Yan. HDGT: Heterogeneous driving graph transformer for multi-agent trajectory prediction via scene encoding. arXiv preprint arXiv:2205.09753 , 2022.
[45] Alexey Kamenev, Lirui Wang, Ollin Boer Bohan, Ishwar Kulkarni, Bilal Kartal, Artem Molchanov, Stan Birchfield, David Nistér, and Nikolai Smolyanskiy. Predictionnet: Real-time joint probabilistic traffic prediction for planning, control, and simulation. In ICRA , 2022.
[46] Alex Kendall, Jeffrey Hawke, David Janz, Przemyslaw Mazur, Daniele Reda, John-Mark Allen, Vinh-Dieu Lam, Alex Bewley, and Amar Shah. Learning to drive in a day. In ICRA , 2019.
[47] Tarasha Khurana, Peiyun Hu, Achal Dave, Jason Ziglar, David Held, and Deva Ramanan. Differentiable raycasting for self-supervised occupancy forecasting. In ECCV , 2022.
[48] Dahun Kim, Sanghyun Woo, Joon-Young Lee, and In So Kweon. Video panoptic segmentation. In CVPR , 2020.
[49] Jinkyu Kim, Reza Mahjourian, Scott Ettinger, Mayank Bansal, Brandyn White, Ben Sapp, and Dragomir Anguelov. Stopnet: Scalable trajectory and occupancy prediction for urban autonomous driving. arXiv preprint arXiv:2206.00991 , 2022.
[50] Alexander Kirillov, Kaiming He, Ross Girshick, Carsten Rother, and Piotr Dollár. Panoptic segmentation. In CVPR , 2019.
[51] Youngwan Lee, Joong-won Hwang, Sangrok Lee, Yuseok Bae, and Jongyoul Park. An energy and gpu-computation efficient backbone network for real-time object detection. In CVPR Workshop , 2019.
[52] Feng Li, Hao Zhang, Shilong Liu, Lei Zhang, Lionel M Ni, and Heung-Yeung Shum. Mask dino: Towards a unified transformer-based framework for object detection and segmentation. In CVPR , 2023.
[53] Lingyun Luke Li, Bin Yang, Ming Liang, Wenyuan Zeng, Mengye Ren, Sean Segal, and Raquel Urtasun. End-to-end contextual perception and prediction with interaction transformer. In IROS , 2020.
[54] Yanwei Li, Yilun Chen, Xiaojuan Qi, Zeming Li, Jian Sun, and Jiaya Jia. Unifying voxel-based representation with transformer for 3d object detection. In NeurIPS , 2022.
[55] Zhiqi Li, Wenhai Wang, Hongyang Li, Enze Xie, Chonghao Sima, Tong Lu, Qiao Yu, and Jifeng Dai. BEVFormer: Learning bird’s-eye-view representation from multi-camera images via spatiotemporal transformers. In ECCV , 2022.
[56] Zhiqi Li, Wenhai Wang, Enze Xie, Zhiding Yu, Anima Anandkumar, Jose M Alvarez, Ping Luo, and Tong Lu. Panoptic segformer: Delving deeper into panoptic segmentation with transformers. In CVPR , 2022.
[57] Ming Liang, Bin Yang, Wenyuan Zeng, Yun Chen, Rui Hu, Sergio Casas, and Raquel Urtasun. Pnpnet: End-to-end perception and prediction with tracking in the loop. In CVPR , 2020.
[58] Tingting Liang, Hongwei Xie, Kaicheng Yu, Zhongyu Xia, Zhiwei Lin, Yongtao Wang, Tao Tang, Bing Wang, and Zhi Tang. BEVFusion: A simple and robust lidar-camera fusion framework. In NeurIPS , 2022.
[59] Xiaodan Liang, Tairui Wang, Luona Yang, and Eric Xing. Cirl: Controllable imitative reinforcement learning for vision-based self-driving. In ECCV , 2018.
[60] Xiwen Liang, Yangxin Wu, Jianhua Han, Hang Xu, Chunjing Xu, and Xiaodan Liang. Effective adaptation in multi-task co-training for unified autonomous driving. In NeurIPS , 2022.
[61] Tsung-Yi Lin, Priya Goyal, Ross Girshick, Kaiming He, and Piotr Dollár. Focal loss for dense object detection. In ICCV , 2017.
[62] Jerry Liu, Wenyuan Zeng, Raquel Urtasun, and Ersin Yumer. Deep structured reactive planning. In ICRA , 2021.
[63] Yicheng Liu, Jinghuai Zhang, Liangji Fang, Qinhong Jiang, and Bolei Zhou. Multimodal motion prediction with stacked transformers. In CVPR , 2021.
[64] Zhijian Liu, Haotian Tang, Alexander Amini, Xingyu Yang, Huizi Mao, Daniela Rus, and Song Han. BEVFusion: Multi-task multi-sensor fusion with unified bird’s-eye view representation. In ICRA , 2023.
[65] Ilya Loshchilov and Frank Hutter. Decoupled weight decay regularization. In ICLR , 2018.
[66] Wenjie Luo, Bin Yang, and Raquel Urtasun. Fast and furious: Real time end-to-end 3d detection, tracking and motion forecasting with a single convolutional net. In CVPR , 2018.
[67] Fausto Milletari, Nassir Navab, and Seyed-Ahmad Ahmadi. V-net: Fully convolutional neural networks for volumetric medical image segmentation. In 3DV , 2016.
[68] Mobileye. Mobileye under the hood. https://www.mobileye.com/ces-2022/ , 2022.
[69] Nigamaa Nayakanti, Rami Al-Rfou, Aurick Zhou, Kratarth Goel, Khaled S Refaat, and Benjamin Sapp. Wayformer: Motion forecasting via simple & efficient attention networks. arXiv preprint arXiv:2207.05844 , 2022.
[70] Jiquan Ngiam, Benjamin Caine, Vijay Vasudevan, Zhengdong Zhang, Hao-Tien Lewis Chiang, Jeffrey Ling, Rebecca Roelofs, Alex Bewley, Chenxi Liu, Ashish Venugopal, David Weiss, Ben Sapp, Zhifeng Chen, and Jonathon Shlens. Scene transformer: A unified multi-task model for behavior prediction and planning. In ICLR , 2022.
[71] Nvidia. NVIDIA DRIVE End-to-End Solutions for Autonomous Vehicles. https://developer.nvidia.com/drive , 2022.
[72] Bowen Pan, Jiankai Sun, Ho Yin Tiga Leung, Alex Andonian, and Bolei Zhou. Cross-view semantic segmentation for sensing surroundings. IEEE RA-L , 2020.
[73] Dennis Park, Rares Ambrus, Vitor Guizilini, Jie Li, and Adrien Gaidon. Is pseudo-lidar needed for monocular 3d object detection? In ICCV , 2021.
[74] Jinhyung Park, Chenfeng Xu, Shijia Yang, Kurt Keutzer, Kris Kitani, Masayoshi Tomizuka, and Wei Zhan. Time will tell: New outlooks and a baseline for temporal multi-view 3d object detection. arXiv preprint arXiv:2210.02443 , 2022.
[75] Neehar Peri, Jonathon Luiten, Mengtian Li, Aljoša Ošep, Laura Leal-Taixé, and Deva Ramanan. Forecasting from lidar via future object detection. In CVPR , 2022.
[76] Jonah Philion and Sanja Fidler. Lift, splat, shoot: Encoding images from arbitrary camera rigs by implicitly unprojecting to 3d. In ECCV , 2020.
[77] Dean A Pomerleau. Alvinn: An autonomous land vehicle in a neural network. In NeurIPS , 1988.
[78] Aditya Prakash, Kashyap Chitta, and Andreas Geiger. Multi-modal fusion transformer for end-to-end autonomous driving. In CVPR , 2021.
[79] Scott Reed, Konrad Zolna, Emilio Parisotto, Sergio Gomez Colmenarejo, Alexander Novikov, Gabriel Barth-Maron, Mai Gimenez, Yury Sulsky, Jackie Kay, Jost Tobias Springenberg, Tom Eccles, Jake Bruce, Ali Razavi, Ashley Edwards, Nicolas Heess, Yutian Chen, Raia Hadsell, Oriol Vinyals, Mahyar Bordbar, and Nando de Freitas. A generalist agent. arXiv preprint arXiv:2205.06175 , 2022.
[80] Hamid Rezatofighi, Nathan Tsoi, JunYoung Gwak, Amir Sadeghian, Ian Reid, and Silvio Savarese. Generalized intersection over union: A metric and a loss for bounding box regression. In CVPR , 2019.
[81] Nicholas Rhinehart, Rowan McAllister, Kris Kitani, and Sergey Levine. PRECOG: Prediction conditioned on goals in visual multi-agent settings. In ICCV , 2019.
[82] Abbas Sadat, Sergio Casas, Mengye Ren, Xinyu Wu, Pranaab Dhawan, and Raquel Urtasun. Perceive, predict, and plan: Safe motion planning through interpretable semantic representations. In ECCV , 2020.
[83] Hao Shao, Letian Wang, Ruobing Chen, Hongsheng Li, and Yu Liu. Safety-enhanced autonomous driving using interpretable sensor fusion transformer. In CoRL , 2022.
[84] Shaoshuai Shi, Li Jiang, Dengxin Dai, and Bernt Schiele. Motion transformer with global intention localization and local movement refinement. In NeurIPS , 2022.
[85] Yining Shi, Jingyan Shen, Yifan Sun, Yunlong Wang, Jiaxin Li, Shiqi Sun, Kun Jiang, and Diange Yang. Srcn3d: Sparse r-cnn 3d surround-view camera object detection and tracking for autonomous driving. arXiv preprint arXiv:2206.14451 , 2022.
[86] Haoran Song, Wenchao Ding, Yuxuan Chen, Shaojie Shen, Michael Yu Wang, and Qifeng Chen. Pip: Planning-informed trajectory prediction for autonomous driving. In ECCV , 2020.
[87] Tesla. Tesla AI Day. https://www.youtube.com/watch?v=ODSJsviD_SU , 2022.
[88] Sebastian Thrun and Arno Bücken. Integrating grid-based and topological maps for mobile robot navigation. In AAAI , 1996.
[89] Marin Toromanoff, Emilie Wirbel, and Fabien Moutarde. End-to-end model-free reinforcement learning for urban driving using implicit affordances. In CVPR , 2020.
[90] Balakrishnan Varadarajan, Ahmed Hefny, Avikalp Srivastava, Khaled S Refaat, Nigamaa Nayakanti, Andre Cornman, Kan Chen, Bertrand Douillard, Chi Pang Lam, Dragomir Anguelov, and Benjamin Sapp. Multipath++: Efficient information fusion and trajectory aggregation for behavior prediction. arXiv preprint arXiv:2111.14973 , 2021.
[91] Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Łukasz Kaiser, and Illia Polosukhin. Attention is all you need. In NeurIPS , 2017.
[92] Peng Wang, An Yang, Rui Men, Junyang Lin, Shuai Bai, Zhikang Li, Jianxin Ma, Chang Zhou, Jingren Zhou, and Hongxia Yang. Ofa: Unifying architectures, tasks, and modalities through a simple sequence-to-sequence learning framework. In ICML , 2022.
[93] Qitai Wang, Yuntao Chen, Ziqi Pang, Naiyan Wang, and Zhaoxiang Zhang. Immortal tracker: Tracklet never dies. arXiv preprint arXiv:2111.13672 , 2021.
[94] Bob Wei, Mengye Ren, Wenyuan Zeng, Ming Liang, Bin Yang, and Raquel Urtasun. Perceive, attend, and drive: Learning spatial attention for safe self-driving. In ICRA , 2021.
[95] Penghao Wu, Li Chen, Hongyang Li, Xiaosong Jia, Junchi Yan, and Yu Qiao. Policy pre-training for autonomous driving via self-supervised geometric modeling. In ICLR , 2023.
[96] Pengxiang Wu, Siheng Chen, and Dimitris N Metaxas. Motionnet: Joint perception and motion prediction for autonomous driving based on bird’s eye view maps. In CVPR , 2020.
[97] Penghao Wu, Xiaosong Jia, Li Chen, Junchi Yan, Hongyang Li, and Yu Qiao. Trajectory-guided control prediction for end-to-end autonomous driving: A simple yet strong baseline. In NeurIPS , 2022.
[98] Jinrong Yang, En Yu, Zeming Li, Xiaoping Li, and Wenbing Tao. Quality matters: Embracing quality clues for robust 3d multi-object tracking. arXiv preprint arXiv:2208.10976 , 2022.
[99] Ye Yuan, Xinshuo Weng, Yanglan Ou, and Kris M Kitani. Agentformer: Agent-aware transformers for socio-temporal multi-agent forecasting. In ICCV , 2021.
[100] Fangao Zeng, Bin Dong, Tiancai Wang, Xiangyu Zhang, and Yichen Wei. Motr: End-to-end multiple-object tracking with transformer. In ECCV , 2021.
[101] Wenyuan Zeng, Wenjie Luo, Simon Suo, Abbas Sadat, Bin Yang, Sergio Casas, and Raquel Urtasun. End-to-end interpretable neural motion planner. In CVPR , 2019.
[102] Wenyuan Zeng, Shenlong Wang, Renjie Liao, Yun Chen, Bin Yang, and Raquel Urtasun. Dsdnet: Deep structured self-driving network. In ECCV , 2020.
[103] Jimuyang Zhang and Eshed Ohn-Bar. Learning by watching. In CVPR , 2021.
[104] Tianyuan Zhang, Xuanyao Chen, Yue Wang, Yilun Wang, and Hang Zhao. MUTR3D: A Multi-camera Tracking Framework via 3D-to-2D Queries. In CVPR Workshop , 2022.
[105] Yunpeng Zhang, Zheng Zhu, Wenzhao Zheng, Junjie Huang, Guan Huang, Jie Zhou, and Jiwen Lu. BEVerse: Unified perception and prediction in birds-eye-view for vision-centric autonomous driving. arXiv preprint arXiv:2205.09743 , 2022.
[106] Zhejun Zhang, Alexander Liniger, Dengxin Dai, Fisher Yu, and Luc Van Gool. End-to-end urban driving by imitating a reinforcement learning coach. In ICCV , 2021.
[107] Hang Zhao, Jiyang Gao, Tian Lan, Chen Sun, Benjamin Sapp, Balakrishnan Varadarajan, Yue Shen, Yi Shen, Yuning Chai, Cordelia Schmid, Congcong Li, and Dragomir Anguelov. TNT: Target-driven trajectory prediction. In CoRL , 2020.
[108] Jinguo Zhu, Xizhou Zhu, Wenhai Wang, Xiaohua Wang, Hongsheng Li, Xiaogang Wang, and Jifeng Dai. Uni-perceiver-moe: Learning sparse generalist models with conditional moes. In NeurIPS , 2022.
[109] Xizhou Zhu, Weijie Su, Lewei Lu, Bin Li, Xiaogang Wang, and Jifeng Dai. Deformable detr: Deformable transformers for end-to-end object detection. In ICLR , 2020.
Appendix A Task Definition
附录 A 任务定义
Detection and tracking.
Detection and tracking are two crucial perception tasks for autonomous driving, and we focus on representing them in the 3D space to facilitate downstream usage. 3D Detection is responsible for locating surrounding objects (coordinates, length, width, height, etc.) at each time stamp; tracking aims at finding the correspondences between different objects across time stamps and associating them temporally (i.e., assigning a consistent track ID for each agent). In the paper, we use multi-object tracking in some cases to denote the detection and tracking process. The final output is a series of associated 3D boxes in each frame, and their corresponding features are forwarded to the motion module. Additionally, note that we have one special query named ego-vehicle query for downstream tasks, which would not be included in the prediction-ground truth matching process and it regresses the location of ego-vehicle accordingly.
检测与跟踪。
检测与跟踪是自动驾驶两项关键感知任务,我们侧重在三维空间表示它们以便下游使用。三维检测负责在每一时刻定位周围物体(坐标、长宽高等);跟踪旨在跨时刻找到不同物体对应关系并做时序关联(即为每个智能体分配一致的 track ID)。文中有时用多目标跟踪统称检测与跟踪过程。最终输出为每帧关联的三维框序列及其对应特征。
Online mapping.
Map intuitively embodies the geometric and semantic information of the environment, and online mapping is to segment meaningful road elements with onboard sensor data (multi-view images in our case) as a substitute for offline annotated high-definition (HD) maps. In UniAD, we model the online map into four categories: lanes, drivable area, dividers and pedestrian crossings, and we segment them in bird’s-eye-view (BEV). Similar to , the map queries would be further utilized in the motion forecasting module to model the agent-map interaction.
在线建图。
地图直观承载环境的几何与语义信息;在线建图用车载传感器数据(本文为多视角图像)分割有意义的道路元素,以替代离线标注的高精(HD)地图。在 UniAD 中,我们将在线地图建模为四类:车道、可行驶区域、隔离带与人行横道,并在鸟瞰(BEV)中分割。类似 ,地图 query 将在运动预报模块中进一步用于建模智能体—地图交互。
Motion forecasting.
Bridging perception and planning, prediction plays an important role in the whole autonomous driving system to ensure final safety. Typically, motion forecasting is an independently developed module that predicts agents’ future trajectories with detected bounding boxes and HD maps. And the bounding boxes are ground truth annotations in most current motion datasets [27], which is not realistic in onboard scenarios. While in this paper, the motion forecasting module takes previously encoded sparse queries (i.e., and ) and dense BEV features as inputs, and forecasts plausible trajectories in future timesteps for each agent. Besides, to be compatible with our end-to-end and scene-centric scenarios, we predict trajectories as offset according to each agent’s current position. The agent features before the last decoding MLPs, which have encoded both the historical and future information will be sent to the occupancy module for scene-level future understanding. For the ego-vehicle query, it predicts future ego-motion as well (actually providing a coarse planning estimation), and the feature is employed by the planner to generate the ultimate goal.
运动预报。
连接感知与规划,预测在整个自动驾驶系统中对最终安全至关重要。通常运动预报是独立开发的模块,用检测到的边界框与 HD 地图预测智能体未来轨迹;且多数现有运动数据集 [27] 中边界框为真实标注,这在车载场景并不现实。本文中,运动预报模块以先前编码的稀疏 query(即 与 )与稠密 BEV 特征 为输入,为每个智能体预报未来 步中 条合理轨迹。此外,自车也参与交互以考虑其对场景的影响。
Occupancy prediction.
Occupancy grid map is a discretized BEV representation where each cell holds a belief indicating whether it is occupied, and the occupancy prediction task is designed to discover how the grid map changes in the future for timesteps with multiple agent dynamics. Complementary to motion forecasting which is conditioned on sparse agents, occupancy prediction is densely represented in the whole-scene level. To investigate how the scene evolves with sparse agent knowledge, our proposed occupancy module takes as inputs both the observed BEV feature and agent features . After the multi-step agent-scene interaction (detailedly described in Appendix E), the instance-level probability map is generated via matrix multiplication between occupancy feature and dense scene feature. To form whole-scene occupancy with agent identity preserved which is used for occupancy evaluation and downstream planning, we simply merge the instance-level probability at each timestep using pixel-wise argmax as in [8].
占据预测。
占据栅格图是离散 BEV 表示,每个格子保存是否被占据的信念;占据预测任务要发现栅格图在未来 步如何随多智能体动态变化。相对以稀疏智能体为条件的运动预报,占据预测在整场景级稠密表示。为考察场景如何随稀疏智能体知识演化,所提占据模块以观测 BEV 特征 与智能体特征 为输入。经多步智能体—场景交互(详见附录 E)后,输出保留身份的实例级占据。
Planning.
As an ultimate goal, the planning module takes all upstream results into consideration. Traditional planning methods in the industry often are rule-based, formulated by “if-else” state machines conditioned on various scenarios which are described with prior detection and prediction results. In our learning-based model, we take the upstream ego-vehicle query, and the dense BEV feature as input, and predict one trajectory for total timesteps. Then, the trajectory is optimized with the upstream predicted future occupancy to avoid collision and ensure final safety.
规划。
作为终极目标,规划模块综合全部上游结果。工业界传统规划多为基于规则,由「if-else」状态机构成,条件来自先验检测与预测结果描述的各类场景。在我们基于学习的模型中,以上游自车 query 与稠密 BEV 特征 为输入,预测总长 步的一条轨迹 。随后用上游预测的未来占据 优化 ,以避免碰撞并保证最终安全。
Appendix B The Necessity of Each Task
附录 B 各任务的必要性
In terms of perception, tracking in the loop as does in PnPNet [57] and ViP3D [30] is proven to complement spatial-temporal features and provide history tracks for occluded agents, refraining from catastrophic decisions for downstream planning. With the aid of HD maps [101, 82, 57, 30] and motion forecasting, planning becomes more accurate toward higher-level intelligence. However, such information is expensive to construct and prone to be outdated, raising the demand for online mapping without HD maps. As for prediction, motion forecasting [10, 42, 41, 29, 107] generates long-term future behaviors and preserves agent identity in form of sparse waypoint outputs. Nonetheless, there exists the challenge to integrate non-differentiable box representation into subsequent planning module [30, 57]. Some recent literature investigates another type of prediction task named occupancy [88] prediction to assist end-to-end planning, in form of cost maps. However, the lack of agent identity and dynamics in occupancy makes it impractical to model social interactions for safe planning. The large computational consumption of modeling multi-step dense features also leads to a much shorter temporal horizon compared to motion forecasting. Therefore, to benefit from the two complementary types of prediction tasks for safe planning, we incorporate both agent-centric motion and whole-scene occupancy in UniAD.
在感知方面,如 PnPNet [57] 与 ViP3D [30] 那样把跟踪纳入闭环,已被证明可互补时空特征,并为被遮挡智能体提供历史轨迹,避免下游规划灾难性决策。借助 HD 地图 [101, 82, 57, 30] 与运动预报,规划可更准确、迈向更高智能。但这类信息构建昂贵且易过时,因而需要无 HD 地图的在线建图。在预测方面,运动预报 [10, 42, 41, 29, 107] 生成长期未来行为,并以稀疏航点形式保留智能体身份。然而,它在遮挡与形状不规则物体上仍有局限。占据预测以稠密场景级表示互补,便于碰撞检查。规划作为终极目标,需要这些上游任务的协同支持,而非孤立优化。
Appendix C Related Work
附录 C 相关工作
C.1 Joint perception and prediction
C.1 联合感知与预测
Joint learning of perception and prediction is proposed to avoid the cascading error in traditional modular-independence pipelines. Similar to the motion forecasting task alone, it usually has two types of output representations: agent-level bounding boxes and scene-level occupancy grid maps. Pioneering work FaF [66] predicts boxes in the future and aggregates past information to produce tracklets. IntentNet [10] extends it to reason about intentions and [25, 28] further predict future states in a refinement fashion. Some exploit detection first and utilize agent features in the second prediction stage [9, 53, 75]. Noticing that history information is ignored, PnPNet [57] enriches it by estimating tracking association scores to avert the non-differentiable optimization process as adopted by the tracking-by-detection paradigm [54, 85, 64, 98]. Yet, all these methods rely on non-maximum suppression (NMS) in detection which still leads to information loss. ViP3D [30] which is closely related to our work, employs agent queries in [104] to forecast, taking HD map as another input. We follow the philosophy of [104, 30] in agent track queries, but also develop non-linear optimization on target trajectories to alleviate the potential inaccurate perception problem. Moreover, we introduce an ego-vehicle query for better capturing the ego behaviors in the dynamic environment, and incorporate online mapping to prevent the localization risk or high construction cost with HD map.
联合学习感知与预测旨在避免传统模块独立管线中的级联误差。与单独的运动预报类似,其输出表示通常有两类:智能体级边界框与场景级占据栅格图。开创性工作 FaF [66] 预测未来框并聚合过去信息以产生轨迹片段。IntentNet [10] 扩展到意图推理;[25, 28] 以 refinement 方式进一步预测未来状态。一些工作先做检测,再在第二阶段预测中利用智能体特征 [9, 53, 75]。注意到历史信息被忽略后,PnPNet [57] 通过估计轨迹将其丰富。ViP3D [30] 等继续推进视觉端到端设定下的联合感知—预测。
The alternative representation, namely the occupancy grid map, discretizes the BEV map into grid cells which holds a belief indicating if it is occupied. Wu et al. [96] estimate a dense motion field, while it could not capture multimodal behaviors. Fishing Net [33] also predicts deterministic future BEV semantic segmentation with multiple sensors. To address this, P3 [82] proposes non-parametric distribution of future semantic occupancy and FIERY [35] devises the first paradigm for multi-view cameras. A few methods improve the performance of FIERY with more sophisticated uncertainty modeling [38, 1, 105]. Notably, this representation could easily extend to motion planning for collision avoidance [82, 11, 38], while it loses the agent identity characteristic and takes a heavy burden to computation which may constrain the prediction horizon. In contrast, we leverage agent-level information for occupancy prediction and ensure accurate and safe planning by unifying these two modes.
另一表示——占据栅格图——把 BEV 图离散为网格,每格保存是否占据的信念。Wu et al. [96] 估计稠密运动场,但难以捕获多模态行为。Fishing Net [33] 也用多传感器预测确定性未来 BEV 语义分割。为此,P3 [82] 提出未来语义占据的非参数分布,FIERY [35] 设计了首个面向多视角相机的范式。若干方法以更精细的不确定性建模改进 FIERY [38, 1, 105]。值得注意的是,该表示易于扩展到运动规划以做碰撞避免。
C.2 Joint prediction and planning
C.2 联合预测与规划
PRECOG [81] proposes a recurrent model that conditions forecasting on the goal position of the ego vehicle, while PiP [86] generates agents’ motion considering complete presumed planning trajectories. However, producing a rough future trajectory is still challenging in the real world, toward which [62] presents a deep structured model to derive both prediction and planning from the same set of learnable costs. [40, 39] couple the prediction model with classic optimization methods. Meanwhile, some motion forecasting methods implicitly include the planning task by producing their future trajectories simultaneously [12, 70, 45]. Similarly, we encode possible behaviors of the ego vehicle in the scene-centric motion forecasting module, but the interpretable occupancy map is utilized to further optimize the plan to stay safe.
PRECOG [81] 提出以自车目标位置为条件的循环预报模型;PiP [86] 则在完整假定规划轨迹条件下生成智能体运动。然而在真实世界产生粗略未来轨迹仍具挑战,为此 [62] 提出深度结构化模型,从同一组可学习代价同时导出预测与规划。[40, 39] 将预测模型与经典优化耦合。同时,一些运动预报方法通过同时产出自车未来轨迹隐式包含规划任务 [12, 70, 45]。类似地,我们在运动模块中编码自车可能行为。
C.3 End-to-end motion planning
C.3 端到端运动规划
End-to-end motion planning has been an active research domain since Pomerleau [77] uses a single neural network that directly predicts control signals. Subsequent studies make great advances especially in closed-loop simulation with deeper networks [4], multi-modal inputs [2, 21, 78], multi-task learning [97, 20], reinforcement learning [59, 46, 89, 13, 14] and distillation from certain privilege knowledge [16, 106, 103]. However, for such methods of directly generating control outputs from sensor data, the transfer from the synthetic environment to realistic application remains a problem considering their robustness and safety assurance [22, 38]. Thus researchers aim at explicitly designing the intermediate representations of the network to prompt safety, where predicting how the scene evolves attracts broad interest. Some works [19, 83, 34] jointly decode planning and BEV semantic predictions to enhance interpretability, while PLOP [5] adopts a polynomial formulation to provide smooth planning results for both ego vehicle and neighbors. Cui et al. [24] introduce a contingency planner with diverse sets of future predictions and LAV [15] trains the planner with all vehicles’ trajectories to provide richer training data. NMP [101] and its variant [94] estimate a cost volume to select the plan with minimal cost besides deterministic future perception. Though they risk producing inconsistent results between two modules, the cost map design is intuitive to recover the final plan in complex scenarios. Inspired by [101], most recent works [102, 82, 11, 38, 37] propose models that construct costs with both learned occupancy prediction and hand-crafted penalties. However, their performances heavily rely on the tailored cost based on human experience and the distribution from where trajectories are sampled [47]. Contrary to these approaches, we leverage the ego-motion information without sophisticated cost design and present the first attempt that incorporates the tracking module along with two genres of prediction representations simultaneously in an end-to-end model.
自 Pomerleau [77] 用单一神经网络直接预测控制信号以来,端到端运动规划一直是活跃研究方向。后续研究在闭环仿真中以更深网络 [4]、多模态输入 [2, 21, 78]、多任务学习 [97, 20]、强化学习 [59, 46, 89, 13, 14] 以及从特权知识蒸馏 [16, 106, 103] 取得重要进展。然而,对此类从传感器数据直接生成控制输出的方法,从合成环境迁移到真实应用时,稳健性与安全保障仍成问题 [22, 38]。因此研究者转向显式设计中间任务,以提升可解释性与安全性;UniAD 沿这一路线,用规划导向的全栈任务协同组织系统。
Appendix D Notations
附录 D 符号
We provide a lookup table of notations and their shapes mentioned in this paper in Table 11 for reference.
我们在表 11 中提供本文出现的符号及其形状的查阅表,供参考。
| Notation | Shape & Params. | Description |
|---|---|---|
| 900 | number of initial object queries | |
| 256 | embed dimensions | |
| BEV feature encoded by a multi-view framework | ||
| 6 | number of transformer decoder layers for TrackFormer | |
| 6 | number of transformer decoder layers for MapFormer | |
| 4 | number of mask decoder layers for MapFormer | |
| 3 | number of transformer decoder layers for MotionFormer | |
| 5 | number of transformer decoder layers for OccFormer | |
| 3 | number of transformer decoder layers for Planner | |
| dynamic | number of agents from TrackFormer | |
| 300 | number of map queries from MapFormer | |
| agent features from TrackFormer | ||
| agent positions from TrackFormer | ||
| map features from MapFormer | ||
| 6 | number of forecasting modality in MotionFormer | |
| ground truth for one agent’s motion forecasting | ||
| prediction of motion forecasting | ||
| 12 | length of prediction timestamps in MotionFormer | |
| query position in MotionFormer | ||
| query context in MotionFormer | ||
| motion query after agent-agent interaction in MotionFormer | ||
| motion query after agent-map interaction in MotionFormer | ||
| motion query after agent-goal point interaction in MotionFormer | ||
| - | index of decoder layer | |
| - | sinusoidal position encoding function | |
| scene-level anchor position in MotionFormer | ||
| agent-level anchor position in MotionFormer | ||
| - | kinematic cost function set | |
| 5 | length of prediction timestamps in OccFormer | |
| agent feature input | ||
| future state output | ||
| motion query (max-pooled on modality level) from the last layer of MotionFormer | ||
| downscaled dense feature | ||
| decoded dense feature after convolutional decoder | ||
| agent-aware dense feature after pixel-agent interaction | ||
| instance-level probability map | ||
| classical instance-agnostic occupancy map merged from for planning | ||
| attention mask for pixel-agent interaction | ||
| mask feature | ||
| occupancy feature | ||
| 6 | length of planning timestamps in Planner | |
| planned trajectory before the optimization with occupancy prediction | ||
| ultimate plan output | ||
| - | hyperparameters in cost functions, target functions, etc. |
Table 11: Lookup table of notations and hyperparameters in the paper. The superscript in certain notations denotes the block of OccFormer, and is omitted in descriptions for simplicity.
| 符号 | 形状与参数 | 说明 |
|---|---|---|
| 900 | 初始目标 query 数量 | |
| 256 | 嵌入维 | |
| 多视角框架编码的 BEV 特征 | ||
| 6 | TrackFormer 的 Transformer 解码器层数 | |
| 6 | MapFormer 的 Transformer 解码器层数 | |
| 4 | MapFormer 的掩码解码器层数 | |
| 3 | MotionFormer 的 Transformer 解码器层数 | |
| 5 | OccFormer 的 Transformer 解码器层数 | |
| 3 | Planner 的 Transformer 解码器层数 | |
| 动态 | TrackFormer 得到的智能体数 | |
| 300 | 地图 query 数量 from MapFormer | |
| agent features from TrackFormer | ||
| agent positions from TrackFormer | ||
| map features from MapFormer | ||
| 6 | number of forecasting modality in MotionFormer | |
| ground truth for one agent’s motion forecasting | ||
| prediction of motion forecasting | ||
| 12 | length of prediction timestamps in MotionFormer | |
| query position in MotionFormer | ||
| query context in MotionFormer | ||
| motion query after agent-agent interaction in MotionFormer | ||
| motion query after agent-map interaction in MotionFormer | ||
| motion query after agent-goal point interaction in MotionFormer | ||
| - | index of decoder layer | |
| - | sinusoidal position encoding function | |
| scene-level anchor position in MotionFormer | ||
| agent-level anchor position in MotionFormer | ||
| - | kinematic cost function set | |
| 5 | length of prediction timestamps in OccFormer | |
| agent feature input | ||
| future state output | ||
| motion query (max-pooled on modality level) from the last layer of MotionFormer | ||
| downscaled dense feature | ||
| decoded dense feature after convolutional decoder | ||
| agent-aware dense feature after pixel-agent interaction | ||
| instance-level probability map | ||
| classical instance-agnostic occupancy map merged from for planning | ||
| attention mask for pixel-agent interaction | ||
| mask feature | ||
| occupancy feature | ||
| 6 | length of planning timestamps in Planner | |
| planned trajectory before the optimization with occupancy prediction | ||
| ultimate plan output | ||
| - | hyperparameters in cost functions, target functions, etc. |
Table 11: Lookup table of notations and hyperparameters in the paper. The superscript in certain notations denotes the block of OccFormer, and is omitted in descriptions for simplicity.
Appendix E Implementation Details
附录 E 实现细节
E.1 Detection and Tracking
E.1 检测与跟踪
We inherit most of the detection designs from BEVFormer [55] which takes a BEV encoder to transform image features into BEV feature and adopts a Deformable DETR head [109] to perform detection on . To further conduct end-to-end tracking without heavy post association, we introduce another group of queries named track queries as in MOTR [100] which continuously tracks previously observed instances according to its assigned track ID. We introduce the tracking process in detail below.
我们大体继承 BEVFormer [55] 的检测设计:用 BEV 编码器把图像特征变为 BEV 特征 ,再用 Deformable DETR 头 [109] 在 上做检测。为进一步做无需繁重后关联的端到端跟踪,我们引入另一组称为 track query 的 query(如 MOTR [100]),按其分配的 track ID 持续跟踪先前观测到的实例。下文详述跟踪过程。
Training stage: At the beginning (i.e., first frame) of each training sequence, all queries are considered detection queries and predict all newborn objects, which is actually the same as BEVFormer. Detection queries are matched to the ground truth by the Hungarian algorithm [8]. They will be stored and updated via the query interaction module (QIM) for the next timestamp serving as track queries following MOTR [100]. In the next timestamp, track queries will be directly matched with a part of ground-truth objects according to the corresponding track ID, and detection queries will be matched with the remaining ground-truth objects (newborn objects). To stabilize training, we adopt the 3D IoU metric to filter the matched queries. Only those predictions having the 3D IoU with ground-truth boxes larger than a certain threshold (0.5 in practice) will be stored and updated.
训练阶段:每个训练序列开始(即第一帧)时,全部 query 视为 detection query,预测所有新生目标,实际与 BEVFormer 相同。Detection query 用匈牙利算法 [8] 与真实目标匹配,再经 query 交互模块(QIM)存储并更新,供下一时间戳作为 track query,遵循 MOTR [100]。下一时间戳中,track query 按对应 track ID 直接与部分真实目标匹配,detection query 与剩余真实目标(新生目标)匹配。为稳定训练,我们采用适当的匹配与更新策略。
Inference stage: Different from the training stage, each frame of a sequence is sent to the network sequentially, meaning that track queries could exist for a longer horizon than the training time. Another difference emerging in the inference stage is about query updating, that we use classification scores to filter the queries (0.4 for detection queries and 0.35 for track queries in practice) instead of the 3D IoU metric since the ground truth is not available. Besides, to avoid the interruption of tracklets caused by short-time occlusion, we use a lifecycle mechanism for the tracklets in the inference stage. Specifically, for each track query, it will be considered to disappear completely and be removed only when its corresponding classification score is smaller than 0.35 for a continuous period (2 in practice).
推理阶段:与训练不同,序列每帧顺序送入网络,意味着 track query 可比训练时存在更长时域。推理阶段另一差异在于 query 更新:因无真实标注,我们用分类分数过滤 query(实践中 detection query 阈值 0.4、track query 0.35),而非三维 IoU。此外,为避免短时遮挡导致轨迹中断,推理阶段对轨迹采用生命周期机制:对每个 track query,仅当其分类分数连续一段时间(实践中 2)低于 0.35 时,才视为完全消失并移除。
E.2 Online Mapping
E.2 在线建图
Following [56], we decompose the map query set into thing queries and stuff queries. The thing queries model instance-wise map elements (i.e., lanes, boundaries, and pedestrian crossings) and are matched with ground truth via bipartite matching, while the stuff query is only in charge of semantic elements (i.e., drivable area) and is processed with a class-fixed assignment. We set the total number of thing queries to 300 and only 1 stuff query for the drivable area. Also, we stack 6 location decoder layers and 4 mask decoder layers (we follow the structure of those layers as in [56]). We empirically choose thing queries after the location decoder as our map queries for downstream tasks.
遵循 [56],我们将地图 query 集合分解为 thing query 与 stuff query。Thing query 建模实例级地图元素(车道、边界与人行横道),经二分图匹配与真实目标配对;stuff query 仅负责语义元素(可行驶区域),采用类别固定分配。Thing query 总数设为 300,可行驶区域仅 1 个 stuff query。我们堆叠 6 个位置解码器层与 4 个掩码解码器层(层结构遵循 [56])。经验上,取位置解码器之后的 thing query 作为下游任务的地图 query 。
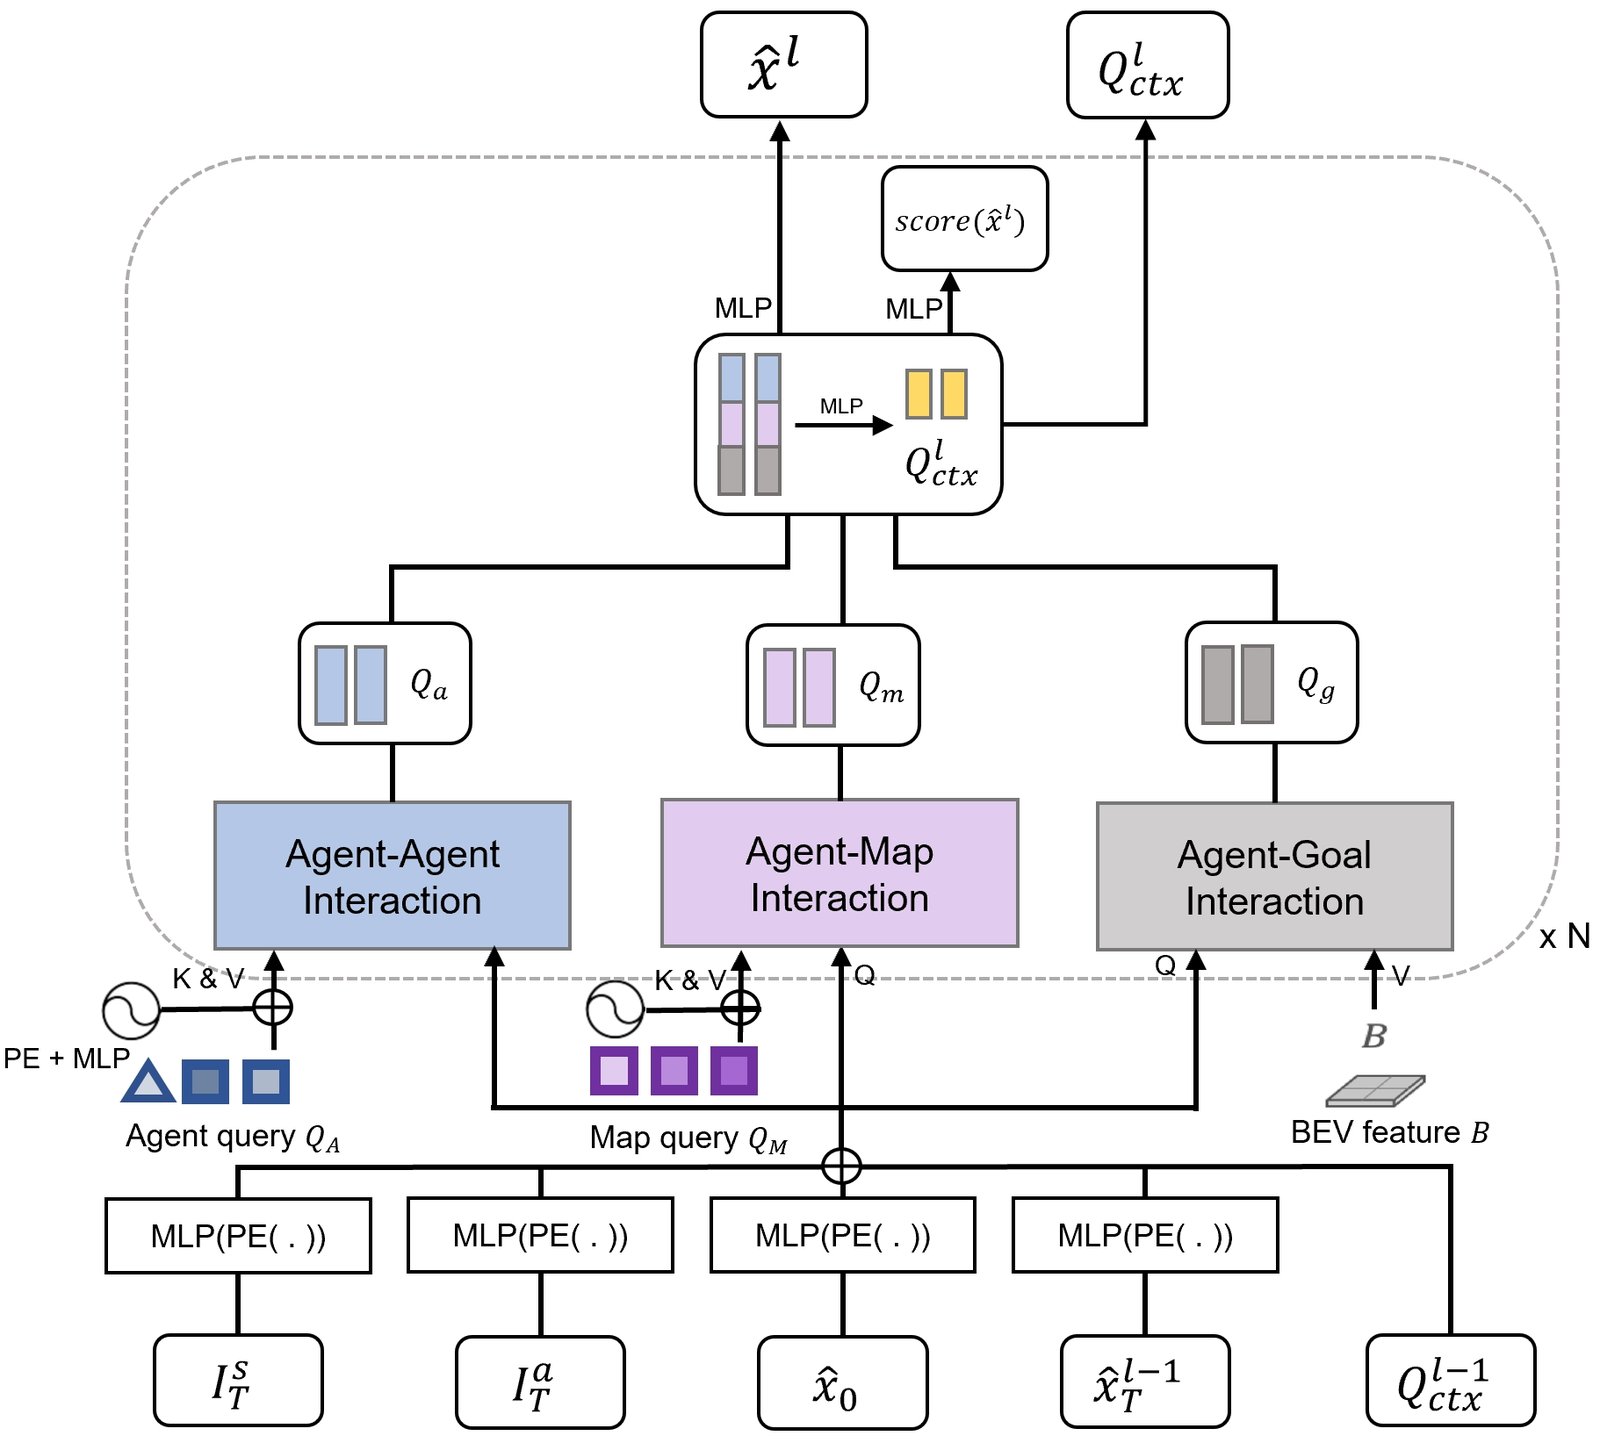
Figure 4: MotionFormer. It consists of stacked agent-agent, agent-map, and agent-goal interaction transformers. The agent-agent, and agent-map interaction modules are built with standard transformer decoder layers. The agent-goal interaction module is constructed upon the deformable cross-attention module [109]. : the end point of scene-level anchor, : the end point of clustered agent-level anchor, : the agent’s current position, : the predicted goal point from the previous layer, : query context from the previous layer.
图 4:MotionFormer。由 层堆叠的智能体—智能体、智能体—地图与智能体—目标交互 Transformer 组成。智能体—智能体与智能体—地图交互模块基于标准 Transformer 解码器层;智能体—目标交互模块基于可变形交叉注意力 [109]。:场景级锚点终点,:聚类得到的智能体级锚点终点,:智能体当前位置,:上一层预测目标点,:上一层 query 上下文。
Figure 5: Illustration of agent-goal interaction Module. The BEV visual feature is sampled near each agent’s goal points with deformable cross-attention.
图 5:智能体—目标交互模块示意。用可变形交叉注意力在每个智能体目标点附近采样 BEV 视觉特征。
E.3 Motion Forecasting
E.3 运动预报
To better illustrate the details, we provide a diagram as shown in Fig. 4. Our MotionFormer takes , , , to embed query position, and takes as query context. Specifically, the anchors are clustered among training data of all agents by the k-means algorithm, and we set which is compatible with our output modalities. To embed the scene-level prior, the anchor is rotated and translated into the global coordinate frame according to each agent’s current location and heading angle, which is denoted as , as shown in Eq. 12,
为更好说明细节,我们提供图 4 所示示意。MotionFormer 取 、、、 嵌入 query 位置,并以 为 query 上下文。具体地,锚点对训练数据中全部智能体用 k-means 聚类,设 以匹配输出模态。为嵌入场景级先验,按每个智能体当前位置与航向角将锚点 旋转平移到全局坐标系,记为 ,如式 12:
where is the index of the agent, and it is omitted later for brevity. To facilitate the coarse-to-fine paradigm, we also adopt the goal point predicted from the previous layer . In the meantime, the agent’s current position is broadcast across the modality, denoted as . Then, MLPs and sinusoidal positional embeddings are applied for each of the prior positional knowledge and we summarize them as the query position , which is of the same shape as the query context . and together build up our motion query. We set to 256 throughout MotionFormer.
其中 为智能体索引,后文为简洁省略。为促进由粗到细范式,我们也采用上一层预测的目标点 。同时,智能体当前位置在模态维广播,记为 。然后对各先验位置知识施加 MLP 与正弦位置嵌入,汇总为 query 位置 ,与 query 上下文 同形。 与 共同构成运动 query。整个 MotionFormer 中 设为 256。
As shown in Fig. 4, our MotionFormer consists of three major transformer blocks, i.e., agent-agent, agent-map and agent-goal interaction modules. The agent-agent, agent-map interaction modules are built with standard transformer decoder layers, which are composed of a multi-head self-attention (MHSA) layer and a multi-head cross-attention (MHCA) layer, a feed-forward network (FFN) and several residual and normalization layers in between [8]. Apart from the agent queries and map queries , we also add the positional embeddings to those queries with sinusoidal positional embedding followed by MLP layers. The agent-goal interaction module is built upon deformable cross-attention module [109], where the goal point from the previously predicted trajectory () is adopted as the reference point, as shown in Fig. 5. Specifically, we set the number of sampled points to 4 per trajectory, and 6 trajectories per agent as we mention above. The output features of each interaction module are concatenated and projected with MLP layers to dimension . Then, we use Gaussian Mixture Model to build each agent’s trajectories, where . We set the prediction time horizon to 12 (6 seconds) in UniAD. Note that we only take the first two of the last dimension (i.e., and ) as final output trajectories. Besides, the scores of each modality are also predicted (). We stack the overall modules for times, and is set to 3 in practice.
如图 4,MotionFormer 含三大 Transformer 块:智能体—智能体、智能体—地图与智能体—目标交互模块。前两者基于标准 Transformer 解码器层,由多头自注意力(MHSA)、多头交叉注意力(MHCA)、前馈网络(FFN)及其间残差与归一化层组成 [8]。除智能体 query 与地图 query 外,还用正弦位置嵌入后接 MLP 为这些 query 加入位置嵌入。智能体—目标交互模块基于可变形交叉注意力 [109],以上一层预测轨迹的目标点()为参考点,见图 5。具体地,每条轨迹采样 4 个点,每智能体 6 条轨迹。各交互模块输出特征拼接后经 MLP 投影到 。再用高斯混合模型构建每个智能体的轨迹,其中 。UniAD 中预测时域 设为 12(6 秒)。注意我们只取最后一维的前两维(即 与 )作为最终输出轨迹。此外还预测各模态分数()。整体模块堆叠 次,实践中 。
E.4 Occupancy Prediction
E.4 占据预测
Given the BEV feature from upstream modules, we first downsample it by /4 with convolutional layers for efficient multi-step prediction, then pass it to our proposed OccFormer. OccFormer is composed of sequential blocks shown in Fig. 6, where is the temporal horizon (including current and future frames) and each block is responsible for generating occupancy of one specific frame. Different from prior works which are short of agent-level knowledge, our proposed method incorporates both dense scene features and sparse agent features when unrolling the future representations. The dense scene feature is from the output of the last block (or the observed feature for current frame) and it’s further downscaled (/8) by a convolution layer to reduce computation for pixel-agent interaction. The sparse agent feature is derived from the concatenation of track query , agent positions , and motion query , and it is then passed to a temporal-specific MLP for temporal sensitivity. We conduct pixel-level self-attention to model the long-term dependency required in some rapidly changing scenes, then perform scene-agent incorporation by attending each pixel of the scene to corresponding agents. To enhance the location alignment between agents and pixels, we restrict the cross-attention with an attention mask which is generated by a matrix multiplication between mask feature and downscaled scene feature, where the mask feature is produced by encoding agent feature with an MLP. We then upsample the attended dense feature to the same resolution as input (/4) and add it with as a residual connection for stability. The resulting feature is both sent to the next block and a convolutional decoder for predicting occupancy at the original BEV resolution (/1). We reuse the mask feature and pass it to another MLP to form occupancy feature, and the instance-level occupancy is therefore generated by a matrix multiplication between occupancy feature and decoded dense feature (/1). Note that the MLP layer for mask feature, the MLP layer for occupancy feature, and the convolutional decoder are shared across all blocks while other components are independent in each block. Dimensions of all dense features and agent features are 256 in OccFormer.
给定上游 BEV 特征,我们先用卷积层将其下采样 /4 以便高效多步预测,再送入所提 OccFormer。OccFormer 由 个顺序块组成(图 6),其中 为时域(含当前与未来帧),每块负责生成某一帧的占据。与缺乏智能体级知识的先前工作不同,我们在展开未来表示时同时纳入稠密场景特征与稀疏智能体特征。稠密场景特征来自上一块输出(当前帧则为观测特征),再经卷积下采样(/8)以降低像素—智能体交互计算。稀疏智能体特征由 track query 、智能体位置 与运动 query 拼接,再经时步专用 MLP 以获得时间敏感性。我们做像素级自注意力以建模快速变化场景所需的长期依赖,再让场景每个像素关注对应智能体以融合场景—智能体。为增强智能体与像素的位置对齐,用掩码特征与下采样场景特征矩阵相乘得到的注意力掩码约束交叉注意力;掩码特征由 MLP 编码智能体特征得到。再将注意力后的稠密特征上采样到与输入 相同分辨率(/4),并与 残差相加以求稳定。所得 既送入下一块,也送入卷积解码器,在原始 BEV 分辨率(/1)预测占据。我们复用掩码特征并经另一 MLP 形成占据特征,实例级占据即由占据特征与解码稠密特征 (/1)的矩阵乘法得到。注意掩码特征 MLP、占据特征 MLP 与卷积解码器在全部 块间共享,其余组件各块独立。OccFormer 中全部稠密特征与智能体特征维均为 256。
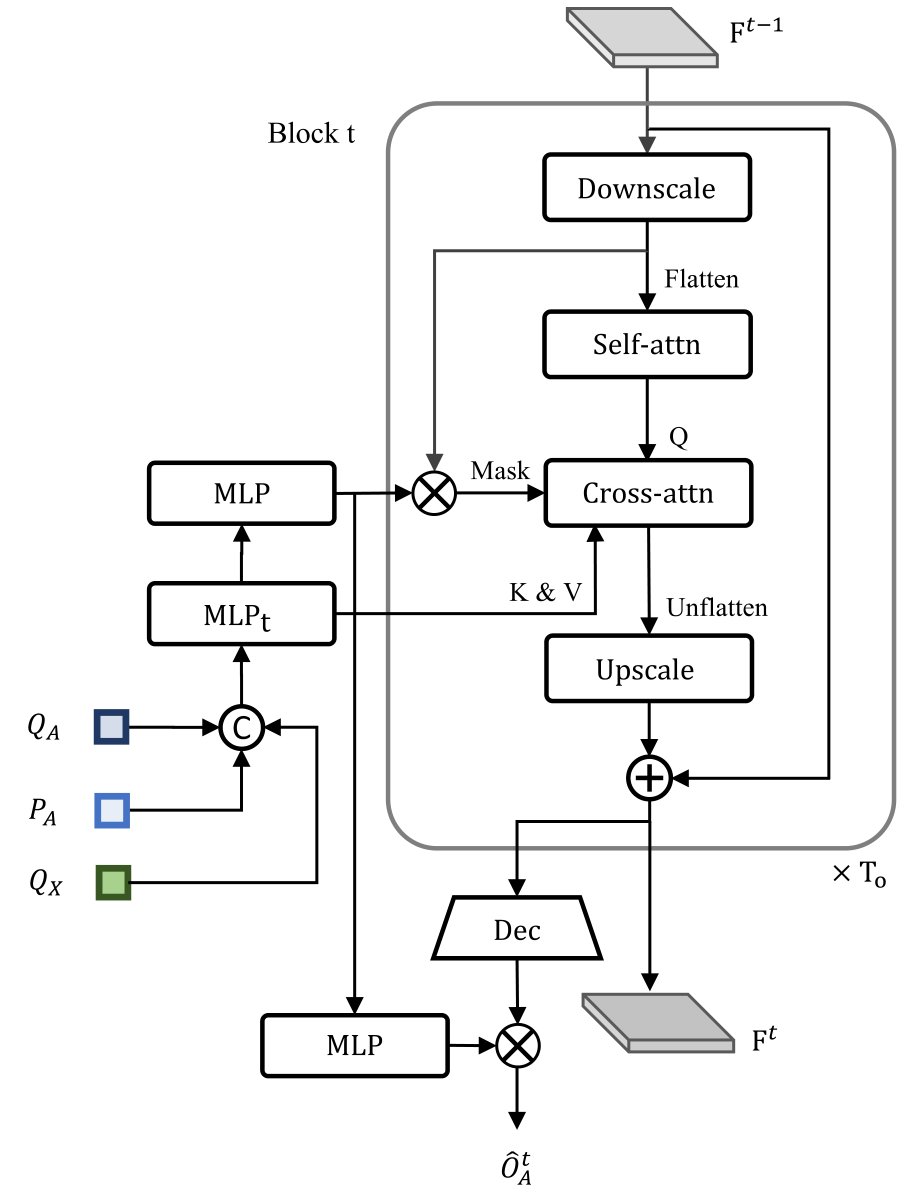
Figure 6: OccFormer. It is composed of sequential blocks where is the temporal horizon (including current and future frames) and each block is responsible for generating occupancy of one specific frame. We incorporate both dense scene features and sparse agent features, which are encoded from upstream track query , agent position and motion query , to inject agent-level knowledge into future scene representations. We form instance-level occupancy via a matrix multiplication between agent-level feature and decoded dense feature at the end of each block.
图 6:OccFormer。由 个顺序块组成, 为时域(含当前与未来帧),每块负责生成某一帧的占据。我们同时纳入稠密场景特征与稀疏智能体特征(由上游 track query 、智能体位置 与运动 query 编码),把智能体级知识注入未来场景表示。每块末尾通过智能体级特征与解码稠密特征的矩阵乘法形成实例级占据 。
E.5 Planning
E.5 规划
As shown in Fig. 7, our planner takes the ego-vehicle query generated from the tracking and motion forecasting module, which is symbolized with the blue triangle and yellow rectangle respectively. These two queries, along with the command embedding, are encoded with MLP layers followed by a max-pooling layer across the modality dimension, where the most salient modal features are selected and aggregated. The BEV feature interaction module is built with standard transformer decoder layers, and it is stacked for layers, where we set here. Specifically, it cross-attends the dense BEV feature with the aggregated plan query. More qualitative results can be found in Sec. F.5 showing the effectiveness of this module. To embed location information, we fuse the plan-query with learned position embedding and the BEV feature with sinusoidal positional embedding. We then regress the planning trajectory with MLP layers, which is denoted as . Here we set (3 seconds). Finally, we devise the collision optimizer for obstacle avoidance, which takes the predicted occupancy and trajectory as input as Eq. 10 in the main paper. We set , , , .
如图 7,规划器取自跟踪与运动预报模块生成的自车 query,分别用蓝色三角与黄色矩形示意。这两个 query 与指令嵌入一起经 MLP,再在模态维做 max-pooling,选出并聚合最显著的模态特征。BEV 特征交互模块基于标准 Transformer 解码器层,堆叠 层(此处 ),将稠密 BEV 特征与聚合后的规划 query 做交叉注意力。更多定性结果见第 F.5 节。为嵌入位置信息,我们将规划 query 与学习位置嵌入融合,BEV 特征则用正弦位置嵌入。再经 MLP 回归规划轨迹,记为 ,此处 (3 秒)。最后设计碰撞优化器做避障,以预测占据 与轨迹 为输入,如正文式 10。我们设 ,,,。
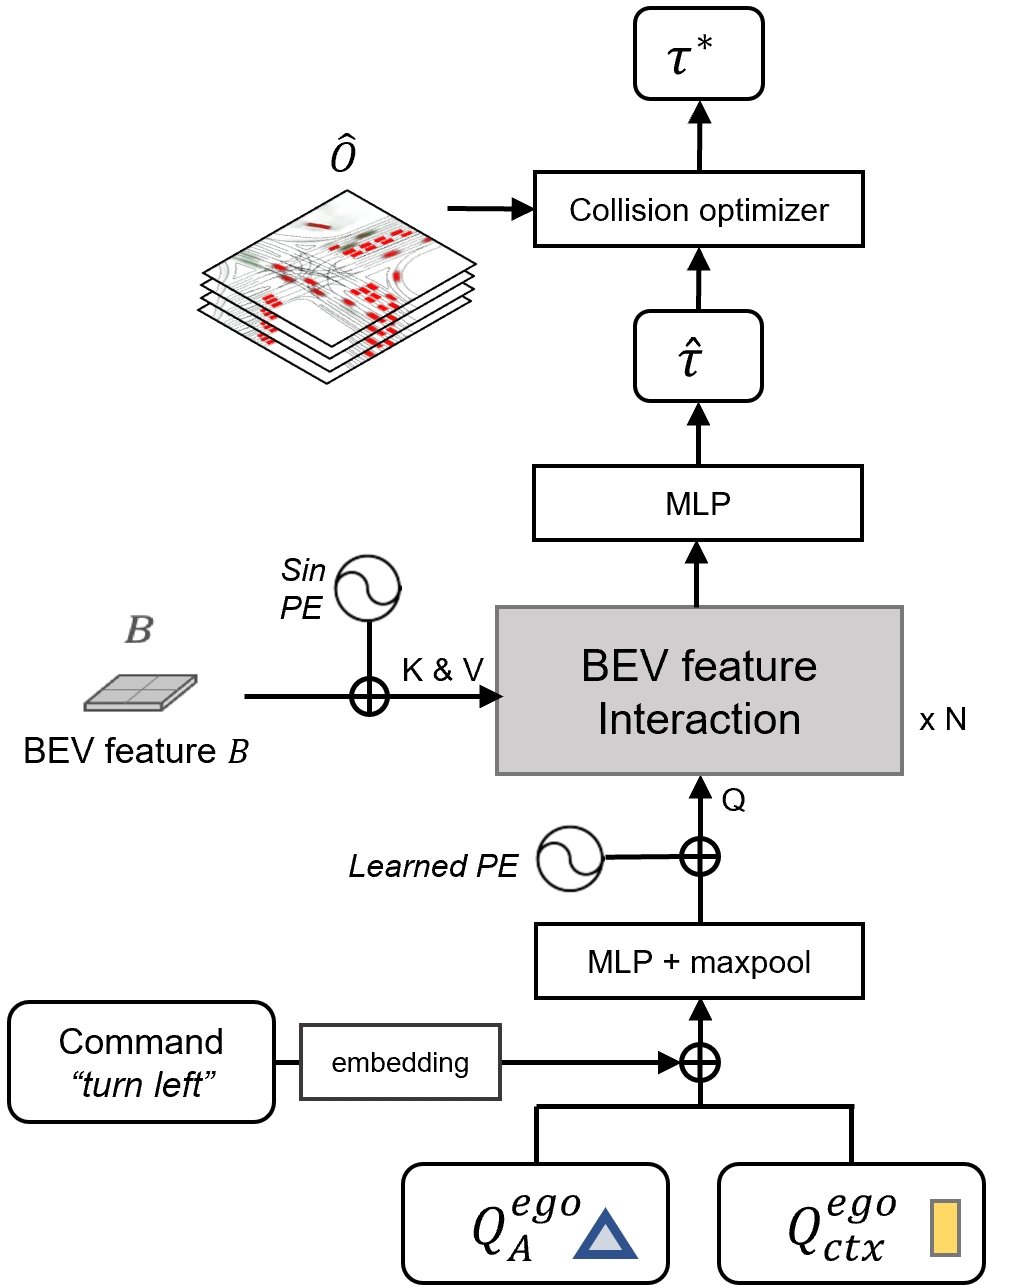
Figure 7: Planner. and are the ego-vehicle query from the tracking and motion forecasting modules, respectively. Along with the high-level command, they are encoded with MLP layers followed by a max-pooling layer across the modality dimension, where the most salient modal features are selected and aggregated. The BEV feature interaction module is built with standard transformer decoder layers, and it is stacked for layers.
图 7:*规划器。 与 分别为跟踪与运动预报模块的自车 query*。它们与高层指令一起经 MLP,再在模态维 max-pooling,选出并聚合最显著模态特征。BEV 特征交互模块基于标准 Transformer 解码器层,堆叠 层。
E.6 Training Details
E.6 训练细节
Joint learning.
UniAD is trained in two stages which we find more stable. In stage one, we pre-train perception tasks including tracking and online mapping to stabilize perception predictions. Specifically, we load corresponding pre-trained BEVFormer [55] weights to UniAD for fast convergence including image backbone, FPN, BEV encoder and detection decoder except for object query embeddings (due to the additional ego-vehicle query). We stop the gradient back-propagation in the image backbone to reduce memory cost and train UniAD for 6 epochs with tracking and online mapping losses as follows:
联合学习。
UniAD 分两阶段训练,我们发现更稳定。阶段一预训跟踪与在线建图等感知任务以稳定感知预测。具体地,加载对应预训练 BEVFormer [55] 权重以加速收敛,包括图像骨干、FPN、BEV 编码器与检测解码器,但不含目标 query 嵌入(因额外引入自车 query)。为降低显存,在图像骨干停止梯度回传,用跟踪与在线建图损失训练 UniAD 6 个 epoch:
In stage two, we keep the image backbone frozen as well, and additionally freeze BEV encoder, which is used for view transformation from image view to BEV, to further reduce memory consumption with more downstream modules. UniAD now is trained with all task losses including tracking, mapping, motion forecasting, occupancy prediction, and planning for 20 epochs (for various ablation studies in main paper, it’s trained for 8 epochs for efficiency):
阶段二同样冻结图像骨干,并额外冻结用于图像视图到 BEV 变换的 BEV 编码器,以在更多下游模块下进一步降低显存。此时 UniAD 用全部任务损失——跟踪、建图、运动预报、占据预测与规划——训练 20 个 epoch(正文各类消融为效率训练 8 个 epoch):
Detailed losses and hyperparameters within each term of and are described below individually. The length of each training sequence (at each step) for tracking and BEV feature aggregation[55] in both stages is 5 (3 in ablation studies for efficiency).
与 各项内的详细损失与超参数见下文。两阶段中跟踪与 BEV 特征聚合 [55] 的每步训练序列长度均为 5(消融中为效率取 3)。
Detection&tracking loss.
Following BEVFormer [55], the Hungarian loss is adopted for each paired result, which is a linear combination of a Focal loss [61] for class labels and an for 3D boxes localization. In terms of the matching strategy, candidates from newborn queries are paired with ground truth objects through bipartite matching, and predictions from track queries inherit the assigned ground truth index from previous frames. Specifically, , where and .
检测与跟踪损失。
遵循 BEVFormer [55],对每对匹配结果采用匈牙利损失,即类别标签的 Focal 损失 [61] 与三维框定位的 的线性组合。匹配策略上,新生 query 候选经二分图匹配与真实目标配对,track query 的预测继承先前帧已分配的真实索引。具体地,,其中 ,。
Online mapping loss.
As in [56], this includes thing losses for lanes, dividers, and contours, also a stuff loss for the drivable area, where Focal loss is responsible for classification, L1 loss is responsible for thing bounding boxes, Dice loss and GIoU loss[80] account for segmentation. Detailedly, , with and .
在线建图损失。
如 [56],包括车道、隔离带与轮廓的 thing 损失,以及可行驶区域的 stuff 损失:Focal 损失负责分类,L1 负责 thing 边界框,Dice 损失与 GIoU 损失 [80] 负责分割。具体地,,其中 ,。
Motion forecasting loss.
Like most of the prior methods, we model the multimodal trajectories as gaussian mixtures, and use the multi-path loss [12, 90], which includes a classification score loss and a negative log-likelihood loss term , and denotes the corresponding weight: , where . To ensure the temporal smoothness of trajectories, we predict agents’ speed at each timestep first and accumulate it across time to obtain their final trajectories [41].
运动预报损失。
与多数先前方法一样,我们将多模态轨迹建模为高斯混合,采用 multi-path 损失 [12, 90],含分类分数损失 与负对数似然项 , 为对应权重:,其中 。为保证轨迹时序平滑,我们先预测各时刻速度再沿时间累积得到最终轨迹 [41]。
Occupancy prediction loss.
The output of instance-level occupancy prediction is a binary segmentation of each agent, therefore we adopt binary cross-entropy and Dice loss [67] as the occupancy loss. Formally, , with and here. Additionally, since the attention mask in the pixel-agent interaction module could be seen as a coarse prediction, we employ an auxiliary occupancy loss with the same form to supervise it.
占据预测损失。
实例级占据预测输出为每个智能体的二值分割,因此采用二值交叉熵与 Dice 损失 [67] 作为占据损失。形式上,,此处 ,。此外,像素—智能体交互模块中的注意力掩码可视为粗预测,我们用同形式的辅助占据损失监督它。
Planning loss.
Safety is the most crucial factor in planning. Therefore, apart from the naive imitation loss, we employ another collision loss which keeps the planned trajectory away from obstacles as follows:
规划损失。
安全是规划中最关键因素。因此除朴素模仿 损失外,我们另采用碰撞损失,使规划轨迹远离障碍:
where , , is a weight-value pair considering additional safety distance, represents the ego bounding box with an increased size at timestamp to keep a larger safe distance, and indicates each agent forecasted in the scene. In practice, we set to .
其中 ,, 为考虑额外安全距离的权重—数值对, 表示时刻 增大尺寸后的自车边界框以保持更大安全距离, 表示场景中预报的各智能体。实践中我们将 设为 、、。
Appendix F Experiments
附录 F 实验
F.1 Protocols
F.1 协议
We follow most of the basic training settings as in BEVFormer [55] for both two stages with a batch size of 1, a learning rate of , learning rate multiplier of the backbone 0.1 and AdamW optimizer [65] with a weight decay of . The default size of BEV size is , covering BEV ranges of [-51.2, 51.2] for both X and Y axis with the interval as 0.512. More hyperparameters related to feature dimensions are shown in Table 11. Experiments are conducted with 16 NVIDIA Tesla A100 GPUs.
两阶段训练大体遵循 BEVFormer [55] 的基本设置:batch size 为 1,学习率 ,骨干学习率乘数 0.1,AdamW 优化器 [65] 权重衰减 。默认 BEV 尺寸为 ,覆盖 X、Y 轴各 ,间隔 。更多与特征维相关的超参数见表 11。实验在 16 张 NVIDIA Tesla A100 GPU 上进行。
F.2 Metrics
F.2 指标
Multi-object tracking.
Following the standard evaluation protocols, we use AMOTA (Average Multi-object Tracking Accuracy), AMOTP (Average Multi-object Tracking Precision), Recall, and IDS (Identity Switches) to evaluate the 3D tracking performance of UniAD on nuScenes dataset. AMOTA and AMOTP are computed by integrating MOTA (Multi-object Tracking Accuracy) and MOTP (Multi-object Tracking Precision) values over all recalls:
多目标跟踪。
遵循标准评估协议,我们使用 AMOTA、AMOTP、召回率与 IDS(身份切换)等指标。AMOTA 越高越好,AMOTP 与 IDS 越低越好。
where , , and represent the number of false positives, false negatives and identity switches computed at the corresponding recall , respectively. GT stands for the number of ground truth objects in this frame. AMOTP can be defined as:
其中 、 与 分别表示在对应召回率 下计算的假阳性、假阴性与身份切换数。GT 表示真实目标数。
where denotes the position error (in and axis) of matched track at time stamp , and is the number of true positives at the corresponding recall .
其中 表示匹配轨迹 在时刻 的位置误差( 与 轴), 为对应召回率 下的真阳性数。
Online mapping.
We have four categories for the online mapping task, i.e., lanes, boundaries, pedestrian crossings and drivable area. We calculate the intersection-over-union (IoU) metric for each class between the network outputs and ground truth maps.
在线建图。
在线建图任务有四类:车道、边界、人行横道与可行驶区域。我们对网络输出与真实地图计算各类别交并比(IoU)。
Motion forecasting.
On one hand, following the standard motion prediction protocols, we adopt conventional metrics, including minADE (minimum Average Displacement Error), minFDE (minimum Final Displacement Error) and MR (Miss Rate). Similar to the prior works [66, 57, 75], these metrics are only calculated within matched TPs, and we set the matching threshold to 1.0 in all of our experiments. As for the MR, we set the miss FDE threshold to 2.0. On the other hand, we also employ recently proposed end-to-end metrics, i.e., EPA (End-to-end Prediction Accuracy) [30] and minFDE-AP [75]. For EPA, we use the same setting as in ViP3D [30] for a fair comparison. For minFDE-AP, we do not separate ground truth into multiple bins (static, linear, and non-linearly moving sub-categories) for simplicity. Specifically, only when an object’s perception location and its min-FDE are within the distance threshold (1.0 and 2.0 respectively), it would be counted as a TP for the AP (average precision) calculation. Similarly to the prior works, we merge the car, truck, construction vehicle, bus, trailer, motorcycle, and bicycle as the vehicle category, and all the motion forecasting metrics provided in the experiments are evaluated on the vehicle category.
运动预报。
一方面,遵循标准运动预测协议,我们采用常规指标,包括 minADE(最小平均位移误差)、minFDE(最小最终位移误差)与 MR(未命中率)。与先前工作 [66, 57, 75] 类似,这些指标仅在匹配的 TP 内计算,全部实验匹配阈值设为 1.0;MR 的未命中 FDE 阈值设为 2.0。另一方面,我们也采用近期提出的端到端指标,即 EPA(端到端预测精度) [30] 与 minFDE-AP [75]。EPA 使用与 ViP3D [30] 相同设定以便公平比较。
| Methods | Encoder | Tracking | Mapping | Motion Forecasting | Occupancy Prediction | Planning | ||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| AMOTA | AMOTP | IDS | IoU-lane | IoU-road | minADE | minFDE | MR | EPA | IoU-n. | IoU-f. | VPQ-n. | VPQ-f. | avg.L2 | avg.Col. | ||
| UniAD-S | R50 | 0.241 | 1.488 | 958 | 0.315 | 0.689 | 0.788 | 1.126 | 0.156 | 0.381 | 59.4 | 35.6 | 49.2 | 28.9 | 1.04 | 0.32 |
| UniAD-B | R101 | 0.359 | 1.320 | 906 | 0.313 | 0.691 | 0.708 | 1.025 | 0.151 | 0.456 | 63.4 | 40.2 | 54.7 | 33.5 | 1.03 | 0.31 |
| UniAD-L | V2-99∗ | 0.409 | 1.259 | 1583 | 0.323 | 0.709 | 0.723 | 1.067 | 0.158 | 0.508 | 64.1 | 42.6 | 55.8 | 36.9 | 1.03 | 0.29 |
Table 12: Comparisons between three variations of UniAD. : pre-trained with extra depth data [73].
| Methods | Encoder | Tracking | Mapping | Motion Forecasting | Occupancy Prediction | Planning | ||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| AMOTA | AMOTP | IDS | IoU-lane | IoU-road | minADE | minFDE | MR | EPA | IoU-n. | IoU-f. | VPQ-n. | VPQ-f. | avg.L2 | avg.Col. | ||
| UniAD-S | R50 | 0.241 | 1.488 | 958 | 0.315 | 0.689 | 0.788 | 1.126 | 0.156 | 0.381 | 59.4 | 35.6 | 49.2 | 28.9 | 1.04 | 0.32 |
| UniAD-B | R101 | 0.359 | 1.320 | 906 | 0.313 | 0.691 | 0.708 | 1.025 | 0.151 | 0.456 | 63.4 | 40.2 | 54.7 | 33.5 | 1.03 | 0.31 |
| UniAD-L | V2-99∗ | 0.409 | 1.259 | 1583 | 0.323 | 0.709 | 0.723 | 1.067 | 0.158 | 0.508 | 64.1 | 42.6 | 55.8 | 36.9 | 1.03 | 0.29 |
Table 12: Comparisons between three variations of UniAD. : pre-trained with extra depth data [73].
表 12:不同模型规模下的 UniAD 变体。
Occupancy prediction.
We evaluate the quality of predicted occupancy in both whole-scene level and instance-level following [35, 105]. Specifically, The IoU measures the whole-scene categorical segmentations which is instance-agnostic, while the Video Panoptic Quality (VPQ) [48] takes into account each instance’s presence and consistency over time. The VPQ metric is calculated as follows:
占据预测。
我们遵循 [35, 105] 在整场景级与实例级评估预测占据质量。具体地,IoU 衡量与实例无关的整场景类别分割,而视频全景质量(VPQ) [48] 考虑每个实例随时间的出现与一致性。VPQ 计算如下:
where is the future horizon and we set (which leads to including the current timestamp) as in [35, 105], covering 2.0 consecutive data at 2Hz. , , and are the set of true positives, false positives, and false negatives at timestamp respectively. Both two metrics are evaluated under two different BEV ranges, near (“-n.”) for and far (“-f.”) for around the ego vehicle. We evaluate the results of the current step () and the future 4 steps together on both metrics.
其中 为未来时域,我们如 [35, 105] 设 (含当前时刻则 ),覆盖 2Hz 下连续 2.0 数据。、、 分别为时刻 的真阳性、假阳性与假阴性集合。两指标均在自车周围两种 BEV 范围评估:近距(「-n.」) 与 远距(「-f.」)。我们在两指标上共同评估当前步()与未来 4 步的结果。
| ID | Det. | Track | Map | Motion | Occ. | Plan | #Params | FLOPs | FPS |
|---|---|---|---|---|---|---|---|---|---|
| 0[105] | ✓ | ✓ | ✓ | 102.5M | 1921G | - | |||
| 1 | ✓ | 65.9M | 1324G | 4.2 | |||||
| 2 | ✓ | ✓ | 68.2M | 1326G | 2.7 | ||||
| 3 | ✓ | ✓ | ✓ | 95.8M | 1520G | 2.2 | |||
| 4 | ✓ | ✓ | ✓ | ✓ | 108.6M | 1535G | 2.1 | ||
| 5 | ✓ | ✓ | ✓ | ✓ | ✓ | 122.5M | 1701G | 2.0 | |
| 6 | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | 125.0M | 1709G | 1.8 |
Table 13: Computational complexity and runtime with different modules incorporated. ID.1 is similar to original BEVFormer [55], and ID. 0 (BEVerse-Tiny) [105] is an MTL framework.
| ID | Det. | Track | Map | Motion | Occ. | Plan | #Params | FLOPs | FPS |
|---|---|---|---|---|---|---|---|---|---|
| 0[105] | ✓ | ✓ | ✓ | 102.5M | 1921G | - | |||
| 1 | ✓ | 65.9M | 1324G | 4.2 | |||||
| 2 | ✓ | ✓ | 68.2M | 1326G | 2.7 | ||||
| 3 | ✓ | ✓ | ✓ | 95.8M | 1520G | 2.2 | |||
| 4 | ✓ | ✓ | ✓ | ✓ | 108.6M | 1535G | 2.1 | ||
| 5 | ✓ | ✓ | ✓ | ✓ | ✓ | 122.5M | 1701G | 2.0 | |
| 6 | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | 125.0M | 1709G | 1.8 |
表 13: 不同模块组合下的计算复杂度与运行时间。 ID.1 类似原版 BEVFormer [55], and ID. 0 (BEVerse-Tiny) [105] 为多任务学习框架。
Planning.
We adopt the same metrics as in ST-P3 [38], i.e., L2 error and collision rate at various timestamps.
规划。
我们采用与 ST-P3 [38] 相同的指标,即不同时刻的 L2 误差 与 碰撞率。
F.3 Model complexity and Computational cost
F.3 模型复杂度与计算代价
We measure the complexity of UniAD and runtime on an Nvidia Tesla A100 GPU, as depicted in Table 13. Though the decoder part of tasks brings a certain amount of parameters, the computational complexity mainly comes from the encoder part, compared to the original BEVFormer detector (ID. 1). We also provide a comparison with the recent BEVerse [105]. UniAD owns more tasks, achieves superior performance, and has lower FLOPs - indicating affordable budget to additional computation cost.
我们在 Nvidia Tesla A100 GPU 上测量 UniAD 的复杂度与运行时间,见表 13。尽管任务解码器带来一定参数量,相对原版 BEVFormer 检测器(ID. 1),计算复杂度主要来自编码器部分。我们也与近期 BEVerse [105] 比较:UniAD 任务更多、表现更优,且 FLOPs 更低——表明额外计算代价在可承受预算内。
F.4 Model scale
F.4 模型规模
We provide three variations of UniAD under different model scales as shown in Table 12. The chosen image backbones for image-view feature extraction are ResNet-50[32], ResNet-101 and VoVNet 2-99[51] for UniAD-S, UniAD-B and UniAD-L respectively. Since the model scale (image encoder) mainly influences the BEV feature quality, we could observe that the perceptual scores improve with a larger backbone, which further could lead to better prediction and planning performance.
我们在表 12 给出三种不同规模的 UniAD 变体。图像视图特征提取所用骨干分别为 UniAD-S 的 ResNet-50[32]、UniAD-B 的 ResNet-101 与 UniAD-L 的 VoVNet 2-99[51]。由于模型规模(图像编码器)主要影响 BEV 特征质量,可观察到更大骨干带来更高感知分数,并进一步改善预测与规划表现。
F.5 Qualitative results
F.5 定性结果
Attention mask visualization.
To investigate the internal mechanism and show its explainability, we visualize the attention mask of the cross-attention module in the planner. As shown in Fig. 8, the predicted tracking bounding boxes, planned trajectory, and the ground truth HD Map are rendered for reference, and the attention mask is overlayered on top. From left to right, we show two consecutive frames in a time sequence but with different navigation commands. We can observe that the planned trajectory varies largely according to the command. Also, much attention is paid to the goal lane as well as the critical agents that are yielding to our ego vehicle.
注意力掩码可视化。
为考察内部机制并展示可解释性,我们可视化规划器中交叉注意力模块的注意力掩码。如图 8,渲染预测跟踪边界框、规划轨迹与真实 HD 地图作参考,并叠加注意力掩码。从左到右展示同一时序中连续两帧但导航指令不同的情况。可见规划轨迹随指令大幅变化;大量注意力落在目标车道以及对自车让行的关键智能体上。
Visualization of different scenarios.
We provide visualizations for more scenarios, including cruising around the urban areas (Fig. 9), critical cases (Fig. 10), and obstacle avoidance scenarios (Fig. 11). One promising evidence for our planning-oriented design is shown in Fig. 12, where inaccurate results occur in prior modules while the later tasks could still recover. Similarly, we show results for all tasks in surround-view images, BEV, as well as the attention mask from the planner. A demo video[^3] is also provided for reference.
不同场景可视化。
我们提供更多场景可视化,包括城区巡航(图 9)、关键案例(图 10)与避障场景(图 11)。图 12 展示规划导向设计的一个有希望证据:上游模块结果不准确时,后续任务仍可恢复。同样,我们在环视图像、BEV 以及规划器注意力掩码中展示全部任务结果。亦提供演示视频[^3]供参考。
Failure cases
are essential for an autonomous driving algorithm to understand its weakness and guide future work, and here we present some failure cases of UniAD. The failure cases of UniAD are mainly under some long-tail scenarios where all modules are affected, as depicted in Fig. 13 and Fig. 14.
失败案例
对自动驾驶算法理解自身弱点并指导未来工作至关重要,此处展示 UniAD 的一些失败案例。如图 13 与图 14,失败主要出现在所有模块均受影响的长尾场景。
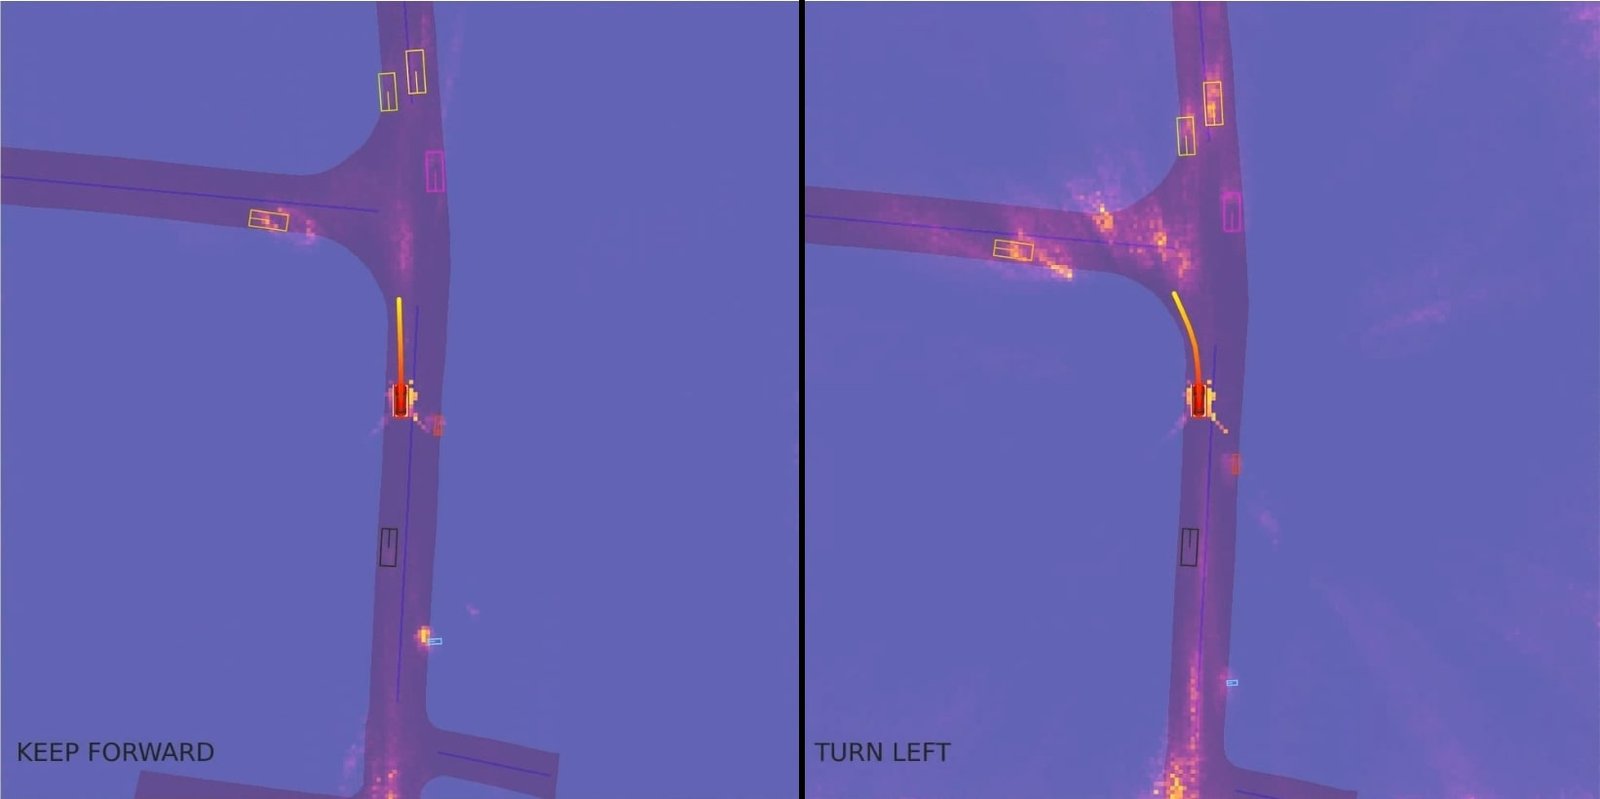
Figure 8: Effectiveness of navigation command and attention mask visualization. Here we demonstrate how attention is paid in accordance with the navigation command. We render the attention mask from the BEV interaction module in the planning module, the predicted tracking bounding boxes as well as the planned trajectory. The navigation command is printed on the bottom left, and the HD Map is rendered only for reference. From left to right, we show two consecutive frames in a time sequence but with different navigation commands. We can observe that the planned trajectory varies largely according to the command. Also, much attention is paid to the goal lane as well as the critical agents that are yielding to our ego vehicle.
图 8:导航指令效果与注意力掩码可视化。展示注意力如何随导航指令变化。我们渲染规划模块 BEV 交互的注意力掩码、预测跟踪边界框以及规划轨迹。导航指令印在左下,HD 地图仅供参考。从左到右为同一时序连续两帧但指令不同:规划轨迹随指令大幅变化;大量注意力落在目标车道以及对自车让行的关键智能体上。
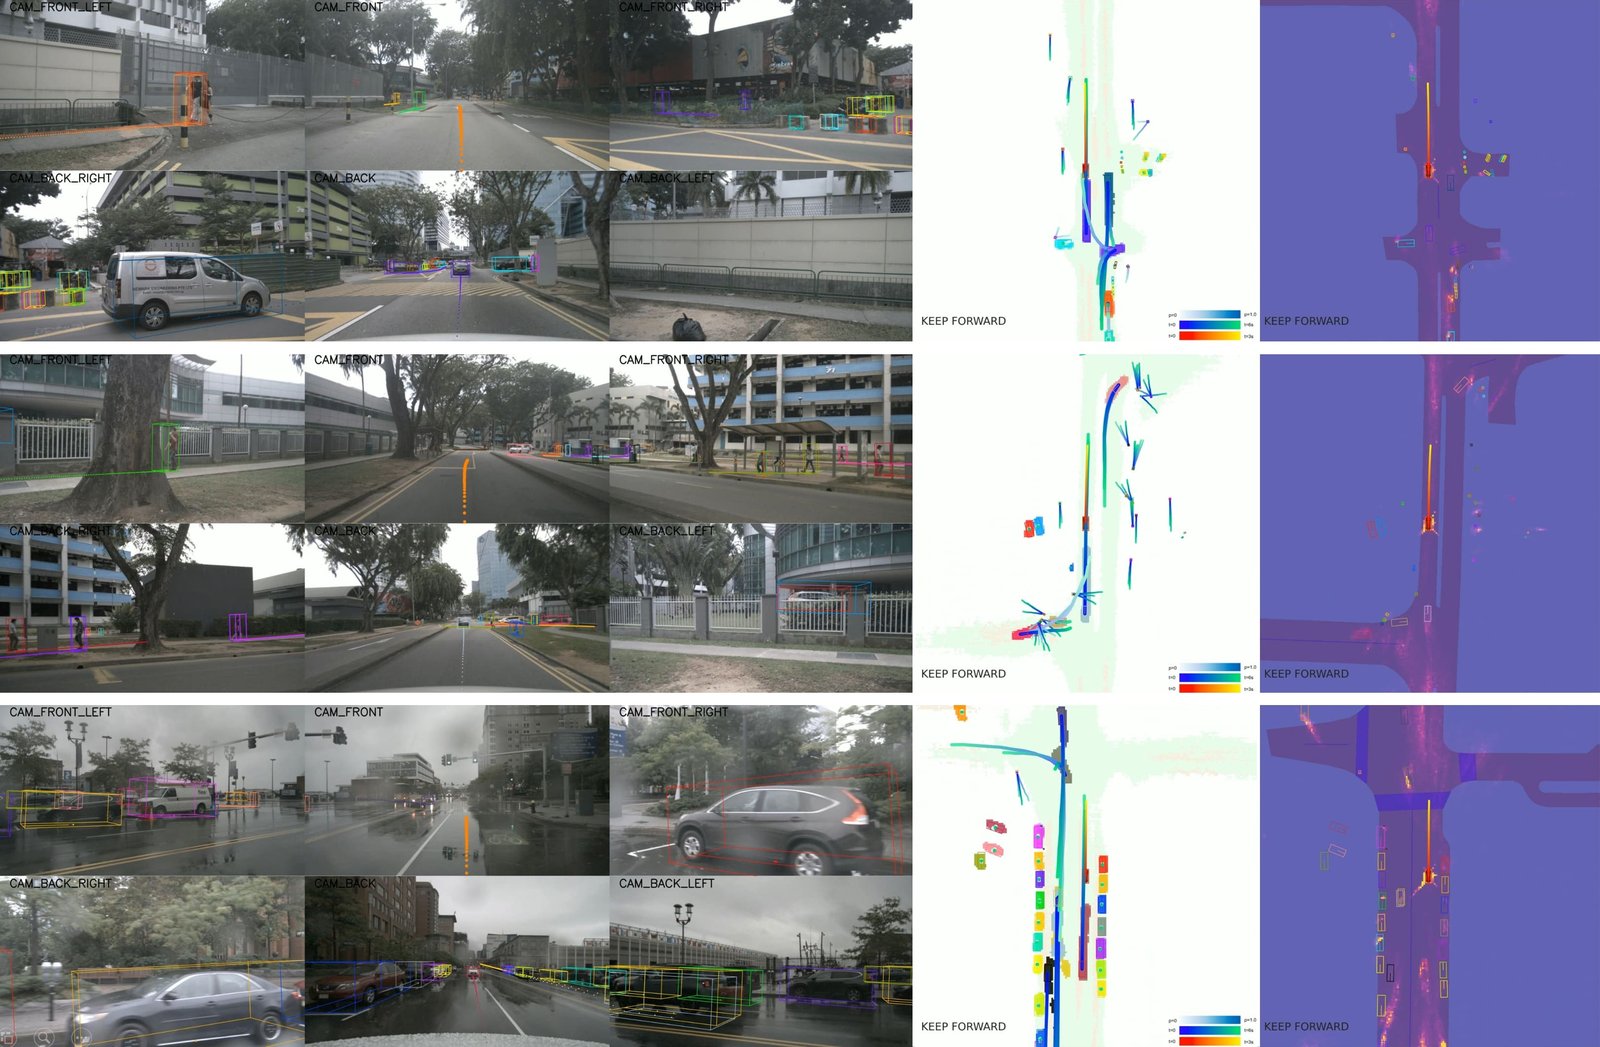
Figure 9: Visualization for cruising around the urban areas. UniAD can generate high-quality interpretable perceptual and prediction results, and make a safe maneuver. The first three columns show six camera views, and the last two columns are the predicted results and the attention mask from the planning module respectively. Each agent is illustrated with a unique color. Only top-1 and top-3 trajectories from motion forecasting are selected for visualization on images-view and BEV respectively.
图 9:城区巡航可视化。UniAD 可生成高质量、可解释的感知与预测结果,并做出安全动作。前三列为六路相机视图,后两列分别为预测结果与规划模块注意力掩码。每个智能体用独特颜色表示。图像视图与 BEV 分别只选取运动预报的 top-1 与 top-3 轨迹可视化。
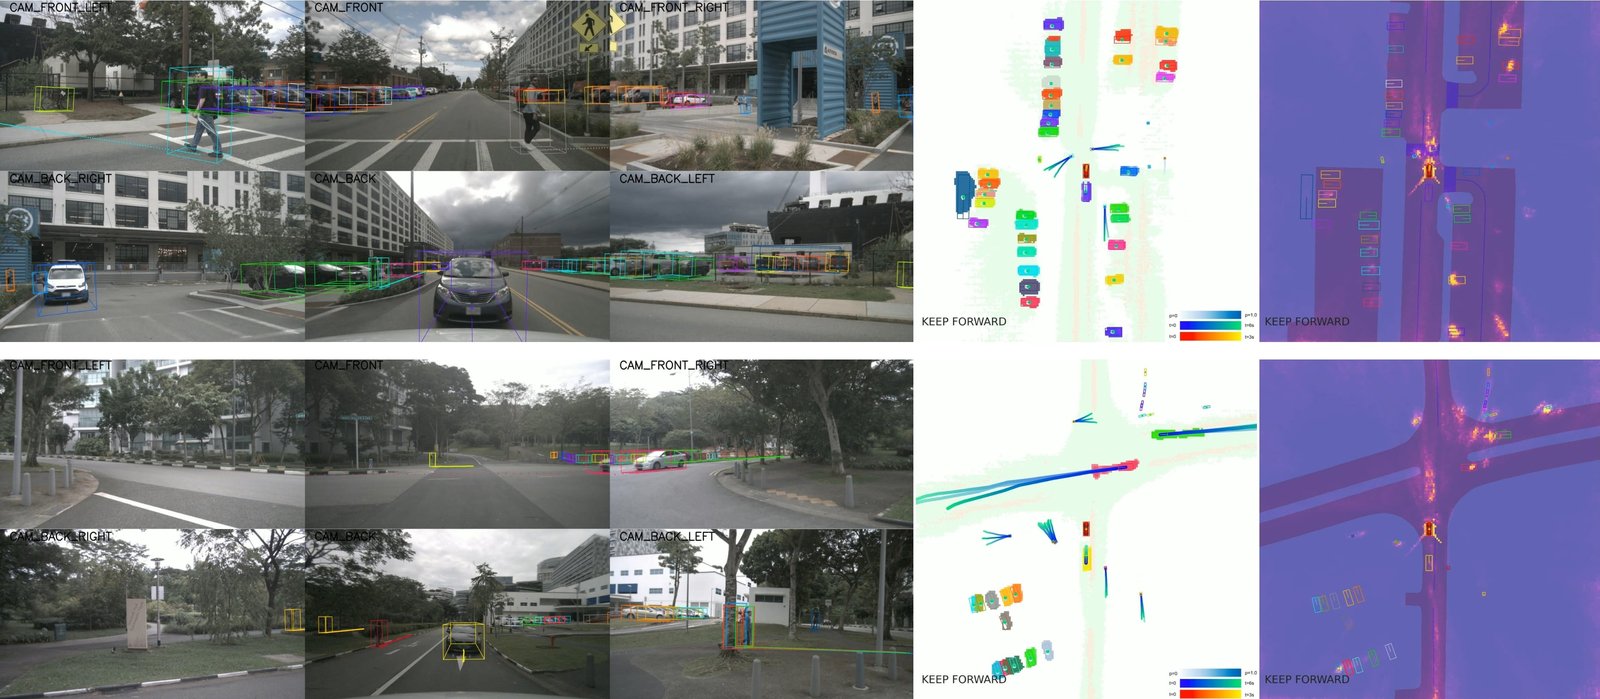
Figure 10: Critical case visualization. Here we demonstrate two critical cases. The first scenario (top) shows that the ego vehicle is yielding to two pedestrians crossing the street, and the second scenario (down) shows that the ego vehicle is yielding to a fast-moving car and waiting to go straight without protection near an intersection. We can observe that much attention is paid to the most critical agents, i.e., pedestrians and fast-moving vehicles, as well as the intended goal location.
图 10:关键案例可视化。展示两个关键案例。上:自车对两名过马路行人让行;下:自车对快速驶来车辆让行,并在无保护路口等待直行。可见大量注意力落在最关键智能体(行人与快速车辆)以及意图目标位置上。
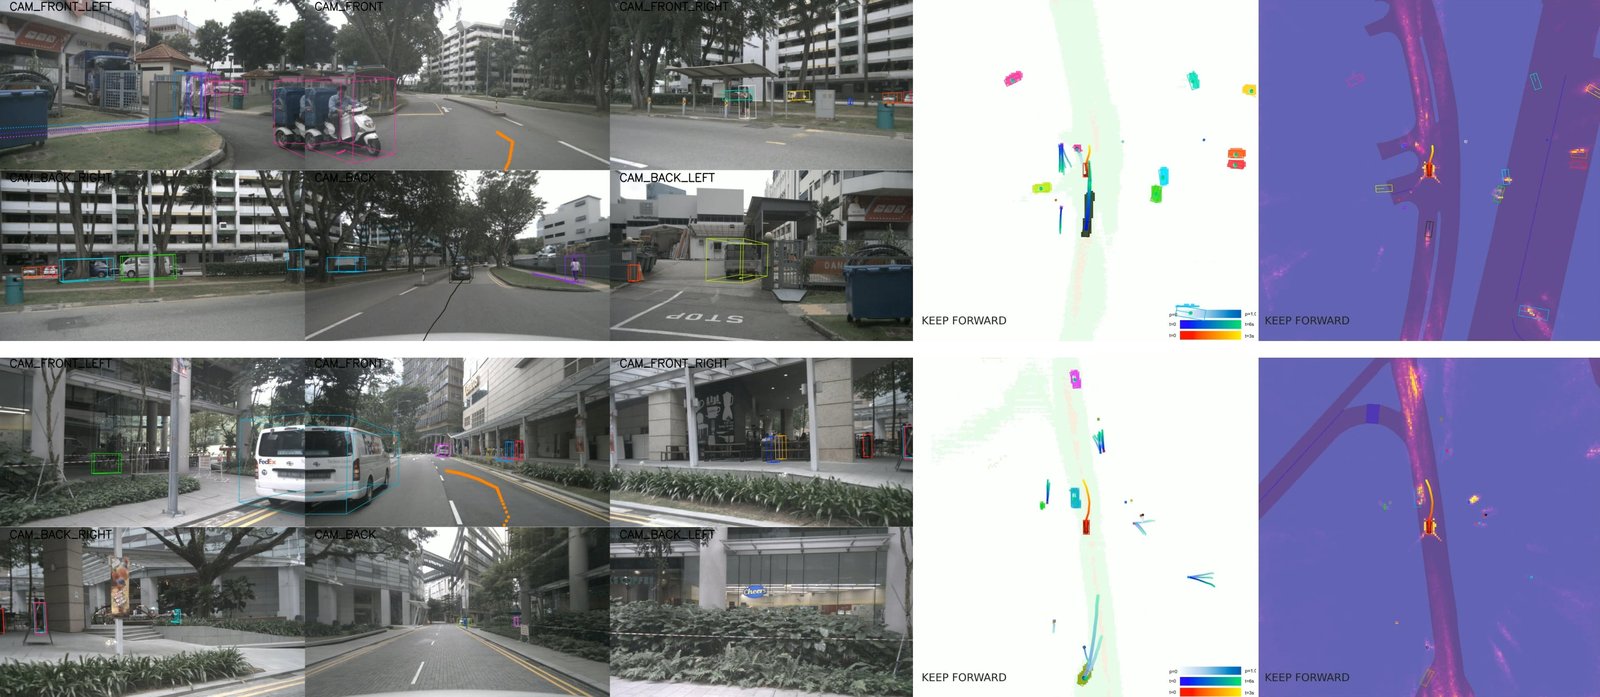
Figure 11: Obstacles avoidance visualization. In these two scenarios, the ego vehicle is changing lanes attentively to avoid the obstacle vehicle. From the attention mask, we can observe that our method focuses on the obstacles as well as the road in the front and back.
图 11:避障可视化。两例中自车注意变道以避开障碍车辆。从注意力掩码可见,方法关注障碍物以及前后方道路。
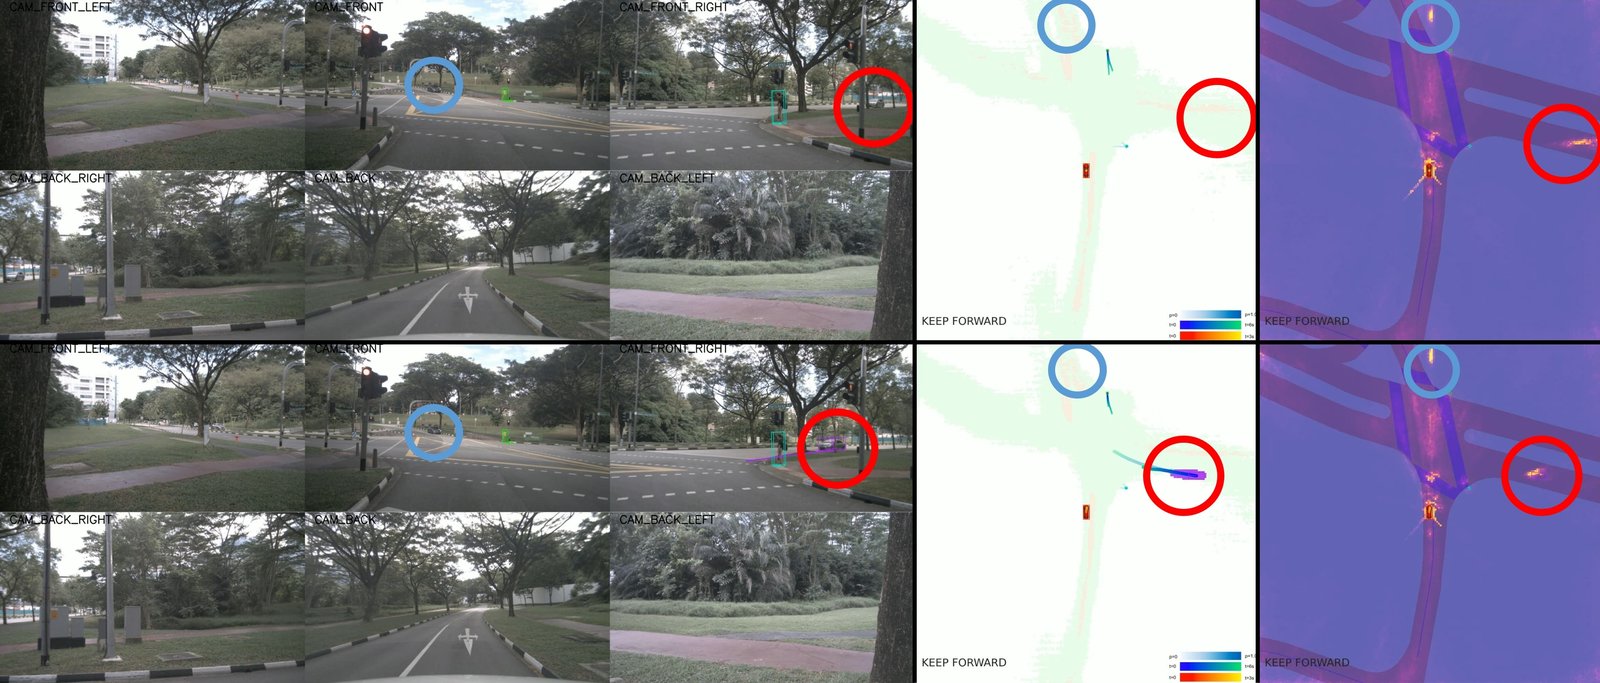
Figure 12: Visualization for planning recovering from perception failures. We show an interesting case where inaccurate results occur in prior modules while the later tasks could still recover. The top row and the down row represent two consecutive frames from the same scenario. The vehicle in the red circle is moving from a far distance toward the intersection at a high speed. It is observed that the tracking module misses it at first, then captures it at the latter frame. The blue circles show a stationary car yielding to the traffic, and it is missed in both frames. Interestingly, both vehicles show strong reactions to the attention masks of the planner, even though they are missed in the prior modules. It means that our planner still pays attention to those critical though missed agents, which is intractable in previous fragmented and non-unified driving systems, and demonstrates the robustness of UniAD.
图 12:规划从感知失败中恢复的可视化。展示上游模块结果不准确而后续任务仍可恢复的有趣案例。上下两行表示同一场景连续两帧。红圈中车辆正高速从远处驶向路口:跟踪模块起初漏检,后一帧捕获。蓝圈为对交通让行的静止车,两帧均漏检。有趣的是,尽管跟踪漏检,两车仍在规划器注意力掩码中有强烈响应。
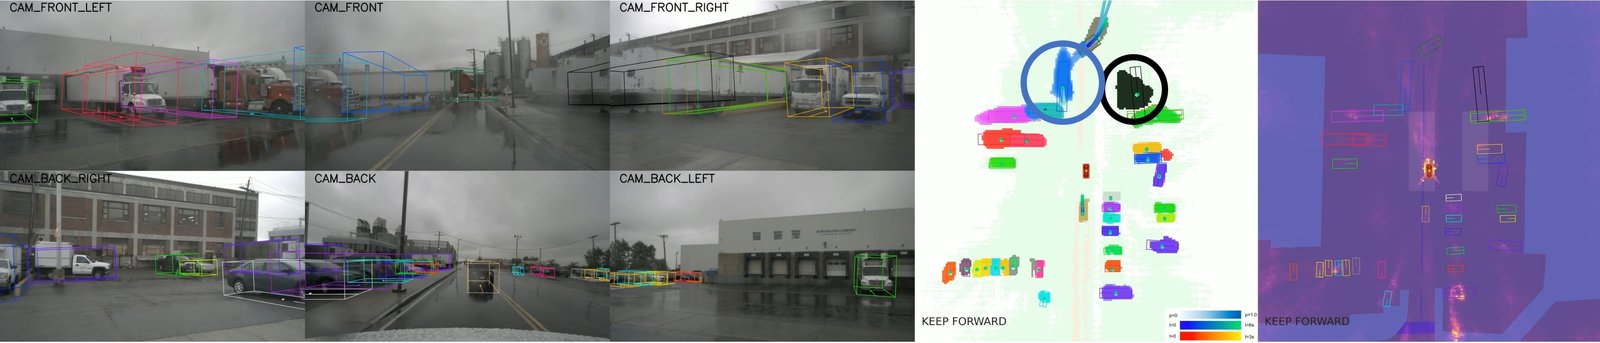
Figure 13: Failure cases 1. Here we present a long-tail scenario, where a large trailer with a white container occupies the entire road. We can observe that our tracking module fails to detect the accurate size of the front trailer and heading angles of vehicles beside the road.
图 13:失败案例 1。展示长尾场景:带白色集装箱的大型拖车占据整条道路。可见跟踪模块未能准确检测前方拖车尺寸以及路边车辆航向角。
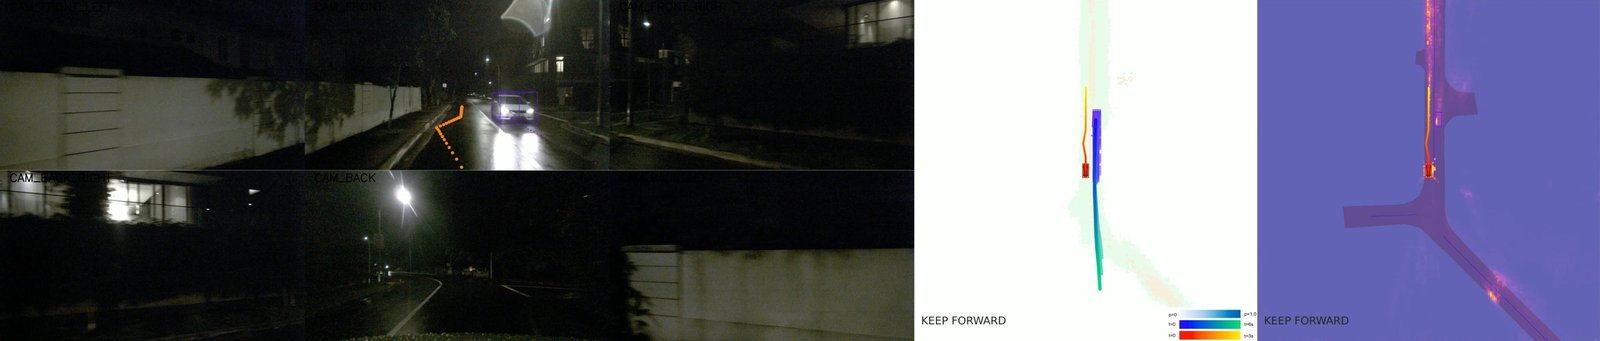
Figure 14: Failure cases 2. In this case, the planner is over-cautious about the incoming vehicle in the narrow street. The dark environment is one critical type of long-tail scenarios in autonomous driving. Applying smaller collision loss weight and more regulation regarding the boundary might mitigate the problem.
图 14:失败案例 2。本例中规划器对窄巷迎面来车过于谨慎。黑暗环境是自动驾驶长尾场景的一类关键类型。减小碰撞损失权重并加强边界相关正则或可缓解该问题。