Train for the Worst, Plan for the Best: Understanding Token Ordering in Masked Diffusions
Train for the Worst, Plan for the Best: Understanding Token Ordering in Masked Diffusions
为最坏情况训练,为最佳路径规划:理解掩码扩散中的 Token 顺序
Jaeyeon Kim Affiliation: Harvard University Kulin Shah Affiliation: University of Texas Austin Correspondence to: kulinshah@utexas.edu Vasilis Kontonis Affiliation: University of Texas Austin Sham Kakade Affiliation: Harvard University Sitan Chen Affiliation: Harvard University
Abstract
摘要
In recent years, masked diffusion models (MDMs) have emerged as a promising alternative approach for generative modeling over discrete domains. Compared to autoregressive models (ARMs), MDMs trade off complexity at training time with flexibility at inference time. At training time, they must learn to solve an exponentially large number of infilling problems, but at inference time, they can decode tokens in essentially arbitrary order. In this work, we closely examine these two competing effects. On the training front, we theoretically and empirically demonstrate that MDMs indeed train on computationally intractable subproblems compared to their autoregressive counterparts. On the inference front, we show that a suitable strategy for adaptively choosing the token decoding order significantly enhances the capabilities of MDMs, allowing them to sidestep hard subproblems. On logic puzzles like Sudoku, we show that adaptive inference can boost solving accuracy in pretrained MDMs from % to %, even outperforming ARMs with as many parameters and that were explicitly trained via teacher forcing to learn the right order of decoding. This shows that MDMs without knowledge of the correct token generation order during training and inference can outperform ARMs trained with knowledge of the correct token generation order. We also show the effectiveness of adaptive MDM inference on reasoning tasks such as coding and math on the 8B large language diffusion model (LLaDa 8B).
近年来,掩码扩散模型(masked diffusion models,MDMs)成为离散域生成建模的一条有前景的替代路线。与自回归模型(autoregressive models,ARMs)相比,MDMs 用训练时更高的复杂度换取推理时更大的灵活性:训练时须学会指数级多种填空问题,推理时却几乎能按任意顺序解码 token。本文仔细审视这两种此消彼长的效应。在训练侧,我们从理论与实验两方面说明:相对自回归对照,MDMs 确实在训练计算上不可行的子问题上用力。在推理侧,我们表明:若能恰当、自适应地选择 token 解码顺序,MDMs 的能力会显著增强,从而绕开困难子问题。在数独这类逻辑谜题上,自适应推理能把预训练 MDM 的求解准确率从不足 7% 提升到约 90%,甚至超过参数量为其 7 倍、且经教师强制显式学习正确解码顺序的 ARM。这说明:训练与推理时都不知道正确 token 生成顺序的 MDM,可以胜过带着正确顺序知识训练的 ARM。我们还在 80 亿参数的大语言扩散模型(LLaDa 8B)上,展示了自适应 MDM 推理在编程与数学等推理任务上的效果。
1 Introduction
1 引言
Keywords:
While diffusion models (Ho et al., 2020; Song et al., 2021) are now the dominant approach for generative modeling in continuous domains like image, video, and audio, efforts to extend this methodology to discrete domains like text and proteins (Austin et al., 2021; Lou et al., 2024; Hoogeboom et al., 2021b) remain nascent. Among numerous proposals, masked diffusion models (MDMs) (Lou et al., 2024; Sahoo et al., 2025; Shi et al., 2024) have emerged as a leading variant, distinguished by a simple and principled objective: to generate samples, learn to reverse a noise process which independently and randomly masks tokens.
关键词:
尽管扩散模型(Ho et al., 2020;Song et al., 2021)已在图像、视频与音频等连续域生成建模中占据主导,把同一思路推广到文本与蛋白质等离散域(Austin et al., 2021;Lou et al., 2024;Hoogeboom et al., 2021b)仍处早期。众多方案里,掩码扩散模型(MDMs)(Lou et al., 2024;Sahoo et al., 2025;Shi et al., 2024)成为主流变体,其目标简洁且有原则:为生成样本,学习反转一个独立、随机地掩码 token 的噪声过程。
In many applications, such as language modeling, masked diffusion models (MDMs) still underperform compared to autoregressive models (ARMs) (Nie et al., 2024; Zheng et al., 2024), which instead learn to reverse a noise process that unmasks tokens sequentially from left to right. However, recent studies suggest that MDMs may offer advantages in areas where ARMs fall short, including reasoning (Nie et al., 2024; Kitouni et al., 2025), planning (Ye et al., 2024), and infilling (Gong et al., 2024). This raises a key question: what are the strengths and limitations of MDMs compared to ARMs, and on what type of tasks can MDMs be scaled to challenge the dominance of ARMs in discrete generative modeling?
在语言建模等许多应用中,MDMs 仍逊于自回归模型(ARMs)(Nie et al., 2024;Zheng et al., 2024);后者学习反转的是从左到右依次揭开 token 的噪声过程。不过近期研究提示:在推理(Nie et al., 2024;Kitouni et al., 2025)、规划(Ye et al., 2024)与填空(Gong et al., 2024)等 ARM 短板场景,MDMs 可能更有优势。关键问题随之而来:相对 ARMs,MDMs 的长短处是什么?在哪些任务上把 MDM 做大,才有望挑战离散生成建模中 ARM 的主导地位?
To understand these questions, we turn a microscope to two key competing factors when weighing the merits of MDMs over ARMs:
为回答这些问题,我们把显微镜对准权衡 MDMs 与 ARMs 时的两个关键竞争因素:
- • Complexity at training time: MDMs face a more challenging training task by design. While ARMs predict the next token given an unmasked prefix, MDMs predict a token conditioned on a set of unmasked tokens in arbitrary positions. This inherently increases their training complexity.
- • 训练时的复杂度:MDMs 的训练任务本身就更难。ARMs 在未掩码前缀上预测下一 token;MDMs 则在任意位置的未掩码集合上条件预测某个 token。训练复杂度因此固有地升高。
- • Flexibility at inference time: On the other hand, the sampling paths taken by an MDM are less rigid. Unlike the fixed left-to-right decoding of ARMs, MDMs decode tokens in random order at inference. Even more is possible: MDMs can be used to decode in any order (including left-to-right).
- • 推理时的灵活性:另一方面,MDM 的采样路径更不僵硬。不像 ARM 固定的从左到右解码,MDMs 在推理时按随机顺序解码 token;甚至还能按任意顺序解码(也包括从左到右)。
Therefore, we ask:
因此我们追问:
Are the benefits of inference flexibility for MDMs enough to outweigh the drawbacks of training complexity?
MDMs 在推理灵活性上的收益,是否足以抵消训练复杂度上的代价?
In this work, we provide dual perspectives on this question.
本文对这一问题给出双重视角。
(1) Training for the worst. First, we provide theoretical and empirical evidence that the overhead imposed by training complexity quantifiably impacts MDMs’ performance.
(1)为最坏情况训练。 首先,我们给出理论与经验证据:训练复杂度带来的额外负担,会量化地影响 MDMs 的表现。
Theoretically, we show examples of simple data distributions with a natural left-to-right order, where ARMs can provably generate samples efficiently. In contrast, there are noise levels at which a large fraction of the corresponding subproblems solved by MDMs for these distributions are provably computationally intractable. Empirically, we validate this claim on real-world text data, known to have left-to-right order and show that the imbalance in training complexity across subproblems persists even in real-world text data (Fig. 2, left).
理论上,我们构造简单且具有自然从左到右顺序的数据分布:ARMs 可被证明能高效生成样本;相对地,在某些噪声水平下,MDMs 为这些分布所解的大量子问题在计算上可证不可行。经验上,我们在已知具有从左到右顺序的真实文本上验证:跨子问题的训练复杂度失衡在真实文本中同样存在(图 2,左)。
(2) Planning for the best.
While the above might appear to be bad news for MDMs, in the second part of this paper, we answer our guiding question in the affirmative by building upon the observation (Chang et al., 2022; Zheng et al., 2023) that MDMs which can perfectly solve all masking subproblems can be used to decode in any order.
(2)为最佳路径规划。
上述观察对 MDMs 看似坏消息;但在论文后半部分,我们基于 Chang et al.(2022)、Zheng et al.(2023)的观察——若 MDM 能完美解所有掩码子问题,就能按任意顺序解码——对引导问题给出肯定回答。
In first part of the paper, we show that the imbalance in complexity across subproblems during the training of MDMs results in some of the subproblems being poorly trained and the vanilla MDM inference that unmasks tokens in random order results in evaluating the poorly trained marginals. Therefore, in place of vanilla MDM inference, we consider adaptive strategies that carefully select which token to unmask next. Our key insight is that the adaptive strategies makes it possible to sidestep the hard subproblems from training (Fig. 1). In particular, we find that even without modifying how MDMs are trained, the resulting models’ logits contain enough information to determine the right order in which to unmask. We show the effectiveness of the adaptive inference in solving logic puzzles, coding, math and infilling tasks. For example, on Sudoku puzzles, a simple adaptive strategy (Section 4.1) improves the accuracy of MDMs from % to almost 90%.
论文前半表明:MDM 训练中子问题复杂度失衡,会使部分子问题学得很差;而按随机顺序揭开 token 的朴素 MDM 推理,恰恰会去评估这些学得差的边缘分布。因此,我们不以朴素推理为终点,而考虑自适应策略:谨慎选择下一步揭开哪个 token。核心洞见是:自适应策略有可能绕开训练中的困难子问题(图 1)。尤其我们发现:即便不改 MDM 的训练方式,模型的 logits 已含有足够信息来决定正确的揭开顺序。我们在逻辑谜题、编程、数学与填空任务上展示自适应推理的效果;例如在数独上,简单自适应策略(第 4.1 节)把 MDM 准确率从不足 7% 提到近 90%。
Advantage of MDMs over ARMs.
We show that the main effectiveness of MDMs lies in tasks that do not have the same natural token generation order across all sequences (e.g., logic puzzles and reasoning tasks like coding and math). By carefully designing experiments on logic puzzles, we show that MDMs without the knowledge of the correct token generation order during training and inference can outperform ARMs trained with the knowledge of the correct token generation order. In particular, we show that MDMs that decide the correct token generation order during inference via adaptive strategies can outperform ARMs that are trained to learn the right token generation order via supervised teacher forcing (Shah et al., 2024; Lehnert et al., 2024).
MDM 相对 ARM 的优势。
我们表明:MDMs 的主要效力,体现在并非所有序列都共享同一自然 token 生成顺序的任务上(例如逻辑谜题,以及编程、数学等推理任务)。通过对逻辑谜题的细致实验设计,我们说明:训练与推理时都不知道正确 token 生成顺序的 MDMs,可以胜过带着正确顺序知识训练的 ARMs。具体而言,推理时靠自适应策略决定正确生成顺序的 MDMs,可胜过经监督教师强制学习正确生成顺序的 ARMs(Shah et al., 2024;Lehnert et al., 2024)。
Organization.
In Section 2, we provide preliminaries on MDMs and set notation. In Section 3, we examine MDM training and demonstrate the imbalance in computational intractability across subproblems. In Section 4, we consider adaptive inference in MDMs and investigate its impact on likelihood modeling across various tasks.
结构安排。
第 2 节给出 MDMs 预备知识与记号;第 3 节审视 MDM 训练,展示跨子问题的计算不可行性失衡;第 4 节讨论 MDMs 的自适应推理,并考察其在多种任务上对似然建模的影响。
2 Masked Diffusion Models (MDM)
2 掩码扩散模型(MDM)
In this section, we explain the framework of Masked Diffusion Models (Shi et al., 2024; Sahoo et al., 2025) and highlight its interpretation as an order-agnostic learner. MDMs gradually add masking noise to the true discrete data and learn the marginal distribution of the induced reverse process. We formally define both the forward and reverse processes for MDMs below.
本节说明掩码扩散模型框架(Shi et al., 2024;Sahoo et al., 2025),并强调其作为与顺序无关的学习者的解释。MDMs 向真实离散数据逐步加入掩码噪声,并学习诱导的反向过程边缘分布。下面形式化定义 MDM 的前向与反向过程。
Let the distribution on be the data distribution over sequences of length and with vocabulary . We use to denote the “mask” token.
设数据分布 定义在 \{1,\ldots,m}^{L} 上,即长度为 、词表为 \{1,\ldots,m} 的序列分布。用 表示「掩码」token。
Forward process.
For a given and a noise level , the forward process is a coordinate-independent masking process via , where
前向过程。
给定 与噪声水平 ,前向过程 是坐标独立的掩码过程:,其中
Here, is a predefined noise schedule satisfying and is a one-hot vector corresponding to the value of token . denotes the categorical distribution given by . In other words, for each -th coordinate, is masked to the mask token with probability and remains unchanged otherwise.
这里 是预定噪声日程,满足 ; 是对应 token 取值的 one-hot 向量。 表示由 给出的类别分布。换言之,对每个第 坐标, 以概率 被掩成掩码 token ,否则保持不变。
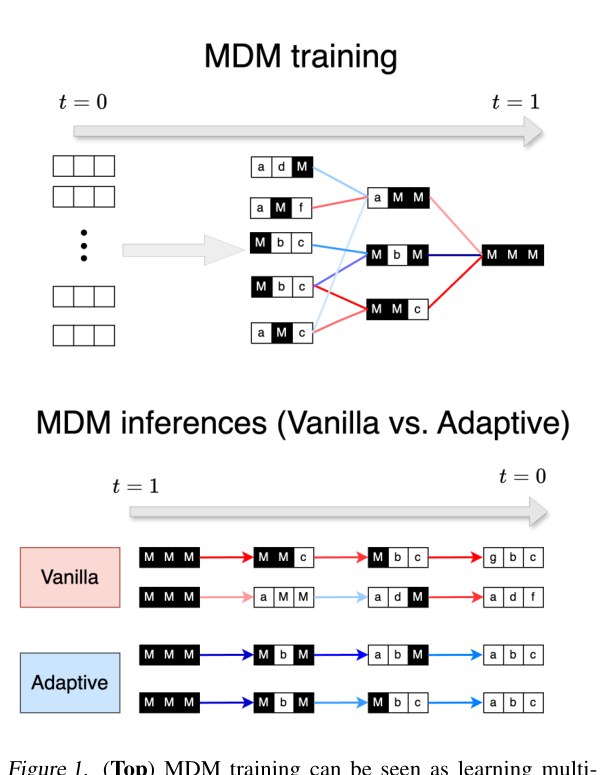
Figure 1: (Top) MDM training can be seen as learning multiple masked prediction problems, where some are harder to learn, leading to performance imbalance (Section 3). (Bottom) During inference, adaptive MDM can avoid difficult problem instances, improving performance (Section 4).
图 1:(上)MDM 训练可视为学习多个掩码预测问题,其中一些更难学,造成性能失衡(第 3 节)。(下)推理时,自适应 MDM 可避开困难问题实例,从而提升性能(第 4 节)。
Reverse process.
The reverse process of the above forward process is denoted by and is given by for any , where
反向过程。
上述前向过程的反向记为 ,对任意 有 ,其中
$$q_{s|t}(x_{s}^{i},\lvert,x_{t},x_{0})=\begin{cases}\mathrm{Cat}(\mathbf{e}{x{t}^{i}})\quad&x_{t}^{i}\neq 0\
\mathrm{Cat}\left(\frac{1-\alpha_{s}}{1-\alpha_{t}}\mathbf{e}{0}+\frac{\alpha{s}-\alpha_{t}}{1-\alpha_{t}}\mathbf{e}{x{0}^{i}}\right)\quad&x_{t}^{i}=0,.\end{cases}$$
The reverse transition probability is approximated using where is a denoising network trained to predict the marginal distribution on via an ELBO-based loss for all masked tokens at noise scale (i.e., for all such that ). To be precise, indicates the conditional probability where is placed in the position of within . The denoising network is trained to minimize the following loss derived from the score-entropy (Lou et al., 2024; Sahoo et al., 2025; Shi et al., 2024; Ou et al., 2024):
反向转移概率 用 近似,其中 是去噪网络,经基于 ELBO 的损失训练,以在噪声尺度 上预测所有被掩码 token 上的 边缘分布(即所有使 的 )。精确地说, 表示把 放进 中 位置后的条件概率。去噪网络最小化由分数熵导出的如下损失(Lou et al., 2024;Sahoo et al., 2025;Shi et al., 2024;Ou et al., 2024):
$$\mathcal{L}{\theta}=\int{0}^{1}\frac{\alpha_{t}^{\prime}}{1-\alpha_{t}}\displaystyle\mathop{\mathbb{E}}{\begin{subarray}{c}x{0}\sim p_{\rm data}\
x_{t}\sim q_{t|0}(\cdot|x_{0})\end{subarray}}\sum_{i:x_{t}^{i}=0}-\log p_{\theta}(x_{0}^{i}|x_{t},t)dt,$$
where and the summation is computed over masked tokens (i.e., all such that ). In practice, a time-embedding-free architecture for the denoising network, i.e., is generally used as implicitly contains information about via the number of masked tokens.
其中 ,求和只对掩码 token(即所有使 的 )。实践中去噪网络常采用无时间嵌入结构,即 ,因为 已通过掩码 token 个数隐式携带 的信息。
The reverse sampling process starts from the fully masked sentence . Suppose we have a partially \fully masked sequence at a given noise level . Then, to obtain for a predetermined noise level , we sample for all . This process is repeated recursively from to .
反向采样从全掩码句 开始。设在噪声水平 已有部分或全掩码序列 ;对预定的 ,对所有 采样 得到 。该过程从 递归做到 。
2.1 Reformulating the training and inference of MDMs
2.1 重述 MDM 的训练与推理
In this section, we first discuss training of MDMs and compare it with “left-to-right” order training of autoregressive models in Section 2.1.1. Then, we reformulate vanilla MDM inference in Section 2.1.2 to set the stage for the upcoming discussion.
本节先在第 2.1.1 小节讨论 MDM 训练,并与自回归模型的「从左到右」顺序训练对比;再在第 2.1.2 小节重述朴素 MDM 推理,为后文铺垫。
2.1.1 Order-agnostic training of MDMs
Recent works (Zheng et al., 2024; Ou et al., 2024) have observed that the learning problem of MDM is equivalent to a masked language model. Building upon their analysis, we reformulate the loss to show that is a linear combination of the loss for all possible infilling masks. We first define as a masked sequence, obtained from original sequence where indices in the mask set (a subset of ) are replaced with mask token .
2.1.1 MDM 的与顺序无关训练
近期工作(Zheng et al., 2024;Ou et al., 2024)观察到:MDM 的学习问题等价于掩码语言模型。沿其分析,我们重写损失 ,表明它是所有可能填空掩码上损失的线性组合。先定义 :由原序列 把掩码集合 ( 的子集)中的下标换成掩码 token 得到的掩码序列。
Proposition 2.1.
Assume , and denoising network is time-embedding free. Then and
命题 2.1。
假设 、,且去噪网络 无时间嵌入。则 ,并且
where is the size of the set and indicates the conditional probability of the -th coordinate from .
其中 是集合 的大小, 表示 在第 坐标上的条件概率。
The proof of the above proposition is given in Appendix E. As the MDM loss is a linear combination of the loss for all possible infilling mask , the minimizer of the loss learns to solve every masking problem. In other words, the optimal predictor is the posterior marginal of the -th token, conditioned on for all masks .
命题证明见附录 E。由于 MDM 损失是所有填空掩码 上损失的线性组合,损失 的极小化者须学会解每一个掩码问题。换言之,最优预测器 是在所有掩码 下,第 个 token 关于 的后验边缘。
On the other hand, Autoregressive Models (ARMs) learn to predict token based on all preceding tokens, from to . This is equivalent to predicting by masking positions from to . Therefore, the training objective for ARMs can be expressed as:
另一方面,自回归模型(ARMs)学习在前缀 token 到 上预测第 个 token 。这等价于把位置 到 掩掉再预测 。因此 ARM 训练目标可写成:
Typically, ARMs are trained to predict tokens sequentially from left to right. We refer to this as left-to-right training. However, it’s also possible to train these models to predict tokens sequentially based on a fixed, known permutation of the sequence. We refer to this general approach as order-aware training.
通常 ARMs 按从左到右顺序预测 token,我们称之为从左到右训练。也可按序列的某个固定、已知置换顺序依次预测,我们把这类做法统称为感知顺序的训练。
To understand the comparison between the training objective of MDMs and ARMs, we want to highlight the equivalence between any-order autoregressive loss and MDM loss (Hoogeboom et al., 2021a; Ou et al., 2024). In particular, under conditions of Proposition 2.1, MDM loss is equal to
为理解 MDM 与 ARM 训练目标的对比,我们强调任意顺序自回归损失与 MDM 损失的等价性(Hoogeboom et al., 2021a;Ou et al., 2024)。在命题 2.1 的条件下,MDM 损失等于
$$\displaystyle\mathcal{L}{\theta}=-\mathop{\mathbb{E}}{\begin{subarray}{c}x_{0}\sim p_{\textrm{data}}\
\pi\sim\textrm{Unif}(\mathbb{S}{L})\end{subarray}}\left[\sum{i=0}^{L-1}\log p_{\theta}\left(x_{0}^{\pi(i)}\Big|x_{0}[\pi{i,\ldots,L-1}]\right)\right],$$
where is a uniform distribution over all the permutations of length (See Appendix E.1 for the proof). Observe that if the expectation is only with respect to the identity permutation, then the loss becomes an autoregressive loss. This shows that MDM loss solves exponentially more subproblems than ARM loss. In contrast to ARM loss, MDM does not prefer any particular (e.g., left-to-right) order during the training; therefore, we call its training order-agnostic training.
其中 是长度 的全部置换上的均匀分布(证明见附录 E.1)。若期望只对恒等置换取,损失就退化为自回归损失。由此可见,MDM 损失比 ARM 损失多解指数级个子问题。与 ARM 损失不同,MDM 训练不偏好任何特定顺序(例如从左到右);因此我们称其训练为与顺序无关的训练。
2.1.2 Order-agnostic inference of MDMs
The MDM inference can be decomposed into two steps: (a) randomly selecting a set of positions to unmask and (b) assigning token values to each position via the denoising network . More precisely, we can reformulate the reverse process as follows.
2.1.2 MDM 的与顺序无关推理
MDM 推理可拆成两步:(a)随机选取要揭开的位置集合;(b)用去噪网络 为各位置赋 token 值。更精确地,可将反向过程 重述如下。
Therefore, the inference in MDM is implemented by randomly selecting and then filling each token value according to the posterior probability .
因此,MDM 推理的实现是:随机选取 ,再按后验概率 填入各 token 值。
On the other hand, ARMs are trained to predict tokens sequentially from left to right and therefore, generate tokens also in left-to-right order. In contrast, vanilla MDM inference generates the tokens in a random order.
另一方面,ARMs 按从左到右训练,因而也按从左到右生成;朴素 MDM 推理则按随机顺序生成 token。
3 MDMs train on hard problems
3 MDMs 在困难问题上训练
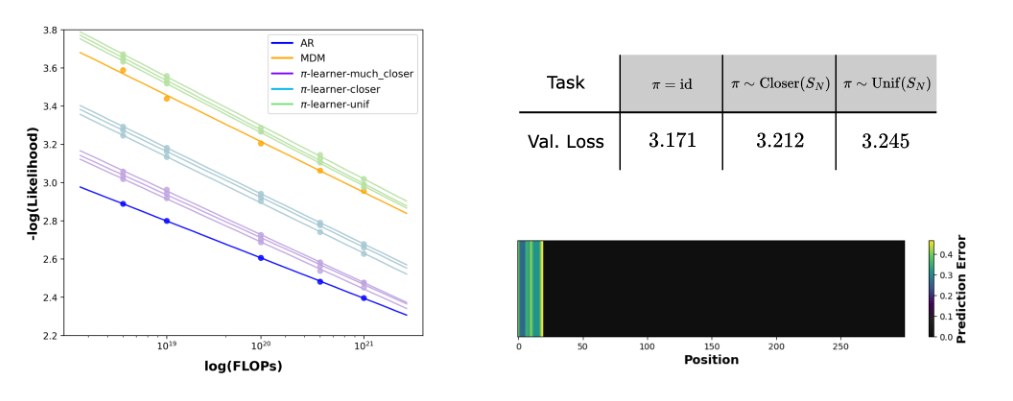
Figure 2: Left: MDMs train on hard problems (Section 3.2). x-axis and y-axis correspond to and , respectively. MDM (Blue) is worse than ARM (Orange) in likelihood modeling. Most masking problems (Other lines) that MDM is trained on are harder than those encountered by ARM, as indicated by small log-likelihoods. Right: Task error imbalance (Section 3.3). MDM’s performance varies across different tasks. For text data (top right), this is indicated by validation loss. For L&O-NAE-SAT (bottom right), MDM performs well on the masking problems for observation positions (light region) but struggles with latent positions (dark region).
图 2:左:MDMs 在困难问题上训练(第 3.2 节)。横轴与纵轴分别为 与 。MDM(蓝)在似然建模上逊于 ARM(橙)。MDM 所训的多数掩码问题(其他曲线)比 ARM 遇到的更难,表现为更小的对数似然。右:任务误差失衡(第 3.3 节)。MDM 在不同任务上表现不一。文本数据(右上)用验证损失体现;对 L&O-NAE-SAT(右下),MDM 在观测位置的掩码问题上表现好(浅色区),在潜变量位置上则吃力(深色区)。
In this section, we provide theoretical and empirical evidence that when the data distribution has left-to-right order (or any fixed known order) then autoregressive training in left-to-right order (or in the known order) is more tractable than MDMs. In particular, for such distributions with fixed order, we show that ARMs can efficiently sample from the distributions but for MDMs, we theoretically and empirically demonstrate that a large portion of masking subproblems can be difficult to learn.
本节给出理论与经验证据:当数据分布具有从左到右顺序(或任一固定已知顺序)时,按该顺序做自回归训练,比 MDMs 更易处理。尤其对这类有固定顺序的分布,我们说明 ARMs 能高效采样;而对 MDMs,我们从理论与实验两方面表明:大量掩码子问题 可能很难学。
In Section 3.1, we show several examples of simple, non-pathological distributions for which: (1) the masking problems encountered during order-aware training (such as in ARMs) are computationally tractable, yet (2) many of the ones encountered during order-agnostic training (such as in MDMs) are computationally intractable. In Section 3.2, we empirically show that text data also exhibits this gap between the computational complexity of order-aware and order-agnostic training and therefore, MDMs train on subproblems of wide variety of complexity (depending on the order/masks). In Section 3.3, we empirically show that the variety in training complexity results in performance imbalance across subproblems: MDMs trained on data from such distributions exhibits small errors on easy subproblems but suffers from large errors on harder ones.
第 3.1 节给出若干简单、非病态分布的例子,满足:(1)感知顺序训练(如 ARMs)遇到的掩码问题在计算上可行;(2)与顺序无关训练(如 MDMs)遇到的许多问题在计算上不可行。第 3.2 节经验上说明文本数据同样存在感知顺序与与顺序无关训练之间的计算复杂度鸿沟,因而 MDMs 在复杂度跨度很大的子问题上训练(取决于顺序/掩码)。第 3.3 节经验上说明:训练复杂度的多样性会带来跨子问题的性能失衡:在这类分布上训练的 MDMs 在容易子问题上误差小,在困难子问题上误差大。
3.1 Benign distributions with hard masking problems
3.1 带困难掩码问题的良性分布
We now describe a simple model of data under which we explore the computational complexity of masking problems and show the contrast between masking problems encountered by MDMs and ARMs.
下面描述一个简单的数据模型,用以考察掩码问题的计算复杂度,并对比 MDMs 与 ARMs 所遇掩码问题的差异。
Definition 3.1.
A latents-and-observations (L&O) distribution is a data distribution over sequence of length with alphabet size (precisely, is over ) is specified by a permutation over indices , number of latent tokens , number of observation tokens such that , prior distribution of latent variables over and efficiently learnable observation functions ,[^1]
定义 3.1。
潜变量与观测(latents-and-observations,L&O)分布是长度 、字母表大小 上的数据分布 (精确地说定义在 上),由以下要素指定:指标 \{1,2,\ldots,L} 上的置换 、潜变量 token 数 、观测 token 数 ()、潜变量在 上的先验 ,以及可高效学习的观测函数 ,[^1]
- • (Latent tokens) For , sample independently from the prior distribution of the latents.
- • (潜变量 token)对 ,独立地从先验 采样 。
- • (Observation tokens) For , sample independently from .
- • (观测 token)对 ,独立地从 采样 。
L&O distributions contain two types of tokens: (1) latent tokens and (2) observation tokens. Intuitively, latent tokens are tokens in the sequence, indexed by that serve as “seeds” that provide randomness in the sequence; the remaining tokens, called observation tokens (indexed by ), are determined as (possibly randomized) functions of the latent tokens via . Observe that L&O distributions specified by a permutation have a natural generation order by permutation .
L&O 分布含两类 token:(1)潜变量 token;(2)观测 token。直观上,由 索引的潜变量 token 充当序列中的「种子」,提供随机性;其余由 索引的观测 token,则经 由潜变量(可能带随机)决定。可见,由置换 指定的 L&O 分布具有沿 的自然生成顺序。
Order-aware training
Order-aware training, i.e. by permuting the sequence so that becomes the identity permutation and then performing autoregressive training, is computationally tractable: predicting given is trivial when as the tokens are independent, and computationally tractable when because only depends on and is efficiently learnable by assumption. In contrast, below we will show examples where if one performs order-agnostic training à la MDMs, one will run into hard masking problems with high probability.
感知顺序的训练
感知顺序训练——即先把序列置换使 变为恒等置换,再做自回归训练——在计算上可行:给定 预测 ,当 时因 token 独立而平凡;当 时, 只依赖 ,且按假设可高效学习。相对地,下文将给出例子:若按 MDM 式做与顺序无关训练,将以高概率撞上困难掩码问题。
Order-agnostic training
We first note that if the observations are given by a cryptographic hash function, then the masking problem of predicting given is computationally intractable by design because it requires inverting the hash function. While this is a well-known folklore observation regarding the role of token ordering in language modeling, it is not entirely satisfying because this construction is worst-case in nature – in real-world data, one rarely trains on sequences given by cryptographic hash functions. Furthermore, it only establishes hardness for a specific masking pattern which need not be encountered in the course of running the reverse process.
与顺序无关的训练
首先指出:若观测 由密码学哈希给出,则在给定 时预测 的掩码问题,本质上要求求逆哈希,因而在设计上计算不可行。这虽是关于语言建模中 token 顺序角色的常见民间观察,却并不完全令人满意:构造是最坏情形的——真实数据很少由密码学哈希生成序列;而且它只对特定掩码模式建立困难性,该模式在反向过程中未必出现。
We provide several simple instances of L&O distributions that address these issues: instead of leveraging delicate cryptographic constructions, they are average-case in nature and furthermore we can establish hardness for typical masking problems encountered along the reverse process.
我们给出若干简单的 L&O 分布实例来回应这些问题:不依赖精巧的密码学构造,而是平均情形的,并且能对反向过程中典型遇到的掩码问题建立困难性。
In all these examples, the hardness results we establish hold even if the algorithm knows all of the parameters of as well as the observation functions . Due to space constraints, here we focus on the following example, deferring two others to Apps. B.1 and B.2.
在所有这些例子中,即使算法已知 的全部参数以及观测函数 ,困难性结论依然成立。因篇幅所限,这里聚焦下面例子,另两个放到附录 B.1 与 B.2。
Example 3.2(Sparse predicate observations).
Consider the following class of L&O distributions. Given arity , fix a predicate function . Consider the set of all ordered subsets of of size and set the total number of observation latents equal to the size of this set (hence ). To sample a new sequence, we first sample latent tokens from the prior distribution and an observation latent corresponding to a -sized subset is given by . In other words, each observation latent corresponds to a -sized subset of and the corresponding observation function is given by .
例 3.2(稀疏谓词观测)。
考虑如下 L&O 分布类。给定元数* ,固定谓词函数 。取 上所有大小为 的有序子集,令观测潜变量总数 等于该集合大小(故 )。采样新序列时,先从先验 采样潜变量 token ;对应于大小为 的子集 的观测潜变量由 给出。换言之,每个观测潜变量对应 的一个 元子集 ,相应观测函数 为 。*
Proposition 3.3.
Let be a sample from an L&O distribution with sparse predicate observations as defined in Example 3.2, with arity and predicate satisfying Assumption B.11, and let be the probability that is satisfied by a random assignment from . Let and be some constants associated with the predicate function (see Definition B.12). Suppose each token in is independently masked with probability , and is the set of indices for the masked tokens. If , then under the 1RSB cavity prediction (see Conjecture B.13), with probability over the randomness of the masking, no polynomial-time algorithm can solve the resulting subproblem of predicting any of the masked tokens among given .
命题 3.3。
设 取自例 3.2 所定义的带稀疏谓词观测的 L&O 分布 ,元数为 ,谓词 满足假设 B.11;令 为随机赋值取自 时 被满足的概率。设 与 为与谓词 相关的常数(见定义 B.12)。若每个 token 独立以概率 被掩码, 为被掩码下标集合,且 ,则在1RSB 腔方法预言*(见猜想 B.13)下,对掩码随机性以概率 ,没有任何多项式时间算法能在给定 时,解出预测 中任一被掩码 token 的子问题。*
The complete proof of the proposition is given in Section B.4. We also provide a proof outline in Section B.3 for a comprehensive understanding.
命题完整证明见第 B.4 节;第 B.3 节给出证明提纲以便把握全貌。
3.2 Empirical evidence of hardness via likelihoods
3.2 经似然度量的困难性经验证据
In the previous section, we provided theoretical evidence that order-aware training is tractable when data has a natural order but the order-agnostic training is not. In this section, we provide empirical evidence to support this claim, using natural text data. Additionally, recent studies (Nie et al., 2024; Zheng et al., 2024) have shown that masked diffusion models (MDMs) underperform compared to autoregressive models (ARMs) on natural text data. In this section, we provide evidence that this performance gap is primarily due to the order-agnostic training of MDMs. Natural text inherently follows a left-to-right token order, and we show that as training deviates from this order, model performance progressively declines.
上一节给出理论证据:数据有自然顺序时,感知顺序训练可行,而与顺序无关训练不可行。本节用自然语言文本提供经验支持。此外,近期研究(Nie et al., 2024;Zheng et al., 2024)表明 MDMs 在自然语言上逊于 ARMs。本节给出证据:这一差距主要来自 MDMs 的与顺序无关训练。自然语言固有地遵循从左到右的 token 顺序;我们说明:训练越偏离该顺序,模型表现越差。
To understand the importance of the order during the training, we use the following setting: Given a permutation of indices , define a -learner to be a likelihood model given as follows:
为理解训练顺序的重要性,采用如下设定:给定指标 \{0,1,\ldots,L-1} 的置换 ,定义 -学习器 为如下似然模型 :
In other words, the -learner predicts the token at position given the clean tokens and masked tokens . If is the identity permutation, this reduces to the standard (left-to-right) autoregressive training. Note that the MDM loss encodes a -learner for every permutation because the MDM loss (1) is equivalent to the average loss of those -learners over sampled from :
换言之,-学习器在干净 token 与掩码 token 的条件下,预测位置 上的 token。若 为恒等置换,则退化为标准(从左到右)自回归训练。注意 MDM 损失对每个置换 都编码了一个 -学习器,因为 MDM 损失(1)等价于对 取平均的那些 -学习器损失:
$$\displaystyle\mathcal{L}{\theta}=-\mathop{\mathbb{E}}{\begin{subarray}{c}x_{0}\sim p_{\textrm{data}}\
\pi\sim\textrm{Unif}(\mathbb{S}{L})\end{subarray}}\left[\sum{i=0}^{L-1}\log p_{\theta}\left(x_{0}^{\pi(i)}\Big|x_{0}[\pi{i,\ldots,L-1}]\right)\right],$$
where denotes the set of all permutations over . The proof of the above equivalence is given in Appendix E. Therefore, by measuring the ‘hardness’ of each -learner, we can probe differences in hardness between arbitrary masking problems and left-to-right masking problems.
其中 表示 \{0,1,\ldots,L-1} 上全部置换的集合。上述等价证明见附录 E。因此,度量每个 -学习器的「难度」,就能探测任意掩码问题与从左到右掩码问题之间的难度差异。
Experimental setup.
We use the Slimpajama dataset (Soboleva et al., 2023) to evaluate the performance of training in different orders. To train a -learner, we employ a transformer with causal attention and use permuted data as input. By varying while maintaining all other training configurations (e.g., model, optimization), we can use the resulting likelihood (computed using Equation 3) as a metric to capture the hardness of subproblems solved by the -learner.
实验设置。
我们用 Slimpajama 数据集(Soboleva et al., 2023)评估不同顺序下的训练表现。训练 -学习器时,采用带因果注意力的 Transformer,并以置换后的数据 为输入。在固定其余训练配置(模型、优化等)下只改变 ,便可用所得似然(按式 3 计算)作为刻画 -学习器所解子问题难度的度量。
In our experiments, the sequence length is , so repeating the scaling laws for each is infeasible. Instead, we sample and examine the scaling law of the -learner’s likelihood. We leverage the codebase from (Nie et al., 2024), where the baseline scaling laws of MDM and ARM were introduced. Moreover, given that RoPE has an inductive bias towards left-to-right ordering, we employ a learnable positional embedding layer for all experiments to correct this. Consequently, we also re-run the baseline results, where RoPE was employed. To investigate how the distance between and the identity permutation affects the scaling law, we consider two interpolating distributions over permutations between (i.e, MDM training) and the point mass at the identical permutation (i.e, ARM training). We sample three permutations from the interpolating distribution and and plot the scaling law for each of the permutation. Due to space constraints, we provide further experimental details in Appendix C.1.
实验中序列长度 ,对每个 重复缩放律不可行。于是我们采样 ,考察 -学习器似然的缩放律。我们借用 Nie et al.(2024)的代码库,其中给出了 MDM 与 ARM 的基线缩放律。又因 RoPE 对从左到右顺序有归纳偏置,所有实验改用可学习位置嵌入以纠正;相应地也重跑了原先使用 RoPE 的基线。为考察 与恒等置换的距离如何影响缩放律,我们考虑在 (即 MDM 训练)与恒等置换上的点质量(即 ARM 训练)之间的两种插值置换分布。从插值分布与 各采样三个置换,并画出各自的缩放律。更多实验细节因篇幅放在附录 C.1。
Results.
As shown in Fig. 2, the scaling law for a -learner with uniformly random is worse than that of an ARM. This elucidates the inherent hardness of masking problems beyond left-to-right prediction and also explains why MDM, which is trained simultaneously on all , is worse than ARM in likelihood modeling. Additionally, as gets closer to the identity permutation, the scaling laws also get closer to ARM (-learner-closer and -learner-much-closer in Fig. 2). This also supports the common belief that ARM is a good fit for text data as it inherently follows a left-to-right ordering.
结果。
如图 2 所示,均匀随机 的 -学习器缩放律逊于 ARM。这说明除从左到右预测之外,掩码问题 固有更难,也解释了为何同时在所有 上训练的 MDM,在似然建模上逊于 ARM。此外,当 越接近恒等置换,缩放律也越接近 ARM(图 2 中的 -learner-closer 与 -learner-much-closer)。这也支持常见信念:ARM 适合文本,因为文本固有从左到右顺序。
That said, it should also be noted that even though MDMs are trained on exponentially more masking problems than ARM ( versus ), its performance is not significantly worse than -learners. We attribute this to the blessing of task diversity; multi-task training can benefit both the optimization dynamics (Kim et al., 2024) and validation performance (Tripuraneni et al., 2021; Maurer et al., 2016; Ruder, 2017) due to positive transfers across tasks.
不过也应注意:尽管 MDMs 比 ARM 多训指数级掩码问题( 对 ),其表现并不显著差于单个 -学习器。我们将其归因于任务多样性之福:多任务训练可因任务间正向迁移而同时惠及优化动态(Kim et al., 2024)与验证表现(Tripuraneni et al., 2021;Maurer et al., 2016;Ruder, 2017)。
3.3 Error is imbalanced across masking problems
3.3 误差在掩码问题上失衡
In previous sections, we have demonstrated that the hardness of different masking problems can vary significantly, potentially hindering the MDM’s learning. In this section, we provide empirical evidence that the MDM’s final performance exhibits a similar imbalance across subproblems. Details are provided in App. C.2.
前几节已表明不同掩码问题 的难度可相差很大,可能妨碍 MDM 学习。本节给出经验证据:MDM 的最终表现在子问题上呈现类似失衡。细节见附录 C.2。
L&O-NAE-SAT.
Consider an L&O distribution with given by the identity permutation and where each observation is deterministically given by for some randomly chosen (prefixed) triples . For an MDM trained on this distribution, we measure the error it achieves on each task via , where denotes the Bayes-optimal predictor. Technically, we do not have access to this, so instead we train another MDM for a much larger number of iterations and use this as a proxy. Fig. 2 reveals that prediction tasks for latent positions (light region) exhibit larger errors compared to those for observation positions (dark region).
L&O-NAE-SAT。
考虑 为恒等置换的 L&O 分布,每个观测 由 确定性给出,其中三元组 预先随机选定。对在该分布上训练的 MDM,我们用 度量各任务 上的误差,其中 表示贝叶斯最优预测器。技术上我们得不到它,于是另训一个迭代次数远更多的 MDM 作代理。图 2 显示:潜变量位置上的预测任务(浅色区)误差大于观测位置(深色区)。
Text.
Here we revisit the text experiment from Section 3.2. Since we do not have access to the Bayes-optimal predictor, we use the metric . This captures the accumulation of error across subproblems , since minimizes this metric. Fig. 2 shows a clear gap between different subproblems.
文本。
这里回顾第 3.2 节的文本实验。因得不到贝叶斯最优预测器,我们采用度量 。它刻画子问题 上误差的累积,因为 极小化该度量。图 2 显示不同子问题之间存在清晰差距。
The theoretical and empirical evidence demonstrates that MDMs perform better in estimating for some subproblems than for others. We therefore want to avoid encountering hard subproblems at inference time. In the next section, we show that while vanilla MDM inference can run into such subproblems, simple modifications at the inference stage can effectively circumvent these issues, resulting in dramatic, training-free performance improvements.
理论与经验证据表明:对某些子问题 ,MDMs 估计 更好。因此我们希望在推理时避开困难子问题 。下一节将说明:朴素 MDM 推理可能撞上这类子问题,但推理阶段的简单修改就能有效规避,从而带来显著的无需再训练的性能提升。
4 MDMs can plan around hard problems
4 MDMs 可以绕开困难问题来规划
We previously argued that due to the complex nature of masking subproblems, MDM must perform poorly on certain ones . Therefore, during vanilla MDM inference, MDM inevitably encounters such difficult subproblems at Step (b). While this might suggest that we need to fundamentally revisit how MDMs are trained, in this section we show that, surprisingly, simple modifications at the inference stage—without any further training—can sidestep these issues and lead to significant performance improvements.
前文论证:因掩码子问题复杂,MDM 必然在某些 上表现差。于是朴素 MDM 推理在步骤(b)难免撞上困难子问题。这似乎意味着必须从根本上重审 MDM 的训练方式;但本节将说明:出人意料的是,仅在推理阶段做简单修改——无需再训练——就能绕开这些问题,并带来显著性能提升。
MDM offers multiple sampling paths.
The vanilla MDM inference (Algorithm 2.1.2) aim to align the intermediate distributions with the forward process, as used in continuous diffusion. However, unlike continuous diffusion, the reverse process of MDM allows multiple valid sampling paths (different orders of unmasking the tokens) that match the starting distribution of the forward process of MDM.
MDM 提供多条采样路径。
朴素 MDM 推理(算法 2.1.2)旨在让中间分布与前向过程对齐,这与连续扩散的用法一致。但与连续扩散不同,MDM 的反向过程允许多条有效采样路径(不同的揭开 token 顺序),它们都与 MDM 前向过程的起始分布匹配。
We first show that when we have an ideal MDM that perfectly solves all masking problems, i.e., , then using any sampling path (unmasking the tokens in any order) results in the same distribution. Consider the following sampler: For every step, is a set with one index selected agnostically (without following any distribution). For any clean sample generated by this sampler, note that by chain rule, and this is equal to . Therefore, other choices of , not necessarily following Algorithm 2.1.2, still capture the true likelihood.
我们首先说明:若有理想 MDM,能完美解所有掩码问题,即 ,则沿任意采样路径(按任意顺序揭开 token)得到的分布相同。考虑如下采样器:每一步 是不可知地(不遵循特定分布)选出的单下标集合。对该采样器生成的任一干净样本 ,由链式法则有 ,且等于 。因此,即便 的选取不遵循算法 2.1.2,仍能刻画真实似然。
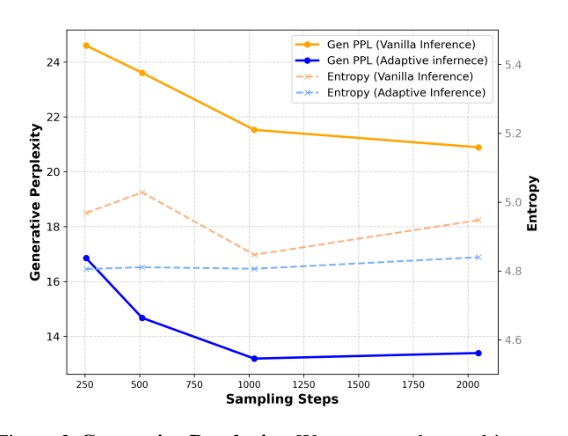
Figure 3: Generative Perplexity. We compare the resulting generative perplexity (GenPPL) of adaptive vs. vanilla MDM inference. We employ a pretrained M MDM and LLaMA-B (Touvron et al., 2023) as inference and evaluation, respectively. Adaptive MDM inference ( Blue) leads to a substantial reduction in generative perplexity, while maintaining the entropy.
图 3:生成困惑度。 比较自适应与朴素 MDM 推理的生成困惑度(GenPPL)。推理用预训练 170M MDM,评估用 LLaMA-7B(Touvron et al., 2023)。自适应 MDM 推理(蓝)在保持熵的同时大幅降低生成困惑度。
In practice, unlike this ideal case, MDM does not perform equally well on all subproblems, as shown in Section 3.3. Consequently, different sampling paths result in varying likelihood modeling abilities. Motivated by this observation, we consider adaptive inference for MDMs:
实践中,与理想情形不同,MDM 并非在所有子问题上同样出色,如第 3.3 节所示。因而不同采样路径对应不同的似然建模能力。受此启发,我们考虑 MDMs 的自适应推理:
Instead of selecting randomly, adaptive MDM inference leverages an oracle to select strategically to avoid hard masking problems. This naturally raises the question of how to design an effective oracle .
不再随机选取 ,自适应 MDM 推理借助 oracle 策略性地选择 ,以避开困难掩码问题。这自然引出如何设计有效 oracle 的问题。
In the following sections, we demonstrate that adaptive MDM inference with careful choices of enhance MDM’s likelihood matching ability. In other words, a pretrained MDM, even if it performs poorly on certain hard subproblems, still contains sufficient information to avoid them when paired with an effective oracle .
下文各节表明:搭配精心选择的 ,自适应 MDM 推理能增强 MDM 的似然匹配能力。换言之,即便预训练 MDM 在某些困难子问题上表现差,只要配上有效的 oracle ,仍含有足够信息去避开它们。
4.1 Effective design of ordering oracle
4.1 顺序 oracle 的有效设计
We introduce two different oracles, Top probability and Top probability margin. Intuitively, both strategies are based on the idea that should be selected based on how “certain” the model is about each position. We caution that these strategies should not be confused with notions like nucleus sampling in ARMs (Holtzman et al., 2019); the oracles we describe are for selecting the position of the next token to decode, rather than the value, and thus are only meaningful in the context of MDMs.
我们引入两类 oracle:最高概率(Top probability)与最高概率间隔(Top probability margin)。直观上,两者都基于「应按模型对各位的『确定程度』来选 」。需注意:它们不应与 ARMs 中的 nucleus sampling 等概念混淆(Holtzman et al., 2019);这里的 oracle 用于选择下一步解码的位置而非取值,因而只在 MDMs 语境下有意义。
| () | Vanilla inference | Adaptive inference |
|---|---|---|
| 78.06% | 93.76% | |
| 75.70% | 93.54% | |
| 74.60% | 92.21% | |
| 67.94% | 90.01% | |
| 62.84% | 88.91% |
Table 1: L&O-NAE-SAT. Adaptive MDM inference achieves better likelihood matching than vanilla MDM inference. Note that naive guessing leads to accuracy, indicating that vanilla inference performs similarly or worse than naive guessing.
| () | 朴素推理 | 自适应推理 |
|---|---|---|
| 78.06% | 93.76% | |
| 75.70% | 93.54% | |
| 74.60% | 92.21% | |
| 67.94% | 90.01% | |
| 62.84% | 88.91% |
表 1:L&O-NAE-SAT。自适应 MDM 推理的似然匹配优于朴素 MDM 推理。注意朴素猜测准确率约 75%,说明朴素推理与之相当或更差。
Top probability (Zheng et al., 2023).
Suppose we want to unmask positions at time step , i.e., select . In the top probability, the uncertainty of a position is estimated by the maximum probability assigned to any value in the vocabulary. More precisely, the certainty at position is and .
最高概率(Zheng et al., 2023)。
设在时间步 要揭开 个位置,即选 。在最高概率策略中,某位置的不确定性由词表上任一取值被赋予的最大概率估计。更精确地,位置 的确定性为 ,且 。
Top probability strategy is a good proxy for many tasks and works well in practice (Zheng et al., 2023; Ye et al., 2024; Wang et al., 2024). However, this approach can often provide misleading estimates of uncertainty. Consider when an MDM is confused between two token values, thus assigning them almost equal but high probabilities. In this case, unmasking according to top probability may still choose to unmask this position, despite its uncertainty. To mitigate this issue, we propose the following alternative strategy.
最高概率策略对许多任务是良好代理,实践中也有效(Zheng et al., 2023;Ye et al., 2024;Wang et al., 2024)。但它常会误估不确定性。例如当 MDM 在两个 token 取值之间摇摆、给它们几乎相等却都偏高的概率时,按最高概率仍可能选择揭开该位置,尽管其实并不确定。为缓解这一问题,我们提出如下替代策略。
Top probability margin.
In this strategy, the uncertainty of a position is instead estimated using the absolute difference between the two most probable values at position . More precisely, if and are the two most probable values in vocabulary according to in position , the certainty in the position is given by and . When multiple values have similar probabilities at a position, top probability margin strategy will provide a better estimate of the uncertainty of a position, and when there is a single best choice of value then top probability and top probability margin work similarly.
最高概率间隔。
该策略改用位置 上两个最可能取值概率之差的绝对值来估计不确定性。更精确地,若按 ,词表中最可能的两个取值是 与 ,则该位置的确定性为 ,且 。当某位置多个取值概率接近时,最高概率间隔能更好估计不确定性;当存在单一最佳取值时,两者表现相近。
| Method | # Param | Accuracy |
|---|---|---|
| ARM (w/o ordering) | 42M | 9.73% |
| ARM (with ordering) | 87.18% | |
| MDM (vanilla) | 6M | 6.88% |
| MDM (Top probability) | 18.51% | |
| MDM (Top prob. margin) | 89.49% |
Table 2: Comparison of accuracy for solving the Sudoku puzzle.
| 方法 | 参数量 | 准确率 |
|---|---|---|
| ARM(无顺序信息) | 42M | 9.73% |
| ARM(有顺序信息) | 87.18% | |
| MDM(朴素) | 6M | 6.88% |
| MDM(最高概率) | 18.51% | |
| MDM(最高概率间隔) | 89.49% |
表 2:数独求解准确率对比。
4.2 Adaptive MDM inference
4.2 自适应 MDM 推理
In this section, we experimentally validate that adaptive MDM inference helps MDMs avoid hard subproblems, leading to better likelihood matching. We first show our results on L&O-NAE-SAT and text data, before turning to our primary application to logic puzzles.
本节实验验证:自适应 MDM 推理帮助 MDMs 避开困难子问题,从而更好匹配似然。我们先报告 L&O-NAE-SAT 与文本上的结果,再转向主要应用——逻辑谜题。
L&O-NAE-SAT and text data. For the L&O-NAE-SAT distribution defined in Section 3.3, we evaluate the effectiveness of adaptive inference by measuring the accuracy in predicting the observation tokens. Table 1 in the appendix reveals a clear improvement over vanilla inference. For the text dataset, we evaluate using the standard metric of generative perplexity, by which likelihood is measured by a large language model. We also compute the entropy of the generated samples to ensure both inference strategies exhibit similar levels of diversity. As shown in Fig. 3, we observe a substantial decrease in generative perplexity using adaptive inference. We defer further experimental details to Appendix D.1.
L&O-NAE-SAT 与文本。 对第 3.3 节定义的 L&O-NAE-SAT 分布,我们通过观测 token 的预测准确率评估自适应推理;附录表 1 显示相对朴素推理有清晰提升。对文本数据,我们用标准的生成困惑度评估,似然由大语言模型度量;同时计算生成样本的熵,以确保两种推理策略多样性水平相近。如图 3,自适应推理大幅降低生成困惑度。更多实验细节见附录 D.1。
Logic puzzles. We consider two different types of logic puzzles: Sudoku and Zebra (Einstein) puzzles. Intuitively, for Sudoku, some empty (masked) cells are significantly easier to predict than others and we want to choose the cells that are easier to predict during the inference. We evaluate the effectiveness of adaptive MDM inference over vanilla MDM inference in selecting such cells.[^2]
逻辑谜题。 我们考虑两类逻辑谜题:数独与斑马(爱因斯坦)谜题。直观上,数独中某些空(掩码)格远比其他格更容易预测,推理时应优先选择易预测的格子。我们评估自适应相对朴素 MDM 推理在选格上的效力。[^2]
To measure the performance of an inference method, we use the percentage of correctly solved puzzles. For both puzzles, we use train and test datasets from (Shah et al., 2024). For the Sudoku puzzle (Table 2) we observe that adaptive MDM inference, in particular, Top probability margin strategy, obtains substantially higher accuracy (89.49%) compared to vanilla MDM inference (6.88%). Additionally, Top probability margin obtains higher accuracy (89.49%) than Top probability strategy (18.51%). As mentioned in Section 4.1, this is because Top probability margin strategy more reliably estimates uncertainty when multiple competing values are close in probability at a given position, as is often the case in Sudoku. For the Zebra puzzle, as shown in Table 3, we observe a consistent result: Top probability (98.5%) and Top probability margin (98.3%) outperform vanilla MDM inference (76.9%).
推理方法的表现用正确解出的谜题百分比衡量。两类谜题均使用 Shah et al.(2024)的训练与测试集。对数独(表 2),自适应 MDM 推理——尤其是最高概率间隔——准确率(89.49%)远高于朴素推理(6.88%);也高于最高概率策略(18.51%)。如第 4.1 节所述,这是因为当某位置多个竞争取值概率接近时(数独中常见),最高概率间隔对不确定性的估计更可靠。对斑马谜题,表 3 显示一致结果:最高概率(98.5%)与最高概率间隔(98.3%)均优于朴素推理(76.9%)。
| Method | # Param | Accuracy |
|---|---|---|
| ARM (w/o ordering) | 42M | 80.31 % |
| ARM (with ordering) | 91.17 % | |
| MDM (vanilla) | 19M | 76.9 % |
| MDM (Top probability) | 98.5 % | |
| MDM (Top prob. margin) | 98.3 % |
Table 3: Comparison of accuracy for solving the Zebra puzzle.
| 方法 | 参数量 | 准确率 |
|---|---|---|
| ARM(无顺序信息) | 42M | 80.31 % |
| ARM(有顺序信息) | 91.17 % | |
| MDM(朴素) | 19M | 76.9 % |
| MDM(最高概率) | 98.5 % | |
| MDM(最高概率间隔) | 98.3 % |
表 3:斑马谜题求解准确率对比。
4.3 Eliciting sequence-dependent reasoning paths using adaptive MDM inference in logic puzzles
4.3 用自适应 MDM 推理引出依赖序列的推理路径
In this section, we study the effectiveness of adaptive MDM inference in finding the right reasoning/generation order for tasks where every sequence has a different “natural” order. To do so, we will compare the performance of adaptive MDM inference to that of ARM on Sudoku and Zebra puzzles. For these puzzles, the natural order of generation is not only different from left-to-right, but it is also sequence-dependent. For such tasks, prior works have shown that ARMs struggle if the information about the order is not provided during the training (Shah et al., 2024; Lehnert et al., 2024). Therefore, to obtain a strong baseline, we not only consider an ARM trained without the order information but also consider an ARM trained with the order information for each sequence in the training data. Note that the latter is a much stronger baseline than the former as one can hope to teach the model to figure out the correct order by some form of supervised teacher forcing (as performed in Shah et al. (2024); Lehnert et al. (2024)), eliminating the issue of finding the right order in an unsupervised manner.
本节研究:当每条序列有不同「自然」顺序时,自适应 MDM 推理能否找到正确的推理/生成顺序。为此,我们在数独与斑马谜题上比较自适应 MDM 推理与 ARM。对这些谜题,自然生成顺序不仅异于从左到右,而且依赖具体序列。先前工作表明:若训练时不提供顺序信息,ARMs 会吃力(Shah et al., 2024;Lehnert et al., 2024)。因此,为得到强基线,我们既考虑不带顺序信息训练的 ARM,也考虑对训练数据中每条序列提供顺序信息的 ARM。后者强得多:可期望通过某种监督教师强制教会模型正确顺序(如 Shah et al., 2024;Lehnert et al., 2024 所做),从而消除无监督找序的问题。
We compare ARMs and MDMs for Sudoku in Table 2 and Zebra puzzles in Table 3. We observe that for both, Top probability margin-based adaptive MDM inference not only outperforms the ARM trained without ordering information, but it even outperforms the ARM trained with ordering information! This shows that the unsupervised way of finding the correct order and solving such logic puzzles using adaptive MDM inference outperforms the supervised way of finding the correct order and solving such puzzles using an ARM, and is significantly less computationally intensive.
表 2(数独)与表 3(斑马)比较 ARMs 与 MDMs。我们观察到:基于最高概率间隔的自适应 MDM 推理不仅胜过不带顺序信息训练的 ARM,甚至胜过带顺序信息训练的 ARM!这说明:用自适应 MDM 推理以无监督方式找正确顺序并解逻辑谜题,胜过用 ARM 以监督方式找正确顺序并解题,且计算开销显著更小。
4.4 Adaptive MDM inference on natural language tasks
4.4 自然语言任务上的自适应 MDM 推理
To examine the effect of different inference strategies on text benchmarks, we adapted LLaDA, the 8B MDM model from (Nie et al., 2025). We compare three inference strategies: vanilla, top probability, and top probability margin. The results are presented in Table 4.
为考察不同推理策略对文本基准的影响,我们改编 Nie et al.(2025)的 80 亿参数 MDM 模型 LLaDA。比较三种推理策略:朴素、最高概率、最高概率间隔。结果见表 4。
We see that both adaptive MDM inference strategies, top probability and top probability margin, consistently outperform vanilla MDM inference. Notably, top probability margin demonstrates a clear advantage over top probability in challenging tasks like HumanEval-Multiline (infill), HumanEval-Split Line (infill), and Math. This is because Top probability margin provides a more reliable estimate of uncertainty when multiple tokens have similar probabilities, a frequent occurrence in these difficult tasks. These results further underscore the potential for developing new, sophisticated adaptive inference strategies for various tasks. We provide experimental details in Appendix D.3.
可见两种自适应策略均稳定优于朴素推理。尤其在 HumanEval-Multiline(填空)、HumanEval-Split Line(填空)与数学等难题上,最高概率间隔相对最高概率优势明显。因为当多个 token 概率接近时(这些难题中常见),最高概率间隔对不确定性估计更可靠。这些结果进一步凸显:可为不同任务开发更精巧的自适应推理策略。实验细节见附录 D.3。
| Method | HumanEval-Single | HumanEval-Multi | HumanEval-Split | Math | MMLU | ROCStories |
|---|---|---|---|---|---|---|
| Vanilla | 31.8% | 16.5% | 14.2% | 28.5% | 33.2% | 21.23% |
| Top probability | 32.9% | 20.8% | 18.4% | 31.3% | 36.5% | 21.10% |
| Top prob. margin | 33.5% | 25.4% | 22.3% | 34.3% | 35.4% | 21.41% |
Table 4: Performance of different inference strategies for LLaDa 8B model on coding and math tasks.
| 方法 | HumanEval-Single | HumanEval-Multi | HumanEval-Split | 数学 | MMLU | ROCStories |
|---|---|---|---|---|---|---|
| 朴素 | 31.8% | 16.5% | 14.2% | 28.5% | 33.2% | 21.23% |
| 最高概率 | 32.9% | 20.8% | 18.4% | 31.3% | 36.5% | 21.10% |
| 最高概率间隔 | 33.5% | 25.4% | 22.3% | 34.3% | 35.4% | 21.41% |
表 4:LLaDa 8B 在编程与数学任务上不同推理策略的表现。
4.5 Easy to hard generalization
4.5 由易到难的泛化
In the previous section we showed that when the training and inference sequences come from the same distribution, order-agnostic training of MDMs combined with adaptive inference can perform very well on logic puzzles. To evaluate if the model has learned the correct way of solving the puzzles and test the robustness of adaptive inference, we also test the MDMs on harder puzzles than the ones from training, for Sudoku.
上一节说明:当训练与推理序列同分布时,MDMs 的与顺序无关训练加上自适应推理,在逻辑谜题上可表现很好。为检验模型是否学到正确解法以及自适应推理的稳健性,我们还在比训练更难的数独上测试 MDMs。
We keep the training dataset the same as proposed in Shah et al. (2024). Shah et al. (2024) created this dataset from Radcliffe (2020) by selecting the puzzles that can be solved using 7 fixed strategies and do not require backtracking-based search. We use the remaining puzzles in Radcliffe (2020) as our hard dataset. Hence, these puzzles all use a strategy not seen during training and/or backtracking to obtain the correct solution.
训练集与 Shah et al.(2024)相同。Shah et al.(2024)从 Radcliffe(2020)中筛出可用 7 种固定策略、无需回溯搜索即可求解的谜题。我们把 Radcliffe(2020)中其余谜题作为困难集;它们都用到训练未见的策略和/或需要回溯才能得到正解。
| Method | Param | Accuracy |
|---|---|---|
| ARM (with ordering) | 42M | 32.57 % |
| MDM (random) | 6M | 3.62 % |
| MDM (Top probability) | 9.44 % | |
| MDM (Top prob. margin) | 49.88 % |
Table 5: Comparison of accuracy for solving the hard Sudokus.
| 方法 | 参数量 | 准确率 |
|---|---|---|
| ARM(有顺序信息) | 42M | 32.57 % |
| MDM(随机) | 6M | 3.62 % |
| MDM(最高概率) | 9.44 % | |
| MDM(最高概率间隔) | 49.88 % |
表 5:困难数独求解准确率对比。
We measure the accuracy of MDMs and ARMs on the hard test set and present the results in Table 5. We see that the Top probability margin-based adaptive MDM inference strategy (49.88%) again significantly outperforms ARMs trained with order information (32.57%). In particular, although the accuracy drops for both methods due to the more challenging test set, MDMs with adaptive inference appear to be more robust to this distribution shift than ARMs. We believe this is due to the fact that MDMs try to solve a significantly higher number of infilling problems than ARMs ( compared to ) and therefore are able to extract knowledge about the problem more efficiently than ARMs.
我们在困难测试集上度量 MDMs 与 ARMs 的准确率,结果见表 5。基于最高概率间隔的自适应 MDM 推理(49.88%)再次显著胜过带顺序信息训练的 ARMs(32.57%)。尽管因测试更难两者准确率都下降,带自适应推理的 MDMs 似乎比 ARMs 对该分布偏移更稳健。我们相信这是因为 MDMs 试图解的填空问题远多于 ARMs( 对 ),因而能比 ARMs 更高效地抽取问题相关知识。
5 Conclusion
5 结论
In this work, we examined the impact of token generation order on training and inference in MDMs. We provided theoretical and experimental evidence that MDMs train on hard masking problems. We also demonstrated that adaptive inference strategies can be used to sidestep these hard problems. For logic puzzles, we find that this leads to dramatic improvements in performance not just over vanilla MDMs, but even over ARMs trained with teacher forcing to learn the right order of decoding. An important direction for future work is to go beyond the relatively simple adaptive strategies to find a better generation order like top probability and top probability margin considered here.
本文考察了 token 生成顺序对 MDMs 训练与推理的影响。我们给出理论与实验证据:MDMs 在困难掩码问题上训练;并表明自适应推理策略可用于绕开这些困难问题。对逻辑谜题,这带来的提升不仅远超朴素 MDMs,甚至超过经教师强制学习正确解码顺序的 ARMs。未来重要方向是:超越本文考虑的最高概率与最高概率间隔等相对简单的自适应策略,寻找更好的生成顺序。
Acknowledgements.
JK thanks Kiwhan Song for discussions about MDM training. KS and VK are supported by the NSF AI Institute for Foundations of Machine Learning (IFML). KS and VK thank the computing support on the Vista GPU Cluster through the Center for Generative AI (CGAI) and the Texas Advanced Computing Center (TACC) at UT Austin. KS thanks Nishanth Dikkala for the initial discussions about the project. SK acknowledges: this work has been made possible in part by a gift from the Chan Zuckerberg Initiative Foundation to establish the Kempner Institute for the Study of Natural and Artificial Intelligence and support from the Office of Naval Research under award N00014-22-1-2377. SC is supported by the Harvard Dean’s Competitive Fund for Promising Scholarship and thanks Brice Huang and Sidhanth Mohanty for enlightening discussions about computational-statistical tradeoffs for planted CSPs.
致谢。
JK 感谢 Kiwhan Song 关于 MDM 训练的讨论。KS 与 VK 得到 NSF AI Institute for Foundations of Machine Learning(IFML)支持。KS 与 VK 感谢 UT Austin 生成式 AI 中心(CGAI)与得州先进计算中心(TACC)通过 Vista GPU 集群提供的计算支持。KS 感谢 Nishanth Dikkala 对项目的初期讨论。SK 致谢:本工作部分得益于 Chan Zuckerberg Initiative Foundation 的捐赠,用以建立 Kempner Institute for the Study of Natural and Artificial Intelligence,以及海军研究办公室资助 N00014-22-1-2377。SC 得到 Harvard Dean’s Competitive Fund for Promising Scholarship 支持,并感谢 Brice Huang 与 Sidhanth Mohanty 关于种植 CSP 计算—统计权衡的启发性讨论。
Impact statement
影响声明
This paper advances the understanding of discrete diffusion models, contributing to the broader field of Machine Learning. There are many potential societal consequences of our work, none of which we feel must be specifically highlighted here.
本文推进对离散扩散模型的理解,贡献于更广阔的机器学习领域。我们的工作可能带来多种社会影响,但作者认为无需在此特别强调其中某一种。
References
参考文献
Alaoui & Gamarnik (2024) Alaoui, A. E. and Gamarnik, D. Hardness of sampling solutions from the symmetric binary perceptron. arXiv preprint arXiv:2407.16627 , 2024.
Alekhnovich (2003) Alekhnovich, M. More on average case vs approximation complexity. In 44th Annual IEEE Symposium on Foundations of Computer Science, 2003. Proceedings. , pp. 298–307. IEEE, 2003.
Aubin et al. (2019) Aubin, B., Perkins, W., and Zdeborová, L. Storage capacity in symmetric binary perceptrons. Journal of Physics A: Mathematical and Theoretical , 52(29):294003, 2019.
Austin et al. (2021) Austin, J., Johnson, D. D., Ho, J., Tarlow, D., and van den Berg, R. Structured denoising diffusion models in discrete state-spaces. NeruIPS , 2021.
Bavarian et al. (2022) Bavarian, M., Jun, H., Tezak, N., Schulman, J., McLeavey, C., Tworek, J., and Chen, M. Efficient training of language models to fill in the middle, 2022. URL https://arxiv.org/abs/2207.14255 .
Bormashenko (2011) Bormashenko, O. A coupling argument for the random transposition walk. arXiv preprint arXiv: 1109.3915 , 2011.
Chang et al. (2022) Chang, H., Zhang, H., Jiang, L., Liu, C., and Freeman, W. T. Maskgit: Masked generative image transformer. CVPR , 2022.
Chen & Ying (2024) Chen, H. and Ying, L. Convergence analysis of discrete diffusion model: Exact implementation through uniformization. arXiv preprint arXiv: 2402.08095 , 2024.
Chen et al. (2024) Chen, X., Chi, R. A., Wang, X., and Zhou, D. Premise order matters in reasoning with large language models. arXiv preprint arXiv:2402.08939 , 2024.
Decelle et al. (2011) Decelle, A., Krzakala, F., Moore, C., and Zdeborová, L. Asymptotic analysis of the stochastic block model for modular networks and its algorithmic applications. Phys. Rev. E , 84:066106, Dec 2011.
Devlin et al. (2019) Devlin, J., Chang, M.-W., Lee, K., and Toutanova, K. BERT: Pre-training of deep bidirectional transformers for language understanding. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) , pp. 4171–4186, 2019.
Gamarnik (2021) Gamarnik, D. The overlap gap property: A topological barrier to optimizing over random structures. Proceedings of the National Academy of Sciences , 118(41):e2108492118, 2021.
Golovneva et al. (2024) Golovneva, O., Allen-Zhu, Z., Weston, J., and Sukhbaatar, S. Reverse training to nurse the reversal curse. arXiv preprint arXiv:2403.13799 , 2024.
Gong et al. (2024) Gong, S., Agarwal, S., Zhang, Y., Ye, J., Zheng, L., Li, M., An, C., Zhao, P., Bi, W., Han, J., et al. Scaling diffusion language models via adaptation from autoregressive models. arXiv preprint arXiv:2410.17891 , 2024.
Ho et al. (2020) Ho, J., Jain, A., and Abbeel, P. Denoising diffusion probabilistic models. Advances in neural information processing systems , 33:6840–6851, 2020.
Hoffmann et al. (2022) Hoffmann, J., Borgeaud, S., Mensch, A., Buchatskaya, E., Cai, T., Rutherford, E., Casas, D. d. L., Hendricks, L. A., Welbl, J., Clark, A., et al. Training compute-optimal large language models. arXiv preprint arXiv:2203.15556 , 2022.
Holtzman et al. (2019) Holtzman, A., Buys, J., Du, L., Forbes, M., and Choi, Y. The curious case of neural text degeneration. arXiv preprint arXiv:1904.09751 , 2019.
Hoogeboom et al. (2021a) Hoogeboom, E., Gritsenko, A. A., Bastings, J., Poole, B., Berg, R. v. d., and Salimans, T. Autoregressive diffusion models. arXiv preprint arXiv:2110.02037 , 2021a.
Hoogeboom et al. (2021b) Hoogeboom, E., Nielsen, D., Jaini, P., Forré, P., and Welling, M. Argmax flows and multinomial diffusion: Learning categorical distributions. NeurIPS , 2021b.
Kaplan et al. (2020) Kaplan, J., McCandlish, S., Henighan, T., Brown, T. B., Chess, B., Child, R., Gray, S., Radford, A., Wu, J., and Amodei, D. Scaling laws for neural language models. arXiv preprint arXiv:2001.08361 , 2020.
Kim et al. (2024) Kim, J., Kwon, S., Choi, J. Y., Park, J., Cho, J., Lee, J. D., and Ryu, E. K. Task diversity shortens the icl plateau. arXiv preprint arXiv:2410.05448 , 2024.
Kitouni et al. (2025) Kitouni, O., Nolte, N. S., Williams, A., Rabbat, M., Bouchacourt, D., and Ibrahim, M. The factorization curse: Which tokens you predict underlie the reversal curse and more. Advances in Neural Information Processing Systems , 37:112329–112355, 2025.
Krzakala & Zdeborová (2009) Krzakala, F. and Zdeborová, L. Hiding quiet solutions in random constraint satisfaction problems. Physical review letters , 102(23):238701, 2009.
Lehnert et al. (2024) Lehnert, L., Sukhbaatar, S., Su, D., Zheng, Q., McVay, P., Rabbat, M., and Tian, Y. Beyond a*: Better planning with transformers via search dynamics bootstrapping. 2024.
Liao et al. (2020) Liao, Y., Jiang, X., and Liu, Q. Probabilistically masked language model capable of autoregressive generation in arbitrary word order. In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics , pp. 263–274. Association for Computational Linguistics, 2020.
Liu et al. (2024a) Liu, A., Broadrick, O., Niepert, M., and Broeck, G. V. d. Discrete copula diffusion. arXiv preprint arXiv:2410.01949 , 2024a.
Liu et al. (2022) Liu, S., Mohanty, S., and Raghavendra, P. On statistical inference when fixed points of belief propagation are unstable . In 2021 IEEE 62nd Annual Symposium on Foundations of Computer Science (FOCS) , pp. 395–405. IEEE Computer Society, 2022.
Liu et al. (2024b) Liu, S., Nam, J., Campbell, A., Stärk, H., Xu, Y., Jaakkola, T., and Gómez-Bombarelli, R. Think while you generate: Discrete diffusion with planned denoising. arXiv preprint arXiv:2410.06264 , 2024b.
Loshchilov & Hutter (2017) Loshchilov, I. and Hutter, F. Decoupled weight decay regularization. arXiv preprint arXiv:1711.05101 , 2017.
Lou et al. (2024) Lou, A., Meng, C., and Ermon, S. Discrete diffusion modeling by estimating the ratios of the data distribution. ICML , 2024.
Maurer et al. (2016) Maurer, A., Pontil, M., and Romera-Paredes, B. The benefit of multitask representation learning. JMLR , 17(81):1–32, 2016.
Montanari (2008) Montanari, A. Estimating random variables from random sparse observations. European Transactions on Telecommunications , 19(4):385–403, 2008.
Nie et al. (2024) Nie, S., Zhu, F., Du, C., Pang, T., Liu, Q., Zeng, G., Lin, M., and Li, C. Scaling up masked diffusion models on text. arXiv preprint arXiv:2410.18514 , 2024.
Nie et al. (2025) Nie, S., Zhu, F., You, Z., Zhang, X., Ou, J., Hu, J., Zhou, J., Lin, Y., Wen, J.-R., and Li, C. Large language diffusion models. arXiv preprint arXiv:2502.09992 , 2025.
Ou et al. (2024) Ou, J., Nie, S., Xue, K., Zhu, F., Sun, J., Li, Z., and Li, C. Your absorbing discrete diffusion secretly models the conditional distributions of clean data. arXiv preprint arXiv:2406.03736 , 2024.
Papadopoulos et al. (2024) Papadopoulos, V., Wenger, J., and Hongler, C. Arrows of time for large language models. arXiv preprint arXiv:2401.17505 , 2024.
Peng et al. (2025) Peng, F. Z., Bezemek, Z., Patel, S., Yao, S., Rector-Brooks, J., Tong, A., and Chatterjee, P. Path planning for masked diffusion model sampling. arXiv preprint arXiv:2502.03540 , 2025.
Radcliffe (2020) Radcliffe, D. G. 3 million sudoku puzzles with ratings, 2020. URL https://www.kaggle.com/dsv/1495975 .
Rector-Brooks et al. (2024) Rector-Brooks, J., Hasan, M., Peng, Z., Quinn, Z., Liu, C., Mittal, S., Dziri, N., Bronstein, M., Bengio, Y., Chatterjee, P., et al. Steering masked discrete diffusion models via discrete denoising posterior prediction. arXiv preprint arXiv:2410.08134 , 2024.
Ruder (2017) Ruder, S. An overview of multi-task learning in deep neural networks. arXiv 1706.05098 , 2017.
Sahoo et al. (2025) Sahoo, S., Arriola, M., Schiff, Y., Gokaslan, A., Marroquin, E., Chiu, J., Rush, A., and Kuleshov, V. Simple and effective masked diffusion language models. Advances in Neural Information Processing Systems , 37:130136–130184, 2025.
Schiff et al. (2024) Schiff, Y., Sahoo, S. S., Phung, H., Wang, G., Boshar, S., Dalla-torre, H., de Almeida, B. P., Rush, A., Pierrot, T., and Kuleshov, V. Simple guidance mechanisms for discrete diffusion models. arXiv preprint arXiv:2412.10193 , 2024.
Shah et al. (2024) Shah, K., Dikkala, N., Wang, X., and Panigrahy, R. Causal language modeling can elicit search and reasoning capabilities on logic puzzles. arXiv preprint arXiv:2409.10502 , 2024.
Shi et al. (2024) Shi, J., Han, K., Wang, Z., Doucet, A., and Titsias, M. K. Simplified and generalized masked diffusion for discrete data. NeurIPS , 2024.
Shih et al. (2022) Shih, A., Sadigh, D., and Ermon, S. Training and inference on any-order autoregressive models the right way. NeurIPS , 2022.
Soboleva et al. (2023) Soboleva, D., Al-Khateeb, F., Myers, R., Steeves, J. R., Hestness, J., and Dey, N. Slimpajama: A 627b token cleaned and deduplicated version of redpajama, June 2023.
Sohl-Dickstein et al. (2015) Sohl-Dickstein, J., Weiss, E. A., Maheswaranathan, N., and Ganguli, S. Deep unsupervised learning using nonequilibrium thermodynamics. ICML , 2015.
Song et al. (2021) Song, Y., Sohl-Dickstein, J., Kingma, D. P., Kumar, A., Ermon, S., and Poole, B. Score-based generative modeling through stochastic differential equations. ICLR , 2021.
Touvron et al. (2023) Touvron, H., Martin, L., Stone, K., Albert, P., Almahairi, A., Babaei, Y., Bashlykov, N., Batra, S., Bhargava, P., Bhosale, S., Bikel, D., Blecher, L., Ferrer, C. C., Chen, M., Cucurull, G., Esiobu, D., Fernandes, J., Fu, J., Fu, W., Fuller, B., Gao, C., Goswami, V., Goyal, N., Hartshorn, A., Hosseini, S., Hou, R., Inan, H., Kardas, M., Kerkez, V., Khabsa, M., Kloumann, I., Korenev, A., Koura, P. S., Lachaux, M.-A., Lavril, T., Lee, J., Liskovich, D., Lu, Y., Mao, Y., Martinet, X., Mihaylov, T., Mishra, P., Molybog, I., Nie, Y., Poulton, A., Reizenstein, J., Rungta, R., Saladi, K., Schelten, A., Silva, R., Smith, E. M., Subramanian, R., Tan, X. E., Tang, B., Taylor, R., Williams, A., Kuan, J. X., Xu, P., Yan, Z., Zarov, I., Zhang, Y., Fan, A., Kambadur, M., Narang, S., Rodriguez, A., Stojnic, R., Edunov, S., and Scialom, T. Llama 2: Open foundation and fine-tuned chat models. arXiv preprint arXiv: 2307.09288 , 2023.
Tripuraneni et al. (2021) Tripuraneni, N., Jin, C., and Jordan, M. I. Provable meta-learning of linear representations. ICML , 2021.
Varma et al. (2024) Varma, H., Nagaraj, D., and Shanmugam, K. Glauber generative model: Discrete diffusion models via binary classification. arXiv preprint arXiv: 2405.17035 , 2024.
Wang et al. (2024) Wang, X., Zheng, Z., Ye, F., Xue, D., Huang, S., and Gu, Q. Diffusion language models are versatile protein learners. ICML , 2024.
Xu et al. (2024) Xu, M., Geffner, T., Kreis, K., Nie, W., Xu, Y., Leskovec, J., Ermon, S., and Vahdat, A. Energy-based diffusion language models for text generation. arxiv preprint arXiv: 2410.21357 , 2024.
Ye et al. (2024) Ye, J., Gao, J., Gong, S., Zheng, L., Jiang, X., Li, Z., and Kong, L. Beyond autoregression: Discrete diffusion for complex reasoning and planning. arXiv preprint arXiv: 2410.14157 , 2024.
Zhang et al. (2024) Zhang, P., Zeng, G., Wang, T., and Lu, W. Tinyllama: An open-source small language model. arXiv preprint arXiv: 2401.02385 , 2024.
Zheng et al. (2024) Zheng, K., Chen, Y., Mao, H., Liu, M.-Y., Zhu, J., and Zhang, Q. Masked diffusion models are secretly time-agnostic masked models and exploit inaccurate categorical sampling. arXiv preprint arXiv:2409.02908 , 2024.
Zheng et al. (2023) Zheng, L., Yuan, J., Yu, L., and Kong, L. A reparameterized discrete diffusion model for text generation. arXiv preprint arXiv:2302.05737 , 2023.
Appendix A Related works
附录 A 相关工作
Discrete diffusion models.
(Continuous) diffusion models were originally built on continuous-space Markov chains with Gaussian transition kernels (Sohl-Dickstein et al., 2015; Ho et al., 2020). This was later extended to continuous time through the theory of stochastic differential equations (Song et al., 2021). In a similar vein, discrete diffusion models have emerged from discrete-space Markov chains (Hoogeboom et al., 2021b). Specifically, (Austin et al., 2021) introduced D3PM with various types of transition matrices. Later, Lou et al. (2024) proposed SEDD, incorporating a theoretically and practically robust score-entropy objective. Additionally, Varma et al. (2024); Liu et al. (2024b) introduced novel modeling strategies that classify tokens in a noisy sequence as either signal (coming from clean data) or noise (arising from the forward process). In particular, Liu et al. (2024b) uses this to give a planner that adaptively determines which tokens to denoise. While this is similar in spirit to our general discussion about devising adaptive inference strategies, we emphasize that their approach is specific to discrete diffusions for which the forward process scrambles the token values, rather than masking them.
离散扩散模型。
(连续)扩散模型最初建立在带高斯转移核的连续空间马尔可夫链上(Sohl-Dickstein et al., 2015;Ho et al., 2020),后经随机微分方程理论推广到连续时间(Song et al., 2021)。类似地,离散扩散模型从离散空间马尔可夫链发展而来(Hoogeboom et al., 2021b)。具体而言,Austin et al.(2021)提出带多种转移矩阵的 D3PM;其后 Lou et al.(2024)提出 SEDD,引入理论与实践上都稳健的分数熵目标。此外,Varma et al.(2024)、Liu et al.(2024b)提出新的建模策略:把噪声序列中的 token 分为信号(来自干净数据)与噪声(来自前向过程)。尤其 Liu et al.(2024b)据此给出一个规划器,自适应决定去噪哪些 token。这在精神上接近我们关于自适应推理策略的一般讨论,但我们强调:他们的方法针对前向过程扰乱 token 取值而非掩码它们的离散扩散。
Masked diffusion models.
Meanwhile, the absorbing transition kernel has gained popularity as a common choice due to its better performance than other kernels. Building on this, Sahoo et al. (2025); Shi et al. (2024) aligned its framework with continuous diffusion, resulting in a simple and principled training recipe, referring to it as Masked Diffusion Model. Subsequent studies have explored various aspects of MDM. Gong et al. (2024) efficiently trained MDM via adaptation from autoregressive models, scaling MDM up to 7B parameters. Zheng et al. (2024) interpreted MDMs as order-agnostic learners and proposed a first-hitting sampler based on this insight. Ye et al. (2024); Gong et al. (2024) demonstrated that MDM outperforms autoregressive models in reasoning and planning tasks, emphasizing its impact on downstream applications. Nie et al. (2024) examined the scaling laws of MDM, while Xu et al. (2024); Liu et al. (2024a) identified limitations in capturing coordinate dependencies when the number of sampling steps is small and proposed additional modeling strategies to address this issue. Schiff et al. (2024) studied conditional generation using MDM and Rector-Brooks et al. (2024) tackled the challenge of controlling generated data distributions through steering methodologies. Chen & Ying (2024) provided a theoretical analysis showing that sampling error is small given accurate score function estimation.
掩码扩散模型。
与此同时,吸收转移核因优于其他核而成为常见选择。在此基础上,Sahoo et al.(2025)、Shi et al.(2024)将其框架与连续扩散对齐,得到简单且有原则的训练配方,并称之为掩码扩散模型。后续工作从多侧面研究 MDM:Gong et al.(2024)经自回归模型适配高效训练 MDM,规模做到 70 亿参数;Zheng et al.(2024)把 MDMs 解释为与顺序无关的学习者,并提出基于该洞见的首达采样器;Ye et al.(2024)、Gong et al.(2024)表明 MDM 在推理与规划任务上胜过自回归模型,强调其对下游应用的影响;Nie et al.(2024)考察 MDM 的缩放律;Xu et al.(2024)、Liu et al.(2024a)指出采样步数较少时难以捕捉坐标依赖,并提出额外建模策略;Schiff et al.(2024)研究 MDM 条件生成;Rector-Brooks et al.(2024)用转向方法控制生成数据分布;Chen & Ying(2024)给出理论分析:在分数函数估计准确时采样误差很小。
Any-order reasoning.
Even though language tasks generally have a natural order of “left-to-right” token generation, in many tasks like planning, reasoning, and combinatorial optimization, the natural order of token generation can be quite different from “left-to-right”. Even though prominent autoregressive-based language models achieve impressive performance on various tasks, many works (Golovneva et al., 2024; Chen et al., 2024; Kitouni et al., 2025) have shown that this performance is tied to the training order of the tasks and therefore can cause brittleness from it. For example, Chen et al. (2024) showed that simply permuting the premise order on math tasks causes a performance drop of 30%. The reason behind such brittleness regarding the ordering is the inherent “left-to-right” nature of the autoregressive models. Several works (Liao et al., 2020) have tried to address this issue in the autoregressive framework. In particular, (Papadopoulos et al., 2024) highlighted the significance of left-to-right ordering in natural language by comparing its likelihood to that of the reverse (right-to-left) ordering.
任意顺序推理。
尽管语言任务通常有「从左到右」的自然 token 生成顺序,但在规划、推理与组合优化等诸多任务中,自然顺序可与「从左到右」大相径庭。即便主流自回归语言模型在多种任务上表现出色,多项工作(Golovneva et al., 2024;Chen et al., 2024;Kitouni et al., 2025)表明这种表现与任务的训练顺序绑定,因而可能因此变得脆弱。例如 Chen et al.(2024)表明:仅打乱数学题前提顺序,表现就下降约 30%。这种对顺序的脆弱性,根源于自回归模型固有的「从左到右」本性。若干工作(Liao et al., 2020)试图在自回归框架内缓解;尤其 Papadopoulos et al.(2024)通过把自然语言的似然与反向(从右到左)顺序对比,突出从左到右顺序的重要性。
Recently, discrete diffusion models have emerged as a promising approach for discrete data apart from autoregressive models. Additionally, the order-agnostic training of discrete diffusion models opens up the multiple sampling paths during the inference but it also faces some challenges during the training therefore, they seem a promising approach to elicit any order reasoning. Zheng et al. (2023) proposed different ways of implementing an adaptive inference strategy for MDM but a concrete understanding of why such an adaptive inference strategy is needed is still lacking. In this work, we explore various aspects of vanilla MDM training and how adaptive MDM inference can mitigate the issues raised by vanilla MDM training and elicit any order reasoning.
近来,离散扩散模型成为有别于自回归模型的有前景路线。其与顺序无关的训练在推理时打开多条采样路径,但训练也面临挑战;因此它们似乎是引出任意顺序推理的有希望途径。Zheng et al.(2023)提出了实现 MDM 自适应推理的多种方式,但为何需要这类自适应策略的具体理解仍不足。本文考察朴素 MDM 训练的多个侧面,以及自适应 MDM 推理如何缓解朴素训练带来的问题,并引出任意顺序推理。
We also want to mention the concurrent work by Peng et al. (2025) that proposes an alternative adaptive inference strategy by selecting based on the BERT model or the denoiser itself. In particular, Peng et al. (2025) uses the BERT model or the denoiser to obtain the uncertainty of a token and then uses Top- to decide the positions to unmask it. In contrast to their work, we disentangle the impact of token ordering on MDM training vs. MDM inference and provide a more complete understanding of the motivations for and benefits of adaptive inference. Additionally, our results indicate drawbacks to using Top- strategy as opposed to Top- margin in deciding which tokens to unmask when there are multiple values with high probabilities.
我们也要提到 Peng et al.(2025)的并行工作:他们提出另一种自适应推理策略,用 BERT 或去噪器本身选取 ;具体是用 BERT 或去噪器得到 token 不确定性,再用 Top- 决定揭开位置。相对其工作,我们把 token 顺序对 MDM 训练与推理的影响拆开讨论,对自适应推理的动机与收益给出更完整理解。此外,我们的结果表明:当多个取值概率都很高时,用 Top- 决定揭开哪些 token 不如 Top- 间隔。
Beyond autoregressive models.
Efforts to learn the natural language using non-autoregressive modeling began with BERT (Devlin et al., 2019). Non-causal approaches can take advantage of the understanding the text data representation. (Chang et al., 2022) adopted a similar approach for learning image representations. Building on these intuitions, (Shih et al., 2022; Hoogeboom et al., 2021a) proposed any-order modeling, which allows a model to generate in any desired order. Shih et al. (2022) made the same observation that any-order models by default have to solve exponentially more masking problems than autoregressive models. However, whereas our work shows that learning in the face of this challenging task diversity can benefit the model at inference time, their work sought to alleviate complexity at training time by reducing the number of masking problems that need to be solved.
超越自回归模型。
用非自回归建模学习自然语言始于 BERT(Devlin et al., 2019)。非因果方法可利用对文本表示的理解。Chang et al.(2022)对图像表示采用类似思路。在这些直觉上,Shih et al.(2022)、Hoogeboom et al.(2021a)提出任意顺序建模,允许模型按任意期望顺序生成。Shih et al.(2022)同样观察到:默认的任意顺序模型须比自回归模型多解指数级掩码问题。不过,我们的工作表明面对这种挑战性任务多样性仍可在推理时受益;他们的工作则试图通过减少须解的掩码问题数来减轻训练复杂度。
Appendix B Technical details from Section 3
附录 B 第 3 节的技术细节
Notations.
Throughout this section, we use to denote the -th coordinate of the vector and to denote the -th example. The -th coordinate of the vector is denoted by .
记号。
本节通篇用 表示向量 的第 坐标, 表示第 个样本。向量 的第 坐标记为 。
B.1 Additional example: sparse parity observations
B.1 补充例子:稀疏奇偶观测
Example B.1(Noisy sparse parity observations).
Let , , and . Fix noise rate as well as strings sampled independently and uniformly at random from the set of -sparse strings in . For each , define to be the distribution which places mass on (resp. ) and mass on (resp. ) if is odd (resp. even). Note that for , each of these observations is efficiently learnable by brute-force.
例 B.1(带噪声的稀疏奇偶观测)。
设 ,,且 。固定噪声率* ,以及独立均匀取自 中 -稀疏串集合的串 。对每个 ,定义 为:若 为奇(或偶),则在 (或 )上放质量 ,在 (或 )上放质量 。注意当 时,这些观测均可由暴力搜索高效学习。*
Below we show that for a certain range of masking fractions, a constant fraction of the masking problems for the corresponding L&O distributions are computationally hard under the Sparse Learning Parity with Noise assumption (Alekhnovich, 2003). Formally we have:
下面证明:在某一掩码比例范围内,对应 L&O 分布的常数比例掩码问题,在稀疏带噪声学习奇偶性假设下计算困难(Alekhnovich, 2003)。形式地:
Proposition B.2.
Let be an arbitrary absolute constant, and let be sufficiently large. Let be a sample from a L&O distribution with noisy parity observations as defined in Example B.1. Suppose each token is independently masked with probability , and is the set of indices for the masked tokens. If , then under the Sparse Learning Parity with Noise (SLPN) assumption (see Definition B.3), with constant probability over , no polynomial-time algorithm can solve the resulting masking problem of predicting any of the masked tokens among given .
命题 B.2。
设 为任意绝对常数, 充分大。设 取自例 B.1 所定义的带噪声奇偶观测的 L&O 分布 。若每个 token 独立以概率 被掩码, 为被掩码下标集合,且 ,则在稀疏带噪声学习奇偶性(SLPN)假设下(见定义 B.3),对 以常数概率,没有任何多项式时间算法能在给定 时,解出预测 中任一被掩码 token 的掩码问题。
We note that it is important for us to take the observations to be sparse parities and to leverage the Sparse Learning Parity with Noise assumption. If instead we used dense parities and invoked the standard Learning Parity with Noise (LPN) assumption, we would still get the hardness of masking problems, but the observations themselves would be hard to learn, assuming LPN. This result is based on the following standard hardness assumption:
我们指出:必须取稀疏奇偶观测,并借助稀疏带噪声学习奇偶性假设。若改用稠密奇偶并诉诸标准带噪声学习奇偶性(LPN)假设,仍可得到掩码问题的困难性,但观测本身在 LPN 下也难学。该结果基于如下标准困难性假设:
Definition B.3(Sparse Learning Parity with Noise).
Given input dimension , noise parameter , and sample size , an instance of the Sparse Learning Parity with Noise (SLPN) problem is generated as follows:
定义 B.3(稀疏带噪声学习奇偶性)。
给定输入维数 、噪声参数 与样本量 ,*稀疏带噪声学习奇偶性(SLPN)*问题的一个实例按如下生成:
- • Nature samples a random bitstring from
- • 自然从 中采样随机比特串
- • We observe examples of the form where is sampled independently and uniformly at random from -sparse bitstrings in , and is given by , where is with probability and otherwise.
- • 我们观测 个形如 的样本,其中 独立均匀取自 中的 -稀疏比特串, 由 给出, 以概率 为 1、否则为 0。
Given the examples , the goal is to recover .
给定样本 ,目标是恢复 。
The SLPN assumption is that for any for constant , and any sufficiently large inverse polynomial noise rate , no -time algorithm can recover with high probability.
SLPN 假设是:对任意 (常数 ),以及任意充分大的逆多项式噪声率 ,没有任何 时间算法能以高概率恢复 。
Proof of Proposition B.2.
With probability at least , all of the variable tokens for are masked. Independently, the number of unmasked tokens among the observation tokens is distributed as , so by a Chernoff bound, with probability at least we have that at least observation tokens are unmasked. The masking problem in this case amounts to an instance of SLPN with input dimension and sample size in . Because of the lower bound on the sample size, prediction of is information-theoretically possible. Because of the upper bound on the sample size, the SLPN assumption makes it computationally hard. As a result, estimating the posterior mean on any entry of given the unmasked tokens is computationally hard as claimed. ∎
命题 B.2 的证明。
以至少 的概率,所有变量 token ()都被掩码。独立地,观测 token 中未掩码个数服从 ;由 Chernoff 界,以至少 的概率,至少有 个观测 token 未掩码。此时掩码问题相当于输入维数 、样本量落在 的 SLPN 实例。因样本量有下界,预测 在信息论上可行;因样本量有上界,SLPN 假设使其计算困难。故在给定未掩码 token 时估计 任一分量的后验均值,如声称般计算困难。∎
B.2 Additional example: random slab observations
B.2 补充例子:随机板观测
Example B.4(Random slab observations).
Let and for constant . Fix slab width and vectors sampled independently from . For each , define the corresponding observation to be deterministically if , and deterministically otherwise.
例 B.4(随机板观测)。
设 ,(常数 )。固定板宽* ,以及独立取自 的向量 。对每个 ,若 ,则相应观测 确定性为 1,否则确定性为 0。*
In (Alaoui & Gamarnik, 2024), it was shown that stable algorithms (Definition B.7), which encompass many powerful methods for statistical inference like low-degree polynomial estimators, MCMC, and algorithmic stochastic localization (Gamarnik, 2021), are unable to sample from the posterior distribution over a random bitstring conditioned on it satisfying for any number of constraints , provided is not too large that the support of the posterior is empty. This ensemble is the well-studied symmetric perceptron (Aubin et al., 2019). The following is a direct reinterpretation of the result of (Alaoui & Gamarnik, 2024):
Alaoui & Gamarnik(2024)证明:稳定算法(定义 B.7)——涵盖低次多项式估计、MCMC、算法随机定位(Gamarnik, 2021)等许多强统计推断方法——无法从后验中采样:该后验是随机比特串在满足任意 条约束 ()条件下的条件分布,前提是 尚未大到使后验支撑为空。该系综是被充分研究的对称感知机(Aubin et al., 2019)。下列命题是对 Alaoui & Gamarnik(2024)结果的直接改写:
Proposition B.5.
Let be a L&O distribution with random slab observations as defined in Example B.4, with parameter and slab width . There exists a constant such that for any absolute constant , if and , the following holds. Let denote the distribution given by independently masking every coordinate in with probability . Then any -stable algorithm, even one not based on masked diffusion, which takes as input a sample from and, with probability outputs a Wasserstein-approximate[^3] sample from conditioned on the unmasked tokens in , must run in super-polynomial time.
命题 B.5。
设 为例 B.4 所定义、参数 、板宽 的带随机板观测的 L&O 分布。存在常数 ,使得对任意绝对常数 ,若 且 ,则有如下结论。令 为对 每个坐标独立以概率 掩码后的分布。则任何* -稳定算法——即便不基于掩码扩散——以 的样本 为输入,并以概率 输出在 未掩码 token 条件下 的 Wasserstein 近似[^3]样本,都必须超多项式时间运行。*
The upshot of this is that any stable, polynomial-time masked diffusion sampler will, with non-negligible probability, encounter a computationally hard masking problem at some point during the reverse process.
要点是:任何稳定、多项式时间的掩码扩散采样器,都会以不可忽略的概率在反向过程某处撞上计算困难的掩码问题。
For the proof, we first formally define the (planted) symmetric Ising perceptron model:
证明前,我们先形式定义(种植的)对称 Ising 感知机模型:
Definition B.6.
Let . The planted symmetric Ising perceptron model is defined as follows:
定义 B.6。
设 。种植对称 Ising 感知机模型定义如下:
- • Nature samples uniformly at random from
- • 自然从 均匀采样
- • For each , we sample independently from conditioned on satisfying .
- • 对每个 ,在满足 的条件下,独立从 采样 。
The goal is to sample from the posterior on conditioned on these observations .
目标是在这些观测 条件下,从 的后验中采样。
Next, we formalize the notion of stable algorithms.
接下来形式化稳定算法的概念。
Definition B.7.
Given a matrix , define for independent . A randomized algorithm which takes as input and outputs an element of is said to be -stable if .
定义 B.7。
给定矩阵 ,定义 ,其中独立的 。以 为输入、输出 中元素的随机算法 ,若 ,则称其为 -稳定。
As discussed at depth in (Gamarnik, 2021), many algorithms like low-degree polynomial estimators and Langevin dynamics are stable.
如 Gamarnik(2021)深入讨论,低次多项式估计与 Langevin 动力学等许多算法是稳定的。
Theorem B.8(Theorem 2.1 in (Alaoui & Gamarnik, 2024)[^4]).
For any constant , there exists such that the following holds for all constants . For , any -stable randomized algorithm which takes as input and outputs an element of will fail to sample from the posterior on conditioned on in the symmetric Ising perceptron model to Wasserstein error .
定理 B.8(Alaoui & Gamarnik, 2024 定理 2.1[^4])。
对任意常数 ,存在 ,使得对所有常数 有:当 时,任何以 为输入、输出 中元素的 -稳定随机算法 ,都无法在对称 Ising 感知机模型中,把在 条件下 的后验采样到 Wasserstein 误差 。
Proof of Proposition B.5.
By a union bound, with probability at least over a draw , all of the tokens are masked. The number of unmasked tokens in among the observations is distributed as . By a Chernoff bound, this is in with at least constant probability. The claim then follows immediately from Theorem B.8 above. ∎
命题 B.5 的证明。
由并界,对 ,以至少 的概率,所有 token 都被掩码。 中观测 的未掩码个数服从 。由 Chernoff 界,该数以至少常数概率落在 。命题随即由上述定理 B.8 直接得到。∎
B.3 Proof outline of Proposition 3.3
B.3 命题 3.3 的证明提纲
To understand the proof idea, we consider the case where all the latent tokens are masked and some of the observation tokens are unmasked. In this case, the prediction task reduces to learning to recover the latent tokens that are consistent with the observations. Intuitively, each observation provides some constraints and the task is to recover an assignment that satisfies the constraints. This is reminiscent of Constraint Satisfaction Problems (CSPs). Indeed, to show the hardness result, we use the rich theory developed for planted CSPs at the intersection of statistical physics and average-case complexity.
为理解证明思路,考虑所有潜变量 token 被掩码、部分观测 token 未掩码的情形。此时预测任务化为:学习恢复与观测一致的潜变量 token。直观上,每个观测提供若干约束,任务是恢复满足约束的赋值。这使人联想到约束满足问题(CSPs)。确实,为证明困难性,我们借助统计物理与平均情形复杂度交叉处关于种植 CSP 的丰富理论。
In a planted CSP, there is an unknown randomly sampled vector of length and, one is given randomly chosen Boolean constraints which is promised to satisfy, and the goal is to recover as best as possible (see Definition B.9). Prior works have shown the hardness of efficiently learning to solve the planted CSP problem (Krzakala & Zdeborová, 2009; Alaoui & Gamarnik, 2024). We show the hardness of masking problems in L&O distributions based on these results. Consider the ground truth latent tokens as the random vector and each observation as a constraint. In this case, the problem of learning to recover the latent tokens from the observation tokens reduces to recovery for the planted CSP.
在种植 CSP 中,有一个未知的、随机采样的长度 向量 ,并给出 承诺满足的随机布尔约束,目标是尽可能好地恢复 (见定义 B.9)。先前工作已表明高效学习种植 CSP 的困难性(Krzakala & Zdeborová, 2009;Alaoui & Gamarnik, 2024)。我们据此建立 L&O 分布中掩码问题的困难性。把真实潜变量 token 视为随机向量 ,每个观测视为一条约束;此时从观测 token 学习恢复潜变量,就化为种植 CSP 的恢复。
There are precise predictions for the values of vocabulary size and the number of observations for which the information-theoretically best possible overlap and the best overlap achievable by any computationally efficient algorithm are different. We show that these predictions directly translate to predictions about when masking problems become computationally intractable:
对词表大小 与观测数目,存在精确预言:信息论上最优可达重叠,与任何计算高效算法可达的最优重叠何时不同。我们说明:这些预言可直接翻译为掩码问题何时计算不可行的预言:
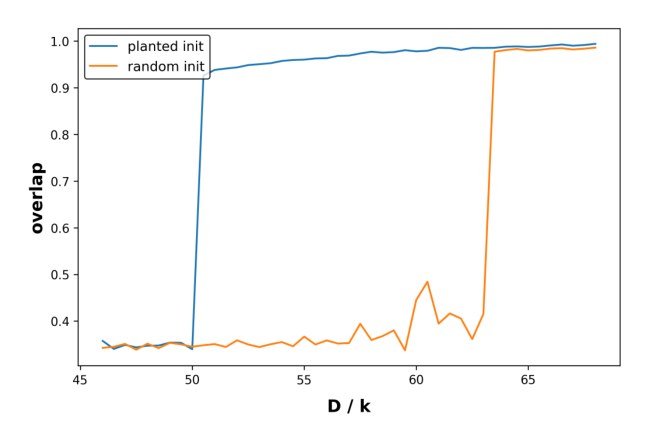
Figure 4: Overlap achieved by belief propagation initialized at ground truth versus random for planted CSP with , , and , for and varying choices of average degree . can be shown analytically to be , consistent with the phase transition depicted. Plot suggests . By Prop. 3.3 this implies a range of masking fractions at which fraction of masking problems are computationally hard.
图 4:对种植 CSP(,,,,平均度 变化),信念传播分别以真值与随机初始化时达到的重叠。可解析证明 为 64,与图中相变一致。图示暗示 。由命题 3.3,这意味着存在一段掩码比例,使 比例的掩码问题计算困难。
As a simple example, let us consider sparse predicate observations with and . These can be formally related to the well-studied problem of planted -coloring. In the planted -coloring, a random graph of average degree is sampled consistent with an unknown vertex coloring and the goal is to estimate the coloring as well as possible (Krzakala & Zdeborová, 2009), as measured by the overlap of the output of the algorithm to the ground-truth coloring (see Definition B.9). As a corollary of our main result, we show that when all the latent tokens are masked and a few unmasked observation tokens provide the information of the form for , then solving the masking problem can be reduced to solving planted coloring.
作为简单例子,考虑 、 的稀疏谓词观测。它们可形式关联到被充分研究的种植 -着色问题。在种植 -着色中,采样与未知顶点着色一致的平均度 的随机图,目标是尽可能好地估计着色(Krzakala & Zdeborová, 2009),度量是算法输出与真值着色的重叠(见定义 B.9)。作为主结果的推论,我们说明:当所有潜变量 token 被掩码,且少量未掩码观测 token 提供形如 ()的信息时,解掩码问题可化为解种植着色。
For planted -coloring, when the thresholds in Proposition 3.3 are given by and (Krzakala & Zdeborová, 2009) (the factor of here is simply because the observations correspond to ordered subsets of size ). For general predicates and arities, there is an established recipe for numerically computing and based on the behavior of the belief propagation algorithm (see the discussion in Appendix B.4). As an example, in Fig. 4, we execute this recipe for , , and given by the Not-All-Equal predicate to obtain thresholds that can be plugged into Proposition 3.3.
对种植 -着色,当 时命题 3.3 中的阈值为 与 (Krzakala & Zdeborová, 2009)(这里的因子 2 只因观测对应大小为 2 的有序子集)。对一般谓词与元数,有基于信念传播算法行为的既定数值配方可计算 与 (见附录 B.4 的讨论)。例如在图 4 中,我们对 、、 为 Not-All-Equal 谓词 执行该配方,得到可代入命题 3.3 的阈值。
Additional examples of the hardness.
The above setup can also be generalized to capture Bayesian constraint satisfaction problems (Montanari, 2008; Liu et al., 2022), one notable example of which is the stochastic block model (Decelle et al., 2011). There are analogous predictions for the onset of hardness of inference, which can likewise be translated to hardness of masking problems for seemingly benign L&O distributions. In Appendix B.1 and B.2, we give two more examples of L&O distributions for which order-aware training is tractable yet order-agnostic training of the MDM is computationally hard.
困难性的其他例子。
上述设定还可推广到捕捉贝叶斯约束满足问题(Montanari, 2008;Liu et al., 2022),其中一个著名例子是随机块模型(Decelle et al., 2011)。推断困难性起始点有类似预言,同样可翻译为看似良性的 L&O 分布上掩码问题的困难性。附录 B.1 与 B.2 再给出两个 L&O 分布例子:感知顺序训练可行,而 MDM 的与顺序无关训练计算困难。
First, we consider L&O distributions whose observations are sparse, noisy parities in the latents and deduce hardness for order-agnostic training from the Sparse Learning Parity with Noise assumption (Alekhnovich, 2003). We then consider L&O distributions whose observations are generalized linear models in the latents, and deduce hardness for a large class of efficient algorithms from existing results on Lipschitz hardness (Alaoui & Gamarnik, 2024) for the symmetric binary perceptron (Aubin et al., 2019).
首先,我们考虑观测为潜变量上稀疏带噪奇偶的 L&O 分布,并从稀疏带噪声学习奇偶性假设(Alekhnovich, 2003)推出与顺序无关训练的困难性。然后考虑观测为潜变量上广义线性模型的 L&O 分布,并从对称二元感知机(Aubin et al., 2019)上已有的 Lipschitz 困难性结果(Alaoui & Gamarnik, 2024)推出一大类高效算法的困难性。
B.4 Proof of Proposition 3.3: sparse predicate observations
B.4 命题 3.3 的证明:稀疏谓词观测
Here we formally define the relevant notions needed to formalize our claim about hardness in Proposition 3.3.
这里形式定义命题 3.3 中困难性论断所需的相关概念。
Definition B.9(Planted CSPs).
Given arity , vocabulary/alphabet size , predicate , latent dimension , and clause density , the corresponding planted constraint satisfaction problem is defined as follows: Nature samples an unknown assignment uniformly at random from , and then for each ordered -tuple of distinct elements from , we observe the clause independently with probability if .
定义 B.9(种植 CSP)。
给定元数 、词表/字母表大小 、谓词 、潜变量维数 与子句密度 ,相应的种植约束满足问题定义如下:自然从 均匀采样未知赋值 ,然后对 中每个大小为 的有序 元组 ,若 ,则以概率 独立观测到子句 。
To measure the quality of an algorithm for recovering given the observations, define the overlap between an estimate and the ground truth by where denotes the set of all permutations of . Define the average degree to be , i.e. the expected number of variables that share at least one clause with a given variable.
为度量在给定观测时恢复 的算法质量,定义估计 与真值 的重叠为 ,其中 表示 \{0,1,\ldots,N-1} 上全部置换的集合。定义平均度为 ,即与给定变量至少共享一条子句的期望变量数。
We begin by defining the central algorithm driving statistical physics predictions about hardness for random constraint satisfaction problems: belief propagation (BP).
我们先定义驱动随机约束满足问题困难性统计物理预言的核心算法:信念传播(BP)。
Definition B.10(BP update rules).
Belief propagation is an algorithm that iteratively updates a set of messages , where range over all pairs of variable indices and observations . At time , the messages are computed via
定义 B.10(BP 更新规则)。
信念传播是迭代更新一组消息 的算法,其中 遍历所有变量下标 与含 的观测 。在时刻 ,消息按如下计算
where assigns to entry and to the remaining entries.
其中 把 赋给第 项,把 赋给其余项。
A set of messages can be used to estimate the marginals of the posterior on conditioned on the observations as follows. The marginal on the -th variable has probability mass function over proportional to . Given a set of marginals, a natural way to extract an estimate for is to round to the color in at which the probability mass function is largest.
一组消息可如下估计在观测条件下 后验的边缘:第 个变量的边缘在 上的概率质量函数正比于 。给定一组边缘,提取 估计的自然做法是取概率质量函数最大处的颜色 。
Throughout we will make the following assumption that ensures that the trivial messages and are a fixed point, sometimes called the paramagnetic fixed point, for the iteration above:
通篇我们做如下假设,以保证平凡消息 与 是上述迭代的不动点,有时称为顺磁不动点:
Assumption B.11.
The quantity is constant across all and .
假设 B.11。
量 对所有 与 为常数。
Definition B.12.
Given , the Kesten-Stigum threshold is defined to be the largest average degree for which BP is locally stable around the paramagnetic fixed point, that is, starting from a small perturbation of the paramagnetic fixed point, it converges to the paramagnetic fixed point. More formally, is the largest average degree at which the Jacobian of the BP operator has spectral radius less than .
定义 B.12。
给定 ,Kesten-Stigum 阈值 定义为 BP 在顺磁不动点附近局部稳定时的最大平均度,即从顺磁不动点的小扰动出发会收敛回顺磁不动点。更形式地, 是 BP 算子 的雅可比谱半径小于 1 时的最大平均度。
The condensation threshold is defined to be the largest average degree at which the planted CSP ensemble and the following simple null model become mutually contiguous and thus statistically indistinguishable as . The null model is defined as follows: there is no single unknown assignment, but instead for every ordered subset of variables, Nature independently samples an unknown local assignment , and the observation is included with probability if .
凝聚阈值 定义为:种植 CSP 系综与如下简单零模型在 时变得相互邻近、因而统计不可区分时的最大平均度。零模型定义如下:不存在单一未知赋值;而是对每个 个变量的有序子集 ,自然独立采样未知局部赋值 ,若 则以概率 纳入观测。
For , there exists some other fixed point of the BP operator whose marginals, once rounded to an assignment, achieves strictly higher overlap than does BP with messages initialized randomly. The prediction is that in this regime, no efficient algorithm can achieve optimal recovery (Krzakala & Zdeborová, 2009).
当 时,存在 BP 算子的另一不动点:其边缘取整为赋值后,比随机初始化的 BP 达到严格更高的重叠。预言是:在该区间,没有高效算法能达到最优恢复(Krzakala & Zdeborová, 2009)。
Conjecture B.13(1RSB cavity prediction).
Suppose satisfy Assumption B.11, and let and denote the associated Kesten-Stigum and condensation thresholds for the average degree. Then for all for which , the best overlap achieved by a computationally efficient algorithm for recovering is strictly less than the best overlap achievable.
猜想 B.13(1RSB 腔方法预言)。
设 满足假设 B.11,令 与 为相应平均度的 Kesten-Stigum 与凝聚阈值。则对所有使 的 ,计算高效算法恢复 所能达到的最优重叠,严格小于可达的最优重叠。
Proof of Proposition 3.3.
At masking fraction satisfying the bounds in the Proposition, with probability at least we have that all tokens corresponding to latents get masked. Independently of this, the number of unmasked tokens among the observation tokens is distributed as , so by standard binomial tail bounds, with constant probability (depending on the gap between and ) this lies between and . Furthermore, of these unmasked tokens in expectation fraction of them correspond to observations for which the associated predicate evaluates to . Conditioned on the above events, the masking problem thus reduces exactly to inference for a planted constraint satisfaction problem at average degree , from which the Proposition follows. ∎
命题 3.3 的证明。
在命题给出的掩码比例 下,以至少 的概率,所有对应潜变量 的 token 都被掩码。独立地,观测 token 中未掩码个数服从 ;由标准二项尾界,以常数概率(取决于 与 的间隙)该数落在 与 之间。进一步,这些未掩码 token 中期望有 比例对应谓词取值为 1 的观测。在上述事件条件下,掩码问题恰化为平均度 的种植约束满足问题的推断,命题随之成立。∎
Appendix C Experimental details in Section 3
附录 C 第 3 节的实验细节
C.1 Experimental details in Section 3.2
C.1 第 3.2 节的实验细节
-learner configurations.
We consider two distributions of that interpolate between where denote the uniform distribution over all permutations of indices and the point mass at the identical distribution: (Closer) and (Much-closer). To construct those distributions, we start from the identity permutation and perform a certain number of random swapping operations. Since number of swaps results in a distribution that is very close to (Bormashenko, 2011), we use and swaps to construct the (Closer) and (Much-closer) distributions, respectively. For consistency, we repeat this sampling process three times.
-学习器配置。
我们考虑在 ( 表示指标 全部置换上的均匀分布)与恒等分布上的点质量之间插值的两种 分布:(Closer)与(Much-closer)。构造时从恒等置换出发,执行一定次数的随机交换。因 次交换会使分布非常接近 (Bormashenko, 2011),我们分别用 与 次交换构造(Closer)与(Much-closer)。为一致性,该采样过程重复三次。
Model and training configurations.
As explained in Section 3.2, to evaluate the scaling law of the -learner, we can simply adapt the autoregressive training setup (a transformer with causal attention) by modifying the input to and using a learnable positional embedding layer instead of RoPE. We borrow the training configurations from (Nie et al., 2024), which are also consistent with the TinyLlama (Zhang et al., 2024) configurations. In particular, we use AdamW optimizer (Loshchilov & Hutter, 2017), setting , , and a weight decay of and . A cosine learning rate schedule is applied, with a maximum learning rate of and a minimum learning rate of . We also note that unless otherwise specified, we maintain the same training configuration throughout the paper.
模型与训练配置。
如第 3.2 节所述,评估 -学习器缩放律时,只需把自回归训练设定(带因果注意力的 Transformer)的输入改为 ,并用可学习位置嵌入替代 RoPE。训练配置借自 Nie et al.(2024),也与 TinyLlama(Zhang et al., 2024)配置一致。具体使用 AdamW(Loshchilov & Hutter, 2017),,,权重衰减 ,。采用余弦学习率日程,最大学习率 ,最小 。另注:除非另行说明,全文保持同一训练配置。
Examining scaling laws.
We conduct IsoFLOP analysis (Hoffmann et al., 2022). For a given number of FLOPs , by varying the number of non-embedding parameters of transformers, we set the iteration numbers so that the total number of tokens observed by the model during training equals , following prior studies (Hoffmann et al., 2022; Kaplan et al., 2020). We then select the smallest validation loss and set it as a data point.
考察缩放律。
我们做 IsoFLOP 分析(Hoffmann et al., 2022)。对给定 FLOPs 数 ,通过改变 Transformer 非嵌入参数量,设定迭代次数使训练期间模型见到的总 token 数等于 ,遵循先前研究(Hoffmann et al., 2022;Kaplan et al., 2020)。再取最小验证损失作为数据点。
C.2 Experimental details in Section 3.3
C.2 第 3.3 节的实验细节
C.2.1 Experiment on L&O-NAE-SAT distribution
We consider the L&O-NAE-SAT distribution with . For each example sequence from L&O-NAE-SAT, we pad the last tokens with an additional token value of . We employ a M MDM with RoPE and a maximum sequence length of . Then, this MDM is trained for iterations. To attain a proxy MDM for the Bayes optimal predictor, we further train it for iterations.
C.2.1 L&O-NAE-SAT 分布上的实验
我们考虑 的 L&O-NAE-SAT 分布。对每个来自该分布的序列样本,用额外取值 2 的 token 把最后 212 个位置填充。采用带 RoPE、最大序列长度 512 的 19M MDM,训练 次迭代。为得到贝叶斯最优预测器的代理 MDM,再训练至 次迭代。
To measure the error across different tasks, we consider the following setup. For each , we randomly mask tokens in the latent positions and tokens in the observed positions. Across all masked prediction positions, , we measure the error for each position. For certainty, we repeat this process times. The result in Figure 2 corresponds to the case when , and we observe the same tendency for other values of .
为度量不同任务上的误差,采用如下设定。对每个 ,在潜变量位置随机掩码 个 token,在观测位置随机掩码 个 token。对全部掩码预测位置 ,逐位置度量误差。为保证可靠性,该过程重复 1000 次。图 2 对应 的情形;对其余 我们观察到相同趋势。
C.2.2 Experiment on text data
We take a M MDM pretrained with text data for a baseline model. To measure the performance imbalance between likelihood modeling tasks
C.2.2 文本数据上的实验
我们取在文本数据上预训练的 170M MDM 作为基线,度量似然建模任务之间的性能失衡
As done in the experiments in Section 3.2, we sample s from three different distributions: , (Closer), the point mass of identical distribution. For each case, we calculate the expectation over samples of .
与第 3.2 节实验相同,我们从三种不同分布采样 :、(Closer)、恒等分布上的点质量。对每种情形,在 个 样本上计算期望。
Appendix D Experimental details in Section 4
附录 D 第 4 节的实验细节
D.1 Experimental details in Section 4.2
D.1 第 4.2 节的实验细节
D.1.1 Experiment on L&O-NAE-SAT distribution
We consider five instances of L&O-NAE-SAT: . For each distribution, we train a 19M MDM and measure the accuracy difference between vanilla inference and adaptive inference using top probability margin.
D.1.1 L&O-NAE-SAT 分布上的实验
我们考虑五组 L&O-NAE-SAT:。对每个分布训练 19M MDM,并用最高概率间隔比较朴素推理与自适应推理的准确率差异。
Top probability margin sampler with temperature.
To modify our inference for text data modeling, which does not have a determined answer, we found that adding a certain level of temperature to the oracle is useful. This is because the top probability margin or the top probability often leads to greedy sampling, which harms the diversity (entropy) of the generated samples. Therefore, we consider a variant of the oracle as follows, incorporating a Gaussian noise term .
带温度的最高概率间隔采样器。
为把推理改用于没有唯一答案的文本建模,我们发现给 oracle 加一定温度有用。因为最高概率间隔或最高概率常导致贪心采样,损害生成样本的多样性(熵)。因此我们考虑如下加入高斯噪声项 的 oracle 变体。
Note that this approach has also been employed for unconditional sampling (Wang et al., 2024; Zheng et al., 2023).
注意无条件采样也采用过类似做法(Wang et al., 2024;Zheng et al., 2023)。
Generative perplexity and entropy.
We employ a 1.1B MDM pretrained on text data as a baseline. For each sampling step, we unconditionally generate samples using both vanilla and adaptive inference. Next, we calculate the likelihood using LLama2-7B as a baseline large language model. Moreover, we denote the entropy of a generated sample as , where .
生成困惑度与熵。
我们以在文本数据上预训练的 1.1B MDM 为基线。对每个采样步,分别用朴素与自适应推理无条件生成样本;再用 LLama2-7B 作为基线大语言模型计算似然。此外,生成样本 的熵记为 ,其中 。
Choice of number of tokens to unmask.
We set the number of tokens to unmask so that the number of unmasked tokens matches that of vanilla MDM inference in expectation. For an inference transition from step to , vanilla MDM expects unmasked. Accordingly, we choose . This choice keeps the number of revealed tokens balanced throughout inference. Alternatively, one can sample stochastically from . We found that both the deterministic and stochastic choices of result in comparable generative perplexity.
揭开 token 数目的选择。
我们设定揭开 token 数 ,使其期望与朴素 MDM 推理的未掩码数一致。对从步 到 的推理转移,朴素 MDM 期望揭开 。据此取 。该选择使推理全程揭开 token 数保持均衡。也可从 随机采样 。我们发现确定性与随机选择 得到的生成困惑度相当。
This choice of can be potentially helpful when the network is time-conditioned, since this keeps (\#\text{mask tokens in the currentx_{t}})\approx(1-\alpha_{t})\times L where is the max sequence length–matching the marginal that the model saw during training.
当网络带时间条件时,该 选择可能有益:它使 ( 为最大序列长度),与训练时模型见到的边缘匹配。
D.2 Experimental details on Sudoku and Zebra puzzles
D.2 数独与斑马谜题的实验细节
Dataset.
For both Sudoku and Zebra puzzles, we use the dataset provided in Shah et al. (2024) to train our model. To evaluate our model on the same difficulty tasks, we use the test dataset proposed in Shah et al. (2024). This dataset is created by filtering the puzzles from (Radcliffe, 2020) that can be solved using a fixed list of 7 strategies. To create a hard dataset to evaluate easy-to-hard generalization, we use the remaining puzzles from (Radcliffe, 2020) as they either require a new strategy unseen during the training and/or require backtracking. The hard dataset contains around 1M Sudoku puzzles.
数据集。
数独与斑马谜题均使用 Shah et al.(2024)提供的数据集训练。为在同等难度任务上评估,使用 Shah et al.(2024)提出的测试集;该集由 Radcliffe(2020)中可用固定 7 种策略求解的谜题筛选而成。为构造评估由易到难泛化的困难集,我们使用 Radcliffe(2020)中其余谜题——它们需要训练未见的新策略和/或需要回溯。困难集约含 100 万个数独。
Model, training, and inference.
For the training and inference, we use the codebase of (Ye et al., 2024) with keeping most of the hyperparameters default given in the codebase. For the Sudoku dataset, we use M GPT-2 model, and for the Zebra dataset, we use M model. We set the learning rate to 0.001 with a batch size of 128 to train the model for 300 epochs. For the inference, we use 50 reverse sampling steps using the appropriate strategy. Additionally, we add Gumbel noise with a coefficient of 0.5 to the MDM inference oracle .
模型、训练与推理。
训练与推理使用 Ye et al.(2024)的代码库,多数超参数保持默认。数独用 6M GPT-2 模型,斑马用 19M 模型。学习率 0.001,批大小 128,训练 300 个 epoch。推理用相应策略做 50 步反向采样。此外,向 MDM 推理 oracle 加入系数为 0.5 的 Gumbel 噪声。
D.3 Experimental details on LLaDA-8B
D.3 LLaDA-8B 上的实验细节
Our evaluation covers two task categories: (i) infilling(HumanEval-Infill and ROCStories) and (ii) instruction–answering (Math). For instruction–answering tasks, we employ a semi-autoregressive sampling strategy, whereas for infilling tasks we retain the non-autoregressive approach. For infilling tasks, the output length is predetermined—matching the size of the masked span—whereas instruction–answering tasks require an explicit length specification. For the latter, we follow the sampling configuration of (Nie et al., 2025).
评估覆盖两类任务:(i)填空(HumanEval-Infill 与 ROCStories);(ii)指令—作答(数学)。指令—作答任务采用半自回归采样策略,填空任务保留非自回归做法。填空任务输出长度预先确定——与掩码跨度大小一致;指令—作答任务则需显式指定长度。对后者,我们遵循 Nie et al.(2025)的采样配置。
For HumanEval-Infill, we adopt the problem set introduced by (Bavarian et al., 2022). Each instance is grouped by the span of the masked code—the region the model must infill—into three categories: single-line, multi-line, and split. The task difficulty rises as the length of the masked span increases.
对 HumanEval-Infill,我们采用 Bavarian et al.(2022)引入的题集。每个实例按须填入的掩码代码跨度分成三类:单行、多行与拆分。掩码跨度越长,任务越难。
Appendix E Omitted proofs
附录 E 省略的证明
Proof of Proposition 2.1.
We build on Proposition 3.1 from (Zheng et al., 2024) to obtain the result of Proposition 2.1. We first re-state the result from (Zheng et al., 2024) for the case when the denoising network does not depend on the noise-scale explicitly. Let be a sequence with tokens being masked from , and denotes the token value of the sequence . Let be the probability distribution corresponding to randomly and uniformly masking tokens of .
命题 2.1 的证明。
我们基于 Zheng et al.(2024)的命题 3.1 得到命题 2.1。先重述 Zheng et al.(2024)在去噪网络 不显式依赖噪声尺度 时的结果。令 为从 掩掉 个 token 的序列, 表示 第 个 token 的取值。令 为对 随机均匀掩掉 个 token 的概率分布。
Proposition E.1(Proposition 3.1 of (Zheng et al., 2024)).
For clean data , let be the discrete forward process that randomly and uniformly masks tokens of . Suppose the noise schedules satisfies and . Then, the MDM training loss (1) can be reformulated as
命题 E.1(Zheng et al., 2024 命题 3.1)。
对干净数据 ,令 为随机均匀掩掉 的 个 token 的离散前向过程。设噪声日程 满足 与 。则 MDM 训练损失(1)可重写为
To obtain an alternative formulation of (6), we expand the expectation . Since there are total positions of , we have the probability assigned for each equals . Therefore, expanding the above equation with the expectation and treating as for some set of size , we obtain the result.
为得到(6)的另一写法,展开期望 。因 共有 个位置,每个 的概率为 。因此用期望 展开上式,并把大小为 的某集合 上的 视为 ,即得结果。
∎
E.1 Equivalence between the MDM loss and any-order autoregressive loss
E.1 MDM 损失与任意顺序自回归损失的等价性
In this section, we will demonstrate the equivalence for MDM loss and any-order autoregressive loss. In particular, for all , we show
本节证明 MDM 损失与任意顺序自回归损失的等价。具体地,对所有 ,我们证明
We now consider and and count the number of that induces a specific term . To induce the term, for a given and , must satisfy
现考虑 且 ,并计有多少 会诱导出特定项 。要诱导该项,对给定的 与 , 须满足
The number of that satisfies above is . Using this and the number of total permutations is , we obtain the result.
满足上式的 个数为 。再利用总置换数 ,即得结果。