Natural TTS Synthesis By Conditioning WaveNet On Mel Spectrogram Predictions
Natural TTS Synthesis By Conditioning WaveNet On Mel Spectrogram Predictions
基于梅尔频谱预测条件化 WaveNet 的自然 TTS 合成(Natural TTS Synthesis By Conditioning WaveNet On Mel Spectrogram Predictions)
Jonathan Shen Affiliation: Google, Inc. Ruoming Pang Affiliation: Google, Inc. Ron J. Weiss Affiliation: Google, Inc. Mike Schuster Affiliation: Google, Inc. Navdeep Jaitly Affiliation: Google, Inc. Zongheng Yang † † thanks: Work done while at Google. Affiliation: University of California, Berkeley Zhifeng Chen Affiliation: Google, Inc. Yu Zhang Affiliation: Google, Inc. Yuxuan Wang Affiliation: Google, Inc. RJ Skerry-Ryan Affiliation: Google, Inc. Rif A. Saurous Affiliation: Google, Inc. Yannis Agiomyrgiannakis Affiliation: Google, Inc. Yonghui Wu Affiliation: {jonathanasdf,rpang,yonghui}@google.com Affiliation: Google, Inc.
Jonathan Shen Ruoming Pang Ron J. Weiss Mike Schuster Navdeep Jaitly Zongheng Yang† Zhifeng Chen Yu Zhang Yuxuan Wang RJ Skerry-Ryan Rif A. Saurous Yannis Agiomyrgiannakis Yonghui Wu
所属机构:Google, Inc.;† 工作完成于 Google,University of California, Berkeley
Abstract
摘要
This paper describes Tacotron 2, a neural network architecture for speech synthesis directly from text. The system is composed of a recurrent sequence-to-sequence feature prediction network that maps character embeddings to mel-scale spectrograms, followed by a modified WaveNet model acting as a vocoder to synthesize time-domain waveforms from those spectrograms. Our model achieves a mean opinion score (MOS) of comparable to a MOS of for professionally recorded speech. To validate our design choices, we present ablation studies of key components of our system and evaluate the impact of using mel spectrograms as the conditioning input to WaveNet instead of linguistic, duration, and features. We further show that using this compact acoustic intermediate representation allows for a significant reduction in the size of the WaveNet architecture.
本文介绍 Tacotron 2:一种直接从文本合成语音的神经网络架构。系统由两部分组成:循环序列到序列特征预测网络,把字符嵌入映射为梅尔频谱;以及作为声码器的改进版 WaveNet,再从这些频谱合成时域波形。模型取得平均意见分(MOS),与专业录制语音的 MOS 相当。为验证设计选择,我们对系统关键组件做了消融,并评估用梅尔频谱(而非语言学特征、时长与 )作为 WaveNet 条件输入的影响。我们进一步表明,使用这种紧凑的声学中间表示可显著缩小 WaveNet 架构规模。
1 Introduction
1 引言
Index Terms:
Generating natural speech from text (text-to-speech synthesis, TTS) remains a challenging task despite decades of investigation [1]. Over time, different techniques have dominated the field. Concatenative synthesis with unit selection, the process of stitching small units of pre-recorded waveforms together [2, 3] was the state-of-the-art for many years. Statistical parametric speech synthesis [4, 5, 6, 7], which directly generates smooth trajectories of speech features to be synthesized by a vocoder, followed, solving many of the issues that concatenative synthesis had with boundary artifacts. However, the audio produced by these systems often sounds muffled and unnatural compared to human speech.
- 索引术语:
尽管经过了几十年的调查[1],但从文本中生成自然语音(文本对语音合成,TTS)仍然是一个具有挑战性的任务. 随着时间的推移,不同的技术主导了这个领域. 与单位选择的配合合成,将预录波形的小单元缝合在一起的过程[2,3]是多年来最先进的. 统计参数语音合成 [4, 5, 6, 7],直接生成语音特征的平滑轨迹,由vocoder合成,随后解决了调谐合成与边界伪影有关的许多问题. 然而,与人类语音相比,这些系统所制作的音频往往听起来很模糊和不自然.
WaveNet [8], a generative model of time domain waveforms, produces audio quality that begins to rival that of real human speech and is already used in some complete TTS systems [9, 10, 11]. The inputs to WaveNet (linguistic features, predicted log fundamental frequency (), and phoneme durations), however, require significant domain expertise to produce, involving elaborate text-analysis systems as well as a robust lexicon (pronunciation guide).
WaveNet [8],一种时间域波形的生成模型,其产生的音频质量开始与真实人类语音相比,并且已经用于一些完整的TTS系统[9,10,11]. 然而,对WaveNet的投入(语言特征、预测的对数基本频率()和电话持续时间)需要大量的域名专门知识来制作,其中涉及详尽的文本分析系统以及强有力的词汇(读音指南)。
Tacotron [12], a sequence-to-sequence architecture [13] for producing magnitude spectrograms from a sequence of characters, simplifies the traditional speech synthesis pipeline by replacing the production of these linguistic and acoustic features with a single neural network trained from data alone. To vocode the resulting magnitude spectrograms, Tacotron uses the Griffin-Lim algorithm [14] for phase estimation, followed by an inverse short-time Fourier transform. As the authors note, this was simply a placeholder for future neural vocoder approaches, as Griffin-Lim produces characteristic artifacts and lower audio quality than approaches like WaveNet.
Tacotron [12],一种用于从字符序列中生成量子谱系的序列到序列架构[13],简化了传统的语音合成管道,将这些语言学和声学特征的制作替换为单一神经网络,仅从数据中培训. 为了对由此产生的星等谱进行vocode,Tacotron使用Griffin-Lim算法[14]进行相位估计,然后进行逆向的Fourier变换. 作者指出,这仅仅是未来神经vocoder的占位符,因为Griffin-Lim制作的特质文物和音频质量低于WaveNet等方法.
In this paper, we describe a unified, entirely neural approach to speech synthesis that combines the best of the previous approaches: a sequence-to-sequence Tacotron-style model [12] that generates mel spectrograms, followed by a modified WaveNet vocoder [10, 15]. Trained directly on normalized character sequences and corresponding speech waveforms, our model learns to synthesize natural sounding speech that is difficult to distinguish from real human speech.
在本文中,我们描述了一种统一,完全神经化的语音合成方法,结合了前作中最好的方法:一个序列到序列的Tacotron风格模型[12],生成mel谱,然后是经过修改的WaveNetvocoder[10,15]. 直接接受规范化人物序列和相应语音波形的训练,我们的模型学习合成自然声学语音,这与真实的人类语音难以区分.
Deep Voice 3 [11] describes a similar approach. However, unlike our system, its naturalness has not been shown to rival that of human speech. Char2Wav [16] describes yet another similar approach to end-to-end TTS using a neural vocoder. However, they use different intermediate representations (traditional vocoder features) and their model architecture differs significantly.
Deep Voice 3 [11] 描述了类似的方法. 然而,与我们的系统不同,它的自然性并没有被证明与人类言论的自然性相抗衡。 Char2Wav [16] 描述了另一种类似的方法,使用神经蒸汽机进行端到端的TTS. 然而,它们使用不同的中间代表物(传统的vocoder特征),它们的模型架构差异很大.
2 Model Architecture
2 模型架构
Our proposed system consists of two components, shown in Figure 1:
我们提议的系统由两个部分组成,如图1所示:
2.1 Intermediate Feature Representation
2.1 中间特征表示
In this work we choose a low-level acoustic representation: mel-frequency spectrograms, to bridge the two components. Using a representation that is easily computed from time-domain waveforms allows us to train the two components separately. This representation is also smoother than waveform samples and is easier to train using a squared error loss because it is invariant to phase within each frame.
在这部作品中,我们选择了一个低级的声波表示: 梅尔频谱,以连接两个元件. 使用一种从时间域波形中轻松计算出来的表示法,使我们能够分别训练这两个组件. 这种表示方式也比波形样本更光滑,更容易使用平方误差损失来训练,因为在每个帧内进行相位不易.
A mel-frequency spectrogram is related to the linear-frequency spectrogram, i.e., the short-time Fourier transform (STFT) magnitude. It is obtained by applying a nonlinear transform to the frequency axis of the STFT, inspired by measured responses from the human auditory system, and summarizes the frequency content with fewer dimensions. Using such an auditory frequency scale has the effect of emphasizing details in lower frequencies, which are critical to speech intelligibility, while de-emphasizing high frequency details, which are dominated by fricatives and other noise bursts and generally do not need to be modeled with high fidelity. Because of these properties, features derived from the mel scale have been used as an underlying representation for speech recognition for many decades [17].
一个中间频谱与线性频谱相关,即短时傅里叶变换(STFT)星等. 它通过应用非线性转换到STFT的频率轴上,受人类听觉系统的测量响应的启发而获得,并用更少的维度来总结频率内容. 使用这样的听频尺度具有在低频率中强调细节的效果,对于语音的知觉至关重要,而去强调高频率的细节则以风化和其他噪声暴发为主,一般不需要以高忠诚度为模型. 由于这些属性,从梅尔标度中衍生出来的特征在数十年[17]中被用作语音识别的基础代表.
While linear spectrograms discard phase information (and are therefore lossy), algorithms such as Griffin-Lim [14] are capable of estimating this discarded information, which enables time-domain conversion via the inverse short-time Fourier transform. Mel spectrograms discard even more information, presenting a challenging inverse problem. However, in comparison to the linguistic and acoustic features used in WaveNet, the mel spectrogram is a simpler, lower-level acoustic representation of audio signals. It should therefore be straightforward for a similar WaveNet model conditioned on mel spectrograms to generate audio, essentially as a neural vocoder. Indeed, we will show that it is possible to generate high quality audio from mel spectrograms using a modified WaveNet architecture.
虽然线性光谱丢弃相位信息(因此是失落的),但Griffin-Lim [14]等算法能够估计这个被丢弃的信息,通过逆向短时间Fourier变换可以实现时间域转换. 梅尔光谱丢弃了更多的信息,提出了一个具有挑战性的反向问题. 然而,与WaveNet中使用的语言和声学特征相比,mel谱系是音频信号的较简单,较低层次的声学表现. 因此,一个以梅尔频谱为条件的类似WaveNet模型可以直接生成音频,基本上是作为神经声码器。 事实上,我们将表明,使用经修改的WaveNet架构,可以从梅尔频谱生成高质量的音频。
2.2 Spectrogram Prediction Network
2.2 频谱预测网络
As in Tacotron, mel spectrograms are computed through a short-time Fourier transform (STFT) using a 50 ms frame size, 12.5 ms frame hop, and a Hann window function. We experimented with a 5 ms frame hop to match the frequency of the conditioning inputs in the original WaveNet, but the corresponding increase in temporal resolution resulted in significantly more pronunciation issues.
与Tacotron一样,梅尔频谱是通过一个使用50ms帧大小、12.5ms帧跳和汉恩窗口功能的短时Fourier变换(STFT)计算出来的。 我们试验了5ms帧hop,以匹配原WaveNet中调制输入的频率,但时间分辨率的相应增加导致发音问题明显增加.
We transform the STFT magnitude to the mel scale using an 80 channel mel filterbank spanning 125 Hz to 7.6 kHz, followed by log dynamic range compression. Prior to log compression, the filterbank output magnitudes are clipped to a minimum value of 0.01 in order to limit dynamic range in the logarithmic domain.
我们使用一个覆盖125赫兹至7.6千赫的80个信道网点滤波库,然后进行日志动态范围压缩,将STFT的体积转换为 mel 尺度。 在日志压缩之前,过滤库输出量被剪切到最低值0.01,以限制对数域的动态范围.
The network is composed of an encoder and a decoder with attention. The encoder converts a character sequence into a hidden feature representation which the decoder consumes to predict a spectrogram. Input characters are represented using a learned 512-dimensional character embedding, which are passed through a stack of 3 convolutional layers each containing 512 filters with shape , i.e., where each filter spans 5 characters, followed by batch normalization [18] and ReLU activations. As in Tacotron, these convolutional layers model longer-term context (e.g., -grams) in the input character sequence. The output of the final convolutional layer is passed into a single bi-directional [19] LSTM [20] layer containing 512 units (256 in each direction) to generate the encoded features.
网络由注意的编码器和解码器组成. 编码器将一个字符序列转换成隐藏的特征表示,解码器为预测光谱而消耗. 输入字符使用一个有学问的512维字符嵌入来表示,这些字符通过一个包含512个包含形状的滤波器的3个卷积层传递,即每个滤波器横跨5个字符,然后进行批归一化[18]和ReLU激活. 和塔科特龙一样,这些卷积层模型在输入字符序列中的较长期上下文(如-grams). 最终卷积层的输出传递为单双向[19] LSTM [20]层,包含512个单元(每个方向256个单元),生成编码特征.
The encoder output is consumed by an attention network which summarizes the full encoded sequence as a fixed-length context vector for each decoder output step. We use the location-sensitive attention from [21], which extends the additive attention mechanism [22] to use cumulative attention weights from previous decoder time steps as an additional feature. This encourages the model to move forward consistently through the input, mitigating potential failure modes where some subsequences are repeated or ignored by the decoder. Attention probabilities are computed after projecting inputs and location features to 128-dimensional hidden representations. Location features are computed using 32 1-D convolution filters of length 31.
编码器输出被一个注意网络消耗,这个网络将完整的编码序列概括为每个解码器输出步骤的固定长上下文矢量. 我们使用来自[21]的对位置敏感的注意,这扩展了添加剂的注意机制[22],将以前解码时间步骤的累积注意权重作为附加特征. 这鼓励模型通过输入一致地前进,减轻一些子序列被解码器重复或忽略的潜在故障模式. 注意概率在投影输入和位置特征到128维隐藏表示后计算. 位置特征使用32个长度31的1-D的演化滤波器计算.
The decoder is an autoregressive recurrent neural network which predicts a mel spectrogram from the encoded input sequence one frame at a time. The prediction from the previous time step is first passed through a small pre-net containing 2 fully connected layers of 256 hidden ReLU units. We found that the pre-net acting as an information bottleneck was essential for learning attention. The pre-net output and attention context vector are concatenated and passed through a stack of 2 uni-directional LSTM layers with 1024 units. The concatenation of the LSTM output and the attention context vector is projected through a linear transform to predict the target spectrogram frame. Finally, the predicted mel spectrogram is passed through a 5-layer convolutional post-net which predicts a residual to add to the prediction to improve the overall reconstruction. Each post-net layer is comprised of 512 filters with shape with batch normalization, followed by activations on all but the final layer.
解码器是一种自动递归的循环神经网络,它从一个帧的编码输入序列中预测一个元谱. 前一时段的预测首先通过一个小的pre-net,包含两个完全连接的层256个隐藏的ReLU单位. 我们发现,作为信息瓶颈的前网对于学习关注至关重要。 网前输出和注意力上下文向量被调和,并经过2个单向LSTM层的堆叠,共1024个单元. 通过线性变换预测LSTM输出和注意力上下文向量的结合,以预测目标光谱框架. 最后,预测的 梅尔频谱通过一个5层的进化* 后网* 传递,它预言一个剩余部分会增加预测,以改善整体重建. 每个后网层由512个滤波器组成,形状为,批归一化,除最后一层外,其余所有部分的激活.
We minimize the summed mean squared error (MSE) from before and after the post-net to aid convergence. We also experimented with a log-likelihood loss by modeling the output distribution with a Mixture Density Network [23, 24] to avoid assuming a constant variance over time, but found that these were more difficult to train and they did not lead to better sounding samples.
我们尽可能减少网后前后总和的平方差错,以便援助趋同。 我们还通过将输出分布建模为混合密度网[23,24]来试验日志相似性损失,以避免长期假定存在恒定差异,但发现这些更难训练,没有导致更好的测距样本.
In parallel to spectrogram frame prediction, the concatenation of decoder LSTM output and the attention context is projected down to a scalar and passed through a sigmoid activation to predict the probability that the output sequence has completed. This “stop token” prediction is used during inference to allow the model to dynamically determine when to terminate generation instead of always generating for a fixed duration. Specifically, generation completes at the first frame for which this probability exceeds a threshold of 0.5.
我有光谱 天啊 与光谱框架预测平行的是 解码器 LSTM 输出和注意力的结合度 预测到一个阶梯上下文 并经过一个sigmoid 激活来预测输出序列完成的概率. 这种“停止信号”预测在推论期间用于使模型能够动态地确定何时终止生成,而不是总是在固定时间内生成。 具体地说,生成完成于第一个框架,这个概率超过0.5的阈值.
The convolutional layers in the network are regularized using dropout [25] with probability 0.5, and LSTM layers are regularized using zoneout [26] with probability 0.1. In order to introduce output variation at inference time, dropout with probability 0.5 is applied only to layers in the pre-net of the autoregressive decoder.
网络中的卷积层通过淘汰法进行规范化[25],概率为0.5,LSTM层通过分区化法进行规范化[26],概率为0.1. 为了在推断时间引入输出变异,概率0.5的退出仅适用于自递减码器的前网层.
In contrast to the original Tacotron, our model uses simpler building blocks, using vanilla LSTM and convolutional layers in the encoder and decoder instead of “CBHG” stacks and GRU recurrent layers. We do not use a “reduction factor”, i.e., each decoder step corresponds to a single spectrogram frame.
与最初的Tacotron不同,我们的模型采用了更简单的构件,在编码器和解码器中使用了香草LSTM和卷积层,而不是“CBHG”堆栈和GRU重复层。 我们不使用“减少系数”,即每个解码器步骤都对应一个光谱框架。
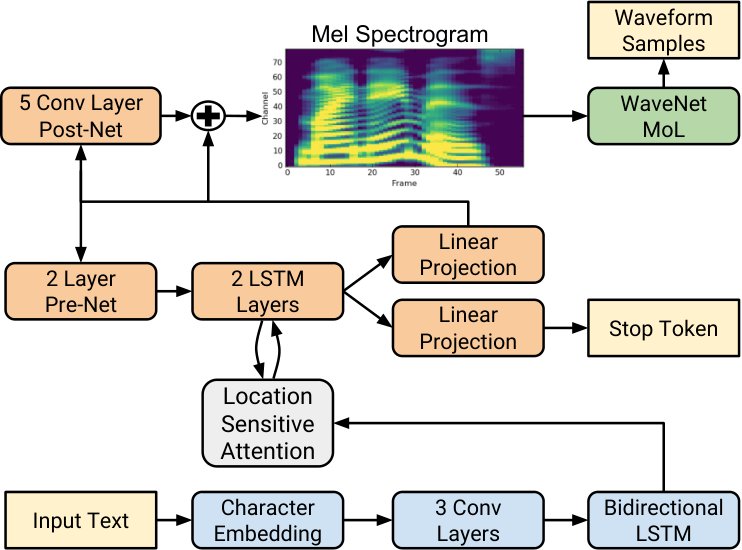
Figure 1: Block diagram of the Tacotron 2 system architecture.
图1:Tacotron 2系统架构的块图。
2.3 WaveNet Vocoder
2.3 WaveNet 声码器
We use a modified version of the WaveNet architecture from [8] to invert the mel spectrogram feature representation into time-domain waveform samples. As in the original architecture, there are 30 dilated convolution layers, grouped into 3 dilation cycles, i.e., the dilation rate of layer k () is . To work with the 12.5 ms frame hop of the spectrogram frames, only 2 upsampling layers are used in the conditioning stack instead of 3 layers.
我们使用[8]的WaveNet架构修改版本,将梅尔频谱特征的表示反转为时域波形样本. 与原始建筑一样,共有30个拓扑层,分为3个拓扑周期,即层k()的拓扑速率为. 为了配合光谱框的12.5ms帧hop,在调制堆栈中仅使用2个升采样层,而不是3个层.
Instead of predicting discretized buckets with a softmax layer, we follow PixelCNN++ [27] and Parallel WaveNet [28] and use a 10-component mixture of logistic distributions (MoL) to generate 16-bit samples at 24 kHz. To compute the logistic mixture distribution, the WaveNet stack output is passed through a ReLU activation followed by a linear projection to predict parameters (mean, log scale, mixture weight) for each mixture component. The loss is computed as the negative log-likelihood of the ground truth sample.
与其用软max层来预测盘状桶,不如跟随PixelCNN++[27]和并行波网[28],并使用物流分布(MoL)的10个组件混合物在24kHz生成16位样本. 为了计算逻辑混合物的分布,WaveNet堆栈输出通过ReLU激活,然后进行线性预测,以预测每种混合物成分的参数(平均、日志尺度、混合物重量)。 损失按地面真象样本的负对数法计算。
3 Experiments & Results
3 实验与结果
3.1 Training Setup
3.1 训练设置
Our training process involves first training the feature prediction network on its own, followed by training a modified WaveNet independently on the outputs generated by the first network.
我们的培训进程亲爱的,首先对特征预测网络进行单独培训,然后就第一个网络产生的产出独立培训一个经过修改的WaveNet。
To train the feature prediction network, we apply the standard maximum-likelihood training procedure (feeding in the correct output instead of the predicted output on the decoder side, also referred to as teacher-forcing) with a batch size of 64 on a single GPU. We use the Adam optimizer [29] with and a learning rate of exponentially decaying to starting after 50,000 iterations. We also apply regularization with weight .
为了训练特征预测网络,我们采用标准的最大相似度训练程序(在解码器一侧的正确输出中喂食而不是预测输出,又称教师-强制),在一个单一的GPU上,批量尺寸为64. 我们使用 Adam 优化器 [29] 与和的学习速率 指数衰减到在 50,000 迭代 后开始。 我们还实行重重的规范化。
We then train our modified WaveNet on the ground truth-aligned predictions of the feature prediction network. That is, the prediction network is run in teacher-forcing mode, where each predicted frame is conditioned on the encoded input sequence and the corresponding previous frame in the ground truth spectrogram. This ensures that each predicted frame exactly aligns with the target waveform samples.
然后,我们训练我们经过修改的WaveNet 关于 * 地面真理-对齐* 对特征预测网络的预测。 也就是说,预测网络以教师强制模式运行,其中每个预测框架都以编码输入序列和地面真理谱系中相应的前帧为条件. 这保证了每个预测框架与目标波形样本完全一致.
We train with a batch size of 128 distributed across 32 GPUs with synchronous updates, using the Adam optimizer with and a fixed learning rate of . It helps quality to average model weights over recent updates. Therefore we maintain an exponentially-weighted moving average of the network parameters over update steps with a decay of 0.9999 – this version is used for inference (see also [29]). To speed up convergence, we scale the waveform targets by a factor of which brings the initial outputs of the mixture of logistics layer closer to the eventual distributions.
我们在32个GPU之间以128的批量规模进行同步更新的训练,使用配有的亚当优化器和的固定学习率. 它有助于在近期更新中平均模型加权。 因此,我们维持网络参数相对于更新步骤的指数加权移动平均值,衰减为0.9999 – 这个版本用于推论(另见[29]). 为了加快趋同速度,我们用的系数将波形目标扩大,使物流层混合的初始产出更接近最终的分布.
We train all models on an internal US English dataset[12], which contains 24.6 hours of speech from a single professional female speaker. All text in our datasets is spelled out. e.g., “16” is written as “sixteen”, i.e., our models are all trained on normalized text.
我们用一个内部的美国英语数据集[12] 对所有模型进行培训,其中包含一名专业女性演讲者24.6小时的演讲. 我们数据集的所有文字都写好了 例如,“16”被写成“十六”,即我们的模型都接受过规范文本的培训。
3.2 Evaluation
3.2 评测
When generating speech in inference mode, the ground truth targets are not known. Therefore, the predicted outputs from the previous step are fed in during decoding, in contrast to the teacher-forcing configuration used for training.
在生成语音推论模式时,地面真理目标并不为人所知. 因此,前一个步骤的预测产出是在解码过程中输入的,与用于培训的教师强制配置不同。
We randomly selected 100 fixed examples from the test set of our internal dataset as the evaluation set. Audio generated on this set are sent to a human rating service similar to Amazon’s Mechanical Turk where each sample is rated by at least 8 raters on a scale from 1 to 5 with 0.5 point increments, from which a subjective mean opinion score (MOS) is calculated. Each evaluation is conducted independently from each other, so the outputs of two different models are not directly compared when raters assign a score to them.
我们随机选择了100个固定的例子 从测试组 我们的内部数据集作为评价集。 本集生成的音频被发送到类似于亚马逊机械图克的人类评级服务,每个样本在1到5的尺度上至少由8位评分员进行评级,并加分0.5分,从中计算出主观平均评分(MOS). 每个评价都是独立进行的,因此在评分者给它们分配分数时,两个不同模型的输出不直接比较.
Note that while instances in the evaluation set never appear in the training set, there are some recurring patterns and common words between the two sets. While this could potentially result in an inflated MOS compared to an evaluation set consisting of sentences generated from random words, using this set allows us to compare to the ground truth. Since all the systems we compare are trained on the same data, relative comparisons are still meaningful.
请注意,虽然评价集中的实例从未出现在培训集中,但两集之间有一些反复出现的模式和共同的词语. 虽然这可能会导致与由随机词生成的句子组成的评价集相比,MOS被夸大,但是使用这个集让我们可以比较地面的真相. 由于我们比较的所有系统都是根据同样的数据来训练的,相对比较仍然是有意义的.
Table 1 shows a comparison of our method against various prior systems. In order to better isolate the effect of using mel spectrograms as features, we compare to a WaveNet conditioned on linguistic features[8] with similar modifications to the WaveNet architecture as introduced above. We also compare to the original Tacotron that predicts linear spectrograms and uses Griffin-Lim to synthesize audio, as well as concatenative [30] and parametric [31] baseline systems, both of which have been used in production at Google. We find that the proposed system significantly outpeforms all other TTS systems, and results in an MOS comparable to that of the ground truth audio. [^2]
表1显示我们的方法与以前各种系统的比较。 为了更好地隔离使用mel谱系作为特征的效果,我们比较了以语言特征为条件的WaveNet[8],上面引入的WaveNet架构也有类似的修改. 我们还比较了最初预测线性谱系的Tacotron,并使用Griffin-Lim合成音频,以及协和[30]和参数[31]基线系统,这两套系统都曾在谷歌生产中使用. 我们认为,拟议的系统大大超过了所有其他的TTS系统,并导致一个与地面真声系统类似的MOS。 [^2]
| System | MOS |
|---|---|
| Parametric | |
| Tacotron (Griffin-Lim) | |
| Concatenative | |
| WaveNet (Linguistic) | |
| Ground truth | |
| Tacotron 2 (this paper) |
Table 1: Mean Opinion Score (MOS) evaluations with 95% confidence intervals computed from the t-distribution for various systems.
| 系统 | 卫生部 |
|---|---|
| 参数 | |
| 塔科特龙(格里芬-林姆) | |
| 调和 | |
| 波浪网 (语言) | |
| 事实 | |
| Tacot未曾使用过, |
表1:平均评分(MOS)评价,95%的置信间隔根据各种系统的t分配计算。
We also conduct a side-by-side evaluation between audio synthesized by our system and the ground truth. For each pair of utterances, raters are asked to give a score ranging from -3 (synthesized much worse than ground truth) to 3 (synthesized much better than ground truth). The overall mean score of shows that raters have a small but statistically significant preference towards ground truth over our results. See Figure 2 for a detailed breakdown. The comments from raters indicate that occasional mispronunciation by our system is the primary reason for this preference.
我们还在由我们的系统合成的音频和地面真相之间进行并肩评估。 每对话,要求评分者给出的分数从-3(合成比地面真理差得多)到3(合成比地面真理好得多)不等. 的总平均分表明,从统计上看,评估者比我们的结果更偏爱地面真相。 详见图2。 评估者的评论表明,我们系统的偶尔发音不当是这种偏好的主要原因。
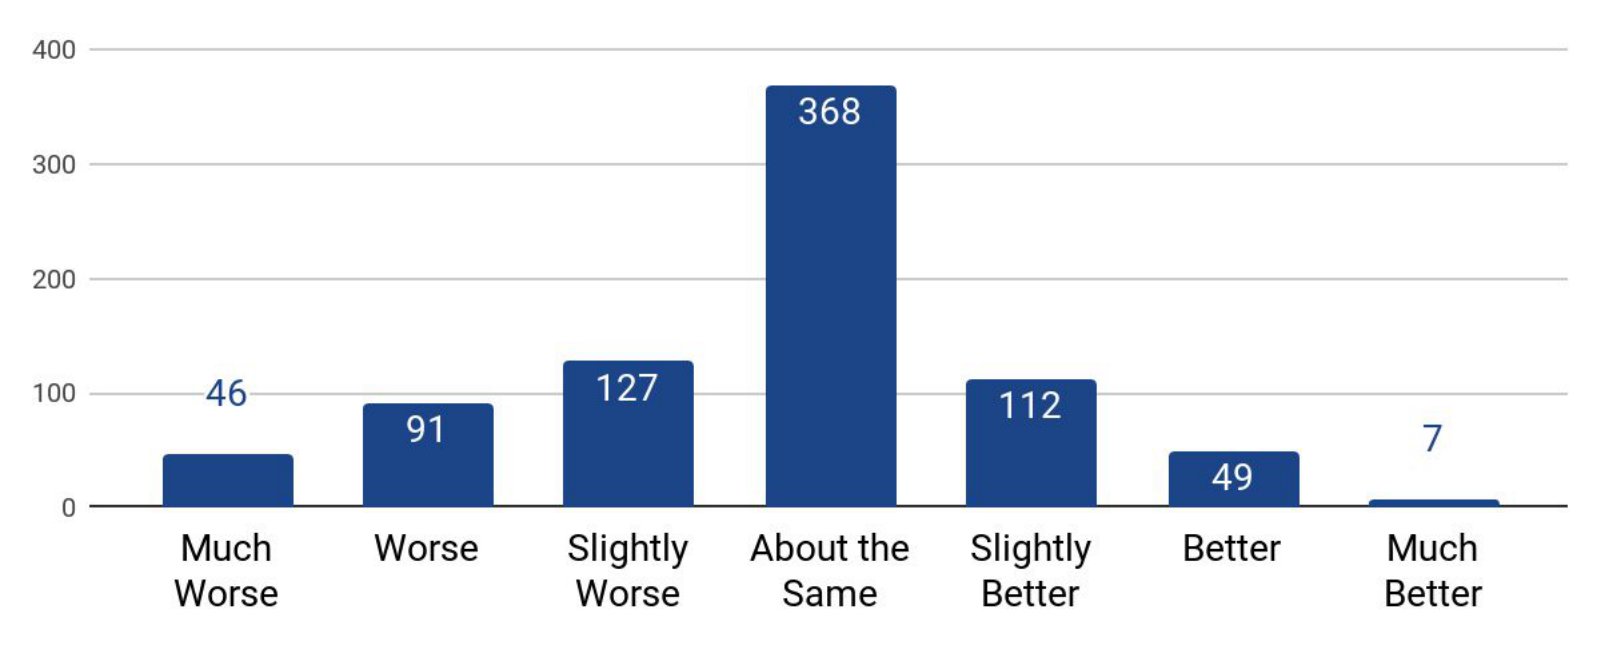
Figure 2: Synthesized vs. ground truth: 800 ratings on 100 items.
图2:合成对地面真相:100项800项收视率.
We ran a separate rating experiment on the custom 100-sentence test set from Appendix E of [11], obtaining a MOS of 4.354. In a manual analysis of the error modes of our system, counting errors in each category independently, 0 sentences contained repeated words, 6 contained mispronunciations, 1 contained skipped words, and 23 were subjectively decided to contain unnatural prosody, such as emphasis on the wrong syllables or words, or unnatural pitch. End-point prediction failed in a single case, on the input sentence containing the most characters. These results show that while our system is able to reliably attend to the entire input, there is still room for improvement in prosody modeling.
我们对附录E[11]中的定制百度判决测试进行了单独的评级试验,获得了4.354的MOS. 在对系统错误模式的人工分析中,独立计数每类错误时,0句包含重复字,6句包含错误的发音,1句包含跳过字,23句主观决定包含不自然的发音,如强调错误的音节或单词,或非自然的发音. 在包含最多字符的输入句上,一个案例的结束点预测失败. 这些结果表明,虽然我们的系统能够可靠地处理整个投入,但在模拟方面仍有改进的余地。
Finally, we evaluate samples generated from 37 news headlines to test the generalization ability of our system to out-of-domain text. On this task, our model receives a MOS of while WaveNet conditioned on linguistic features receives a MOS of . A side-by-side evaluation comparing the output of these systems also shows a virtual tie – a statistically insignificant preference towards our results by . Examination of rater comments shows that our neural system tends to generate speech that feels more natural and human-like, but it sometimes runs into pronunciation difficulties, e.g., when handling names. This result points to a challenge for end-to-end approaches – they require training on data that cover intended usage.
最后,我们评价了37条新闻头条的样本,以测试我们系统对域外文本的通用能力。 关于这项任务,我们的模型得到的MOS,而以语言特征为条件的WaveNet则得到的MOS. 对比这些系统产出的侧面评价也显示出了一种虚拟的比对 — — 从统计学上看,倾向于我们的结果是微不足道的。 对测评员评论的检查表明,我们的神经系统往往会产生感觉更自然和人性的语音,但有时会遇到发音困难,例如在处理名字时. 这一结果表明对端到端方法的挑战——它们需要关于涵盖预期使用的数据的培训。
3.3 Ablation Studies
3.3 消融实验
3.3.1 Predicted Features versus Ground Truth
While the two components of our model were trained separately, the WaveNet component depends on the predicted features for training. An alternative is to train WaveNet independently on mel spectrograms extracted from ground truth audio. We explore this in Table 2.
3.3.1 预测特征与地面真相
虽然我们模式的两个组成部分分别培训,但WaveNet组成部分取决于培训的预测特点。 另一种方法是在从地面真相音频中提取的梅尔频谱上独立训练WaveNet. 我们在表2中对此进行了探讨。
| Synthesis | ||
|---|---|---|
| Training | Predicted | Ground truth |
| Predicted | ||
| Ground truth |
Table 2: Comparison of evaluated MOS for our system when WaveNet trained on predicted/ground truth mel spectrograms are made to synthesize from predicted/ground truth mel spectrograms.
| 综述 | ||
|---|---|---|
| 培训 | 预测 | 事实 |
| 预测 | ||
| 事实 |
表2:在WaveNet接受预测/地面真象分光谱培训,从预测/地面真象分光谱合成时,我们系统的评估MOS比较。
As expected, the best performance is obtained when the features used for training match those used for inference. However, when trained on ground truth features and made to synthesize from predicted features, the result is worse than the opposite. This is due to the tendency of the predicted spectrograms to be oversmoothed and less detailed than the ground truth – a consequence of the squared error loss optimized by the feature prediction network. When trained on ground truth spectrograms, the network does not learn to generate high quality speech waveforms from oversmoothed features.
如预期的那样,如果用于培训的特征与用于推论的特征相匹配,就能取得最佳业绩。 然而,当接受地面真象特征的训练,并从预测的特征合成时,结果比相反的要糟糕. 这是因为预测的光谱往往过于平缓,而且比地面的真相更详细,这是特征预测网络优化的平方误差损失的结果。 在接受地面真象谱学训练时,网络不会从过度流畅的特性中学习生成高质量的语音波形.
3.3.2 Linear Spectrograms
Instead of predicting mel spectrograms, we experiment with training to predict linear-frequency spectrograms instead, making it possible to invert the spectrogram using Griffin-Lim.
3.3.2线性光龛
我们不是预测mel谱系,而是试验训练来预测线频谱系,从而有可能用Griffin-Lim来反转谱系.
| System | MOS |
|---|---|
| Tacotron 2 (Linear + G-L) | |
| Tacotron 2 (Linear + WaveNet) | |
| Tacotron 2 (Mel + WaveNet) |
Table 3: Comparison of evaluated MOS for Griffin-Lim vs. WaveNet as a vocoder, and using 1,025-dimensional linear spectrograms vs. 80-dimensional mel spectrograms as conditioning inputs to WaveNet.
| 系统 | 卫生部 |
|---|---|
| 楞伽二(ear+G-L) | |
| Tacotron 2 (线条+波浪网) | |
| Tacotron 2 (迈尔+波浪网) |
表3:对Griffin-Lim vs. WaveNet作为vocoder的评价MOS的比较,并使用1,025维线性光谱与80维Mel光谱作为WaveNet的调制输入.
As noted in [10], WaveNet produces much higher quality audio compared to Griffin-Lim. However, there is not much difference between the use of linear-scale or mel-scale spectrograms. As such, the use of mel spectrograms seems to be a strictly better choice since it is a more compact representation. It would be interesting to explore the trade-off between the number of mel frequency bins versus audio quality in future work.
如[10]所述,WaveNet制作的音频质量比Griffin-Lim要高得多. 然而,线性尺度或mel尺度光谱的使用差别不大. 就此而言, " 球形 " 球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球状球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形球形 在今后的工作中,探讨金属频箱的数量与音频质量之间的取舍,将很有意义。
3.3.3 Post-Processing Network
Since it is not possible to use the information of predicted future frames before they have been decoded, we use a convolutional post-processing network to incorporate past and future frames after decoding to improve the feature predictions. However, because WaveNet already contains convolutional layers, one may wonder if the post-net is still necessary when WaveNet is used as the vocoder. To answer this question, we compared our model with and without the post-net, and found that without it, our model only obtains a MOS score of , compared to with it, meaning that empirically the post-net is still an important part of the network design.
3.3.3 处理后网络
由于在预言的未来帧解码之前无法使用这些信息,我们使用一个演化的后处理网络,在解码后纳入过去和未来帧,以改善特征预测. 然而,由于WaveNet已经包含革命层,人们可能会怀疑当WaveNet被用作vocoder时,后网是否仍然有必要. 为了回答这个问题,我们将我们的模型与后网和没有后网进行比较,发现没有后网,我们的模型只能获得MOS的的分数,与之相比,的分数,这意味着经验上后网仍然是网络设计的重要组成部分.
3.3.4 Simplifying WaveNet
A defining feature of WaveNet is its use of dilated convolution to increase the receptive field exponentially with the number of layers. We evaluate models with varying receptive field sizes and number of layers to test our hypothesis that a shallow network with a small receptive field may solve the problem satisfactorily since mel spectrograms are a much closer representation of the waveform than linguistic features and already capture long-term dependencies across frames.
3.3.4 简化波浪网
WaveNet的一个决定性特征是它利用膨胀的演化来随着层数的指数增加可接受场. 我们以不同的可接受字段大小和层数来评价模型,以测试我们的假设,即具有小可接受字段的浅层网络可以令人满意地解决问题,因为mel谱系比语言特征更接近于波形的表达,并且已经捕捉到跨帧的长期依赖性.
As shown in Table 4, we find that our model can generate high-quality audio using as few as 12 layers with a receptive field of 10.5 ms, compared to 30 layers and 256 ms in the baseline model. These results confirm the observations in [9] that a large receptive field size is not an essential factor for audio quality. However, we hypothesize that it is the choice to condition on mel spectrograms that allows this reduction in complexity.
如表4所示,我们发现我们的模型能够利用多达12层的可接受场为10.5 ms的音频产生高质量的音频,而基线模型中只有30层和256 ms. 这些结果证实了[9]中的意见,即大面积的可接受字段面积并不是音频质量的基本要素。 然而,我们假设,正是基于梅尔频谱的选择允许这种复杂性的减少。
On the other hand, if we eliminate dilated convolutions altogether, the receptive field becomes two orders of magnitude smaller than the baseline and the quality degrades significantly even though the stack is as deep as the baseline model. This indicates that the model requires sufficient context at the time scale of waveform samples in order to generate high quality sound.
另一方面,如果我们完全消除膨胀的演化,可接受场就变成两个比基线小的大小级,质量会显著地下降,甚至像基准模型一样,堆栈是深的。 这表明模型在波形样品的时间尺度上需要足够的上下文,以便产生高质量的声音.
| Total layers | Num cycles | Dilation cycle size | Receptive field (samples / ms) | MOS |
|---|---|---|---|---|
| 30 | 3 | 10 | 6,139 / 255.8 | |
| 24 | 4 | 6 | 505 / 21.0 | |
| 12 | 2 | 6 | 253 / 10.5 | |
| 30 | 30 | 1 | 61 / 2.5 |
Table 4: WaveNet with various layer and receptive field sizes.
| 层共计 | 数值周期 | 剪切周期大小 | 受体场(样本/毫秒) | 卫生部 |
|---|---|---|---|---|
| 30 | 3 | 10 | 6,139 / 255.8 | |
| 24 | 4 | 6 | 505 / 21.0 | |
| 12 | 2 | 6 | 253 / 10.5 | |
| 30 | 30 | 1 | 61 / 2.5 |
表4:各层和可接受字段大小的波浪网。
4 Conclusion
4 结论
This paper describes Tacotron 2, a fully neural TTS system that combines a sequence-to-sequence recurrent network with attention to predicts mel spectrograms with a modified WaveNet vocoder. The resulting system synthesizes speech with Tacotron-level prosody and WaveNet-level audio quality. This system can be trained directly from data without relying on complex feature engineering, and achieves state-of-the-art sound quality close to that of natural human speech.
本文描述了Tacotron 2,一种全神经TTS系统,将序列到序列的经常性网络结合在一起,注意用经过修改的WaveNetvocoder来预测梅尔频谱. 由此形成的系统以Tacotron级的Prosody和WaveNet级的音频质量合成语音. 这个系统可以直接从数据中进行训练,而不依赖于复杂的特征工程,并实现接近自然人语的先进音质.
5 Acknowledgments
5 致谢
The authors thank Jan Chorowski, Samy Bengio, Aäron van den Oord, and the WaveNet and Machine Hearing teams for their helpful discussions and advice, as well as Heiga Zen and the Google TTS team for their feedback and assistance with running evaluations. The authors are also grateful to the very thorough reviewers.
作者感谢Jan Chorowski、Samy Bengio、Aäron van den Oord以及WaveNet和机器听觉小组的有益讨论和建议,并感谢Heiga Zen和Google TTS小组的反馈和协助进行评价。 作者们也感谢非常彻底的审查者。
References
参考文献
[1] P. Taylor, Text-to-Speech Synthesis , Cambridge University Press, New York, NY, USA, 1st edition, 2009.
[2] A. J. Hunt and A. W. Black, “Unit selection in a concatenative speech synthesis system using a large speech database,” in Proc. ICASSP , 1996, pp. 373–376.
[3] A. W. Black and P. Taylor, “Automatically clustering similar units for unit selection in speech synthesis,” in Proc. Eurospeech , September 1997, pp. 601–604.
[4] K. Tokuda, T. Yoshimura, T. Masuko, T. Kobayashi, and T. Kitamura, “Speech parameter generation algorithms for HMM-based speech synthesis,” in Proc. ICASSP , 2000, pp. 1315–1318.
[5] H. Zen, K. Tokuda, and A. W. Black, “Statistical parametric speech synthesis,” Speech Communication , vol. 51, no. 11, pp. 1039–1064, 2009.
[6] H. Zen, A. Senior, and M. Schuster, “Statistical parametric speech synthesis using deep neural networks,” in Proc. ICASSP , 2013, pp. 7962–7966.
[7] K. Tokuda, Y. Nankaku, T. Toda, H. Zen, J. Yamagishi, and K. Oura, “Speech synthesis based on hidden Markov models,” Proc. IEEE , vol. 101, no. 5, pp. 1234–1252, 2013.
[8] A. van den Oord, S. Dieleman, H. Zen, K. Simonyan, O. Vinyals, A. Graves, N. Kalchbrenner, A. W. Senior, and K. Kavukcuoglu, “WaveNet: A generative model for raw audio,” CoRR , vol. abs/1609.03499, 2016.
[9] S. Ö. Arik, M. Chrzanowski, A. Coates, G. Diamos, A. Gibiansky, Y. Kang, X. Li, J. Miller, J. Raiman, S. Sengupta, and M. Shoeybi, “Deep voice: Real-time neural text-to-speech,” CoRR , vol. abs/1702.07825, 2017.
[10] S. Ö. Arik, G. F. Diamos, A. Gibiansky, J. Miller, K. Peng, W. Ping, J. Raiman, and Y. Zhou, “Deep voice 2: Multi-speaker neural text-to-speech,” CoRR , vol. abs/1705.08947, 2017.
[11] W. Ping, K. Peng, A. Gibiansky, S. Ö. Arik, A. Kannan, S. Narang, J. Raiman, and J. Miller, “Deep voice 3: 2000-speaker neural text-to-speech,” CoRR , vol. abs/1710.07654, 2017.
[12] Y. Wang, R. Skerry-Ryan, D. Stanton, Y. Wu, R. J. Weiss, N. Jaitly, Z. Yang, Y. Xiao, Z. Chen, S. Bengio, Q. Le, Y. Agiomyrgiannakis, R. Clark, and R. A. Saurous, “Tacotron: Towards end-to-end speech synthesis,” in Proc. Interspeech , Aug. 2017, pp. 4006–4010.
[13] I. Sutskever, O. Vinyals, and Q. V. Le, “Sequence to sequence learning with neural networks.,” in Proc. NIPS , Z. Ghahramani, M. Welling, C. Cortes, N. D. Lawrence, and K. Q. Weinberger, Eds., 2014, pp. 3104–3112.
[14] D. W. Griffin and J. S. Lim, “Signal estimation from modified short-time Fourier transform,” IEEE Transactions on Acoustics, Speech and Signal Processing , pp. 236–243, 1984.
[15] A. Tamamori, T. Hayashi, K. Kobayashi, K. Takeda, and T. Toda, “Speaker-dependent WaveNet vocoder,” in Proc. Interspeech , 2017, pp. 1118–1122.
[16] J. Sotelo, S. Mehri, K. Kumar, J. F. Santos, K. Kastner, A. Courville, and Y. Bengio, “Char2Wav: End-to-end speech synthesis,” in Proc. ICLR , 2017.
[17] S. Davis and P. Mermelstein, “Comparison of parametric representations for monosyllabic word recognition in continuously spoken sentences,” IEEE Transactions on Acoustics, Speech and Signal Processing , vol. 28, no. 4, pp. 357 – 366, 1980.
[18] S. Ioffe and C. Szegedy, “Batch normalization: Accelerating deep network training by reducing internal covariate shift,” in Proc. ICML , 2015, pp. 448–456.
[19] M. Schuster and K. K. Paliwal, “Bidirectional recurrent neural networks,” IEEE Transactions on Signal Processing , vol. 45, no. 11, pp. 2673–2681, Nov. 1997.
[20] S. Hochreiter and J. Schmidhuber, “Long short-term memory,” Neural Computation , vol. 9, no. 8, pp. 1735–1780, Nov. 1997.
[21] J. K. Chorowski, D. Bahdanau, D. Serdyuk, K. Cho, and Y. Bengio, “Attention-based models for speech recognition,” in Proc. NIPS , 2015, pp. 577–585.
[22] D. Bahdanau, K. Cho, and Y. Bengio, “Neural machine translation by jointly learning to align and translate,” in Proc. ICLR , 2015.
[23] C. M. Bishop, “Mixture density networks,” Tech. Rep., 1994.
[24] M. Schuster, On supervised learning from sequential data with applications for speech recognition , Ph.D. thesis, Nara Institute of Science and Technology, 1999.
[25] N. Srivastava, G. E. Hinton, A. Krizhevsky, I. Sutskever, and R. Salakhutdinov, “Dropout: a simple way to prevent neural networks from overfitting.,” Journal of Machine Learning Research , vol. 15, no. 1, pp. 1929–1958, 2014.
[26] D. Krueger, T. Maharaj, J. Kramár, M. Pezeshki, N. Ballas, N. R. Ke, A. Goyal, Y. Bengio, H. Larochelle, A. Courville, et al., “Zoneout: Regularizing RNNs by randomly preserving hidden activations,” in Proc. ICLR , 2017.
[27] T. Salimans, A. Karpathy, X. Chen, and D. P. Kingma, “PixelCNN++: Improving the PixelCNN with discretized logistic mixture likelihood and other modifications,” in Proc. ICLR , 2017.
[28] A. van den Oord, Y. Li, I. Babuschkin, K. Simonyan, O. Vinyals, K. Kavukcuoglu, G. van den Driessche, E. Lockhart, L. C. Cobo, F. Stimberg, N. Casagrande, D. Grewe, S. Noury, S. Dieleman, E. Elsen, N. Kalchbrenner, H. Zen, A. Graves, H. King, T. Walters, D. Belov, and D. Hassabis, “Parallel WaveNet: Fast High-Fidelity Speech Synthesis,” CoRR , vol. abs/1711.10433, Nov. 2017.
[29] D. P. Kingma and J. Ba, “Adam: A method for stochastic optimization,” in Proc. ICLR , 2015.
[30] X. Gonzalvo, S. Tazari, C.-a. Chan, M. Becker, A. Gutkin, and H. Silen, “Recent advances in Google real-time HMM-driven unit selection synthesizer,” in Proc. Interspeech , 2016.
[31] H. Zen, Y. Agiomyrgiannakis, N. Egberts, F. Henderson, and P. Szczepaniak, “Fast, compact, and high quality LSTM-RNN based statistical parametric speech synthesizers for mobile devices,” in Proc. Interspeech , 2016.