SuperGlue: Learning Feature Matching With Graph Neural Networks
SuperGlue: Learning Feature Matching with Graph Neural Networks
ETH Zurich \qquad Magic Leap, Inc.
Abstract
摘要
This paper introduces SuperGlue, a neural network that matches two sets of local features by jointly finding correspondences and rejecting non-matchable points. Assignments are estimated by solving a differentiable optimal transport problem, whose costs are predicted by a graph neural network. We introduce a flexible context aggregation mechanism based on attention, enabling SuperGlue to reason about the underlying 3D scene and feature assignments jointly. Compared to traditional, hand-designed heuristics, our technique learns priors over geometric transformations and regularities of the 3D world through end-to-end training from image pairs. SuperGlue outperforms other learned approaches and achieves state-of-the-art results on the task of pose estimation in challenging real-world indoor and outdoor environments. The proposed method performs matching in real-time on a modern GPU and can be readily integrated into modern SfM or SLAM systems. The code and trained weights are publicly available at github.com/magicleap/SuperGluePretrainedNetwork.
本文提出 SuperGlue:这是一种神经网络,通过联合寻找对应关系并剔除不可匹配的点,来匹配两组局部特征。分配通过对一个可微的最优传输问题求解来估计,其代价由一个图神经网络预测。我们引入一种基于注意力的灵活上下文聚合机制,使 SuperGlue 能够同时对底层三维场景和特征分配进行推理。与传统的、手工设计的启发式方法相比,我们的技术通过从图像对进行端到端训练,学习关于几何变换和三维世界规律的先验。SuperGlue 优于其他学习方法,并在具有挑战性的真实室内外环境中的位姿估计任务上取得当时最优结果。所提出的方法可以在现代 GPU 上实时完成匹配,并且可以方便地集成到现代的 SfM 或 SLAM 系统中。代码与训练好的权重公开发布于 github.com/magicleap/SuperGluePretrainedNetwork。
1. Introduction
1. 引言
Correspondences between points in images are essential for estimating the 3D structure and camera poses in geometric computer vision tasks such as Simultaneous Localization and Mapping (SLAM) and Structure-from-Motion (SfM). Such correspondences are generally estimated by matching local features, a process known as data association. Large viewpoint and lighting changes, occlusion, blur, and lack of texture are factors that make 2D-to-2D data association particularly challenging.
图像中点与点之间的对应关系,对于同时定位与地图构建(SLAM)和从运动恢复结构(SfM)这类几何计算机视觉任务中估计三维结构和相机位姿至关重要。这类对应通常通过匹配局部特征来估计,这一过程称为数据关联。较大的视点变化和光照变化、遮挡、模糊以及缺乏纹理,都会使二维到二维的数据关联特别困难。
In this paper, we present a new way of thinking about the feature matching problem. Instead of learning better task-agnostic local features followed by simple matching heuristics and tricks, we propose to learn the matching process from pre-existing local features using a novel neural architecture called SuperGlue. In the context of SLAM, which typically [7] decomposes the problem into the visual feature extraction front-end and the bundle adjustment or pose estimation back-end, our network lies directly in the middle – SuperGlue is a learnable middle-end (see Figure 1).
在本文中,我们提出一种思考特征匹配问题的新方式。我们不再先学习更好的、与任务无关的局部特征,再跟上简单的匹配启发式和技巧,而是提出用一种名为 SuperGlue 的新神经网络结构,从已有的局部特征学习匹配过程。在 SLAM 的语境中,问题通常 [7] 被分解为视觉特征提取前端,以及光束法平差或位姿估计后端;我们的网络正好位于中间——SuperGlue 是一个可学习的中间端(见图 1)。
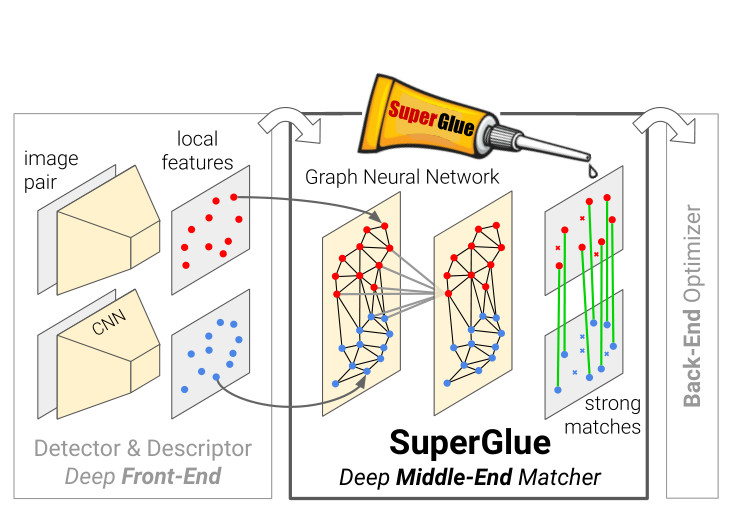
Figure 1: Feature matching with SuperGlue. Our approach establishes pointwise correspondences from off-the-shelf local features: it acts as a middle-end between hand-crafted or learned front-end and back-end. SuperGlue uses a graph neural network and attention to solve an assignment optimization problem, and handles partial point visibility and occlusion elegantly, producing a partial assignment.
图 1:用 SuperGlue 做特征匹配。我们的方法从现成的局部特征出发建立点对点对应:它充当手工或学习得到的前端与后端之间的中间端。SuperGlue 用图神经网络和注意力来求解一个分配优化问题,并能妥善处理点的部分可见与遮挡,从而产生部分分配。
In this work, learning feature matching is viewed as finding the partial assignment between two sets of local features. We revisit the classical graph-based strategy of matching by solving a linear assignment problem, which, when relaxed to an optimal transport problem, can be solved differentiably. The cost function of this optimization is predicted by a Graph Neural Network (GNN). Inspired by the success of the Transformer [55], it uses self- (intra-image) and cross- (inter-image) attention to leverage both spatial relationships of the keypoints and their visual appearance. This formulation enforces the assignment structure of the predictions while enabling the cost to learn complex priors, elegantly handling occlusion and non-repeatable keypoints. Our method is trained end-to-end from image pairs – we learn priors for pose estimation from a large annotated dataset, enabling SuperGlue to reason about the 3D scene and the assignment. Our work can be applied to a variety of multiple-view geometry problems that require high-quality feature correspondences (see Figure 2).
在这项工作中,学习特征匹配被看成在两组局部特征之间寻找部分分配。我们重新采用通过求解线性分配问题来匹配的经典图方法;当该问题被松弛为最优传输问题时,就可以可微地求解。这一优化的代价函数由一个图神经网络(GNN)预测。受 Transformer [55] 成功的启发,它使用自注意力(图像内)和交叉注意力(图像间),以同时利用关键点的空间关系及其视觉外观。这一表述在预测中强制保留分配结构,同时又让代价能够学习复杂先验,并妥善处理遮挡和不可重复的关键点。我们的方法从图像对端到端训练——我们从大规模带标注的数据集中学位姿估计的先验,使 SuperGlue 能够对三维场景和分配进行推理。这项工作可以应用于各种需要高质量特征对应的多视几何问题(见图 2)。
*Work done at Magic Leap, Inc. for a Master's degree. The author thanks his academic supervisors: Cesar Cadena, Marcin Dymczyk, Juan Nieto.
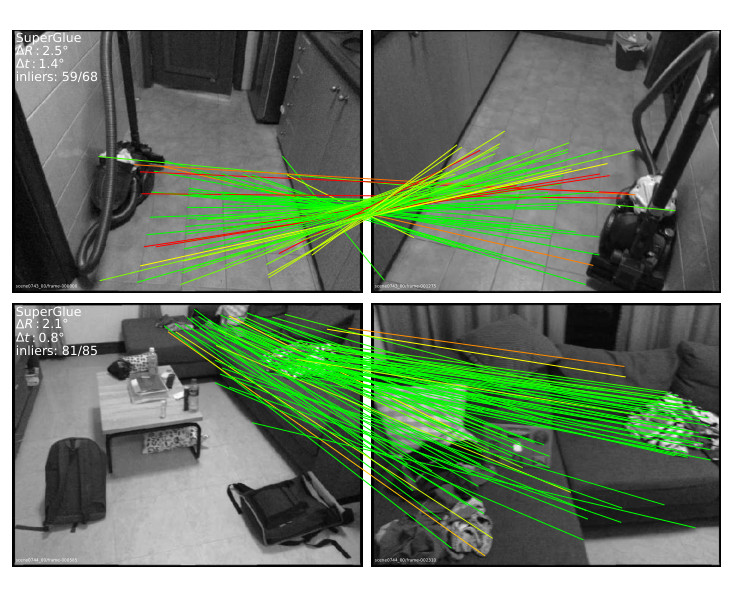
Figure 2: SuperGlue correspondences. For these two challenging indoor image pairs, matching with SuperGlue results in accurate poses while other learned or handcrafted methods fail (correspondences colored by epipolar error).
图 2:SuperGlue 的对应关系。对这两对具有挑战性的室内图像,用 SuperGlue 匹配可以得到准确的位姿,而其他学习或手工方法则会失败(对应线按对极误差着色)。
We show the superiority of SuperGlue compared to both handcrafted matchers and learned inlier classifiers. When combined with SuperPoint [16], a deep front-end, SuperGlue advances the state-of-the-art on the tasks of indoor and outdoor pose estimation and paves the way towards end-to-end deep SLAM.
我们展示了 SuperGlue 相对于手工匹配器和学习得到的内点分类器的优越性。当与深度前端 SuperPoint [16] 结合时,SuperGlue 在室内和室外位姿估计任务上推进了当时的最优水平,并为走向端到端的深度 SLAM 铺平了道路。
2. Related work
2. 相关工作
Local feature matching is generally performed by i) detecting interest points, ii) computing visual descriptors, iii) matching these with a Nearest Neighbor (NN) search, iv) filtering incorrect matches, and finally v) estimating a geometric transformation. The classical pipeline developed in the 2000s is often based on SIFT [28], filters matches with Lowe's ratio test [28], the mutual check, and heuristics such as neighborhood consensus [53, 9, 5, 45], and finds a transformation with a robust solver like RANSAC [19, 40].
局部特征匹配通常按以下步骤进行:i) 检测兴趣点,ii) 计算视觉描述子,iii) 用最近邻(NN)搜索进行匹配,iv) 过滤错误匹配,最后 v) 估计几何变换。2000 年代发展出的经典流程常常基于 SIFT [28],用 Lowe 的比率检验 [28]、互检验,以及邻域一致性 [53, 9, 5, 45] 这类启发式来过滤匹配,再用 RANSAC [19, 40] 这类鲁棒求解器寻找变换。
Recent works on deep learning for matching often focus on learning better sparse detectors and local descriptors [16, 17, 34, 42, 61] from data using Convolutional Neural Networks (CNNs). To improve their discriminativeness, some works explicitly look at a wider context using regional features [29] or log-polar patches [18]. Other approaches learn to filter matches by classifying them into inliers and outliers [30, 41, 6, 63]. These operate on sets of matches, still estimated by NN search, and thus ignore the assignment structure and discard visual information. Works that learn to perform matching have so far focused on dense matching [43] or 3D point clouds [59], and still exhibit the same limitations. In contrast, our learnable middle-end simultaneously performs context aggregation, matching, and filtering in a single end-to-end architecture.
近来用深度学习做匹配的工作,常常着眼于用卷积神经网络(CNN)从数据中学习更好的稀疏检测器和局部描述子 [16, 17, 34, 42, 61]。为提高可判别性,有些工作用区域特征 [29] 或对数极坐标图块 [18] 显式地看更宽的上下文。另一些方法学习通过把匹配分成内点和外点来过滤 [30, 41, 6, 63]。这些方法作用在仍由最近邻搜索估计得到的匹配集合上,因而忽略了分配结构,也丢掉了视觉信息。迄今学习执行匹配的工作主要集中在稠密匹配 [43] 或三维点云 [59] 上,并且仍然表现出同样的局限。相比之下,我们可学习的中间端在单一的端到端结构中同时完成上下文聚合、匹配和过滤。
Graph matching problems are usually formulated as quadratic assignment problems, which are NP-hard, requiring expensive, complex, and thus impractical solvers [27]. For local features, the computer vision literature of the 2000s [4, 24, 51] uses handcrafted costs with many heuristics, making it complex and brittle. Caetano et al. [8] learn the cost of the optimization for a simpler linear assignment, but only use a shallow model, while our SuperGlue learns a flexible cost using a deep neural network. Related to graph matching is the problem of optimal transport [57] – it is a generalized linear assignment with an efficient yet simple approximate solution, the Sinkhorn algorithm [49, 11, 36].
图匹配问题通常被表述为二次分配问题,这类问题是 NP 难的,需要昂贵、复杂因而并不实用的求解器 [27]。对于局部特征,2000 年代的计算机视觉文献 [4, 24, 51] 使用带有大量启发式的手工代价,因而复杂且脆弱。Caetano 等人 [8] 为更简单的线性分配学习优化代价,但只用了浅层模型;而我们的 SuperGlue 用深度神经网络学习一种灵活的代价。与图匹配相关的是最优传输问题 [57]——它是一种广义线性分配,并有一种高效而简单的近似解法,即 Sinkhorn 算法 [49, 11, 36]。
Deep learning for sets such as point clouds aims at designing permutation equi- or invariant functions by aggregating information across elements. Some works treat all elements equally, through global pooling [62, 37, 13] or instance normalization [54, 30, 29], while others focus on a local neighborhood in coordinate or feature space [38, 60]. Attention [55, 58, 56, 23] can perform both global and data-dependent local aggregation by focusing on specific elements and attributes, and is thus more flexible. By observing that self-attention can be seen as an instance of a Message Passing Graph Neural Network [21, 3] on a complete graph, we apply attention to graphs with multiple types of edges, similar to [25, 64], and enable SuperGlue to learn complex reasoning about the two sets of local features.
针对点云这类集合的深度学习,旨在通过在元素之间聚合信息,设计对排列等变或不变的函数。有些工作通过全局池化 [62, 37, 13] 或实例归一化 [54, 30, 29] 平等对待所有元素,另一些则关注坐标空间或特征空间中的局部邻域 [38, 60]。注意力 [55, 58, 56, 23] 可以通过聚焦特定元素和属性,同时进行全局的和依赖于数据的局部聚合,因而更加灵活。我们观察到自注意力可以看成完整图上消息传递图神经网络 [21, 3] 的一个实例,于是把注意力用到具有多种边类型的图上,这与 [25, 64] 类似,并使 SuperGlue 能够学习对两组局部特征进行复杂推理。
3. The SuperGlue Architecture
3. SuperGlue 结构
Motivation: In the image matching problem, some regularities of the world could be leveraged: the 3D world is largely smooth and sometimes planar, all correspondences for a given image pair derive from a single epipolar transform if the scene is static, and some poses are more likely than others. In addition, 2D keypoints are usually projections of salient 3D points, like corners or blobs, thus correspondences across images must adhere to certain physical constraints: i) a keypoint can have at most a single correspondence in the other image; and ii) some keypoints will be unmatched due to occlusion and failure of the detector. An effective model for feature matching should aim at finding all correspondences between reprojections of the same 3D points and identifying keypoints that have no matches. We formulate SuperGlue (see Figure 3) as solving an optimization problem, whose cost is predicted by a deep neural network. This alleviates the need for domain expertise and heuristics – we learn relevant priors directly from the data.
动机: 在图像匹配问题中,可以利用世界的一些规律:三维世界大体平滑,有时还是平面的;如果场景是静止的,给定图像对的全部对应都来自同一个对极变换;并且有些位姿比其他位姿更常见。此外,二维关键点通常是显著三维点(如角点或斑点)的投影,因此跨图像的对应必须遵守某些物理约束:i) 一个关键点在另一幅图像中至多有一个对应;ii) 有些关键点会因为遮挡或检测器失败而没有匹配。一个有效的特征匹配模型,应当力求找出同一三维点的再投影之间的全部对应,并识别出没有匹配的关键点。我们把 SuperGlue(见图 3)表述为求解一个优化问题,其代价由深度神经网络预测。这减轻了对领域知识和启发式的依赖——我们直接从数据中学习相关先验。
Formulation: Consider two images and , each with a set of keypoint positions and associated visual descriptors – we refer to them jointly as the local features. Positions consist of and image coordinates as well as a detection confidence , . Visual descriptors can be those extracted by a CNN like SuperPoint or traditional descriptors like SIFT. Images and have and local features, indexed by and , respectively.
形式化: 考虑两幅图像 和 ,各有一组关键点位置 和相应的视觉描述子 ——我们把它们合在一起 称为局部特征。位置由图像坐标 、 以及检测置信度 组成,。视觉描述子 可以是由 SuperPoint 这类 CNN 提取的,也可以是 SIFT 这类传统描述子。图像 和 分别有 和 个局部特征,下标集合为 和 。
Partial Assignment: Constraints i) and ii) mean that correspondences derive from a partial assignment between the two sets of keypoints. For the integration into downstream tasks and better interpretability, each possible correspondence should have a confidence value. We consequently define a partial soft assignment matrix as:
Our goal is to design a neural network that predicts the assignment from two sets of local features.
部分分配: 约束 i) 和 ii) 意味着对应关系来自两组关键点之间的部分分配。为了便于接入下游任务并提高可解释性,每个可能的对应都应当有一个置信度。因此我们定义部分软分配矩阵 为:
我们的目标是设计一个神经网络,从两组局部特征预测分配 。
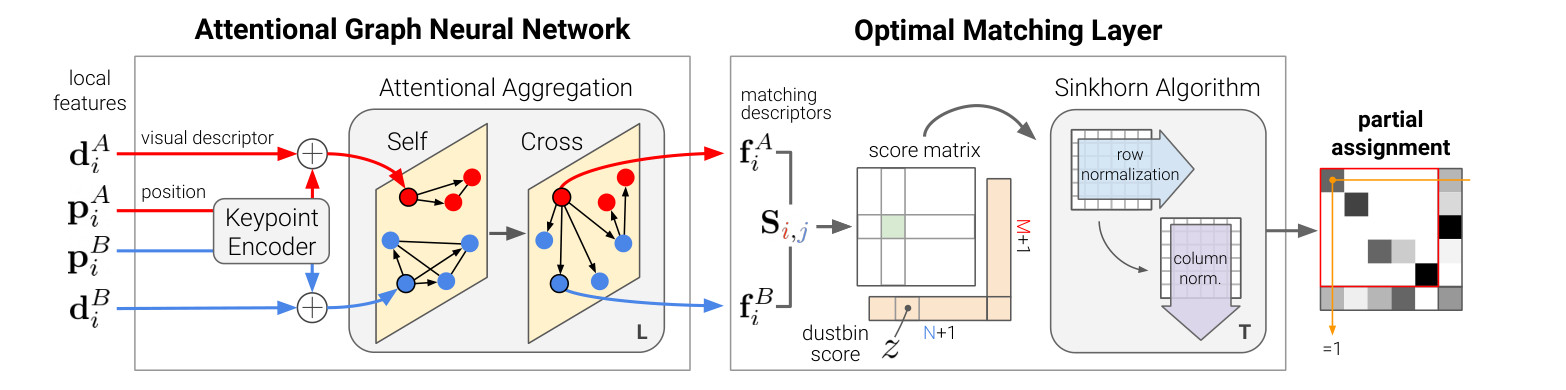
Figure 3: The SuperGlue architecture. SuperGlue is made up of two major components: the attentional graph neural network (Section 3.1), and the optimal matching layer (Section 3.2). The first component uses a keypoint encoder to map keypoint positions and their visual descriptors into a single vector, and then uses alternating self- and cross-attention layers (repeated times) to create more powerful representations . The optimal matching layer creates an by score matrix, augments it with dustbins, then finds the optimal partial assignment using the Sinkhorn algorithm (for iterations).
图 3:SuperGlue 结构。SuperGlue 由两个主要部分组成:注意力图神经网络(第 3.1 节)和最优匹配层(第 3.2 节)。第一部分用关键点编码器把关键点位置 及其视觉描述子 映射成单个向量,然后交替使用自注意力层和交叉注意力层(重复 次),以产生更强的表示 。最优匹配层建立一个 乘 的分数矩阵,用垃圾箱(dustbin)加以增广,再用 Sinkhorn 算法(迭代 次)求出最优部分分配。
3.1. Attentional Graph Neural Network
3.1. 注意力图神经网络
Besides the position of a keypoint and its visual appearance, integrating other contextual cues can intuitively increase its distinctiveness. We can for example consider its spatial and visual relationship with other co-visible keypoints, such as ones that are salient [29], self-similar [48], statistically co-occurring [65], or adjacent [52]. On the other hand, knowledge of keypoints in the second image can help to resolve ambiguities by comparing candidate matches or estimating the relative photometric or geometric transformation from global and unambiguous cues.
除了关键点的位置和视觉外观,融入其他上下文线索,直观上可以提高它的可区分性。例如,我们可以考虑它与其他共同可见关键点在空间和视觉上的关系,比如显著的 [29]、自相似的 [48]、统计上共现的 [65],或相邻的 [52] 关键点。另一方面,关于第二幅图像中关键点的知识,可以通过比较候选匹配,或从全局且无歧义的线索估计相对光度或几何变换,来帮助消除歧义。
When asked to match a given ambiguous keypoint, humans look back-and-forth at both images: they sift through tentative matching keypoints, examine each, and look for contextual cues that help disambiguate the true match from other self-similarities [10]. This hints at an iterative process that can focus its attention on specific locations.
在被要求匹配一个给定的、有歧义的关键点时,人会在两幅图像之间来回查看:他们筛选暂定的匹配关键点,逐个检查,并寻找有助于把真正匹配与其他自相似之处区分开的上下文线索 [10]。这提示了一种可以把注意力集中到特定位置的迭代过程。
We consequently design the first major block of SuperGlue as an Attentional Graph Neural Network (see Figure 3). Given initial local features, it computes matching descriptors by letting the features communicate with each other. As we will show, long-range feature aggregation within and across images is vital for robust matching.
因此,我们把 SuperGlue 的第一个主要模块设计成注意力图神经网络(见图 3)。给定初始局部特征,它通过让这些特征彼此通信,来计算匹配描述子 。如我们将展示的,在图像内部和图像之间进行长程特征聚合,对于稳健匹配至关重要。
Keypoint Encoder: The initial representation for each keypoint combines its visual appearance and location. We embed the keypoint position into a high-dimensional vector with a Multilayer Perceptron (MLP) as:
This encoder enables the graph network to later reason about both appearance and position jointly, especially when combined with attention, and is an instance of the “positional encoder” popular in language processing [20, 55].
关键点编码器: 每个关键点 的初始表示 结合了它的视觉外观和位置。我们用多层感知机(MLP)把关键点位置嵌入到一个高维向量中:
这一编码器使图网络随后能够同时对外观与位置进行推理,尤其是与注意力结合时;它也是语言处理中流行的“位置编码器”的一个实例 [20, 55]。
Multiplex Graph Neural Network: We consider a single complete graph whose nodes are the keypoints of both images. The graph has two types of undirected edges – it is a multiplex graph [31, 33]. Intra-image edges, or self edges, , connect keypoints to all other keypoints within the same image. Inter-image edges, or cross edges, , connect keypoints to all keypoints in the other image. We use the message passing formulation [21, 3] to propagate information along both types of edges. The resulting multiplex Graph Neural Network starts with a high-dimensional state for each node and computes at each layer an updated representation by simultaneously aggregating messages across all given edges for all nodes.
多重图神经网络: 我们考虑一张完整图,其节点是两幅图像的全部关键点。该图有两类无向边——它是一张多重图(multiplex graph)[31, 33]。图像内的边,即自边 ,把关键点 连接到同一幅图像中的所有其他关键点。图像间的边,即交叉边 ,把关键点 连接到另一幅图像中的所有关键点。我们使用消息传递表述 [21, 3],沿两类边传播信息。由此得到的多重图神经网络从每个节点的高维状态出发,在每一层通过同时沿所有给定边为所有节点聚合消息,来计算更新后的表示。
Let be the intermediate representation for element in image at layer . The message is the result of the aggregation from all keypoints , where . The residual message passing update for all in is:
where denotes concatenation. A similar update can be simultaneously performed for all keypoints in image . A fixed number of layers with different parameters are chained and alternatively aggregate along the self and cross edges. As such, starting from , if is odd and if is even.
设 为图像 中元素 在第 层的中间表示。消息 是从所有关键点 聚合的结果,其中 。对 中所有 的残差消息传递更新为:
其中 表示拼接。对图像 中的所有关键点可以同时做类似的更新。将固定数量、参数各不相同的 层串联起来,并交替沿自边和交叉边聚合。因此,从 开始,当 为奇数时 ,当 为偶数时 。
Attentional Aggregation: An attention mechanism performs the aggregation and computes the message . Self edges are based on self-attention [55] and cross edges are based on cross-attention. Akin to database retrieval, a representation of , the query , retrieves the values of some elements based on their attributes, the keys . The message is computed as a weighted average of the values:
where the attention weight is the Softmax over the key-query similarities: .
注意力聚合: 注意力机制执行聚合并计算消息 。自边基于自注意力 [55],交叉边基于交叉注意力。与数据库检索类似, 的一个表示,即查询 ,根据某些元素的属性(键 )检索它们的值 。消息计算为这些值的加权平均:
其中注意力权重 是对键-查询相似度的 Softmax:。
The key, query, and value are computed as linear projections of deep features of the graph neural network. Considering that query keypoint is in the image and all source keypoints are in image , , we can write:
Each layer has its own projection parameters, learned and shared for all keypoints of both images. In practice, we improve the expressivity with multi-head attention [55].
键、查询和值由图神经网络的深层特征经线性投影得到。考虑到查询关键点 位于图像 ,而所有源关键点位于图像 ,,我们可以写成:
每一层 有自己的投影参数,这些参数是学习得到的,并对两幅图像的所有关键点共享。实践中,我们用多头注意力 [55] 提高表达能力。
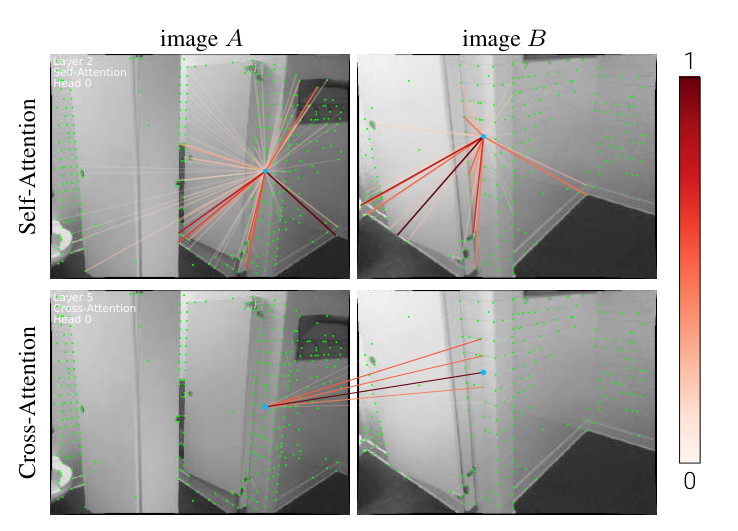
Figure 4: Visualizing self- and cross-attention. Attentional aggregation builds a dynamic graph between keypoints. Weights are shown as rays. Self-attention (top) can attend anywhere in the same image, e.g. distinctive locations, and is thus not restricted to nearby locations. Cross-attention (bottom) attends to locations in the other image, such as potential matches that have a similar appearance.
图 4:可视化自注意力和交叉注意力。注意力聚合在关键点之间建立一张动态图。权重 用射线表示。自注意力(上)可以注意到同一幅图像中的任意位置,例如有区分度的位置,因此并不局限于邻近位置。交叉注意力(下)注意到另一幅图像中的位置,例如外观相似的潜在匹配。
Our formulation provides maximum flexibility as the network can learn to focus on a subset of keypoints based on specific attributes (see Figure 4). SuperGlue can retrieve or attend based on both appearance and keypoint location as they are encoded in the representation . This includes attending to a nearby keypoint and retrieving the relative positions of similar or salient keypoints. This enables representations of the geometric transformation and the assignment. The final matching descriptors are linear projections:
and similarly for keypoints in .
我们的表述提供了最大的灵活性,因为网络可以学习根据特定属性聚焦于一个关键点子集(见图 4)。由于外观和关键点位置都编码在表示 中,SuperGlue 可以基于二者进行检索或注意。这包括注意到邻近的关键点,并检索相似或显著关键点的相对位置。这使得关于几何变换和分配的表示成为可能。最终的匹配描述子是线性投影:
对 中的关键点也类似。
3.2. Optimal matching layer
3.2. 最优匹配层
The second major block of SuperGlue (see Figure 3) is the optimal matching layer, which produces a partial assignment matrix. As in the standard graph matching formulation, the assignment can be obtained by computing a score matrix for all possible matches and maximizing the total score under the constraints in Equation 1. This is equivalent to solving a linear assignment problem.
SuperGlue 的第二个主要模块(见图 3)是最优匹配层,它产生一个部分分配矩阵。与标准的图匹配表述一样,分配 可以通过为所有可能的匹配计算分数矩阵 ,并在公式 1 的约束下最大化总分 来得到。这等价于求解一个线性分配问题。
Score Prediction: Building a separate representation for all potential matches would be prohibitive. We instead express the pairwise score as the similarity of matching descriptors:
where is the inner product. As opposed to learned visual descriptors, the matching descriptors are not normalized, and their magnitude can change per feature and during training to reflect the prediction confidence.
分数预测: 为全部 个潜在匹配分别建立表示,代价将过高。我们转而把成对分数表示为匹配描述子的相似度:
其中 是内积。与学习得到的视觉描述子不同,匹配描述子不做归一化,其幅度可以随特征以及训练过程变化,以反映预测置信度。
Occlusion and Visibility: To let the network suppress some keypoints, we augment each set with a dustbin so that unmatched keypoints are explicitly assigned to it. This technique is common in graph matching, and dustbins have also been used by SuperPoint [16] to account for image cells that might not have a detection. We augment the scores to by appending a new row and column, the point-to-bin and bin-to-bin scores, filled with a single learnable parameter:
While keypoints in will be assigned to a single keypoint in or the dustbin, each dustbin has as many matches as there are keypoints in the other set: , for dustbins in , respectively. We denote as and the number of expected matches for each keypoint and dustbin in and . The augmented assignment now has the constraints:
遮挡与可见性: 为了让网络抑制某些关键点,我们给每一组加上一个垃圾箱(dustbin),使未匹配的关键点被明确分配到其中。这一技术在图匹配中很常见,SuperPoint [16] 也曾用垃圾箱来处理可能没有检测的图像单元。我们通过追加一行和一列(点到箱以及箱到箱的分数),把分数 增广为 ,这些位置填入单个可学习参数:
虽然 中的关键点会被分配到 中的单个关键点或垃圾箱,但每个垃圾箱的匹配数等于另一组中的关键点数:对 、 中的垃圾箱分别是 、。我们把 和 中每个关键点和垃圾箱的期望匹配数记为 和 。增广后的分配 现在具有约束:
Sinkhorn Algorithm: The solution of the above optimization problem corresponds to the optimal transport [36] between discrete distributions and with scores . Its entropy-regularized formulation naturally results in the desired soft assignment, and can be efficiently solved on GPU with the Sinkhorn algorithm [49, 11]. It is a differentiable version of the Hungarian algorithm [32], classically used for bipartite matching, that consists in iteratively normalizing along rows and columns, similar to row and column Softmax. After iterations, we drop the dustbins and recover .
Sinkhorn 算法: 上述优化问题的解,对应于以分数 在离散分布 与 之间的最优传输 [36]。它的熵正则化表述自然得到所需的软分配,并且可以用 Sinkhorn 算法 [49, 11] 在 GPU 上高效求解。它是经典用于二分图匹配的匈牙利算法 [32] 的可微版本,做法是沿行和列迭代地归一化 ,类似于行和列的 Softmax。经过 次迭代后,我们丢掉垃圾箱,恢复出 。
3.3. Loss
3.3. 损失
By design, both the graph neural network and the optimal matching layer are differentiable – this enables backpropagation from matches to visual descriptors. SuperGlue is trained in a supervised manner from ground truth matches . These are estimated from ground truth relative transformations – using poses and depth maps or homographies. This also lets us label some keypoints and as unmatched if they do not have any reprojection in their vicinity. Given these labels, we minimize the negative log-likelihood of the assignment :
This supervision aims at simultaneously maximizing the precision and the recall of the matching.
按照设计,图神经网络和最优匹配层都是可微的——这使得梯度可以从匹配回传到视觉描述子。SuperGlue 以监督方式从真值匹配 训练。这些匹配由真值相对变换估计得到——使用位姿和深度图,或单应。这也可以让我们把一些在邻近处没有任何再投影的关键点 和 标为未匹配。给定这些标签,我们最小化分配 的负对数似然:
这一监督的目标是同时最大化匹配的精度和召回。
3.4. Comparisons to related work
3.4. 与相关工作的比较
The SuperGlue architecture is equivariant to permutation of the keypoints within an image. Unlike other handcrafted or learned approaches, it is also equivariant to permutation of the images, which better reflects the symmetry of the problem and provides a beneficial inductive bias. Additionally, the optimal transport formulation enforces reciprocity of the matches, like the mutual check, but in a soft manner, similar to [43], thus embedding it into the training process.
SuperGlue 的结构对一幅图像内关键点的排列是等变的。与其他手工或学习方法不同,它对两幅图像的排列也是等变的,这更好地反映了问题的对称性,并提供了有益的归纳偏置。此外,最优传输表述像互检验一样强制匹配的互惠性,但是以软的方式,这与 [43] 类似,从而把它嵌入到训练过程中。
SuperGlue vs. Instance Normalization [54]: Attention, as used by SuperGlue, is a more flexible and powerful context aggregation mechanism than instance normalization, which treats all keypoints equally, as used by previous work on feature matching [30, 63, 29, 41, 6].
SuperGlue 与实例归一化 [54]: SuperGlue 所使用的注意力,是一种比实例归一化更灵活、更有力的上下文聚合机制;实例归一化平等对待所有关键点,曾被先前的特征匹配工作采用 [30, 63, 29, 41, 6]。
SuperGlue vs. ContextDesc [29]: SuperGlue can jointly reason about appearance and position while ContextDesc processes them separately. Moreover, ContextDesc is a front-end that additionally requires a larger regional extractor, and a loss for keypoints scoring. SuperGlue only needs local features, learned or handcrafted, and can thus be a simple drop-in replacement for existing matchers.
SuperGlue 与 ContextDesc [29]: SuperGlue 可以同时对外观和位置进行推理,而 ContextDesc 将二者分开处理。此外,ContextDesc 是一个前端,还需要一个更大的区域提取器,以及用于关键点打分的损失。SuperGlue 只需要学习的或手工的局部特征,因此可以简单地替换现有匹配器。
SuperGlue vs. Transformer [55]: SuperGlue borrows the self-attention from the Transformer, but embeds it into a graph neural network, and additionally introduces the cross-attention, which is symmetric. This simplifies the architecture and results in better feature reuse across layers.
SuperGlue 与 Transformer [55]: SuperGlue 借用了 Transformer 中的自注意力,但把它嵌入图神经网络,并额外引入了对称的交叉注意力。这简化了结构,并带来更好的跨层特征复用。
4. Implementation details
4. 实现细节
SuperGlue can be combined with any local feature detector and descriptor but works particularly well with SuperPoint [16], which produces repeatable and sparse keypoints – enabling very efficient matching. Visual descriptors are bilinearly sampled from the semi-dense feature map. For a fair comparison to other matchers, unless explicitly mentioned, we do not train the visual descriptor network when training SuperGlue. At test time, one can use a confidence threshold (we choose 0.2) to retain some matches from the soft assignment, or use all of them and their confidence in a subsequent step, such as weighted pose estimation.
SuperGlue 可以与任何局部特征检测器和描述子结合,但与 SuperPoint [16] 搭配尤其好,后者产生可重复且稀疏的关键点,从而使匹配非常高效。视觉描述子从半稠密特征图中双线性采样得到。为了与其他匹配器公平比较,除非另行说明,我们在训练 SuperGlue 时不训练视觉描述子网络。测试时,可以用一个置信度阈值(我们取 0.2)从软分配中保留部分匹配,也可以把全部匹配及其置信度用于后续步骤,例如加权位姿估计。
Architecture details: All intermediate representations (key, query value, descriptors) have the same dimension as the SuperPoint descriptors. We use layers of alternating multi-head self- and cross-attention with 4 heads each, and perform Sinkhorn iterations. The model is implemented in PyTorch [35], contains 12M parameters, and runs in real-time on an NVIDIA GTX 1080 GPU: a forward pass takes on average 69 ms (15 FPS) for an indoor image pair (see Appendix C).
结构细节: 所有中间表示(键、查询值、描述子)的维度都与 SuperPoint 描述子相同,为 。我们使用 层交替的多头自注意力和交叉注意力,每层 4 个头,并执行 次 Sinkhorn 迭代。模型用 PyTorch [35] 实现,包含 1200 万参数,并在一块 NVIDIA GTX 1080 GPU 上实时运行:对一对室内图像,一次前向平均需要 69 毫秒(15 帧每秒)(见附录 C)。
Training details: To allow for data augmentation, SuperPoint detect and describe steps are performed on-the-fly as batches during training. A number of random keypoints are further added for efficient batching and increased robustness. More details are provided in Appendix E.
训练细节:为了能够做数据增强,SuperPoint 的检测与描述步骤在训练过程中按批次即时进行。我们还进一步加入若干随机关键点,以便高效组批并提高稳健性。更多细节见附录 E。
5. Experiments
5. 实验
5.1. Homography estimation
5.1. 单应估计
We perform a large-scale homography estimation experiment using real images and synthetic homographies with both robust (RANSAC) and non-robust (DLT) estimators.
我们用真实图像和合成单应,同时使用鲁棒(RANSAC)和非鲁棒(DLT)估计器,进行了大规模单应估计实验。
Dataset: We generate image pairs by sampling random homographies and applying random photometric distortions to real images, following a recipe similar to [14, 16, 42, 41]. The underlying images come from the set of 1M distractor images in the Oxford and Paris dataset [39], split into training, validation, and test sets.
数据集: 我们通过采样随机单应,并对真实图像施加随机光度扰动来生成图像对,做法与 [14, 16, 42, 41] 类似。所用图像来自 Oxford 和 Paris 数据集 [39] 中的 100 万张干扰图像,并划分成训练、验证和测试集。
| Local features | Matcher | Homography estimation AUCRANSAC | Homography estimation AUCDLT | P | R |
|---|---|---|---|---|---|
| SuperPoint | NN | 39.47 | 0.00 | 21.7 | 65.4 |
| SuperPoint | NN + mutual | 42.45 | 0.24 | 43.8 | 56.5 |
| SuperPoint | NN + PointCN | 43.02 | 45.40 | 76.2 | 64.2 |
| SuperPoint | NN + OANet | 44.55 | 52.29 | 82.8 | 64.7 |
| SuperPoint | SuperGlue | 53.67 | 65.85 | 90.7 | 98.3 |
Table 1: Homography estimation. SuperGlue recovers almost all possible matches while suppressing most outliers. Because SuperGlue correspondences are high-quality, the Direct Linear Transform (DLT), a least-squares based solution with no robustness mechanism, outperforms RANSAC.
| Local features | Matcher | Homography estimation AUCRANSAC | Homography estimation AUCDLT | P | R |
|---|---|---|---|---|---|
| SuperPoint | NN | 39.47 | 0.00 | 21.7 | 65.4 |
| SuperPoint | NN + mutual | 42.45 | 0.24 | 43.8 | 56.5 |
| SuperPoint | NN + PointCN | 43.02 | 45.40 | 76.2 | 64.2 |
| SuperPoint | NN + OANet | 44.55 | 52.29 | 82.8 | 64.7 |
| SuperPoint | SuperGlue | 53.67 | 65.85 | 90.7 | 98.3 |
表 1:单应估计。SuperGlue 恢复了几乎所有可能的匹配,同时抑制了大多数外点。由于 SuperGlue 的对应质量高,没有鲁棒机制的、基于最小二乘的直接线性变换(DLT)反而优于 RANSAC。
Baselines: We compare SuperGlue against several matchers applied to SuperPoint local features – the Nearest Neighbor (NN) matcher and various outlier rejectors: the mutual NN constraint, PointCN [30], and Order-Aware Network (OANet) [63]. All learned methods, including SuperGlue, are trained on ground truth correspondences, found by projecting keypoints from one image to the other. We generate homographies and photometric distortions on-the-fly – an image pair is never seen twice during training.
基线: 我们将 SuperGlue 与若干作用在 SuperPoint 局部特征上的匹配器进行比较——最近邻(NN)匹配器,以及各种剔外点方法:互最近邻约束、PointCN [30] 和 Order-Aware Network(OANet)[63]。包括 SuperGlue 在内的所有学习方法,都在通过把关键点从一幅图像投影到另一幅图像得到的真值对应上训练。我们即时生成单应和光度扰动——训练中同一对图像不会出现两次。
Metrics: Match precision (P) and recall (R) are computed from the ground truth correspondences. Homography estimation is performed with both RANSAC and the Direct Linear Transformation [22] (DLT), which has a direct least-squares solution. We compute the mean reprojection error of the four corners of the image and report the area under the cumulative error curve (AUC) up to a value of 10 pixels.
指标: 匹配精度(P)和召回(R)由真值对应计算。单应估计同时使用 RANSAC 和具有直接最小二乘解的直接线性变换 [22](DLT)。我们计算图像四个角点的平均重投影误差,并报告累计误差曲线下、直至 10 个像素的面积(AUC)。
Results: SuperGlue is sufficiently expressive to master homographies, achieving 98% recall and high precision (see Table 1). The estimated correspondences are so good that a robust estimator is not required – SuperGlue works even better with DLT than RANSAC. Outlier rejection methods like PointCN and OANet cannot predict more correct matches than the NN matcher itself, overly relying on the initial descriptors (see Figure 6 and Appendix A).
结果:SuperGlue 的表达能力足以掌握单应,达到 98% 的召回和很高的精度(见表 1)。估计得到的对应质量很高,以至于不需要鲁棒估计器——SuperGlue 配 DLT 甚至比配 RANSAC 更好。PointCN 和 OANet 这类剔外点方法无法预测出比最近邻匹配器本身更多的正确匹配,过度依赖初始描述子(见图 6 和附录 A)。
5.2. Indoor pose estimation
5.2. 室内位姿估计
Indoor image matching is very challenging due to the lack of texture, the abundance of self-similarities, the complex 3D geometry of scenes, and large viewpoint changes. As we show in the following, SuperGlue can effectively learn priors to overcome these challenges.
室内图像匹配非常困难,原因是缺乏纹理、大量自相似、场景的复杂三维几何,以及较大的视点变化。如下所示,SuperGlue 能够有效学习先验来克服这些挑战。
Dataset: We use ScanNet [12], a large-scale indoor dataset composed of monocular sequences with ground truth poses and depth images, and well-defined training, validation, and test splits corresponding to different scenes. Previous works select training and evaluation pairs based on time difference [34, 15] or SfM covisibility [30, 63, 6], usually computed using SIFT. We argue that this limits the difficulty of the pairs, and instead select these based on an overlap score computed for all possible image pairs in a given sequence using only ground truth poses and depth. This results in significantly wider-baseline pairs, which corresponds to the current frontier for real-world indoor image matching. Discarding pairs with too small or too large overlap, we select 230M training and 1500 test pairs.
数据集: 我们使用 ScanNet [12],这是一个大规模室内数据集,由带有真值位姿和深度图像的单目序列组成,并有对应不同场景的明确训练、验证和测试划分。先前工作根据时间差 [34, 15] 或通常用 SIFT 计算的 SfM 共视 [30, 63, 6] 来选择训练和评估对。我们认为这限制了对的难度,转而根据只用真值位姿和深度、对给定序列中所有可能图像对计算的重叠分数来选择。由此得到明显更宽基线的图像对,这对应于真实世界室内图像匹配当时的前沿。丢掉重叠过小或过大的对之后,我们选出 2.30 亿训练对和 1500 个测试对。
Metrics: As in previous work [30, 63, 6], we report the AUC of the pose error at the thresholds (, , ), where the pose error is the maximum of the angular errors in rotation and translation. Relative poses are obtained from essential matrix estimation with RANSAC. We also report the match precision and the matching score [16, 61], where a match is deemed correct based on its epipolar distance.
指标: 与先前工作 [30, 63, 6] 一样,我们报告位姿误差在阈值(,,)处的 AUC,其中位姿误差是旋转与平移角误差中的较大者。相对位姿由带 RANSAC 的本质矩阵估计得到。我们还报告匹配精度和匹配分数 [16, 61],其中匹配是否正确按其对极距离判定。
| Local features | Matcher | Pose estimation AUC@5° | @10° | @20° | P | MS |
|---|---|---|---|---|---|---|
| ORB | NN + GMS | 5.21 | 13.65 | 25.36 | 72.0 | 5.7 |
| D2-Net | NN + mutual | 5.25 | 14.53 | 27.96 | 46.7 | 12.0 |
| ContextDesc | NN + ratio test | 6.64 | 15.01 | 25.75 | 51.2 | 9.2 |
| SIFT | NN + ratio test | 5.83 | 13.06 | 22.47 | 40.3 | 1.0 |
| SIFT | NN + NG-RANSAC | 6.19 | 13.80 | 23.73 | 61.9 | 0.7 |
| SIFT | NN + OANet | 6.00 | 14.33 | 25.90 | 38.6 | 4.2 |
| SIFT | SuperGlue | 6.71 | 15.70 | 28.67 | 74.2 | 9.8 |
| SuperPoint | NN + mutual | 9.43 | 21.53 | 36.40 | 50.4 | 18.8 |
| SuperPoint | NN + distance + mutual | 9.82 | 22.42 | 36.83 | 63.9 | 14.6 |
| SuperPoint | NN + GMS | 8.39 | 18.96 | 31.56 | 50.3 | 19.0 |
| SuperPoint | NN + PointCN | 11.40 | 25.47 | 41.41 | 71.8 | 25.5 |
| SuperPoint | NN + OANet | 11.76 | 26.90 | 43.85 | 74.0 | 25.7 |
| SuperPoint | SuperGlue | 16.16 | 33.81 | 51.84 | 84.4 | 31.5 |
Table 2: Wide-baseline indoor pose estimation. We report the AUC of the pose error, the matching score (MS) and precision (P), all in percents %. SuperGlue outperforms all handcrafted and learned matchers when applied to both SIFT and SuperPoint.
| Local features | Matcher | Pose estimation AUC@5° | @10° | @20° | P | MS |
|---|---|---|---|---|---|---|
| ORB | NN + GMS | 5.21 | 13.65 | 25.36 | 72.0 | 5.7 |
| D2-Net | NN + mutual | 5.25 | 14.53 | 27.96 | 46.7 | 12.0 |
| ContextDesc | NN + ratio test | 6.64 | 15.01 | 25.75 | 51.2 | 9.2 |
| SIFT | NN + ratio test | 5.83 | 13.06 | 22.47 | 40.3 | 1.0 |
| SIFT | NN + NG-RANSAC | 6.19 | 13.80 | 23.73 | 61.9 | 0.7 |
| SIFT | NN + OANet | 6.00 | 14.33 | 25.90 | 38.6 | 4.2 |
| SIFT | SuperGlue | 6.71 | 15.70 | 28.67 | 74.2 | 9.8 |
| SuperPoint | NN + mutual | 9.43 | 21.53 | 36.40 | 50.4 | 18.8 |
| SuperPoint | NN + distance + mutual | 9.82 | 22.42 | 36.83 | 63.9 | 14.6 |
| SuperPoint | NN + GMS | 8.39 | 18.96 | 31.56 | 50.3 | 19.0 |
| SuperPoint | NN + PointCN | 11.40 | 25.47 | 41.41 | 71.8 | 25.5 |
| SuperPoint | NN + OANet | 11.76 | 26.90 | 43.85 | 74.0 | 25.7 |
| SuperPoint | SuperGlue | 16.16 | 33.81 | 51.84 | 84.4 | 31.5 |
表 2:宽基线室内位姿估计。我们报告位姿误差的 AUC、匹配分数(MS)和精度(P),全部以百分比 % 计。当用于 SIFT 和 SuperPoint 时,SuperGlue 都优于所有手工和学习匹配器。
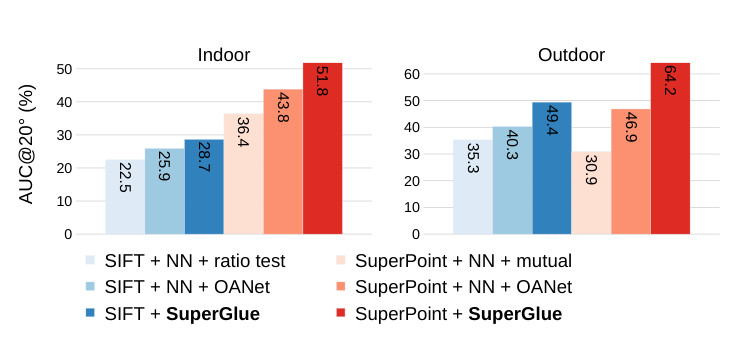
Figure 5: Indoor and outdoor pose estimation. SuperGlue works with SIFT or SuperPoint local features and consistently improves by a large margin the pose accuracy over OANet, a state-of-the-art outlier rejection neural network.
图 5:室内和室外位姿估计。SuperGlue 可与 SIFT 或 SuperPoint 局部特征配合,并相对于当时先进的剔外点神经网络 OANet,稳定地大幅提高位姿精度。
Baselines: We evaluate SuperGlue and various baseline matchers using both root-normalized SIFT [28, 2] and SuperPoint [16] features. SuperGlue is trained with correspondences and unmatched keypoints derived from ground truth poses and depth. All baselines are based on the Nearest Neighbor (NN) matcher and potentially an outlier rejection method. In the “Handcrafted” category, we consider the mutual check, the ratio test [28], thresholding by descriptor distance, and the more complex GMS [5]. Methods in the “Learned” category are PointCN [30], and its follow-ups OANet [63] and NG-RANSAC [6]. We retrain PointCN and OANet on ScanNet for both SuperPoint and SIFT with the classification loss using the above-defined correctness criterion and their respective regression losses. For NG-RANSAC, we use the original trained model. We do not include any graph matching methods as they are orders of magnitude too slow for the number of keypoints that we consider (). Other local features are evaluated as reference: ORB [44] with GMS, D2-Net [17], and ContextDesc [29] using the publicly available trained models.
基线: 我们用根归一化的 SIFT [28, 2] 和 SuperPoint [16] 特征,评估 SuperGlue 以及各种基线匹配器。SuperGlue 用由真值位姿和深度得到的对应及未匹配关键点来训练。所有基线都基于最近邻(NN)匹配器,并可能加上剔外点方法。在“手工”一类中,我们考虑互检验、比率检验 [28]、按描述子距离阈值化,以及更复杂的 GMS [5]。“学习”一类中的方法是 PointCN [30],以及它的后续工作 OANet [63] 和 NG-RANSAC [6]。我们在 ScanNet 上为 SuperPoint 和 SIFT 重新训练 PointCN 和 OANet,分类损失使用上面定义的正确性标准,并使用它们各自的回归损失。对 NG-RANSAC,我们使用原先训练好的模型。我们没有纳入任何图匹配方法,因为对于我们所考虑的关键点数量(),它们要慢上几个数量级。作为参照,我们还评估了其他局部特征:配 GMS 的 ORB [44]、D2-Net [17],以及使用公开已训练模型的 ContextDesc [29]。
Results: SuperGlue enables significantly higher pose accuracy compared to both handcrafted and learned matchers (see Table 2 and Figure 5), and works well with both SIFT and SuperPoint. It has a significantly higher precision than other learned matchers, demonstrating its higher representation power. It also produces a larger number of correct matches – up to 10 times more than the ratio test when applied to SIFT, because it operates on the full set of possible matches, rather than the limited set of nearest neighbors. SuperGlue with SuperPoint achieves state-of-the-art results on indoor pose estimation. They complement each other well since repeatable keypoints make it possible to estimate a larger number of correct matches even in very challenging situations (see Figure 2, Figure 6, and Appendix A).
结果:与手工和学习匹配器相比,SuperGlue 都能显著提高位姿精度(见表 2 和图 5),并且与 SIFT 和 SuperPoint 都能很好配合。它的精度显著高于其他学习匹配器,表明其表示能力更强。它还产生更多正确匹配——用于 SIFT 时最多可比比率检验多约 10 倍,因为它在全部可能匹配的集合上操作,而不是仅在有限的最近邻集合上。SuperGlue 与 SuperPoint 结合,在室内位姿估计上取得了当时最优结果。二者互补良好,因为可重复的关键点使得即使在非常困难的情形下,也有可能估计出更多正确匹配(见图 2、图 6 和附录 A)。
5.3. Outdoor pose estimation
5.3. 室外位姿估计
As outdoor image sequences present their own set of challenges (e.g., lighting changes and occlusion), we train and evaluate SuperGlue for pose estimation in an outdoor setting. We use the same evaluation metrics and baseline methods as in the indoor pose estimation task.
由于室外图像序列有其自身的一组挑战(例如光照变化和遮挡),我们在室外设定中训练并评估 SuperGlue 的位姿估计。我们使用与室内位姿估计任务相同的评估指标和基线方法。
Dataset: We evaluate on the PhotoTourism dataset, which is part of the CVPR'19 Image Matching Challenge [1]. It is a subset of the YFCC100M dataset [50] and has ground truth poses and sparse 3D models obtained from an off-the-shelf SfM tool [34, 46, 47]. All learned methods are trained on the larger MegaDepth dataset [26], which also has depth maps computed with multi-view stereo. Scenes that are in the PhotoTourism test set are removed from the training set. Similarly as in the indoor case, we select challenging image pairs for training and evaluation using an overlap score computed from the SfM covisibility as in [17, 34].
数据集: 我们在 PhotoTourism 数据集上评估,它是 CVPR'19 Image Matching Challenge [1] 的一部分。它是 YFCC100M 数据集 [50] 的一个子集,并带有由现成 SfM 工具 [34, 46, 47] 得到的真值位姿和稀疏三维模型。所有学习方法都在更大的 MegaDepth 数据集 [26] 上训练,该数据集还带有用多视立体计算得到的深度图。PhotoTourism 测试集中的场景会从训练集中去掉。与室内情形类似,我们用由 SfM 共视计算的重叠分数,按 [17, 34] 的方式,为训练和评估选择具有挑战性的图像对。
| Local features | Matcher | Pose estimation AUC@5° | @10° | @20° | P | MS |
|---|---|---|---|---|---|---|
| ContextDesc | NN + ratio test | 20.16 | 31.65 | 44.05 | 56.2 | 3.3 |
| SIFT | NN + ratio test | 15.19 | 24.72 | 35.30 | 43.4 | 1.7 |
| SIFT | NN + NG-RANSAC | 15.61 | 25.28 | 35.87 | 64.4 | 1.9 |
| SIFT | NN + OANet | 18.02 | 28.76 | 40.31 | 55.0 | 3.7 |
| SIFT | SuperGlue | 23.68 | 36.44 | 49.44 | 74.1 | 7.2 |
| SuperPoint | NN + mutual | 9.80 | 18.99 | 30.88 | 22.5 | 4.9 |
| SuperPoint | NN + GMS | 13.96 | 24.58 | 36.53 | 47.1 | 4.7 |
| SuperPoint | NN + OANet | 21.03 | 34.08 | 46.88 | 52.4 | 8.4 |
| SuperPoint | SuperGlue | 34.18 | 50.32 | 64.16 | 84.9 | 11.1 |
Table 3: Outdoor pose estimation. Matching SuperPoint and SIFT features with SuperGlue results in significantly higher pose accuracy (AUC), precision (P), and matching score (MS) than with handcrafted or other learned methods.
| Local features | Matcher | Pose estimation AUC@5° | @10° | @20° | P | MS |
|---|---|---|---|---|---|---|
| ContextDesc | NN + ratio test | 20.16 | 31.65 | 44.05 | 56.2 | 3.3 |
| SIFT | NN + ratio test | 15.19 | 24.72 | 35.30 | 43.4 | 1.7 |
| SIFT | NN + NG-RANSAC | 15.61 | 25.28 | 35.87 | 64.4 | 1.9 |
| SIFT | NN + OANet | 18.02 | 28.76 | 40.31 | 55.0 | 3.7 |
| SIFT | SuperGlue | 23.68 | 36.44 | 49.44 | 74.1 | 7.2 |
| SuperPoint | NN + mutual | 9.80 | 18.99 | 30.88 | 22.5 | 4.9 |
| SuperPoint | NN + GMS | 13.96 | 24.58 | 36.53 | 47.1 | 4.7 |
| SuperPoint | NN + OANet | 21.03 | 34.08 | 46.88 | 52.4 | 8.4 |
| SuperPoint | SuperGlue | 34.18 | 50.32 | 64.16 | 84.9 | 11.1 |
表 3:室外位姿估计。用 SuperGlue 匹配 SuperPoint 和 SIFT 特征,得到的位姿精度(AUC)、精度(P)和匹配分数(MS)都显著高于手工或其他学习方法。
Results: As shown in Table 3, SuperGlue outperforms all baselines, at all relative pose thresholds, when applied to both SuperPoint and SIFT. Most notably, the precision of the resulting matching is very high (84.9%), reinforcing the analogy that SuperGlue “glues” together local features.
结果: 如表 3 所示,无论用于 SuperPoint 还是 SIFT,SuperGlue 在所有相对位姿阈值上都优于全部基线。尤其突出的是,由此得到的匹配精度非常高(84.9%),这加强了 SuperGlue 把局部特征“粘”在一起的这一类比。
5.4. Understanding SuperGlue
5.4. 理解 SuperGlue
| Matcher | Pose AUC@20° | Match precision | Matching score | |
|---|---|---|---|---|
| NN + mutual | 36.40 | 50.4 | 18.8 | |
| SuperGlue | No Graph Neural Net | 38.56 | 66.0 | 17.2 |
| SuperGlue | No cross-attention | 42.57 | 74.0 | 25.3 |
| SuperGlue | No positional encoding | 47.12 | 75.8 | 26.6 |
| SuperGlue | Smaller (3 layers) | 46.93 | 79.9 | 30.0 |
| SuperGlue | Full (9 layers) | 51.84 | 84.4 | 31.5 |
Table 4: Ablation of SuperGlue. While the optimal matching layer alone improves over the baseline Nearest Neighbor matcher, the Graph Neural Network explains the majority of the gains brought by SuperGlue. Both cross-attention and positional encoding are critical for strong gluing, and a deeper network further improves the precision.
| Matcher | Pose AUC@20° | Match precision | Matching score | |
|---|---|---|---|---|
| NN + mutual | 36.40 | 50.4 | 18.8 | |
| SuperGlue | No Graph Neural Net | 38.56 | 66.0 | 17.2 |
| SuperGlue | No cross-attention | 42.57 | 74.0 | 25.3 |
| SuperGlue | No positional encoding | 47.12 | 75.8 | 26.6 |
| SuperGlue | Smaller (3 layers) | 46.93 | 79.9 | 30.0 |
| SuperGlue | Full (9 layers) | 51.84 | 84.4 | 31.5 |
表 4:SuperGlue 的消融。虽然仅最优匹配层就已经优于基线最近邻匹配器,但图神经网络解释了 SuperGlue 所带来增益的大部分。交叉注意力和位置编码对强有力的“粘合”都至关重要,更深的网络还进一步提高了精度。
Ablation study: To evaluate our design decisions, we repeat the indoor experiments with SuperPoint features, but this time focusing on different SuperGlue variants. This ablation study, presented in Table 4, shows that all SuperGlue blocks are useful and bring substantial performance gains. When we additionally backpropagate through the SuperPoint descriptor network while training SuperGlue, we observe an improvement in AUC@20° from 51.84 to 53.38. This confirms that SuperGlue is suitable for end-to-end learning beyond matching.
消融实验: 为评估我们的设计选择,我们用 SuperPoint 特征重复室内实验,但这次聚焦于不同的 SuperGlue 变体。表 4 中的消融表明,SuperGlue 的各个模块都有用,并带来显著的性能增益。当我们在训练 SuperGlue 时额外把梯度回传到 SuperPoint 描述子网络时,观察到 AUC@20° 从 51.84 提升到 53.38。这证实 SuperGlue 适合超出匹配本身的端到端学习。
Visualizing Attention: The extensive diversity of self- and cross-attention patterns is shown in Figure 7 and reflects the complexity of the learned behavior. A detailed analysis of the trends and inner-workings is performed in Appendix D.
可视化注意力: 图 7 展示了自注意力和交叉注意力模式的广泛多样性,也反映出所学行为的复杂性。对趋势和内部机制的详细分析见附录 D。
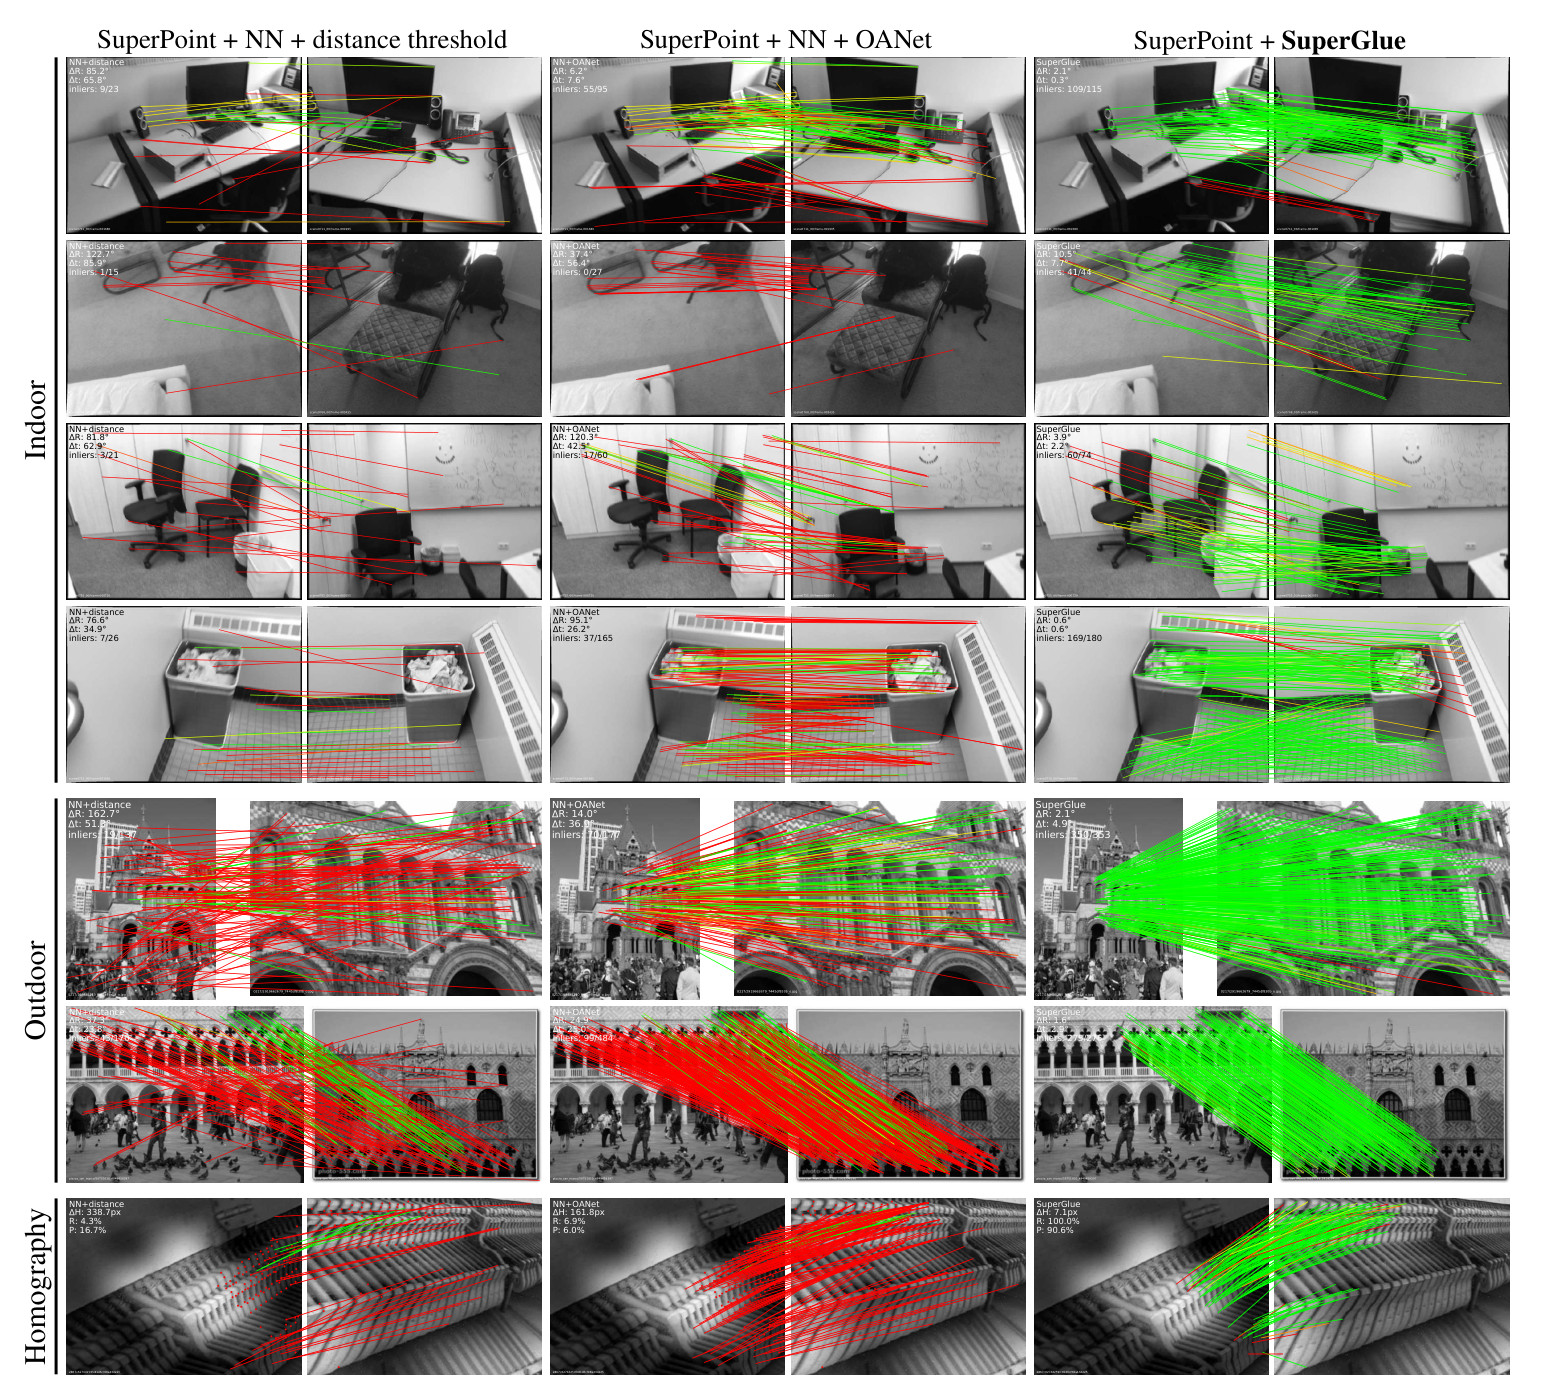
Figure 6: Qualitative image matches. We compare SuperGlue to the Nearest Neighbor (NN) matcher with two outlier rejectors, handcrafted and learned, in three environments. SuperGlue consistently estimates more correct matches (green lines) and fewer mismatches (red lines), successfully coping with repeated texture, large viewpoint, and illumination changes.
图 6:定性图像匹配。我们在三种环境中,把 SuperGlue 与配有两种剔外点方法(手工的和学习的)的最近邻(NN)匹配器进行比较。SuperGlue 稳定地估计出更多正确匹配(绿线)和更少错误匹配(红线),并能成功应对重复纹理、大视点变化和光照变化。
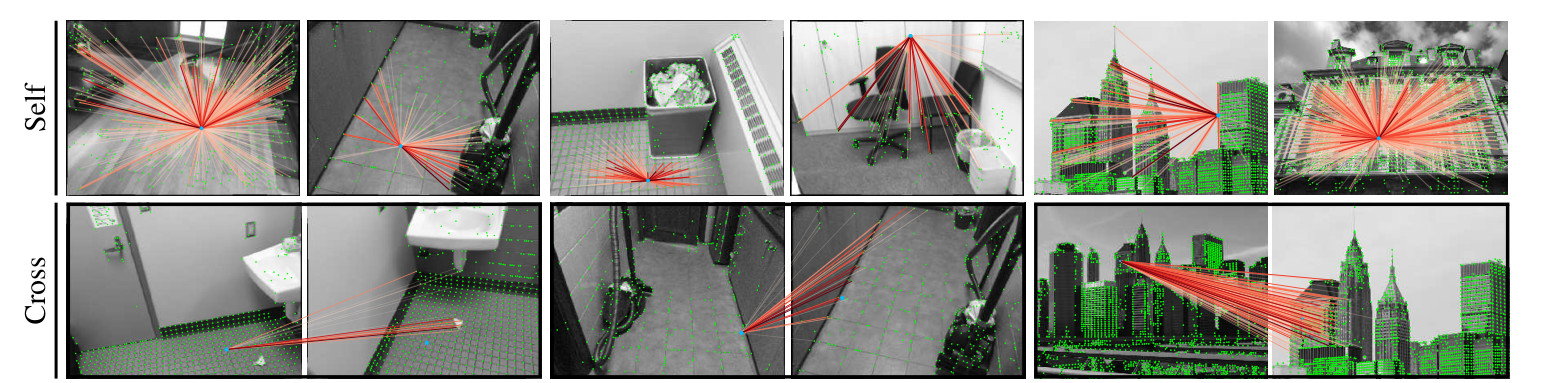
Figure 7: Visualizing attention. We show self- and cross-attention weights at various layers and heads. SuperGlue exhibits a diversity of patterns: it can focus on global or local context, self-similarities, distinctive features, or match candidates.
图 7:可视化注意力。我们展示不同层和不同头上的自注意力与交叉注意力权重 。SuperGlue 表现出多样的模式:它可以聚焦全局或局部上下文、自相似、有区分度的特征,或匹配候选。
6. Conclusion
6. 结论
This paper demonstrates the power of attention-based graph neural networks for local feature matching. SuperGlue's architecture uses two kinds of attention: (i) self-attention, which boosts the receptive field of local descriptors, and (ii) cross-attention, which enables cross-image communication and is inspired by the way humans look back-and-forth when matching images. Our method elegantly handles partial assignments and occluded points by solving an optimal transport problem. Our experiments show that SuperGlue achieves significant improvement over existing approaches, enabling highly accurate relative pose estimation on extreme wide-baseline indoor and outdoor image pairs. In addition, SuperGlue runs in real-time and works well with both classical and learned features.
本文展示了基于注意力的图神经网络在局部特征匹配上的能力。SuperGlue 的结构使用两种注意力:(i)自注意力,它扩大了局部描述子的感受野;(ii)交叉注意力,它实现跨图像通信,并受到人在匹配图像时来回查看这一方式的启发。我们的方法通过求解最优传输问题,妥善处理部分分配和被遮挡的点。实验表明,SuperGlue 相对于现有方法有显著改进,能够在极端宽基线的室内外图像对上做出高精度的相对位姿估计。此外,SuperGlue 可以实时运行,并且与经典特征和学习特征都能很好配合。
In summary, our learnable middle-end replaces hand-crafted heuristics with a powerful neural model that simultaneously performs context aggregation, matching, and filtering in a single unified architecture. We believe that, when combined with a deep front-end, SuperGlue is a major milestone towards end-to-end deep SLAM.
总之,我们可学习的中间端用一个有力的神经模型取代了手工启发式,在单一的统一结构中同时完成上下文聚合、匹配和过滤。我们认为,当与深度前端结合时,SuperGlue 是走向端到端深度 SLAM 的一个重要里程碑。
References
参考文献
[1] Phototourism Challenge, CVPR 2019 Image Matching Workshop. https://image-matching-workshop.github.io. Accessed November 8, 2019. 7
[2] Relja Arandjelović and Andrew Zisserman. Three things everyone should know to improve object retrieval. In CVPR, 2012. 6
[3] Peter W Battaglia, Jessica B Hamrick, Victor Bapst, Alvaro Sanchez-Gonzalez, Vinicius Zambaldi, Mateusz Malinowski, Andrea Tacchetti, David Raposo, Adam Santoro, Ryan Faulkner, et al. Relational inductive biases, deep learning, and graph networks. arXiv:1806.01261, 2018. 2, 3
[4] Alexander C Berg, Tamara L Berg, and Jitendra Malik. Shape matching and object recognition using low distortion correspondences. In CVPR, 2005. 2
[5] JiaWang Bian, Wen-Yan Lin, Yasuyuki Matsushita, Sai-Kit Yeung, Tan-Dat Nguyen, and Ming-Ming Cheng. GMS: Grid-based motion statistics for fast, ultra-robust feature correspondence. In CVPR, 2017. 2, 6
[6] Eric Brachmann and Carsten Rother. Neural-Guided RANSAC: Learning where to sample model hypotheses. In ICCV, 2019. 2, 5, 6
[7] Cesar Cadena, Luca Carlone, Henry Carrillo, Yasir Latif, Davide Scaramuzza, José Neira, Ian Reid, and John J Leonard. Past, present, and future of simultaneous localization and mapping: Toward the robust-perception age. IEEE Transactions on robotics, 32(6):1309–1332, 2016. 1
[8] Tibério S Caetano, Julian J McAuley, Li Cheng, Quoc V Le, and Alex J Smola. Learning graph matching. IEEE TPAMI, 31(6):1048–1058, 2009. 2
[9] Jan Cech, Jiri Matas, and Michal Perdoch. Efficient sequential correspondence selection by cosegmentation. IEEE TPAMI, 32(9):1568–1581, 2010. 2
[10] Marvin M Chun. Contextual cueing of visual attention. Trends in cognitive sciences, 4(5):170–178, 2000. 3
[11] Marco Cuturi. Sinkhorn distances: Lightspeed computation of optimal transport. In NIPS, 2013. 2, 5
[12] Angela Dai, Angel X Chang, Manolis Savva, Maciej Halber, Thomas Funkhouser, and Matthias Nießner. ScanNet: Richly-annotated 3D reconstructions of indoor scenes. In CVPR, 2017. 6
[13] Haowen Deng, Tolga Birdal, and Slobodan Ilic. PPFNet: Global context aware local features for robust 3D point matching. In CVPR, 2018. 2
[14] Daniel DeTone, Tomasz Malisiewicz, and Andrew Rabinovich. Deep image homography estimation. In RSS Workshop: Limits and Potentials of Deep Learning in Robotics, 2016. 5
[15] Daniel DeTone, Tomasz Malisiewicz, and Andrew Rabinovich. Self-improving visual odometry. arXiv:1812.03245, 2018. 6
[16] Daniel DeTone, Tomasz Malisiewicz, and Andrew Rabinovich. SuperPoint: Self-supervised interest point detection and description. In CVPR Workshop on Deep Learning for Visual SLAM, 2018. 2, 4, 5, 6
[17] Mihai Dusmanu, Ignacio Rocco, Tomas Pajdla, Marc Pollefeys, Josef Sivic, Akihiko Torii, and Torsten Sattler. D2-Net: A trainable CNN for joint detection and description of local features. In CVPR, 2019. 2, 6, 7
[18] Patrick Ebel, Anastasiia Mishchuk, Kwang Moo Yi, Pascal Fua, and Eduard Trulls. Beyond cartesian representations for local descriptors. In ICCV, 2019. 2
[19] Martin A Fischler and Robert C Bolles. Random sample consensus: a paradigm for model fitting with applications to image analysis and automated cartography. Communications of the ACM, 24(6):381–395, 1981. 2
[20] Jonas Gehring, Michael Auli, David Grangier, Denis Yarats, and Yann N Dauphin. Convolutional sequence to sequence learning. In ICML, 2017. 3
[21] Justin Gilmer, Samuel S Schoenholz, Patrick F Riley, Oriol Vinyals, and George E Dahl. Neural message passing for quantum chemistry. In ICML, 2017. 2, 3
[22] Richard Hartley and Andrew Zisserman. Multiple view geometry in computer vision. Cambridge university press, 2003. 6
[23] Juho Lee, Yoonho Lee, Jungtaek Kim, Adam Kosiorek, Seungjin Choi, and Yee Whye Teh. Set Transformer: A framework for attention-based permutation-invariant neural networks. In ICML, 2019. 2
[24] Marius Leordeanu and Martial Hebert. A spectral technique for correspondence problems using pairwise constraints. In ICCV, 2005. 2
[25] Yujia Li, Chenjie Gu, Thomas Dullien, Oriol Vinyals, and Pushmeet Kohli. Graph matching networks for learning the similarity of graph structured objects. In ICML, 2019. 2
[26] Zhengqi Li and Noah Snavely. MegaDepth: Learning single-view depth prediction from internet photos. In CVPR, 2018. 7
[27] Eliane Maria Loiola, Nair Maria Maia de Abreu, Paulo Oswaldo Boaventura-Netto, Peter Hahn, and Tania Querido. A survey for the quadratic assignment problem. European journal of operational research, 176(2):657–690, 2007. 2
[28] David G Lowe. Distinctive image features from scale-invariant keypoints. International Journal of Computer Vision, 60(2):91–110, 2004. 2, 6
[29] Zixin Luo, Tianwei Shen, Lei Zhou, Jiahui Zhang, Yao Yao, Shiwei Li, Tian Fang, and Long Quan. ContextDesc: Local descriptor augmentation with cross-modality context. In CVPR, 2019. 2, 3, 5, 6
[30] Kwang Moo Yi, Eduard Trulls, Yuki Ono, Vincent Lepetit, Mathieu Salzmann, and Pascal Fua. Learning to find good correspondences. In CVPR, 2018. 2, 5, 6
[31] Peter J Mucha, Thomas Richardson, Kevin Macon, Mason A Porter, and Jukka-Pekka Onnela. Community structure in time-dependent, multiscale, and multiplex networks. Science, 328(5980):876–878, 2010. 3
[32] James Munkres. Algorithms for the assignment and transportation problems. Journal of the society for industrial and applied mathematics, 5(1):32–38, 1957. 5
[33] Vincenzo Nicosia, Ginestra Bianconi, Vito Latora, and Marc Barthelemy. Growing multiplex networks. Physical review letters, 111(5):058701, 2013. 3
[34] Yuki Ono, Eduard Trulls, Pascal Fua, and Kwang Moo Yi. LF-Net: Learning local features from images. In NeurIPS, 2018. 2, 6, 7
[35] Adam Paszke, Sam Gross, Soumith Chintala, Gregory Chanan, Edward Yang, Zachary DeVito, Zeming Lin, Alban Desmaison, Luca Antiga, and Adam Lerer. Automatic differentiation in PyTorch. In NIPS Workshops, 2017. 5
[36] Gabriel Peyré and Marco Cuturi. Computational optimal transport. Foundations and Trends ® in Machine Learning, 11(5-6):355–607, 2019. 2, 4
[37] Charles R Qi, Hao Su, Kaichun Mo, and Leonidas J Guibas. PointNet: Deep learning on point sets for 3D classification and segmentation. In CVPR, 2017. 2
[38] Charles Ruizhongtai Qi, Li Yi, Hao Su, and Leonidas J Guibas. Pointnet++: Deep hierarchical feature learning on point sets in a metric space. In NIPS, 2017. 2
[39] Filip Radenović, Ahmet Iscen, Giorgos Tolias, Yannis Avrithis, and Ondřej Chum. Revisiting Oxford and Paris: Large-scale image retrieval benchmarking. In CVPR, 2018. 5
[40] Rahul Raguram, Jan-Michael Frahm, and Marc Pollefeys. A comparative analysis of RANSAC techniques leading to adaptive real-time random sample consensus. In ECCV, 2008. 2
[41] René Ranftl and Vladlen Koltun. Deep fundamental matrix estimation. In ECCV, 2018. 2, 5
[42] Jerome Revaud, Philippe Weinzaepfel, César De Souza, Noe Pion, Gabriela Csurka, Yohann Cabon, and Martin Humenberger. R2D2: Repeatable and reliable detector and descriptor. In NeurIPS, 2019. 2, 5
[43] Ignacio Rocco, Mircea Cimpoi, Relja Arandjelović, Akihiko Torii, Tomas Pajdla, and Josef Sivic. Neighbourhood consensus networks. In NeurIPS, 2018. 2, 5
[44] Ethan Rublee, Vincent Rabaud, Kurt Konolige, and Gary R Bradski. ORB: An efficient alternative to SIFT or SURF. In ICCV, 2011. 6
[45] Torsten Sattler, Bastian Leibe, and Leif Kobbelt. SCRAMSAC: Improving RANSAC’s efficiency with a spatial consistency filter. In ICCV, 2009. 2
[46] Johannes Lutz Schönberger and Jan-Michael Frahm. Structure-from-motion revisited. In CVPR, 2016. 7
[47] Johannes Lutz Schönberger, Enliang Zheng, Marc Pollefeys, and Jan-Michael Frahm. Pixelwise view selection for unstructured multi-view stereo. In ECCV, 2016. 7
[48] Eli Shechtman and Michal Irani. Matching local self-similarities across images and videos. In CVPR, 2007. 3
[49] Richard Sinkhorn and Paul Knopp. Concerning nonnegative matrices and doubly stochastic matrices. Pacific Journal of Mathematics, 1967. 2, 5
[50] Bart Thomee, David A Shamma, Gerald Friedland, Benjamin Elizalde, Karl Ni, Douglas Poland, Damian Borth, and Li-Jia Li. YFCC100M: The new data in multimedia research. Communications of the ACM, 59(2):64–73, 2016. 7
[51] Lorenzo Torresani, Vladimir Kolmogorov, and Carsten Rother. Feature correspondence via graph matching: Models and global optimization. In ECCV, 2008. 2
[52] Tomasz Trzcinski, Jacek Komorowski, Lukasz Dabala, Konrad Czarnota, Grzegorz Kurzejamski, and Simon Lynen. SConE: Siamese constellation embedding descriptor for image matching. In ECCV Workshops, 2018. 3
[53] Tinne Tuytelaars and Luc J Van Gool. Wide baseline stereo matching based on local, affinely invariant regions. In BMVC, 2000. 2
[54] Dmitry Ulyanov, Andrea Vedaldi, and Victor Lempitsky. Instance normalization: The missing ingredient for fast stylization. arXiv:1607.08022, 2016. 2, 5
[55] Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Łukasz Kaiser, and Illia Polosukhin. Attention is all you need. In NIPS, 2017. 1, 2, 3, 4, 5
[56] Petar Veličković, Guillem Cucurull, Arantxa Casanova, Adriana Romero, Pietro Liò, and Yoshua Bengio. Graph attention networks. In ICLR, 2018. 2
[57] Cédric Villani. Optimal transport: old and new, volume 338. Springer Science & Business Media, 2008. 2
[58] Xiaolong Wang, Ross Girshick, Abhinav Gupta, and Kaiming He. Non-local neural networks. In CVPR, 2018. 2
[59] Yue Wang and Justin M Solomon. Deep Closest Point: Learning representations for point cloud registration. In ICCV, 2019. 2
[60] Yue Wang, Yongbin Sun, Ziwei Liu, Sanjay E. Sarma, Michael M. Bronstein, and Justin M. Solomon. Dynamic Graph CNN for learning on point clouds. ACM Transactions on Graphics, 2019. 2
[61] Kwang Moo Yi, Eduard Trulls, Vincent Lepetit, and Pascal Fua. LIFT: Learned invariant feature transform. In ECCV, 2016. 2, 6
[62] Manzil Zaheer, Satwik Kottur, Siamak Ravanbakhsh, Barnabas Poczos, Ruslan R Salakhutdinov, and Alexander J Smola. Deep sets. In NIPS, 2017. 2
[63] Jiahui Zhang, Dawei Sun, Zixin Luo, Anbang Yao, Lei Zhou, Tianwei Shen, Yurong Chen, Long Quan, and Hongen Liao. Learning two-view correspondences and geometry using order-aware network. In ICCV, 2019. 2, 5, 6
[64] Li Zhang, Xiangtai Li, Anurag Arnab, Kuiyuan Yang, Yunhai Tong, and Philip HS Torr. Dual graph convolutional network for semantic segmentation. In BMVC, 2019. 2
[65] Yimeng Zhang, Zhaoyin Jia, and Tsuhan Chen. Image retrieval with geometry-preserving visual phrases. In CVPR, 2011. 3