A Style-Based Generator Architecture for Generative Adversarial Networks
A Style-Based Generator Architecture for Generative Adversarial Networks
一种基于风格的生成对抗网络生成器架构(A Style-Based Generator Architecture for Generative Adversarial Networks)
Tero Karras Affiliation: NVIDIA Email: tkarras@nvidia.com Samuli Laine Affiliation: NVIDIA Email: slaine@nvidia.com Timo Aila Affiliation: NVIDIA Email: taila@nvidia.com
Tero Karras Samuli Laine Timo Aila
所属机构:NVIDIA
{tkarras, slaine, taila}@nvidia.com
Abstract
摘要
We propose an alternative generator architecture for generative adversarial networks, borrowing from style transfer literature. The new architecture leads to an automatically learned, unsupervised separation of high-level attributes (e.g., pose and identity when trained on human faces) and stochastic variation in the generated images (e.g., freckles, hair), and it enables intuitive, scale-specific control of the synthesis. The new generator improves the state-of-the-art in terms of traditional distribution quality metrics, leads to demonstrably better interpolation properties, and also better disentangles the latent factors of variation. To quantify interpolation quality and disentanglement, we propose two new, automated methods that are applicable to any generator architecture. Finally, we introduce a new, highly varied and high-quality dataset of human faces.
我们为生成对抗网络提出一种替代生成器架构,借鉴风格迁移文献。新架构能自动、无监督地分离高层属性(例如在人脸数据上训练时的姿态与身份)与生成图像中的随机变化(例如雀斑、头发),并支持对合成过程做直观、按尺度的控制。新生成器在传统分布质量指标上改进了当时最优结果,插值性质明显更好,也更好解耦潜在变化因素。为量化插值质量与解耦程度,我们提出两种适用于任意生成器架构的自动化方法。最后,我们发布一个高度多样、高质量的人脸新数据集。
1 Introduction
1 引言
The resolution and quality of images produced by generative methods — especially generative adversarial networks (GAN) [22] — have seen rapid improvement recently [30, 45, 5]. Yet the generators continue to operate as black boxes, and despite recent efforts [3], the understanding of various aspects of the image synthesis process, e.g., the origin of stochastic features, is still lacking. The properties of the latent space are also poorly understood, and the commonly demonstrated latent space interpolations [13, 52, 37] provide no quantitative way to compare different generators against each other.
通过基因方法生成的图像——特别是基因对抗网络(GAN)[22]——的分辨率和质量最近迅速改善[30、45、5]。 然而,发电机继续作为黑匣子运行,尽管最近做出了[3],对图像合成过程各个方面的理解,例如结构特征的起源,仍然缺乏. 潜在空间的特性也没有得到很好的了解,通常显示的潜在空间插值[13、52、37]没有提供将不同的生成器相互比较日在数量上的方法。
Motivated by style transfer literature [27], we re-design the generator architecture in a way that exposes novel ways to control the image synthesis process. Our generator starts from a learned constant input and adjusts the “style” of the image at each convolution layer based on the latent code, therefore directly controlling the strength of image features at different scales. Combined with noise injected directly into the network, this architectural change leads to automatic, unsupervised separation of high-level attributes (e.g., pose, identity) from stochastic variation (e.g., freckles, hair) in the generated images, and enables intuitive scale-specific mixing and interpolation operations. We do not modify the discriminator or the loss function in any way, and our work is thus orthogonal to the ongoing discussion about GAN loss functions, regularization, and hyper-parameters [24, 45, 5, 40, 44, 36].
基于风格转移文献[27]的动机,我们以暴露控制图像合成过程的新方式来重新设计生成器架构. 我们的生成器从学习到的不断输入开始,根据潜伏的代码调整每个卷积层的图像“风格”,从而直接控制不同尺度的图像特性的强度。 这种建筑变化与直接注入网络的噪声相结合,导致在生成的图像中,将高阶属性(如姿势,身份)自动地,不受监督地从结构变异(如雀斑,毛发)中分离出来,并使得直观的尺度特异性混合和内插操作成为可能. 我们不以任何方式修改歧视者或损失函数,因此,我们的工作正视正在进行的关于GAN损失函数、正规化和超参数的讨论[24、45、5、40、44、36]。
Our generator embeds the input latent code into an intermediate latent space, which has a profound effect on how the factors of variation are represented in the network. The input latent space must follow the probability density of the training data, and we argue that this leads to some degree of unavoidable entanglement. Our intermediate latent space is free from that restriction and is therefore allowed to be disentangled. As previous methods for estimating the degree of latent space disentanglement are not directly applicable in our case, we propose two new automated metrics — perceptual path length and linear separability — for quantifying these aspects of the generator. Using these metrics, we show that compared to a traditional generator architecture, our generator admits a more linear, less entangled representation of different factors of variation.
我们的生成器将输入潜伏代码嵌入中间潜伏空间,这对网络中如何反映变化因素有着深远的影响。 输入的潜在空间必须跟随培训数据的概率密度,我们争辩说,这会导致一定程度的不可避免的纠缠。 我们中间的潜在空间不受这种限制,因此可以分散。 由于过去估计潜在空间分散程度的方法并不直接适用于我们的情况,我们提议采用两个新的自动衡量标准,即概念路径长度和线性分离性,以量化发电机的这些方面。 与传统的发电机结构相比, 我们的发电机会接受一种 比较直线性,不太纠缠的 不同变异因素的表示。
Finally, we present a new dataset of human faces (Flickr-Faces-HQ, FFHQ) that offers much higher quality and covers considerably wider variation than existing high-resolution datasets (Appendix A). We have made this dataset publicly available, along with our source code and pre-trained networks.[^1] The accompanying video can be found under the same link.
最后,我们提出了一个新的人脸数据集(Flickr-Faces-HQ,FFHQ),它提供的质量要高得多,涵盖的变异比现有的高分辨率数据集(Appendix A)要大得多. 我们已经公开了这一数据集,以及我们的源代码和经过预先培训的网络。 随附的视频可在同一链接下找到.
2 Style-based generator
2 基于风格的生成器
(a) Traditional (b) Style-based generator
Figure 1: While a traditional generator [30] feeds the latent code though the input layer only, we first map the input to an intermediate latent space , which then controls the generator through adaptive instance normalization (AdaIN) at each convolution layer. Gaussian noise is added after each convolution, before evaluating the nonlinearity. Here “A” stands for a learned affine transform, and “B” applies learned per-channel scaling factors to the noise input. The mapping network consists of 8 layers and the synthesis network consists of 18 layers — two for each resolution (). The output of the last layer is converted to RGB using a separate convolution, similar to Karras et al. [30]. Our generator has a total of 26.2M trainable parameters, compared to 23.1M in the traditional generator.
(a) 传统(b) 风格生成器
图1:虽然传统的生成器[30] 仅通过输入层来输入潜在代码,但我们首先将输入图映射到中间潜在空间,然后通过每个卷积层的适应性实例正常化(AdaIN)来控制生成器。 高斯噪声在每次演化后加入,然后评价非线性. 这里的“A”表示一个有学问的亲缘变换,“B”将每个渠道的有学识的缩放系数应用于噪音输入。 测绘网由8层组成,合成网由18层组成——每个分辨率为2层(). 最后一层的输出使用单独的旋式转换成RGB,类似于Karras等人[30]. 我们的发电机共有26.2M的可列车参数,而传统发电机的可列车参数为23.1M.
Traditionally the latent code is provided to the generator through an input layer, i.e., the first layer of a feedforward network (Figure 1a). We depart from this design by omitting the input layer altogether and starting from a learned constant instead (Figure 1b, right). Given a latent code in the input latent space , a non-linear mapping network first produces (Figure 1b, left). For simplicity, we set the dimensionality of both spaces to 512, and the mapping is implemented using an 8-layer MLP, a decision we will analyze in Section 4.1. Learned affine transformations then specialize to styles that control adaptive instance normalization (AdaIN) [27, 17, 21, 16] operations after each convolution layer of the synthesis network . The AdaIN operation is defined as
传统上,潜伏代码是通过输入层,即向导网络的第一层(图1a),向生成器提供. 我们偏离了这种设计,完全省略了输入层,从一个学到的常数开始取而代之(图1b,右)。 鉴于输入潜入空间中有一个潜在的代码,一个非线性绘图网络首先产生(图1b,左侧). 简而言之,我们把两个空间的维度设定为512,使用8层的MLP进行绘图,我们将在第4.1节中分析这一决定。 然后,在合成网络的每个卷积层之后,专门将控制适应性实例正常化(AdaIN)的改为*型()[27、17、21、16]操作。 AdaIN业务的定义是:
where each feature map is normalized separately, and then scaled and biased using the corresponding scalar components from style . Thus the dimensionality of is twice the number of feature maps on that layer.
,然后使用样式中相应的scalar 组件进行缩放和偏差。 因此,的维度是该层地物图的两倍。
Comparing our approach to style transfer, we compute the spatially invariant style from vector instead of an example image. We choose to reuse the word “style” for because similar network architectures are already used for feedforward style transfer [27], unsupervised image-to-image translation [28], and domain mixtures [23]. Compared to more general feature transforms [38, 57], AdaIN is particularly well suited for our purposes due to its efficiency and compact representation.
比较我们对于风格转移的方法,我们从矢量计算出空间变化的风格,而不是示例图像. 我们选择重用的“样式”一词,因为类似的网络架构已经用于向导样式传输[27]、未经监督的图像到图像翻译[28]和域名混合物[23]。 与更一般的特性转变[38,57]相比,AdaIN由于其效率和紧凑的代表性,特别适合我们的目的.
Finally, we provide our generator with a direct means to generate stochastic detail by introducing explicit noise inputs. These are single-channel images consisting of uncorrelated Gaussian noise, and we feed a dedicated noise image to each layer of the synthesis network. The noise image is broadcasted to all feature maps using learned per-feature scaling factors and then added to the output of the corresponding convolution, as illustrated in Figure 1b. The implications of adding the noise inputs are discussed in Sections 3.2 and 3.3.
最后,我们向发电机提供一种直接手段,通过引入明确的“噪音投入”来产生细腻的细节。 这些是由不相关联的高斯噪音构成的单通道图像,我们为合成网络的每层提供专用的噪音图像. 如图1b所示,噪声图像利用每个地貌的学习度量因子广播到所有地物图,然后添加到相应的演化输出中. 第3.2和3.3节讨论了增加噪音投入的影响。
| Method | CelebA-HQ | FFHQ | |
|---|---|---|---|
| a | Baseline Progressive GAN [30] | 7.79 | 8.04 |
| b | + Tuning (incl. bilinear up/down) | 6.11 | 5.25 |
| c | + Add mapping and styles | 5.34 | 4.85 |
| d | + Remove traditional input | 5.07 | 4.88 |
| e | + Add noise inputs | 5.06 | 4.42 |
| f | + Mixing regularization | 5.17 | 4.40 |
Table 1: Fréchet inception distance (FID) for various generator designs (lower is better). In this paper we calculate the FIDs using 50,000 images drawn randomly from the training set, and report the lowest distance encountered over the course of training.
| 鳕 农药 | ** 喜剧团。 | 页:1 | |
|---|---|---|---|
| a | 基线渐进GAN [30] | 7.79 | 8.04 |
| b | + Tu(包括双线上下) | 6.11 | 5.25 |
| c | + 添加映射和样式 | 5.34 | 4.85 |
| D. 国家 | + 删除传统输入 | 5.07 | 4.88 |
| 页:1 | + 添加噪音输入 | ** 5.06 ** | 4.42 |
| f 时值 | + 混合正规化 | 5.17 | 页:1 |
表1:各种发电机设计的Fréchet启动距离(FID)(更低). 在本文中,我们使用从培训单元中随机抽取的5万张图像来计算FID,并报告在培训过程中遇到的最低距离。
2.1 Quality of generated images
2.1 生成图像质量
Before studying the properties of our generator, we demonstrate experimentally that the redesign does not compromise image quality but, in fact, improves it considerably. Table 1 gives Fréchet inception distances (FID) [25] for various generator architectures in CelebA-HQ [30] and our new FFHQ dataset (Appendix A). Results for other datasets are given in Appendix E. Our baseline configuration (a) is the Progressive GAN setup of Karras et al. [30], from which we inherit the networks and all hyperparameters except where stated otherwise. We first switch to an improved baseline (b) by using bilinear up/downsampling operations [64], longer training, and tuned hyperparameters. A detailed description of training setups and hyperparameters is included in Appendix C. We then improve this new baseline further by adding the mapping network and AdaIN operations (c), and make a surprising observation that the network no longer benefits from feeding the latent code into the first convolution layer. We therefore simplify the architecture by removing the traditional input layer and starting the image synthesis from a learned constant tensor (d). We find it quite remarkable that the synthesis network is able to produce meaningful results even though it receives input only through the styles that control the AdaIN operations.
在研究发电机的特性之前,我们实验地证明重新设计不会损害图像质量,但事实上大大改进了图像质量。 表1给出了CelebA-HQ的各种生成器架构的Fréchet启动距离(FID)[25][30]和我们新的FFHQ数据集(附录A). 其他数据集的结果载于附录E。 我们的基准配置(a)是Karras等人的渐进式GAN设置[30],我们继承了这些网络和所有超参数,除非另有说明。 我们首先采用双线式上下取样作业[64]、较长的训练和调制的超参数,从而改进基线(b)。 附录C详细介绍了训练设置和超参数。 然后,我们通过增加绘图网络和AdaIN业务(c)来进一步改进这一新的基准,并令人惊讶地指出,将潜在代码输入第一个演进层已不再有好处。 因此,我们通过去除传统的输入层和从一个学习的常数(d)开始图像合成来简化架构. 我们发现相当了不起的是,这个合成网络能够产生有意义的结果,尽管它只能通过控制AdaIN操作的风格获得投入.
Finally, we introduce the noise inputs (e) that improve the results further, as well as novel mixing regularization (f) that decorrelates neighboring styles and enables more fine-grained control over the generated imagery (Section 3.1).
最后,我们介绍了能进一步改善结果的噪音投入(e),以及新颖的混合规范化(f),该规范装饰了邻居的风格,能够对生成的图像进行更精细的控制(第3.1节)。
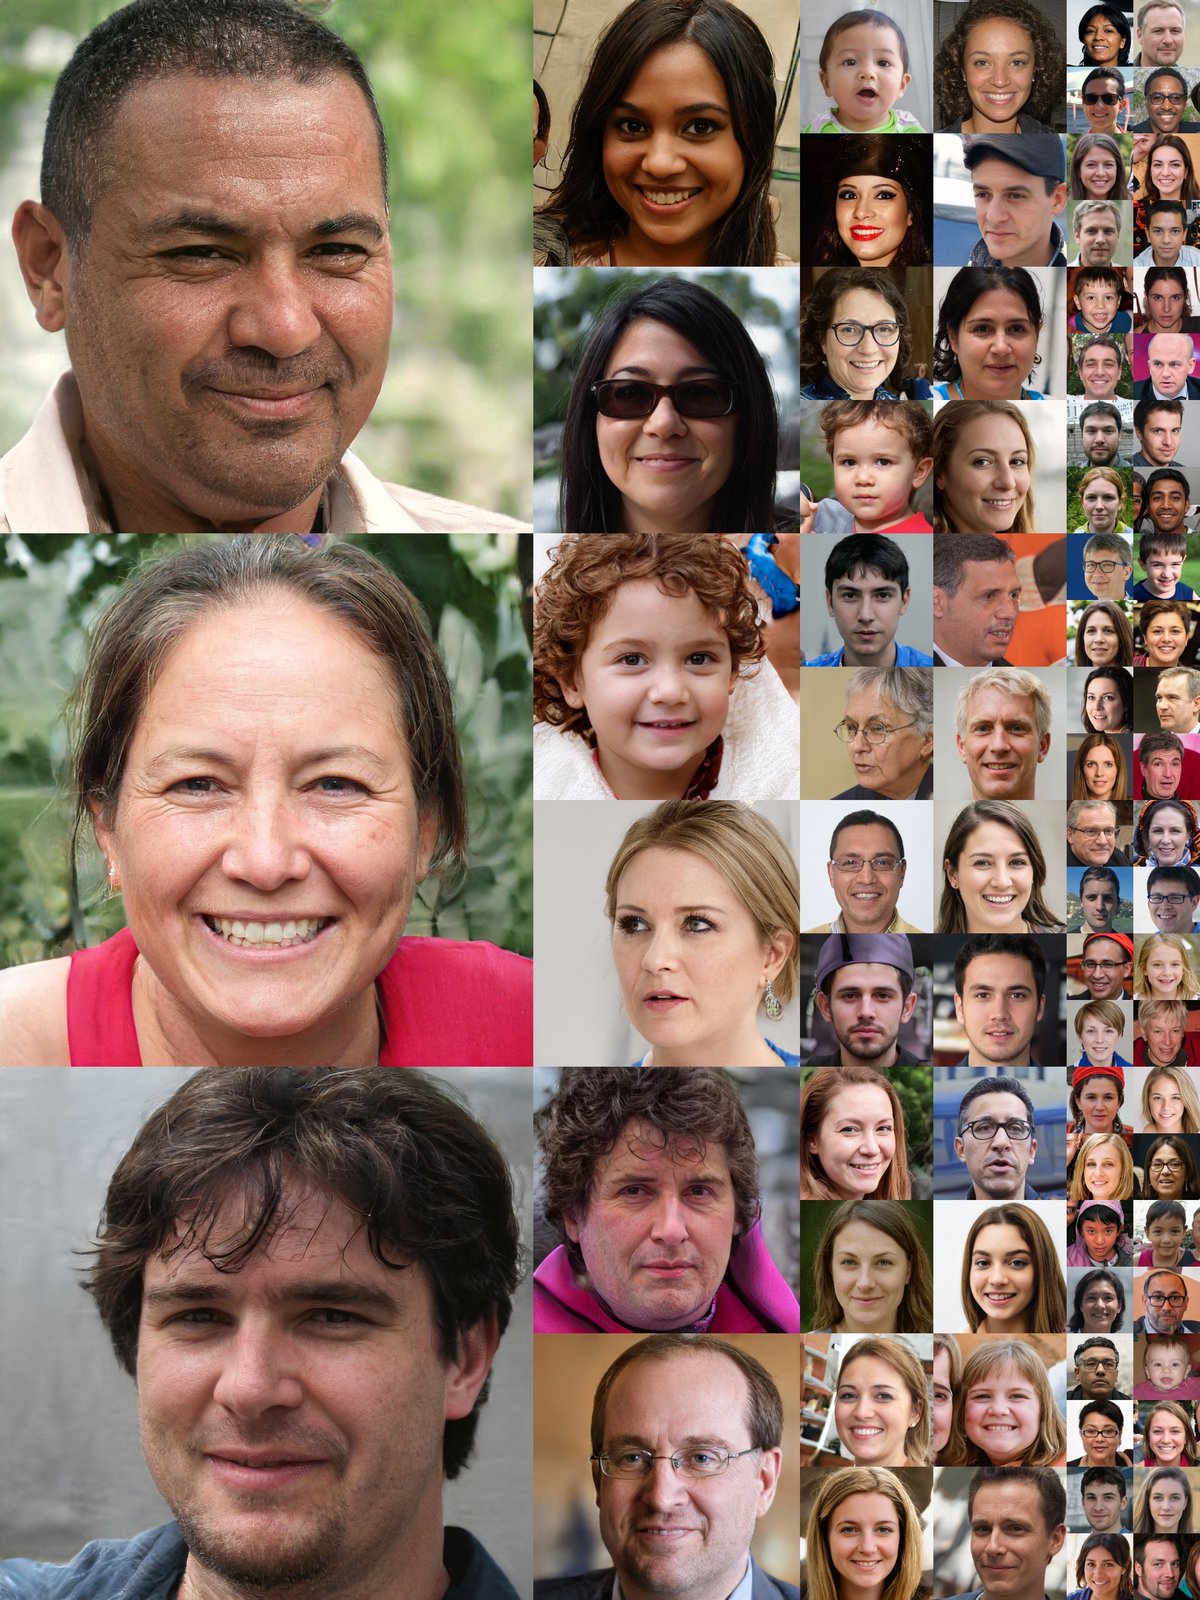
Figure 2: Uncurated set of images produced by our style-based generator (config f) with the FFHQ dataset. Here we used a variation of the truncation trick [42, 5, 34] with for resolutions . Please see the accompanying video for more results.
图2:我们基于样式的生成器(配置f)与FFHQ数据集产生的一组未校准的图像. 在这里,我们用号决议的来变换调值法 [42, 5, 34]. 请参看所附的视频,了解更多结果。
We evaluate our methods using two different loss functions: for CelebA-HQ we rely on WGAN-GP [24], while FFHQ uses WGAN-GP for configuration a and non-saturating loss [22] with regularization [44, 51, 14] for configurations b–f. We found these choices to give the best results. Our contributions do not modify the loss function.
我们使用两种不同的损失功能来评估我们的方法:对CelebA-HQ来说,我们依赖WGAN-GP[24],而FFHQ则使用WGAN-GP来配置a和不饱和损失[22],配置b-f的规范化[44,51,14]. 我们发现这些选择能带来最佳结果。 我们的捐款不会改变损失的功能。
We observe that the style-based generator (e) improves FIDs quite significantly over the traditional generator (b), almost 20%, corroborating the large-scale ImageNet measurements made in parallel work [6, 5]. Figure 2 shows an uncurated set of novel images generated from the FFHQ dataset using our generator. As confirmed by the FIDs, the average quality is high, and even accessories such as eyeglasses and hats get successfully synthesized. For this figure, we avoided sampling from the extreme regions of using the so-called truncation trick [42, 5, 34] — Appendix B details how the trick can be performed in instead of . Note that our generator allows applying the truncation selectively to low resolutions only, so that high-resolution details are not affected.
我们注意到,基于样式的生成器(e)比传统的生成器(b)有很大的改进,几乎达到20%,证实了在平行工作[6、5]中所作的大规模图像网络测量。 图2显示使用我们的生成器从FFHQ数据集生成的一组未经校验的新图像. 正如FID所证实的那样,平均质量很高,甚至眼镜和帽子等配件都能成功合成. 对于这个数字,我们利用所谓的截断法[42、5、34]——附录B详细介绍了如何在而不是中实施这一技巧,避免了从的极端地区取样。 请注意,我们的生成器允许有选择地对低分辨率进行截断,这样高分辨率的细节就不会受到影响。
All FIDs in this paper are computed without the truncation trick, and we only use it for illustrative purposes in Figure 2 and the video. All images are generated in resolution.
本文中的所有FID都是在不使用调试法的情况下计算出来的,我们只用于图2和视频中的说明目的. 所有图像都在分辨率中生成.
2.2 Prior art
2.2 先前工作
Much of the work on GAN architectures has focused on improving the discriminator by, e.g., using multiple discriminators [18, 47, 11], multiresolution discrimination [60, 55], or self-attention [63]. The work on generator side has mostly focused on the exact distribution in the input latent space [5] or shaping the input latent space via Gaussian mixture models [4], clustering [48], or encouraging convexity [52].
有关GAN架构的许多工作都侧重于改善歧视者,例如利用多重歧视者[18、47、11]、多解歧视[60、55]或自我关注[63]。 发电机边的工作主要集中于输入潜在空间中的确切分布[5]或通过高斯混合模型[4],集群[48],或鼓励对流[52]塑造输入潜在空间.
Recent conditional generators feed the class identifier through a separate embedding network to a large number of layers in the generator [46], while the latent is still provided though the input layer. A few authors have considered feeding parts of the latent code to multiple generator layers [9, 5]. In parallel work, Chen et al. [6] “self modulate” the generator using AdaINs, similarly to our work, but do not consider an intermediate latent space or noise inputs.
最近的有条件的发电机通过单独的嵌入网络将类标识输入到生成器中的大量层中[46],而潜在的通过输入层仍然提供. 一些作者曾考虑将潜伏代码的部件喂入多个生成层[9,5]. 在平行工作中将能使用AdaINs的生成器“自行调制”,类似于我们的工作,但不考虑中间潜在空间或噪音输入。
Source A Source B
Source B
Coarse styles from source B
Coarse styles from source B
Middle styles from source B
Middle styles from source B
Fine from B
Fine from B
Figure 3: Two sets of images were generated from their respective latent codes (sources A and B); the rest of the images were generated by copying a specified subset of styles from source B and taking the rest from source A. Copying the styles corresponding to coarse spatial resolutions ( – ) brings high-level aspects such as pose, general hair style, face shape, and eyeglasses from source B, while all colors (eyes, hair, lighting) and finer facial features resemble A. If we instead copy the styles of middle resolutions ( – ) from B, we inherit smaller scale facial features, hair style, eyes open/closed from B, while the pose, general face shape, and eyeglasses from A are preserved. Finally, copying the fine styles ( – ) from B brings mainly the color scheme and microstructure.
** 来源A** 来源B**
** 资料来源B**
来源 B 的粗体样式
来源 B 的粗体样式
来自源 B 的中间样式
来自源 B 的中间样式
B的罚款
B的罚款
图3:两组图像由各自的潜伏代码生成(来源A和B);其余的图像则通过复制来源B的指定子集样式和从来源A获取其余的样式生成. 复制与粗细空间分辨率对应的样式(–)带来高层次的方面,如姿势,一般发型,面部形状,以及来自来源B的眼镜,而所有颜色(眼,发,照明)和细细的面部特征类似A. 如果我们从B复制中间分辨率的样式( –),我们就继承了较小的面部特征,发型,睁开/闭开B的眼睛,而姿势,一般面部形状,以及A的眼镜则保留下来. 最后,从B复制精细的样式( – )主要带来色彩图案和微结构.
3 Properties of the style-based generator
3 基于风格的生成器的性质
Our generator architecture makes it possible to control the image synthesis via scale-specific modifications to the styles. We can view the mapping network and affine transformations as a way to draw samples for each style from a learned distribution, and the synthesis network as a way to generate a novel image based on a collection of styles. The effects of each style are localized in the network, i.e., modifying a specific subset of the styles can be expected to affect only certain aspects of the image.
我们的生成器架构使得通过对样式的特定尺度修改来控制图像合成成为可能. 我们可以将绘图网络和affine变换视为从一个学得的分布中为每种样式绘制样本的方法,而合成网络则视为根据一套样式集生成新形象的方法. 每个样式的效果都是在网络中局部化的,即修改样式的特定子集可以预期只影响图像的某些方面.
To see the reason for this localization, let us consider how the AdaIN operation (Eq. 1) first normalizes each channel to zero mean and unit variance, and only then applies scales and biases based on the style. The new per-channel statistics, as dictated by the style, modify the relative importance of features for the subsequent convolution operation, but they do not depend on the original statistics because of the normalization. Thus each style controls only one convolution before being overridden by the next AdaIN operation.
为了了解这种本地化的原因,让我们来考虑AdaIN 操作(Eq. 1)如何首先将每个信道的正常化,即零平均和单位差异,然后只应用基于样式的尺度和偏差. 由风格决定的新每道统计修改了特征对后来的演化操作的相对重要性,但由于正常化,它们并不依赖于原始统计. 因此,每种风格都只控制一种进化,然后被下一次AdaIN操作推翻。
3.1 Style mixing
3.1 风格混合
To further encourage the styles to localize, we employ mixing regularization, where a given percentage of images are generated using two random latent codes instead of one during training. When generating such an image, we simply switch from one latent code to another — an operation we refer to as style mixing — at a randomly selected point in the synthesis network. To be specific, we run two latent codes through the mapping network, and have the corresponding control the styles so that applies before the crossover point and after it. This regularization technique prevents the network from assuming that adjacent styles are correlated.
为了进一步鼓励风格本地化,我们采用了“混合规范化”的做法,即使用两个随机潜在代码而不是在培训期间使用一个代码生成一定比例的图像。 在生成这样的图像时,我们简单地在合成网络中随机选择的点上从一个潜伏的代码切换到另一个——我们称之为tyle mixing的操作. 具体来说,我们通过映射网络运行两个潜伏代码,并拥有相应的控制样式,使得在交叉点之前适用,在交叉点之后适用. 这种规范化技术使得网络无法假设相邻的样式是相互关联的.
Table 2 shows how enabling mixing regularization during training improves the localization considerably, indicated by improved FIDs in scenarios where multiple latents are mixed at test time. Figure 3 presents examples of images synthesized by mixing two latent codes at various scales. We can see that each subset of styles controls meaningful high-level attributes of the image.
表2显示,在测试时多种潜在因素混合的假想中,通过改进识别数据,培训期间的混合规范可如何大大改善本地化。 图3举例说明了通过混合各种尺度的两个潜在代码合成的图像。 我们可以看到,每个样式的子集都控制着图像的有意义的高级属性.
| Mixing | Number of latents during testing | ||||
|---|---|---|---|---|---|
| regularization | 1 | 2 | 3 | 4 | |
| e | 0% | 4.42 | 8.22 | 12.88 | 17.41 |
| 50% | 4.41 | 6.10 | 08.71 | 11.61 | |
| f | 90% | 4.40 | 5.11 | 06.88 | 09.03 |
| 100% | 4.83 | 5.17 | 0****6.63 | 0****8.40 |
Table 2: FIDs in FFHQ for networks trained by enabling the mixing regularization for different percentage of training examples. Here we stress test the trained networks by randomizing latents and the crossover points between them. Mixing regularization improves the tolerance to these adverse operations significantly. Labels e and f refer to the configurations in Table 1.
| ** 混合** | ** 测试中潜伏的数量** | ||||
|---|---|---|---|---|---|
| ** 正规化** | 页:1 | 页:1 | 页:1 | 页:1 | |
| 页:1 | 0% | 4.42 | 8.22 | 12.88 | 17.41 |
| 50% | 4.41 | 6.10 | 08.71 | 11.61 | |
| f 时值 | 90% | 页:1 | 页:1 | 06.88 | 09.03 |
| 100% | 4.83 | 5.17 | *∗6.63 ∗∗∗∗∗ | 页:1 |
表2:通过对不同比例的培训实例进行混合规范培训的网络,在FFHQ的FID。 在这里,我们通过随机排列潜伏物和它们之间的交叉点来测试训练有素的网络。 混合规范化大大提高了对这些不良操作的耐受性. 标签e和f指表1中的配置.
3.2 Stochastic variation
3.2 随机变化
(a) Generated image (b) Stochastic variation (c) Standard deviation
Figure 4: Examples of stochastic variation. (a) Two generated images. (b) Zoom-in with different realizations of input noise. While the overall appearance is almost identical, individual hairs are placed very differently. (c) Standard deviation of each pixel over 100 different realizations, highlighting which parts of the images are affected by the noise. The main areas are the hair, silhouettes, and parts of background, but there is also interesting stochastic variation in the eye reflections. Global aspects such as identity and pose are unaffected by stochastic variation.
(a) 生成图像 (b) 结构变化 (c) 标准偏差
图4:结构变化实例。 (a) 生成两个图像。 (b) 以不同的输入噪声实现放大。 虽然整体外观几乎完全相同,但个别的毛被的位置却非常不同. (c) 每个像素超过100个不同实现的标准偏差,突出图像的哪些部分受到噪音的影响。 主要领域是毛发,剪影,以及部分背景,但眼反射中也有有趣的结构变化. 特征和姿势等全球方面不受变化不定的影响。
There are many aspects in human portraits that can be regarded as stochastic, such as the exact placement of hairs, stubble, freckles, or skin pores. Any of these can be randomized without affecting our perception of the image as long as they follow the correct distribution.
人类肖像画中有许多方面可以被认为是有斑纹的,例如毛发,斑纹,雀斑或皮肤毛孔的确切放置. 只要它们跟随正确的分布,它们都可以随机化而不影响我们对图像的认知.
Let us consider how a traditional generator implements stochastic variation. Given that the only input to the network is through the input layer, the network needs to invent a way to generate spatially-varying pseudorandom numbers from earlier activations whenever they are needed. This consumes network capacity and hiding the periodicity of generated signal is difficult — and not always successful, as evidenced by commonly seen repetitive patterns in generated images. Our architecture sidesteps these issues altogether by adding per-pixel noise after each convolution.
让我们考虑一下传统生成器如何执行结构变化。 鉴于对网络的唯一投入是通过输入层,网络需要发明一种方法,从早期的激活中产生空间变化的假随机数,只要需要. 这消耗了网络容量,隐藏生成信号的周期性是困难的——并不总是成功的,在生成的图像中常见的重复模式就证明了这一点. 我们的建筑通过在每次演化后增加每个像素的噪音来完全回避这些问题.
Figure 4 shows stochastic realizations of the same underlying image, produced using our generator with different noise realizations. We can see that the noise affects only the stochastic aspects, leaving the overall composition and high-level aspects such as identity intact. Figure 5 further illustrates the effect of applying stochastic variation to different subsets of layers. Since these effects are best seen in animation, please consult the accompanying video for a demonstration of how changing the noise input of one layer leads to stochastic variation at a matching scale.
图4显示了使用我们发电机产生的、具有不同噪音的同一基本图像的有条理的实现。 我们可以看到,噪声只影响有条理的方面,使整体构成和诸如身份等高层方面保持不变. 图5进一步说明了对不同子集层应用分层变异的影响. 由于这些效果在动画中表现得最好,所以请参考所附的视频,以展示改变一层的噪音输入如何在匹配尺度上导致结构变化.
(a) (b)
(c) (d)
Figure 5: Effect of noise inputs at different layers of our generator. (a) Noise is applied to all layers. (b) No noise. (c) Noise in fine layers only ( – ). (d) Noise in coarse layers only ( – ). We can see that the artificial omission of noise leads to featureless “painterly” look. Coarse noise causes large-scale curling of hair and appearance of larger background features, while the fine noise brings out the finer curls of hair, finer background detail, and skin pores.
(a)(b)
(c) (d 说真的)
图5:噪音输入对我们生成器不同层的影响。 (a) 噪音适用于所有层。 (b本国境内)无噪声。 (c) 仅细层中的噪声( – )。 (d) 仅粗层中的噪声( – )。 我们可以看到,人为地忽略噪音导致无特色的“悲观”表情。 粗糙的噪声导致毛发大规模卷曲,外观具有更大的背景特征,而细细的噪声则带出细细的卷曲,细细的背景细节,以及皮肤毛孔.
We find it interesting that the effect of noise appears tightly localized in the network. We hypothesize that at any point in the generator, there is pressure to introduce new content as soon as possible, and the easiest way for our network to create stochastic variation is to rely on the noise provided. A fresh set of noise is available for every layer, and thus there is no incentive to generate the stochastic effects from earlier activations, leading to a localized effect.
我们觉得有趣的是,噪音的影响在网络中呈现出紧密的局部性。 我们假设,在生成器中的任何一点, 都有压力 尽快引入新的内容, 我们的网络 最容易 创造 变形的方法 是依赖提供的噪音。 每层都有一套新鲜的噪音,因此没有动力从早期的激活中产生扭曲效应,导致局部效应.
3.3 Separation of global effects from stochasticity
3.3 将全局效应与随机性分离
The previous sections as well as the accompanying video demonstrate that while changes to the style have global effects (changing pose, identity, etc.), the noise affects only inconsequential stochastic variation (differently combed hair, beard, etc.). This observation is in line with style transfer literature, where it has been established that spatially invariant statistics (Gram matrix, channel-wise mean, variance, etc.) reliably encode the style of an image [20, 39] while spatially varying features encode a specific instance.
前几节以及随附的视频显示,虽然风格的改变具有全局效应(改变姿势,身份等),但噪音只影响不切实际的变体(不同梳理的头发,胡子等). 这种观察符合风格传动文献,在文献中,已经确定空间变化性统计(Gram矩阵,频道偏平均值,差异等)可靠地编码了图像的风格[20,39],而空间变化的特征编码了特定实例.
In our style-based generator, the style affects the entire image because complete feature maps are scaled and biased with the same values. Therefore, global effects such as pose, lighting, or background style can be controlled coherently. Meanwhile, the noise is added independently to each pixel and is thus ideally suited for controlling stochastic variation. If the network tried to control, e.g., pose using the noise, that would lead to spatially inconsistent decisions that would then be penalized by the discriminator. Thus the network learns to use the global and local channels appropriately, without explicit guidance.
在我们基于风格的生成器中,该风格会影响整个图像,因为完整的特征地图是缩放的,带有相同的值的偏差. 因此,姿势、照明或背景样式等全球效应可以一致地加以控制。 同时,噪声会独立地添加到每个像素上,因此最适合控制色变. 如果网络试图控制,例如利用噪声进行姿势,将导致空间不一致的决定,然后受到歧视者的处罚。 因此,该网络学会在没有明确指导的情况下适当利用全球和地方渠道。
4 Disentanglement studies
4 解耦研究
(a) Distribution of (b) Mapping from (c) Mapping from features in training set to features to features
Figure 6: Illustrative example with two factors of variation (image features, e.g., masculinity and hair length). (a) An example training set where some combination (e.g., long haired males) is missing. (b) This forces the mapping from to image features to become curved so that the forbidden combination disappears in to prevent the sampling of invalid combinations. (c) The learned mapping from to is able to “undo” much of the warping.
(a) 将(b) 从(c) 从培训集到图象到图象的绘图
图6:具有两个变化因素(图像特征,如男性特征和头发长度)的典型例子。 (a) 一个缺少某种组合(如长毛雄性)的范例培训集. (b) 国家 这迫使从到图像特性的映射变为曲线化,使得被禁止的组合在中消失,以防止无效组合的取样. (c) 从第到第号所学的绘图能够“不做”大部分的绘图。
There are various definitions for disentanglement [54, 50, 2, 7, 19], but a common goal is a latent space that consists of linear subspaces, each of which controls one factor of variation. However, the sampling probability of each combination of factors in needs to match the corresponding density in the training data. As illustrated in Figure 6, this precludes the factors from being fully disentangled with typical datasets and input latent distributions.[^2]
分离有各种定义[54,50,2,7,19],但一个共同的目标是一个由线性亚空间组成的潜伏空间,每个亚空间控制一个变异因素. 然而,中各种因素组合的采样概率需要与培训数据中相应的密度相匹配. 如图6所示,这排除了这些因素与典型数据集和输入潜在分布完全脱钩。
A major benefit of our generator architecture is that the intermediate latent space does not have to support sampling according to any fixed distribution; its sampling density is induced by the learned piecewise continuous mapping . This mapping can be adapted to “unwarp” so that the factors of variation become more linear. We posit that there is pressure for the generator to do so, as it should be easier to generate realistic images based on a disentangled representation than based on an entangled representation. As such, we expect the training to yield a less entangled in an unsupervised setting, i.e., when the factors of variation are not known in advance [10, 35, 49, 8, 26, 32, 7].
我们发电机结构的一个主要好处是,中间潜在空间不必根据任何固定分布支持采样;其采样密度是由吸取片面连续绘制所诱导的。 这种绘图可适应“unwarp”,使变异因素更加线性。 我们认为,生成者有这样做的压力,因为生成基于分散的表达方式的现实图像要比基于缠绕的表述方式更为容易。 因此,我们期望在不受监督的情况下,即在事先不知道变化因素[10、35、49、8、26、32、7]的情况下,培训会产生不那么纠缠的。
Unfortunately the metrics recently proposed for quantifying disentanglement [26, 32, 7, 19] require an encoder network that maps input images to latent codes. These metrics are ill-suited for our purposes since our baseline GAN lacks such an encoder. While it is possible to add an extra network for this purpose [8, 12, 15], we want to avoid investing effort into a component that is not a part of the actual solution. To this end, we describe two new ways of quantifying disentanglement, neither of which requires an encoder or known factors of variation, and are therefore computable for any image dataset and generator.
遗憾的是,最近为量化脱节[26、32、7、19]而提出的衡量标准需要一个编码网络,将图像输入到潜在编码中。 这些衡量标准不适合我们的目的,因为我们的基线GAN缺乏这样的编码器. 虽然为此目的可以增加一个额外的网络[8、12、15],但我们希望避免将努力投入到一个不属于实际解决办法的部分。 为此,我们又一次描述了两种新的分解量化方法,它们都不需要编码器或已知的变异因素,因此对任何图像数据集和生成器都是可以计算出来的.
4.1 Perceptual path length
4.1 感知路径长度
As noted by Laine [37], interpolation of latent-space vectors may yield surprisingly non-linear changes in the image. For example, features that are absent in either endpoint may appear in the middle of a linear interpolation path. This is a sign that the latent space is entangled and the factors of variation are not properly separated. To quantify this effect, we can measure how drastic changes the image undergoes as we perform interpolation in the latent space. Intuitively, a less curved latent space should result in perceptually smoother transition than a highly curved latent space.
正如Laine[37]所指出的,潜在空间所面对的矢量的插值可能会使图像发生惊人的非线性变化。 例如,任一端点中缺失的特征可能出现在线性插值路径中间. 这表明潜在的空间被缠绕在一起,变异因素没有适当分离. 为了量化这种影响,我们可以测量在我们在潜在空间进行插值时,图像是如何急剧变化的。 从直觉上看,一个不太弯曲的潜伏空间应该比一个高度弯曲的潜伏空间更能感知地平滑地过渡。
As a basis for our metric, we use a perceptually-based pairwise image distance [65] that is calculated as a weighted difference between two VGG16 [58] embeddings, where the weights are fit so that the metric agrees with human perceptual similarity judgments. If we subdivide a latent space interpolation path into linear segments, we can define the total perceptual length of this segmented path as the sum of perceptual differences over each segment, as reported by the image distance metric. A natural definition for the perceptual path length would be the limit of this sum under infinitely fine subdivision, but in practice we approximate it using a small subdivision epsilon . The average perceptual path length in latent space , over all possible endpoints, is therefore
作为我们度量衡的基础,我们使用一个基于感知的双向图像距离[65],这个距离是作为两个VGG16[58]嵌入物之间的加权差计算的,其中的权重是合适的,因此度量法与人的感知相似性判断是一致的. 如果我们将一个潜在的空间插值路径细分为线性段,我们可以按照图像距离测量法报告的那样,将这个分块路径的总的感知长度定义为每个段的感知差异的总和. 知觉路径长度的自然定义是在无限细小的分区下这个总和的限度,但实际上我们使用一个小分区的epsilon 来估算. 因此,在所有可能的终点上,在潜在空间的平均感知路径长度是:
$$\begin{array}[]{r@{}l}\hskip-8.53581ptl_{\mathcal{Z}}=\EX\Big[{\displaystyle\frac{1}{\epsilon^{2}}}d\big(&G(\mathrm{slerp}({\bf z}{1},{\bf z}{2};,t)),\
&G(\mathrm{slerp}({\bf z}{1},{\bf z}{2};,t+\epsilon))\big)\Big]\textrm{,}\end{array} \tag{2}$$
where , is the generator (i.e., for style-based networks), and evaluates the perceptual distance between the resulting images. Here denotes spherical interpolation [56], which is the most appropriate way of interpolating in our normalized input latent space [61]. To concentrate on the facial features instead of background, we crop the generated images to contain only the face prior to evaluating the pairwise image metric. As the metric is quadratic [65], we divide by . We compute the expectation by taking 100,000 samples.
其中,是生成器(即基于样式的网络的),评价所生成图像之间的感知距离. 表示球形插值[56],这是在我们正常输入潜伏空间中插值的最适当方式[61]. 为了专注于面部特征而不是背景,我们裁剪生成的图像,在评价对映度量之前,只包含面部. 由于指标是四极[65],我们除以。 我们通过采集10万个样本来计算预期值.
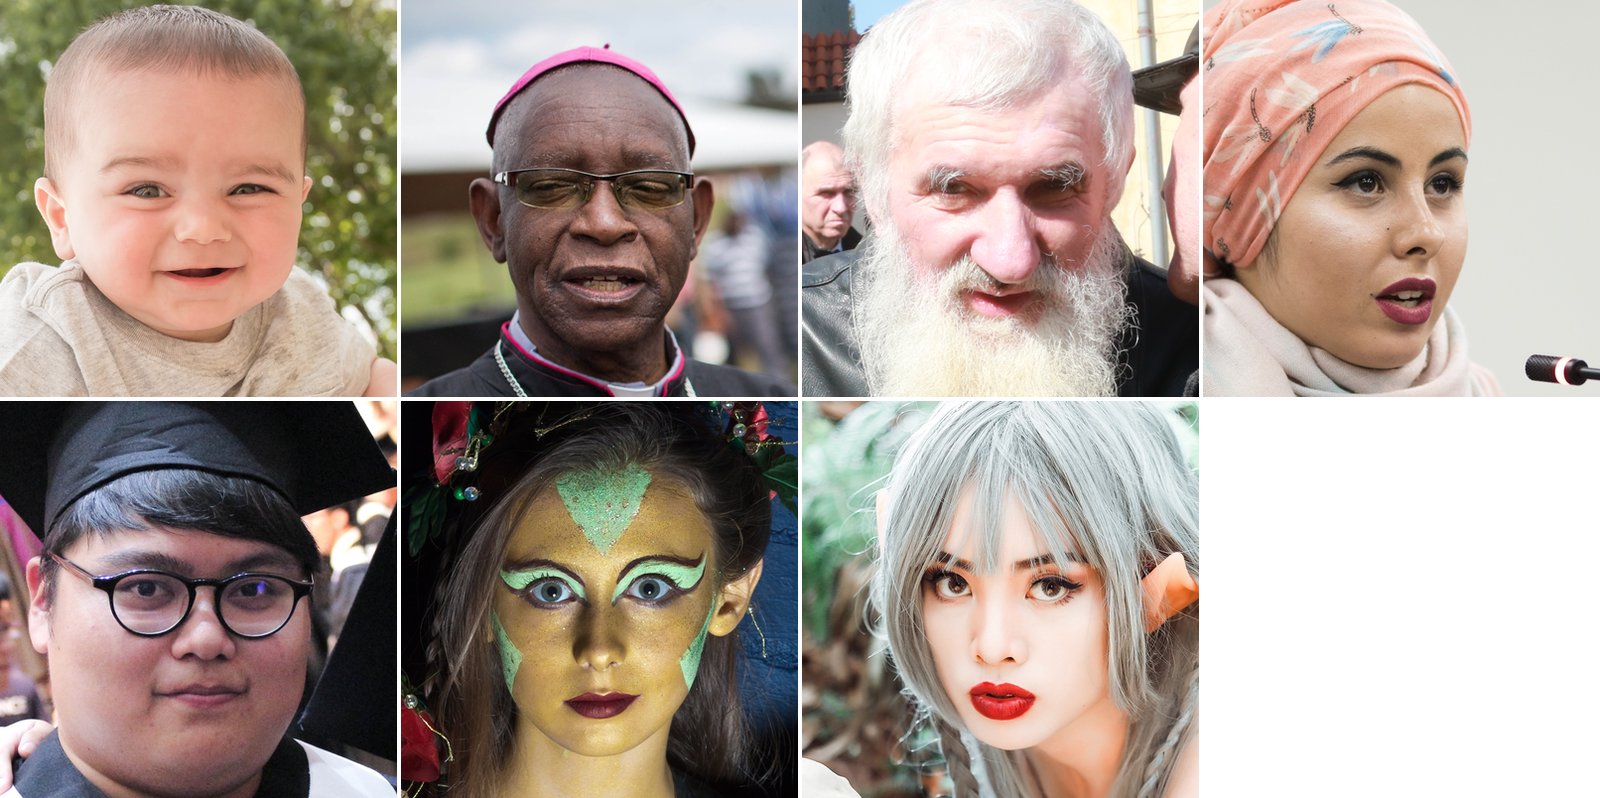
Figure 7: The FFHQ dataset offers a lot of variety in terms of age, ethnicity, viewpoint, lighting, and image background.
图7:FFHQ数据集在年龄,种族,观点,照明和图像背景方面提供了很多不同的数据.
Computing the average perceptual path length in is carried out in a similar fashion:
以类似方式计算中的平均知觉路径长度:
$$\begin{array}[]{r@{}l}\hskip-8.53581ptl_{\mathcal{W}}=\EX\Big[{\displaystyle\frac{1}{\epsilon^{2}}}d\big(&g(\mathrm{lerp}(f({\bf z}{1}),f({\bf z}{2});,t)),\
&g(\mathrm{lerp}(f({\bf z}{1}),f({\bf z}{2});,t+\epsilon))\big)\Big]\textrm{,}\end{array} \tag{3}$$
where the only difference is that interpolation happens in space. Because vectors in are not normalized in any fashion, we use linear interpolation ().
其中唯一的区别是插值发生在空间. 由于中的矢量不以任何方式正常化,我们使用线性插值().
| Method | Path length | Separa- | |||
|---|---|---|---|---|---|
| full | end | bility | |||
| b | Traditional generator | 412.0 | 415.3 | 10.78 | |
| d | Style-based generator | 446.2 | 376.6 | 03.61 | |
| e | + Add noise inputs | 200.5 | 160.6 | 03.54 | |
| + Mixing 50% | 231.5 | 182.1 | 0****3.51 | ||
| f | + Mixing 90% | 234.0 | 195.9 | 03.79 |
Table 3: Perceptual path lengths and separability scores for various generator architectures in FFHQ (lower is better). We perform the measurements in for the traditional network, and in for style-based ones. Making the network resistant to style mixing appears to distort the intermediate latent space somewhat. We hypothesize that mixing makes it more difficult for to efficiently encode factors of variation that span multiple scales.
| ** 方法** | ** 长度** | ** 执行部分第7段** | |||
|---|---|---|---|---|---|
| ** 全文** | ** 结束** | ** 走吧。 | |||
| b | 传统发电机 | 412.0 | 415.3 | 10.78 | |
| D. 国家 | 基于样式的生成器 | 446.2 | 376.6 | 03.61 | |
| 页:1 | + 添加噪音输入 | 页:1 | 页:1 | 03.54 | |
| + 混合50% | 231.5 | 182.1 | ∗∗* 3.51** | ||
| f 时值 | 你能帮我吗? | 234.0 | 195.9 | 03.79 |
表3:FFHQ中各种生成器架构的感知路径长度和可分离性分数(较低更好). 我们在中为传统网络进行测量,在中为风格网络进行测量。 使网络抵制风格混合似乎在一定程度上扭曲了中间潜在空间。 我们假设混合使得更难以有效地编码跨越多个尺度的变异因素。
Table 3 shows that this full-path length is substantially shorter for our style-based generator with noise inputs, indicating that is perceptually more linear than . Yet, this measurement is in fact slightly biased in favor of the input latent space . If is indeed a disentangled and “flattened” mapping of , it may contain regions that are not on the input manifold — and are thus badly reconstructed by the generator — even between points that are mapped from the input manifold, whereas the input latent space has no such regions by definition. It is therefore to be expected that if we restrict our measure to path endpoints, i.e., , we should obtain a smaller while is not affected. This is indeed what we observe in Table 3.
表3显示,这种全路径长度大大缩短了我们具有噪音输入的基于样式的生成器,表明在感知上比更线性. 然而,这种测量事实上对输入性潜在空间稍有偏差。 如果确实是对的分散和“夸大”的绘图,它可能包含一些区域,这些区域不在输入复数上,因此由生成器重建得很差,甚至位于从输入复数上绘图的点之间,而输入潜伏空间在定义上没有这种区域。 因此,如果将我们的措施限制在路径终点,即,我们应获得较小的,而则不受影响。 这确实是我们在表3中观察到的。
Table 4 shows how path lengths are affected by the mapping network. We see that both traditional and style-based generators benefit from having a mapping network, and additional depth generally improves the perceptual path length as well as FIDs. It is interesting that while improves in the traditional generator, becomes considerably worse, illustrating our claim that the input latent space can indeed be arbitrarily entangled in GANs.
表4显示了路径长度如何受到绘图网络的影响. 我们认为,传统和基于风格的发电机都受益于一个绘图网络,而更多的深度一般会改善感知路径长度和识别线。 令人感兴趣的是,虽然在传统发电机方面有所改进,但却变得更加糟糕,说明我们的说法,即输入的潜在空间确实可以任意地缠绕在GANs中。
| Method | FID | Path length | Separa- | |||
|---|---|---|---|---|---|---|
| full | end | bility | ||||
| b | Traditional 0 | 5.25 | 412.0 | 415.3 | 010.78 | |
| Traditional 8 | 4.87 | 896.2 | 902.0 | 170.29 | ||
| Traditional 8 | 4.87 | 324.5 | 212.2 | 006.52 | ||
| Style-based 0 | 5.06 | 283.5 | 285.5 | 009.88 | ||
| Style-based 1 | 4.60 | 219.9 | 209.4 | 006.81 | ||
| Style-based 2 | 4.43 | 217.8 | 199.9 | 006.25 | ||
| f | Style-based 8 | 4.40 | 234.0 | 195.9 | 003.79 |
Table 4: The effect of a mapping network in FFHQ. The number in method name indicates the depth of the mapping network. We see that FID, separability, and path length all benefit from having a mapping network, and this holds for both style-based and traditional generator architectures. Furthermore, a deeper mapping network generally performs better than a shallow one.
| ** 方法** | 页:1 | ** 长度** | ** 执行部分第7段** | |||
|---|---|---|---|---|---|---|
| ** 全文** | **可否通过? | ** 能力** | ||||
| b | 传统 0 | 5.25 | 412.0 | 415.3 | 010.78 | |
| 传统 8 | 4.87 | 896.2 | 902.0 | 170.29 | ||
| 传统 8 | 4.87 | 324.5 | 212.2 | 006.52 | ||
| 基于样式的 0 | 5.06 | 283.5 | 285.5 | 009.88 | ||
| 基于样式的 1 | 4.60 | 219.9 | 209.4 | 006.81 | ||
| 基于样式的 2 | 4.43 | ** 217.8** (中文(简体) ). | 199.9 | 006.25 | ||
| 审查报告 | 基于样式的 8 | 页:1 | 234.0 | ** 195.9** (单位:千美元) | 页:1 |
表4:一个测绘网络在FFHQ的影响. 方法名称中的数字表示绘图网络的深度. 我们看到,FID、可分离性和路径长度都得益于一个绘图网络,这对基于样式的和传统的生成器建筑都有利。 此外,更深层的测绘网络一般比浅层的要好。
4.2 Linear separability
4.2 线性可分性
If a latent space is sufficiently disentangled, it should be possible to find direction vectors that consistently correspond to individual factors of variation. We propose another metric that quantifies this effect by measuring how well the latent-space points can be separated into two distinct sets via a linear hyperplane, so that each set corresponds to a specific binary attribute of the image.
如果潜在空间充分分散,就应有可能找到与个别变化因素一致的方向矢量。 我们提出另一个指标,通过测量潜在空间点能在多大程度上通过线性超平面分离成两组不同的点来量化这种效应,这样,每组点都对应图像的特定二进制属性.
In order to label the generated images, we train auxiliary classification networks for a number of binary attributes, e.g., to distinguish male and female faces. In our tests, the classifiers had the same architecture as the discriminator we use (i.e., same as in [30]), and were trained using the CelebA-HQ dataset that retains the 40 attributes available in the original CelebA dataset. To measure the separability of one attribute, we generate 200,000 images with and classify them using the auxiliary classification network. We then sort the samples according to classifier confidence and remove the least confident half, yielding 100,000 labeled latent-space vectors.
为了给生成的图像贴上标签,我们训练一些二进制属性的辅助分类网络,例如区分男女面孔. 在我们的测试中,分类器的架构与我们使用的区别器相同(即与[30]中的相同),并使用保留原始的CelebA数据集中现有的40个属性的CelebA-HQ数据集进行训练. 为了测量一个属性的可分离性,我们用生成20万张图像,并利用辅助分类网络进行分类. 然后,我们按照分类器的置信度对样本进行分类,去除最不自信的一半,产生10万个贴标签的潜在空间矢量。
For each attribute, we fit a linear SVM to predict the label based on the latent-space point — for traditional and for style-based — and classify the points by this plane. We then compute the conditional entropy where are the classes predicted by the SVM and are the classes determined by the pre-trained classifier. This tells how much additional information is required to determine the true class of a sample, given that we know on which side of the hyperplane it lies. A low value suggests consistent latent space directions for the corresponding factor(s) of variation.
对于每个属性,我们用笼统的S所遇到的线性SVM来预测基于潜在-空间点的标签——传统为,样式为——并按此平面对点进行分类. 然后我们计算有条件的entropy ,其中是SVM预测的类,是由预先训练的分类器确定的类. 这说明需要多少额外的信息来确定样本的真实类别,因为我们知道它位于哪一边。 低值表明相应的变异因素具有一致的潜在空间方向。
We calculate the final separability score as , where enumerates the 40 attributes. Similar to the inception score [53], the exponentiation brings the values from logarithmic to linear domain so that they are easier to compare.
我们计算最终的可分离性分数为,其中列举了40个属性. 与起始分数[53]类似,引数将数值从对数到线域,这样比较就更容易了.
Tables 3 and 4 show that is consistently better separable than , suggesting a less entangled representation. Furthermore, increasing the depth of the mapping network improves both image quality and separability in , which is in line with the hypothesis that the synthesis network inherently favors a disentangled input representation. Interestingly, adding a mapping network in front of a traditional generator results in severe loss of separability in but improves the situation in the intermediate latent space , and the FID improves as well. This shows that even the traditional generator architecture performs better when we introduce an intermediate latent space that does not have to follow the distribution of the training data.
表3和表4显示,的分离性一直比要好,这表明其缠绕性较少。 此外,增加绘图网络的深度提高了的图像质量和可分离性,这符合合成网络内在倾向于分散输入表示的假设. 有趣的是,在传统发电机前增加一个绘图网络,导致严重丧失了可分离性,但改善了中间潜在空间的情况,FID也有所改善。 这表明,当我们引入一个不需要跟踪培训数据分布的中间潜伏空间时,即使是传统的生成器架构也表现更好。
5 Conclusion
5 结论
Based on both our results and parallel work by Chen et al. [6], it is becoming clear that the traditional GAN generator architecture is in every way inferior to a style-based design. This is true in terms of established quality metrics, and we further believe that our investigations to the separation of high-level attributes and stochastic effects, as well as the linearity of the intermediate latent space will prove fruitful in improving the understanding and controllability of GAN synthesis.
根据我们的成果和陈等人的平行工作[6],越来越明显的是,传统的GAN生成器建筑在任何方面都低于以风格为基础的设计. 就既定的质量衡量标准而言,情况就是这样。 我们还认为,我们对高层次属性和结构效应的分离以及中间潜在空间的线性性进行调查,将证明在增进对GAN合成的理解和可控性方面卓有成效。
We note that our average path length metric could easily be used as a regularizer during training, and perhaps some variant of the linear separability metric could act as one, too. In general, we expect that methods for directly shaping the intermediate latent space during training will provide interesting avenues for future work.
我们注意到,在培训期间,我们的平均路径长度衡量标准可以很容易地用作常态器,也许线性分离衡量标准的某些变体也可以起到一个作用。 总的来说,我们期望在培训期间直接形成中间潜在空间的方法将为今后的工作提供令人感兴趣的途径。
6 Acknowledgements
6 致谢
We thank Jaakko Lehtinen, David Luebke, and Tuomas Kynkäänniemi for in-depth discussions and helpful comments; Janne Hellsten, Tero Kuosmanen, and Pekka Jänis for compute infrastructure and help with the code release.
我们感谢Jaakko Lehtinen、David Luebke和Tuomas Kynkäänniemi进行了深入讨论并发表了有益的评论;感谢Janne Hellsten、Tero Kuosmanen和Pekka Jänis计算基础设施并协助了代码发布。
Appendix A The FFHQ dataset
附录 A FFHQ 数据集
We have collected a new dataset of human faces, Flickr-Faces-HQ (FFHQ), consisting of 70,000 high-quality images at resolution (Figure 7). The dataset includes vastly more variation than CelebA-HQ [30] in terms of age, ethnicity and image background, and also has much better coverage of accessories such as eyeglasses, sunglasses, hats, etc. The images were crawled from Flickr (thus inheriting all the biases of that website) and automatically aligned [31] and cropped. Only images under permissive licenses were collected. Various automatic filters were used to prune the set, and finally Mechanical Turk allowed us to remove the occasional statues, paintings, or photos of photos. We have made the dataset publicly available at https://github.com/NVlabs/ffhq-dataset
我们收集了一个新的人脸数据集Flickr-Faces-HQ(FFHQ),由70,000个在分辨率的高质量图像组成(图7)。 数据集在年龄,种族和图像背景上的差异远远大于CelebA-HQ[30],并且对眼镜,太阳镜,帽子等饰品的覆盖也好得多. 图片从Flickr上爬出(从而继承了该网站的所有偏见),自动对齐[31]并收割。 仅收集了许可许可证下的图像。 使用各种自动滤波器来喷洒镜头,最后Mechanical Turk允许我们移除偶尔出现的雕像,绘画或照片. 我们已在https://github.com/NVlabs/ffhq-dataset上公布数据集。
Appendix B Truncation trick in
附录 B 中的截断技巧
If we consider the distribution of training data, it is clear that areas of low density are poorly represented and thus likely to be difficult for the generator to learn. This is a significant open problem in all generative modeling techniques. However, it is known that drawing latent vectors from a truncated [42, 5] or otherwise shrunk [34] sampling space tends to improve average image quality, although some amount of variation is lost.
如果我们考虑培训数据的分布,显然低密度地区代表不足,因此发电机可能难以学习。 这是所有基因建模技术中一个重大的公开问题。 然而,众所周知,从一个截断的[42、5]或以其他方式缩小的[34]采样空间中抽取潜在的矢量,往往会提高平均图像质量,尽管会失去一些变化。
We can follow a similar strategy. To begin, we compute the center of mass of as . In case of FFHQ this point represents a sort of an average face (Figure 8, ). We can then scale the deviation of a given from the center as , where . While Brock et al. [5] observe that only a subset of networks is amenable to such truncation even when orthogonal regularization is used, truncation in space seems to work reliably even without changes to the loss function.
我们可以采取类似的策略。 首先,我们计算质量中心的为. 就FFHQ而言,这一点代表一种平均面孔(图8,)。 然后,我们可以将给定的从中心向偏差缩放为,即. Brock等人[5]指出,即使在使用正交正统化时,只有一部分网络可以进行这种截断,但空间的截断似乎可靠,即使损失功能没有变化。
Figure 8: The effect of truncation trick as a function of style scale . When we fade , all faces converge to the “mean” face of FFHQ. This face is similar for all trained networks, and the interpolation towards it never seems to cause artifacts. By applying negative scaling to styles, we get the corresponding opposite or “anti-face”. It is interesting that various high-level attributes often flip between the opposites, including viewpoint, glasses, age, coloring, hair length, and often gender.
图8:调戏作为风格尺度的函数的作用. 当我们淡出时,所有面孔都与FFHQ的“副面孔”一致。 这张脸对于所有训练有素的网络来说都是相似的,向它的插图似乎从未引起过文物. 通过对样式进行负面缩放,我们得到相应的反面或“反面”。 有趣的是,各种高层次的属性往往在对立面之间翻转,包括视线,眼镜,年龄,染色,发长,而且常常是性别.
Appendix C Hyperparameters and training details
附录 C 超参数与训练细节
We build upon the official TensorFlow [1] implementation of Progressive GANs by Karras et al. [30], from which we inherit most of the training details.[^3] This original setup corresponds to configuration a in Table 1. In particular, we use the same discriminator architecture, resolution-dependent minibatch sizes, Adam [33] hyperparameters, and exponential moving average of the generator. We enable mirror augmentation for CelebA-HQ and FFHQ, but disable it for LSUN. Our training time is approximately one week on an NVIDIA DGX-1 with 8 Tesla V100 GPUs.
我们借鉴了Karras等人对进步型GANs[1]的正式执行[30],我们继承了大部分培训细节。 此原始设置与表1中的配置对应. 特别是,我们使用相同的歧义架构,依赖分辨率的小批量大小,亚当[33]超参数,以及生成器的指数移动平均值. 我们允许对CelebA-HQ和FFHQ进行镜像增强,但对LSUN则禁用. 我们的训练时间大约为一周,使用8台特斯拉V100GPU的NVIDIA DGX-1.
For our improved baseline (b in Table 1), we make several modifications to improve the overall result quality. We replace the nearest-neighbor up/downsampling in both networks with bilinear sampling, which we implement by low-pass filtering the activations with a separable 2nd order binomial filter after each upsampling layer and before each downsampling layer [64]. We implement progressive growing the same way as Karras et al. [30], but we start from images instead of . For the FFHQ dataset, we switch from WGAN-GP to the non-saturating loss [22] with regularization [44] using . With we found that the FID scores keep decreasing for considerably longer than with WGAN-GP, and we thus increase the training time from 12M to 25M images. We use the same learning rates as Karras et al. [30] for FFHQ, but we found that setting the learning rate to 0.002 instead of 0.003 for and leads to better stability with CelebA-HQ.
为了改进基线(表1b),我们作了若干修改,以提高总体结果的质量。 我们用双线取样取代两个网络中最近的上下取样,我们采用低通道过滤激活,在每个上下取样层之后和每个下取样层之前分别使用第2顺序的双层过滤器[64]。 我们实施渐进增长的方式与Karras等人[30]一样,但我们从图像开始,而不是. 对于FFHQ数据集,我们从WGAN-GP转换为不饱和损失[22],使用正规化[44]使用. 有了,我们发现FID的分数比WGAN-GP的分数持续下降相当长,因此,我们把训练时间从12M图像增加到25M图像. 我们对FFHQ使用与Karras等人[30]相同的学习率,但我们发现,将和的学习率设定为0.002而不是0.003会导致与CelebA-HQ的更好稳定性.
For our style-based generator (f in Table 1), we use leaky ReLU [41] with and equalized learning rate [30] for all layers. We use the same feature map counts in our convolution layers as Karras et al. [30]. Our mapping network consists of 8 fully-connected layers, and the dimensionality of all input and output activations — including and — is 512. We found that increasing the depth of the mapping network tends to make the training unstable with high learning rates. We thus reduce the learning rate by two orders of magnitude for the mapping network, i.e., . We initialize all weights of the convolutional, fully-connected, and affine transform layers using . The constant input in synthesis network is initialized to one. The biases and noise scaling factors are initialized to zero, except for the biases associated with that we initialize to one.
对于我们的基于风格的生成器(表1中的f),我们使用漏流的ReLU[41]与,所有层均匀的学习率[30]. 我们在卷积层中使用了与Karras等人[30]相同的特征图。 我们的应成为地图网络由8个完全连接的层组成,所有输入和输出激活的维度——包括和——为512. 我们发现,增加绘图网络的深度往往使培训不稳定,学习率很高。 因此,我们把测绘网络的学习率降低了两个数量级,即。 我们用来初始化所有重心, 完全连接, 和affine转换层。 合成网络中的常数输入被初始化为1. 偏差和噪声缩放因素初始化为零,但与有关的偏差除外,我们初始化为1。
The classifiers used by our separability metric (Section 4.2) have the same architecture as our discriminator except that minibatch standard deviation [30] is disabled. We use the learning rate of , minibatch size of 8, Adam optimizer, and training length of 150,000 images. The classifiers are trained independently of generators, and the same 40 classifiers, one for each CelebA attribute, are used for measuring the separability metric for all generators. We will release the pre-trained classifier networks so that our measurements can be reproduced.
我们的分离度量度(第4.2节)所使用的分类器与我们的歧视者具有相同的结构,但小批量标准偏差[30]被禁用。 我们使用的学习率,小批量尺寸为8,亚当优化器,训练长度为15万个图像. 分类器是独立于发电机训练的,同样的40个分类器,每个CelebA属性一个,都用于测量所有发电机的分离度量. 我们将释放 预先训练的分类器网络 这样我们的测量可以复制。
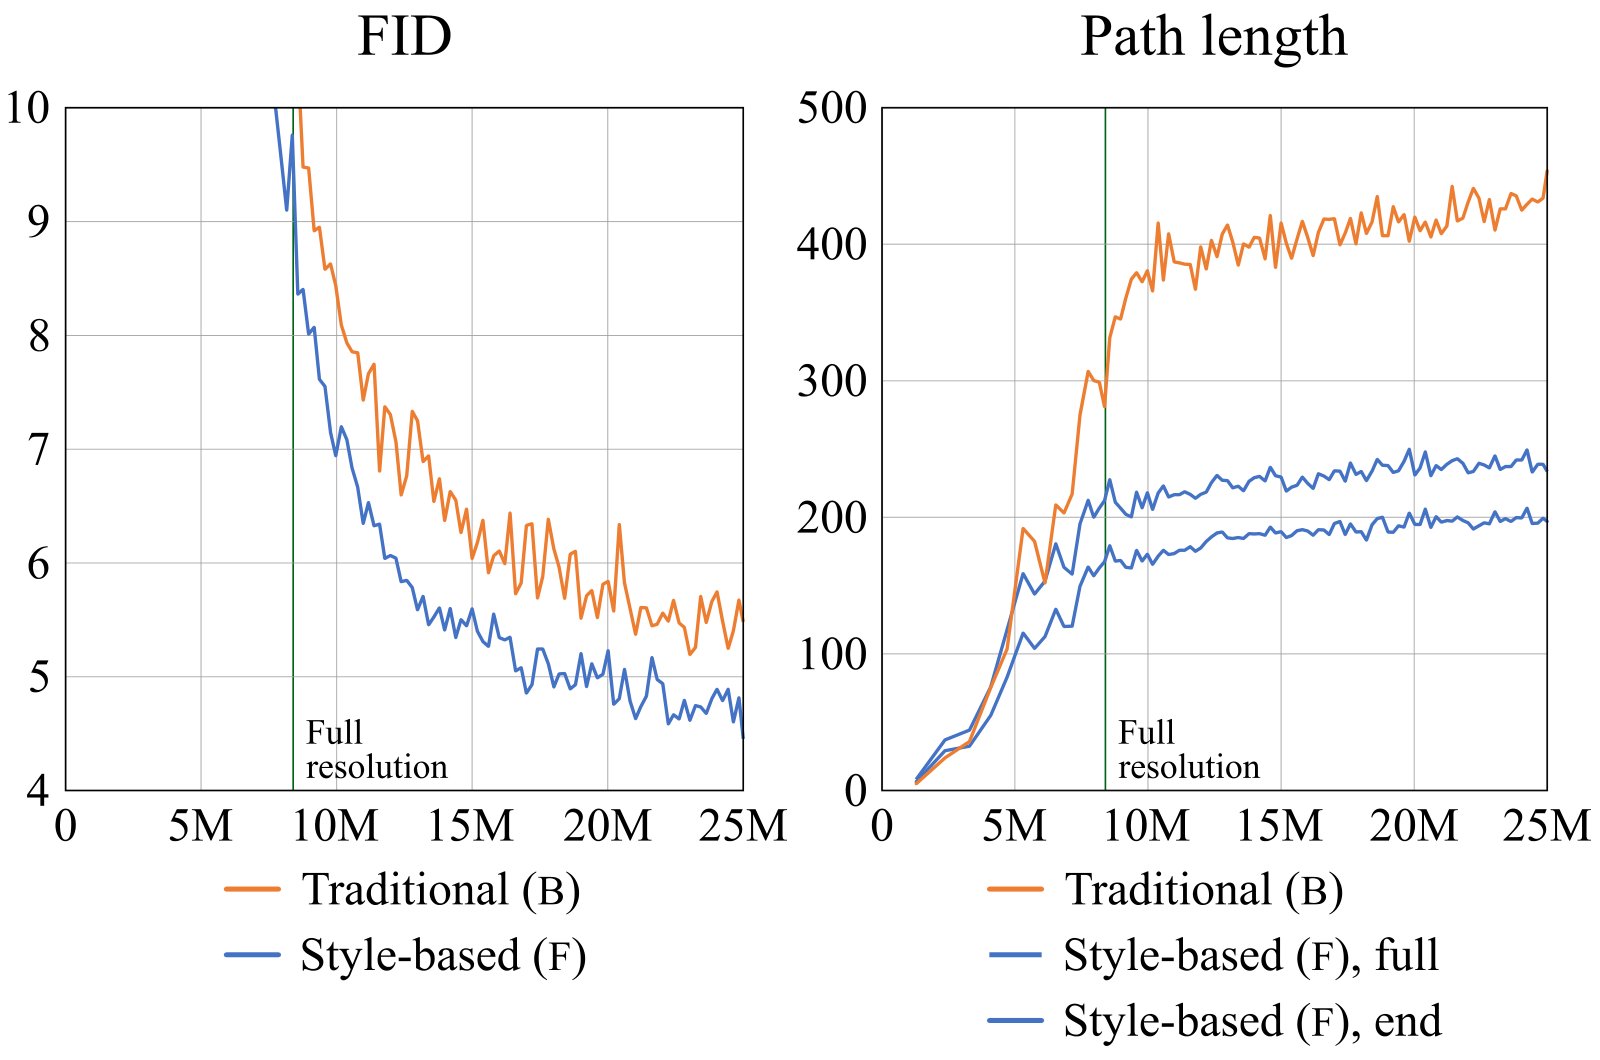
Figure 9: FID and perceptual path length metrics over the course of training in our configurations b and f using the FFHQ dataset. Horizontal axis denotes the number of training images seen by the discriminator. The dashed vertical line at 8.4M images marks the point when training has progressed to full resolution. On the right, we show only one curve for the traditional generator’s path length measurements, because there is no discernible difference between full-path and endpoint sampling in .
图9:使用FFHQ数据集进行b和f配置培训过程中的FID和感知路径长度测量。 水平轴表示歧视者看到的训练图像的数量。 8.4M图像的破损垂直线标志着训练已进入完全分辨率。 在右侧,我们仅显示传统发电机路径长度测量的一个曲线,因为在中,全路径取样和终点取样之间没有明显的区别。
We do not use batch normalization [29], spectral normalization [45], attention mechanisms [63], dropout [59], or pixelwise feature vector normalization [30] in our networks.
我们的网络不使用批归一化[29],光谱正常化[45],注意机制[63],退出[59],或像素特性矢量正常化[30]。
Appendix D Training convergence
附录 D 训练收敛
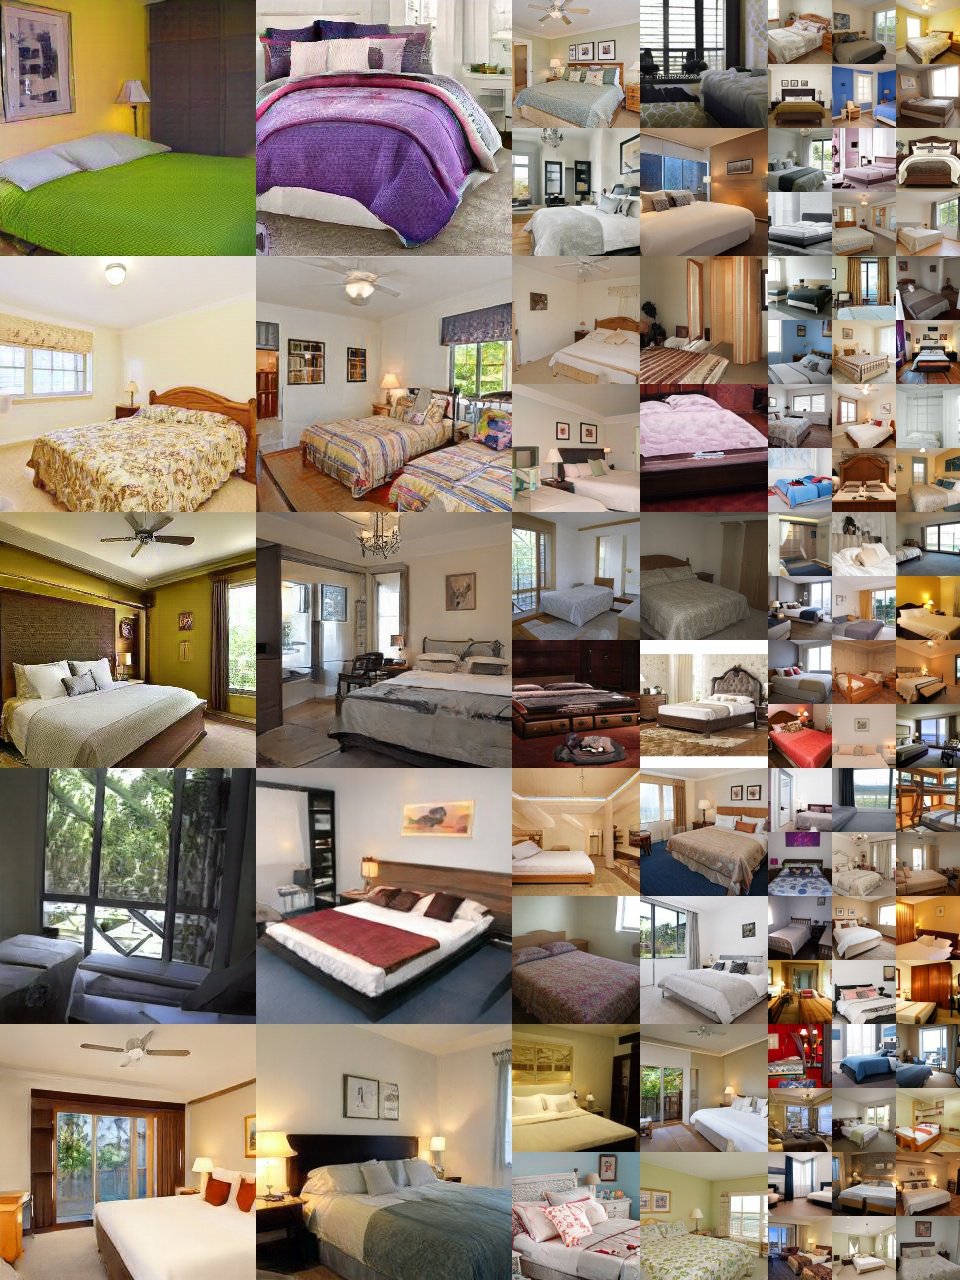
Figure 10: Uncurated set of images produced by our style-based generator (config f) with the LSUN Bedroom dataset at . FID computed for 50K images was 2.65.
图10:我们基于风格的生成器(配置f)与位于的LSUN床位数据集生成的一组不准确的图像. 50K图像的FID计算为2.65。
Figure 9 shows how the FID and perceptual path length metrics evolve during the training of our configurations b and f with the FFHQ dataset. With regularization active in both configurations, FID continues to slowly decrease as the training progresses, motivating our choice to increase the training time from 12M images to 25M images. Even when the training has reached the full resolution, the slowly rising path lengths indicate that the improvements in FID come at the cost of a more entangled representation. Considering future work, it is an interesting question whether this is unavoidable, or if it were possible to encourage shorter path lengths without compromising the convergence of FID.
图9显示在使用FFHQ数据集培训我们的配置b和f的过程中,FID和感知路径长度的度量衡是如何演变的. 随着规范化在两种配置中都活跃,FID随着培训的进展而持续缓慢减少,促使我们选择将训练时间从12M图像增加到25M图像. 即使培训达到了的完整分辨率,缓慢上升的路径长度也表明,FID的改进是以更加纠缠的表述为代价的. 考虑到今后的工作,这是一个令人感兴趣的问题,即这是否不可避免,或者是否能够鼓励缩短路径长度而不损害国际开发部的趋同。
Appendix E Other datasets
附录 E 其他数据集
Figures 10, 11, and 12 show an uncurated set of results for LSUN [62] Bedroom, Cars, and Cats, respectively. In these images we used the truncation trick from Appendix Bwith for resolutions . The accompanying video provides results for style mixing and stochastic variation tests. As can be seen therein, in case of Bedroom the coarse styles basically control the viewpoint of the camera, middle styles select the particular furniture, and fine styles deal with colors and smaller details of materials. In Cars the effects are roughly similar. Stochastic variation affects primarily the fabrics in Bedroom, backgrounds and headlamps in Cars, and fur, background, and interestingly, the positioning of paws in Cats. Somewhat surprisingly the wheels of a car never seem to rotate based on stochastic inputs.
图10、图11和图12分别显示LSUN[62]寝室、汽车和猫的一套未确定的结果。 在这些图像中,我们用附录B中的截断法把用于第号决议。 随附的视频提供了风格混合和结构变化测试的结果. 从中可以看出,就寝室而言,粗糙的风格基本上控制着相机的视角,中间的风格选择了特定的家具,精细的风格处理着颜色和材料的较小的细节. 在汽车中,效果大致相似. 结构变化主要影响着寝室的织物,车内的背景和头灯,以及皮毛,背景,有趣的是爪子在猫体内的定位. 有一点令人惊讶的是,汽车的轮子 似乎从来没有旋转 依据有条理的输入。
These datasets were trained using the same setup as FFHQ for the duration of 70M images for Bedroom and Cats, and 46M for Cars. We suspect that the results for Bedroom are starting to approach the limits of the training data, as in many images the most objectionable issues are the severe compression artifacts that have been inherited from the low-quality training data. Cars has much higher quality training data that also allows higher spatial resolution ( instead of ), and Cats continues to be a difficult dataset due to the high intrinsic variation in poses, zoom levels, and backgrounds.
这些数据集在寝室和猫的70M图像,以及汽车的46M图像持续期间,使用与FFHQ相同的设置进行了培训. 我们怀疑Bedroom的成果正开始接近培训数据的极限,因为在许多图像中,最令人反感的问题是从低质量培训数据中继承下来的严重压缩文物。 动车拥有更高质量的训练数据,也允许更高的空间分辨率(而不是),由于布局,缩放水平和背景的内在差异很大,Cats继续是一个困难的数据集.
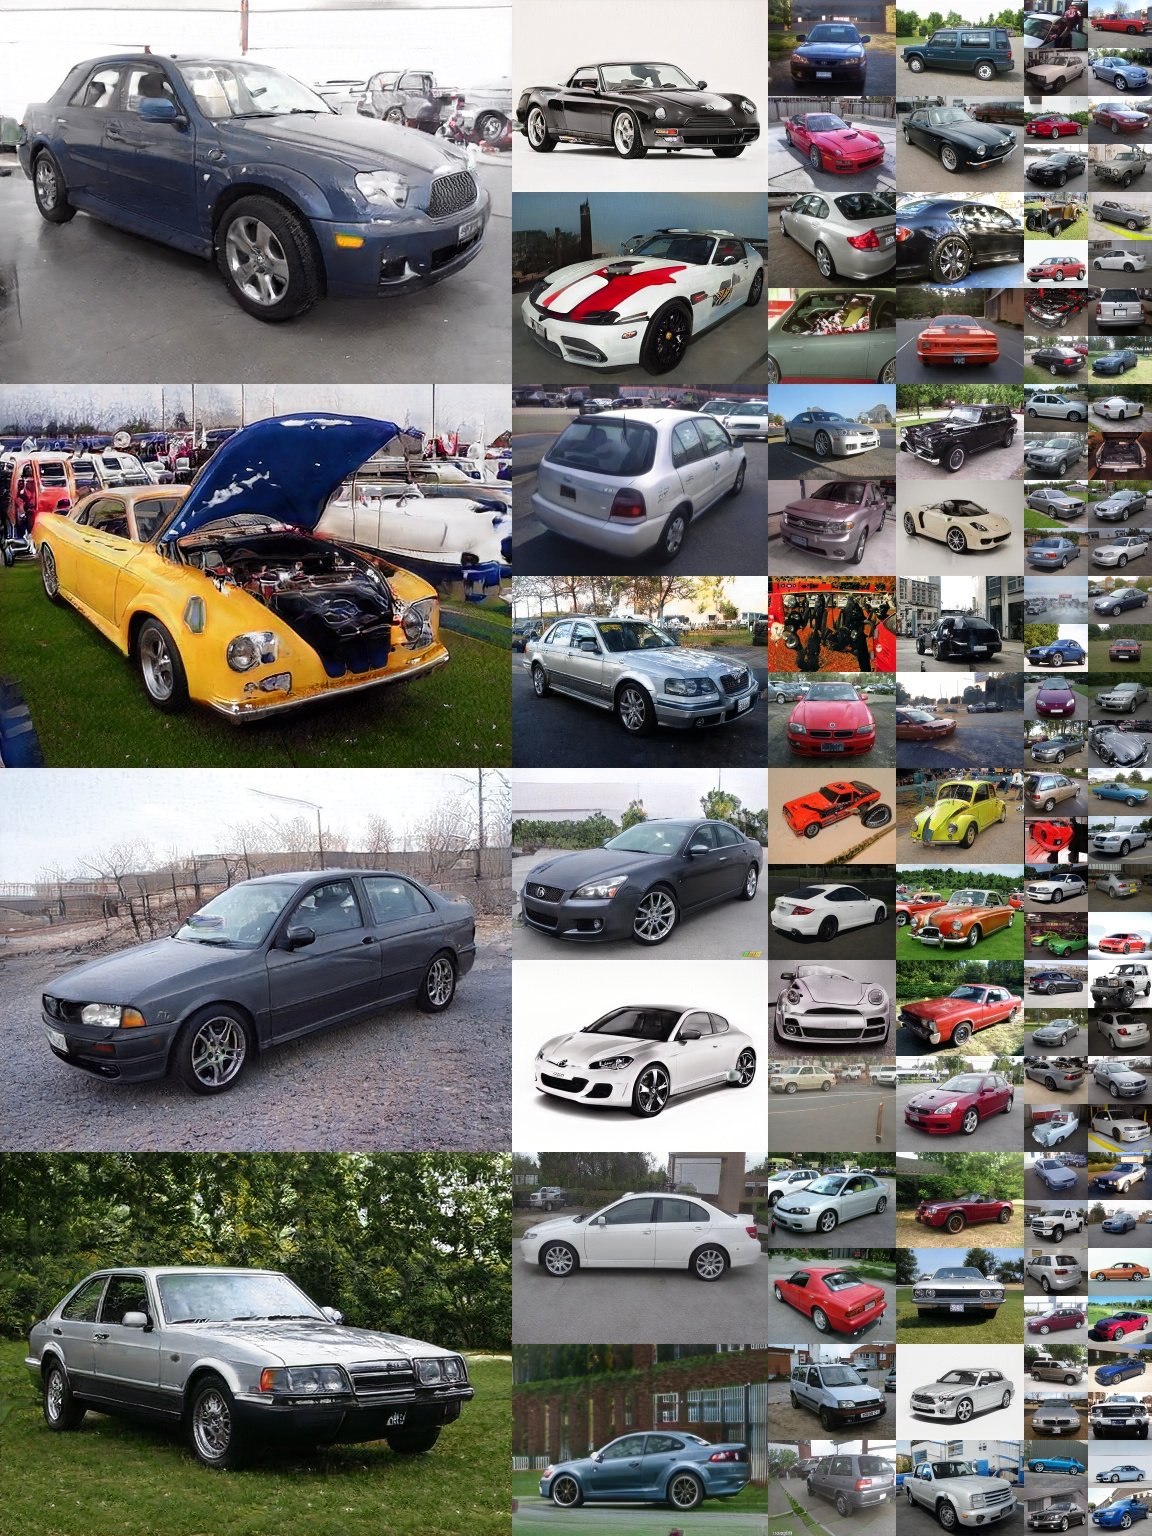
Figure 11: Uncurated set of images produced by our style-based generator (config f) with the LSUN Car dataset at . FID computed for 50K images was 3.27.
图11:我们基于风格的生成器(配置f)在的LSUN汽车数据集生成的未校准的一组图像. 50K图像的FID计算为3.27。
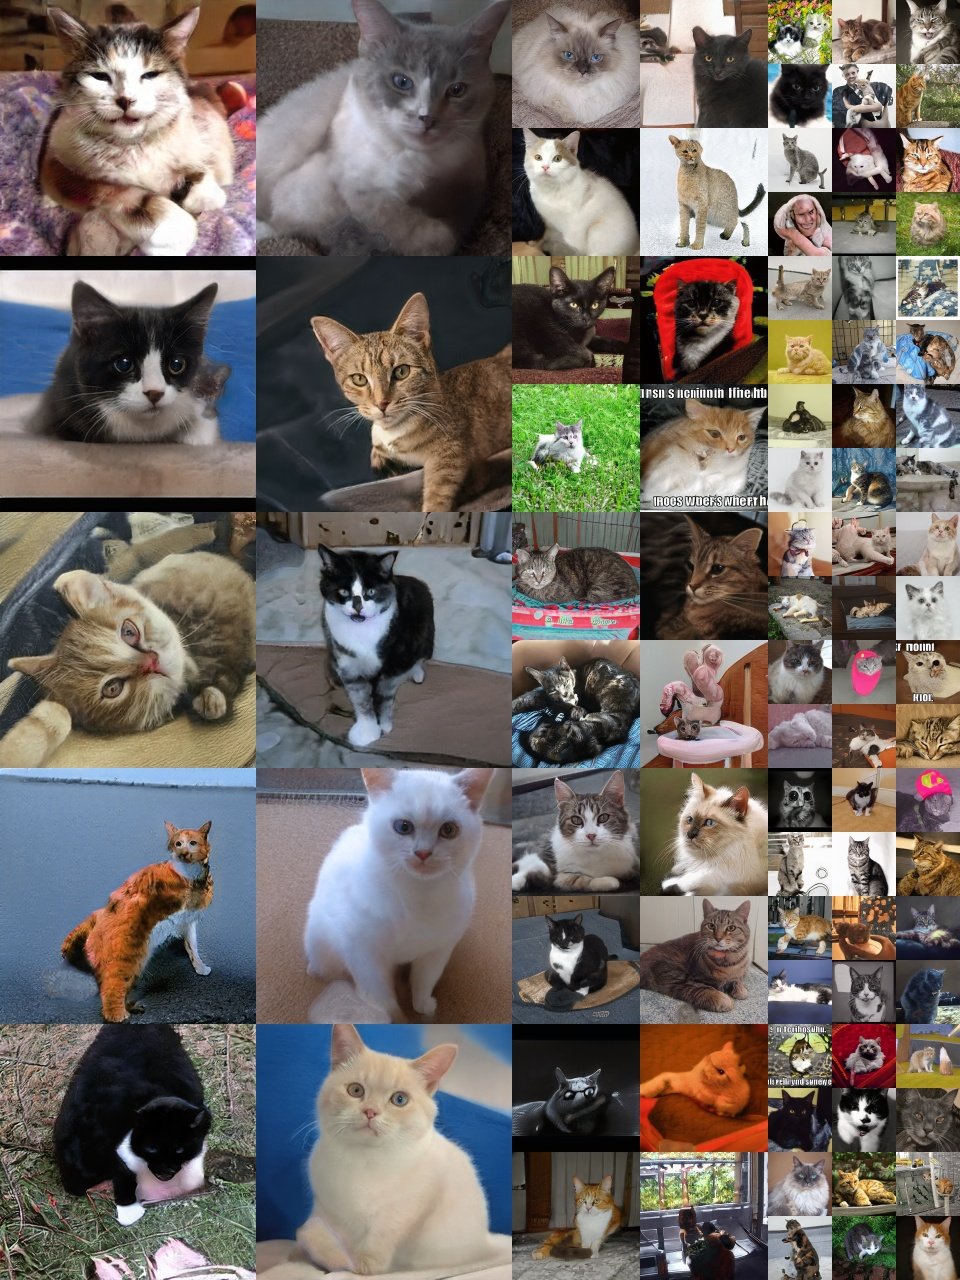
Figure 12: Uncurated set of images produced by our style-based generator (config f) with the LSUN Cat dataset at . FID computed for 50K images was 8.53.
图12:我们基于风格的生成器(配置 f)在的 LSUN Cat 数据集生成的一组未校准的图像. 50K图像的FID计算为8.53。
References
参考文献
[1] M. Abadi, P. Barham, J. Chen, Z. Chen, A. Davis, J. Dean, M. Devin, S. Ghemawat, G. Irving, M. Isard, M. Kudlur, J. Levenberg, R. Monga, S. Moore, D. G. Murray, B. Steiner, P. Tucker, V. Vasudevan, P. Warden, M. Wicke, Y. Yu, and X. Zheng. TensorFlow: a system for large-scale machine learning. In Proc. 12th USENIX Conference on Operating Systems Design and Implementation , OSDI’16, pages 265–283, 2016.
[2] A. Achille and S. Soatto. On the emergence of invariance and disentangling in deep representations. CoRR , abs/1706.01350, 2017.
[3] D. Bau, J. Zhu, H. Strobelt, B. Zhou, J. B. Tenenbaum, W. T. Freeman, and A. Torralba. GAN dissection: Visualizing and understanding generative adversarial networks. In Proc. ICLR , 2019.
[4] M. Ben-Yosef and D. Weinshall. Gaussian mixture generative adversarial networks for diverse datasets, and the unsupervised clustering of images. CoRR , abs/1808.10356, 2018.
[5] A. Brock, J. Donahue, and K. Simonyan. Large scale GAN training for high fidelity natural image synthesis. CoRR , abs/1809.11096, 2018.
[6] T. Chen, M. Lucic, N. Houlsby, and S. Gelly. On self modulation for generative adversarial networks. CoRR , abs/1810.01365, 2018.
[7] T. Q. Chen, X. Li, R. B. Grosse, and D. K. Duvenaud. Isolating sources of disentanglement in variational autoencoders. CoRR , abs/1802.04942, 2018.
[8] X. Chen, Y. Duan, R. Houthooft, J. Schulman, I. Sutskever, and P. Abbeel. InfoGAN: interpretable representation learning by information maximizing generative adversarial nets. CoRR , abs/1606.03657, 2016.
[9] E. L. Denton, S. Chintala, A. Szlam, and R. Fergus. Deep generative image models using a Laplacian pyramid of adversarial networks. CoRR , abs/1506.05751, 2015.
[10] G. Desjardins, A. Courville, and Y. Bengio. Disentangling factors of variation via generative entangling. CoRR , abs/1210.5474, 2012.
[11] T. Doan, J. Monteiro, I. Albuquerque, B. Mazoure, A. Durand, J. Pineau, and R. D. Hjelm. Online adaptative curriculum learning for GANs. CoRR , abs/1808.00020, 2018.
[12] J. Donahue, P. Krähenbühl, and T. Darrell. Adversarial feature learning. CoRR , abs/1605.09782, 2016.
[13] A. Dosovitskiy, J. T. Springenberg, and T. Brox. Learning to generate chairs with convolutional neural networks. CoRR , abs/1411.5928, 2014.
[14] H. Drucker and Y. L. Cun. Improving generalization performance using double backpropagation. IEEE Transactions on Neural Networks , 3(6):991–997, 1992.
[15] V. Dumoulin, I. Belghazi, B. Poole, A. Lamb, M. Arjovsky, O. Mastropietro, and A. Courville. Adversarially learned inference. In Proc. ICLR , 2017.
[16] V. Dumoulin, E. Perez, N. Schucher, F. Strub, H. d. Vries, A. Courville, and Y. Bengio. Feature-wise transformations. Distill , 2018. https://distill.pub/2018/feature-wise-transformations.
[17] V. Dumoulin, J. Shlens, and M. Kudlur. A learned representation for artistic style. CoRR , abs/1610.07629, 2016.
[18] I. P. Durugkar, I. Gemp, and S. Mahadevan. Generative multi-adversarial networks. CoRR , abs/1611.01673, 2016.
[19] C. Eastwood and C. K. I. Williams. A framework for the quantitative evaluation of disentangled representations. In Proc. ICLR , 2018.
[20] L. A. Gatys, A. S. Ecker, and M. Bethge. Image style transfer using convolutional neural networks. In Proc. CVPR , 2016.
[21] G. Ghiasi, H. Lee, M. Kudlur, V. Dumoulin, and J. Shlens. Exploring the structure of a real-time, arbitrary neural artistic stylization network. CoRR , abs/1705.06830, 2017.
[22] I. Goodfellow, J. Pouget-Abadie, M. Mirza, B. Xu, D. Warde-Farley, S. Ozair, A. Courville, and Y. Bengio. Generative Adversarial Networks. In NIPS , 2014.
[23] W.-S. Z. Guang-Yuan Hao, Hong-Xing Yu. MIXGAN: learning concepts from different domains for mixture generation. CoRR , abs/1807.01659, 2018.
[24] I. Gulrajani, F. Ahmed, M. Arjovsky, V. Dumoulin, and A. C. Courville. Improved training of Wasserstein GANs. CoRR , abs/1704.00028, 2017.
[25] M. Heusel, H. Ramsauer, T. Unterthiner, B. Nessler, and S. Hochreiter. GANs trained by a two time-scale update rule converge to a local Nash equilibrium. In Proc. NIPS , pages 6626–6637, 2017.
[26] I. Higgins, L. Matthey, A. Pal, C. Burgess, X. Glorot, M. Botvinick, S. Mohamed, and A. Lerchner. beta-vae: Learning basic visual concepts with a constrained variational framework. In Proc. ICLR , 2017.
[27] X. Huang and S. J. Belongie. Arbitrary style transfer in real-time with adaptive instance normalization. CoRR , abs/1703.06868, 2017.
[28] X. Huang, M. Liu, S. J. Belongie, and J. Kautz. Multimodal unsupervised image-to-image translation. CoRR , abs/1804.04732, 2018.
[29] S. Ioffe and C. Szegedy. Batch normalization: Accelerating deep network training by reducing internal covariate shift. CoRR , abs/1502.03167, 2015.
[30] T. Karras, T. Aila, S. Laine, and J. Lehtinen. Progressive growing of GANs for improved quality, stability, and variation. CoRR , abs/1710.10196, 2017.
[31] V. Kazemi and J. Sullivan. One millisecond face alignment with an ensemble of regression trees. In Proc. CVPR , 2014.
[32] H. Kim and A. Mnih. Disentangling by factorising. In Proc. ICML , 2018.
[33] D. P. Kingma and J. Ba. Adam: A method for stochastic optimization. In ICLR , 2015.
[34] D. P. Kingma and P. Dhariwal. Glow: Generative flow with invertible 1x1 convolutions. CoRR , abs/1807.03039, 2018.
[35] D. P. Kingma and M. Welling. Auto-encoding variational bayes. In ICLR , 2014.
[36] K. Kurach, M. Lucic, X. Zhai, M. Michalski, and S. Gelly. The gan landscape: Losses, architectures, regularization, and normalization. CoRR , abs/1807.04720, 2018.
[37] S. Laine. Feature-based metrics for exploring the latent space of generative models. ICLR workshop poster , 2018.
[38] Y. Li, C. Fang, J. Yang, Z. Wang, X. Lu, and M.-H. Yang. Universal style transfer via feature transforms. In Proc. NIPS , 2017.
[39] Y. Li, N. Wang, J. Liu, and X. Hou. Demystifying neural style transfer. CoRR , abs/1701.01036, 2017.
[40] M. Lucic, K. Kurach, M. Michalski, S. Gelly, and O. Bousquet. Are GANs created equal? a large-scale study. CoRR , abs/1711.10337, 2017.
[41] A. L. Maas, A. Y. Hannun, and A. Ng. Rectifier nonlinearities improve neural network acoustic models. In Proc. International Conference on Machine Learning (ICML) , volume 30, 2013.
[42] M. Marchesi. Megapixel size image creation using generative adversarial networks. CoRR , abs/1706.00082, 2017.
[43] L. Matthey, I. Higgins, D. Hassabis, and A. Lerchner. dsprites: Disentanglement testing sprites dataset. https://github.com/deepmind/dsprites-dataset/, 2017.
[44] L. Mescheder, A. Geiger, and S. Nowozin. Which training methods for GANs do actually converge? CoRR , abs/1801.04406, 2018.
[45] T. Miyato, T. Kataoka, M. Koyama, and Y. Yoshida. Spectral normalization for generative adversarial networks. CoRR , abs/1802.05957, 2018.
[46] T. Miyato and M. Koyama. cGANs with projection discriminator. CoRR , abs/1802.05637, 2018.
[47] G. Mordido, H. Yang, and C. Meinel. Dropout-gan: Learning from a dynamic ensemble of discriminators. CoRR , abs/1807.11346, 2018.
[48] S. Mukherjee, H. Asnani, E. Lin, and S. Kannan. ClusterGAN : Latent space clustering in generative adversarial networks. CoRR , abs/1809.03627, 2018.
[49] D. J. Rezende, S. Mohamed, and D. Wierstra. Stochastic backpropagation and approximate inference in deep generative models. In Proc. ICML , 2014.
[50] K. Ridgeway. A survey of inductive biases for factorial representation-learning. CoRR , abs/1612.05299, 2016.
[51] A. S. Ross and F. Doshi-Velez. Improving the adversarial robustness and interpretability of deep neural networks by regularizing their input gradients. CoRR , abs/1711.09404, 2017.
[52] T. Sainburg, M. Thielk, B. Theilman, B. Migliori, and T. Gentner. Generative adversarial interpolative autoencoding: adversarial training on latent space interpolations encourage convex latent distributions. CoRR , abs/1807.06650, 2018.
[53] T. Salimans, I. J. Goodfellow, W. Zaremba, V. Cheung, A. Radford, and X. Chen. Improved techniques for training GANs. In NIPS , 2016.
[54] J. Schmidhuber. Learning factorial codes by predictability minimization. Neural Computation , 4(6):863–879, 1992.
[55] R. Sharma, S. Barratt, S. Ermon, and V. Pande. Improved training with curriculum gans. CoRR , abs/1807.09295, 2018.
[56] K. Shoemake. Animating rotation with quaternion curves. In Proc. SIGGRAPH ’85 , 1985.
[57] A. Siarohin, E. Sangineto, and N. Sebe. Whitening and coloring transform for GANs. CoRR , abs/1806.00420, 2018.
[58] K. Simonyan and A. Zisserman. Very deep convolutional networks for large-scale image recognition. CoRR , abs/1409.1556, 2014.
[59] N. Srivastava, G. Hinton, A. Krizhevsky, I. Sutskever, and R. Salakhutdinov. Dropout: A simple way to prevent neural networks from overfitting. Journal of Machine Learning Research , 15:1929–1958, 2014.
[60] T. Wang, M. Liu, J. Zhu, A. Tao, J. Kautz, and B. Catanzaro. High-resolution image synthesis and semantic manipulation with conditional GANs. CoRR , abs/1711.11585, 2017.
[61] T. White. Sampling generative networks: Notes on a few effective techniques. CoRR , abs/1609.04468, 2016.
[62] F. Yu, Y. Zhang, S. Song, A. Seff, and J. Xiao. LSUN: Construction of a large-scale image dataset using deep learning with humans in the loop. CoRR , abs/1506.03365, 2015.
[63] H. Zhang, I. Goodfellow, D. Metaxas, and A. Odena. Self-attention generative adversarial networks. CoRR , abs/1805.08318, 2018.
[64] R. Zhang. Making convolutional networks shift-invariant again, 2019.
[65] R. Zhang, P. Isola, A. A. Efros, E. Shechtman, and O. Wang. The unreasonable effectiveness of deep features as a perceptual metric. In Proc. CVPR , 2018.