StreamTimer: Efficient Inference for Long-Context Time Series Transformers
StreamTimer: Efficient Inference for Long-Context Time Series Transformers
Zhejiang University
Sun Yat-sen University
{mengxiyu, wuyuhan, dongyb, xdq}@zju.edu.cn, xiaocanran999@gmail.com
Abstract
摘要
Time series forecasting (TSF) plays a vital role across various domains such as finance, energy, healthcare, and meteorology. Currently, most deep learning based TSF methods typically operate with a fixed lookback window. This approach comes from the high compute and memory costs of long contexts, as well as the standard practice of using sliding windows. This creates a trade-off. Making the window larger reduces the number of training samples, which can harm stability and generalization. However, keeping the window small prevents the model from using long history during inference. We propose an inference-only streaming autoregressive framework that replaces repeated full-context recomputation with a one-time context warmup and incremental decoding, enabling efficient long-history forecasting without retraining. While straightforward caching attentions is brittle for time series due to distribution shifts and noisy or redundant histories, we address these issues with cache-consistent normalization and selective memory under a fixed cache budget. Across diverse benchmarks, our approach substantially reduces inference latency with no or marginal accuracy loss, and often improves performance when longer lookbacks are beneficial.
时间序列预测(TSF)在金融、能源、医疗和气象等领域都很关键。目前,大多数基于深度学习的时间序列预测方法仍按固定回看窗口来工作。这样做,既是因为长上下文的计算和内存开销很高,也是因为滑动窗口已成为常规做法。于是就出现了权衡:窗口加长会减少训练样本,可能损害稳定性和泛化;窗口太短,模型在推理时又用不上更长的历史。我们提出一套只在推理阶段使用的流式自回归框架,用一次上下文预热加增量解码,取代反复对完整上下文重新计算,从而不必重新训练就能高效地利用长历史做预测。对时间序列来说,直接缓存注意力并不稳妥,因为存在分布偏移,历史里也常有噪声或冗余;我们用与缓存一致的归一化,并在固定缓存预算下做选择性记忆,来应对这些问题。在多种基准上,该方法大幅降低了推理延迟,准确率没有损失或只有很小损失,并且在更长回看有益时往往还能提高性能。
1 Introduction
1 引言
Long-term time series forecasting has evolved rapidly over the past decades, witnessing a paradigm shift from traditional statistical methods to deep learning architectures [Jin et al., 2024; Wang et al., 2024b]. While these substantial architectural innovations, their fundamental operational protocol remains surprisingly static, characterized by a reliance on a fixed lookback window [Qiu et al., 2024]. Specifically, models are constrained to a pre-determined number of historical time steps (e.g., 96 days or 720 hours) to forecast future values [Liu et al., 2024b]. This rigid sliding window approach persists even as underlying architectures grow increasingly complex, creating a misalignment between the model's intrinsic capacity and its effective utilization of context.
过去几十年里,长期时间序列预测发展很快,经历了从传统统计方法到深度学习架构的转变 [Jin et al., 2024; Wang et al., 2024b]。尽管架构上的创新已经相当可观,其基本运行协议却出人意料地几乎没变,仍然依赖固定的回看窗口 [Qiu et al., 2024]。具体来说,模型被限制在预先设定的历史步数(例如 96 天或 720 小时)上去预测未来值 [Liu et al., 2024b]。即便底层架构越来越复杂,这种刻板的滑动窗口做法依然保留着,于是模型本身的能力与它实际利用上下文的方式之间出现了错位。
This operational rigidity introduces a paradox in modern TSF. That is, longer historical contexts theoretically harbor richer temporal information, but extending the window to capture it is computationally expensive. Given the quadratic complexity of self-attention, lengthening the window substantially increases memory and compute costs [Zhou et al., 2021]. Besides, empirical evidence suggests that simply enlarging the window often degrades performance due to attention dispersion, insufficient training samples, and overfitting to irrelevant noise [Nie et al., 2023; Liu et al., 2024d]. Consequently, practitioners are trapped in a dilemma: they must either truncate history or risk computational intractability and model instability. This suggests that the fixed-window paradigm is inherently suboptimal for capturing the continuous and unrestricted dynamics of time series data.
这种运行上的刻板,给当代时间序列预测带来一个矛盾:更长的历史上下文理论上包含更丰富的时间信息,但把窗口拉长去捕捉这些信息,计算代价很高。由于自注意力是平方复杂度,加长窗口会显著增加内存和计算开销 [Zhou et al., 2021]。此外,经验证据表明,只是把窗口做大,往往会因为注意力分散、训练样本不足,以及对无关噪声过拟合,反而把性能做差 [Nie et al., 2023; Liu et al., 2024d]。于是实践者陷入两难:要么截断历史,要么承担计算上难以承受和模型不稳的风险。这说明,固定窗口范式本质上并不适合刻画时间序列数据连续、不受窗口限制的动态。
To resolve these structural limitations, we propose a transition from the repeated recomputation of fixed windows to an Inference-Only Streaming Autoregressive Framework. Inspired by the efficient caching mechanisms in Large Language Models (LLMs), our approach views forecasting as a continuous, stateful process. By replacing repeated full-context recomputation with a one-time context warmup followed by incremental decoding, we reduce the complexity of extending context from quadratic to linear. This allows the model to efficiently leverage extensive historical data without the latency penalties of massive fixed windows. Moreover, as an inference-time optimization, this framework requires no retraining, allowing the trained model to achieve superior long-context performance directly.
为克服这些结构性限制,我们主张从反复对固定窗口重新计算,转向一套只在推理阶段使用的流式自回归框架。受大语言模型(LLM)中高效缓存机制的启发,我们把预测看成一个连续、有状态的过程。用一次上下文预热加增量解码,取代反复对完整上下文重新计算,从而把扩展上下文的复杂度从平方降到线性。这样,模型就能高效利用大量历史数据,而不必承担巨大固定窗口带来的延迟。而且,作为推理阶段的优化,这套框架不必重新训练,已训练好的模型可以直接获得更好的长上下文表现。
However, the direct adaptation of NLP-style Key-Value (KV) caching [Xiao et al., 2024] to time series is brittle due to two domain challenges. First, time series data are non-stationary. Current baselines typically employ Reversible Instance Normalization (RevIN) [Kim et al., 2021; Qiu et al., 2024] to mitigate statistical drifts; however, this creates distribution cache mismatches, meaning that the key vectors stored at time effectively reside in a different feature space than Query vectors generated at . Second, unlike semantically dense text, time series history is replete with redundancy, where indiscriminately caching noise diminishes the efficacy of the attention mechanism.
不过,把自然语言里那种键值(KV)缓存 [Xiao et al., 2024] 直接搬到时间序列上并不稳妥,原因在于两个领域特有的困难。第一,时间序列数据是非平稳的。现有基线通常用可逆实例归一化(RevIN)[Kim et al., 2021; Qiu et al., 2024] 来缓解统计漂移;但这会造成分布与缓存不一致,也就是说,存储在 时刻的 Key 向量,实际上处在与 时刻生成的 Query 向量不同的特征空间里。第二,与语义密集的文本不同,时间序列历史里充满冗余,不加选择地把噪声也缓存下来,会削弱注意力机制的效果。
To overcome these issues, we introduce StreamTimer, a robust streaming framework tailored for TSF. We propose Cache-Consistent Normalization to dynamically align cached representations with the current statistical regime, and incorporate window attention with attention sinks to maintain temporal coherence while retaining only high-value historical tokens. Our contributions lie in three aspects:
为解决这些问题,我们提出面向时间序列预测的稳健流式框架 StreamTimer。我们提出与缓存一致的归一化(Cache-Consistent Normalization),使缓存中的表示动态对齐到当前统计状态,并引入带有 attention sink 的窗口注意力,以在只保留高价值历史 token 的同时维持时间上的连贯。贡献主要有三点:
We propose the first inference-only streaming framework with Timer backbones for TSF that effectively utilizes the lookback window, decoupling context length from computational cost.
我们提出首个以 Timer 为骨干、只在推理阶段使用的时间序列预测流式框架,能够有效利用回看窗口,并把上下文长度从计算代价中解开。
We identify and resolve the normalization mismatch problem in generative trained large time series models, ensuring mathematically consistent distribution during streaming inference.
我们指出并解决了生成式训练的大规模时间序列模型中的归一化不一致问题,使流式推理过程中的分布在数学上保持一致。
Experiments validate that StreamTimer achieves significant speedup while outperforming SOTA baselines, particularly on ultra-long sequences.
实验表明,StreamTimer 在明显加速的同时优于当时的先进基线,在超长序列上尤其如此。
2 Related Work
2 相关工作
2.1 Time Series Forecasting
2.1 时间序列预测
Contemporary deep learning architectures for time series forecasting predominantly focus on modeling complex global temporal dependencies and multivariate interactions from historical data. Early studies built on Recurrent Neural Networks [Lin et al., 2023] and Temporal Convolutional Networks [Luo and Wang, 2024] to capture local patterns through gated recurrences and dilated convolutions. More recently, Transformers have emerged as the mainstream for long-horizon forecasting due to their capability to capture long-range dependencies. Specifically, Informer [Zhou et al., 2021] introduces sparse attention tailored to long sequences, PatchTST [Nie et al., 2023] and iTransformer [Liu et al., 2024b] leverage patch- and channel-centric designs, and TimeMixer [Wang et al., 2024a] and TimeMoE [Shi et al., 2025] enhance the exploitation of multivariate structures and multi-scale temporal patterns. While these backbones provide robust representation capabilities, they typically rely on a fixed-lookback-fixed-forecast recomputation paradigm.
当代用于时间序列预测的深度学习架构,主要关注从历史数据中建模复杂的全局时间依赖以及多变量之间的相互作用。早期工作建立在循环神经网络 [Lin et al., 2023] 和时间卷积网络 [Luo and Wang, 2024] 上,借助门控循环和膨胀卷积捕捉局部模式。更近一些,Transformer 因其捕捉长程依赖的能力,成为长视野预测的主流。具体而言,Informer [Zhou et al., 2021] 引入面向长序列的稀疏注意力,PatchTST [Nie et al., 2023] 和 iTransformer [Liu et al., 2024b] 分别利用以 patch 和通道为中心的设计,TimeMixer [Wang et al., 2024a] 和 TimeMoE [Shi et al., 2025] 则加强了对多变量结构及多尺度时间模式的利用。这些骨干虽然提供了稳健的表示能力,但通常仍依赖“固定回看、固定预测、反复重算”的范式。
2.2 Generative Pre-training for Large Time Series Models
2.2 大规模时间序列模型的生成式预训练
The field of TSF has transitioned from small-scale, task-specific deep learning models [Wu et al., 2025; Lin et al., 2024; Wu et al., 2024; Zeng et al., 2023] to Large Time Series Models (LTSMs) [Zhou et al., 2023; Jin et al., 2024; Liu et al., 2024a; Woo et al., 2024; Ansari and Stella, 2024] powered by unsupervised pre-training on massive datasets. Inspired by the success of LLMs, recent works have explored generative pre-training paradigms to build foundation models for time series.
时间序列预测已经从规模较小、面向特定任务的深度学习模型 [Wu et al., 2025; Lin et al., 2024; Wu et al., 2024; Zeng et al., 2023],转向在大规模数据上做无监督预训练的大型时间序列模型(LTSM)[Zhou et al., 2023; Jin et al., 2024; Liu et al., 2024a; Woo et al., 2024; Ansari and Stella, 2024]。受大语言模型成功的启发,近期工作开始探索用生成式预训练来构建时间序列基础模型。
Early efforts, such as Time-LLM [Jin et al., 2024] and LLM4TS [Chang et al., 2024], repurposed pre-trained LLMs (e.g., LLaMA, GPT-2) by aligning time series modalities with textual tokens. However, these methods often suffer from high computational overhead due to cross-modality alignment. More recently, native LTSMs like Timer [Liu et al., 2024d] have emerged, employing a decoder-only Transformer architecture trained via next-token prediction on large-scale heterogeneous datasets. Timer unifies various forecasting tasks into a single generative framework, demonstrating strong zero-shot generalization capabilities. Building on this, Timer-XL [Liu et al., 2024c] addresses the context bottleneck by introducing TimeAttention to capture fine-grained intra- and inter-series dependencies, expanding the context window to thousands of tokens.
早期工作如 Time-LLM [Jin et al., 2024] 和 LLM4TS [Chang et al., 2024],通过把时间序列模态与文本 token 对齐,来改用已经预训练好的大语言模型(例如 LLaMA、GPT-2)。不过,这类方法常常因为跨模态对齐而计算开销很高。更近一些,出现了 Timer [Liu et al., 2024d] 这类原生的大型时间序列模型,采用只含解码器的 Transformer 架构,在大规模异构数据上用下一 token 预测来训练。Timer 把多种预测任务统一到同一个生成框架里,并表现出较强的零样本泛化能力。在此基础上,Timer-XL [Liu et al., 2024c] 引入 TimeAttention 来捕捉更细的序列内部和序列之间依赖,把上下文窗口扩展到数千个 token,以缓解上下文瓶颈。
Despite these architectural advancements, both Timer and Timer-XL adhere to a recomputation-based inference protocol. To forecast a future horizon, these models require processing a fixed lookback window from scratch at each step. This rigid mechanism incurs quadratic computational complexity with respect to the context length and the forecast horizon , severely limiting their efficiency when handling extremely long historical contexts in real-time streaming scenarios.
尽管有这些架构上的进展,Timer 和 Timer-XL 仍然沿用基于重新计算的推理协议。要预测未来一段视野,这些模型需要在每一步都从头处理一个固定的回看窗口。这种刻板机制带来相对于上下文长度 和预测视野 的平方计算复杂度 ,在实时流式场景里处理极长历史时,效率会受到严重限制。
3 Approach
3 方法
3.1 Preliminaries
3.1 预备知识
We construct our streaming framework upon the foundation of LTSMs, specifically adopting the decoder-only Transformer architecture employed by Timer [Liu et al., 2024d] and Timer-XL [Liu et al., 2024c]. Unlike traditional deep forecasters that rely on encoder-decoder structures, Timer and Timer-XL treat time series forecasting as a native sequence generation task.
我们把流式框架建立在大型时间序列模型之上,具体采用 Timer [Liu et al., 2024d] 和 Timer-XL [Liu et al., 2024c] 所用的只含解码器的 Transformer 架构。与依赖编码器–解码器结构的传统深度预测模型不同,Timer 和 Timer-XL 把时间序列预测当作原生的序列生成任务。
Patch-based Tokenization. Given a raw univariate time series , the model first transforms the continuous data points into a sequence of discrete embeddings. We adopt a patching strategy where non-overlapping windows of size are aggregated into tokens. The resulting sequence consists of tokens, where each represents a local temporal segment. These segments are then projected into a high-dimensional latent space via a learnable linear embedding :
基于 patch 的 tokenization。 给定一条原始单变量时间序列 ,模型先把连续数据点变成一串离散嵌入。我们采用 patch 策略,把大小为 的不重叠窗口聚合成 token。得到的序列 含有 个 token,其中每个 表示一段局部时间片段。这些片段再通过可学习的线性嵌入 投影到高维潜在空间 :
where denotes the positional encoding required to preserve temporal ordering.
其中 表示用于保持时间顺序的位置编码。
Causal Contextualization. The core computation occurs within a stack of decoder-only Transformer blocks. To ensure the autoregressive property, a strict causal mask is applied to the self-attention mechanism. For the -th layer, the representation is updated by attending solely to historical tokens:
因果上下文化。 核心计算发生在 个只含解码器的 Transformer 块组成的堆叠中。为确保自回归性质,自注意力机制会加上严格的因果掩码 。对第 层而言,表示 只通过对历史 token 做注意力来更新:
where if . This mechanism guarantees that the information flow at step is strictly isolated from future signals.
其中当 时 。这一机制保证第 步的信息流严格与未来信号隔开。
Generative Objective. The training paradigm mirrors that of LLMs, formulating forecasting as a next token prediction (NTP) problem. The joint probability of the time series is factorized into a product of conditional probabilities:
生成目标。 训练范式与大语言模型类似,把预测写成下一 token 预测(NTP)问题。时间序列的联合概率被分解为条件概率的乘积:
In the continuous domain of time series, this probabilistic objective manifests as minimizing the reconstruction error between the predicted next patch and the ground truth. The model outputs the prediction via a linear projection head applied to the final hidden state . The optimization objective is defined as the Mean Squared Error (MSE) over the sequence:
在时间序列的连续域中,这一概率目标体现为最小化预测的下一 patch 与真值之间的重构误差。模型把线性投影头 作用在最后一层隐状态 上,得到预测 。优化目标定义为整段序列上的均方误差(MSE):
Through this formulation, the model learns to synthesize future trajectories based on the unified history representations, establishing the theoretical basis for our subsequent streaming optimizations.
借助这一表述,模型学会在统一的历史表示之上合成未来轨迹,也为后面的流式优化打下理论基座。
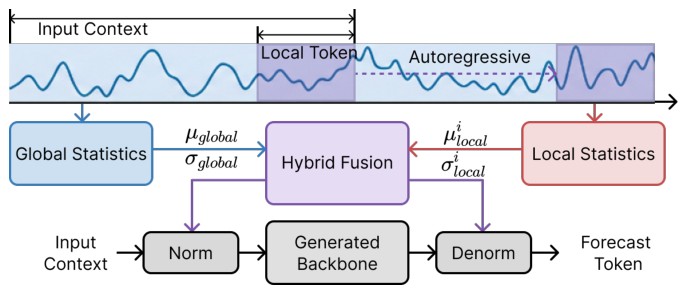
Figure 1: Proposed Hybrid-Scale Normalization Module.
图 1:所提出的混合尺度归一化模块。
3.2 Hybrid-Scale Normalization for Patch-based Generators
3.2 面向基于 patch 的生成器的混合尺度归一化
RevIN [Kim et al., 2021] effectively mitigates distribution shifts by normalizing the input using the mean and variance over the entire lookback window. However, for patch-based autoregressive models like Timer, relying solely on global statistics may overlook rapid and high-frequency fluctuations within individual patches. Conversely, normalizing strictly at the patch level risks discarding the global amplitude information necessary for accurate trajectory reconstruction.
RevIN [Kim et al., 2021] 用整个回看窗口上的均值和方差来归一化输入,能有效缓解分布偏移。不过,对 Timer 这类基于 patch 的自回归模型来说,只依赖全局统计量,可能会忽略单个 patch 内部快速、高频的波动。反过来,如果严格按 patch 做归一化,又可能丢掉准确重构轨迹所需的全局幅度信息。
To address this dilemma, we introduce a Hybrid-Scale Normalization strategy that dynamically calibrates the distribution by fusing global and local statistics. Let denote the input lookback window with length and variables. We first compute the global statistics across the temporal dimension:
为应对这一两难,我们提出混合尺度归一化策略,通过融合全局和局部统计量来动态校准分布。设 表示长度为 、含 个变量的输入回看窗口。我们先沿时间维计算全局统计量:
Simultaneously, for the -th patch , where is the patch size, we compute its local statistics and .
与此同时,对第 个 patch ( 为 patch 大小),我们计算其局部统计量 和 。
To balance the stability of global trends with the sensitivity to local variations, we define the normalization statistics as a convex combination of both scales, controlled by a mixing coefficient :
为了在全局趋势的稳定性与对局部变化的敏感性之间取得平衡,我们把归一化统计量定义为两种尺度的凸组合,并由混合系数 控制:
Each input patch is then normalized as . Crucially, to ensure consistency, the generative output is denormalized using the same hybrid statistics:
随后,每个输入 patch 被归一化为 。关键在于,为保持一致,生成输出 用同一组混合统计量做反归一化:
In our implementation, is a learnable parameter initialized to 0.5. This design allows the model to remain robust to non-stationary drifts while retaining essential global context, thereby enhancing the generation stability of Timer and Timer-XL. We provide detailed empirical and theoretical verification of this choice in Appendix C.
实现中, 是一个可学习参数,初始化为 0.5。这样设计使模型既能抵抗非平稳漂移,又能保留必要的全局上下文,从而增强 Timer 和 Timer-XL 的生成稳定性。关于这一选择更细致的经验与理论验证,见附录 C。
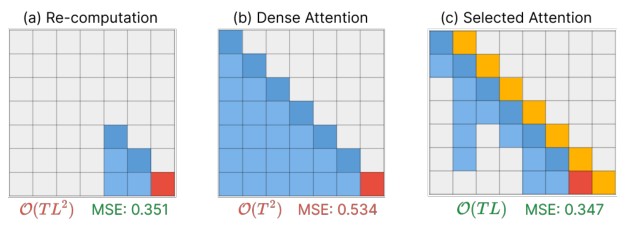
Figure 2: Illustration of proposed KV cache technique.
图 2:所提出的 KV 缓存方法示意。
3.3 Linear-Complexity Streaming via KV Caching
3.3 借助 KV 缓存实现线性复杂度的流式推理
The standard inference paradigm of Transformers typically involves a recomputation strategy, where the entire history is processed repeatedly to generate the next token. For a sequence of length , this results in a computational complexity of , rendering long-context forecasting prohibitively expensive. To address this, we implement a Streaming Inference Mechanism based on KV Caching, adapted for the patch-based architecture of Timer.
Transformer 的标准推理范式通常是反复处理全部历史来生成下一个 token。对长度为 的序列,这会带来 的计算复杂度,使长上下文预测变得代价过高。为此,我们实现一套基于 KV 缓存的流式推理机制,并适配到 Timer 的 patch 架构上。
Mechanism. Instead of recalculating the representations of historical patches at every step, we cache the Key and Value matrices computed in previous iterations. Let denote the input patch at step . During the streaming process, the model only computes the Query , Key , and Value for the current patch. The attention mechanism then attends to the concatenation of the cached states and the current states:
机制。 我们不再在每一步重新计算历史 patch 的表示,而是缓存先前迭代得到的 Key 和 Value 矩阵。设 为第 步的输入 patch。流式过程中,模型只计算当前 patch 的 Query 、Key 和 Value 。注意力机制随后对缓存状态与当前状态的拼接做注意力:
Here, denotes concatenation along the temporal dimension. By maintaining this persistent memory state, the computation for the current step becomes independent of the history length in terms of feature extraction, involving only a single forward pass of the Transformer block.
这里, 表示沿时间维拼接。通过维持这一持久记忆状态,当前第 步在特征提取上不再依赖于历史长度 ,而只需要 Transformer 块做一次前向计算。
Implementation Protocol. Operationally, we reformulate the inference process as a stateful autoregressive protocol over the discretized time horizon. The procedure commences by initializing an empty Key-Value memory. Unlike standard batch processing, the model subsequently enters a streaming phase where it ingests exclusively the current patch at each time step . During this incremental pass, the transformer blocks query the historical context persisted in the cache to derive the current representation . Crucially, to constrain memory growth, we employ an attention-based eviction policy: post-computation, we retain only the token serving as an attention sink and the subset of historical tokens with the highest attention scores. Low-scoring tokens are discarded from the memory bank. This selective retention strategy allows us to reconstruct the coherent forecast trajectory with a bounded memory overhead per step.
实现协议。 操作上,我们把推理过程改写成在离散时间视野上的有状态自回归协议。流程从初始化一个空的键值记忆开始。与标准的批处理不同,模型随后进入流式阶段,在每个时间步 只摄入当前 patch 。在这一增量过程中,Transformer 块查询缓存在记忆里的历史上下文,得到当前表示 。关键在于,为限制记忆增长,我们采用基于注意力的驱逐策略:计算完成后,只保留作为 attention sink 的 token,以及注意力分数最高的那一部分历史 token。分数低的 token 会从记忆库中丢弃。这种选择性保留策略使我们能在每步记忆开销有界的前提下,重构出连贯的预测轨迹。
4 Experiments
4 实验
We evaluate StreamTimer across three dimensions: (1) supervised training as a task-specific forecaster, (2) transferring as a zero-shot forecaster, and (3) the effectiveness of normalization and model efficiency. Since performance saturation on previous benchmarks [Qiu et al., 2024; Wang et al., 2024b] often conceals the challenges of the long-context forecasting paradigm, we establish new long-context forecasting benchmarks by following the experimental settings of Timer-XL [Liu et al., 2024c]. Detailed experimental configurations are provided in Appendix A.
我们从三个维度评估 StreamTimer:(1)作为面向特定任务的预测器做有监督训练;(2)作为零样本预测器做迁移;(3)归一化效果与模型效率。由于已有基准上的性能饱和 [Qiu et al., 2024; Wang et al., 2024b] 常常掩盖长上下文预测范式本身的困难,我们沿用 Timer-XL [Liu et al., 2024c] 的实验设置,建立新的长上下文预测基准。更细致的实验配置见附录 A。
4.1 Univariate Time Series Forecasting
4.1 单变量时间序列预测
Setups. To address the issue of data scarcity often encountered when extending context lengths in univariate time series [Makridakis et al., 2020], we follow the experimental protocol of Timer-XL [Liu et al., 2024c]. Specifically, we leverage the multivariate datasets from [Liu et al., 2024b] and formulate univariate forecasting tasks by applying channel independence. The core objective of our experiments is to evaluate model robustness given long historical inputs, rather than merely pursuing extended forecasting horizons. Consequently, we fix the forecast horizon and focus on expanding the lookback window to monthly and yearly scales. Furthermore, we establish a challenging long-context univariate benchmark named ERA5-S, derived from the ECMWF Reanalysis v5 (ERA5) dataset [Muñoz-Sabater et al., 2021]. Leveraging its 40-year temporal span, this benchmark is specifically designed to assess land-surface temperature forecasting capabilities based on yearly contexts.
实验设置。 为应对单变量时间序列在加长上下文时常常遇到的数据稀缺问题 [Makridakis et al., 2020],我们沿用 Timer-XL [Liu et al., 2024c] 的实验协议。具体来说,我们使用 [Liu et al., 2024b] 中的多变量数据集,并按通道独立把任务写成单变量预测。实验的核心目标是评估模型在长历史输入下的稳健性,而不是只追求更长的预测视野。因此,我们固定预测视野,把重点放在把回看窗口扩展到月、年尺度。此外,我们建立了一个更具挑战性的长上下文单变量基准 ERA5-S,数据来自 ECMWF 第五代再分析(ERA5)数据集 [Muñoz-Sabater et al., 2021]。该基准利用约 40 年的时间跨度,专门用来评估基于年度上下文的地表温度预测能力。
Results. As illustrated in Figure 3, increasing the context length generally leads to improved prediction accuracy across univariate datasets. While previous state-of-the-art models like Timer-XL show promising results, they tend to encounter performance saturation or even deterioration in excessively long contexts (e.g., monthly and yearly levels), likely due to the accumulation of noise. In contrast, our proposed StreamTimer exhibits superior robustness. As shown in the curves, StreamTimer consistently outperforms Timer-XL and DLinear, particularly achieving lower MSE in the longest lookback settings across all datasets. This indicates that StreamTimer effectively mitigates the impact of irrelevant history while capturing critical long-term dependencies. A similar conclusion can be drawn from the ERA5-S benchmark (Table 1), where StreamTimer surpasses both PatchTST and Timer-XL on all sites, demonstrating its efficacy in handling complex meteorological data with extended contexts.
结果。 如图 3 所示,加长上下文通常会提高各单变量数据集上的预测精度。Timer-XL 这类先前的先进模型虽然表现可观,但在过长的上下文(例如月、年尺度)上往往出现性能饱和甚至变差,这很可能是噪声累积所致。相比之下,我们提出的 StreamTimer 更为稳健。曲线显示,它持续优于 Timer-XL 和 DLinear,尤其在各数据集最长回看设置上获得更低的 MSE。这说明 StreamTimer 在捕捉关键长期依赖的同时,有效减弱了无关历史的影响。ERA5-S 基准(表 1)也得出类似结论:StreamTimer 在所有站点上都超过 PatchTST 和 Timer-XL,表明它能在更长上下文下处理复杂气象数据。
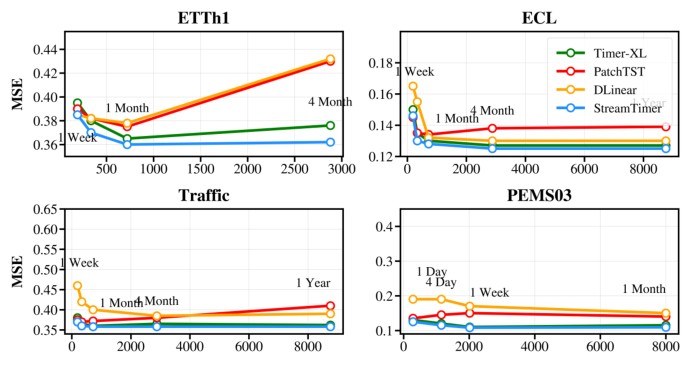
Figure 3: Univariate forecasting performance (pred-96) on established benchmarks under channel independence, with lookback lengths extended to monthly and yearly scales.
图 3:在已有基准上按通道独立设定做单变量预测(预测步长 96),回看长度延伸到月、年尺度。
Revisiting Non-stationary Forecasting. We delve into the widespread non-stationarity in univariate tasks. While normalization techniques like RevIN [Kim et al., 2021] generally benefit Transformer performance by aligning statistical distributions, their limitations become pronounced in ultra-long contexts. We argue that standard normalization oversimplifies the time-varying statistics inherent in long history. Specifically, as the context length increases, both the internal distribution shifts within the input and the statistical discrepancy between input and output are significantly exacerbated. Forcing such complex sequences into a unified distribution constrains the model capacity of Transformers. The model is compelled to handle these distorted distributions rather than learning distinct temporal variations, leading to side effects such as mode collapse and oversmoothed predictions. In contrast, our proposed normalization optimizes the distributional properties, thereby liberating the model's capacity to focus on the forecasting task itself rather than struggling with distribution alignment. As evidenced in Table 1, this approach allows Timer-XL and Timer to achieve superior results on ERA5-S without the pitfalls of standard normalization.
再看非平稳预测。 我们进一步讨论单变量任务中普遍存在的非平稳性。RevIN [Kim et al., 2021] 这类归一化技术虽然通常能通过对齐统计分布来帮助 Transformer,但其局限在超长上下文中会变得明显。我们认为,标准归一化过分简化了长历史中随时间变化的统计量。具体来说,随着上下文变长,输入内部的分布偏移以及输入与输出之间的统计差异都会显著加剧。把如此复杂的序列强行纳入统一分布,会束缚 Transformer 的模型容量。模型不得不去应付被扭曲的分布,而不是学习彼此不同的时间变化,进而出现模式坍缩和过度平滑的预测等副作用。相比之下,我们提出的归一化优化了分布特性,从而把模型容量解放出来,使其专注于预测任务本身,而不必疲于对齐分布。如表 1 所示,这一做法使 Timer-XL 和 Timer 能在 ERA5-S 上取得更好结果,并避开标准归一化的那些陷阱。
Table 1: Univariate forecasting (input-3072-pred-96) of ERA5-S, encompassing 117k time points in each station (40-years). We compare the original Timer and Timer-XL with versions using standard normalization (+ RevIN) and our proposed normalization (+ Ours).
| Station | Beijing | Hongkong | London | New York | Paris | Seoul | Shanghai | Average | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Model | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE |
| Timer | 0.076 | 0.212 | 0.189 | 0.321 | 0.277 | 0.414 | 0.185 | 0.332 | 0.262 | 0.413 | 0.090 | 0.227 | 0.136 | 0.285 | 0.174 | 0.315 |
| + RevIN | 0.076 | 0.211 | 0.192 | 0.324 | 0.277 | 0.415 | 0.187 | 0.334 | 0.268 | 0.409 | 0.090 | 0.227 | 0.137 | 0.285 | 0.175 | 0.315 |
| + Ours | 0.073 | 0.208 | 0.181 | 0.315 | 0.269 | 0.409 | 0.182 | 0.330 | 0.261 | 0.408 | 0.087 | 0.224 | 0.130 | 0.278 | 0.169 | 0.310 |
| Timer-XL | 0.074 | 0.210 | 0.179 | 0.316 | 0.262 | 0.404 | 0.182 | 0.327 | 0.254 | 0.399 | 0.090 | 0.229 | 0.134 | 0.282 | 0.168 | 0.310 |
| + RevIN | 0.074 | 0.210 | 0.183 | 0.317 | 0.278 | 0.418 | 0.181 | 0.330 | 0.264 | 0.407 | 0.090 | 0.227 | 0.133 | 0.281 | 0.172 | 0.313 |
| + Ours | 0.073 | 0.208 | 0.173 | 0.312 | 0.260 | 0.403 | 0.180 | 0.317 | 0.251 | 0.396 | 0.088 | 0.224 | 0.130 | 0.279 | 0.165 | 0.306 |
表 1:ERA5-S 上的单变量预测(输入 3072、预测 96),每个站点约有 11.7 万个时间点(40 年)。我们比较原始的 Timer 和 Timer-XL,以及使用标准归一化(+ RevIN)和我们提出的归一化(+ Ours)的版本。加粗为最优(原文以蓝色标注)。
| 站点 | Beijing | Hongkong | London | New York | Paris | Seoul | Shanghai | 平均 | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 模型 | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE |
| Timer | 0.076 | 0.212 | 0.189 | 0.321 | 0.277 | 0.414 | 0.185 | 0.332 | 0.262 | 0.413 | 0.090 | 0.227 | 0.136 | 0.285 | 0.174 | 0.315 |
| + RevIN | 0.076 | 0.211 | 0.192 | 0.324 | 0.277 | 0.415 | 0.187 | 0.334 | 0.268 | 0.409 | 0.090 | 0.227 | 0.137 | 0.285 | 0.175 | 0.315 |
| + Ours | 0.073 | 0.208 | 0.181 | 0.315 | 0.269 | 0.409 | 0.182 | 0.330 | 0.261 | 0.408 | 0.087 | 0.224 | 0.130 | 0.278 | 0.169 | 0.310 |
| Timer-XL | 0.074 | 0.210 | 0.179 | 0.316 | 0.262 | 0.404 | 0.182 | 0.327 | 0.254 | 0.399 | 0.090 | 0.229 | 0.134 | 0.282 | 0.168 | 0.310 |
| + RevIN | 0.074 | 0.210 | 0.183 | 0.317 | 0.278 | 0.418 | 0.181 | 0.330 | 0.264 | 0.407 | 0.090 | 0.227 | 0.133 | 0.281 | 0.172 | 0.313 |
| + Ours | 0.073 | 0.208 | 0.173 | 0.312 | 0.260 | 0.403 | 0.180 | 0.317 | 0.251 | 0.396 | 0.088 | 0.224 | 0.130 | 0.279 | 0.165 | 0.306 |
4.2 Multivariate Time Series Forecasting
4.2 多变量时间序列预测
Setups. Following the experimental protocols of Timer-XL [Liu et al., 2024b], we evaluate multivariate forecasting performance. To advance the development of generated transformers, we focus on the rolling forecast setting, where a single trained model adapts to various prediction horizons by recursively integrating previous predictions into the lookback window for the next iteration. Furthermore, we establish a long-context multivariate benchmark, the ERA5 multi-station land-surface temperature prediction (ERA5-MS). This benchmark is designed to facilitate the learning of complex temporal dynamics and inter-variable correlations with sufficient training samples.
实验设置。 我们沿用 Timer-XL [Liu et al., 2024b] 的实验协议,评估多变量预测性能。为推进生成式 Transformer 的发展,我们聚焦滚动预测设定:同一个训练好的模型,通过把先前预测递归并入下一轮的回看窗口,来适应不同的预测视野。此外,我们建立长上下文多变量基准 ERA5 多站点地表温度预测(ERA5-MS)。该基准旨在在训练样本充足的条件下,帮助学习复杂的时间动态和变量之间的相关。
Results. As shown in Table 2, StreamTimer achieves the best results on the established benchmarks. Our comparison focuses primarily on its predecessors, Timer and Timer-XL.
结果。 如表 2 所示,StreamTimer 在已有基准上取得最好结果。比较主要针对它的前身 Timer 和 Timer-XL。
Table 2: Multivariate forecasting results: we conduct rolling forecast with a single model trained on each dataset. Lookback length is 672, and forecast lengths are in {96, 192, 336, 720}. Blue: the best, underline: the second best.
| Dataset | Horizon | StreamTimer (Ours) | Timer-XL (2025) | Timer (2024) | UniTST (2024) | iTransformer (2023) | DLinear (2023) | PatchTST (2022) | TimesNet (2022) | Stationary (2022) | Autoformer (2011) | ||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | ||
| ETTh1 | 96 | 0.347 | 0.387 | 0.364 | 0.397 | 0.371 | 0.404 | 0.379 | 0.415 | 0.387 | 0.418 | 0.369 | 0.400 | 0.373 | 0.403 | 0.452 | 0.463 | 0.452 | 0.478 | 0.467 | 0.499 |
| ETTh1 | 192 | 0.376 | 0.407 | 0.405 | 0.424 | 0.407 | 0.429 | 0.415 | 0.438 | 0.416 | 0.437 | 0.405 | 0.422 | 0.405 | 0.425 | 0.474 | 0.477 | 0.484 | 0.510 | 0.492 | 0.523 |
| 336 | 0.389 | 0.417 | 0.427 | 0.439 | 0.434 | 0.445 | 0.440 | 0.454 | 0.434 | 0.450 | 0.435 | 0.445 | 0.423 | 0.440 | 0.493 | 0.489 | 0.511 | 0.522 | 0.519 | 0.531 | |
| 720 | 0.399 | 0.434 | 0.439 | 0.459 | 0.461 | 0.466 | 0.482 | 0.482 | 0.447 | 0.473 | 0.493 | 0.508 | 0.445 | 0.471 | 0.560 | 0.534 | 0.571 | 0.543 | 0.589 | 0.560 | |
| Avg | 0.378 | 0.411 | 0.409 | 0.430 | 0.418 | 0.436 | 0.429 | 0.447 | 0.421 | 0.445 | 0.426 | 0.444 | 0.412 | 0.435 | 0.495 | 0.491 | 0.505 | 0.513 | 0.517 | 0.528 | |
| ETTh2 | 96 | 0.275 | 0.339 | 0.277 | 0.343 | 0.285 | 0.344 | 0.343 | 0.398 | 0.304 | 0.362 | 0.305 | 0.371 | 0.289 | 0.347 | 0.340 | 0.374 | 0.348 | 0.403 | 0.358 | 0.397 |
| ETTh2 | 192 | 0.336 | 0.376 | 0.348 | 0.391 | 0.365 | 0.400 | 0.376 | 0.420 | 0.372 | 0.407 | 0.412 | 0.439 | 0.360 | 0.393 | 0.402 | 0.414 | 0.408 | 0.448 | 0.435 | 0.451 |
| 336 | 0.356 | 0.407 | 0.375 | 0.418 | 0.412 | 0.440 | 0.399 | 0.435 | 0.418 | 0.440 | 0.527 | 0.508 | 0.389 | 0.420 | 0.452 | 0.452 | 0.424 | 0.457 | 0.454 | 0.475 | |
| 720 | 0.401 | 0.445 | 0.409 | 0.458 | 0.468 | 0.487 | 0.419 | 0.457 | 0.463 | 0.476 | 0.830 | 0.653 | 0.398 | 0.440 | 0.462 | 0.468 | 0.448 | 0.476 | 0.479 | 0.492 | |
| Avg | 0.342 | 0.392 | 0.352 | 0.402 | 0.382 | 0.418 | 0.384 | 0.428 | 0.389 | 0.421 | 0.518 | 0.493 | 0.359 | 0.400 | 0.414 | 0.427 | 0.407 | 0.446 | 0.431 | 0.454 | |
| ETTm1 | 96 | 0.275 | 0.335 | 0.290 | 0.341 | 0.281 | 0.338 | 0.289 | 0.348 | 0.311 | 0.365 | 0.307 | 0.350 | 0.285 | 0.346 | 0.338 | 0.375 | 0.414 | 0.414 | 0.466 | 0.466 |
| ETTm1 | 192 | 0.322 | 0.365 | 0.337 | 0.369 | 0.330 | 0.368 | 0.332 | 0.375 | 0.353 | 0.390 | 0.337 | 0.368 | 0.329 | 0.372 | 0.371 | 0.387 | 0.524 | 0.482 | 0.504 | 0.496 |
| 336 | 0.358 | 0.388 | 0.374 | 0.392 | 0.367 | 0.393 | 0.365 | 0.397 | 0.387 | 0.411 | 0.366 | 0.387 | 0.363 | 0.394 | 0.410 | 0.411 | 0.541 | 0.497 | 0.574 | 0.530 | |
| 720 | 0.416 | 0.422 | 0.437 | 0.428 | 0.432 | 0.433 | 0.421 | 0.431 | 0.452 | 0.445 | 0.419 | 0.419 | 0.421 | 0.426 | 0.478 | 0.450 | 0.578 | 0.509 | 0.596 | 0.558 | |
| Avg | 0.343 | 0.378 | 0.359 | 0.382 | 0.352 | 0.383 | 0.352 | 0.388 | 0.376 | 0.403 | 0.357 | 0.381 | 0.349 | 0.385 | 0.399 | 0.406 | 0.514 | 0.475 | 0.535 | 0.512 | |
| ETTm2 | 96 | 0.166 | 0.256 | 0.175 | 0.257 | 0.175 | 0.257 | 0.171 | 0.260 | 0.183 | 0.272 | 0.167 | 0.263 | 0.172 | 0.259 | 0.187 | 0.267 | 0.237 | 0.306 | 0.255 | 0.339 |
| ETTm2 | 192 | 0.228 | 0.288 | 0.242 | 0.301 | 0.239 | 0.301 | 0.228 | 0.230 | 0.250 | 0.315 | 0.230 | 0.311 | 0.233 | 0.299 | 0.249 | 0.309 | 0.330 | 0.387 | 0.279 | 0.335 |
| 336 | 0.283 | 0.330 | 0.293 | 0.337 | 0.293 | 0.342 | 0.282 | 0.336 | 0.311 | 0.356 | 0.298 | 0.361 | 0.280 | 0.331 | 0.321 | 0.351 | 0.404 | 0.424 | 0.331 | 0.374 | |
| 720 | 0.368 | 0.387 | 0.376 | 0.390 | 0.392 | 0.407 | 0.380 | 0.398 | 0.417 | 0.419 | 0.432 | 0.446 | 0.357 | 0.382 | 0.497 | 0.403 | 0.525 | 0.486 | 0.413 | 0.450 | |
| Avg | 0.261 | 0.315 | 0.271 | 0.322 | 0.275 | 0.327 | 0.265 | 0.306 | 0.290 | 0.340 | 0.282 | 0.345 | 0.261 | 0.318 | 0.314 | 0.333 | 0.374 | 0.401 | 0.320 | 0.374 | |
| 96 | 0.125 | 0.218 | 0.127 | 0.219 | 0.129 | 0.221 | 0.130 | 0.225 | 0.133 | 0.229 | 0.138 | 0.238 | 0.132 | 0.232 | 0.184 | 0.288 | 0.185 | 0.287 | 0.256 | 0.357 | |
| 192 | 0.141 | 0.233 | 0.145 | 0.236 | 0.148 | 0.239 | 0.150 | 0.244 | 0.158 | 0.258 | 0.152 | 0.251 | 0.151 | 0.250 | 0.192 | 0.295 | 0.282 | 0.368 | 0.291 | 0.376 | |
| ECL | 336 | 0.152 | 0.246 | 0.159 | 0.252 | 0.164 | 0.256 | 0.166 | 0.262 | 0.168 | 0.262 | 0.167 | 0.268 | 0.171 | 0.272 | 0.200 | 0.303 | 0.289 | 0.377 | 0.290 | 0.379 |
| 720 | 0.177 | 0.270 | 0.187 | 0.277 | 0.201 | 0.289 | 0.206 | 0.297 | 0.205 | 0.294 | 0.203 | 0.302 | 0.222 | 0.318 | 0.228 | 0.325 | 0.305 | 0.399 | 0.320 | 0.403 | |
| Avg | 0.149 | 0.242 | 0.155 | 0.246 | 0.161 | 0.251 | 0.163 | 0.257 | 0.164 | 0.258 | 0.165 | 0.265 | 0.169 | 0.268 | 0.201 | 0.303 | 0.265 | 0.358 | 0.289 | 0.379 | |
| Traffic | 96 | 0.341 | 0.236 | 0.340 | 0.238 | 0.348 | 0.240 | 0.359 | 0.250 | 0.353 | 0.259 | 0.399 | 0.285 | 0.359 | 0.255 | 0.593 | 0.315 | 0.610 | 0.322 | 0.675 | 0.412 |
| Traffic | 192 | 0.358 | 0.241 | 0.360 | 0.247 | 0.369 | 0.250 | 0.373 | 0.257 | 0.373 | 0.267 | 0.409 | 0.290 | 0.377 | 0.265 | 0.596 | 0.317 | 0.626 | 0.346 | 0.679 | 0.423 |
| 336 | 0.374 | 0.251 | 0.377 | 0.256 | 0.388 | 0.260 | 0.386 | 0.265 | 0.386 | 0.275 | 0.422 | 0.297 | 0.393 | 0.276 | 0.600 | 0.319 | 0.633 | 0.352 | 0.688 | 0.440 | |
| 720 | 0.412 | 0.275 | 0.418 | 0.279 | 0.431 | 0.285 | 0.421 | 0.286 | 0.425 | 0.296 | 0.461 | 0.319 | 0.436 | 0.305 | 0.619 | 0.335 | 0.651 | 0.366 | 0.693 | 0.457 | |
| Avg | 0.371 | 0.251 | 0.374 | 0.255 | 0.384 | 0.259 | 0.385 | 0.265 | 0.385 | 0.274 | 0.423 | 0.298 | 0.391 | 0.275 | 0.602 | 0.322 | 0.630 | 0.347 | 0.684 | 0.433 | |
| Weather | 96 | 0.148 | 0.200 | 0.157 | 0.205 | 0.151 | 0.202 | 0.152 | 0.206 | 0.174 | 0.225 | 0.169 | 0.229 | 0.149 | 0.202 | 0.169 | 0.228 | 0.185 | 0.241 | 0.355 | 0.409 |
| Weather | 192 | 0.191 | 0.238 | 0.206 | 0.250 | 0.196 | 0.245 | 0.198 | 0.249 | 0.227 | 0.268 | 0.211 | 0.268 | 0.194 | 0.245 | 0.222 | 0.269 | 0.286 | 0.325 | 0.421 | 0.450 |
| 336 | 0.241 | 0.279 | 0.259 | 0.291 | 0.249 | 0.288 | 0.251 | 0.291 | 0.290 | 0.309 | 0.258 | 0.306 | 0.244 | 0.285 | 0.290 | 0.310 | 0.323 | 0.347 | 0.452 | 0.465 | |
| 720 | 0.311 | 0.335 | 0.337 | 0.344 | 0.330 | 0.344 | 0.322 | 0.340 | 0.374 | 0.360 | 0.320 | 0.362 | 0.317 | 0.329 | 0.376 | 0.364 | 0.436 | 0.401 | 0.513 | 0.496 | |
| Avg | 0.223 | 0.263 | 0.240 | 0.273 | 0.232 | 0.270 | 0.231 | 0.272 | 0.266 | 0.291 | 0.239 | 0.291 | 0.226 | 0.268 | 0.264 | 0.293 | 0.308 | 0.329 | 0.435 | 0.455 | |
| Solar-Energy | 96 | 0.159 | 0.216 | 0.162 | 0.221 | 0.212 | 0.230 | 0.190 | 0.240 | 0.183 | 0.265 | 0.193 | 0.258 | 0.168 | 0.237 | 0.180 | 0.272 | 0.199 | 0.290 | 0.206 | 0.296 |
| 192 | 0.183 | 0.236 | 0.187 | 0.239 | 0.232 | 0.246 | 0.223 | 0.264 | 0.205 | 0.283 | 0.214 | 0.274 | 0.189 | 0.257 | 0.199 | 0.286 | 0.243 | 0.307 | 0.254 | 0.328 | |
| 336 | 0.203 | 0.251 | 0.205 | 0.255 | 0.237 | 0.253 | 0.250 | 0.283 | 0.224 | 0.299 | 0.233 | 0.291 | 0.212 | 0.277 | 0.220 | 0.301 | 0.264 | 0.322 | 0.272 | 0.330 | |
| 720 | 0.233 | 0.276 | 0.238 | 0.279 | 0.252 | 0.266 | 0.292 | 0.311 | 0.239 | 0.316 | 0.246 | 0.307 | 0.240 | 0.305 | 0.251 | 0.321 | 0.310 | 0.339 | 0.326 | 0.347 | |
| Avg | 0.195 | 0.245 | 0.198 | 0.249 | 0.233 | 0.249 | 0.241 | 0.275 | 0.213 | 0.291 | 0.222 | 0.283 | 0.202 | 0.269 | 0.213 | 0.295 | 0.254 | 0.315 | 0.265 | 0.325 | |
| 1st Count | 36 | 33 | 1 | 0 | 0 | 1 | 0 | 2 | 0 | 0 | 0 | 1 | 3 | 3 | 0 | 0 | 0 | 0 | 0 | 0 |
表 2:多变量预测结果:我们在每个数据集上训练单个模型,做滚动预测。回看长度为 672,预测长度取 {96, 192, 336, 720}。加粗为最优(原文以蓝色标注),次优在原文以下划线标出,表中数值仍按原文抄录。
| 数据集 | 预测步长 | StreamTimer (Ours) | Timer-XL (2025) | Timer (2024) | UniTST (2024) | iTransformer (2023) | DLinear (2023) | PatchTST (2022) | TimesNet (2022) | Stationary (2022) | Autoformer (2011) | ||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | ||
| ETTh1 | 96 | 0.347 | 0.387 | 0.364 | 0.397 | 0.371 | 0.404 | 0.379 | 0.415 | 0.387 | 0.418 | 0.369 | 0.400 | 0.373 | 0.403 | 0.452 | 0.463 | 0.452 | 0.478 | 0.467 | 0.499 |
| ETTh1 | 192 | 0.376 | 0.407 | 0.405 | 0.424 | 0.407 | 0.429 | 0.415 | 0.438 | 0.416 | 0.437 | 0.405 | 0.422 | 0.405 | 0.425 | 0.474 | 0.477 | 0.484 | 0.510 | 0.492 | 0.523 |
| 336 | 0.389 | 0.417 | 0.427 | 0.439 | 0.434 | 0.445 | 0.440 | 0.454 | 0.434 | 0.450 | 0.435 | 0.445 | 0.423 | 0.440 | 0.493 | 0.489 | 0.511 | 0.522 | 0.519 | 0.531 | |
| 720 | 0.399 | 0.434 | 0.439 | 0.459 | 0.461 | 0.466 | 0.482 | 0.482 | 0.447 | 0.473 | 0.493 | 0.508 | 0.445 | 0.471 | 0.560 | 0.534 | 0.571 | 0.543 | 0.589 | 0.560 | |
| Avg | 0.378 | 0.411 | 0.409 | 0.430 | 0.418 | 0.436 | 0.429 | 0.447 | 0.421 | 0.445 | 0.426 | 0.444 | 0.412 | 0.435 | 0.495 | 0.491 | 0.505 | 0.513 | 0.517 | 0.528 | |
| ETTh2 | 96 | 0.275 | 0.339 | 0.277 | 0.343 | 0.285 | 0.344 | 0.343 | 0.398 | 0.304 | 0.362 | 0.305 | 0.371 | 0.289 | 0.347 | 0.340 | 0.374 | 0.348 | 0.403 | 0.358 | 0.397 |
| ETTh2 | 192 | 0.336 | 0.376 | 0.348 | 0.391 | 0.365 | 0.400 | 0.376 | 0.420 | 0.372 | 0.407 | 0.412 | 0.439 | 0.360 | 0.393 | 0.402 | 0.414 | 0.408 | 0.448 | 0.435 | 0.451 |
| 336 | 0.356 | 0.407 | 0.375 | 0.418 | 0.412 | 0.440 | 0.399 | 0.435 | 0.418 | 0.440 | 0.527 | 0.508 | 0.389 | 0.420 | 0.452 | 0.452 | 0.424 | 0.457 | 0.454 | 0.475 | |
| 720 | 0.401 | 0.445 | 0.409 | 0.458 | 0.468 | 0.487 | 0.419 | 0.457 | 0.463 | 0.476 | 0.830 | 0.653 | 0.398 | 0.440 | 0.462 | 0.468 | 0.448 | 0.476 | 0.479 | 0.492 | |
| Avg | 0.342 | 0.392 | 0.352 | 0.402 | 0.382 | 0.418 | 0.384 | 0.428 | 0.389 | 0.421 | 0.518 | 0.493 | 0.359 | 0.400 | 0.414 | 0.427 | 0.407 | 0.446 | 0.431 | 0.454 | |
| ETTm1 | 96 | 0.275 | 0.335 | 0.290 | 0.341 | 0.281 | 0.338 | 0.289 | 0.348 | 0.311 | 0.365 | 0.307 | 0.350 | 0.285 | 0.346 | 0.338 | 0.375 | 0.414 | 0.414 | 0.466 | 0.466 |
| ETTm1 | 192 | 0.322 | 0.365 | 0.337 | 0.369 | 0.330 | 0.368 | 0.332 | 0.375 | 0.353 | 0.390 | 0.337 | 0.368 | 0.329 | 0.372 | 0.371 | 0.387 | 0.524 | 0.482 | 0.504 | 0.496 |
| 336 | 0.358 | 0.388 | 0.374 | 0.392 | 0.367 | 0.393 | 0.365 | 0.397 | 0.387 | 0.411 | 0.366 | 0.387 | 0.363 | 0.394 | 0.410 | 0.411 | 0.541 | 0.497 | 0.574 | 0.530 | |
| 720 | 0.416 | 0.422 | 0.437 | 0.428 | 0.432 | 0.433 | 0.421 | 0.431 | 0.452 | 0.445 | 0.419 | 0.419 | 0.421 | 0.426 | 0.478 | 0.450 | 0.578 | 0.509 | 0.596 | 0.558 | |
| Avg | 0.343 | 0.378 | 0.359 | 0.382 | 0.352 | 0.383 | 0.352 | 0.388 | 0.376 | 0.403 | 0.357 | 0.381 | 0.349 | 0.385 | 0.399 | 0.406 | 0.514 | 0.475 | 0.535 | 0.512 | |
| ETTm2 | 96 | 0.166 | 0.256 | 0.175 | 0.257 | 0.175 | 0.257 | 0.171 | 0.260 | 0.183 | 0.272 | 0.167 | 0.263 | 0.172 | 0.259 | 0.187 | 0.267 | 0.237 | 0.306 | 0.255 | 0.339 |
| ETTm2 | 192 | 0.228 | 0.288 | 0.242 | 0.301 | 0.239 | 0.301 | 0.228 | 0.230 | 0.250 | 0.315 | 0.230 | 0.311 | 0.233 | 0.299 | 0.249 | 0.309 | 0.330 | 0.387 | 0.279 | 0.335 |
| 336 | 0.283 | 0.330 | 0.293 | 0.337 | 0.293 | 0.342 | 0.282 | 0.336 | 0.311 | 0.356 | 0.298 | 0.361 | 0.280 | 0.331 | 0.321 | 0.351 | 0.404 | 0.424 | 0.331 | 0.374 | |
| 720 | 0.368 | 0.387 | 0.376 | 0.390 | 0.392 | 0.407 | 0.380 | 0.398 | 0.417 | 0.419 | 0.432 | 0.446 | 0.357 | 0.382 | 0.497 | 0.403 | 0.525 | 0.486 | 0.413 | 0.450 | |
| Avg | 0.261 | 0.315 | 0.271 | 0.322 | 0.275 | 0.327 | 0.265 | 0.306 | 0.290 | 0.340 | 0.282 | 0.345 | 0.261 | 0.318 | 0.314 | 0.333 | 0.374 | 0.401 | 0.320 | 0.374 | |
| 96 | 0.125 | 0.218 | 0.127 | 0.219 | 0.129 | 0.221 | 0.130 | 0.225 | 0.133 | 0.229 | 0.138 | 0.238 | 0.132 | 0.232 | 0.184 | 0.288 | 0.185 | 0.287 | 0.256 | 0.357 | |
| 192 | 0.141 | 0.233 | 0.145 | 0.236 | 0.148 | 0.239 | 0.150 | 0.244 | 0.158 | 0.258 | 0.152 | 0.251 | 0.151 | 0.250 | 0.192 | 0.295 | 0.282 | 0.368 | 0.291 | 0.376 | |
| ECL | 336 | 0.152 | 0.246 | 0.159 | 0.252 | 0.164 | 0.256 | 0.166 | 0.262 | 0.168 | 0.262 | 0.167 | 0.268 | 0.171 | 0.272 | 0.200 | 0.303 | 0.289 | 0.377 | 0.290 | 0.379 |
| 720 | 0.177 | 0.270 | 0.187 | 0.277 | 0.201 | 0.289 | 0.206 | 0.297 | 0.205 | 0.294 | 0.203 | 0.302 | 0.222 | 0.318 | 0.228 | 0.325 | 0.305 | 0.399 | 0.320 | 0.403 | |
| Avg | 0.149 | 0.242 | 0.155 | 0.246 | 0.161 | 0.251 | 0.163 | 0.257 | 0.164 | 0.258 | 0.165 | 0.265 | 0.169 | 0.268 | 0.201 | 0.303 | 0.265 | 0.358 | 0.289 | 0.379 | |
| Traffic | 96 | 0.341 | 0.236 | 0.340 | 0.238 | 0.348 | 0.240 | 0.359 | 0.250 | 0.353 | 0.259 | 0.399 | 0.285 | 0.359 | 0.255 | 0.593 | 0.315 | 0.610 | 0.322 | 0.675 | 0.412 |
| Traffic | 192 | 0.358 | 0.241 | 0.360 | 0.247 | 0.369 | 0.250 | 0.373 | 0.257 | 0.373 | 0.267 | 0.409 | 0.290 | 0.377 | 0.265 | 0.596 | 0.317 | 0.626 | 0.346 | 0.679 | 0.423 |
| 336 | 0.374 | 0.251 | 0.377 | 0.256 | 0.388 | 0.260 | 0.386 | 0.265 | 0.386 | 0.275 | 0.422 | 0.297 | 0.393 | 0.276 | 0.600 | 0.319 | 0.633 | 0.352 | 0.688 | 0.440 | |
| 720 | 0.412 | 0.275 | 0.418 | 0.279 | 0.431 | 0.285 | 0.421 | 0.286 | 0.425 | 0.296 | 0.461 | 0.319 | 0.436 | 0.305 | 0.619 | 0.335 | 0.651 | 0.366 | 0.693 | 0.457 | |
| Avg | 0.371 | 0.251 | 0.374 | 0.255 | 0.384 | 0.259 | 0.385 | 0.265 | 0.385 | 0.274 | 0.423 | 0.298 | 0.391 | 0.275 | 0.602 | 0.322 | 0.630 | 0.347 | 0.684 | 0.433 | |
| Weather | 96 | 0.148 | 0.200 | 0.157 | 0.205 | 0.151 | 0.202 | 0.152 | 0.206 | 0.174 | 0.225 | 0.169 | 0.229 | 0.149 | 0.202 | 0.169 | 0.228 | 0.185 | 0.241 | 0.355 | 0.409 |
| Weather | 192 | 0.191 | 0.238 | 0.206 | 0.250 | 0.196 | 0.245 | 0.198 | 0.249 | 0.227 | 0.268 | 0.211 | 0.268 | 0.194 | 0.245 | 0.222 | 0.269 | 0.286 | 0.325 | 0.421 | 0.450 |
| 336 | 0.241 | 0.279 | 0.259 | 0.291 | 0.249 | 0.288 | 0.251 | 0.291 | 0.290 | 0.309 | 0.258 | 0.306 | 0.244 | 0.285 | 0.290 | 0.310 | 0.323 | 0.347 | 0.452 | 0.465 | |
| 720 | 0.311 | 0.335 | 0.337 | 0.344 | 0.330 | 0.344 | 0.322 | 0.340 | 0.374 | 0.360 | 0.320 | 0.362 | 0.317 | 0.329 | 0.376 | 0.364 | 0.436 | 0.401 | 0.513 | 0.496 | |
| Avg | 0.223 | 0.263 | 0.240 | 0.273 | 0.232 | 0.270 | 0.231 | 0.272 | 0.266 | 0.291 | 0.239 | 0.291 | 0.226 | 0.268 | 0.264 | 0.293 | 0.308 | 0.329 | 0.435 | 0.455 | |
| Solar-Energy | 96 | 0.159 | 0.216 | 0.162 | 0.221 | 0.212 | 0.230 | 0.190 | 0.240 | 0.183 | 0.265 | 0.193 | 0.258 | 0.168 | 0.237 | 0.180 | 0.272 | 0.199 | 0.290 | 0.206 | 0.296 |
| 192 | 0.183 | 0.236 | 0.187 | 0.239 | 0.232 | 0.246 | 0.223 | 0.264 | 0.205 | 0.283 | 0.214 | 0.274 | 0.189 | 0.257 | 0.199 | 0.286 | 0.243 | 0.307 | 0.254 | 0.328 | |
| 336 | 0.203 | 0.251 | 0.205 | 0.255 | 0.237 | 0.253 | 0.250 | 0.283 | 0.224 | 0.299 | 0.233 | 0.291 | 0.212 | 0.277 | 0.220 | 0.301 | 0.264 | 0.322 | 0.272 | 0.330 | |
| 720 | 0.233 | 0.276 | 0.238 | 0.279 | 0.252 | 0.266 | 0.292 | 0.311 | 0.239 | 0.316 | 0.246 | 0.307 | 0.240 | 0.305 | 0.251 | 0.321 | 0.310 | 0.339 | 0.326 | 0.347 | |
| Avg | 0.195 | 0.245 | 0.198 | 0.249 | 0.233 | 0.249 | 0.241 | 0.275 | 0.213 | 0.291 | 0.222 | 0.283 | 0.202 | 0.269 | 0.213 | 0.295 | 0.254 | 0.315 | 0.265 | 0.325 | |
| 最优次数 | 36 | 33 | 1 | 0 | 0 | 1 | 0 | 2 | 0 | 0 | 0 | 1 | 3 | 3 | 0 | 0 | 0 | 0 | 0 | 0 |
While Timer-XL already demonstrates strong capabilities over Timer by leveraging extended contexts, StreamTimer pushes the performance boundary even further. It is particularly noteworthy that StreamTimer significantly outperforms Timer-XL, especially on non-stationary time series (improving by 8.2% in ETTh1). We attribute this substantial improvement over Timer-XL to two key innovations: first, our proposed normalization effectively resolves the distribution shift issues that hinder Timer-XL in ultra-long contexts; second, the streaming forecasting mechanism enhances stability during continuous inference. Furthermore, we find StreamTimer achieves 69 wins out of 80 tests under different metrics and conditions, and maintains strong performance even on low-dimensional datasets with low predictability (e.g., ETT), underscoring its effectiveness and superiority.
Timer-XL 已经通过利用更长上下文,相对 Timer 展现出更强的能力,而 StreamTimer 把性能边界又往前推了一步。尤其值得注意的是,它显著优于 Timer-XL,在非平稳时间序列上更为明显(在 ETTh1 上改进 8.2%)。我们认为,相对 Timer-XL 的这一明显改进来自两项关键创新:第一,我们提出的归一化有效解决了 Timer-XL 在超长上下文中受到的分布偏移问题;第二,流式预测机制增强了连续推理时的稳定性。此外,StreamTimer 在不同指标和条件下的 80 项测试中拿到 69 次最优,即使在可预测性较低的低维数据集(例如 ETT)上也保持了较强表现,进一步说明其有效性和优势。
Table 3: Multivariate forecasting (input-3072-pred-96) of ERA5-MS (40 years and 7 stations). We fairly evaluate Transformers that adopt patched time series. Different from ERA5-S, we train one model for all sites.
| Model | Beijing | Hongkong | London | New York | Paris | Seoul | Shanghai | Average | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | |
| PatchTST | 0.0815 | 0.222 | 0.190 | 0.326 | 0.275 | 0.414 | 0.185 | 0.333 | 0.265 | 0.407 | 0.0977 | 0.240 | 0.139 | 0.290 | 0.176 | 0.319 |
| UniTST | 0.0753 | 0.213 | 0.179 | 0.318 | 0.269 | 0.410 | 0.185 | 0.330 | 0.256 | 0.401 | 0.0901 | 0.230 | 0.135 | 0.284 | 0.170 | 0.312 |
| Timer | 0.0734 | 0.210 | 0.182 | 0.319 | 0.268 | 0.407 | 0.183 | 0.329 | 0.255 | 0.399 | 0.0877 | 0.226 | 0.132 | 0.281 | 0.169 | 0.310 |
| Timer-XL | 0.0736 | 0.209 | 0.174 | 0.309 | 0.263 | 0.404 | 0.182 | 0.327 | 0.252 | 0.396 | 0.0872 | 0.225 | 0.130 | 0.278 | 0.166 | 0.307 |
| StreamTimer | 0.0732 | 0.207 | 0.172 | 0.306 | 0.260 | 0.401 | 0.181 | 0.325 | 0.251 | 0.394 | 0.0868 | 0.223 | 0.130 | 0.277 | 0.165 | 0.304 |
表 3:ERA5-MS(40 年、7 个站点)上的多变量预测(输入 3072、预测 96)。我们公平评估采用 patched 时间序列的 Transformer。与 ERA5-S 不同,这里为所有站点训练同一个模型。加粗为最优。
| 模型 | Beijing | Hongkong | London | New York | Paris | Seoul | Shanghai | 平均 | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | |
| PatchTST | 0.0815 | 0.222 | 0.190 | 0.326 | 0.275 | 0.414 | 0.185 | 0.333 | 0.265 | 0.407 | 0.0977 | 0.240 | 0.139 | 0.290 | 0.176 | 0.319 |
| UniTST | 0.0753 | 0.213 | 0.179 | 0.318 | 0.269 | 0.410 | 0.185 | 0.330 | 0.256 | 0.401 | 0.0901 | 0.230 | 0.135 | 0.284 | 0.170 | 0.312 |
| Timer | 0.0734 | 0.210 | 0.182 | 0.319 | 0.268 | 0.407 | 0.183 | 0.329 | 0.255 | 0.399 | 0.0877 | 0.226 | 0.132 | 0.281 | 0.169 | 0.310 |
| Timer-XL | 0.0736 | 0.209 | 0.174 | 0.309 | 0.263 | 0.404 | 0.182 | 0.327 | 0.252 | 0.396 | 0.0872 | 0.225 | 0.130 | 0.278 | 0.166 | 0.307 |
| StreamTimer | 0.0732 | 0.207 | 0.172 | 0.306 | 0.260 | 0.401 | 0.181 | 0.325 | 0.251 | 0.394 | 0.0868 | 0.223 | 0.130 | 0.277 | 0.165 | 0.304 |
Table 4: Ablation study of different modules on Timer and Timer-XL. +RevIN columns contain the real baseline results from the main experiment. +SAN, Dish-TS, and +MPNorm denote adding the specific modules. +Ours denotes our normalization module.
| Timer | Timer-XL | ||||||||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Dataset | Horizon | +RevIN | +SAN | +Dish-TS | +MPNorm | +Ours | +RevIN | +SAN | +Dish-TS | +MPNorm | +Ours | ||||||||||
| MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | ||
| ETTh1 | 96 | 0.371 | 0.404 | 0.363 | 0.399 | 0.363 | 0.396 | 0.361 | 0.397 | 0.347 | 0.387 | 0.364 | 0.397 | 0.370 | 0.401 | 0.423 | 0.455 | 0.368 | 0.401 | 0.352 | 0.392 |
| 192 | 0.407 | 0.429 | 0.395 | 0.418 | 0.400 | 0.418 | 0.396 | 0.422 | 0.378 | 0.405 | 0.405 | 0.424 | 0.412 | 0.427 | 0.490 | 0.496 | 0.397 | 0.422 | 0.380 | 0.410 | |
| 336 | 0.434 | 0.445 | 0.416 | 0.430 | 0.425 | 0.435 | 0.411 | 0.426 | 0.392 | 0.421 | 0.427 | 0.439 | 0.444 | 0.447 | 0.542 | 0.529 | 0.422 | 0.445 | 0.393 | 0.421 | |
| 720 | 0.461 | 0.466 | 0.456 | 0.464 | 0.451 | 0.458 | 0.454 | 0.462 | 0.398 | 0.433 | 0.439 | 0.459 | 0.472 | 0.475 | 0.663 | 0.614 | 0.447 | 0.451 | 0.403 | 0.437 | |
| Avg | 0.418 | 0.436 | 0.407 | 0.428 | 0.410 | 0.427 | 0.405 | 0.427 | 0.382 | 0.416 | 0.409 | 0.430 | 0.424 | 0.438 | 0.530 | 0.523 | 0.409 | 0.430 | 0.382 | 0.415 | |
| Weather | 96 | 0.151 | 0.202 | 0.158 | 0.210 | 0.158 | 0.211 | 0.157 | 0.210 | 0.149 | 0.201 | 0.157 | 0.205 | 0.157 | 0.210 | 0.161 | 0.220 | 0.156 | 0.208 | 0.152 | 0.201 |
| 192 | 0.196 | 0.245 | 0.203 | 0.252 | 0.204 | 0.254 | 0.196 | 0.249 | 0.194 | 0.240 | 0.206 | 0.250 | 0.202 | 0.251 | 0.214 | 0.267 | 0.200 | 0.248 | 0.196 | 0.243 | |
| 336 | 0.249 | 0.288 | 0.250 | 0.289 | 0.257 | 0.294 | 0.248 | 0.286 | 0.244 | 0.287 | 0.259 | 0.291 | 0.248 | 0.288 | 0.270 | 0.311 | 0.247 | 0.286 | 0.245 | 0.281 | |
| 720 | 0.330 | 0.344 | 0.313 | 0.335 | 0.331 | 0.347 | 0.318 | 0.341 | 0.312 | 0.339 | 0.337 | 0.344 | 0.312 | 0.335 | 0.343 | 0.367 | 0.313 | 0.336 | 0.314 | 0.330 | |
| Avg | 0.232 | 0.270 | 0.231 | 0.271 | 0.237 | 0.276 | 0.230 | 0.271 | 0.225 | 0.267 | 0.240 | 0.272 | 0.230 | 0.271 | 0.247 | 0.291 | 0.229 | 0.270 | 0.227 | 0.264 |
表 4:在 Timer 和 Timer-XL 上对不同模块做消融。+RevIN 列给出主实验中的真实基线结果。+SAN、Dish-TS 和 +MPNorm 表示加入相应模块。+Ours 表示我们的归一化模块。加粗为最优。
| Timer | Timer-XL | ||||||||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 数据集 | 预测步长 | +RevIN | +SAN | +Dish-TS | +MPNorm | +Ours | +RevIN | +SAN | +Dish-TS | +MPNorm | +Ours | ||||||||||
| MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | ||
| ETTh1 | 96 | 0.371 | 0.404 | 0.363 | 0.399 | 0.363 | 0.396 | 0.361 | 0.397 | 0.347 | 0.387 | 0.364 | 0.397 | 0.370 | 0.401 | 0.423 | 0.455 | 0.368 | 0.401 | 0.352 | 0.392 |
| 192 | 0.407 | 0.429 | 0.395 | 0.418 | 0.400 | 0.418 | 0.396 | 0.422 | 0.378 | 0.405 | 0.405 | 0.424 | 0.412 | 0.427 | 0.490 | 0.496 | 0.397 | 0.422 | 0.380 | 0.410 | |
| 336 | 0.434 | 0.445 | 0.416 | 0.430 | 0.425 | 0.435 | 0.411 | 0.426 | 0.392 | 0.421 | 0.427 | 0.439 | 0.444 | 0.447 | 0.542 | 0.529 | 0.422 | 0.445 | 0.393 | 0.421 | |
| 720 | 0.461 | 0.466 | 0.456 | 0.464 | 0.451 | 0.458 | 0.454 | 0.462 | 0.398 | 0.433 | 0.439 | 0.459 | 0.472 | 0.475 | 0.663 | 0.614 | 0.447 | 0.451 | 0.403 | 0.437 | |
| Avg | 0.418 | 0.436 | 0.407 | 0.428 | 0.410 | 0.427 | 0.405 | 0.427 | 0.382 | 0.416 | 0.409 | 0.430 | 0.424 | 0.438 | 0.530 | 0.523 | 0.409 | 0.430 | 0.382 | 0.415 | |
| Weather | 96 | 0.151 | 0.202 | 0.158 | 0.210 | 0.158 | 0.211 | 0.157 | 0.210 | 0.149 | 0.201 | 0.157 | 0.205 | 0.157 | 0.210 | 0.161 | 0.220 | 0.156 | 0.208 | 0.152 | 0.201 |
| 192 | 0.196 | 0.245 | 0.203 | 0.252 | 0.204 | 0.254 | 0.196 | 0.249 | 0.194 | 0.240 | 0.206 | 0.250 | 0.202 | 0.251 | 0.214 | 0.267 | 0.200 | 0.248 | 0.196 | 0.243 | |
| 336 | 0.249 | 0.288 | 0.250 | 0.289 | 0.257 | 0.294 | 0.248 | 0.286 | 0.244 | 0.287 | 0.259 | 0.291 | 0.248 | 0.288 | 0.270 | 0.311 | 0.247 | 0.286 | 0.245 | 0.281 | |
| 720 | 0.330 | 0.344 | 0.313 | 0.335 | 0.331 | 0.347 | 0.318 | 0.341 | 0.312 | 0.339 | 0.337 | 0.344 | 0.312 | 0.335 | 0.343 | 0.367 | 0.313 | 0.336 | 0.314 | 0.330 | |
| Avg | 0.232 | 0.270 | 0.231 | 0.271 | 0.237 | 0.276 | 0.230 | 0.271 | 0.225 | 0.267 | 0.240 | 0.272 | 0.230 | 0.271 | 0.247 | 0.291 | 0.229 | 0.270 | 0.227 | 0.264 |
Performance on ERA5-MS. To evaluate the model's capability in multivariate time series forecasting, we conducted experiments on the real-world ERA5-MS benchmark as shown in Table 3. We compared StreamTimer with strong baselines ranging from channel-independent approaches PatchTST, UniTST to large-scale generative models Timer, Timer-XL. The results indicate that StreamTimer effectively combines the benefits of advanced tokenization and architectural design, surpassing the Timer-XL. By consistently achieving the best metrics in both MSE and MAE across diverse stations, StreamTimer proves to be the most effective solution for multivariate forecasting in this setting.
ERA5-MS 上的表现。 为评估模型在多变量时间序列预测中的能力,我们在真实世界基准 ERA5-MS 上做了实验,结果见表 3。比较对象既包括通道独立的 PatchTST、UniTST,也包括大规模生成模型 Timer、Timer-XL。结果表明,StreamTimer 有效结合了更先进的 tokenization 与架构设计的长处,超过了 Timer-XL。它在各站点的 MSE 和 MAE 上持续取得最好指标,成为这一设定下最有效的多变量预测方案。
Table 5: Zero-shot forecasting results. Bold indicates the best result, and underline indicates the second best.
| Task | StreamTimer | Timer-XL | Timer | PatchTST | ||||
|---|---|---|---|---|---|---|---|---|
| MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | |
| ETTh1 → ETTh2 | 0.345 | 0.388 | 0.367 | 0.398 | 0.354 | 0.385 | 0.386 | 0.400 |
| ETTh1 → ETTm2 | 0.273 | 0.344 | 0.302 | 0.361 | 0.277 | 0.347 | 0.314 | 0.360 |
| ETTh2 → ETTh1 | 0.485 | 0.485 | 0.508 | 0.499 | 0.588 | 0.537 | 0.565 | 0.509 |
| ETTh2 → ETTm2 | 0.282 | 0.342 | 0.303 | 0.357 | 0.285 | 0.347 | 0.289 | 0.345 |
| ETTm1 → ETTh2 | 0.377 | 0.412 | 0.402 | 0.429 | 0.395 | 0.415 | 0.447 | 0.434 |
| ETTm1 → ETTm2 | 0.231 | 0.294 | 0.268 | 0.324 | 0.235 | 0.297 | 0.258 | 0.311 |
| ETTm2 → ETTh2 | 0.354 | 0.394 | 0.358 | 0.396 | 0.394 | 0.410 | 0.411 | 0.418 |
| ETTm2 → ETTm1 | 0.481 | 0.455 | 0.483 | 0.446 | 0.477 | 0.459 | 0.530 | 0.470 |
表 5:零样本预测结果。加粗为最优,次优在原文以下划线标出,表中数值仍按原文抄录。
| 任务 | StreamTimer | Timer-XL | Timer | PatchTST | ||||
|---|---|---|---|---|---|---|---|---|
| MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | |
| ETTh1 → ETTh2 | 0.345 | 0.388 | 0.367 | 0.398 | 0.354 | 0.385 | 0.386 | 0.400 |
| ETTh1 → ETTm2 | 0.273 | 0.344 | 0.302 | 0.361 | 0.277 | 0.347 | 0.314 | 0.360 |
| ETTh2 → ETTh1 | 0.485 | 0.485 | 0.508 | 0.499 | 0.588 | 0.537 | 0.565 | 0.509 |
| ETTh2 → ETTm2 | 0.282 | 0.342 | 0.303 | 0.357 | 0.285 | 0.347 | 0.289 | 0.345 |
| ETTm1 → ETTh2 | 0.377 | 0.412 | 0.402 | 0.429 | 0.395 | 0.415 | 0.447 | 0.434 |
| ETTm1 → ETTm2 | 0.231 | 0.294 | 0.268 | 0.324 | 0.235 | 0.297 | 0.258 | 0.311 |
| ETTm2 → ETTh2 | 0.354 | 0.394 | 0.358 | 0.396 | 0.394 | 0.410 | 0.411 | 0.418 |
| ETTm2 → ETTm1 | 0.481 | 0.455 | 0.483 | 0.446 | 0.477 | 0.459 | 0.530 | 0.470 |
Zero-shot Forecasting Results. To evaluate the generalization capability of StreamTimer on unseen datasets, we conducted zero-shot forecasting experiments. Following previous protocols [Jin et al., 2024; Kudrat et al., 2025], we selected ETTh1, ETTh2, ETTm1, and ETTm2 as source datasets and performed direct inference on the remaining datasets as targets. Table 5 presents the results for a prediction horizon of 192, where StreamTimer demonstrates consistent superiority across transfer tasks, significantly outperforming PatchTST and the baseline models, Timer and Timer-XL. This robustness across different granularities and domains is primarily attributed to StreamTimer's streaming dynamic adaptation mechanism. This mechanism enables the model to keenly capture and adapt to the distribution evolution of the target domain during the inference phase, thereby effectively mitigating the distribution shift challenges between the source and unseen target domains.
零样本预测结果。 为评估 StreamTimer 在未见过数据集上的泛化能力,我们做了零样本预测实验。沿用已有协议 [Jin et al., 2024; Kudrat et al., 2025],我们选择 ETTh1、ETTh2、ETTm1 和 ETTm2 作为源数据集,并在其余数据集上直接推理作为目标。表 5 给出预测视野为 192 时的结果:StreamTimer 在各迁移任务上持续更好,明显优于 PatchTST 以及基线模型 Timer 和 Timer-XL。这种跨不同粒度和领域的稳健性,主要归功于 StreamTimer 的流式动态适应机制。该机制使模型能在推理阶段敏锐捕捉并适应目标域的分布演化,从而有效缓解源域与未见目标域之间的分布偏移。
Ablation on Hybrid-scale Normalization. To verify the effectiveness of our proposed normalization strategy, we conducted a comprehensive ablation study comparing it with several state-of-the-art normalization techniques, including RevIN [Kim et al., 2021], SAN [Liu et al., 2023], Dish-TS [Fan et al., 2023], and MPNorm [Zhang and Dong, 2025]. Table 4 reports the results on ETTh1 and Weather datasets using both Timer and Timer-XL as backbones. The results demonstrate that our proposed module consistently achieves the lowest MSE and MAE across almost all prediction lengths. While RevIN and MPNorm serve as strong baselines, our method further boosts performance, particularly on the ETTh1 dataset where non-stationarity is significant. Notably, while SAN and Dish-TS employ model-based statistics prediction that necessitates complex pre-processing and auxiliary modules, this added complexity yields negligible performance gains.
混合尺度归一化的消融。 为验证所提归一化策略的有效性,我们做了较完整的消融,把它与若干先进归一化技术比较,包括 RevIN [Kim et al., 2021]、SAN [Liu et al., 2023]、Dish-TS [Fan et al., 2023] 和 MPNorm [Zhang and Dong, 2025]。表 4 报告了在 ETTh1 和 Weather 上分别以 Timer 和 Timer-XL 为骨干的结果。结果表明,我们提出的模块在几乎所有预测长度上都取得最低的 MSE 和 MAE。RevIN 和 MPNorm 已是较强基线,我们的方法仍能继续提高性能,在非平稳性显著的 ETTh1 上尤其明显。值得注意的是,SAN 和 Dish-TS 采用基于模型的统计量预测,需要复杂的预处理和辅助模块,但这些额外复杂度带来的性能增益可以忽略。
Ablation on KV Cache. As shown in Table 6, our ablation study uncovers that RevIN induces severe distribution shift during KV cache streaming. Specifically, RevIN's error rises markedly as the horizon extends to 720, reflecting its failure to manage statistical variations in long streams. On the contrary, our method maintains a stable and low MSE, verifying that it causes almost no harm to model performance in streaming scenarios.
KV 缓存的消融。 如表 6 所示,消融表明 RevIN 在 KV 缓存流式推理中会引发严重的分布偏移。具体来说,随着预测视野延伸到 720,RevIN 的误差明显上升,说明它无法把握长流中的统计变化。相反,我们的方法保持了稳定且较低的 MSE,验证了它在流式场景中几乎不会损害模型性能。
Table 6: Ablation study on ETTh1 and Weather datasets using KV cache streaming. We compare +RevIN and +Ours methods based on Timer and Timer-XL backbones.
| Backbone | Timer | Timer-XL | |||||||
|---|---|---|---|---|---|---|---|---|---|
| Normalization | + RevIN | + Ours | + RevIN | + Ours | |||||
| Dataset | Horizon | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE |
| ETTh1 | 196 | 0.420 | 0.439 | 0.377 | 0.407 | 0.425 | 0.441 | 0.382 | 0.412 |
| 336 | 0.462 | 0.478 | 0.389 | 0.417 | 0.456 | 0.477 | 0.392 | 0.424 | |
| 720 | 0.524 | 0.540 | 0.399 | 0.434 | 0.531 | 0.547 | 0.403 | 0.438 | |
| Weather | 196 | 0.238 | 0.275 | 0.194 | 0.240 | 0.241 | 0.274 | 0.195 | 0.242 |
| 336 | 0.383 | 0.365 | 0.245 | 0.285 | 0.391 | 0.370 | 0.244 | 0.280 | |
| 720 | 0.491 | 0.430 | 0.312 | 0.339 | 0.485 | 0.427 | 0.311 | 0.333 |
表 6:在 ETTh1 和 Weather 上使用 KV 缓存流式推理的消融。我们比较基于 Timer 和 Timer-XL 骨干的 +RevIN 与 +Ours 方法。
| 骨干网络 | Timer | Timer-XL | |||||||
|---|---|---|---|---|---|---|---|---|---|
| 归一化 | + RevIN | + Ours | + RevIN | + Ours | |||||
| 数据集 | 预测步长 | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE |
| ETTh1 | 196 | 0.420 | 0.439 | 0.377 | 0.407 | 0.425 | 0.441 | 0.382 | 0.412 |
| 336 | 0.462 | 0.478 | 0.389 | 0.417 | 0.456 | 0.477 | 0.392 | 0.424 | |
| 720 | 0.524 | 0.540 | 0.399 | 0.434 | 0.531 | 0.547 | 0.403 | 0.438 | |
| Weather | 196 | 0.238 | 0.275 | 0.194 | 0.240 | 0.241 | 0.274 | 0.195 | 0.242 |
| 336 | 0.383 | 0.365 | 0.245 | 0.285 | 0.391 | 0.370 | 0.244 | 0.280 | |
| 720 | 0.491 | 0.430 | 0.312 | 0.339 | 0.485 | 0.427 | 0.311 | 0.333 |
4.3 Model Analysis
4.3 模型分析
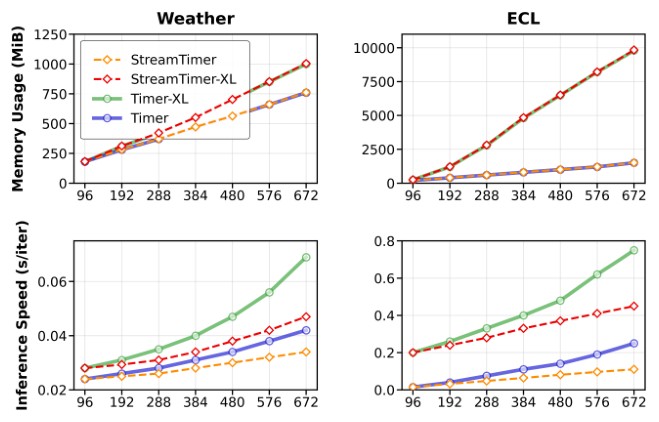
Figure 4: Efficiency analysis. We compare StreamTimer with baselines on multivariate datasets with variable numbers ranging from ten to hundred and increase the forecast horizon.
图 4:效率分析。我们在变量数从十到一百不等的多变量数据集上比较 StreamTimer 与各基线,并逐步加大预测视野。
Model Efficiency. To comprehensively evaluate model efficiency, it is essential to consider the input context length , the number of variables , and crucially, the prediction horizon . Unlike 1D sequences, the computational overhead in multivariate time series forecasting is dictated by the interplay of these three dimensions. We provide a theoretical complexity analysis comparing StreamTimer against the baseline models, Timer and Timer-XL. Specifically, the complexity of Timer, which adopts channel independence, scales as . Meanwhile, Timer-XL, which incorporates channel dependence to capture inter-variable correlations, sees its complexity escalate to . Crucially, the computational burden of both architectures involves a multiplicative coupling with the prediction horizon and quadratic terms of , leading to significant overhead accumulation in long-term forecasting scenarios. In contrast, leveraging the streaming forecasting mechanism, StreamTimer effectively avoids the redundant re-computation of Keys and Values. As derived in Table 10, StreamTimer significantly optimizes the overall complexity to . This indicates that the computational cost of StreamTimer scales linearly with the total sequence length, rather than multiplicatively. As shown in Figure 4, by eliminating these redundant operations, StreamTimer demonstrates an order-of-magnitude efficiency advantage, particularly in tasks involving extensive contexts and extended prediction horizons.
模型效率。 要较全面地评估模型效率,需要同时考虑输入上下文长度 、变量数 ,以及关键的预测视野 。与一维序列不同,多变量时间序列预测的计算开销由这三维的相互作用决定。我们给出 StreamTimer 相对基线模型 Timer 和 Timer-XL 的理论复杂度分析。具体而言,采用通道独立的 Timer,复杂度按 增长;而引入通道依赖以捕捉变量间相关的 Timer-XL,复杂度上升到 。关键在于,这两种架构的计算负担都与预测视野 成乘性耦合,并含有 的平方项,因而在长期预测场景中会显著累积开销。相比之下,借助流式预测机制,StreamTimer 有效避免了对 Key 和 Value 的重复计算。如 Table 10 所推导的,StreamTimer 把总体复杂度明显优化到 。这意味着它的计算代价随序列总长度线性增长,而不是乘性增长。如图 4 所示,去掉这些冗余操作后,StreamTimer 展现出一个数量级的效率优势,在上下文很长、预测视野也很长的任务上尤其明显。
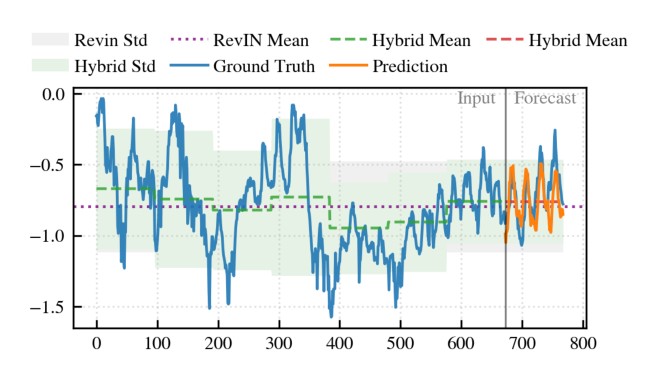
Figure 5: Visualization of proposed normalization.
图 5:所提出归一化方法的可视化。
Visualization of Hybrid-Scale Normalization. Figure 5 visualizes the effectiveness of the proposed normalization strategy. The blue and orange solid lines represent the ground truth and the model prediction, respectively. While RevIN relies on a static global mean (purple dotted line), which fails to capture temporal variations, our Hybrid-Scale Normalization utilizes local means (green and red dashed lines) that dynamically track local trends. Specifically, the red dashed line indicates that the model successfully infers the future distribution mean based on historical patterns. The alignment between the local statistics and the actual data demonstrates the method's precision in mitigating the impact of non-stationarity.
混合尺度归一化的可视化。 图 5 展示了所提归一化策略的效果。蓝色和橙色实线分别表示真值和模型预测。RevIN 依赖静态的全局均值(紫色点线),无法捕捉时间上的变化;我们的混合尺度归一化则使用局部均值(绿色和红色虚线),动态跟踪局部趋势。具体来说,红色虚线表明模型能够根据历史模式成功推断未来分布的均值。局部统计量与实际数据之间的对齐,说明该方法在减轻非平稳性影响时相当精确。
5 Conclusions
5 结论
In this paper, we propose StreamTimer, a streaming inference framework designed to address the limitations of fixed lookback windows in time series forecasting. By reformulating the forecasting process into a continuous state update mechanism, we effectively leverage extremely long historical information without incurring additional computational burden. Our core technical innovations—particularly Cache-Consistent Normalization tailored for non-stationary data—effectively overcome the domain-specific barriers to applying KV caching in time series. Extensive experiments validate the efficiency of StreamTimer, demonstrating substantial reductions in both computational and memory costs while matching or even exceeding predictive performance. These results prove that decoupling context length from computational cost via streaming is both feasible and efficient, paving a new direction for the development of ultra-long sequence modeling and Time Series Foundation Models.
本文提出 StreamTimer,一套流式推理框架,用来应对时间序列预测中固定回看窗口的局限。通过把预测过程改写成连续的状态更新机制,我们能够有效利用极长的历史信息,而不增加额外的计算负担。我们的核心技术贡献——尤其是面向非平稳数据的与缓存一致的归一化——有效克服了把 KV 缓存用到时间序列时的领域障碍。大量实验验证了 StreamTimer 的效率:计算和内存开销都明显下降,预测性能则持平甚至更好。这些结果说明,用流式推理把上下文长度从计算代价中解开,既可行也高效,为超长序列建模和时间序列基础模型的发展提供了新的方向。
Acknowledgments
致谢
This work was supported in part by the Zhejiang Provincial Science and Technology Plan Project under Grant 2024C03261 and in part by Key Scientific Research Base for Digital Conservation of Cave Temples (Zhejiang University), National Cultural Heritage Administration.
本工作部分得到浙江省科技计划项目(批准号 2024C03261)资助,部分得到国家文物局石窟寺数字化保护重点科研基地(浙江大学)资助。
Contribution Statement
贡献说明
Xiyu Meng and Yuhan Wu contributed equally to this work. Yabo Dong is the corresponding author.
Xiyu Meng 与 Yuhan Wu 对本文贡献同等。Yabo Dong 为通讯作者。
References
参考文献
[Ansari and Stella, 2024] Abdul Fatir Ansari and Stella. Chronos: Learning the language of time series. Transactions on Machine Learning Research, 2024.
[Chang et al., 2024] Ching Chang, Wei-Yao Wang, Wen-Chih Peng, and Tien-Fu Chen. Llm4ts: Aligning pretrained llms as data-efficient time-series forecasters, 2024.
[Fan et al., 2023] Wei Fan, Pengyang Wang, Dongkun Wang, Dongjie Wang, Yuanchun Zhou, and Yanjie Fu. Dish-ts: A general paradigm for alleviating distribution shift in time series forecasting. In Proceedings of the AAAI Conference on Artificial Intelligence, volume 37, pages 7522-7529, 2023.
[Jin et al., 2024] Ming Jin, Shiyu Wang, Lintao Ma, Zhixuan Chu, James Y. Zhang, Xiaoming Shi, Pin-Yu Chen, Yuxuan Liang, Yuan-Fang Li, Shirui Pan, and Qingsong Wen. Time-llm: Time series forecasting by reprogramming large language models, 2024.
[Kim et al., 2021] Taesung Kim, Jinhee Kim, Yunwon Tae, Cheonbok Park, Jang-Ho Choi, and Jaegul Choo. Reversible instance normalization for accurate time-series forecasting against distribution shift. In International Conference on Learning Representations, 2021.
[Kudrat et al., 2025] Dilfira Kudrat, Zongxia Xie, Yanru Sun, Tianyu Jia, and Qinghua Hu. Patch-wise structural loss for time series forecasting. In Aarti Singh, Maryam Fazel, Daniel Hsu, Simon Lacoste-Julien, Felix Berkenkamp, Tegan Maharaj, Kiri Wagstaff, and Jerry Zhu, editors, Proceedings of the 42nd International Conference on Machine Learning, volume 267 of Proceedings of Machine Learning Research, pages 31841-31859. PMLR, 13-19 Jul 2025.
[Lin et al., 2023] Shengsheng Lin, Weiwei Lin, Wentai Wu, Feiyu Zhao, Ruichao Mo, and Haotong Zhang. Segrnn: Segment recurrent neural network for long-term time series forecasting, 2023.
[Lin et al., 2024] Shengsheng Lin, Weiwei Lin, Wentai Wu, Haojun Chen, and Junjie Yang. Sparsetsf: Modeling longterm time series forecasting with 1k parameters. In Fortyfirst International Conference on Machine Learning, 2024.
[Liu et al., 2023] Zhiding Liu, Mingyue Cheng, Zhi Li, Zhenya Huang, Qi Liu, Yanhu Xie, and Enhong Chen. Adaptive normalization for non-stationary time series forecasting: A temporal slice perspective. In Thirtyseventh Conference on Neural Information Processing Systems, 2023.
[Liu et al., 2024a] Xu Liu, Juncheng Liu, Gerald Woo, Taha Aksu, Yuxuan Liang, Roger Zimmermann, Chenghao Liu, Silvio Savarese, Caiming Xiong, and Doyen Sahoo. Moirai-moe: Empowering time series foundation models with sparse mixture of experts. arXiv preprint arXiv:2410.10469, 2024.
[Liu et al., 2024b] Yong Liu, Tengge Hu, Haoran Zhang, Haixu Wu, Shiyu Wang, Lintao Ma, and Mingsheng Long. itransformer: Inverted transformers are effective for time series forecasting, 2024.
[Liu et al., 2024c] Yong Liu, Guo Qin, Xiangdong Huang, Jianmin Wang, and Mingsheng Long. Timer-xl: Longcontext transformers for unified time series forecasting. arXiv preprint arXiv:2410.04803, 2024.
[Liu et al., 2024d] Yong Liu, Haoran Zhang, Chenyu Li, Xiangdong Huang, Jianmin Wang, and Mingsheng Long. Timer: Generative pre-trained transformers are large time series models. In Forty-first International Conference on Machine Learning, 2024.
[Luo and Wang, 2024] Donghao Luo and Xue Wang. Moderntcn: A modern pure convolution structure for general time series analysis. In The Twelfth International Conference on Learning Representations, 2024.
[Makridakis et al., 2020] Spyros Makridakis, Evangelos Spiliotis, and Vassilios Assimakopoulos. The m4 competition: 100,000 time series and 61 forecasting methods. International Journal of Forecasting, 36(1):54-74, 2020.
[Muñoz-Sabater et al., 2021] Joaquín Muñoz-Sabater, Emanuel Dutra, Anna Agustí-Panareda, Clément Albergel, Gabriele Arduini, Gianpaolo Balsamo, Souhail Boussetta, Margarita Choulga, Shaun Harrigan, Hans Hersbach, et al. Era5-land: A state-of-the-art global reanalysis dataset for land applications. Earth system science data, 13(9):4349-4383, 2021.
[Nie et al., 2023] Yuqi Nie, Nam H. Nguyen, Phanwadee Sinthong, and Jayant Kalagnanam. A time series is worth 64 words: Long-term forecasting with transformers. In The Eleventh International Conference on Learning Representations, ICLR 2023, Kigali, Rwanda, May 1-5, 2023. OpenReview.net, 2023.
[Qiu et al., 2024] Xiangfei Qiu, Jilin Hu, Lekui Zhou, Xingjian Wu, Junyang Du, Buang Zhang, Chenjuan Guo, Aoying Zhou, Christian S. Jensen, Zhenli Sheng, and Bin Yang. Tfb: Towards comprehensive and fair benchmarking of time series forecasting methods, 2024.
[Shi et al., 2025] Xiaoming Shi, Shiyu Wang, Yuqi Nie, Dianqi Li, Zhou Ye, Qingsong Wen, and Ming Jin. Timemoe: Billion-scale time series foundation models with mixture of experts, 2025.
[Wang et al., 2024a] Shiyu Wang, Haixu Wu, Xiaoming Shi, Tengge Hu, Huakun Luo, Lintao Ma, James Y. Zhang, and Jun Zhou. Timemixer: Decomposable multiscale mixing for time series forecasting. In The Twelfth International Conference on Learning Representations, ICLR 2024, Vienna, Austria, May 7-11, 2024. OpenReview.net, 2024.
[Wang et al., 2024b] Yuxuan Wang, Haixu Wu, Jiaxiang Dong, Yong Liu, Mingsheng Long, and Jianmin Wang. Deep time series models: A comprehensive survey and benchmark. CoRR, abs/2407.13278, 2024.
[Woo et al., 2024] Gerald Woo, Chenghao Liu, Akshat Kumar, Caiming Xiong, Silvio Savarese, and Doyen Sahoo. Unified training of universal time series forecasting transformers. In Forty-first International Conference on Machine Learning, 2024.
[Wu et al., 2024] Yuhan Wu, Xiyu Meng, Yang He, Junru Zhang, Haowen Zhang, Yabo Dong, and Dongming Lu. Multi-view self-supervised contrastive learning for multivariate time series. In Proceedings of the 32nd ACM International Conference on Multimedia, pages 9582-9590, 2024.
[Wu et al., 2025] Yuhan Wu, Xiyu Meng, Huajin Hu, Junru Zhang, Yabo Dong, and Dongming Lu. Affirm: Interactive mamba with adaptive fourier filters for long-term time series forecasting. In Toby Walsh, Julie Shah, and Zico Kolter, editors, AAAI-25, Sponsored by the Association for the Advancement of Artificial Intelligence, February 25 -March 4, 2025, Philadelphia, PA, USA, pages 21599- 21607. AAAI Press, 2025.
[Xiao et al., 2024] Guangxuan Xiao, Yuandong Tian, Beidi Chen, Song Han, and Mike Lewis. Efficient streaming language models with attention sinks. In International Conference on Learning Representations (ICLR), 2024.
[Zeng et al., 2023] Ailing Zeng, Muxi Chen, Lei Zhang, and Qiang Xu. Are transformers effective for time series forecasting? In Brian Williams, Yiling Chen, and Jennifer Neville, editors, Thirty-Seventh AAAI Conference on Artificial Intelligence, AAAI 2023, Thirty-Fifth Conference on Innovative Applications of Artificial Intelligence, IAAI 2023, Thirteenth Symposium on Educational Advances in Artificial Intelligence, EAAI 2023, Washington, DC, USA, February 7-14, 2023, pages 11121-11128. AAAI Press, 2023.
[Zhang and Dong, 2025] Jiayu Zhang and Yuantong Dong. Multi-period normalization for long-term time series forecasting. In ICASSP 2025 -2025 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), pages 1-5, 2025.
[Zhou et al., 2021] Haoyi Zhou, Shanghang Zhang, Jieqi Peng, Shuai Zhang, Jianxin Li, Hui Xiong, and Wancai Zhang. Informer: Beyond efficient transformer for long sequence time-series forecasting. In Thirty-Fifth AAAI Conference on Artificial Intelligence, AAAI 2021, Thirty-Third Conference on Innovative Applications of Artificial Intelligence, IAAI 2021, The Eleventh Symposium on Educational Advances in Artificial Intelligence, EAAI 2021, Virtual Event, February 2-9, 2021, pages 11106-11115. AAAI Press, 2021.
[Zhou et al., 2023] Tian Zhou, Peisong Niu, Xue Wang, Liang Sun, and Rong Jin. One fits all: Power general time series analysis by pretrained LM. In NeurIPS, 2023.