ShuffleNet: An Extremely Efficient Convolutional Neural Network for Mobile Devices
ShuffleNet: An Extremely Efficient Convolutional Neural Network for Mobile Devices
Xiangyu Zhang 1 1 footnotemark: 1 Xinyu Zhou 1 1 footnotemark: 1 Mengxiao Lin Jian Sun Affiliation: Megvii Inc (Face++) Email: {zhangxiangyu,zxy,linmengxiao,sunjian}@megvii.com
Abstract
摘要
We introduce an extremely computation-efficient CNN architecture named ShuffleNet, which is designed specially for mobile devices with very limited computing power (e.g., 10-150 MFLOPs). The new architecture utilizes two new operations, pointwise group convolution and channel shuffle, to greatly reduce computation cost while maintaining accuracy. Experiments on ImageNet classification and MS COCO object detection demonstrate the superior performance of ShuffleNet over other structures, e.g. lower top-1 error (absolute 7.8%) than recent MobileNet [12] on ImageNet classification task, under the computation budget of 40 MFLOPs. On an ARM-based mobile device, ShuffleNet achieves 13 actual speedup over AlexNet while maintaining comparable accuracy.
我们提出一种计算量极低的卷积神经网络结构 ShuffleNet,专门面向算力非常有限的移动设备(例如 10–150 MFLOPs)。新结构利用两种新操作——逐点分组卷积(pointwise group convolution)和通道混洗(channel shuffle)——在保持精度的同时大幅降低计算量。在 ImageNet 分类和 MS COCO 目标检测上的实验表明,ShuffleNet 优于其他结构:例如在 40 MFLOPs 的计算预算下,ImageNet 分类的 top-1 误差比当时的 MobileNet [12] 低 7.8 个百分点。在基于 ARM 的移动设备上,ShuffleNet 在精度相当的情况下,相对 AlexNet 获得约 的实际加速。
1 Introduction
1 引言
Building deeper and larger convolutional neural networks (CNNs) is a primary trend for solving major visual recognition tasks [21, 9, 33, 5, 28, 24]. The most accurate CNNs usually have hundreds of layers and thousands of channels [9, 34, 32, 40], thus requiring computation at billions of FLOPs. This report examines the opposite extreme: pursuing the best accuracy in very limited computational budgets at tens or hundreds of MFLOPs, focusing on common mobile platforms such as drones, robots, and smartphones. Note that many existing works [16, 22, 43, 42, 38, 27] focus on pruning, compressing, or low-bit representing a “basic” network architecture. Here we aim to explore a highly efficient basic architecture specially designed for our desired computing ranges.
把卷积神经网络(CNN)做得更深、更大,是解决主要视觉识别任务的一条主线 [21, 9, 33, 5, 28, 24]。精度最高的 CNN 通常有数百层、数千个通道 [9, 34, 32, 40],计算量因此要以数十亿次浮点运算来计。本文看的是相反的一端:在数十或数百 MFLOPs 这种非常紧的计算预算下追求最好的精度,对象是无人机、机器人和智能手机这类常见移动平台。需要说明的是,已有不少工作 [16, 22, 43, 42, 38, 27] 关注对一个“基础”网络做剪枝、压缩或低比特表示。这里我们想探索的,是专门为上述计算区间设计的高效基础结构。
We notice that state-of-the-art basic architectures such as Xception [3] and ResNeXt [40] become less efficient in extremely small networks because of the costly dense convolutions. We propose using pointwise group convolutions to reduce computation complexity of convolutions. To overcome the side effects brought by group convolutions, we come up with a novel channel shuffle operation to help the information flowing across feature channels. Based on the two techniques, we build a highly efficient architecture called ShuffleNet. Compared with popular structures like [30, 9, 40], for a given computation complexity budget, our ShuffleNet allows more feature map channels, which helps to encode more information and is especially critical to the performance of very small networks.
我们注意到,像 Xception [3] 和 ResNeXt [40] 这样当时领先的基础结构,在极小的网络里效率会下降,原因是密集的 卷积代价很高。我们提出用逐点分组卷积来降低 卷积的计算复杂度。为克服分组卷积带来的副作用,我们引入一种新的通道混洗操作,帮助信息在特征通道之间流动。基于这两项技术,我们搭建了高效结构 ShuffleNet。与 [30, 9, 40] 等常见结构相比,在给定计算复杂度预算下,ShuffleNet 可以使用更多的特征图通道,从而编码更多信息;这一点对很小的网络尤其关键。
We evaluate our models on the challenging ImageNet classification [4, 29] and MS COCO object detection [23] tasks. A series of controlled experiments shows the effectiveness of our design principles and the better performance over other structures. Compared with the state-of-the-art architecture MobileNet [12], ShuffleNet achieves superior performance by a significant margin, e.g. absolute 7.8% lower ImageNet top-1 error at level of 40 MFLOPs.
我们在具有挑战性的 ImageNet 分类 [4, 29] 和 MS COCO 目标检测 [23] 任务上评估模型。一组受控实验表明,设计原则是有效的,并且优于其他结构。与当时最好的结构 MobileNet [12] 相比,ShuffleNet 有明显优势,例如在 40 MFLOPs 量级上,ImageNet top-1 误差绝对低 7.8 个百分点。
We also examine the speedup on real hardware, i.e. an off-the-shelf ARM-based computing core. The ShuffleNet model achieves 13 actual speedup (theoretical speedup is 18) over AlexNet [21] while maintaining comparable accuracy.
我们还在真实硬件上考察了加速,即一块现成的 ARM 计算核心。ShuffleNet 模型在精度相当的情况下,相对 AlexNet [21] 获得约 的实际加速(理论加速为 )。
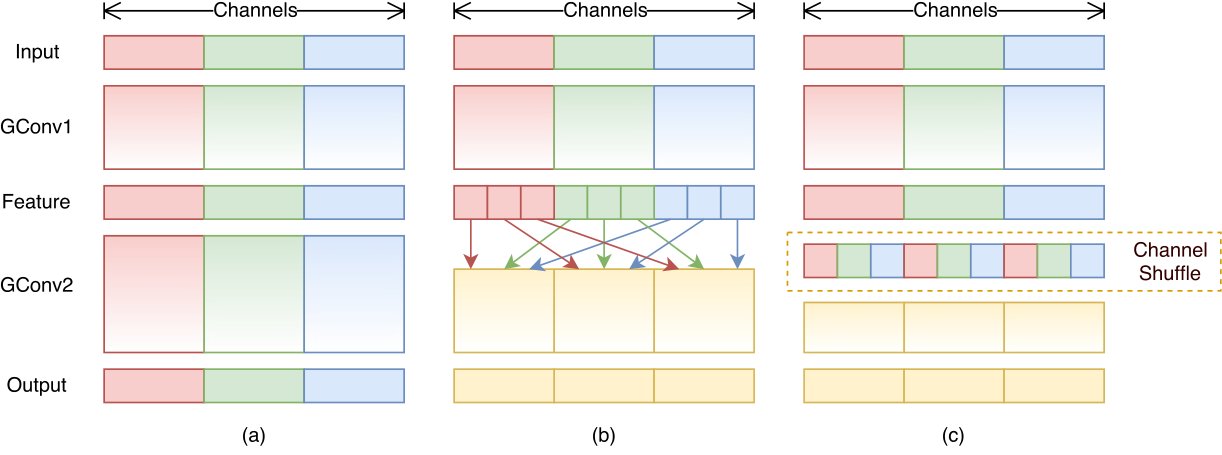
Figure 1: Channel shuffle with two stacked group convolutions. GConv stands for group convolution. a) two stacked convolution layers with the same number of groups. Each output channel only relates to the input channels within the group. No cross talk; b) input and output channels are fully related when GConv2 takes data from different groups after GConv1; c) an equivalent implementation to b) using channel shuffle.
图 1:两次堆叠的分组卷积中的通道混洗。GConv 表示分组卷积。a)两组数相同的卷积层堆叠在一起。每个输出通道只与组内的输入通道有关,组间没有交流;b)GConv2 在 GConv1 之后从不同组取数据,输入与输出通道因此完全关联;c)用通道混洗实现与 b)等价的效果。
2 Related Work
2 相关工作
Efficient Model Designs
The last few years have seen the success of deep neural networks in computer vision tasks [21, 36, 28], in which model designs play an important role. The increasing needs of running high quality deep neural networks on embedded devices encourage the study on efficient model designs [8]. For example, GoogLeNet [33] increases the depth of networks with much lower complexity compared to simply stacking convolution layers. SqueezeNet [14] reduces parameters and computation significantly while maintaining accuracy. ResNet [9, 10] utilizes the efficient bottleneck structure to achieve impressive performance. SENet [13] introduces an architectural unit that boosts performance at slight computation cost. Concurrent with us, a very recent work [46] employs reinforcement learning and model search to explore efficient model designs. The proposed mobile NASNet model achieves comparable performance with our counterpart ShuffleNet model (26.0% @ 564 MFLOPs vs. 26.3% @ 524 MFLOPs for ImageNet classification error). But [46] do not report results on extremely tiny models (e.g. complexity less than 150 MFLOPs), nor evaluate the actual inference time on mobile devices.
高效模型设计
过去几年,深度神经网络在计算机视觉任务中取得了成功 [21, 36, 28],其中模型设计起着重要作用。在嵌入式设备上运行高质量深度网络的需求,推动了高效模型设计的研究 [8]。例如,GoogLeNet [33] 在增加网络深度的同时,复杂度远低于简单堆叠卷积层。SqueezeNet [14] 在保持精度的同时显著减少参数和计算量。ResNet [9, 10] 利用高效的瓶颈结构取得了出色表现。SENet [13] 引入一种结构单元,以很小的计算代价提升性能。与我们同期,一项非常新的工作 [46] 用强化学习和模型搜索来探索高效模型设计。其提出的移动版 NASNet 与我们对等的 ShuffleNet 模型性能相当(ImageNet 分类误差为 26.0%,564 MFLOPs,而我们为 26.3%,524 MFLOPs)。但 [46] 没有报告极小模型(例如复杂度低于 150 MFLOPs)的结果,也没有在移动设备上评估实际推理时间。
Group Convolution
The concept of group convolution, which was first introduced in AlexNet [21] for distributing the model over two GPUs, has been well demonstrated its effectiveness in ResNeXt [40]. Depthwise separable convolution proposed in Xception [3] generalizes the ideas of separable convolutions in Inception series [34, 32]. Recently, MobileNet [12] utilizes the depthwise separable convolutions and gains state-of-the-art results among lightweight models. Our work generalizes group convolution and depthwise separable convolution in a novel form.
分组卷积
分组卷积的概念最早在 AlexNet [21] 中提出,用于把模型分到两块 GPU 上,后来在 ResNeXt [40] 中很好地展示了有效性。Xception [3] 提出的深度可分离卷积,推广了 Inception 系列 [34, 32] 中可分离卷积的思路。随后,MobileNet [12] 采用深度可分离卷积,在轻量模型中取得了当时最好的结果。我们的工作以一种新的形式,对分组卷积和深度可分离卷积做了推广。
Channel Shuffle Operation
To the best of our knowledge, the idea of channel shuffle operation is rarely mentioned in previous work on efficient model design, although CNN library cuda-convnet [20] supports “random sparse convolution” layer, which is equivalent to random channel shuffle followed by a group convolutional layer. Such “random shuffle” operation has different purpose and been seldom exploited later. Very recently, another concurrent work [41] also adopt this idea for a two-stage convolution. However, [41] did not specially investigate the effectiveness of channel shuffle itself and its usage in tiny model design.
通道混洗操作
据我们所知,在以往的高效模型设计中,通道混洗这一想法很少被提到。不过 CNN 库 cuda-convnet [20] 支持“随机稀疏卷积”层,它等价于先做随机通道混洗,再接一层分组卷积。这种“随机混洗”的目的不同,后来也很少被继续使用。就在最近,另一项同期工作 [41] 也把这一想法用在两阶段卷积上。不过 [41] 并没有专门考察通道混洗本身的有效性,以及它在极小模型设计中的用法。
Model Acceleration
This direction aims to accelerate inference while preserving accuracy of a pre-trained model. Pruning network connections [6, 7] or channels [38] reduces redundant connections in a pre-trained model while maintaining performance. Quantization [31, 27, 39, 45, 44] and factorization [22, 16, 18, 37] are proposed in literature to reduce redundancy in calculations to speed up inference. Without modifying the parameters, optimized convolution algorithms implemented by FFT [25, 35] and other methods [2] decrease time consumption in practice. Distilling [11] transfers knowledge from large models into small ones, which makes training small models easier.
模型加速
这一方向的目标是:在加速推理的同时,尽量保住已训练模型的精度。剪掉网络连接 [6, 7] 或通道 [38],可以减少预训练模型中的冗余连接并维持性能。文献中还提出量化 [31, 27, 39, 45, 44] 和分解 [22, 16, 18, 37],通过减少计算中的冗余来加快推理。在不改参数的前提下,用 FFT [25, 35] 以及其他方法 [2] 实现的优化卷积算法,也能在实践中缩短耗时。蒸馏 [11] 则把大模型中的知识转移到小模型,使小模型更容易训练。
3 Approach
3 方法
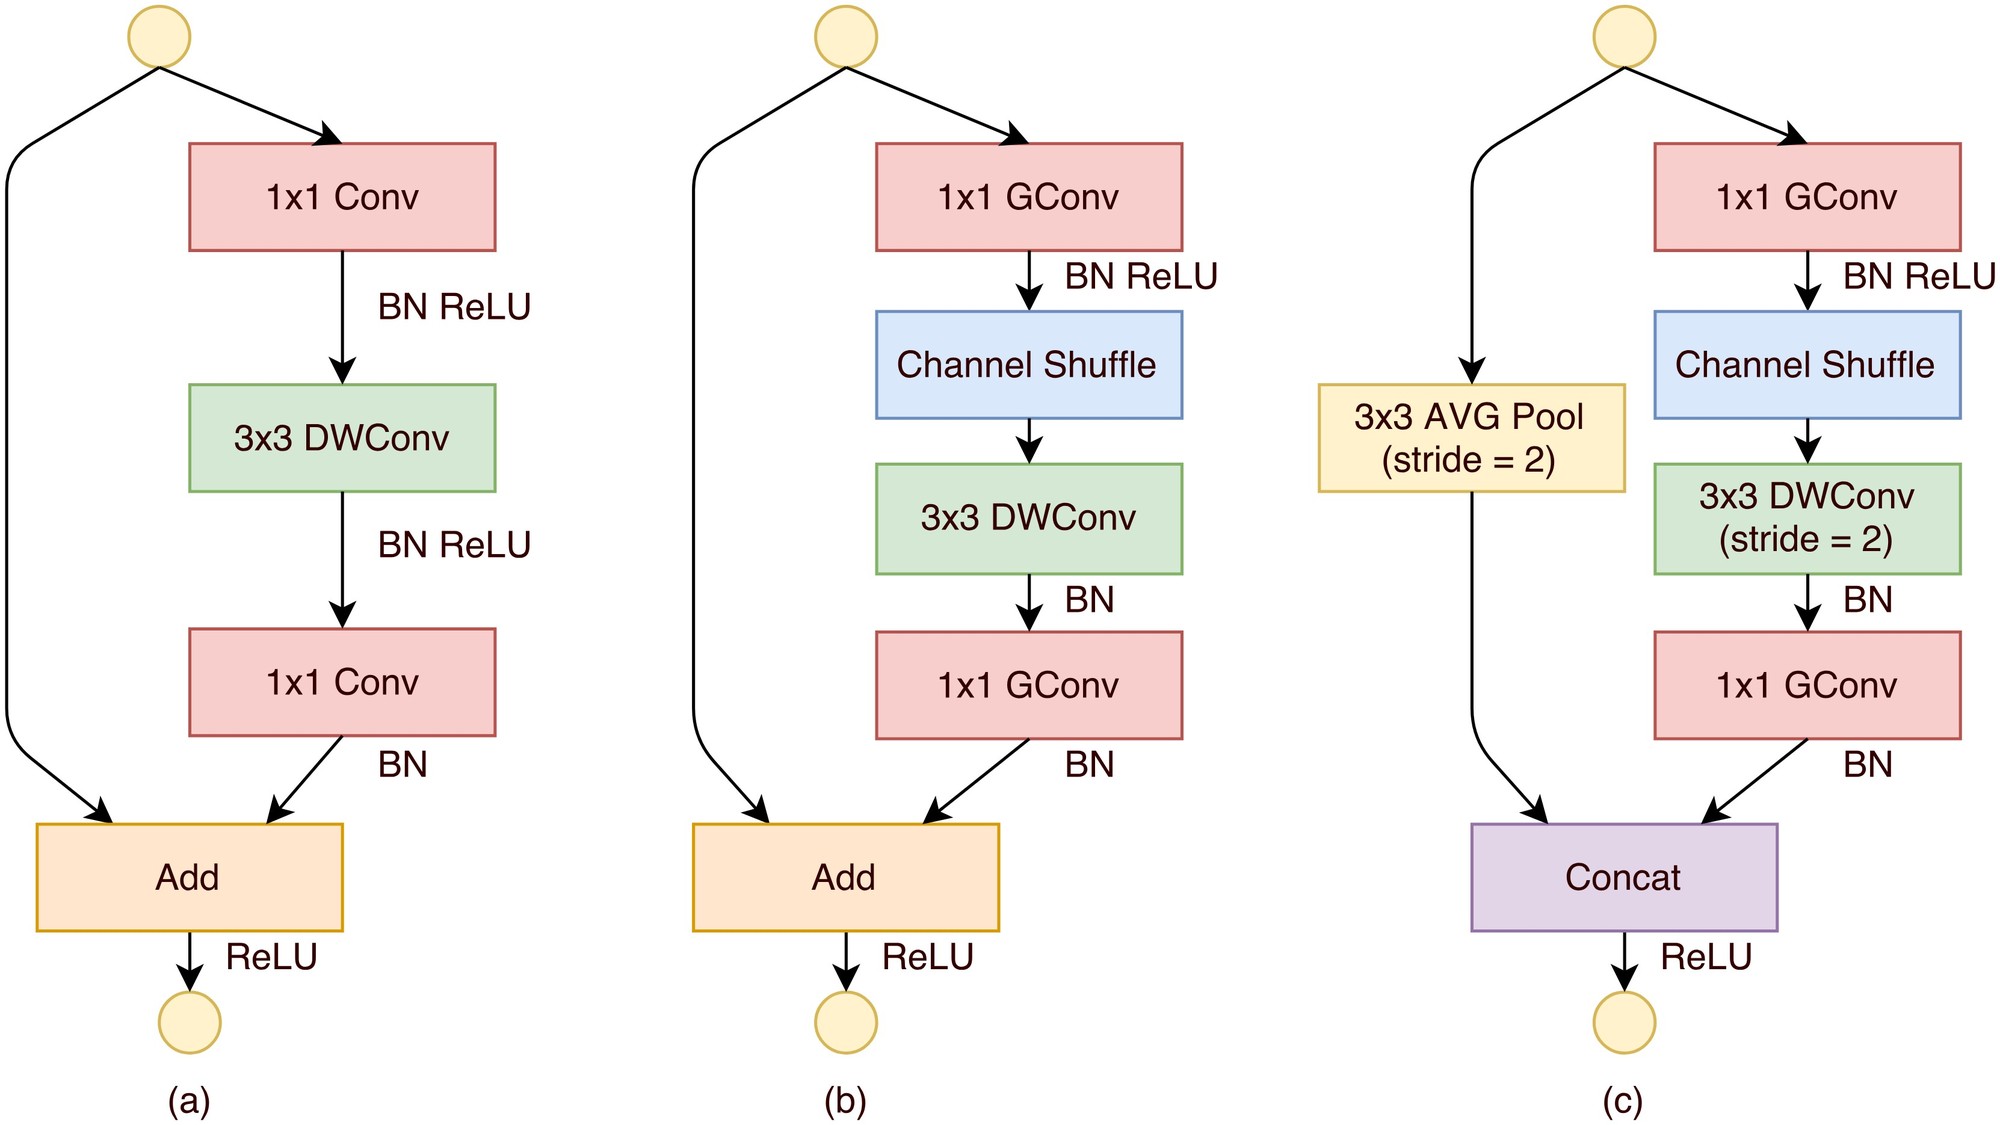
Figure 2: ShuffleNet Units. a) bottleneck unit [9] with depthwise convolution (DWConv) [3, 12]; b) ShuffleNet unit with pointwise group convolution (GConv) and channel shuffle; c) ShuffleNet unit with stride = 2.
图 2:ShuffleNet 单元。a)带深度卷积(DWConv) [3, 12] 的瓶颈单元 [9];b)带逐点分组卷积(GConv)和通道混洗的 ShuffleNet 单元;c)步长为 2 的 ShuffleNet 单元。
3.1 Channel Shuffle for Group Convolutions
3.1 面向分组卷积的通道混洗
Modern convolutional neural networks [30, 33, 34, 32, 9, 10] usually consist of repeated building blocks with the same structure. Among them, state-of-the-art networks such as Xception [3] and ResNeXt [40] introduce efficient depthwise separable convolutions or group convolutions into the building blocks to strike an excellent trade-off between representation capability and computational cost. However, we notice that both designs do not fully take the convolutions (also called pointwise convolutions in [12]) into account, which require considerable complexity. For example, in ResNeXt [40] only layers are equipped with group convolutions. As a result, for each residual unit in ResNeXt the pointwise convolutions occupy 93.4% multiplication-adds (cardinality = 32 as suggested in [40]). In tiny networks, expensive pointwise convolutions result in limited number of channels to meet the complexity constraint, which might significantly damage the accuracy.
现代卷积神经网络 [30, 33, 34, 32, 9, 10] 通常由结构相同的重复模块组成。其中,Xception [3] 和 ResNeXt [40] 等当时领先的网络,在模块里引入高效的深度可分离卷积或分组卷积,以在表示能力与计算代价之间取得很好的折中。不过我们注意到,这两种设计都没有充分处理 卷积(在 [12] 中也称为逐点卷积)的开销,而这部分计算量相当可观。例如在 ResNeXt [40] 里,只有 层使用了分组卷积。结果是,ResNeXt 的每个残差单元中,逐点卷积占据了 93.4% 的乘加次数(按 [40] 建议取 cardinality = 32)。在很小的网络里,昂贵的逐点卷积会迫使通道数被压得很紧,才能满足复杂度约束,这可能明显损害精度。
To address the issue, a straightforward solution is to apply channel sparse connections, for example group convolutions, also on layers. By ensuring that each convolution operates only on the corresponding input channel group, group convolution significantly reduces computation cost. However, if multiple group convolutions stack together, there is one side effect: outputs from a certain channel are only derived from a small fraction of input channels. Fig 1 (a) illustrates a situation of two stacked group convolution layers. It is clear that outputs from a certain group only relate to the inputs within the group. This property blocks information flow between channel groups and weakens representation.
要解决这个问题,一个直截了当的办法是在 层上也采用通道稀疏连接,例如分组卷积。只要保证每次卷积只作用在对应的输入通道组上,分组卷积就能显著降低计算量。然而,如果把多层分组卷积叠在一起,会出现一个副作用:某个通道的输出只来自一小部分输入通道。图 1(a)画出了两层分组卷积堆叠的情形。可以清楚地看到,某一组的输出只与该组内的输入有关。这一性质阻断了通道组之间的信息流动,削弱了表示能力。
If we allow group convolution to obtain input data from different groups (as shown in Fig 1 (b)), the input and output channels will be fully related. Specifically, for the feature map generated from the previous group layer, we can first divide the channels in each group into several subgroups, then feed each group in the next layer with different subgroups. This can be efficiently and elegantly implemented by a channel shuffle operation (Fig 1 (c)): suppose a convolutional layer with groups whose output has channels; we first reshape the output channel dimension into , transposing and then flattening it back as the input of next layer. Note that the operation still takes effect even if the two convolutions have different numbers of groups. Moreover, channel shuffle is also differentiable, which means it can be embedded into network structures for end-to-end training.
如果允许分组卷积从不同组获取输入数据(如图 1(b)所示),输入与输出通道就会完全关联。具体来说,对上一层分组卷积得到的特征图,可以先把每组内的通道再分成若干子组,然后让下一层的每一组分别接收来自不同子组的数据。这一过程可以通过通道混洗操作高效而简洁地实现(图 1(c)):设某一卷积层有 组,输出有 个通道;先把输出通道维重塑为 ,再转置并展平,作为下一层的输入。即使两层卷积的组数不同,这一操作仍然有效。此外,通道混洗是可微的,因此可以嵌入网络结构中做端到端训练。
Channel shuffle operation makes it possible to build more powerful structures with multiple group convolutional layers. In the next subsection we will introduce an efficient network unit with channel shuffle and group convolution.
有了通道混洗,就可以用多层分组卷积搭建更有表达力的结构。下一小节我们将介绍一种同时使用通道混洗和分组卷积的高效网络单元。
3.2 ShuffleNet Unit
3.2 ShuffleNet 单元
| Layer | Output size | KSize | Stride | Repeat | Output channels ( groups) | ||||
|---|---|---|---|---|---|---|---|---|---|
| Image | 3 | 3 | 3 | 3 | 3 | ||||
| Conv1 | 2 | 1 | 24 | 24 | 24 | 24 | 24 | ||
| MaxPool | 2 | ||||||||
| Stage2 | 2 | 1 | 144 | 200 | 240 | 272 | 384 | ||
| 1 | 3 | 144 | 200 | 240 | 272 | 384 | |||
| Stage3 | 2 | 1 | 288 | 400 | 480 | 544 | 768 | ||
| 1 | 7 | 288 | 400 | 480 | 544 | 768 | |||
| Stage4 | 2 | 1 | 576 | 800 | 960 | 1088 | 1536 | ||
| 1 | 3 | 576 | 800 | 960 | 1088 | 1536 | |||
| GlobalPool | |||||||||
| FC | 1000 | 1000 | 1000 | 1000 | 1000 | ||||
| Complexity | 143M | 140M | 137M | 133M | 137M |
Table 1: ShuffleNet architecture. The complexity is evaluated with FLOPs, i.e. the number of floating-point multiplication-adds. Note that for Stage 2, we do not apply group convolution on the first pointwise layer because the number of input channels is relatively small.
| 层 | 输出尺寸 | 卷积核大小 | 步长 | 重复次数 | 输出通道数( 组) | ||||
|---|---|---|---|---|---|---|---|---|---|
| Image | 3 | 3 | 3 | 3 | 3 | ||||
| Conv1 | 2 | 1 | 24 | 24 | 24 | 24 | 24 | ||
| MaxPool | 2 | ||||||||
| Stage2 | 2 | 1 | 144 | 200 | 240 | 272 | 384 | ||
| 1 | 3 | 144 | 200 | 240 | 272 | 384 | |||
| Stage3 | 2 | 1 | 288 | 400 | 480 | 544 | 768 | ||
| 1 | 7 | 288 | 400 | 480 | 544 | 768 | |||
| Stage4 | 2 | 1 | 576 | 800 | 960 | 1088 | 1536 | ||
| 1 | 3 | 576 | 800 | 960 | 1088 | 1536 | |||
| GlobalPool | |||||||||
| FC | 1000 | 1000 | 1000 | 1000 | 1000 | ||||
| 复杂度 | 143M | 140M | 137M | 133M | 137M |
表 1:ShuffleNet 结构。复杂度以 FLOPs 计,即浮点乘加次数。注意在 Stage 2,我们没有对第一个逐点卷积层使用分组卷积,因为输入通道数相对较少。
| Model | Complexity | Classification error (%) | ||||
|---|---|---|---|---|---|---|
| (MFLOPs) | ||||||
| ShuffleNet 1 | 140 | 33.6 | 32.7 | 32.6 | 32.8 | 32.4 |
| ShuffleNet 0.5 | 38 | 45.1 | 44.4 | 43.2 | 41.6 | 42.3 |
| ShuffleNet 0.25 | 13 | 57.1 | 56.8 | 55.0 | 54.2 | 52.7 |
Table 2: Classification error vs. number of groups (smaller number represents better performance)
| 模型 | 复杂度 | 分类误差(%) | ||||
|---|---|---|---|---|---|---|
| (MFLOPs) | ||||||
| ShuffleNet 1 | 140 | 33.6 | 32.7 | 32.6 | 32.8 | 32.4 |
| ShuffleNet 0.5 | 38 | 45.1 | 44.4 | 43.2 | 41.6 | 42.3 |
| ShuffleNet 0.25 | 13 | 57.1 | 56.8 | 55.0 | 54.2 | 52.7 |
表 2:分类误差与组数 的关系(数字越小表示性能越好)
Taking advantage of the channel shuffle operation, we propose a novel ShuffleNet unit specially designed for small networks. We start from the design principle of bottleneck unit [9] in Fig 2 (a). It is a residual block. In its residual branch, for the layer, we apply a computational economical depthwise convolution [3] on the bottleneck feature map. Then, we replace the first layer with pointwise group convolution followed by a channel shuffle operation, to form a ShuffleNet unit, as shown in Fig 2 (b). The purpose of the second pointwise group convolution is to recover the channel dimension to match the shortcut path. For simplicity, we do not apply an extra channel shuffle operation after the second pointwise layer as it results in comparable scores. The usage of batch normalization (BN) [15] and nonlinearity is similar to [9, 40], except that we do not use ReLU after depthwise convolution as suggested by [3]. As for the case where ShuffleNet is applied with stride, we simply make two modifications (see Fig 2 (c)): (i) add a average pooling on the shortcut path; (ii) replace the element-wise addition with channel concatenation, which makes it easy to enlarge channel dimension with little extra computation cost.
借助通道混洗操作,我们提出一种专为小网络设计的 ShuffleNet 单元。我们从图 2(a)中瓶颈单元 [9] 的设计原则出发。它是一个残差块。在残差分支上,对于 层,我们在瓶颈特征图上使用计算更省的 深度卷积 [3]。然后,把第一个 层换成逐点分组卷积,并接上通道混洗,就得到如图 2(b)所示的 ShuffleNet 单元。第二个逐点分组卷积的作用,是把通道维恢复到与捷径分支一致。为简单起见,我们没有在第二个逐点层之后再加一次通道混洗,因为分数相当。批归一化(BN) [15] 和非线性的用法与 [9, 40] 类似,只是按 [3] 的建议,深度卷积之后不用 ReLU。当 ShuffleNet 需要带步长时,我们只做两处改动(见图 2(c)):(i)在捷径分支上加一个 平均池化;(ii)把逐元素相加换成通道拼接,这样可以在几乎不增加额外计算的情况下扩大通道维。
Thanks to pointwise group convolution with channel shuffle, all components in ShuffleNet unit can be computed efficiently. Compared with ResNet [9] (bottleneck design) and ResNeXt [40], our structure has less complexity under the same settings. For example, given the input size and the bottleneck channels , ResNet unit requires FLOPs and ResNeXt has FLOPs, while our ShuffleNet unit requires only FLOPs, where means the number of groups for convolutions. In other words, given a computational budget, ShuffleNet can use wider feature maps. We find this is critical for small networks, as tiny networks usually have an insufficient number of channels to process the information.
由于采用了带通道混洗的逐点分组卷积,ShuffleNet 单元中的各部分都可以高效计算。与 ResNet [9](瓶颈设计)和 ResNeXt [40] 相比,在相同设置下我们的结构复杂度更低。例如,给定输入尺寸 和瓶颈通道数 ,ResNet 单元需要 FLOPs,ResNeXt 需要 FLOPs,而我们的 ShuffleNet 单元只需 FLOPs,其中 是卷积的组数。换句话说,在给定计算预算下,ShuffleNet 可以使用更宽的特征图。我们发现这对小网络很关键,因为很小的网络通常没有足够的通道来处理信息。
In addition, in ShuffleNet depthwise convolution only performs on bottleneck feature maps. Even though depthwise convolution usually has very low theoretical complexity, we find it difficult to efficiently implement on low-power mobile devices, which may result from a worse computation/memory access ratio compared with other dense operations. Such drawback is also referred in [3], which has a runtime library based on TensorFlow [1]. In ShuffleNet units, we intentionally use depthwise convolution only on bottleneck in order to prevent overhead as much as possible.
此外,在 ShuffleNet 中,深度卷积只作用在瓶颈特征图上。尽管深度卷积的理论复杂度通常很低,我们发现它在低功耗移动设备上并不容易高效实现,这可能是因为与其他密集运算相比,它的计算/访存比更差。这一缺点在 [3] 中也有提及,该工作有一个基于 TensorFlow [1] 的运行时库。在 ShuffleNet 单元里,我们有意只在瓶颈上使用深度卷积,以尽量避免这种额外开销。
3.3 Network Architecture
3.3 网络结构
Built on ShuffleNet units, we present the overall ShuffleNet architecture in Table 1. The proposed network is mainly composed of a stack of ShuffleNet units grouped into three stages. The first building block in each stage is applied with stride = 2. Other hyper-parameters within a stage stay the same, and for the next stage the output channels are doubled. Similar to [9], we set the number of bottleneck channels to 1/4 of the output channels for each ShuffleNet unit. Our intent is to provide a reference design as simple as possible, although we find that further hyper-parameter tunning might generate better results.
基于 ShuffleNet 单元,表 1 给出了整体的 ShuffleNet 结构。提出的网络主要由堆叠的 ShuffleNet 单元组成,并分成三个阶段。每个阶段的第一个模块使用步长 2。同一阶段内的其他超参数保持不变,到下一阶段时输出通道数加倍。与 [9] 类似,我们把每个 ShuffleNet 单元的瓶颈通道数设为输出通道数的 1/4。我们的意图是尽量给出一个简单的参考设计,尽管我们发现进一步调节超参数或许还能得到更好的结果。
In ShuffleNet units, group number controls the connection sparsity of pointwise convolutions. Table 1 explores different group numbers and we adapt the output channels to ensure overall computation cost roughly unchanged (140 MFLOPs). Obviously, larger group numbers result in more output channels (thus more convolutional filters) for a given complexity constraint, which helps to encode more information, though it might also lead to degradation for an individual convolutional filter due to limited corresponding input channels. In Sec 4.1.1 we will study the impact of this number subject to different computational constrains.
在 ShuffleNet 单元中,组数 控制着逐点卷积的连接稀疏程度。表 1 考察了不同的组数,并调整输出通道数,使总体计算量大致不变(约 140 MFLOPs)。显然,在给定复杂度约束下,更大的组数会带来更多输出通道(因而也有更多卷积滤波器),有助于编码更多信息;不过,由于每个滤波器对应的输入通道有限,单个卷积滤波器也可能因此变弱。我们将在第 4.1.1 节中,在不同计算约束下研究这一数目的影响。
To customize the network to a desired complexity, we can simply apply a scale factor on the number of channels. For example, we denote the networks in Table 1 as ”ShuffleNet 1”, then ”ShuffleNet ” means scaling the number of filters in ShuffleNet 1 by times thus overall complexity will be roughly times of ShuffleNet 1.
若要把网络定制到所需的复杂度,只需对通道数施加一个缩放因子 。例如,我们把表 1 中的网络记为“ShuffleNet 1”,则“ShuffleNet ”表示把 ShuffleNet 1 中的滤波器数目缩放 倍,从而总体复杂度大约是 ShuffleNet 1 的 倍。
4 Experiments
4 实验
| Model | Cls err. (%, no shuffle) | Cls err. (%, shuffle) | err. (%) |
|---|---|---|---|
| ShuffleNet 1x () | 34.5 | 32.6 | 1.9 |
| ShuffleNet 1x () | 37.6 | 32.4 | 5.2 |
| ShuffleNet 0.5x () | 45.7 | 43.2 | 2.5 |
| ShuffleNet 0.5x () | 48.1 | 42.3 | 5.8 |
| ShuffleNet 0.25x () | 56.3 | 55.0 | 1.3 |
| ShuffleNet 0.25x () | 56.5 | 52.7 | 3.8 |
Table 3: ShuffleNet with/without channel shuffle (smaller number represents better performance)
| 模型 | 分类误差(%,无混洗) | 分类误差(%,有混洗) | 误差变化 (%) |
|---|---|---|---|
| ShuffleNet 1x () | 34.5 | 32.6 | 1.9 |
| ShuffleNet 1x () | 37.6 | 32.4 | 5.2 |
| ShuffleNet 0.5x () | 45.7 | 43.2 | 2.5 |
| ShuffleNet 0.5x () | 48.1 | 42.3 | 5.8 |
| ShuffleNet 0.25x () | 56.3 | 55.0 | 1.3 |
| ShuffleNet 0.25x () | 56.5 | 52.7 | 3.8 |
表 3:有无通道混洗的 ShuffleNet(数字越小表示性能越好)
We mainly evaluate our models on the ImageNet 2012 classification dataset [29, 4]. We follow most of the training settings and hyper-parameters used in [40], with two exceptions: (i) we set the weight decay to 4e-5 instead of 1e-4 and use linear-decay learning rate policy (decreased from 0.5 to 0); (ii) we use slightly less aggressive scale augmentation for data preprocessing. Similar modifications are also referenced in [12] because such small networks usually suffer from underfitting rather than overfitting. It takes 1 or 2 days to train a model for iterations on 4 GPUs, whose batch size is set to 1024. To benchmark, we compare single crop top-1 performance on ImageNet validation set, i.e. cropping center view from input image and evaluating classification accuracy. We use exactly the same settings for all models to ensure fair comparisons.
我们主要在 ImageNet 2012 分类数据集 [29, 4] 上评估模型。训练设置和超参数大多沿用 [40],只有两处例外:(i)把权重衰减设为 4e-5 而非 1e-4,并使用线性衰减的学习率策略(从 0.5 降到 0);(ii)数据预处理中的尺度增强稍弱一些。类似改动在 [12] 中也有提到,因为这样的小网络通常更容易欠拟合,而不是过拟合。在 4 块 GPU 上训练一个模型需要 1 到 2 天, 次迭代,批大小设为 1024。评测时,我们比较 ImageNet 验证集上的单裁剪 top-1 表现,即从 的输入图像中裁出 的中心视图,再评估分类精度。所有模型使用完全相同的设置,以保证比较公平。
4.1 Ablation Study
4.1 消融实验
The core idea of ShuffleNet lies in pointwise group convolution and channel shuffle operation. In this subsection we evaluate them respectively.
ShuffleNet 的核心想法是逐点分组卷积和通道混洗操作。本小节分别评估它们。
4.1.1 Pointwise Group Convolutions
To evaluate the importance of pointwise group convolutions, we compare ShuffleNet models of the same complexity whose numbers of groups range from 1 to 8. If the group number equals 1, no pointwise group convolution is involved and then the ShuffleNet unit becomes an ”Xception-like” [3] structure. For better understanding, we also scale the width of the networks to 3 different complexities and compare their classification performance respectively. Results are shown in Table 2.
4.1.1 逐点分组卷积
为了评估逐点分组卷积的重要性,我们比较了复杂度相同、组数从 1 到 8 的 ShuffleNet 模型。当组数为 1 时,不涉及逐点分组卷积,此时 ShuffleNet 单元变成一种“类 Xception” [3] 结构。为了更好地理解,我们还把网络宽度缩放到三种不同的复杂度,并分别比较分类性能。结果见表 2。
From the results, we see that models with group convolutions () consistently perform better than the counterparts without pointwise group convolutions (). Smaller models tend to benefit more from groups. For example, for ShuffleNet 1 the best entry () is 1.2% better than the counterpart, while for ShuffleNet 0.5 and 0.25 the gaps become 3.5% and 4.4% respectively. Note that group convolution allows more feature map channels for a given complexity constraint, so we hypothesize that the performance gain comes from wider feature maps which help to encode more information. In addition, a smaller network involves thinner feature maps, meaning it benefits more from enlarged feature maps.
从结果可以看出,使用分组卷积()的模型一贯优于没有逐点分组卷积的对照()。更小的模型往往从分组中获益更多。例如,对 ShuffleNet 1 而言,最好的一项()比对照好 1.2 个百分点,而对 ShuffleNet 0.5 和 0.25,差距分别达到 3.5 和 4.4 个百分点。需要注意的是,分组卷积在给定复杂度约束下允许使用更多特征图通道,因此我们推测,性能提升来自更宽的特征图,它们有助于编码更多信息。此外,更小的网络本身特征图更窄,因而从加宽特征图中获益也更多。
Table 2 also shows that for some models (e.g. ShuffleNet 0.5) when group numbers become relatively large (e.g. ), the classification score saturates or even drops. With an increase in group number (thus wider feature maps), input channels for each convolutional filter become fewer, which may harm representation capability. Interestingly, we also notice that for smaller models such as ShuffleNet 0.25 larger group numbers tend to better results consistently, which suggests wider feature maps bring more benefits for smaller models.
表 2 还显示,对某些模型(例如 ShuffleNet 0.5),当组数变得相对较大(例如 )时,分类分数会饱和甚至下降。随着组数增加(特征图因此更宽),每个卷积滤波器的输入通道变少,可能损害表示能力。有意思的是,我们还注意到,对 ShuffleNet 0.25 这样更小的模型,更大的组数往往持续带来更好的结果,这说明更宽的特征图对更小的模型益处更大。
4.1.2 Channel Shuffle vs. No Shuffle
The purpose of shuffle operation is to enable cross-group information flow for multiple group convolution layers. Table 3 compares the performance of ShuffleNet structures (group number is set to 3 or 8 for instance) with/without channel shuffle. The evaluations are performed under three different scales of complexity. It is clear that channel shuffle consistently boosts classification scores for different settings. Especially, when group number is relatively large (e.g. ), models with channel shuffle outperform the counterparts by a significant margin, which shows the importance of cross-group information interchange.
4.1.2 通道混洗与不做混洗
混洗操作的目的,是为多层分组卷积打通组间信息流。表 3 比较了 ShuffleNet 结构(组数举例取 3 或 8)在有无通道混洗时的表现。评测在三种不同复杂度尺度下进行。可以清楚地看到,在不同设置下,通道混洗都稳定地提高了分类分数。尤其当组数相对较大(例如 )时,带通道混洗的模型明显优于对照,说明跨组信息交换很重要。
4.2 Comparison with Other Structure Units
4.2 与其他结构单元的比较
| Complexity (MFLOPs) | VGG-like | ResNet | Xception-like | ResNeXt | ShuffleNet (ours) |
|---|---|---|---|---|---|
| 140 | 50.7 | 37.3 | 33.6 | 33.3 | 32.4 (1, ) |
| 38 | - | 48.8 | 45.1 | 46.0 | 41.6 (0.5, ) |
| 13 | - | 63.7 | 57.1 | 65.2 | 52.7 (0.25, ) |
Table 4: Classification error vs. various structures (%, smaller number represents better performance). We do not report VGG-like structure on smaller networks because the accuracy is significantly worse.
| 复杂度(MFLOPs) | VGG-like | ResNet | Xception-like | ResNeXt | ShuffleNet(本文) |
|---|---|---|---|---|---|
| 140 | 50.7 | 37.3 | 33.6 | 33.3 | 32.4(1,) |
| 38 | - | 48.8 | 45.1 | 46.0 | 41.6(0.5,) |
| 13 | - | 63.7 | 57.1 | 65.2 | 52.7(0.25,) |
表 4:不同结构的分类误差(%,数字越小表示性能越好)。我们没有在更小的网络上报告类 VGG 结构,因为精度明显更差。
| Model | Complexity (MFLOPs) | Cls err. (%) | err. (%) |
|---|---|---|---|
| 1.0 MobileNet-224 | 569 | 29.4 | - |
| ShuffleNet 2 () | 524 | 26.3 | 3.1 |
| ShuffleNet 2 (with SE[13], ) | 527 | 24.7 | 4.7 |
| 0.75 MobileNet-224 | 325 | 31.6 | - |
| ShuffleNet 1.5 () | 292 | 28.5 | 3.1 |
| 0.5 MobileNet-224 | 149 | 36.3 | - |
| ShuffleNet 1 () | 140 | 32.4 | 3.9 |
| 0.25 MobileNet-224 | 41 | 49.4 | - |
| ShuffleNet 0.5 () | 38 | 41.6 | 7.8 |
| ShuffleNet 0.5 (shallow, ) | 40 | 42.8 | 6.6 |
Table 5: ShuffleNet vs. MobileNet [12] on ImageNet Classification
| 模型 | 复杂度(MFLOPs) | 分类误差(%) | 误差变化 (%) |
|---|---|---|---|
| 1.0 MobileNet-224 | 569 | 29.4 | - |
| ShuffleNet 2() | 524 | 26.3 | 3.1 |
| ShuffleNet 2(加 SE[13],) | 527 | 24.7 | 4.7 |
| 0.75 MobileNet-224 | 325 | 31.6 | - |
| ShuffleNet 1.5() | 292 | 28.5 | 3.1 |
| 0.5 MobileNet-224 | 149 | 36.3 | - |
| ShuffleNet 1() | 140 | 32.4 | 3.9 |
| 0.25 MobileNet-224 | 41 | 49.4 | - |
| ShuffleNet 0.5() | 38 | 41.6 | 7.8 |
| ShuffleNet 0.5(浅层,) | 40 | 42.8 | 6.6 |
表 5:ShuffleNet 与 MobileNet [12] 在 ImageNet 分类上的比较
| Model | Cls err. (%) | Complexity (MFLOPs) |
|---|---|---|
| VGG-16 [30] | 28.5 | 15300 |
| ShuffleNet 2 () | 26.3 | 524 |
| GoogleNet [33]* | 31.3 | 1500 |
| ShuffleNet 1 () | 32.4 | 140 |
| AlexNet [21] | 42.8 | 720 |
| SqueezeNet [14] | 42.5 | 833 |
| ShuffleNet 0.5 () | 41.6 | 38 |
Table 6: Complexity comparison. *Implemented by BVLC (https://github.com/BVLC/caffe/tree/master/models/bvlc_googlenet)
| 模型 | 分类误差(%) | 复杂度(MFLOPs) |
|---|---|---|
| VGG-16 [30] | 28.5 | 15300 |
| ShuffleNet 2() | 26.3 | 524 |
| GoogleNet [33]* | 31.3 | 1500 |
| ShuffleNet 1() | 32.4 | 140 |
| AlexNet [21] | 42.8 | 720 |
| SqueezeNet [14] | 42.5 | 833 |
| ShuffleNet 0.5() | 41.6 | 38 |
表 6:复杂度比较。*由 BVLC 实现(https://github.com/BVLC/caffe/tree/master/models/bvlc_googlenet)
Recent leading convolutional units in VGG [30], ResNet [9], GoogleNet [33], ResNeXt [40] and Xception [3] have pursued state-of-the-art results with large models (e.g. GFLOPs), but do not fully explore low-complexity conditions. In this section we survey a variety of building blocks and make comparisons with ShuffleNet under the same complexity constraint.
近年来,VGG [30]、ResNet [9]、GoogleNet [33]、ResNeXt [40] 和 Xception [3] 中的主流卷积单元,都在大模型(例如不低于 1 GFLOPs)上追求当时最好的结果,但没有充分探索低复杂度条件。本节我们考察多种基本模块,并在相同的复杂度约束下与 ShuffleNet 比较。
For fair comparison, we use the overall network architecture as shown in Table 1. We replace the ShuffleNet units in Stage 2-4 with other structures, then adapt the number of channels to ensure the complexity remains unchanged. The structures we explored include:
为了公平比较,我们使用表 1 所示的整体网络结构。把 Stage 2–4 中的 ShuffleNet 单元替换成其他结构,再调整通道数,使复杂度保持不变。我们考察的结构包括:
- • VGG-like. Following the design principle of VGG net [30], we use a two-layer 33 convolutions as the basic building block. Different from [30], we add a Batch Normalization layer [15] after each of the convolutions to make end-to-end training easier.
- VGG-like。遵循 VGG 网络 [30] 的设计原则,我们用两层 卷积作为基本模块。与 [30] 不同的是,我们在每个卷积之后加上批归一化层 [15],以便更容易做端到端训练。
- • ResNet. We adopt the ”bottleneck” design in our experiment, which has been demonstrated more efficient in [9] . Same as [9], the bottleneck ratio[^1] is also .
[^1]: In the bottleneck-like units (like ResNet, ResNeXt or ShuffleNet) bottleneck ratio implies the ratio of bottleneck channels to output channels. For example, bottleneck ratio = means the output feature map is 4 times the width of the bottleneck feature map.
- ResNet。实验中我们采用“瓶颈”设计,这在 [9] 中已被证明更高效。与 [9] 相同,瓶颈比[^1] 也取 。
[^1]: 在类瓶颈单元(如 ResNet、ResNeXt 或 ShuffleNet)中,瓶颈比指瓶颈通道数与输出通道数之比。例如,瓶颈比 表示输出特征图的宽度是瓶颈特征图的 4 倍。
- • Xception-like. The original structure proposed in [3] involves fancy designs or hyper-parameters for different stages, which we find difficult for fair comparison on small models. Instead, we remove the pointwise group convolutions and channel shuffle operation from ShuffleNet (also equivalent to ShuffleNet with ). The derived structure shares the same idea of “depthwise separable convolution” as in [3], which is called an Xception-like structure here.
- Xception-like。 [3] 中提出的原始结构,在不同阶段包含较复杂的设计或超参数,我们发现这很难在小模型上做公平比较。于是,我们从 ShuffleNet 中去掉逐点分组卷积和通道混洗操作(这也等价于 的 ShuffleNet)。得到的结构与 [3] 中“深度可分离卷积”的想法一致,这里称为 Xception-like 结构。
- • ResNeXt. We use the settings of cardinality and bottleneck ratio as suggested in [40]. We also explore other settings, e.g. bottleneck ratio , and get similar results.
- ResNeXt。我们采用 cardinality 、瓶颈比 的设置,这是 [40] 中的建议。我们也尝试了其他设置,例如瓶颈比 ,得到的结果相近。
| Model | mAP (300 image) | mAP (600 image) |
|---|---|---|
| ShuffleNet 2 () | 18.7% | 25.0% |
| ShuffleNet 1 () | 14.5% | 19.8% |
| 1.0 MobileNet-224 [12] | 16.4% | 19.8% |
| 1.0 MobileNet-224 (our impl.) | 14.9% | 19.3% |
Table 7: Object detection results on MS COCO (larger numbers represents better performance). For MobileNets we compare two results: 1) COCO detection scores reported by [12]; 2) finetuning from our reimplemented MobileNets, whose training and finetuning settings are exactly the same as that for ShuffleNets.
| 模型 | mAP ( 图像) | mAP ( 图像) |
|---|---|---|
| ShuffleNet 2() | 18.7% | 25.0% |
| ShuffleNet 1() | 14.5% | 19.8% |
| 1.0 MobileNet-224 [12] | 16.4% | 19.8% |
| 1.0 MobileNet-224(我们的实现) | 14.9% | 19.3% |
表 7:MS COCO 上的目标检测结果(数字越大表示性能越好)。对 MobileNet,我们比较两种结果:1)[12] 报告的 COCO 检测分数;2)从我们复现的 MobileNet 微调得到的结果,其训练和微调设置与 ShuffleNet 完全相同。
| Model | Cls err. (%) | FLOPs | |||
|---|---|---|---|---|---|
| ShuffleNet 0.5 () | 43.2 | 38M | 15.2ms | 87.4ms | 260.1ms |
| ShuffleNet 1 () | 32.6 | 140M | 37.8ms | 222.2ms | 684.5ms |
| ShuffleNet 2 () | 26.3 | 524M | 108.8ms | 617.0ms | 1857.6ms |
| AlexNet [21] | 42.8 | 720M | 184.0ms | 1156.7ms | 3633.9ms |
| 1.0 MobileNet-224 [12] | 29.4 | 569M | 110.0ms | 612.0ms | 1879.2ms |
Table 8: Actual inference time on mobile device (smaller number represents better performance). The platform is based on a single Qualcomm Snapdragon 820 processor. All results are evaluated with single thread.
| 模型 | 分类误差(%) | FLOPs | |||
|---|---|---|---|---|---|
| ShuffleNet 0.5() | 43.2 | 38M | 15.2ms | 87.4ms | 260.1ms |
| ShuffleNet 1() | 32.6 | 140M | 37.8ms | 222.2ms | 684.5ms |
| ShuffleNet 2() | 26.3 | 524M | 108.8ms | 617.0ms | 1857.6ms |
| AlexNet [21] | 42.8 | 720M | 184.0ms | 1156.7ms | 3633.9ms |
| 1.0 MobileNet-224 [12] | 29.4 | 569M | 110.0ms | 612.0ms | 1879.2ms |
表 8:移动设备上的实际推理时间(数字越小表示性能越好)。平台基于单颗 Qualcomm Snapdragon 820 处理器。所有结果均以单线程评测。
We use exactly the same settings to train these models. Results are shown in Table 4. Our ShuffleNet models outperform most others by a significant margin under different complexities. Interestingly, we find an empirical relationship between feature map channels and classification accuracy. For example, under the complexity of 38 MFLOPs, output channels of Stage 4 (see Table 1) for VGG-like, ResNet, ResNeXt, Xception-like, ShuffleNet models are 50, 192, 192, 288, 576 respectively, which is consistent with the increase of accuracy. Since the efficient design of ShuffleNet, we can use more channels for a given computation budget, thus usually resulting in better performance.
我们用完全相同的设置训练这些模型。结果见表 4。在不同复杂度下,我们的 ShuffleNet 模型都以明显优势优于大多数对照。有意思的是,我们发现特征图通道数与分类精度之间存在经验上的对应关系。例如,在 38 MFLOPs 的复杂度下,VGG-like、ResNet、ResNeXt、Xception-like、ShuffleNet 模型在 Stage 4(见表 1)的输出通道数分别是 50、192、192、288、576,这与精度的提升一致。由于 ShuffleNet 的高效设计,我们可以在给定计算预算下使用更多通道,因而通常获得更好的性能。
Note that the above comparisons do not include GoogleNet or Inception series [33, 34, 32]. We find it nontrivial to generate such Inception structures to small networks because the original design of Inception module involves too many hyper-parameters. As a reference, the first GoogleNet version [33] has 31.3% top-1 error at the cost of 1.5 GFLOPs (See Table 6). More sophisticated Inception versions [34, 32] are more accurate, however, involve significantly increased complexity. Recently, Kim et al. propose a lightweight network structure named PVANET [19] which adopts Inception units. Our reimplemented PVANET (with 224224 input size) has 29.7% classification error with a computation complexity of 557 MFLOPs, while our ShuffleNet 2x model () gets 26.3% with 524 MFLOPs (see Table 6).
需要说明的是,上述比较没有纳入 GoogleNet 或 Inception 系列 [33, 34, 32]。我们发现,要把这类 Inception 结构生成到小网络上并不容易,因为 Inception 模块的原始设计包含太多超参数。作为参考,第一版 GoogleNet [33] 在 1.5 GFLOPs 的代价下 top-1 误差为 31.3%(见表 6)。更复杂的 Inception 版本 [34, 32] 更准确,但复杂度也显著增加。最近,Kim 等人提出一种名为 PVANET [19] 的轻量结构,其中采用了 Inception 单元。我们复现的 PVANET(输入尺寸为 )分类误差为 29.7%,计算复杂度为 557 MFLOPs,而我们的 ShuffleNet 2x 模型()在 524 MFLOPs 下得到 26.3%(见表 6)。
4.3 Comparison with MobileNets and Other Frameworks
4.3 与 MobileNets 及其他框架的比较
Recently Howard et al. have proposed MobileNets [12] which mainly focus on efficient network architecture for mobile devices. MobileNet takes the idea of depthwise separable convolution from [3] and achieves state-of-the-art results on small models.
最近,Howard 等人提出了主要面向移动设备高效网络结构的 MobileNets [12]。MobileNet 借鉴了 [3] 中深度可分离卷积的想法,并在小模型上取得了当时最好的结果。
Table 5 compares classification scores under a variety of complexity levels. It is clear that our ShuffleNet models are superior to MobileNet for all the complexities. Though our ShuffleNet network is specially designed for small models ( MFLOPs), we find it is still better than MobileNet for higher computation cost, e.g. 3.1% more accurate than MobileNet 1 at the cost of 500 MFLOPs. For smaller networks (40 MFLOPs) ShuffleNet surpasses MobileNet by 7.8%. Note that our ShuffleNet architecture contains 50 layers while MobileNet only has 28 layers. For better understanding, we also try ShuffleNet on a 26-layer architecture by removing half of the blocks in Stage 2-4 (see ”ShuffleNet 0.5 shallow ()” in Table 5). Results show that the shallower model is still significantly better than the corresponding MobileNet, which implies that the effectiveness of ShuffleNet mainly results from its efficient structure, not the depth.
表 5 在多种复杂度水平下比较了分类分数。可以清楚地看到,在所有复杂度上,我们的 ShuffleNet 模型都优于 MobileNet。尽管 ShuffleNet 网络是专门为小模型(低于 150 MFLOPs)设计的,我们发现在更高计算量下它仍然好于 MobileNet,例如在约 500 MFLOPs 的代价下,比 MobileNet 1 更准确 3.1 个百分点。对于更小的网络(约 40 MFLOPs),ShuffleNet 超出 MobileNet 7.8 个百分点。需要注意的是,我们的 ShuffleNet 结构有 50 层,而 MobileNet 只有 28 层。为了更好地理解,我们还在 26 层结构上尝试了 ShuffleNet,方法是去掉 Stage 2–4 中一半的模块(见表 5 中的“ShuffleNet 0.5 浅层()”)。结果表明,更浅的模型仍然明显好于对应的 MobileNet,这意味着 ShuffleNet 的有效性主要来自其高效结构,而不是深度。
Table 6 compares our ShuffleNet with a few popular models. Results show that with similar accuracy ShuffleNet is much more efficient than others. For example, ShuffleNet 0.5 is theoretically 18 faster than AlexNet [21] with comparable classification score. We will evaluate the actual running time in Sec 4.5.
表 6 把我们的 ShuffleNet 与若干常见模型做了比较。结果显示,在精度相近时,ShuffleNet 比其他模型高效得多。例如,ShuffleNet 0.5 在分类分数相当的情况下,理论上比 AlexNet [21] 快 。我们将在第 4.5 节评估实际运行时间。
It is also worth noting that the simple architecture design makes it easy to equip ShuffeNets with the latest advances such as [13, 26]. For example, in [13] the authors propose Squeeze-and-Excitation (SE) blocks which achieve state-of-the-art results on large ImageNet models. We find SE modules also take effect in combination with the backbone ShuffleNets, for instance, boosting the top-1 error of ShuffleNet 2 to 24.7% (shown in Table 5). Interestingly, though negligible increase of theoretical complexity, we find ShuffleNets with SE modules are usually slower than the “raw” ShuffleNets on mobile devices, which implies that actual speedup evaluation is critical on low-cost architecture design. In Sec 4.5 we will make further discussion.
还值得指出的是,简单的结构设计使 ShuffleNet 很容易配上 [13, 26] 等最新进展。例如,[13] 的作者提出 Squeeze-and-Excitation(SE) 块,并在大型 ImageNet 模型上取得了当时最好的结果。我们发现 SE 模块与 ShuffleNet 骨干结合同样有效,例如把 ShuffleNet 2 的 top-1 误差提升到 24.7%(见表 5)。有意思的是,尽管理论复杂度增加可以忽略,我们却发现带 SE 模块的 ShuffleNet 在移动设备上通常比“原版”ShuffleNet 慢 ,这说明在低成本结构设计中,实际加速评测非常关键。我们将在第 4.5 节进一步讨论。
4.4 Generalization Ability
4.4 泛化能力
To evaluate the generalization ability for transfer learning, we test our ShuffleNet model on the task of MS COCO object detection [23]. We adopt Faster-RCNN [28] as the detection framework and use the publicly released Caffe code [28, 17] for training with default settings. Similar to [12], the models are trained on the COCO train+val dataset excluding 5000 minival images and we conduct testing on the minival set. Table 7 shows the comparison of results trained and evaluated on two input resolutions. Comparing ShuffleNet 2 with MobileNet whose complexity are comparable (524 vs. 569 MFLOPs), our ShuffleNet 2 surpasses MobileNet by a significant margin on both resolutions; our ShuffleNet 1 also achieves comparable results with MobileNet on 600 resolution, but has 4 complexity reduction. We conjecture that this significant gain is partly due to ShuffleNet’s simple design of architecture without bells and whistles.
为了评估迁移学习中的泛化能力,我们在 MS COCO 目标检测任务 [23] 上测试 ShuffleNet 模型。我们采用 Faster-RCNN [28] 作为检测框架,并使用公开的 Caffe 代码 [28, 17],按默认设置训练。与 [12] 类似,模型在去掉 5000 张 minival 图像后的 COCO train+val 数据集上训练,并在 minival 集合上测试。表 7 给出了在两种输入分辨率上训练和评估的结果比较。把复杂度相当的 ShuffleNet 2 与 MobileNet 相比(524 对 569 MFLOPs),我们的 ShuffleNet 2 在两种分辨率上都明显超过 MobileNet;我们的 ShuffleNet 1 在 分辨率上也达到与 MobileNet 相当的结果,但复杂度降低约 。我们推测,这一显著收益部分来自 ShuffleNet 简洁、没有多余技巧的结构设计。
4.5 Actual Speedup Evaluation
4.5 实际加速评测
Finally, we evaluate the actual inference speed of ShuffleNet models on a mobile device with an ARM platform. Though ShuffleNets with larger group numbers (e.g. or ) usually have better performance, we find it less efficient in our current implementation. Empirically usually has a proper trade-off between accuracy and actual inference time. As shown in Table 8, three input resolutions are exploited for the test. Due to memory access and other overheads, we find every 4 theoretical complexity reduction usually results in 2.6 actual speedup in our implementation. Nevertheless, compared with AlexNet [21] our ShuffleNet 0.5 model still achieves 13 actual speedup under comparable classification accuracy (the theoretical speedup is 18), which is much faster than previous AlexNet-level models or speedup approaches such as [14, 16, 22, 42, 43, 38].
最后,我们在一块采用 ARM 平台的移动设备上评估 ShuffleNet 模型的实际推理速度。尽管组数更大(例如 或 )的 ShuffleNet 通常性能更好,但在我们当前的实现里,它们的效率并不高。经验上, 通常能在精度和实际推理时间之间取得合适的折中。如表 8 所示,测试使用了三种输入分辨率。由于访存和其他开销,我们发现在我们的实现中,理论复杂度每降低 ,实际加速通常约为 。尽管如此,与 AlexNet [21] 相比,我们的 ShuffleNet 0.5 模型在分类精度相当的情况下,仍然获得约 的实际加速(理论加速为 ),这比以往达到 AlexNet 水平的模型,或 [14, 16, 22, 42, 43, 38] 这类加速方法,都要快得多。
References
参考文献
[1] M. Abadi, A. Agarwal, P. Barham, E. Brevdo, Z. Chen, C. Citro, G. S. Corrado, A. Davis, J. Dean, M. Devin, et al. Tensorflow: Large-scale machine learning on heterogeneous distributed systems. arXiv preprint arXiv:1603.04467 , 2016.
[2] H. Bagherinezhad, M. Rastegari, and A. Farhadi. Lcnn: Lookup-based convolutional neural network. arXiv preprint arXiv:1611.06473 , 2016.
[3] F. Chollet. Xception: Deep learning with depthwise separable convolutions. arXiv preprint arXiv:1610.02357 , 2016.
[4] J. Deng, W. Dong, R. Socher, L.-J. Li, K. Li, and L. Fei-Fei. Imagenet: A large-scale hierarchical image database. In Computer Vision and Pattern Recognition, 2009. CVPR 2009. IEEE Conference on , pages 248–255. IEEE, 2009.
[5] R. Girshick, J. Donahue, T. Darrell, and J. Malik. Rich feature hierarchies for accurate object detection and semantic segmentation. In Proceedings of the IEEE conference on computer vision and pattern recognition , pages 580–587, 2014.
[6] S. Han, H. Mao, and W. J. Dally. Deep compression: Compressing deep neural networks with pruning, trained quantization and huffman coding. arXiv preprint arXiv:1510.00149 , 2015.
[7] S. Han, J. Pool, J. Tran, and W. Dally. Learning both weights and connections for efficient neural network. In Advances in Neural Information Processing Systems , pages 1135–1143, 2015.
[8] K. He and J. Sun. Convolutional neural networks at constrained time cost. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pages 5353–5360, 2015.
[9] K. He, X. Zhang, S. Ren, and J. Sun. Deep residual learning for image recognition. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pages 770–778, 2016.
[10] K. He, X. Zhang, S. Ren, and J. Sun. Identity mappings in deep residual networks. In European Conference on Computer Vision , pages 630–645. Springer, 2016.
[11] G. Hinton, O. Vinyals, and J. Dean. Distilling the knowledge in a neural network. arXiv preprint arXiv:1503.02531 , 2015.
[12] A. G. Howard, M. Zhu, B. Chen, D. Kalenichenko, W. Wang, T. Weyand, M. Andreetto, and H. Adam. Mobilenets: Efficient convolutional neural networks for mobile vision applications. arXiv preprint arXiv:1704.04861 , 2017.
[13] J. Hu, L. Shen, and G. Sun. Squeeze-and-excitation networks. arXiv preprint arXiv:1709.01507 , 2017.
[14] F. N. Iandola, S. Han, M. W. Moskewicz, K. Ashraf, W. J. Dally, and K. Keutzer. Squeezenet: Alexnet-level accuracy with 50x fewer parameters and¡ 0.5 mb model size. arXiv preprint arXiv:1602.07360 , 2016.
[15] S. Ioffe and C. Szegedy. Batch normalization: Accelerating deep network training by reducing internal covariate shift. arXiv preprint arXiv:1502.03167 , 2015.
[16] M. Jaderberg, A. Vedaldi, and A. Zisserman. Speeding up convolutional neural networks with low rank expansions. arXiv preprint arXiv:1405.3866 , 2014.
[17] Y. Jia, E. Shelhamer, J. Donahue, S. Karayev, J. Long, R. Girshick, S. Guadarrama, and T. Darrell. Caffe: Convolutional architecture for fast feature embedding. In Proceedings of the 22nd ACM international conference on Multimedia , pages 675–678. ACM, 2014.
[18] J. Jin, A. Dundar, and E. Culurciello. Flattened convolutional neural networks for feedforward acceleration. arXiv preprint arXiv:1412.5474 , 2014.
[19] K.-H. Kim, S. Hong, B. Roh, Y. Cheon, and M. Park. Pvanet: Deep but lightweight neural networks for real-time object detection. arXiv preprint arXiv:1608.08021 , 2016.
[20] A. Krizhevsky. cuda-convnet: High-performance c++/cuda implementation of convolutional neural networks, 2012.
[21] A. Krizhevsky, I. Sutskever, and G. E. Hinton. Imagenet classification with deep convolutional neural networks. In Advances in neural information processing systems , pages 1097–1105, 2012.
[22] V. Lebedev, Y. Ganin, M. Rakhuba, I. Oseledets, and V. Lempitsky. Speeding-up convolutional neural networks using fine-tuned cp-decomposition. arXiv preprint arXiv:1412.6553 , 2014.
[23] T.-Y. Lin, M. Maire, S. Belongie, J. Hays, P. Perona, D. Ramanan, P. Dollár, and C. L. Zitnick. Microsoft coco: Common objects in context. In European Conference on Computer Vision , pages 740–755. Springer, 2014.
[24] J. Long, E. Shelhamer, and T. Darrell. Fully convolutional networks for semantic segmentation. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pages 3431–3440, 2015.
[25] M. Mathieu, M. Henaff, and Y. LeCun. Fast training of convolutional networks through ffts. arXiv preprint arXiv:1312.5851 , 2013.
[26] P. Ramachandran, B. Zoph, and Q. V. Le. Swish: a self-gated activation function. arXiv preprint arXiv:1710.05941 , 2017.
[27] M. Rastegari, V. Ordonez, J. Redmon, and A. Farhadi. Xnor-net: Imagenet classification using binary convolutional neural networks. In European Conference on Computer Vision , pages 525–542. Springer, 2016.
[28] S. Ren, K. He, R. Girshick, and J. Sun. Faster r-cnn: Towards real-time object detection with region proposal networks. In Advances in neural information processing systems , pages 91–99, 2015.
[29] O. Russakovsky, J. Deng, H. Su, J. Krause, S. Satheesh, S. Ma, Z. Huang, A. Karpathy, A. Khosla, M. Bernstein, et al. Imagenet large scale visual recognition challenge. International Journal of Computer Vision , 115(3):211–252, 2015.
[30] K. Simonyan and A. Zisserman. Very deep convolutional networks for large-scale image recognition. arXiv preprint arXiv:1409.1556 , 2014.
[31] D. Soudry, I. Hubara, and R. Meir. Expectation backpropagation: Parameter-free training of multilayer neural networks with continuous or discrete weights. In Advances in Neural Information Processing Systems , pages 963–971, 2014.
[32] C. Szegedy, S. Ioffe, V. Vanhoucke, and A. Alemi. Inception-v4, inception-resnet and the impact of residual connections on learning. arXiv preprint arXiv:1602.07261 , 2016.
[33] C. Szegedy, W. Liu, Y. Jia, P. Sermanet, S. Reed, D. Anguelov, D. Erhan, V. Vanhoucke, and A. Rabinovich. Going deeper with convolutions. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pages 1–9, 2015.
[34] C. Szegedy, V. Vanhoucke, S. Ioffe, J. Shlens, and Z. Wojna. Rethinking the inception architecture for computer vision. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pages 2818–2826, 2016.
[35] N. Vasilache, J. Johnson, M. Mathieu, S. Chintala, S. Piantino, and Y. LeCun. Fast convolutional nets with fbfft: A gpu performance evaluation. arXiv preprint arXiv:1412.7580 , 2014.
[36] O. Vinyals, A. Toshev, S. Bengio, and D. Erhan. Show and tell: A neural image caption generator. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pages 3156–3164, 2015.
[37] M. Wang, B. Liu, and H. Foroosh. Design of efficient convolutional layers using single intra-channel convolution, topological subdivisioning and spatial ”bottleneck” structure. arXiv preprint arXiv:1608.04337 , 2016.
[38] W. Wen, C. Wu, Y. Wang, Y. Chen, and H. Li. Learning structured sparsity in deep neural networks. In Advances in Neural Information Processing Systems , pages 2074–2082, 2016.
[39] J. Wu, C. Leng, Y. Wang, Q. Hu, and J. Cheng. Quantized convolutional neural networks for mobile devices. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pages 4820–4828, 2016.
[40] S. Xie, R. Girshick, P. Dollár, Z. Tu, and K. He. Aggregated residual transformations for deep neural networks. arXiv preprint arXiv:1611.05431 , 2016.
[41] T. Zhang, G.-J. Qi, B. Xiao, and J. Wang. Interleaved group convolutions for deep neural networks. In International Conference on Computer Vision , 2017.
[42] X. Zhang, J. Zou, K. He, and J. Sun. Accelerating very deep convolutional networks for classification and detection. IEEE transactions on pattern analysis and machine intelligence , 38(10):1943–1955, 2016.
[43] X. Zhang, J. Zou, X. Ming, K. He, and J. Sun. Efficient and accurate approximations of nonlinear convolutional networks. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pages 1984–1992, 2015.
[44] A. Zhou, A. Yao, Y. Guo, L. Xu, and Y. Chen. Incremental network quantization: Towards lossless cnns with low-precision weights. arXiv preprint arXiv:1702.03044 , 2017.
[45] S. Zhou, Y. Wu, Z. Ni, X. Zhou, H. Wen, and Y. Zou. Dorefa-net: Training low bitwidth convolutional neural networks with low bitwidth gradients. arXiv preprint arXiv:1606.06160 , 2016.
[46] B. Zoph, V. Vasudevan, J. Shlens, and Q. V. Le. Learning transferable architectures for scalable image recognition. arXiv preprint arXiv:1707.07012 , 2017.