Show, Attend and Tell: Neural Image Caption Generation with Visual Attention
Show, Attend and Tell: Neural Image Caption Generation with Visual Attention
看、注意、讲述:带视觉注意力的神经图像描述生成(Show, Attend and Tell: Neural Image Caption Generation with Visual Attention)
Kelvin Xu kelvin.xu@umontreal.ca
Jimmy Lei Ba jimmy@psi.utoronto.ca
Ryan Kiros rkiros@cs.toronto.edu
Kyunghyun Cho kyunghyun.cho@umontreal.ca
Aaron Courville aaron.courville@umontreal.ca
Ruslan Salakhutdinov rsalakhu@cs.toronto.edu
Richard S. Zemel zemel@cs.toronto.edu
Yoshua Bengio find-me@the.web
Abstract
摘要
Inspired by recent work in machine translation and object detection, we introduce an attention based model that automatically learns to describe the content of images. We describe how we can train this model in a deterministic manner using standard backpropagation techniques and stochastically by maximizing a variational lower bound. We also show through visualization how the model is able to automatically learn to fix its gaze on salient objects while generating the corresponding words in the output sequence. We validate the use of attention with state-of-the-art performance on three benchmark datasets: Flickr8k, Flickr30k and MS COCO.
受机器翻译与目标检测近期工作启发,我们引入一种基于注意力的模型,能自动学习描述图像内容。我们说明如何用标准反向传播以确定性方式训练该模型,以及如何通过最大化变分下界以随机方式训练。我们还展示如何在生成描述的过程中可视化注意力的“注视”位置。在 Flickr8k、Flickr30k 与 MS COCO 三个基准数据集上,我们用 BLEU 与 METEOR 指标达到当时最好结果。对注意力的定性分析表明,所学对齐与人类直觉高度吻合。
1 Introduction
1 引言
Automatically generating captions of an image is a task very close to the heart of scene understanding — one of the primary goals of computer vision. Not only must caption generation models be powerful enough to solve the computer vision challenges of determining which objects are in an image, but they must also be capable of capturing and expressing their relationships in a natural language. For this reason, caption generation has long been viewed as a difficult problem. It is a very important challenge for machine learning algorithms, as it amounts to mimicking the remarkable human ability to compress huge amounts of salient visual infomation into descriptive language.
自动生成图像的字幕是一项非常接近场景理解核心的任务——计算机视觉的主要目标之一. 不仅必须使字幕生成模型 我们也能够用自然语言捕捉和表达它们的关系。 因此,标题生成长期以来一直被视为一个困难的问题。 这对机器学习算法来说是一个非常重要的挑战, 如果是模仿人类将大量突出的视觉信息压缩成描述性语言的显著能力。
Despite the challenging nature of this task, there has been a recent surge of research interest in attacking the image caption generation problem. Aided by advances in training neural networks (Krizhevsky et al., 2012) and large classification datasets (Russakovsky et al., 2014), recent work has significantly improved the quality of caption generation using a combination of convolutional neural networks (convnets) to obtain vectorial representation of images and recurrent neural networks to decode those representations into natural language sentences (see Sec. 2).
尽管这一任务很有挑战性,最近仍出现大量研究兴趣。借助深度神经网络(卷积网络与循环网络)的进展,以及用于训练它们的大型分类数据集(Krizhevsky 等, 2012;Ilya Sutskever & Vinyals, 2014),模型现在可以不必再严重依赖复杂的流水线与传统的计算机视觉与自然语言处理技术。
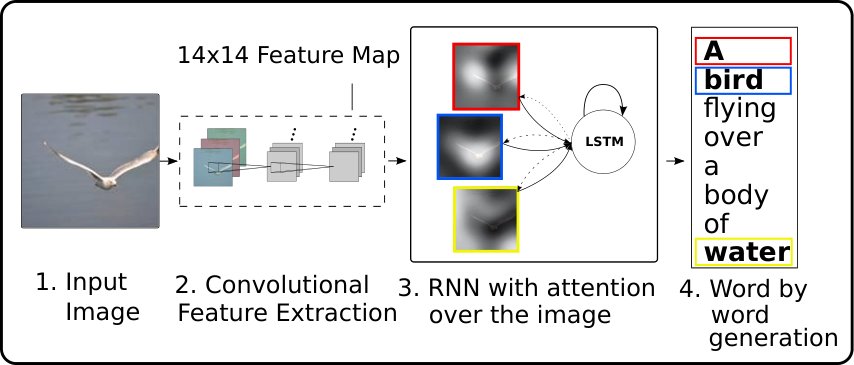
Figure 1: Our model learns a words/image alignment. The visualized attentional maps (3) are explained in section 3.1 & 5.4
图 1:我们的模型学习词与图像的对齐。可视化的注意力图(3)在第 3.1 与 5.4 节解释。
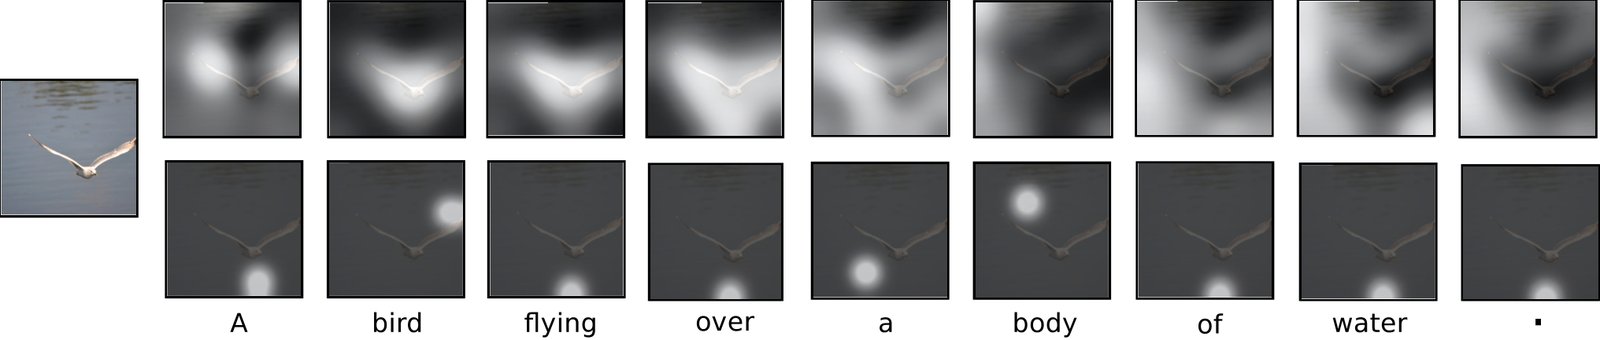
Figure 2: Attention over time. As the model generates each word, its attention changes to reflect the relevant parts of the image. “soft” (top row) vs “hard” (bottom row) attention. (Note that both models generated the same captions in this example.)
图 2:注意力随时间变化。模型每生成一个词,注意力就转向图像中相关的部分。“软”注意力(上行)与“硬”注意力(下行)。(本例中两个模型生成了相同的描述。)
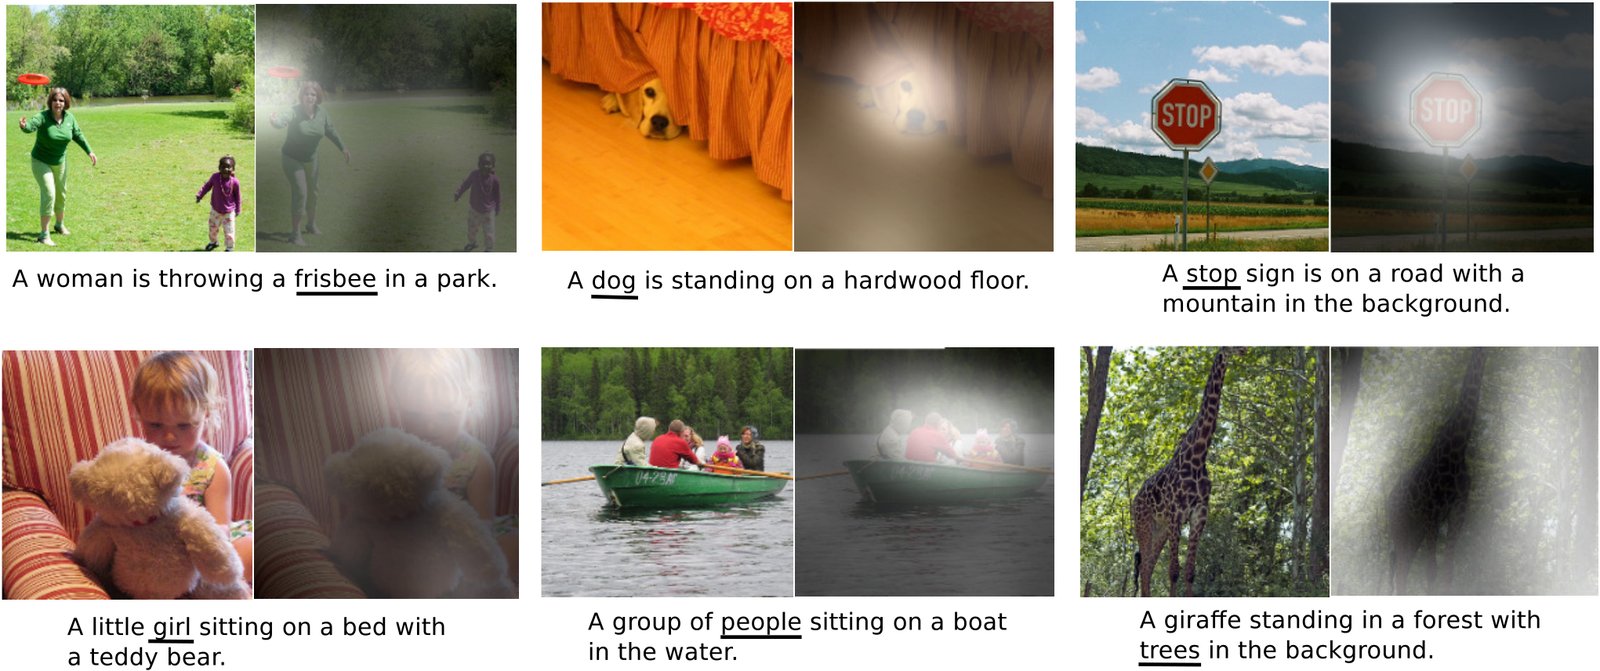
Figure 3: Examples of attending to the correct object (white indicates the attended regions, underlines indicated the corresponding word)
图 3:关注到正确物体的例子(白色表示被关注区域,下划线标出对应的词)
One of the most curious facets of the human visual system is the presence of attention (Rensink, 2000; Corbetta & Shulman, 2002). Rather than compress an entire image into a static representation, attention allows for salient features to dynamically come to the forefront as needed. This is especially important when there is a lot of clutter in an image. Using representations (such as those from the top layer of a convnet) that distill information in image down to the most salient objects is one effective solution that has been widely adopted in previous work. Unfortunately, this has one potential drawback of losing information which could be useful for richer, more descriptive captions. Using more low-level representation can help preserve this information. However working with these features necessitates a powerful mechanism to steer the model to information important to the task at hand.
人类视觉系统最令人好奇的一面是注意力的存在(Rensink, 2000;Corbetta & Shulman, 2002)。注意力并不把整幅图像压成静态表示,而是让显著特征按需动态地走到前台。图像里杂乱物体很多时,这一点尤其重要。用把图像信息蒸馏到最显著物体上的表示(例如卷积网络顶层表示)是先前工作广泛采用的有效做法。但这样做的一个缺点是:一旦信息在这一步被丢掉,后面就无法恢复。
In this paper, we describe approaches to caption generation that attempt to incorporate a form of attention with two variants: a “hard” attention mechanism and a “soft” attention mechanism. We also show how one advantage of including attention is the ability to visualize what the model “sees”. Encouraged by recent advances in caption generation and inspired by recent success in employing attention in machine translation (Bahdanau et al., 2014) and object recognition (Ba et al., 2014; Mnih et al., 2014), we investigate models that can attend to salient part of an image while generating its caption.
本文描述把注意力纳入描述生成的方法,包含两种变体:“硬”注意力机制与“软”注意力机制。我们还说明,加入注意力的一个好处是能够可视化模型“看到”了什么。在描述生成与机器翻译的近期进展鼓励下,我们给出一种可学习的对齐框架,把图像区域与生成词对应起来。
The contributions of this paper are the following:
本文件的贡献如下:
- • We introduce two attention-based image caption generators under a common framework (Sec. 3.1): 1) a “soft” deterministic attention mechanism trainable by standard back-propagation methods and 2) a “hard” stochastic attention mechanism trainable by maximizing an approximate variational lower bound or equivalently by REINFORCE (Williams, 1992).
- • 我们在同一框架下引入两种基于注意力的图像描述生成器(第 3.1 节):1)可用标准反向传播训练的“软”确定性注意力机制;2)可通过最大化近似变分下界、或等价地用 REINFORCE(Williams, 1992)训练的“硬”随机注意力机制。
- • We show how we can gain insight and interpret the results of this framework by visualizing “where” and “what” the attention focused on. (see Sec. 5.4)
- • 我们说明如何可视化模型在生成每个词时关注的图像区域,并表明所学对齐与人类直觉高度一致(第 5.4 节)。
- • Finally, we quantitatively validate the usefulness of attention in caption generation with state of the art performance (Sec. 5.3) on three benchmark datasets: Flickr8k (Hodosh et al., 2013) , Flickr30k (Young et al., 2014) and the MS COCO dataset (Lin et al., 2014).
- • 我们在 Flickr8k、Flickr30k 与 MS COCO 上取得当时最好的 BLEU / METEOR 结果,且使用单模型、不做集成(第 5.3 节)。
2 Related Work
2 相关工作
In this section we provide relevant background on previous work on image caption generation and attention. Recently, several methods have been proposed for generating image descriptions. Many of these methods are based on recurrent neural networks and inspired by the successful use of sequence to sequence training with neural networks for machine translation (Cho et al., 2014; Bahdanau et al., 2014; Sutskever et al., 2014). One major reason image caption generation is well suited to the encoder-decoder framework (Cho et al., 2014) of machine translation is because it is analogous to “translating” an image to a sentence.
在本节中,我们提供了以往关于图像标题生成和关注工作的相关背景。 最近,提出了几种生成图像描述的方法. 许多这些方法都基于反复出现的神经网络,并受到成功及早利用序列与神经网络进行序列培训的启发,用于机器翻译(C 这不是 51.Cho等人,2014年;Bahdanau等人,2014年;Sutskever等人,2014年)。 一个ẫn 原因 的某些方面 图像标题生成非常适合机器翻译的编码器-解码器框架(Cho等人,2014年),因为它类似于将图像“转换”成 你自己的句子。
The first approach to use neural networks for caption generation was Kiros et al. (2014a), who proposed a multimodal log-bilinear model that was biased by features from the image. This work was later followed by Kiros et al. (2014b) whose method was designed to explicitly allow a natural way of doing both ranking and generation. Mao et al. (2014) took a similar approach to generation but replaced a feed-forward neural language model with a recurrent one. Both Vinyals et al. (2014) and Donahue et al. (2014) use LSTM RNNs for their models. Unlike Kiros et al. (2014a) and Mao et al. (2014) whose models see the image at each time step of the output word sequence, Vinyals et al. (2014) only show the image to the RNN at the beginning. Along with images, Donahue et al. (2014) also apply LSTMs to videos, allowing their model to generate video descriptions.
Kiros等人(2014年a)是使用神经网络生成标题的第一个方法提倡采用城里图像特征偏颇的多式对数比线模型行为的受害者。 这部作品后来被正在为明确允许自然的排名和生成本来就允许的方法的基罗斯等人(2014年b)所遵循. Mao等人(2014年)对生成采取了类似的做法,但用反复出现的神经语言模型巷道取代了向导神经语言模型. Vinyals等人(2014年)和Donahue等人(2014年)都使用LSTM RNNs作为模型. 事实上,与基罗斯等人(2014年a)和毛泽东等人(2014年ẩn)不同的是,他们的模型在输出词序列的每个步骤都能看到图像,Vinyals等人(2014年)只在开头向RNN显示图像. Donahue等人(2014年)也将LSTMs应用于视频,使其模型能够生成视频描述.
All of these works represent images as a single feature vector from the top layer of a pre-trained convolutional network. Karpathy & Li (2014) instead proposed to learn a joint embedding space for ranking and generation whose model learns to score sentence and image similarity as a function of R-CNN object detections with outputs of a bidirectional RNN. Fang et al. (2014) proposed a three-step pipeline for generation by incorporating object detections. Their model first learn detectors for several visual concepts based on a multi-instance learning framework. A language model trained on captions was then applied to the detector outputs, followed by rescoring from a joint image-text embedding space. Unlike these models, our proposed attention framework does not explicitly use object detectors but instead learns latent alignments from scratch. This allows our model to go beyond “objectness” and learn to attend to abstract concepts.
所有这些作品都代表着图像作为来自一个预先株式会方面取得了重大进展的演聆网络顶层的单一特征矢量. Karpathy & Li (2014) 转而提议学习一个排名正在开展和生成的联合嵌入空间,其模型学习nake 句子和图像相似度作为R-CNN对象检测功能,其输出为双向RNN.踊跃向Fang等人(2014年)提议采用三步式管道,通过安装物体探测器进行生成。 他们的模型首先撬动基于多层学习框架的几种视觉概念的探测器. 然后,呱嬷在探测器输出才能够使用经过字幕培训的语言模型,然后从联合图像文本嵌入带动空间之间的互动疮。 与这些标明模型不同,我们贯彻的注意框架并没有明确地使用物体探测的基本原理,而是从零开始学习潜在的对齐. 这使得我们的模型能够超越“目标”,؟抽象的概念。
Prior to the use of neural networks for generating captions, two main approaches were dominant. The first involved generating caption templates which were filled in based on the results of object detections and attribute discovery (Kulkarni et al. (2013), Li et al. (2011), Yang et al. (2011), Mitchell et al. (2012), Elliott & Keller (2013)). The second approach was based on first retrieving similar captioned images from a large database then modifying these retrieved captions to fit the query (Kuznetsova et al., 2012; Kuznetsova et al., 2014). These approaches typically involved an intermediate “generalization” step to remove the specifics of a caption that are only relevant to the retrieved image, such as the name of a city. Both of these approaches have since fallen out of favour to the now dominant neural network methods.
在使用神经网络生成标题之前,主要有两种方法。 首先是生成根据物体检测和属性发现结果(Kulkarni等人,2013年;Li等人,2011年;Yang等人,2011年;Mitchell等人,2012年;Elliott & Keller,2013年)填报的字幕对发展的模板。 第二种方法是首先从一个大型数据库检索类似的标题图像,通过以下方式修改这些还将检索到的标题,以适应查询(Kuznetsova等人,2012年;Kuznetsova等人, 2014年)。 这些办法通常涉及ằ 哪一种的结论,即采取中间“一般化”步骤,删除实质内容中仅与取回的图像有关的具体内容, 现在我们可以从城市名称中取出。 这两种方法后来都不再十分重视的目的是现在占主导地位的神经网络方法。
There has been a long line of previous work incorporating attention into neural networks for vision related tasks. Some that share the same spirit as our work include Larochelle & Hinton (2010); Denil et al. (2012); Tang et al. (2014). In particular however, our work directly extends the work of Bahdanau et al. (2014); Mnih et al. (2014); Ba et al. (2014).
过去的工作很长,把注意力纳入神经网络,以完成与愿景有关的任务。 一些与我们的工作具有相同精神的国家包括Larochelle & Hinton(2010年);Denil等人(2012年);Tang等人(2014年)。 然而,我们的工作尤其直接扩展了Bahdanau等人(2014年)、Mnih等人(2014年)、Ba等人(2014年) 明天的工作。
3 Image Caption Generation with Attention Mechanism
3 带注意力机制的图像描述生成
3.1 Model Details
3.1 模型细节
In this section, we describe the two variants of our attention-based model by first describing their common framework. The main difference is the definition of the function which we describe in detail in Section 4. We denote vectors with bolded font and matrices with capital letters. In our description below, we suppress bias terms for readability.
在本节中,我们首先描述了我们以关注为基础的模式的两个变体。 主要的区别在于对函数的定义,我们在 我不禁在第4节中详细描述了这一定义. 我们用粗体表示无法确定的矢量,用大写字母表示矩阵。 在下文的描述中无法确定可读性的偏差术语。
3.1.1 Encoder: Convolutional Features
Our model takes a single raw image and generates a caption encoded as a sequence of 1-of- encoded words.
的一名
我们 为什么该模型罢了? 我们的模型基本上是一个昙花一现的图像 并生成一个被编码为的字符串。
where is the size of the vocabulary and is the length of the caption.
其中ằng XX 我以前是词汇的年龄,而是标题的长度。
We use a convolutional neural network in order to extract a set of feature vectors which we refer to as annotation vectors. The extractor produces vectors, each of which is a D-dimensional representation corresponding to a part of the image.
我们用卷积神经网络提取一组特征向量,称作标注向量。提取器产生 个向量,每个是对应图像某一部分的 维表示。
In order to obtain a correspondence between the feature vectors and portions of the 2-D image, we extract features from a lower convolutional layer unlike previous work which instead used a fully connected layer. This allows the decoder to selectively focus on certain parts of an image by selecting a subset of all the feature vectors.
为了让特征向量与二维图像的局部区域对应起来,我们从较低的卷积层提取特征,而不是像先前工作那样使用全连接层。这样,解码器可以通过选择全部特征向量的一个子集,有选择地聚焦图像的某些部分。
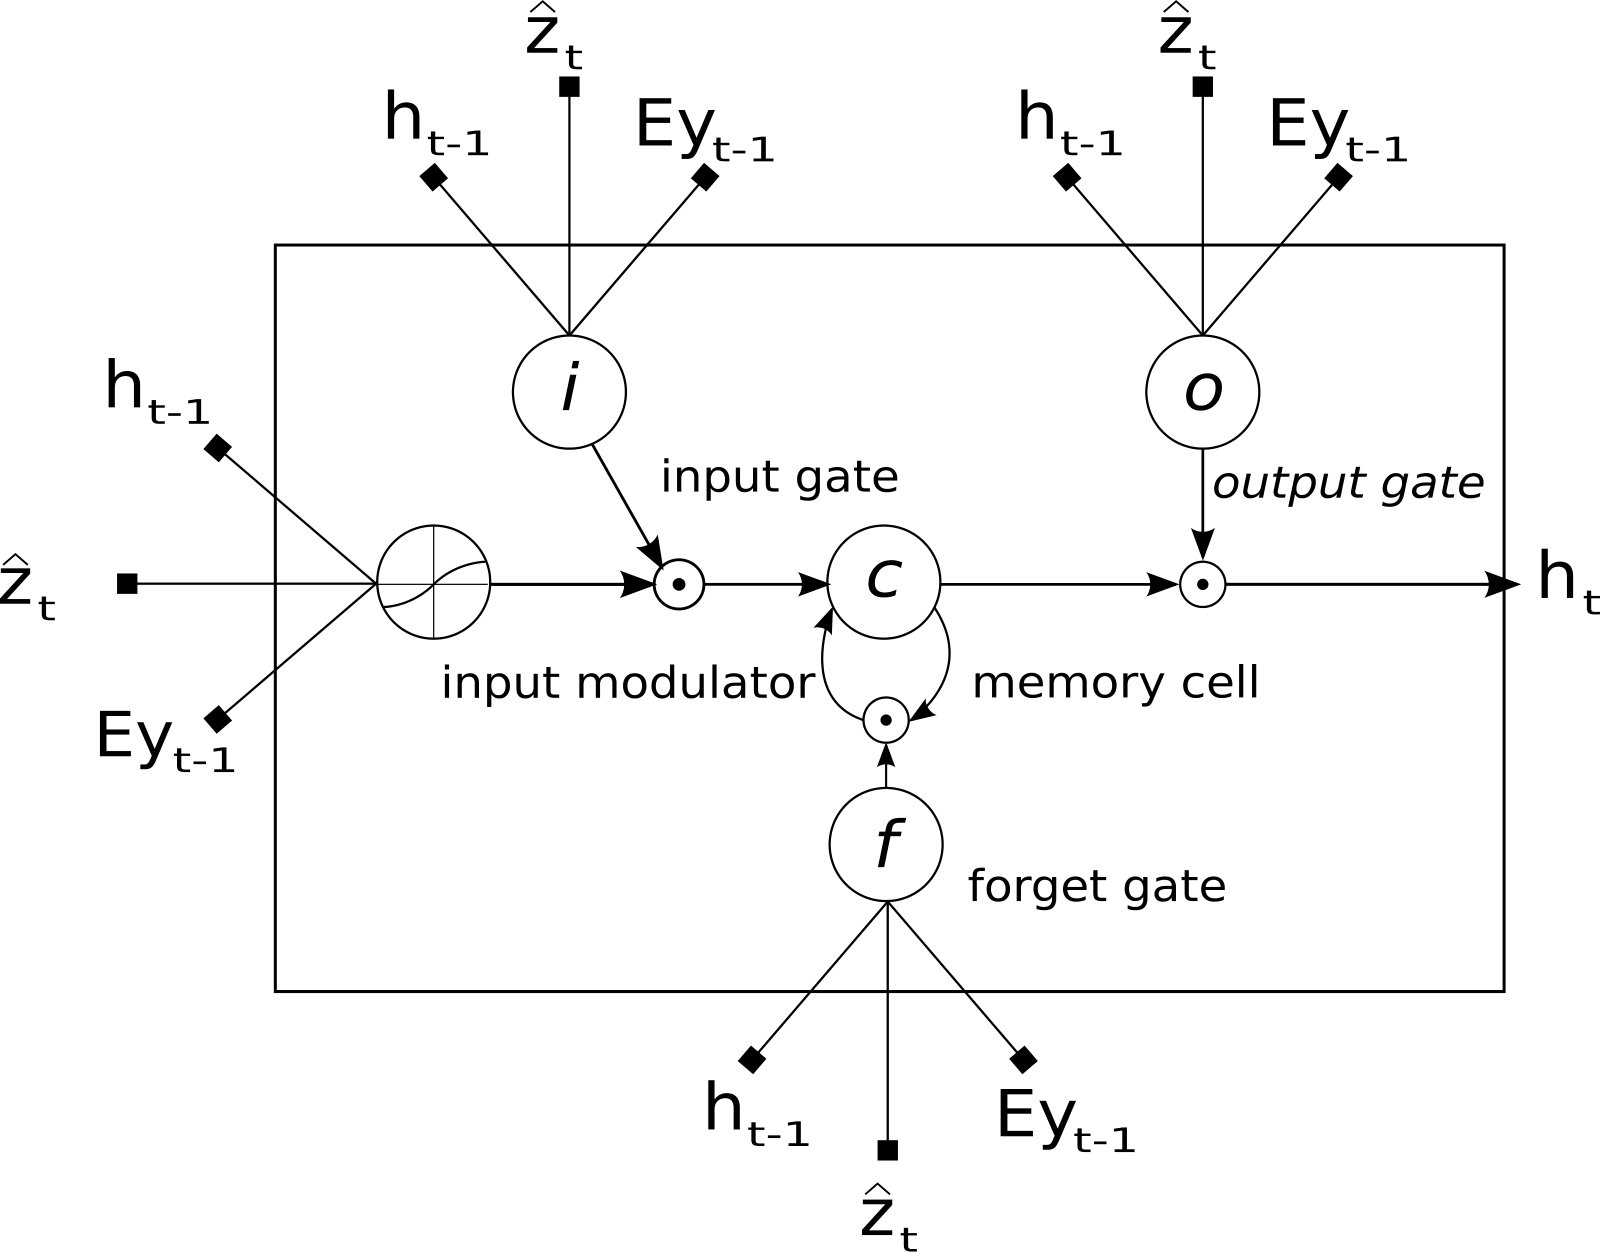
Figure 4: A LSTM cell, lines with bolded squares imply projections with a learnt weight vector. Each cell learns how to weigh its input components (input gate), while learning how to modulate that contribution to the memory (input modulator). It also learns weights which erase the memory cell (forget gate), and weights which control how this memory should be emitted (output gate).
图 4:一个 LSTM 单元;带粗方框的线表示带可学习权重向量的投影。每个单元学习如何对输入分量加权(输入门),如何调节其对记忆的贡献(输入调制),如何擦除记忆(遗忘门),以及如何把记忆暴露给隐状态(输出门)。
3.1.2 Decoder: Long Short-Term Memory Network
We use a long short-term memory (LSTM) network (Hochreiter & Schmidhuber, 1997) that produces a caption by generating one word at every time step conditioned on a context vector, the previous hidden state and the previously generated words. Our implementation of LSTM closely follows the one used in Zaremba et al. (2014) (see Fig. 4). Using to denote a simple affine transformation with parameters that are learned,
3.1.2 解轩:长期短期记忆网.
我们使用一个长期的短期内存(LSTM)网络(H在制订Hochreiter & Schmidhuber,1997年), 未按上下文向量、 先前隐藏状态囤积的状态和先前生成的单词的每个步骤生成一个单词,从而产生一个标题。对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对法律依据对对对对对对对对对对对对对对对对对对对对对对对对对对对的民主和对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对的议程项目对对对对对对对对对对所表明的对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对 Anh对对对对对对对一会对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对对展开了对对对对对对对对ụ对对对对对对对对对对对 使用表示带有所学参数的简单近缘转换,
$$\displaystyle\begin{pmatrix}\mathbf{i}{t}\
\mathbf{f}{t}\
\mathbf{o}{t}\
\mathbf{g}{t}\
\end{pmatrix}= \ \displaystyle\begin{pmatrix}\sigma\
\sigma\
\sigma\
\tanh\
\end{pmatrix}T_{D+m+n,n}\begin{pmatrix}\mathbf{E}\mathbf{y}{t-1}\
\mathbf{h}{t-1}\
\hat{\mathbf{z}{t}}\
\end{pmatrix} \ \displaystyle\mathbf{c}{t} \ \displaystyle=\mathbf{f}{t}\odot\mathbf{c}{t-1}+\mathbf{i}{t}\odot\mathbf{g}{t} \ \displaystyle\mathbf{h}{t} \ \displaystyle=\mathbf{o}{t}\odot\tanh(\mathbf{c}_{t}). \tag{1}$$
Here, , , , , are the input, forget, memory, output and hidden state of the LSTM, respectively. The vector is the context vector, capturing the visual information associated with a particular input location, as explained below. is an embedding matrix. Let and denote the embedding and LSTM dimensionality respectively and and be the logistic sigmoid activation and element-wise multiplication respectively.
这里,、、、、 分别是 LSTM 的输入门、遗忘门、记忆、输出门与隐状态。向量 是上下文向量,捕获与特定输入位置相关的视觉信息,下文说明。 是嵌入矩阵, 是嵌入维数。在条件语言模型语境中,可把投影矩阵 、偏置与嵌入矩阵 理解为解码器的参数。
In simple terms, the context vector (equations (1)–(3)) is a dynamic representation of the relevant part of the image input at time . We define a mechanism that computes from the annotation vectors corresponding to the features extracted at different image locations. For each location , the mechanism generates a positive weight which can be interpreted either as the probability that location is the right place to focus for producing the next word (the “hard” but stochastic attention mechanism), or as the relative importance to give to location in blending the ’s together. The weight of each annotation vector is computed by an attention model for which we use a multilayer perceptron conditioned on the previous hidden state . The soft version of this attention mechanism was introduced by Bahdanau et al. (2014). For emphasis, we note that the hidden state varies as the output RNN advances in its output sequence: “where” the network looks next depends on the sequence of words that has already been generated.
简单地说,上下文向量 (式 (1)–(3))是时刻 与输入图像相关部分对应的动态表示。我们定义机制 ,根据对应不同图像位置提取的标注向量 ,计算 。
Once the weights (which sum to one) are computed, the context vector is computed by
一旦加权数(总和为1)计算出来,则上下文矢量由
where is a function that returns a single vector given the set of annotation vectors and their corresponding weights. The details of function are discussed in Sec. 4.
其中 ′是返回单个矢量的函数,以对应的注释矢量及其相应的权重。 43 第4节讨论了函数的细节。
The initial memory state and hidden state of the LSTM are predicted by an average of the annotation vectors fed through two separate MLPs (init,c and init,h):
LSTM 的初始记忆状态与隐状态,由标注向量的平均经两个独立的 MLP(init,c 与 init,h)预测得到:
In this work, we use a deep output layer (Pascanu et al., 2014) to compute the output word probability given the LSTM state, the context vector and the previous word:
在这部作品中,我们使用深输出层(Pascanu et al., 2014)来计算输出单词概率,考虑到LSTM状态,上下文矢量和上ح的单词:
Where , , , and are learned parameters initialized randomly.
其中 ,,,以及 是随机初始化的可学习参数。
4 Learning Stochastic “Hard” vs Deterministic “Soft” Attention
4 学习随机“硬”注意力与确定性“软”注意力
In this section we discuss two alternative mechanisms for the attention model : stochastic attention and deterministic attention.
实际上是 我只是 听 59/250 上帝 酝 那么你 所有的 你应该 罗 马上 知道了 开始进行
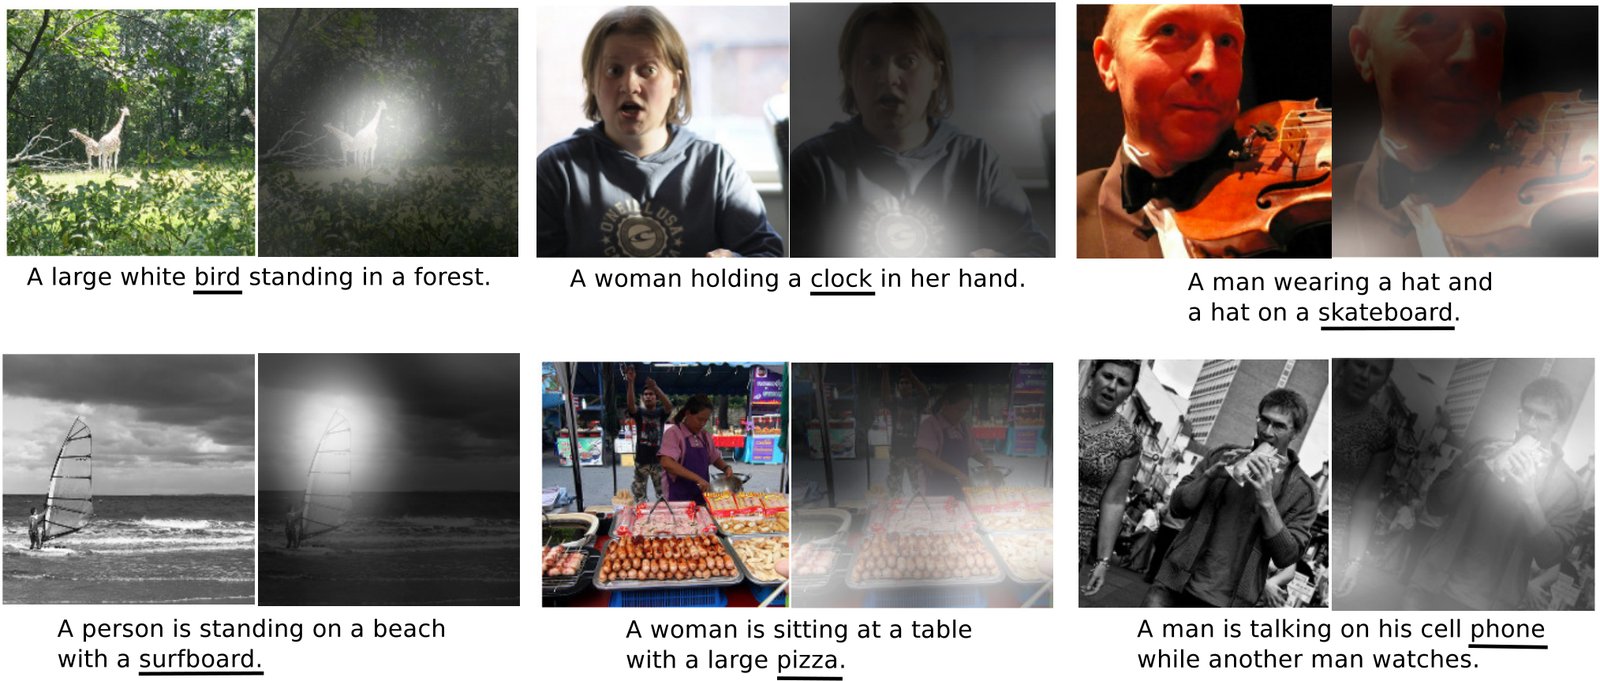
Figure 5: Examples of mistakes where we can use attention to gain intuition into what the model saw.
图 5:可用注意力理解模型“看错了什么”的出错例子。
4.1 Stochastic “Hard” Attention
4.1 随机“硬”注意力
We represent the location variable as where the model decides to focus attention when generating the word. is an indicator one-hot variable which is set to 1 if the -th location (out of ) is the one used to extract visual features. By treating the attention locations as intermediate latent variables, we can assign a multinoulli distribution parametrized by , and view as a random variable:
我们代表的是位置变量,即模型在生成的主题词时决定集中关注的位置. 是一个指标一热变量,如果XXMA▪TH3XX - 第1位(在中)是用来提取视觉特征的,则设定为1 没有. 通过将注意力位置作为中间潜伏变量处理,我们可以指定一个由化的多诺利分布 天呐,并视为随机变量:
We define a new objective function that is a variational lower bound on the marginal log-likelihood of observing the sequence of words given image features . The learning algorithm for the parameters of the models can be derived by directly optimizing :
我们定义新目标函数 ,它是在给定图像特征 时观测到词序列 的边缘对数似然 的变分下界。模型参数 的学习规则可通过直接优化 得到:
$$\frac{\partial L_{s}}{\partial W}=\sum_{s}p(s\mid\mathbf{a})\bigg[\frac{\partial\log p(\mathbf{y}\mid s,\mathbf{a})}{\partial W}+\
\log p(\mathbf{y}\mid s,\mathbf{a})\frac{\partial\log p(s\mid\mathbf{a})}{\partial W}\bigg]. \tag{11}$$
Equation 11 suggests a Monte Carlo based sampling approximation of the gradient with respect to the model parameters. This can be done by sampling the location from a multinouilli distribution defined by Equation 8.
方程式11建议对模型参数的梯度进行基于蒙特卡洛的采样近似。 这可以通过从 我还是方程式8定义能够获得的多努伊利分布物中取样来进行。
$$\frac{\partial L_{s}}{\partial W}\approx\frac{1}{N}\sum_{n=1}^{N}\bigg[\frac{\partial\log p(\mathbf{y}\mid\tilde{s}^{n},\mathbf{a})}{\partial W}+\
\log p(\mathbf{y}\mid\tilde{s}^{n},\mathbf{a})\frac{\partial\log p(\tilde{s}^{n}\mid\mathbf{a})}{\partial W}\bigg] \tag{12}$$
A moving average baseline is used to reduce the variance in the Monte Carlo estimator of the gradient, following Weaver & Tao (2001). Similar, but more complicated variance reduction techniques have previously been used by Mnih et al. (2014) and Ba et al. (2014). Upon seeing the mini-batch, the moving average baseline is estimated as an accumulated sum of the previous log likelihoods with exponential decay:
采用了移动平均基线,以减少Weaver & Tao (2001年) 难道在蒙特卡洛梯度估计值中的差异吗? Mnih等人(2014年)和Ba等人(2014ằng,2014年)以前 你先使用过类似但更为复杂的减差技术。 在看到小批量后,移动女友平均基线估计为指数衰减的 这样以前的的步伐:
To further reduce the estimator variance, an entropy term on the multinouilli distribution is added. Also, with probability 0.5 for a given image, we set the sampled attention location to its expected value . Both techniques improve the robustness of the stochastic attention learning algorithm. The final learning rule for the model is then the following:
为了进一步减少估计提交其差异,在多努伊利分配上 Adriannp憧憬词被添加. 另外,如果精灵图 请将本函及其附件作为安全理事会值为0.5,我们将把 我从没被抽样的注意位置确定为。 这两种技术都提高了斯图克注意力学习算法的稳健性. 模型的最后学习规则是:
$$\frac{\partial L_{s}}{\partial W}\approx\frac{1}{N}\sum_{n=1}^{N}\bigg[\frac{\partial\log p(\mathbf{y}\mid\tilde{s}^{n},\mathbf{a})}{\partial W}+\
\lambda_{r}(\log p(\mathbf{y}\mid\tilde{s}^{n},\mathbf{a})-b)\frac{\partial\log p(\tilde{s}^{n}\mid\mathbf{a})}{\partial W}+\lambda_{e}\frac{\partial H[\tilde{s}^{n}]}{\partial W}\bigg] \tag{13}$$
where, and are two hyper-parameters set by cross-validation. As pointed out and used in Ba et al. (2014) and Mnih et al. (2014), this is formulation is equivalent to the REINFORCE learning rule (Williams, 1992), where the reward for the attention choosing a sequence of actions is a real value proportional to the log likelihood of the target sentence under the sampled attention trajectory.
其中,鼎 ()和鼎XX()是通过交叉验证设定的两个超参数. 正如Ba方面的努力是吗( 我们去2014年)和Mnih等人的报告(2014年)所指出和使用的那样,这种提法相当于REINFORCE学习规则(Williams,1992年),其中对注意选择一系列行动给予的奖励是相对于抽样注意轨迹下目标句 我们走吧对数可能性的实际价值。
In making a hard choice at every point, from Equation 6 is a function that returns a sampled at every point in time based upon a multinouilli distribution parameterized by .
我应该在每点进行硬性选择时,从方程式6的是一个函数,它会基于由 化的多努伊利分布参数,在每点返回一个样本的. 我们有这样的功能.
4.2 Deterministic “Soft” Attention
4.2 确定性“软”注意力
Learning stochastic attention requires sampling the attention location each time, instead we can take the expectation of the context vector directly,
学习随机注意力需要每次采样注意力位置 ;我们也可以直接取上下文向量 的期望,
and formulate a deterministic attention model by computing a soft attention weighted annotation vector as introduced by Bahdanau et al. (2014). This corresponds to feeding in a soft weighted context into the system. The whole model is smooth and differentiable under the deterministic attention, so learning end-to-end is trivial by using standard back-propagation.
并像 Bahdanau 等人(2014)那样,用软注意力加权的标注向量 构成确定性注意力模型。这相当于把经软 加权的上下文送入系统。整个模型因此可微,可用标准反向传播训练。
Learning the deterministic attention can also be understood as approximately optimizing the marginal likelihood in Equation 10 under the attention location random variable from Sec. 4.1. The hidden activation of LSTM is a linear projection of the stochastic context vector followed by non-linearity. To the first order Taylor approximation, the expected value is equal to computing using a single forward prop with the expected context vector . Considering Eq. 7, let , denotes computed by setting the random variable value to . We define the normalized weighted geometric mean for the softmax word prediction:
学习确定性注意力也可以理解为:在第 4.1 节的注意力位置随机变量 下,近似优化式 (10) 中的边缘似然。LSTM 的隐激活 是随机上下文向量 的线性投影再接 非线性。
The equation above shows the normalized weighted geometric mean of the caption prediction can be approximated well by using the expected context vector, where . It shows that the NWGM of a softmax unit is obtained by applying softmax to the expectations of the underlying linear projections. Also, from the results in Baldi & Sadowski (2014), under softmax activation. That means the expectation of the outputs over all possible attention locations induced by random variable is computed by simple feedforward propagation with expected context vector . In other words, the deterministic attention model is an approximation to the marginal likelihood over the attention locations.
以上方程显示,通过使用预期的上下文矢量,可以很好地大致得出标题预测的正常加权几何平均值。 它表明,实施一项软马克就其单位的NWGM是通过将软马克应用到联合国系统各基础线性预测的预期中来获得的. 另外,根据Baldi &政府提供的结果好几两族(2014年 我保证),在软马克斯激活下. 他们是通过使用预期的上下文 什么事? 换句话说,决定性关注模型是相对于关注地点的边际可能性的近似.
4.2.1 Doubly Stochastic Attention
By construction, as they are the output of a softmax. In training the deterministic version of our model we introduce a form of doubly stochastic regularization, where we also encourage . This can be interpreted as encouraging the model to pay equal attention to every part of the image over the course of generation. In our experiments, we observed that this penalty was important quantitatively to improving overall BLEU score and that qualitatively this leads to more rich and descriptive captions. In addition, the soft attention model predicts a gating scalar from previous hidden state at each time step , such that, , where . We notice our attention weights put more emphasis on the objects in the images by including the scalar .
4.2.1 双重随机注意力
由构造可知,,因为它们是 softmax 的输出。在训练确定性版本时,我们引入一种双重随机正则:同时鼓励 。这可以理解为鼓励模型在整句生成过程中对每个空间位置给予大致均等的总关注,避免注意力塌缩到少数区域。
| BLEU | |||||||||||||||||||||||||||||||||||||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Dataset | Model | BLEU-1 | BLEU-2 | BLEU-3 | BLEU-4 | METEOR | |||||||||||||||||||||||||||||||||||||||||||
| Flickr8k | Google NIC(Vinyals et al., 2014)†Σ Log Bilinear (Kiros et al., 2014a)∘ Soft-Attention Hard-Attention | Google NIC(Vinyals et al., 2014)†Σ | Log Bilinear (Kiros et al., 2014a)∘ | Soft-Attention | Hard-Attention | 63 65.6 67 67 | 63 | 65.6 | 67 | 67 | 41 42.4 44.8 45.7 | 41 | 42.4 | 44.8 | 45.7 | 27 27.7 29.9 31.4 | 27 | 27.7 | 29.9 | 31.4 | — 17.7 19.5 21.3 | — | 17.7 | 19.5 | 21.3 | — 17.31 18.93 20.30 | — | 17.31 | 18.93 | 20.30 | |||||||||||||||||||
| Google NIC(Vinyals et al., 2014)†Σ | |||||||||||||||||||||||||||||||||||||||||||||||||
| Log Bilinear (Kiros et al., 2014a)∘ | |||||||||||||||||||||||||||||||||||||||||||||||||
| Soft-Attention | |||||||||||||||||||||||||||||||||||||||||||||||||
| Hard-Attention | |||||||||||||||||||||||||||||||||||||||||||||||||
| 63 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 65.6 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 67 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 67 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 41 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 42.4 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 44.8 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 45.7 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 27 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 27.7 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 29.9 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 31.4 | |||||||||||||||||||||||||||||||||||||||||||||||||
| — | |||||||||||||||||||||||||||||||||||||||||||||||||
| 17.7 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 19.5 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 21.3 | |||||||||||||||||||||||||||||||||||||||||||||||||
| — | |||||||||||||||||||||||||||||||||||||||||||||||||
| 17.31 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 18.93 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 20.30 | |||||||||||||||||||||||||||||||||||||||||||||||||
| Flickr30k | Google NIC†∘Σ Log Bilinear Soft-Attention Hard-Attention | Google NIC†∘Σ | Log Bilinear | Soft-Attention | Hard-Attention | 66.3 60.0 66.7 66.9 | 66.3 | 60.0 | 66.7 | 66.9 | 42.3 38 43.4 43.9 | 42.3 | 38 | 43.4 | 43.9 | 27.7 25.4 28.8 29.6 | 27.7 | 25.4 | 28.8 | 29.6 | 18.3 17.1 19.1 19.9 | 18.3 | 17.1 | 19.1 | 19.9 | — 16.88 18.49 18.46 | — | 16.88 | 18.49 | 18.46 | |||||||||||||||||||
| Google NIC†∘Σ | |||||||||||||||||||||||||||||||||||||||||||||||||
| Log Bilinear | |||||||||||||||||||||||||||||||||||||||||||||||||
| Soft-Attention | |||||||||||||||||||||||||||||||||||||||||||||||||
| Hard-Attention | |||||||||||||||||||||||||||||||||||||||||||||||||
| 66.3 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 60.0 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 66.7 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 66.9 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 42.3 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 38 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 43.4 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 43.9 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 27.7 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 25.4 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 28.8 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 29.6 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 18.3 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 17.1 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 19.1 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 19.9 | |||||||||||||||||||||||||||||||||||||||||||||||||
| — | |||||||||||||||||||||||||||||||||||||||||||||||||
| 16.88 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 18.49 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 18.46 | |||||||||||||||||||||||||||||||||||||||||||||||||
| COCO | CMU/MS Research (Chen & Zitnick, 2014)a MS Research (Fang et al., 2014)†a BRNN (Karpathy & Li, 2014)∘ Google NIC†∘Σ Log Bilinear∘ Soft-Attention Hard-Attention | CMU/MS Research (Chen & Zitnick, 2014)a | MS Research (Fang et al., 2014)†a | BRNN (Karpathy & Li, 2014)∘ | Google NIC†∘Σ | Log Bilinear∘ | Soft-Attention | Hard-Attention | — — 64.2 66.6 70.8 70.7 71.8 | — | — | 64.2 | 66.6 | 70.8 | 70.7 | 71.8 | — — 45.1 46.1 48.9 49.2 50.4 | — | — | 45.1 | 46.1 | 48.9 | 49.2 | 50.4 | — — 30.4 32.9 34.4 34.4 35.7 | — | — | 30.4 | 32.9 | 34.4 | 34.4 | 35.7 | — — 20.3 24.6 24.3 24.3 25.0 | — | — | 20.3 | 24.6 | 24.3 | 24.3 | 25.0 | 20.41 20.71 — — 20.03 23.90 23.04 | 20.41 | 20.71 | — | — | 20.03 | 23.90 | 23.04 | |
| CMU/MS Research (Chen & Zitnick, 2014)a | |||||||||||||||||||||||||||||||||||||||||||||||||
| MS Research (Fang et al., 2014)†a | |||||||||||||||||||||||||||||||||||||||||||||||||
| BRNN (Karpathy & Li, 2014)∘ | |||||||||||||||||||||||||||||||||||||||||||||||||
| Google NIC†∘Σ | |||||||||||||||||||||||||||||||||||||||||||||||||
| Log Bilinear∘ | |||||||||||||||||||||||||||||||||||||||||||||||||
| Soft-Attention | |||||||||||||||||||||||||||||||||||||||||||||||||
| Hard-Attention | |||||||||||||||||||||||||||||||||||||||||||||||||
| — | |||||||||||||||||||||||||||||||||||||||||||||||||
| — | |||||||||||||||||||||||||||||||||||||||||||||||||
| 64.2 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 66.6 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 70.8 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 70.7 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 71.8 | |||||||||||||||||||||||||||||||||||||||||||||||||
| — | |||||||||||||||||||||||||||||||||||||||||||||||||
| — | |||||||||||||||||||||||||||||||||||||||||||||||||
| 45.1 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 46.1 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 48.9 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 49.2 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 50.4 | |||||||||||||||||||||||||||||||||||||||||||||||||
| — | |||||||||||||||||||||||||||||||||||||||||||||||||
| — | |||||||||||||||||||||||||||||||||||||||||||||||||
| 30.4 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 32.9 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 34.4 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 34.4 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 35.7 | |||||||||||||||||||||||||||||||||||||||||||||||||
| — | |||||||||||||||||||||||||||||||||||||||||||||||||
| — | |||||||||||||||||||||||||||||||||||||||||||||||||
| 20.3 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 24.6 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 24.3 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 24.3 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 25.0 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 20.41 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 20.71 | |||||||||||||||||||||||||||||||||||||||||||||||||
| — | |||||||||||||||||||||||||||||||||||||||||||||||||
| — | |||||||||||||||||||||||||||||||||||||||||||||||||
| 20.03 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 23.90 | |||||||||||||||||||||||||||||||||||||||||||||||||
| 23.04 |
| Google NIC(Vinyals et al., 2014)†Σ |
|---|
| Log Bilinear (Kiros et al., 2014a)∘ |
| Soft-Attention |
| Hard-Attention |
| 63 |
|---|
| 65.6 |
| 67 |
| 67 |
| 41 |
|---|
| 42.4 |
| 44.8 |
| 45.7 |
| 27 |
|---|
| 27.7 |
| 29.9 |
| 31.4 |
| — |
|---|
| 17.7 |
| 19.5 |
| 21.3 |
| — |
|---|
| 17.31 |
| 18.93 |
| 20.30 |
| Google NIC†∘Σ |
|---|
| Log Bilinear |
| Soft-Attention |
| Hard-Attention |
| 66.3 |
|---|
| 60.0 |
| 66.7 |
| 66.9 |
| 42.3 |
|---|
| 38 |
| 43.4 |
| 43.9 |
| 27.7 |
|---|
| 25.4 |
| 28.8 |
| 29.6 |
| 18.3 |
|---|
| 17.1 |
| 19.1 |
| 19.9 |
| — |
|---|
| 16.88 |
| 18.49 |
| 18.46 |
| CMU/MS Research (Chen & Zitnick, 2014)a |
|---|
| MS Research (Fang et al., 2014)†a |
| BRNN (Karpathy & Li, 2014)∘ |
| Google NIC†∘Σ |
| Log Bilinear∘ |
| Soft-Attention |
| Hard-Attention |
| — |
|---|
| — |
| 64.2 |
| 66.6 |
| 70.8 |
| 70.7 |
| 71.8 |
| — |
|---|
| — |
| 45.1 |
| 46.1 |
| 48.9 |
| 49.2 |
| 50.4 |
| — |
|---|
| — |
| 30.4 |
| 32.9 |
| 34.4 |
| 34.4 |
| 35.7 |
| — |
|---|
| — |
| 20.3 |
| 24.6 |
| 24.3 |
| 24.3 |
| 25.0 |
| 20.41 |
|---|
| 20.71 |
| — |
| — |
| 20.03 |
| 23.90 |
| 23.04 |
Table 1: BLEU-1,2,3,4/METEOR metrics compared to other methods, indicates a different split, (—) indicates an unknown metric, indicates the authors kindly provided missing metrics by personal communication, indicates an ensemble, indicates using AlexNet
表 1:Flickr8k、Flickr30k 与 MS COCO 上的 BLEU-1..4 与 METEOR。Soft-Attention 与 Hard-Attention 为我们的模型;与使用可比卷积特征的先前结果对照。加粗为各列最优。详细数字见原文表 1。
Concretely, the model is trained end-to-end by minimizing the following penalized negative log-likelihood:
啸 具体地说,该模式通过尽量减少以下受的案件中的负对数而经过了 Minnesota 天呐 。
4.3 Training Procedure
4.3 训练过程
Both variants of our attention model were trained with stochastic gradient descent using adaptive learning rate algorithms. For the Flickr8k dataset, we found that RMSProp (Tieleman & Hinton, 2012) worked best, while for Flickr30k/MS COCO dataset we used the recently proposed Adam algorithm (Kingma & Ba, 2014) .
我们的注意力模型的两种变体 都通过适应性学习速率算法 进行了有弹性的梯度下降训练 Flickr8k数据集,我们发现RMSProp(Tiele 操控公司(Tieleman & Hinton,2012年))效果最好,而Flickr30k/MS COCO数据集则采用了最近提出的Adam算法(Kingma & Ba,2014年)。
To create the annotations used by our decoder, we used the Oxford VGGnet (Simonyan & Zisserman, 2014) pre-trained on ImageNet without finetuning. In principle however, any encoding function could be used. In addition, with enough data, we could also train the encoder from scratch (or fine-tune) with the rest of the model. In our experiments we use the 1414512 feature map of the fourth convolutional layer before max pooling. This means our decoder operates on the flattened 196 512 (i.e ) encoding.
为了创建我们解码器使用的注释,我们使用了牛津VGGnet(Simonyan & Zisserman,2014年)在ImageNet上预训,没有开始进行微调. 然而,原则上可以使用任何编码功能。 此外,只要有足够的数据,我们还可以从零开始(或微调)与模型的其余见下表训练编码器. 在我们的实验中 我们用 14 XX 那就是14512 地貌图 在最大集合之前 第四演勉强层。 这意味着我们的解码器在扁平的196512(即)编码上运行.
As our implementation requires time proportional to the length of the longest sentence per update, we found training on a random group of captions to be computationally wasteful. To mitigate this problem, in preprocessing we build a dictionary mapping the length of a sentence to the corresponding subset of captions. Then, during training we randomly sample a length and retrieve a mini-batch of size 64 of that length. We found that this greatly improved convergence speed with no noticeable diminishment in performance. On our largest dataset (MS COCO), our soft attention model took less than 3 days to train on an NVIDIA Titan Black GPU.
由于我们的执行需要时间与每次更新最长刑期的长度成比例,我们发现随机编组标题的培训在计算上是浪费的。 为了的执行工作减轻这一问题,在预处理中,我们建立一个字典,将句子长度平等地映射到为实现相应的标题子集。 然后,在训练期间,我们随机抽取一个长度, 并取回一个小批量64的长度。 我们发现,这大大提高在这一过程中的汇合速度,没有明显降低业绩 这是我们的事业。嗡嗡声在最大的数据集(MS COCO)上,我们的软注意力模型用了不到3天的时间来训练NVIDIA泰坦黑色GP 43.
In addition to dropout (Srivastava et al., 2014), the only other regularization strategy we used was early stopping on BLEU score. We observed a breakdown in correlation between the validation set log-likelihood and BLEU in the later stages of training during our experiments. Since BLEU is the most commonly reported metric, we used BLEU on our validation set for model selection.
除了辍学(Sri的提议,Srivastava等人,2014年)外,我们采用的唯一其他正规化战略是提前停止对BLEU的评分。 列车下 24.5 列车下方 由于溴化 你们最常用的衡量标准,我们用BLEU进行模型选择的验证。
In our experiments with soft attention, we also used Whetlab[^1] (Snoek et al., 2012; Snoek et al., 2014) in our Flickr8k experiments. Some of the intuitions we gained from hyperparameter regions it explored were especially important in our Flickr30k and COCO experiments.
在我们以软注意力进行的实验中,我们还在Flickr8k实验中使用了Whetlab^1。 待我们探索的超参数区域中,
We make our code for these models based in Theano (Bergstra et al., 2010) publicly available upon publication to encourage future research in this area.
我们公布基于咀诺(Bergstra等人,2010年)的这些模型凳码,以鼓励今后在这一领域进行研究。
5 Experiments
5 实验
We describe our experimental methodology and quantitative results which validate the effectiveness of our model for caption generation.
本节说明评估流程与和先前工作比较时需要注意的几点。
5.1 Data
5.1 数据
We report results on the popular Flickr8k and Flickr30k dataset which has 8,000 and 30,000 images respectively as well as the more challenging Microsoft COCO dataset which has 82,783 images. The Flickr8k/Flickr30k dataset both come with 5 reference sentences per image, but for the MS COCO dataset, some of the images have references in excess of 5 which for consistency across our datasets we discard. We applied only basic tokenization to MS COCO so that it is consistent with the tokenization present in Flickr8k and Flickr30k. For all our experiments, we used a fixed vocabulary size of 10,000.
我们在常用的 Flickr8k(8,000 张图)与 Flickr30k(30,000 张图)以及更具挑战的 Microsoft COCO(82,783 张图)上报告结果。Flickr8k/Flickr30k 每张图有 5 条参考句;MS COCO 部分图像参考句超过 5 条,为保持一致我们丢弃多余的。对 MS COCO 只做了与 Flickr 一致的基本分词。所有实验词表大小固定为 10,000。
Results for our attention-based architecture are reported in Table 1. We report results with the frequently used BLEU metric[^2] which is the standard in the caption generation literature. We report BLEU from 1 to 4 without a brevity penalty. There has been, however, criticism of BLEU, so in addition we report another common metric METEOR (Denkowski & Lavie, 2014), and compare whenever possible.
基于关注的架构的成果见表1。 我们报告身份 与喀什喀什喀什各种不同的身份 喀什喀什喀什喀什喀 phải 我们报告BLEU从1到4,问题的讨论没有很短的处罚。 然而,人们一直对BLEU提出批评,因此我们除了报告另一个通用的公制METEOR(Denkowski & Lavie,2014年),并尽可能进行比较靖.
5.2 Evaluation Procedures
5.2 评估流程
A few challenges exist for comparison, which we explain here. The first is a difference in choice of convolutional feature extractor. For identical decoder architectures, using more recent architectures such as GoogLeNet or Oxford VGG Szegedy et al. (2014), Simonyan & Zisserman (2014) can give a boost in performance over using the AlexNet (Krizhevsky et al., 2012). In our evaluation, we compare directly only with results which use the comparable GoogLeNet/Oxford VGG features, but for METEOR comparison we note some results that use AlexNet.
有一些挑战需要比较,我们在这里对此作了解释。 第一种是区别于对演化特征提取器的选择. 对于和其他人一样的解码器建筑,使用 我猜Google包括为GoogleNet 或 Oxford一声GGG Szegedy et al. (2014) , Simonyan & Zisserman (2014) 可以在使用 AlexNet 的基础上提升性能(Krizzevsky et al., 2012岔). 在我们的评价中,我们只直接比较使用可比的GoogleNet/Oxford VGG特性的结果,但对于ME所给予的比较我们注意到的批准使用AlexNet的一些结果。
The second challenge is a single model versus ensemble comparison. While other methods have reported performance boosts by using ensembling, in our results we report a single model performance.
第二个挑战是单一模式与综艺比较。 虽然其他方法都报告的临时议程通过综艺促进业绩,但我们在结果中报告的是单一的示范业绩。
Finally, there is challenge due to differences between dataset splits. In our reported results, we use the pre-defined splits of Flickr8k. However, one challenge for the Flickr30k and COCO datasets is the lack of standardized splits. As a result, we report with the publicly available splits[^3] used in previous work (Karpathy & Li, 2014). In our experience, differences in splits do not make a substantial difference in overall performance, but we note the differences where they exist.
最后,由于数据集分割的差异,存在挑战。 在报导结果中,矛头不明 1995年, 因此, 你确定在前一部作品中使用的可公开获取的分 我们得报告[^3 ♪(Karopathy & Li将提供,2014年)。 充分地说,根据我们的经验,分歧对发展的总体表现没有实质性的区别,但我们注意到存在分歧的地方。
5.3 Quantitative Analysis
5.3 定量分析
In Table 1, we provide a summary of the experiment validating the quantitative effectiveness of attention. We obtain state of the art performance on the Flickr8k, Flickr30k and MS COCO. In addition, we note that in our experiments we are able to significantly improve the state of the art performance METEOR on MS COCO that we speculate is connected to some of the regularization techniques we used 4.2.1 and our lower level representation. Finally, we also note that we are able to obtain this performance using a single model without an ensemble.
表 1 汇总了验证注意力定量效果的实验。我们在 Flickr8k、Flickr30k 与 MS COCO 上取得当时最好表现。此外,在 MS COCO 上我们显著提升了 METEOR 的最好结果,我们推测这与第 4.2.1 节的正则以及更低层的空间表示有关。最后,这些结果来自单模型,没有使用集成。
5.4 Qualitative Analysis: Learning to attend
5.4 定性分析:学会注视
By visualizing the attention component learned by the model, we are able to add an extra layer of interpretability to the output of the model (see Fig. 1). Other systems that have done this rely on object detection systems to produce candidate alignment targets (Karpathy & Li, 2014). Our approach is much more flexible, since the model can attend to “non object” salient regions.
通过可视化模型学到的注意力分量,我们能为模型输出增加一层可解释性(见图 1)。其他做过类似事的系统依赖目标检测产生候选对齐目标(Karpathy & Li, 2014)。我们的方法更灵活,因为模型可以关注“非对象”的显著区域。
The 19-layer OxfordNet uses stacks of 3x3 filters meaning the only time the feature maps decrease in size are due to the max pooling layers. The input image is resized so that the shortest side is 256 dimensional with preserved aspect ratio. The input to the convolutional network is the center cropped 224x224 image. Consequently, with 4 max pooling layers we get an output dimension of the top convolutional layer of 14x14. Thus in order to visualize the attention weights for the soft model, we simply upsample the weights by a factor of = 16 and apply a Gaussian filter. We note that the receptive fields of each of the 14x14 units are highly overlapping.
19层的OxfordNet使用3x3滤镜的堆栈,意思是特性图缩小的唯一一次是由于最大集合层.则是将输入 Collins并为此腻度 61. 这几个小尺寸的图像向最不发达国家提供调整,以便最顺便的一面是256维作出有效的保存宽度比。 Natalie. 进化网的输入是中央所裁剪的224x 在这段图像上. 因此,有了4个 你在干什么最大集合层 我们得到了一个输出维度 在顶层 14x14。 因此,为了将软模型的注意力权重直观化,我们简单地将权重用 = 16的因子来做一个样本,并应用一个 高霄 这里是高 坐式滤波器. 我们注意到,14x14单元中的每一个单元的下列方面高度重叠。
As we can see in Figure 2 and 3, the model learns alignments that correspond very strongly with human intuition. Especially in the examples of mistakes, we see that it is possible to exploit such visualizations to get an intuition as to why those mistakes were made. We provide a more extensive list of visualizations in Appendix A for the reader.
正如我们在 你喜欢图2和图3中看到的 再见 特别是在犯将其视为错误的事例中,我们发现有可能利用这种可视化来了解这些错误的原因。 我们提供了蛊惑读者的附录A中更为豺张的可视化清单.
6 Conclusion
6 结论
We propose an attention based approach that gives state of the art performance on three benchmark datasets using the BLEU and METEOR metric. We also show how the learned attention can be exploited to give more interpretability into the models generation process, and demonstrate that the learned alignments correspond very well to human intuition. We hope that the results of this paper will encourage future work in using visual attention. We also expect that the modularity of the encoder-decoder approach combined with attention to have useful applications in other domains.
我们提出一种基于注意力的方法,在三个基准数据集上以 BLEU 与 METEOR 达到当时最好表现。我们还说明如何利用所学注意力,让生成过程更可解释,并表明所学对齐与人类直觉高度吻合。
Acknowledgments
致谢
The authors would like to thank the developers of Theano (Bergstra et al., 2010; Bastien et al., 2012). We acknowledge the support of the following organizations for research funding and computing support: the Nuance Foundation, NSERC, Samsung, Calcul Québec, Compute Canada, the Canada Research Chairs and CIFAR. The authors would also like to thank Nitish Srivastava for assistance with his ConvNet package as well as preparing the Oxford convolutional network and Relu Patrascu for helping with numerous infrastructure related problems.
作者们要感谢Theano的开发者(Bergstra等人,2010年;Bastien等人,2012为妇女提供)。 我们感谢髻斯基金会、NSERC、三星、魁北克的家庭、计算加拿大、加拿大研究主席和CIFAR抨击中心等组织对能够得到研究资金和计算支持的支持。 提交人还感谢Nitish Srivawheeltava 妈的ConvNet渊源的协助撬动 我听说了牛津革命与各国的交流只是个小问题。
References
参考文献
Ba et al. (2014) Ba, Jimmy Lei, Mnih, Volodymyr, and Kavukcuoglu, Koray. Multiple object recognition with visual attention. arXiv: 1412.7755 , December 2014.
Bahdanau et al. (2014) Bahdanau, Dzmitry, Cho, Kyunghyun, and Bengio, Yoshua. Neural machine translation by jointly learning to align and translate. arXiv: 1409.0473 , September 2014.
Baldi & Sadowski (2014) Baldi, Pierre and Sadowski, Peter. The dropout learning algorithm. Artificial intelligence , 210:78–122, 2014.
Bastien et al. (2012) Bastien, Frederic, Lamblin, Pascal, Pascanu, Razvan, Bergstra, James, Goodfellow, Ian, Bergeron, Arnaud, Bouchard, Nicolas, Warde-Farley, David, and Bengio, Yoshua. Theano: new features and speed improvements. Submited to the Deep Learning and Unsupervised Feature Learning NIPS 2012 Workshop, 2012.
Bergstra et al. (2010) Bergstra, James, Breuleux, Olivier, Bastien, Frédéric, Lamblin, Pascal, Pascanu, Razvan, Desjardins, Guillaume, Turian, Joseph, Warde-Farley, David, and Bengio, Yoshua. Theano: a CPU and GPU math expression compiler. In Proceedings of the Python for Scientific Computing Conference (SciPy) , 2010.
Chen & Zitnick (2014) Chen, Xinlei and Zitnick, C Lawrence. Learning a recurrent visual representation for image caption generation. arXiv preprint arXiv:1411.5654 , 2014.
Cho et al. (2014) Cho, Kyunghyun, van Merrienboer, Bart, Gulcehre, Caglar, Bougares, Fethi, Schwenk, Holger, and Bengio, Yoshua. Learning phrase representations using RNN encoder-decoder for statistical machine translation. In EMNLP , October 2014.
Corbetta & Shulman (2002) Corbetta, Maurizio and Shulman, Gordon L. Control of goal-directed and stimulus-driven attention in the brain. Nature reviews neuroscience , 3(3):201–215, 2002.
Denil et al. (2012) Denil, Misha, Bazzani, Loris, Larochelle, Hugo, and de Freitas, Nando. Learning where to attend with deep architectures for image tracking. Neural Computation , 2012.
Denkowski & Lavie (2014) Denkowski, Michael and Lavie, Alon. Meteor universal: Language specific translation evaluation for any target language. In Proceedings of the EACL 2014 Workshop on Statistical Machine Translation , 2014.
Donahue et al. (2014) Donahue, Jeff, Hendrikcs, Lisa Anne, Guadarrama, Segio, Rohrbach, Marcus, Venugopalan, Subhashini, Saenko, Kate, and Darrell, Trevor. Long-term recurrent convolutional networks for visual recognition and description. arXiv: 1411.4389v2 , November 2014.
Elliott & Keller (2013) Elliott, Desmond and Keller, Frank. Image description using visual dependency representations. In EMNLP , 2013.
Fang et al. (2014) Fang, Hao, Gupta, Saurabh, Iandola, Forrest, Srivastava, Rupesh, Deng, Li, Dollár, Piotr, Gao, Jianfeng, He, Xiaodong, Mitchell, Margaret, Platt, John, et al. From captions to visual concepts and back. arXiv: 1411.4952 , November 2014.
Hochreiter & Schmidhuber (1997) Hochreiter, S. and Schmidhuber, J. Long short-term memory. Neural Computation , 9(8):1735–1780, 1997.
Hodosh et al. (2013) Hodosh, Micah, Young, Peter, and Hockenmaier, Julia. Framing image description as a ranking task: Data, models and evaluation metrics. Journal of Artificial Intelligence Research , pp. 853–899, 2013.
Karpathy & Li (2014) Karpathy, Andrej and Li, Fei-Fei. Deep visual-semantic alignments for generating image descriptions. arXiv: 1412.2306 , December 2014.
Kingma & Ba (2014) Kingma, Diederik P. and Ba, Jimmy. Adam: A Method for Stochastic Optimization. arXiv: 1412.6980 , December 2014.
Kiros et al. (2014a) Kiros, Ryan, Salahutdinov, Ruslan, and Zemel, Richard. Multimodal neural language models. In International Conference on Machine Learning , pp. 595–603, 2014a.
Kiros et al. (2014b) Kiros, Ryan, Salakhutdinov, Ruslan, and Zemel, Richard. Unifying visual-semantic embeddings with multimodal neural language models. arXiv: 1411.2539 , November 2014b.
Krizhevsky et al. (2012) Krizhevsky, Alex, Sutskever, Ilya, and Hinton, Geoffrey. ImageNet classification with deep convolutional neural networks. In NIPS . 2012.
Kulkarni et al. (2013) Kulkarni, Girish, Premraj, Visruth, Ordonez, Vicente, Dhar, Sagnik, Li, Siming, Choi, Yejin, Berg, Alexander C, and Berg, Tamara L. Babytalk: Understanding and generating simple image descriptions. PAMI, IEEE Transactions on , 35(12):2891–2903, 2013.
Kuznetsova et al. (2012) Kuznetsova, Polina, Ordonez, Vicente, Berg, Alexander C, Berg, Tamara L, and Choi, Yejin. Collective generation of natural image descriptions. In Association for Computational Linguistics . ACL, 2012.
Kuznetsova et al. (2014) Kuznetsova, Polina, Ordonez, Vicente, Berg, Tamara L, and Choi, Yejin. Treetalk: Composition and compression of trees for image descriptions. TACL , 2(10):351–362, 2014.
Larochelle & Hinton (2010) Larochelle, Hugo and Hinton, Geoffrey E. Learning to combine foveal glimpses with a third-order boltzmann machine. In NIPS , pp. 1243–1251, 2010.
Li et al. (2011) Li, Siming, Kulkarni, Girish, Berg, Tamara L, Berg, Alexander C, and Choi, Yejin. Composing simple image descriptions using web-scale n-grams. In Computational Natural Language Learning . ACL, 2011.
Lin et al. (2014) Lin, Tsung-Yi, Maire, Michael, Belongie, Serge, Hays, James, Perona, Pietro, Ramanan, Deva, Dollár, Piotr, and Zitnick, C Lawrence. Microsoft coco: Common objects in context. In ECCV , pp. 740–755. 2014.
Mao et al. (2014) Mao, Junhua, Xu, Wei, Yang, Yi, Wang, Jiang, and Yuille, Alan. Deep captioning with multimodal recurrent neural networks (m-rnn). arXiv: 1412.6632 , December 2014.
Mitchell et al. (2012) Mitchell, Margaret, Han, Xufeng, Dodge, Jesse, Mensch, Alyssa, Goyal, Amit, Berg, Alex, Yamaguchi, Kota, Berg, Tamara, Stratos, Karl, and Daumé III, Hal. Midge: Generating image descriptions from computer vision detections. In European Chapter of the Association for Computational Linguistics , pp. 747–756. ACL, 2012.
Mnih et al. (2014) Mnih, Volodymyr, Hees, Nicolas, Graves, Alex, and Kavukcuoglu, Koray. Recurrent models of visual attention. In NIPS , 2014.
Pascanu et al. (2014) Pascanu, Razvan, Gulcehre, Caglar, Cho, Kyunghyun, and Bengio, Yoshua. How to construct deep recurrent neural networks. In ICLR , 2014.
Rensink (2000) Rensink, Ronald A. The dynamic representation of scenes. Visual cognition , 7(1-3):17–42, 2000.
Russakovsky et al. (2014) Russakovsky, Olga, Deng, Jia, Su, Hao, Krause, Jonathan, Satheesh, Sanjeev, Ma, Sean, Huang, Zhiheng, Karpathy, Andrej, Khosla, Aditya, Bernstein, Michael, Berg, Alexander C., and Fei-Fei, Li. ImageNet Large Scale Visual Recognition Challenge, 2014.
Simonyan & Zisserman (2014) Simonyan, K. and Zisserman, A. Very deep convolutional networks for large-scale image recognition. CoRR , abs/1409.1556, 2014.
Snoek et al. (2012) Snoek, Jasper, Larochelle, Hugo, and Adams, Ryan P. Practical bayesian optimization of machine learning algorithms. In NIPS , pp. 2951–2959, 2012.
Snoek et al. (2014) Snoek, Jasper, Swersky, Kevin, Zemel, Richard S, and Adams, Ryan P. Input warping for bayesian optimization of non-stationary functions. arXiv preprint arXiv:1402.0929 , 2014.
Srivastava et al. (2014) Srivastava, Nitish, Hinton, Geoffrey, Krizhevsky, Alex, Sutskever, Ilya, and Salakhutdinov, Ruslan. Dropout: A simple way to prevent neural networks from overfitting. JMLR , 15, 2014.
Sutskever et al. (2014) Sutskever, Ilya, Vinyals, Oriol, and Le, Quoc VV. Sequence to sequence learning with neural networks. In NIPS , pp. 3104–3112, 2014.
Szegedy et al. (2014) Szegedy, Christian, Liu, Wei, Jia, Yangqing, Sermanet, Pierre, Reed, Scott, Anguelov, Dragomir, Erhan, Dumitru, Vanhoucke, Vincent, and Rabinovich, Andrew. Going deeper with convolutions. arXiv preprint arXiv:1409.4842 , 2014.
Tang et al. (2014) Tang, Yichuan, Srivastava, Nitish, and Salakhutdinov, Ruslan R. Learning generative models with visual attention. In NIPS , pp. 1808–1816, 2014.
Tieleman & Hinton (2012) Tieleman, Tijmen and Hinton, Geoffrey. Lecture 6.5 - rmsprop. Technical report, 2012.
Vinyals et al. (2014) Vinyals, Oriol, Toshev, Alexander, Bengio, Samy, and Erhan, Dumitru. Show and tell: A neural image caption generator. arXiv: 1411.4555 , November 2014.
Weaver & Tao (2001) Weaver, Lex and Tao, Nigel. The optimal reward baseline for gradient-based reinforcement learning. In Proc. UAI’2001 , pp. 538–545, 2001.
Williams (1992) Williams, Ronald J. Simple statistical gradient-following algorithms for connectionist reinforcement learning. Machine learning , 8(3-4):229–256, 1992.
Yang et al. (2011) Yang, Yezhou, Teo, Ching Lik, Daumé III, Hal, and Aloimonos, Yiannis. Corpus-guided sentence generation of natural images. In EMNLP , pp. 444–454. ACL, 2011.
Young et al. (2014) Young, Peter, Lai, Alice, Hodosh, Micah, and Hockenmaier, Julia. From image descriptions to visual denotations: New similarity metrics for semantic inference over event descriptions. TACL , 2:67–78, 2014.
Zaremba et al. (2014) Zaremba, Wojciech, Sutskever, Ilya, and Vinyals, Oriol. Recurrent neural network regularization. arXiv preprint arXiv:1409.2329 , September 2014.
Appendix A Appendix
附录 A 附录
Visualizations from our “hard” (a) and “soft” (b) attention model. White indicates the regions where the model roughly attends to (see section 5.4).
“硬目前正在”(a)所做的工作和“软”(b)的注意模式。 * 白色* 表示模型社区的大致情况( 好啊,第5.4节)。
(a) A man and a woman playing frisbee in a field.
(b) A woman is throwing a frisbee in a park.
Figure 6:
(a) 一男一女在田间玩飞盘。
(b) 一个妇女在公园里扔一只飞盘。
缔合书
(a) A giraffe standing in the field with trees.
(b) A large white bird standing in a forest.
Figure 7:
(a) 你要用树站在田株上鳌头。
(b) 一只大白鸟站在森林中。
图7:
(a) A dog is laying on a bed with a book.
(b) A dog is standing on a hardwood floor.
Figure 8:
(洙)一只狗躺在不扩散条约的床上,拿着一本书。
( 收到)一只狗现在已经站在硬木地板上。
图8:
(a) A woman is holding a donut in his hand.
(b) A woman holding a clock in her hand.
Figure 9:
女子手持手黄色手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手持手手手手手手手手手手手手手手手手手手手手手手手手手手持手手手手手的人数手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手暮手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手手
(b) 手持钟表的妇女。
图9:
(a) A stop sign with a stop sign on it.
(b) A stop sign is on a road with a mountain in the background.
Figure 10:
(a) 事实上,一个停车标志,上面有停车标志。
(b) 停车标志位于有山的道路上。
图还参加了:
(a) A man in a suit and a hat holding a remote control.
(b) A man wearing a hat and a hat on a skateboard.
Figure 11:
(a既没有穿西装,又戴帽子的男子持有遥控器。)
(b) 在滑板上戴帽子和的各个 importance;
图11:
(a) A little girl sitting on a couch with a teddy bear.
(b) A little girl sitting on a bed with a teddy bear.
行为的受害者是调查报告的作者。
一个与当地熊一起坐在床上的小女孩。
(a) A man is standing on a beach with a surfboard.
(b) A person is standing on a beach with a surfboard.
(a极为重视一名男子站在沙滩上,有冲浪板。
(b) 一个人站在沙滩上,有冲浪板。
(a) A man and a woman riding a boat in the water.
(b) A group of people sitting on a boat in the water.
Figure 12:
的答复是: (a 这方面) 一男一女在水 我跟你讲
(b) 一群人坐在船上。
图12:
(a) A man is standing in a market with a large amount of food.
(b) A woman is sitting at a table with a large pizza.
Figure 13:
(a) 一个人站在一个拥有大量 phải食物的市场上。
(b)ỉ坐在一张大比萨的桌子上。
!
(a) A giraffe standing in a field with trees.
(b) A giraffe standing in a forest with trees in the background.
Figure 14:
(a) 长颈鹿站在有树木的田野上。
(b) 长颈鹿站在一个林中,背景是树木。
发扬光大预期将实现以下目标:
(a) A group of people standing next to each other.
(b) A man is talking on his cell phone while another man watches.
Figure 15:
——"一个具有普遍性的提示","一个个子","一个个子","一视同仁","一个子","一个子","一个子","一个子","一个子","一个子","一个子","一个子","一个子","一个子".
(b) 一个男子在手机上说话,而另一个男子在看。
我的意思是,如果有的话,步伐是有限的。撰文: