Sentence-BERT: Sentence Embeddings using Siamese BERT-Networks
Sentence-BERT: Sentence Embeddings using Siamese BERT-Networks
Sentence-BERT:基于孪生 BERT 网络的句向量
Nils Reimers Iryna Gurevych Affiliation: Ubiquitous Knowledge Processing Lab (UKP-TUDA) Affiliation: Department of Computer Science, Technische Universität Darmstadt Affiliation: www.ukp.tu-darmstadt.de
Abstract
摘要
BERT Devlin et al. 2018 and RoBERTa Liu et al. 2019 has set a new state-of-the-art performance on sentence-pair regression tasks like semantic textual similarity (STS). However, it requires that both sentences are fed into the network, which causes a massive computational overhead: Finding the most similar pair in a collection of 10,000 sentences requires about 50 million inference computations (~65 hours) with BERT. The construction of BERT makes it unsuitable for semantic similarity search as well as for unsupervised tasks like clustering.
BERT(Devlin et al. 2018)与 RoBERTa(Liu et al. 2019)在语义文本相似度(STS)等句对回归任务上刷新了表现。但二者要求两句一起送入网络,计算开销极大:在一万句中找最相似的一对,用 BERT 约需五千万次推理(约 65 小时)。BERT 的结构因此既不适合语义相似检索,也不适合聚类等无监督任务。
In this publication, we present Sentence-BERT (SBERT), a modification of the pretrained BERT network that use siamese and triplet network structures to derive semantically meaningful sentence embeddings that can be compared using cosine-similarity. This reduces the effort for finding the most similar pair from 65 hours with BERT / RoBERTa to about 5 seconds with SBERT, while maintaining the accuracy from BERT.
本文提出 Sentence-BERT(SBERT):在预训练 BERT 上引入孪生与三元组网络结构,得到可用余弦相似度比较的语义句向量。找最相似句对的耗时从 BERT / RoBERTa 的约 65 小时降到 SBERT 的约 5 秒,同时保持与 BERT 相当的精度。
We evaluate SBERT and SRoBERTa on common STS tasks and transfer learning tasks, where it outperforms other state-of-the-art sentence embeddings methods.[^1]
我们在常用 STS 任务与迁移学习任务上评测 SBERT 与 SRoBERTa,结果优于当时其他前沿句向量方法。[^1]
1 Introduction
1 引言
In this publication, we present Sentence-BERT (SBERT), a modification of the BERT network using siamese and triplet networks that is able to derive semantically meaningful sentence embeddings[^2]. This enables BERT to be used for certain new tasks, which up-to-now were not applicable for BERT. These tasks include large-scale semantic similarity comparison, clustering, and information retrieval via semantic search.
本文提出 Sentence-BERT(SBERT):在 BERT 上采用孪生与三元组网络,得到语义上有意义的句向量[^2]。由此 BERT 可扩展到此前难以直接应用的任务,包括大规模语义相似比较、聚类,以及基于语义检索的信息检索。
BERT set new state-of-the-art performance on various sentence classification and sentence-pair regression tasks. BERT uses a cross-encoder: Two sentences are passed to the transformer network and the target value is predicted. However, this setup is unsuitable for various pair regression tasks due to too many possible combinations. Finding in a collection of sentences the pair with the highest similarity requires with BERT inference computations. On a modern V100 GPU, this requires about 65 hours. Similar, finding which of the over 40 million existent questions of Quora is the most similar for a new question could be modeled as a pair-wise comparison with BERT, however, answering a single query would require over 50 hours.
BERT 在多种句子分类与句对回归任务上刷新了表现。它采用交叉编码器:两句一并送入 Transformer,再预测目标值。可组合的句对数量过大时,该设定并不适用。在 句的集合中找相似度最高的一对,BERT 需要 次推理;在当代 V100 GPU 上约需 65 小时。类似地,若用 BERT 对 Quora 上逾四千万已有问题做两两比较来找与新问题最相似者,单次查询就要五十多小时。
A common method to address clustering and semantic search is to map each sentence to a vector space such that semantically similar sentences are close. Researchers have started to input individual sentences into BERT and to derive fixed-size sentence embeddings. The most commonly used approach is to average the BERT output layer (known as BERT embeddings) or by using the output of the first token (the [CLS] token). As we will show, this common practice yields rather bad sentence embeddings, often worse than averaging GloVe embeddings Pennington et al. 2014.
应对聚类与语义检索的常见做法,是把每句映到向量空间,使语义相近的句子彼此靠近。已有工作开始把单句输入 BERT,再得到固定维句向量;最常用的是对 BERT 输出层做平均(所谓 BERT embeddings),或取首个 token([CLS])的输出。我们将说明:这种通行做法得到的句向量相当差,往往还不如对 GloVe 词向量(Pennington et al. 2014)做平均。
To alleviate this issue, we developed SBERT. The siamese network architecture enables that fixed-sized vectors for input sentences can be derived. Using a similarity measure like cosine-similarity or Manhatten / Euclidean distance, semantically similar sentences can be found. These similarity measures can be performed extremely efficient on modern hardware, allowing SBERT to be used for semantic similarity search as well as for clustering. The complexity for finding the most similar sentence pair in a collection of 10,000 sentences is reduced from 65 hours with BERT to the computation of 10,000 sentence embeddings (~5 seconds with SBERT) and computing cosine-similarity (~0.01 seconds). By using optimized index structures, finding the most similar Quora question can be reduced from 50 hours to a few milliseconds Johnson et al. 2017.
为此我们提出 SBERT。孪生结构可对输入句导出固定维向量;再用余弦相似度或曼哈顿 / 欧氏距离即可找语义相近的句子。这些相似度在现代硬件上极高效,使 SBERT 可用于语义相似检索与聚类。一万句中找最相似句对的复杂度,从 BERT 的 65 小时降为:算一万个句向量(SBERT 约 5 秒)再算余弦相似度(约 0.01 秒)。借助优化索引结构,找最相似的 Quora 问题可从 50 小时压到数毫秒(Johnson et al. 2017)。
We fine-tune SBERT on NLI data, which creates sentence embeddings that significantly outperform other state-of-the-art sentence embedding methods like InferSent Conneau et al. 2017 and Universal Sentence Encoder Cer et al. 2018. On seven Semantic Textual Similarity (STS) tasks, SBERT achieves an improvement of 11.7 points compared to InferSent and 5.5 points compared to Universal Sentence Encoder. On SentEval Conneau and Kiela 2018, an evaluation toolkit for sentence embeddings, we achieve an improvement of 2.1 and 2.6 points, respectively.
我们在 NLI 数据上微调 SBERT,得到的句向量显著优于 InferSent(Conneau et al. 2017)、Universal Sentence Encoder(Cer et al. 2018)等当时前沿方法。在七项语义文本相似度(STS)任务上,SBERT 相对 InferSent 提高 11.7 分,相对 Universal Sentence Encoder 提高 5.5 分;在句向量评测套件 SentEval(Conneau and Kiela 2018)上分别提高 2.1 与 2.6 分。
SBERT can be adapted to a specific task. It sets new state-of-the-art performance on a challenging argument similarity dataset Misra et al. 2016 and on a triplet dataset to distinguish sentences from different sections of a Wikipedia article Dor et al. 2018.
SBERT 也可针对具体任务适配:在颇具挑战的论证相似度数据集(Misra et al. 2016),以及用于区分维基百科文章不同小节句子的三元组数据集(Dor et al. 2018)上,均刷新了表现。
The paper is structured in the following way: Section 3 presents SBERT, section 4 evaluates SBERT on common STS tasks and on the challenging Argument Facet Similarity (AFS) corpus Misra et al. 2016. Section 5 evaluates SBERT on SentEval. In section 6, we perform an ablation study to test some design aspect of SBERT. In section 7, we compare the computational efficiency of SBERT sentence embeddings in contrast to other state-of-the-art sentence embedding methods.
论文结构如下:第 3 节介绍 SBERT;第 4 节在常用 STS 任务与有难度的 Argument Facet Similarity(AFS)语料(Misra et al. 2016)上评测;第 5 节用 SentEval 评测;第 6 节做消融,检验若干设计选择;第 7 节对比 SBERT 句向量相对其他前沿方法的计算效率。
2 Related Work
2 相关工作
We first introduce BERT, then, we discuss state-of-the-art sentence embedding methods.
我们先介绍 BERT,再讨论当时的前沿句向量方法。
BERT Devlin et al. 2018 is a pre-trained transformer network Vaswani et al. 2017, which set for various NLP tasks new state-of-the-art results, including question answering, sentence classification, and sentence-pair regression. The input for BERT for sentence-pair regression consists of the two sentences, separated by a special [SEP] token. Multi-head attention over 12 (base-model) or 24 layers (large-model) is applied and the output is passed to a simple regression function to derive the final label. Using this setup, BERT set a new state-of-the-art performance on the Semantic Textual Semilarity (STS) benchmark Cer et al. 2017. RoBERTa Liu et al. 2019 showed, that the performance of BERT can further improved by small adaptations to the pre-training process. We also tested XLNet Yang et al. 2019, but it led in general to worse results than BERT.
BERT(Devlin et al. 2018)是预训练 Transformer 网络(Vaswani et al. 2017),在问答、句子分类、句对回归等多种 NLP 任务上刷新了结果。句对回归时,输入为两句,中间以特殊 [SEP] token 分隔;经 12 层(base)或 24 层(large)多头注意力后,输出送入简单回归函数得到最终标签。该设定下 BERT 在语义文本相似度(STS)基准(Cer et al. 2017)上刷新表现。RoBERTa(Liu et al. 2019)表明,对预训练过程做小幅调整还可进一步提升 BERT。我们也试过 XLNet(Yang et al. 2019),整体效果一般不如 BERT。
A large disadvantage of the BERT network structure is that no independent sentence embeddings are computed, which makes it difficult to derive sentence embeddings from BERT. To bypass this limitations, researchers passed single sentences through BERT and then derive a fixed sized vector by either averaging the outputs (similar to average word embeddings) or by using the output of the special CLS token (for example: May et al. 2019; Zhang et al. 2019; Qiao et al. 2019). These two options are also provided by the popular bert-as-a-service-repository[^3]. Up to our knowledge, there is so far no evaluation if these methods lead to useful sentence embeddings.
BERT 网络结构的一大缺点是不直接产生独立句向量,因而很难从中导出句嵌入。为绕开限制,研究者把单句送入 BERT,再对输出做平均(类似平均词向量),或取特殊 CLS token 的输出,得到固定维向量(例如 May et al. 2019;Zhang et al. 2019;Qiao et al. 2019)。流行的 bert-as-a-service 仓库[^3]也提供这两种选项。据我们所知,此前尚无系统评测说明这些做法能否得到有用的句向量。
Sentence embeddings are a well studied area with dozens of proposed methods. Skip-Thought Kiros et al. 2015 trains an encoder-decoder architecture to predict the surrounding sentences. InferSent Conneau et al. 2017 uses labeled data of the Stanford Natural Language Inference dataset Bowman et al. 2015 and the Multi-Genre NLI dataset Williams et al. 2018 to train a siamese BiLSTM network with max-pooling over the output. Conneau et al. showed, that InferSent consistently outperforms unsupervised methods like SkipThought. Universal Sentence Encoder Cer et al. 2018 trains a transformer network and augments unsupervised learning with training on SNLI. Hill et al. 2016 showed, that the task on which sentence embeddings are trained significantly impacts their quality. Previous work Conneau et al. 2017; Cer et al. 2018 found that the SNLI datasets are suitable for training sentence embeddings. Yang et al. 2018 presented a method to train on conversations from Reddit using siamese DAN and siamese transformer networks, which yielded good results on the STS benchmark dataset.
句向量是长期研究领域,方法众多。Skip-Thought(Kiros et al. 2015)训练编码器–解码器以预测上下文句子。InferSent(Conneau et al. 2017)用斯坦福自然语言推理(SNLI,Bowman et al. 2015)与多体裁 NLI(MultiNLI,Williams et al. 2018)标注数据,训练带输出最大池化的孪生 BiLSTM。Conneau 等人表明 InferSent 稳定优于 SkipThought 等无监督方法。Universal Sentence Encoder(Cer et al. 2018)训练 Transformer,并在无监督学习之外叠加 SNLI 训练。Hill et al. 2016 指出,句向量的训练任务会显著影响质量。既有工作(Conneau et al. 2017;Cer et al. 2018)发现 SNLI 类数据适合训句向量。Yang et al. 2018 提出用 Reddit 对话、以孪生 DAN 与孪生 Transformer 训练,在 STS 基准上效果不错。
Humeau et al. 2019 addresses the run-time overhead of the cross-encoder from BERT and present a method (poly-encoders) to compute a score between context vectors and pre-computed candidate embeddings using attention. This idea works for finding the highest scoring sentence in a larger collection. However, poly-encoders have the drawback that the score function is not symmetric and the computational overhead is too large for use-cases like clustering, which would require score computations.
Humeau et al. 2019 针对 BERT 交叉编码器的运行时开销,提出 poly-encoders:用注意力在 个上下文向量与预计算候选嵌入之间打分。该思路适用于在较大集合中找最高分句子,但打分函数非对称,且对聚类等需要 次打分的场景计算开销仍然过大。
Previous neural sentence embedding methods started the training from a random initialization. In this publication, we use the pre-trained BERT and RoBERTa network and only fine-tune it to yield useful sentence embeddings. This reduces significantly the needed training time: SBERT can be tuned in less than 20 minutes, while yielding better results than comparable sentence embedding methods.
此前神经句向量方法多从随机初始化起步。本文直接使用预训练 BERT 与 RoBERTa,仅微调以得到有用句向量。训练时间因此大幅缩短:SBERT 可在不到 20 分钟内调好,效果仍优于可比的句向量方法。
3 Model
3 模型
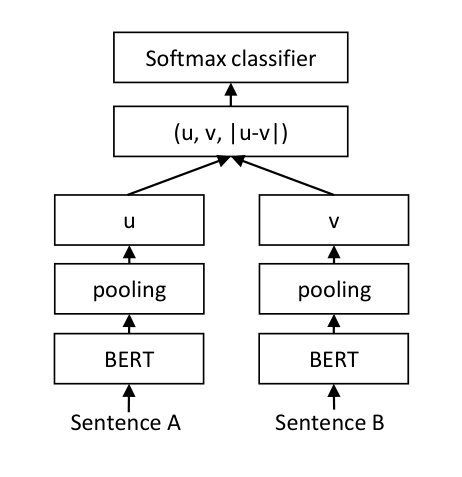
Figure 1: SBERT architecture with classification objective function, e.g., for fine-tuning on SNLI dataset. The two BERT networks have tied weights (siamese network structure).
图 1:带分类目标函数的 SBERT 结构(例如在 SNLI 上微调)。两个 BERT 网络权重共享(孪生结构)。
SBERT adds a pooling operation to the output of BERT / RoBERTa to derive a fixed sized sentence embedding. We experiment with three pooling strategies: Using the output of the CLS-token, computing the mean of all output vectors (MEAN-strategy), and computing a max-over-time of the output vectors (MAX-strategy). The default configuration is MEAN.
SBERT 在 BERT / RoBERTa 输出上增加池化,得到固定维句向量。我们试验三种池化:取 CLS token 输出、对全部输出向量取均值(MEAN)、对输出向量做时序最大池化(MAX)。默认配置为 MEAN。
In order to fine-tune BERT / RoBERTa, we create siamese and triplet networks Schroff et al. 2015 to update the weights such that the produced sentence embeddings are semantically meaningful and can be compared with cosine-similarity.
为微调 BERT / RoBERTa,我们构建孪生与三元组网络(Schroff et al. 2015),更新权重,使产出的句向量语义上有意义,可用余弦相似度比较。
The network structure depends on the available training data. We experiment with the following structures and objective functions.
网络结构取决于可用训练数据。我们试验了下列结构与目标函数。
Classification Objective Function. We concatenate the sentence embeddings and with the element-wise difference and multiply it with the trainable weight :
分类目标函数。 将句向量 与 与逐元素差 拼接,再乘以可训练权重 :
where is the dimension of the sentence embeddings and the number of labels. We optimize cross-entropy loss. This structure is depicted in Figure 1.
其中 为句向量维数, 为标签数。优化交叉熵损失。结构见图 1。
Regression Objective Function. The cosine-similarity between the two sentence embeddings and is computed (Figure 2). We use mean-squared-error loss as the objective function.
回归目标函数。 计算两句向量 与 的余弦相似度(图 2),以均方误差为优化目标。
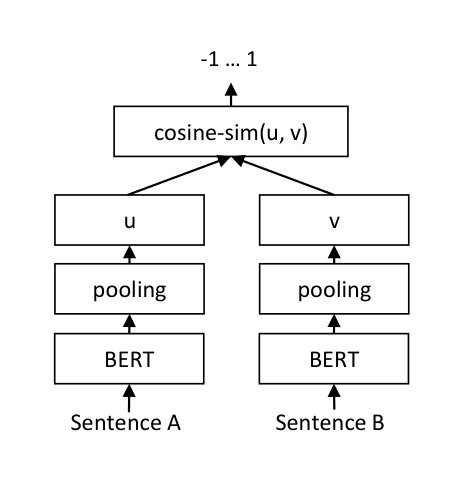
Figure 2: SBERT architecture at inference, for example, to compute similarity scores. This architecture is also used with the regression objective function.
图 2:推理时的 SBERT 结构,例如用于计算相似度分数;回归目标函数也采用该结构。
Triplet Objective Function. Given an anchor sentence , a positive sentence , and a negative sentence , triplet loss tunes the network such that the distance between and is smaller than the distance between and . Mathematically, we minimize the following loss function:
三元组目标函数。 给定锚句 、正例 与负例 ,三元组损失调节网络,使 与 的距离小于 与 。形式上最小化:
with the sentence embedding for //, a distance metric and margin . Margin ensures that is at least closer to than . As metric we use Euclidean distance and we set in our experiments.
其中 为 // 的句向量, 为距离度量, 为间隔。间隔保证 至少比 更靠近 达 。实验中用欧氏距离,并设 。
| Model | STS12 | STS13 | STS14 | STS15 | STS16 | STSb | SICK-R | Avg. |
|---|---|---|---|---|---|---|---|---|
| Avg. GloVe embeddings | 55.14 | 70.66 | 59.73 | 68.25 | 63.66 | 58.02 | 53.76 | 61.32 |
| Avg. BERT embeddings | 38.78 | 57.98 | 57.98 | 63.15 | 61.06 | 46.35 | 58.40 | 54.81 |
| BERT CLS-vector | 20.16 | 30.01 | 20.09 | 36.88 | 38.08 | 16.50 | 42.63 | 29.19 |
| InferSent - Glove | 52.86 | 66.75 | 62.15 | 72.77 | 66.87 | 68.03 | 65.65 | 65.01 |
| Universal Sentence Encoder | 64.49 | 67.80 | 64.61 | 76.83 | 73.18 | 74.92 | 76.69 | 71.22 |
| SBERT-NLI-base | 70.97 | 76.53 | 73.19 | 79.09 | 74.30 | 77.03 | 72.91 | 74.89 |
| SBERT-NLI-large | 72.27 | 78.46 | 74.90 | 80.99 | 76.25 | 79.23 | 73.75 | 76.55 |
| SRoBERTa-NLI-base | 71.54 | 72.49 | 70.80 | 78.74 | 73.69 | 77.77 | 74.46 | 74.21 |
| SRoBERTa-NLI-large | 74.53 | 77.00 | 73.18 | 81.85 | 76.82 | 79.10 | 74.29 | 76.68 |
Table 1: Spearman rank correlation between the cosine similarity of sentence representations and the gold labels for various Textual Similarity (STS) tasks. Performance is reported by convention as . STS12-STS16: SemEval 2012-2016, STSb: STSbenchmark, SICK-R: SICK relatedness dataset.
| 模型 | STS12 | STS13 | STS14 | STS15 | STS16 | STSb | SICK-R | 平均 |
|---|---|---|---|---|---|---|---|---|
| Avg. GloVe embeddings | 55.14 | 70.66 | 59.73 | 68.25 | 63.66 | 58.02 | 53.76 | 61.32 |
| Avg. BERT embeddings | 38.78 | 57.98 | 57.98 | 63.15 | 61.06 | 46.35 | 58.40 | 54.81 |
| BERT CLS-vector | 20.16 | 30.01 | 20.09 | 36.88 | 38.08 | 16.50 | 42.63 | 29.19 |
| InferSent - Glove | 52.86 | 66.75 | 62.15 | 72.77 | 66.87 | 68.03 | 65.65 | 65.01 |
| Universal Sentence Encoder | 64.49 | 67.80 | 64.61 | 76.83 | 73.18 | 74.92 | 76.69 | 71.22 |
| SBERT-NLI-base | 70.97 | 76.53 | 73.19 | 79.09 | 74.30 | 77.03 | 72.91 | 74.89 |
| SBERT-NLI-large | 72.27 | 78.46 | 74.90 | 80.99 | 76.25 | 79.23 | 73.75 | 76.55 |
| SRoBERTa-NLI-base | 71.54 | 72.49 | 70.80 | 78.74 | 73.69 | 77.77 | 74.46 | 74.21 |
| SRoBERTa-NLI-large | 74.53 | 77.00 | 73.18 | 81.85 | 76.82 | 79.10 | 74.29 | 76.68 |
表 1:句表示余弦相似度与金标之间的 Spearman 秩相关 。按惯例报告 。STS12–STS16:SemEval 2012–2016;STSb:STSbenchmark;SICK-R:SICK 相关度数据集。
3.1 Training Details
3.1 训练细节
We train SBERT on the combination of the SNLI Bowman et al. 2015 and the Multi-Genre NLI Williams et al. 2018 dataset. The SNLI is a collection of 570,000 sentence pairs annotated with the labels contradiction, eintailment, and neutral. MultiNLI contains 430,000 sentence pairs and covers a range of genres of spoken and written text. We fine-tune SBERT with a 3-way softmax-classifier objective function for one epoch. We used a batch-size of 16, Adam optimizer with learning rate , and a linear learning rate warm-up over 10% of the training data. Our default pooling strategy is MEAN.
我们在 SNLI(Bowman et al. 2015)与 Multi-Genre NLI(Williams et al. 2018)的合并数据上训练 SBERT。SNLI 含约 57 万句对,标注为矛盾、蕴含、中立三类;MultiNLI 含约 43 万句对,覆盖多种口语与书面体裁。以三路 softmax 分类目标微调一个 epoch;批大小 16,Adam,学习率 ,并在前 10% 训练数据上做线性学习率预热。默认池化为 MEAN。
4 Evaluation - Semantic Textual Similarity
4 评测——语义文本相似度
We evaluate the performance of SBERT for common Semantic Textual Similarity (STS) tasks. State-of-the-art methods often learn a (complex) regression function that maps sentence embeddings to a similarity score. However, these regression functions work pair-wise and due to the combinatorial explosion those are often not scalable if the collection of sentences reaches a certain size. Instead, we always use cosine-similarity to compare the similarity between two sentence embeddings. We ran our experiments also with negative Manhatten and negative Euclidean distances as similarity measures, but the results for all approaches remained roughly the same.
我们在常用语义文本相似度(STS)任务上评测 SBERT。前沿方法常再学一个(较复杂的)回归函数,把句向量映到相似度分数;这类回归按对工作,句子集合一大就因组合爆炸难以扩展。我们始终用余弦相似度比较两句向量。也曾用负曼哈顿距离与负欧氏距离作相似度,各方法结果大致不变。
4.1 Unsupervised STS
4.1 无监督 STS
We evaluate the performance of SBERT for STS without using any STS specific training data. We use the STS tasks 2012 - 2016 Agirre et al. 2012; Agirre et al. 2013; Agirre et al. 2014; Agirre et al. 2015; Agirre et al. 2016, the STS benchmark Cer et al. 2017, and the SICK-Relatedness dataset Marelli et al. 2014. These datasets provide labels between 0 and 5 on the semantic relatedness of sentence pairs. We showed in Reimers et al. 2016 that Pearson correlation is badly suited for STS. Instead, we compute the Spearman’s rank correlation between the cosine-similarity of the sentence embeddings and the gold labels. The setup for the other sentence embedding methods is equivalent, the similarity is computed by cosine-similarity. The results are depicted in Table 1.
我们在不使用任何 STS 专用训练数据的设定下评测 SBERT:STS 2012–2016(Agirre et al. 2012–2016)、STS 基准(Cer et al. 2017)与 SICK-Relatedness(Marelli et al. 2014)。这些数据集对句对语义相关度给出 0–5 的标注。我们曾说明(Reimers et al. 2016)Pearson 相关不适合 STS,因而报告句向量余弦相似度与金标之间的 Spearman 秩相关。其他句向量方法同样用余弦相似度。结果见表 1。
The results shows that directly using the output of BERT leads to rather poor performances. Averaging the BERT embeddings achieves an average correlation of only 54.81, and using the CLS-token output only achieves an average correlation of 29.19. Both are worse than computing average GloVe embeddings.
结果表明:直接使用 BERT 输出表现相当差。平均 BERT 嵌入平均相关仅 54.81,CLS token 输出仅 29.19,两者都不如平均 GloVe 嵌入。
Using the described siamese network structure and fine-tuning mechanism substantially improves the correlation, outperforming both InferSent and Universal Sentence Encoder substantially. The only dataset where SBERT performs worse than Universal Sentence Encoder is SICK-R. Universal Sentence Encoder was trained on various datasets, including news, question-answer pages and discussion forums, which appears to be more suitable to the data of SICK-R. In contrast, SBERT was pre-trained only on Wikipedia (via BERT) and on NLI data.
采用所述孪生结构与微调机制后,相关度大幅提升,显著优于 InferSent 与 Universal Sentence Encoder。唯一弱于 Universal Sentence Encoder 的是 SICK-R:后者在新闻、问答页、论坛等多种数据上训练,更贴近 SICK-R;SBERT 则仅经 BERT 在维基百科上预训练,再在 NLI 上微调。
While RoBERTa was able to improve the performance for several supervised tasks, we only observe minor difference between SBERT and SRoBERTa for generating sentence embeddings.
尽管 RoBERTa 在若干有监督任务上提升了 BERT,生成句向量时 SBERT 与 SRoBERTa 差异不大。
4.2 Supervised STS
4.2 有监督 STS
The STS benchmark (STSb) Cer et al. 2017 provides is a popular dataset to evaluate supervised STS systems. The data includes 8,628 sentence pairs from the three categories captions, news, and forums. It is divided into train (5,749), dev (1,500) and test (1,379). BERT set a new state-of-the-art performance on this dataset by passing both sentences to the network and using a simple regression method for the output.
STS 基准(STSb,Cer et al. 2017)是评测有监督 STS 的常用数据集,含来自字幕、新闻、论坛三类的 8,628 句对,划分为训练(5,749)、开发(1,500)与测试(1,379)。BERT 把两句一并送入网络并用简单回归,在该集上刷新了表现。
| Model | Spearman |
|---|---|
| Not trained for STS | |
| Avg. GloVe embeddings | 58.02 |
| Avg. BERT embeddings | 46.35 |
| InferSent - GloVe | 68.03 |
| Universal Sentence Encoder | 74.92 |
| SBERT-NLI-base | 77.03 |
| SBERT-NLI-large | 79.23 |
| Trained on STS benchmark dataset | |
| BERT-STSb-base | 84.30 0.76 |
| SBERT-STSb-base | 84.67 0.19 |
| SRoBERTa-STSb-base | 84.92 0.34 |
| BERT-STSb-large | 85.64 0.81 |
| SBERT-STSb-large | 84.45 0.43 |
| SRoBERTa-STSb-large | 85.02 0.76 |
| Trained on NLI data + STS benchmark data | |
| BERT-NLI-STSb-base | 88.33 0.19 |
| SBERT-NLI-STSb-base | 85.35 0.17 |
| SRoBERTa-NLI-STSb-base | 84.79 0.38 |
| BERT-NLI-STSb-large | 88.77 0.46 |
| SBERT-NLI-STSb-large | 86.10 0.13 |
| SRoBERTa-NLI-STSb-large | 86.15 0.35 |
Table 2: Evaluation on the STS benchmark test set. BERT systems were trained with 10 random seeds and 4 epochs. SBERT was fine-tuned on the STSb dataset, SBERT-NLI was pretrained on the NLI datasets, then fine-tuned on the STSb dataset.
| 模型 | Spearman |
|---|---|
| 未针对 STS 训练 | |
| Avg. GloVe embeddings | 58.02 |
| Avg. BERT embeddings | 46.35 |
| InferSent - GloVe | 68.03 |
| Universal Sentence Encoder | 74.92 |
| SBERT-NLI-base | 77.03 |
| SBERT-NLI-large | 79.23 |
| 在 STS 基准上训练 | |
| BERT-STSb-base | 84.30 0.76 |
| SBERT-STSb-base | 84.67 0.19 |
| SRoBERTa-STSb-base | 84.92 0.34 |
| BERT-STSb-large | 85.64 0.81 |
| SBERT-STSb-large | 84.45 0.43 |
| SRoBERTa-STSb-large | 85.02 0.76 |
| 先 NLI 再 STS 基准 | |
| BERT-NLI-STSb-base | 88.33 0.19 |
| SBERT-NLI-STSb-base | 85.35 0.17 |
| SRoBERTa-NLI-STSb-base | 84.79 0.38 |
| BERT-NLI-STSb-large | 88.77 0.46 |
| SBERT-NLI-STSb-large | 86.10 0.13 |
| SRoBERTa-NLI-STSb-large | 86.15 0.35 |
表 2:STS 基准测试集评测。BERT 系统用 10 个随机种子训练 4 个 epoch。SBERT 在 STSb 上微调;SBERT-NLI 先在 NLI 上预训练,再在 STSb 上微调。
We use the training set to fine-tune SBERT using the regression objective function. At prediction time, we compute the cosine-similarity between the sentence embeddings. All systems are trained with 10 random seeds to counter variances Reimers and Gurevych 2018.
我们用训练集、以回归目标函数微调 SBERT;预测时计算句向量余弦相似度。为抑制方差,各系统均用 10 个随机种子训练(Reimers and Gurevych 2018)。
The results are depicted in Table 2. We experimented with two setups: Only training on STSb, and first training on NLI, then training on STSb. We observe that the later strategy leads to a slight improvement of 1-2 points. This two-step approach had an especially large impact for the BERT cross-encoder, which improved the performance by 3-4 points. We do not observe a significant difference between BERT and RoBERTa.
结果见表 2。我们试了两种设定:仅在 STSb 上训练;以及先在 NLI、再在 STSb 上训练。后者通常再提升 1–2 分;对 BERT 交叉编码器影响尤其大,可提高 3–4 分。BERT 与 RoBERTa 之间未见显著差异。
4.3 Argument Facet Similarity
4.3 论证侧面相似度
We evaluate SBERT on the Argument Facet Similarity (AFS) corpus by Misra et al. 2016. The AFS corpus annotated 6,000 sentential argument pairs from social media dialogs on three controversial topics: gun control, gay marriage, and death penalty. The data was annotated on a scale from 0 (“different topic”) to 5 (“completely equivalent”). The similarity notion in the AFS corpus is fairly different to the similarity notion in the STS datasets from SemEval. STS data is usually descriptive, while AFS data are argumentative excerpts from dialogs. To be considered similar, arguments must not only make similar claims, but also provide a similar reasoning. Further, the lexical gap between the sentences in AFS is much larger. Hence, simple unsupervised methods as well as state-of-the-art STS systems perform badly on this dataset Reimers et al. 2019.
我们在 Misra et al. 2016 的 Argument Facet Similarity(AFS)语料上评测 SBERT。该语料标注了社交媒体对话中关于控枪、同性婚姻、死刑三个争议话题的 6,000 句级论证对,相似度从 0(「不同话题」)到 5(「完全等价」)。AFS 的相似度概念与 SemEval STS 明显不同:STS 多为描述性文本,AFS 则是对话中的论证摘录;要判为相似,论证不仅主张接近,推理也要接近,且词面差距更大。因此简单无监督方法与当时前沿 STS 系统在该集上表现都差(Reimers et al. 2019)。
We evaluate SBERT on this dataset in two scenarios: 1) As proposed by Misra et al., we evaluate SBERT using 10-fold cross-validation. A draw-back of this evaluation setup is that it is not clear how well approaches generalize to different topics. Hence, 2) we evaluate SBERT in a cross-topic setup. Two topics serve for training and the approach is evaluated on the left-out topic. We repeat this for all three topics and average the results.
我们在两种场景下评测:1)按 Misra 等人建议做 10 折交叉验证——缺点是不清楚方法对不同话题的泛化;2)跨话题设定:两话题训练、剩下一话题测试,三轮轮换后取平均。
SBERT is fine-tuned using the Regression Objective Function. The similarity score is computed using cosine-similarity based on the sentence embeddings. We also provide the Pearson correlation to make the results comparable to Misra et al. However, we showed Reimers et al. 2016 that Pearson correlation has some serious drawbacks and should be avoided for comparing STS systems. The results are depicted in Table 3.
SBERT 以回归目标函数微调,相似度由句向量余弦相似度给出。为与 Misra 等人可比,我们也报告 Pearson 相关 ;但我们曾说明(Reimers et al. 2016)Pearson 有严重缺陷,不宜用于比较 STS 系统。结果见表 3。
Unsupervised methods like tf-idf, average GloVe embeddings or InferSent perform rather badly on this dataset with low scores. Training SBERT in the 10-fold cross-validation setup gives a performance that is nearly on-par with BERT.
tf-idf、平均 GloVe、InferSent 等无监督方法在该集上分数很低。10 折交叉验证下训练的 SBERT 表现几乎与 BERT 持平。
However, in the cross-topic evaluation, we observe a performance drop of SBERT by about 7 points Spearman correlation. To be considered similar, arguments should address the same claims and provide the same reasoning. BERT is able to use attention to compare directly both sentences (e.g. word-by-word comparison), while SBERT must map individual sentences from an unseen topic to a vector space such that arguments with similar claims and reasons are close. This is a much more challenging task, which appears to require more than just two topics for training to work on-par with BERT.
但在跨话题评测中,SBERT 的 Spearman 相关约掉 7 分。要判为相似,论证需触及相同主张并给出相同推理。BERT 可用注意力直接对照两句(如逐词比较);SBERT 则须把未见话题上的单句映到向量空间,使主张与理由相近的论证彼此靠近——这难得多,似乎仅靠两个训练话题还不足以与 BERT 持平。
| Model | ||
|---|---|---|
| Unsupervised methods | ||
| tf-idf | 46.77 | 42.95 |
| Avg. GloVe embeddings | 32.40 | 34.00 |
| InferSent - GloVe | 27.08 | 26.63 |
| 10-fold Cross-Validation | ||
| SVR Misra et al. 2016 | 63.33 | - |
| BERT-AFS-base | 77.20 | 74.84 |
| SBERT-AFS-base | 76.57 | 74.13 |
| BERT-AFS-large | 78.68 | 76.38 |
| SBERT-AFS-large | 77.85 | 75.93 |
| Cross-Topic Evaluation | ||
| BERT-AFS-base | 58.49 | 57.23 |
| SBERT-AFS-base | 52.34 | 50.65 |
| BERT-AFS-large | 62.02 | 60.34 |
| SBERT-AFS-large | 53.82 | 53.10 |
Table 3: Average Pearson correlation and average Spearman’s rank correlation on the Argument Facet Similarity (AFS) corpus Misra et al. 2016. Misra et al. proposes 10-fold cross-validation. We additionally evaluate in a cross-topic scenario: Methods are trained on two topics, and are evaluated on the third topic.
| 模型 | ||
|---|---|---|
| 无监督方法 | ||
| tf-idf | 46.77 | 42.95 |
| Avg. GloVe embeddings | 32.40 | 34.00 |
| InferSent - GloVe | 27.08 | 26.63 |
| 10 折交叉验证 | ||
| SVR Misra et al. 2016 | 63.33 | - |
| BERT-AFS-base | 77.20 | 74.84 |
| SBERT-AFS-base | 76.57 | 74.13 |
| BERT-AFS-large | 78.68 | 76.38 |
| SBERT-AFS-large | 77.85 | 75.93 |
| 跨话题评测 | ||
| BERT-AFS-base | 58.49 | 57.23 |
| SBERT-AFS-base | 52.34 | 50.65 |
| BERT-AFS-large | 62.02 | 60.34 |
| SBERT-AFS-large | 53.82 | 53.10 |
表 3:Argument Facet Similarity(AFS)语料(Misra et al. 2016)上的平均 Pearson 相关 与平均 Spearman 秩相关 。Misra 等人提出 10 折交叉验证;我们另做跨话题评测:两话题训练、第三话题测试。
4.4 Wikipedia Sections Distinction
4.4 维基百科小节区分
Dor et al. 2018 use Wikipedia to create a thematically fine-grained train, dev and test set for sentence embeddings methods. Wikipedia articles are separated into distinct sections focusing on certain aspects. Dor et al. assume that sentences in the same section are thematically closer than sentences in different sections. They use this to create a large dataset of weakly labeled sentence triplets: The anchor and the positive example come from the same section, while the negative example comes from a different section of the same article. For example, from the Alice Arnold article: Anchor: Arnold joined the BBC Radio Drama Company in 1988., positive: Arnold gained media attention in May 2012., negative: Balding and Arnold are keen amateur golfers.
Dor et al. 2018 用维基百科构造主题粒度更细的句向量训练 / 开发 / 测试集。维基条目按侧面分成不同小节;他们假定同小节内的句子主题上更接近,据此构造大规模弱标注三元组:锚句与正例来自同小节,负例来自同条目的另一小节。例如 Alice Arnold 条目:锚句 Arnold joined the BBC Radio Drama Company in 1988.,正例 Arnold gained media attention in May 2012.,负例 Balding and Arnold are keen amateur golfers.
We use the dataset from Dor et al. We use the Triplet Objective, train SBERT for one epoch on the about 1.8 Million training triplets and evaluate it on the 222,957 test triplets. Test triplets are from a distinct set of Wikipedia articles. As evaluation metric, we use accuracy: Is the positive example closer to the anchor than the negative example?
我们使用 Dor 等人的数据:以三元组目标在约 180 万训练三元组上训 SBERT 一个 epoch,在 222,957 个测试三元组上评测;测试三元组来自另一批维基条目。指标为准确率:正例是否比负例更靠近锚句。
Results are presented in Table 4. Dor et al. fine-tuned a BiLSTM architecture with triplet loss to derive sentence embeddings for this dataset. As the table shows, SBERT clearly outperforms the BiLSTM approach by Dor et al.
结果见表 4。Dor 等人用三元组损失微调 BiLSTM 以得到该集上的句向量;表中显示 SBERT 明显优于其 BiLSTM 方案。
| Model | Accuracy |
|---|---|
| mean-vectors | 0.65 |
| skip-thoughts-CS | 0.62 |
| Dor et al. | 0.74 |
| SBERT-WikiSec-base | 0.8042 |
| SBERT-WikiSec-large | 0.8078 |
| SRoBERTa-WikiSec-base | 0.7945 |
| SRoBERTa-WikiSec-large | 0.7973 |
Table 4: Evaluation on the Wikipedia section triplets dataset Dor et al. 2018. SBERT trained with triplet loss for one epoch.
| 模型 | 准确率 |
|---|---|
| mean-vectors | 0.65 |
| skip-thoughts-CS | 0.62 |
| Dor et al. | 0.74 |
| SBERT-WikiSec-base | 0.8042 |
| SBERT-WikiSec-large | 0.8078 |
| SRoBERTa-WikiSec-base | 0.7945 |
| SRoBERTa-WikiSec-large | 0.7973 |
表 4:维基百科小节三元组数据集(Dor et al. 2018)评测。SBERT 以三元组损失训练一个 epoch。
5 Evaluation - SentEval
5 评测——SentEval
| Model | MR | CR | SUBJ | MPQA | SST | TREC | MRPC | Avg. |
|---|---|---|---|---|---|---|---|---|
| Avg. GloVe embeddings | 77.25 | 78.30 | 91.17 | 87.85 | 80.18 | 83.0 | 72.87 | 81.52 |
| Avg. fast-text embeddings | 77.96 | 79.23 | 91.68 | 87.81 | 82.15 | 83.6 | 74.49 | 82.42 |
| Avg. BERT embeddings | 78.66 | 86.25 | 94.37 | 88.66 | 84.40 | 92.8 | 69.45 | 84.94 |
| BERT CLS-vector | 78.68 | 84.85 | 94.21 | 88.23 | 84.13 | 91.4 | 71.13 | 84.66 |
| InferSent - GloVe | 81.57 | 86.54 | 92.50 | 90.38 | 84.18 | 88.2 | 75.77 | 85.59 |
| Universal Sentence Encoder | 80.09 | 85.19 | 93.98 | 86.70 | 86.38 | 93.2 | 70.14 | 85.10 |
| SBERT-NLI-base | 83.64 | 89.43 | 94.39 | 89.86 | 88.96 | 89.6 | 76.00 | 87.41 |
| SBERT-NLI-large | 84.88 | 90.07 | 94.52 | 90.33 | 90.66 | 87.4 | 75.94 | 87.69 |
Table 5: Evaluation of SBERT sentence embeddings using the SentEval toolkit. SentEval evaluates sentence embeddings on different sentence classification tasks by training a logistic regression classifier using the sentence embeddings as features. Scores are based on a 10-fold cross-validation.
| 模型 | MR | CR | SUBJ | MPQA | SST | TREC | MRPC | 平均 |
|---|---|---|---|---|---|---|---|---|
| Avg. GloVe embeddings | 77.25 | 78.30 | 91.17 | 87.85 | 80.18 | 83.0 | 72.87 | 81.52 |
| Avg. fast-text embeddings | 77.96 | 79.23 | 91.68 | 87.81 | 82.15 | 83.6 | 74.49 | 82.42 |
| Avg. BERT embeddings | 78.66 | 86.25 | 94.37 | 88.66 | 84.40 | 92.8 | 69.45 | 84.94 |
| BERT CLS-vector | 78.68 | 84.85 | 94.21 | 88.23 | 84.13 | 91.4 | 71.13 | 84.66 |
| InferSent - GloVe | 81.57 | 86.54 | 92.50 | 90.38 | 84.18 | 88.2 | 75.77 | 85.59 |
| Universal Sentence Encoder | 80.09 | 85.19 | 93.98 | 86.70 | 86.38 | 93.2 | 70.14 | 85.10 |
| SBERT-NLI-base | 83.64 | 89.43 | 94.39 | 89.86 | 88.96 | 89.6 | 76.00 | 87.41 |
| SBERT-NLI-large | 84.88 | 90.07 | 94.52 | 90.33 | 90.66 | 87.4 | 75.94 | 87.69 |
表 5:用 SentEval 工具包评测 SBERT 句向量。SentEval 以句向量为特征训练逻辑回归,在多种句子分类任务上做 10 折交叉验证并报告测试折准确率。
SentEval Conneau and Kiela 2018 is a popular toolkit to evaluate the quality of sentence embeddings. Sentence embeddings are used as features for a logistic regression classifier. The logistic regression classifier is trained on various tasks in a 10-fold cross-validation setup and the prediction accuracy is computed for the test-fold.
SentEval(Conneau and Kiela 2018)是评测句向量质量的常用工具包:以句向量为特征训练逻辑回归,在多种任务上做 10 折交叉验证,并报告测试折预测准确率。
The purpose of SBERT sentence embeddings are not to be used for transfer learning for other tasks. Here, we think fine-tuning BERT as described by Devlin et al. 2018 for new tasks is the more suitable method, as it updates all layers of the BERT network. However, SentEval can still give an impression on the quality of our sentence embeddings for various tasks.
SBERT 句向量的本意并非服务其他任务的迁移学习。我们认为,按 Devlin et al. 2018 所述对 BERT 做任务微调、更新全部层,更合适。但 SentEval 仍能让我们大致了解句向量在多种任务上的质量。
We compare the SBERT sentence embeddings to other sentence embeddings methods on the following seven SentEval transfer tasks:
我们在下列七项 SentEval 迁移任务上,把 SBERT 句向量与其他方法比较:
- • MR: Sentiment prediction for movie reviews snippets on a five start scale Pang and Lee 2005.
- • CR: Sentiment prediction of customer product reviews Hu and Liu 2004.
- • SUBJ: Subjectivity prediction of sentences from movie reviews and plot summaries Pang and Lee 2004.
- • MPQA: Phrase level opinion polarity classification from newswire Wiebe et al. 2005.
- • SST: Stanford Sentiment Treebank with binary labels Socher et al. 2013.
- • TREC: Fine grained question-type classification from TREC Li and Roth 2002.
- • MRPC: Microsoft Research Paraphrase Corpus from parallel news sources Dolan et al. 2004.
- • MR:电影评论片段五星情感预测(Pang and Lee 2005)。
- • CR:顾客产品评论情感预测(Hu and Liu 2004)。
- • SUBJ:电影评论与剧情摘要句子的主客观预测(Pang and Lee 2004)。
- • MPQA:新闻电讯短语级观点极性分类(Wiebe et al. 2005)。
- • SST:斯坦福情感树库二分类(Socher et al. 2013)。
- • TREC:TREC 细粒度问题类型分类(Li and Roth 2002)。
- • MRPC:微软研究院平行新闻来源复述语料(Dolan et al. 2004)。
The results can be found in Table 5. SBERT is able to achieve the best performance in 5 out of 7 tasks. The average performance increases by about 2 percentage points compared to InferSent as well as the Universal Sentence Encoder. Even though transfer learning is not the purpose of SBERT, it outperforms other state-of-the-art sentence embeddings methods on this task.
结果见表 5。SBERT 在 7 项中的 5 项取得最佳;相对 InferSent 与 Universal Sentence Encoder,平均约高 2 个百分点。尽管迁移学习并非 SBERT 的目标,它在该设定上仍优于其他前沿句向量方法。
It appears that the sentence embeddings from SBERT capture well sentiment information: We observe large improvements for all sentiment tasks (MR, CR, and SST) from SentEval in comparison to InferSent and Universal Sentence Encoder.
看起来 SBERT 句向量较好地抓住了情感信息:相对 InferSent 与 Universal Sentence Encoder,SentEval 全部情感任务(MR、CR、SST)都有明显提升。
The only dataset where SBERT is significantly worse than Universal Sentence Encoder is the TREC dataset. Universal Sentence Encoder was pre-trained on question-answering data, which appears to be beneficial for the question-type classification task of the TREC dataset.
唯一明显弱于 Universal Sentence Encoder 的是 TREC:后者在问答数据上预训练,似乎有利于 TREC 的问题类型分类。
Average BERT embeddings or using the CLS-token output from a BERT network achieved bad results for various STS tasks (Table 1), worse than average GloVe embeddings. However, for SentEval, average BERT embeddings and the BERT CLS-token output achieves decent results (Table 5), outperforming average GloVe embeddings. The reason for this are the different setups. For the STS tasks, we used cosine-similarity to estimate the similarities between sentence embeddings. Cosine-similarity treats all dimensions equally. In contrast, SentEval fits a logistic regression classifier to the sentence embeddings. This allows that certain dimensions can have higher or lower impact on the classification result.
平均 BERT 嵌入或 BERT 的 CLS 输出在多项 STS 上很差(表 1),不如平均 GloVe;但在 SentEval 上尚可(表 5),且优于平均 GloVe。原因在于设定不同:STS 用余弦相似度估计相似性,各维一视同仁;SentEval 则拟合逻辑回归,允许某些维对分类影响更大或更小。
We conclude that average BERT embeddings / CLS-token output from BERT return sentence embeddings that are infeasible to be used with cosine-similarity or with Manhatten / Euclidean distance. For transfer learning, they yield slightly worse results than InferSent or Universal Sentence Encoder. However, using the described fine-tuning setup with a siamese network structure on NLI datasets yields sentence embeddings that achieve a new state-of-the-art for the SentEval toolkit.
我们结论是:平均 BERT 嵌入 / CLS 输出不宜配合余弦相似度或曼哈顿 / 欧氏距离使用;用于迁移学习时略逊于 InferSent 或 Universal Sentence Encoder。而在 NLI 上以孪生结构按所述方式微调后,句向量在 SentEval 工具包上刷新了表现。
6 Ablation Study
6 消融实验
We have demonstrated strong empirical results for the quality of SBERT sentence embeddings. In this section, we perform an ablation study of different aspects of SBERT in order to get a better understanding of their relative importance.
前文已展示 SBERT 句向量的强经验表现。本节对若干设计侧面做消融,以理解其相对重要性。
We evaluated different pooling strategies (MEAN, MAX, and CLS). For the classification objective function, we evaluate different concatenation methods. For each possible configuration, we train SBERT with 10 different random seeds and average the performances.
我们评测不同池化策略(MEAN、MAX、CLS)。对分类目标函数,还评测不同拼接方式。每种配置用 10 个随机种子训练 SBERT,再对表现取平均。
The objective function (classification vs. regression) depends on the annotated dataset. For the classification objective function, we train SBERT-base on the SNLI and the Multi-NLI dataset. For the regression objective function, we train on the training set of the STS benchmark dataset. Performances are measured on the development split of the STS benchmark dataset. Results are shown in Table 6.
目标函数(分类 vs. 回归)取决于标注数据:分类目标下,在 SNLI 与 Multi-NLI 上训 SBERT-base;回归目标下,在 STS 基准训练集上训练。表现在 STS 基准开发集上度量,结果见表 6。
| NLI | STSb | |
|---|---|---|
| Pooling Strategy | ||
| MEAN | 80.78 | 87.44 |
| MAX | 79.07 | 69.92 |
| CLS | 79.80 | 86.62 |
| Concatenation | ||
| 66.04 | - | |
| 69.78 | - | |
| 70.54 | - | |
| 78.37 | - | |
| 77.44 | - | |
| 80.78 | - | |
| 80.44 | - |
Table 6: SBERT trained on NLI data with the classification objective function, on the STS benchmark (STSb) with the regression objective function. Configurations are evaluated on the development set of the STSb using cosine-similarity and Spearman’s rank correlation. For the concatenation methods, we only report scores with MEAN pooling strategy.
| NLI | STSb | |
|---|---|---|
| 池化策略 | ||
| MEAN | 80.78 | 87.44 |
| MAX | 79.07 | 69.92 |
| CLS | 79.80 | 86.62 |
| 拼接方式 | ||
| 66.04 | - | |
| 69.78 | - | |
| 70.54 | - | |
| 78.37 | - | |
| 77.44 | - | |
| 80.78 | - | |
| 80.44 | - |
表 6:在 NLI 上以分类目标、在 STS 基准(STSb)上以回归目标训练的 SBERT。配置在 STSb 开发集上用余弦相似度与 Spearman 秩相关评测。拼接方式仅报告 MEAN 池化分数。
When trained with the classification objective function on NLI data, the pooling strategy has a rather minor impact. The impact of the concatenation mode is much larger. InferSent Conneau et al. 2017 and Universal Sentence Encoder Cer et al. 2018 both use as input for a softmax classifier. However, in our architecture, adding the element-wise decreased the performance.
在 NLI 上以分类目标训练时,池化策略影响较小,拼接方式影响更大。InferSent(Conneau et al. 2017)与 Universal Sentence Encoder(Cer et al. 2018)都把 送入 softmax 分类器;在我们的结构中,再加逐元素积 反而降点。
The most important component is the element-wise difference . Note, that the concatenation mode is only relevant for training the softmax classifier. At inference, when predicting similarities for the STS benchmark dataset, only the sentence embeddings and are used in combination with cosine-similarity. The element-wise difference measures the distance between the dimensions of the two sentence embeddings, ensuring that similar pairs are closer and dissimilar pairs are further apart.
最关键的成分是逐元素差 。注意拼接方式只影响训练 softmax 分类器;推理在 STS 基准上预测相似度时,只用句向量 、 配合余弦相似度。逐元素差度量两句向量各维距离,促使相似对更近、不相似对更远。
When trained with the regression objective function, we observe that the pooling strategy has a large impact. There, the MAX strategy perform significantly worse than MEAN or CLS-token strategy. This is in contrast to Conneau et al. 2017, who found it beneficial for the BiLSTM-layer of InferSent to use MAX instead of MEAN pooling.
以回归目标训练时,池化策略影响很大:MAX 明显弱于 MEAN 或 CLS。这与 Conneau et al. 2017 相反——他们发现 InferSent 的 BiLSTM 层用 MAX 优于 MEAN。
7 Computational Efficiency
7 计算效率
Sentence embeddings need potentially be computed for Millions of sentences, hence, a high computation speed is desired. In this section, we compare SBERT to average GloVe embeddings, InferSent Conneau et al. 2017, and Universal Sentence Encoder Cer et al. 2018.
句向量常需对上百万句计算,因此希望速度高。本节把 SBERT 与平均 GloVe、InferSent(Conneau et al. 2017)、Universal Sentence Encoder(Cer et al. 2018)比较。
For our comparison we use the sentences from the STS benchmark Cer et al. 2017. We compute average GloVe embeddings using a simple for-loop with python dictionary lookups and NumPy. InferSent[^4] is based on PyTorch. For Universal Sentence Encoder, we use the TensorFlow Hub version[^5], which is based on TensorFlow. SBERT is based on PyTorch. For improved computation of sentence embeddings, we implemented a smart batching strategy: Sentences with similar lengths are grouped together and are only padded to the longest element in a mini-batch. This drastically reduces computational overhead from padding tokens.
比较使用 STS 基准(Cer et al. 2017)中的句子。平均 GloVe 用 Python 字典查找与 NumPy 的简单循环;InferSent[^4] 基于 PyTorch;Universal Sentence Encoder 用 TensorFlow Hub 版本[^5](基于 TensorFlow);SBERT 基于 PyTorch。为加速句向量计算,我们实现了智能批处理:长度相近的句子分到一组,只填充到该 mini-batch 中最长者,从而大幅减少填充 token 的开销。
Performances were measured on a server with Intel i7-5820K CPU @ 3.30GHz, Nvidia Tesla V100 GPU, CUDA 9.2 and cuDNN. The results are depicted in Table 7.
性能在配备 Intel i7-5820K CPU @ 3.30GHz、Nvidia Tesla V100 GPU、CUDA 9.2 与 cuDNN 的服务器上测量,结果见表 7。
| Model | CPU | GPU |
|---|---|---|
| Avg. GloVe embeddings | 6469 | - |
| InferSent | 137 | 1876 |
| Universal Sentence Encoder | 67 | 1318 |
| SBERT-base | 44 | 1378 |
| SBERT-base - smart batching | 83 | 2042 |
Table 7: Computation speed (sentences per second) of sentence embedding methods. Higher is better.
| 模型 | CPU | GPU |
|---|---|---|
| Avg. GloVe embeddings | 6469 | - |
| InferSent | 137 | 1876 |
| Universal Sentence Encoder | 67 | 1318 |
| SBERT-base | 44 | 1378 |
| SBERT-base - smart batching | 83 | 2042 |
表 7:句向量方法的计算速度(句/秒)。越高越好。
On CPU, InferSent is about 65% faster than SBERT. This is due to the much simpler network architecture. InferSent uses a single BiLSTM layer, while BERT uses 12 stacked transformer layers. However, an advantage of transformer networks is the computational efficiency on GPUs. There, SBERT with smart batching is about 9% faster than InferSent and about 55% faster than Universal Sentence Encoder. Smart batching achieves a speed-up of 89% on CPU and 48% on GPU. Average GloVe embeddings is obviously by a large margin the fastest method to compute sentence embeddings.
在 CPU 上,InferSent 约比 SBERT 快 65%,因其网络简单得多:InferSent 单层 BiLSTM,BERT 则是 12 层堆叠 Transformer。Transformer 的优势在 GPU:带智能批处理的 SBERT 约比 InferSent 快 9%,比 Universal Sentence Encoder 快约 55%。智能批处理在 CPU 上加速 89%,在 GPU 上加速 48%。平均 GloVe 显然仍是算句向量最快的方法。
8 Conclusion
8 结论
We showed that BERT out-of-the-box maps sentences to a vector space that is rather unsuitable to be used with common similarity measures like cosine-similarity. The performance for seven STS tasks was below the performance of average GloVe embeddings.
我们表明:开箱即用的 BERT 把句子映到的向量空间,并不适合配合余弦相似度等常用度量;在七项 STS 任务上的表现甚至低于平均 GloVe 嵌入。
To overcome this shortcoming, we presented Sentence-BERT (SBERT). SBERT fine-tunes BERT in a siamese / triplet network architecture. We evaluated the quality on various common benchmarks, where it could achieve a significant improvement over state-of-the-art sentence embeddings methods. Replacing BERT with RoBERTa did not yield a significant improvement in our experiments.
为克服这一不足,我们提出 Sentence-BERT(SBERT):以孪生 / 三元组结构微调 BERT。在多种常用基准上,它相对当时前沿句向量方法有显著提升。实验中用 RoBERTa 替换 BERT 未见明显增益。
SBERT is computationally efficient. On a GPU, it is about 9% faster than InferSent and about 55% faster than Universal Sentence Encoder. SBERT can be used for tasks which are computationally not feasible to be modeled with BERT. For example, clustering of 10,000 sentences with hierarchical clustering requires with BERT about 65 hours, as around 50 Million sentence combinations must be computed. With SBERT, we were able to reduce the effort to about 5 seconds.
SBERT 计算高效:在 GPU 上约比 InferSent 快 9%,比 Universal Sentence Encoder 快约 55%。它可用于 BERT 在计算上难以建模的任务。例如对一万句做层次聚类,BERT 约需 65 小时(约五千万句对组合);SBERT 可将开销降到约 5 秒。
Acknowledgments
致谢
This work has been supported by the German Research Foundation through the German-Israeli Project Cooperation (DIP, grant DA 1600/1-1 and grant GU 798/17-1). It has been co-funded by the German Federal Ministry of Education and Research (BMBF) under the promotional references 03VP02540 (ArgumenText).
本工作获德国研究基金会德以项目合作(DIP,资助号 DA 1600/1-1 与 GU 798/17-1)支持,并获德国联邦教育与研究部(BMBF)在宣传编号 03VP02540(ArgumenText)下的共同资助。
References
参考文献
Agirre et al. (2015) Eneko Agirre, Carmen Banea, Claire Cardie, Daniel Cer, Mona Diab, Aitor Gonzalez-Agirre, Weiwei Guo, Inigo Lopez-Gazpio, Montse Maritxalar, Rada Mihalcea, German Rigau, Larraitz Uria, and Janyce Wiebe. 2015. SemEval-2015 Task 2: Semantic Textual Similarity, English, Spanish and Pilot on Interpretability . In Proceedings of the 9th International Workshop on Semantic Evaluation (SemEval 2015) , pages 252–263, Denver, Colorado. Association for Computational Linguistics.
Agirre et al. (2014) Eneko Agirre, Carmen Banea, Claire Cardie, Daniel Cer, Mona Diab, Aitor Gonzalez-Agirre, Weiwei Guo, Rada Mihalcea, German Rigau, and Janyce Wiebe. 2014. SemEval-2014 Task 10: Multilingual Semantic Textual Similarity . In Proceedings of the 8th International Workshop on Semantic Evaluation (SemEval 2014) , pages 81–91, Dublin, Ireland. Association for Computational Linguistics.
Agirre et al. (2016) Eneko Agirre, Carmen Banea, Daniel M. Cer, Mona T. Diab, Aitor Gonzalez-Agirre, Rada Mihalcea, German Rigau, and Janyce Wiebe. 2016. SemEval-2016 Task 1: Semantic Textual Similarity, Monolingual and Cross-Lingual Evaluation . In Proceedings of the 10th International Workshop on Semantic Evaluation, SemEval@NAACL-HLT 2016, San Diego, CA, USA, June 16-17, 2016 , pages 497–511.
Agirre et al. (2013) Eneko Agirre, Daniel Cer, Mona Diab, Aitor Gonzalez-Agirre, and Weiwei Guo. 2013. *SEM 2013 shared task: Semantic Textual Similarity . In Second Joint Conference on Lexical and Computational Semantics (*SEM), Volume 1: Proceedings of the Main Conference and the Shared Task: Semantic Textual Similarity , pages 32–43, Atlanta, Georgia, USA. Association for Computational Linguistics.
Agirre et al. (2012) Eneko Agirre, Mona Diab, Daniel Cer, and Aitor Gonzalez-Agirre. 2012. SemEval-2012 Task 6: A Pilot on Semantic Textual Similarity . In Proceedings of the First Joint Conference on Lexical and Computational Semantics - Volume 1: Proceedings of the Main Conference and the Shared Task, and Volume 2: Proceedings of the Sixth International Workshop on Semantic Evaluation , SemEval ’12, pages 385–393, Stroudsburg, PA, USA. Association for Computational Linguistics.
Bowman et al. (2015) Samuel R. Bowman, Gabor Angeli, Christopher Potts, and Christopher D. Manning. 2015. A large annotated corpus for learning natural language inference . In Proceedings of the 2015 Conference on Empirical Methods in Natural Language Processing , pages 632–642, Lisbon, Portugal. Association for Computational Linguistics.
Cer et al. (2017) Daniel Cer, Mona Diab, Eneko Agirre, Iñigo Lopez-Gazpio, and Lucia Specia. 2017. SemEval-2017 Task 1: Semantic Textual Similarity Multilingual and Crosslingual Focused Evaluation . In Proceedings of the 11th International Workshop on Semantic Evaluation (SemEval-2017) , pages 1–14, Vancouver, Canada.
Cer et al. (2018) Daniel Cer, Yinfei Yang, Sheng-yi Kong, Nan Hua, Nicole Limtiaco, Rhomni St. John, Noah Constant, Mario Guajardo-Cespedes, Steve Yuan, Chris Tar, Yun-Hsuan Sung, Brian Strope, and Ray Kurzweil. 2018. Universal Sentence Encoder . arXiv preprint arXiv:1803.11175 .
Conneau and Kiela (2018) Alexis Conneau and Douwe Kiela. 2018. SentEval: An Evaluation Toolkit for Universal Sentence Representations . arXiv preprint arXiv:1803.05449 .
Conneau et al. (2017) Alexis Conneau, Douwe Kiela, Holger Schwenk, Loïc Barrault, and Antoine Bordes. 2017. Supervised Learning of Universal Sentence Representations from Natural Language Inference Data . In Proceedings of the 2017 Conference on Empirical Methods in Natural Language Processing , pages 670–680, Copenhagen, Denmark. Association for Computational Linguistics.
Devlin et al. (2018) Jacob Devlin, Ming-Wei Chang, Kenton Lee, and Kristina Toutanova. 2018. BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding . arXiv preprint arXiv:1810.04805 .
Dolan et al. (2004) Bill Dolan, Chris Quirk, and Chris Brockett. 2004. Unsupervised Construction of Large Paraphrase Corpora: Exploiting Massively Parallel News Sources . In Proceedings of the 20th International Conference on Computational Linguistics , COLING ’04, Stroudsburg, PA, USA. Association for Computational Linguistics.
Dor et al. (2018) Liat Ein Dor, Yosi Mass, Alon Halfon, Elad Venezian, Ilya Shnayderman, Ranit Aharonov, and Noam Slonim. 2018. Learning Thematic Similarity Metric from Article Sections Using Triplet Networks . In Proceedings of the 56th Annual Meeting of the Association for Computational Linguistics (Volume 2: Short Papers) , pages 49–54, Melbourne, Australia. Association for Computational Linguistics.
Hill et al. (2016) Felix Hill, Kyunghyun Cho, and Anna Korhonen. 2016. Learning Distributed Representations of Sentences from Unlabelled Data . In Proceedings of the 2016 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies , pages 1367–1377, San Diego, California. Association for Computational Linguistics.
Hu and Liu (2004) Minqing Hu and Bing Liu. 2004. Mining and Summarizing Customer Reviews . In Proceedings of the Tenth ACM SIGKDD International Conference on Knowledge Discovery and Data Mining , KDD ’04, pages 168–177, New York, NY, USA. ACM.
Humeau et al. (2019) Samuel Humeau, Kurt Shuster, Marie-Anne Lachaux, and Jason Weston. 2019. Real-time Inference in Multi-sentence Tasks with Deep Pretrained Transformers . arXiv preprint arXiv:1905.01969 , abs/1905.01969.
Johnson et al. (2017) Jeff Johnson, Matthijs Douze, and Hervé Jégou. 2017. Billion-scale similarity search with GPUs . arXiv preprint arXiv:1702.08734 .
Kiros et al. (2015) Ryan Kiros, Yukun Zhu, Ruslan R Salakhutdinov, Richard Zemel, Raquel Urtasun, Antonio Torralba, and Sanja Fidler. 2015. Skip-Thought Vectors . In C. Cortes, N. D. Lawrence, D. D. Lee, M. Sugiyama, and R. Garnett, editors, Advances in Neural Information Processing Systems 28 , pages 3294–3302. Curran Associates, Inc.
Li and Roth (2002) Xin Li and Dan Roth. 2002. Learning Question Classifiers . In Proceedings of the 19th International Conference on Computational Linguistics - Volume 1 , COLING ’02, pages 1–7, Stroudsburg, PA, USA. Association for Computational Linguistics.
Liu et al. (2019) Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, and Veselin Stoyanov. 2019. RoBERTa: A Robustly Optimized BERT Pretraining Approach . arXiv preprint arXiv:1907.11692 .
Marelli et al. (2014) Marco Marelli, Stefano Menini, Marco Baroni, Luisa Bentivogli, Raffaella Bernardi, and Roberto Zamparelli. 2014. A SICK cure for the evaluation of compositional distributional semantic models . In Proceedings of the Ninth International Conference on Language Resources and Evaluation (LREC’14) , pages 216–223, Reykjavik, Iceland. European Language Resources Association (ELRA).
May et al. (2019) Chandler May, Alex Wang, Shikha Bordia, Samuel R. Bowman, and Rachel Rudinger. 2019. On Measuring Social Biases in Sentence Encoders . arXiv preprint arXiv:1903.10561 .
Misra et al. (2016) Amita Misra, Brian Ecker, and Marilyn A. Walker. 2016. Measuring the Similarity of Sentential Arguments in Dialogue . In Proceedings of the SIGDIAL 2016 Conference, The 17th Annual Meeting of the Special Interest Group on Discourse and Dialogue, 13-15 September 2016, Los Angeles, CA, USA , pages 276–287.
Pang and Lee (2004) Bo Pang and Lillian Lee. 2004. A Sentimental Education: Sentiment Analysis Using Subjectivity Summarization Based on Minimum Cuts . In Proceedings of the 42nd Meeting of the Association for Computational Linguistics (ACL’04), Main Volume , pages 271–278, Barcelona, Spain.
Pang and Lee (2005) Bo Pang and Lillian Lee. 2005. Seeing Stars: Exploiting Class Relationships for Sentiment Categorization with Respect to Rating Scales . In Proceedings of the 43rd Annual Meeting of the Association for Computational Linguistics (ACL’05) , pages 115–124, Ann Arbor, Michigan. Association for Computational Linguistics.
Pennington et al. (2014) Jeffrey Pennington, Richard Socher, and Christopher D. Manning. 2014. GloVe: Global Vectors for Word Representation . In Empirical Methods in Natural Language Processing (EMNLP) , pages 1532–1543.
Qiao et al. (2019) Yifan Qiao, Chenyan Xiong, Zheng-Hao Liu, and Zhiyuan Liu. 2019. Understanding the Behaviors of BERT in Ranking . arXiv preprint arXiv:1904.07531 .
Reimers et al. (2016) Nils Reimers, Philip Beyer, and Iryna Gurevych. 2016. Task-Oriented Intrinsic Evaluation of Semantic Textual Similarity . In Proceedings of the 26th International Conference on Computational Linguistics (COLING) , pages 87–96.
Reimers and Gurevych (2018) Nils Reimers and Iryna Gurevych. 2018. Why Comparing Single Performance Scores Does Not Allow to Draw Conclusions About Machine Learning Approaches . arXiv preprint arXiv:1803.09578 , abs/1803.09578.
Reimers et al. (2019) Nils Reimers, Benjamin Schiller, Tilman Beck, Johannes Daxenberger, Christian Stab, and Iryna Gurevych. 2019. Classification and Clustering of Arguments with Contextualized Word Embeddings . In Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics , pages 567–578, Florence, Italy. Association for Computational Linguistics.
Schroff et al. (2015) Florian Schroff, Dmitry Kalenichenko, and James Philbin. 2015. FaceNet: A Unified Embedding for Face Recognition and Clustering . arXiv preprint arXiv:1503.03832 , abs/1503.03832.
Socher et al. (2013) Richard Socher, Alex Perelygin, Jean Wu, Jason Chuang, Christopher D. Manning, Andrew Ng, and Christopher Potts. 2013. Recursive Deep Models for Semantic Compositionality Over a Sentiment Treebank . In Proceedings of the 2013 Conference on Empirical Methods in Natural Language Processing , pages 1631–1642, Seattle, Washington, USA. Association for Computational Linguistics.
Vaswani et al. (2017) Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Łukasz Kaiser, and Illia Polosukhin. 2017. Attention is All you Need . In I. Guyon, U. V. Luxburg, S. Bengio, H. Wallach, R. Fergus, S. Vishwanathan, and R. Garnett, editors, Advances in Neural Information Processing Systems 30 , pages 5998–6008.
Wiebe et al. (2005) Janyce Wiebe, Theresa Wilson, and Claire Cardie. 2005. Annotating Expressions of Opinions and Emotions in Language . Language Resources and Evaluation , 39(2):165–210.
Williams et al. (2018) Adina Williams, Nikita Nangia, and Samuel Bowman. 2018. A Broad-Coverage Challenge Corpus for Sentence Understanding through Inference . In Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers) , pages 1112–1122. Association for Computational Linguistics.
Yang et al. (2018) Yinfei Yang, Steve Yuan, Daniel Cer, Sheng-Yi Kong, Noah Constant, Petr Pilar, Heming Ge, Yun-hsuan Sung, Brian Strope, and Ray Kurzweil. 2018. Learning Semantic Textual Similarity from Conversations . In Proceedings of The Third Workshop on Representation Learning for NLP , pages 164–174, Melbourne, Australia. Association for Computational Linguistics.
Yang et al. (2019) Zhilin Yang, Zihang Dai, Yiming Yang, Jaime G. Carbonell, Ruslan Salakhutdinov, and Quoc V. Le. 2019. XLNet: Generalized Autoregressive Pretraining for Language Understanding . arXiv preprint arXiv:1906.08237 , abs/1906.08237.
Zhang et al. (2019) Tianyi Zhang, Varsha Kishore, Felix Wu, Kilian Q. Weinberger, and Yoav Artzi. 2019. BERTScore: Evaluating Text Generation with BERT . arXiv preprint arXiv:1904.09675 .