Score-Based Generative Modeling through Stochastic Differential Equations
Score-Based Generative Modeling through Stochastic Differential Equations
通过随机微分方程进行基于分数的生成建模
Yang Song † † thanks: Work partially done during an internship at Google Brain. Affiliation: Stanford University Email: yangsong@cs.stanford.edu Jascha Sohl-Dickstein Affiliation: Google Brain Email: jaschasd@google.com Diederik P. Kingma Affiliation: Google Brain Email: durk@google.com Abhishek Kumar Affiliation: Google Brain Email: abhishk@google.com Stefano Ermon Affiliation: Stanford University Email: ermon@cs.stanford.edu Ben Poole Affiliation: Google Brain Email: pooleb@google.com
Abstract
摘要
Creating noise from data is easy; creating data from noise is generative modeling. We present a stochastic differential equation (SDE) that smoothly transforms a complex data distribution to a known prior distribution by slowly injecting noise, and a corresponding reverse-time SDE that transforms the prior distribution back into the data distribution by slowly removing the noise. Crucially, the reverse-time SDE depends only on the time-dependent gradient field (a.k.a., score) of the perturbed data distribution. By leveraging advances in score-based generative modeling, we can accurately estimate these scores with neural networks, and use numerical SDE solvers to generate samples. We show that this framework encapsulates previous approaches in score-based generative modeling and diffusion probabilistic modeling, allowing for new sampling procedures and new modeling capabilities. In particular, we introduce a predictor-corrector framework to correct errors in the evolution of the discretized reverse-time SDE. We also derive an equivalent neural ODE that samples from the same distribution as the SDE, but additionally enables exact likelihood computation, and improved sampling efficiency. In addition, we provide a new way to solve inverse problems with score-based models, as demonstrated with experiments on class-conditional generation, image inpainting, and colorization. Combined with multiple architectural improvements, we achieve record-breaking performance for unconditional image generation on CIFAR-10 with an Inception score of 9.89 and FID of 2.20, a competitive likelihood of 2.99 bits/dim, and demonstrate high fidelity generation of images for the first time from a score-based generative model.
从数据制造噪声很容易;从噪声里再造出数据,才是生成建模。我们给出一条随机微分方程(SDE),它通过慢慢注入噪声,把复杂的数据分布平滑地变成已知的先验分布;再给出对应的时间反向 SDE,通过慢慢去掉噪声,把先验变回数据分布。关键在于,反向 SDE 只依赖于扰动数据分布随时间变化的梯度场,也就是分数(score)。借助基于分数的生成建模方面的进展,我们可以用神经网络把这些分数估准,再用数值 SDE 求解器来生成样本。这一框架把先前的分数生成模型和扩散概率模型都收了进来,从而允许新的采样程序和新的建模能力。具体而言,我们引入一套预测-校正框架,用来修正离散化反向 SDE 演化中的误差。我们还推导出一条等价的神经 ODE,它与 SDE 采样同一分布,同时又可以精确计算似然,并提高采样效率。此外,我们给出一种用分数模型求解反问题的新方法,并在类别条件生成、图像补全和上色实验中做了验证。再加上多项结构改进,我们在 CIFAR-10 无条件图像生成上达到当时最好的 Inception 分数 9.89 和 FID 2.20,似然也有竞争力,为 2.99 bits/dim,并且第一次用分数生成模型给出了 的高保真样本。
1 Introduction
1 引言
Two successful classes of probabilistic generative models involve sequentially corrupting training data with slowly increasing noise, and then learning to reverse this corruption in order to form a generative model of the data. Score matching with Langevin dynamics (SMLD) (Song & Ermon, 2019) estimates the score (i.e., the gradient of the log probability density with respect to data) at each noise scale, and then uses Langevin dynamics to sample from a sequence of decreasing noise scales during generation. Denoising diffusion probabilistic modeling (DDPM) (Sohl-Dickstein et al., 2015; Ho et al., 2020) trains a sequence of probabilistic models to reverse each step of the noise corruption, using knowledge of the functional form of the reverse distributions to make training tractable. For continuous state spaces, the DDPM training objective implicitly computes scores at each noise scale. We therefore refer to these two model classes together as score-based generative models.
有两类成功的概率生成模型,都是先用缓慢增大的噪声依次腐蚀训练数据,再学习把这一腐蚀过程反过来,从而得到数据的生成模型。带 Langevin 动力学的分数匹配(SMLD)(Song & Ermon, 2019)在每个噪声尺度上估计分数(即对数概率密度对数据的梯度),生成时再用 Langevin 动力学沿着一组由大到小的噪声尺度采样。去噪扩散概率建模(DDPM)(Sohl-Dickstein et al., 2015; Ho et al., 2020)则训练一串概率模型,分别反转每一步噪声腐蚀,并利用反向分布的函数形式使训练变得可行。在连续状态空间里,DDPM 的训练目标其实也在各个噪声尺度上隐式地计算分数。因此,我们把这两类模型合称为基于分数的生成模型。
Score-based generative models, and related techniques (Bordes et al., 2017; Goyal et al., 2017; Du & Mordatch, 2019), have proven effective at generation of images (Song & Ermon, 2019; Song & Ermon, 2020; Ho et al., 2020), audio (Chen et al., 2020; Kong et al., 2020), graphs (Niu et al., 2020), and shapes (Cai et al., 2020). To enable new sampling methods and further extend the capabilities of score-based generative models, we propose a unified framework that generalizes previous approaches through the lens of stochastic differential equations (SDEs).
基于分数的生成模型,以及一些相关方法(Bordes et al., 2017; Goyal et al., 2017; Du & Mordatch, 2019),已经在图像(Song & Ermon, 2019; Song & Ermon, 2020; Ho et al., 2020)、音频(Chen et al., 2020; Kong et al., 2020)、图(Niu et al., 2020)和形状(Cai et al., 2020)生成上表现出色。为了引入新的采样方法并进一步扩展分数生成模型的能力,我们提出一个统一框架,从随机微分方程(SDE)的角度概括先前的做法。
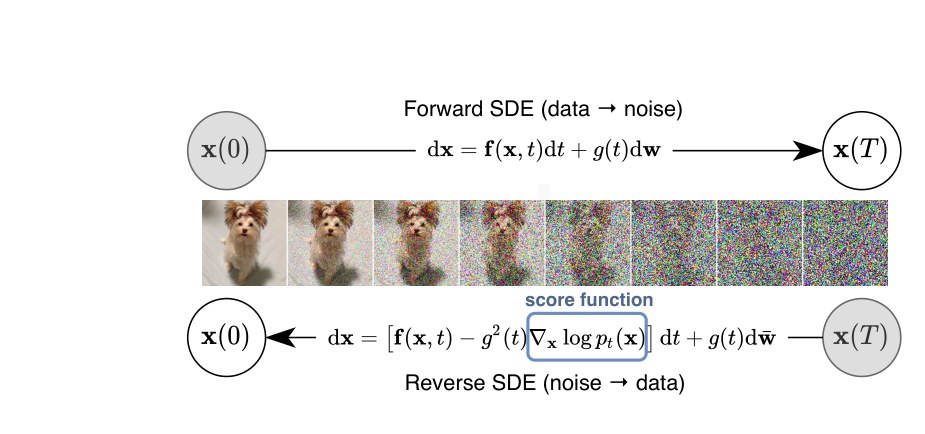
Figure 1: Solving a reverse-time SDE yields a score-based generative model. Transforming data to a simple noise distribution can be accomplished with a continuous-time SDE. This SDE can be reversed if we know the score of the distribution at each intermediate time step, .
图 1:求解一条时间反向的 SDE,就得到一个基于分数的生成模型。 用一条连续时间 SDE,就可以把数据变成简单的噪声分布。只要知道每个中间时刻该分布的分数 ,这条 SDE 就可以反转。
Specifically, instead of perturbing data with a finite number of noise distributions, we consider a continuum of distributions that evolve over time according to a diffusion process. This process progressively diffuses a data point into random noise, and is given by a prescribed SDE that does not depend on the data and has no trainable parameters. By reversing this process, we can smoothly mold random noise into data for sample generation. Crucially, this reverse process satisfies a reverse-time SDE (Anderson, 1982), which can be derived from the forward SDE given the score of the marginal probability densities as a function of time. We can therefore approximate the reverse-time SDE by training a time-dependent neural network to estimate the scores, and then produce samples using numerical SDE solvers. Our key idea is summarized in Fig. 1.
具体来说,我们不再只用有限个噪声分布去扰动数据,而是考虑一族随时间按扩散过程演化的连续分布。这一过程把数据点逐步扩散成随机噪声,并由一条预先给定、不依赖于数据、也没有可训练参数的 SDE 描述。把这一过程反过来,就可以把随机噪声平滑地塑成数据,从而生成样本。关键在于,这一反向过程满足一条时间反向 SDE(Anderson, 1982),只要知道边际概率密度的分数随时间如何变化,就可以从正向 SDE 把它推导出来。因此,我们可以训练一个随时间变化的神经网络去估计这些分数,从而近似反向 SDE,再用数值 SDE 求解器产生样本。核心想法概括在图 1 中。
Our proposed framework has several theoretical and practical contributions:
我们提出的框架在理论和实践上有以下几方面贡献:
Flexible sampling and likelihood computation: We can employ any general-purpose SDE solver to integrate the reverse-time SDE for sampling. In addition, we propose two special methods not viable for general SDEs: (i) Predictor-Corrector (PC) samplers that combine numerical SDE solvers with score-based MCMC approaches, such as Langevin MCMC (Parisi, 1981) and HMC (Neal et al., 2011); and (ii) deterministic samplers based on the probability flow ordinary differential equation (ODE). The former unifies and improves over existing sampling methods for score-based models. The latter allows for fast adaptive sampling via black-box ODE solvers, flexible data manipulation via latent codes, a uniquely identifiable encoding, and notably, exact likelihood computation.
灵活的采样与似然计算: 我们可以用任何通用 SDE 求解器来积分反向 SDE,从而采样。此外,我们还提出两种一般 SDE 并不具备的方法:(i)预测-校正(PC)采样器,把数值 SDE 求解器与基于分数的 MCMC 方法结合起来,例如 Langevin MCMC(Parisi, 1981)和 HMC(Neal et al., 2011);(ii)基于概率流常微分方程(ODE)的确定性采样器。前者统一并改进了已有的分数模型采样方法。后者则允许借助黑盒 ODE 求解器做快速自适应采样,借助潜编码做灵活的数据操作,还具有唯一可识别的编码,尤其是可以精确计算似然。
Controllable generation: We can modulate the generation process by conditioning on information not available during training, because the conditional reverse-time SDE can be efficiently estimated from unconditional scores. This enables applications such as class-conditional generation, image inpainting, colorization and other inverse problems, all achievable using a single unconditional score-based model without re-training.
可控生成: 生成过程可以按训练时并未提供的信息来调节,因为条件反向 SDE 可以由无条件分数高效地估计出来。这样一来,类别条件生成、图像补全、上色以及其他反问题,都可以用同一个无条件分数模型完成,不必重新训练。
Unified framework: Our framework provides a unified way to explore and tune various SDEs for improving score-based generative models. The methods of SMLD and DDPM can be amalgamated into our framework as discretizations of two separate SDEs. Although DDPM (Ho et al., 2020) was recently reported to achieve higher sample quality than SMLD (Song & Ermon, 2019; Song & Ermon, 2020), we show that with better architectures and new sampling algorithms allowed by our framework, the latter can catch up—it achieves new state-of-the-art Inception score (9.89) and FID score (2.20) on CIFAR-10, as well as high-fidelity generation of images for the first time from a score-based model. In addition, we propose a new SDE under our framework that achieves a likelihood value of 2.99 bits/dim on uniformly dequantized CIFAR-10 images, setting a new record on this task.
统一框架: 这一框架提供了一种统一的方式,去探索和调节各种 SDE,以改进基于分数的生成模型。SMLD 和 DDPM 的方法,可以分别看作两条不同 SDE 的离散化,从而被收进这一框架。尽管 DDPM(Ho et al., 2020)当时被报告为样本质量高于 SMLD(Song & Ermon, 2019; Song & Ermon, 2020),我们表明,借助本框架所允许的更好结构和新的采样算法,后者可以迎头赶上——它在 CIFAR-10 上达到了新的最好 Inception 分数(9.89)和 FID(2.20),并且第一次用分数模型给出了 的高保真样本。此外,我们在该框架下提出一条新的 SDE,在均匀去量化的 CIFAR-10 图像上把似然做到 2.99 bits/dim,刷新了这一任务的纪录。
2 Background
2 背景
2.1 Denoising score matching with Langevin dynamics (SMLD)
2.1 去噪分数匹配与 Langevin 动力学(SMLD)
Let be a perturbation kernel, and , where denotes the data distribution. Consider a sequence of positive noise scales . Typically, is small enough such that , and is large enough such that . Song & Ermon (2019) propose to train a Noise Conditional Score Network (NCSN), denoted by , with a weighted sum of denoising score matching (Vincent, 2011) objectives:
设 为扰动核,并令 ,其中 表示数据分布。考虑一串正的噪声尺度 。通常, 足够小,使得 ,而 足够大,使得 。Song & Ermon (2019) 提出训练一个噪声条件分数网络(NCSN),记为 ,目标是若干去噪分数匹配(Vincent, 2011)目标的加权和:
Given sufficient data and model capacity, the optimal score-based model matches almost everywhere for . For sampling, Song & Ermon (2019) run steps of Langevin MCMC to get a sample for each sequentially:
只要数据和模型容量足够,最优的分数模型 就会在几乎处处与 吻合,其中 。采样时,Song & Ermon (2019) 对每个 依次跑 步 Langevin MCMC:
where is the step size, and is standard normal. The above is repeated for in turn with and when . As and for all , becomes an exact sample from under some regularity conditions.
其中 是步长, 是标准正态。上述步骤按 依次重复,并取 ,当 时令 。在一定正则条件下,当 且对所有 都有 时, 就成为 的精确样本。
2.2 Denoising diffusion probabilistic models (DDPM)
2.2 去噪扩散概率模型(DDPM)
Sohl-Dickstein et al. (2015); Ho et al. (2020) consider a sequence of positive noise scales . For each training data point , a discrete Markov chain is constructed such that , and therefore , where . Similar to SMLD, we can denote the perturbed data distribution as . The noise scales are prescribed such that is approximately distributed according to . A variational Markov chain in the reverse direction is parameterized with , and trained with a re-weighted variant of the evidence lower bound (ELBO):
Sohl-Dickstein et al. (2015); Ho et al. (2020) 考虑一串正的噪声尺度 。对每个训练数据点 ,构造一条离散马尔可夫链 ,使得 ,从而 ,其中 。与 SMLD 类似,扰动后的数据分布可记为 。噪声尺度被规定成使 近似服从 。反向的变分马尔可夫链参数化为 ,并用证据下界(ELBO)的一种重加权变体来训练:
After solving Eq. 3 to get the optimal model , samples can be generated by starting from and following the estimated reverse Markov chain as below
求解式 3 得到最优模型 之后,可以从 出发,按下面的估计反向马尔可夫链生成样本
We call this method ancestral sampling, since it amounts to performing ancestral sampling from the graphical model . The objective Eq. 3 described here is in Ho et al. (2020), written in a form to expose more similarity to Eq. 1. Like Eq. 1, Eq. 3 is also a weighted sum of denoising score matching objectives, which implies that the optimal model, , matches the score of the perturbed data distribution, . Notably, the weights of the -th summand in Eq. 1 and Eq. 3, namely and , are related to corresponding perturbation kernels in the same functional form: and .
我们把这种方法称为祖先采样(ancestral sampling),因为它相当于在图模型 上做祖先采样。这里写出的目标式 3 就是 Ho et al. (2020) 中的 ,只是改写成更便于看出与式 1 相似之处的形式。与式 1 一样,式 3 也是去噪分数匹配目标的加权和,这意味着最优模型 会匹配扰动数据分布的分数 。值得注意的是,式 1 和式 3 中第 项的权重,也就是 和 ,与各自的扰动核有相同的函数关系:,。
3 Score-based generative modeling with SDEs
3 基于 SDE 的分数生成建模
Perturbing data with multiple noise scales is key to the success of previous methods. We propose to generalize this idea further to an infinite number of noise scales, such that perturbed data distributions evolve according to an SDE as the noise intensifies. An overview of our framework is given in Fig. 2.
用多个噪声尺度扰动数据,是先前方法成功的关键。我们把这一想法进一步推广到无穷多个噪声尺度,使受扰动的数据分布随着噪声增强而按一条 SDE 演化。框架概览见图 2。
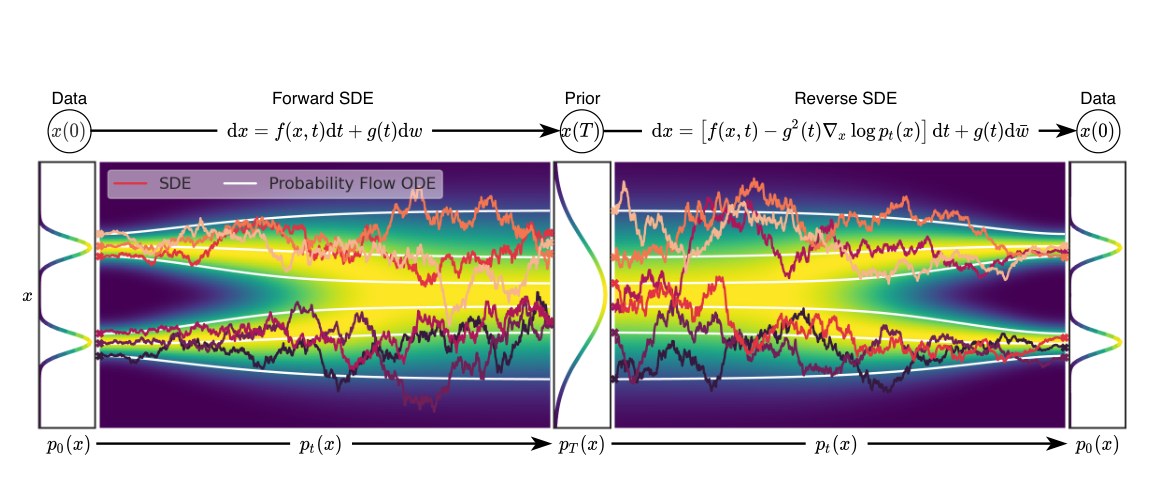
Figure 2: Overview of score-based generative modeling through SDEs. We can map data to a noise distribution (the prior) with an SDE (Section 3.1), and reverse this SDE for generative modeling (Section 3.2). We can also reverse the associated probability flow ODE (Section 4.3), which yields a deterministic process that samples from the same distribution as the SDE. Both the reverse-time SDE and probability flow ODE can be obtained by estimating the score (Section 3.3).
图 2:通过 SDE 进行基于分数的生成建模的概览。我们可以用一条 SDE 把数据映射到噪声分布(先验)(第 3.1 节),再反转这条 SDE 来做生成建模(第 3.2 节)。也可以反转与之相伴的概率流 ODE(第 4.3 节),得到一条与 SDE 采样同一分布的确定性过程。反向 SDE 和概率流 ODE 都可以通过估计分数 得到(第 3.3 节)。
3.1 Perturbing data with SDEs
3.1 用 SDE 扰动数据
Our goal is to construct a diffusion process indexed by a continuous time variable , such that , for which we have a dataset of i.i.d. samples, and , for which we have a tractable form to generate samples efficiently. In other words, is the data distribution and is the prior distribution. This diffusion process can be modeled as the solution to an Itô SDE:
我们的目标是构造一个由连续时间变量 索引的扩散过程 ,使得 (对此我们有一组独立同分布的样本),并且 (对此我们有便于高效采样的解析形式)。换句话说, 是数据分布, 是先验分布。这一扩散过程可以建模为一条 Itô SDE 的解:
where is the standard Wiener process (a.k.a., Brownian motion), is a vector-valued function called the drift coefficient of , and is a scalar function known as the diffusion coefficient of . For ease of presentation we assume the diffusion coefficient is a scalar (instead of a matrix) and does not depend on , but our theory can be generalized to hold in those cases (see Appendix A). The SDE has a unique strong solution as long as the coefficients are globally Lipschitz in both state and time (Øksendal, 2003). We hereafter denote by the probability density of , and use to denote the transition kernel from to , where .
其中 是标准 Wiener 过程(也就是布朗运动), 是一个向量值函数,称为 的漂移系数, 是一个标量函数,称为 的扩散系数。为便于叙述,我们假定扩散系数是标量(而不是 矩阵),并且不依赖于 ,但理论可以推广到那些更一般的情形(见附录 A)。只要系数在状态和时间上都是全局 Lipschitz 的,这条 SDE 就有唯一的强解(Øksendal, 2003)。下文用 表示 的概率密度,并用 表示从 到 的转移核,其中 。
Typically, is an unstructured prior distribution that contains no information of , such as a Gaussian distribution with fixed mean and variance. There are various ways of designing the SDE in Eq. 5 such that it diffuses the data distribution into a fixed prior distribution. We provide several examples later in Section 3.4 that are derived from continuous generalizations of SMLD and DDPM.
通常, 是一个不带 任何信息的无结构先验,例如均值和方差都固定的高斯分布。设计式 5 中的 SDE、使它把数据分布扩散成固定先验的办法有很多。我们稍后在第 3.4 节给出若干例子,它们来自 SMLD 和 DDPM 的连续推广。
3.2 Generating samples by reversing the SDE
3.2 反转 SDE 以生成样本
By starting from samples of and reversing the process, we can obtain samples . A remarkable result from Anderson (1982) states that the reverse of a diffusion process is also a diffusion process, running backwards in time and given by the reverse-time SDE:
从 的样本出发并把过程反转,就可以得到样本 。Anderson (1982) 的一个出色结果表明:一个扩散过程的反向同样是扩散过程,只是时间倒着走,并由下面的时间反向 SDE 给出:
where is a standard Wiener process when time flows backwards from to , and is an infinitesimal negative timestep. Once the score of each marginal distribution, , is known for all , we can derive the reverse diffusion process from Eq. 6 and simulate it to sample from .
其中 是时间从 流向 时的标准 Wiener 过程, 是无穷小的负时间步。一旦对所有 都知道每个边际分布的分数 ,就可以从式 6 写出反向扩散过程,并模拟它来从 中采样。
3.3 Estimating scores for the SDE
3.3 估计 SDE 所需的分数
The score of a distribution can be estimated by training a score-based model on samples with score matching (Hyvärinen, 2005; Song et al., 2019a). To estimate , we can train a time-dependent score-based model via a continuous generalization to Eqs. 1 and 3:
分布的分数可以通过分数匹配,在样本上训练一个分数模型来估计(Hyvärinen, 2005; Song et al., 2019a)。要估计 ,我们可以把式 1 和式 3 推广到连续时间,训练一个随时间变化的分数模型 :
Here is a positive weighting function, is uniformly sampled over , and . With sufficient data and model capacity, score matching ensures that the optimal solution to Eq. 7, denoted by , equals for almost all and . As in SMLD and DDPM, we can typically choose . Note that Eq. 7 uses denoising score matching, but other score matching objectives, such as sliced score matching (Song et al., 2019a) and finite-difference score matching (Pang et al., 2020) are also applicable here.
这里 是一个正的加权函数, 在 上均匀抽取,,。只要数据和模型容量足够,分数匹配可以保证式 7 的最优解 对几乎所有 和 都等于 。与 SMLD 和 DDPM 中一样,我们通常可以取 。注意,式 7 用的是去噪分数匹配,但其他分数匹配目标,例如切片分数匹配(Song et al., 2019a)和有限差分分数匹配(Pang et al., 2020),在这里同样适用。
We typically need to know the transition kernel to efficiently solve Eq. 7. When is affine, the transition kernel is always a Gaussian distribution, where the mean and variance are often known in closed-forms and can be obtained with standard techniques (see Section 5.5 in Särkkä & Solin (2019)). For more general SDEs, we may solve Kolmogorov’s forward equation (Øksendal, 2003) to obtain . Alternatively, we can simulate the SDE to sample from and replace denoising score matching in Eq. 7 with sliced score matching for model training, which bypasses the computation of (see Appendix A).
为了高效求解式 7,我们通常需要知道转移核 。当 是仿射的时候,转移核一定是高斯分布,其均值和方差往往有闭式,可用标准方法求得(见 Särkkä & Solin (2019) 第 5.5 节)。对更一般的 SDE,可以通过求解 Kolmogorov 正向方程(Øksendal, 2003)来得到 。另一种办法是模拟这条 SDE 来从 中采样,并把式 7 中的去噪分数匹配换成切片分数匹配来训练模型,从而绕开 的计算(见附录 A)。
3.4 Examples: VE, VP SDEs and beyond
3.4 例子:VE、VP SDE 及其他
The noise perturbations used in SMLD and DDPM can be regarded as discretizations of two different SDEs. Below we provide a brief discussion and relegate more details to Appendix B.
SMLD 和 DDPM 所用的噪声扰动,可以看作两条不同 SDE 的离散化。下面做一简要讨论,更多细节放到附录 B。
When using a total of noise scales, each perturbation kernel of SMLD corresponds to the distribution of in the following Markov chain:
当一共使用 个噪声尺度时,SMLD 的每个扰动核 都对应于下面这条马尔可夫链中 的分布:
where , and we have introduced to simplify the notation. In the limit of , becomes a function , becomes , and the Markov chain becomes a continuous stochastic process , where we have used a continuous time variable for indexing, rather than an integer . The process is given by the following SDE
其中 ,并为简化记号引入了 。在 的极限下, 变成函数 , 变成 ,马尔可夫链 变成连续随机过程 。这里我们改用连续时间变量 来做索引,而不再用整数 。过程 由下面的 SDE 给出
Likewise for the perturbation kernels of DDPM, the discrete Markov chain is
对 DDPM 的扰动核 ,相应的离散马尔可夫链是
As , Eq. 10 converges to the following SDE,
当 时,式 10 收敛到下面的 SDE,
Therefore, the noise perturbations used in SMLD and DDPM correspond to discretizations of SDEs Eqs. 9 and 11. Interestingly, the SDE of Eq. 9 always gives a process with exploding variance when , whilst the SDE of Eq. 11 yields a process with a fixed variance of one when the initial distribution has unit variance (proof in Appendix B). Due to this difference, we hereafter refer to Eq. 9 as the Variance Exploding (VE) SDE, and Eq. 11 the Variance Preserving (VP) SDE.
因此,SMLD 和 DDPM 所用的噪声扰动,分别对应于式 9 和式 11 这两条 SDE 的离散化。有意思的是,式 9 的 SDE 在 时总会给出方差趋于无穷的过程;而如果初始分布具有单位方差,式 11 的 SDE 会给出方差固定为 1 的过程(证明见附录 B)。由于这一差别,我们此后把式 9 称为方差爆炸(VE)SDE,把式 11 称为方差保持(VP)SDE。
Inspired by the VP SDE, we propose a new type of SDEs which perform particularly well on likelihoods (see Section 4.3), given by
受 VP SDE 启发,我们提出一类在似然上表现特别好的新 SDE(见第 4.3 节),形式为
When using the same and starting from the same initial distribution, the variance of the stochastic process induced by Eq. 12 is always bounded by the VP SDE at every intermediate time step (proof in Appendix B). For this reason, we name Eq. 12 the sub-VP SDE.
当使用相同的 、并从相同的初始分布出发时,式 12 所诱导的随机过程,其方差在每一个中间时刻都不会超过 VP SDE(证明见附录 B)。因此,我们把式 12 称为 sub-VP SDE。
Since VE, VP and sub-VP SDEs all have affine drift coefficients, their perturbation kernels are all Gaussian and can be computed in closed-forms, as discussed in Section 3.3. This makes training with Eq. 7 particularly efficient.
由于 VE、VP 和 sub-VP SDE 的漂移系数都是仿射的,它们的扰动核 都是高斯的,并且可以写成闭式,正如第 3.3 节所讨论的。这使得用式 7 训练变得特别高效。
4 Solving the reverse SDE
4 求解反向 SDE
After training a time-dependent score-based model , we can use it to construct the reverse-time SDE and then simulate it with numerical approaches to generate samples from .
训练好随时间变化的分数模型 之后,我们就可以用它来构造时间反向 SDE,再借助数值方法模拟这条方程,从而从 中生成样本。
4.1 General-purpose numerical SDE solvers
4.1 通用数值 SDE 求解器
Numerical solvers provide approximate trajectories from SDEs. Many general-purpose numerical methods exist for solving SDEs, such as Euler-Maruyama and stochastic Runge-Kutta methods (Kloeden & Platen, 2013), which correspond to different discretizations of the stochastic dynamics. We can apply any of them to the reverse-time SDE for sample generation.
数值求解器给出的是 SDE 的近似轨迹。求解 SDE 的通用数值方法有很多,例如欧拉–丸山方法和随机 Runge-Kutta 方法(Kloeden & Platen, 2013),它们对应于随机动力学的不同离散化。我们可以把其中任何一种用到时间反向 SDE 上,用来生成样本。
Ancestral sampling, the sampling method of DDPM (Eq. 4), actually corresponds to one special discretization of the reverse-time VP SDE (Eq. 11) (see Appendix E). Deriving the ancestral sampling rules for new SDEs, however, can be non-trivial. To remedy this, we propose reverse diffusion samplers (details in Appendix E), which discretize the reverse-time SDE in the same way as the forward one, and thus can be readily derived given the forward discretization. As shown in Table 1, reverse diffusion samplers perform slightly better than ancestral sampling for both SMLD and DDPM models on CIFAR-10 (DDPM-type ancestral sampling is also applicable to SMLD models, see Appendix F.)
DDPM 的采样方法,也就是祖先采样(式 4),其实对应于时间反向 VP SDE(式 11)的一种特殊离散化(见附录 E)。不过,为新的 SDE 推导祖先采样规则往往并不轻松。为此,我们提出反向扩散采样器(细节见附录 E):它按与正向过程相同的方式离散化反向 SDE,因而只要有正向离散化,就可以直接写出来。如表 1 所示,在 CIFAR-10 上,无论是 SMLD 还是 DDPM 模型,反向扩散采样器都略好于祖先采样(DDPM 式的祖先采样也可以用在 SMLD 模型上,见附录 F)。
4.2 Predictor-corrector samplers
4.2 预测-校正采样器
Unlike generic SDEs, we have additional information that can be used to improve solutions. Since we have a score-based model , we can employ score-based MCMC approaches, such as Langevin MCMC (Parisi, 1981; Grenander & Miller, 1994) or HMC (Neal et al., 2011) to sample from directly, and correct the solution of a numerical SDE solver.
与一般的 SDE 不同,这里还有额外信息可以用来改进解。既然我们有分数模型 ,就可以用基于分数的 MCMC 方法,例如 Langevin MCMC(Parisi, 1981; Grenander & Miller, 1994)或 HMC(Neal et al., 2011),直接从 中采样,并校正数值 SDE 求解器给出的解。
Specifically, at each time step, the numerical SDE solver first gives an estimate of the sample at the next time step, playing the role of a “predictor”. Then, the score-based MCMC approach corrects the marginal distribution of the estimated sample, playing the role of a “corrector”. The idea is analogous to Predictor-Corrector methods, a family of numerical continuation techniques for solving systems of equations (Allgower & Georg, 2012), and we similarly name our hybrid sampling algorithms Predictor-Corrector (PC) samplers. Please find pseudo-code and a complete description in Appendix G. PC samplers generalize the original sampling methods of SMLD and DDPM: the former uses an identity function as the predictor and annealed Langevin dynamics as the corrector, while the latter uses ancestral sampling as the predictor and identity as the corrector.
具体来说,在每一个时间步,数值 SDE 求解器先给出下一步样本的一个估计,扮演“预测器”的角色;然后,基于分数的 MCMC 方法再校正这个估计样本的边际分布,扮演“校正器”的角色。这一想法类似于预测-校正方法,也就是求解方程组时一类数值延拓技术(Allgower & Georg, 2012),我们因而把这种混合采样算法同样称为预测-校正(PC)采样器。伪代码和完整说明见附录 G。PC 采样器概括了 SMLD 和 DDPM 原有的采样方法:前者把预测器取成恒等映射,把退火 Langevin 动力学当作校正器;后者则把祖先采样当作预测器,把校正器取成恒等映射。
Table 1: Comparing different reverse-time SDE solvers on CIFAR-10. Shaded regions are obtained with the same computation (number of score function evaluations). Mean and standard deviation are reported over five sampling runs. “P1000” or “P2000”: predictor-only samplers using 1000 or 2000 steps. “C2000”: corrector-only samplers using 2000 steps. “PC1000”: Predictor-Corrector (PC) samplers using 1000 predictor and 1000 corrector steps.
| FID \ Sampler / Predictor | P1000 (VE / SMLD) | P2000 (VE) | C2000 (VE) | PC1000 (VE) | P1000 (VP / DDPM) | P2000 (VP) | C2000 (VP) | PC1000 (VP) |
|---|---|---|---|---|---|---|---|---|
| ancestral sampling | ||||||||
| reverse diffusion | ||||||||
| probability flow |
(Two super-columns: Variance Exploding SDE (SMLD) and Variance Preserving SDE (DDPM). Shaded in the original table: the P2000 and PC1000 columns, which use the same number of score function evaluations.)
表 1: 在 CIFAR-10 上比较不同的时间反向 SDE 求解器。阴影区域对应相同的计算量(分数函数求值次数)。均值和标准差按五次采样运行报告。“P1000”或“P2000”:只用预测器、走 1000 或 2000 步的采样器。“C2000”:只用校正器、走 2000 步的采样器。“PC1000”:预测-校正(PC)采样器,使用 1000 步预测和 1000 步校正。
| FID \ 采样器 / 预测器 | P1000(VE / SMLD) | P2000(VE) | C2000(VE) | PC1000(VE) | P1000(VP / DDPM) | P2000(VP) | C2000(VP) | PC1000(VP) |
|---|---|---|---|---|---|---|---|---|
| 祖先采样 | ||||||||
| 反向扩散 | ||||||||
| 概率流 |
(表分两大栏:方差爆炸 SDE(SMLD)与方差保持 SDE(DDPM)。原表中 P2000 与 PC1000 两列为阴影,对应相同的分数函数求值次数。)
We test PC samplers on SMLD and DDPM models (see Algorithms 2 and 3 in Appendix G) trained with original discrete objectives given by Eqs. 1 and 3. This exhibits the compatibility of PC samplers to score-based models trained with a fixed number of noise scales. We summarize the performance of different samplers in Table 1, where probability flow is a predictor to be discussed in Section 4.3. Detailed experimental settings and additional results are given in Appendix G. We observe that our reverse diffusion sampler always outperform ancestral sampling, and corrector-only methods (C2000) perform worse than other competitors (P2000, PC1000) with the same computation (In fact, we need way more corrector steps per noise scale, and thus more computation, to match the performance of other samplers.) For all predictors, adding one corrector step for each predictor step (PC1000) doubles computation but always improves sample quality (against P1000). Moreover, it is typically better than doubling the number of predictor steps without adding a corrector (P2000), where we have to interpolate between noise scales in an ad hoc manner (detailed in Appendix G) for SMLD/DDPM models. In Fig. 9 (Appendix G), we additionally provide qualitative comparison for models trained with the continuous objective Eq. 7 on LSUN images and the VE SDE, where PC samplers clearly surpass predictor-only samplers under comparable computation, when using a proper number of corrector steps.
我们在用式 1 和式 3 的原有离散目标训练的 SMLD 与 DDPM 模型上测试了 PC 采样器(见附录 G 中的算法 2 和算法 3)。这显示出,PC 采样器也可以用在按固定数目噪声尺度训练的分数模型上。表 1 汇总了不同采样器的表现,其中概率流是将在第 4.3 节讨论的一种预测器。详细实验设置和更多结果见附录 G。我们观察到,反向扩散采样器始终优于祖先采样;在相同计算量下,只使用校正器的方法(C2000)不如其他竞争者(P2000、PC1000)。(实际上,要追上其他采样器的表现,每个噪声尺度需要多得多的校正步,因而也需要多得多的计算。)对所有预测器而言,每一步预测再加一步校正(PC1000)会使计算量加倍,但样本质量总是好于只用预测器的 P1000。而且,它通常也优于在不加校正器的情况下把预测步数加倍(P2000)——对 SMLD/DDPM 模型,后者还不得不在噪声尺度之间做一种临时的插值(细节见附录 G)。在图 9(附录 G)中,我们还对用连续目标式 7 训练、并采用 VE SDE 的 LSUN 图像模型做了定性比较:只要校正步数选得合适,在相当的计算量下,PC 采样器明显超过只用预测器的采样器。
4.3 Probability flow and connection to neural ODEs
4.3 概率流及其与神经 ODE 的联系
Score-based models enable another numerical method for solving the reverse-time SDE. For all diffusion processes, there exists a corresponding deterministic process whose trajectories share the same marginal probability densities as the SDE. This deterministic process satisfies an ODE (more details in Section D.1):
分数模型还使另一种求解时间反向 SDE 的数值方法成为可能。对所有扩散过程,都存在一条对应的确定性过程,其轨迹与这条 SDE 共享同一族边际概率密度 。这条确定性过程满足下面的 ODE(更多细节见第 D.1 节):
which can be determined from the SDE once scores are known. We name the ODE in Eq. 13 the probability flow ODE. When the score function is approximated by the time-dependent score-based model, which is typically a neural network, this is an example of a neural ODE (Chen et al., 2018).
一旦知道分数,就可以从 SDE 确定这条 ODE。我们把式 13 中的 ODE 称为概率流 ODE。当分数函数由随时间变化的分数模型来近似、而该模型通常是神经网络时,这就是神经 ODE 的一个例子(Chen et al., 2018)。
Exact likelihood computation Leveraging the connection to neural ODEs, we can compute the density defined by Eq. 13 via the instantaneous change of variables formula (Chen et al., 2018). This allows us to compute the exact likelihood on any input data (details in Section D.2). As an example, we report negative log-likelihoods (NLLs) measured in bits/dim on the CIFAR-10 dataset in Table 2. We compute log-likelihoods on uniformly dequantized data, and only compare to models evaluated in the same way (omitting models evaluated with variational dequantization (Ho et al., 2019) or discrete data), except for DDPM (/) whose ELBO values (annotated with *) are reported on discrete data. Main results: (i) For the same DDPM model in Ho et al. (2020), we obtain better bits/dim than ELBO, since our likelihoods are exact; (ii) Using the same architecture, we trained another DDPM model with the continuous objective in Eq. 7 (i.e., DDPM cont.), which further improves the likelihood; (iii) With sub-VP SDEs, we always get higher likelihoods compared to VP SDEs; (iv) With improved architecture (i.e., DDPM++ cont., details in Section 4.4) and the sub-VP SDE, we can set a new record bits/dim of 2.99 on uniformly dequantized CIFAR-10 even without maximum likelihood training.
精确的似然计算: 借助与神经 ODE 的联系,我们可以通过瞬时变量变换公式(Chen et al., 2018)来计算式 13 所定义的密度。这使得我们可以对任意输入数据计算精确似然(细节见第 D.2 节)。作为例子,表 2 报告了 CIFAR-10 上以 bits/dim 计的负对数似然(NLL)。我们在均匀去量化的数据上计算对数似然,并且只与按同样方式评测的模型比较(略去用变分去量化(Ho et al., 2019)或离散数据评测的模型),唯一的例外是 DDPM(/),其 ELBO 值(标有 )是在离散数据上报告的。主要结果是:(i)对 Ho et al. (2020) 中同一个 DDPM 模型,我们得到的 bits/dim 好于 ELBO,因为我们的似然是精确的;(ii)用同一结构、但按式 7 的连续目标另训了一个 DDPM 模型(即 DDPM cont.),似然进一步提升;(iii)采用 sub-VP SDE 时,似然总是高于 VP SDE;(iv)结合改进后的结构(即 DDPM++ cont.,细节见第 4.4 节)和 sub-VP SDE,即使不做最大似然训练*,也能在均匀去量化的 CIFAR-10 上把 bits/dim 刷新到 2.99。
Table 2: NLLs and FIDs (ODE) on CIFAR-10.
| Model | NLL Test | FID |
|---|---|---|
| RealNVP (Dinh et al., 2016) | 3.49 | — |
| iResNet (Behrmann et al., 2019) | 3.45 | — |
| Glow (Kingma & Dhariwal, 2018) | 3.35 | — |
| MintNet (Song et al., 2019b) | 3.32 | — |
| Residual Flow (Chen et al., 2019) | 3.28 | 46.37 |
| FFJORD (Grathwohl et al., 2018) | 3.40 | — |
| Flow++ (Ho et al., 2019) | 3.29 | — |
| DDPM () (Ho et al., 2020) | 13.51 | |
| DDPM () (Ho et al., 2020) | 3.17 | |
| DDPM | 3.28 | 3.37 |
| DDPM cont. (VP) | 3.21 | 3.69 |
| DDPM cont. (sub-VP) | 3.05 | 3.56 |
| DDPM++ cont. (VP) | 3.16 | 3.93 |
| DDPM++ cont. (sub-VP) | 3.02 | 3.16 |
| DDPM++ cont. (deep, VP) | 3.13 | 3.08 |
| DDPM++ cont. (deep, sub-VP) |
Table 3: CIFAR-10 sample quality.
| Model | FID | IS |
|---|---|---|
| Conditional | ||
| BigGAN (Brock et al., 2018) | 14.73 | 9.22 |
| StyleGAN2-ADA (Karras et al., 2020a) | ||
| Unconditional | ||
| StyleGAN2-ADA (Karras et al., 2020a) | 2.92 | 9.83 |
| NCSN (Song & Ermon, 2019) | 25.32 | |
| NCSNv2 (Song & Ermon, 2020) | 10.87 | |
| DDPM (Ho et al., 2020) | 3.17 | |
| DDPM++ | 2.78 | 9.64 |
| DDPM++ cont. (VP) | 2.55 | 9.58 |
| DDPM++ cont. (sub-VP) | 2.61 | 9.56 |
| DDPM++ cont. (deep, VP) | 2.41 | 9.68 |
| DDPM++ cont. (deep, sub-VP) | 2.41 | 9.57 |
| NCSN++ | 2.45 | 9.73 |
| NCSN++ cont. (VE) | 2.38 | 9.83 |
| NCSN++ cont. (deep, VE) |
表 2: CIFAR-10 上的负对数似然(NLL)与 FID(由 ODE 得到)。
| 模型 | NLL Test | FID |
|---|---|---|
| RealNVP (Dinh et al., 2016) | 3.49 | — |
| iResNet (Behrmann et al., 2019) | 3.45 | — |
| Glow (Kingma & Dhariwal, 2018) | 3.35 | — |
| MintNet (Song et al., 2019b) | 3.32 | — |
| Residual Flow (Chen et al., 2019) | 3.28 | 46.37 |
| FFJORD (Grathwohl et al., 2018) | 3.40 | — |
| Flow++ (Ho et al., 2019) | 3.29 | — |
| DDPM () (Ho et al., 2020) | 13.51 | |
| DDPM () (Ho et al., 2020) | 3.17 | |
| DDPM | 3.28 | 3.37 |
| DDPM cont. (VP) | 3.21 | 3.69 |
| DDPM cont. (sub-VP) | 3.05 | 3.56 |
| DDPM++ cont. (VP) | 3.16 | 3.93 |
| DDPM++ cont. (sub-VP) | 3.02 | 3.16 |
| DDPM++ cont. (deep, VP) | 3.13 | 3.08 |
| DDPM++ cont. (deep, sub-VP) |
表 3: CIFAR-10 的样本质量。
| 模型 | FID | IS |
|---|---|---|
| 有条件 | ||
| BigGAN (Brock et al., 2018) | 14.73 | 9.22 |
| StyleGAN2-ADA (Karras et al., 2020a) | ||
| 无条件 | ||
| StyleGAN2-ADA (Karras et al., 2020a) | 2.92 | 9.83 |
| NCSN (Song & Ermon, 2019) | 25.32 | |
| NCSNv2 (Song & Ermon, 2020) | 10.87 | |
| DDPM (Ho et al., 2020) | 3.17 | |
| DDPM++ | 2.78 | 9.64 |
| DDPM++ cont. (VP) | 2.55 | 9.58 |
| DDPM++ cont. (sub-VP) | 2.61 | 9.56 |
| DDPM++ cont. (deep, VP) | 2.41 | 9.68 |
| DDPM++ cont. (deep, sub-VP) | 2.41 | 9.57 |
| NCSN++ | 2.45 | 9.73 |
| NCSN++ cont. (VE) | 2.38 | 9.83 |
| NCSN++ cont. (deep, VE) |
Manipulating latent representations By integrating Eq. 13, we can encode any datapoint into a latent space . Decoding can be achieved by integrating a corresponding ODE for the reverse-time SDE. As is done with other invertible models such as neural ODEs and normalizing flows (Dinh et al., 2016; Kingma & Dhariwal, 2018), we can manipulate this latent representation for image editing, such as interpolation, and temperature scaling (see Fig. 3 and Section D.4).
操作潜表示: 积分式 13,就可以把任意数据点 编码到潜空间 。解码则通过对时间反向 SDE 所对应的 ODE 做积分来完成。与神经 ODE、归一化流(Dinh et al., 2016; Kingma & Dhariwal, 2018)等其他可逆模型一样,我们可以操作这一潜表示来做图像编辑,例如插值和温度缩放(见图 3 和第 D.4 节)。
Uniquely identifiable encoding Unlike most current invertible models, our encoding is uniquely identifiable, meaning that with sufficient training data, model capacity, and optimization accuracy, the encoding for an input is uniquely determined by the data distribution (Roeder et al., 2020). This is because our forward SDE, Eq. 5, has no trainable parameters, and its associated probability flow ODE, Eq. 13, provides the same trajectories given perfectly estimated scores. We provide additional empirical verification on this property in Section D.5.
唯一可识别的编码: 与目前大多数可逆模型不同,我们的编码是唯一可识别的,意思是:只要训练数据、模型容量和优化精度都足够,一个输入的编码就由数据分布唯一决定(Roeder et al., 2020)。这是因为我们的正向 SDE(式 5)没有可训练参数,而与之相伴的概率流 ODE(式 13)在分数被完美估计时给出相同的轨迹。我们在第 D.5 节对这一性质做了更多实证核验。
Efficient sampling As with neural ODEs, we can sample by solving Eq. 13 from different final conditions . Using a fixed discretization strategy we can generate competitive samples, especially when used in conjuction with correctors (Table 1, “probability flow sampler”, details in Section D.3). Using a black-box ODE solver (Dormand & Prince, 1980) not only produces high quality samples (Table 2, details in Section D.4), but also allows us to explicitly trade-off accuracy for efficiency. With a larger error tolerance, the number of function evaluations can be reduced by over without affecting the visual quality of samples (Fig. 3).
高效采样: 与神经 ODE 一样,我们可以从不同的终端条件 出发求解式 13,从而采样 。若采用固定的离散化策略,就可以生成有竞争力的样本,尤其是再与校正器合用时(表 1,“概率流采样器”,细节见第 D.3 节)。若改用黑盒 ODE 求解器(Dormand & Prince, 1980),则不但能产生高质量样本(表 2,细节见第 D.4 节),还可以在精度和效率之间做显式权衡。把误差容限放得更大时,函数求值次数可以减少 90% 以上,而不影响样本的视觉质量(图 3)。
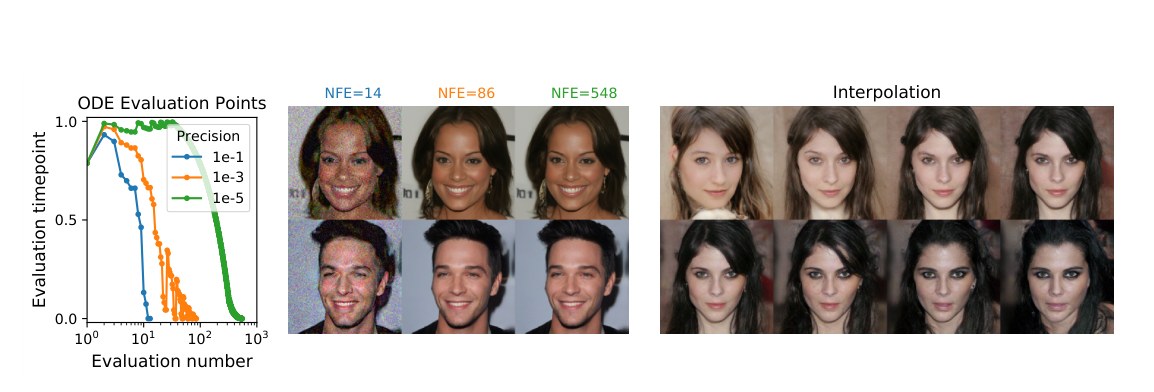
Figure 3: Probability flow ODE enables fast sampling with adaptive stepsizes as the numerical precision is varied (left), and reduces the number of score function evaluations (NFE) without harming quality (middle). The invertible mapping from latents to images allows for interpolations (right).
图 3:概率流 ODE 使快速采样成为可能:随着数值精度变化采用自适应步长(左),并在不损害质量的前提下减少分数函数求值次数(NFE)(中)。从潜变量到图像的可逆映射还允许做插值(右)。
4.4 Architecture improvements
4.4 结构上的改进
We explore several new architecture designs for score-based models using both VE and VP SDEs (details in Appendix H), where we train models with the same discrete objectives as in SMLD/DDPM. We directly transfer the architectures for VP SDEs to sub-VP SDEs due to their similarity. Our optimal architecture for the VE SDE, named NCSN++, achieves an FID of 2.45 on CIFAR-10 with PC samplers, while our optimal architecture for the VP SDE, called DDPM++, achieves 2.78.
我们为同时使用 VE 和 VP SDE 的分数模型探索了若干新的结构设计(细节见附录 H),训练时采用与 SMLD/DDPM 相同的离散目标。由于 VP 与 sub-VP SDE 很相近,我们把 VP SDE 上的结构直接迁移到 sub-VP SDE。VE SDE 上的最优结构称为 NCSN++,用 PC 采样器在 CIFAR-10 上做到 FID 2.45;VP SDE 上的最优结构称为 DDPM++,FID 为 2.78。
By switching to the continuous training objective in Eq. 7, and increasing the network depth, we can further improve sample quality for all models. The resulting architectures are denoted as NCSN++ cont. and DDPM++ cont. in Table 3 for VE and VP/sub-VP SDEs respectively. Results reported in Table 3 are for the checkpoint with the smallest FID over the course of training, where samples are generated with PC samplers. In contrast, FID scores and NLL values in Table 2 are reported for the last training checkpoint, and samples are obtained with black-box ODE solvers. As shown in Table 3, VE SDEs typically provide better sample quality than VP/sub-VP SDEs, but we also empirically observe that their likelihoods are worse than VP/sub-VP SDE counterparts. This indicates that practitioners likely need to experiment with different SDEs for varying domains and architectures.
改用式 7 的连续训练目标,并加深网络,还可以进一步提高所有模型的样本质量。得到的结构在表 3 中分别记为 NCSN++ cont. 和 DDPM++ cont.,对应 VE 与 VP/sub-VP SDE。表 3 报告的是训练过程中 FID 最小的检查点,样本由 PC 采样器生成。相比之下,表 2 中的 FID 和 NLL 针对的是最后一个训练检查点,样本由黑盒 ODE 求解器得到。如表 3 所示,VE SDE 的样本质量通常好于 VP/sub-VP SDE,但我们同时也观察到,它们的似然不如对应的 VP/sub-VP SDE。这说明,面对不同的领域和结构,实践中可能需要尝试不同的 SDE。
Our best model for sample quality, NCSN++ cont. (deep, VE), doubles the network depth and sets new records for both inception score and FID on unconditional generation for CIFAR-10. Surprisingly, we can achieve better FID than the previous best conditional generative model without requiring labeled data. With all improvements together, we also obtain the first set of high-fidelity samples on CelebA-HQ from score-based models (see Section H.3). Our best model for likelihoods, DDPM++ cont. (deep, sub-VP), similarly doubles the network depth and achieves a log-likelihood of 2.99 bits/dim with the continuous objective in Eq. 7. To our best knowledge, this is the highest likelihood on uniformly dequantized CIFAR-10.
样本质量最好的模型 NCSN++ cont.(deep, VE)把网络深度加倍,并在 CIFAR-10 无条件生成上同时刷新了 Inception 分数和 FID。出人意料的是,我们不必使用带标签的数据,FID 就超过了此前最好的有条件生成模型。把全部改进合在一起,我们还第一次用分数模型在 CelebA-HQ 上得到了高保真样本(见第 H.3 节)。似然最好的模型 DDPM++ cont.(deep, sub-VP)同样把网络深度加倍,并用式 7 的连续目标把对数似然做到 2.99 bits/dim。据我们所知,这是均匀去量化 CIFAR-10 上当时最高的似然。
5 Controllable generation
5 可控生成
The continuous structure of our framework allows us to not only produce data samples from , but also from if is known. Given a forward SDE as in Eq. 5, we can sample from by starting from and solving a conditional reverse-time SDE:
框架的连续结构不仅允许我们从 中产生数据样本,而且在 已知时,还可以从 中采样。给定式 5 那样的正向 SDE,我们可以从 出发,求解下面的条件时间反向 SDE,从而从 中采样:
In general, we can use Eq. 14 to solve a large family of inverse problems with score-based generative models, once given an estimate of the gradient of the forward process, . In some cases, it is possible to train a separate model to learn the forward process and compute its gradient. Otherwise, we may estimate the gradient with heuristics and domain knowledge. In Section I.4, we provide a broadly applicable method for obtaining such an estimate without the need of training auxiliary models.
一般而言,只要有了正向过程梯度 的估计,就可以用式 14、借助分数生成模型求解一大类反问题。有些情况下,可以另训一个模型来学习正向过程 并计算其梯度;否则,也可以借助启发式方法和领域知识来估计这一梯度。在第 I.4 节,我们给出一种适用范围较广的估计办法,不必训练辅助模型。
We consider three applications of controllable generation with this approach: class-conditional generation, image imputation and colorization. When represents class labels, we can train a time-dependent classifier for class-conditional sampling. Since the forward SDE is tractable, we can easily create training data for the time-dependent classifier by first sampling from a dataset, and then sampling . Afterwards, we may employ a mixture of cross-entropy losses over different time steps, like Eq. 7, to train the time-dependent classifier . We provide class-conditional CIFAR-10 samples in Fig. 4 (left), and relegate more details and results to Appendix I.
我们考虑这一做法在可控生成上的三种应用:类别条件生成、图像补全和上色。当 表示类别标签时,可以训练一个随时间变化的分类器 来做类别条件采样。由于正向 SDE 是可计算的,我们可以先从数据集中抽取 ,再采样 ,从而轻易得到该分类器的训练数据 。随后,可以像式 7 那样,把不同时间步上的交叉熵损失混合起来,训练 。图 4(左)给出了 CIFAR-10 上的类别条件样本,更多细节和结果放到附录 I。
Imputation is a special case of conditional sampling. Suppose we have an incomplete data point where only some subset, is known. Imputation amounts to sampling from , which we can accomplish using an unconditional model (see Section I.2). Colorization is a special case of imputation, except that the known data dimensions are coupled. We can decouple these data dimensions with an orthogonal linear transformation, and perform imputation in the transformed space (details in Section I.3). Fig. 4 (right) shows results for inpainting and colorization achieved with unconditional time-dependent score-based models.
补全是条件采样的一种特殊情形。假设我们有一个不完整的数据点 ,其中只有某个子集 是已知的。补全相当于从 中采样,而这可以用一个无条件模型来完成(见第 I.2 节)。上色也是补全的特殊情形,只是已知的数据维是耦合的。我们可以用一个正交线性变换把这些维解开,再在变换后的空间里做补全(细节见第 I.3 节)。图 4(右)展示了用无条件、随时间变化的分数模型得到的补全和上色结果。
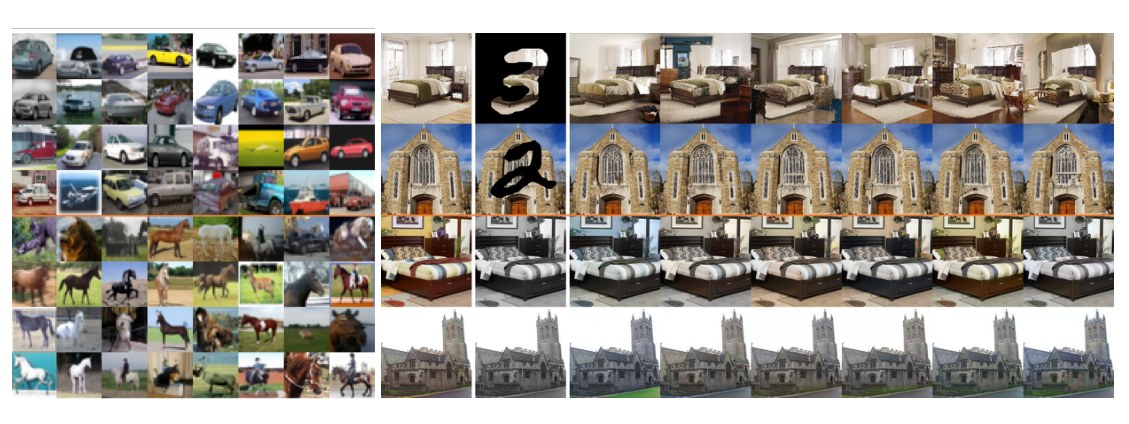
Figure 4: Left: Class-conditional samples on CIFAR-10. Top four rows are automobiles and bottom four rows are horses. Right: Inpainting (top two rows) and colorization (bottom two rows) results on LSUN. First column is the original image, second column is the masked/gray-scale image, remaining columns are sampled image completions or colorizations.
图 4:左: CIFAR-10 上的类别条件样本。上面四行是汽车,下面四行是马。右: LSUN 上的补全(上两行)和上色(下两行)结果。第一列是原图,第二列是被遮挡或灰度化的图像,其余各列是采样得到的补全或上色。
6 Conclusion
6 结论
We presented a framework for score-based generative modeling based on SDEs. Our work enables a better understanding of existing approaches, new sampling algorithms, exact likelihood computation, uniquely identifiable encoding, latent code manipulation, and brings new conditional generation abilities to the family of score-based generative models.
我们提出了一个基于 SDE 的分数生成建模框架。这项工作有助于更好地理解已有方法,带来了新的采样算法、精确的似然计算、唯一可识别的编码以及潜编码操作,并为基于分数的生成模型这一家族增添了新的条件生成能力。
While our proposed sampling approaches improve results and enable more efficient sampling, they remain slower at sampling than GANs (Goodfellow et al., 2014) on the same datasets. Identifying ways of combining the stable learning of score-based generative models with the fast sampling of implicit models like GANs remains an important research direction. Additionally, the breadth of samplers one can use when given access to score functions introduces a number of hyper-parameters. Future work would benefit from improved methods to automatically select and tune these hyper-parameters, as well as more extensive investigation on the merits and limitations of various samplers.
尽管我们提出的采样方法改进了结果、也使采样更加高效,但在同一批数据上,它们的采样速度仍然慢于 GAN(Goodfellow et al., 2014)。如何把分数生成模型的稳定训练与 GAN 这类隐式模型的快速采样结合起来,仍然是一个重要的研究方向。此外,一旦有了分数函数,可以使用的采样器种类很多,也会引入一批超参数。未来的工作若能改进自动选择和调节这些超参数的方法,并更系统地考察各种采样器的长处与局限,将会很有帮助。
Acknowledgements
We would like to thank Nanxin Chen, Ruiqi Gao, Jonathan Ho, Kevin Murphy, Tim Salimans and Han Zhang for their insightful discussions during the course of this project. This research was partially supported by NSF (#1651565, #1522054, #1733686), ONR (N000141912145), AFOSR (FA95501910024), and TensorFlow Research Cloud. Yang Song was partially supported by the Apple PhD Fellowship in AI/ML.
致谢
我们感谢 Nanxin Chen、Ruiqi Gao、Jonathan Ho、Kevin Murphy、Tim Salimans 和 Han Zhang 在本项目过程中富有启发的讨论。本研究部分得到 NSF(#1651565、#1522054、#1733686)、ONR(N000141912145)、AFOSR(FA95501910024)以及 TensorFlow Research Cloud 的支持。Yang Song 部分得到 Apple PhD Fellowship in AI/ML 的资助。
References
参考文献
Allgower & Georg (2012) Eugene L Allgower and Kurt Georg. Numerical continuation methods: an introduction , volume 13. Springer Science & Business Media, 2012.
Anderson (1982) Brian D O Anderson. Reverse-time diffusion equation models. Stochastic Process. Appl. , 12(3):313–326, May 1982.
Behrmann et al. (2019) Jens Behrmann, Will Grathwohl, Ricky TQ Chen, David Duvenaud, and Jörn-Henrik Jacobsen. Invertible residual networks. In International Conference on Machine Learning , pp. 573–582, 2019.
Bordes et al. (2017) Florian Bordes, Sina Honari, and Pascal Vincent. Learning to generate samples from noise through infusion training. arXiv preprint arXiv:1703.06975 , 2017.
Brock et al. (2018) Andrew Brock, Jeff Donahue, and Karen Simonyan. Large scale gan training for high fidelity natural image synthesis. In International Conference on Learning Representations , 2018.
Cai et al. (2020) Ruojin Cai, Guandao Yang, Hadar Averbuch-Elor, Zekun Hao, Serge Belongie, Noah Snavely, and Bharath Hariharan. Learning gradient fields for shape generation. In Proceedings of the European Conference on Computer Vision (ECCV) , 2020.
Chen et al. (2020) Nanxin Chen, Yu Zhang, Heiga Zen, Ron J Weiss, Mohammad Norouzi, and William Chan. Wavegrad: Estimating gradients for waveform generation. arXiv preprint arXiv:2009.00713 , 2020.
Chen et al. (2018) Ricky TQ Chen, Yulia Rubanova, Jesse Bettencourt, and David K Duvenaud. Neural ordinary differential equations. In Advances in neural information processing systems , pp. 6571–6583, 2018.
Chen et al. (2019) Ricky TQ Chen, Jens Behrmann, David K Duvenaud, and Jörn-Henrik Jacobsen. Residual flows for invertible generative modeling. In Advances in Neural Information Processing Systems , pp. 9916–9926, 2019.
Dinh et al. (2016) Laurent Dinh, Jascha Sohl-Dickstein, and Samy Bengio. Density estimation using real nvp. arXiv preprint arXiv:1605.08803 , 2016.
Dormand & Prince (1980) John R Dormand and Peter J Prince. A family of embedded runge-kutta formulae. Journal of computational and applied mathematics , 6(1):19–26, 1980.
Du & Mordatch (2019) Yilun Du and Igor Mordatch. Implicit generation and modeling with energy based models. In H. Wallach, H. Larochelle, A. Beygelzimer, F. d'Alché-Buc, E. Fox, and R. Garnett (eds.), Advances in Neural Information Processing Systems , volume 32, pp. 3608–3618. Curran Associates, Inc., 2019.
Efron (2011) Bradley Efron. Tweedie’s formula and selection bias. Journal of the American Statistical Association , 106(496):1602–1614, 2011.
Goodfellow et al. (2014) Ian Goodfellow, Jean Pouget-Abadie, Mehdi Mirza, Bing Xu, David Warde-Farley, Sherjil Ozair, Aaron Courville, and Yoshua Bengio. Generative adversarial nets. In Advances in neural information processing systems , pp. 2672–2680, 2014.
Goyal et al. (2017) Anirudh Goyal Alias Parth Goyal, Nan Rosemary Ke, Surya Ganguli, and Yoshua Bengio. Variational walkback: Learning a transition operator as a stochastic recurrent net. In Advances in Neural Information Processing Systems , pp. 4392–4402, 2017.
Grathwohl et al. (2018) Will Grathwohl, Ricky TQ Chen, Jesse Bettencourt, Ilya Sutskever, and David Duvenaud. Ffjord: Free-form continuous dynamics for scalable reversible generative models. In International Conference on Learning Representations , 2018.
Grenander & Miller (1994) Ulf Grenander and Michael I Miller. Representations of knowledge in complex systems. Journal of the Royal Statistical Society: Series B (Methodological) , 56(4):549–581, 1994.
Ho et al. (2019) Jonathan Ho, Xi Chen, Aravind Srinivas, Yan Duan, and Pieter Abbeel. Flow++: Improving flow-based generative models with variational dequantization and architecture design. In International Conference on Machine Learning , pp. 2722–2730, 2019.
Ho et al. (2020) Jonathan Ho, Ajay Jain, and Pieter Abbeel. Denoising diffusion probabilistic models. Advances in Neural Information Processing Systems , 33, 2020.
Hutchinson (1990) Michael F Hutchinson. A stochastic estimator of the trace of the influence matrix for Laplacian smoothing splines. Communications in Statistics-Simulation and Computation , 19(2):433–450, 1990.
Hyvärinen (2005) Aapo Hyvärinen. Estimation of non-normalized statistical models by score matching. Journal of Machine Learning Research , 6(Apr):695–709, 2005.
Jolicoeur-Martineau et al. (2020) Alexia Jolicoeur-Martineau, Rémi Piché-Taillefer, Rémi Tachet des Combes, and Ioannis Mitliagkas. Adversarial score matching and improved sampling for image generation. arXiv preprint arXiv:2009.05475 , 2020.
Karras et al. (2018) Tero Karras, Timo Aila, Samuli Laine, and Jaakko Lehtinen. Progressive growing of gans for improved quality, stability, and variation. In International Conference on Learning Representations , 2018.
Karras et al. (2019) Tero Karras, Samuli Laine, and Timo Aila. A style-based generator architecture for generative adversarial networks. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pp. 4401–4410, 2019.
Karras et al. (2020a) Tero Karras, Miika Aittala, Janne Hellsten, Samuli Laine, Jaakko Lehtinen, and Timo Aila. Training generative adversarial networks with limited data. Advances in Neural Information Processing Systems , 33, 2020a.
Karras et al. (2020b) Tero Karras, Samuli Laine, Miika Aittala, Janne Hellsten, Jaakko Lehtinen, and Timo Aila. Analyzing and improving the image quality of StyleGAN. In Proc. CVPR , 2020b.
Kingma & Dhariwal (2018) Durk P Kingma and Prafulla Dhariwal. Glow: Generative flow with invertible 1x1 convolutions. In Advances in Neural Information Processing Systems , pp. 10215–10224, 2018.
Kloeden & Platen (2013) Peter E Kloeden and Eckhard Platen. Numerical solution of stochastic differential equations , volume 23. Springer Science & Business Media, 2013.
Kong et al. (2020) Zhifeng Kong, Wei Ping, Jiaji Huang, Kexin Zhao, and Bryan Catanzaro. Diffwave: A versatile diffusion model for audio synthesis. arXiv preprint arXiv:2009.09761 , 2020.
Krizhevsky et al. (2009) Alex Krizhevsky, Geoffrey Hinton, et al. Learning multiple layers of features from tiny images. 2009.
Liu et al. (2015) Ziwei Liu, Ping Luo, Xiaogang Wang, and Xiaoou Tang. Deep learning face attributes in the wild. In Proceedings of International Conference on Computer Vision (ICCV) , December 2015.
Maoutsa et al. (2020) Dimitra Maoutsa, Sebastian Reich, and Manfred Opper. Interacting particle solutions of fokker-planck equations through gradient-log-density estimation. arXiv preprint arXiv:2006.00702 , 2020.
Neal et al. (2011) Radford M Neal et al. Mcmc using hamiltonian dynamics. Handbook of markov chain monte carlo , 2(11):2, 2011.
Niu et al. (2020) Chenhao Niu, Yang Song, Jiaming Song, Shengjia Zhao, Aditya Grover, and Stefano Ermon. Permutation invariant graph generation via score-based generative modeling. volume 108 of Proceedings of Machine Learning Research , pp. 4474–4484, Online, 26–28 Aug 2020. PMLR.
Øksendal (2003) Bernt Øksendal. Stochastic differential equations. In Stochastic differential equations , pp. 65–84. Springer, 2003.
Pang et al. (2020) Tianyu Pang, Kun Xu, Chongxuan Li, Yang Song, Stefano Ermon, and Jun Zhu. Efficient learning of generative models via finite-difference score matching. arXiv preprint arXiv:2007.03317 , 2020.
Parisi (1981) Giorgio Parisi. Correlation functions and computer simulations. Nuclear Physics B , 180(3):378–384, 1981.
Razavi et al. (2019) Ali Razavi, Aaron van den Oord, and Oriol Vinyals. Generating diverse high-fidelity images with vq-vae-2. In Advances in Neural Information Processing Systems , pp. 14837–14847, 2019.
Roeder et al. (2020) Geoffrey Roeder, Luke Metz, and Diederik P Kingma. On linear identifiability of learned representations. arXiv preprint arXiv:2007.00810 , 2020.
Särkkä & Solin (2019) Simo Särkkä and Arno Solin. Applied stochastic differential equations , volume 10. Cambridge University Press, 2019.
Skilling (1989) John Skilling. The eigenvalues of mega-dimensional matrices. In Maximum Entropy and Bayesian Methods , pp. 455–466. Springer, 1989.
Sohl-Dickstein et al. (2015) Jascha Sohl-Dickstein, Eric Weiss, Niru Maheswaranathan, and Surya Ganguli. Deep unsupervised learning using nonequilibrium thermodynamics. In International Conference on Machine Learning , pp. 2256–2265, 2015.
Song & Ermon (2019) Yang Song and Stefano Ermon. Generative modeling by estimating gradients of the data distribution. In Advances in Neural Information Processing Systems , pp. 11895–11907, 2019.
Song & Ermon (2020) Yang Song and Stefano Ermon. Improved techniques for training score-based generative models. Advances in Neural Information Processing Systems , 33, 2020.
Song et al. (2019a) Yang Song, Sahaj Garg, Jiaxin Shi, and Stefano Ermon. Sliced score matching: A scalable approach to density and score estimation. In Proceedings of the Thirty-Fifth Conference on Uncertainty in Artificial Intelligence, UAI 2019, Tel Aviv, Israel, July 22-25, 2019 , pp. 204, 2019a.
Song et al. (2019b) Yang Song, Chenlin Meng, and Stefano Ermon. Mintnet: Building invertible neural networks with masked convolutions. In Advances in Neural Information Processing Systems , pp. 11002–11012, 2019b.
Tancik et al. (2020) Matthew Tancik, Pratul P. Srinivasan, Ben Mildenhall, Sara Fridovich-Keil, Nithin Raghavan, Utkarsh Singhal, Ravi Ramamoorthi, Jonathan T. Barron, and Ren Ng. Fourier features let networks learn high frequency functions in low dimensional domains. NeurIPS , 2020.
Vincent (2011) Pascal Vincent. A connection between score matching and denoising autoencoders. Neural computation , 23(7):1661–1674, 2011.
Yu et al. (2015) Fisher Yu, Ari Seff, Yinda Zhang, Shuran Song, Thomas Funkhouser, and Jianxiong Xiao. Lsun: Construction of a large-scale image dataset using deep learning with humans in the loop. arXiv preprint arXiv:1506.03365 , 2015.
Zagoruyko & Komodakis (2016) Sergey Zagoruyko and Nikos Komodakis. Wide residual networks. arXiv preprint arXiv:1605.07146 , 2016.
Zhang (2019) Richard Zhang. Making convolutional networks shift-invariant again. In ICML , 2019.
Appendix
附录
We include several appendices with additional details, derivations, and results. Our framework allows general SDEs with matrix-valued diffusion coefficients that depend on the state, for which we provide a detailed discussion in Appendix A. We give a full derivation of VE, VP and sub-VP SDEs in Appendix B, and discuss how to use them from a practitioner’s perspective in Appendix C. We elaborate on the probability flow formulation of our framework in Appendix D, including a derivation of the probability flow ODE (Section D.1), exact likelihood computation (Section D.2), probability flow sampling with a fixed discretization strategy (Section D.3), sampling with black-box ODE solvers (Section D.4), and experimental verification on uniquely identifiable encoding (Section D.5). We give a full description of the reverse diffusion sampler in Appendix E, the DDPM-type ancestral sampler for SMLD models in Appendix F, and Predictor-Corrector samplers in Appendix G. We explain our model architectures and detailed experimental settings in Appendix H, with CelebA-HQ samples therein. Finally, we detail on the algorithms for controllable generation in Appendix I, and include extended results for class-conditional generation (Section I.1), image inpainting (Section I.2), colorization (Section I.3), and a strategy for solving general inverse problems (Section I.4).
我们附上若干附录,补充细节、推导和结果。本框架允许扩散系数为矩阵值、并且依赖于状态的一般 SDE,附录 A 对此做了详细讨论。附录 B 给出 VE、VP 和 sub-VP SDE 的完整推导,附录 C 则从实践者的角度讨论如何使用它们。附录 D 展开本框架的概率流表述,包括概率流 ODE 的推导(第 D.1 节)、精确似然计算(第 D.2 节)、按固定离散化策略做概率流采样(第 D.3 节)、用黑盒 ODE 求解器采样(第 D.4 节),以及对唯一可识别编码的实验核验(第 D.5 节)。附录 E 完整描述反向扩散采样器,附录 F 给出用于 SMLD 模型的 DDPM 式祖先采样器,附录 G 给出预测-校正采样器。附录 H 说明模型结构和详细实验设置,其中包含 的 CelebA-HQ 样本。最后,附录 I 详述可控生成的算法,并补充类别条件生成(第 I.1 节)、图像补全(第 I.2 节)、上色(第 I.3 节)的扩展结果,以及求解一般反问题的策略(第 I.4 节)。
Appendix A The framework for more general SDEs
附录 A 更一般 SDE 下的框架
In the main text, we introduced our framework based on a simplified SDE Eq. 5 where the diffusion coefficient is independent of . It turns out that our framework can be extended to hold for more general diffusion coefficients. We can consider SDEs in the following form:
在正文中,我们以一条简化的 SDE(式 5)为基础介绍了这一框架,其中扩散系数不依赖于 。事实上,框架可以推广到更一般的扩散系数。我们可以考虑如下形式的 SDE:
where and . We follow the Itô interpretation of SDEs throughout this paper.
其中 ,。本文始终采用 SDE 的 Itô 解释。
According to (Anderson, 1982), the reverse-time SDE is given by (cf., Eq. 6)
根据 Anderson (1982),时间反向 SDE 由下式给出(对照式 6)
where we define for a matrix-valued function throughout the paper.
其中,对矩阵值函数 ,我们在全文中定义 。
The probability flow ODE corresponding to Eq. 15 has the following form (cf., Eq. 13, see a detailed derivation in Section D.1):
与式 15 对应的概率流 ODE 具有如下形式(对照式 13,详细推导见第 D.1 节):
Finally for conditional generation with the general SDE Eq. 15, we can solve the conditional reverse-time SDE below (cf., Eq. 14, details in Appendix I):
最后,要对一般 SDE(式 15)做条件生成,可以求解下面的条件时间反向 SDE(对照式 14,细节见附录 I):
$$\mathrm{d}\mathbf{x}={\mathbf{f}(\mathbf{x},t)-\nabla\cdot[\mathbf{G}(\mathbf{x},t)\mathbf{G}(\mathbf{x},t)^{\mkern-1.5mu\mathsf{T}}]-\mathbf{G}(\mathbf{x},t)\mathbf{G}(\mathbf{x},t)^{\mkern-1.5mu\mathsf{T}}\nabla_{\mathbf{x}}\log p_{t}(\mathbf{x})\
-\mathbf{G}(\mathbf{x},t)\mathbf{G}(\mathbf{x},t)^{\mkern-1.5mu\mathsf{T}}\nabla_{\mathbf{x}}\log p_{t}(\mathbf{y}\mid\mathbf{x})}\mathrm{d}t+\mathbf{G}(\mathbf{x},t)\mathrm{d}\bar{\mathbf{w}}. \tag{18}$$
When the drift and diffusion coefficient of an SDE are not affine, it can be difficult to compute the transition kernel in closed form. This hinders the training of score-based models, because Eq. 7 requires knowing . To overcome this difficulty, we can replace denoising score matching in Eq. 7 with other efficient variants of score matching that do not require computing . For example, when using sliced score matching (Song et al., 2019a), our training objective Eq. 7 becomes
当一条 SDE 的漂移系数和扩散系数都不是仿射的时候,转移核 往往很难写成闭式。这会妨碍分数模型的训练,因为式 7 需要知道 。为克服这一困难,可以把式 7 中的去噪分数匹配换成其他高效的分数匹配变体,这些变体不必计算 。例如,若采用切片分数匹配(Song et al., 2019a),则训练目标式 7 变为
where is a positive weighting function, , , and . We can always simulate the SDE to sample from , and solve Eq. 19 to train the time-dependent score-based model .
其中 是正的加权函数,,,。我们总可以模拟这条 SDE 来从 中采样,并求解式 19 来训练随时间变化的分数模型 。
Appendix B VE, VP and sub-VP SDEs
附录 B VE、VP 与 sub-VP SDE
Below we provide detailed derivations to show that the noise perturbations of SMLD and DDPM are discretizations of the Variance Exploding (VE) and Variance Preserving (VP) SDEs respectively. We additionally introduce sub-VP SDEs, a modification to VP SDEs that often achieves better performance in both sample quality and likelihoods.
下面给出详细推导,以说明 SMLD 和 DDPM 的噪声扰动分别是方差爆炸(VE)SDE 和方差保持(VP)SDE 的离散化。我们还另外引入 sub-VP SDE,它是对 VP SDE 的一种修改,往往在样本质量和似然上都有更好的表现。
First, when using a total of noise scales, each perturbation kernel of SMLD can be derived from the following Markov chain:
首先,当一共使用 个噪声尺度时,SMLD 的每个扰动核 都可以由下面这条马尔可夫链导出:
where , , and we have introduced to simplify the notation. In the limit of , the Markov chain becomes a continuous stochastic process , becomes a function , and becomes , where we have used a continuous time variable for indexing, rather than an integer . Let , , and for . We can rewrite Eq. 20 as follows with and :
其中 ,,并为简化记号引入了 。在 的极限下,马尔可夫链 变成连续随机过程 , 变成函数 , 变成 。这里我们改用连续时间变量 来做索引,而不再用整数 。对 ,令 ,,。取 ,并令 ,可以把式 20 改写为:
where the approximate equality holds when . In the limit of , this converges to
其中,当 时近似等号成立。在 的极限下,它收敛到
which is the VE SDE.
这就是 VE SDE。
For the perturbation kernels used in DDPM, the discrete Markov chain is
对 DDPM 所用的扰动核 ,离散马尔可夫链是
where . To obtain the limit of this Markov chain when , we define an auxiliary set of noise scales , and re-write Eq. 22 as below
其中 。为得到这条马尔可夫链在 时的极限,我们定义一组辅助噪声尺度 ,并把式 22 改写为
In the limit of , becomes a function indexed by . Let , , . We can rewrite the Markov chain Eq. 23 as the following with and :
在 的极限下, 变成由 索引的函数 。令 ,,。取 ,并令 ,可以把马尔可夫链式 23 改写为:
where the approximate equality holds when . Therefore, in the limit of , Eq. 24 converges to the following VP SDE:
其中,当 时近似等号成立。因此,在 的极限下,式 24 收敛到下面的 VP SDE:
So far, we have demonstrated that the noise perturbations used in SMLD and DDPM correspond to discretizations of VE and VP SDEs respectively. The VE SDE always yields a process with exploding variance when . In contrast, the VP SDE yields a process with bounded variance. In addition, the process has a constant unit variance for all when has a unit variance. Since the VP SDE has affine drift and diffusion coefficients, we can use Eq. (5.51) in Särkkä & Solin (2019) to obtain an ODE that governs the evolution of variance
至此,我们已经说明,SMLD 和 DDPM 所用的噪声扰动分别对应于 VE SDE 和 VP SDE 的离散化。VE SDE 在 时总会给出方差趋于无穷的过程;相比之下,VP SDE 给出的过程方差有界。此外,当 具有单位方差时,该过程对所有 都保持单位方差。由于 VP SDE 的漂移和扩散系数都是仿射的,我们可以利用 Särkkä & Solin (2019) 中的式 (5.51) 得到支配方差演化的 ODE
where for obeying a VP SDE. Solving this ODE, we obtain
其中,对服从 VP SDE 的 ,记 。求解这条 ODE,得到
from which it is clear that the variance is always bounded given . Moreover, if . Due to this difference, we name Eq. 9 as the Variance Exploding (VE) SDE, and Eq. 11 the Variance Preserving (VP) SDE.
由此可以清楚地看出,只要 给定,方差 就始终有界。而且,若 ,则 。正是由于这一差别,我们把式 9 称为方差爆炸(VE)SDE,把式 11 称为方差保持(VP)SDE。
Inspired by the VP SDE, we propose a new SDE called the sub-VP SDE, namely
受 VP SDE 启发,我们提出一条新的 SDE,称为 sub-VP SDE,即
Following standard derivations, it is straightforward to show that is the same for both VP and sub-VP SDEs; the variance function of sub-VP SDEs is different, given by
按标准推导不难看出,VP 与 sub-VP SDE 的 相同;sub-VP SDE 的方差函数则不同,由下式给出
where for a process obtained by solving Eq. 27. In addition, we observe that (i) for all with and shared ; and (ii) if . The former is why we name Eq. 27 the sub-VP SDE—its variance is always upper bounded by the corresponding VP SDE. The latter justifies the use of sub-VP SDEs for score-based generative modeling, since they can perturb any data distribution to standard Gaussian under suitable conditions, just like VP SDEs.
其中,对通过求解式 27 得到的过程 ,记 。此外,我们观察到:(i)当 且共用同一个 时,对所有 都有 ;(ii)若 ,则 。前者正是我们把式 27 称为 sub-VP SDE 的原因——它的方差始终被对应的 VP SDE 上界住。后者则说明,在合适的条件下,sub-VP SDE 也可以像 VP SDE 一样,把任意数据分布扰动成标准高斯,因而可以用于基于分数的生成建模。
VE, VP and sub-VP SDEs all have affine drift coefficients. Therefore, their perturbation kernels are all Gaussian and can be computed with Eqs. (5.50) and (5.51) in Särkkä & Solin (2019):
VE、VP 和 sub-VP SDE 的漂移系数都是仿射的。因此,它们的扰动核 都是高斯的,并且可以用 Särkkä & Solin (2019) 中的式 (5.50) 和 (5.51) 来计算:
$$\displaystyle p_{0t}(\mathbf{x}(t)\mid\mathbf{x}(0))=\begin{cases}\mathcal{N}\big(\mathbf{x}(t);\mathbf{x}(0),[\sigma^{2}(t)-\sigma^{2}(0)]\mathbf{I}\big),&~~~\text{(VE SDE)}\
\mathcal{N}\big(\mathbf{x}(t);\mathbf{x}(0)e^{-\frac{1}{2}\int_{0}^{t}\beta(s)\mathrm{d}s},\mathbf{I}-\mathbf{I}e^{-\int_{0}^{t}\beta(s)\mathrm{d}s}\big)&~~~\text{(VP SDE)}\
\mathcal{N}\big(\mathbf{x}(t);\mathbf{x}(0)e^{-\frac{1}{2}\int_{0}^{t}\beta(s)\mathrm{d}s},[1-e^{-\int_{0}^{t}\beta(s)\mathrm{d}s}]^{2}\mathbf{I}\big)&~~~\text{(sub-VP SDE)}\end{cases}. \tag{29}$$
As a result, all SDEs introduced here can be efficiently trained with the objective in Eq. 7.
于是,这里引入的所有 SDE 都可以用式 7 中的目标高效地训练。
Appendix C SDEs in the wild
附录 C 实践中的 SDE
Below we discuss concrete instantiations of VE and VP SDEs whose discretizations yield SMLD and DDPM models, and the specific sub-VP SDE used in our experiments. In SMLD, the noise scales is typically a geometric sequence where is fixed to and is chosen according to Technique 1 in Song & Ermon (2020). Usually, SMLD models normalize image inputs to the range . Since is a geometric sequence, we have for . In the limit of , we have for . The corresponding VE SDE is
下面讨论其离散化分别给出 SMLD 和 DDPM 模型的 VE、VP SDE 的具体实例,以及实验中所用的那条 sub-VP SDE。在 SMLD 中,噪声尺度 通常是几何序列, 固定为 , 则按 Song & Ermon (2020) 中的 Technique 1 选取。SMLD 模型通常把图像输入归一化到 。由于 是几何序列,对 有 。在 的极限下,对 有 。对应的 VE SDE 是
and the perturbation kernel can be derived via Eq. 29:
扰动核则可以由式 29 导出:
There is one subtlety when : by definition, (following the convention in Eq. 20), but . In other words, for SMLD is not differentiable since , causing the VE SDE in Eq. 21 undefined for . In practice, we bypass this issue by always solving the SDE and its associated probability flow ODE in the range for some small constant , and we use in our VE SDE experiments.
当 时有一个细节:按定义,(沿用式 20 中的约定),但 。换句话说,SMLD 的 并不可微,因为 ,这使得式 21 中的 VE SDE 在 处没有定义。实践中,我们总是在 上求解这条 SDE 及其对应的概率流 ODE,其中 是某个小常数;在 VE SDE 实验里我们取 。
For DDPM models, is typically an arithmetic sequence where for . Therefore, for in the limit of . This corresponds to the following instantiation of the VP SDE:
对 DDPM 模型, 通常是算术序列,其中 ,。因此,在 的极限下,对 有 。这对应于下面这条具体的 VP SDE:
where . In our experiments, we let and to match the settings in Ho et al. (2020). The perturbation kernel is given by
其中 。在实验中,我们取 、,以与 Ho et al. (2020) 的设置对齐。扰动核由下式给出
$$p_{0t}(\mathbf{x}(t)\mid\mathbf{x}(0))\
=\mathcal{N}\left(\mathbf{x}(t);e^{-\frac{1}{4}t^{2}(\bar{\beta}{\text{max}}-\bar{\beta}{\text{min}})-\frac{1}{2}t\bar{\beta}{\text{min}}}\mathbf{x}(0),\mathbf{I}-\mathbf{I}e^{-\frac{1}{2}t^{2}(\bar{\beta}{\text{max}}-\bar{\beta}{\text{min}})-t\bar{\beta}{\text{min}}}\right),\quad t\in[0,1]. \tag{33}$$
For DDPM, there is no discontinuity issue with the corresponding VP SDE; yet, there are numerical instability issues for training and sampling at , due to the vanishing variance of as . Therefore, same as the VE SDE, we restrict computation to for a small . For sampling, we choose so that the variance of in VP SDE matches the variance of in DDPM; for training and likelihood computation, we adopt which empirically gives better results.
对 DDPM 而言,对应的 VP SDE 没有间断问题;但在 处训练和采样会有数值不稳定性,因为当 时 的方差趋于零。因此,与 VE SDE 一样,我们把计算限制在 ,其中 较小。采样时取 ,使 VP SDE 中 的方差与 DDPM 中 的方差一致;训练和似然计算则采用 ,这在经验上效果更好。
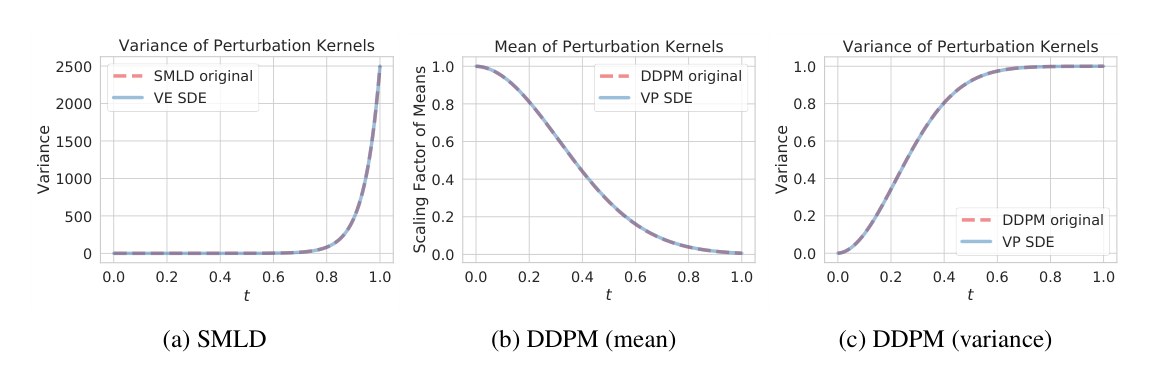
Figure 5: Discrete-time perturbation kernels and our continuous generalizations match each other almost exactly. (a) compares the variance of perturbation kernels for SMLD and VE SDE; (b) compares the scaling factors of means of perturbation kernels for DDPM and VP SDE; and (c) compares the variance of perturbation kernels for DDPM and VP SDE.
图 5:离散时间扰动核与我们的连续推广几乎完全吻合。(a)比较 SMLD 与 VE SDE 扰动核的方差;(b)比较 DDPM 与 VP SDE 扰动核均值的缩放因子;(c)比较 DDPM 与 VP SDE 扰动核的方差。
As a sanity check for our SDE generalizations to SMLD and DDPM, we compare the perturbation kernels of SDEs and original discrete Markov chains in Fig. 5. The SMLD and DDPM models both use noise scales. For SMLD, we only need to compare the variances of perturbation kernels since means are the same by definition. For DDPM, we compare the scaling factors of means and the variances. As demonstrated in Fig. 5, the discrete perturbation kernels of original SMLD and DDPM models align well with perturbation kernels derived from VE and VP SDEs.
作为对 SMLD 和 DDPM 之 SDE 推广的合理性检查,我们在图 5 中比较了 SDE 的扰动核与原来的离散马尔可夫链。SMLD 和 DDPM 模型都使用 个噪声尺度。对 SMLD,由于均值按定义相同,只需比较扰动核的方差;对 DDPM,则比较均值的缩放因子以及方差。如图 5 所示,原来 SMLD 和 DDPM 模型的离散扰动核,与由 VE、VP SDE 导出的扰动核对齐得很好。
For sub-VP SDEs, we use exactly the same as VP SDEs. This leads to the following perturbation kernel
对 sub-VP SDE,我们使用与 VP SDE 完全相同的 。由此得到下面的扰动核
$$p_{0t}(\mathbf{x}(t)\mid\mathbf{x}(0))\
=\mathcal{N}\left(\mathbf{x}(t);e^{-\frac{1}{4}t^{2}(\bar{\beta}{\text{max}}-\bar{\beta}{\text{min}})-\frac{1}{2}t\bar{\beta}{\text{min}}}\mathbf{x}(0),[1-e^{-\frac{1}{2}t^{2}(\bar{\beta}{\text{max}}-\bar{\beta}{\text{min}})-t\bar{\beta}{\text{min}}}]^{2}\mathbf{I}\right),\quad t\in[0,1]. \tag{34}$$
We also restrict numerical computation to the same interval of as VP SDEs.
数值计算同样被限制在与 VP SDE 相同的区间 上。
Empirically, we observe that smaller generally yields better likelihood values for all SDEs. For sampling, it is important to use an appropriate for better Inception scores and FIDs, although samples across different look visually the same to human eyes.
经验上,我们观察到,对所有 SDE,更小的 通常都会给出更好的似然。对采样而言,选用合适的 对提高 Inception 分数和 FID 很重要,尽管不同 下的样本在人眼看来几乎没有差别。
Appendix D Probability flow ODE
附录 D 概率流 ODE
D.1 Derivation
D.1 推导
The idea of probability flow ODE is inspired by Maoutsa et al. (2020), and one can find the derivation of a simplified case therein. Below we provide a derivation for the fully general ODE in Eq. 17. We consider the SDE in Eq. 15, which possesses the following form:
概率流 ODE 的想法受到 Maoutsa et al. (2020) 的启发,其中可以找到一种简化情形的推导。下面我们给出式 17 中完全一般的 ODE 的推导。我们考虑式 15 中的 SDE,其形式为:
where and . The marginal probability density evolves according to Kolmogorov’s forward equation (Fokker-Planck equation) (Øksendal, 2003)
其中 ,。边际概率密度 按 Kolmogorov 正向方程(Fokker-Planck 方程)演化(Øksendal, 2003)
We can easily rewrite Eq. 35 to obtain
我们可以很容易地把式 35 改写为
Note that
注意
based on which we can continue the rewriting of Eq. 36 to obtain
据此可以继续改写式 36,得到
where we define
其中我们定义
Inspecting Eq. 37, we observe that it equals Kolmogorov’s forward equation of the following SDE with (Kolmogorov’s forward equation in this case is also known as the Liouville equation.)
审视式 37 可以发现,它等于下面这条 SDE 在 时的 Kolmogorov 正向方程(此时该方程也称为 Liouville 方程。)
which is essentially an ODE:
而这本质上就是一条 ODE:
same as the probability flow ODE given by Eq. 17. Therefore, we have shown that the probability flow ODE Eq. 17 induces the same marginal probability density as the SDE in Eq. 15.
与式 17 给出的概率流 ODE 相同。因此,我们已经表明,概率流 ODE(式 17)诱导的边际概率密度 与式 15 中的 SDE 相同。
D.2 Likelihood computation
D.2 似然计算
The probability flow ODE in Eq. 17 has the following form when we replace the score with the time-dependent score-based model :
当我们用随时间变化的分数模型 替换分数 时,式 17 中的概率流 ODE 具有如下形式:
With the instantaneous change of variables formula (Chen et al., 2018), we can compute the log-likelihood of using
利用瞬时变量变换公式(Chen et al., 2018),我们可以用下式计算 的对数似然
where the random variable as a function of can be obtained by solving the probability flow ODE in Eq. 38. In many cases computing is expensive, so we follow Grathwohl et al. (2018) to estimate it with the Skilling-Hutchinson trace estimator (Skilling, 1989; Hutchinson, 1990). In particular, we have
其中作为 的函数的随机变量 可以通过求解式 38 中的概率流 ODE 得到。在许多情形下,计算 的代价很高,因此我们沿用 Grathwohl et al. (2018) 的做法,用 Skilling-Hutchinson 迹估计器(Skilling, 1989; Hutchinson, 1990)来估计它。具体而言,我们有
where denotes the Jacobian of , and the random variable satisfies and . The vector-Jacobian product can be efficiently computed using reverse-mode automatic differentiation, at approximately the same cost as evaluating . As a result, we can sample and then compute an efficient unbiased estimate to using . Since this estimator is unbiased, we can attain an arbitrarily small error by averaging over a sufficient number of runs. Therefore, by applying the Skilling-Hutchinson estimator Eq. 40 to Eq. 39, we can compute the log-likelihood to any accuracy.
其中 表示 的 Jacobian,随机变量 满足 以及 。向量-Jacobian 乘积 可以用反向模式自动微分高效计算,代价与求值 大致相同。因此,我们可以从 中采样 ,再用 得到 的一个高效无偏估计。由于这一估计器是无偏的,只要平均足够多次运行,就可以把误差压到任意小。因此,把 Skilling-Hutchinson 估计器(式 40)用到式 39 上,我们就可以把对数似然算到任意精度。
In our experiments, we use the RK45 ODE solver (Dormand & Prince, 1980) provided by scipy.integrate.solve_ivp in all cases. The bits/dim values in Table 2 are computed with atol=1e-5 and rtol=1e-5, same as Grathwohl et al. (2018). To give the likelihood results of our models in Table 2, we average the bits/dim obtained on the test dataset over five different runs with (see definition of in Appendix C).
在实验中,我们在所有情形下都使用 scipy.integrate.solve_ivp 提供的 RK45 ODE 求解器(Dormand & Prince, 1980)。表 2 中的 bits/dim 用 atol=1e-5 和 rtol=1e-5 计算,与 Grathwohl et al. (2018) 相同。为给出表 2 中我们模型的似然结果,我们在测试集上把 bits/dim 对五次不同运行取平均,并取 ( 的定义见附录 C)。
D.3 Probability flow sampling
D.3 概率流采样
Suppose we have a forward SDE
假设我们有一条正向 SDE
and one of its discretization
以及它的一种离散化
where . We assume the discretization schedule of time is fixed beforehand, and thus we absorb the dependency on into the notations of and . Using Eq. 17, we can obtain the following probability flow ODE:
其中 。我们假定时间的离散化日程预先固定,因而可以把对 的依赖吸收进 和 的记号里。利用式 17,可以得到下面的概率流 ODE:
We may employ any numerical method to integrate the probability flow ODE backwards in time for sample generation. In particular, we propose a discretization in a similar functional form to Eq. 41:
我们可以用任何数值方法把概率流 ODE 沿时间反向积分,以生成样本。特别地,我们提出一种与式 41 函数形式相近的离散化:
where the score-based model is conditioned on the iteration number . This is a deterministic iteration rule. Unlike reverse diffusion samplers or ancestral sampling, there is no additional randomness once the initial sample is obtained from the prior distribution. When applied to SMLD models, we can get the following iteration rule for probability flow sampling:
其中分数模型 以迭代编号 为条件。这是一条确定性的迭代规则。与反向扩散采样器或祖先采样不同,一旦初始样本 已从先验分布中得到,就不会再有额外的随机性。把它用到 SMLD 模型上,可以得到下面的概率流采样迭代规则:
Similarly, for DDPM models, we have
类似地,对 DDPM 模型,我们有
D.4 Sampling with black-box ODE solvers
D.4 用黑盒 ODE 求解器采样
For producing figures in Fig. 3, we use a DDPM model trained on CelebA-HQ with the same settings in Ho et al. (2020). All FID scores of our models in Table 2 are computed on samples from the RK45 ODE solver implemented in scipy.integrate.solve_ivp with atol=1e-5 and rtol=1e-5. We use for VE SDEs and for VP SDEs (see also Appendix C).
为绘制图 3 中的图,我们使用一个在 CelebA-HQ 上、按 Ho et al. (2020) 相同设置训练的 DDPM 模型。表 2 中我们模型的全部 FID 分数,都是在 scipy.integrate.solve_ivp 实现的 RK45 ODE 求解器给出的样本上计算的,atol=1e-5,rtol=1e-5。对 VE SDE 我们取 ,对 VP SDE 取 (亦见附录 C)。
Aside from the interpolation results in Fig. 3, we demonstrate more examples of latent space manipulation in Fig. 6, including interpolation and temperature scaling. The model tested here is a DDPM model trained with the same settings in Ho et al. (2020).
除了图 3 中的插值结果,我们在图 6 中展示了更多潜空间操作的例子,包括插值和温度缩放。这里测试的模型是按 Ho et al. (2020) 相同设置训练的 DDPM 模型。
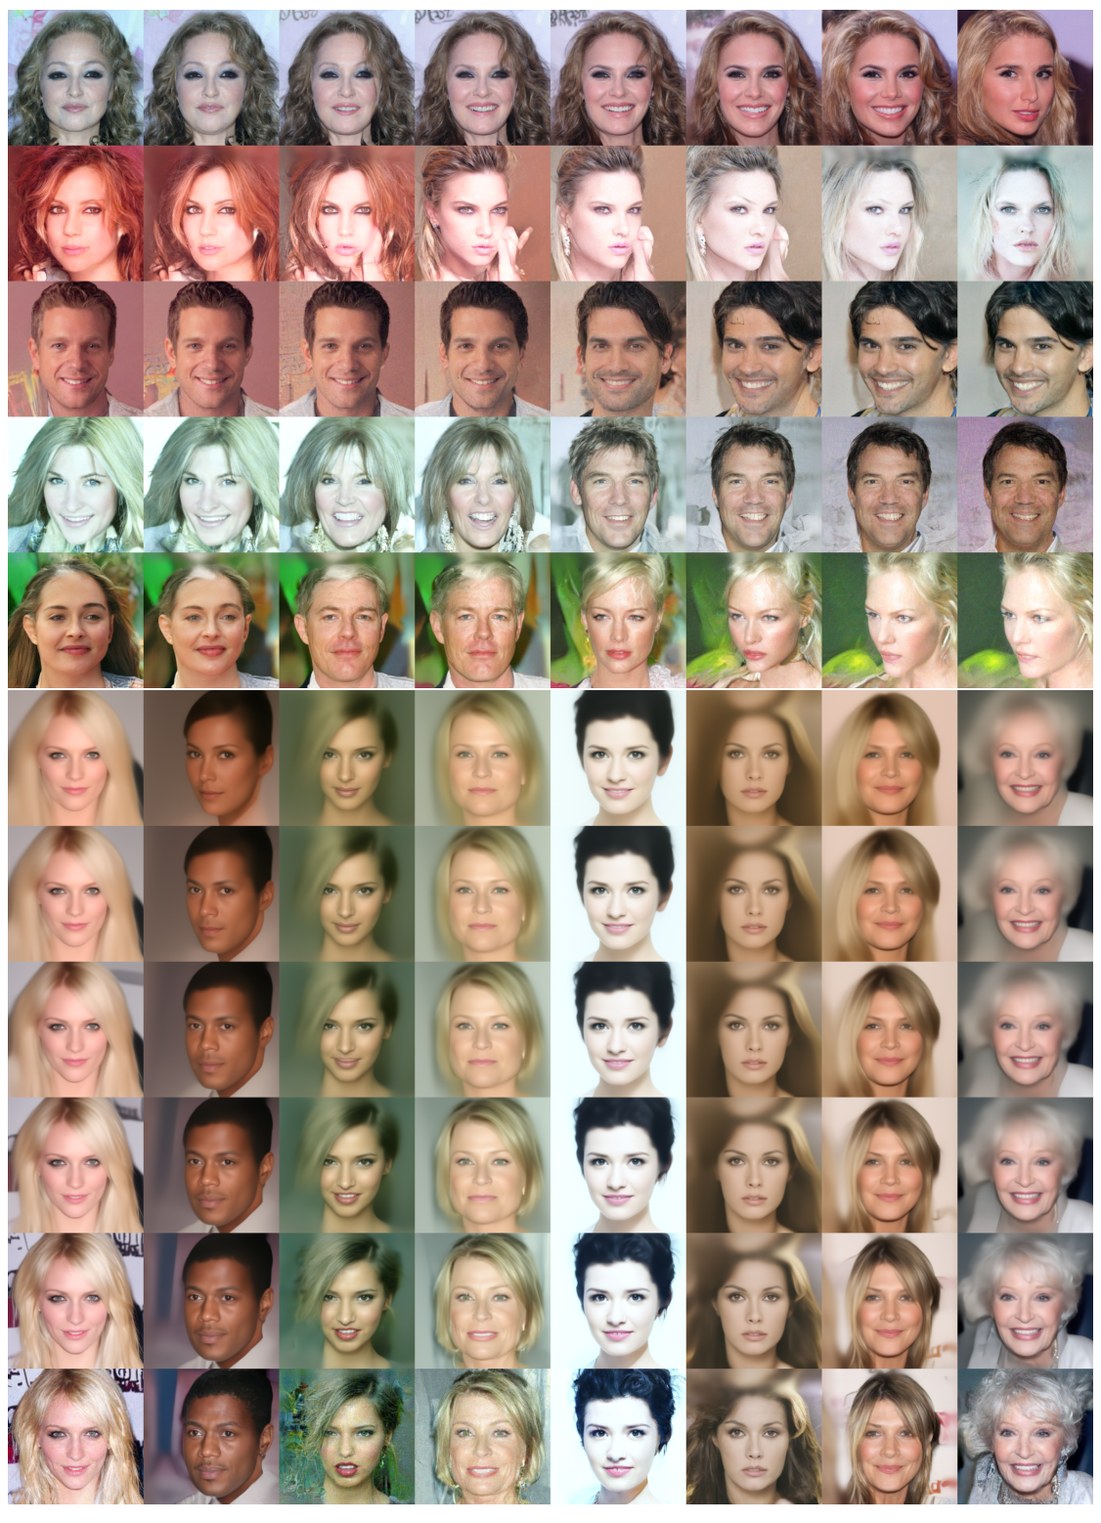
Figure 6: Samples from the probability flow ODE for VP SDE on CelebA-HQ. Top: spherical interpolations between random samples. Bottom: temperature rescaling (reducing norm of embedding).
图 6:VP SDE 的概率流 ODE 在 CelebA-HQ 上的样本。上:随机样本之间的球面插值。下:温度重缩放(减小嵌入的范数)。
Although solvers for the probability flow ODE allow fast sampling, their samples typically have higher (worse) FID scores than those from SDE solvers if no corrector is used. We have this empirical observation for both the discretization strategy in Section D.3, and black-box ODE solvers introduced above. Moreover, the performance of probability flow ODE samplers depends on the choice of the SDE—their sample quality for VE SDEs is much worse than VP SDEs especially for high-dimensional data.
尽管概率流 ODE 的求解器允许快速采样,但如果不使用校正器,它们的样本 FID 通常高于(也就是差于)SDE 求解器给出的样本。无论是第 D.3 节中的离散化策略,还是上面介绍的黑盒 ODE 求解器,我们都有这一经验观察。此外,概率流 ODE 采样器的表现还依赖于 SDE 的选择——它们在 VE SDE 上的样本质量远差于 VP SDE,在高维数据上尤其明显。
D.5 Uniquely identifiable encoding
D.5 唯一可识别的编码
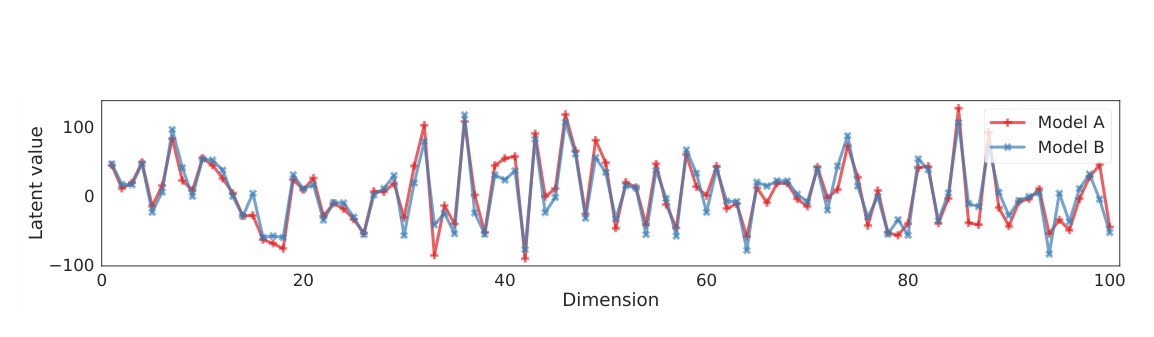
Figure 7: Comparing the first 100 dimensions of the latent code obtained for a random CIFAR-10 image. “Model A” and “Model B” are separately trained with different architectures.
图 7:比较一张随机 CIFAR-10 图像所得到的潜编码的前 100 维。“模型 A”和“模型 B”用不同结构分别训练。
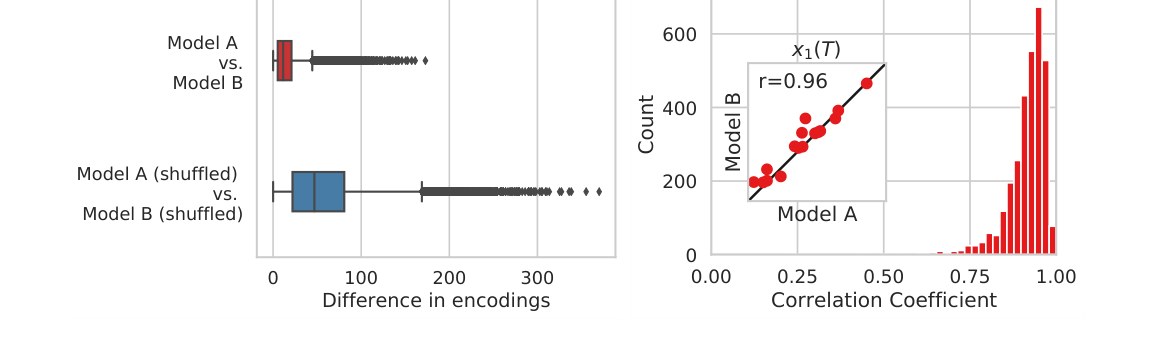
Figure 8: Left: The dimension-wise difference between encodings obtained by Model A and B. As a baseline, we also report the difference between shuffled representations of these two models. Right: The dimension-wise correlation coefficients of encodings obtained by Model A and Model B.
图 8:左:模型 A 与模型 B 所得编码的逐维差。作为基线,我们也报告把这两个模型的表示打乱之后的差。右:模型 A 与模型 B 所得编码的逐维相关系数。
As a sanity check, we train two models (denoted as “Model A” and “Model B”) with different architectures using the VE SDE on CIFAR-10. Here Model A is an NCSN++ model with 4 layers per resolution trained using the continuous objective in Eq. 7, and Model B is all the same except that it uses 8 layers per resolution. Model definitions are in Appendix H.
作为合理性检查,我们在 CIFAR-10 上用 VE SDE 训练了两个不同结构的模型(记为“模型 A”和“模型 B”)。其中模型 A 是按式 7 的连续目标训练、每个分辨率 4 层的 NCSN++ 模型,模型 B 除此之外全部相同,只是每个分辨率用 8 层。模型定义见附录 H。
We report the latent codes obtained by Model A and Model B for a random CIFAR-10 image in Fig. 7. In Fig. 8, we show the dimension-wise differences and correlation coefficients between latent encodings on a total of 16 CIFAR-10 images. Our results demonstrate that for the same inputs, Model A and Model B provide encodings that are close in every dimension, despite having different model architectures and training runs.
图 7 报告了模型 A 和模型 B 对一张随机 CIFAR-10 图像得到的潜编码。图 8 则展示了在共 16 张 CIFAR-10 图像上,潜编码的逐维差和相关系数。结果表明,尽管模型结构和训练运行不同,对相同输入,模型 A 和模型 B 给出的编码在每一个维上都接近。
Appendix E Reverse diffusion sampling
附录 E 反向扩散采样
Given a forward SDE
给定一条正向 SDE
and suppose the following iteration rule is a discretization of it:
并假设下面的迭代规则是它的一种离散化:
where . Here we assume the discretization schedule of time is fixed beforehand, and thus we can absorb it into the notations of and .
其中 。这里我们假定时间的离散化日程预先固定,因而可以把它吸收进 和 的记号里。
Based on Eq. 45, we propose to discretize the reverse-time SDE
基于式 45,我们提议用相近的函数形式来离散化时间反向 SDE
with a similar functional form, which gives the following iteration rule for :
从而对 给出下面的迭代规则:
where our trained score-based model is conditioned on iteration number .
其中我们训练好的分数模型 以迭代编号 为条件。
When applying Eq. 46 to Eqs. 20 and 10, we obtain a new set of numerical solvers for the reverse-time VE and VP SDEs, resulting in sampling algorithms as shown in the “predictor” part of Algorithms 2 and 3. We name these sampling methods (that are based on the discretization strategy in Eq. 46) reverse diffusion samplers.
把式 46 用到式 20 和式 10 上,我们就为时间反向的 VE、VP SDE 得到了一组新的数值求解器,相应的采样算法见算法 2 和算法 3 中的“预测器”部分。我们把这些基于式 46 离散化策略的采样方法称为反向扩散采样器。
As expected, the ancestral sampling of DDPM (Ho et al., 2020) (Eq. 4) matches its reverse diffusion counterpart when for all (which happens when since , see Appendix B), because
正如所料,DDPM(Ho et al., 2020)的祖先采样(式 4)在对所有 都有 时(当 时就会发生,因为 ,见附录 B)与对应的反向扩散采样一致,因为
Therefore, the original ancestral sampler of Eq. 4 is essentially a different discretization to the same reverse-time SDE. This unifies the sampling method in Ho et al. (2020) as a numerical solver to the reverse-time VP SDE in our continuous framework.
因此,式 4 原来的祖先采样器,本质上只是对同一条时间反向 SDE 的另一种离散化。这就把 Ho et al. (2020) 中的采样方法,统一成本连续框架中时间反向 VP SDE 的一种数值求解器。
Appendix F Ancestral sampling for SMLD models
附录 F 用于 SMLD 模型的祖先采样
The ancestral sampling method for DDPM models can also be adapted to SMLD models. Consider a sequence of noise scales as in SMLD. By perturbing a data point with these noise scales sequentially, we obtain a Markov chain , where
DDPM 模型的祖先采样方法也可以改用于 SMLD 模型。与 SMLD 中一样,考虑一串噪声尺度 。用这些噪声尺度依次扰动一个数据点 ,就得到一条马尔可夫链 ,其中
Here we assume to simplify notations. Following Ho et al. (2020), we can compute
这里假定 以简化记号。沿用 Ho et al. (2020),我们可以计算
If we parameterize the reverse transition kernel as , then
若把反向转移核参数化为 ,则
where is one representative term in the ELBO objective (see Eq. (8) in Ho et al. (2020)), is a constant that does not depend on , , and . We can therefore parameterize via
其中 是 ELBO 目标中的一个代表性项(见 Ho et al. (2020) 的式 (8)), 是不依赖于 的常数,,并且 。因此可以把 参数化为
where is to estimate . As in Ho et al. (2020), we let . Through ancestral sampling on , we obtain the following iteration rule
其中 用来估计 。与 Ho et al. (2020) 中一样,我们令 。在 上做祖先采样,就得到下面的迭代规则
where , denotes the optimal parameter of , and . We call Eq. 47 the ancestral sampling method for SMLD models.
其中 , 表示 的最优参数,。我们把式 47 称为用于 SMLD 模型的祖先采样方法。
Appendix G Predictor-Corrector samplers
附录 G 预测-校正采样器
Algorithm 1 Predictor-Corrector (PC) sampling
Require: : Number of discretization steps for the reverse-time SDE; : Number of corrector steps
1: Initialize
2: for to do
3:
4: for to do
5:
6: return
算法 1 预测-校正(PC)采样
Require: :时间反向 SDE 的离散化步数;:校正器步数
1: 初始化
2: for to do
3:
4: for to do
5:
6: return
Predictor-Corrector (PC) sampling
The predictor can be any numerical solver for the reverse-time SDE with a fixed discretization strategy. The corrector can be any score-based MCMC approach. In PC sampling, we alternate between the predictor and corrector, as described in Algorithm 1. For example, when using the reverse diffusion SDE solver (Appendix E) as the predictor, and annealed Langevin dynamics (Song & Ermon, 2019) as the corrector, we have Algorithms 2 and 3 for VE and VP SDEs respectively, where are step sizes for Langevin dynamics as specified below.
预测-校正(PC)采样
预测器可以是按固定离散化策略求解时间反向 SDE 的任何数值求解器。校正器可以是任何基于分数的 MCMC 方法。在 PC 采样中,我们按算法 1 所述,在预测器和校正器之间交替进行。例如,若把反向扩散 SDE 求解器(附录 E)当作预测器,把退火 Langevin 动力学(Song & Ermon, 2019)当作校正器,就分别得到用于 VE、VP SDE 的算法 2 和算法 3,其中 是下面给出的 Langevin 动力学步长。
Algorithm 2 PC sampling (VE SDE)
1:
2: for to do
3:
4:
5:
6: for to do
7:
8:
9: return
Algorithm 3 PC sampling (VP SDE)
1:
2: for to do
3:
4:
5:
6: for to do
7:
8:
9: return
算法 2 PC 采样(VE SDE)
1:
2: for to do
3:
4:
5:
6: for to do
7:
8:
9: return
算法 3 PC 采样(VP SDE)
1:
2: for to do
3:
4:
5:
6: for to do
7:
8:
9: return
The corrector algorithms
We take the schedule of annealed Langevin dynamics in Song & Ermon (2019), but re-frame it with slight modifications in order to get better interpretability and empirical performance. We provide the corrector algorithms in Algorithms 4 and 5 respectively, where we call the “signal-to-noise” ratio. We determine the step size using the norm of the Gaussian noise , norm of the score-based model and the signal-to-noise ratio . When sampling a large batch of samples together, we replace the norm with the average norm across the mini-batch. When the batch size is small, we suggest replacing with , where is the dimensionality of .
校正器算法
我们采用 Song & Ermon (2019) 中退火 Langevin 动力学的日程,但稍作改写,以便有更好的可解释性和经验表现。校正器算法分别给在算法 4 和算法 5 中,其中我们把 称为“信噪”比。步长 由高斯噪声的范数 、分数模型的范数 以及信噪比 共同决定。当一次采样很大一批样本时,我们把范数 换成小批量上的平均范数。当批量较小时,我们建议把 换成 ,其中 是 的维数。
Algorithm 4 Corrector algorithm (VE SDE).
Require: , , , .
1:
2: for to do
3: for to do
4:
5:
6:
7:
8:
9: return
算法 4 校正器算法(VE SDE)。
Require: ,,,。
1:
2: for to do
3: for to do
4:
5:
6:
7:
8:
9: return
Algorithm 5 Corrector algorithm (VP SDE).
Require: , , , , .
1:
2: for to do
3: for to do
4:
5:
6:
7:
8:
9: return
算法 5 校正器算法(VP SDE)。
Require: ,,,,。
1:
2: for to do
3: for to do
4:
5:
6:
7:
8:
9: return
Denoising
For both SMLD and DDPM models, the generated samples typically contain small noise that is hard to detect by humans. As noted by Jolicoeur-Martineau et al. (2020), FIDs can be significantly worse without removing this noise. This unfortunate sensitivity to noise is also part of the reason why NCSN models trained with SMLD has been performing worse than DDPM models in terms of FID, because the former does not use a denoising step at the end of sampling, while the latter does. In all experiments of this paper we ensure there is a single denoising step at the end of sampling, using Tweedie’s formula (Efron, 2011).
去噪
对 SMLD 和 DDPM 模型,生成的样本通常都带有人眼不易察觉的小噪声。正如 Jolicoeur-Martineau et al. (2020) 所指出的,若不去掉这一噪声,FID 会差很多。对噪声的这种不幸敏感性,也是用 SMLD 训练的 NCSN 模型在 FID 上一直不如 DDPM 模型的部分原因:前者在采样结束时没有去噪一步,而后者有。本文的全部实验都保证在采样结束时用 Tweedie 公式(Efron, 2011)做一次去噪。
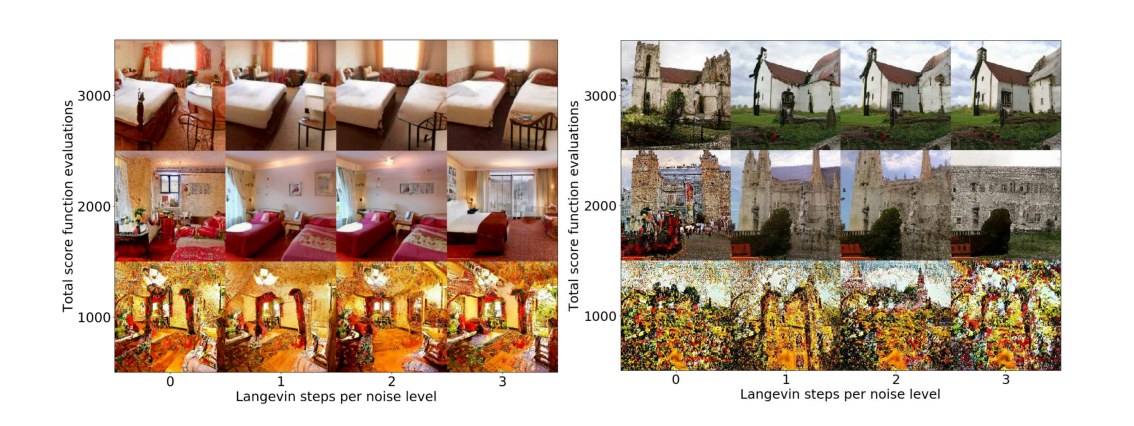
Figure 9: PC sampling for LSUN bedroom and church. The vertical axis corresponds to the total computation, and the horizontal axis represents the amount of computation allocated to the corrector. Samples are the best when computation is split between the predictor and corrector.
图 9:在 LSUN bedroom 和 church 上的 PC 采样。纵轴对应总计算量,横轴表示分配给校正器的计算量。当计算量在预测器和校正器之间分担时,样本最好。
Training
We use the same architecture in Ho et al. (2020) for our score-based models. For the VE SDE, we train a model with the original SMLD objective in Eq. 1; similarly for the VP SDE, we use the original DDPM objective in Eq. 3. We apply a total number of 1000 noise scales for training both models. For results in Fig. 9, we train an NCSN++ model (definition in Appendix H) on LSUN bedroom and church_outdoor (Yu et al., 2015) datasets with the VE SDE and our continuous objective Eq. 7. The batch size is fixed to 128 on CIFAR-10 and 64 on LSUN.
训练
分数模型采用与 Ho et al. (2020) 相同的结构。对 VE SDE,我们用式 1 中原来的 SMLD 目标训练模型;对 VP SDE,则用式 3 中原来的 DDPM 目标。两个模型的训练都使用共 1000 个噪声尺度。对图 9 中的结果,我们在 的 LSUN bedroom 和 church_outdoor(Yu et al., 2015)数据集上,用 VE SDE 和我们的连续目标式 7 训练了一个 NCSN++ 模型(定义见附录 H)。批量在 CIFAR-10 上固定为 128,在 LSUN 上为 64。
Ad-hoc interpolation methods for noise scales
Models in this experiment are all trained with 1000 noise scales. To get results for P2000 (predictor-only sampler using 2000 steps) which requires 2000 noise scales, we need to interpolate between 1000 noise scales at test time. The specific architecture of the noise-conditional score-based model in Ho et al. (2020) uses sinusoidal positional embeddings for conditioning on integer time steps. This allows us to interpolate between noise scales at test time in an ad-hoc way (while it is hard to do so for other architectures like the one in Song & Ermon (2019)). Specifically, for SMLD models, we keep and fixed and double the number of time steps. For DDPM models, we halve and before doubling the number of time steps. Suppose is a score-based model trained on time steps, and let denote the corresponding interpolated score-based model at time steps. We test two different interpolation strategies for time steps: linear interpolation where and rounding interpolation where . We provide results with linear interpolation in Table 1, and give results of rounding interpolation in Table 4. We observe that different interpolation methods result in performance differences but maintain the general trend of predictor-corrector methods performing on par or better than predictor-only or corrector-only samplers.
噪声尺度的临时插值方法
本实验中的模型都用 1000 个噪声尺度训练。要得到需要 2000 个噪声尺度的 P2000(只用预测器、走 2000 步的采样器)结果,就必须在测试时在 1000 个噪声尺度之间插值。Ho et al. (2020) 中噪声条件分数模型的具体结构,用正弦位置嵌入来对整数时间步做条件化。这使我们能在测试时用一种临时的方式在噪声尺度之间插值(而对 Song & Ermon (2019) 那样的其他结构则很难做到)。具体来说,对 SMLD 模型,我们保持 和 不变,并把时间步数加倍;对 DDPM 模型,则先把 和 减半,再把时间步数加倍。设 是在 个时间步上训练的分数模型,并令 表示在 个时间步上相应的插值分数模型。我们测试了两种时间步插值策略:线性插值 ,以及四舍五入插值 。表 1 给出线性插值的结果,表 4 给出四舍五入插值的结果。我们观察到,不同插值方法会造成表现上的差异,但总的趋势仍然是:预测-校正方法与只用预测器或只用校正器的采样器相当,或更好。
Hyper-parameters of the samplers
For Predictor-Corrector and corrector-only samplers on CIFAR-10, we search for the best signal-to-noise ratio () over a grid that increments at 0.01. We report the best in Table 5. For LSUN bedroom/church_outdoor, we fix to 0.075. Unless otherwise noted, we use one corrector step per noise scale for all PC samplers. We use two corrector steps per noise scale for corrector-only samplers on CIFAR-10. For sample generation, the batch size is 1024 on CIFAR-10 and 8 on LSUN bedroom/church_outdoor.
采样器的超参数
对 CIFAR-10 上的预测-校正采样器和只用校正器的采样器,我们在以 0.01 为步长的网格上搜索最好的信噪比(),并在表 5 中报告最优的 。对 LSUN bedroom/church_outdoor,我们把 固定为 0.075。除非另行说明,所有 PC 采样器在每个噪声尺度上使用一步校正。CIFAR-10 上只用校正器的采样器,每个噪声尺度使用两步校正。生成样本时,CIFAR-10 上的批量是 1024,LSUN bedroom/church_outdoor 上是 8。
Table 4: Comparing different samplers on CIFAR-10, where “P2000” uses the rounding interpolation between noise scales. Shaded regions are obtained with the same computation (number of score function evaluations). Mean and standard deviation are reported over five sampling runs.
| FID \ Sampler / Predictor | P1000 (VE / SMLD) | P2000 (VE) | C2000 (VE) | PC1000 (VE) | P1000 (VP / DDPM) | P2000 (VP) | C2000 (VP) | PC1000 (VP) |
|---|---|---|---|---|---|---|---|---|
| ancestral sampling | ||||||||
| reverse diffusion | ||||||||
| probability flow |
(Two super-columns: Variance Exploding SDE (SMLD) and Variance Preserving SDE (DDPM). Shaded in the original table: the P2000 and PC1000 columns.)
表 4: 在 CIFAR-10 上比较不同采样器,其中“P2000”在噪声尺度之间使用四舍五入插值。阴影区域对应相同的计算量(分数函数求值次数)。均值和标准差按五次采样运行报告。
| FID \ 采样器 / 预测器 | P1000(VE / SMLD) | P2000(VE) | C2000(VE) | PC1000(VE) | P1000(VP / DDPM) | P2000(VP) | C2000(VP) | PC1000(VP) |
|---|---|---|---|---|---|---|---|---|
| 祖先采样 | ||||||||
| 反向扩散 | ||||||||
| 概率流 |
(表分两大栏:方差爆炸 SDE(SMLD)与方差保持 SDE(DDPM)。原表中 P2000 与 PC1000 两列为阴影。)
Table 5: Optimal signal-to-noise ratios of different samplers. “P1000” or “P2000”: predictor-only samplers using 1000 or 2000 steps. “C2000”: corrector-only samplers using 2000 steps. “PC1000”: PC samplers using 1000 predictor and 1000 corrector steps.
| \ Sampler / Predictor | P1000 (VE / SMLD) | P2000 (VE) | C2000 (VE) | PC1000 (VE) | P1000 (VP / DDPM) | P2000 (VP) | C2000 (VP) | PC1000 (VP) |
|---|---|---|---|---|---|---|---|---|
| ancestral sampling | — | — | 0.17 | — | — | 0.01 | ||
| reverse diffusion | — | — | 0.22 | 0.16 | — | — | 0.27 | 0.01 |
| probability flow | — | — | 0.17 | — | — | 0.04 |
(Two super-columns: VE SDE (SMLD) and VP SDE (DDPM). Predictor-only columns are dashes, since is a corrector hyper-parameter.)
表 5: 不同采样器的最优信噪比。“P1000”或“P2000”:只用预测器、走 1000 或 2000 步的采样器。“C2000”:只用校正器、走 2000 步的采样器。“PC1000”:使用 1000 步预测和 1000 步校正的 PC 采样器。
| \ 采样器 / 预测器 | P1000(VE / SMLD) | P2000(VE) | C2000(VE) | PC1000(VE) | P1000(VP / DDPM) | P2000(VP) | C2000(VP) | PC1000(VP) |
|---|---|---|---|---|---|---|---|---|
| 祖先采样 | — | — | 0.17 | — | — | 0.01 | ||
| 反向扩散 | — | — | 0.22 | 0.16 | — | — | 0.27 | 0.01 |
| 概率流 | — | — | 0.17 | — | — | 0.04 |
(表分两大栏:VE SDE(SMLD)与 VP SDE(DDPM)。只用预测器的各列为破折号,因为 是校正器的超参数。)
Appendix H Architecture improvements
附录 H 结构上的改进
We explored several architecture designs to improve score-based models for both VE and VP SDEs. Our endeavor gives rise to new state-of-the-art sample quality on CIFAR-10, new state-of-the-art likelihood on uniformly dequantized CIFAR-10, and enables the first high-fidelity image samples of resolution from score-based generative models. Code and checkpoints are open-sourced at https://github.com/yang-song/score_sde.
我们探索了若干结构设计,以改进同时用于 VE 和 VP SDE 的分数模型。这一努力在 CIFAR-10 上给出了新的最好样本质量,在均匀去量化的 CIFAR-10 上给出了新的最好似然,并使分数生成模型第一次能够给出 分辨率的高保真图像样本。代码和检查点已开源:https://github.com/yang-song/score_sde。
H.1 Settings for architecture exploration
H.1 结构探索的设置
Unless otherwise noted, all models are trained for 1.3M iterations, and we save one checkpoint per 50k iterations. For VE SDEs, we consider two datasets: CIFAR-10 (Krizhevsky et al., 2009) and CelebA (Liu et al., 2015), pre-processed following Song & Ermon (2020). We compare different configurations based on their FID scores averaged over checkpoints after 0.5M iterations. For VP SDEs, we only consider the CIFAR-10 dataset to save computation, and compare models based on the average FID scores over checkpoints obtained between 0.25M and 0.5M iterations, because FIDs turn to increase after 0.5M iterations for VP SDEs.
除非另行说明,所有模型都训练 130 万次迭代,每 5 万次迭代保存一个检查点。对 VE SDE,我们考虑两个数据集: 的 CIFAR-10(Krizhevsky et al., 2009)和 的 CelebA(Liu et al., 2015),预处理按 Song & Ermon (2020)。比较不同配置时,依据的是 50 万次迭代之后各检查点 FID 的平均值。对 VP SDE,为节省计算只考虑 CIFAR-10,并依据 25 万到 50 万次迭代之间各检查点 FID 的平均值来比较模型,因为 VP SDE 的 FID 在 50 万次迭代之后往往会上升。
All FIDs are computed on 50k samples with tensorflow_gan. For sampling, we use the PC sampler discretized at 1000 time steps. We choose reverse diffusion (see Appendix E) as the predictor. We use one corrector step per update of the predictor for VE SDEs with a signal-to-noise ratio of 0.16, but save the corrector step for VP SDEs since correctors there only give slightly better results but require double computation. We follow Ho et al. (2020) for optimization, including the learning rate, gradient clipping, and learning rate warm-up schedules. Unless otherwise noted, models are trained with the original discrete SMLD and DDPM objectives in Eqs. 1 and 3 and use a batch size of 128. The optimal architectures found under these settings are subsequently transferred to continuous objectives and deeper models. We also directly transfer the best architecture for VP SDEs to sub-VP SDEs, given the similarity of these two SDEs.
全部 FID 都在 5 万个样本上用 tensorflow_gan 计算。采样时,我们使用在 1000 个时间步上离散化的 PC 采样器。预测器选用反向扩散(见附录 E)。对 VE SDE,预测器每更新一次就做一步校正,信噪比为 0.16;对 VP SDE 则省去校正步,因为那里的校正器只带来略好的结果,却要使计算量加倍。优化沿用 Ho et al. (2020),包括学习率、梯度裁剪和学习率预热日程。除非另行说明,模型用式 1 和式 3 中原来的离散 SMLD、DDPM 目标训练,批量大小为 128。在这些设置下找到的最优结构,随后被迁移到连续目标和更深的模型上。鉴于 VP 与 sub-VP SDE 很相近,我们还把 VP SDE 上最好的结构直接迁移到 sub-VP SDE。
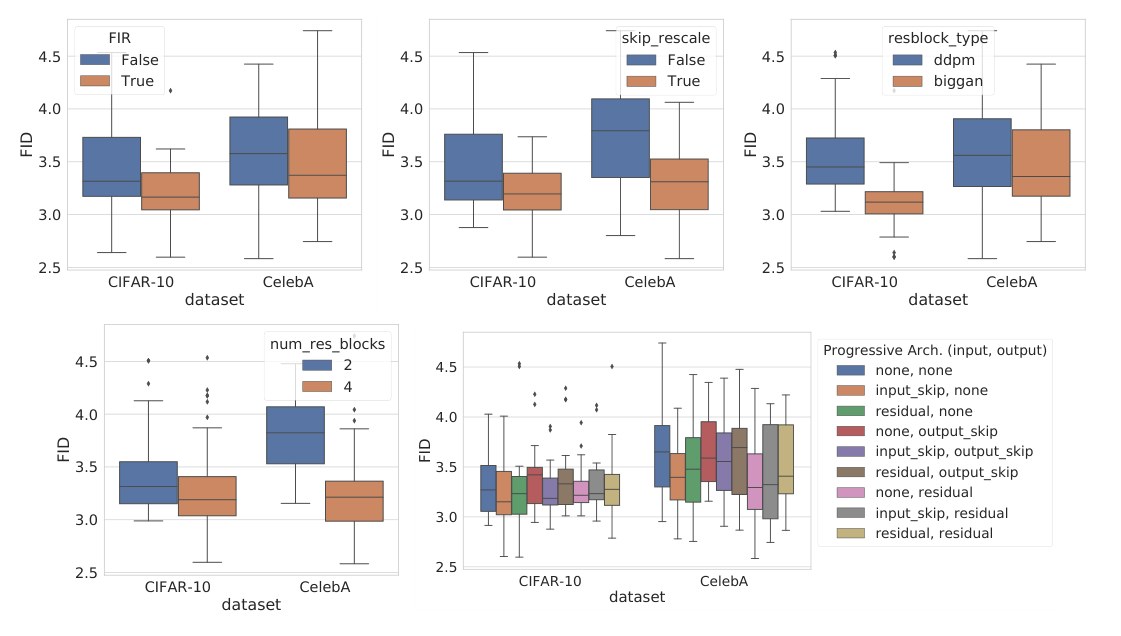
Figure 10: The effects of different architecture components for score-based models trained with VE perturbations.
图 10:用 VE 扰动训练的分数模型中,不同结构组件的作用。
Our architecture is mostly based on Ho et al. (2020). We additionally introduce the following components to maximize the potential improvement of score-based models.
我们的结构大体以 Ho et al. (2020) 为基础。为尽量发掘分数模型的改进空间,我们另外引入了下面这些组件。
- Upsampling and downsampling images with anti-aliasing based on Finite Impulse Response (FIR) (Zhang, 2019). We follow the same implementation and hyper-parameters in StyleGAN-2 (Karras et al., 2020b).
- 基于有限脉冲响应(FIR)的抗混叠上采样与下采样(Zhang, 2019)。实现和超参数与 StyleGAN-2(Karras et al., 2020b)相同。
- Rescaling all skip connections by . This has been demonstrated effective in several best-in-class GAN models, including ProgressiveGAN (Karras et al., 2018), StyleGAN (Karras et al., 2019) and StyleGAN-2 (Karras et al., 2020b).
- 把所有跳跃连接按 重新缩放。这在若干一流的 GAN 模型中已被证明有效,包括 ProgressiveGAN(Karras et al., 2018)、StyleGAN(Karras et al., 2019)和 StyleGAN-2(Karras et al., 2020b)。
- Replacing the original residual blocks in DDPM with residual blocks from BigGAN (Brock et al., 2018).
- 把 DDPM 中原来的残差块换成 BigGAN(Brock et al., 2018)中的残差块。
- Increasing the number of residual blocks per resolution from to .
- 把每个分辨率上的残差块数目从 增加到 。
- Incorporating progressive growing architectures. We consider two progressive architectures for input: “input skip” and “residual”, and two progressive architectures for output: “output skip” and “residual”. These progressive architectures are defined and implemented according to StyleGAN-2.
- 引入渐进式增长结构。我们为输入考虑两种渐进结构:“input skip”和“residual”,为输出也考虑两种:“output skip”和“residual”。这些渐进结构按 StyleGAN-2 来定义和实现。
We also tested equalized learning rates, a trick used in very successful models like ProgressiveGAN (Karras et al., 2018) and StyleGAN (Karras et al., 2019). However, we found it harmful at an early stage of our experiments, and therefore decided not to explore more on it.
我们还测试了均衡学习率,这是 ProgressiveGAN(Karras et al., 2018)和 StyleGAN(Karras et al., 2019)等非常成功的模型用过的技巧。不过,在实验较早阶段我们就发现它有害,因此决定不再继续探索。
The exponential moving average (EMA) rate has a significant impact on performance. For models trained with VE perturbations, we notice that 0.999 works better than 0.9999, whereas for models trained with VP perturbations it is the opposite. We therefore use an EMA rate of 0.999 and 0.9999 for VE and VP models respectively.
指数滑动平均(EMA)速率对表现有显著影响。对用 VE 扰动训练的模型,我们注意到 0.999 比 0.9999 更好;对用 VP 扰动训练的模型则正好相反。因此,VE 和 VP 模型分别采用 0.999 和 0.9999 的 EMA 速率。
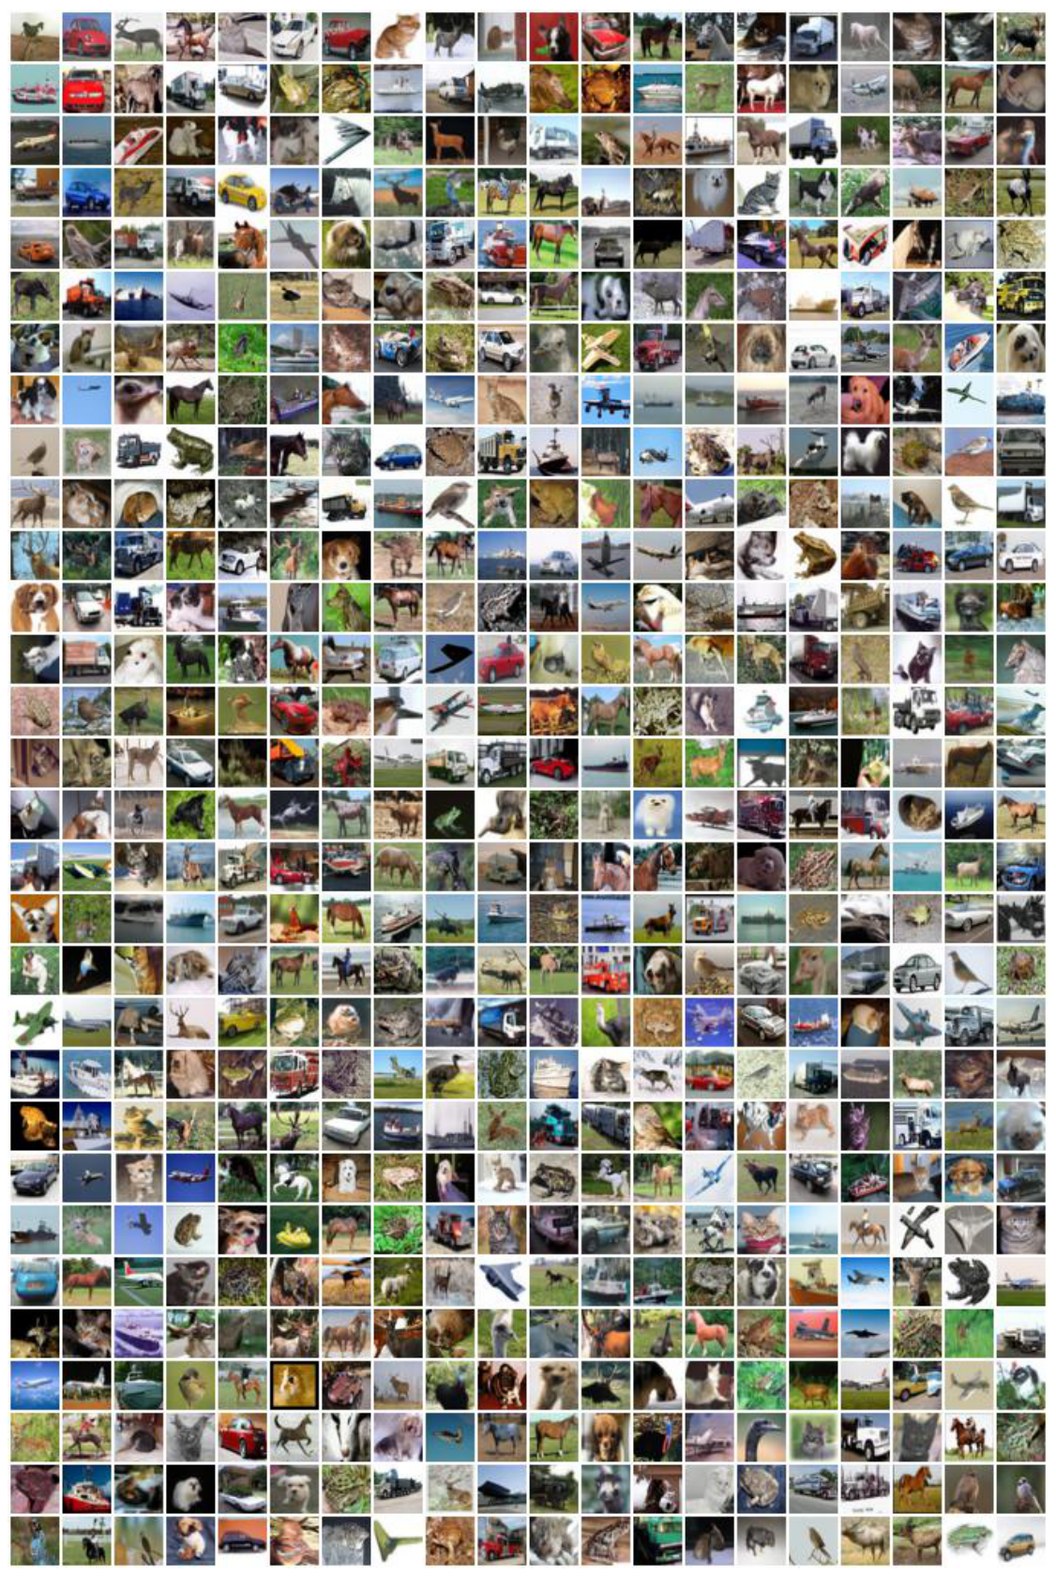
Figure 11: Unconditional CIFAR-10 samples from NCSN++ cont. (deep, VE).
图 11:来自 NCSN++ cont.(deep, VE)的无条件 CIFAR-10 样本。
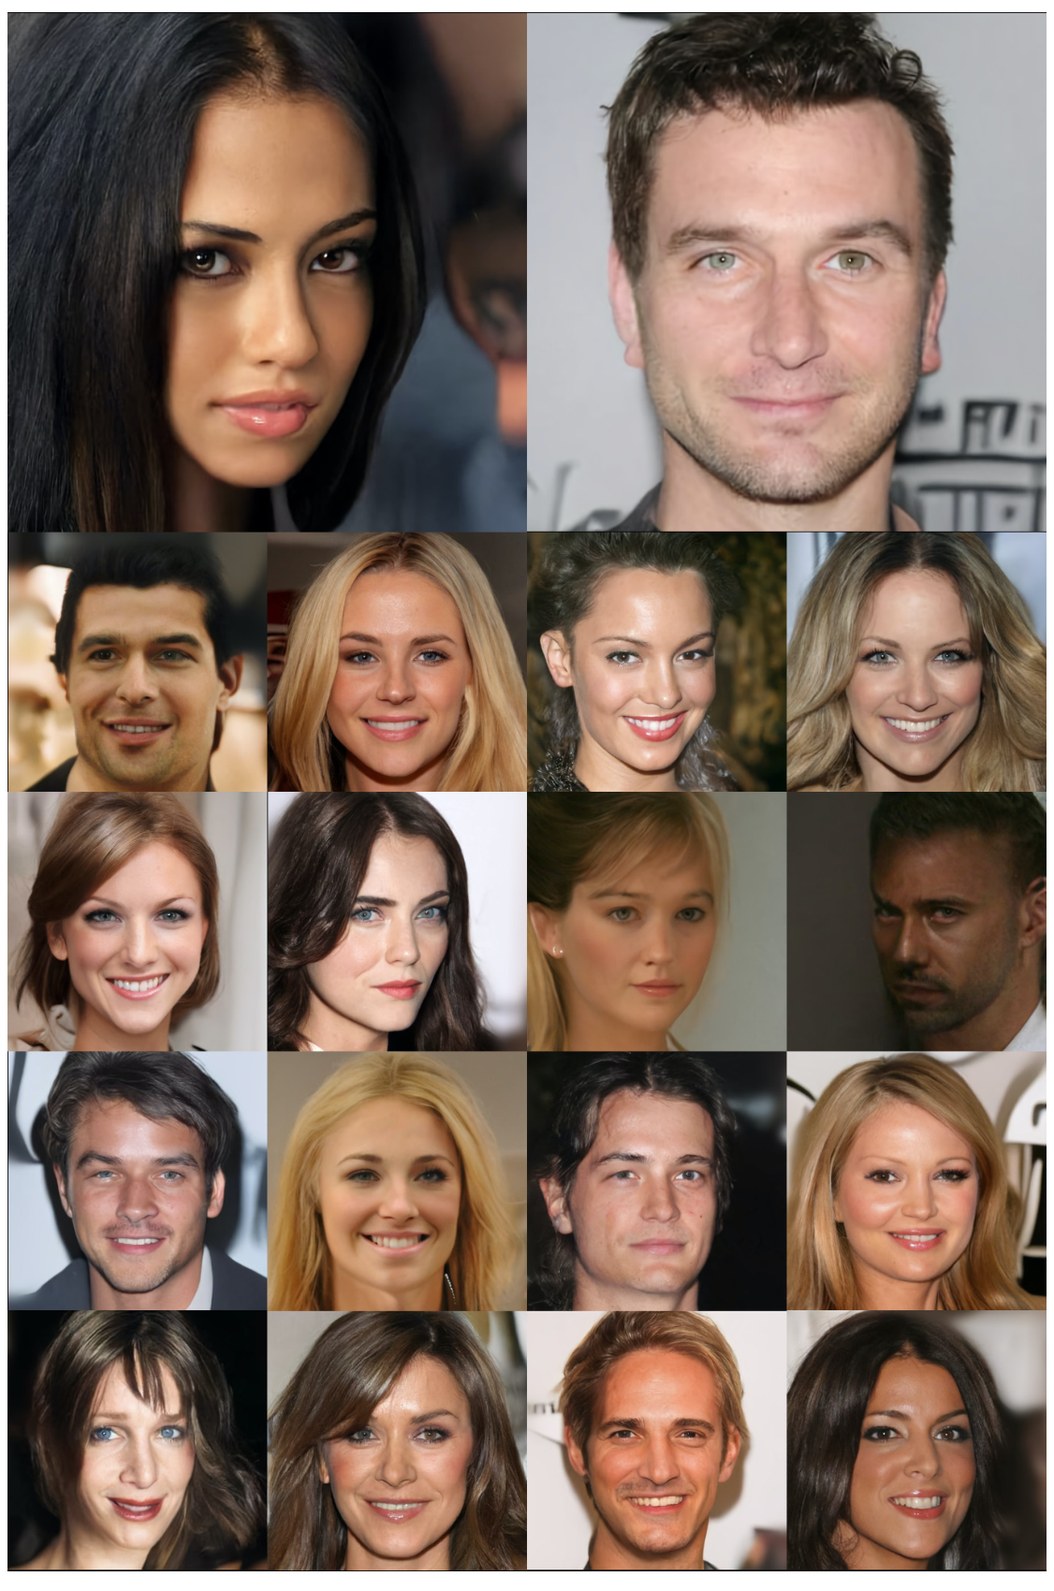
Figure 12: Samples on CelebA-HQ from a modified NCSN++ model trained with the VE SDE.
图 12:用 VE SDE 训练的改进版 NCSN++ 模型在 CelebA-HQ 上的样本。
H.2 Results on CIFAR-10
H.2 CIFAR-10 上的结果
All architecture components introduced above can improve the performance of score-based models trained with VE SDEs, as shown in Fig. 10. The box plots demonstrate the importance of each component when other components can vary freely. On both CIFAR-10 and CelebA, the additional components that we explored always improve the performance on average for VE SDEs. For progressive growing, it is not clear which combination of configurations consistently performs the best, but the results are typically better than when no progressive growing architecture is used. Our best score-based model for VE SDEs 1) uses FIR upsampling/downsampling, 2) rescales skip connections, 3) employs BigGAN-type residual blocks, 4) uses 4 residual blocks per resolution instead of 2, and 5) uses “residual” for input and no progressive growing architecture for output. We name this model “NCSN++”, following the naming convention of previous SMLD models (Song & Ermon, 2019; Song & Ermon, 2020).
上面引入的全部结构组件都可以改进用 VE SDE 训练的分数模型,如图 10 所示。箱线图展示了在其他组件可以自由变化时,每一个组件有多重要。在 CIFAR-10 和 CelebA 上,我们探索的这些额外组件对 VE SDE 的平均表现总是有帮助。对渐进式增长而言,尚不清楚哪一种配置组合能始终最好,但结果通常好于完全不使用渐进结构。VE SDE 上我们最好的分数模型:(1)使用 FIR 上/下采样;(2)重新缩放跳跃连接;(3)采用 BigGAN 式残差块;(4)每个分辨率用 4 个残差块而不是 2 个;(5)输入用“residual”,输出不用渐进结构。沿用先前 SMLD 模型的命名习惯(Song & Ermon, 2019; Song & Ermon, 2020),我们把这一模型称为“NCSN++”。
We followed a similar procedure to examine these architecture components for VP SDEs, except that we skipped experiments on CelebA due to limited computing resources. The NCSN++ architecture worked decently well for VP SDEs, ranked 4th place over all 144 possible configurations. The top configuration, however, has a slightly different structure, which uses no FIR upsampling/downsampling and no progressive growing architecture compared to NCSN++. We name this model “DDPM++”, following the naming convention of Ho et al. (2020).
我们用类似的程序检查了这些结构组件对 VP SDE 的作用,只是由于计算资源有限,跳过了 CelebA 上的实验。NCSN++ 结构在 VP SDE 上也相当不错,在全部 144 种可能配置中排第 4。不过,最好的配置结构稍有不同:与 NCSN++ 相比,它既不用 FIR 上/下采样,也不用渐进结构。沿用 Ho et al. (2020) 的命名习惯,我们把这一模型称为“DDPM++”。
The basic NCSN++ model with 4 residual blocks per resolution achieves an FID of 2.45 on CIFAR-10, whereas the basic DDPM++ model achieves an FID of 2.78. Here in order to match the convention used in Karras et al. (2018); Song & Ermon (2019) and Ho et al. (2020), we report the lowest FID value over the course of training, rather than the average FID value over checkpoints after 0.5M iterations (used for comparing different models of VE SDEs) or between 0.25M and 0.5M iterations (used for comparing VP SDE models) in our architecture exploration.
每个分辨率 4 个残差块的基本 NCSN++ 模型在 CIFAR-10 上做到 FID 2.45,基本 DDPM++ 模型则做到 2.78。这里为了与 Karras et al. (2018)、Song & Ermon (2019) 以及 Ho et al. (2020) 的惯例对齐,我们报告的是训练过程中最低的 FID,而不是结构探索里所用的平均值——后者对 VE SDE 是 50 万次迭代之后各检查点的平均 FID,对 VP SDE 则是 25 万到 50 万次迭代之间的平均 FID。
Switching from discrete training objectives to continuous ones in Eq. 7 further improves the FID values for all SDEs. To condition the NCSN++ model on continuous time variables, we change positional embeddings, the layers in Ho et al. (2020) for conditioning on discrete time steps, to random Fourier feature embeddings (Tancik et al., 2020). The scale parameter of these random Fourier feature embeddings is fixed to 16. We also reduce the number of training iterations to 0.95M to suppress overfitting. These changes improve the FID on CIFAR-10 from 2.45 to 2.38 for NCSN++ trained with the VE SDE, resulting in a model called “NCSN++ cont.”. In addition, we can further improve the FID from 2.38 to 2.20 by doubling the number of residual blocks per resolution for NCSN++ cont., resulting in the model denoted as “NCSN++ cont. (deep)”. All quantitative results are summarized in Table 3, and we provide random samples from our best model in Fig. 11.
从离散训练目标改到式 7 的连续目标,还会进一步提高所有 SDE 的 FID。为了让 NCSN++ 模型以连续时间变量为条件,我们把 Ho et al. (2020) 中用于离散时间步条件化的位置嵌入,改成随机傅里叶特征嵌入(Tancik et al., 2020)。这些随机傅里叶特征嵌入的尺度参数固定为 16。我们还把训练迭代次数减到 95 万,以抑制过拟合。这些改动把用 VE SDE 训练的 NCSN++ 在 CIFAR-10 上的 FID 从 2.45 降到 2.38,得到的模型称为“NCSN++ cont.”。此外,再把 NCSN++ cont. 每个分辨率的残差块数目加倍,可以把 FID 从 2.38 进一步降到 2.20,得到记为“NCSN++ cont.(deep)”的模型。全部定量结果汇总在表 3,图 11 给出了我们最好模型的随机样本。
Similarly, we can also condition the DDPM++ model on continuous time steps, resulting in a model “DDPM++ cont.”. When trained with the VP SDE, it improves the FID of 2.78 from DDPM++ to 2.55. When trained with the sub-VP SDE, it achieves an FID of 2.61. To get better performance, we used the Euler-Maruyama solver as the predictor for continuously-trained models, instead of the ancestral sampling predictor or the reverse diffusion predictor. This is because the discretization strategy of the original DDPM method does not match the variance of the continuous process well when , which significantly hurts FID scores. As shown in Table 2, the likelihood values are 3.21 and 3.05 bits/dim for VP and sub-VP SDEs respectively. Doubling the depth, and trainin with 0.95M iterations, we can improve both FID and bits/dim for both VP and sub-VP SDEs, leading to a model “DDPM++ cont. (deep)”. Its FID score is 2.41, same for both VP and sub-VP SDEs. When trained with the sub-VP SDE, it can achieve a likelihood of 2.99 bits/dim. Here all likelihood values are reported for the last checkpoint during training.
类似地,我们也可以让 DDPM++ 模型以连续时间步为条件,得到模型“DDPM++ cont.”。用 VP SDE 训练时,它把 DDPM++ 的 FID 从 2.78 降到 2.55;用 sub-VP SDE 训练时,FID 为 2.61。为取得更好表现,对连续训练的模型,我们用欧拉–丸山求解器作为预测器,而不再用祖先采样或反向扩散预测器。这是因为原来 DDPM 方法的离散化策略,在 时与连续过程的方差匹配得不好,会显著损害 FID。如表 2 所示,VP 和 sub-VP SDE 的似然分别是 3.21 和 3.05 bits/dim。把深度加倍,并训练 95 万次迭代,可以同时改进 VP 和 sub-VP SDE 的 FID 与 bits/dim,得到模型“DDPM++ cont.(deep)”。它的 FID 为 2.41,对 VP 和 sub-VP SDE 相同。用 sub-VP SDE 训练时,似然可以做到 2.99 bits/dim。这里报告的全部似然值,都针对训练过程中的最后一个检查点。
H.3 High resolution images
H.3 高分辨率图像
Encouraged by the success of NCSN++ on CIFAR-10, we proceed to test it on CelebA-HQ (Karras et al., 2018), a task that was previously only achievable by some GAN models and VQ-VAE-2 (Razavi et al., 2019). We used a batch size of 8, increased the EMA rate to 0.9999, and trained a model similar to NCSN++ with the continuous objective (Eq. 7) for around 2.4M iterations (please find the detailed architecture in our code release.) We use the PC sampler discretized at 2000 steps with the reverse diffusion predictor, one Langevin step per predictor update and a signal-to-noise ratio of 0.15. The scale parameter for the random Fourier feature embeddings is fixed to 16. We use the “input skip” progressive architecture for the input, and “output skip” progressive architecture for the output. We provide samples in Fig. 12. Although these samples are not perfect (e.g., there are visible flaws on facial symmetry), we believe these results are encouraging and can demonstrate the scalability of our approach. Future work on more effective architectures are likely to significantly advance the performance of score-based generative models on this task.
受到 NCSN++ 在 CIFAR-10 上成功的鼓舞,我们接着在 的 CelebA-HQ(Karras et al., 2018)上测试它——此前这一任务只有部分 GAN 模型和 VQ-VAE-2(Razavi et al., 2019)能够完成。我们使用批量 8,把 EMA 速率提高到 0.9999,并用连续目标(式 7)训练了一个与 NCSN++ 相近的模型,大约 240 万次迭代(详细结构见我们发布的代码)。采样使用在 2000 步上离散化的 PC 采样器,预测器为反向扩散,预测器每更新一次做一步 Langevin,信噪比为 0.15。随机傅里叶特征嵌入的尺度参数固定为 16。输入采用“input skip”渐进结构,输出采用“output skip”渐进结构。样本见图 12。尽管这些样本并不完美(例如,面部对称性上有可见缺陷),我们仍认为这些结果令人鼓舞,并能够说明本方法的可扩展性。未来若有更有效的结构,很可能会显著推进分数生成模型在这一任务上的表现。
Appendix I Controllable generation
附录 I 可控生成
Consider a forward SDE with the following general form
考虑如下一般形式的正向 SDE
and suppose the initial state distribution is . The density at time is when conditioned on . Therefore, using Anderson (1982), the reverse-time SDE is given by
并假设初始状态分布为 。以 为条件时,时刻 的密度是 。因此,根据 Anderson (1982),时间反向 SDE 由下式给出
\displaystyle\resizebox{23965562}{}{$\displaystyle\mathrm{d}\mathbf{x}=\{\mathbf{f}(\mathbf{x},t)-\nabla\cdot[\mathbf{G}(\mathbf{x},t)\mathbf{G}(\mathbf{x},t)^{\mkern-1.5mu\mathsf{T}}]-\mathbf{G}(\mathbf{x},t)\mathbf{G}(\mathbf{x},t)^{\mkern-1.5mu\mathsf{T}}\nabla_{\mathbf{x}}\log p_{t}(\mathbf{x}\mid\mathbf{y})\}\mathrm{d}t+\mathbf{G}(\mathbf{x},t)\mathrm{d}\bar{\mathbf{w}}$}. \tag{48}
Since , the score can be computed easily by
由于 ,分数 可以很容易地由下式计算
This subsumes the conditional reverse-time SDE in Eq. 14 as a special case. All sampling methods we have discussed so far can be applied to the conditional reverse-time SDE for sample generation.
这把式 14 中的条件时间反向 SDE 作为特殊情形包含了进来。到目前为止讨论过的全部采样方法,都可以用到这条条件时间反向 SDE 上来生成样本。
I.1 Class-conditional sampling
I.1 类别条件采样
When represents class labels, we can train a time-dependent classifier for class-conditional sampling. Since the forward SDE is tractable, we can easily create a pair of training data by first sampling from a dataset and then obtaining . Afterwards, we may employ a mixture of cross-entropy losses over different time steps, like Eq. 7, to train the time-dependent classifier .
当 表示类别标签时,可以训练一个随时间变化的分类器 来做类别条件采样。由于正向 SDE 是可计算的,我们可以先从数据集中抽取 ,再得到 ,从而轻易构造训练数据对 。随后,可以像式 7 那样,把不同时间步上的交叉熵损失混合起来,训练 。
To test this idea, we trained a Wide ResNet (Zagoruyko & Komodakis, 2016) (Wide-ResNet-28-10) on CIFAR-10 with VE perturbations. The classifier is conditioned on using random Fourier features (Tancik et al., 2020), and the training objective is a simple sum of cross-entropy losses sampled at different scales. We provide a plot to show the accuracy of this classifier over noise scales in Fig. 13. The score-based model is an unconditional NCSN++ (4 blocks/resolution) in Table 3, and we generate samples using the PC algorithm with 2000 discretization steps. The class-conditional samples are provided in Fig. 4, and an extended set of conditional samples is given in Fig. 13.
为检验这一想法,我们在带 VE 扰动的 CIFAR-10 上训练了一个 Wide ResNet(Zagoruyko & Komodakis, 2016)(Wide-ResNet-28-10)。分类器通过随机傅里叶特征(Tancik et al., 2020)以 为条件,训练目标就是在不同尺度上采样的交叉熵损失之和。图 13 给出了这一分类器随噪声尺度变化的准确率曲线。分数模型是表 3 中的无条件 NCSN++(每个分辨率 4 个块),我们用离散化为 2000 步的 PC 算法生成样本。类别条件样本见图 4,更完整的一组条件样本见图 13。
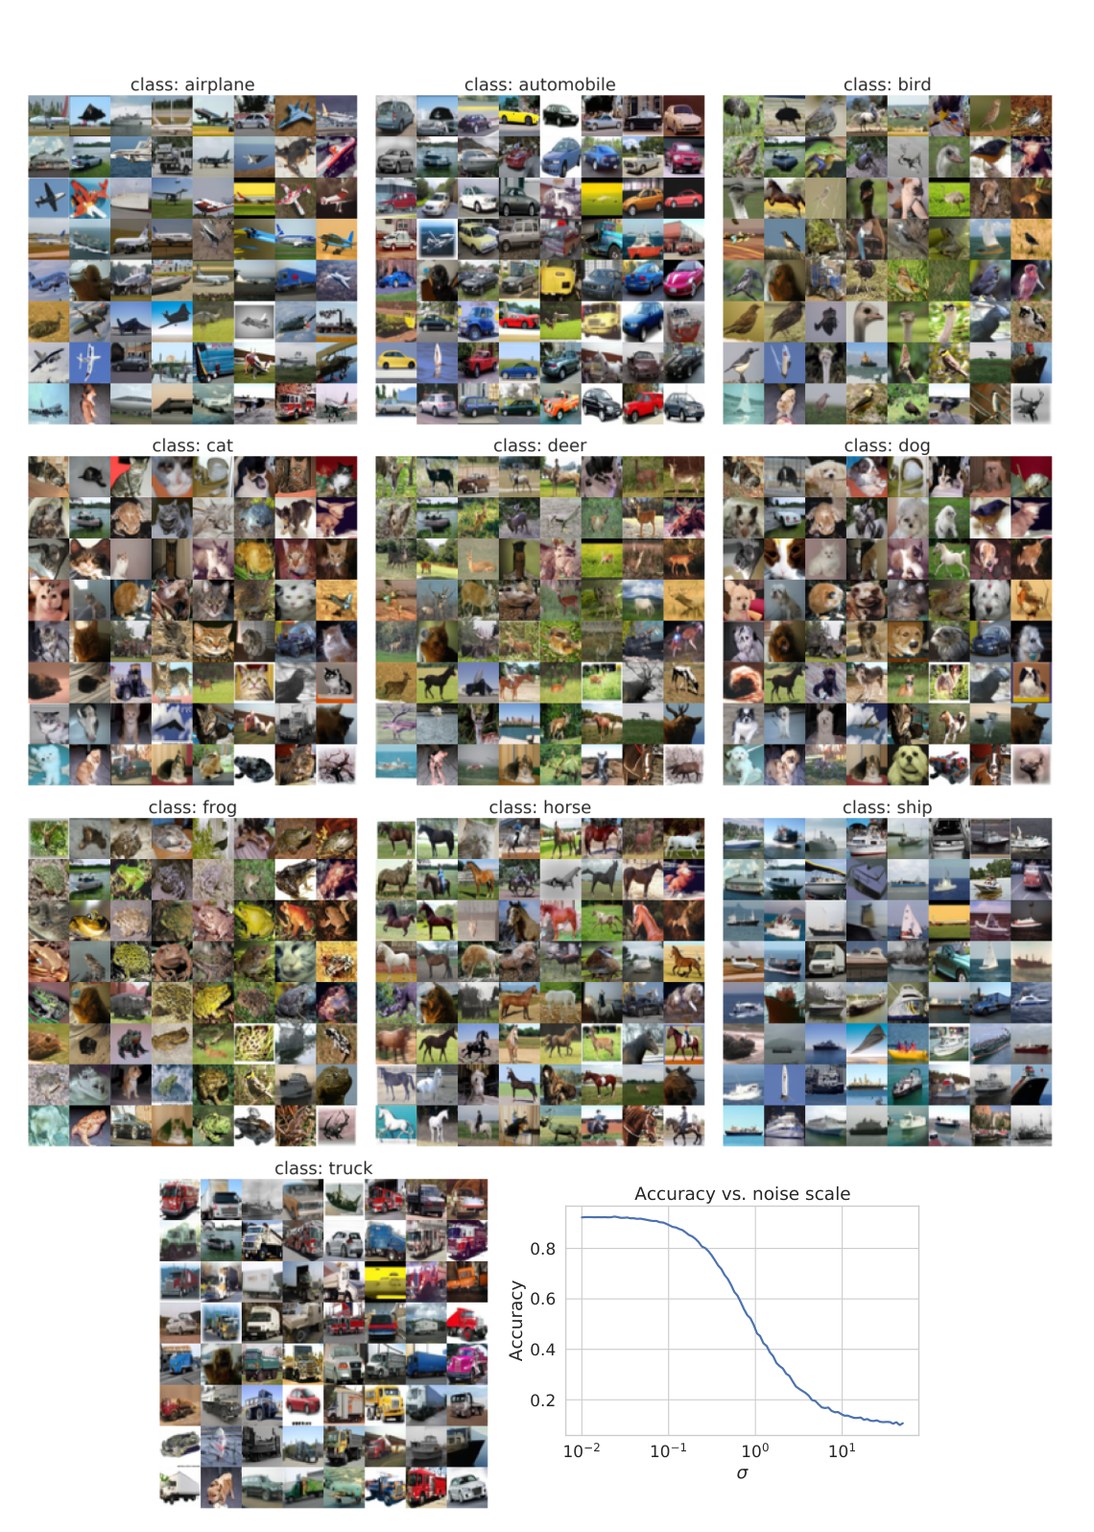
Figure 13: Class-conditional image generation by solving the conditional reverse-time SDE with PC. The curve shows the accuracy of our noise-conditional classifier over different noise scales.
图 13:用 PC 求解条件时间反向 SDE,做类别条件图像生成。曲线给出我们的噪声条件分类器在不同噪声尺度上的准确率。
I.2 Imputation
I.2 补全
Imputation is a special case of conditional sampling. Denote by and the known and unknown dimensions of respectively, and let and denote and restricted to the unknown dimensions. For VE/VP SDEs, the drift coefficient is element-wise, and the diffusion coefficient is diagonal. When is element-wise, denotes the same element-wise function applied only to the unknown dimensions. When is diagonal, denotes the sub-matrix restricted to unknown dimensions.
补全是条件采样的一种特殊情形。分别用 和 表示 的已知维和未知维,并用 和 表示限制在未知维上的 和 。对 VE/VP SDE,漂移系数 是逐元素的,扩散系数 是对角的。当 逐元素时, 表示只作用在未知维上的同一个逐元素函数;当 对角时, 表示限制在未知维上的子矩阵。
For imputation, our goal is to sample from . Define a new diffusion process , and note that the SDE for can be written as
对补全而言,我们的目标是从 中采样。定义一个新的扩散过程 ,并注意 的 SDE 可以写成
The reverse-time SDE, conditioned on , is given by
以 为条件的时间反向 SDE 由下式给出
$$\mathrm{d}\mathbf{z}=\big{\mathbf{f}{\bar{\Omega}}(\mathbf{z},t)-\nabla\cdot[\mathbf{G}{{\bar{\Omega}}}(\mathbf{z},t)\mathbf{G}{{\bar{\Omega}}}(\mathbf{z},t)^{\mkern-1.5mu\mathsf{T}}]\
-\mathbf{G}{\bar{\Omega}}(\mathbf{z},t)\mathbf{G}{\bar{\Omega}}(\mathbf{z},t)^{\mkern-1.5mu\mathsf{T}}\nabla{\mathbf{z}}\log p_{t}(\mathbf{z}\mid\Omega(\mathbf{z}(0))=\mathbf{y})\big}\mathrm{d}t+\mathbf{G}_{\bar{\Omega}}(\mathbf{z},t)\mathrm{d}\bar{\mathbf{w}}.$$
Although is in general intractable, it can be approximated. Let denote the event . We have
尽管 一般不可计算,但可以近似。令 表示事件 。我们有
where is a random sample from , which is typically a tractable distribution. Therefore,
其中 是来自 的一个随机样本,而后者通常是可计算的分布。因此,
where denotes a vector such that and , and the identity holds because .
其中 表示满足 且 的向量 ,等式成立是因为 。
We provided an extended set of inpainting results in Figs. 14 and 15.
我们在图 14 和图 15 中给出了更完整的一组补全结果。
I.3 Colorization
I.3 上色
Colorization is a special case of imputation, except that the known data dimensions are coupled. We can decouple these data dimensions by using an orthogonal linear transformation to map the gray-scale image to a separate channel in a different space, and then perform imputation to complete the other channels before transforming everything back to the original image space. The orthogonal matrix we used to decouple color channels is
上色是补全的一种特殊情形,只是已知的数据维是耦合的。我们可以用一个正交线性变换,把灰度图像映射到另一空间中单独的一个通道,从而把这些维解开,再补全其余通道,最后把一切变回原来的图像空间。我们用来解开颜色通道的正交矩阵是
$$\displaystyle\begin{pmatrix}0.577&-0.816&0\
0.577&0.408&0.707\
0.577&0.408&-0.707\
\end{pmatrix}.$$
Because the transformations are all orthogonal matrices, the standard Wiener process will still be a standard Wiener process in the transformed space, allowing us to build an SDE and use the same imputation method in Section I.2. We provide an extended set of colorization results in Figs. 16 and 17.
因为这些变换都是正交矩阵,标准 Wiener 过程 在变换后的空间里仍然是标准 Wiener 过程,从而使我们能够建立一条 SDE,并使用第 I.2 节中同样的补全方法。图 16 和图 17 给出了更完整的一组上色结果。
I.4 Solving general inverse problems
I.4 求解一般反问题
Suppose we have two random variables and , and we know the forward process of generating from , given by . The inverse problem is to obtain from , that is, generating samples from . In principle, we can estimate the prior distribution and obtain using Bayes’ rule: . In practice, however, both estimating the prior and performing Bayesian inference are non-trivial.
假设我们有两个随机变量 和 ,并且知道从 生成 的正向过程,由 给出。反问题是从 得到 ,也就是从 中生成样本。原则上,可以估计先验分布 ,再用贝叶斯法则得到 。但在实践中,估计先验和做贝叶斯推断都不轻松。
Leveraging Eq. 48, score-based generative models provide one way to solve the inverse problem. Suppose we have a diffusion process generated by perturbing with an SDE, and a time-dependent score-based model trained to approximate . Once we have an estimate of , we can simulate the reverse-time SDE in Eq. 48 to sample from . To obtain this estimate, we first observe that
借助式 48,基于分数的生成模型提供了一种求解反问题的途径。假设我们有一个扩散过程 ,它通过用一条 SDE 扰动 得到,并且有一个随时间变化的分数模型 被训练来近似 。一旦有了 的估计,就可以模拟式 48 中的时间反向 SDE,从 中采样。为得到这一估计,我们首先观察到
where is defined via and the forward process . Now assume two conditions:
其中 由 和正向过程 定义。现在假定两个条件:
- • is tractable. We can often derive this distribution from the interaction between the forward process and the SDE, like in the case of image imputation and colorization.
- • 是可计算的。我们常常可以从正向过程与 SDE 的相互作用中导出这一分布,就像图像补全和上色的情形那样。
- • . For small , is almost the same as so the approximation holds. For large , becomes further away from in the Markov chain, and thus have smaller impact on . Moreover, the approximation error for large matter less for the final sample, since it is used early in the sampling process.
- • 。当 较小时, 与 几乎相同,因而近似成立;当 较大时, 在马尔可夫链上离 更远,因而对 的影响更小。而且,大 时的近似误差对最终样本的影响也更小,因为它用在采样过程的较早阶段。
Given these two assumptions, we have
在这两个假定之下,我们有
where is a sample from . Now we can plug Eq. 50 into Eq. 48 and solve the resulting reverse-time SDE to generate samples from .
其中 是来自 的一个样本。现在可以把式 50 代入式 48,并求解得到的时间反向 SDE,从而从 中生成样本。
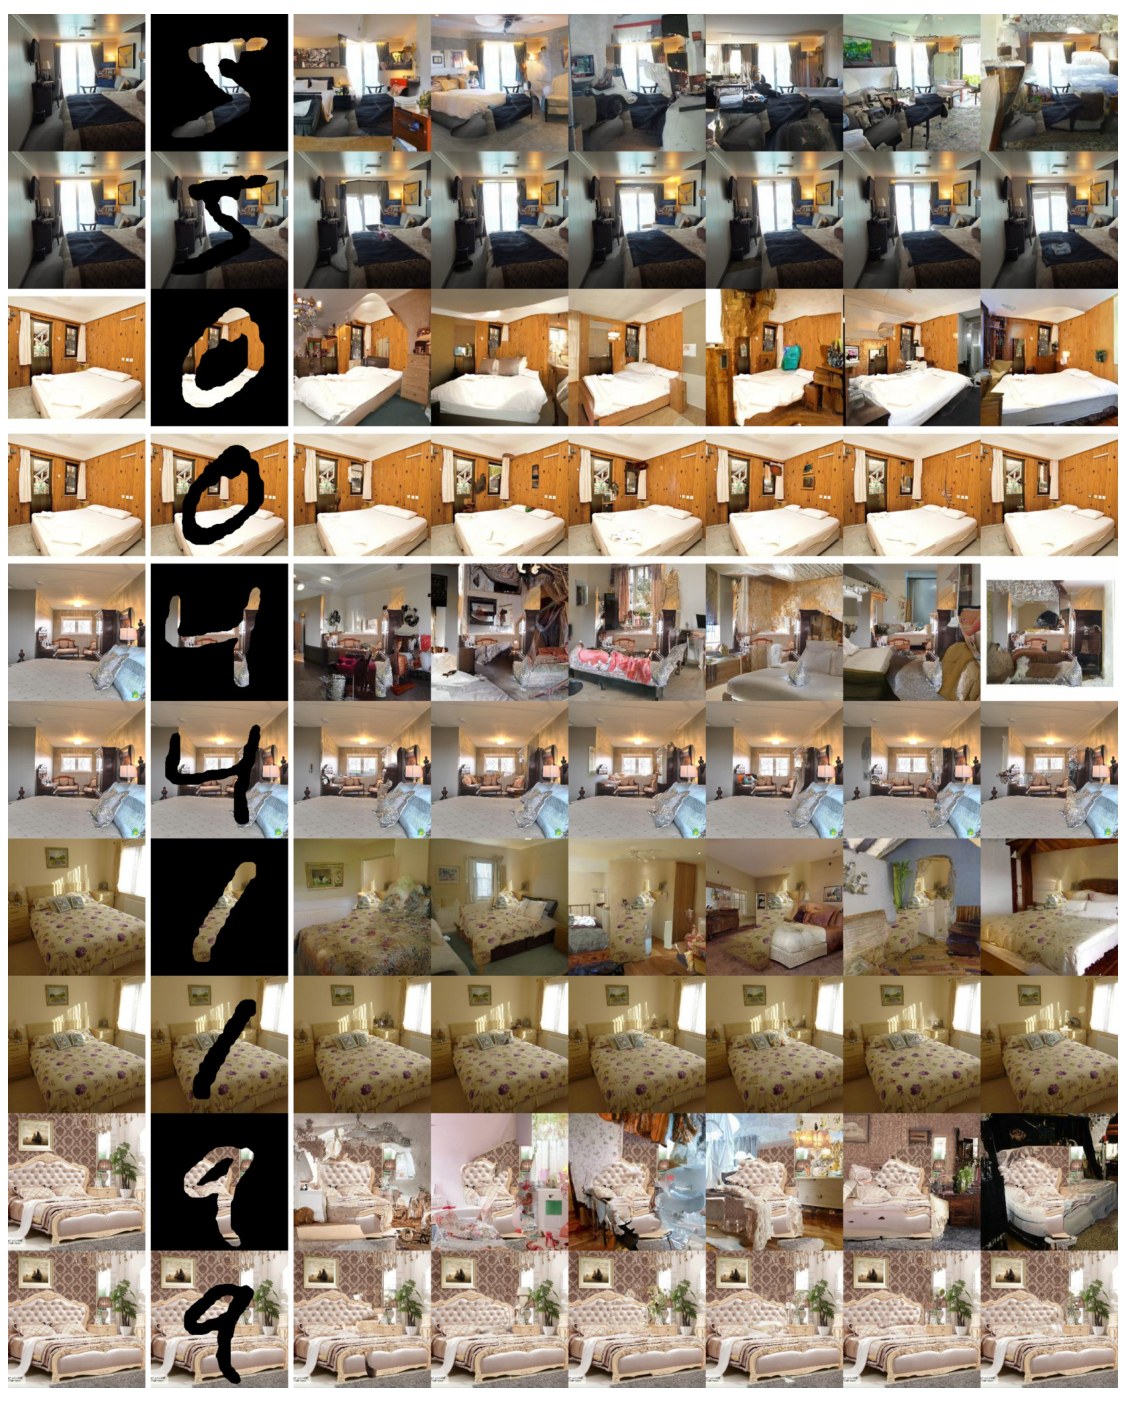
Figure 14: Extended inpainting results for bedroom images.
图 14: 卧室图像上的扩展补全结果。
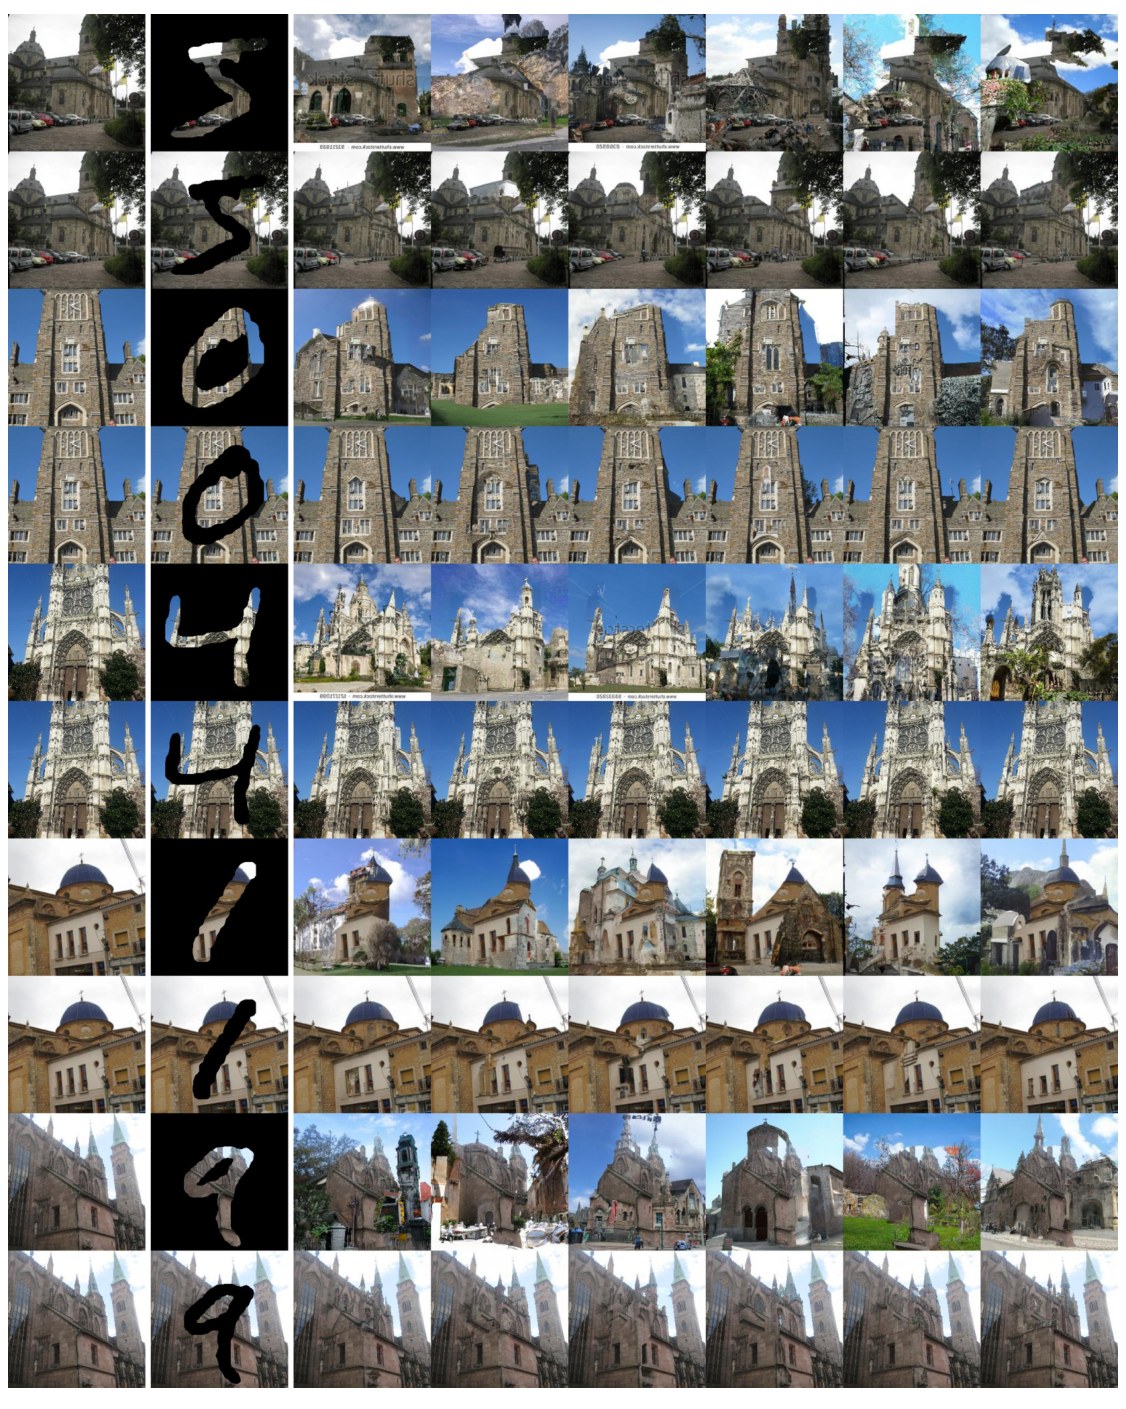
Figure 15: Extended inpainting results for church images.
图 15: 教堂图像上的扩展补全结果。
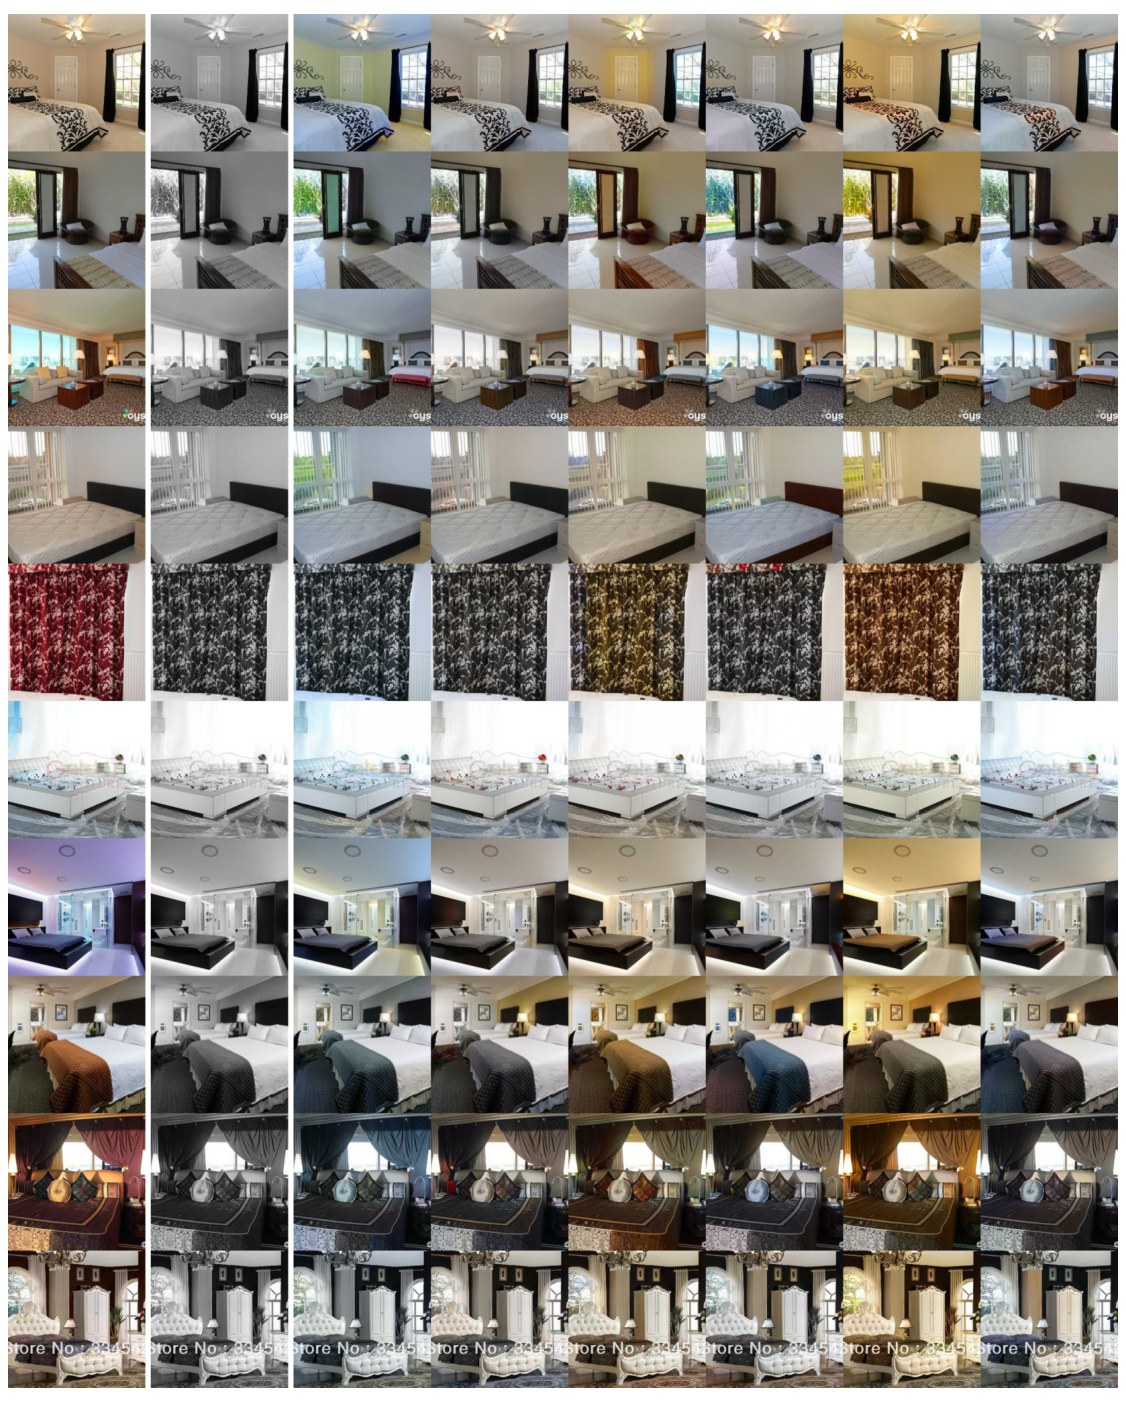
Figure 16: Extended colorization results for bedroom images.
图 16: 卧室图像上的扩展上色结果。
Figure 17: Extended colorization results for church images.
图 17: 教堂图像上的扩展上色结果。