Scaling Laws for Neural Language Models
Scaling Laws for Neural Language Models
神经语言模型的缩放定律(Scaling Laws for Neural Language Models)
Jared Kaplan † † thanks: Equal contribution. Contributions: Jared Kaplan and Sam McCandlish led the research. Tom Henighan contributed the LSTM experiments. Tom Brown, Rewon Child, and Scott Gray, and Alec Radford developed the optimized Transformer implementation. Jeff Wu, Benjamin Chess, and Alec Radford developed the text datasets. Dario Amodei provided guidance throughout the project. Affiliation: Johns Hopkins University, OpenAI Email: jaredk@jhu.edu Sam McCandlish ∗ Affiliation: OpenAI Email: sam@openai.com Tom Henighan Affiliation: OpenAI Email: henighan@openai.com Tom B. Brown Affiliation: OpenAI Email: tom@openai.com Benjamin Chess Affiliation: OpenAI Email: bchess@openai.com Rewon Child Affiliation: OpenAI Email: rewon@openai.com Scott Gray Affiliation: OpenAI Email: scott@openai.com Alec Radford Affiliation: OpenAI Email: alec@openai.com Jeffrey Wu Affiliation: OpenAI Email: jeffwu@openai.com Dario Amodei Affiliation: OpenAI Email: damodei@openai.com
Jared Kaplan* Sam McCandlish* Tom Henighan Tom B. Brown Benjamin Chess Rewon Child Scott Gray Alec Radford Jeffrey Wu Dario Amodei
所属机构:Johns Hopkins University;OpenAI
- 同等贡献。Kaplan 与 McCandlish 主导研究;Henighan 贡献 LSTM 实验;Brown、Child、Gray、Radford 开发优化 Transformer 实现;Wu、Chess、Radford 开发文本数据集;Amodei 提供全程指导。
Abstract
摘要
We study empirical scaling laws for language model performance on the cross-entropy loss. The loss scales as a power-law with model size, dataset size, and the amount of compute used for training, with some trends spanning more than seven orders of magnitude. Other architectural details such as network width or depth have minimal effects within a wide range. Simple equations govern the dependence of overfitting on model/dataset size and the dependence of training speed on model size. These relationships allow us to determine the optimal allocation of a fixed compute budget. Larger models are significantly more sample-efficient, such that optimally compute-efficient training involves training very large models on a relatively modest amount of data and stopping significantly before convergence.
我们研究语言模型在交叉熵损失上的经验缩放定律。损失随模型规模、数据集规模与训练所用算力呈幂律缩放,部分趋势跨越超过七个数量级。网络宽度或深度等其他架构细节在相当宽的范围内影响很小。简单方程刻画了过拟合对模型/数据规模的依赖,以及训练速度对模型规模的依赖。据此可确定固定算力预算的最优分配。更大的模型显著更样本高效,因此算力最优的训练方式是:在相对适中的数据量上训练非常大的模型,并在远未收敛时显著提前停止。
1 Introduction
1 引言
Contents
Language provides a natural domain for the study of artificial intelligence, as the vast majority of reasoning tasks can be efficiently expressed and evaluated in language, and the world’s text provides a wealth of data for unsupervised learning via generative modeling. Deep learning has recently seen rapid progress in language modeling, with state of the art models [RNSS18, DCLT18, YDY+19, LOG+19, RSR+19] approaching human-level performance on many specific tasks [WPN+19], including the composition of coherent multi-paragraph prompted text samples [RWC+19].
从一开始就是《公约》缔约国。
语言为人工智能的研究提供了自然领域,因为绝大多数推理任务可以用语言有效表达和评价,世界文本通过生成模型学为无监督的学习提供了丰富的数据. 深度学习近来在语言建模方面迅速取得进展,最先进的艺术模型[RNSS18,DCLT18,YDY+19,LOG+19,RSR+19]在许多具体任务上接近人类层面的性能[WPN+19],包括连贯多段激发文本样本的构成[RWC+19].
One might expect language modeling performance to depend on model architecture, the size of neural models, the computing power used to train them, and the data available for this training process. In this work we will empirically investigate the dependence of language modeling loss on all of these factors, focusing on the Transformer architecture [VSP+17, LSP+18]. The high ceiling and low floor for performance on language tasks allows us to study trends over more than seven orders of magnitude in scale.
人们可能期望语言建模的性能取决于模型架构,神经模型的大小,用来训练这些模型的计算力,以及这个训练过程可用的数据. 在这项工作中,我们将实证地调查语言模型丢失对所有这些因素的依赖性,重点是Transformer架构[VSP+17,LSP+18]. 语文任务执行的上限高,下限低,使我们能够研究七个以上规模的趋势。
Throughout we will observe precise power-law scalings for performance as a function of training time, context length, dataset size, model size, and compute budget.
在整个过程中,我们将根据训练时间、背景长度、数据集大小、模型大小和预算计算情况,对业绩进行精确的电法缩放。
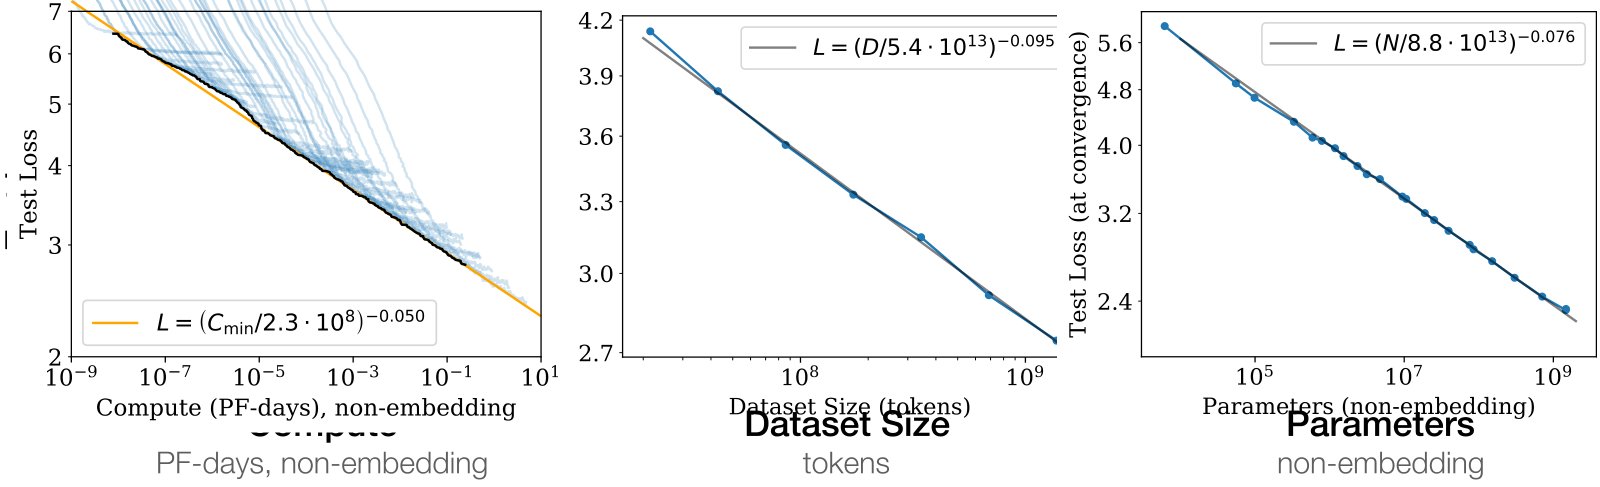
Figure 1: Language modeling performance improves smoothly as we increase the model size, datasetset size, and amount of compute[^1] used for training. For optimal performance all three factors must be scaled up in tandem. Empirical performance has a power-law relationship with each individual factor when not bottlenecked by the other two.
图1:随着我们增加模型大小,数据集大小,以及用于培训的计算量[^1],语言模型的性能得到顺利改善. 为了取得最佳业绩,所有三个因素都必须同步扩大。 经验性表现在不受到其他两个因素的束缚时,与每个个体因素都有幂律关系.
1.1 Summary
1.1 总结
Our key findings for Transformer language models are are as follows:
我们对变形语模式的主要发现如下:
Performance depends strongly on scale, weakly on model shape:
Model performance depends most strongly on scale, which consists of three factors: the number of model parameters (excluding embeddings), the size of the dataset , and the amount of compute used for training. Within reasonable limits, performance depends very weakly on other architectural hyperparameters such as depth vs. width. (Section 3)
性能主要取决于规模,弱于模型形状:
模型性能最依赖于尺度,由三个因素组成:模型参数(不包括嵌入)的数量,数据集的大小,以及用于培训的计算的金额. 在合理的限度内,性能非常弱依赖于其他建筑超参数,如深度对宽度. (第3节)
Smooth power laws:
Performance has a power-law relationship with each of the three scale factors when not bottlenecked by the other two, with trends spanning more than six orders of magnitude (see Figure 1). We observe no signs of deviation from these trends on the upper end, though performance must flatten out eventually before reaching zero loss. (Section 3)
平滑幂律:
性能与的三个尺度因子在不受其他两个因子的束缚时,每个因子都具有幂律关系,其趋势超过六个规模(见图1)。 我们没有观察到在上端偏离这些趋势的迹象,尽管在达到零损失之前,业绩必须最终平息下来。 (第3节)
Universality of overfitting:
Performance improves predictably as long as we scale up and in tandem, but enters a regime of diminishing returns if either or is held fixed while the other increases. The performance penalty depends predictably on the ratio , meaning that every time we increase the model size 8x, we only need to increase the data by roughly 5x to avoid a penalty. (Section 4)
- 过于适应的普遍性:
只要我们同步扩大和,性能就可以预测得到改善,但如果或被固定,而其他增加则进入递减回报的制度。 性能处罚可以预测取决于的比例,这意味着每次增加模型尺寸8x,我们只需要增加大约5x的数据来避免惩罚. (第4节)
Universality of training:
Training curves follow predictable power-laws whose parameters are roughly independent of the model size. By extrapolating the early part of a training curve, we can roughly predict the loss that would be achieved if we trained for much longer. (Section 5)
培训的普遍性:
训练曲线遵循可预测的幂律,其参数大致独立于模型大小。 通过推断一个训练曲线的早期部分,我们可以大致预测如果我们训练更长的时间将会实现的损失. (第5节)
Transfer improves with test performance:
When we evaluate models on text with a different distribution than they were trained on, the results are strongly correlated to those on the training validation set with a roughly constant offset in the loss – in other words, transfer to a different distribution incurs a constant penalty but otherwise improves roughly in line with performance on the training set. (Section 3.2.2)
QQ 传输随着测试性能的改善:
当我们对文本促成了不同分布的模型进行评估时,结果与培训鉴定组的模型有着密切的联系,而且损失被大致固定地抵消了,换句话说,转移到不同分布的模型将不断受到惩罚,但除此之外,结果与培训组的绩效大致相符。 (第3.2.2节)
Sample efficiency:
Large models are more sample-efficient than small models, reaching the same level of performance with fewer optimization steps (Figure 2) and using fewer data points (Figure 4).
- 样本效率:
大型模型比小型模型更具有样本效率,以较少的优化步骤(图2)达到相同的性能水平,并使用较少的数据点(图4).
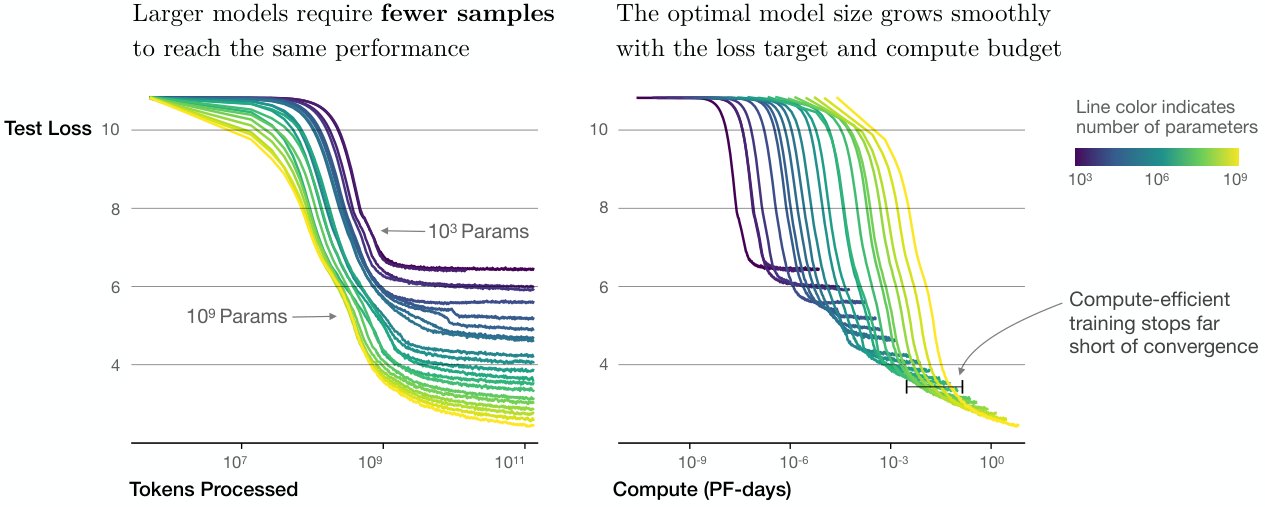
Figure 2: We show a series of language model training runs, with models ranging in size from to parameters (excluding embeddings).
图2:我们显示了一系列语言模型训练运行,模型大小从到参数(不包括嵌入)不等.
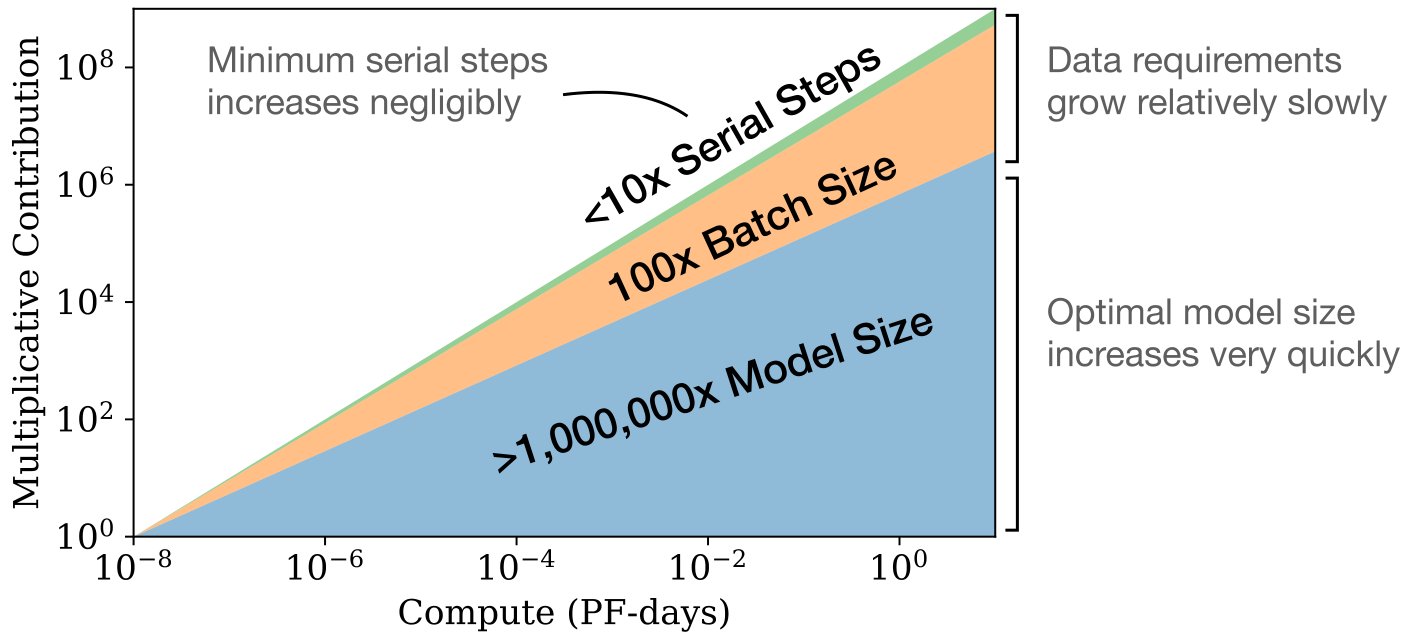
Figure 3: As more compute becomes available, we can choose how much to allocate towards training larger models, using larger batches, and training for more steps. We illustrate this for a billion-fold increase in compute. For optimally compute-efficient training, most of the increase should go towards increased model size. A relatively small increase in data is needed to avoid reuse. Of the increase in data, most can be used to increase parallelism through larger batch sizes, with only a very small increase in serial training time required.
图3 随着更多的计算,我们可以选择分配多少用于培训更大的模型,使用更大的批次,以及培训更多的步骤。 我们用计算数的十亿倍来说明这一点。 为了优化计算效率的培训,增加的多数应增加模式规模。 为了避免重复使用,需要较少增加数据。 在增加的数据中,大多数可以通过较大的批量大小来增加并行性,只需要极小的增加序列训练时间.
Convergence is inefficient:
When working within a fixed compute budget but without any other restrictions on the model size or available data , we attain optimal performance by training very large models and stopping significantly short of convergence (see Figure 3). Maximally compute-efficient training would therefore be far more sample efficient than one might expect based on training small models to convergence, with data requirements growing very slowly as with training compute. (Section 6)
校对:Soup
当在固定计算预算范围内工作,但对模型大小或现有数据没有任何其他限制时,我们通过培训非常大的模型 和阻止* 严重缺乏趋同性* 来达到最佳性能(见图3)。 因此,最高效的计算培训的样本效率将远远高于基于培训小模式的预期,随着培训计算,数据要求增长非常缓慢。 (第6节)
Optimal batch size:
The ideal batch size for training these models is roughly a power of the loss only, and continues to be determinable by measuring the gradient noise scale [MKAT18]; it is roughly 1-2 million tokens at convergence for the largest models we can train. (Section 5.1)
最佳批量大小 :
欢迎各位来到美国, (第5.1节)
Taken together, these results show that language modeling performance improves smoothly and predictably as we appropriately scale up model size, data, and compute. We expect that larger language models will perform better and be more sample efficient than current models.
综合起来,这些结果表明,随着我们适当扩大模型大小、数据和计算,语言模型的性能可以顺利和预测地改进。 我们预计,更大的语言模型将比目前的模型发挥更好和更有效率的样本。
1.2 Summary of Scaling Laws
1.2 缩放定律摘要
The test loss of a Transformer trained to autoregressively model language can be predicted using a power-law when performance is limited by only either the number of non-embedding parameters , the dataset size , or the optimally allocated compute budget (see Figure 1):
当性能仅受非嵌入参数,数据集大小的限制,或者最优化分配的计算预算的限制时,可以使用幂律来预测测试器的丢失:
- For models with a limited number of parameters, trained to convergence on sufficiently large datasets: (1.1)
- For large models trained with a limited dataset with early stopping: (1.2)
- When training with a limited amount of compute, a sufficiently large dataset, an optimally-sized model, and a sufficiently small batch size (making optimal[^2] use of compute): (1.3)
- 对于参数数量有限的模型,经培训可在足够大的数据集上趋同:(1.1)
- 受过有限数据集培训并提前停止的大型模型:(1.2)
- 当训练使用有限的计算量时,一个足够大的数据集,一个最优化的大小模型和一个足够小的批量大小(使计算量得到最佳[^2]的使用): (1.3)
These relations hold across eight orders of magnitude in , six orders of magnitude in , and over two orders of magnitude in . They depend very weakly on model shape and other Transformer hyperparameters (depth, width, number of self-attention heads), with specific numerical values associated with the Webtext2 training set [RWC+19]. The power laws specify the degree of performance improvement expected as we scale up , , or ; for example, doubling the number of parameters yields a loss that is smaller by a factor . The precise numerical values of and depend on the vocabulary size and tokenization and hence do not have a fundamental meaning.
这些关系在有8个数量级,在有6个数量级,在有2个以上数量级。 它们非常微弱地依赖于模型形状和其他Transformer超参数(深度,宽度,自注意力头数),具体数值与Webtext2训练集[RWC+19]相关.我就用电法规定,当我们扩大、或时,预期的性能改善程度;例如,将参数数翻一番,损失率比小。 和的精确数值取决于词汇大小和符号化,因此没有根本意义.
The critical batch size, which determines the speed/efficiency tradeoff for data parallelism ([MKAT18]), also roughly obeys a power law in :
关键批量大小决定了数据并行性的速度/效率权衡([MKAT18]),也大致遵守中的功率定律:
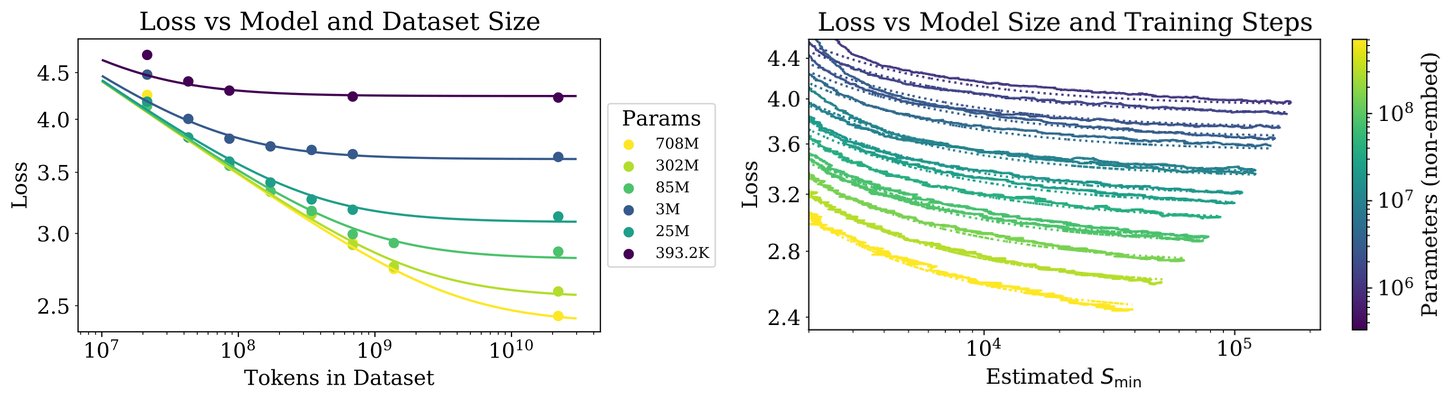
Figure 4: Left: The early-stopped test loss varies predictably with the dataset size and model size according to Equation (1.5). Right: After an initial transient period, learning curves for all model sizes can be fit with Equation (1.6), which is parameterized in terms of , the number of steps when training at large batch size (details in Section 5.1).
图4:左: 早期停止的测试损失随着数据集大小和模型大小根据方程式(1.5)的预测而变化. ** 权利**: 经过最初的短暂时期后,所有型号的的学习曲线可以与方程式(1.6)相适应,方程式以为参数,大批量规模的训练时的步骤数(详见第5.1节).
Equation (1.1) and (1.2) together suggest that as we increase the model size, we should increase the dataset size sublinearly according to . In fact, we find that there is a single equation combining (1.1) and (1.2) that governs the simultaneous dependence on and and governs the degree of overfitting:
方程式(1.1)和(1.2)一起表明,随着模型规模的扩大,我们应当根据线性地增加数据集大小。 事实上,我们发现有一个将1.1和1.2合并在一起的单一方程式,用以规范同时依赖和,并规范过拟合的程度:
with fits pictured on the left in figure 4. We conjecture that this functional form may also parameterize the trained log-likelihood for other generative modeling tasks.
图4中左侧的图片。 我们推测,这种功能形式也可以将训练过的日志相似性参数化,用于其他生成模型制作任务.
When training a given model for a finite number of parameter update steps in the infinite data limit, after an initial transient period, the learning curves can be accurately fit by (see the right of figure 4)
当在无限数据限值中为有限数量的参数更新步骤培训特定模型时,在初始瞬间后,学习曲线可以通过(见图4的权利)准确匹配.
where and , and is the minimum possible number of optimization steps (parameter updates) estimated using Equation (5.4).
其中和,和是使用方程式估算的最小可能的优化步骤(参数更新)数(5.4).
When training within a fixed compute budget , but with no other constraints, Equation (1.6) leads to the prediction that the optimal model size , optimal batch size , optimal number of steps , and dataset size should grow as
当在固定计算预算范围内进行训练但没有其他限制时,方程式(1.6)导致预测最佳模型大小,最佳批量大小,最佳步骤数量,以及数据集大小应该随着增长而增长.
with
与
which closely matches the empirically optimal results , , and . As the computational budget increases, it should be spent primarily on larger models, without dramatic increases in training time or dataset size (see Figure 3). This also implies that as models grow larger, they become increasingly sample efficient. In practice, researchers typically train smaller models for longer than would be maximally compute-efficient because of hardware constraints. Optimal performance depends on total compute as a power law (see Equation (1.3)).
(b) 与经验最佳结果、和密切匹配。 随着计算预算的增加,它应主要用于更大的模型,而不大幅度增加训练时间或数据集的规模(见图3)。 这还意味着,随着模型的扩大,它们越来越有效率。 在实践中,研究人员通常对较小的模型进行培训的时间长于由于硬件限制而产生最大计算效率的水平。 最佳性能取决于作为动力定律的总计算(见Equation (1.3)).
We provide some basic theoretical motivation for Equation (1.5), an analysis of learning curve fits and their implications for training time, and a breakdown of our results per token. We also make some brief comparisons to LSTMs and recurrent Transformers [DGV+18].
我们为方程式学提供了一些基本的理论动力(1.5)求职,对学习曲线及其对训练时间持久的和平进行分析,并对我们的成果逐个进行细分。 我们还与LSTMs和反复出现的变换器[DGV+18]进行一些简短的比较.
1.3 Notation
1.3 记号
We use the following notation:
我们使用下列标记:
- • – the cross entropy loss in nats. Typically it will be averaged over the tokens in a context, but in some cases we report the loss for specific tokens within the context.
- • – the number of model parameters, excluding all vocabulary and positional embeddings
- • – an estimate of the total non-embedding training compute, where is the batch size, and is the number of training steps (ie parameter updates). We quote numerical values in PF-days, where one PF-day floating point operations.
- • – the dataset size in tokens
- • – the critical batch size [MKAT18], defined and discussed in Section 5.1. Training at the critical batch size provides a roughly optimal compromise between time and compute efficiency.
- • – an estimate of the minimum amount of non-embedding compute to reach a given value of the loss. This is the training compute that would be used if the model were trained at a batch size much less than the critical batch size.
- • – an estimate of the minimal number of training steps needed to reach a given value of the loss. This is also the number of training steps that would be used if the model were trained at a batch size much greater than the critical batch size.
- • – power-law exponents for the scaling of the loss as where can be any of .
-– Nats的交叉 en损. 通常情况下,在上下文中,它将平均于物证,但在某些情况下,我们报告在上下文中的具体物证的损失。
-- 模型参数的数目,* 不包括所有词汇和位置嵌入*
- ——对非嵌入式训练总计算的估计,其中为批量规模,为训练步骤的数量(i参数更新). 我们引用PF日的数值,其中一个PF日的浮点操作.
--- -- 代号数据集大小 - ——第5.1节界定和讨论的关键批量尺寸[MKAT18]。 关键批量规模的培训在时间和计算效率之间提供了大致最佳的妥协。
--- -- 估计非嵌入计算得出某一损失价值的最低数额。 如果该型号的批号比批号要小得多,则使用这种训练计算法。
--- --啪声 -- 估计达到一定损失价值所需的最低限度训练步骤。 这也是如果该型号的分批培训比关键分批培训大得多,将使用的培训步骤的数目。
-– 作为将损失缩放为的任何一种的幂律促进者.
2 Background and Methods
2 背景与方法
We train language models on WebText2, an extended version of the WebText [RWC+19] dataset, tokenized using byte-pair encoding [SHB15] with a vocabulary size . We optimize the autoregressive log-likelihood (i.e. cross-entropy loss) averaged over a 1024-token context, which is also our principal performance metric. We record the loss on the WebText2 test distribution and on a selection of other text distributions. We primarily train decoder-only [LSP+18, RNSS18] Transformer [VSP+17] models, though we also train LSTM models and Universal Transformers [DGV+18] for comparison.
我们在WebText2上培训语言模型,这是WebText[RWC+19]数据集的扩展版本,以字节-pair编码[SHB15]为标志,词汇大小为. 我们优化了自递式的类似日志(即交叉输入损失),平均在1024个上下文上,这也是我们的主要业绩衡量标准。 我们在WebText2测试分发和其他文本分发选集中记录损失. 我们主要只培训解码器[LSP+18,RNSS18]变压器[VSP+17]型号,虽然我们也培训LSTM型号和通用变压器[DGV+18]进行对比.
2.1 Parameter and Compute Scaling of Transformers
2.1 Transformer 的参数与算力缩放
| Operation | Parameters | FLOPs per Token |
|---|---|---|
| Embed | ||
| Attention: QKV | ||
| Attention: Mask | — | |
| Attention: Project | ||
| Feedforward | ||
| De-embed | — | |
| Total (Non-Embedding) |
Table 1: Parameter counts and compute (forward pass) estimates for a Transformer model. Sub-leading terms such as nonlinearities, biases, and layer normalization are omitted.
| ** 行动** | ** 参数** | ** 按托肯计算的供资比率** |
|---|---|---|
| 内嵌 | 第二十届 | |
| 注意:QKV | 第二十届 | 第二十届 |
| 注意:面具 | . . . . . . | 第二十届 |
| 注意:项目 | 互信 | 互信 |
| 向导 | 第二十届 | 第二十届 |
| 卸载 | . . . . . . | 第二十届 |
| ** 总计(不计费用)** | 第二十届 | 第二十届 |
表1:变压器模型参数计算和计算(前传)估计数。 省略了非线性、偏差和层层正常化等次要术语。
We parameterize the Transformer architecture using hyperparameters (number of layers), (dimension of the residual stream), (dimension of the intermediate feed-forward layer), (dimension of the attention output), and (number of attention heads per layer). We include tokens in the input context, with except where otherwise noted.
我们使用超采取协调一致的参数来参数化Transformer架构 (层数), (残流的分数), (中间向导层的分数), (注意力输出的分数),和 (每层注意力头数). 我们在输入语境中包括令牌,除另有说明外,还有.
We use to denote the model size, which we define as the number of non-embedding parameters
我们使用来表示模型大小,我们将其定义为既没有嵌入参数的数量
where we have excluded biases and other sub-leading terms. Our models also have parameters in an embedding matrix, and use parameters for positional embeddings, but we do not include these when discussing the ‘model size’ ; we will see that this produces significantly cleaner scaling laws.
我们排除了偏见和其他次要条件。 我们的模型在嵌入式矩阵中也有参数,并使用参数进行位置嵌入,但我们在讨论`模型大小 ' 时并不包括这些参数;我们将看到这会产生显著的更清洁的缩放法则.
Evaluating a forward pass of the Transformer involves roughly
评估Transformer的前传涉及大致
add-multiply operations, where the factor of two comes from the multiply-accumulate operation used in matrix multiplication. A more detailed per-operation parameter and compute count is included in Table 1.
加乘运算,其中2的系数来自矩阵乘法中使用的乘积运算. 表1列有更详细的每个操作参数和计算数。
For contexts and models with , the context-dependent computational cost per token is a relatively small fraction of the total compute. Since we primarily study models where , we do not include context-dependent terms in our training compute estimate. Accounting for the backwards pass (approximately twice the compute as the forwards pass), we then define the estimated non-embedding compute as floating point operators per training token.
对于具有的上下文和模型,每令牌依赖上下文的计算成本是计算总成本的相对一小部分. 由于我们主要研究的模型,因此我们的培训计算估计数中并不包括取决于具体情况的术语。 计算后传(大约为前传的两倍计算),然后将估计的非嵌入式计算定义为每个训练楷书的浮点运算符.
2.2 Training Procedures
2.2 训练流程
Unless otherwise noted, we train models with the Adam optimizer [KB14] for a fixed steps with a batch size of sequences of tokens. Due to memory constraints, our largest models (more than 1B parameters) were trained with Adafactor [SS18]. We experimented with a variety of learning rates and schedules, as discussed in Appendix D.6. We found that results at convergence were largely independent of learning rate schedule. Unless otherwise noted, all training runs included in our data used a learning rate schedule with a 3000 step linear warmup followed by a cosine decay to zero.
除非另有说明,否则 这里是使用亚当优化器[KB14]为固定的步骤训练模型,其批量大小为序列为令牌. 由于内存的限制,我们最大的模型(超过1B参数)在Aductor[SS18]训练. 如附录D.6所述,我们试验了各种学习率和学习时间表。 我们发现,趋同的结果在很大程度上独立于学习率时间表。 除非另有说明,我们数据中包括的所有培训都采用了学习速度表,采用3000步线性热速率,然后将余弦衰减到零。
2.3 Datasets
2.3 数据集
We train our models on an extended version of the WebText dataset described in [RWC+19]. The original WebText dataset was a web scrape of outbound links from Reddit through December 2017 which received at least 3 karma. In the second version, WebText2, we added outbound Reddit links from the period of January to October 2018, also with a minimum of 3 karma. The karma threshold served as a heuristic for whether people found the link interesting or useful. The text of the new links was extracted with the Newspaper3k python library. In total, the dataset consists of 20.3M documents containing 96 GB of text and words (as defined by wc). We then apply the reversible tokenizer described in [RWC+19], which yields tokens. We reserve of these tokens for use as a test set, and we also test on similarly-prepared samples of Books Corpus [ZKZ+15], Common Crawl [Fou], English Wikipedia, and a collection of publicly-available Internet Books.
我们用[RWC+19]中描述的WebText数据集的扩展版本来训练我们的模型. 最初的WebText数据集是一个从Reddit到2017年12月的输出链接的网络刮痕,它至少收到了3个因果. 在第二个版本WebText2中,我们增加了从2018年1月至10月的外出Reddit链接,同样最少3个因果. 因果门槛对于人们是否觉得联系有趣或有用,起到了推力作用. 与Newspaper3k python库一起提取了新链接的文本. 数据集总共包括包含96GB文本的20.3M文档和词(由wc定义). 然后,我们使用[RWC+19]中描述的可逆的代币,该代币产生. 我们保留其中的作为测试集使用,我们还测试了类似准备的Books Corpus [ZKZ+15],Common Crawl [Fou],英语维基百科,以及可公开查阅的互联网图书集.
3 Empirical Results and Basic Power Laws
3 经验结果与基本幂律
To characterize language model scaling we train a wide variety of models, varying a number of factors including:
为了描述语言模型的规模,我们培训了各种各样的模型,其中有若干因素,包括:
- • Model size (ranging in size from 768 to 1.5 billion non-embedding parameters)
- • Dataset size (ranging from 22 million to 23 billion tokens)
- • Shape (including depth, width, attention heads, and feed-forward dimension)
- • Context length (1024 for most runs, though we also experiment with shorter contexts)
- • Batch size ( for most runs, but we also vary it to measure the critical batch size)
• 模型尺寸(大小从768亿到15亿非嵌入参数不等)
• 数据集大小(从2 200万到230亿令牌不等)
• 形状(包括深度、宽度、注意力头和向导维度)
- 背景长度(大多数时间为1024次,尽管我们也试验时间较短)
- 批量体积(大多数批量体积为,但我们也为了测量批量体积而改变)
In this section we will display data along with empirically-motivated fits, deferring theoretical analysis to later sections.
在本节中,我们将展示数据以及以经验为动力的适合情况,将理论分析推迟到以后各节。
3.1 Approximate Transformer Shape and Hyperparameter Independence
3.1 近似 Transformer 形状与超参数无关性
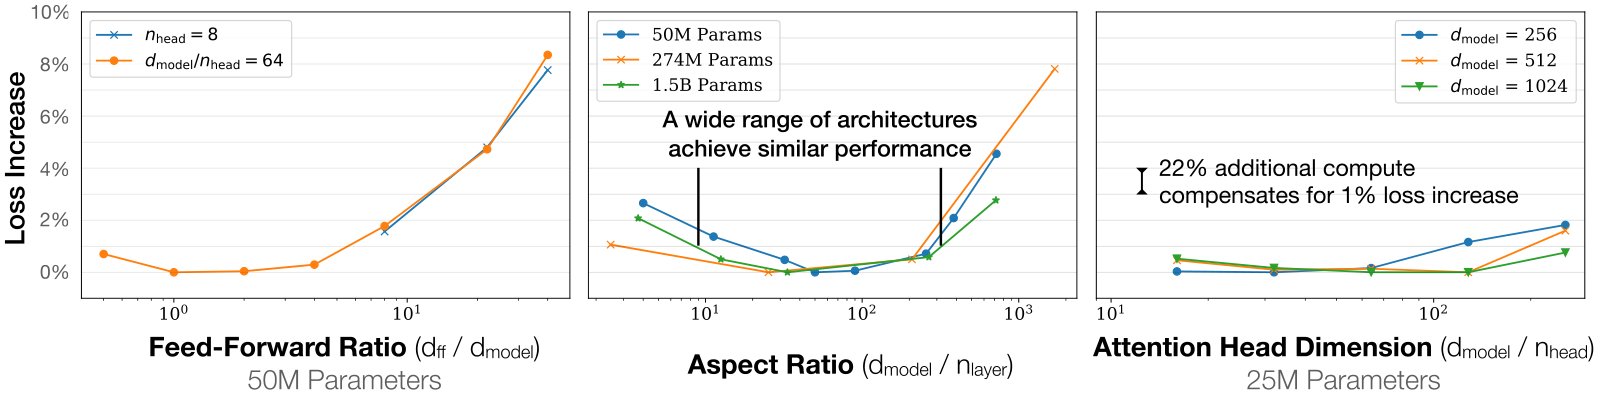
Figure 5: Performance depends very mildly on model shape when the total number of non-embedding parameters is held fixed. The loss varies only a few percent over a wide range of shapes. Small differences in parameter counts are compensated for by using the fit to as a baseline. Aspect ratio in particular can vary by a factor of 40 while only slightly impacting performance; an reaches a loss within 3% of the model used in [RWC+19].
图5:当的非嵌入参数总数被固定时,性能非常温和地依赖于模型形状. 损失在各种各样的形状上只有很小的差别。 参数计数的微小差异通过将适值与作为基线予以补偿。 光谱比尤其可以因40而异,而只略微影响性能;在[RWC+19]中使用的模型的3%范围内达到损失.
Transformer performance depends very weakly on the shape parameters , and when we hold the total non-embedding parameter count fixed. To establish these results we trained models with fixed size while varying a single hyperparameter. This was simplest for the case of . When varying , we simultaneously varied while keeping fixed. Similarly, to vary at fixed model size we also simultaneously varied the parameter, as required by the parameter counts in Table 1. Independence of would follow if deeper Transformers effectively behave as ensembles of shallower models, as has been suggested for ResNets [VWB16]. The results are shown in Figure 5.
Transformer的性能非常微弱地依赖于形状参数,当我们持有总的非嵌入参数计数固定时的. 为了确定这些结果,我们培训了固定尺寸的模型,同时采用了一个超参数。 这对一案最为简单。 当改变时,我们同时改变,同时保持的固定. 同样,为了在固定模型大小上改变,我们也同时按照表1参数计数的要求改变参数. 如果更深的变换器能像ResNets[VWB16]所建议的那样,有效地发挥更浅的模型的组合作用,则的独立将随之而来。 结果见图5。
3.2 Performance with Non-Embedding Parameter Count
3.2 相对非嵌入参数量 的性能
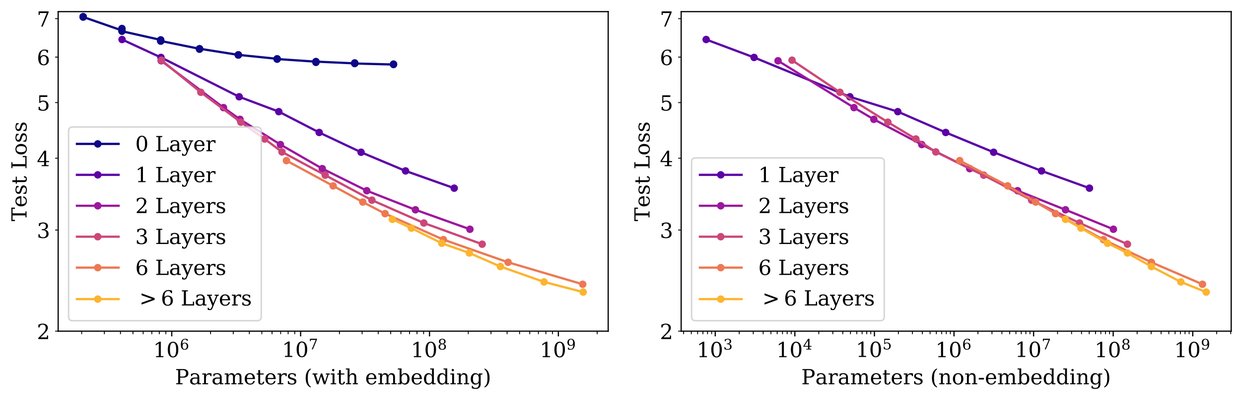
Figure 6: Left: When we include embedding parameters, performance appears to depend strongly on the number of layers in addition to the number of parameters. Right: When we exclude embedding parameters, the performance of models with different depths converge to a single trend. Only models with fewer than 2 layers or with extreme depth-to-width ratios deviate significantly from the trend.
图6:左: 当我们列入嵌入参数时,性能似乎除了参数数量外,还严重依赖于层数. ** 权利**: 当我们排除嵌入参数时,不同深度的模型的性能会趋同于单一的趋势. 只有少于2层或极深比比宽的模型,才明显偏离趋势.
In Figure 6 we display the performance of a wide variety of models, ranging from small models with shape through billion-parameter models, ranging in shape from through . Here we have trained to near convergence on the full WebText2 dataset and observe no overfitting (except possibly for the very largest models).
在图6中,我们展示了各种模型的性能,从形状为的小模型到10亿参数模型,形状从到. 在这里,我们训练了在完整的WebText2数据集上接近趋同,并且观测到没有过拟合(除了可能是最大的模型).
As shown in Figure 1, we find a steady trend with non-embedding parameter count , which can be fit to the first term of Equation (1.5), so that
如图1所示,我们发现一个稳定的趋势,非嵌入参数计数为,这可以适应方程式的第一个术语(1.5),因此,
To observe these trends it is crucial to study performance as a function of ; if we instead use the total parameter count (including the embedding parameters) the trend is somewhat obscured (see Figure 6). This suggests that the embedding matrix can be made smaller without impacting performance, as has been seen in recent work [LCG+19].
要观察这些趋势,必须研究作为函数的性能;如果我们使用总参数计数(包括嵌入参数),趋势就有些模糊(见图6)。 这表明嵌入式矩阵可以变小而不影响性能,这在近期的作品[LCG+19]中已经看到.
Although these models have been trained on the WebText2 dataset, their test loss on a variety of other datasets is also a power-law in with nearly identical power, as shown in Figure 8.
虽然这些模型在WebText2数据集上接受了培训,但是它们在各种其他数据集上的测试丢失也是中功率几乎相同的功率定律,如图8所示.
3.2.1 Comparing to LSTMs and Universal Transformers
Figure 7:
3.2.1 与 LSTM 和通用Transformer进行比较
图7:
In Figure 7 we compare LSTM and Transformer performance as a function of non-embedding parameter count . The LSTMs were trained with the same dataset and context length. We see from these figures that the LSTMs perform as well as Transformers for tokens appearing early in the context, but cannot match the Transformer performance for later tokens. We present power-law relationships between performance and context position Appendix D.5, where increasingly large powers for larger models suggest improved ability to quickly recognize patterns.
在图7中,我们比较了LSTM和Transformer的性能,作为非嵌入参数计算的一个函数. LSTMs接受了同样的数据集和上下文长度的培训. 我们从这些数字中看到,LSTM和Transformer在上下文中早期出现的代号上都表现出来,但不能与Transformer的性能相匹配来表示后来的代号. 我们提出业绩与背景立场之间的幂律关系附录D.5,其中对较大模型的日益强大的权力表明,快速识别模式的能力得到了提高。
We also compare the performance of standard Transformers to recurrent Transformers [DGV+18] in Figure 17 in the appendix. These models re-use parameters, and so perform slightly better as a function of , at the cost of additional compute per-parameter.
我们还将标准变换器的性能与附录图17中的反复变换器[DGV+18]进行比较.的案例重新使用参数,因此作为的函数性能稍好一些,成本为每参数的额外计算.
3.2.2 Generalization Among Data Distributions
We have also tested our models on a set of additional text data distributions. The test loss on these datasets as a function of model size is shown in Figure 8; in all cases the models were trained only on the WebText2 dataset. We see that the loss on these other data distributions improves smoothly with model size, in direct parallel with the improvement on WebText2. We find that generalization depends almost exclusively on the in-distribution validation loss, and does not depend on the duration of training or proximity to convergence. We also observe no dependence on model depth (see Appendix D.8).
3.2.2 数据分配的概况
我们还测试了一套额外的文本数据分布模型。 这些数据集作为 58. 模型大小函数的测试损失见图8;在所有情况下,模型都是在WebText2数据集中培训的。 我们看到这些其它数据分布的损失随着模型大小的改善而顺利改善,与WebText2上的改进直接平行. 我们认为,一般化几乎完全取决于分配中的验证损失,并不取决于培训的持续时间或接近趋同的程度。 我们还观察到没有依赖模型深度(见附录D.8)。
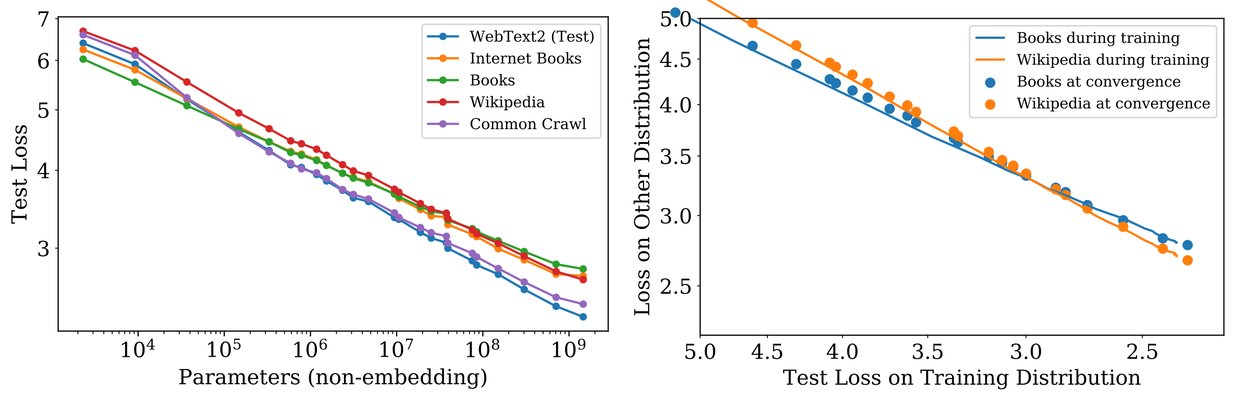
Figure 8: Left: Generalization performance to other data distributions improves smoothly with model size, with only a small and very slowly growing offset from the WebText2 training distribution. Right: Generalization performance depends only on training distribution performance, and not on the phase of training. We compare generalization of converged models (points) to that of a single large model (dashed curves) as it trains.
图8:左: 通向其他数据分布的通用性能随着模型大小的改善而顺利改善,只有很小且非常缓慢增长的WebText2训练分布抵消. ** 权利**: 一般化的表现只取决于培训分配的表现,而不取决于培训阶段。 我们把趋同模型(点)的概括性与训练时的单一大模型(凹陷曲线)的概括性进行比较。
3.3 Performance with Dataset Size and Compute
3.3 相对数据集规模与算力的性能
We display empirical trends for the test loss as a function of dataset size (in tokens) and training compute in Figure 1.
我们显示测试损失的经验趋势,作为数据集大小(以符号表示)和训练计算在图1中的函数.
For the trend with we trained a model with on fixed subsets of the WebText2 dataset. We stopped training once the test loss ceased to decrease. We see that the resulting test losses can be fit with simple power-law
关于的趋势,我们在WebText2数据集的固定子集上用培训了一个模型。 一旦测试损失不再减少,我们就停止了训练。 我们发现 由此造成的测试损失 能够适应简单的电法
in the dataset size. The data and fit appear in Figure 1.
在数据集大小中。 数据和适用情况见图1。
The total amount of non-embedding compute used during training can be estimated as , where is the batch size, is the number of parameter updates, and the factor of accounts for the forward and backward passes. Thus for a given value of we can scan over all models with various to find the model with the best performance on step . Note that in these results the batch size remains fixed for all models, which means that these empirical results are not truly optimal. We will account for this in later sections using an adjusted to produce cleaner trends.
培训期间使用的非依循计算总数可估算为,其中为批量大小,为参数更新数,因数为前向和后向通行证. 因此,对于给定的值,我们可以用各种扫描所有模型,找到在步骤上表现最好的模型. 请注意,在这些结果中,* 批量大小 对所有模型仍然固定*,这意味着这些经验性结果并非真正最佳. 我们将在以后各节中说明这一点,使用经调整的来产生更清洁的趋势。
The result appears as the heavy black line on the left-hand plot in Figure 1. It can be fit with
结果以图1中左手图中的重黑线出现. 它可以适应
The figure also includes images of individual learning curves to clarify when individual models are optimal. We will study the optimal allocation of compute more closely later on. The data strongly suggests that sample efficiency improves with model size, and we also illustrate this directly in Figure 19 in the appendix.
该图还包括个人学习曲线的图像,以澄清单个模型何时是最佳. 我们稍后将更仔细地研究计算的最佳分配。 数据强烈表明,样本效率随着模型大小的提高而提高,我们在附录图19中也直接说明了这一点.
4 Charting the Infinite Data Limit and Overfitting
4 刻画无限数据极限与过拟合
In Section 3 we found a number of basic scaling laws for language modeling performance. Here we will study the performance of a model of size trained on a dataset with tokens while varying and simultaneously. We will empirically demonstrate that the optimally trained test loss accords with the scaling law of Equation (1.5). This provides guidance on how much data we would need to train models of increasing size while keeping overfitting under control.
在第3节中,我们发现了一些关于语言模型表现的基本缩放法。 在此,我们将研究一个大小为的模型的性能,该模型在使用令牌的数据集上培训,同时不同大小为和。 我们将实证地证明,经过最佳训练的测试损失符合方程式定律(1.5)。 这提供了指导,说明我们需要多少数据来训练规模越来越大的模型,同时保持过度调整的控制。
4.1 Proposed Equation
4.1 提议的 方程
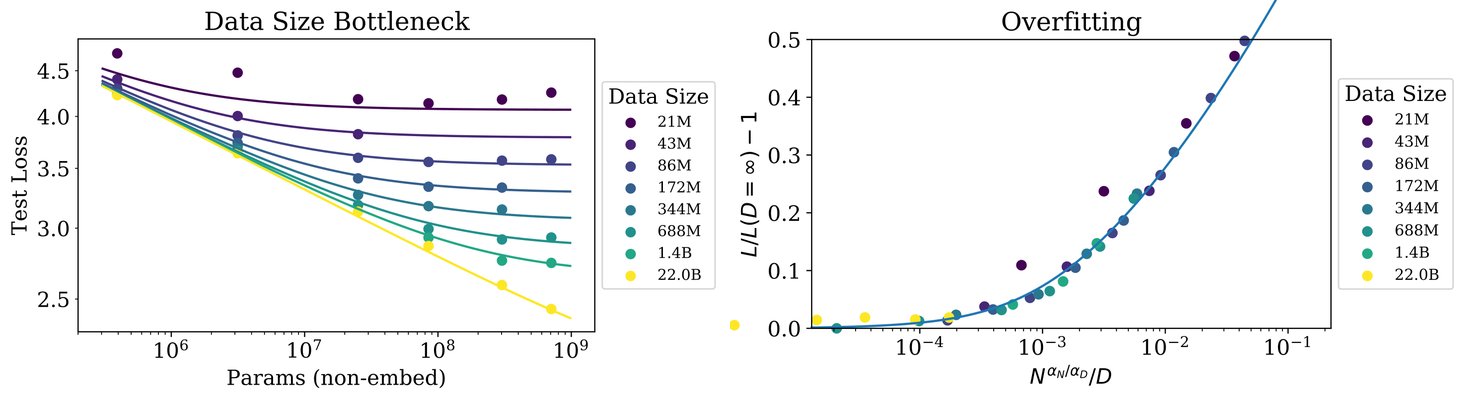
Figure 9: The early-stopped test loss depends predictably on the dataset size and model size according to Equation (1.5). Left: For large , performance is a straight power law in . For a smaller fixed , performance stops improving as increases and the model begins to overfit. (The reverse is also true, see Figure 4.) Right: The extent of overfitting depends predominantly on the ratio , as predicted in equation (4.3). The line is our fit to that equation.
图9:早期停止的测试损失卷宗ắn根据方程式(1.5)预测取决于数据集大小和模型大小. ** 左侧: 对于大型的,性能是中的直电法. 对于一个较小的固定的,随着的增加,性能停止改善,模型开始过拟合. (反之亦然,见图4) ** 权利**: 过于适应的程度主要取决于的比例,如方程式预测(4.3). 这条线是我们适合这个方程式的。
We have chosen the parameterization (1.5) (repeated here for convenience):
- 我们选择了参数化(1.5)(为方便起见在此重复):
using three principles:
采用三项原则:
- Changes in vocabulary size or tokenization are expected to rescale the loss by an overall factor. The parameterization of (and all models of the loss) must naturally allow for such a rescaling.
- Fixing and sending , the overall loss should approach . Conversely, fixing and sending the loss must approach .
- should be analytic at , so that it has a series expansion in with integer powers. Theoretical support for this principle is significantly weaker than for the first two.
- 词汇大小或符号化的变化预计将按总体因素调整损失规模。 的参数化(以及损失的所有模型)必须自然允许这种缩放.
- 修复和发送,总损失应接近。 相反,确定和发送的损失必须接近。
- 应在进行分析,使其在具有整数功率的系列扩展. 对这一原则的理论支持明显弱于前两项.
Our choice of satisfies the first requirement because we can rescale with changes in the vocabulary. This also implies that the values of have no fundamental meaning.
我们对的选择满足了第一个要求,因为随着词汇的变化,我们可以对进行调整. 这也意味着的价值没有根本意义.
Since we stop training early when the test loss ceases to improve and optimize all models in the same way, we expect that larger models should always perform better than smaller models. But with fixed finite , we also do not expect any model to be capable of approaching the best possible loss (ie the entropy of text). Similarly, a model with fixed size will be capacity-limited. These considerations motivate our second principle. Note that knowledge of at infinite and at infinite fully determines all the parameters in .
由于在测试损失停止以同样的方式改进和优化所有模型时,我们很早就停止了训练,我们期望更大的模型总是比较小的模型表现更好. 但是,有了固定的有限,我们也并不期望任何模型能够接近尽可能最好的损失(即文字的 en). 同样,固定规模的模型也将是能力有限的。 这些考虑推动了我们的第二项原则。 注意对在无限和对在无限的知识完全决定了中的所有参数.
The third principle is more speculative. There is a simple and general reason one might expect overfitting to scale at very large . Overfitting should be related to the variance or the signal-to-noise ratio of the dataset [AS17], and this scales as . This expectation should hold for any smooth loss function, since we expect to be able to expand the loss about the limit. However, this argument assumes that corrections dominate over other sources of variance, such as the finite batch size and other limits on the efficacy of optimization. Without empirical confirmation, we would not be very confident of its applicability.
第三项原则是更投机。 一个简单和普遍的理由,是人们可能期望在非常大范围的中超标为。 过于适应应当与数据集[AS17]的差值或信号与噪声之比有关,而这个尺度作为. 这种期望应维持任何顺畅的损失功能,因为我们期望能够扩大有关限制的损失。 然而,这一论点假定,更正在其它差异源之上占主导地位,例如有限批量大小和对优化效果的其他限制。 如果没有经验的证实,我们不会非常相信它的适用性。
Our third principle explains the asymmetry between the roles of and in Equation (1.5). Very similar symmetric expressions[^3] are possible, but they would not have a expansion with integer powers, and would require the introduction of an additional parameter.
我们的第三项原则解释了和在方程式(1.5)中的角色不对称. 非常相似的对称表达式[^3]是可能的,但它们不会有一个具有整数功率的扩展,需要引入额外的参数.
In any case, we will see that our equation for fits the data well, which is the most important justification for our ansatz.
无论如何,我们将看到,我们的等式非常符合数据,这是我们 ansatz最重要的理由。
4.2 Results
4.2 结果
We regularize all our models with 10% dropout, and by tracking test loss and stopping once it is no longer decreasing. The results are displayed in Figure 9, including a fit to the four parameters in Equation (1.5):
我们把所有的模型规范化 10%的辍学, 通过跟踪测试损失, 停止一旦它不再下降。 图9显示这些结果,包括与方程式(1.5)中的四个参数相符的结果:
| Parameter | ||||
|---|---|---|---|---|
| Value |
Table 2: Fits to
| 参数 | ||||
|---|---|---|---|---|
| 数值 |
表 2: 适合第号决定
We obtain an excellent fit, with the exception of the runs where the dataset has been reduced by a factor of , to about tokens. With such a small dataset, an epoch consists of only 40 parameter updates. Perhaps such a tiny dataset represents a different regime for language modeling, as overfitting happens very early in training (see Figure 16). Also note that the parameters differ very slightly from those obtained in Section 3, as here we are fitting the full rather than just or .
我们得到了一个绝佳的合身,除了数据集被缩小为倍的运行,大约是令牌. 由于数据集如此小,一个时代只包含40个参数更新. 也许如此微小的数据集代表了不同的语言建模制度,因为过拟合在培训初期就发生了(见图16)。 那是因为这里我们配有完整的, 而不仅仅是或。
To chart the borderlands of the infinite data limit, we can directly study the extent of overfitting. For all but the largest models, we see no sign of overfitting when training with the full 22B token WebText2 dataset, so we can take it as representative of . Thus we can compare finite to the infinite data limit by defining
为了绘制无限数据极限的边界地带,我们可以直接研究过拟合的程度. 除了最大的型号外,我们没有看到训练时使用完整的22B令牌WebText2数据集时过于匹配的迹象,因此我们可以把它当作的代表. 因此,我们可以通过定义:
and studying it as a function of . In fact, we see empirically that depends only a specific combination of and , as shown in Figure 16. This follows from the scaling law of Equation (1.5), which implies
并且作为的一个函数来研究. 事实上,我们实证地看到,只取决于和的具体组合,如图16所示. 这源于方程式定律(1.5),这意味着
Note that at large this formula also has a series expansion in powers of .
可在一般情况下,这一公式还具有的一系列权力扩张.
We estimate that the variation in the loss with different random seeds is roughly , which means that to avoid overfitting when training to within that threshold of convergence we require
我们估计,使用不同随机种子的损失变化大致为,这意味着为了避免在训练时过于适应我们要求达到的趋同阈值。
With this relation, models smaller than parameters can be trained with minimal overfitting on the 22B token WebText2 dataset, but our largest models will encounter some mild overfitting. More generally, this relation shows that dataset size may grow sub-linearly in model size while avoiding overfitting. Note however that this does not typically represent maximally compute-efficient training. We should also emphasize that we have not optimized regularization (eg the dropout probability) while varying dataset and model size.
在这种关系下,小于参数的模型可以在22B令牌WebText2数据集上进行最小的超配训练,但我们最大的模型会遇到一些轻微的超配. 更一般地说,这种关系表明,数据集大小可能在模型大小中子线性增长,同时避免过于适应. 但请注意,这通常并不代表计算效率最高的培训。 我们还应强调,我们没有优化正规化(如辍学概率),而不同的数据集和模型规模。
5 Scaling Laws with Model Size and Training Time
5 相对模型规模与训练时间的缩放定律
In this section we will demonstrate that a simple scaling law provides a good description for the loss as a function of model size and training time. First we will explain how to use the results of [MKAT18] to define a universal training step , which accounts for the fact that most of our models have not been trained at an optimal batch size. Then we will demonstrate that we can fit the model size and training time dependence of the loss using Equation (1.6). Later we will use these results to predict the optimal allocation of training compute between model size and training time, and then confirm that prediction.
在本节中,我们将表明,一个简单的缩放法很好地描述了损失作为模型大小和训练时间的函数。 首先,我们将解释如何利用[MKAT18]的结果来定义一个通用培训步骤,这说明我们大多数的模型没有以最佳的批量规模进行训练。 然后,我们将证明,我们可以使用方程式(1.6)来适应损失的模型大小和训练时间依赖。 后来我们将利用这些结果来预测在模型大小和训练时间之间计算出的训练的最佳分配,然后确认这一预测。
5.1 Adjustment for Training at
5.1 在 下训练的修正
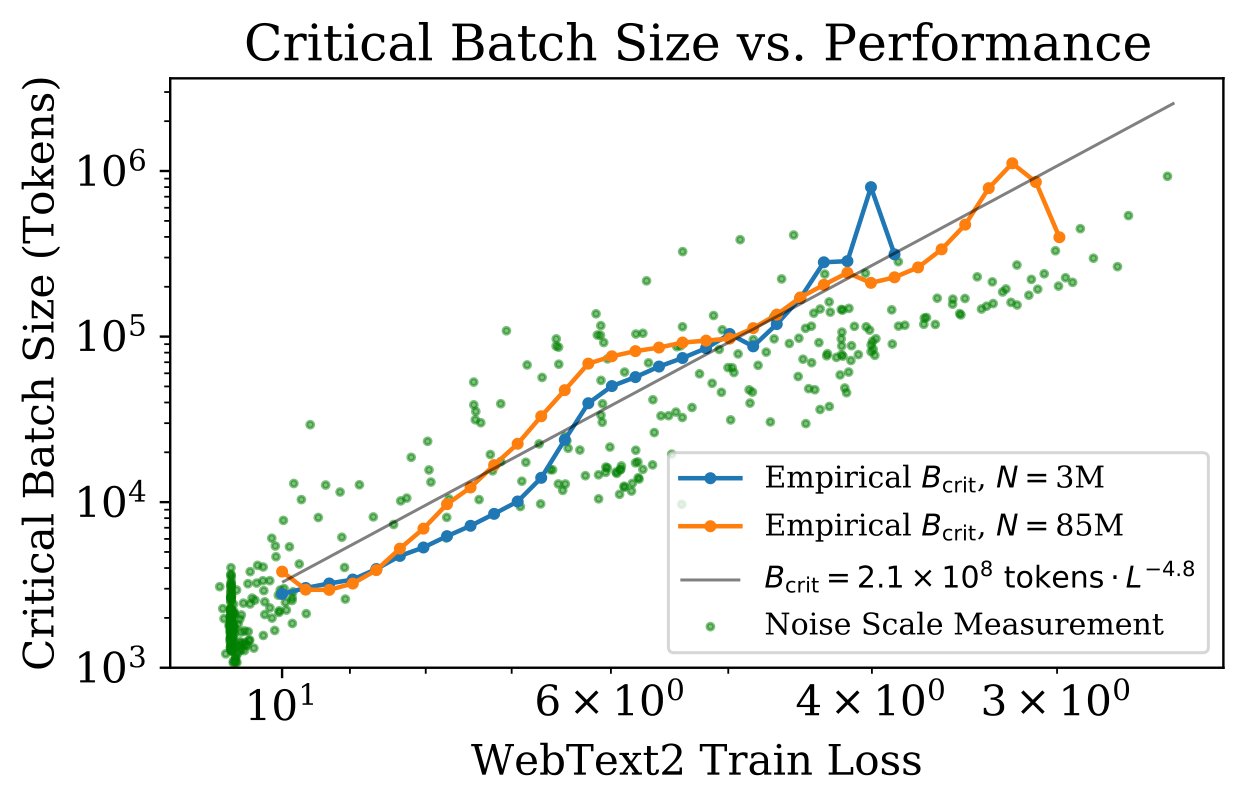
Figure 10: The critical batch size follows a power law in the loss as performance increase, and does not depend directly on the model size. We find that the critical batch size approximately doubles for every decrease in loss. is measured empirically from the data shown in Figure 18, but it is also roughly predicted by the gradient noise scale, as in [MKAT18].
图10:关键批量尺寸在性能增加时在损失中遵循动力定律,不直接取决于模型大小. 我们发现,每损失减少一倍左右的批量。 从图18显示的数据中经验性地进行了测量,但也大致通过梯度噪声尺度来预测,如[MKAT18].
A simple empirical theory for the batch size dependence of training was developed in [MKAT18] (see also [SLA+18, ZLN+19]). It was argued that there is a critical batch size for training; for up to the batch size can be increased with very minimal degradation in compute-efficiency, whereas for increases in result in diminishing returns. It was also argued that the gradient noise scale provides a simple prediction for , and that neither depends directly on model size except through the value of the loss that has been attained. These results can be used to predict how training time and compute will vary with the batch size. To utilize both training time and compute as effectively as possible, it is best to train with a batch size . Training at minimizes the number of training steps, while minimizes the use of compute.
在MKAT18中为培训的批量大小依赖性开发了一个简单的经验理论. 据认为,培训有关键的批量尺寸;对于至,批量尺寸可以增加,计算效率的降解程度极低,而对于,的增加导致回报下降。 也有人认为,梯度噪声尺度为提供了一个简单的预测,除了通过已经实现的损失值外,两者都不直接取决于模型大小. 这些结果可用于预测训练时间和计算会如何随批量大小而变化. 为了尽可能有效地利用训练时间和计算,最好采用第号批量培训。 的培训尽量减少了培训步骤的数量,而则尽量减少了计算的使用.
More specifically, it was demonstrated that for a wide variety of neural network tasks, the number of training steps and the number of data examples processed satisfy the simple relation
更具体地说,证明对于多种神经网络任务来说,训练步骤的数量和处理的数据实例的数量满足了简单的关系.
when training to any fixed value of the loss . Here is the minimum number of steps necessary to reach , while is the minimum number of data examples that must be processed.
当训练达到损失的任何固定价值时 这里的是达到所需的最低步骤数,而是必须处理的数据示例的最低数目.
We demonstrate the relation (5.1) for Transformers in Figure 18 in the appendix. This relation defines the critical batch size
我们在附录图18中展示了Transformer的关系(5.1)。 此关系定义了批量批量大小
which is a function of the target value of the loss. Training at the critical batch size makes a roughly optimal time/compute tradeoff, requiring training steps and processing data examples.
这是损失目标值的函数。 关键批量规模的培训可以作出大致最佳的时间/计算权衡,需要培训步骤和处理数据实例。
In Figure 10 we have plotted the critical batch size and gradient noise scale[^4] as a function of training loss for two different models. We see that is independent of model size, and only depends on the loss . So the predictions of [MKAT18] continue to hold for Transformer language models. The critical batch size can be fit with a power-law in the loss
在图10中,我们绘制了临界批量提供关于梯度噪声的尺度[^4],作为两种不同模型培训损失的一个函数。 我们看到,独立于模型大小,仅取决于损失. 因此,[MKAT18]的预测继续为Transformer语言模型所持有. 关键批量的尺寸与损失中的电源法相符
where and .
竿头:
We have chosen this parameterization for because as the loss approaches its minimum value , the gradient noise scale is expected to diverge, and we expect to track this noise scale. We do not know , as we see no sign that our models are approaching it, but since the entropy of natural language is non-zero. Since apparently is much smaller than the values of we have achieved, we used a parameterization where diverges as .
我们为选择了这个参数化,因为随着损失接近其最低值,梯度噪声尺度预计会有所不同,我们期望跟踪这个噪声尺度. 我们不知道,因为我们没有看到我们的模型接近它的迹象,但是因为自然语言的 en是非零的. 由于显然比我们所实现的的值要小得多,我们使用了一个参数化方法,其中与不同。
We will use to estimate the relation between the number of training steps while training at batch size tokens and the number of training steps while training at . This is simply
我们将使用来估计在培训时的训练步骤数量与在培训时的训练步骤数量之间的关系。 这很简单
for any given target value for the loss. This also defines a critical value of the compute needed to train to with a model of size if we were to train at . This is
有关损失的。 这还定义了如果我们要在进行训练,需要使用大小为的型号来进行训练的计算的关键值. 这是
where estimates the (non-embedding) compute used at batch size .
其中估算了按批号使用的(非嵌入式)计算.
5.2 Results for and Performance with Model Size and Compute
5.2 的结果以及相对模型规模与算力的性能
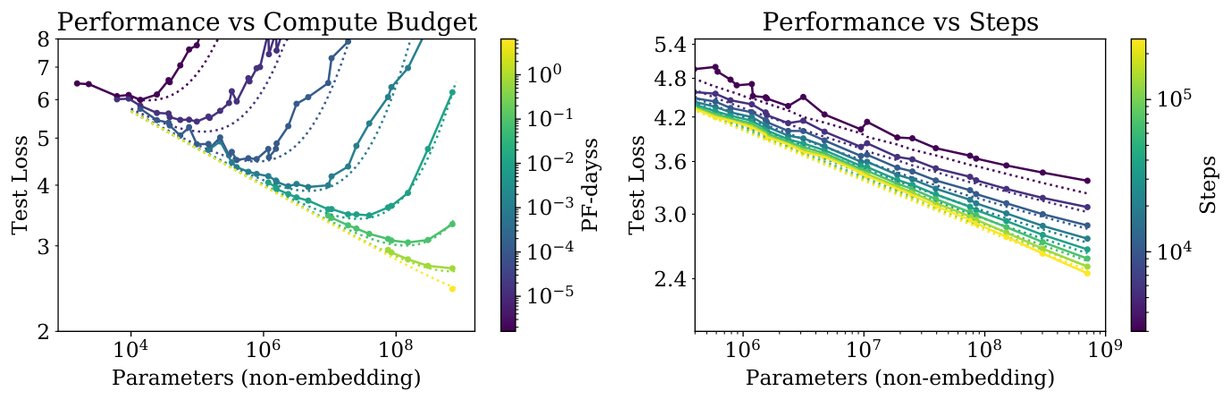
Figure 11: When we hold either total compute or number of training steps fixed, performance follows from Equation (5.6). Each value of compute budget has an associated optimal model size that maximizes performance. Mediocre fits at small are unsurprising, as the power-law equation for the learning curves breaks down very early in training.
图11:当我们掌握总计算数或固定培训步骤数时,业绩与方程式的(5.6)。 计算预算的每个价值都有一个相关的最佳模型规模,可以最大限度地提高绩效。 在小的中,平庸的配方并不奇怪,因为学习曲线的幂律方程在训练初期就崩溃了.
Now we will use defined in Equation (5.4) to obtain a simple and universal fit for the dependence of the loss on model size and training time in the infinite data limit. We will fit the stable, Adam-optimized training runs using Equation (1.6), repeated here for convenience:
现在,我们将使用在方程式(5.4)中定义的来获得一个简单和通用的适应,以适应在无限数据限制中对模型大小和训练时间的依赖. 使用方程式(1.6)进行最优化的稳定训练,
for the loss. We include all training steps after the warmup period of the learning rate schedule, and find a fit to the data with the parameters:
为损失。 我们包括学习率表的热化期之后的所有培训步骤,并找到与参数相匹配的数据:
| Parameter | ||||
|---|---|---|---|---|
| Value |
Table 3: Fits to
| 参数 | ||||
|---|---|---|---|---|
| 数值 |
表3 适合第号决定
With these parameters, we obtain the learning curve fits in Figure 4. Though the fits are imperfect, we believe they are quite compelling given the simplicity of Equation (5.6).
通过这些参数,我们获得了图4中的学习曲线。 虽然不符合标准,但我们认为,考虑到方程式的简单性(5.6)。
The data and fits can be visualized in a different and more interesting way, as shown in Figure 11. There we study the test loss as a function of model size while fixing either the total non-embedding compute used in training, or the number of steps . For the fits we use Equation (5.5) and (5.4) along with the parameters above and Equation (5.6).
如图11所示,可以以不同和更有趣的方式对数据进行可视化。 在那里,我们作为模型大小的函数来研究测试损失,同时确定训练中使用的总非嵌入计算值,或者确定步骤数. 为了符合要求,我们使用方程式(5.5)和(5.4)以及上述参数和方程式(5.6)。
The power-law dependence of the loss on reflects the interplay of optimizer dynamics and the loss landscape. Since the fits are best late in training, when the loss may be approximately quadratic, the power-law should provide information about the spectrum of the Hessian of the loss. Its universality suggests that the Hessian eigenvalue density is roughly independent of model size.
损失对的功率法依赖反映了优化动力学与损失景观的相互作用. 由于适合性在训练后期最好,当损失可能大约为四倍时,幂律应提供关于损失的黑森人谱的信息. 其普遍性表明,黑森等值密度大致独立于模型大小.
5.3 Lower Bound on Early Stopping Step
5.3 早停步数的下界
The results for can be used to derive a lower-bound (and rough estimate) of the step at which early stopping should occur when training is data limited. It is motivated by the idea that finite and infinite learning curves for a given model will be very similar until we reach . Thus overfitting should be proportional to the correction from simply ending training at . This will underestimate , because in reality the test loss will decrease more slowly when we have a finite , and therefore we will require more training steps to reach the optimal test loss at finite . This line of reasoning leads to the inequality
的结果可用来得出较低的(和粗略的估计)数据,说明在培训数据有限时,提前停止的阶段。 其动机是,在达到之前,特定模型的有限和无限的学习曲线将非常相似。 因此,过度调整应当与仅仅结束培训的纠正相称。 这将低估,因为实际上,当我们拥有一个有限的时,测试损失将减少得更慢,因此我们需要更多的培训步骤,以便在达到最佳测试损失。 这种推理导致不平等
where is the converged loss, evaluated with infinite available data. This inequality and its comparison to the empirical data is displayed in Figure 16 in the appendix. In that figure, the values of and are empirical (though is adjusted to mimic training at ), while is computed from the fit to evaluated at .
其中是集中损失,以无限可得数据加以评估。 这种不平等及其与实证数据的比较见附录图16。 在该图中,和的数值是实证的(虽然在被调整为模仿训练),而则从评价的适值到计算.
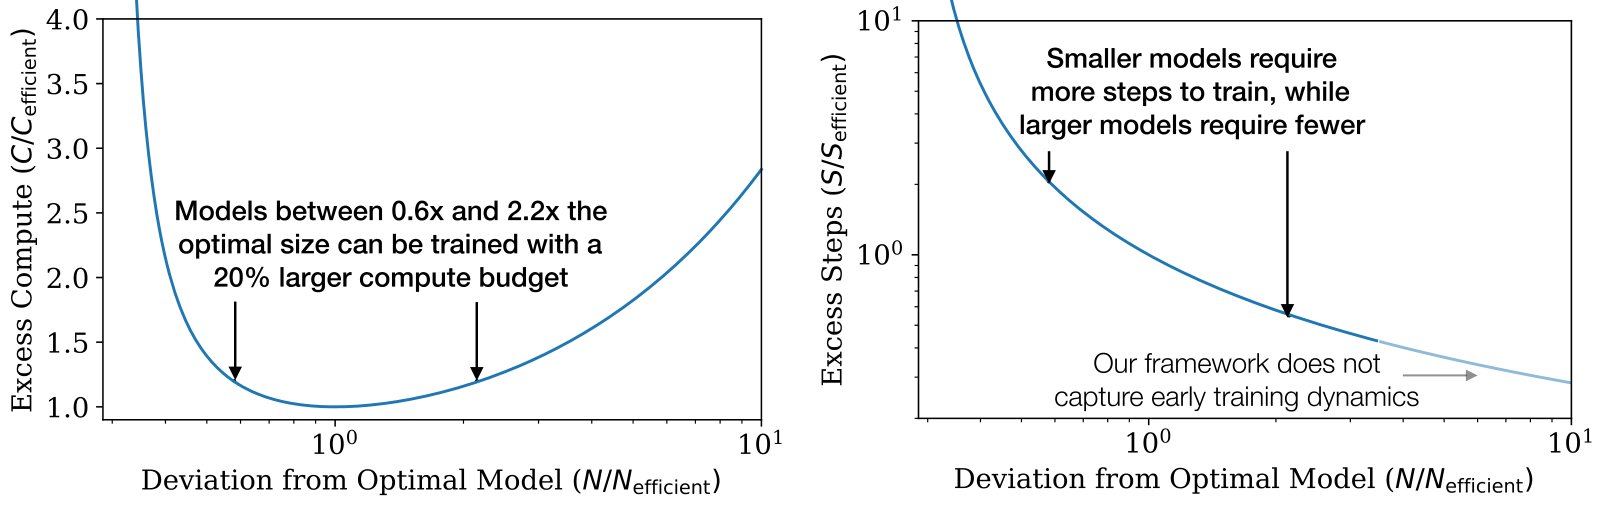
Figure 12: Left: Given a fixed compute budget, a particular model size is optimal, though somewhat larger or smaller models can be trained with minimal additional compute. Right: Models larger than the compute-efficient size require fewer steps to train, allowing for potentially faster training if sufficient additional parallelism is possible. Note that this equation should not be trusted for very large models, as it is only valid in the power-law region of the learning curve, after initial transient effects.
图12:左: 由于有固定的计算预算,特定的模型大小是最佳的,虽然用最小的附加计算可以训练一些大或小的模型. ** 权利**: 规模大于计算效率的型号需要较少的训练步骤,如果可能有足够的额外平行性,则有可能进行更快的训练。 注意这个方程不应该被信任于非常大的模型,因为它只有在学习曲线的幂律区,在初始瞬态效应之后才有效.
6 Optimal Allocation of the Compute Budget
6 算力预算的最优分配
We displayed the empirical trend of performance as a function of the computation used during training in the top-right of Figure 1. However, this result involved training at a fixed batch size , whereas we know that in fact we could train more efficiently[^5] by training at the batch size discussed in Section 5.1. Large and small values of the loss could have been achieved with fewer samples or fewer steps, respectively, and correcting for this inefficiency by standardizing to the critical batch size results in cleaner and more predictable trends.
我们在图1的右上角显示“经验”业绩趋势,作为训练期间使用的计算函数。 然而,这一object结果涉及固定批量的培训,而我们知道,事实上,我们可以通过第5.1节讨论的批量培训,提高培训效率。 损失的大小可以分别用较少的样品或较少的步骤来实现,并且通过按照批量临界量标准化来纠正这种效率低下的现象,从而形成更清洁和更可预测的趋势。
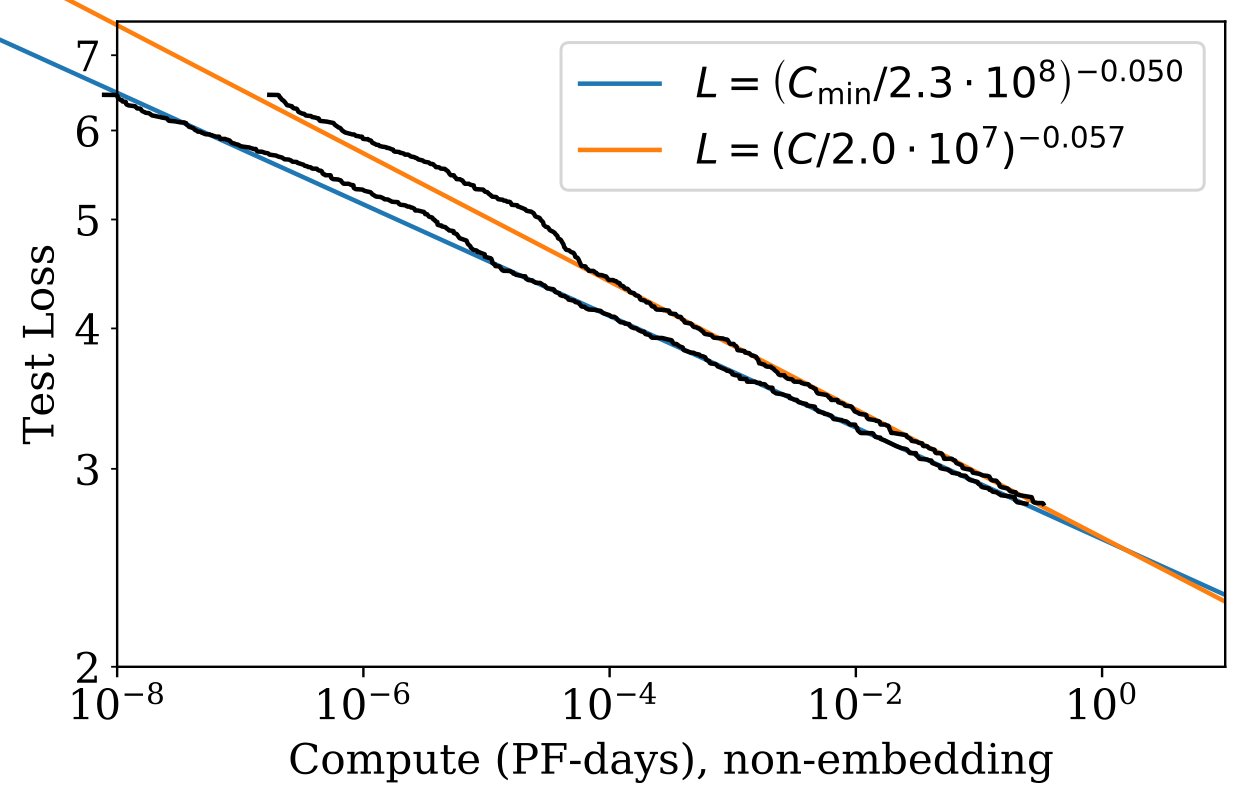
Figure 13: When adjusting performance to simulate training far below the critical batch size, we find a somewhat altered power law for when compared with the fully empirical results. The conspicuous lump at PF-days marks the transition from 1-layer to 2-layer networks; we exclude 1-layer networks in the power-law fits. It is the trend that we expect to provide a reliable extrapolation for larger compute.
图13:当调整性能以模拟远低于临界批量规模的训练时,我们发现,与完全实证结果相比,的功率定律有所改变。PF-日的显著整数标志着从一级网络向二级网络的过渡;我们在电力法中排除了一级网络。 我们期望为更大的计算提供可靠的推算。
In this section we will adjust for this oversight. More importantly, we will use the results of Section 5 to determine the optimal allocation of compute between model size and the quantity of data processed during training, namely . We will determine this allocation both empirically and theoretically, by using the equation for , and we will demonstrate that these methods agree.
在本节中,我们将调整这一监督。 更重要的是,我们将利用第5节的结果,确定在模型大小和在培训期间处理的数据数量(即)之间计算的最佳分配。 我们将采用的方程式,在经验上和理论上确定这一分配,我们将证明这些方法是一致的。
6.1 Optimal Performance and Allocations
6.1 最优性能与分配
Let us first study the loss as a function of the optimally allocated compute from Equation (5.5). The result is plotted in Figure 13, along with a power-law fit. We see that as compared to the compute plot of Figure 1, the new fit with is somewhat improved.
让我们首先研究损失,作为从方程式(5.5)中最佳分配计算的一个函数。 结果如图13所示,并附有适合的幂律。 我们看到,与图 1 的 计算 图 . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . .
Given , it is natural to ask for the optimal model size that provides the minimal loss with a given quantity of training compute. The optimal model size is shown in Figure 14. We observe that can be fit very well with a power-law
鉴于,自然要求优化型号为,通过一定数量的训练计算提供最小损失。 最佳模型尺寸见图14。 我们发现第号非常适合 一部幂律
In Figure 12, we show the effect of training models of sub-optimal sizes (see Appendix B.4).
在图12中,我们显示了培训模式对非最佳规模的影响(见附录B.4)。
By definition , and so we can use to extract further results. In particular, since prior fits show and , we can conclude that . This leads us to conclude that the optimal number of steps will only grow very slowly with compute, as
顾名思义的,因此我们可以使用来获取进一步的结果. 特别是,由于先前的适合显示和,我们可以得出的结论。 这使我们得出以下结论,即最佳步骤的数量将随着计算而缓慢增长,因为
matching the empirical results in Figure 14. In fact the measured exponent is sufficiently small that our results may even be consistent with an exponent of zero.
与图14中的经验结果相匹配。 事实上,所测量的指数足够小,我们的结果甚至可能与零指数一致。
Thus we conclude that as we scale up language modeling with an optimal allocation of computation, we should predominantly increase the model size , while simultaneously scaling up the batch size via with negligible increase in the number of serial steps. Since compute-efficient training uses relatively few optimization steps, additional work on speeding up early training dynamics may be warranted.
因此,我们的结论是,随着我们以优化的计算分配方式扩大语言模型,我们应主要增加模型大小,同时通过扩大批量大小,序列步骤的数目可忽略不计。 由于计算效率高的培训利用的优化步骤相对较少,因此可能需要就加快早期培训动态开展更多工作。
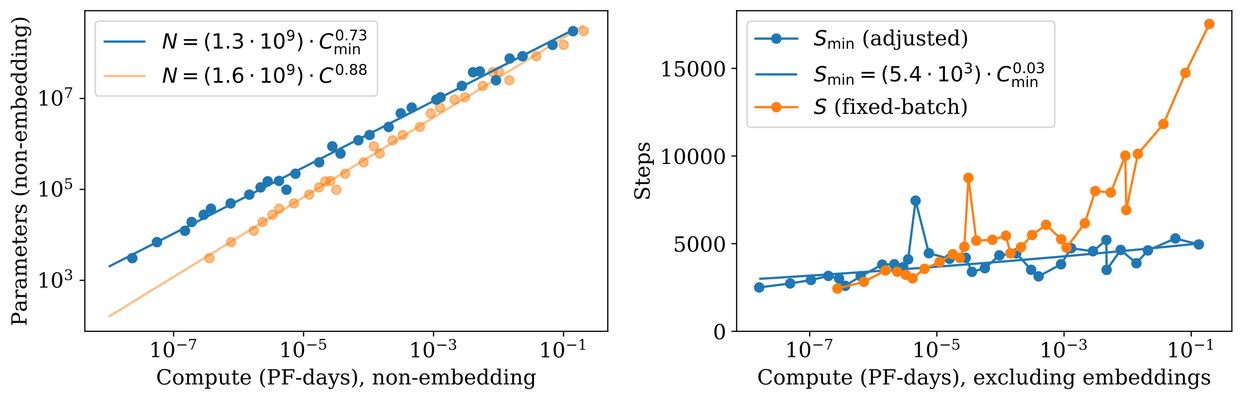
Figure 14: Left: Each value of the compute budget has an associated optimal model size . Optimal model size grows very rapidly with , increasing by 5x for each 10x increase in compute. The number of data examples processed makes up the remainder of the increase, growing relatively modestly by only 2x. Right: The batch-adjusted number of optimization steps also grows very slowly, if at all, meaning that most of the growth in data examples processed can be used for increased batch sizes.
图14:左: 计算预算的每个值都有相关的最佳模型大小. 优化模型大小随的快速增长,计算每增加10x就增加5x. 所处理的数据实例数量占了增长的其余部分,只相对略微增加了2x。 ** 权利**: 按批量调整的优化步骤的数量也增长非常缓慢,如果有的话,意味着所处理的数据示例的大部分增长可以用于增加批量大小.
6.2 Predictions from
6.2 来自 的预测
The results for and the allocations can be predicted from the equation obtained in Section 5. Given our equation for , we can substitute and then find the minimum of the loss as a function of , while fixing the training compute. We carry out this procedure in detail in Appendix B, where we also provide some additional predictions.
的结果和分配款可以从第5节中取得的方程中预测. 鉴于我们为制定的方程式,我们可以替代,然后作为的一个函数找到损失的最小值,同时确定训练计算. 我们在附录B中详细介绍了这一程序,并提供了一些额外的预测。
For the loss as a function of training compute, we predict that
对于作为训练功能的损失,我们预测
where
地点
in excellent agreement with the exponent of Figure 13. We also predict that
与图13的作者达成极好的一致。 我们还预测
which also matches the scaling of Figure 14 to within a few percent. Our scaling laws provide a predictive framework for the performance of language modeling.
也与图14的缩放率相匹配,在几率以内。 我们的缩放定律为语言建模的表现提供了一个预测性框架.
6.3 Contradictions and a Conjecture
6.3 矛盾与猜想
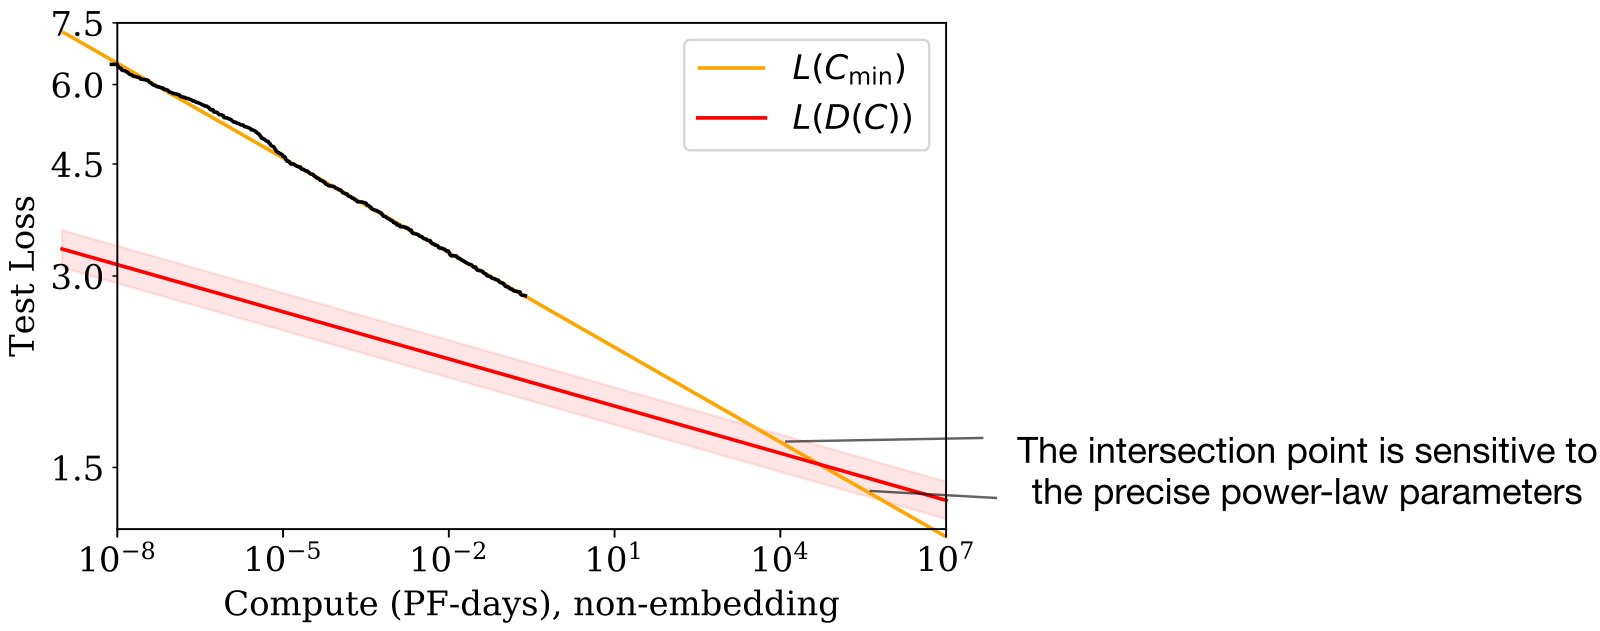
Figure 15: Far beyond the model sizes we study empirically, we find a contradiction between our equations for and due to the slow growth of data needed for compute-efficient training. The intersection marks the point before which we expect our predictions to break down. The location of this point is highly sensitive to the precise exponents from our power-law fits.
图15:远远超出我们经验研究的模型大小,我们发现,由于计算高效培训所需的数据增长缓慢,我们为和制定的方程式之间有矛盾. 交叉点标志着我们期望我们的预测破灭。 这一点的位置对我们的幂律的精确解释非常敏感。
We observe no signs of deviation from straight power-law trends at large values of compute, data, or model size. Our trends must eventually level off, though, since natural language has non-zero entropy.
我们没有观察到在计算、数据或模型大小等大值上偏离直电法趋势的迹象。 但是,我们的趋势必须最终平息下来, 因为自然语言有非零的 en。
Indeed, the trends for compute-efficient training described in this section already contain an apparent contradiction. At scales several orders of magnitude above those documented here, the performance predicted by the scaling law decreases below what should be possible given the slow growth in training data with compute. This implies that our scaling laws must break down before this point, but we conjecture that the intersection point has a deeper meaning: it provides an estimate of the point at which Transformer language models reach maximal performance.
实际上,本节所述计算效率培训的趋势已经存在明显的矛盾。 按比本文所记载的几级规模,缩放法预测的成绩低于计算培训数据缓慢增长所应达到的水平。 这意味着我们的缩放定律必须 只有在此点之前破解, 但我们猜想交叉点有更深的含义: 它提供了对Transformer语言模型达到最大性能的点的估计.
Since the amount of data used by compute-efficient training grows slowly with the compute budget, the performance predicted by eventually hits a lower bound set by the power law (see Figure 15). Let us work this out in more detail.
由于计算效率培训使用的数据量随着计算预算缓慢增长,预测的性能最终会击中幂律设定的下限(见图15). 让我们更详细地解决这个问题。
To keep overfitting under control, the results of Section 4 imply that we should scale the dataset size as
为了保持过度控制,第4节的结果意味着,我们应该将数据集的规模扩大为:
where we have used the compute-efficient from Figure 14.
其中我们使用了图14中计算效率的。
Let us compare this to the data requirements of compute-efficient training. If we train at the critical batch size (i.e. ) and never re-use data during training, we find that data usage grows with compute as
让我们将此与计算效率培训的数据要求进行比较。 如果我们按照关键批量规模(即)进行训练,在训练期间永远不重复使用数据,我们发现数据使用量随着计算增加而增加。
This is the maximum rate at which the dataset size can productively grow with compute, since it means that we are only training for a single epoch. But it grows the dataset much more slowly than in Equation (6.6). It appears to imply that compute-efficient training will eventually run into a problem with overfitting, even if the training process never re-uses any data!
这是数据集大小能够通过计算产生生产力增长的最大速度,因为它意味着我们只是为一个时代而训练。 但与方程式(6.6)相比,数据组的生长速度要慢得多. 这似乎意味着计算效率的训练最终会遇到过于适应的问题,即使训练过程从未重复使用任何数据!
According to Figure 1, we expect that when we are bottlenecked by the dataset size (ie by overfitting), the loss should scale as . This implies that the loss would scale with compute as once we are data-limited. Once again, we have a contradiction, as this will eventually intersect with our prediction for from Figure 13, where we found a scaling .
根据图1,我们预计,当我们受到数据集大小的束缚(即过度调整)时,损失应该扩大为。 这意味着,一旦数据有限,损失将按计算。 我们再次出现矛盾,因为这最终将同图13对的预测相交,我们在那里发现了一个缩放的。
The intersection point of and occurs at
和的交汇点发生在
though the numerical values are highly uncertain, varying by an order or magnitude in either direction depending on the precise values of the exponents from the power-law fits. The most obvious interpretation is that our scaling laws break down at or before we reach this point, which is still many orders of magnitude away in both compute and model size.
虽然数字值很不确定,但根据幂律给出者的确切值,在两个方向的顺序或数量上都有所不同。 最明显的解释是,我们的缩放法则在我们到达这个点之前或之前就已经崩溃了,在计算和模型规模上,这仍然是许多数量级的距离.
One might also conjecture that this intersection point has a deeper meaning. If we cannot increase the model size beyond without qualitatively different data requirements, perhaps this means that once we reach and , we have extracted all of the reliable information available in natural language data. In this interpretation, would provide a rough estimate for the entropy-per-token[^6] of natural language. In this scenario, we would expect the loss trend to level off at or before .
人们还可能猜想,这一交叉点具有更深的意义。 如果我们不能将模型的大小扩大至之外,而没有质量上的不同数据要求,也许这意味着,一旦我们达到和,我们就提取了自然语言数据中现有的所有可靠信息。 在本解释中,将提供自然语言的Entropy-per-token[^6]的粗略估计. 在此情况下,我们预计损失趋势将在之前或之前平缓。
We can guess at the functional form of as it levels off by considering a version of our training dataset with added noise. For example, we could append a random string of tokens to each context shown to the model to artificially boost the loss by a constant additive factor. Then, the distance from the noise floor would be a more meaningful performance metric, with even a small decrease in this distance potentially representing a significant boost in qualitative performance. Since the artificial noise would affect all of our trends equally, the critical point of 6.8 would not change (aside from the absolute value of ), and may be meaningful even if it occurs after the leveling off.
我们可以猜测的功能形式, 它通过考虑一个版本的训练数据 加上噪音。 例如,我们可以在模型上显示的每个上下文上附加一串随机的符号,以人为地通过一个恒定的添加系数来提升损失. 然后,与噪音底座的距离将是一个更有意义的性能衡量标准,即使这一距离小幅缩小,也有可能大大提升质量性能。 由于人工噪音将同样影响我们的所有趋势,6.8的临界点不会改变(除了的绝对值外),即使它发生在平定之后,也可能有意义。
7 Related Work
7 相关工作
Power laws can arise from a wide variety of sources [THK18]. Power-law scalings with model and dataset size in density estimation [Was06] and in random forest models [Bia12] may be connected with our results. These models suggest that power-law exponents may have a very rough interpretation as the inverse of the number of relevant features in the data.
权力定律可以从多种来源产生[THK18]. 在密度估计[Was06]和随机森林模型[Bia12]中,与模型和数据集大小的电法缩放可能与我们的结果有关。 这些模型表明,幂律论者可能有一个非常粗略的解释,认为数据中相关特征的数量是反向的.
Some early [BB01, Goo01] work found power-law scalings between performance and dataset size. More recent work [HNA+17, HAD19] also investigated scaling between model size and data size; their work is perhaps the closest to ours in the literature[^7]. Note, however, that [HNA+17] found super-linear scaling of dataset size with model size, whereas we find a sub-linear scaling. There are some parallels between our findings on optimal allocation of compute and [Kom19], including power-law learning curves. EfficientNets [TL19] also appear to obey an approximate power-law relation between accuracy and model size. Very recent work [RRBS19b] studies scaling with both dataset size and model size for a variety of datasets, and fits an ansatz similar to ours.
一些早期的[BB01,Goo01]作品在性能和数据集大小之间发现了幂律缩放. 最近的工作[HNA+17,HAD19]也调查了模型大小和数据大小之间的比例;他们的工作在文献中也许最接近我们的工作[^7]. 但请注意,[HNA+17]发现了带有模型大小的数据集大小的超线性缩放,而我们却发现了子线性缩放. 我们关于计算的最佳分配的结论与[Kom19],包括幂律学习曲线,有一些相似之处。 效率网[TL19]似乎也遵循精确度和模型大小之间的近似幂律关系。 近期的工作[RRBS19b]对各种数据集的数据集大小和模型大小进行缩放研究,并搭配了与我们相似的Assatz.
EfficientNet [TL19] advocates scaling depth and width exponentially (with different coefficients) for optimal performance of image models, resulting in a power-law scaling of width as a function of depth. We find that for language models this power should be roughly one when scaling up (as width/depth should remain fixed). But more importantly, we find that the precise architectural hyperparameters are unimportant compared to the overall scale of the language model. In [VWB16] it was argued that deep models can function as ensembles of shallower models, which could potentially explain this finding. Earlier work [ZK16] has compared width and depth, and found that wide ResNets can outperform deep ResNets on image classification. Some studies fix computation per data example, which tends to scale in proportion to the number of model parameters, whereas we investigate scaling with both model size and the quantity of training computation.
高效网[TL19]主张以指数(有不同的系数)来缩放深度和宽度,以优化图像模型的性能,从而形成作为深度函数的宽度的功率法缩放. 我们认为,对于语言模型来说,这种力量在扩大时应该大约是一个(因为宽度/深度应该保持不变)。 但更重要的是,我们发现精确的建筑超参数与语言模型的整体尺度相比并不重要. 在[VWB16]中,有人认为深层模型可以作为较浅的模型的集合体发挥作用,这有可能解释这个发现. 早期的作品[ZK16]比较了宽度和深度,发现宽度的ResNet在图像分类上可以超过深度的ResNet. 一些研究固定了每个数据示例的计算,这往往与模型参数的数量成比例,而我们则以模型大小和培训计算的数量来调查比例。
Various works [AS17, BHMM18] have investigated generalization in highly overparameterized models, finding a “jamming transition” [GJS+19] when the model size reaches the dataset size (this may require training many orders of magnitude beyond typical practice, and in particular does not use early stopping). We do not observe such a transition, and find that the necessary training data scales sublinearly in the model size. Expansions in the model size, particularly at large width [JGH18, LXS+19], may provide a useful framework for thinking about some of our scaling relations. Our results on optimization, such as the shape of learning curves, can likely be explained using a noisy quadratic model, which can provide quite accurate predictions [ZLN+19] in realistic settings. Making this connection quantitative will require a characterization of the Hessian spectrum [Pap18, GKX19, GARD18].
各种作品[AS17,BHMM18]在高度参数化的模型中调查了通用性,在模型大小达到数据集大小时发现了"jamming transition"GJS+19. 我们没有看到这种过渡,发现必要的培训数据在模型大小中是线性地缩小。 模型大小的扩大,特别是宽度较大的[JGH18,LXS+19],可以为思考我们的一些缩放关系提供一个有用的框架. 我们优化的结果,如学习曲线的形状,很可能可以用吵闹的四极模型来解释,这种模型可以在现实环境中提供相当准确的预测[ZLN+19]. 使这种连接量化将需要对黑森光谱进行定性[Pap18,GKX19,GARD18].
8 Discussion
8 讨论
We have observed consistent scalings of language model log-likelihood loss with non-embedding parameter count , dataset size , and optimized training computation , as encapsulated in Equations (1.5) and (1.6). Conversely, we find very weak dependence on many architectural and optimization hyperparameters. Since scalings with are power-laws, there are diminishing returns with increasing scale.
我们观测到,语言模型的逻辑相似性损失与非嵌入参数计算值,数据集大小,优化了培训计算值,封装在方程式(1.5)和(1.6)中. 相反,我们发现对许多建筑和优化超参数的依赖非常薄弱。 由于使用的缩放是幂律则,因此回报率随着规模的增加而不断下降.
We were able to precisely model the dependence of the loss on and , and alternatively on and , when these parameters are varied simultaneously. We used these relations to derive the compute scaling, magnitude of overfitting, early stopping step, and data requirements when training large language models. So our scaling relations go beyond mere observation to provide a predictive framework. One might interpret these relations as analogues of the ideal gas law, which relates the macroscopic properties of a gas in a universal way, independent of most of the details of its microscopic consituents.
我们精确地模拟了损失对和的依赖,以及如果这些参数同时不同,则对和的依赖。 我们利用这些关系来得出计算尺度, 过分适应的程度, 早期停止步骤, 以及训练大型语言模型的数据要求。 因此,我们的规模关系超越了单纯的观察,而提供了一个预测性框架。 人们可能将这些关系解释为理想气体法的类比,它以普遍的方式将气体的宏观性质联系起来,独立于其微观形态的大部分细节。
It is natural to conjecture that the scaling relations will apply to other generative modeling tasks with a maximum likelihood loss, and perhaps in other settings as well. To this purpose, it will be interesting to test these relations on other domains, such as images, audio, and video models, and perhaps also for random network distillation. At this point we do not know which of our results depend on the structure of natural language data, and which are universal. It would also be exciting to find a theoretical framework from which the scaling relations can be derived: a ‘statistical mechanics’ underlying the ‘thermodynamics’ we have observed. Such a theory might make it possible to derive other more precise predictions, and provide a systematic understanding of the limitations of the scaling laws.
自然可以推测,缩放关系将适用于其他生成模型制作任务,其损失概率最大,也许在其他情况下也是如此。 为此,在图像、音频和视频模型等其他领域测试这些关系,或许还可以进行随机的网络蒸馏,将很有趣。 目前,我们不知道哪些结果取决于自然语言数据的结构,哪些是普遍的。 寻找一个理论框架,从中得出比例关系,也是令人振奋的:我们观察到的“热力学”背后的“统计力学”。 这种理论可能使人们有可能得出其他更准确的预测,并系统了解缩放法的局限性。
In the domain of natural language, it will be important to investigate whether continued improvement on the loss translates into improvement on relevant language tasks. Smooth quantitative change can mask major qualitative improvements: “more is different”. For example, the smooth aggregate growth of the economy provides no indication of the specific technological developments that underwrite it. Similarly, the smooth improvements in language model loss may hide seemingly qualitative changes in capability.
在自然语言领域,必须调查持续改善损失是否转化为相关语言任务的改进。 数量上的平稳变化可以掩盖重大的质量改进:“更多的是不同的”。 例如,经济的平稳总体增长没有说明支撑经济的具体技术发展。 同样,语言模型丧失的顺利改进可能掩盖了能力似乎在质量上的变化。
Our results strongly suggest that larger models will continue to perform better, and will also be much more sample efficient than has been previously appreciated. Big models may be more important than big data. In this context, further investigation into model parallelism is warranted. Deep models can be trained using pipelining [HCC+18], which splits parameters depth-wise between devices, but eventually requires increased batch sizes as more devices are used. Wide networks on the other hand are more amenable to parallelization [SCP+18], since large layers can be split between multiple workers with less serial dependency. Sparsity [CGRS19, GRK17] or branching (e.g. [KSH12]) may allow for even faster training of large networks through increased model parallelism. And using methods like [WRH17, WYL19], which grow networks as they train, it might be possible to remain on the compute-efficient frontier for an entire training run.
我们的结果强烈表明,更大的模型将继续发挥更好的作用,而且比以前得到赞赏的样本效率要高得多。 大模型可能比大数据更重要. 在这方面,需要进一步调查模式平行主义。 深层模型可以使用管道衬线[HCC+18]进行训练,在设备之间按照深度划分参数,但随着更多设备的使用,最终需要增加批量尺寸. 另一方面,宽网更倾向于并行化[SCP+18],因为大层可以被分拆成多个工人,而序列依赖性较低. Sparsity[CGRS19,GRK17]或分支化(如[KSH12])可能允许通过增加模式平行性对大型网络进行更快的训练. 并且使用[WRH17,WYL19]等方法,这些方法在训练时会成长网络,因此可能在整个训练活动中会留在计算效率高的前沿.
Acknowledgements
致谢
We would like to thank Shan Carter, Paul Christiano, Jack Clark, Ajeya Cotra, Ethan Dyer, Jason Eisner, Danny Hernandez, Jacob Hilton, Brice Menard, Chris Olah, and Ilya Sutskever for discussions and for feedback on drafts of this work.
我们要感谢山卡特、保罗·克里斯蒂亚诺、杰克·克拉克、阿杰亚·科特拉、伊森·戴尔、杰森·艾斯纳、丹尼·赫南德斯、雅各布·希尔顿、布里斯·梅纳德、克里斯·奥拉和伊利亚·苏茨卡韦尔就这项工作的草案进行讨论和反馈。
Appendix A Summary of Power Laws
附录 A 幂律摘要
For easier reference, we provide a summary below of the key trends described throughout the paper.
为便于参考,下文概述整个文件所述的主要趋势。
| Parameters | Data | Compute | Batch Size | Equation |
|---|---|---|---|---|
| Fixed | ||||
| Early Stop | Fixed | |||
| Optimal | Fixed | (naive) | ||
| Early Stop | Fixed | |||
| steps |
Table 4:
| ** 参数** | ** 数据** | ** 计算** | ** 批量大小** | ** 公式** |
|---|---|---|---|---|
| 固定 | 第二十届 | |||
| 提早停止 | 固定 | 第二十届 | ||
| 优化 | 固定 | (无) | ||
| 第二十届 | ||||
| 提早停止 | 固定 | XX这边 | ||
| steps | XX这边 |
表 4: 国家
The empirical fitted values for these trends are:
这可是符合这些趋势的经验价值:
| Power Law | Scale (tokenization-dependent) |
|---|---|
| params (non-embed) | |
| tokens | |
| PF-days | |
| PF-days | |
| tokens | |
| steps |
Table 5:
| ** 幂律** | ** 规模(依赖抚养)** |
|---|---|
| 参数(非嵌入) | |
| 符号 | |
| 二十岁/月 | |
| 第二十届 | 二十岁/月 |
| 符号 | |
| 步骤 |
表 5: 国家
The optimal parameters for compute efficient training are given by:
计算高效培训的最佳参数如下:
| Compute-Efficient Value | Power Law | Scale |
|---|---|---|
| params | ||
| tokens | ||
| (lower bound) | steps | |
| (1 epoch) | tokens |
Table 6:
| ** 计算有效价值** | ** 幂律** | ** 比额表** |
|---|---|---|
| 第二十届 | 段落 | |
| 第二十届 | 符号 | |
| 不要 ( 下限) | XXMATH魄XX步骤 | |
| (原始内容存档于2018-09Ô). ONTHE ONTHE INTER. | 符号 |
表 6: 国家
Appendix B Empirical Model of Compute-Efficient Frontier
附录 B 算力有效前沿的经验模型
Throughout this appendix all values of and are adjusted for training at the critical batch size . We have left off the ‘adj’ label to avoid cluttering the notation.
在本附录中,对和的所有值按关键批量大小调整。 我们放弃了“adj”的标签,以避免打乱标记。
B.1 Defining Equations
B.1 界定方程
The power-law fit to the learning curves implies a simple prescription for compute-efficient training. In this appendix, we will derive the optimal performance, model size, and number of training steps as a function of the compute budget. We start with the Equation (1.6), repeated here for convenience:
适合学习曲线的幂律意味着计算效率培训的简单处方. 在本附录中,我们将根据计算预算得出最佳业绩、模式规模和培训步骤的数目。 我们从方程式(1.6)开始,为了方便在这里重复:
Here, represents the number of parameter updates when training at the critical batch size [MKAT18], which was defined in Equation (5.2)[^8]:
此处, 表示在关键批量大小** [MKAT18] 培训时更新参数的数量,定义在方程式(5.2)[^8]:
We would like to determine optimal training parameters for a fixed compute budget, so we replace , where is the number of FLOPs used in the training run:
我们想确定固定计算预算的最佳培训参数,因此我们取代,其中是训练中使用的FLOP的数量:
Now, we set to find the condition for optimality:
目前,我们把第XXMITH XX 号决议作为实现最佳发展的条件:
Equation (B.3) and (B.4) together determine the compute-efficient frontier.
公式(B.3)和(B.4)共同确定计算效率高的边界。
B.2 Efficient Training
B.2 高效训练
Now we assemble the implications of (B.3) and (B.4). First, note that inserting (B.4) into (B.3) yields
现在我们总结(B.3)和(B.4)的影响。 首先,注意在(B.3)产量中插入(B.4)
which implies that for compute-efficient training, we should train to a fixed percentage above the converged loss. Next, let’s determine how the optimal loss depends on the compute budget. Eliminating yields a power-law dependence of performance on compute:
这意味着,对于计算效率的训练,我们应进行培训,使其达到高于合并损失的** 固定百分比** 。 接下来,让我们确定最佳损失如何取决于计算预算。 消除第号令在业绩上依赖于计算:
where we defined
在那里,我们定义
Similarly, we can eliminate to find :
同样,我们可以删除,找到:
and
和
B.3 Comparison to Inefficient
B.3 与低效率情形比较
Typically, researchers train models until they appear to be close to convergence. In this section, we compare the efficient training procedure described above to this more typical setup. We define a the convergence factor as the percent deviation from the converged loss:
通常情况下,研究人员会训练模型,直到它们看起来接近趋同. 在本节中,我们将上述高效训练流程与这种更为典型的设置进行比较。 我们把的趋同系数定义为与趋同损失的百分比偏差:
For compute-efficient training we have from the previous section, but researchers typically use a much smaller value. Here, we choose as an estimate. For a fixed value of the loss, we predict:
对于计算效率的训练,我们从上一节有了,但研究者通常使用的数值要小得多。 在这里,我们选择作为估算. 关于损失的固定价值,我们预测:
So that compute-efficient training uses 7.7x fewer parameter updates, 2.7x more parameters, and 65% less compute to reach the same loss.
这样计算效率的训练使用7.7x更少的参数更新,2.7x多的参数,65%的计算达到同样的损失.
B.4 Suboptimal Model Sizes
B.4 非最优模型规模
We can solve A.1 to find an expression for the amount of compute needed to reach a given value of the loss with a model of size :
我们可以用一个大小为的模型解决A.1,以找到达到损失特定值所需的计算量的表达式:
Using A.6 and A.9, we can eliminate in favor of , the model size which reaches most efficiently. From there, we find an expression for the excess compute needed as a consequence of using a suboptimal model size:
使用A.6和A.9,我们可以取消,而采用,这个模型尺寸最能达到。 我们从中找到一种表达方式,来表示由于使用非最佳模型尺寸而需要的过量计算:
The result is shown in Figure X. Models between 0.6x and 2.2x the optimal size can be used with only a 20% increase in compute budget. Using a smaller model is useful when accounting for the cost inference. A larger model can be trained the the same level of performance in fewer steps, allowing for more parallelism and faster training if sufficient harware is available (see Figure Y):
结果如图十所示,在0.6x到2.2x之间的模型,在计算预算只增加20%的情况下,可以使用最佳尺寸. 在计算成本推论时,使用较小的模型是有用的。 一个较大的模型可以在更少的 54. 步绫中接受相同的性能训练,如果有足够的哈瓦雷(见图Y):
A 2.2x larger model requires 45% fewer steps at a cost of 20% more training compute. Note that this equation should not be trusted for very large models, as it is only valid in the power-law region of the learning curve after initial transient effects.
一个2.2x更大的型号需要减少45%的步数,而增加20%的培训计算。 请注意,这种方程不应该被信任于非常大的模型,因为它只有在初始瞬态效应后在学习曲线的幂律区有效.
Appendix C Caveats
附录 C 注意事项
In this section we list some potential caveats to our analysis.
在本节中,我们列出我们的分析中的一些可能的告诫。
- • At present we do not have a solid theoretical understanding for any of our proposed scaling laws. The scaling relations with model size and compute are especially mysterious. It may be possible to understand scaling at very large holding model size fixed [AS17], and also the shape of learning curves late in training, by modeling the loss with a noisy quadratic. But the scaling with at very large model size still remains mysterious. Without a theory or a systematic understanding of the corrections to our scaling laws, it’s difficult to determine in what circumstances they can be trusted.
- • We are not especially confident in the prediction of for values of the loss far outside the range we have explored. Changes in could have a significant impact on trade-offs between data parallelism and the number of serial training steps required, which would have a major impact on training time.
- • We did not thoroughly investigate the small data regime, and our fits for were poor for the smallest values of (where an epoch corresponded to only steps). Furthermore, we did not experiment with regularization and data augmentation. Improvements in these could alter our results, quantitatively or qualitatively.
- • We used the estimated training compute , which did not include contributions proportional to (see Section 2.1). So our scalings with compute may be confounded in practice in the regime of very large , specifically where .
- • We tuned learning rates, and we experimented with learning rate schedules. But we may have neglected to tune some hyperparameter (e.g. intialization scale or momentum) that have an important effect on scaling.
- • The optimal choice of learning rate is sensitive to the target loss. When training close to convergence, it may be necessary to use a smaller learning rate to avoid divergences. But when conducting a short training run (eg due to compute limitations), it may be possible to use a larger learning rate. We did not experiment with higher learning rates for training runs that did not proceed to convergence.
- 目前,我们还没有对我们提出的任何规模法有坚实的理论理解。 与模型大小和计算之间的缩放关系特别神秘. 可以通过使用吵闹的四面体模型模拟损失,了解在非常大的上缩放固定模型尺寸[AS17],以及学习曲线在训练后期的形状。 但与在非常大的模型尺寸上的缩放仍然神秘. 没有理论或系统理解我们的缩放定律,
- 我们并不特别相信对远超出我们探索范围的损失值的的预测。 的改变可能对数据并行性和所需系列培训步骤的数目之间的权衡产生重大影响,这将对训练时间产生重大影响。
- 我们没有彻底调查小数据制度,而我们对于的适值是最小的(一个时代只相当于步骤)。 此外,我们没有试验正规化和数据扩充。 这些方面的改进可能会在数量上或质量上改变我们的成果。
- 我们使用估计培训计算值的,其中不包括与成比例的捐款(见第2.1节)。 因此,在非常大的制度下,特别是在制度下,我们用计算法的缩放可能在实践中令人困惑。
- 我们调整了学习率,并试验了学习率时间表。 但我们可能忽略了调谐一些对缩放有重要影响的超参数(如插入尺度或动力).
- 最佳的学习率选择对目标损失敏感。 当培训接近趋同时,可能有必要使用较小的学习率来避免分歧。 但在进行短期训练(例如由于计算限制)时,可能采用较大的学习率. 我们没有试验没有走向趋同的高等教育率。
Appendix D Supplemental Figures
附录 D 补充图表
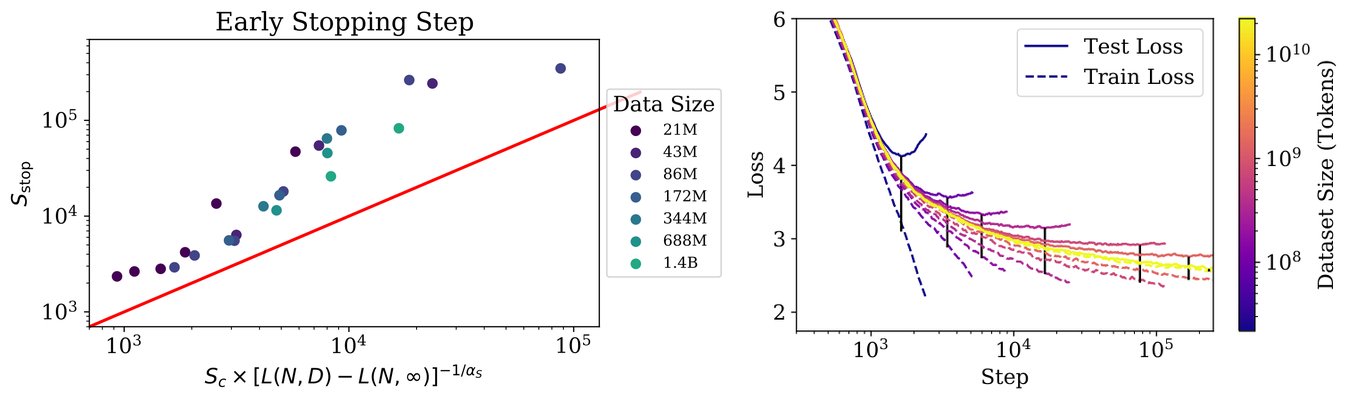
Figure 16: Left: We characterize the step on which early stopping occurs, as a function of the extent of overfitting. The red line indicates a lower bound for early stopping that is derived in Section 5.3. Right: We display train and test loss for a series of 300M parameter models trained on different sized dataset sub-samples. The test loss typically follows that of a run done with unrestricted data until diverging. Note that the degree of overfitting (as compared to the infinite data limit) is significantly overestimated by (denoted by a black bar for each run).
图16:左: 我们把发生早停的步骤定性为与过拟合的程度有关。 红线表示早期停止的下限,这是第5.3节衍生出来的. ** 权利**: 我们显示列车和测试损失 一系列300M参数模型 训练不同的大小数据集子样本。 测试损失通常沿用无限制数据进行运行直至出现差异。 请注意,(每跑一次用黑色栏标注)对过度调整的程度(与无限数据限制相比)的估算明显过高.
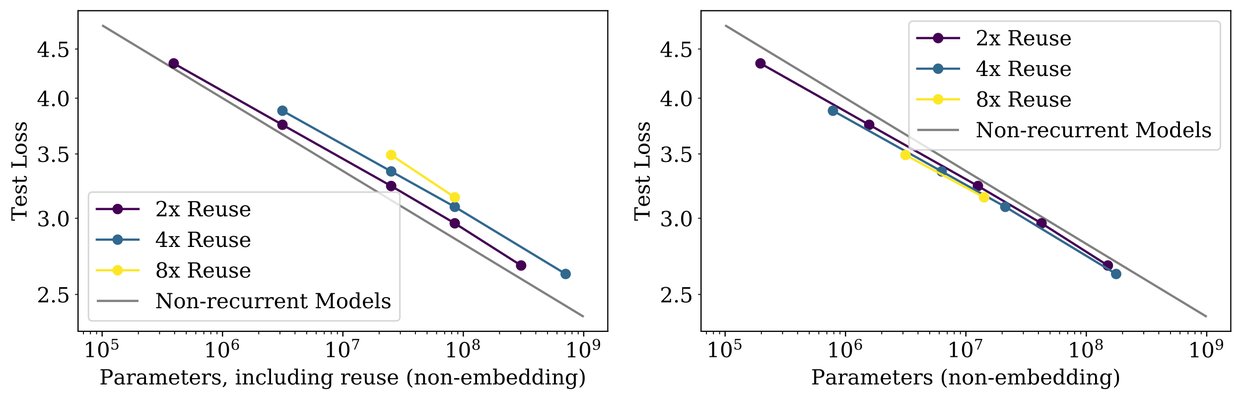
Figure 17: We compare recurrent Transformers [DGV+18], which re-use parameters, to standard Transformers. Recurrent Transformers perform slightly better when comparing models with equal parameter count, but slightly worse when accounting for reuse and comparing per FLOP.
图17:我们把重复使用的变换器[DGV+18],再使用参数,与标准变换器进行比较. 经常变换器在将模型与等参数计数进行比较时表现略好,但在计算再利用和比较每个FLOP时表现略差.
D.1 Early Stopping and Test vs Train
D.1 早停与试验到训练
In section 5.3 we described the result shown in Figure 16, which provides a prediction for a lower bound on the early stopping step. We also show the train and test loss for a given model size when training on different sized datasets.
在第5.3节中,我们描述了图16所示的结果,图16预测了早期停止步骤的下限。 我们还在对不同大小的数据集进行培训时,显示某一模型大小的列车和测试损失。
D.2 Universal Transformers
D.2 通用 Transformer
We compare the performance of standard Transformers to recurrent Transformers [DGV+18] in Figure 17. These models re-use parameters, and so perform slightly better as a function of , but slightly worse as a function of compute . We include several different different possibilities for parameter re-use.
我们在图17中将标准Transformer的性能与经常性Transformer[DGV+18]进行比较. 为什么不使用这些模型? 这些模型重新使用参数,因此,作为的函数性能稍好,但作为计算的函数性能稍差. 我们列入了若干不同的参数再使用的可能性。
D.3 Batch Size
D.3 有利设置
We measure the critical batch size using the data displayed in figure 18. This made it possible to estimate in figure 10.
我们利用图18中显示的数据测量批量临界大小。 这使得有可能在图10中估计。
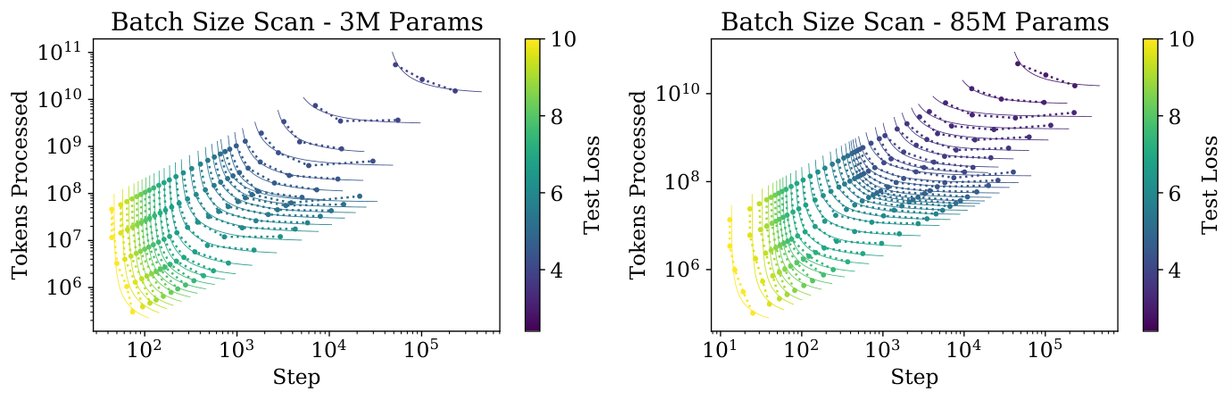
Figure 18: These figures demonstrate fits to Equation (5.1) for a large number of values of the loss , and for two different Transformer model sizes. These fits were used to measure for Figure 10.
图18:这些数字表明,在损失的的大量值和两个不同的Transformer模型尺寸方面,与方程式(5.1)相符。 这些适合度用于对图10的进行测量。
D.4 Sample Efficiency vs Model Size
D.4 模型规模
It is easy to see from figure 2 that larger models train faster, and are therefore more sample efficient. We provide another way of looking at this phenomenon in figure 19, which shows when different models reach various fixed values of the loss.
从图2中可以很容易地看到,较大的模型的运行速度更快,因此更具有样本效率. 我们在图19中提供了另一种看待这一现象的方法,表明不同的模型何时达到损失的各种固定值。
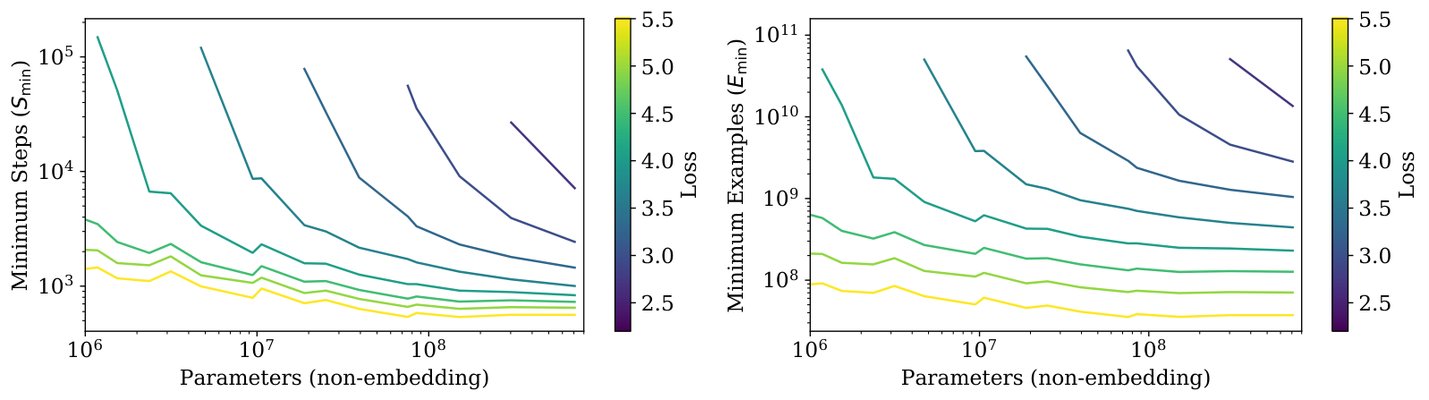
Figure 19: The number of minimum serial steps needed to reach any fixed value of the test loss decreases precipitously with model size. Sample efficiency (show here for training far below the critical batch size) improves greatly as well, improving by a factor of almost 100 when comparing the smallest possible model to a very large one.
图19:达到试验损失的任何固定值所需的最低序列步骤的数目随模型大小而急剧减少。 抽样效率(此处显示的培训远远低于批量规模)也大大提高,在比较最小的可能模式和非常大的模式时,提高了近100倍。
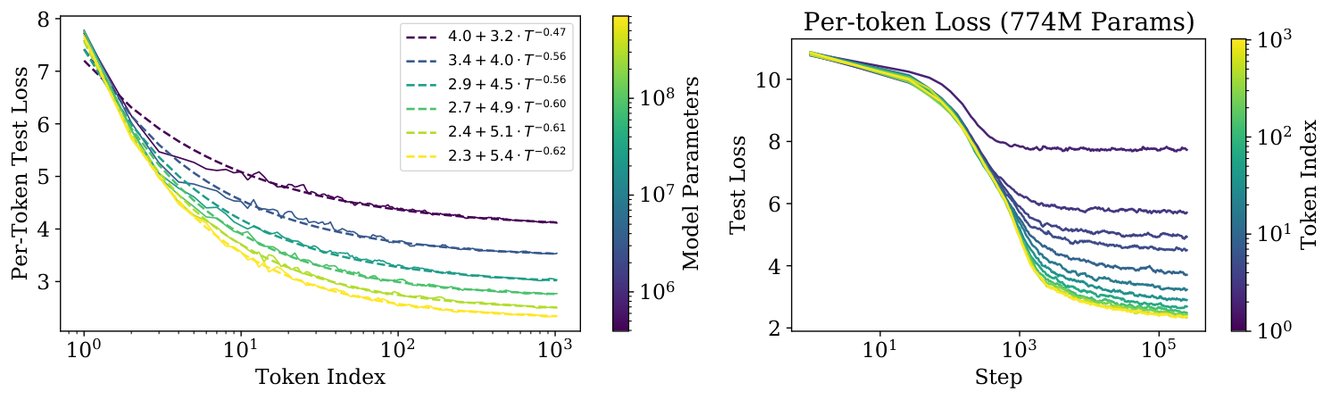
Figure 20: This figure provides information about the performance per token as a function of model size and training time. Left: Loss per token as a function of its position in the 1024-token context. Loss scales predictably as a power-law in . Right: Test loss per token as a function of training step.
图20:这个数字提供了每个标志的性能信息,作为模型大小和训练时间的函数. ** 左边:** 1024-token语境中,每个令牌损失是其位置的一个函数. 在中,作为幂律的损失可以预测。 ** 作为培训步骤的一项功能,测试每个标志的损失。
D.5 Context Dependence
D.5 上下文依赖
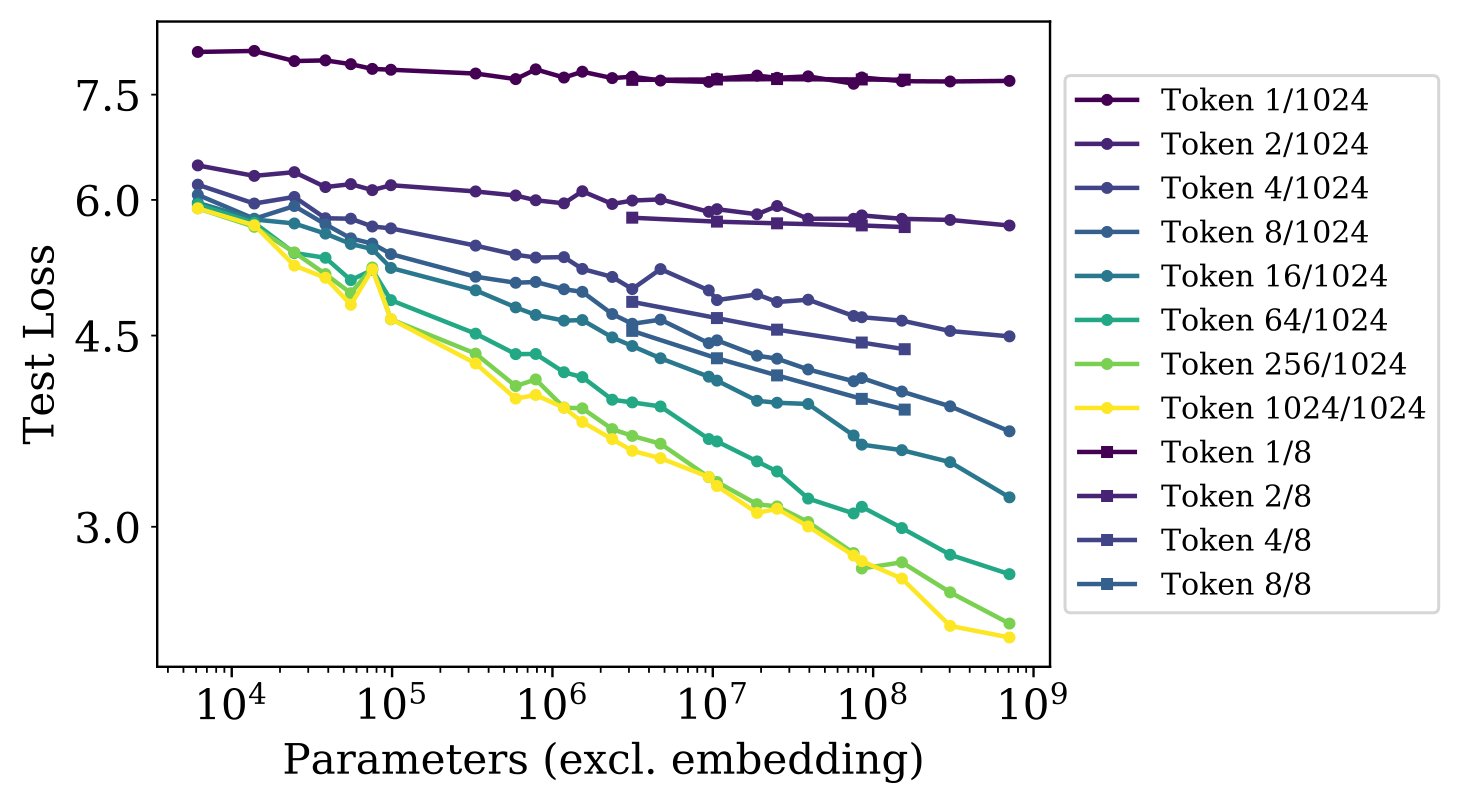
Figure 21: In addition to the averaged loss, individual tokens within the 1024-token context also improve smoothly as model size increases. Training runs with shorter context (dashed lines) perform better on early tokens, since they can allocate all of their capacity to them.
图21:除平均损失外,1024-token范围内的单个代币也随着模型大小的增加而平稳改善. 培训内容较短的(线条)在早期的标志上表现较好,因为他们可以把全部能力分配给他们。
The trends for loss as a function of model size are displayed for different tokens in the context in Figure 21. We see that models trained on show steady improvement with model size on all but the first token.
在图21的上下文中,显示不同符号的损失趋势作为模型大小的函数。 我们看到,在上接受过训练的模型显示,除了第一标志外,所有模型都稳步改进。
Fixing model size, it appears that the loss scales as a power-law as a function of position in the context, see Figure 20. This may be a consequence of underlying power-law correlations in language [EP94, ACDE12, LT16], or a more general feature of the model architecture and optimization. It provides some suggestion for the potential benefits (or lack thereof) from training on larger contexts. Not only do larger models converge to better performance at , but they also improve more quickly at early tokens, suggesting that larger models are more efficient at detecting patterns with less contextual information. In the right-hand plot we show how per-token performance varies for a fixed model as a function of the training step. The model begins by learning short-range information, and only learns longer-range correlations later in training.
修复模型大小,损失尺度似乎作为动力定律作为上下文中位置的函数,见图20。 这可能是语言中基础性的幂律相关性[EP94, ACDE12, LT16] 的结果,或者是模型架构和优化的一个更普遍的特征. 它就大背景培训的潜在好处(或缺乏好处)提出了一些建议。 不仅大型模型在上趋同到更好的性能,而且在早期的标语上也会更快的改进,这表明大型模型在发现图案时更有效率,背景信息较少. 在右侧的图中,我们显示一个固定模型作为训练步骤的一个功能,每个脚趾的性能如何变化。 该模型从学习短程信息开始,只在后来的训练中学习较长距离的关联性.
We have also included models trained with a tiny context in order to compare with our longer context models. Even modestly sized models trained on can dominate our largest models on very early tokens. This also suggests that further improvements should be possible with much larger models trained on large contexts.
我们还包括了经过微小背景培训的模型,以便与我们较长的背景模型进行比较。 即使是在上受过训练的尺寸不大的模型,也能在非常早的征兆上主宰我们最大的模型. 这也表明,如果对大范围模式进行培训,就有可能进一步改进。
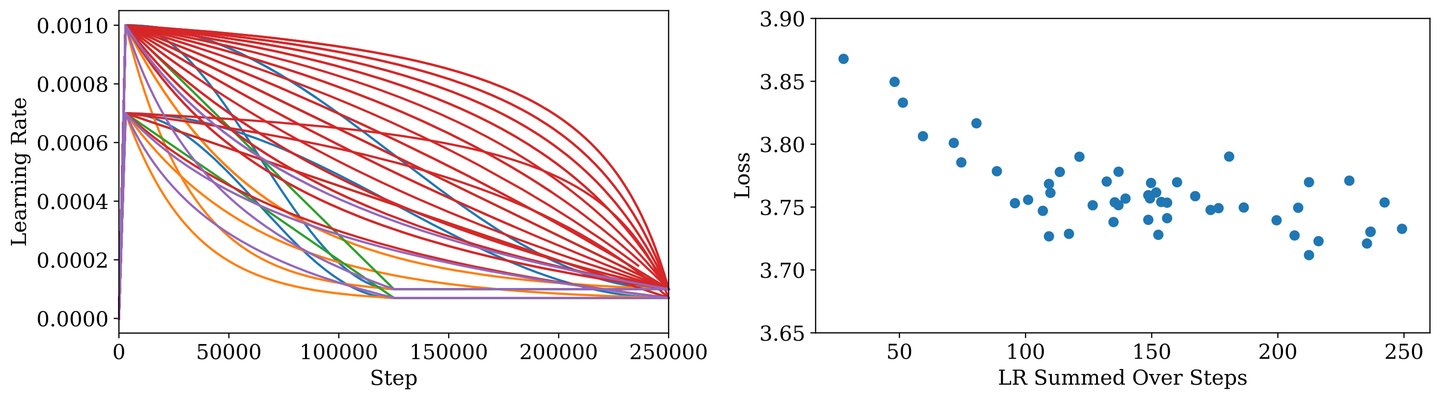
Figure 22: We test a variety of learning rate schedules including cosine decay, linear decay, as well as other faster/slower decays schedules on a 3 million parameter model, shown on the left. For these experiments we do not decay to zero, since we find that this tends to give a fixed improvement close to the end of training. We find that, as long as the learning rate is not too small and does not decay too quickly, performance does not depend strongly on learning rate. Run-to-run variation is at the level of 0.05 in the loss, so averaging multiple runs is necessary to validate performance changes smaller than this level.
图22:我们测试各种学习速率表,包括余弦衰减,线性衰减,以及左侧显示的300万个参数模型上的其他较快/较慢的衰减速率表. 对于这些实验,我们不会衰减到零,因为我们发现这往往会给接近训练结束的固定改进. 我们发现,只要学习率不太小,也不会太快衰败,表现就不会严重依赖学习率. 运行到运行的变异在损失中为0.05级,因此平均多运行对于验证低于该级的性能变化是必要的.
D.6 Learning Rate Schedules and Error Analysis
D.6 学习率日程与误差分析
We experimented with a variety of learning rates and schedules. A host of schedules and resulting test performances for a small language model are plotted in Figure 22. We conclude that the choice of learning rate schedule is mostly irrelevant, as long as the total summed learning rate is sufficiently large, and the schedule includes a warmup period and a final decay to near-vanishing learning rate. Variations among schedules appear to be statistical noise, and provide a rough gauge for the scale of variation between different training runs. Experiments on larger models suggest that the variation in the final test loss between different random seeds is roughly constant in magnitude for different model sizes.
我们试验了各种学习率和时间表。 图22绘制了小语言模型的一系列时间表和由此产生的测试性能。 我们的说法是,只要总和的学习率足够大,学习率表的选择大多无关紧要,而且学习率表包括一个温暖期和最后衰减到接近畅销的学习率。 时间表之间的差异似乎是统计噪音,对不同培训活动之间的差异程度作了粗略的衡量。 对较大模型的实验表明,不同随机种子之间最终测试损失的变异,对于不同的模型大小来说大致是恒定的.
We found that larger models require a smaller learning rate to prevent divergence, while smaller models can tolerate a larger learning rate. To implement this, the following rule of thumb was used for most runs:
我们发现,较大的模型需要较小的学习率来防止差异,而较小的模型可以容忍更大的学习率. 为了执行这一点,在大多数运行中使用了以下拇指规则:
We expect that this formula could be improved. There may be a dependence on network width, likely set by the initialization scale. The formula also breaks down for parameters. Nevertheless, we found that it works sufficiently well for the models we considered.
我们期望这一办法能够得到改进。 可能会依赖网络宽度,可能由初始化尺度设定. 该公式还细分为参数. 然而,我们发现,这对我们所考虑的模式来说是相当有效的。
D.7 Fit Details and Power Law Quality
D.7 拟合细节与幂律质量
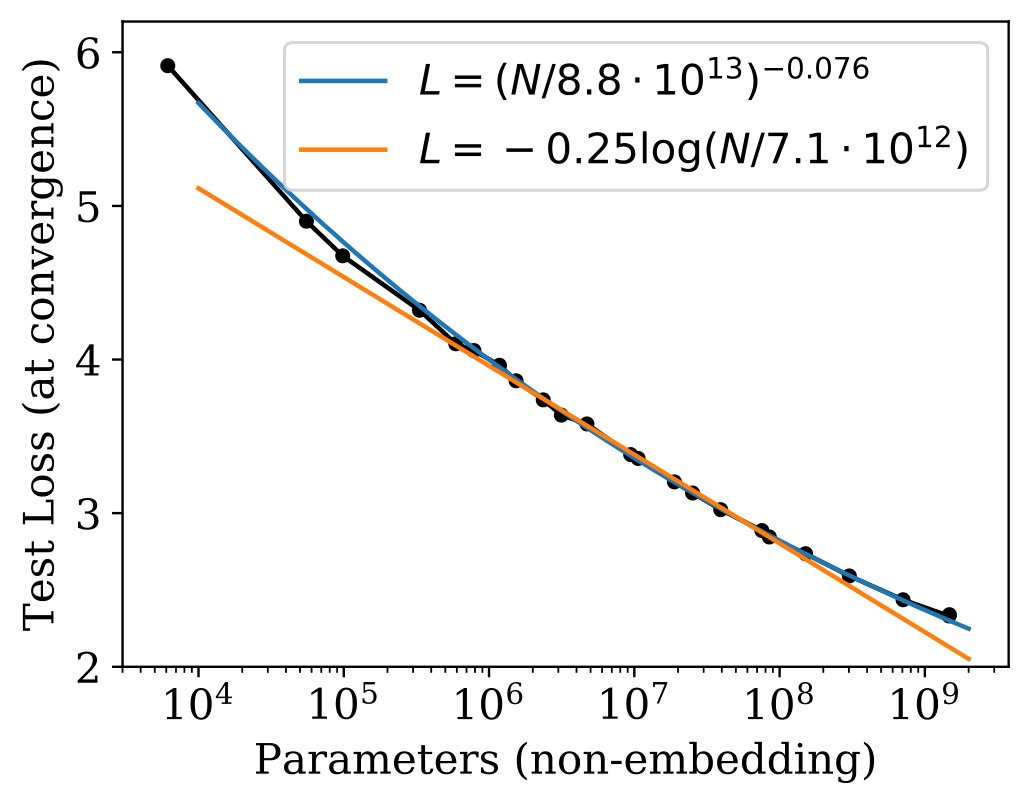
Figure 23: The trend for performance as a function of parameter count, , is fit better by a power law than by other functions such as a logarithm at a qualitative level.
图23:作为参数计数函数的性能趋势,,比起质量级对数等其他函数,幂律更适合.
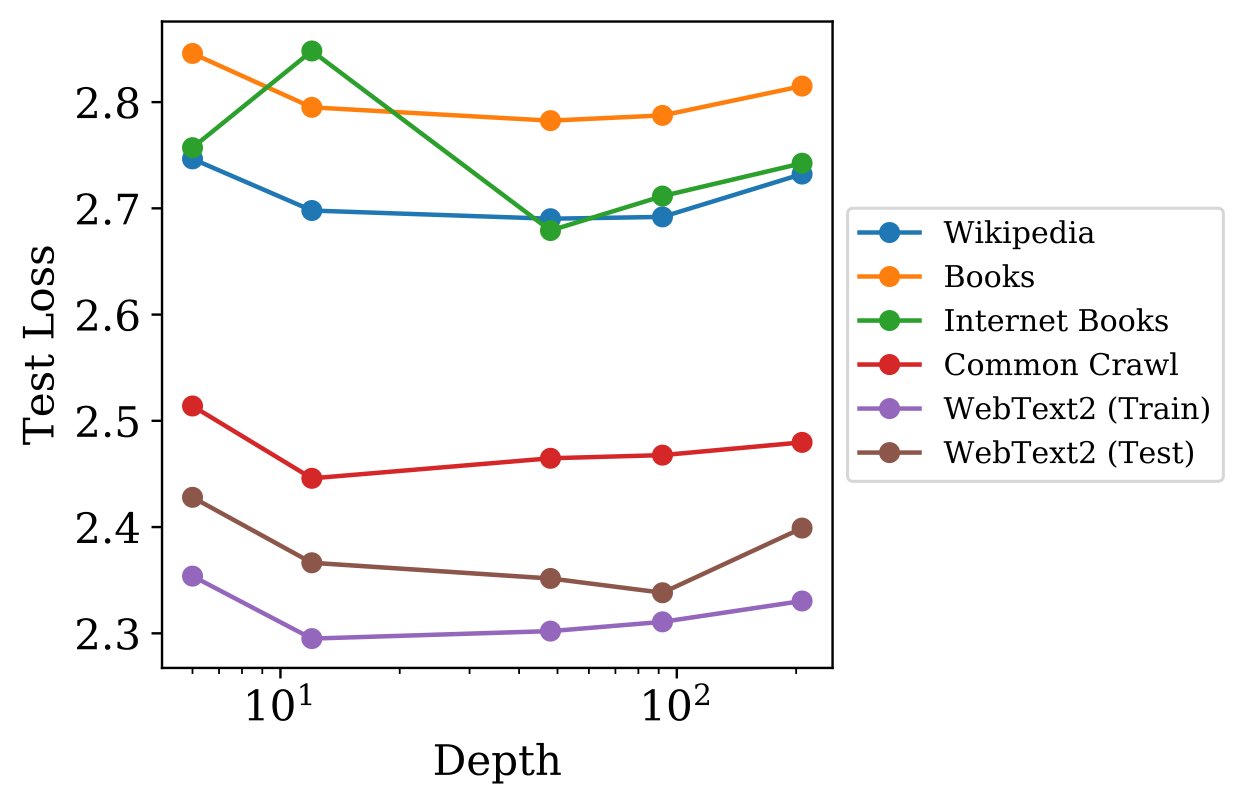
Figure 24: We show evaluations on a series of datasets for models with approximately 1.5 Billion parameters. We observe no effect of depth on generalization; generalization performance depends primarily on training distribution performance. The 12-layer model overfit the Internet Books dataset and we show the early-stopped performance; we have not seen this surprising result in other experiments.
图24:我们显示对大约1.5亿参数的模型的一系列数据集的评价。 我们没有看到深度对一般化的影响;一般化的表现主要取决于培训分配的表现。 12层模型过拟合了互联网图书数据集,我们展示了早期停止的性能;我们没有看到这种令人惊讶的结果在其他实验中.
We experimented with a number of functional forms for the fits to , and ; the power-law fits were qualitatively much more accurate than other functions such as logarithms (see Figure 23).
我们试验了若干功能形式,以适应和;与对数等其他功能相比,电源法在质量上更为准确(见图23)。
For , we do not include small models with only 1 layer in the fit, as the transition from 1 to 2 layers causes a noticable lump in the data. For we also do not include very small models with only 1 layer in the fit, and we exclude the largest models that have not trained fully to convergence. Fit parameters change marginally if we do include them, and the trend extrapolates well in both directions regardless.
对于,我们不包括只有1层的小型模型,因为从1层到2层的过渡导致数据中出现一个引人注目的整块. 对于,我们也不包括只有1层的非常小的模型,我们排除了还没有充分训练来趋同的最大模型. 如果我们确实包括这些参数,适切的参数就会略有变化,而且无论如何,趋势在两个方向上都推断良好。
D.8 Generalization and Architecture
D.8 概况与架构
In figure 24 we show that generalization to other data distributions does not depend on network depth when we hold the total parameter count fixed. It seems to depend only on the performance on the training distribution.
在图24中,我们显示,当我们保留总参数数时,对其他数据分布的概括并不取决于网络深度。 这似乎只取决于培训分配的表现。
References
参考文献
[ACDE12] Eduardo G Altmann, Giampaolo Cristadoro, and Mirko Degli Esposti. On the origin of long-range correlations in texts. Proceedings of the National Academy of Sciences , 109(29):11582–11587, 2012.
[AS17] Madhu S. Advani and Andrew M. Saxe. High-dimensional dynamics of generalization error in neural networks. arXiv , 2017, 1710.03667 .
[BB01] Michele Banko and Eric Brill. Scaling to very very large corpora for natural language disambiguation. In Proceedings of the 39th annual meeting on association for computational linguistics , pages 26–33. Association for Computational Linguistics, 2001.
[BHMM18] Mikhail Belkin, Daniel Hsu, Siyuan Ma, and Soumik Mandal. Reconciling modern machine learning and the bias-variance trade-off. arXiv , 2018, 1812.11118 .
[Bia12] GÊrard Biau. Analysis of a random forests model. Journal of Machine Learning Research , 13(Apr):1063–1095, 2012.
[CGRS19] Rewon Child, Scott Gray, Alec Radford, and Ilya Sutskever. Generating long sequences with sparse transformers. CoRR , abs/1904.10509, 2019, 1904.10509 . URL http://arxiv.org/abs/1904.10509 .
[DCLT18] Jacob Devlin, Ming-Wei Chang, Kenton Lee, and Kristina Toutanova. Bert: Pre-training of deep bidirectional transformers for language understanding, 2018, arXiv:1810.04805 .
[DGV + 18] Mostafa Dehghani, Stephan Gouws, Oriol Vinyals, Jakob Uszkoreit, and Lukasz Kaiser. Universal transformers. CoRR , abs/1807.03819, 2018, 1807.03819 . URL http://arxiv.org/abs/1807.03819 .
[EP94] Werner Ebeling and Thorsten Pöschel. Entropy and long-range correlations in literary english. EPL (Europhysics Letters) , 26(4):241, 1994.
[Fou] The Common Crawl Foundation. Common crawl. URL http://commoncrawl.org .
[GARD18] Guy Gur-Ari, Daniel A. Roberts, and Ethan Dyer. Gradient descent happens in a tiny subspace. 2018, arXiv:1812.04754 .
[GJS + 19] Mario Geiger, Arthur Jacot, Stefano Spigler, Franck Gabriel, Levent Sagun, Stéphane d’Ascoli, Giulio Biroli, Clément Hongler, and Matthieu Wyart. Scaling description of generalization with number of parameters in deep learning. arXiv , 2019, 1901.01608 .
[GKX19] Behrooz Ghorbani, Shankar Krishnan, and Ying Xiao. An investigation into neural net optimization via hessian eigenvalue density. CoRR , abs/1901.10159, 2019, 1901.10159 . URL http://arxiv.org/abs/1901.10159 .
[Goo01] Joshua Goodman. A bit of progress in language modeling. CoRR , cs.CL/0108005, 2001. URL http://arxiv.org/abs/cs.CL/0108005 .
[GRK17] Scott Gray, Alec Radford, and Diederik P Kingma. Gpu kernels for block-sparse weights. openai.com , 2017.
[HAD19] Joel Hestness, Newsha Ardalani, and Gregory Diamos. Beyond human-level accuracy: Computational challenges in deep learning. In Proceedings of the 24th Symposium on Principles and Practice of Parallel Programming , PPoPP ’19, pages 1–14, New York, NY, USA, 2019. ACM. doi:10.1145/3293883.3295710 .
[HCC + 18] Yanping Huang, Yonglong Cheng, Dehao Chen, HyoukJoong Lee, Jiquan Ngiam, Quoc V. Le, and Zhifeng Chen. Gpipe: Efficient training of giant neural networks using pipeline parallelism. CoRR , abs/1811.06965, 2018, 1811.06965 . URL http://arxiv.org/abs/1811.06965 .
[HNA + 17] Joel Hestness, Sharan Narang, Newsha Ardalani, Gregory Diamos, Heewoo Jun, Hassan Kianinejad, Md. Mostofa Ali Patwary, Yang Yang, and Yanqi Zhou. Deep learning scaling is predictable, empirically, 2017, 1712.00409 .
[JGH18] Arthur Jacot, Franck Gabriel, and Clément Hongler. Neural tangent kernel: Convergence and generalization in neural networks. In Advances in neural information processing systems , pages 8571–8580, 2018.
[KB14] Diederik P. Kingma and Jimmy Ba. Adam: A method for stochastic optimization, 2014, 1412.6980 .
[Kom19] Aran Komatsuzaki. One epoch is all you need, 2019, arXiv:1906.06669 .
[KSH12] Alex Krizhevsky, Ilya Sutskever, and Geoffrey E. Hinton. Imagenet classification with deep convolutional neural networks. In Proceedings of the 25th International Conference on Neural Information Processing Systems - Volume 1 , NIPS’12, pages 1097–1105, USA, 2012. Curran Associates Inc. URL http://dl.acm.org/citation.cfm?id=2999134.2999257 .
[LCG + 19] Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, and Radu Soricut. Albert: A lite bert for self-supervised learning of language representations, 2019, 1909.11942 .
[LOG + 19] Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, and Veselin Stoyanov. Roberta: A robustly optimized BERT pretraining approach. CoRR , abs/1907.11692, 2019, 1907.11692 . URL http://arxiv.org/abs/1907.11692 .
[LSP + 18] Peter J. Liu, Mohammad Saleh, Etienne Pot, Ben Goodrich, Ryan Sepassi, Lukasz Kaiser, and Noam Shazeer. Generating wikipedia by summarizing long sequences. arXiv:1801.10198 [cs] , 2018, 1801.10198 . URL http://arxiv.org/abs/1801.10198 .
[LT16] Henry W Lin and Max Tegmark. Criticality in formal languages and statistical physics. arXiv preprint arXiv:1606.06737 , 2016.
[LXS + 19] Jaehoon Lee, Lechao Xiao, Samuel S. Schoenholz, Yasaman Bahri, Roman Novak, Jascha Sohl-Dickstein, and Jeffrey Pennington. Wide neural networks of any depth evolve as linear models under gradient descent, 2019, arXiv:1902.06720 .
[MKAT18] Sam McCandlish, Jared Kaplan, Dario Amodei, and OpenAI Dota Team. An empirical model of large-batch training, 2018, arXiv:1812.06162 .
[Pap18] Vardan Papyan. The full spectrum of deep net hessians at scale: Dynamics with sample size. CoRR , abs/1811.07062, 2018, 1811.07062 . URL http://arxiv.org/abs/1811.07062 .
[RNSS18] Alec Radford, Karthik Narasimhan, Tim Salimans, and Ilya Sutskever. Improving language understanding by generative pre-training. URL https://s3-us-west-2. amazonaws. com/openai-assets/research-covers/languageunsupervised/language understanding paper. pdf , 2018.
[RRBS19a] Jonathan S. Rosenfeld, Amir Rosenfeld, Yonatan Belinkov, and Nir Shavit. A constructive prediction of the generalization error across scales, 2019, 1909.12673 .
[RRBS19b] Jonathan S. Rosenfeld, Amir Rosenfeld, Yonatan Belinkov, and Nir Shavit. A constructive prediction of the generalization error across scales, 2019, arXiv:1909.12673 .
[RSR + 19] Colin Raffel, Noam Shazeer, Adam Roberts, Katherine Lee, Sharan Narang, Michael Matena, Yanqi Zhou, Wei Li, and Peter J. Liu. Exploring the limits of transfer learning with a unified text-to-text transformer, 2019, arXiv:1910.10683 .
[RWC + 19] Alec Radford, Jeff Wu, Rewon Child, David Luan, Dario Amodei, and Ilya Sutskever. Language models are unsupervised multitask learners. openai.com , 2019.
[SCP + 18] Noam Shazeer, Youlong Cheng, Niki Parmar, Dustin Tran, Ashish Vaswani, Penporn Koanantakool, Peter Hawkins, HyoukJoong Lee, Mingsheng Hong, Cliff Young, Ryan Sepassi, and Blake Hechtman. Mesh-tensorflow: Deep learning for supercomputers, 2018, 1811.02084 .
[SHB15] Rico Sennrich, Barry Haddow, and Alexandra Birch. Neural machine translation of rare words with subword units. CoRR , 2015, 1508.07909 .
[SLA + 18] Christopher J. Shallue, Jaehoon Lee, Joe Antognini, Jascha Sohl-Dickstein, Roy Frostig, and George E. Dahl. Measuring the effects of data parallelism on neural network training, 2018, arXiv:1811.03600 .
[SS18] Noam Shazeer and Mitchell Stern. Adafactor: Adaptive learning rates with sublinear memory cost. CoRR , abs/1804.04235, 2018, 1804.04235 . URL http://arxiv.org/abs/1804.04235 .
[THK18] Stefan Thurner, Rudolf Hanel, and Peter Klimek. Introduction to the theory of complex systems . Oxford University Press, 2018.
[TL19] Mingxing Tan and Quoc V. Le. Efficientnet: Rethinking model scaling for convolutional neural networks. CoRR , abs/1905.11946, 2019, 1905.11946 . URL http://arxiv.org/abs/1905.11946 .
[VSP + 17] Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Ł ukasz Kaiser, and Illia Polosukhin. Attention is all you need. In I. Guyon, U. V. Luxburg, S. Bengio, H. Wallach, R. Fergus, S. Vishwanathan, and R. Garnett, editors, Advances in Neural Information Processing Systems 30 , pages 5998–6008. Curran Associates, Inc., 2017. URL http://papers.nips.cc/paper/7181-attention-is-all-you-need.pdf .
[VWB16] Andreas Veit, Michael Wilber, and Serge Belongie. Residual networks behave like ensembles of relatively shallow networks, 2016, arXiv:1605.06431 .
[Was06] Larry Wasserman. All of nonparametric statistics . Springer Science & Business Media, 2006.
[WPN + 19] Alex Wang, Yada Pruksachatkun, Nikita Nangia, Amanpreet Singh, Julian Michael, Felix Hill, Omer Levy, and Samuel R. Bowman. Superglue: A stickier benchmark for general-purpose language understanding systems, 2019, 1905.00537 .
[WRH17] Yu-Xiong Wang, Deva Ramanan, and Martial Hebert. Growing a brain: Fine-tuning by increasing model capacity. 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) , Jul 2017. doi:10.1109/cvpr.2017.323 .
[WYL19] Wei Wen, Feng Yan, and Hai Li. Autogrow: Automatic layer growing in deep convolutional networks, 2019, 1906.02909 .
[YDY + 19] Zhilin Yang, Zihang Dai, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, and Quoc V. Le. Xlnet: Generalized autoregressive pretraining for language understanding, 2019, arXiv:1906.08237 .
[ZK16] Sergey Zagoruyko and Nikos Komodakis. Wide residual networks. Procedings of the British Machine Vision Conference 2016 , 2016. doi:10.5244/c.30.87 .
[ZKZ + 15] Yukun Zhu, Ryan Kiros, Rich Zemel, Ruslan Salakhutdinov, Raquel Urtasun, Antonio Torralba, and Sanja Fidler. Aligning books and movies: Towards story-like visual explanations by watching movies and reading books. 2015 IEEE International Conference on Computer Vision (ICCV) , Dec 2015. doi:10.1109/iccv.2015.11 .
[ZLN + 19] Guodong Zhang, Lala Li, Zachary Nado, James Martens, Sushant Sachdeva, George E. Dahl, Christopher J. Shallue, and Roger B. Grosse. Which algorithmic choices matter at which batch sizes? insights from a noisy quadratic model. CoRR , abs/1907.04164, 2019, 1907.04164 . URL http://arxiv.org/abs/1907.04164 .