SAM 2: Segment Anything in Images and Videos
SAM 2: Segment Anything in Images and Videos
SAM 2:在图像与视频中分割任意对象
Nikhila Ravi Valentin Gabeur Yuan-Ting Hu Ronghang Hu Chaitanya Ryali Tengyu Ma Haitham Khedr Roman Rädle Chloe Rolland Laura Gustafson Eric Mintun Junting Pan Kalyan Vasudev Alwala Nicolas Carion Chao-Yuan Wu Ross Girshick Piotr Dollár Christoph Feichtenhofer
Abstract
摘要
We present Segment Anything Model 2 (SAM 2), a foundation model towards solving promptable visual segmentation in images and videos. We build a data engine, which improves model and data via user interaction, to collect the largest video segmentation dataset to date. Our model is a simple transformer architecture with streaming memory for real-time video processing. SAM 2 trained on our data provides strong performance across a wide range of tasks. In video segmentation, we observe better accuracy, using 3 fewer interactions than prior approaches. In image segmentation, our model is more accurate and 6 faster than the Segment Anything Model (SAM). We believe that our data, model, and insights will serve as a significant milestone for video segmentation and related perception tasks. We are releasing our main model, dataset, as well as code for model training and our demo.
我们提出 Segment Anything Model 2(SAM 2):面向图像与视频中可提示视觉分割的基础模型。我们构建数据引擎,通过用户交互同时改进模型与数据,从而收集迄今规模最大的视频分割数据集。模型采用带流式记忆的简洁 Transformer 结构,可实时处理视频。在我们数据上训练的 SAM 2 在广泛任务上表现强劲:视频分割中,以相对先前方法约 3 更少的交互取得更高精度;图像分割中,比 Segment Anything Model(SAM)更准且快约 6。我们相信数据、模型与洞见将成为视频分割及相关感知任务的重要里程碑。主模型、数据集以及训练与演示代码一并发布。
1 Introduction
1 引言
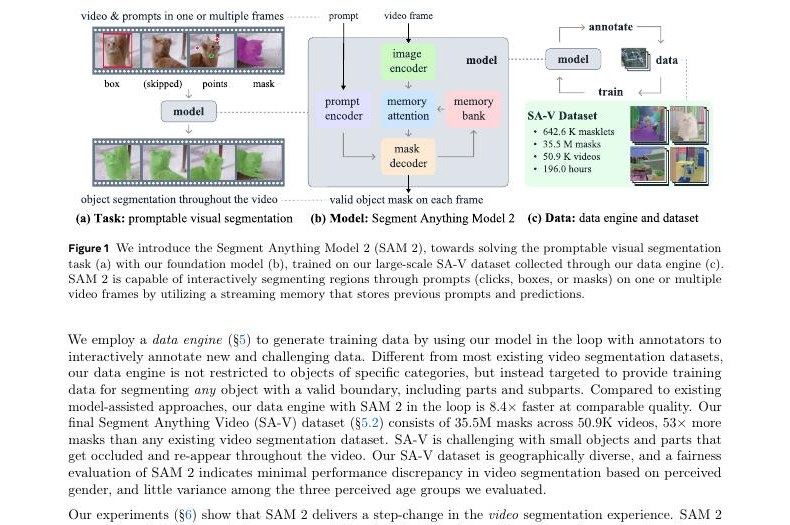
Figure 1: We introduce the Segment Anything Model 2 (SAM 2), towards solving the promptable visual segmentation task (a) with our foundation model (b), trained on our large-scale SA-V dataset collected through our data engine (c). SAM 2 is capable of interactively segmenting regions through prompts (clicks, boxes, or masks) on one or multiple video frames by utilizing a streaming memory that stores previous prompts and predictions.
图 1:我们提出 Segment Anything Model 2(SAM 2),面向可提示视觉分割任务(a),以我们的基础模型(b)在经数据引擎(c)采集的大规模 SA-V 数据集上训练。SAM 2 可借助存储以往提示与预测的流式记忆,在一帧或多帧视频上通过提示(点击、框或掩码)交互式分割区域。
Segment Anything (SA) introduced a foundation model for promptable segmentation in images (Kirillov et al. 2023). However an image is only a static snapshot of the real world in which visual segments can exhibit complex motion, and with the rapid growth of multimedia content, a significant portion is now recorded with a temporal dimension, particularly in video data. Many important applications in AR/VR, robotics, autonomous vehicles, and video editing require temporal localization beyond image-level segmentation. We believe a universal visual segmentation system should be applicable to both images and videos.
Segment Anything(SA)提出了面向图像可提示分割的基础模型(Kirillov et al. 2023)。然而图像只是真实世界的静态快照,其中视觉片段往往伴随复杂运动;多媒体内容快速增长后,带时间维的数据——尤其是视频——占比很大。AR/VR、机器人、自动驾驶与视频编辑等应用都需要超越图像级分割的时间定位。我们认为,通用视觉分割系统应同时适用于图像与视频。
Segmentation in video aims to determine the spatio-temporal extent of entities, which presents unique challenges beyond those in images. Entities can undergo significant changes in appearance due to motion, deformation, occlusion, lighting changes, and other factors. Videos often have lower quality than images due to camera motion, blur, and lower resolution. Further, efficient processing of a large number of frames is a key challenge. While SA successfully addresses segmentation in images, existing video segmentation models and datasets fall short in providing a comparable capability to “segment anything in videos”.
视频分割要确定实体的时空范围,挑战超出图像:实体会因运动、形变、遮挡、光照等显著改变外观;视频常因相机运动、模糊与更低分辨率而画质弱于图像;高效处理大量帧也是关键。SA 成功解决了图像分割,但现有视频分割模型与数据集尚不足以提供「在视频中分割任意对象」的可比能力。
We introduce the Segment Anything Model 2 (SAM 2), a unified model for video and image segmentation (we consider an image as a single-frame video). Our work includes a task, model, and dataset (see Fig. 1).
我们提出 Segment Anything Model 2(SAM 2):面向视频与图像分割的统一模型(把图像视为单帧视频)。工作涵盖任务、模型与数据集(见图 1)。
We focus on the Promptable Visual Segmentation (PVS) task that generalizes image segmentation to the video domain. The task takes as input points, boxes, or masks on any frame of the video to define a segment of interest for which the spatio-temporal mask (i.e., a ‘masklet’) is to be predicted. Once a masklet is predicted, it can be iteratively refined by providing prompts in additional frames.
我们聚焦可提示视觉分割(Promptable Visual Segmentation,PVS)任务,把图像分割推广到视频域。输入为视频任意帧上的点、框或掩码,用以定义感兴趣片段,并预测其时空掩码(即「masklet」)。一旦得到 masklet,可在额外帧上继续给提示以迭代 refinement。
Our model (§4) produces segmentation masks of the object of interest, in single images and across video frames. SAM 2 is equipped with a memory that stores information about the object and previous interactions, which allows it to generate masklet predictions throughout the video, and also effectively correct these based on the stored memory context of the object from previously observed frames. Our streaming architecture is a natural generalization of SAM to the video domain, processing video frames one at a time, equipped with a memory attention module to attend to the previous memories of the target object. When applied to images, the memory is empty and the model behaves like SAM.
我们的模型(§4)在单张图像以及跨视频帧上产出感兴趣对象的分割掩码。SAM 2 配有存储对象信息与既往交互的记忆,从而可在整段视频上生成 masklet 预测,并基于此前观测帧中对象的记忆上下文有效纠正。流式结构是 SAM 向视频域的自然推广:逐帧处理,并用记忆注意力模块关注目标对象的既往记忆。用于图像时记忆为空,行为类似 SAM。
We employ a data engine (§5) to generate training data by using our model in the loop with annotators to interactively annotate new and challenging data. Different from most existing video segmentation datasets, our data engine is not restricted to objects of specific categories, but instead targeted to provide training data for segmenting any object with a valid boundary, including parts and subparts. Compared to existing model-assisted approaches, our data engine with SAM 2 in the loop is 8.4 faster at comparable quality. Our final Segment Anything Video (SA-V) dataset (§5.2) consists of 35.5M masks across 50.9K videos, 53 more masks than any existing video segmentation dataset. SA-V is challenging with small objects and parts that get occluded and re-appear throughout the video. Our SA-V dataset is geographically diverse, and a fairness evaluation of SAM 2 indicates minimal performance discrepancy in video segmentation based on perceived gender, and little variance among the three perceived age groups we evaluated.
我们采用数据引擎(§5):模型在环,与标注者交互,标注新的困难数据。与多数现有视频分割数据集不同,数据引擎不限于特定类别,而是面向具有有效边界的任意对象(含部件与子部件)。相对既有模型辅助方案,带 SAM 2 在环的数据引擎在相近质量下快约 8.4。最终的 Segment Anything Video(SA-V)数据集(§5.2)含 50.9K 视频上的 35.5M 掩码,比任何现有视频分割数据集多约 53 掩码。SA-V 有挑战性:小对象与部件会遮挡并在视频中重现。数据集地理多样;对 SAM 2 的公平性评测显示,按感知性别的视频分割差异很小,所评测的三个感知年龄组之间方差也不大。
Our experiments (§6) show that SAM 2 delivers a step-change in the video segmentation experience. SAM 2 can produce better segmentation accuracy while using 3 fewer interactions than prior approaches. Further, SAM 2 outperforms prior work in established video object segmentation benchmarks, under multiple evaluation settings, and delivers better performance compared to SAM on image segmentation benchmarks, while being 6 faster. SAM 2 is shown to be effective across a variety of video and image distributions as observed through numerous zero-shot benchmarks including 17 for video segmentation and 37 for single-image segmentation.
实验(§6)表明 SAM 2 显著改变了视频分割体验:可用约 3更少的交互取得更好的分割精度。在既有视频目标分割基准的多种设定下,SAM 2 超过先前工作;在图像分割基准上相对 SAM 也更好,且快约 6。在包括 17 个视频分割与 37 个单图分割在内的大量零样本基准上,SAM 2 对多种视频与图像分布均有效。
We are releasing our work under permissive open licences, including the SA-V dataset (CC by 4.0), the SAM 2 model checkpoints[^1], training code (Apache 2.0), and code for our interactive online demo (Apache 2.0).
我们以宽松开源许可发布成果,包括 SA-V 数据集(CC by 4.0)、SAM 2 模型检查点[^1]、训练代码(Apache 2.0)以及交互式在线演示代码(Apache 2.0)。
2 Related work
2 相关工作
Image segmentation.
Segment Anything (Kirillov et al. 2023) introduces a promptable image segmentation task where the goal is to output a valid segmentation mask given an input prompt such as a bounding box or a point that refers to the object of interest. SAM trained on the SA-1B dataset allows for zero-shot segmentation which enabled its adoption to a wide range of applications. Recent work has extended SAM, e.g., by introducing a High-Quality output token to train on fine-grained masks (Ke et al. 2024), or improve SAM’s efficiency (Xiong et al. 2023; Zhang et al. 2023a; Zhao et al. 2023). More broadly, SAM is used in a wide range of applications, including medical imaging (Ma et al. 2024; Deng et al. 2023; Mazurowski et al. 2023; Wu et al. 2023a), remote sensing (Chen et al. 2024; Ren et al. 2024), motion segmentation (Xie et al. 2024), and camouflaged object detection (Tang et al. 2023).
图像分割。
Segment Anything(Kirillov et al. 2023)提出可提示图像分割任务:给定指向感兴趣对象的框或点等输入提示,输出有效分割掩码。在 SA-1B 上训练的 SAM 支持零样本分割,并被广泛采用。近期工作扩展了 SAM,例如引入 High-Quality 输出 token 以在细粒度掩码上训练(Ke et al. 2024),或提升 SAM 效率(Xiong et al. 2023;Zhang et al. 2023a;Zhao et al. 2023)。更广地,SAM 用于医学影像(Ma et al. 2024;Deng et al. 2023;Mazurowski et al. 2023;Wu et al. 2023a)、遥感(Chen et al. 2024;Ren et al. 2024)、运动分割(Xie et al. 2024)与伪装目标检测(Tang et al. 2023)等。
Interactive Video Object Segmentation (iVOS).
Interactive video object segmentation has emerged as a crucial task to efficiently obtain object segmentations in videos (masklets) with user guidance, often in the form of scribbles, clicks, or bounding boxes. A few early approaches (Wang et al. 2005; Bai & Sapiro 2007; Fan et al. 2015) deploy graph-based optimization to guide the segmentation annotation process. More recent approaches (Heo et al. 2020; Cheng et al. 2021b; Delatolas et al. 2024) often adopt a modular design, converting user inputs into a mask representation on a single frame and then propagating it to other frames.
交互式视频目标分割(iVOS)。
交互式视频目标分割已成为在涂鸦、点击或框等用户引导下高效得到视频对象分割(masklet)的关键任务。早期若干方法(Wang et al. 2005;Bai & Sapiro 2007;Fan et al. 2015)用基于图的优化引导分割标注。更近的方法(Heo et al. 2020;Cheng et al. 2021b;Delatolas et al. 2024)常采用模块化设计:把用户输入转成单帧掩码表征,再传播到其他帧。
Click-based input is easier to collect (Homayounfar et al. 2021) for interactive video segmentation. Recent works have used a combination of SAM on images with video trackers based on masks (Cheng et al. 2023b; Yang et al. 2023; Cheng et al. 2023c) or points (Rajič et al. 2023). However, these approaches have limitations: the tracker may not work for all objects, SAM may not perform well on video frames, and there is no mechanism to interactively refine a model’s mistakes, other than re-annotating using SAM in each frame and restarting the tracking from there.
基于点击的输入更易采集(Homayounfar et al. 2021)。近期工作把图像上的 SAM 与基于掩码(Cheng et al. 2023b;Yang et al. 2023;Cheng et al. 2023c)或点(Rajič et al. 2023)的视频跟踪器结合。但这些做法有局限:跟踪器未必对所有对象有效,SAM 在视频帧上未必表现好,且除了在每帧用 SAM 重标并从头重启跟踪外,缺少交互式 refinement 模型错误的机制。
Our work shares a similar goal to these works to segment objects across videos interactively, and we build a strong unified model that directly takes prompts for interactive video segmentation, along with a large and diverse dataset in pursuit of solving this goal.
我们与这些工作目标相近——交互式跨视频分割对象;并构建可直接接受提示做交互式视频分割的强统一模型,以及服务该目标的大规模多样数据集。
Video Object Segmentation (VOS).
The VOS task begins with an object mask as input in the first frame, which must be accurately tracked throughout the video (Pont-Tuset et al. 2017). The task is referred to as “semi-supervised VOS” since the input mask can be seen as supervision signal of the object which is available only in the first frame. This task has drawn significant attention due to its relevance in applications, including video editing or robotics.
视频目标分割(VOS)。
VOS 任务以首帧对象掩码为输入,需在整段视频中准确跟踪(Pont-Tuset et al. 2017)。因输入掩码可视为仅在首帧可用的对象监督信号,该任务也称「半监督 VOS」。因其与视频编辑、机器人等应用相关而受到广泛关注。
Early deep learning based approaches have often used online fine-tuning on the first video frame (Caelles et al. 2016; Perazzi et al. 2016; Yoon et al. 2017; Maninis et al. 2017; Hu et al. 2018a; Bhat et al. 2020; Robinson et al. 2020) or on all frames (Voigtlaender & Leibe 2017) to adapt the model to the target object. Faster inference has been achieved with offline-trained models, conditioned either only on the first frame (Hu et al. 2018b; Chen et al. 2018), or also integrating the previous frame (Oh et al. 2018; Yang et al. 2018; Yang et al. 2020). This multi-conditioning has been extended to all frames with RNNs (Xu et al. 2018a) and transformers (Oh et al. 2019; Cheng et al. 2021a; Li et al. 2022a; Yang et al. 2021b; Yang et al. 2024; Cheng & Schwing 2022; Yang & Yang 2022; Wang et al. 2022; Cheng et al. 2023a; Goyal et al. 2023; Zhang et al. 2023b; Wu et al. 2023b).
早期基于深度学习的方法常在首帧(Caelles et al. 2016;Perazzi et al. 2016;Yoon et al. 2017;Maninis et al. 2017;Hu et al. 2018a;Bhat et al. 2020;Robinson et al. 2020)或全部帧(Voigtlaender & Leibe 2017)上做在线微调,使模型适配目标。更快推理来自离线训练模型:仅条件于首帧(Hu et al. 2018b;Chen et al. 2018),或同时融合前一帧(Oh et al. 2018;Yang et al. 2018;Yang et al. 2020)。这种多条件化又扩展到用 RNN(Xu et al. 2018a)与 Transformer(Oh et al. 2019;Cheng et al. 2021a;Li et al. 2022a;Yang et al. 2021b;Yang et al. 2024;Cheng & Schwing 2022;Yang & Yang 2022;Wang et al. 2022;Cheng et al. 2023a;Goyal et al. 2023;Zhang et al. 2023b;Wu et al. 2023b)覆盖全部帧。
Semi-supervised VOS can be seen as a special case of our Promptable Visual Segmentation (PVS) task, with only a mask prompt in the first video frame. Notably, annotating the required high-quality object mask in the first frame in VOS is practically challenging and time-consuming for inference.
半监督 VOS 可视为我们可提示视觉分割(PVS)任务的特例:仅在首帧给掩码提示。值得注意的是,VOS 推理时在首帧标注所需高质量对象掩码本身既难又耗时。
Video segmentation datasets.
Many datasets have been proposed to support the VOS task. Early VOS datasets (Prest et al. 2012; Li et al. 2013; Ochs et al. 2014; Fan et al. 2015), such as DAVIS (Pont-Tuset et al. 2017; Caelles et al. 2019), include high-quality annotations but their size limits deep-learning based approaches. YouTube-VOS (Xu et al. 2018b) is the first large-scale dataset for VOS. As algorithms became better and benchmark performance started to saturate, researchers have looked at increasing the difficulty of the VOS task by specifically focusing on occlusions (Qi et al. 2022; Ding et al. 2023), long videos (Hong et al. 2023; Hong et al. 2024), extreme transformations (Tokmakov et al. 2022), object diversity (Wang et al. 2021b; Wang et al. 2023) or scene diversity (Athar et al. 2022).
视频分割数据集。
支撑 VOS 的数据集很多。早期 VOS 数据集(Prest et al. 2012;Li et al. 2013;Ochs et al. 2014;Fan et al. 2015)如 DAVIS(Pont-Tuset et al. 2017;Caelles et al. 2019)标注质量高,但规模限制了深度学习方法。YouTube-VOS(Xu et al. 2018b)是首个大规模 VOS 数据集。随着算法变强、基准表现趋近饱和,研究者通过聚焦遮挡(Qi et al. 2022;Ding et al. 2023)、长视频(Hong et al. 2023;Hong et al. 2024)、极端变换(Tokmakov et al. 2022)、对象多样性(Wang et al. 2021b;Wang et al. 2023)或场景多样性(Athar et al. 2022)来提高 VOS 难度。
We find that current video segmentation datasets lack sufficient coverage to achieve the capability of “segmenting anything in videos”. Their annotations typically cover entire objects (not parts) and datasets are often centered around specific object classes, such as people, vehicles, and animals. In comparison to these datasets, our released SA-V dataset not only focuses on whole objects but also extensively covers object parts and contains over an order of magnitude more masks.
我们发现:现有视频分割数据集覆盖不足,难以实现「在视频中分割任意对象」。标注通常覆盖整物(不含部件),且常围绕人、车、动物等特定类别。相较之下,我们发布的 SA-V 不仅关注整物,也广泛覆盖对象部件,掩码数量高出一个数量级以上。
3 Task: promptable visual segmentation
3 任务:可提示视觉分割
Our PVS task allows providing prompts to the model on any frame of a video. Prompts can be positive/negative clicks, boxes, or masks, either to define an object to segment or to refine a model-predicted one. To provide an interactive experience, upon receiving a prompt on a specific frame, the model should immediately respond with a valid segmentation mask of the object on this frame. After receiving initial prompts (either on the same frame or different frames), the model should propagate these prompts to obtain the masklet of the object across the entire video, localizing the segmentation mask of the target on every video frame. Additional prompts can be provided to the model on any frame to refine the segment throughout the video (example in Fig. 2). For details on the task, see §B.
我们的 PVS 任务允许在视频的任意帧上向模型提供提示。提示可以是正/负点击、框或掩码,用于定义要分割的对象,或 refinement 模型已预测的结果。为提供交互体验,在特定帧收到提示后,模型应立即返回该帧上对象的有效分割掩码。收到初始提示后(可在同一帧或不同帧),模型应把这些提示传播开,得到对象贯穿整段视频的 masklet,并在每一帧定位目标分割掩码。还可在任意帧继续给提示,以在整段视频上 refinement 片段(样例见图 2)。任务细节见 §B。
SAM 2 (§4) is applied as a data collection tool to the PVS task for building our SA-V dataset (§5). We evaluate the model (§6) by simulating interactive video segmentation scenarios across multiple frames, in the conventional semi-supervised VOS setting where annotations are limited to the first frame, and for image segmentation on the SA benchmarks.
SAM 2(§4)被用作数据采集工具,服务 PVS 任务以构建 SA-V 数据集(§5)。评测(§6)包括:跨多帧的交互式视频分割仿真、标注仅限首帧的传统半监督 VOS 设定,以及 SA 基准上的图像分割。
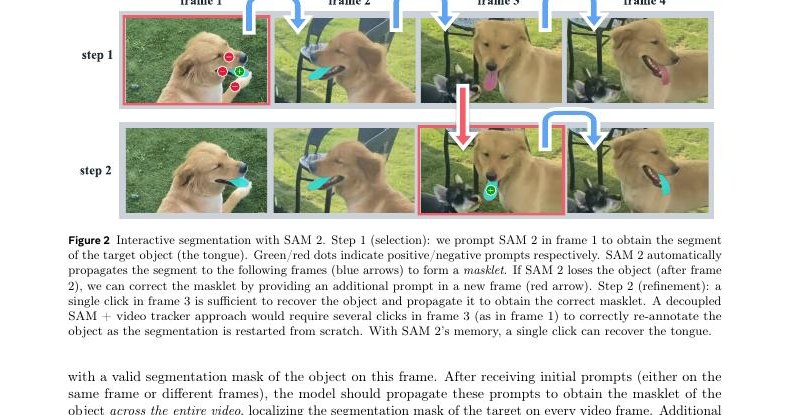
Figure 2: Interactive segmentation with SAM 2. Step 1 (selection): we prompt SAM 2 in frame 1 to obtain the segment of the target object (the tongue). Green/red dots indicate positive/negative prompts respectively. SAM 2 automatically propagates the segment to the following frames (blue arrows) to form a masklet. If SAM 2 loses the object (after frame 2), we can correct the masklet by providing an additional prompt in a new frame (red arrow). Step 2 (refinement): a single click in frame 3 is sufficient to recover the object and propagate it to obtain the correct masklet. A decoupled SAM + video tracker approach would require several clicks in frame 3 (as in frame 1) to correctly re-annotate the object as the segmentation is restarted from scratch. With SAM 2’s memory, a single click can recover the tongue.
图 2:用 SAM 2 做交互式分割。步骤 1(选择):在第 1 帧提示 SAM 2,得到目标对象(舌头)的片段。绿/红点分别表示正/负提示。SAM 2 自动把片段传播到后续帧(蓝箭头)形成 masklet。若丢失对象(第 2 帧之后),可在新帧再给提示纠正(红箭头)。步骤 2(refinement):在第 3 帧单次点击即可恢复对象并传播得到正确 masklet。解耦的 SAM + 视频跟踪器方案在第 3 帧需要多次点击(如同第 1 帧)才能正确重标,因为分割从头重启。借助 SAM 2 的记忆,一次点击即可找回舌头。
4 Model
4 模型
SAM 2 (Fig. 3) can be seen as a generalization of SAM to the video (and image) domain, taking point, box, and mask prompts on individual frames to define the spatial extent of the object to be segmented spatio-temporally. Spatially, the model behaves similarly to SAM. A promptable and light-weight mask decoder takes an image embedding and prompts (if any) and outputs a segmentation mask for the frame. Prompts can be iteratively added on a frame in order to refine the masks.
SAM 2(图 3)可视为 SAM 向视频(与图像)域的推广:在单帧上接受点、框与掩码提示,以定义要做时空分割的对象空间范围。空间上行为类似 SAM。可提示且轻量的掩码解码器接收图像嵌入与提示(若有),输出该帧分割掩码。可在一帧上迭代添加提示以refinement掩码。
The frame embedding used by the SAM 2 decoder is not directly from an image encoder and is instead conditioned on memories of past predictions and prompted frames. It is possible for prompted frames to also come “from the future” relative to the current frame. Memories of frames are created by the memory encoder based on the current prediction and placed in a memory bank for use in subsequent frames. The memory attention operation takes the per-frame embedding from the image encoder and conditions it on the memory bank, before the mask decoder ingests it to form a prediction.
SAM 2 解码器所用的帧嵌入并非直接来自图像编码器,而是条件于既往预测与被提示帧的记忆。被提示帧相对当前帧也可「来自未来」。帧记忆由记忆编码器根据当前预测生成,放入记忆库供后续帧使用。记忆注意力操作取图像编码器的逐帧嵌入,条件于记忆库,再交掩码解码器形成预测。
We describe individual components and training below and provide more details in Appendix D.
下文描述各组件与训练,更多细节见附录 D。
Image encoder.
For real-time processing of arbitrarily long videos, we take a streaming approach, consuming video frames as they become available. The image encoder is only run once for the entire interaction and its role is to provide unconditioned tokens (feature embeddings) representing each frame. We use an MAE (He et al. 2022) pre-trained Hiera (Ryali et al. 2023; Bolya et al. 2023) image encoder, which is hierarchical, allowing us to use multiscale features during decoding.
图像编码器。
为实时处理任意长度视频,我们采用流式做法,随帧到达逐帧消费。整次交互中图像编码器只跑一次,职责是为每帧提供无条件 token(特征嵌入)。我们使用经 MAE(He et al. 2022)预训练的 Hiera(Ryali et al. 2023;Bolya et al. 2023)图像编码器;其层次结构使我们能在解码时使用多尺度特征。
Memory attention.
The role of memory attention is to condition the current frame features on the past frames features and predictions as well as on any new prompts. We stack transformer blocks, the first one taking the image encoding from the current frame as input. Each block performs self-attention, followed by cross-attention to memories of (prompted/unprompted) frames and object pointers (see below), stored in a memory bank (see below), followed by an MLP. We use vanilla attention operations for self- and cross-attention, allowing us to benefit from recent developments in efficient attention kernels (Dao 2023).
记忆注意力。
记忆注意力的作用是把当前帧特征条件于过去帧特征与预测以及任何新提示。我们堆叠 个 Transformer 块,第一块以当前帧图像编码为输入。每块先做自注意力,再对保存在记忆库中的(被提示/未被提示)帧记忆与对象指针(见下)做交叉注意力,最后接 MLP。自注意力与交叉注意力均用标准注意力,以便受益于高效注意力核的近期进展(Dao 2023)。
Prompt encoder and mask decoder.
Our prompt encoder is identical to SAM’s and can be prompted by clicks (positive or negative), boxes, or masks to define the extent of the object in a given frame. Sparse prompts are represented by positional encodings summed with learned embeddings for each prompt type, while masks are embedded using convolutions and summed with the frame embedding.
提示编码器与掩码解码器。
提示编码器与 SAM 相同,可用点击(正或负)、框或掩码定义给定帧上对象的范围。稀疏提示由位置编码与各提示类型的可学习嵌入相加表示;掩码则经卷积嵌入后与帧嵌入相加。
Our decoder design largely follows SAM. We stack “two-way” transformer blocks that update prompt and frame embeddings. As in SAM, for ambiguous prompts (i.e., a single click) where there may be multiple compatible target masks, we predict multiple masks. This design is important to ensure that the model outputs valid masks. In video, where ambiguity can extend across video frames, the model predicts multiple masks on each frame. If no follow-up prompts resolve the ambiguity, the model only propagates the mask with the highest predicted IoU for the current frame.
解码器设计大体沿用 SAM。我们堆叠双向(two-way)Transformer 块,更新提示与帧嵌入。与 SAM 一样,对可能对应多个兼容目标掩码的模糊提示(如单次点击),我们预测多个掩码。这对确保输出有效掩码很重要。在视频中,模糊性可跨帧延续,模型在每帧预测多个掩码;若后续提示未消歧,则只传播当前帧预测 IoU 最高的掩码。
Unlike SAM where there is always a valid object to segment given a positive prompt, in the PVS task it is possible for no valid object to exist on some frames (e.g. due to occlusion). To support this new output mode, we add an additional head that predicts whether the object of interest is present on the current frame. Another novelty are skip connections from our hierarchical image encoder (bypassing the memory attention) to incorporate high-resolution embeddings for mask decoding (see §D).
与 SAM「给定正提示总有有效对象可分割」不同,PVS 任务中某些帧可能没有有效对象(如因遮挡)。为支持这一新输出模式,我们增加一个头,预测感兴趣对象是否出现在当前帧。另一新颖点是从层次图像编码器引出跳跃连接(绕过记忆注意力),为掩码解码并入高分辨率嵌入(见 §D)。
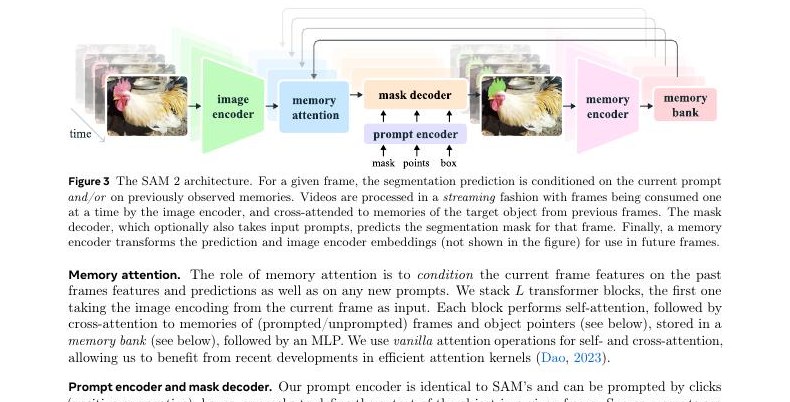
Figure 3: The SAM 2 architecture. For a given frame, the segmentation prediction is conditioned on the current prompt and/or on previously observed memories. Videos are processed in a streaming fashion with frames being consumed one at a time by the image encoder, and cross-attended to memories of the target object from previous frames. The mask decoder, which optionally also takes input prompts, predicts the segmentation mask for that frame. Finally, a memory encoder transforms the prediction and image encoder embeddings (not shown in the figure) for use in future frames.
图 3:SAM 2 结构。对给定帧,分割预测条件于当前提示和/或既往观测记忆。视频以流式处理:图像编码器逐帧消费,并对先前帧中目标对象的记忆做交叉注意力。掩码解码器(可选地再接收输入提示)预测该帧分割掩码。最后,记忆编码器变换预测与图像编码器嵌入(图中未画出)供未来帧使用。
Memory encoder.
The memory encoder generates a memory by downsampling the output mask using a convolutional module and summing it element-wise with the unconditioned frame embedding from the image-encoder (not shown in Fig. 3), followed by light-weight convolutional layers to fuse the information.
记忆编码器。
记忆编码器先用卷积模块下采样输出掩码,再与图像编码器的无条件帧嵌入逐元素相加(图 3 未画出),随后经轻量卷积层融合信息。
Memory bank.
The memory bank retains information about past predictions for the target object in the video by maintaining a FIFO queue of memories of up to recent frames and stores information from prompts in a FIFO queue of up to prompted frames. For instance, in the VOS task where the initial mask is the only prompt, the memory bank consistently retains the first frame’s memory along with memories of up to recent (unprompted) frames. Both sets of memories are stored as spatial feature maps.
记忆库。
记忆库通过维护最多 个近期帧记忆的 FIFO 队列,保留视频中目标对象的既往预测信息;并以最多 个被提示帧的 FIFO 队列存储提示信息。例如在仅以初始掩码为提示的 VOS 任务中,记忆库始终保留首帧记忆,以及最多 个近期(未被提示)帧的记忆。两套记忆均存为空间特征图。
In addition to the spatial memory, we store a list of object pointers as lightweight vectors for high-level semantic information of the object to segment, based on mask decoder output tokens of each frame. Our memory attention cross-attends to both spatial memory features and these object pointers.
除空间记忆外,我们还基于每帧掩码解码器输出 token,存储一列轻量向量形式的对象指针,承载待分割对象的高层语义信息。记忆注意力同时对空间记忆特征与这些对象指针做交叉注意力。
We embed temporal position information into the memories of recent frames, allowing the model to represent short-term object motion, but not into those of prompted frames, because the training signal from prompted frames is sparser and it is more difficult to generalize to the inference setting where prompted frames may come from a very different temporal range than seen during training.
我们把时间位置信息嵌入 个近期帧的记忆,使模型能表示短期对象运动;但不嵌入被提示帧的记忆——因为被提示帧的训练信号更稀疏,且推理时被提示帧的时间范围可能与训练差异很大,更难泛化。
Training.
The model is trained jointly on image and video data. Similar to previous work (Kirillov et al. 2023; Sofiiuk et al. 2022), we simulate interactive prompting of the model. We sample sequences of 8 frames and randomly select up to 2 frames to prompt and probabilistically receive corrective clicks which are sampled using the ground-truth masklet and model predictions during training. The training task is to sequentially (and “interactively”) predict the ground-truth masklet. Initial prompts to the model can be the ground-truth mask with probability , a positive click sampled from the ground-truth mask with probability , or a bounding box input with probability . See §D for more details.
训练。
模型在图像与视频数据上联合训练。与先前工作类似(Kirillov et al. 2023;Sofiiuk et al. 2022),我们仿真对模型的交互式提示:采样 8 帧序列,随机选最多 2 帧给提示,并以一定概率接收用真值 masklet 与训练中模型预测采样得到的纠正点击。训练任务是顺序(且「交互式」)预测真值 masklet。初始提示可为真值掩码(概率 )、从真值掩码采样的正点击()或边界框()。详见 §D。
5 Data
5 数据
To develop the capability to “segment anything” in video, we built a data engine to collect a large and diverse video segmentation dataset. We employ an interactive model in the loop setup with human annotators. Similar to Kirillov et al. 2023, we do not impose semantic constraints on the annotated masklets, and focus on both whole objects (e.g., a person) and parts (e.g., a person’s hat). Our data engine went through three phases, each categorized based on the level of model assistance provided to annotators. Next, we describe each data engine phase and our SA-V dataset.
为发展在视频中「分割任意对象」的能力,我们构建数据引擎以采集大规模多样的视频分割数据集。采用模型在环的交互设定,配合人工标注者。与 Kirillov et al. 2023 类似,不对标注的 masklet 施加语义约束,同时关注整物(如人)与部件(如帽子)。数据引擎经历三阶段,按向标注者提供的模型辅助程度划分。下文描述各阶段与 SA-V 数据集。
5.1 Data engine
5.1 数据引擎
Phase 1: SAM per frame.
The initial phase used the image-based interactive SAM (Kirillov et al. 2023) to assist human annotation. Annotators are tasked with annotating the mask of a target object in every frame of the video at 6 frames per second (FPS) using SAM, and pixel-precise manual editing tools such as a “brush” and “eraser”. There is no tracking model involved to assist with the temporal propagation of masks to other frames. As this is a per-frame method, and all frames require mask annotation from scratch, the process is slow, with an average annotation time of 37.8 seconds per frame in our experiment. However, this yields high-quality spatial annotations per frame. In this phase, we collected 16K masklets across 1.4K videos. We further use this approach to annotate our SA-V val and test sets to mitigate potential biases of SAM 2 during evaluation.
阶段 1:逐帧 SAM。
初始阶段用基于图像的交互式 SAM(Kirillov et al. 2023)辅助人工标注。标注者需以 6 FPS,用 SAM 以及「画笔」「橡皮」等像素级手动工具,在视频每一帧标注目标对象掩码。没有跟踪模型协助把掩码时间传播到其他帧。因是逐帧方法且每帧都要从头标掩码,过程很慢:实验中平均每帧 37.8 秒。但这能得到高质量的逐帧空间标注。本阶段在 1.4K 视频上采集了 16K 个 masklet。我们还用该方法标注 SA-V 验证与测试集,以减轻评测时 SAM 2 可能带来的偏差。
Phase 2: SAM + SAM 2 Mask.
The second phase added SAM 2 into the loop, where SAM 2 only accepted masks as prompts. We refer to this version as SAM 2 Mask. Annotators used SAM and other tools as in Phase 1 to generate spatial masks in the first frame, and then use SAM 2 Mask to temporally propagate the annotated mask to other frames to get the full spatio-temporal masklets. At any subsequent video frame, annotators can spatially modify the predictions made by SAM 2 Mask by annotating a mask from scratch with SAM, a “brush” and/or “eraser”, and re-propagate with SAM 2 Mask, repeating this process until the masklet is correct. SAM 2 Mask was initially trained on the Phase 1 data and publicly available datasets. During Phase 2, we re-trained and updated SAM 2 Mask in the annotation loop twice using the collected data. In Phase 2, we collected 63.5K masklets. The annotation time went down to 7.4 s/frame, a 5.1x speed up over Phase 1.
阶段 2:SAM + SAM 2 Mask。
第二阶段把 SAM 2 加入环中,且此时 SAM 2 只接受掩码作提示,称为 SAM 2 Mask。标注者如阶段 1 用 SAM 等工具在首帧生成空间掩码,再用 SAM 2 Mask 时间传播到其他帧,得到完整时空 masklet。在任意后续帧,标注者可用 SAM、「画笔」和/或「橡皮」从头标掩码以空间修改 SAM 2 Mask 的预测,再重新传播,直至 masklet 正确。SAM 2 Mask 最初在阶段 1 数据与公开数据集上训练;阶段 2 中我们用新采集数据在环内重训并更新两次。本阶段采集 63.5K 个 masklet,标注时间降到 7.4 秒/帧,相对阶段 1 约 5.1× 加速。
Despite an improvement in annotation time, this approach requires annotating masks in intermediate frames from scratch without previous memory. We then advanced to develop the fully-featured SAM 2, capable of both interactive segmentation and mask propagation in a unified model.
尽管标注时间改善,该方法仍要求在中间帧从头标掩码、且无既往记忆。我们进而发展功能完备的 SAM 2,在统一模型中同时支持交互式分割与掩码传播。
Phase 3: SAM 2.
In the final phase, we utilize the fully-featured SAM 2, which accepts various types of prompts, including points and masks. SAM 2 benefits from memories of objects across the temporal dimension to generate mask predictions. This means annotators only need to provide occasional refinement clicks to SAM 2 to edit the predicted masklets in intermediate frames, as opposed to annotating from scratch with a spatial SAM which has no such memory context. During Phase 3, we re-trained and updated SAM 2 using the collected annotations five times. With SAM 2 in the loop, the annotation time per frame went down to 4.5 seconds, a 8.4x speed up over Phase 1. In Phase 3, we collected 197.0K masklets.
阶段 3:SAM 2。
最终阶段使用功能完备的 SAM 2,可接受点、掩码等多种提示。SAM 2 受益于跨时间维的对象记忆以生成掩码预测,因此标注者只需偶尔向 SAM 2 提供refinement点击以编辑中间帧的预测 masklet,而不必用无记忆上下文的空间 SAM 从头标注。阶段 3 中我们用采集标注重训并更新 SAM 2 五次。有 SAM 2 在环时,每帧标注时间降至 4.5 秒,相对阶段 1 约 8.4× 加速。本阶段采集 197.0K 个 masklet。
Quality verification.
To uphold a high standard for annotation, we introduce a verification step. A separate set of annotators are tasked with verifying the quality of each annotated masklet as “satisfactory” (correctly and consistently tracking the target object across all frames) or “unsatisfactory” (target object is well defined with a clear boundary but the masklet is not correct or consistent). Unsatisfactory masklets were sent back to the annotation pipeline for refinement. Any masklets tracking not well defined objects were rejected entirely.
质量核验。
为维持高标注标准,我们引入核验步骤。另一组标注者把每个已标 masklet 判为「合格」(在全部帧上正确、一致地跟踪目标)或「不合格」(目标定义清楚且边界清晰,但 masklet 不正确或不一致)。不合格 masklet 退回标注流水线 refinement;跟踪定义不清对象的 masklet 则整体拒绝。
Auto masklet generation.
Ensuring diversity in annotation is important to enable the anything capability of our model. As human annotators might typically focus more on salient objects, we augment the annotations with automatically generated masklets (referred to as “Auto”). This serves a dual purpose of increasing the coverage of annotations and helping identify model failure cases. To generate auto masklets, we prompt SAM 2 with a regular grid of points in the first frame and generate candidate masklets. These are then sent to the masklet verification step for filtering. Automatic masklets tagged as “satisfactory” are added to the SA-V dataset. Masklets identified as “unsatisfactory” (i.e., model failure cases) are sampled and presented to annotators to refine with SAM 2 in the loop (Phase 3 of the data engine). These automatic masklets cover large salient central objects but also objects of varying sizes and positions in the background.
自动 masklet 生成。
标注多样性对模型的任意对象能力很重要。人工往往更关注显著对象,因此我们用自动生成的 masklet(称「Auto」)做增强:既扩大覆盖,也帮助发现模型失败案例。做法是在首帧用规则点网格提示 SAM 2 生成候选 masklet,再送入核验过滤。「合格」者加入 SA-V;「不合格」(即模型失败)则采样后交标注者用阶段 3 的 SAM 2 在环 refinement。这些自动 masklet 既覆盖大而居中的显著对象,也覆盖背景中不同大小与位置的对象。
| Model in the Loop | Time per Frame | Edited Frames | Clicks per Clicked Frame | Phase 1 Mask Alignment Score (IoU>0.75) | ||||
|---|---|---|---|---|---|---|---|---|
| All | Small | Medium | Large | |||||
| Phase 1 | SAM only | 37.8 s | 100.00 % | 4.80 | - | - | - | - |
| Phase 2 | SAM + SAM 2 Mask | 7.4 s | 23.25 % | 3.61 | 86.4 | 71.3 | 80.4 | 97.9 |
| Phase 3 | SAM 2 | 4.5 s | 19.04 % | 2.68 | 89.1 | 72.8 | 81.8 | 100.0 |
Table 1: Evolution of data engine phases showing the average annotation time per frame, the average percent of edited frames per masklet, the number of manual clicks per clicked frame, and Mask Alignment to Phase 1 by mask size.
| 环内模型 | 每帧耗时 | 编辑帧比例 | 每点击帧点击数 | 相对阶段 1 掩码对齐分(IoU>0.75) | ||||
|---|---|---|---|---|---|---|---|---|
| 全部 | 小 | 中 | 大 | |||||
| 阶段 1 | 仅 SAM | 37.8 s | 100.00 % | 4.80 | - | - | - | - |
| 阶段 2 | SAM + SAM 2 Mask | 7.4 s | 23.25 % | 3.61 | 86.4 | 71.3 | 80.4 | 97.9 |
| 阶段 3 | SAM 2 | 4.5 s | 19.04 % | 2.68 | 89.1 | 72.8 | 81.8 | 100.0 |
表 1:数据引擎各阶段演进:平均每帧标注时间、每个 masklet 手工编辑帧占比、每点击帧的手工点击数,以及按掩码尺寸相对阶段 1 的掩码对齐。
Analysis.
Table 1 shows a comparison of the annotation protocol in each data engine phase through a controlled experiment (details in §E.2.2). We compare the average annotation time per frame, the average percentage of manually edited frames per masklet, and the average number of clicks per clicked frame. For quality evaluation, we define the Phase 1 Mask Alignment Score as the percentage of masks whose IoU compared to the corresponding masks in Phase 1 exceeds 0.75. Phase 1 data is chosen as a reference as it has per-frame high quality manual annotations. Phase 3 with SAM 2 in the loop leads to increased efficiency and comparable quality: it is 8.4 faster than Phase 1, has the lowest edited frame percentage and clicks per frame, and results in better alignment.
分析。
表 1 通过受控实验比较各数据引擎阶段的标注协议(细节见 §E.2.2)。我们比较平均每帧标注时间、每个 masklet 手工编辑帧占比,以及每点击帧的平均点击数。质量上,定义阶段 1 掩码对齐分为相对阶段 1 对应掩码 IoU 超过 0.75 的掩码百分比。以阶段 1 为参考,因其具有逐帧高质量人工标注。阶段 3 有 SAM 2 在环时效率更高且质量可比:比阶段 1 快 8.4,编辑帧比例与每帧点击最低,对齐也更好。
| Training data | SA-V val | 9 zero-shot |
|---|---|---|
| VOS + SA-1B | 50.0 | 62.5 |
| + Phase 1 | 53.0 | 66.9 |
| + Phase 2 | 58.8 | 70.9 |
| + Phase 3 | 62.5 | 71.2 |
| + Auto | 63.2 | 71.5 |
Table 2: Segmentation accuracy ( metric) improvement from adding data from each data engine phase. “VOS” is a set of video object segmentation datasets. Details are in §F.
| 训练数据 | SA-V val | 9 个零样本 |
|---|---|---|
| VOS + SA-1B | 50.0 | 62.5 |
| + 阶段 1 | 53.0 | 66.9 |
| + 阶段 2 | 58.8 | 70.9 |
| + 阶段 3 | 62.5 | 71.2 |
| + Auto | 63.2 | 71.5 |
表 2:加入各数据引擎阶段数据后的分割精度( 指标)提升。「VOS」为一组视频目标分割数据集。细节见 §A。
In Table 2, we show the performance comparison of SAM 2 trained on the available data at the end of each phase keeping the number of iterations fixed, therefore measuring solely the impact of the additional data. We evaluate on our own SA-V val set and also on 9 zero-shot benchmarks (see §F.1 for details) using the standard accuracy metric (the higher the better) when prompting with 3-clicks on the first frame. We note a consistent improvement after iteratively including the data from each phase, not only on the in-domain SA-V val set, but also on the 9 zero-shot benchmarks.
表 2 比较在各阶段结束时可用数据上训练的 SAM 2,固定迭代次数,从而只衡量额外数据的影响。在自有 SA-V val 以及 9 个零样本基准上(细节见 §F.1),用标准 精度(越高越好)评测;提示为首帧上的真值掩码。
5.2 SA-V dataset
5.2 SA-V 数据集
The SA-V dataset collected with our data engine comprises 50.9K videos with 642.6K masklets. In Table 3 we compare the SA-V composition to common VOS datasets across the number of videos, masklets, and masks. Notably, the number of annotated masks is 53 (15 without auto) larger than any existing VOS dataset, providing a substantial resource for future work. We are releasing SA-V under a permissive license.
经数据引擎采集的 SA-V 含 50.9K 视频与 642.6K 个 masklet。表 3 从视频数、masklet 数与掩码数上把 SA-V 构成与常见 VOS 数据集比较。值得注意的是,标注掩码数比任何现有 VOS 数据集大约 53(不含自动约为 15),为后续工作提供可观资源。我们按宽松许可发布 SA-V。
Videos.
We collected a new set of 50.9K videos captured by crowdworkers. Videos comprise 54% indoor and 46% outdoor scenes with an average duration of 14 seconds. Videos feature “in-the-wild” diverse environments, and cover various everyday scenarios.
视频。
我们采集了由众包工作者拍摄的 50.9K 新视频。室内场景约占 54%、室外 46%,平均时长 14 秒。视频呈现「野外」多样环境,覆盖多种日常场景。
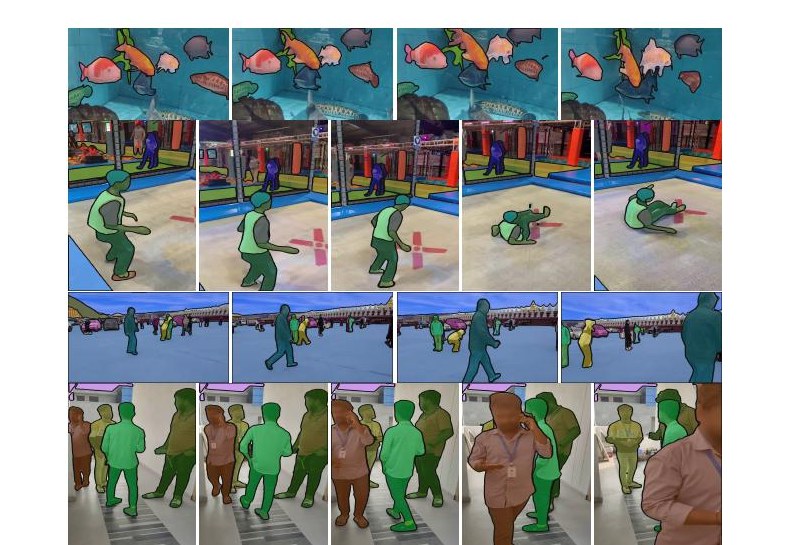
Figure 4: Example videos from the SA-V dataset with masklets overlaid (manual and automatic). Each masklet has a unique color, and each row represents frames from one video, with 1 second between them.
图 4:SA-V 数据集样例视频,叠加 masklet(人工与自动)。每个 masklet 颜色唯一;每行来自同一视频的帧,间隔 1 秒。
Masklets.
The annotations comprise 190.9K manual masklet annotations and 451.7K automatic masklets collected using our data engine. Example videos with masklets overlaid (manual and automatic) are shown in Fig. 4. SA-V has 53 (15 without auto annotations) more masks than the largest VOS dataset. The disappearance rate (Ding et al. 2023) in SA-V Manual (the percentage of annotated masklets that disappear in at least one frame and then re-appear) is 42.5, competitive among existing datasets.
Masklets。
标注含经数据引擎采集的 190.9K 个人工 masklet 与 451.7K 个自动 masklet。叠加人工与自动 masklet 的样例见图 4。SA-V 的掩码数比最大的 VOS 数据集多约 53(不含自动标注约 15)。SA-V Manual 中的消失率(Ding et al. 2023;即标注对象在至少一帧完全消失的百分比)更高,表明遮挡与重现更具挑战。
SA-V training, validation and test splits.
We split SA-V based on the video authors (and their geographic locations) to ensure minimal overlap of similar objects. To create SA-V val and SA-V test sets, we focus on challenging scenarios in selecting videos, and ask annotators to identify challenging targets that are fast-moving, have complex occlusions by other objects as well as disappearance/re-appearance patterns. These targets were annotated at 6 FPS using the data engine Phase 1 setup in §5.1. There are 293 masklets and 155 videos in the SA-V val split, and 278 masklets and 150 videos in the SA-V test split.
SA-V 训练、验证与测试划分。
我们按视频作者(及其地理位置)划分 SA-V,以尽量减少相似对象重叠。构建 SA-V val 与 SA-V test 时,选视频聚焦困难场景,并请标注者识别有挑战的目标:快速运动、被其他对象复杂遮挡,以及消失与重现等。
Internal dataset.
We also used internally available licensed video data to further augment our training set. Our internal dataset is comprised of 62.9K videos and 69.6K masklets annotated in Phase 2 and Phase 3 (see §5.1) for training, and 96 videos and 189 masklets annotated using Phase 1 for testing (Internal-test).
内部数据集。
我们还用内部可获得的授权视频数据进一步扩充训练集。内部数据集含阶段 2 与阶段 3(见 §5.1)标注的 62.9K 视频、69.6K 个 masklet 用于训练,以及用阶段 1 标注的 96 视频、189 个 masklet 用于测试(Internal-test)。
See Appendix E for more details on the data engine and SA-V dataset, including a fairness evaluation.
数据引擎与 SA-V 数据集的更多细节(含公平性评测)见附录 E。
| #Videos | Duration | #Masklets | #Masks | #Frames | Disapp. Rate | |
|---|---|---|---|---|---|---|
| DAVIS 2017 (Pont-Tuset et al. 2017) | 0.2K | 0.1 hr | 0.4K | 27.1K | 10.7K | 16.1 |
| YouTube-VOS (Xu et al. 2018b) | 4.5K | 5.6 hr | 8.6K | 197.3K | 123.3K | 13.0 |
| UVO-dense (Wang et al. 2021b) | 1.0K | 0.9 hr | 10.2K | 667.1K | 68.3K | 9.2 |
| VOST (Tokmakov et al. 2022) | 0.7K | 4.2 hr | 1.5K | 175.0K | 75.5K | 41.7 |
| BURST (Athar et al. 2022) | 2.9K | 28.9 hr | 16.1K | 600.2K | 195.7K | 37.7 |
| MOSE (Ding et al. 2023) | 2.1K | 7.4 hr | 5.2K | 431.7K | 638.8K | 41.5 |
| Internal | 62.9K | 281.8 hr | 69.6K | 5.4M | 6.0M | 36.4 |
| SA-V Manual | 50.9K | 196.0 hr | 190.9K | 10.0M | 4.2M | 42.5 |
| SA-V Manual+Auto | 50.9K | 196.0 hr | 642.6K | 35.5M | 4.2M | 27.7 |
Table 3: Comparison of our datasets with open source VOS datasets in terms of number of videos, duration, number of masklets, masks, frames, and disappearance rate. SA-V Manual contains only manually annotated labels. SA-V Manual+Auto combines manually annotated labels with automatically generated masklets.
| #视频 | 时长 | #Masklets | #掩码 | #帧 | 消失率 | |
|---|---|---|---|---|---|---|
| DAVIS 2017 (Pont-Tuset et al. 2017) | 0.2K | 0.1 hr | 0.4K | 27.1K | 10.7K | 16.1 |
| YouTube-VOS (Xu et al. 2018b) | 4.5K | 5.6 hr | 8.6K | 197.3K | 123.3K | 13.0 |
| UVO-dense (Wang et al. 2021b) | 1.0K | 0.9 hr | 10.2K | 667.1K | 68.3K | 9.2 |
| VOST (Tokmakov et al. 2022) | 0.7K | 4.2 hr | 1.5K | 175.0K | 75.5K | 41.7 |
| BURST (Athar et al. 2022) | 2.9K | 28.9 hr | 16.1K | 600.2K | 195.7K | 37.7 |
| MOSE (Ding et al. 2023) | 2.1K | 7.4 hr | 5.2K | 431.7K | 638.8K | 41.5 |
| Internal | 62.9K | 281.8 hr | 69.6K | 5.4M | 6.0M | 36.4 |
| SA-V Manual | 50.9K | 196.0 hr | 190.9K | 10.0M | 4.2M | 42.5 |
| SA-V Manual+Auto | 50.9K | 196.0 hr | 642.6K | 35.5M | 4.2M | 27.7 |
表 3: Comparison of our datasets with open source VOS datasets in terms of number of videos, duration, number of masklets, masks, frames, and disappearance rate. SA-V Manual contains only manually annotated labels. SA-V Manual+Auto combines manually annotated labels with automatically generated masklets.
6 Zero-shot experiments
6 零样本实验
Here, we compare SAM 2 with previous work on zero-shot video and image tasks. We report the standard metric (Pont-Tuset et al. 2017) for video and mIoU metric for image tasks. Unless otherwise mentioned, the results in this section follow our default setup using Hiera-B+ image encoder with a resolution of 1024 and trained on the full combination of datasets, i.e., SAM 2 (Hiera-B+) in Table 6 (see also §D.2 for details).
本节在零样本视频与图像任务上把 SAM 2 与先前工作比较。视频用标准 (Pont-Tuset et al. 2017),图像用 mIoU。除非另说明,本节默认设定为分辨率 1024 的 Hiera-B+ 图像编码器,并在完整数据组合上训练,即表 6 中的 SAM 2(Hiera-B+)(细节亦见 §D.2)。
6.1 Promptable video segmentation
6.1 可提示视频分割
| (a) offline average across datasets (3-click) | (b) online average across datasets (3-click) |
Figure 5: Zero-shot accuracy over 9 datasets in interactive offline and online evaluation settings.
| (a) 跨数据集离线平均 (3 点击) | (b) 跨数据集在线平均 (3 点击) |
图 5:9 个数据集上交互式离线与在线评测设定中的零样本精度。
We first evaluate promptable video segmentation, which involves simulating an interactive setting that resembles the user experience. We have two settings, offline evaluation, where multiple passes are made through a video to select frames to interact with based on the largest model error, and online evaluation, where the frames are annotated in a single forward pass through the video. These evaluations are conducted on 9 densely annotated zero-shot video datasets using clicks per frame (see §F.1 for details).
我们首先评测可提示视频分割:仿真贴近用户体验的交互设定。两种设定:离线评测——多次遍历视频,按最大模型误差选择交互帧;在线评测——单次前向遍历视频完成标注。评测在 9 个稠密标注的零样本视频数据集上,每帧 次点击(细节见 §F.1)。
We create two strong baselines, SAM+XMem++ and SAM+Cutie, based on two state-of-the-art models for video object segmentation, XMem++ (Bekuzarov et al. 2023) and Cutie (Cheng et al. 2023a).
我们基于两个前沿视频目标分割模型 XMem++(Bekuzarov et al. 2023)与 Cutie(Cheng et al. 2023a)构建两个强基线:SAM+XMem++ 与 SAM+Cutie。
We use XMem++ to generate a video segmentation based on mask inputs on one or multiple frames. SAM is used to provide an initial mask or to refine an output (by feeding the current segmentation as a mask prompt to SAM). For the SAM+Cutie baseline, we modify Cutie to allow taking mask inputs on multiple frames.
用 XMem++ 根据一帧或多帧上的掩码输入生成视频分割;SAM 用于提供初始掩码或 refinement 输出(把当前分割作为掩码提示送入 SAM)。对 SAM+Cutie 基线,我们修改 Cutie 以支持多帧掩码输入。
In Fig. 5, we report the average accuracy over interacted frames. SAM 2 outperforms SAM+XMem++ and SAM+Cutie for both offline and online evaluation settings. Across all 9 datasets (see per-dataset results in §F.1), SAM 2 dominates both methods, generating high-quality video segmentation from a few clicks while allowing continued refinement with prompts. Overall, SAM 2 can generate better segmentation accuracy, with 3 fewer interactions.
图 5 报告在 个交互帧上的平均 。离线与在线设定下 SAM 2 均优于 SAM+XMem++ 与 SAM+Cutie。在全部 9 个数据集上(逐数据集结果见 §F.1),SAM 2 全面领先:少量点击即可得到高质量视频分割,并可继续用提示 refinement。总体而言,SAM 2 以 3 更少的交互取得更好分割精度。
6.2 Semi-supervised video object segmentation
6.2 半监督视频目标分割
| Method | 1-click | 3-click | 5-click | bounding box | ground-truth mask‡ |
|---|---|---|---|---|---|
| SAM+XMem++ | 56.9 | 68.4 | 70.6 | 67.6 | 72.7 |
| SAM+Cutie | 56.7 | 70.1 | 72.2 | 69.4 | 74.1 |
| SAM 2 | 64.7 | 75.3 | 77.6 | 74.4 | 79.3 |
Table 4: Zero-shot accuracy across 17 video datasets using different prompts. We report average accuracy for each type of prompt (1, 3 or 5 clicks, bounding boxes, or ground-truth masks) in the first video frame (‡: this case directly uses masks as inputs into XMem++ or Cutie without SAM).
| 方法 | 1 点击 | 3 点击 | 5 点击 | 边界框 | 真值掩码‡ |
|---|---|---|---|---|---|
| SAM+XMem++ | 56.9 | 68.4 | 70.6 | 67.6 | 72.7 |
| SAM+Cutie | 56.7 | 70.1 | 72.2 | 69.4 | 74.1 |
| SAM 2 | 64.7 | 75.3 | 77.6 | 74.4 | 79.3 |
表 4:17 个视频数据集上不同提示的零样本精度。报告首帧各类提示(1/3/5 点击、边界框或真值掩码)的平均精度(‡:该情形直接把掩码输入 XMem++ 或 Cutie,不经 SAM)。
We evaluate the semi-supervised video object segmentation (VOS) setting (Pont-Tuset et al. 2017) with click, box, or mask prompts only on the first frame of the video. When using click prompts, we interactively sample either 1, 3 or 5 clicks on the first video frame.
我们评测半监督视频目标分割(VOS)设定(Pont-Tuset et al. 2017):仅在视频首帧使用点击、框或掩码提示。使用点击提示时,在首帧交互式采样 1、3 或 5 次点击。
Similar to the interactive setting in §6.1, we compare to XMem++ and Cutie, using SAM for click and box prompts, and in their default setting when using mask prompts. We report the standard accuracy (Pont-Tuset et al. 2017), except for on VOST (Tokmakov et al. 2022), where we report the metric following its protocol. The results are in Table 4. SAM 2 outperforms both methods on the 17 datasets. The results underline that SAM 2 also excels at the conventional, non-interactive VOS task with mask input, for which these other works are specifically designed. Details are in §F.1.3.
与 §6.1 的交互设定类似,我们与 XMem++、Cutie 比较:点击与框提示用 SAM,掩码提示用其默认设定。报告标准 (Pont-Tuset et al. 2017);在 VOST(Tokmakov et al. 2022)上按其协议报告 。结果见表 4。SAM 2 在 17 个数据集上均优于两种方法。结果也说明:即便在这些工作专门设计的、以掩码输入的传统非交互 VOS 任务上,SAM 2 同样出色。细节见 §F.1.3。
6.3 Image segmentation
6.3 图像分割
We evaluate SAM 2 on the Segment Anything task across 37 zero-shot datasets, including 23 datasets previously used by SAM for evaluation. 1-click and 5-click mIoUs are reported in Table 5 and we show the average mIoU by dataset domain and model speed in frames per second (FPS) on a single A100 GPU.
我们在 37 个零样本数据集上评测 SAM 2 的 Segment Anything 任务,其中 23 个此前由 SAM 用于评测。表 5 报告 1 点击与 5 点击 mIoU,并按数据集域给出平均 mIoU,以及单卡 A100 上的帧率(FPS)。
The first column (SA-23 All) shows accuracy on the 23 datasets from SAM. SAM 2 achieves higher accuracy (58.9 mIoU with 1 click) than SAM (58.1 mIoU with 1 click), without using any extra data and while being 6 faster. This can be mainly attributed to the smaller but more effective Hiera image encoder in SAM 2.
第一列(SA-23 All)为 SAM 所用 23 个数据集上的精度。SAM 2 在未使用额外数据且快 6 的情况下,1 点击 mIoU(58.9)高于 SAM(58.1)。这主要归因于 SAM 2 中更小但更有效的 Hiera 图像编码器。
The bottom row shows how training on our SA-1B and video data mix can further improve accuracy to 61.4% on average on the 23 datasets. We also see exceptional gains on the video benchmarks from SA-23 (video datasets are evaluated as images, identical to Kirillov et al. 2023), and the 14 new video datasets we added. More detailed results including a breakdown by dataset are in §F.3.
底行显示:在我们的 SA-1B 与视频数据混合上训练,可把 23 个数据集平均精度进一步提到 61.4%。在 SA-23 的视频基准(按图像评测,与 Kirillov et al. 2023 相同)以及新增的 14 个视频数据集上,提升尤为显著。更细的按数据集分解见 §F.3。
| 1 (5) click mIoU | ||||||
|---|---|---|---|---|---|---|
| Model | Data | SA-23 All | SA-23 Image | SA-23 Video | 14 new Video | FPS |
| SAM | SA-1B | 58.1 (81.3) | 60.8 (82.1) | 54.5 (80.3) | 59.1 (83.4) | 21.7 |
| SAM 2 | SA-1B | 58.9 (81.7) | 60.8 (82.1) | 56.4 (81.2) | 56.6 (83.7) | 130.1 |
| SAM 2 | our mix | 61.9 (83.5) | 63.3 (83.8) | 60.1 (83.2) | 69.6 (85.8) | 130.1 |
Table 5: Zero-shot accuracy on the Segment Anything (SA) task across 37 datasets. The table shows the average 1- and 5-click mIoU of SAM 2 compared to SAM by domains (image/video). We report the average metrics on the 23 datasets used by SAM (SA-23) and the average across 14 additional zero-shot video datasets (as detailed in §F.3).
| 1(5)点击 mIoU | ||||||
|---|---|---|---|---|---|---|
| 模型 | 数据 | SA-23 全部 | SA-23 图像 | SA-23 视频 | 14 个新视频 | FPS |
| SAM | SA-1B | 58.1 (81.3) | 60.8 (82.1) | 54.5 (80.3) | 59.1 (83.4) | 21.7 |
| SAM 2 | SA-1B | 58.9 (81.7) | 60.8 (82.1) | 56.4 (81.2) | 56.6 (83.7) | 130.1 |
| SAM 2 | 我们的混合 | 61.9 (83.5) | 63.3 (83.8) | 60.1 (83.2) | 69.6 (85.8) | 130.1 |
表 5:37 个数据集上 Segment Anything(SA)任务的零样本精度。表按域(图像/视频)比较 SAM 2 与 SAM 的平均 1 与 5 点击 mIoU。报告 SAM 所用 23 个数据集(SA-23)平均,以及额外 14 个零样本视频数据集平均(细节见 §F.3)。
7 Comparison to state-of-the-art in semi-supervised VOS
7 与半监督 VOS 前沿比较
| Method | MOSE val | DAVIS 2017 val | LVOS val | SA-V val | SA-V test | YTVOS 2019 val |
| STCN (Cheng et al. 2021a) | 52.5 | 85.4 | - | 61.0 | 62.5 | 82.7 |
| SwinB-AOT (Yang et al. 2021b) | 59.4 | 85.4 | - | 51.1 | 50.3 | 84.5 |
| SwinB-DeAOT (Yang & Yang 2022) | 59.9 | 86.2 | - | 61.4 | 61.8 | 86.1 |
| RDE (Li et al. 2022a) | 46.8 | 84.2 | - | 51.8 | 53.9 | 81.9 |
| XMem (Cheng & Schwing 2022) | 59.6 | 86.0 | - | 60.1 | 62.3 | 85.6 |
| SimVOS-B (Wu et al. 2023b) | - | 88.0 | - | 44.2 | 44.1 | 84.2 |
| JointFormer (Zhang et al. 2023b) | - | 90.1 | - | - | - | 87.4 |
| ISVOS (Wang et al. 2022) | - | 88.2 | - | - | - | 86.3 |
| DEVA (Cheng et al. 2023b) | 66.0 | 87.0 | 55.9 | 55.4 | 56.2 | 85.4 |
| Cutie-base (Cheng et al. 2023a) | 69.9 | 87.9 | 66.0 | 60.7 | 62.7 | 87.0 |
| Cutie-base+ (Cheng et al. 2023a) | 71.7 | 88.1 | - | 61.3 | 62.8 | 87.5 |
| SAM 2 (Hiera-B+) | 76.6 | 90.2 | 78.0 | 76.8 | 77.0 | 88.6 |
| SAM 2 (Hiera-L) | 77.9 | 90.7 | 78.0 | 77.9 | 78.4 | 89.3 |
Table 6: VOS comparison to prior work. SAM 2 performs well in accuracy (, ) for video segmentation based on first-frame ground-truth mask prompts. SAM 2 performs significantly better on SA-V val/test.
| 方法 | MOSE val | DAVIS 2017 val | LVOS val | SA-V val | SA-V test | YTVOS 2019 val |
| STCN (Cheng et al. 2021a) | 52.5 | 85.4 | - | 61.0 | 62.5 | 82.7 |
| SwinB-AOT (Yang et al. 2021b) | 59.4 | 85.4 | - | 51.1 | 50.3 | 84.5 |
| SwinB-DeAOT (Yang & Yang 2022) | 59.9 | 86.2 | - | 61.4 | 61.8 | 86.1 |
| RDE (Li et al. 2022a) | 46.8 | 84.2 | - | 51.8 | 53.9 | 81.9 |
| XMem (Cheng & Schwing 2022) | 59.6 | 86.0 | - | 60.1 | 62.3 | 85.6 |
| SimVOS-B (Wu et al. 2023b) | - | 88.0 | - | 44.2 | 44.1 | 84.2 |
| JointFormer (Zhang et al. 2023b) | - | 90.1 | - | - | - | 87.4 |
| ISVOS (Wang et al. 2022) | - | 88.2 | - | - | - | 86.3 |
| DEVA (Cheng et al. 2023b) | 66.0 | 87.0 | 55.9 | 55.4 | 56.2 | 85.4 |
| Cutie-base (Cheng et al. 2023a) | 69.9 | 87.9 | 66.0 | 60.7 | 62.7 | 87.0 |
| Cutie-base+ (Cheng et al. 2023a) | 71.7 | 88.1 | - | 61.3 | 62.8 | 87.5 |
| SAM 2 (Hiera-B+) | 76.6 | 90.2 | 78.0 | 76.8 | 77.0 | 88.6 |
| SAM 2 (Hiera-L) | 77.9 | 90.7 | 78.0 | 77.9 | 78.4 | 89.3 |
表 6: 与先前工作的 VOS 比较。基于首帧真值掩码提示做视频分割时,SAM 2 在精度(,)上表现良好;在 SA-V val/test 上显著更好。
Our primary focus is on the general, interactive PVS task, but we also address the specific semi-supervised VOS setting (where the prompt is a ground-truth mask on the first frame), as it is a historically common protocol. We evaluate two versions of SAM 2 with varying image encoder sizes (Hiera-B+/-L) with different speed-vs-accuracy tradeoffs. We measure frames per second (FPS) on a single A100 GPU using a batch-size of one. SAM 2 based on Hiera-B+ and Hiera-L runs at real-time speeds of 43.8 and 30.2 FPS, respectively.
我们主要关注通用交互式 PVS 任务,但也覆盖特定的半监督 VOS 设定(提示为首帧真值掩码),因其是历史上常见的协议。我们评测两种图像编码器规模的 SAM 2(Hiera-B+/-L),对应不同速度—精度权衡。在单卡 A100、批大小为 1 时测 FPS:基于 Hiera-B+ 与 Hiera-L 的 SAM 2 分别以 43.8 与 30.2 FPS 实时运行。
We present a comparison with existing state-of-the-art in Table 6, reporting accuracy using standard protocols. SAM 2 shows significant improvement over the best existing methods. We observe that using a larger image encoder brings significant accuracy gains across the board.
表 6 按标准协议与现有前沿比较精度。SAM 2 相对最佳既有方法显著提升。更大图像编码器在各项上带来明显精度增益。
We also evaluate existing work on the SA-V val and test sets which measure performance for open-world segments of “any” object class. When comparing on this benchmark, we see that most previous methods peak at around the same accuracy. The best performance on SA-V val and SA-V test for prior work is significantly lower demonstrating the gap to a “segment anything in videos” capability. Finally, we see that SAM 2 also brings notable gains in long-term video object segmentation as observed in the LVOS benchmark result. For data and model ablations, see §A.
我们还在衡量开放世界「任意」对象类别片段表现的 SA-V val 与 test 上评测既有工作。多数先前方法在该基准上精度大致封顶;相对「在视频中分割任意对象」能力仍有明显差距。最后,LVOS 结果表明 SAM 2 在长期视频目标分割上也有可观提升。数据与模型消融见 §A。
8 Conclusion
8 结论
We present a natural evolution of Segment Anything into the video domain, based on three key aspects: (i) extending the promptable segmentation task to video, (ii) equipping the SAM architecture to use memory when applied to video, and (iii) the diverse SA-V dataset for training and benchmarking video segmentation. We believe SAM 2 marks a significant advancement in visual perception, positioning our contributions as milestones that will propel further research and applications.
我们从三方面把 Segment Anything 自然演进到视频域:(i)把可提示分割任务扩展到视频;(ii)让 SAM 结构在用于视频时具备记忆;(iii)提供多样的 SA-V 数据集以训练与评测视频分割。我们相信 SAM 2 标志着视觉感知的重要进展,所做贡献将成为推动后续研究与应用的里程碑。
Acknowledgements.
We thank Alexander Kirillov and Jitendra Malik for discussions on project direction. Thanks to Andrew Huang, Sahir Gomez, Miguel Martin, Devansh Kukreja, and Somya Jain for work on the demo, and to Aohan Lin and Meng Wang for creating the dataset visualizer. We thank Shoubhik Debnath and Sagar Vaze for their work on dataset preparation. Thanks also to William Ngan and Sasha Mitts for their design expertise and to Grant Gardner and George Orlin for leading product management. We are grateful to Joelle Pineau, Daniel Bolya, Kate Saenko, Pengchuan Zhang, and Christopher Chedeau, for valuable discussions. Thanks to Rene Martinez Doehner and Baishan Guo for data support, and to our annotation engineering and management partners: Robert Kuo, Rishi Godugu, Bob Kamma, Ida Cheng, Claudette Ward, Kai Brown, Jake Kinney, Jenny Truong, and Karen Bergan. Thanks to Vispi Cassod, Parth Malani, Shiva Koduvayur, Alexander Miller, and Caleb Ho for their support with compute and infra. Finally, we thank Azita Shokrpour, Mallika Malhotra, Rodrick Shepard, Jonathan Torres, Luc Dahlin, David Soofian, Alex Bosenberg, and Amanda Kallet for project-level support.
致谢。
感谢 Alexander Kirillov 与 Jitendra Malik 就项目方向的讨论。感谢 Andrew Huang、Sahir Gomez、Miguel Martin、Devansh Kukreja 与 Somya Jain 在演示上的工作,以及 Aohan Lin 与 Meng Wang 制作数据集可视化。感谢 Shoubhik Debnath 与 Sagar Vaze 在数据准备上的工作。亦感谢 William Ngan 与 Sasha Mitts 的设计专长,以及 Grant Gardner 与 George Orlin 主导产品管理。感谢 Joelle Pineau、Daniel Bolya、Kate Saenko、Pengchuan Zhang 与 Christopher Chedeau 的宝贵讨论。感谢 Rene Martinez Doehner 与 Baishan Guo 的数据支持,以及标注工程与管理合作伙伴:Robert Kuo、Rishi Godugu、Bob Kamma、Ida Cheng、Claudette Ward、Kai Brown、Jake Kinney、Jenny Truong 与 Karen Bergan。感谢 Vispi Cassod、Parth Malani、Shiva Koduvayur、Alexander Miller 与 Caleb Ho 在算力与基础设施上的支持。最后感谢 Azita Shokrpour、Mallika Malhotra、Rodrick Shepard、Jonathan Torres、Luc Dahlin、David Soofian、Alex Bosenberg 与 Amanda Kallet 在项目层面的支持。
Appendix
附录
Table of content:
- • §A: Data and Model Ablations
目录:
- • §A:数据与模型消融
- • §B: Task Details
- • §B:任务细节
- • §C: Limitations
- • §C:局限
- • §D: Model Details
- • §D:模型细节
- • §E: Dataset Details
- • §E:数据集细节
- • §E.2.1: Annotation Guidelines
- • §E.2.1:标注指南
- • §F: Zero-shot Experiments Details
- • §F:零样本实验细节
- • §H: Dataset, Annotation, and Model Cards
- • §H:数据集、标注与模型卡片
Appendix A Data and model ablations
附录 A 数据与模型消融
This section presents ablations that informed the design decisions for SAM 2. We evaluate on SA-V val, Internal-test, our MOSE development set (“MOSE dev”) which contains 200 randomly-sampled videos from the MOSE training split, excluded from our training data and the average over 9 zero-shot video datasets. As the metric for comparison, we report under 3-click input on the first frame as a balance between the 1-click regime and the VOS-style mask prompts. Additionally, we report the average 1-click mIoU on the 23-dataset benchmark used by SAM for the SA task on images. Unless otherwise specified, we perform our ablations at 5122 spatial resolution, trained with SA-V manual and a 10% subset of SA-1B. Additional details are in §D.2.
本节给出指导 SAM 2 设计决策的消融。评测集包括 SA-V val、Internal-test、从 MOSE 训练划分随机抽 200 条且未进训练的 MOSE 开发集(「MOSE dev」),以及 9 个零样本视频数据集的平均。比较指标为在首帧 3 点击输入下的 ,以在 1 点击设定与 VOS 式掩码提示之间折中。另报告 SAM 在图像 SA 任务所用 23 数据集基准上的平均 1 点击 mIoU。除非另说明,消融在空间分辨率 512、用 SA-V manual 与 10% SA-1B 子集训练。更多细节见 §D.2。
A.1 Data ablations
A.1 数据消融
| Training data | mIoU | ||||||||
|---|---|---|---|---|---|---|---|---|---|
| VOS | Internal | SA-V | SA-1B | SA-V val | Internal-test | MOSE dev | 9 zero-shot | SA-23 | |
| 1 | ✓ | 48.1 | 60.2 | 76.9 | 59.7 | 45.4 | |||
| 2 | ✓ | 57.0 | 72.2 | 70.6 | 70.0 | 54.4 | |||
| 3 | ✓ | 63.0 | 72.6 | 72.8 | 69.7 | 53.0 | |||
| 4 | ✓ | ✓ | 62.9 | 73.2 | 73.6 | 69.7 | 58.6 | ||
| 5 | ✓ | ✓ | 63.0 | 73.2 | 73.3 | 70.9 | 55.8 | ||
| 6 | ✓ | ✓ | ✓ | 63.6 | 75.0 | 74.4 | 71.6 | 58.6 | |
| 7 | ✓ | ✓ | 50.0 | 63.2 | 77.6 | 62.5 | 54.8 | ||
| 8 | ✓ | ✓ | 54.9 | 71.5 | 77.9 | 70.6 | 55.1 | ||
| 9 | ✓ | ✓ | 61.6 | 72.8 | 78.3 | 69.9 | 51.0 | ||
| 10 | ✓ | ✓ | ✓ | 62.2 | 74.1 | 78.5 | 70.3 | 57.3 | |
| 11 | ✓ | ✓ | ✓ | 61.8 | 74.4 | 78.5 | 71.8 | 55.7 | |
| 12 | ✓ | ✓ | ✓ | ✓ | 63.1 | 73.7 | 79.0 | 71.6 | 58.9 |
Table 7: We train our model on different data mixtures including VOS (DAVIS, MOSE, YouTubeVOS), and subsets of Internal-train, SA-V, and SA-1B. We report the accuracy when prompted with 3 clicks in the first frame on SA-V val and Internal-test, MOSE, and 9 zero-shot datasets, and the average 1-click mIoU on SA-23 datasets.
| 训练数据 | mIoU | ||||||||
|---|---|---|---|---|---|---|---|---|---|
| VOS | Internal | SA-V | SA-1B | SA-V val | Internal-test | MOSE dev | 9 zero-shot | SA-23 | |
| 1 | ✓ | 48.1 | 60.2 | 76.9 | 59.7 | 45.4 | |||
| 2 | ✓ | 57.0 | 72.2 | 70.6 | 70.0 | 54.4 | |||
| 3 | ✓ | 63.0 | 72.6 | 72.8 | 69.7 | 53.0 | |||
| 4 | ✓ | ✓ | 62.9 | 73.2 | 73.6 | 69.7 | 58.6 | ||
| 5 | ✓ | ✓ | 63.0 | 73.2 | 73.3 | 70.9 | 55.8 | ||
| 6 | ✓ | ✓ | ✓ | 63.6 | 75.0 | 74.4 | 71.6 | 58.6 | |
| 7 | ✓ | ✓ | 50.0 | 63.2 | 77.6 | 62.5 | 54.8 | ||
| 8 | ✓ | ✓ | 54.9 | 71.5 | 77.9 | 70.6 | 55.1 | ||
| 9 | ✓ | ✓ | 61.6 | 72.8 | 78.3 | 69.9 | 51.0 | ||
| 10 | ✓ | ✓ | ✓ | 62.2 | 74.1 | 78.5 | 70.3 | 57.3 | |
| 11 | ✓ | ✓ | ✓ | 61.8 | 74.4 | 78.5 | 71.8 | 55.7 | |
| 12 | ✓ | ✓ | ✓ | ✓ | 63.1 | 73.7 | 79.0 | 71.6 | 58.9 |
表 7: 我们在不同数据混合上训练模型,包括 VOS(DAVIS、MOSE、YouTubeVOS)以及 Internal-train、SA-V、SA-1B 子集。报告首帧 3 点击提示下在 SA-V val、Internal-test、MOSE 与 9 个零样本数据集上的 ,以及 SA-23 上的平均 1 点击 mIoU。
Data mix ablation.
In Table 7, we compare the accuracy of SAM 2 when trained on different data mixtures. We pre-train on SA-1B and then train a separate model for each setting. We fix the number of iterations (200k) and batch size (128) with only the training data changing between experiments. We report accuracy on our SA-V val and Internal set, MOSE, 9 zero-shot video benchmarks, and the SA-23 tasks (§6.3).
数据混合消融。
表 7 比较在不同数据混合上训练的 SAM 2 精度。先在 SA-1B 上预训练,再为每种设定单独训练。固定迭代次数(200k)与批大小(128),仅训练数据变化。报告在 SA-V val、Internal、MOSE、9 个零样本视频基准与 SA-23 任务(§6.3)上的精度。
Row 1 shows that a model purely trained on existing VOS datasets (DAVIS, MOSE, YouTubeVOS) performs well on the in-domain MOSE dev, but poorly on all the others including the 9 zero-shot VOS datasets (59.7 ). We observe tremendous benefit from adding our data engine data into the training mix, including +12.1% average performance improvement on 9 zero-shot datasets (row 11 vs 1). This can be attributed to the limited coverage and size of VOS datasets. Adding SA-1B images improves the performance on the image segmentation task (rows 3 vs 4, 5 vs 6, 9 vs 10, 11 vs 12) without degrading the VOS capability. Training only on SA-V and SA-1B (row 4) is enough to obtain strong performance on all benchmarks except for MOSE (specific object categories). Overall, we obtain the best results when mixing all datasets: VOS, SA-1B, and our data engine data (row 12).
第 1 行显示:仅在现有 VOS 数据集(DAVIS、MOSE、YouTubeVOS)上训练的模型在域内 MOSE dev 上表现好,但在其余全部——包括 9 个零样本 VOS 数据集(59.7 )上很差。把数据引擎数据加入训练混合带来巨大收益,在 9 个零样本数据集上平均提升 +12.1%(第 11 行对第 1 行),可归因于 VOS 数据集覆盖与规模有限。加入 SA-1B 图像提升图像分割(第 3 对 4、5 对 6、9 对 10、11 对 12),且不损害 VOS 能力。仅在 SA-V 与 SA-1B 上训练(第 4 行)已足以在除 MOSE(特定对象类别)外的所有基准上取得强表现。总体最佳来自混合全部数据:VOS、SA-1B 与数据引擎数据(第 12 行)。
Data quantity ablation.
Next, we study the effect of scaling training data. SAM 2 is pre-trained on SA-1B before training on varying sizes of SA-V. We report average score (when prompted with 3 clicks in the first frame) over 3 benchmarks: SA-V val, zero-shot, and MOSE dev. Fig. 6 shows a consistent power law relationship between the quantity of training data and the video segmentation accuracy on all benchmarks.
数据量消融。
接着研究扩展训练数据的影响。SAM 2 先在 SA-1B 预训练,再在不同规模 SA-V 上训练。报告三个基准上的平均 (首帧 3 点击):SA-V val、零样本与 MOSE dev。图 6 显示训练数据量与各基准视频分割精度之间存在稳定的幂律关系。
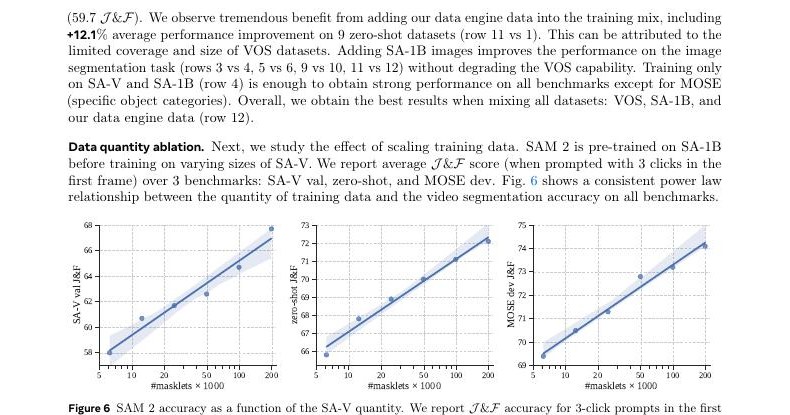
Figure 6: SAM 2 accuracy as a function of the SA-V quantity. We report accuracy for 3-click prompts in the first frame on SA-V val (left), 9 zero-shot datasets (center), and MOSE dev (right).
图 6:SAM 2 精度随 SA-V 数据量变化。报告首帧 3 点击提示下在 SA-V val(左)、9 个零样本数据集(中)与 MOSE dev(右)上的 。
Data quality ablation.
In Table 8, we experiment with filtering strategies for quality. We subsample 50k masklets from SA-V, either randomly or by taking the masklets that have been edited the most by annotators. Filtering based on the number of edited frames leads to strong performance using just 25% of the data, and outperforms random sampling, but is worse than using all 190k SA-V masklets.
数据质量消融。
表 8 试验质量过滤策略。从 SA-V 子采样 50k 个 masklet:随机采样,或取标注者编辑最多的 masklet。按编辑帧数过滤仅用 25% 数据即可取得强表现,优于随机采样,但仍逊于使用全部 190k 个 SA-V masklet。
| mIoU | |||||
|---|---|---|---|---|---|
| Setting | SA-V val | Internal-test | MOSE dev | 9 zero-shot | SA-23 |
| SA-1B + SA-V 50k random | 63.7 | 70.3 | 72.3 | 68.7 | 59.1 |
| SA-1B + SA-V 50k most edited | 66.2 | 73.0 | 72.5 | 69.2 | 58.6 |
| SA-1B + SA-V | 69.9 | 73.8 | 73.9 | 70.8 | 59.8 |
Table 8: We train our model on different subsets of our SA-V Manual data: 50k randomly sampled masklets, 50k masklets with the most edited frames, and the full SA-V dataset (190k masklets).
| mIoU | |||||
|---|---|---|---|---|---|
| 设定 | SA-V val | Internal-test | MOSE dev | 9 zero-shot | SA-23 |
| SA-1B + SA-V 50k random | 63.7 | 70.3 | 72.3 | 68.7 | 59.1 |
| SA-1B + SA-V 50k most edited | 66.2 | 73.0 | 72.5 | 69.2 | 58.6 |
| SA-1B + SA-V | 69.9 | 73.8 | 73.9 | 70.8 | 59.8 |
表 8: 我们在 SA-V Manual 的不同子集上训练:随机 50k 个 masklet、编辑帧最多的 50k 个,以及完整 SA-V(190k 个 masklet)。
A.2 Model architecture ablations
A.2 模型结构消融
In this section, we present model ablations that guided design decisions, conducted under a smaller model setup with 512 input resolution by default. For each ablation setting, we report segmentation accuracy for video () and image (mIoU) tasks, and its relative video segmentation speed (the maximum inference throughput relative to the ablation default setup in gray). We find design choices for image and video components to be largely decoupled – this can be attributed to our modular design and training strategy.
本节给出指导设计决策的模型消融,默认在更小模型设定、输入分辨率 512 下进行。每种消融报告视频()与图像(mIoU)分割精度,以及相对视频分割速度(相对灰色默认设定的最大推理吞吐)。我们发现图像与视频组件的设计选择大体解耦——可归因于模块化设计与训练策略。
A.2.1 Capacity ablations
| mIoU | |||||
|---|---|---|---|---|---|
| res. | MOSE dev | SA-V val | 9 zero-shot | speed | SA-23 |
| 512 | 73.0 | 68.3 | 70.7 | 1.00 | 59.7 |
| 768 | 76.1 | 71.1 | 72.5 | 0.43 | 61.0 |
| 1024 | 77.0 | 70.1 | 72.3 | 0.22 | 61.5 |
| mIoU | |||||
|---|---|---|---|---|---|
| #frames | MOSE dev | SA-V val | 9 zero-shot | speed | SA-23 |
| 4 | 71.1 | 60.0 | 67.7 | 1.00 | 60.1 |
| 8 | 73.0 | 68.3 | 70.7 | 1.00 | 59.7 |
| 10 | 74.5 | 68.1 | 71.1 | 1.00 | 59.9 |
| mIoU | |||||
|---|---|---|---|---|---|
| #mem. | MOSE dev | SA-V val | 9 zero-shot | speed | SA-23 |
| 4 | 73.5 | 68.6 | 70.5 | 1.01 | 59.9 |
| 6 | 73.0 | 68.3 | 70.7 | 1.00 | 59.7 |
| 8 | 73.2 | 69.0 | 70.7 | 0.93 | 59.9 |
| mIoU | |||||
|---|---|---|---|---|---|
| chan. dim. | MOSE dev | SA-V val | 9 zero-shot | speed | SA-23 |
| 64 | 73.0 | 68.3 | 70.7 | 1.00 | 59.7 |
| 256 | 73.4 | 66.4 | 70.0 | 0.92 | 60.0 |
| mIoU | |||||
|---|---|---|---|---|---|
| (#sa, #ca) | MOSE dev | SA-V val | 9 zero-shot | speed | SA-23 |
| (2, 2) | 73.3 | 67.3 | 70.2 | 1.13 | 59.9 |
| (3, 2) | 72.7 | 64.1 | 69.5 | 1.08 | 60.0 |
| (4, 4) | 73.0 | 68.3 | 70.7 | 1.00 | 59.7 |
| mIoU | |||||
|---|---|---|---|---|---|
| img. enc. | MOSE dev | SA-V val | 9 zero-shot | speed | SA-23 |
| S | 70.9 | 65.5 | 69.4 | 1.33 | 57.8 |
| B+ | 73.0 | 68.3 | 70.7 | 1.00 | 59.7 |
| L | 75.0 | 66.3 | 71.9 | 0.60 | 61.1 |
(a)
A.2.1 Capacity ablations
| mIoU | |||||
|---|---|---|---|---|---|
| res. | MOSE dev | SA-V val | 9 zero-shot | 速度 | SA-23 |
| 512 | 73.0 | 68.3 | 70.7 | 1.00 | 59.7 |
| 768 | 76.1 | 71.1 | 72.5 | 0.43 | 61.0 |
| 1024 | 77.0 | 70.1 | 72.3 | 0.22 | 61.5 |
| mIoU | |||||
|---|---|---|---|---|---|
| #frames | MOSE dev | SA-V val | 9 zero-shot | 速度 | SA-23 |
| 4 | 71.1 | 60.0 | 67.7 | 1.00 | 60.1 |
| 8 | 73.0 | 68.3 | 70.7 | 1.00 | 59.7 |
| 10 | 74.5 | 68.1 | 71.1 | 1.00 | 59.9 |
| mIoU | |||||
|---|---|---|---|---|---|
| #mem. | MOSE dev | SA-V val | 9 zero-shot | 速度 | SA-23 |
| 4 | 73.5 | 68.6 | 70.5 | 1.01 | 59.9 |
| 6 | 73.0 | 68.3 | 70.7 | 1.00 | 59.7 |
| 8 | 73.2 | 69.0 | 70.7 | 0.93 | 59.9 |
| mIoU | |||||
|---|---|---|---|---|---|
| chan. dim. | MOSE dev | SA-V val | 9 zero-shot | 速度 | SA-23 |
| 64 | 73.0 | 68.3 | 70.7 | 1.00 | 59.7 |
| 256 | 73.4 | 66.4 | 70.0 | 0.92 | 60.0 |
| mIoU | |||||
|---|---|---|---|---|---|
| (#sa, #ca) | MOSE dev | SA-V val | 9 zero-shot | 速度 | SA-23 |
| (2, 2) | 73.3 | 67.3 | 70.2 | 1.13 | 59.9 |
| (3, 2) | 72.7 | 64.1 | 69.5 | 1.08 | 60.0 |
| (4, 4) | 73.0 | 68.3 | 70.7 | 1.00 | 59.7 |
| mIoU | |||||
|---|---|---|---|---|---|
| img. enc. | MOSE dev | SA-V val | 9 zero-shot | 速度 | SA-23 |
| S | 70.9 | 65.5 | 69.4 | 1.33 | 57.8 |
| B+ | 73.0 | 68.3 | 70.7 | 1.00 | 59.7 |
| L | 75.0 | 66.3 | 71.9 | 0.60 | 61.1 |
(a)
Input size.
During training, we sample sequences of frames of fixed resolution and fixed length (here denoted by # frames). We ablate their impact in Tables , . A higher resolution leads to significant improvements across image and video tasks, and we use a spatial input resolution of 10242 in our final model. Increasing the number of frames brings notable gains on video benchmarks and we use a default of 8 to balance speed and accuracy.
输入尺寸。
训练时采样固定分辨率、固定长度(记为 #frames)的帧序列。表中消融其影响。更高分辨率显著提升图像与视频任务,最终模型用空间输入分辨率 1024。增加帧数在视频基准上带来可观收益,默认用 8 帧以平衡速度与精度。
Memory size.
Increasing the (maximum) number of memories, , generally helps the performance although there could be some variance, as in Table . We use a default value of 6 past frames to strike a balance between temporal context length and computational cost. Using fewer channels for memories does not cause much performance regression as in Table , while making the memory required for storage 4 smaller.
记忆大小。
增大(最大)记忆数 通常有帮助,尽管可能有波动。我们默认用 6 个过去帧,以在时间上下文长度与计算代价之间折中。减少记忆通道数不会造成明显性能回退,同时存储所需记忆降为约 4 更小。
Model size.
More capacity in the image encoder or memory-attention (#self-/#cross-attention blocks) generally leads to improved results, as shown in Tables , . Scaling the image encoder brings gains on both image and video metrics, while scaling the memory-attention only improves video metrics. We default to using a B+ image encoder, which provides a reasonable balance for speed and accuracy.
模型规模。
图像编码器或记忆注意力(#自注意力/#交叉注意力块)容量更大通常带来更好结果。扩展图像编码器同时提升图像与视频指标,扩展记忆注意力主要提升视频指标。默认用 B+ 图像编码器,在速度与精度间较均衡。
A.2.2 Relative positional encoding
| mIoU | |||||||
|---|---|---|---|---|---|---|---|
| RPB | 2d-RoPE | MOSE dev | SA-V val | LVOSv2 val | 9 zero-shot | speed | SA-23 |
| ✓ | 73.0 | 68.3 | 71.6 | 70.7 | 1.00 | 59.7 | |
| ✓ | ✓ | 73.6 | 67.9 | 71.0 | 71.5 | 0.93 | 60.0 |
| 72.8 | 67.1 | 70.3 | 70.3 | 1.04 | 59.9 |
Table 10: We use 2d-RoPE positional encoding in memory attention while removing RPB from the image encoder by default (gray). Removing RPB also allows us to enable FlashAttention-2 (Dao 2023), which gives a significant speed boost at (10242) resolution. At such higher resolution , the speed gap between 2d-RoPE (1st row) and the no RoPE baseline (3rd row) becomes small (4%).
A.2.2 Relative positional encoding
| mIoU | |||||||
|---|---|---|---|---|---|---|---|
| RPB | 2d-RoPE | MOSE dev | SA-V val | LVOSv2 val | 9 zero-shot | speed | SA-23 |
| ✓ | 73.0 | 68.3 | 71.6 | 70.7 | 1.00 | 59.7 | |
| ✓ | ✓ | 73.6 | 67.9 | 71.0 | 71.5 | 0.93 | 60.0 |
| 72.8 | 67.1 | 70.3 | 70.3 | 1.04 | 59.9 |
表 10: 默认在记忆注意力中用 2d-RoPE 位置编码,并从图像编码器去除 RPB(灰行)。去除 RPB 还可启用 FlashAttention-2(Dao 2023),在(1024)分辨率上显著加速。在更高分辨率下,2d-RoPE(第 1 行)与无 RoPE 基线(第 3 行)的速度差距变小(约 4%)。
By default, we always use absolute positional encoding in both the image encoder as well as memory attention. In Table 10, we study relative positional encoding design choices. Here we also evaluate on LVOSv2 (Hong et al. 2024) with 3 clicks on the 1st frame as a benchmark for long-term video object segmentation.
默认在图像编码器与记忆注意力中始终使用绝对位置编码。表 10 研究相对位置编码设计。这里也在 LVOSv2(Hong et al. 2024)上以首帧 3 点击评测,作为长期视频目标分割基准。
While SAM (Kirillov et al. 2023) follows Li et al. 2022b in adding relative positional biases (RPB) to all image encoder layers, Bolya et al. 2023 improve upon this by removing RPB in all but the global attention layers while adopting “absolute-win” positional encoding which brings large speed gains. We improve upon this further by removing all RPB from the image encoder, with no performance regression on SA-23 and minimal regression on video benchmarks (see Table 10), while giving a significant speed boost at 1024 resolution. We also find it is beneficial to use 2d-RoPE (Su et al. 2021; Heo et al. 2024) in the memory attention.
SAM(Kirillov et al. 2023)按 Li et al. 2022b 在全部图像编码器层加入相对位置偏置(RPB);Bolya et al. 2023 改进为仅在全局注意力层保留 RPB,并采用「absolute-win」位置编码以大幅加速。我们进一步从图像编码器去掉全部 RPB:在 SA-23 上无性能回退,视频基准仅轻微回退(见表 10),同时在 1024 分辨率上显著加速。我们也发现在记忆注意力中使用 2d-RoPE(Su et al. 2021;Heo et al. 2024)有益。
Recurrent memory.
We investigate the effectiveness of feeding the memory features to a GRU before adding them to the memory bank. Similar to §A.2.2, we also evaluate on LVOSv2 as an additional benchmark for long-term object segmentation. While prior works have commonly employed GRU (Cho et al. 2014) states as a means of incorporating memory into the tracking process, our findings in Table 11 suggest that this approach does not provide an improvement (except slightly on LVOSv2). Instead, we find it sufficient to directly store the memory features in the memory bank, which is both simpler and more efficient.
循环记忆。
我们检验在把记忆特征加入记忆库前先送入 GRU 是否有效。与 §A.2.2 类似,也在 LVOSv2 上作为长期目标分割附加基准。尽管先前工作常用 GRU(Cho et al. 2014)状态纳入跟踪记忆,表 11 显示该方法并无提升(仅在 LVOSv2 上略好)。直接把记忆特征存入记忆库既更简单也更高效,已足够。
Object pointers.
We ablate the impact of cross-attending to the object pointer vectors from the mask decoder output in other frames (see §4). The results presented in Table 11 show that while cross-attending to object pointers does not enhance average performance across the 9 zero-shot datasets, it significantly boosts performance on SA-V val dataset as well as on the challenging LVOSv2 benchmark (validation split). Hence, we default to cross-attending to object pointers together with the memory bank embeddings from the memory encoder.
对象指针。
我们消融对其他帧掩码解码器输出的对象指针向量做交叉注意力的影响(见 §4)。表 11 显示:对对象指针交叉注意力并未提升 9 个零样本数据集平均表现,但显著提升 SA-V val 以及困难的 LVOSv2 基准(验证划分)。因此默认在交叉注意力中同时使用对象指针与记忆编码器得到的记忆库嵌入。
| mIoU | |||||||
|---|---|---|---|---|---|---|---|
| Object Pointers | GRU | MOSE dev | SA-V val | LVOSv2 val | 9 zero-shot | speed | SA-23 |
| 73.1 | 64.5 | 67.0 | 70.9 | 1.00 | 59.9 | ||
| ✓ | 72.3 | 65.3 | 68.9 | 70.5 | 0.97 | 60.0 | |
| ✓ | 73.0 | 68.3 | 71.6 | 70.7 | 1.00 | 59.7 |
Table 11: Ablations on memory design. We use object pointers by default (gray) and also study recurrent GRU memory.
| mIoU | |||||||
|---|---|---|---|---|---|---|---|
| 对象指针 | GRU | MOSE dev | SA-V val | LVOSv2 val | 9 zero-shot | speed | SA-23 |
| 73.1 | 64.5 | 67.0 | 70.9 | 1.00 | 59.9 | ||
| ✓ | 72.3 | 65.3 | 68.9 | 70.5 | 0.97 | 60.0 | |
| ✓ | 73.0 | 68.3 | 71.6 | 70.7 | 1.00 | 59.7 |
表 11: 记忆设计消融。默认使用对象指针(灰行),并研究循环 GRU 记忆。
Appendix B Details on the PVS Task
附录 B PVS 任务细节
The Promptable Visual Segmentation (PVS) task can be seen as an extension of the Segment Anything (SA) task from static images to videos. In the PVS setting, given an input video, the model can be interactively prompted with different types of inputs (including clicks, boxes, or masks) on any frame in the video, with the goal of segmenting (and tracking) a valid object throughout the video. When interacting with a video, the model provides an instant response on the frame being prompted (similar to the interactive experience of SAM on images), and also returns the segmentation of the object throughout the entire video in near real-time. Similar to SAM the focus is on valid objects which have a clearly defined boundary, and we do not consider regions without visual boundaries (e.g. Bekuzarov et al. 2023). Fig. 7 illustrates the task.
可提示视觉分割(PVS)任务可视为把 Segment Anything(SA)任务从静态图像扩展到视频。在 PVS 设定下,给定输入视频,可在任意帧用点击、框或掩码等不同类型输入交互式提示模型,目标是在整段视频中分割(并跟踪)有效对象。与视频交互时,模型在被提示帧上即时响应(类似 SAM 在图像上的交互体验),并以近实时返回对象在整段视频上的分割。与 SAM 一样,焦点是边界清晰定义的有效对象,不考虑无视觉边界的区域(如 Bekuzarov et al. 2023)。图 7 示意该任务。
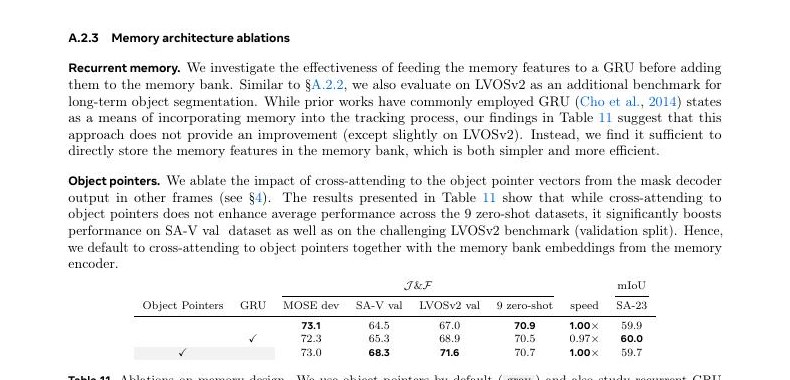
Figure 7: An illustration of the Promptable Visual Segmentation task (PVS). Previously studied tasks such as Segment Anything (SA) and semi-supervised Video Object Segmentation (VOS) can be seen as special cases of the PVS task.
图 7:可提示视觉分割任务(PVS)示意。先前研究的 Segment Anything(SA)与半监督视频目标分割(VOS)等任务可视为 PVS 的特例。
PVS is related to tasks in the image and video domains. For images, the SA task can be considered a subset of PVS with the video reduced to a single frame. Similarly, traditional semi-supervised and interactive VOS (Pont-Tuset et al. 2017) tasks are special cases of PVS, limited to mask prompts provided only on the first frame and scribbles on multiple frames to segment objects throughout a video, respectively. In PVS, prompts can either be clicks, masks, or boxes, and the focus is on enhancing the interactive experience, enabling refinement of a segmentation with minimal interaction.
PVS 与图像、视频域任务相关。对图像,SA 任务可视为视频退化为单帧时的 PVS 子集。类似地,传统半监督与交互式 VOS(Pont-Tuset et al. 2017)分别是 PVS 的特例:半监督限于仅在首帧给掩码提示;交互式则在多帧给涂鸦以分割整段视频中的对象。PVS 中提示可以是点击、掩码或框,重点是增强交互体验,以最少交互 refinement 分割。
Appendix C Limitations
附录 C 局限
SAM 2 demonstrates strong performance in both static image and video domains, yet it encounters difficulties in certain scenarios. The model may fail to segment objects across shot changes and can lose track of or confuse objects in crowded scenes, after long occlusions or in extended videos. To alleviate this issue, we designed the ability to prompt SAM 2 in any frame: if the model loses the object or makes an error, refinement clicks on additional frames can quickly recover the correct prediction in most cases. SAM 2 also struggles with accurately tracking objects with very thin or fine details especially when they are fast-moving. Another challenging scenario occurs when there are nearby objects with similar appearance (e.g., multiple identical juggling balls). Incorporating more explicit motion modeling into SAM 2 could mitigate errors in such cases.
SAM 2 在静态图像与视频域均表现强劲,但在某些场景仍有困难。模型可能无法跨镜头切换分割对象,也可能在拥挤场景、长时间遮挡或长视频中跟丢或混淆对象。为缓解,我们设计了可在任意帧提示 SAM 2 的能力:若模型丢失对象或出错,在额外帧上 refinement 点击多数情况下可快速恢复正确预测。SAM 2 也难以准确跟踪带极细或精细细节、尤其是快速运动的对象。另一挑战是外观相近的邻近对象(如多个相同的杂耍球)。在 SAM 2 中引入更显式的运动建模或可减轻此类错误。
While SAM 2 can track multiple objects in a video simultaneously, SAM 2 processes each object separately, utilizing only shared per-frame embeddings without inter-object communication. While this approach is simple, incorporating shared object-level contextual information could aid in improving efficiency.
虽可同时跟踪视频中多个对象,但 SAM 2 对每个对象单独处理,仅共享逐帧嵌入、对象间无通信。做法简单,但纳入共享的对象级上下文信息或有助于提升效率。
Our data engine relies on human annotators to verify masklet quality and select frames that require correction. Future developments could include automating this process to enhance efficiency.
我们的数据引擎依赖人工标注者核验 masklet 质量并选择需纠正的帧。未来可自动化该流程以提升效率。
Appendix D SAM 2 details
附录 D SAM 2 细节
D.1 Architecture
D.1 结构
Here we discuss further architecture details, expanding on the model description in §4.
这里进一步讨论结构细节,扩展 §4 的模型描述。
Image encoder.
We use a feature pyramid network (Lin et al. 2017) to fuse the stride 16 and 32 features from Stages 3 and 4 of the Hiera image encoder respectively to produce the image embeddings for each frame. In addition, the stride 4 and 8 features from Stages 1 and 2 are not used in the memory attention but are added to the upsampling layers in the mask decoder as shown in Figure 8, which helps produce high-resolution segmentation details. We follow Bolya et al. 2023 in using windowed absolute positional embeddings in the Hiera image encoder. In Bolya et al. 2023, RPB provided positional information spanning across windows in the image encoder, in lieu of which we adopt a simpler approach of interpolating the global positional embedding instead to span across windows. We do not use any relative positional encoding. We train models with varying image encoder sizes – T, S, B+ and L. We follow Li et al. 2022b and use global attention in only a subset of the image encoder layers (see Table 12).
图像编码器。
我们用特征金字塔网络(Lin et al. 2017)融合 Hiera 图像编码器第 3、4 阶段的 stride 16 与 32 特征,得到每帧图像嵌入。此外,第 1、2 阶段的 stride 4 与 8 特征不进入记忆注意力,但如图 8 所示加入掩码解码器的上采样层,以产出高分辨率分割细节。按 Bolya et al. 2023,在 Hiera 图像编码器中使用窗口化绝对位置嵌入。Bolya et al. 2023 用 RPB 提供跨窗口的位置信息;我们改为更简单的做法:插值全局位置嵌入以跨越窗口。不使用任何相对位置编码。训练 T、S、B+、L 等不同图像编码器规模。按 Li et al. 2022b,仅在图像编码器部分层使用全局注意力(见表 12)。
Memory attention.
In addition to sinusoidal absolute positional embeddings, we use 2d spatial Rotary Positional Embedding (RoPE) (Su et al. 2021; Heo et al. 2024) in self-attention and cross-attention layers. The object pointer tokens are excluded from RoPE as they do not have specific spatial correspondence. By default, the memory attention uses layers.
记忆注意力。
除正弦绝对位置嵌入外,在自注意力与交叉注意力层使用二维空间旋转位置嵌入(RoPE)(Su et al. 2021;Heo et al. 2024)。对象指针 token 无特定空间对应,故排除在 RoPE 之外。默认记忆注意力用 层。
Figure 8: Mask decoder architecture. The design largely follows SAM, and we additionally include the stride 4 and 8 features from the image encoder during upsampling. We also use the mask token corresponding to the output mask as an object pointer and generate an occlusion score which indicates if the object of interest is visible in the current frame.
图 8:掩码解码器结构。设计大体沿用 SAM,并在上采样时额外并入图像编码器的 stride 4 与 8 特征。我们还把对应输出掩码的 mask token 用作对象指针,并生成遮挡分数,指示感兴趣对象在当前帧是否可见。
Prompt encoder and mask decoder.
The prompt encoder design follows SAM, and we next discuss additional details on design changes in the mask decoder. We use the mask token corresponding to the output mask as the object pointer token for the frame, which is placed in the memory bank. As discussed in §4, we also introduce an occlusion prediction head. This is accomplished by including an additional token along with the mask and IoU output tokens. An additional MLP head is applied to this new token to produce a score indicating the likelihood of the object of interest being visible in the current frame (as shown in Figure 8). In the memory bank, we also add a learned occlusion embedding to the memory features of those frames that are predicted to be occluded (invisible) by the occlusion prediction head.
提示编码器与掩码解码器。
提示编码器设计沿用 SAM;下面补充掩码解码器的设计变化。我们把对应输出掩码的 mask token 作为该帧的对象指针 token,放入记忆库。如 §4 所述,还引入遮挡预测头:在掩码与 IoU 输出 token 之外再加一个 token,并对该新 token 施加额外 MLP 头,产出感兴趣对象在当前帧可见的似然分数(见图 8)。在记忆库中,对遮挡预测头判定为被遮挡(不可见)的帧,还向其记忆特征加入可学习的遮挡嵌入。
SAM introduced the ability to output multiple valid masks when faced with ambiguity about the object being segmented in an image. For example, when a person clicks on the tire of a bike, the model can interpret this click as referring to only the tire or the entire bike and output multiple predictions. In videos, this ambiguity can extend across video frames. For example, if in one frame only the tire is visible, a click on the tire might relate to just the tire, or as more of the bike becomes visible in subsequent frames, this click could have been intended for the entire bike. To handle this ambiguity, SAM 2 predicts multiple masks at each step of the video. If further prompts do not resolve the ambiguity, the model selects the mask with the highest predicted IoU for the current frame for further propagation in the video.
SAM 在图像分割对象存在歧义时可输出多个有效掩码。例如点击自行车轮胎时,模型可理解为仅轮胎或整车并给出多种预测。在视频中,歧义可跨帧延续:若一帧只见轮胎,点击可能只指轮胎;后续帧露出更多车身时,同一点击也可能本意是整车。为处理该歧义,SAM 2 在视频每一步预测多个掩码;若后续提示仍未消歧,则选当前帧预测 IoU 最高的掩码继续在视频中传播。
Memory encoder and memory bank.
Our memory encoder does not use an additional image encoder and instead reuses the image embeddings produced by the Hiera encoder, which are fused with the predicted mask information to produce memory features (as discussed in §4). This design allows the memory features to benefit from the strong representations produced by the image encoder (especially when we scale the image encoder to a larger size). Further, we project the memory features in our memory bank to a dimension of 64, and split the 256-dim object pointer into 4 tokens of 64-dim for cross-attention to the memory bank.
记忆编码器与记忆库。
记忆编码器不另用图像编码器,而是复用 Hiera 编码器产出的图像嵌入,再与预测掩码信息融合得到记忆特征(见 §4)。该设计使记忆特征受益于图像编码器的强表征(尤其在把图像编码器扩到更大时)。此外,我们把记忆库中的记忆特征投影到 64 维,并把 256 维对象指针拆成 4 个 64 维 token,以便对记忆库做交叉注意力。
Handling multiple objects in a video.
When applying SAM 2 to segment multiple objects in the same video (such as multi-object tracking in the semi-supervised VOS evaluation), we perform inference on each object independently. More specifically, we share the visual features from the image encoder between all the objects in the video but run all the other model components (such as the memory bank and the mask decoder) separately for each object.
处理视频中的多对象。
把 SAM 2 用于同一视频中分割多个对象时(如半监督 VOS 评测中的多目标跟踪),对每个对象独立推理。更具体地,所有对象共享图像编码器的视觉特征,但其余组件(如记忆库与掩码解码器)按对象分别运行。
D.2 Training
D.2 训练
D.2.1 Pre-training
We first pre-train SAM 2 on static images on the SA-1B dataset. Table details the settings used during pre-training on SA-1B – other settings not mentioned here follow Kirillov et al. 2023. The image encoder is initialized from MAE pre-trained Hiera (Ryali et al. 2023). Similar to SAM, we filter masks covering more than 90% of the image and restricted training to 64 randomly sampled masks per image.
D.2.1 预训练
我们先在 SA-1B 静态图像上预训练 SAM 2。表中详列 SA-1B 预训练设定——未提及处遵循 Kirillov et al. 2023。图像编码器由 MAE 预训练的 Hiera(Ryali et al. 2023)初始化。与 SAM 一样,过滤覆盖图像超过 90% 的掩码,并限制每图随机采样最多 64 个掩码。
Unlike SAM, we found it beneficial to use an loss to more aggressively supervise the IoU predictions and to apply a sigmoid activation to the IoU logits to restrict the output into the range between 0 and 1. For multi-mask predictions (on the first click), we supervise the IoU predictions of all masks to encourage better learning of when a mask might be bad, but only supervise the mask logits with the lowest segmentation loss (linear combination of focal and dice loss). In SAM, during iterative sampling of points, two iterations were inserted with no additional prompts (only feeding the previous mask logits) – we do not add such iterations during our training and use 7 correction clicks (instead of 8 in SAM). We also employ horizontal flip augmentation during training and resize the image to a square size of 10241024.
与 SAM 不同,我们发现用 损失更积极地监督 IoU 预测、并对 IoU logits 施加 sigmoid激活以把输出限制在 0 到 1 之间有益。对多掩码预测(首次点击),我们监督全部掩码的 IoU 预测,以更好学习何时掩码可能较差;但掩码 logits 只监督分割损失最低者(focal 与 dice 的线性组合)。SAM 在迭代采样点时会插入两次无额外提示的迭代(只喂入先前掩码 logits)——我们训练中不加此类迭代,并用 7 次纠正点击(SAM 为 8)。训练时还做水平翻转增强,并把图像缩放为正方形 10241024。
We use AdamW (Loshchilov & Hutter 2019) and apply layer decay (Clark et al. 2020) on the image encoder and follow a reciprocal square-root schedule (Zhai et al. 2022). See Table 12 (a) for the hyperparameters in our pre-training stage.
我们用 AdamW(Loshchilov & Hutter 2019),对图像编码器施加分层衰减(Clark et al. 2020),并遵循倒数平方根日程(Zhai et al. 2022)。预训练超参见表 12(a)。
D.2.2 Full training
After pre-training, we train SAM 2 on our introduced datasets SA-V + Internal (section §5.2), a 10% subset of SA-1B, and a mixture of open-source video datasets including DAVIS (Pont-Tuset et al. 2017; Caelles et al. 2019), MOSE (Ding et al. 2023), and YouTubeVOS (Xu et al. 2018b). Our released model is trained on SA-V manual + Internal and SA-1B.
D.2.2 完整训练
预训练后,在我们引入的 SA-V + Internal(§5.2)、10% SA-1B 子集,以及 DAVIS(Pont-Tuset et al. 2017;Caelles et al. 2019)、MOSE(Ding et al. 2023)、YouTubeVOS(Xu et al. 2018b)等开源视频数据混合上训练 SAM 2。发布模型在 SA-V manual + Internal 与 SA-1B 上训练。
SAM 2 is designed for two tasks; the PVS task (on videos) and the SA task (on images). Training is done jointly on image and video data. To optimize our data usage and computational resources during training, we adopt an alternating training strategy between video data (multiple frames) and static images (one single frame). Specifically, in each training iteration, we sample a full batch either from the image or video dataset, with their sampling probabilities proportional to the size of each data source. This approach allows for a balanced exposure to both tasks and a different batch size for each data source to maximize compute utilization. Settings not explicitly mentioned here for the image task follow settings from the pre-training phase. See Table 12 (b) for the hyperparameters in our full training stage. The training data mixture consists of 15.2% SA-1B, 70% SA-V and 14.8% Internal. The same settings are used when open-source datasets are included, with the change that the additional data is included (1.3% DAVIS, 9.4% MOSE, 9.2% YouTubeVOS, 15.5% SA-1B, 49.5% SA-V, 15.1% Internal). When training on SA-V and other video datasets, we only use those manually annotated masklets (without adding automatically generated ones), which are sufficient to achieve strong performance based on our analyses.
SAM 2 面向两项任务:视频上的 PVS 与图像上的 SA。训练在图像与视频数据上联合进行。为优化数据利用与算力,我们在视频数据(多帧)与静态图像(单帧)之间交替训练:每次迭代从图像或视频数据集采样完整一批,采样概率与各数据源规模成正比。这样可均衡接触两项任务,并为各数据源使用不同批大小以最大化算力利用。图像任务未明示的设定沿用预训练阶段。完整训练超参见表 12(b)。训练数据混合约为 15.2% SA-1B、70% SA-V、14.8% Internal。纳入开源数据集时比例变为约 1.3% DAVIS、9.4% MOSE、9.2% YouTubeVOS、15.5% SA-1B、49.5% SA-V、15.1% Internal。在 SA-V 与其他视频数据集上训练时,仅用人工标注 masklet(不加自动生成),按我们的分析已足以取得强表现。
We apply a series of data augmentations to the training videos (detailed in Table 12), including random horizontal flips, random affine transforms, random color jittering, and random grayscale transforms, as listed in Table 12. We also adopt a mosaic transform to simulate challenging scenarios with multiple similar-looking objects – with 10% probability, we tile the same training video into a 22 grid and select a masklet from one of the 4 quadrants as the target object to segment. In this case, the model must focus on other cues like motion or temporal continuity to distinguish the target object from their identical-looking counterparts in other quadrants. In addition, the videos and objects in each quadrant are smaller in size (only half the original width and height) after this mosaic transform, which also facilitates learning to segment small objects.
我们对训练视频施加一系列数据增强(详见表 12),包括随机水平翻转、随机仿射、随机颜色抖动与随机灰度等。还采用马赛克变换以仿真多个外观相似对象的困难场景:以 10% 概率把同一训练视频铺成 22 网格,并从四个象限之一选一个 masklet 作为目标。此时模型须依赖运动或时间连续性等其他线索,把目标与其他象限中外观相同的对应物区分开。此外,马赛克后各象限中的视频与对象更小(宽高仅原尺寸一半),也有助于学习分割小对象。
| config | value |
|---|---|
| data | SA-1B |
| steps | 90k |
| resolution | 1024 |
| precision | bfloat16 |
| optimizer | AdamW |
| optimizer momentum | |
| gradient clipping | type: , max: 0.1 |
| weight decay | 0.1 |
| learning rate (lr) | 4e-4 |
| lr schedule | reciprocal sqrt, timescale=1000 |
| warmup | linear, 1k iters |
| cooldown | linear, 5k iters |
| layer-wise decay | 0.8 (T, S), 0.9 (B+), 0.925 (L) |
| augmentation | hflip, resize to 1024 (square) |
| batch size | 256 |
| drop path | 0.1 (T, S), 0.2 (B+), 0.3 (L) |
| mask losses (weight) | focal (20), dice (1) |
| IoU loss (weight) | (1) |
| max # masks per image | 64 |
| # correction points | 7 |
| global attn. blocks | 5-7-9 (T), 7-10-13 (S), 12-16-20 (B+), 23-33-43 (L) |
| config | value |
|---|---|
| data | SA-1B, Internal, SA-V |
| steps | 150k |
| resolution | 1024 |
| precision | bfloat16 |
| optimizer | AdamW |
| optimizer momentum | |
| gradient clipping | type: , max: 0.1 |
| weight decay | 0.1 |
| learning rate (lr) | img. enc.: 6e-5, other: 3.0e-4 |
| lr schedule | cosine |
| warmup | linear, 7.5k iters |
| layer-wise decay | 0.8 (T, S), 0.9 (B+), 0.925 (L) |
| image augmentation | hflip, resize to 1024 (square) |
| video augmentation | hflip, affine (deg: 25, shear: 20), colorjitter (b: 0.1, c: 0.03, s: 0.03, h: null), grayscale (0.05), per frame colorjitter (b: 0.1, c: 0.05, s: 0.05, h: null), mosaic-22 (0.1) |
| batch size | 256 |
| drop path | 0.1 (T, S), 0.2 (B+), 0.3 (L) |
| mask losses (weight) | focal (20), dice (1) |
| IoU loss (weight) | (1) |
| occlusion loss (weight) | cross-entropy (1) |
| max. masks per frame. | image: 64, video: 3 |
| # correction points | 7 |
| global attn. blocks | 5-7-9 (T), 7-10-13 (S), 12-16-20 (B+), 23-33-43 (L) |
(a)
| 配置 | 取值 |
|---|---|
| data | SA-1B |
| steps | 90k |
| resolution | 1024 |
| precision | bfloat16 |
| optimizer | AdamW |
| optimizer momentum | |
| gradient clipping | type: , max: 0.1 |
| weight decay | 0.1 |
| learning rate (lr) | 4e-4 |
| lr schedule | reciprocal sqrt, timescale=1000 |
| warmup | linear, 1k iters |
| cooldown | linear, 5k iters |
| layer-wise decay | 0.8 (T, S), 0.9 (B+), 0.925 (L) |
| augmentation | hflip, resize to 1024 (square) |
| batch size | 256 |
| drop path | 0.1 (T, S), 0.2 (B+), 0.3 (L) |
| mask losses (weight) | focal (20), dice (1) |
| IoU loss (weight) | (1) |
| max # masks per image | 64 |
| # correction points | 7 |
| global attn. blocks | 5-7-9 (T), 7-10-13 (S), 12-16-20 (B+), 23-33-43 (L) |
| 配置 | 取值 |
|---|---|
| data | SA-1B, Internal, SA-V |
| steps | 150k |
| resolution | 1024 |
| precision | bfloat16 |
| optimizer | AdamW |
| optimizer momentum | |
| gradient clipping | type: , max: 0.1 |
| weight decay | 0.1 |
| learning rate (lr) | img. enc.: 6e-5, other: 3.0e-4 |
| lr schedule | cosine |
| warmup | linear, 7.5k iters |
| layer-wise decay | 0.8 (T, S), 0.9 (B+), 0.925 (L) |
| image augmentation | hflip, resize to 1024 (square) |
| video augmentation | hflip, affine (deg: 25, shear: 20), colorjitter (b: 0.1, c: 0.03, s: 0.03, h: null), grayscale (0.05), per frame colorjitter (b: 0.1, c: 0.05, s: 0.05, h: null), mosaic-22 (0.1) |
| batch size | 256 |
| drop path | 0.1 (T, S), 0.2 (B+), 0.3 (L) |
| mask losses (weight) | focal (20), dice (1) |
| IoU loss (weight) | (1) |
| occlusion loss (weight) | cross-entropy (1) |
| max. masks per frame. | image: 64, video: 3 |
| # correction points | 7 |
| global attn. blocks | 5-7-9 (T), 7-10-13 (S), 12-16-20 (B+), 23-33-43 (L) |
(a)
We train by simulating an interactive setting, sampling 8-frame sequences and randomly selecting up to 2 frames (including the first) for corrective clicks. During training, we use ground-truth masklets and model predictions to sample prompts, with initial prompts being the ground-truth mask (50% probability), a positive click from the ground-truth mask (25%), or a bounding box input (25%).
我们通过仿真交互设定训练:采样 8 帧序列,随机选最多 2 帧(含第一帧)做纠正点击。训练时用真值 masklet 与模型预测采样提示;初始提示为真值掩码(50%)、来自真值掩码的正点击(25%)或边界框(25%)。
We restrict the maximum number of masklets for each sequence of 8 frames to 3 randomly chosen ones. We reverse the temporal order with a probability of 50% to help generalization to bi-directional propagation. When we sample corrective clicks, with a small probability of 10%, we randomly sample clicks from the ground truth mask, irrespective of the model prediction, to allow additional flexibility in mask refinement.
每个 8 帧序列最多随机选 3 个 masklet。以 50% 概率反转时间顺序,以利于双向传播泛化。采样纠正点击时,以 10% 小概率直接从真值掩码随机采样点击(不论模型预测),以便掩码 refinement 更灵活。
Fine-tuning using 16-frame sequences.
A potential shortcoming of the procedure above is that the model only sees sampled 8-frame sequences during training, which is relatively short compared to the full video length during inference. To alleviate this issue and further boost the segmentation quality on long videos, we introduce an extra fine-tuning stage where we sample 16-frame sequences on challenging videos (those videos with the highest number of edited frames, as described in §E.2.1). More specifically, we sort our masklets by number of edited frames and only consider the top 50% most edited masklets for training, for both SA-V and Internal datasets. We still keep the complete versions of the OSS datasets (DAVIS, MOSE, and YouTubeVOS) in the training mix. We fine-tune for 50k iterations (1/3 of the original schedule) using half of the original learning rate and freeze the image encoder to fit the 16-frame sequence into the 80 GB memory of A100 GPUs.
用 16 帧序列微调。
上述流程的潜在不足是:训练只见 8 帧序列,相对推理时的完整视频偏短。为缓解并进一步提升长视频分割质量,我们引入额外微调阶段:在困难视频(编辑帧数最多者,见 §E.2.1)上采样 16 帧序列。具体地,按编辑帧数给 masklet 排序,仅取编辑最多的前 50% 用于训练(SA-V 与 Internal 皆然)。开源数据集(DAVIS、MOSE、YouTubeVOS)仍用完整版本。微调 50k 次迭代(原日程的 1/3),学习率为原先一半,并冻结图像编码器,以便把 16 帧序列装进 A100 的 80 GB 显存。
Losses and optimization.
We supervise the model’s predictions using a linear combination of focal and dice losses for the mask prediction, mean-absolute-error (MAE) loss for the IoU prediction, and cross-entropy loss for object prediction with a ratio of 20:1:1:1 respectively. As during pre-training, for multi-mask predictions, we only supervise the mask with the lowest segmentation loss. If the ground-truth does not contain a mask for a frame, we do not supervise any of the mask outputs (but always supervise the occlusion prediction head that predicts whether there should exist a mask in the frame).
损失与优化。
用 focal 与 dice 损失的线性组合监督掩码预测,用平均绝对误差(MAE)监督 IoU 预测,用交叉熵监督对象预测,比例为 20:1:1:1。与预训练一样,多掩码预测时只监督分割损失最低的掩码。若某帧真值无掩码,则不监督任何掩码输出(但始终监督遮挡预测头,即是否应存在掩码)。
D.3 Speed benchmarking
D.3 速度基准
We conduct all benchmarking experiments on a single A100 GPU using PyTorch 2.3.1 and CUDA 12.1, under automatic mixed precision with bfloat16. We compile the image encoder with torch.compile for all SAM 2 models and do the same for SAM and HQ-SAM for direct comparison on the SA task (Tables 5 and 15). The FPS measurements for the SA task were conducted using a batch size of 10 images, which was found to yield the highest FPS across all three model types. For video tasks, we use a batch size of 1 following the common protocol in video segmentation.
全部基准实验在单卡 A100 上,用 PyTorch 2.3.1 与 CUDA 12.1,在 bfloat16 自动混合精度下进行。对所有 SAM 2 模型用 torch.compile 编译图像编码器;在 SA 任务上对 SAM 与 HQ-SAM 同样处理以便直接比较(表 5 与 15)。SA 任务 FPS 用批大小 10(三类模型上该设定 FPS 最高);视频任务按视频分割通行协议用批大小 1。
Appendix E Data details
附录 E 数据细节
E.1 SA-V dataset details
E.1 SA-V 数据集细节
| (a) ML only | (b) With Auto |
Figure 9: Annotations overlaid on the first frame: (a) manual labels (ML) only, (b) with automatic labels (Auto). Automatic labels increase diversity and coverage.
| (a) 仅人工标注 (ML) | (b) 含自动标注 (Auto) |
图 9:叠加在首帧上的标注:(a) 仅人工标注(ML),(b) 含自动标注(Auto)。自动标注提升多样性与覆盖。
Videos. Resolutions range from 240p to 4K with 1,401 1,037 on average. Duration ranges from 4 seconds to 2.3 minutes, with an average of 13.8 seconds, totaling 4.2M frames and 196 hours.
视频。 分辨率从 240p 到 4K,平均 1,401 1,037。时长从 4 秒到 2.3 分钟,平均 13.8 秒;合计 420 万帧、196 小时。
Dataset diversity. As shown in Fig. 10, SA-V videos were recorded across 47 countries (Fig. 10(b)), by diverse participants (self-reported demographics in Fig. 10(c)). Fig. 10(a) shows a comparison of mask size distribution (normalized by video resolution) with DAVIS, MOSE, and YouTubeVOS. More than of SA-V masks have a normalized mask area less than 0.1.
数据集多样性。 如图 10,SA-V 视频录自 47 个国家(图 10(b)),参与者背景多样(自报人口统计见图 10(c))。图 10(a) 给出按视频分辨率归一化的掩码尺寸分布,并与 DAVIS、MOSE、YouTubeVOS 对比。超过 的 SA-V 掩码归一化面积小于 0.1。
Automatic masklets. Similar to the approach described by Kirillov et al. 2023, automatic masklets are generated by prompting the model with regular grids. We prompt the model with a grid on the first frame, and additionally we use a grid on 4 zoomed image crops of the first frame (derived from a overlapped window) and a grid on 16 zoomed image crops of the first frame (derived from a overlapped window). We apply two post-processing steps across all frames. First, we remove tiny disconnected components with areas smaller than 200 pixels. Second, we fill in holes in segmentation masks if the area of the hole is less than 200 pixels. By combining these automatically generated masklets with manually created ones, we enhance the coverage of annotations in the SA-V dataset, as illustrated in Fig. 9.
自动 masklet。 类似 Kirillov et al. 2023,用规则网格提示模型生成自动 masklet。在首帧用 网格提示,另在首帧 4 个放大裁剪(来自 重叠窗)上用 网格,在 16 个放大裁剪(来自 重叠窗)上用 网格。对所有帧做两步后处理:先去除面积小于 200 像素的细小连通分量;再填充面积小于 200 像素的掩码孔洞。把这些自动 masklet 与人工标注合并,可增强 SA-V 标注覆盖,见图 9。
(a) Size
(a) 尺寸
E.1.1 Fairness evaluation
| 1-click | 3-click | mask | |
|---|---|---|---|
| gender | |||
| male | 81.9 | 95.1 | 95.9 |
| female | 75.1 | 94.1 | 95.2 |
| age | |||
| 18-26 | 77.2 | 95.0 | 95.7 |
| 26-50 | 76.7 | 94.7 | 95.8 |
| 50+ | 81.4 | 95.1 | 96.2 |
Table 13: Fairness evaluation of SAM 2 (under metric) on protected demographic groups.
E.1.1 公平性评估
| 1-click | 3-click | mask | |
|---|---|---|---|
| gender | |||
| male | 81.9 | 95.1 | 95.9 |
| female | 75.1 | 94.1 | 95.2 |
| age | |||
| 18-26 | 77.2 | 95.0 | 95.7 |
| 26-50 | 76.7 | 94.7 | 95.8 |
| 50+ | 81.4 | 95.1 | 96.2 |
表 13:在受保护人口统计群体上,对 SAM 2 的公平性评估( 指标)。
We evaluate SAM 2 for fairness across demographic groups. We collect annotations for the people category in the Ego-Exo4D (Grauman et al. 2023) dataset, which contains self-reported demographic information supplied by the subject of the video. We employ the same annotation setup as for SA-V val and test sets and apply this to 20-second clips from the third-person (exo) videos. We evaluate SAM 2 on this data using 1-, 3-clicks, and ground-truth mask on the first frame.
我们按人口统计群体评估 SAM 2 公平性。在 Ego-Exo4D(Grauman et al. 2023)的人物类别上收集标注,该数据含视频主体自报的人口统计信息。采用与 SA-V val/test 相同的标注设定,作用于第三人称(exo)视频的 20 秒片段。用首帧 1 次、3 次点击以及真值掩码评估 SAM 2。
Table 13 shows the comparison in accuracy of SAM 2 for segmenting people across gender and age. At 3 clicks and with ground-truth mask prompts there is minimal discrepancy. We manually inspect 1 click predictions, and find the model frequently predicts the mask for a part instead of the person. When limiting the comparison to clips where the person is correctly segmented, the gap in 1 click shrinks substantially ( male 94.3, female 92.7), suggesting the discrepancy can be partially attributed to ambiguity in the prompt.
表 13 比较了跨性别与年龄分割人物时的 。在 3 次点击与真值掩码提示下差异很小。人工检查 1 次点击预测发现,模型常预测部件掩码而非整人。若只比较人物被正确分割的片段,1 次点击差距大幅缩小( 男性 94.3、女性 92.7),说明差异部分可归因于提示歧义。
In Appendix H, we provide model, data and annotation cards for SA-V.
附录 H 给出 SA-V 的模型、数据与标注卡片。
E.2 Data engine details
E.2 数据引擎细节
E.2.1 Annotation protocol
Figure 11: Annotation guideline overview. There are 3 main annotation tasks: masklet selection, masklet tracking, and masklet verification. Each task has a different set of annotators working on it.
E.2.1 标注协议
图 11:标注指南概览。主要标注任务有三类:masklet 选择、masklet 跟踪与 masklet 核验。每类由不同标注员完成。
A diagram of the annotation protocol used in our data engine is shown in Fig. 11. The annotation task was separated into steps each carried out by a different annotator: Steps 1 and 2 focus on object selection, Steps 3 and 4 on masklet tracking, and Step 5 on quality verification. SAM 2 was deployed on GPU as an API and built into the annotation tool to enable interactive use.
数据引擎所用标注协议示意见图 11。任务拆成多步并由不同标注员执行:第 1、2 步侧重对象选择,第 3、4 步侧重masklet 跟踪,第 5 步侧重质量核验。SAM 2 以 GPU API 部署并嵌入标注工具,支持交互使用。
Compared to image segmentation annotation, large-scale video segmentation annotation presents unique challenges which require innovations in the annotation task design and protocol. To improve our model’s ability to “segment anything”, it was important to focus annotation on challenging objects where SAM 2 struggled. We leveraged our online model in the loop setup to enable this, requesting annotators to use SAM 2 interactively to identify failure modes and then correct them.
相较图像分割标注,大规模视频分割标注有独特挑战,需要在任务设计与协议上创新。为提升模型「分割任意对象」能力,标注应聚焦 SAM 2 仍困难的对象。我们借助在线人机回环:要求标注员交互使用 SAM 2 找出失败模式并纠正。
We found the number of edited frames to be a proxy to the “challengingness” of an object as shown in Table 8. Therefore, we asked annotators to annotate objects that required at least 2 edited frames with SAM 2 in the loop. To focus annotation on less prominent and more challenging cases, annotators were presented with videos pre-filled with verified satisfactory automatic masklets and asked to find un-annotated challenging objects. We further decouple the object selection task from the annotation task: in the selection task annotators focus on choosing the challenging objects in one frame, while in the annotation task annotators are presented with a challenging target object and requested to annotate the masklet consistently throughout the video.
我们发现编辑帧数可作为对象「难度」代理,见表 8。因此要求标注员标注在回环中至少需要 2 帧编辑的对象。为聚焦不显眼、更困难的情形,视频会预填已核验合格的自动 masklet,并请标注员寻找尚未标注的困难对象。我们还把对象选择与标注解耦:选择任务中标注员在一帧上挑困难对象;标注任务中则给出困难目标,要求在整段视频中一致标注 masklet。
E.2.2 Data engine phase comparison
The comparison of data engine phases shown in Table 1 was conducted as a controlled experiment using 169 videos and 452 masklets. We ask three subsets of annotators to annotate the same set of objects with the annotation protocol from each phase. We categorize masklets into three buckets based on the mask area in the first frame (small: 1 to , medium: to , and large: equal or greater than ). Phase 1 data is used as the quality reference, due to the high quality masks from frame-by-frame manual annotation with SAM.
E.2.2 数据引擎阶段对比
表 1 中的阶段对比是在 169 段视频、452 个 masklet 上的受控实验。三组标注员分别按各阶段协议标注同一组对象。按首帧掩码面积把 masklet 分为三档(小:1 到 ,中: 到 ,大:不小于 )。阶段 1 数据因逐帧人工用 SAM 标注、质量高,用作质量参考。
Appendix F Details on zero-shot transfer experiments
附录 F 零样本迁移实验细节
In this section, we describe further details of our zero-shot experiments (§6). Unless otherwise noted, the results reported in this section follow our default setup using Hiera-B+ image encoder with a resolution of 1024 and trained on the full combination of datasets, i.e., SAM 2 (Hiera-B+) in Table 6.
本节补充零样本实验(§6)细节。除非另说明,本节结果均按默认设定:Hiera-B+ 图像编码器、分辨率 1024,并在完整数据组合上训练,即表 6 中的 SAM 2(Hiera-B+)。
F.1 Zero-shot video tasks
F.1 零样本视频任务
F.1.1 Video dataset details
We evaluate SAM 2 on a diverse benchmark of 17 zero-shot datasets: EndoVis 2018 (Allan et al. 2020) contains medical surgery videos with robotic instruments. ESD (Huang et al. 2023) contains videos from a robot manipulator camera often with motion blur. LVOSv2 (Hong et al. 2024) is a benchmark for long-term video object segmentation. LV-VIS (Wang et al. 2023) contains videos from a diverse set of open-vocabulary object categories. UVO (Wang et al. 2021b) contains videos for open-world object segmentation, and VOST (Tokmakov et al. 2022) contains videos with objects undergoing large transformations such as egg broken or paper torn. PUMaVOS (Bekuzarov et al. 2023) contains videos with segments around object parts such as a person’s cheek. Virtual KITTI 2 (Cabon et al. 2020) is a synthetic video dataset with driving scenes. VIPSeg (Miao et al. 2022) provides object segmentation in panoptic videos. Wildfires (Toulouse et al. 2017) contains wildfire videos under different conditions from the Corsican Fire Database. VISOR (Darkhalil et al. 2022) contains egocentric videos in kitchen scenes with segments around hands and active objects. FBMS (Brox et al. 2010) provides motion segmentation over moving objects in videos. Ego-Exo4D (Grauman et al. 2023) is a large dataset with egocentric videos around various human activities. Cityscapes (Cordts et al. 2016) contains videos for urban driving scenes. Lindenthal Camera (Haucke & Steinhage 2021) contains videos in a wildlife park with segments around observed animals such as birds and mammals. HT1080WT Cells (Gómez-de Mariscal et al. 2021) contains microscopy videos with cell segments. Drosophila Heart (Fishman et al. 2023) contains microscopy videos for the heart of fruit flies.
F.1.1 视频数据集细节
我们在 17 个零样本数据集组成的多样基准上评估 SAM 2:EndoVis 2018(Allan et al. 2020)含带机器人器械的医学手术视频;ESD(Huang et al. 2023)来自机械臂相机、常有运动模糊;LVOSv2(Hong et al. 2024)面向长时视频目标分割;LV-VIS(Wang et al. 2023)覆盖多样开放词汇类别;UVO(Wang et al. 2021b)面向开放世界目标分割;VOST(Tokmakov et al. 2022)含鸡蛋破碎、纸张撕裂等大幅形变;PUMaVOS(Bekuzarov et al. 2023)围绕脸颊等部件;Virtual KITTI 2(Cabon et al. 2020)为合成驾驶场景;VIPSeg(Miao et al. 2022)提供全景视频目标分割;Wildfires(Toulouse et al. 2017)来自科西嘉火灾库的不同条件下野火视频;VISOR(Darkhalil et al. 2022)为厨房自我中心视频,标注手与活跃物体;FBMS(Brox et al. 2010)做运动物体分割;Ego-Exo4D(Grauman et al. 2023)覆盖多种人类活动的自我中心视频;Cityscapes(Cordts et al. 2016)为城市场景驾驶视频;Lindenthal Camera(Haucke & Steinhage 2021)为野生动物园区鸟类与哺乳动物等;HT1080WT Cells(Gómez-de Mariscal et al. 2021)为显微细胞视频;Drosophila Heart(Fishman et al. 2023)为果蝇心脏显微视频。
Among these 17 zero-shot video datasets above, 9 of them (EndoVis, ESD, LVOSv2, LV-VIS, UVO, VOST, PUMaVOS, Virtual KITTI 2, and VIPSeg) have dense object segments annotated for every video frame. In the remaining 8 datasets (Wildfires, VISOR, FBMS, Ego-Exo4D, Cityscapes, Lindenthal Camera, HT1080WT Cells, and Drosophila Heart), the object segments are sparsely annotated over only a subset of video frames, and we compute the metrics on those frames where the ground-truth segmentation masks are available. In most evaluations of the paper, we only evaluate zero-shot performance on the 9 densely annotated datasets, while in our semi-supervised VOS evaluation (§6.2), we evaluate on all these 17 datasets listed above.
上述 17 个零样本视频数据集中,9 个(EndoVis、ESD、LVOSv2、LV-VIS、UVO、VOST、PUMaVOS、Virtual KITTI 2、VIPSeg)对每一帧都有稠密目标标注。其余 8 个(Wildfires、VISOR、FBMS、Ego-Exo4D、Cityscapes、Lindenthal Camera、HT1080WT Cells、Drosophila Heart)仅在部分帧稀疏标注,我们只在有真值掩码的帧上计算指标。论文多数评测只在 9 个稠密标注集上报告零样本表现;半监督 VOS 评测(§6.2)则覆盖全部 17 个。
F.1.2 Interactive offline and online evaluation details
Offline evaluation involves multiple passes over the entire video. We start with click prompts on the first frame, segment the object throughout the entire video, and then in the next pass, we select the frame with the lowest segmentation w.r.t. the ground-truth as the new frame for prompting. The model then segments the object again throughout the video based on all prompts received previously, until reaching a maximum of passes (with one new prompted frame in each pass).
F.1.2 交互式离线与在线评测细节
离线评测对整段视频做多轮遍历。先在首帧给点击提示并整段分割,再在下一轮选相对真值分割 最低的帧作为新提示帧;模型基于此前全部提示再次整段分割,直至达到最多 轮(每轮新增一帧提示)。
Online evaluation involves only one pass over the entire video. We start with click prompts on the first frame and propagate the prompts across the video, pausing propagation when encountering a frame with a low-quality prediction ( with ground-truth). We then add additional click prompts on the paused frame to correct the segment on this frame and resume the propagation forward until reaching another low quality frame with . This is repeated while the number of prompted frames is less than the maximum . Unlike the previous offline evaluation, in this setting, the new prompts only affect the frames after the current paused frame but not the frames before it.
在线评测对整段视频只做一轮。先在首帧给点击并沿视频传播;遇到低质量预测(与真值 )时暂停,在暂停帧追加点击纠正后继续向前传播,直至再遇 的帧。在提示帧数少于上限 时重复。与离线不同,新提示只影响当前暂停帧之后的帧,不影响之前的帧。
In both settings, we evaluate on 9 densely annotated datasets in §F.1.1 (EndoVis, ESD, LVOSv2, LV-VIS, UVO, VOST, PUMaVOS, Virtual KITTI 2, and VIPSeg). If a video contains multiple objects to segment in its ground-truth annotations, we perform inference on each object independently. We simulate interactive video segmentation with clicks per frame, assuming that the user would visually locate the object to label it (with initial clicks) or to refine the current segmentation prediction of it (with correction clicks). Specifically, when starting the first pass (where there are not any existing predictions yet), we place an initial click on the first frame at the center[^2] of the object’s ground-truth mask and then interactively add two more clicks based on the center of the error region (between the ground-truth mask and the predicted segments on the first frame). Then in subsequent passes (where there are already predicted segments), we interactively add three clicks based on the center of the error region (between the ground-truth mask and the predicted segments on the frame being prompted).
两种设定均在 §F.1.1 的 9 个稠密标注集上评估。若视频真值含多个待分割对象,则对每个对象独立推理。我们用每帧 次点击仿真交互视频分割,假定标注者会先视觉定位对象(初始点击)或 refinement 当前预测(纠正点击)。具体地,第一轮尚无预测时,在首帧真值掩码中心[^2]放初始点击,再按误差区域中心交互追加两次点击;后续轮次(已有预测)则按误差区域中心交互追加三次点击。
We report the average metric over interacted frames and the metrics under different annotation time on a video based on the following assumptions:
我们报告 交互帧上的平均 ,以及按以下假设换算的不同标注耗时下的 :
- • On each frame, it takes sec for the annotator to visually locate an object in the frame, and sec to add each click, following Delatolas et al. 2024.
- • 每帧上,标注者视觉定位对象耗时 秒,每次点击 秒,遵循 Delatolas et al. 2024。
- • In offline mode, it takes sec on a 300-frame video to examine the results throughout the video in each round, including finding the frame with the worst segmentation quality to add corrections (and for longer or shorter videos, this time is proportional to the video length , assuming the annotator could examine the results at 10 FPS).
- • 离线模式下,对 300 帧视频每轮检查结果(含找出分割最差帧以追加纠正)耗时 秒;更长或更短视频按长度 成比例(假定可按 10 FPS 检查)。
- • In online mode, it takes sec on a 300-frame video to follow the results throughout the video in total, including pausing at a frame with low quality for further corrections (and this time is proportional to the video length similar to the offline mode).
- • 在线模式下,全程跟随结果(含在低质量帧暂停以进一步纠正)对 300 帧视频合计 秒;同样与视频长度 成比例。
- • The annotation time for an object is in offline mode and in online mode, where is the total frame number in the video, is the number of frames annotated (i.e., the number of interactive rounds), and is the number of clicks per frame.[^3]
- • 单个对象的标注时间为:离线模式下 ,在线模式下 ,其中 为总帧数, 为标注帧数(交互轮数), 为每帧点击数。[^3]
We show per-dataset results of SAM 2 and the two baselines (SAM+XMem++ and SAM+Cutie, see their details below) for interactive offline and online evaluation in Fig. 12 and Fig. 13. SAM 2 outperforms both baselines with a notable margin on all datasets and settings.
图 12 与图 13 给出 SAM 2 与两个基线(SAM+XMem++、SAM+Cutie,细节见下)在交互离线与在线评测上的分数据集结果。SAM 2 在全部数据集与设定上均以明显优势胜出。
F.1.3 Semi-supervised VOS evaluation details
| EndoVis | Virtual | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| Method | 2018 | ESD | LVOSv2 | LV-VIS | PUMaVOS | UVO | VIPSeg | KITTI 2 | VOST | (average) |
| SAM + XMem++ | 68.9 | 88.2 | 72.1 | 86.4 | 60.2 | 74.5 | 84.2 | 63.8 | 46.6 | 71.7 |
| SAM + Cutie | 71.8 | 87.6 | 82.1 | 87.1 | 59.4 | 75.2 | 84.4 | 70.3 | 54.3 | 74.7 |
| SAM 2 | 77.0 | 90.2 | 87.9 | 90.3 | 68.5 | 79.2 | 88.3 | 74.1 | 67.5 | 80.3 |
Figure 12: Zero-shot performance of SAM 2 vs baselines (SAM+XMem++ and SAM+Cutie) under interactive offline evaluation with different numbers of interacted frames, using 3 clicks per interacted frame. See §F.1.2 for details.
F.1.3 半监督 VOS 评测细节
| EndoVis | Virtual | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| Method | 2018 | ESD | LVOSv2 | LV-VIS | PUMaVOS | UVO | VIPSeg | KITTI 2 | VOST | (average) |
| SAM + XMem++ | 68.9 | 88.2 | 72.1 | 86.4 | 60.2 | 74.5 | 84.2 | 63.8 | 46.6 | 71.7 |
| SAM + Cutie | 71.8 | 87.6 | 82.1 | 87.1 | 59.4 | 75.2 | 84.4 | 70.3 | 54.3 | 74.7 |
| SAM 2 | 77.0 | 90.2 | 87.9 | 90.3 | 68.5 | 79.2 | 88.3 | 74.1 | 67.5 | 80.3 |
图 12:在交互离线评测下,不同交互帧数、每交互帧 3 次点击时,SAM 2 相对基线(SAM+XMem++ 与 SAM+Cutie)的零样本表现。细节见 §F.1.2。
| EndoVis | Virtual | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| Method | 2018 | ESD | LVOSv2 | LV-VIS | PUMaVOS | UVO | VIPSeg | KITTI 2 | VOST | (average) |
| SAM + XMem++ | 71.4 | 87.8 | 72.9 | 85.2 | 63.7 | 74.7 | 82.5 | 63.9 | 52.7 | 72.8 |
| SAM + Cutie | 70.5 | 87.3 | 80.6 | 86.0 | 58.9 | 75.2 | 82.1 | 70.4 | 54.6 | 74.0 |
| SAM 2 | 77.5 | 88.9 | 87.8 | 88.7 | 72.7 | 78.6 | 85.5 | 74.0 | 65.0 | 79.8 |
Figure 13: Zero-shot performance of SAM 2 vs baselines (SAM+XMem++ and SAM+Cutie) under interactive online evaluation with different numbers of interacted frames, using 3 clicks per interacted frame. See §F.1.2 for details.
| EndoVis | Virtual | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| Method | 2018 | ESD | LVOSv2 | LV-VIS | PUMaVOS | UVO | VIPSeg | KITTI 2 | VOST | (average) |
| SAM + XMem++ | 71.4 | 87.8 | 72.9 | 85.2 | 63.7 | 74.7 | 82.5 | 63.9 | 52.7 | 72.8 |
| SAM + Cutie | 70.5 | 87.3 | 80.6 | 86.0 | 58.9 | 75.2 | 82.1 | 70.4 | 54.6 | 74.0 |
| SAM 2 | 77.5 | 88.9 | 87.8 | 88.7 | 72.7 | 78.6 | 85.5 | 74.0 | 65.0 | 79.8 |
图 13:在交互在线评测下,不同交互帧数、每交互帧 3 次点击时,SAM 2 相对基线(SAM+XMem++ 与 SAM+Cutie)的零样本表现。细节见 §F.1.2。
In §6.2, we also compare with previous video tracking methods under the semi-supervised VOS setting (Pont-Tuset et al. 2017), where prompts (which can be foreground/background clicks, bounding boxes, or ground-truth object masks) are provided only on the first frame of the video. When using click prompts, we interactively sample either 1, 3 or 5 clicks on the first video frame, and then track the object based on these clicks. Following the click-based evaluation in prior work (Kirillov et al. 2023; Sofiiuk et al. 2022), the initial click is placed on the object center and subsequent clicks are obtained from the center of the error region.
在 §6.2 中,我们还在半监督 VOS 设定(Pont-Tuset et al. 2017)下与既有视频跟踪方法比较:提示(可为前景/背景点击、边界框或真值对象掩码)只在视频首帧给出。用点击提示时,在首帧交互采样 1、3 或 5 次点击,再据此跟踪对象。遵循先前工作(Kirillov et al. 2023;Sofiiuk et al. 2022)的点击评测:初始点击放在对象中心,后续点击取自误差区域中心。
Similar to the interactive setting, here we also use SAM+XMem++ and SAM+Cutie as two baselines. For click or box prompts, SAM is first used to handle click or bounding box inputs, and its output mask is then used as input to XMem++ or Cutie. For mask prompts, the ground-truth object masks on the first frame are directly used as input to XMem++ and Cutie – this is the standard semi-supervised VOS setting and evaluates XMem++ and Cutie without using SAM.
与交互设定类似,这里仍用 SAM+XMem++ 与 SAM+Cutie 作基线。对点击或框提示,先用 SAM 处理,再把其输出掩码喂给 XMem++ 或 Cutie。对掩码提示,首帧真值对象掩码直接作为 XMem++/Cutie 输入——这是标准半监督 VOS 设定,评估的是不使用 SAM 时的 XMem++ 与 Cutie。
In this setting, we evaluate on all 17 zero-shot video datasets in §F.1.1. If a dataset does not follow the standard VOS format, we preprocess it into a format similar to MOSE (Ding et al. 2023). During processing, we ensure that all objects in each video have a valid non-empty segmentation mask on the first frame to be compatible with semi-supervised VOS evaluation. In case an object doesn’t appear in the first frame, we create a separate video for it starting from the first frame where the object appears.
该设定在 §F.1.1 全部 17 个零样本视频集上评估。若某数据集不符合标准 VOS 格式,则预处理成类似 MOSE(Ding et al. 2023)的格式。处理时保证每段视频中所有对象在首帧都有非空有效分割掩码,以兼容半监督 VOS。若对象未出现在首帧,则从其首次出现的帧起单独切出一段视频。
We report the standard metric (Pont-Tuset et al. 2017) for this evaluation. If a dataset provides an official evaluation toolkit, we use it for evaluation (on the VOST dataset, we report the metric instead, following its official protocol (Tokmakov et al. 2022)). The results are shown in Table 4, where SAM 2 performs better than both baselines on the majority of the 17 datasets across different types of prompts.
该评测报告标准 (Pont-Tuset et al. 2017)。若数据集提供官方评测工具则用之(在 VOST 上按官方协议报告 (Tokmakov et al. 2022))。结果见表 4:在多数数据集与各类提示上,SAM 2 均优于两个基线。
We show per-dataset results of SAM 2 and the two baselines (SAM+XMem++ and SAM+Cutie, see their details below) for semi-supervised VOS evaluation in Fig. 14. SAM 2 outperforms both baselines on the majority of these datasets across different types of prompts.
图 14 给出半监督 VOS 评测下 SAM 2 与两个基线的分数据集结果。在多数数据集与各类提示上,SAM 2 均优于两者。
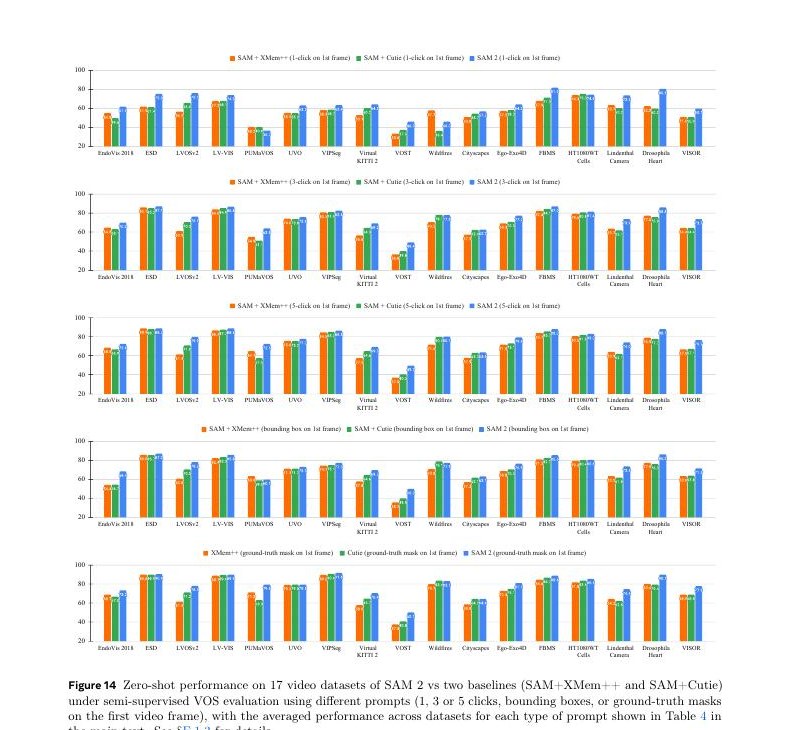
Figure 14: Zero-shot performance on 17 video datasets of SAM 2 vs two baselines (SAM+XMem++ and SAM+Cutie) under semi-supervised VOS evaluation using different prompts (1, 3 or 5 clicks, bounding boxes, or ground-truth masks on the first video frame), with the averaged performance across datasets for each type of prompt shown in Table 4 in the main text. See §F.1.3 for details.
图 14:在 17 个视频数据集上,半监督 VOS 评测下 SAM 2 相对两个基线(SAM+XMem++ 与 SAM+Cutie)的零样本表现;提示类型为视频首帧的 1、3 或 5 次点击、边界框或真值掩码。各类提示的跨数据集平均见表 4 正文。细节见 §F.1.3。
F.1.4 SAM+XMem++ and SAM+Cutie baseline details
We adopt SAM+XMem++ and SAM+Cutie as two baselines for promptable video segmentation, where the click (or box) prompts are first processed by SAM to obtain an object mask, and then XMem++ / Cutie models track this SAM mask across the video to obtain the final masklet. In these two baselines, SAM can be used to provide both an initial object mask on the first frame, or to correct an existing object mask output by XMem++ or Cutie. This is used for subsequent interacted frames during interactive offline and online evaluation, where new positive and negative clicks are provided as corrections over an existing mask.
F.1.4 SAM+XMem++ 与 SAM+Cutie 基线细节
我们采用 SAM+XMem++ 与 SAM+Cutie 作为可提示视频分割基线:点击(或框)提示先由 SAM 得到对象掩码,再由 XMem++ / Cutie 在视频中跟踪该 SAM 掩码得到最终 masklet。这两个基线中,SAM 既可在首帧提供初始对象掩码,也可纠正 XMem++ 或 Cutie 已有的对象掩码输出——用于交互离线/在线评测中后续交互帧,此时用新的正负点击纠正现有掩码。
When using SAM to apply a correction over an existing mask prediction in a given frame, we follow the strategy in EVA-VOS (Delatolas et al. 2024) to first initialize SAM with the XMem++ or Cutie output mask before incorporating the new correction clicks. Specifically, we first reconstruct the XMem++ or Cutie output mask in SAM by sampling clicks from them and feeding them as inputs to SAM until the reconstructed mask in SAM reaches with the XMem++ or Cutie output mask. Then, to incorporate new positive and negative clicks for correction, we concatenate these additional correction clicks with the initial clicks sampled during mask construction, and feed the joint concatenated list as input into SAM to obtain the final corrected masks. We find that this strategy works better than several alternatives (such as feeding the XMem++ or Cutie output mask as a mask prompt together with new correction clicks into SAM, or taking only the correction clicks as inputs to SAM while ignoring the XMem++ or Cutie output mask).
当用 SAM 在给定帧纠正已有掩码预测时,我们遵循 EVA-VOS(Delatolas et al. 2024):先用 XMem++ 或 Cutie 输出掩码初始化 SAM,再纳入新的纠正点击。具体地,先从 XMem++/Cutie 输出采样点击并喂给 SAM,直到 SAM 重建掩码与该输出达到 ;再把新的正负纠正点击与掩码构建时的初始点击拼接,一并输入 SAM 得到最终纠正掩码。我们发现该策略优于若干替代方案(例如把 XMem++/Cutie 输出作为掩码提示与新纠正点击一并喂给 SAM,或只把纠正点击喂给 SAM 而忽略其输出掩码)。
F.2 DAVIS interactive benchmark
F.2 DAVIS 交互基准
We also evaluate on the DAVIS interactive benchmark (Caelles et al. 2018), which resembles our interactive offline evaluation in §6.1, where in each round of interaction, the evaluation server would provide new annotations on frames with the worst segmentation performance. The official DAVIS eval toolkit provides scribble prompts during interactions, while other work such as CiVOS (Vujasinović et al. 2022) has also extended this to cover click prompts.
我们还在 DAVIS 交互基准(Caelles et al. 2018)上评估,其形式类似 §6.1 的交互离线评测:每轮交互由评测服务器在分割最差的帧上提供新标注。官方 DAVIS 评测工具在交互中提供涂鸦提示;CiVOS(Vujasinović et al. 2022)等工作也扩展到点击提示。
Here we follow CiVOS to use positive and negative clicks as input prompts and adopt the same strategy for click sampling. We report the @60s and AUC- metrics on this benchmark as provided by its evaluator, and compare to two baselines: MiVOS (Cheng et al. 2021b), which directly uses the provided scribbles via a scribble-to-mask module (and is also extended to click prompts in Vujasinović et al. 2022), and CiVOS, which samples click from the provided scribbles. The results are shown in Table 14, where SAM 2 (based on click inputs) outperforms both baselines under click inputs. We note that SAM 2 often tends to segment object parts (e.g. a person’s arm) on the first click while the DAVIS dataset mainly contains whole objects (e.g. an entire person), which could penalize SAM 2’s & performance on this benchmark.
这里按 CiVOS 用正负点击作输入,并采用相同的点击采样策略。报告评测器提供的 @60s 与 AUC-,并与两个基线比较:MiVOS(Cheng et al. 2021b)经 scribble-to-mask 模块直接使用涂鸦(Vujasinović et al. 2022 也扩展到点击),以及从涂鸦采样点击的 CiVOS。结果见表 14:在点击输入下 SAM 2 优于两基线。需注意 SAM 2 常在首次点击时倾向分割部件(如手臂),而 DAVIS 主要含完整对象(如整人),这可能拉低其在该基准上的 &。
| Method | input type | AUC-& | &@60s |
|---|---|---|---|
| MiVOS (Cheng et al. 2021b) | scribbles | 0.87 | 0.88 |
| MiVOS (Cheng et al. 2021b)‡ | clicks | 0.75 | 0.75 |
| CiVOS (Vujasinović et al. 2022) | clicks | 0.83 | 0.84 |
| SAM 2 | clicks | 0.86 | 0.90 |
Table 14: Performance of SAM 2 and other models on the DAVIS interactive benchmark. For SAM 2, we use clicks as inputs following the click sampling strategy from CiVOS (Vujasinović et al. 2022). See §F.2 for details (‡: performance reported in Vujasinović et al. 2022).
| Method | 输入类型 | AUC-& | &@60s |
|---|---|---|---|
| MiVOS (Cheng et al. 2021b) | scribbles | 0.87 | 0.88 |
| MiVOS (Cheng et al. 2021b)‡ | clicks | 0.75 | 0.75 |
| CiVOS (Vujasinović et al. 2022) | clicks | 0.83 | 0.84 |
| SAM 2 | clicks | 0.86 | 0.90 |
表 14:SAM 2 与其他模型在 DAVIS 交互基准上的表现。SAM 2 按 CiVOS(Vujasinović et al. 2022)的点击采样策略使用点击输入。细节见 §F.2(‡:表现引自 Vujasinović et al. 2022)。
F.3 Zero-shot image tasks
F.3 零样本图像任务
F.3.1 Dataset details
For the interactive segmentation task, we evaluated SAM 2 on a comprehensive suite of 37 datasets. This suite includes the 23 datasets previously used by SAM for zero-shot evaluation. For completeness, we list the 23 datasets: LVIS (Gupta et al. 2019), ADE20K (Zhou et al. 2019), Hypersim (Roberts et al. 2021), Cityscapes (Cordts et al. 2016), BBBC038v1 (Caicedo et al. 2019), DOORS (Pugliatti & Topputo 2022), DRAM (Cohen et al. 2022), EgoHOS (Zhang et al. 2022), GTEA (Fathi et al. 2011; Li et al. 2015), iShape (Yang et al. 2021a), NDD20 (Trotter et al. 2020), NDISPark (Ciampi et al. 2021; Ciampi et al. 2022), OVIS (Qi et al. 2022), PPDLS (Minervini et al. 2016), Plittersdorf (Haucke et al. 2022), STREETS (Snyder & Do 2019), TimberSeg (Fortin et al. 2022), TrashCan (Hong et al. 2020), VISOR (Darkhalil et al. 2022; Damen et al. 2022), WoodScape (Yogamani et al. 2019), PIDRay (Wang et al. 2021a), ZeroWaste-f (Bashkirova et al. 2022), and IBD (Chen et al. 2022). For more detailed information about these datasets, we refer the reader to Kirillov et al. 2023. In addition to these 23 datasets, we evaluated on frames sampled from 14 video datasets to assess SAM 2’s performance on images from the video domain. The video datasets used are listed as follows: Lindenthal Camera Traps (LCT) (Haucke & Steinhage 2021), VOST (Tokmakov et al. 2022), LV-VIS (Wang et al. 2023), FBMS (Brox et al. 2010), Virtual KITTI 2 (Cabon et al. 2020), Corsican Fire Database (CFD) (Toulouse et al. 2017), VIPSeg (Miao et al. 2022), Drosophila Heart OCM (DH OCM) (Fishman et al. 2023), EndoVis 2018 (Allan et al. 2020), ESD (Huang et al. 2023), UVO (Wang et al. 2021b), Ego-Exo4d (Grauman et al. 2023), LVOSv2 (Hong et al. 2024), and HT1080WT (Gómez-de Mariscal et al. 2021). Table 16 has a more detailed description of these datasets. (Some of these datasets are obtained from the same data source as the zero-shot video datasets in §F.1.1.)
F.3.1 数据集细节
对交互分割任务,我们在 37 个数据集组成的全面套件上评估 SAM 2,其中包含 SAM 此前用于零样本评测的 23 个数据集。为完整起见列出这 23 个:LVIS、ADE20K、Hypersim、Cityscapes、BBBC038v1、DOORS、DRAM、EgoHOS、GTEA、iShape、NDD20、NDISPark、OVIS、PPDLS、Plittersdorf、STREETS、TimberSeg、TrashCan、VISOR、WoodScape、PIDRay、ZeroWaste-f 与 IBD。更细信息见 Kirillov et al. 2023。除此之外,我们还在从 14 个视频数据集采样的帧上评估,以检验 SAM 2 在视频域图像上的表现。这些视频数据集包括:Lindenthal Camera Traps(LCT)、VOST、LV-VIS、FBMS、Virtual KITTI 2、Corsican Fire Database(CFD)、VIPSeg、Drosophila Heart OCM(DH OCM)、EndoVis 2018、ESD、UVO、Ego-Exo4d、LVOSv2 与 HT1080WT。表 16 有更细描述。(其中部分与 §F.1.1 零样本视频集同源。)
F.3.2 Detailed zero-shot experiments
In this section, we include a more detailed version of the experiments in §6.3. We compare SAM 2 to SAM and HQ-SAM with different model sizes in Table 15. The main metrics we use for evaluation are the 1- and 5-click mIoU and we categorize the results by the dataset domain.
F.3.2 更细的零样本实验
本节给出 §6.3 实验的更细版本。表 15 比较不同规模下的 SAM 2、SAM 与 HQ-SAM。主要指标为 1 次与 5 次点击 mIoU,并按数据集域归类。
Table 15 first shows a comparison of the models trained only on images (for the SA task) with different image encoder sizes on both the SA-23 benchmark as well as the 14 newly introduced video datasets. SAM 2 (Hiera-B+) trained only on SA-1B outperforms SAM (ViT-H) on 1-click accuracy, and both SAM (ViT-H) and HQ-SAM (ViT-H) on 5-click accuracy while being 6x faster. SAM 2 (Hiera-L) further improves the 1-click accuracy by 1 point on average, but trading off speed. Despite being slower than Hiera-B+, it is still 3.4x faster than SAM (ViT-H) and 1.5x faster than SAM (ViT-B).
表 15 首先比较仅在图像上(SA 任务)训练、不同图像编码器规模的模型,在 SA-23 基准以及新引入的 14 个视频数据集上的表现。仅在 SA-1B 上训练的 SAM 2(Hiera-B+)在 1 次点击准确率上超过 SAM(ViT-H),在 5 次点击上同时超过 SAM(ViT-H)与 HQ-SAM(ViT-H),且快 6 倍。SAM 2(Hiera-L)再把平均 1 次点击准确率提高 1 个点,但牺牲速度;虽慢于 Hiera-B+,仍比 SAM(ViT-H)快 3.4 倍、比 SAM(ViT-B)快 1.5 倍。
The last two rows in Table 15 illustrate the benefits of training with our mix of image and video data, which boosts the average accuracy to 61.4% across the 23 datasets with the Hirea-B+ image encoder. Additionally, we observe substantial improvements on the video benchmarks of SA-23 as well as the 14 newly introduced video datasets. We note that we do not scale beyond Hiera-L, but expect better performance for a larger model.
表 15 最后两行展示在我们的图像与视频混合数据上训练的收益:Hiera-B+ 编码器下,23 个数据集平均准确率升至 61.4%。在 SA-23 的视频子集以及新引入的 14 个视频集上也有显著提升。我们未扩到超过 Hiera-L 的规模,但预期更大模型会更好。
| 1 (5) click mIoU | ||||||
|---|---|---|---|---|---|---|
| Model | Data | SA-23 All | SA-23 Image | SA-23 Video | 14 new Video | FPS |
| SAM (ViT-B) | SA-1B | 55.9 (80.9) | 57.4 (81.3) | 54.0 (80.4) | 54.5 (82.6) | 76.7 |
| SAM (ViT-H) | SA-1B | 58.1 (81.3) | 60.8 (82.1) | 54.5 (80.3) | 59.1 (83.4) | 21.7 |
| HQ-SAM (ViT-B) | HQSEG-44k | 53.9 (72.1) | 56.3 (73.9) | 50.7 (69.9) | 54.5 (75.0) | 73.5 |
| HQ-SAM (ViT-H) | HQSEG-44k | 59.1 (79.8) | 61.8 (80.5) | 55.7 (78.9) | 58.9 (81.6) | 21.4 |
| SAM 2 (Hiera-B+) | SA-1B | 58.9 (81.7) | 60.8 (82.1) | 56.4 (81.2) | 56.6 (83.7) | 130.1 |
| SAM 2 (Hiera-L) | SA-1B | 60.0 (81.8) | 62.0 (82.2) | 57.4 (81.2) | 58.5 (83.8) | 61.4 |
| SAM 2 (Hiera-B+) | our mix | 61.9 (83.5) | 63.3 (83.8) | 60.1 (83.2) | 69.6 (85.8) | 130.1 |
| SAM 2 (Hiera-L) | our mix | 63.6 (83.5) | 64.7 (83.7) | 62.2 (83.2) | 71.1 (85.7) | 61.4 |
Table 15: Zero-shot performance on the Segment Anything (SA) task across a suite of 37 datasets. The table shows the average 1- and 5- click mIoU of SAM 2 compared to two baselines, categorized by dataset domain. We report the average metrics on the 23 datasets used by SAM for zero-shot evaluation, as well as the average across 14 newly introduced zero-shot video benchmarks.
| 1 (5) click mIoU | ||||||
|---|---|---|---|---|---|---|
| Model | Data | SA-23 All | SA-23 Image | SA-23 Video | 14 new Video | FPS |
| SAM (ViT-B) | SA-1B | 55.9 (80.9) | 57.4 (81.3) | 54.0 (80.4) | 54.5 (82.6) | 76.7 |
| SAM (ViT-H) | SA-1B | 58.1 (81.3) | 60.8 (82.1) | 54.5 (80.3) | 59.1 (83.4) | 21.7 |
| HQ-SAM (ViT-B) | HQSEG-44k | 53.9 (72.1) | 56.3 (73.9) | 50.7 (69.9) | 54.5 (75.0) | 73.5 |
| HQ-SAM (ViT-H) | HQSEG-44k | 59.1 (79.8) | 61.8 (80.5) | 55.7 (78.9) | 58.9 (81.6) | 21.4 |
| SAM 2 (Hiera-B+) | SA-1B | 58.9 (81.7) | 60.8 (82.1) | 56.4 (81.2) | 56.6 (83.7) | 130.1 |
| SAM 2 (Hiera-L) | SA-1B | 60.0 (81.8) | 62.0 (82.2) | 57.4 (81.2) | 58.5 (83.8) | 61.4 |
| SAM 2 (Hiera-B+) | our mix | 61.9 (83.5) | 63.3 (83.8) | 60.1 (83.2) | 69.6 (85.8) | 130.1 |
| SAM 2 (Hiera-L) | our mix | 63.6 (83.5) | 64.7 (83.7) | 62.2 (83.2) | 71.1 (85.7) | 61.4 |
表 15:在 37 个数据集套件上的 Segment Anything(SA)任务零样本表现。表给出相对两个基线的平均 1 次与 5 次点击 mIoU,并按数据集域归类。我们报告 SAM 用于零样本评测的 23 个数据集平均,以及新引入的 14 个零样本视频基准平均。
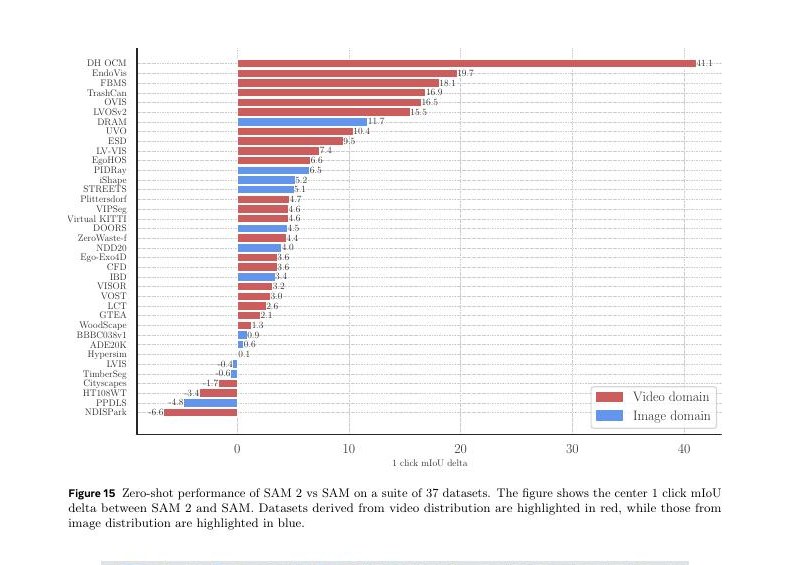
Figure 15: Zero-shot performance of SAM 2 vs SAM on a suite of 37 datasets. The figure shows the center 1 click mIoU delta between SAM 2 and SAM. Datasets derived from video distribution are highlighted in red, while those from image distribution are highlighted in blue.
图 15:在 37 个数据集套件上 SAM 2 相对 SAM 的零样本表现。图给出 SAM 2 与 SAM 的中心 1 次点击 mIoU 差值。来自视频分布的数据集标红,来自图像分布的标蓝。
A breakdown of the accuracy across datasets is presented in Fig. 16, where the per-dataset delta in 1-click mIoU relative to SAM is color-coded to indicate the data type (image or video). Notably, SAM 2 (Hiera-B+) surpasses SAM on 29 datasets[^4] by up to 53.9 mIoU, despite using a smaller Hiera-B+ image encoder.
图 16 给出分数据集精度分解,相对 SAM 的 1 次点击 mIoU 差值按数据类型(图像或视频)着色。值得注意的是,尽管使用更小的 Hiera-B+ 图像编码器,SAM 2(Hiera-B+)仍在 29 个数据集[^4]上超过 SAM,最高高出 53.9 mIoU。
| dataset | abbreviation & link | video type | description | annotation type | source split | # videos sampled | # masklets sampled | # frames sampled | # masks sampled |
|---|---|---|---|---|---|---|---|---|---|
| LV-VIS (Wang et al. 2023) | LV-VIS | Open Vocabulary | Large scale open vocabulary video instance segmentation | Dense | Validation | 690 | 2536 | 15,604 | 54,077 |
| A Drosophila heart optical coherence microscopy database for automatic video segmentation (Fishman et al. 2023) | DH OCM | Microscopy; heart | Segmentation of a fruit fly heart in optical coherence microscopy videos | Sparse | All | 213 | 213 | 608,000 | 607,158 |
| Video Object Segmentation under Transformations (Tokmakov et al. 2022) | VOST | Deformation | Video object segmentation with emphasis on shape transformations | Dense | Validation | 635 | 882 | 67,004 | 89,722 |
| Cityscapes-VPS (Cordts et al. 2016; Kim et al. 2020) | Cityscapes-VPS | Driving | Panoptic segmentation for Cityscapes driving dataset | Sparse | Validation Instance | 209 | 1372 | 4,259 | 4,579 |
| Corsican Fire Database (Toulouse et al. 2017) | CFD | Wildfire | Segmentation of wildfires | Sparse | All | 5 | 5 | 541 | 541 |
| Partial and Unusual Masks for Video Object Segmentation (Bekuzarov et al. 2023) | PUMaVOS | Parts | Video object segmentation with a focus on parts and practical use cases | Dense | All | 24 | 26 | 21,187 | 21,485 |
| EPIC-KITCHENS VISOR (Darkhalil et al. 2022) | VISOR | Egocentric | Video object segmentation benchmark containing egocentric videos of cooking with an emphasis on segmenting active objects. | Sparse | Validation | 921 | 921 | 736,030 | 4,426 |
| HT1080WT cells embedded in 3D collagen type I matrices (Gómez-de Mariscal et al. 2021) | HT1080WT | Microscopy; cells | Timelapse videos of HT1080WT cell movement | Sparse | All | 60 | 150 | 1,010 | 2,694 |
| Freiburg-Berkeley Motion Segmentation Dataset (Brox et al. 2010) | FBMS | Moving Object | Precise segmentation of moving objects | Sparse | All | 45 | 70 | 9734 | 755 |
| Virtual KITTI 2 (Cabon et al. 2020) | Virtual KITTI 2 | Synthetic; Driving | Synthetic driving videos generated by a game engine that recreate real world KITTI videos. | Dense | All from video angle Camera_0 | 996 | 1,638 | 109,368 | 162,708 |
| EndoVis 2018 (Allan et al. 2020) | EndoVis 2018 | Endoscopic video; surgery | Segmentation of medical tools in endoscopic videos | Dense | All | 15 | 29 | 2,325 | 4,314 |
| Lindenthal Camera Traps (Haucke & Steinhage 2021) | LCT | Stereo | Wildlife videos captured using stereo cameras. | Sparse | All | 12 | 12 | 4,012 | 412 |
| LVOSv2 (Hong et al. 2024) | LVOSv2 | Long videos | Long-term video object segmentation benchmark, on average 1.14 minutes | Dense | Validation | 136 | 225 | 64,523 | 91,510 |
| UVO (Wang et al. 2021b) | UVO | Open World | Open World instance segmentation of all objects in a video | Dense | Validation | 54 | 311 | 4,860 | 26,747 |
| EgoExo4d (Grauman et al. 2023) | EgoExo4d | Egocentric | Egocentric videos of participants completing skilled activities. | Sparse | Validation videos on egocentric cameras | 1185 | 1185 | 327,080 | 9,035 |
| VIPSeg (Miao et al. 2022) | VIPSeg | Panoptic | Large scale and real world scenarios for video panoptic segmentation | Dense | Validation | 152 | 1,457 | 3,416 | 30,408 |
| Event-based Segmentation Dataset (Huang et al. 2023) | ESD | Clutter | Tabletop object segmentation in an indoor cluttered environment | Dense | All | 135 | 814 | 13,325 | 78,243 |
Table 16: Video segmentation datasets used for zero-shot evaluation.
| 数据集 | 缩写与链接 | 视频类型 | 描述 | 标注类型 | 来源划分 | 采样视频数 | 采样 masklet 数 | 采样帧数 | 采样掩码数 |
|---|---|---|---|---|---|---|---|---|---|
| LV-VIS (Wang et al. 2023) | LV-VIS | Open Vocabulary | Large scale open vocabulary video instance segmentation | Dense | Validation | 690 | 2536 | 15,604 | 54,077 |
| A Drosophila heart optical coherence microscopy database for automatic video segmentation (Fishman et al. 2023) | DH OCM | Microscopy; heart | Segmentation of a fruit fly heart in optical coherence microscopy videos | Sparse | All | 213 | 213 | 608,000 | 607,158 |
| Video Object Segmentation under Transformations (Tokmakov et al. 2022) | VOST | Deformation | Video object segmentation with emphasis on shape transformations | Dense | Validation | 635 | 882 | 67,004 | 89,722 |
| Cityscapes-VPS (Cordts et al. 2016; Kim et al. 2020) | Cityscapes-VPS | Driving | Panoptic segmentation for Cityscapes driving dataset | Sparse | Validation Instance | 209 | 1372 | 4,259 | 4,579 |
| Corsican Fire Database (Toulouse et al. 2017) | CFD | Wildfire | Segmentation of wildfires | Sparse | All | 5 | 5 | 541 | 541 |
| Partial and Unusual Masks for Video Object Segmentation (Bekuzarov et al. 2023) | PUMaVOS | Parts | Video object segmentation with a focus on parts and practical use cases | Dense | All | 24 | 26 | 21,187 | 21,485 |
| EPIC-KITCHENS VISOR (Darkhalil et al. 2022) | VISOR | Egocentric | Video object segmentation benchmark containing egocentric videos of cooking with an emphasis on segmenting active objects. | Sparse | Validation | 921 | 921 | 736,030 | 4,426 |
| HT1080WT cells embedded in 3D collagen type I matrices (Gómez-de Mariscal et al. 2021) | HT1080WT | Microscopy; cells | Timelapse videos of HT1080WT cell movement | Sparse | All | 60 | 150 | 1,010 | 2,694 |
| Freiburg-Berkeley Motion Segmentation Dataset (Brox et al. 2010) | FBMS | Moving Object | Precise segmentation of moving objects | Sparse | All | 45 | 70 | 9734 | 755 |
| Virtual KITTI 2 (Cabon et al. 2020) | Virtual KITTI 2 | Synthetic; Driving | Synthetic driving videos generated by a game engine that recreate real world KITTI videos. | Dense | All from video angle Camera_0 | 996 | 1,638 | 109,368 | 162,708 |
| EndoVis 2018 (Allan et al. 2020) | EndoVis 2018 | Endoscopic video; surgery | Segmentation of medical tools in endoscopic videos | Dense | All | 15 | 29 | 2,325 | 4,314 |
| Lindenthal Camera Traps (Haucke & Steinhage 2021) | LCT | Stereo | Wildlife videos captured using stereo cameras. | Sparse | All | 12 | 12 | 4,012 | 412 |
| LVOSv2 (Hong et al. 2024) | LVOSv2 | Long videos | Long-term video object segmentation benchmark, on average 1.14 minutes | Dense | Validation | 136 | 225 | 64,523 | 91,510 |
| UVO (Wang et al. 2021b) | UVO | Open World | Open World instance segmentation of all objects in a video | Dense | Validation | 54 | 311 | 4,860 | 26,747 |
| EgoExo4d (Grauman et al. 2023) | EgoExo4d | Egocentric | Egocentric videos of participants completing skilled activities. | Sparse | Validation videos on egocentric cameras | 1185 | 1185 | 327,080 | 9,035 |
| VIPSeg (Miao et al. 2022) | VIPSeg | Panoptic | Large scale and real world scenarios for video panoptic segmentation | Dense | Validation | 152 | 1,457 | 3,416 | 30,408 |
| Event-based Segmentation Dataset (Huang et al. 2023) | ESD | Clutter | Tabletop object segmentation in an indoor cluttered environment | Dense | All | 135 | 814 | 13,325 | 78,243 |
表 16:用于零样本评测的视频分割数据集。
| UVO | Ego-Exo4d | LVOSv2 | EndoVis 2018 | LCT | VIPSeg |
|---|---|---|---|---|---|
| Virtual KITTI 2 | ESD | FBMS | HT1080WT | VISOR |
|---|---|---|---|---|
| PUMaVOS | CFD | Cityscapes-VPS | VOST | DH OCM | LV-VIS |
|---|---|---|---|---|---|
Figure 17: Examples from SAM 2 zero-shot video benchmark suite.
| UVO | Ego-Exo4d | LVOSv2 | EndoVis 2018 | LCT | VIPSeg |
|---|---|---|---|---|---|
| Virtual KITTI 2 | ESD | FBMS | HT1080WT | VISOR |
|---|---|---|---|---|
| PUMaVOS | CFD | Cityscapes-VPS | VOST | DH OCM | LV-VIS |
|---|---|---|---|---|---|
图 17:SAM 2 零样本视频基准套件示例。
Appendix G Details on comparison to state-of-the-art in semi-supervised VOS
附录 G 半监督 VOS 与现有最优对比的细节
We provide additional details on the comparison to the previous state-of-the-art in semi-supervised VOS (§7). We include results from SAM 2 trained only on SA-1B, SA-V and Internal data, for different encoder sizes.
我们补充 §7 中与先前半监督 VOS 最优方法对比的细节,并给出仅在 SA-1B、SA-V 与 Internal 数据上、不同编码器规模训练的 SAM 2 结果。
Qualitative comparison: In Fig. 16, we show a comparison between our baseline (Cutie-base+, top row) and our model (SAM 2, bottom row) when prompted with a mask in the first frame. While the mask prompt in the first frame only covers the shirt of the person, the masklet predicted by the baseline wrongfully propagates to the whole person. Our model, however, is able to restrict the masklet to the target object.
定性对比: 图 16 比较基线(Cutie-base+,上行)与我们的模型(SAM 2,下行)在首帧掩码提示下的表现。首帧掩码提示只覆盖人物上衣时,基线错误地把 masklet 传播到整人;我们的模型则能把 masklet 限制在目标对象上。
Quantitative comparison: In Table 17, we compare the performance of our model to previous approaches on additional semi-supervised VOS metrics. SAM 2 outperforms prior work on all evaluated benchmarks, in all metrics. Note that unlike these previous approaches, SAM 2 is not specialized in the semi-supervised VOS task but is capable of more general promptable segmentation. SAM 2 is also not restricted to a specific set of object classes. The performance of our model on the SA-V benchmark (Table ) demonstrates its capability to segment anything in a video.
定量对比: 表 17 在额外半监督 VOS 指标上比较我们的模型与先前方法。SAM 2 在全部评测基准与全部指标上均优于先前工作。与这些方法不同,SAM 2 并非专攻半监督 VOS,而能做更通用的可提示分割,也不局限于特定对象类别。模型在 SA-V 基准(表)上的表现表明其能在视频中分割任意对象。
| SA-V val | SA-V test | |||||
|---|---|---|---|---|---|---|
| Method | ||||||
| STCN (Cheng et al. 2021a) | 61.0 | 57.4 | 64.5 | 62.5 | 59.0 | 66.0 |
| SwinB-AOT-L (Yang et al. 2021b) | 51.1 | 46.4 | 55.7 | 50.3 | 46.0 | 54.6 |
| SwinB-DeAOT-L (Yang & Yang 2022) | 61.4 | 56.6 | 66.2 | 61.8 | 57.2 | 66.3 |
| RDE (Li et al. 2022a) | 51.8 | 48.4 | 55.2 | 53.9 | 50.5 | 57.3 |
| XMem (Cheng & Schwing 2022) | 60.1 | 56.3 | 63.9 | 62.3 | 58.9 | 65.8 |
| SimVOS-B (Wu et al. 2023b) | 44.2 | 40.0 | 48.3 | 44.1 | 40.5 | 47.7 |
| DEVA (Cheng et al. 2023b) | 55.4 | 51.5 | 59.2 | 56.2 | 52.4 | 60.1 |
| Cutie-base (Cheng et al. 2023a) | 60.7 | 57.7 | 63.7 | 62.7 | 59.7 | 65.7 |
| Cutie-base+ (Cheng et al. 2023a) | 61.3 | 58.3 | 64.4 | 62.8 | 59.8 | 65.8 |
| SAM 2 (Hiera-B+) | 76.8 | 73.4 | 80.1 | 77.0 | 73.5 | 80.5 |
| SAM 2 (Hiera-L) | 77.9 | 74.5 | 81.3 | 78.4 | 74.9 | 82.0 |
| SAM 2 (Hiera-T)‡ | 75.2 | 71.7 | 78.7 | 76.5 | 72.9 | 80.1 |
| SAM 2 (Hiera-S)‡ | 77.0 | 73.6 | 80.5 | 76.6 | 73.0 | 80.2 |
| SAM 2 (Hiera-B+)‡ | 77.5 | 74.1 | 80.9 | 78.2 | 74.8 | 81.7 |
| SAM 2 (Hiera-L)‡ | 78.6 | 75.3 | 82.0 | 79.5 | 76.0 | 83.0 |
| LVOS val | |||
|---|---|---|---|
| Method | |||
| DEVA (Cheng et al. 2023b) | 55.9 | 51.1 | 60.7 |
| DDMemory (Hong et al. 2023) | 60.7 | 55.0 | 66.3 |
| Cutie-base (Cheng et al. 2023a) | 66.0 | 61.3 | 70.6 |
| SAM 2 (Hiera-B+) | 78.0 | 73.2 | 82.7 |
| SAM 2 (Hiera-L) | 78.0 | 73.2 | 82.7 |
| SAM 2 (Hiera-T)‡ | 77.5 | 73.0 | 82.1 |
| SAM 2 (Hiera-S)‡ | 77.3 | 72.3 | 82.2 |
| SAM 2 (Hiera-B+)‡ | 77.7 | 73.1 | 82.4 |
| SAM 2 (Hiera-L)‡ | 80.1 | 75.4 | 84.9 |
| LVOSv2 val | |||||
|---|---|---|---|---|---|
| Method | |||||
| STCN (Cheng et al. 2021a) | 60.6 | 57.2 | 64.0 | 57.5 | 63.8 |
| RDE (Li et al. 2022a) | 62.2 | 56.7 | 64.1 | 60.8 | 67.2 |
| SwinB-DeAOT-L (Yang & Yang 2022) | 63.9 | 61.5 | 69.0 | 58.4 | 66.6 |
| XMem (Cheng & Schwing 2022) | 64.5 | 62.6 | 69.1 | 60.6 | 65.6 |
| SAM 2 (Hiera-B+) | 78.7 | 80.6 | 87.2 | 69.0 | 77.8 |
| SAM 2 (Hiera-L) | 79.6 | 81.0 | 87.4 | 70.4 | 79.8 |
| SAM 2 (Hiera-T)‡ | 77.3 | 79.9 | 86.9 | 67.1 | 75.4 |
| SAM 2 (Hiera-S)‡ | 78.3 | 79.2 | 85.9 | 69.0 | 79.0 |
| SAM 2 (Hiera-B+)‡ | 78.2 | 80.5 | 87.2 | 68.1 | 76.9 |
| SAM 2 (Hiera-L)‡ | 80.6 | 81.7 | 88.2 | 71.4 | 81.0 |
| MOSE val | DAVIS17 val | DAVIS17 test | YTVOS19 val | |||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Method | ||||||||||||||
| STCN (Cheng et al. 2021a) | 52.5 | 48.5 | 56.6 | 85.4 | 82.2 | 88.6 | 76.1 | 72.7 | 79.6 | 82.7 | 81.1 | 85.4 | 78.2 | 85.9 |
| SwinB-AOT-L (Yang et al. 2021b) | 59.4 | 55.5 | 63.2 | 85.4 | 82.4 | 88.4 | 81.2 | 77.3 | 85.1 | 84.5 | 84.0 | 88.8 | 78.4 | 86.7 |
| SwinB-DeAOT-L (Yang & Yang 2022) | 59.9 | 55.7 | 64.0 | 86.2 | 83.1 | 89.2 | 82.8 | 78.9 | 86.7 | 86.1 | 85.3 | 90.2 | 80.4 | 88.6 |
| RDE (Li et al. 2022a) | 46.8 | 42.4 | 51.3 | 84.2 | 80.8 | 87.5 | 77.4 | 73.6 | 81.2 | 81.9 | 81.1 | 85.5 | 76.2 | 84.8 |
| XMem (Cheng & Schwing 2022) | 59.6 | 55.4 | 63.7 | 86.0 | 82.8 | 89.2 | 79.6 | 76.1 | 83.0 | 85.6 | 84.1 | 88.5 | 81.0 | 88.9 |
| SimVOS-B (Wu et al. 2023b) | - | - | - | 88.0 | 85.0 | 91.0 | 80.4 | 76.1 | 84.6 | 84.2 | 83.1 | - | 79.1 | - |
| JointFormer (Zhang et al. 2023b) | - | - | - | 90.1 | 87.0 | 93.2 | 88.1 | 84.7 | 91.6 | 87.4 | 86.5 | 90.9 | 82.0 | 90.3 |
| ISVOS (Wang et al. 2022) | - | - | - | 88.2 | 84.5 | 91.9 | 84.0 | 80.1 | 87.8 | 86.3 | 85.2 | 89.7 | 81.0 | 89.1 |
| DEVA (Cheng et al. 2023b) | 66.0 | 61.8 | 70.3 | 87.0 | 83.8 | 90.2 | 82.6 | 78.9 | 86.4 | 85.4 | 84.9 | 89.4 | 79.6 | 87.8 |
| Cutie-base (Cheng et al. 2023a) | 69.9 | 65.8 | 74.1 | 87.9 | 84.6 | 91.1 | 86.1 | 82.4 | 89.9 | 87.0 | 86.0 | 90.5 | 82.0 | 89.6 |
| Cutie-base+ (Cheng et al. 2023a) | 71.7 | 67.6 | 75.8 | 88.1 | 85.5 | 90.8 | 88.1 | 84.7 | 91.4 | 87.5 | 86.3 | 90.6 | 82.7 | 90.5 |
| SAM 2 (Hiera-B+) | 76.6 | 72.6 | 80.6 | 90.2 | 87.0 | 93.4 | 87.9 | 84.7 | 91.1 | 88.6 | 87.1 | 91.6 | 83.9 | 91.9 |
| SAM 2 (Hiera-L) | 77.9 | 73.9 | 81.9 | 90.7 | 87.5 | 94.0 | 87.7 | 84.6 | 90.9 | 89.3 | 87.5 | 92.0 | 84.8 | 92.8 |
| SAM 2 (Hiera-T)‡ | 71.8 | 67.4 | 76.1 | 89.4 | 85.8 | 92.9 | 86.9 | 83.4 | 90.3 | 87.4 | 85.7 | 90.1 | 82.7 | 91.1 |
| SAM 2 (Hiera-S)‡ | 73.5 | 69.2 | 77.7 | 89.6 | 86.3 | 92.9 | 87.6 | 84.1 | 91.1 | 88.0 | 85.9 | 90.2 | 83.9 | 91.9 |
| SAM 2 (Hiera-B+)‡ | 73.8 | 69.7 | 77.9 | 90.0 | 86.8 | 93.1 | 86.6 | 83.3 | 89.8 | 88.2 | 86.1 | 90.6 | 84.0 | 92.1 |
| SAM 2 (Hiera-L)‡ | 74.6 | 70.6 | 78.6 | 90.2 | 86.9 | 93.4 | 88.9 | 85.3 | 92.5 | 88.8 | 86.5 | 91.0 | 84.7 | 92.8 |
(a)
Appendix H Model, data and annotation cards
附录 H 模型、数据与标注卡片
H.1 Model card
H.1 模型卡片
| Model Overview | |
|---|---|
| Name | SAM 2 (Segment Anything Model 2) |
| Version | 1.0 |
| Date | 2024 |
| Organization | Meta FAIR |
| Mode type | Promptable segmentation model |
| Architecture | See Section 4 |
| Repository | https://github.com/facebookresearch/sam2 |
| License | Apache 2.0 |
| Intended Use | |
| Primary intended users | SAM 2 was designed as a unified model for promptable video and image segmentation tasks. The model was primarily developed for research use cases. SAM 2 is released under an Apache 2.0 license. |
| Out-of-scope use cases | See Ethical considerations and license for restrictions. |
| Caveats and recommendations | See Appendix C for limitations. |
| Relevant Factors | |
| Groups | SAM 2 is class agnostic and was designed for promptable image and video segmentation. It can segment and track any object. |
| Instrumentation and environment | SAM 2 was evaluated across a variety of types of video and image data. The video benchmark suite included domains such as driving data, microscopy, egocentric video, robotic surgery. See Table 16 for descriptions of the benchmarks and Figure 17 for example frames. SAM 2 was evaluated on the same suite of image benchmarks as Kirillov et al. 2023, which covers domains including underwater images, paintings, fish-eye images. |
| Metrics | |
| We evaluate the performance of SAM 2 using the following metrics: : We evaluate performance using (Pont-Tuset et al. 2017) for the promptable video segmentation and semi-supervised VOS tasks. : We use for evaluation on YTVOS 2019 for the semi-supervised VOS task. mIoU: We evaluate performance using mIoU for the promptable image segmentation task. | |
| Evaluation Data | |
| Data sources | See Appendix F |
| Training Data | |
| Data source | SAM 2 was trained on the SA-V dataset alongside internally available licensed video data. See Section 5 of the main text for more details and Appendix H.2 for the SA-V dataset data card. |
| Ethical Considerations | |
| Data | See Section 5 for more details about the SAM 2 training data. In Section E.1 we show a geographic distribution of the videos and demographic distribution of the crowdworkers who collected the videos in the SA-V dataset. |
| Cost and impact of compute | The released SAM 2 was trained on 256 A100 GPUs for 108 hours. This corresponds to 12165.12 kWH and an estimated emissions of 3.89 metric tons of CO2e (Patterson et al. 2021; Lacoste et al. 2019). The emissions from training the released SAM 2 are equivalent to 10k miles driven by an average gasoline-powered passenger vehicle (Agency 2022). |
| Risks and harms | In Section E.1.1 of the main text we analyze SAM 2 performance on people across demographic groups. When using SAM 2 in new settings, we suggest that researchers perform their own fairness evaluation for SAM 2 specific to their use case. |
| Use cases | We implore users to use their best judgement. |
Table 18: Model card for SAM 2 following the structure in Mitchell et al. 2019
| 模型概览 | |
|---|---|
| Name | SAM 2 (Segment Anything Model 2) |
| Version | 1.0 |
| Date | 2024 |
| Organization | Meta FAIR |
| Mode type | 可提示分割模型 |
| Architecture | 见第 4 节 |
| Repository | https://github.com/facebookresearch/sam2 |
| License | Apache 2.0 |
| 预期用途 | |
| Primary intended users | SAM 2 设计为可提示视频与图像分割的统一模型,主要用于研究场景,并以 Apache 2.0 许可发布。 |
| Out-of-scope use cases | 见伦理考量与许可中的限制。 |
| Caveats and recommendations | 局限见附录 C。 |
| 相关因素 | |
| Groups | SAM 2 类别无关,面向可提示图像与视频分割,可分割并跟踪任意对象。 |
| Instrumentation and environment | SAM 2 在多种视频与图像数据上评估。视频基准套件覆盖驾驶、显微、自我中心、机器人手术等域。基准描述见表 16,示例帧见图 17。图像基准与 Kirillov et al. 2023 相同,覆盖水下、绘画、鱼眼等。 |
| 指标 | |
| 我们用以下指标评估 SAM 2::可提示视频分割与半监督 VOS(Pont-Tuset et al. 2017)。:YTVOS 2019 半监督 VOS。mIoU:可提示图像分割。 | |
| 评测数据 | |
| Data sources | 见附录 F |
| 训练数据 | |
| Data source | SAM 2 在 SA-V 以及内部可用的授权视频数据上训练。细节见正文第 5 节;SA-V 数据卡片见附录 H.2。 |
| 伦理考量 | |
| Data | SAM 2 训练数据见第 5 节。§E.1 给出 SA-V 视频地理分布与采集众包人员人口统计分布。 |
| Cost and impact of compute | 发布版 SAM 2 在 256 张 A100 上训练 108 小时,约合 12165.12 kWH、估计排放 3.89 公吨 CO2e(Patterson et al. 2021;Lacoste et al. 2019),约等于平均汽油乘用车行驶 1 万英里(Agency 2022)。 |
| Risks and harms | §E.1.1 分析了跨人口统计群体分割人物的表现。在新场景使用时,建议研究者按自身用例做针对性公平性评估。 |
| Use cases | 恳请用户审慎判断。 |
表 18:按 Mitchell et al. 2019 结构编写的 SAM 2 模型卡片
H.2 Dataset card for SA-V dataset
H.2 SA-V 数据集卡片
Motivation
- For what purpose was the dataset created? Was there a specific task in mind? Was there a specific gap that needed to be filled? Please provide a description. The dataset was designed for the PVS task. The contributions of our dataset to the vision community are: (1) The dataset, composed of 50.9K videos and 642.6K masklets, is the largest video segmentation dataset publicly available today (see 5.2 for comparisons to current VOS datasets) (2) The dataset is available under a Creative Commons Attribution 4.0 International Public License at https://ai.meta.com/datasets/segment-anything-video/, (3) The data is a more geographically diverse, publicly available, video segmentation dataset than its predecessors.
动机
- 数据集为何创建?是否针对特定任务或缺口?请说明。 数据集面向 PVS 任务。对视觉社区的贡献包括:(1)含 50.9K 视频与 642.6K masklet,是目前公开最大的视频分割数据集(与现有 VOS 数据集对比见 5.2);(2)以 Creative Commons Attribution 4.0 International 许可发布于 https://ai.meta.com/datasets/segment-anything-video/;(3)相较前作,地理多样性更高且公开可用。
- Who created the dataset (e.g., which team, research group) and on behalf of which entity (e.g., company, institution, organization)? The dataset was created by Meta FAIR. The underlying videos were collected via a contracted third party company.
- 谁创建了数据集(团队、研究组),代表哪个实体? 由 Meta FAIR 创建。底层视频由签约第三方公司采集。
- Who funded the creation of the dataset? The dataset was funded by Meta FAIR.
- 谁资助了数据集创建? Meta FAIR 资助。
- Any other comments? No.
- 其他评论? 无。
Composition
- What do the instances that comprise the dataset represent (e.g., documents, photos, people, countries)? Are there multiple types of instances (e.g., movies, users, and ratings; people and interactions between them; nodes and edges)? Please provide a description. All of the instances in the dataset are videos. Subject matter diversity was encouraged and no specific themes were applied during video collection. Common themes of the video include: locations, objects, scenes. All the videos are distinct, however there are some sets of videos that were taken of the same subject matter.
构成
- 实例代表什么(文档、照片、人、国家等)?是否有多种实例类型?请说明。 全部实例为视频。采集时鼓励题材多样,未施加特定主题。常见主题包括地点、对象、场景。视频彼此不同,但有些集合拍摄同一题材。
- How many instances are there in total (of each type, if appropriate)? There are 50.9K videos.
- 各类实例总数? 共 50.9K 段视频。
- Does the dataset contain all possible instances or is it a sample (not necessarily random) of instances from a larger set? If the dataset is a sample, then what is the larger set? Is the sample representative of the larger set (e.g., geographic coverage)? If so, please describe how this representativeness was validated/verified. If it is not representative of the larger set, please describe why not (e.g., to cover a more diverse range of instances, because instances were withheld or unavailable). While the dataset contains all possible instances, reviewers were advised to refuse to annotate content containing explicit imagery.
- 数据集是全部可能实例,还是更大集合的样本?若是样本,更大集合是什么?是否有代表性(如地理覆盖)?如何验证?若不具代表性,原因是什么? 虽含全部可用实例,但审核员被建议拒绝标注含露骨内容的素材。
- What data does each instance consist of? “Raw” data (e.g., unprocessed text or images) or features? In either case, please provide a description. Each instance is a video.
- 每个实例由什么数据构成?“原始”数据还是特征?请说明。 每个实例是一段视频。
- Is there a label or target associated with each instance? If so, please provide a description. Each video is annotated with masklets that track objects throughout the video. There are no categories or text associated with the masklets. The data was annotated at 6 FPS. There are an average of 3.8 manual masklets, and 8.9 auto masklets per video, and there are 642.6K masklets in total.
- 每个实例是否有标签或目标?请说明。 每段视频标注有贯穿全程的 masklet,无类别或文本。标注帧率为 6 FPS。平均每视频 3.8 个人工 masklet、8.9 个自动 masklet,合计 642.6K 个 masklet。
- Is any information missing from individual instances? If so, please provide a description, explaining why this information is missing (e.g., because it was unavailable). This does not include intentionally removed information, but might include, e.g., redacted text. No.
- 单个实例是否缺信息?若有,请说明原因(不含有意删除)。 无。
- Are relationships between individual instances made explicit (e.g., users’ movie ratings, social network links)? If so, please describe how these relationships are made explicit. No.
- 实例间关系是否明示(如用户评分、社交链接)?若有,如何明示? 无。
- Are there any errors, sources of noise, or redundancies in the dataset? If so, please provide a description. For manual masklets, human errors may exist; for example, annotators may miss a frame to check or fix when needed. For auto masklets, as SAM 2 is used to generates them, model errors such as inconsistencies in the masklets may exist.
- 数据集是否有错误、噪声或冗余?请说明。 人工 masklet 可能有漏检或漏修;自动 masklet 由 SAM 2 生成,可能存在不一致等模型错误。
- Is the dataset self-contained, or does it link to or otherwise rely on external resources (e.g., websites, tweets, other datasets)? If it links to or relies on external resources, a) are there guarantees that they will exist, and remain constant, over time; b) are there official archival versions of the complete dataset (e.g., including the external resources as they existed at the time the dataset was created); c) are there any restrictions (e.g., licenses, fees) associated with any of the external resources that might apply to a dataset consumer? Please provide descriptions of all external resources and any restrictions associated with them, as well as links or other access points, as appropriate. The dataset is self contained.
- 数据集是否自洽,或依赖外部资源(网站、推文、其他数据集)?若依赖:a) 是否保证长期存在且不变;b) 是否有完整存档版;c) 外部资源是否有许可或费用限制?请描述并给出链接。 数据集自洽。
- Does the dataset contain data that might be considered confidential (e.g., data that is protected by legal privilege or by doctor-patient confidentiality, data that includes the content of individuals’ non-public communications)? If so, please provide a description. No.
- 是否含可能被视为机密的数据(法律特权、医患机密、非公开通信等)?请说明。 否。
- Does the dataset contain data that, if viewed directly, might be offensive, insulting, threatening, or might otherwise cause anxiety? If so, please describe why. We have three safety measures to prevent objectionable content: (1) The video collecting crowdworkers were provided instructions to not record videos that might contain objectionable content (e.g., graphic, nudity, or inappropriate content). (2) The expert annotators who annotated the videos were provided instructions to flag and reject videos if objectionable content was present. (3) reports about video(s) in the dataset can be submitted to segment-anything@meta.com.
- Does the dataset identify any subpopulations (e.g., by age, gender)? If so, please describe how these subpopulations are identified and provide a description of their respective distributions within the dataset. The dataset does not identify any subpopulations of the people in the videos. The demographics of the crowdworkers who collected the videos in the dataset are presented in 5.2.
- 数据集是否识别任何子群体(如年龄、性别)?若有,如何识别并描述分布? 不识别视频中人物的子群体。采集视频的众包人员人口统计见 5.2。
- Is it possible to identify individuals (i.e, one or more natural persons), either directly or indirectly (i.e., in combination with other data) from the dataset? If so, please describe how. Videos were subjected to a face blurring model. Reports about videos in the dataset can be submitted to segment-anything@meta.com.
- Does the dataset contain data that might be considered sensitive in any way (e.g., data that reveals race or ethnic origins, sexual orientations, religious beliefs, political opinions or union memberships, or locations; financial or health data; biometric or genetic data; forms of government identification, such as social security numbers; criminal history)? If so, please provide a description. The dataset is not focused on data that may be considered sensitive. Reports about videos in the dataset can be submitted to segment-anything@meta.com.
- Any other comments? No.
- 其他评论? 无。
Collection Process
- How was the data associated with each instance acquired? Was the data directly observable (e.g., raw text, movie ratings), reported by subjects (e.g., survey responses), or indirectly inferred/derived from other data (e.g., part-of-speech tags, model-based guesses for age or language)? If the data was reported by subjects or indirectly inferred/derived from other data, was the data validated/verified? If so, please describe how. The released masklets associated with each video were collected using two methods. (1) SAM 2 assisted manual annotation (2) automatically generated by SAM 2 and verified by annotators.
采集流程
- 每个实例关联数据如何获得?直接可观察、受试者报告,还是间接推断?若为报告或推断,是否验证?如何验证? 发布的 masklet 经两种方式采集:(1)SAM 2 辅助的人工标注;(2)由 SAM 2 自动生成并经标注员核验。
- What mechanisms or procedures were used to collect the data (e.g., hardware apparatuses or sensors, manual human curation, software programs, software APIs)? How were these mechanisms or procedures validated? The videos in the dataset were collected via a contracted third-party vendor. They are videos taken by crowdworkers with unknown equipment.
- 用何种机制或程序采集(硬件传感器、人工策展、软件、API)?如何验证? 视频由签约第三方供应商采集,由众包人员用未知设备拍摄。
- If the dataset is a sample from a larger set, what was the sampling strategy (e.g., deterministic, probabilistic with specific sampling probabilities)? N/A.
- 若为更大集合的样本,采样策略是什么? 不适用。
- Who was involved in the data collection process (e.g., students, crowdworkers, contractors) and how were they compensated (e.g., how much were crowdworkers paid)? (1) The videos in the dataset were collected via a contracted third-party vendor. They are videos taken by crowdworkers who were compensated with an hourly wage set by the vendor. (2) The manually collected masklets in the dataset were collected by annotators via another third-party vendor. Annotators were compensated with an hourly wage set by the vendor.
- 谁参与数据采集(学生、众包、承包商),如何补偿? (1)视频由签约第三方供应商采集,众包人员按供应商设定时薪补偿。(2)人工 masklet 由另一第三方供应商的标注员采集,按供应商设定时薪补偿。
- Over what timeframe was the data collected? Does this timeframe match the creation timeframe of the data associated with the instances (e.g., recent crawl of old news articles)? If not, please describe the timeframe in which the data associated with the instances was created. The videos were filmed between November 2023 and March 2024. The masklet annotations were collected between April 2024 and July 2024.
- 数据采集时间跨度?是否与实例关联数据的创建时间一致?若否,说明关联数据的创建时间。 视频拍摄于 2023 年 11 月至 2024 年 3 月;masklet 标注采集于 2024 年 4 月至 7 月。
- Were any ethical review processes conducted (e.g., by an institutional review board)? If so, please provide a description of these review processes, including the outcomes, as well as a link or other access point to any supporting documentation. If the dataset does not relate to people, you may skip the remaining questions in this section. The project underwent an internal review process.
- 是否经过伦理审查(如 IRB)?请描述流程、结果及支持文档链接。若与人不相关可跳过本节其余问题。 项目经过内部审查。
- Did you collect the data from the individuals in question directly, or obtain it via third parties or other sources (e.g. websites)? We contracted with third-party vendors to collect the videos and to generate or review annotations.
- 数据是直接从相关个人采集,还是经第三方或其他来源? 我们与第三方供应商签约采集视频并生成或审核标注。
- Were the individuals in question notified about the data collection? If so, please describe (or show with screenshots or other information) how notice was provided, and provide a link or other access point to, or otherwise reproduce, the exact language of the notification itself. The videos were collected by crowdworkers via a contracted third-party vendor. The crowdworkers agreed to consent forms.
- 相关个人是否获知数据采集?如何告知?请给出通知原文或链接。 视频由签约第三方的众包人员采集,众包人员签署了同意书。
- Did the individuals in question consent to the collection and use of their data? If so, please describe (or show with screenshots or other information) how consent was requested and provided, and provide a link or other access point to, or otherwise reproduce, the exact language to which the individuals consented. The videos were collected via a contracted third-party who provided appropriate representations regarding the collection of any notices and consents as required from individuals.
- 相关个人是否同意采集与使用其数据?如何征求与提供同意?请给出同意原文或链接。 视频经签约第三方采集,该方就所需通知与同意作出相应陈述。
- If consent was obtained, were the consenting individuals provided with a mechanism to revoke their consent in the future or for certain uses? If so, please provide a description, as well as a link or other access point to the mechanism (if appropriate). Pursuant to the contract, the contracted third-party collected consents and provided opportunity for consent revocation.
- 若已获同意,同意者是否有机制可在将来或针对特定用途撤销同意?请描述及链接。 按合同,签约第三方收集同意并提供撤销机会。
- Has an analysis of the potential impact of the dataset and its use on data subjects (e.g., a data protection impact analysis) been conducted? If so, please provide a description of this analysis, including the outcomes, as well as a link or other access point to any supporting documentation. See detail in E.1.1.
- 是否分析过数据集及其使用对数据主体的潜在影响(如数据保护影响分析)?请描述结果及文档链接。 细节见 E.1.1。
- Any other comments? No.
- 其他评论? 无。
Preprocessing / Cleaning / Labeling
- Was any preprocessing / cleaning / labeling of the data done (e.g., discretization or bucketing, tokenization, part-of-speech tagging, SIFT feature extraction, removal of instances, processing of missing values)? If so, please provide a description. If not, you may skip the remaining questions in this section. The videos were re-sampled to 24 fps and converted to mp4 format.
预处理 / 清洗 / 标注
- 是否做过预处理 / 清洗 / 标注(离散化、分词、词性标注、SIFT、删实例、处理缺失等)?请说明;若无,可跳过本节其余问题。 视频重采样为 24 fps 并转为 mp4。
- Was the “raw” data saved in addition to the preprocessed/cleaned/labeled data (e.g., to support unanticipated future uses)? If so, please provide a link or other access point to the “raw” data. No.
- 除预处理/清洗/标注数据外,是否另存“原始”数据?若有,请给链接。 否。
Uses
- Has the dataset been used for any tasks already? If so, please provide a description. The dataset has been used to train and evaluate SAM 2.
用途
- 数据集是否已用于某些任务?请说明。 已用于训练与评估 SAM 2。
- What (other) tasks could the dataset be used for? The data could be used for VOS, iVOS, or PVS tasks. If frames are sampled from the videos, the dataset can be used for the image segmentation task.
- 还可用于哪些(其他)任务? 可用于 VOS、iVOS 或 PVS;若从视频采样帧,也可用于图像分割。
- Is there anything about the composition of the dataset or the way it was collected and preprocessed/cleaned/labeled that might impact future uses? For example, is there anything that a dataset consumer might need to know to avoid uses that could result in unfair treatment of individuals or groups (e.g., stereotyping, quality of service issues) or other risks or harms (e.g., legal risks, financial harms)? If so, please provide a description. Is there anything a dataset consumer could do to mitigate these risks or harms? We have an analysis of the geography and crowdworker demographic of our dataset in 5.2. While we believe our dataset to be more representative on these factors than most of the publicly existing datasets of its kind at this time, we acknowledge that we do not have parity across all geographic and demographic groups, and we encourage users of the dataset to be mindful of any potential biases models may learn using this dataset.
- 构成或采集/预处理/标注方式是否可能影响未来用途?例如是否可能导致对个体或群体的不公对待(刻板印象、服务质量)或其他风险?可如何缓解? 地理与众包人口统计见 5.2。我们认为相较多数同类公开数据更具代表性,但承认并非所有地理与人口群体都均衡,鼓励使用者留意模型可能学到的偏差。
- Are there tasks for which the dataset should not be used? If so, please provide a description. No. Full terms of use for the dataset can be found at https://ai.meta.com/datasets/segment-anything-video-downloads/.
- 有哪些任务不应使用该数据集?请说明。 无特别禁止。完整使用条款见 https://ai.meta.com/datasets/segment-anything-video-downloads/。
- Any other comments? No.
- 其他评论? 无。
Distribution
- Will the dataset be distributed to third parties outside of the entity (e.g., company, institution, organization) on behalf of which the dataset was created? If so, please provide a description. The dataset will be available under the permissive Creative Commons Attribution 4.0 International Public License.
分发
- 是否向创建实体之外的第三方分发?请说明。 数据集以宽松的 Creative Commons Attribution 4.0 International 许可提供。
- How will the dataset will be distributed (e.g., tarball on website, API, GitHub)? Does the dataset have a digital object identifier (DOI)? The dataset is available at https://ai.meta.com/datasets/segment-anything-video/.
- 如何分发(网站压缩包、API、GitHub)?是否有 DOI? 见 https://ai.meta.com/datasets/segment-anything-video/。
- When will the dataset be distributed? The dataset will be distributed in July 2024.
- 何时分发? 2024 年 7 月分发。
- Will the dataset be distributed under a copyright or other intellectual property (IP) license, and/or under applicable terms of use (ToU)? If so, please describe this license and/or ToU, and provide a link or other access point to, or otherwise reproduce, any relevant licensing terms or ToU, as well as any fees associated with these restrictions. Yes, the dataset will be available under the Creative Commons Attribution 4.0 International Public License. The license agreement and terms of use for the dataset can be found at https://ai.meta.com/datasets/segment-anything-video-downloads/. Users must agree to the terms of use before downloading or using the dataset.
- 是否在版权或其他知识产权许可和/或使用条款下分发?请描述并给出链接或费用。 是,以 Creative Commons Attribution 4.0 International 许可提供。许可协议与使用条款见 https://ai.meta.com/datasets/segment-anything-video-downloads/。用户须同意条款后方可下载或使用。
- Have any third parties imposed IP-based or other restrictions on the data associated with the instances? If so, please describe these restrictions, and provide a link or other access point to, or otherwise reproduce, any relevant licensing terms, as well as any fees associated with these restrictions. Full terms of use and restrictions on use of the SA-V dataset can be found at https://ai.meta.com/datasets/segment-anything-video-downloads/.
- 第三方是否对实例关联数据施加基于 IP 或其他限制?请描述并给链接。 SA-V 完整使用条款与限制见 https://ai.meta.com/datasets/segment-anything-video-downloads/。
- Do any export controls or other regulatory restrictions apply to the dataset or to individual instances? If so, please describe these restrictions, and provide a link or other access point to, or otherwise reproduce, any supporting documentation. The license and restrictions on use of the SA-V dataset can be found at https://ai.meta.com/datasets/segment-anything-video-downloads/.
- 是否适用出口管制或其他监管限制?请描述并给文档链接。 许可与使用限制见 https://ai.meta.com/datasets/segment-anything-video-downloads/。
- Any other comments? No.
- 其他评论? 无。
Maintenance
- Who will be supporting/hosting/maintaining the dataset? The dataset will be hosted at https://ai.meta.com/datasets/segment-anything-video/ and maintained by Meta FAIR.
维护
- 谁支持/托管/维护数据集? 托管于 https://ai.meta.com/datasets/segment-anything-video/,由 Meta FAIR 维护。
- How can the owner/curator/manager of the dataset be contacted (e.g., email address)? Please email segment-anything@meta.com.
- Is there an erratum? If so, please provide a link or other access point. No.
- 是否有勘误?若有请给链接。 无。
- Will the dataset be updated (e.g., to correct labeling errors, add new instances, delete instances)? If so, please describe how often, by whom, and how updates will be communicated to dataset consumers (e.g., mailing list, GitHub)? Updates may be made pursuant to inbound received at segment-anything@meta.com.
- If the dataset relates to people, are there applicable limits on the retention of the data associated with the instances (e.g., were the individuals in question told that their data would be retained for a fixed period of time and then deleted)? If so, please describe these limits and explain how they will be enforced. There are no limits on data retention.
- 若与人相关,实例关联数据的保留是否有时限?如何执行? 无保留时限。
- Will older versions of the dataset continue to be supported/hosted/maintained? If so, please describe how. If not, please describe how its obsolescence will be communicated to dataset consumers. No. If updates are made to the dataset, previous versions will not continue to be hosted.
- 旧版本是否继续支持/托管/维护?如何告知过时? 否。若更新数据集,先前版本将不再托管。
- If others want to extend/augment/build on/contribute to the dataset, is there a mechanism for them to do so? If so, please provide a description. Will these contributions be validated/verified? If so, please describe how. If not, why not? Is there a process for communicating/distributing these contributions to dataset consumers? If so, please provide a description. We encourage further annotations for SA-V, but these will not be validated/verified or supported/hosted/maintained by Meta.
- 他人若想扩展/增强/贡献,是否有机制?是否核验?如何向消费者传达贡献? 鼓励为 SA-V 追加标注,但 Meta 不会核验或支持/托管/维护这些贡献。
- Any other comments? No.
- 其他评论? 无。
H.3 Data annotation card
H.3 数据标注卡片
Task Formulation
- At a high level, what are the subjective aspects of your task? Selecting objects to mask and track in a video is inherently a subjective task, and annotators might differ in their decision to mask objects.
任务表述
- 任务的主观方面有哪些? 选择在视频中要掩码并跟踪的对象本身主观,标注员对掩码哪些对象可能不同。
- What assumptions do you make about annotators? We assume our annotators understand the PVS task and are well trained on video related tasks. Our annotators worked full time on our annotation task. This made it possible to train the annotators by sharing feedback on a regular basis.
- 对标注员有何假设? 假定标注员理解 PVS 任务并受过视频相关训练。标注员全职从事本任务,便于通过定期反馈培训。
- How did you choose the specific wording of your task instructions? What steps, if any, were taken to verify the clarity of task instructions and wording for annotators? (1) The task instructions included visual examples (images and videos) to provide clarity. (2) Annotators were well trained before working on production queues. (3) The research team shared feedback daily and met with the annotators weekly for Q&A sessions.
- 如何选定任务说明措辞?采取了哪些步骤核实清晰度? (1)说明含图像与视频示例;(2)进入生产队列前充分培训;(3)研究团队每日反馈,并每周与标注员开问答会。
- What, if any, risks did your task pose for annotators and were they informed of the risks prior to engagement with the task? Annotators were informed to reject objectionable videos.
- 任务对标注员有何风险?参与前是否告知? 已告知可拒绝不当视频。
- What are the precise instructions that were provided to annotators? See detail in 11 for annotation instructions.
- 提供给标注员的精确说明是什么? 标注说明细节见 11。
Selecting Annotations
- Are there certain perspectives that should be privileged? If so, how did you seek these perspectives out? We chose to work with annotators with previous video annotation experience.
选择标注
- 是否应优先某些视角?如何寻求? 我们选择有视频标注经验的标注员。
- Are there certain perspectives that would be harmful to include? If so, how did you screen these perspectives out? No.
- 是否有应排除的有害视角?如何筛除? 无。
- Were sociodemographic characteristics used to select annotators for your task? If so, please detail the process. For masklet annotations, sociodemographic characteristics were not used to select the annotators. For video collection, we emphasized the importance of diversity among the crowdworkers to our third-party vendor. While it was not a strict requirement, we encouraged the inclusion of a diverse group of crowdworkers to enrich the data collection process with a wide range of perspectives. This approach aimed to naturally incorporate diversity without imposing strict selection based on sociodemographic factors.
- 是否用社会人口特征筛选标注员?请详述。 masklet 标注未按社会人口特征筛选。视频采集方面,我们向第三方强调众包多样性;虽非硬性要求,但鼓励纳入多元众包以丰富视角,尽量在不强制按社会人口筛选的情况下自然纳入多样性。
- If you have any aggregated socio-demographic statistics about your annotator pool, please describe. Do you have reason to believe that sociodemographic characteristics of annotators may have impacted how they annotated the data? Why or why not? Aggregated socio-demographic statistics about the crowdworkers who collected the videos are presented in 5.2.
- 若有标注员池的汇总社会人口统计,请描述。是否有理由认为这些特征影响了标注方式? 采集视频的众包汇总社会人口统计见 5.2。
- Consider the intended context of use of the dataset and the individuals and communities that may be impacted by a model trained on this dataset. Are these communities represented in your annotator pool? The SA-V dataset is a geographically diverse, publicly available, video segmentation dataset, as discussed in 5.2. In addition, we analyze the responsible AI axes of a model trained on the dataset, as discussed in E.1.1.
- 考虑数据集预期使用场景及可能受影响的个人与社区,这些社区是否在标注员池中有代表? SA-V 地理多样且公开,见 5.2。另分析了在其上训练模型的负责任 AI 维度,见 E.1.1。
Platform and Infrastructure Choices
- What annotation platform did you utilize? At a high level, what considerations informed your decision to choose this platform? Did the chosen platform sufficiently meet the requirements you outlined for annotator pools? Are any aspects not covered? We used an internal annotation platform.
平台与基础设施选择
- 使用何种标注平台?高层考量是什么?是否满足标注员池要求?有何未覆盖方面? 使用内部标注平台。
- What, if any, communication channels did your chosen platform offer to facilitate communication with annotators? How did this channel of communication influence the annotation process and/or resulting annotations? The research team shared feedback daily and met with the annotators weekly to align on the task instructions and expectations and to hold Q&A sessions. Outside of those sessions, annotators had access to a spreadsheet and chat group to facilitate communication with the research team.
- 平台提供了哪些沟通渠道?如何影响标注过程与结果? 研究团队每日反馈,每周与标注员对齐说明与期望并开问答会;会外标注员可通过表格与聊天群联系研究团队。
- How much were annotators compensated? Did you consider any particular pay standards, when determining their compensation? If so, please describe. (1) The video collecting crowdworkers were compensated with an hourly wage set by the vendor. (2) Annotators were compensated with an hourly wage set by the vendor.
- 标注员如何补偿?确定报酬时是否参考特定薪酬标准? (1)视频采集众包按供应商设定时薪;(2)标注员按供应商设定时薪。
Dataset Analysis and Evaluation
- How do you define the quality of annotations in your context, and how did you assess the quality in the dataset you constructed? Annotators were required to follow a training before moving to production queues. Annotators followed a 2-day training session led by the vendor and then were asked to annotate jobs from a training queue. Annotators were able to move from training to production after the vendor Q&A team or the research team reviewed their work and assessed quality. On average, annotators spent 1 - 2 weeks in training before moving to production. Similarly, the vendor and research team Q&A manually reviewed the production queues’ annotations daily, sharing feedback daily.
数据集分析与评估
- 在你们的语境中如何定义标注质量?如何评估所建数据集质量? 标注员须先培训再进生产队列:由供应商主导 2 天培训后,在培训队列标注;经供应商问答团队或研究团队审阅并评估质量后方可进生产。平均培训 1–2 周。生产队列标注亦由供应商与研究团队问答每日人工审阅并反馈。
- Have you conducted any analysis on disagreement patterns? If so, what analyses did you use and what were the major findings? Did you analyze potential sources of disagreement? The disagreement patterns were shared daily and weekly during feedback and Q&A sessions.
- 是否分析过分歧模式?用了哪些分析、主要发现?是否分析分歧来源? 分歧模式在每日与每周反馈及问答会上分享。
- How do the individual annotator responses relate to the final labels released in the dataset? The final labels are after data cleaning and post processing from the individual annotator responses.
- 单个标注员响应与数据集最终标签的关系? 最终标签是对单个标注员响应做数据清洗与后处理之后的结果。
Dataset Release and Maintenance
- Do you have reason to believe the annotations in this dataset may change over time? Do you plan to update your dataset? No.
数据集发布与维护
- 是否有理由认为标注会随时间变化?是否计划更新数据集? 否。
- Are there any conditions or definitions that, if changed, could impact the utility of your dataset? No.
- 是否有条件或定义一旦改变会影响数据集效用? 否。
- Will you attempt to track, impose limitations on, or otherwise influence how your dataset is used? If so, how? The SA-V dataset is released under a permissive CC by 4.0 license.
- 是否会尝试跟踪、限制或以其他方式影响数据集用法?如何? SA-V 以宽松的 CC BY 4.0 许可发布。
- Were annotators informed about how the data is externalized? If changes to the dataset are made, will they be informed? No.
- 是否告知标注员数据如何对外化?若数据集变更,是否告知? 否。
- Is there a process by which annotators can later choose to withdraw their data from the dataset? If so, please detail. No.
- 标注员日后能否申请撤回其数据?若有请详述。 否。
References
参考文献
Agency (2022) United States Environmental Protection Agency. Greenhouse gas equivalencies calculator. https://www.epa.gov/energy/greenhouse-gas-equivalencies-calculator , 2022.
Allan et al. (2020) Max Allan, Satoshi Kondo, Sebastian Bodenstedt, Stefan Leger, Rahim Kadkhodamohammadi, Imanol Luengo, Felix Fuentes, Evangello Flouty, Ahmed Mohammed, Marius Pedersen, et al. 2018 robotic scene segmentation challenge. arXiv preprint arXiv:2001.11190 , 2020.
Athar et al. (2022) Ali Athar, Jonathon Luiten, Paul Voigtlaender, Tarasha Khurana, Achal Dave, Bastian Leibe, and Deva Ramanan. Burst: A benchmark for unifying object recognition, segmentation and tracking in video. WACV , pp. 1674–1683, 2022.
Bai & Sapiro (2007) Xue Bai and Guillermo Sapiro. A geodesic framework for fast interactive image and video segmentation and matting. In ICCV , 2007.
Bashkirova et al. (2022) Dina Bashkirova, Mohamed Abdelfattah, Ziliang Zhu, James Akl, Fadi Alladkani, Ping Hu, Vitaly Ablavsky, Berk Calli, Sarah Adel Bargal, and Kate Saenko. ZeroWaste dataset: Towards deformable object segmentation in cluttered scenes. CVPR , 2022.
Bekuzarov et al. (2023) Maksym Bekuzarov, Ariana Bermudez, Joon-Young Lee, and Hao Li. Xmem++: Production-level video segmentation from few annotated frames. In ICCV , pp. 635–644, 2023.
Bhat et al. (2020) Goutam Bhat, Felix Järemo Lawin, Martin Danelljan, Andreas Robinson, Michael Felsberg, Luc Van Gool, and Radu Timofte. Learning what to learn for video object segmentation. ECCV , abs/2003.11540, 2020.
Bolya et al. (2023) Daniel Bolya, Chaitanya Ryali, Judy Hoffman, and Christoph Feichtenhofer. Window attention is bugged: How not to interpolate position embeddings. ICLR , 2023.
Brox et al. (2010) T Brox, J Malik, and P Ochs. Freiburg-berkeley motion segmentation dataset (fbms-59). In ECCV , volume 1, pp. 9, 2010.
Cabon et al. (2020) Yohann Cabon, Naila Murray, and Martin Humenberger. Virtual KITTI 2. arXiv preprint arXiv:2001.10773 , 2020.
Caelles et al. (2016) Sergi Caelles, Kevis-Kokitsi Maninis, Jordi Pont-Tuset, Laura Leal-Taixé, Daniel Cremers, and Luc Van Gool. One-shot video object segmentation. CVPR , pp. 5320–5329, 2016.
Caelles et al. (2018) Sergi Caelles, Alberto Montes, Kevis-Kokitsi Maninis, Yuhua Chen, Luc Van Gool, Federico Perazzi, and Jordi Pont-Tuset. The 2018 davis challenge on video object segmentation. arXiv preprint arXiv:1803.00557 , 2018.
Caelles et al. (2019) Sergi Caelles, Jordi Pont-Tuset, Federico Perazzi, Alberto Montes, Kevis-Kokitsi Maninis, and Luc Van Gool. The 2019 davis challenge on vos: Unsupervised multi-object segmentation. arXiv preprint arXiv:1905.00737 , 2019.
Caicedo et al. (2019) Juan C. Caicedo, Allen Goodman, Kyle W. Karhohs, Beth A. Cimini, Jeanelle Ackerman, Marzieh Haghighi, CherKeng Heng, Tim Becker, Minh Doan, Claire McQuin, Mohammad Rohban, Shantanu Singh, and Anne E. Carpenter. Nucleus segmentation across imaging experiments: the 2018 data science bowl. Nature Methods , 2019.
Chen et al. (2022) Jiazhou Chen, Yanghui Xu, Shufang Lu, Ronghua Liang, and Liangliang Nan. 3D instance segmentation of MVS buildings. IEEE Transactions on Geoscience and Remote Sensing , 2022.
Chen et al. (2024) Keyan Chen, Chenyang Liu, Hao Chen, Haotian Zhang, Wenyuan Li, Zhengxia Zou, and Zhenwei Shi. Rsprompter: Learning to prompt for remote sensing instance segmentation based on visual foundation model. IEEE Transactions on Geoscience and Remote Sensing , 2024.
Chen et al. (2018) Yuhua Chen, Jordi Pont-Tuset, Alberto Montes, and Luc Van Gool. Blazingly fast video object segmentation with pixel-wise metric learning. CVPR , pp. 1189–1198, 2018.
Cheng & Schwing (2022) Ho Kei Cheng and Alexander G Schwing. Xmem: Long-term video object segmentation with an atkinson-shiffrin memory model. In ECCV , pp. 640–658. Springer, 2022.
Cheng et al. (2021a) Ho Kei Cheng, Yu-Wing Tai, and Chi-Keung Tang. Rethinking space-time networks with improved memory coverage for efficient video object segmentation. In NeurIPS , 2021a.
Cheng et al. (2021b) Ho Kei Cheng, Yu-Wing Tai, and Chi-Keung Tang. Modular interactive video object segmentation: Interaction-to-mask, propagation and difference-aware fusion. In CVPR , 2021b.
Cheng et al. (2023a) Ho Kei Cheng, Seoung Wug Oh, Brian Price, Joon-Young Lee, and Alexander Schwing. Putting the object back into video object segmentation. In arXiv , 2023a.
Cheng et al. (2023b) Ho Kei Cheng, Seoung Wug Oh, Brian L. Price, Alexander Schwing, and Joon-Young Lee. Tracking anything with decoupled video segmentation. ICCV , pp. 1316–1326, 2023b.
Cheng et al. (2023c) Yangming Cheng, Liulei Li, Yuanyou Xu, Xiaodi Li, Zongxin Yang, Wenguan Wang, and Yi Yang. Segment and track anything. arXiv preprint arXiv:2305.06558 , 2023c.
Cho et al. (2014) Kyunghyun Cho, Bart van Merrienboer, Caglar Gulcehre, Dzmitry Bahdanau, Fethi Bougares, Holger Schwenk, and Yoshua Bengio. Learning phrase representations using rnn encoder-decoder for statistical machine translation, 2014. cite arxiv:1406.1078Comment: EMNLP 2014.
Ciampi et al. (2021) Luca Ciampi, Carlos Santiago, Joao Costeira, Claudio Gennaro, and Giuseppe Amato. Domain adaptation for traffic density estimation. International Joint Conference on Computer Vision, Imaging and Computer Graphics Theory and Applications , 2021.
Ciampi et al. (2022) Luca Ciampi, Carlos Santiago, Joao Costeira, Claudio Gennaro, and Giuseppe Amato. Night and day instance segmented park (NDISPark) dataset: a collection of images taken by day and by night for vehicle detection, segmentation and counting in parking areas. Zenodo , 2022.
Clark et al. (2020) Kevin Clark, Minh-Thang Luong, Quoc V Le, and Christopher D Manning. ELECTRA: Pre-training text encoders as discriminators rather than generators. In ICLR , 2020.
Cohen et al. (2022) Nadav Cohen, Yael Newman, and Ariel Shamir. Semantic segmentation in art paintings. Computer Graphics Forum , 2022.
Cordts et al. (2016) Marius Cordts, Mohamed Omran, Sebastian Ramos, Timo Rehfeld, Markus Enzweiler, Rodrigo Benenson, Uwe Franke, Stefan Roth, and Bernt Schiele. The cityscapes dataset for semantic urban scene understanding. In CVPR , pp. 3213–3223, 2016.
Damen et al. (2022) Dima Damen, Hazel Doughty, Giovanni Maria Farinella, Antonino Furnari, Jian Ma, Evangelos Kazakos, Davide Moltisanti, Jonathan Munro, Toby Perrett, Will Price, and Michael Wray. Rescaling egocentric vision: Collection, pipeline and challenges for EPIC-KITCHENS-100. IJCV , 2022.
Dao (2023) Tri Dao. Flashattention-2: Faster attention with better parallelism and work partitioning. arXiv preprint arXiv:2307.08691 , 2023.
Darkhalil et al. (2022) Ahmad Darkhalil, Dandan Shan, Bin Zhu, Jian Ma, Amlan Kar, Richard Higgins, Sanja Fidler, David Fouhey, and Dima Damen. Epic-kitchens visor benchmark: Video segmentations and object relations. NeurIPS , 35:13745–13758, 2022.
Delatolas et al. (2024) Thanos Delatolas, Vicky Kalogeiton, and Dim P Papadopoulos. Learning the what and how of annotation in video object segmentation. In WACV , pp. 6951–6961, 2024.
Deng et al. (2023) Ruining Deng, Can Cui, Quan Liu, Tianyuan Yao, Lucas W Remedios, Shunxing Bao, Bennett A Landman, Lee E Wheless, Lori A Coburn, Keith T Wilson, et al. Segment anything model (sam) for digital pathology: Assess zero-shot segmentation on whole slide imaging. arXiv preprint arXiv:2304.04155 , 2023.
Ding et al. (2023) Henghui Ding, Chang Liu, Shuting He, Xudong Jiang, Philip H. S. Torr, and Song Bai. Mose: A new dataset for video object segmentation in complex scenes. ICCV , pp. 20167–20177, 2023.
Fan et al. (2015) Qingnan Fan, Fan Zhong, Dani Lischinski, Daniel Cohen-Or, and Baoquan Chen. Jumpcut: non-successive mask transfer and interpolation for video cutout. ACM Transactions on Graphics , 2015.
Fathi et al. (2011) Alireza Fathi, Xiaofeng Ren, and James M. Rehg. Learning to recognize objects in egocentric activities. CVPR , 2011.
Fishman et al. (2023) Matthew Fishman, Abigail Matt, Fei Wang, Elena Gracheva, Jiantao Zhu, Xiangping Ouyang, Andrey Komarov, Yuxuan Wang, Hongwu Liang, and Chao Zhou. A drosophila heart optical coherence microscopy dataset for automatic video segmentation. Scientific Data , 10(1):886, 2023.
Fortin et al. (2022) Jean-Michel Fortin, Olivier Gamache, Vincent Grondin, François Pomerleau, and Philippe Giguère. Instance segmentation for autonomous log grasping in forestry operations. IROS , 2022.
Gómez-de Mariscal et al. (2021) Estibaliz Gómez-de Mariscal, Hasini Jayatilaka, Özgün Çiçek, Thomas Brox, Denis Wirtz, and Arrate Muñoz-Barrutia. Search for temporal cell segmentation robustness in phase-contrast microscopy videos. arXiv preprint arXiv:2112.08817 , 2021.
Goyal et al. (2023) Raghav Goyal, Wan-Cyuan Fan, Mennatullah Siam, and Leonid Sigal. Tam-vt: Transformation-aware multi-scale video transformer for segmentation and tracking. arXiv preprint arXiv:2312.08514 , 2023.
Grauman et al. (2023) Kristen Grauman, Andrew Westbury, Lorenzo Torresani, Kris Kitani, Jitendra Malik, Triantafyllos Afouras, Kumar Ashutosh, Vijay Baiyya, Siddhant Bansal, Bikram Boote, et al. Ego-exo4d: Understanding skilled human activity from first-and third-person perspectives. arXiv preprint arXiv:2311.18259 , 2023.
Gupta et al. (2019) Agrim Gupta, Piotr Dollar, and Ross Girshick. LVIS: A dataset for large vocabulary instance segmentation. CVPR , 2019.
Haucke & Steinhage (2021) Timm Haucke and Volker Steinhage. Exploiting depth information for wildlife monitoring. arXiv preprint arXiv:2102.05607 , 2021.
Haucke et al. (2022) Timm Haucke, Hjalmar S. Kühl, and Volker Steinhage. SOCRATES: Introducing depth in visual wildlife monitoring using stereo vision. Sensors , 2022.
He et al. (2022) Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Dollár, and Ross Girshick. Masked autoencoders are scalable vision learners. In CVPR , 2022.
Heo et al. (2024) Byeongho Heo, Song Park, Dongyoon Han, and Sangdoo Yun. Rotary position embedding for vision transformer. arXiv preprint arXiv:2403.13298 , 2024.
Heo et al. (2020) Yuk Heo, Yeong Jun Koh, and Chang-Su Kim. Interactive video object segmentation using global and local transfer modules. In ECCV , 2020.
Homayounfar et al. (2021) Namdar Homayounfar, Justin Liang, Wei-Chiu Ma, and Raquel Urtasun. Videoclick: Video Object Segmentation with a Single Click. arXiv preprint arXiv:2101.06545 , 2021.
Hong et al. (2020) Jungseok Hong, Michael Fulton, and Junaed Sattar. TrashCan: A semantically-segmented dataset towards visual detection of marine debris. arXiv:2007.08097 , 2020.
Hong et al. (2023) Lingyi Hong, Wenchao Chen, Zhongying Liu, Wei Zhang, Pinxue Guo, Zhaoyu Chen, and Wenqiang Zhang. Lvos: A benchmark for long-term video object segmentation. In ICCV , pp. 13480–13492, 2023.
Hong et al. (2024) Lingyi Hong, Zhongying Liu, Wenchao Chen, Chenzhi Tan, Yuang Feng, Xinyu Zhou, Pinxue Guo, Jinglun Li, Zhaoyu Chen, Shuyong Gao, et al. Lvos: A benchmark for large-scale long-term video object segmentation. arXiv preprint arXiv:2404.19326 , 2024.
Hu et al. (2018a) Yuan-Ting Hu, Jia-Bin Huang, and Alexander G. Schwing. MaskRNN: Instance level video object segmentation. In NeurIPS , 2018a.
Hu et al. (2018b) Yuan-Ting Hu, Jia-Bin Huang, and Alexander G. Schwing. VideoMatch: Matching based video object segmentation. ECCV , abs/1809.01123, 2018b.
Huang et al. (2023) Xiaoqian Huang, Kachole Sanket, Abdulla Ayyad, Fariborz Baghaei Naeini, Dimitrios Makris, and Yahya Zweiri. A neuromorphic dataset for object segmentation in indoor cluttered environment. arXiv preprint arXiv:2302.06301 , 2023.
Ke et al. (2024) Lei Ke, Mingqiao Ye, Martin Danelljan, Yu-Wing Tai, Chi-Keung Tang, Fisher Yu, et al. Segment anything in high quality. NeurIPS , 36, 2024.
Kim et al. (2020) Dahun Kim, Sanghyun Woo, Joon-Young Lee, and In So Kweon. Video panoptic segmentation. In CVPR , 2020.
Kirillov et al. (2023) Alexander Kirillov, Eric Mintun, Nikhila Ravi, Hanzi Mao, Chloe Rolland, Laura Gustafson, Tete Xiao, Spencer Whitehead, Alexander C Berg, Wan-Yen Lo, et al. Segment anything. In ICCV , 2023.
Lacoste et al. (2019) Alexandre Lacoste, Alexandra Luccioni, Victor Schmidt, and Thomas Dandres. Quantifying the carbon emissions of machine learning. arXiv preprint arXiv:1910.09700 , 2019.
Li et al. (2013) Fuxin Li, Taeyoung Kim, Ahmad Humayun, David Tsai, and James M. Rehg. Video segmentation by tracking many figure-ground segments. CVPR , pp. 2192–2199, 2013.
Li et al. (2022a) Mingxing Li, Liucheng Hu, Zhiwei Xiong, Bang Zhang, Pan Pan, and Dong Liu. Recurrent dynamic embedding for video object segmentation. CVPR , pp. 1322–1331, 2022a.
Li et al. (2022b) Yanghao Li, Hanzi Mao, Ross Girshick, and Kaiming He. Exploring plain vision transformer backbones for object detection. In ECCV , 2022b.
Li et al. (2015) Yin Li, Zhefan Ye, and James M. Rehg. Delving into egocentric actions. CVPR , 2015.
Lin et al. (2017) Tsung-Yi Lin, Piotr Dollár, Ross Girshick, Kaiming He, Bharath Hariharan, and Serge Belongie. Feature pyramid networks for object detection. In CVPR , 2017.
Loshchilov & Hutter (2019) Ilya Loshchilov and Frank Hutter. Decoupled weight decay regularization. ICLR , 2019.
Ma et al. (2024) Jun Ma, Yuting He, Feifei Li, Lin Han, Chenyu You, and Bo Wang. Segment anything in medical images. Nature Communications , 15(1):654, 2024.
Maninis et al. (2017) Kevis-Kokitsi Maninis, Sergi Caelles, Yuhua Chen, Jordi Pont-Tuset, Laura Leal-Taixé, Daniel Cremers, and Luc Van Gool. Video object segmentation without temporal information. IEEE Transactions on Pattern Analysis and Machine Intelligence , 41:1515–1530, 2017.
Mazurowski et al. (2023) Maciej A Mazurowski, Haoyu Dong, Hanxue Gu, Jichen Yang, Nicholas Konz, and Yixin Zhang. Segment anything model for medical image analysis: an experimental study. Medical Image Analysis , 89:102918, 2023.
Miao et al. (2022) Jiaxu Miao, Xiaohan Wang, Yu Wu, Wei Li, Xu Zhang, Yunchao Wei, and Yi Yang. Large-scale video panoptic segmentation in the wild: A benchmark. In CVPR , pp. 21033–21043, 2022.
Minervini et al. (2016) Massimo Minervini, Andreas Fischbach, Hanno Scharr, and Sotirios A. Tsaftaris. Finely-grained annotated datasets for image-based plant phenotyping. Pattern Recognition Letters , 2016.
Mitchell et al. (2019) Margaret Mitchell, Simone Wu, Andrew Zaldivar, Parker Barnes, Lucy Vasserman, Ben Hutchinson, Elena Spitzer, Inioluwa Deborah Raji, and Timnit Gebru. Model cards for model reporting. In Proceedings of the conference on fairness, accountability, and transparency , pp. 220–229, 2019.
Ochs et al. (2014) Peter Ochs, Jitendra Malik, and Thomas Brox. Segmentation of moving objects by long term video analysis. IEEE Transactions on Pattern Analysis and Machine Intelligence , 36(6):1187–1200, 2014.
Oh et al. (2018) Seoung Wug Oh, Joon-Young Lee, Kalyan Sunkavalli, and Seon Joo Kim. Fast video object segmentation by reference-guided mask propagation. CVPR , pp. 7376–7385, 2018.
Oh et al. (2019) Seoung Wug Oh, Joon-Young Lee, N. Xu, and Seon Joo Kim. Video object segmentation using space-time memory networks. ICCV , pp. 9225–9234, 2019.
Patterson et al. (2021) David Patterson, Joseph Gonzalez, Quoc Le, Chen Liang, Lluis-Miquel Munguia, Daniel Rothchild, David So, Maud Texier, and Jeff Dean. Carbon emissions and large neural network training. arXiv preprint arXiv:2104.10350 , 2021.
Perazzi et al. (2016) Federico Perazzi, Anna Khoreva, Rodrigo Benenson, Bernt Schiele, and Alexander Sorkine-Hornung. Learning video object segmentation from static images. CVPR , pp. 3491–3500, 2016.
Pont-Tuset et al. (2017) Jordi Pont-Tuset, Federico Perazzi, Sergi Caelles, Pablo Arbeláez, Alexander Sorkine-Hornung, and Luc Van Gool. The 2017 davis challenge on video object segmentation. arXiv:1704.00675 , 2017.
Prest et al. (2012) Alessandro Prest, Christian Leistner, Javier Civera, Cordelia Schmid, and Vittorio Ferrari. Learning object class detectors from weakly annotated video. CVPR , pp. 3282–3289, 2012.
Pugliatti & Topputo (2022) Mattia Pugliatti and Francesco Topputo. DOORS: Dataset fOr bOuldeRs Segmentation. Zenodo , 2022.
Qi et al. (2022) Jiyang Qi, Yan Gao, Yao Hu, Xinggang Wang, Xiaoyu Liu, Xiang Bai, Serge Belongie, Alan Yuille, Philip Torr, and Song Bai. Occluded video instance segmentation: A benchmark. IJCV , 2022.
Rajič et al. (2023) Frano Rajič, Lei Ke, Yu-Wing Tai, Chi-Keung Tang, Martin Danelljan, and Fisher Yu. Segment anything meets point tracking. arXiv:2307.01197 , 2023.
Ren et al. (2024) Simiao Ren, Francesco Luzi, Saad Lahrichi, Kaleb Kassaw, Leslie M Collins, Kyle Bradbury, and Jordan M Malof. Segment anything, from space? In WACV , pp. 8355–8365, 2024.
Roberts et al. (2021) Mike Roberts, Jason Ramapuram, Anurag Ranjan, Atulit Kumar, Miguel Angel Bautista, Nathan Paczan, Russ Webb, and Joshua M. Susskind. Hypersim: A photorealistic synthetic dataset for holistic indoor scene understanding. ICCV , 2021.
Robinson et al. (2020) Andreas Robinson, Felix Järemo Lawin, Martin Danelljan, Fahad Shahbaz Khan, and Michael Felsberg. Learning fast and robust target models for video object segmentation. CVPR , pp. 7404–7413, 2020.
Ryali et al. (2023) Chaitanya Ryali, Yuan-Ting Hu, Daniel Bolya, Chen Wei, Haoqi Fan, Po-Yao Huang, Vaibhav Aggarwal, Arkabandhu Chowdhury, Omid Poursaeed, Judy Hoffman, Jitendra Malik, Yanghao Li, and Christoph Feichtenhofer. Hiera: A hierarchical vision transformer without the bells-and-whistles. ICML , 2023.
Snyder & Do (2019) Corey Snyder and Minh Do. STREETS: A novel camera network dataset for traffic flow. NeurIPS , 2019.
Sofiiuk et al. (2022) Konstantin Sofiiuk, Ilya A Petrov, and Anton Konushin. Reviving iterative training with mask guidance for interactive segmentation. In ICIP , pp. 3141–3145. IEEE, 2022.
Su et al. (2021) Jianlin Su, Yu Lu, Shengfeng Pan, Bo Wen, and Yunfeng Liu. Roformer: Enhanced transformer with rotary position embedding. arXiv preprint arXiv:2104.09864 , 2021.
Tang et al. (2023) Lv Tang, Haoke Xiao, and Bo Li. Can sam segment anything? when sam meets camouflaged object detection. arXiv preprint arXiv:2304.04709 , 2023.
Tokmakov et al. (2022) Pavel Tokmakov, Jie Li, and Adrien Gaidon. Breaking the “object” in video object segmentation. CVPR , pp. 22836–22845, 2022.
Toulouse et al. (2017) Tom Toulouse, Lucile Rossi, Antoine Campana, Turgay Celik, and Moulay A Akhloufi. Computer vision for wildfire research: An evolving image dataset for processing and analysis. Fire Safety Journal , 92:188–194, 2017.
Trotter et al. (2020) Cameron Trotter, Georgia Atkinson, Matt Sharpe, Kirsten Richardson, A. Stephen McGough, Nick Wright, Ben Burville, and Per Berggren. NDD20: A large-scale few-shot dolphin dataset for coarse and fine-grained categorisation. arXiv:2005.13359 , 2020.
Voigtlaender & Leibe (2017) Paul Voigtlaender and B. Leibe. Online adaptation of convolutional neural networks for video object segmentation. ArXiv , abs/1706.09364, 2017.
Vujasinović et al. (2022) Stéphane Vujasinović, Sebastian Bullinger, Stefan Becker, Norbert Scherer-Negenborn, Michael Arens, and Rainer Stiefelhagen. Revisiting click-based interactive video object segmentation. In ICIP , pp. 2756–2760. IEEE, 2022.
Wang et al. (2021a) Boying Wang, Libo Zhang, Longyin Wen, Xianglong Liu, and Yanjun Wu. Towards real-world prohibited item detection: A large-scale x-ray benchmark. CVPR , 2021a.
Wang et al. (2023) Haochen Wang, Cilin Yan, Shuai Wang, Xiaolong Jiang, Xu Tang, Yao Hu, Weidi Xie, and Efstratios Gavves. Towards open-vocabulary video instance segmentation. In ICCV , pp. 4057–4066, 2023.
Wang et al. (2005) Jue Wang, Pravin Bhat, R Alex Colburn, Maneesh Agrawala, and Michael F Cohen. Interactive video cutout. ACM Transactions on Graphics , 2005.
Wang et al. (2022) Junke Wang, Dongdong Chen, Zuxuan Wu, Chong Luo, Chuanxin Tang, Xiyang Dai, Yucheng Zhao, Yujia Xie, Lu Yuan, and Yu-Gang Jiang. Look before you match: Instance understanding matters in video object segmentation. CVPR , pp. 2268–2278, 2022.
Wang et al. (2021b) Weiyao Wang, Matt Feiszli, Heng Wang, and Du Tran. Unidentified video objects: A benchmark for dense, open-world segmentation. In ICCV , pp. 10776–10785, 2021b.
Wu et al. (2023a) Junde Wu, Wei Ji, Yuanpei Liu, Huazhu Fu, Min Xu, Yanwu Xu, and Yueming Jin. Medical sam adapter: Adapting segment anything model for medical image segmentation. arXiv preprint arXiv:2304.12620 , 2023a.
Wu et al. (2023b) Qiangqiang Wu, Tianyu Yang, Wei Wu, and Antoni B. Chan. Scalable video object segmentation with simplified framework. In ICCV , 2023b.
Xie et al. (2024) Junyu Xie, Charig Yang, Weidi Xie, and Andrew Zisserman. Moving object segmentation: All you need is sam (and flow). arXiv preprint arXiv:2404.12389 , 2024.
Xiong et al. (2023) Yunyang Xiong, Bala Varadarajan, Lemeng Wu, Xiaoyu Xiang, Fanyi Xiao, Chenchen Zhu, Xiaoliang Dai, Dilin Wang, Fei Sun, Forrest Iandola, Raghuraman Krishnamoorthi, and Vikas Chandra. Efficientsam: Leveraged masked image pretraining for efficient segment anything, 2023.
Xu et al. (2018a) N. Xu, L. Yang, Yuchen Fan, Jianchao Yang, Dingcheng Yue, Yuchen Liang, Brian L. Price, Scott D. Cohen, and Thomas S. Huang. Youtube-vos: Sequence-to-sequence video object segmentation. In ECCV , 2018a.
Xu et al. (2018b) N. Xu, L. Yang, Yuchen Fan, Dingcheng Yue, Yuchen Liang, Jianchao Yang, and Thomas S. Huang. Youtube-vos: A large-scale video object segmentation benchmark. ArXiv , abs/1809.03327, 2018b.
Yang et al. (2023) Jinyu Yang, Mingqi Gao, Zhe Li, Shang Gao, Fangjing Wang, and Feng Zheng. Track anything: Segment anything meets videos. arXiv preprint arXiv:2304.11968 , 2023.
Yang et al. (2018) L. Yang, Yanran Wang, Xuehan Xiong, Jianchao Yang, and Aggelos K. Katsaggelos. Efficient video object segmentation via network modulation. CVPR , pp. 6499–6507, 2018.
Yang et al. (2021a) Lei Yang, Yan Zi Wei, Yisheng HE, Wei Sun, Zhenhang Huang, Haibin Huang, and Haoqiang Fan. iShape: A first step towards irregular shape instance segmentation. arXiv:2109.15068 , 2021a.
Yang & Yang (2022) Zongxin Yang and Yi Yang. Decoupling features in hierarchical propagation for video object segmentation. In NeurIPS , 2022.
Yang et al. (2020) Zongxin Yang, Yunchao Wei, and Yi Yang. Collaborative video object segmentation by foreground-background integration. In ECCV , 2020.
Yang et al. (2021b) Zongxin Yang, Yunchao Wei, and Yi Yang. Associating objects with transformers for video object segmentation. In NeurIPS , 2021b.
Yang et al. (2024) Zongxin Yang, Jiaxu Miao, Yunchao Wei, Wenguan Wang, Xiaohan Wang, and Yi Yang. Scalable video object segmentation with identification mechanism. TPAMI , 2024.
Yogamani et al. (2019) Senthil Yogamani, Ciarán Hughes, Jonathan Horgan, Ganesh Sistu, Padraig Varley, Derek O’Dea, Michal Uricár, Stefan Milz, Martin Simon, Karl Amende, et al. WoodScape: A multi-task, multi-camera fisheye dataset for autonomous driving. ICCV , 2019.
Yoon et al. (2017) Jae Shin Yoon, François Rameau, Junsik Kim, Seokju Lee, Seunghak Shin, and In-So Kweon. Pixel-level matching for video object segmentation using convolutional neural networks. ICCV , pp. 2186–2195, 2017.
Zhai et al. (2022) Xiaohua Zhai, Alexander Kolesnikov, Neil Houlsby, and Lucas Beyer. Scaling vision transformers. In CVPR , pp. 12104–12113, 2022.
Zhang et al. (2023a) Chaoning Zhang, Dongshen Han, Yu Qiao, Jung Uk Kim, Sung-Ho Bae, Seungkyu Lee, and Choong Seon Hong. Faster segment anything: Towards lightweight sam for mobile applications, 2023a.
Zhang et al. (2023b) Jiaming Zhang, Yutao Cui, Gangshan Wu, and Limin Wang. Joint modeling of feature, correspondence, and a compressed memory for video object segmentation. ArXiv , abs/2308.13505, 2023b.
Zhang et al. (2022) Lingzhi Zhang, Shenghao Zhou, Simon Stent, and Jianbo Shi. Fine-grained egocentric hand-object segmentation: Dataset, model, and applications. ECCV , 2022.
Zhao et al. (2023) Xu Zhao, Wenchao Ding, Yongqi An, Yinglong Du, Tao Yu, Min Li, Ming Tang, and Jinqiao Wang. Fast segment anything, 2023.
Zhou et al. (2019) Bolei Zhou, Hang Zhao, Xavier Puig, Tete Xiao, Sanja Fidler, Adela Barriuso, and Antonio Torralba. Semantic understanding of scenes through the ADE20K dataset. IJCV , 2019.