Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks
Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks
面向知识密集型 NLP 任务的检索增强生成
Patrick Lewis Email: plewis@fb.com Ethan Perez ⋆ Aleksandra Piktus † , Fabio Petroni † , Vladimir Karpukhin † , Naman Goyal † , Heinrich Küttler † Mike Lewis † Wen-tau Yih † Tim Rocktäschel Sebastian Riedel Douwe Kiela † † Facebook AI Research; ‡ University College London; ⋆ New York University
Abstract
摘要
Large pre-trained language models have been shown to store factual knowledge in their parameters, and achieve state-of-the-art results when fine-tuned on downstream NLP tasks. However, their ability to access and precisely manipulate knowledge is still limited, and hence on knowledge-intensive tasks, their performance lags behind task-specific architectures. Additionally, providing provenance for their decisions and updating their world knowledge remain open research problems. Pre-trained models with a differentiable access mechanism to explicit non-parametric memory have so far been only investigated for extractive downstream tasks. We explore a general-purpose fine-tuning recipe for retrieval-augmented generation (RAG) — models which combine pre-trained parametric and non-parametric memory for language generation. We introduce RAG models where the parametric memory is a pre-trained seq2seq model and the non-parametric memory is a dense vector index of Wikipedia, accessed with a pre-trained neural retriever. We compare two RAG formulations, one which conditions on the same retrieved passages across the whole generated sequence, and another which can use different passages per token. We fine-tune and evaluate our models on a wide range of knowledge-intensive NLP tasks and set the state of the art on three open domain QA tasks, outperforming parametric seq2seq models and task-specific retrieve-and-extract architectures. For language generation tasks, we find that RAG models generate more specific, diverse and factual language than a state-of-the-art parametric-only seq2seq baseline.
大规模预训练语言模型已被证明能把事实知识存进参数,并在下游 NLP 任务微调后达到当时最优水平。然而它们访问与精确操纵知识的能力仍有限,因此在知识密集型任务上,表现落后于任务专用架构。此外,如何为决策提供出处、如何更新世界知识,仍是开放问题。带可微访问机制、显式非参数记忆的预训练模型,此前主要只在抽取式下游任务上被研究。我们探索一种通用的检索增强生成(RAG)微调配方——把预训练的参数记忆与非参数记忆结合起来做语言生成。我们引入的 RAG 模型以预训练 seq2seq 为参数记忆,以维基百科的稠密向量索引为非参数记忆,并用预训练神经检索器访问。我们比较两种 RAG 形式:一种在整段生成中条件于同一批检索段落;另一种允许每个 token 使用不同段落。我们在一系列知识密集型 NLP 任务上微调并评估,在三个开放域问答任务上刷新当时最优,超过纯参数 seq2seq 与任务专用的“检索再抽取”架构。在语言生成任务上,我们发现 RAG 比当时最优的纯参数 seq2seq 基线生成更具体、更多样、也更符合事实的文本。
1 Introduction
1 引言
Pre-trained neural language models have been shown to learn a substantial amount of in-depth knowledge from data [47]. They can do so without any access to an external memory, as a parameterized implicit knowledge base [51, 52]. While this development is exciting, such models do have downsides: They cannot easily expand or revise their memory, can’t straightforwardly provide insight into their predictions, and may produce “hallucinations” [38]. Hybrid models that combine parametric memory with non-parametric (i.e., retrieval-based) memories [20, 26, 48] can address some of these issues because knowledge can be directly revised and expanded, and accessed knowledge can be inspected and interpreted. REALM [20] and ORQA [31], two recently introduced models that combine masked language models [8] with a differentiable retriever, have shown promising results, but have only explored open-domain extractive question answering. Here, we bring hybrid parametric and non-parametric memory to the “workhorse of NLP,” i.e. sequence-to-sequence (seq2seq) models.
预训练神经语言模型已被证明能从数据中学到大量深层知识 [47]。它们无需访问外部记忆,就能充当参数化的隐式知识库 [51, 52]。这一进展令人振奋,但也有代价:记忆不易扩展或修订,难以直接解释预测,还可能产生“幻觉” [38]。把参数记忆与非参数(即基于检索的)记忆结合起来的混合模型 [20, 26, 48] 能缓解部分问题——知识可以直接修订与扩展,被访问的知识也可检查与解释。REALM [20] 与 ORQA [31] 等近期工作把掩码语言模型 [8] 与可微检索器结合,结果可观,但只探索了开放域抽取式问答。本文把混合的参数与非参数记忆带到 NLP 的“主力”——序列到序列(seq2seq)模型上。
We endow pre-trained, parametric-memory generation models with a non-parametric memory through a general-purpose fine-tuning approach which we refer to as retrieval-augmented generation (RAG). We build RAG models where the parametric memory is a pre-trained seq2seq transformer, and the non-parametric memory is a dense vector index of Wikipedia, accessed with a pre-trained neural retriever. We combine these components in a probabilistic model trained end-to-end (Fig. 1). The retriever (Dense Passage Retriever [26], henceforth DPR) provides latent documents conditioned on the input, and the seq2seq model (BART [32]) then conditions on these latent documents together with the input to generate the output. We marginalize the latent documents with a top-K approximation, either on a per-output basis (assuming the same document is responsible for all tokens) or a per-token basis (where different documents are responsible for different tokens). Like T5 [51] or BART, RAG can be fine-tuned on any seq2seq task, whereby both the generator and retriever are jointly learned.
我们通过一种通用微调方法,给带参数记忆的预训练生成模型配上非参数记忆,称之为检索增强生成(RAG)。构建时,参数记忆是预训练 seq2seq Transformer,非参数记忆是维基百科的稠密向量索引,由预训练神经检索器访问。我们把这些组件放进端到端训练的概率模型(图 1)。检索器(Dense Passage Retriever [26],下文称 DPR)按输入给出潜在文档,seq2seq 模型(BART [32])再条件于这些潜在文档与输入来生成输出。我们对潜在文档做 top-K 近似边缘化:既可以按整段输出(假定同一文档负责所有 token),也可以按 token(不同文档负责不同 token)。与 T5 [51] 或 BART 一样,RAG 可在任意 seq2seq 任务上微调,生成器与检索器联合学习。
There has been extensive previous work proposing architectures to enrich systems with non-parametric memory which are trained from scratch for specific tasks, e.g. memory networks [64, 55], stack-augmented networks [25] and memory layers [30]. In contrast, we explore a setting where both parametric and non-parametric memory components are pre-trained and pre-loaded with extensive knowledge. Crucially, by using pre-trained access mechanisms, the ability to access knowledge is present without additional training.
此前有大量工作提出用非参数记忆丰富系统、并从零为特定任务训练的架构,例如记忆网络 [64, 55]、栈增强网络 [25] 与记忆层 [30]。我们则探索另一种设定:参数与非参数记忆组件都已预训练,并预装了大量知识。关键在于,借助预训练的访问机制,访问知识的能力在无需额外训练时就已具备。
Our results highlight the benefits of combining parametric and non-parametric memory with generation for knowledge-intensive tasks—tasks that humans could not reasonably be expected to perform without access to an external knowledge source. Our RAG models achieve state-of-the-art results on open Natural Questions [29], WebQuestions [3] and CuratedTrec [2] and strongly outperform recent approaches that use specialised pre-training objectives on TriviaQA [24]. Despite these being extractive tasks, we find that unconstrained generation outperforms previous extractive approaches. For knowledge-intensive generation, we experiment with MS-MARCO [1] and Jeopardy question generation, and we find that our models generate responses that are more factual, specific, and diverse than a BART baseline. For FEVER [56] fact verification, we achieve results within 4.3% of state-of-the-art pipeline models which use strong retrieval supervision. Finally, we demonstrate that the non-parametric memory can be replaced to update the models’ knowledge as the world changes.[^1]
结果凸显了:在知识密集型任务——人类若无外部知识源就难以合理完成的任务——上,把参数与非参数记忆与生成结合起来的好处。我们的 RAG 在开放 Natural Questions [29]、WebQuestions [3] 与 CuratedTrec [2] 上达到当时最优,并在 TriviaQA [24] 上明显超过使用专门预训练目标的近期方法。尽管这些是抽取式任务,我们发现无约束生成仍优于先前的抽取式方法。在知识密集型生成上,我们在 MS-MARCO [1] 与 Jeopardy 问题生成上实验,发现相对 BART 基线,模型回复更符合事实、更具体、也更多样。在 FEVER [56] 事实验证上,我们距使用强检索监督的流水线式当时最优模型不到 4.3%。最后,我们展示可用替换非参数记忆来更新模型的世界知识。[^1]
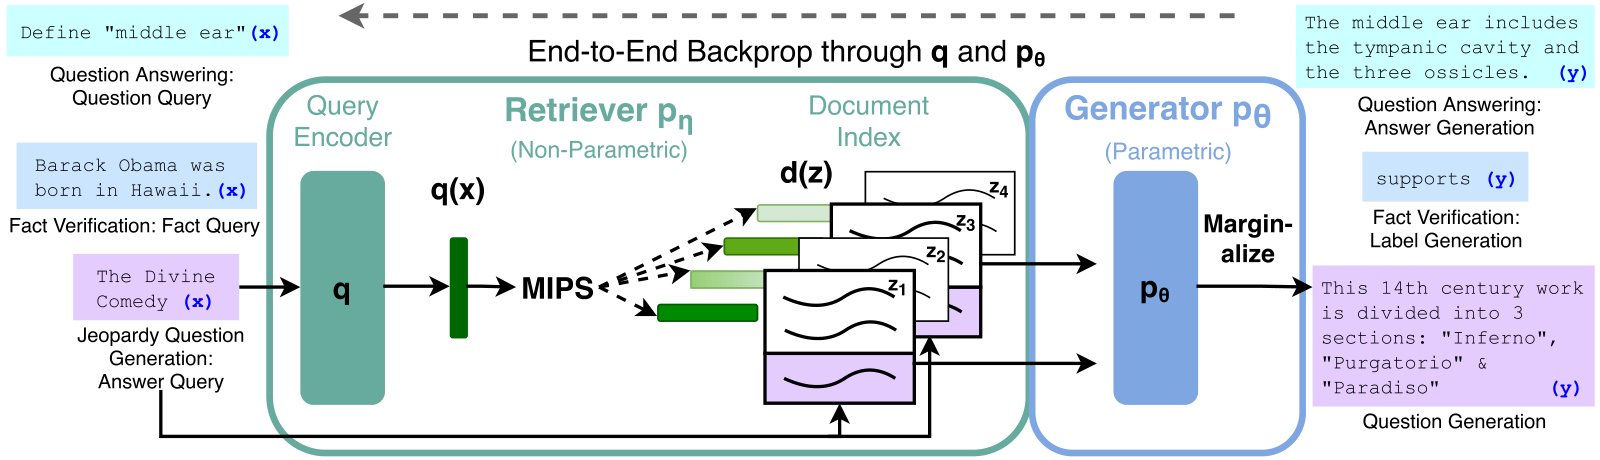
Figure 1: Overview of our approach. We combine a pre-trained retriever (Query Encoder + Document Index) with a pre-trained seq2seq model (Generator) and fine-tune end-to-end. For query , we use Maximum Inner Product Search (MIPS) to find the top-K documents . For final prediction , we treat as a latent variable and marginalize over seq2seq predictions given different documents.
图 1:方法概览。我们把预训练检索器(查询编码器 + 文档索引)与预训练 seq2seq 模型(生成器)结合起来端到端微调。对查询 ,用最大内积搜索(MIPS)找 top-K 文档 。最终预测 时,把 当作潜变量,对不同文档下的 seq2seq 预测做边缘化。
2 Methods
2 方法
We explore RAG models, which use the input sequence to retrieve text documents and use them as additional context when generating the target sequence . As shown in Figure 1, our models leverage two components: (i) a retriever with parameters that returns (top-K truncated) distributions over text passages given a query and (ii) a generator parametrized by that generates a current token based on a context of the previous tokens , the original input and a retrieved passage .
我们探索的 RAG 模型用输入序列 检索文本文档 ,并在生成目标序列 时把它们当作额外上下文。如图 1,模型有两块:(i) 检索器 ,参数为 ,在给定查询 时返回(经 top-K 截断的)文本段落分布;(ii) 生成器 ,参数为 ,基于前 个 token 、原始输入 与检索段落 生成当前 token。
To train the retriever and generator end-to-end, we treat the retrieved document as a latent variable. We propose two models that marginalize over the latent documents in different ways to produce a distribution over generated text. In one approach, RAG-Sequence, the model uses the same document to predict each target token. The second approach, RAG-Token, can predict each target token based on a different document. In the following, we formally introduce both models and then describe the and components, as well as the training and decoding procedure.
为端到端训练检索器与生成器,我们把检索到的文档当作潜变量。我们提出两种模型,以不同方式对潜在文档边缘化,得到生成文本的分布。一种是 RAG-Sequence:用同一文档预测每个目标 token。另一种是 RAG-Token:每个目标 token 可以基于不同文档预测。下文先形式化两种模型,再分别说明 与 ,以及训练与解码流程。
2.1 Models
2.1 模型
RAG-Sequence Model
The RAG-Sequence model uses the same retrieved document to generate the complete sequence. Technically, it treats the retrieved document as a single latent variable that is marginalized to get the seq2seq probability via a top-K approximation. Concretely, the top K documents are retrieved using the retriever, and the generator produces the output sequence probability for each document, which are then marginalized,
RAG-Sequence 模型
RAG-Sequence 用同一篇检索文档生成完整序列。技术上,它把检索文档当作单一潜变量,经 top-K 近似边缘化得到 seq2seq 概率 。具体地,检索器取出 top K 文档,生成器为每篇文档产生输出序列概率,再边缘化,
RAG-Token Model
In the RAG-Token model we can draw a different latent document for each target token and marginalize accordingly. This allows the generator to choose content from several documents when producing an answer. Concretely, the top K documents are retrieved using the retriever, and then the generator produces a distribution for the next output token for each document, before marginalizing, and repeating the process with the following output token, Formally, we define:
RAG-Token 模型
在 RAG-Token 中,每个目标token 可以抽取不同的潜在文档并相应边缘化。这样生成器在产出答案时可以从多篇文档选内容。具体地,检索器取出 top K 文档,生成器再对每篇文档产生下一输出 token 的分布,边缘化后,对后续输出 token 重复该过程。形式上:
Finally, we note that RAG can be used for sequence classification tasks by considering the target class as a target sequence of length one, in which case RAG-Sequence and RAG-Token are equivalent.
最后需说明:RAG 也可用于序列分类——把目标类别当作长度为 1 的目标序列,此时 RAG-Sequence 与 RAG-Token 等价。
2.2 Retriever: DPR
2.2 检索器:DPR
The retrieval component is based on DPR [26]. DPR follows a bi-encoder architecture:
检索组件 基于 DPR [26]。DPR 采用双编码器架构:
where is a dense representation of a document produced by a BERTBASE document encoder [8], and a query representation produced by a query encoder, also based on BERTBASE. Calculating , the list of documents with highest prior probability , is a Maximum Inner Product Search (MIPS) problem, which can be approximately solved in sub-linear time [23]. We use a pre-trained bi-encoder from DPR to initialize our retriever and to build the document index. This retriever was trained to retrieve documents which contain answers to TriviaQA [24] questions and Natural Questions [29]. We refer to the document index as the non-parametric memory.
其中 是 BERTBASE 文档编码器 [8] 产出的文档稠密表示, 是同样基于 BERTBASE 的 查询编码器 产出的查询表示。计算 ,即先验 最高的 篇文档,是最大内积搜索(MIPS)问题,可在次线性时间内近似求解 [23]。我们用 DPR 的预训练双编码器初始化检索器并构建文档索引。该检索器曾被训练为检索包含 TriviaQA [24] 与 Natural Questions [29] 答案的文档。我们把文档索引称为非参数记忆。
2.3 Generator: BART
2.3 生成器:BART
The generator component could be modelled using any encoder-decoder. We use BART-large [32], a pre-trained seq2seq transformer [58] with 400M parameters. To combine the input with the retrieved content when generating from BART, we simply concatenate them. BART was pre-trained using a denoising objective and a variety of different noising functions. It has obtained state-of-the-art results on a diverse set of generation tasks and outperforms comparably-sized T5 models [32]. We refer to the BART generator parameters as the parametric memory henceforth.
生成器 可用任意编码器—解码器建模。我们采用 BART-large [32],这是一个约 4 亿参数的预训练 seq2seq Transformer [58]。从 BART 生成时,把输入 与检索内容 简单拼接即可。BART 用去噪目标与多种噪声函数预训练,在多种生成任务上达到当时最优,并优于同规模 T5 [32]。下文把 BART 生成器参数 称为参数记忆。
2.4 Training
2.4 训练
We jointly train the retriever and generator components without any direct supervision on what document should be retrieved. Given a fine-tuning training corpus of input/output pairs , we minimize the negative marginal log-likelihood of each target, using stochastic gradient descent with Adam [28]. Updating the document encoder during training is costly as it requires the document index to be periodically updated as REALM does during pre-training [20]. We do not find this step necessary for strong performance, and keep the document encoder (and index) fixed, only fine-tuning the query encoder and the BART generator.
我们联合训练检索器与生成器,不对“该检索哪篇文档”做直接监督。给定微调语料中的输入/输出对 ,用 Adam [28] 随机梯度下降最小化每个目标的负边缘对数似然 。训练中更新文档编码器 代价很高,因为需要像 REALM 预训练那样周期性更新文档索引 [20]。我们发现这一步对强性能并非必要,因而固定文档编码器(与索引),只微调查询编码器 与 BART 生成器。
2.5 Decoding
2.5 解码
At test time, RAG-Sequence and RAG-Token require different ways to approximate .
测试时,RAG-Sequence 与 RAG-Token 需要不同方式近似 。
RAG-Token
The RAG-Token model can be seen as a standard, autoregressive seq2seq generator with transition probability: To decode, we can plug into a standard beam decoder.
RAG-Token
RAG-Token 可视为标准自回归 seq2seq 生成器,转移概率为:。解码时,把 代入标准束搜索即可。
RAG-Sequence
For RAG-Sequence, the likelihood does not break into a conventional per- token likelihood, hence we cannot solve it with a single beam search. Instead, we run beam search for each document , scoring each hypothesis using . This yields a set of hypotheses , some of which may not have appeared in the beams of all documents. To estimate the probability of an hypothesis we run an additional forward pass for each document for which does not appear in the beam, multiply generator probability with and then sum the probabilities across beams for the marginals. We refer to this decoding procedure as “Thorough Decoding.” For longer output sequences, can become large, requiring many forward passes. For more efficient decoding, we can make a further approximation that where was not generated during beam search from . This avoids the need to run additional forward passes once the candidate set has been generated. We refer to this decoding procedure as “Fast Decoding.”
RAG-Sequence
对 RAG-Sequence,似然 不能拆成常规的逐 token 似然,因而无法用单次束搜索求解。我们改为对每篇文档 跑束搜索,用 给假设打分,得到假设集合 ,其中有些可能并未出现在所有文档的束中。为估计假设 的概率,对那些束中未出现 的文档 再跑一次前向,把生成器概率乘以 ,再跨束求和得到边缘概率。我们称这种解码为“Thorough Decoding(详尽解码)”。输出序列较长时 会变大,需要很多次前向。为更高效,可进一步近似:若 在从 的束搜索中未被生成,则 。候选集 生成后就不必再跑额外前向。我们称其为“Fast Decoding(快速解码)”。
3 Experiments
3 实验
We experiment with RAG in a wide range of knowledge-intensive tasks. For all experiments, we use a single Wikipedia dump for our non-parametric knowledge source. Following [31] and [26], we use the December 2018 dump. Each Wikipedia article is split into disjoint 100-word chunks, to make a total of 21M documents. We use the document encoder to compute an embedding for each document, and build a single MIPS index using FAISS [23] with a Hierarchical Navigable Small World approximation for fast retrieval [37]. During training, we retrieve the top documents for each query. We consider for training and set for test time using dev data. We now discuss experimental details for each task.
我们在广泛的知识密集型任务上实验 RAG。所有实验共用一份维基百科转储作为非参数知识源。沿用 [31] 与 [26],我们使用 2018 年 12 月转储。每篇文章切成互不重叠的 100 词块,共约 2100 万文档。用文档编码器为每篇文档算嵌入,并用 FAISS [23] 构建单一 MIPS 索引,配合 Hierarchical Navigable Small World 近似以实现快速检索 [37]。训练时对每个查询检索 top 文档。训练取 ,测试时的 用开发集选定。下文分任务说明实验细节。
3.1 Open-domain Question Answering
3.1 开放域问答
Open-domain question answering (QA) is an important real-world application and common testbed for knowledge-intensive tasks [20]. We treat questions and answers as input-output text pairs and train RAG by directly minimizing the negative log-likelihood of answers. We compare RAG to the popular extractive QA paradigm [5, 7, 31, 26], where answers are extracted spans from retrieved documents, relying primarily on non-parametric knowledge. We also compare to “Closed-Book QA” approaches [52], which, like RAG, generate answers, but which do not exploit retrieval, instead relying purely on parametric knowledge. We consider four popular open-domain QA datasets: Natural Questions (NQ) [29], TriviaQA (TQA) [24]. WebQuestions (WQ) [3] and CuratedTrec (CT) [2]. As CT and WQ are small, we follow DPR [26] by initializing CT and WQ models with our NQ RAG model. We use the same train/dev/test splits as prior work [31, 26] and report Exact Match (EM) scores. For TQA, to compare with T5 [52], we also evaluate on the TQA Wiki test set.
开放域问答(QA)是重要的现实应用,也是知识密集型任务的常用试验台 [20]。我们把问题与答案当作输入—输出文本对 ,直接最小化答案的负对数似然来训练 RAG。我们与流行的抽取式 QA 范式 [5, 7, 31, 26] 比较——答案是检索文档中的片段,主要依赖非参数知识;也与“闭卷 QA”方法 [52] 比较——同样生成答案,但不做检索,纯靠参数知识。我们考虑四个常用开放域 QA 数据集:Natural Questions (NQ) [29]、TriviaQA (TQA) [24]、WebQuestions (WQ) [3] 与 CuratedTrec (CT) [2]。CT 与 WQ 较小,我们按 DPR [26] 用 NQ 上的 RAG 模型初始化。划分与先前工作 [31, 26] 一致,报告 Exact Match(EM)。对 TQA,为与 T5 [52] 对比,也在 TQA Wiki 测试集上评估。
3.2 Abstractive Question Answering
3.2 摘要式问答
RAG models can go beyond simple extractive QA and answer questions with free-form, abstractive text generation. To test RAG’s natural language generation (NLG) in a knowledge-intensive setting, we use the MSMARCO NLG task v2.1 [43]. The task consists of questions, ten gold passages retrieved from a search engine for each question, and a full sentence answer annotated from the retrieved passages. We do not use the supplied passages, only the questions and answers, to treat MSMARCO as an open-domain abstractive QA task. MSMARCO has some questions that cannot be answered in a way that matches the reference answer without access to the gold passages, such as “What is the weather in Volcano, CA?” so performance will be lower without using gold passages. We also note that some MSMARCO questions cannot be answered using Wikipedia alone. Here, RAG can rely on parametric knowledge to generate reasonable responses.
RAG 可超越简单抽取式 QA,用自由形式的摘要式文本生成来回答。为在知识密集型设定下测试 RAG 的自然语言生成(NLG),我们使用 MSMARCO NLG 任务 v2.1 [43]。该任务包含问题、每个问题由搜索引擎检索的十条金标段落,以及基于检索段落标注的整句答案。我们不用所给段落,只用问题与答案,把 MSMARCO 当作开放域摘要式 QA。有些 MSMARCO 问题若不看金标段落就无法生成与参考答案匹配的回答,例如“What is the weather in Volcano, CA?”,因此不用金标段落时分数会偏低。我们也注意到,有些问题单靠维基百科无法回答;此时 RAG 可依赖参数知识给出合理回复。
3.3 Jeopardy Question Generation
3.3 Jeopardy 问题生成
To evaluate RAG’s generation abilities in a non-QA setting, we study open-domain question generation. Rather than use questions from standard open-domain QA tasks, which typically consist of short, simple questions, we propose the more demanding task of generating Jeopardy questions. Jeopardy is an unusual format that consists of trying to guess an entity from a fact about that entity. For example, “The World Cup” is the answer to the question “In 1986 Mexico scored as the first country to host this international sports competition twice.” As Jeopardy questions are precise, factual statements, generating Jeopardy questions conditioned on their answer entities constitutes a challenging knowledge-intensive generation task.
为在非 QA 设定下评估 RAG 的生成能力,我们研究开放域问题生成。不用标准开放域 QA 中通常简短的问题,我们提出更难的任务:生成 Jeopardy 问题。Jeopardy 的形式特殊——根据关于某实体的事实去猜该实体。例如,“The World Cup”对应问题“In 1986 Mexico scored as the first country to host this international sports competition twice.”。Jeopardy 问题是精确的事实陈述,以答案实体为条件生成 Jeopardy 问题,构成具有挑战性的知识密集型生成任务。
We use the splits from SearchQA [10], with 100K train, 14K dev, and 27K test examples. As this is a new task, we train a BART model for comparison. Following [67], we evaluate using the SQuAD-tuned Q-BLEU-1 metric [42]. Q-BLEU is a variant of BLEU with a higher weight for matching entities and has higher correlation with human judgment for question generation than standard metrics. We also perform two human evaluations, one to assess generation factuality, and one for specificity. We define factuality as whether a statement can be corroborated by trusted external sources, and specificity as high mutual dependence between the input and output [33]. We follow best practice and use pairwise comparative evaluation [34]. Evaluators are shown an answer and two generated questions, one from BART and one from RAG. They are then asked to pick one of four options—quuestion A is better, question B is better, both are good, or neither is good.
我们使用 SearchQA [10] 的划分:训练集 10 万、开发集 1.4 万、测试集 2.7 万。因是新任务,另训一个 BART 作对比。沿用 [67],用经 SQuAD 调参的 Q-BLEU-1 [42] 评估。Q-BLEU 是提高实体匹配权重的 BLEU 变体,与问题生成上的人类判断相关性高于标准指标。我们还做两项人工评估:事实性与具体性。事实性定义为陈述能否被可信外部来源证实;具体性定义为输入与输出之间的高互依赖 [33]。我们按最佳实践做成对比较评估 [34]。评估者看到一个答案与两个生成问题(分别来自 BART 与 RAG),再从四个选项中选一:问题 A 更好、问题 B 更好、两者都好、或两者都不好。
3.4 Fact Verification
3.4 事实验证
FEVER [56] requires classifying whether a natural language claim is supported or refuted by Wikipedia, or whether there is not enough information to decide. The task requires retrieving evidence from Wikipedia relating to the claim and then reasoning over this evidence to classify whether the claim is true, false, or unverifiable from Wikipedia alone. FEVER is a retrieval problem coupled with an challenging entailment reasoning task. It also provides an appropriate testbed for exploring the RAG models’ ability to handle classification rather than generation. We map FEVER class labels (supports, refutes, or not enough info) to single output tokens and directly train with claim-class pairs. Crucially, unlike most other approaches to FEVER, we do not use supervision on retrieved evidence. In many real-world applications, retrieval supervision signals aren’t available, and models that do not require such supervision will be applicable to a wider range of tasks. We explore two variants: the standard 3-way classification task (supports/refutes/not enough info) and the 2-way (supports/refutes) task studied in [57]. In both cases we report label accuracy.
FEVER [56] 要求判断自然语言论断是否被维基百科支持或反驳,或信息不足无法判定。任务需要从维基百科检索与论断相关的证据,再推理分类论断为真、假,或仅凭维基百科不可验证。FEVER 是检索问题与具有挑战性的蕴含推理的结合,也适合检验 RAG 做分类而非生成的能力。我们把 FEVER 类别标签(supports、refutes 或 not enough info)映射为单输出 token,直接用论断—类别对训练。关键是:与多数 FEVER 方法不同,我们不用检索证据上的监督。许多现实应用没有检索监督信号,不依赖这类监督的模型适用范围更广。我们探索两种变体:标准三分类(supports/refutes/not enough info),以及 [57] 研究的二分类(supports/refutes)。均报告标签准确率。
4 Results
4 结果
| Model | NQ | TQA | WQ | CT | ||
|---|---|---|---|---|---|---|
| Closed Book | T5-11B [52] | 34.5 | - / | 50.1 | 37.4 | - |
| T5-11B+SSM[52] | 36.6 | - / | 60.5 | 44.7 | - | |
| Open Book | REALM [20] | 40.4 | - / | - | 40.7 | 46.8 |
| DPR [26] | 41.5 | 57.9 / | - | 41.1 | 50.6 | |
| RAG-Token | 44.1 | 55.2 / | 66.1 | 45.5 | 50.0 | |
| RAG-Seq. | 44.5 | 56.8 / | 68.0 | 45.2 | 52.2 |
| Model | Jeopardy | MSMARCO | FVR3 | FVR2 | ||
|---|---|---|---|---|---|---|
| B-1 | QB-1 | R-L | B-1 | Label Acc. | ||
| SotA | - | - | 49.8* | 49.9* | 76.8 | 92.2* |
| BART | 15.1 | 19.7 | 38.2 | 41.6 | 64.0 | 81.1 |
| RAG-Tok. | 17.3 | 22.2 | 40.1 | 41.5 | 72.5 | 89.5 |
| RAG-Seq. | 14.7 | 21.4 | 40.8 | 44.2 |
Table 1: Open-Domain QA Test Scores. For TQA, left column uses the standard test set for Open- Domain QA, right column uses the TQA-Wiki test set. See Appendix D for further details.
| Model | NQ | TQA | WQ | CT | ||
|---|---|---|---|---|---|---|
| Closed Book | T5-11B [52] | 34.5 | - / | 50.1 | 37.4 | - |
| T5-11B+SSM[52] | 36.6 | - / | 60.5 | 44.7 | - | |
| Open Book | REALM [20] | 40.4 | - / | - | 40.7 | 46.8 |
| DPR [26] | 41.5 | 57.9 / | - | 41.1 | 50.6 | |
| RAG-Token | 44.1 | 55.2 / | 66.1 | 45.5 | 50.0 | |
| RAG-Seq. | 44.5 | 56.8 / | 68.0 | 45.2 | 52.2 |
| Model | Jeopardy | MSMARCO | FVR3 | FVR2 | ||
|---|---|---|---|---|---|---|
| B-1 | QB-1 | R-L | B-1 | Label Acc. | ||
| SotA | - | - | 49.8* | 49.9* | 76.8 | 92.2* |
| BART | 15.1 | 19.7 | 38.2 | 41.6 | 64.0 | 81.1 |
| RAG-Tok. | 17.3 | 22.2 | 40.1 | 41.5 | 72.5 | 89.5 |
| RAG-Seq. | 14.7 | 21.4 | 40.8 | 44.2 |
表 1:开放域 QA 测试分数。对 TQA,左列为开放域 QA 常用测试集,右列为 TQA-Wiki 测试集。更多细节见附录 D。
4.1 Open-domain Question Answering
4.1 开放域问答
Table 2 shows results for RAG along with state-of-the-art models. On all four open-domain QA tasks, RAG sets a new state of the art (only on the T5-comparable split for TQA). RAG combines the generation flexibility of the “closed-book” (parametric only) approaches and the performance of "open-book" retrieval-based approaches. Unlike REALM and T5+SSM, RAG enjoys strong results without expensive, specialized “salient span masking” pre-training [20]. It is worth noting that RAG’s retriever is initialized using DPR’s retriever, which uses retrieval supervision on Natural Questions and TriviaQA. RAG compares favourably to the DPR QA system, which uses a BERT-based “cross-encoder” to re-rank documents, along with an extractive reader. RAG demonstrates that neither a re-ranker nor extractive reader is necessary for state-of-the-art performance.
表 2 给出 RAG 与当时最优模型的结果。在全部四个开放域 QA 任务上,RAG 刷新最优(TQA 仅在与 T5 可比的划分上)。RAG 兼具“闭卷”(纯参数)方法的生成灵活性与“开卷”检索方法的性能。与 REALM 和 T5+SSM 不同,RAG 无需昂贵、专门的“显著跨度掩码”预训练也能取得强结果 [20]。需指出,RAG 的检索器用 DPR 检索器初始化,后者在 Natural Questions 与 TriviaQA 上用了检索监督。RAG 相对 DPR QA 系统表现良好——后者用基于 BERT 的“交叉编码器”重排文档,再配抽取式阅读器。RAG 表明:要达到当时最优,重排器与抽取式阅读器都非必需。
There are several advantages to generating answers even when it is possible to extract them. Documents with clues about the answer but do not contain the answer verbatim can still contribute towards a correct answer being generated, which is not possible with standard extractive approaches, leading to more effective marginalization over documents. Furthermore, RAG can generate correct answers even when the correct answer is not in any retrieved document, achieving 11.8% accuracy in such cases for NQ, where an extractive model would score 0%.
即便答案本可抽取,生成仍有若干优势。文档若只含线索而不含 verbatim 答案,仍可贡献于生成正确答案,这是标准抽取式方法做不到的,从而使跨文档边缘化更有效。此外,即便正确答案不在任何检索文档中,RAG 仍可生成正确答——在 NQ 上这类情形准确率达 11.8%,抽取式模型则为 0%。
4.2 Abstractive Question Answering
4.2 摘要式问答
As shown in Table 2, RAG-Sequence outperforms BART on Open MS-MARCO NLG by 2.6 Bleu points and 2.6 Rouge-L points. RAG approaches state-of-the-art model performance, which is impressive given that (i) those models access gold passages with specific information required to generate the reference answer , (ii) many questions are unanswerable without the gold passages, and (iii) not all questions are answerable from Wikipedia alone. Table 3 shows some generated answers from our models. Qualitatively, we find that RAG models hallucinate less and generate factually correct text more often than BART. Later, we also show that RAG generations are more diverse than BART generations (see §4.5).
如表 2,RAG-Sequence 在 Open MS-MARCO NLG 上相对 BART 高 2.6 Bleu 与 2.6 Rouge-L。RAG 接近当时最优模型的表现——考虑到:(i) 那些模型能访问含生成参考答案所需信息的金标段落;(ii) 许多问题没有金标段落就无法回答;(iii) 并非所有问题单靠维基百科可答——这已很可观。表 3 给出若干生成样例。定性上,我们发现 RAG 比 BART 更少幻觉、更常生成事实正确的文本。后文还显示 RAG 的生成多样性高于 BART(见 §4.5)。
4.3 Jeopardy Question Generation
4.3 Jeopardy 问题生成
Table 2 shows that RAG-Token performs better than RAG-Sequence on Jeopardy question generation, with both models outperforming BART on Q-BLEU-1. 5 shows human evaluation results, over 452 pairs of generations from BART and RAG-Token. Evaluators indicated that BART was more factual than RAG in only 7.1% of cases, while RAG was more factual in 42.7% of cases, and both RAG and BART were factual in a further 17% of cases, clearly demonstrating the effectiveness of RAG on the task over a state-of-the-art generation model. Evaluators also find RAG generations to be more specific by a large margin. Table 3 shows typical generations from each model.
表 2 显示:在 Jeopardy 问题生成上 RAG-Token 优于 RAG-Sequence,两者在 Q-BLEU-1 上都超过 BART。表 5 给出人工评估:对 452 对来自 BART 与 RAG-Token 的生成。评估者认为 BART 比 RAG 更符合事实的仅占 7.1%,RAG 更符合事实的占 42.7%,另有 17% 两者都符合事实,清楚表明 RAG 相对当时最优生成模型在该任务上的有效性。评估者也认为 RAG 生成在具体性上大幅领先。表 3 给出各模型的典型生成。
Jeopardy questions often contain two separate pieces of information, and RAG-Token may perform best because it can generate responses that combine content from several documents. Figure 2 shows an example. When generating “Sun”, the posterior is high for document 2 which mentions “The Sun Also Rises”. Similarly, document 1 dominates the posterior when “A Farewell to Arms” is generated. Intriguingly, after the first token of each book is generated, the document posterior flattens. This observation suggests that the generator can complete the titles without depending on specific documents. In other words, the model’s parametric knowledge is sufficient to complete the titles. We find evidence for this hypothesis by feeding the BART-only baseline with the partial decoding "The Sun. BART completes the generation "The Sun Also Rises" is a novel by this author of "The Sun Also Rises" indicating the title "The Sun Also Rises" is stored in BART’s parameters. Similarly, BART will complete the partial decoding "The Sun Also Rises" is a novel by this author of "A with "The Sun Also Rises" is a novel by this author of "A Farewell to Arms". This example shows how parametric and non-parametric memories work together—the non-parametric component helps to guide the generation, drawing out specific knowledge stored in the parametric memory.
Jeopardy 问题常含两段独立信息,RAG-Token 可能因此表现最好——它能把多篇文档的内容组合进回复。图 2 给出一例。生成 “Sun” 时,提到 “The Sun Also Rises” 的文档 2 后验很高;生成 “A Farewell to Arms” 时文档 1 主导后验。有趣的是,每本书名的第一个 token 生成后,文档后验会变平。这表明生成器可以不依赖特定文档就补全书名,亦即参数知识足以补全书名。把仅含 BART 的基线喂入部分解码 “The Sun.”,BART 会补成 “The Sun Also Rises” is a novel by this author of "The Sun Also Rises",说明书名存在 BART 参数里。类似地,BART 会把 “The Sun Also Rises" is a novel by this author of "A 补成含 “A Farewell to Arms” 的句子。该例说明参数与非参数记忆如何协作——非参数组件引导生成,把参数记忆中存着的具体知识“勾”出来。
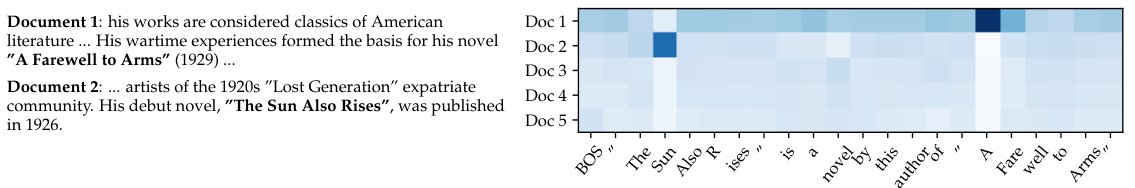
Figure 2: RAG-Token document posterior for each generated token for input “Hemingway" for Jeopardy generation with 5 retrieved documents. The posterior for document 1 is high when generating “A Farewell to Arms" and for document 2 when generating “The Sun Also Rises".
图 2:输入为 “Hemingway” 的 Jeopardy 生成中,RAG-Token 在每个生成 token 上对 5 篇检索文档的后验 。生成 “A Farewell to Arms” 时文档 1 后验高,生成 “The Sun Also Rises” 时文档 2 后验高。
| Task | Input | Model | Generation |
|---|---|---|---|
| MS-MARCO | define middle ear | BART | ?The middle ear is the part of the ear between the middle ear and the nose. |
| RAG-T | The middle ear is the portion of the ear internal to the eardrum. | ||
| RAG-S | The middle ear includes the tympanic cavity and the three ossicles. | ||
| what currency needed in scotland | BART | The currency needed in Scotland is Pound sterling. | |
| RAG-T | Pound is the currency needed in Scotland. | ||
| RAG-S | The currency needed in Scotland is the pound sterling. | ||
| Jeopardy Question Gener -ation | Washington | BART | ?This state has the largest number of counties in the U.S. |
| RAG-T | It’s the only U.S. state named for a U.S. president | ||
| RAG-S | It’s the state where you’ll find Mount Rainier National Park | ||
| The Divine Comedy | BART | *This epic poem by Dante is divided into 3 parts: the Inferno, the Purgatorio & the Purgatorio | |
| RAG-T | Dante’s "Inferno" is the first part of this epic poem | ||
| RAG-S | This 14th century work is divided into 3 sections: "Inferno", "Purgatorio" & "Paradiso" |
Table 3: Examples from generation tasks. RAG models generate more specific and factually accurate responses. ‘?’ indicates factually incorrect responses, * indicates partially correct responses.
| Task | Input | Model | Generation |
|---|---|---|---|
| MS-MARCO | define middle ear | BART | ?The middle ear is the part of the ear between the middle ear and the nose. |
| RAG-T | The middle ear is the portion of the ear internal to the eardrum. | ||
| RAG-S | The middle ear includes the tympanic cavity and the three ossicles. | ||
| what currency needed in scotland | BART | The currency needed in Scotland is Pound sterling. | |
| RAG-T | Pound is the currency needed in Scotland. | ||
| RAG-S | The currency needed in Scotland is the pound sterling. | ||
| Jeopardy Question Gener -ation | Washington | BART | ?This state has the largest number of counties in the U.S. |
| RAG-T | It’s the only U.S. state named for a U.S. president | ||
| RAG-S | It’s the state where you’ll find Mount Rainier National Park | ||
| The Divine Comedy | BART | *This epic poem by Dante is divided into 3 parts: the Inferno, the Purgatorio & the Purgatorio | |
| RAG-T | Dante’s "Inferno" is the first part of this epic poem | ||
| RAG-S | This 14th century work is divided into 3 sections: "Inferno", "Purgatorio" & "Paradiso" |
表 3:生成任务样例。RAG 模型生成更具体、事实更准的回复。“?” 表示事实错误,* 表示部分正确。
| Factuality | Specificity | |
|---|---|---|
| BART better | 7.1% | 16.8% |
| RAG better | 42.7% | 37.4% |
| Both good | 11.7% | 11.8% |
| Both poor | 17.7% | 6.9% |
| No majority | 20.8% | 20.1% |
| MSMARCO | Jeopardy QGen | |
|---|---|---|
| Gold | 89.6% | 90.0% |
| BART | 70.7% | 32.4% |
| RAG-Token | 77.8% | 46.8% |
| RAG-Seq. | 83.5% | 53.8% |
Table 4: Human assessments for the Jeopardy Question Generation Task.
| Factuality | Specificity | |
|---|---|---|
| BART better | 7.1% | 16.8% |
| RAG better | 42.7% | 37.4% |
| Both good | 11.7% | 11.8% |
| Both poor | 17.7% | 6.9% |
| No majority | 20.8% | 20.1% |
| MSMARCO | Jeopardy QGen | |
|---|---|---|
| Gold | 89.6% | 90.0% |
| BART | 70.7% | 32.4% |
| RAG-Token | 77.8% | 46.8% |
| RAG-Seq. | 83.5% | 53.8% |
表 4:Jeopardy 问题生成任务的人工评估。
4.4 Fact Verification
4.4 事实验证
Table 2 shows our results on FEVER. For 3-way classification, RAG scores are within 4.3% of state-of-the-art models, which are complex pipeline systems with domain-specific architectures and substantial engineering, trained using intermediate retrieval supervision, which RAG does not require. For 2-way classification, we compare against [57], who train RoBERTa [35] to classify the claim as true or false given the gold evidence sentence. RAG achieves an accuracy within 2.7% of this model, despite being supplied with only the claim and retrieving its own evidence. We also analyze whether documents retrieved by RAG correspond to documents annotated as gold evidence in FEVER. We calculate the overlap in article titles between the top documents retrieved by RAG and gold evidence annotations. We find that the top retrieved document is from a gold article in 71% of cases, and a gold article is present in the top 10 retrieved articles in 90% of cases.
表 2 给出 FEVER 结果。三分类上,RAG 距当时最优不到 4.3%——后者是复杂流水线,含领域专用架构与大量工程,并用中间检索监督,而 RAG 不需要。二分类上,我们与 [57] 比较:对方在给定金标证据句时用 RoBERTa [35] 把论断判真或假。RAG 仅凭论断自行检索证据,准确率距该模型不到 2.7%。我们还分析 RAG 检索文档是否对应 FEVER 标注的金标证据:计算 top 检索文档与金标证据在文章标题上的重叠。发现 top-1 检索来自金标文章的比例为 71%,top-10 中出现金标文章的比例为 90%。
4.5 Additional Results
4.5 补充结果
Generation Diversity
Section 4.3 shows that RAG models are more factual and specific than BART for Jeopardy question generation. Following recent work on diversity-promoting decoding [33, 59, 39], we also investigate generation diversity by calculating the ratio of distinct ngrams to total ngrams generated by different models. Table 5 shows that RAG-Sequence’s generations are more diverse than RAG-Token’s, and both are significantly more diverse than BART without needing any diversity-promoting decoding.
生成多样性
§4.3 表明:在 Jeopardy 问题生成上,RAG 比 BART 更符合事实、更具体。沿用近期多样性促进解码的工作 [33, 59, 39],我们也用 distinct n-gram 占总 n-gram 的比例衡量生成多样性。表 5 显示:RAG-Sequence 比 RAG-Token 更多样,两者都显著多于 BART,且无需任何多样性促进解码。
| Model | NQ | TQA | WQ | CT | Jeopardy-QGen | MSMarco | FVR-3 | FVR-2 | ||
|---|---|---|---|---|---|---|---|---|---|---|
| Exact Match | B-1 | QB-1 | R-L | B-1 | Label Accuracy | |||||
| RAG-Token-BM25 | 29.7 | 41.5 | 32.1 | 33.1 | 17.5 | 22.3 | 55.5 | 48.4 | 75.1 | 91.6 |
| RAG-Sequence-BM25 | 31.8 | 44.1 | 36.6 | 33.8 | 11.1 | 19.5 | 56.5 | 46.9 | ||
| RAG-Token-Frozen | 37.8 | 50.1 | 37.1 | 51.1 | 16.7 | 21.7 | 55.9 | 49.4 | 72.9 | 89.4 |
| RAG-Sequence-Frozen | 41.2 | 52.1 | 41.8 | 52.6 | 11.8 | 19.6 | 56.7 | 47.3 | ||
| RAG-Token | 43.5 | 54.8 | 46.5 | 51.9 | 17.9 | 22.6 | 56.2 | 49.4 | 74.5 | 90.6 |
| RAG-Sequence | 44.0 | 55.8 | 44.9 | 53.4 | 15.3 | 21.5 | 57.2 | 47.5 |
Table 6: Ablations on the dev set. As FEVER is a classification task, both RAG models are equivalent.
| Model | NQ | TQA | WQ | CT | Jeopardy-QGen | MSMarco | FVR-3 | FVR-2 | ||
|---|---|---|---|---|---|---|---|---|---|---|
| Exact Match | B-1 | QB-1 | R-L | B-1 | Label Accuracy | |||||
| RAG-Token-BM25 | 29.7 | 41.5 | 32.1 | 33.1 | 17.5 | 22.3 | 55.5 | 48.4 | 75.1 | 91.6 |
| RAG-Sequence-BM25 | 31.8 | 44.1 | 36.6 | 33.8 | 11.1 | 19.5 | 56.5 | 46.9 | ||
| RAG-Token-Frozen | 37.8 | 50.1 | 37.1 | 51.1 | 16.7 | 21.7 | 55.9 | 49.4 | 72.9 | 89.4 |
| RAG-Sequence-Frozen | 41.2 | 52.1 | 41.8 | 52.6 | 11.8 | 19.6 | 56.7 | 47.3 | ||
| RAG-Token | 43.5 | 54.8 | 46.5 | 51.9 | 17.9 | 22.6 | 56.2 | 49.4 | 74.5 | 90.6 |
| RAG-Sequence | 44.0 | 55.8 | 44.9 | 53.4 | 15.3 | 21.5 | 57.2 | 47.5 |
表 6:开发集消融。FEVER 为分类任务,两种 RAG 模型等价。
Retrieval Ablations
A key feature of RAG is learning to retrieve relevant information for the task. To assess the effectiveness of the retrieval mechanism, we run ablations where we freeze the retriever during training. As shown in Table 6, learned retrieval improves results for all tasks.
检索消融
RAG 的关键特性是学会为任务检索相关信息。为评估检索机制,我们做训练中冻结检索器的消融。如表 6,可学习检索在所有任务上都提升结果。
We compare RAG’s dense retriever to a word overlap-based BM25 retriever [53]. Here, we replace RAG’s retriever with a fixed BM25 system, and use BM25 retrieval scores as logits when calculating . Table 6 shows the results. For FEVER, BM25 performs best, perhaps since FEVER claims are heavily entity-centric and thus well-suited for word overlap-based retrieval. Differentiable retrieval improves results on all other tasks, especially for Open-Domain QA, where it is crucial.
我们把 RAG 的稠密检索器与基于词重叠的 BM25 [53] 比较:用固定 BM25 替换 RAG 检索器,并以 BM25 检索分数作为计算 时的 logits。表 6 给出结果。FEVER 上 BM25 最好,或许因为 FEVER 论断高度以实体为中心,适合词重叠检索。可微检索在其余任务上都更好,尤其对开放域 QA 至关重要。
Index hot-swapping
An advantage of non-parametric memory models like RAG is that knowledge can be easily updated at test time. Parametric-only models like T5 or BART need further training to update their behavior as the world changes. To demonstrate, we build an index using the DrQA [5] Wikipedia dump from December 2016 and compare outputs from RAG using this index to the newer index from our main results (December 2018). We prepare a list of 82 world leaders who had changed between these dates and use a template “Who is {position}?” (e.g. “Who is the President of Peru?”) to query our NQ RAG model with each index. RAG answers 70% correctly using the 2016 index for 2016 world leaders and 68% using the 2018 index for 2018 world leaders. Accuracy with mismatched indices is low (12% with the 2018 index and 2016 leaders, 4% with the 2016 index and 2018 leaders). This shows we can update RAG’s world knowledge by simply replacing its non-parametric memory.
索引热替换
像 RAG 这样的非参数记忆模型有一个优点:测试时可轻易更新知识。T5 或 BART 等纯参数模型要随世界变化更新行为,还需继续训练。为演示,我们用 DrQA [5] 的 2016 年 12 月维基百科转储建索引,并把该索引下 RAG 的输出与主结果所用较新索引(2018 年 12 月)比较。我们整理了这两个日期之间发生变动的 82 位世界领导人名单,用模板 “Who is {position}?”(如 “Who is the President of Peru?”)查询 NQ 上的 RAG。用 2016 索引答 2016 领导人正确率 70%,用 2018 索引答 2018 领导人正确率 68%。索引与领导人年份错配时准确率很低(2018 索引对 2016 领导人 12%,2016 索引对 2018 领导人 4%)。这说明只需替换非参数记忆即可更新 RAG 的世界知识。
Effect of Retrieving more documents
Models are trained with either 5 or 10 retrieved latent documents, and we do not observe significant differences in performance between them. We have the flexibility to adjust the number of retrieved documents at test time, which can affect performance and runtime. Figure 3 (left) shows that retrieving more documents at test time monotonically improves Open-domain QA results for RAG-Sequence, but performance peaks for RAG-Token at 10 retrieved documents. Figure 3 (right) shows that retrieving more documents leads to higher Rouge-L for RAG-Token at the expense of Bleu-1, but the effect is less pronounced for RAG-Sequence.
检索更多文档的影响
模型以检索 5 或 10 篇潜在文档训练,两者性能无明显差异。测试时可灵活调整检索文档数,这会影响性能与运行时间。图 3(左)显示:测试时检索更多文档,RAG-Sequence 的开放域 QA 结果单调提升;RAG-Token 在 10 篇时见顶。图 3(右)显示:检索更多文档会提高 RAG-Token 的 Rouge-L、但牺牲 Bleu-1;对 RAG-Sequence 影响较弱。
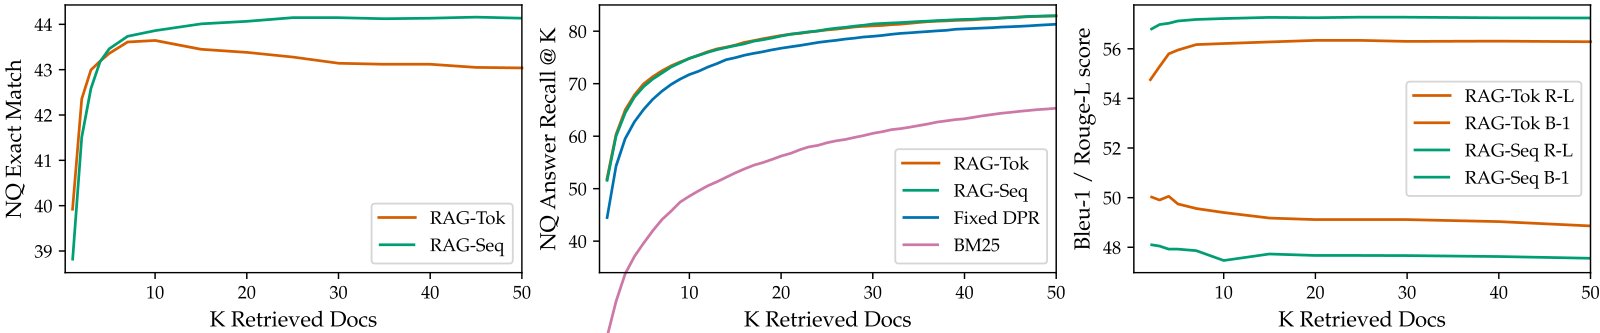
Figure 3: Left: NQ performance as more documents are retrieved. Center: Retrieval recall performance in NQ. Right: MS-MARCO Bleu-1 and Rouge-L as more documents are retrieved.
图 3:左:检索文档数增加时的 NQ 性能。中:NQ 上的检索召回。右:检索文档数增加时 MS-MARCO 的 Bleu-1 与 Rouge-L。
5 Related Work
5 相关工作
Single-Task Retrieval
Prior work has shown that retrieval improves performance across a variety of NLP tasks when considered in isolation. Such tasks include open-domain question answering [5, 29], fact checking [56], fact completion [48], long-form question answering [12], Wikipedia article generation [36], dialogue [41, 65, 9, 13], translation [17], and language modeling [19, 27]. Our work unifies previous successes in incorporating retrieval into individual tasks, showing that a single retrieval-based architecture is capable of achieving strong performance across several tasks.
单任务检索
先前工作表明:单独看时,检索能提升多种 NLP 任务的表现,包括开放域问答 [5, 29]、事实核查 [56]、事实补全 [48]、长文问答 [12]、维基百科文章生成 [36]、对话 [41, 65, 9, 13]、翻译 [17] 与语言建模 [19, 27]。我们的工作把此前在各任务上引入检索的成功统一起来,表明单一基于检索的架构也能在多项任务上取得强性能。
General-Purpose Architectures for NLP
Prior work on general-purpose architectures for NLP tasks has shown great success without the use of retrieval. A single, pre-trained language model has been shown to achieve strong performance on various classification tasks in the GLUE benchmarks [60, 61] after fine-tuning [49, 8]. GPT-2 [50] later showed that a single, left-to-right, pre-trained language model could achieve strong performance across both discriminative and generative tasks. For further improvement, BART [32] and T5 [51, 52] propose a single, pre-trained encoder-decoder model that leverages bi-directional attention to achieve stronger performance on discriminative and generative tasks. Our work aims to expand the space of possible tasks with a single, unified architecture, by learning a retrieval module to augment pre-trained, generative language models.
NLP 的通用架构
不使用检索的通用 NLP 架构此前已很成功。单一预训练语言模型经微调后,可在 GLUE 基准 [60, 61] 的多种分类任务上取得强表现 [49, 8]。GPT-2 [50] 随后表明:单一从左到右的预训练语言模型,也能在判别与生成任务上都表现强劲。为进一步提升,BART [32] 与 T5 [51, 52] 提出单一预训练编码器—解码器,利用双向注意力在判别与生成任务上更强。我们的工作旨在扩大单一统一架构可覆盖的任务空间:学习检索模块来增强预训练生成式语言模型。
Learned Retrieval
There is significant work on learning to retrieve documents in information retrieval, more recently with pre-trained, neural language models [44, 26] similar to ours. Some work optimizes the retrieval module to aid in a specific, downstream task such as question answering, using search [46], reinforcement learning [6, 63, 62], or a latent variable approach [31, 20] as in our work. These successes leverage different retrieval-based architectures and optimization techniques to achieve strong performance on a single task, while we show that a single retrieval-based architecture can be fine-tuned for strong performance on a variety of tasks.
可学习检索
信息检索中学习检索文档的工作很多,近期也有与我们类似的、基于预训练神经语言模型的方法 [44, 26]。有些工作优化检索模块以服务特定下游任务(如问答),手段包括搜索 [46]、强化学习 [6, 63, 62],或如本文的潜变量方法 [31, 20]。这些成功用不同的检索架构与优化技术在单任务上取得强表现;我们则表明:单一基于检索的架构经微调后,可在多种任务上取得强表现。
Memory-based Architectures
Our document index can be seen as a large external memory for neural networks to attend to, analogous to memory networks [64, 55]. Concurrent work [14] learns to retrieve a trained embedding for each entity in the input, rather than to retrieve raw text as in our work. Other work improves the ability of dialog models to generate factual text by attending over fact embeddings [15, 13]. A key feature of our memory is that it is comprised of raw text rather distributed representations, which makes the memory both (i) human-readable, lending a form of interpretability to our model, and (ii) human-writable, enabling us to dynamically update the model’s memory by editing the document index. This approach has also been used in knowledge-intensive dialog, where generators have been conditioned on retrieved text directly, albeit obtained via TF-IDF rather than end-to-end learnt retrieval [9].
基于记忆的架构
我们的文档索引可视为神经网络可关注的大型外部记忆,类似于记忆网络 [64, 55]。同期工作 [14] 学习为输入中每个实体检索一个训练好的嵌入,而非像我们这样检索原始文本。另有工作通过关注事实嵌入来提升对话模型生成事实文本的能力 [15, 13]。我们记忆的关键特点是由原始文本而非分布式表示构成,因此记忆既 (i) 人类可读,带来一定可解释性,又 (ii) 人类可写,可通过编辑文档索引动态更新模型记忆。知识密集型对话中也有直接条件于检索文本的生成器,不过检索来自 TF-IDF 而非端到端学习的检索 [9]。
Retrieve-and-Edit approaches
Our method shares some similarities with retrieve-and-edit style approaches, where a similar training input-output pair is retrieved for a given input, and then edited to provide a final output. These approaches have proved successful in a number of domains including Machine Translation [18, 22] and Semantic Parsing [21]. Our approach does have several differences, including less of emphasis on lightly editing a retrieved item, but on aggregating content from several pieces of retrieved content, as well as learning latent retrieval, and retrieving evidence documents rather than related training pairs. This said, RAG techniques may work well in these settings, and could represent promising future work.
检索再编辑方法
我们的方法与 retrieve-and-edit 风格有一些相似:对给定输入检索相似的训练输入—输出对,再编辑得到最终输出。这类方法在机器翻译 [18, 22] 与语义解析 [21] 等领域已获成功。我们的方法有若干不同:重点不在对检索项做轻度编辑,而在聚合多篇检索内容;还学习潜在检索,并检索证据文档而非相关训练对。即便如此,RAG 技术也可能适用于这些设定,值得作为未来工作探索。
6 Discussion
6 讨论
In this work, we presented hybrid generation models with access to parametric and non-parametric memory. We showed that our RAG models obtain state of the art results on open-domain QA. We found that people prefer RAG’s generation over purely parametric BART, finding RAG more factual and specific. We conducted an thorough investigation of the learned retrieval component, validating its effectiveness, and we illustrated how the retrieval index can be hot-swapped to update the model without requiring any retraining. In future work, it may be fruitful to investigate if the two components can be jointly pre-trained from scratch, either with a denoising objective similar to BART or some another objective. Our work opens up new research directions on how parametric and non-parametric memories interact and how to most effectively combine them, showing promise in being applied to a wide variety of NLP tasks.
本文提出可访问参数与非参数记忆的混合生成模型。我们表明 RAG 在开放域 QA 上达到当时最优;人们更偏好 RAG 的生成而非纯参数 BART,认为 RAG 更符合事实、更具体。我们对学到的检索组件做了充分调查,验证其有效性,并说明可用热替换检索索引来更新模型而无需再训练。未来工作或可探索两组件能否从零联合预训练——用类似 BART 的去噪目标或其他目标。我们的工作开辟了关于参数与非参数记忆如何交互、如何最有效结合的新研究方向,并显示其有望应用于广泛 NLP 任务。
Broader Impact
更广泛影响
This work offers several positive societal benefits over previous work: the fact that it is more strongly grounded in real factual knowledge (in this case Wikipedia) makes it “hallucinate” less with generations that are more factual, and offers more control and interpretability. RAG could be employed in a wide variety of scenarios with direct benefit to society, for example by endowing it with a medical index and asking it open-domain questions on that topic, or by helping people be more effective at their jobs.
相对先前工作,本文带来若干积极的社会收益:更强地锚定于真实事实知识(此处为维基百科),使“幻觉”更少、生成更符合事实,并提供更多控制与可解释性。RAG 可用于多种直接造福社会的场景,例如配上医学索引并就其主题做开放域提问,或帮助人们更高效地完成工作。
With these advantages also come potential downsides: Wikipedia, or any potential external knowledge source, will probably never be entirely factual and completely devoid of bias. Since RAG can be employed as a language model, similar concerns as for GPT-2 [50] are valid here, although arguably to a lesser extent, including that it might be used to generate abuse, faked or misleading content in the news or on social media; to impersonate others; or to automate the production of spam/phishing content [54]. Advanced language models may also lead to the automation of various jobs in the coming decades [16]. In order to mitigate these risks, AI systems could be employed to fight against misleading content and automated spam/phishing.
这些优势也伴随潜在风险:维基百科或任何外部知识源,几乎不可能完全符合事实、毫无偏见。由于 RAG 可用作语言模型,与 GPT-2 [50] 类似的关切在此同样成立,尽管程度或更轻,包括:可能被用来生成辱骂、伪造或误导性新闻/社交媒体内容;冒充他人;或自动化生产垃圾邮件/钓鱼内容 [54]。先进语言模型也可能在未来几十年推动若干岗位自动化 [16]。为缓解风险,可用 AI 系统对抗误导内容与自动化垃圾邮件/钓鱼。
Acknowledgments
致谢
The authors would like to thank the reviewers for their thoughtful and constructive feedback on this paper, as well as HuggingFace for their help in open-sourcing code to run RAG models. The authors would also like to thank Kyunghyun Cho and Sewon Min for productive discussions and advice. EP thanks supports from the NSF Graduate Research Fellowship. PL is supported by the FAIR PhD program.
作者感谢审稿人对本文深思熟虑、富有建设性的反馈,以及 HuggingFace 协助开源运行 RAG 模型的代码。也感谢 Kyunghyun Cho 与 Sewon Min 富有成效的讨论与建议。EP 感谢 NSF 研究生研究奖学金支持。PL 获 FAIR 博士项目支持。
References
参考文献
Appendices for Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks
附录: 面向知识密集型 NLP 任务的检索增强生成
[1] Payal Bajaj, Daniel Campos, Nick Craswell, Li Deng, Jianfeng Gao, Xiaodong Liu, Rangan Majumder, Andrew McNamara, Bhaskar Mitra, Tri Nguyen, Mir Rosenberg, Xia Song, Alina Stoica, Saurabh Tiwary, and Tong Wang. MS MARCO: A Human Generated MAchine Reading COmprehension Dataset. arXiv:1611.09268 [cs] , November 2016. URL http://arxiv.org/abs/1611.09268 . arXiv: 1611.09268.
[2] Petr Baudiš and Jan Šedivỳ. Modeling of the question answering task in the yodaqa system. In International Conference of the Cross-Language Evaluation Forum for European Languages , pages 222–228. Springer, 2015. URL https://link.springer.com/chapter/10.1007%2F978-3-319-24027-5_20 .
[3] Jonathan Berant, Andrew Chou, Roy Frostig, and Percy Liang. Semantic Parsing on Freebase from Question-Answer Pairs. In Proceedings of the 2013 Conference on Empirical Methods in Natural Language Processing , pages 1533–1544, Seattle, Washington, USA, October 2013. Association for Computational Linguistics. URL http://www.aclweb.org/anthology/D13-1160 .
[4] Bin Bi, Chenliang Li, Chen Wu, Ming Yan, and Wei Wang. Palm: Pre-training an autoencoding&autoregressive language model for context-conditioned generation. ArXiv , abs/2004.07159, 2020. URL https://arxiv.org/abs/2004.07159 .
[5] Danqi Chen, Adam Fisch, Jason Weston, and Antoine Bordes. Reading Wikipedia to Answer Open-Domain Questions. In Proceedings of the 55th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) , pages 1870–1879, Vancouver, Canada, July 2017. Association for Computational Linguistics. doi: 10.18653/v1/P17-1171 . URL https://www.aclweb.org/anthology/P17-1171 .
[6] Eunsol Choi, Daniel Hewlett, Jakob Uszkoreit, Illia Polosukhin, Alexandre Lacoste, and Jonathan Berant. Coarse-to-fine question answering for long documents. In Proceedings of the 55th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) , pages 209–220, Vancouver, Canada, July 2017. Association for Computational Linguistics. doi: 10.18653/v1/P17-1020 . URL https://www.aclweb.org/anthology/P17-1020 .
[7] Christopher Clark and Matt Gardner. Simple and Effective Multi-Paragraph Reading Comprehension. arXiv:1710.10723 [cs] , October 2017. URL http://arxiv.org/abs/1710.10723 . arXiv: 1710.10723.
[8] Jacob Devlin, Ming-Wei Chang, Kenton Lee, and Kristina Toutanova. BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) , pages 4171–4186, Minneapolis, Minnesota, June 2019. Association for Computational Linguistics. doi: 10.18653/v1/N19-1423 . URL https://www.aclweb.org/anthology/N19-1423 .
[9] Emily Dinan, Stephen Roller, Kurt Shuster, Angela Fan, Michael Auli, and Jason Weston. Wizard of wikipedia: Knowledge-powered conversational agents. In International Conference on Learning Representations , 2019. URL https://openreview.net/forum?id=r1l73iRqKm .
[10] Matthew Dunn, Levent Sagun, Mike Higgins, V. Ugur Guney, Volkan Cirik, and Kyunghyun Cho. SearchQA: A New Q&A Dataset Augmented with Context from a Search Engine. arXiv:1704.05179 [cs] , April 2017. URL http://arxiv.org/abs/1704.05179 . arXiv: 1704.05179.
[11] Angela Fan, Mike Lewis, and Yann Dauphin. Hierarchical neural story generation. In Proceedings of the 56th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) , pages 889–898, Melbourne, Australia, July 2018. Association for Computational Linguistics. doi: 10.18653/v1/P18-1082 . URL https://www.aclweb.org/anthology/P18-1082 .
[12] Angela Fan, Yacine Jernite, Ethan Perez, David Grangier, Jason Weston, and Michael Auli. ELI5: Long form question answering. In Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics , pages 3558–3567, Florence, Italy, July 2019. Association for Computational Linguistics. doi: 10.18653/v1/P19-1346 . URL https://www.aclweb.org/anthology/P19-1346 .
[13] Angela Fan, Claire Gardent, Chloe Braud, and Antoine Bordes. Augmenting transformers with KNN-based composite memory, 2020. URL https://openreview.net/forum?id=H1gx1CNKPH .
[14] Thibault Févry, Livio Baldini Soares, Nicholas FitzGerald, Eunsol Choi, and Tom Kwiatkowski. Entities as experts: Sparse memory access with entity supervision. ArXiv , abs/2004.07202, 2020. URL https://arxiv.org/abs/2004.07202 .
[15] Marjan Ghazvininejad, Chris Brockett, Ming-Wei Chang, Bill Dolan, Jianfeng Gao, Wen tau Yih, and Michel Galley. A knowledge-grounded neural conversation model. In AAAI Conference on Artificial Intelligence , 2018. URL https://www.aaai.org/ocs/index.php/AAAI/AAAI18/paper/view/16710 .
[16] Katja Grace, John Salvatier, Allan Dafoe, Baobao Zhang, and Owain Evans. When will AI exceed human performance? evidence from AI experts. CoRR , abs/1705.08807, 2017. URL http://arxiv.org/abs/1705.08807 .
[17] Jiatao Gu, Yong Wang, Kyunghyun Cho, and Victor O.K. Li. Search engine guided neural machine translation. In AAAI Conference on Artificial Intelligence , 2018a. URL https://www.aaai.org/ocs/index.php/AAAI/AAAI18/paper/view/17282 .
[18] Jiatao Gu, Yong Wang, Kyunghyun Cho, and Victor O.K. Li. Search engine guided neural machine translation. In 32nd AAAI Conference on Artificial Intelligence, AAAI 2018 , 32nd AAAI Conference on Artificial Intelligence, AAAI 2018, pages 5133–5140. AAAI press, 2018b. 32nd AAAI Conference on Artificial Intelligence, AAAI 2018 ; Conference date: 02-02-2018 Through 07-02-2018.
[19] Kelvin Guu, Tatsunori B. Hashimoto, Yonatan Oren, and Percy Liang. Generating sentences by editing prototypes. Transactions of the Association for Computational Linguistics , 6:437–450, 2018. doi: 10.1162/tacl_a_00030 . URL https://www.aclweb.org/anthology/Q18-1031 .
[20] Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat, and Ming-Wei Chang. REALM: Retrieval-augmented language model pre-training. ArXiv , abs/2002.08909, 2020. URL https://arxiv.org/abs/2002.08909 .
[21] Tatsunori B Hashimoto, Kelvin Guu, Yonatan Oren, and Percy S Liang. A retrieve-and-edit framework for predicting structured outputs. In S. Bengio, H. Wallach, H. Larochelle, K. Grauman, N. Cesa-Bianchi, and R. Garnett, editors, Advances in Neural Information Processing Systems 31 , pages 10052–10062. Curran Associates, Inc., 2018. URL http://papers.nips.cc/paper/8209-a-retrieve-and-edit-framework-for-predicting-structured-outputs.pdf .
[22] Nabil Hossain, Marjan Ghazvininejad, and Luke Zettlemoyer. Simple and effective retrieve-edit-rerank text generation. In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics , pages 2532–2538, Online, July 2020. Association for Computational Linguistics. doi: 10.18653/v1/2020.acl-main.228 . URL https://www.aclweb.org/anthology/2020.acl-main.228 .
[23] Jeff Johnson, Matthijs Douze, and Hervé Jégou. Billion-scale similarity search with gpus. arXiv preprint arXiv:1702.08734 , 2017. URL https://arxiv.org/abs/1702.08734 .
[24] Mandar Joshi, Eunsol Choi, Daniel Weld, and Luke Zettlemoyer. TriviaQA: A Large Scale Distantly Supervised Challenge Dataset for Reading Comprehension. In Proceedings of the 55th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) , pages 1601–1611, Vancouver, Canada, July 2017. Association for Computational Linguistics. doi: 10.18653/v1/P17-1147 . URL https://www.aclweb.org/anthology/P17-1147 .
[25] Armand Joulin and Tomas Mikolov. Inferring algorithmic patterns with stack-augmented recurrent nets. In Proceedings of the 28th International Conference on Neural Information Processing Systems - Volume 1 , NIPS’15, page 190–198, Cambridge, MA, USA, 2015. MIT Press. URL https://papers.nips.cc/paper/5857-inferring-algorithmic-patterns-with-stack-augmented-recurrent-nets .
[26] Vladimir Karpukhin, Barlas Oguz, Sewon Min, Ledell Wu, Sergey Edunov, Danqi Chen, and Wen-tau Yih. Dense passage retrieval for open-domain question answering. arXiv preprint arXiv:2004.04906 , 2020. URL https://arxiv.org/abs/2004.04906 .
[27] Urvashi Khandelwal, Omer Levy, Dan Jurafsky, Luke Zettlemoyer, and Mike Lewis. Generalization through memorization: Nearest neighbor language models. In International Conference on Learning Representations , 2020. URL https://openreview.net/forum?id=HklBjCEKvH .
[28] Diederik P. Kingma and Jimmy Ba. Adam: A method for stochastic optimization. In Yoshua Bengio and Yann LeCun, editors, 3rd International Conference on Learning Representations, ICLR 2015, San Diego, CA, USA, May 7-9, 2015, Conference Track Proceedings , 2015. URL http://arxiv.org/abs/1412.6980 .
[29] Tom Kwiatkowski, Jennimaria Palomaki, Olivia Redfield, Michael Collins, Ankur Parikh, Chris Alberti, Danielle Epstein, Illia Polosukhin, Matthew Kelcey, Jacob Devlin, Kenton Lee, Kristina N. Toutanova, Llion Jones, Ming-Wei Chang, Andrew Dai, Jakob Uszkoreit, Quoc Le, and Slav Petrov. Natural Questions: a Benchmark for Question Answering Research. Transactions of the Association of Computational Linguistics , 2019. URL https://tomkwiat.users.x20web.corp.google.com/papers/natural-questions/main-1455-kwiatkowski.pdf .
[30] Guillaume Lample, Alexandre Sablayrolles, Marc’ Aurelio Ranzato, Ludovic Denoyer, and Herve Jegou. Large memory layers with product keys. In H. Wallach, H. Larochelle, A. Beygelzimer, F. d’ Alché-Buc, E. Fox, and R. Garnett, editors, Advances in Neural Information Processing Systems 32 , pages 8548–8559. Curran Associates, Inc., 2019. URL http://papers.nips.cc/paper/9061-large-memory-layers-with-product-keys.pdf .
[31] Kenton Lee, Ming-Wei Chang, and Kristina Toutanova. Latent retrieval for weakly supervised open domain question answering. In Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics , pages 6086–6096, Florence, Italy, July 2019. Association for Computational Linguistics. doi: 10.18653/v1/P19-1612 . URL https://www.aclweb.org/anthology/P19-1612 .
[32] Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Veselin Stoyanov, and Luke Zettlemoyer. BART: Denoising sequence-to-sequence pre-training for natural language generation, translation, and comprehension. arXiv preprint arXiv:1910.13461 , 2019. URL https://arxiv.org/abs/1910.13461 .
[33] Jiwei Li, Michel Galley, Chris Brockett, Jianfeng Gao, and Bill Dolan. A diversity-promoting objective function for neural conversation models. In Proceedings of the 2016 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies , pages 110–119, San Diego, California, June 2016. Association for Computational Linguistics. doi: 10.18653/v1/N16-1014 . URL https://www.aclweb.org/anthology/N16-1014 .
[34] Margaret Li, Jason Weston, and Stephen Roller. Acute-eval: Improved dialogue evaluation with optimized questions and multi-turn comparisons. ArXiv , abs/1909.03087, 2019. URL https://arxiv.org/abs/1909.03087 .
[35] Hairong Liu, Mingbo Ma, Liang Huang, Hao Xiong, and Zhongjun He. Robust neural machine translation with joint textual and phonetic embedding. In Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics , pages 3044–3049, Florence, Italy, July 2019. Association for Computational Linguistics. doi: 10.18653/v1/P19-1291 . URL https://www.aclweb.org/anthology/P19-1291 .
[36] Peter J. Liu*, Mohammad Saleh*, Etienne Pot, Ben Goodrich, Ryan Sepassi, Lukasz Kaiser, and Noam Shazeer. Generating wikipedia by summarizing long sequences. In International Conference on Learning Representations , 2018. URL https://openreview.net/forum?id=Hyg0vbWC- .
[37] Yury A. Malkov and D. A. Yashunin. Efficient and robust approximate nearest neighbor search using hierarchical navigable small world graphs. IEEE Transactions on Pattern Analysis and Machine Intelligence , 42:824–836, 2016. URL https://arxiv.org/abs/1603.09320 .
[38] Gary Marcus. The next decade in ai: four steps towards robust artificial intelligence. arXiv preprint arXiv:2002.06177 , 2020. URL https://arxiv.org/abs/2002.06177 .
[39] Luca Massarelli, Fabio Petroni, Aleksandra Piktus, Myle Ott, Tim Rocktäschel, Vassilis Plachouras, Fabrizio Silvestri, and Sebastian Riedel. How decoding strategies affect the verifiability of generated text. arXiv preprint arXiv:1911.03587 , 2019. URL https://arxiv.org/abs/1911.03587 .
[40] Paulius Micikevicius, Sharan Narang, Jonah Alben, Gregory Diamos, Erich Elsen, David Garcia, Boris Ginsburg, Michael Houston, Oleksii Kuchaiev, Ganesh Venkatesh, and Hao Wu. Mixed precision training. In ICLR , 2018. URL https://openreview.net/forum?id=r1gs9JgRZ .
[41] Nikita Moghe, Siddhartha Arora, Suman Banerjee, and Mitesh M. Khapra. Towards exploiting background knowledge for building conversation systems. In Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing , pages 2322–2332, Brussels, Belgium, October-November 2018. Association for Computational Linguistics. doi: 10.18653/v1/D18-1255 . URL https://www.aclweb.org/anthology/D18-1255 .
[42] Preksha Nema and Mitesh M. Khapra. Towards a better metric for evaluating question generation systems. In Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing , pages 3950–3959, Brussels, Belgium, October-November 2018. Association for Computational Linguistics. doi: 10.18653/v1/D18-1429 . URL https://www.aclweb.org/anthology/D18-1429 .
[43] Tri Nguyen, Mir Rosenberg, Xia Song, Jianfeng Gao, Saurabh Tiwary, Rangan Majumder, and Li Deng. MS MARCO: A human generated machine reading comprehension dataset. In Tarek Richard Besold, Antoine Bordes, Artur S. d’Avila Garcez, and Greg Wayne, editors, Proceedings of the Workshop on Cognitive Computation: Integrating neural and symbolic approaches 2016 co-located with the 30th Annual Conference on Neural Information Processing Systems (NIPS 2016), Barcelona, Spain, December 9, 2016 , volume 1773 of CEUR Workshop Proceedings . CEUR-WS.org, 2016. URL http://ceur-ws.org/Vol-1773/CoCoNIPS_2016_paper9.pdf .
[44] Rodrigo Nogueira and Kyunghyun Cho. Passage re-ranking with BERT. arXiv preprint arXiv:1901.04085 , 2019. URL https://arxiv.org/abs/1901.04085 .
[45] Myle Ott, Sergey Edunov, Alexei Baevski, Angela Fan, Sam Gross, Nathan Ng, David Grangier, and Michael Auli. fairseq: A fast, extensible toolkit for sequence modeling. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics (Demonstrations) , pages 48–53, Minneapolis, Minnesota, June 2019. Association for Computational Linguistics. doi: 10.18653/v1/N19-4009 . URL https://www.aclweb.org/anthology/N19-4009 .
[46] Ethan Perez, Siddharth Karamcheti, Rob Fergus, Jason Weston, Douwe Kiela, and Kyunghyun Cho. Finding generalizable evidence by learning to convince q&a models. In Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP) , pages 2402–2411, Hong Kong, China, November 2019. Association for Computational Linguistics. doi: 10.18653/v1/D19-1244 . URL https://www.aclweb.org/anthology/D19-1244 .
[47] Fabio Petroni, Tim Rocktäschel, Sebastian Riedel, Patrick Lewis, Anton Bakhtin, Yuxiang Wu, and Alexander Miller. Language models as knowledge bases? In Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP) , pages 2463–2473, Hong Kong, China, November 2019. Association for Computational Linguistics. doi: 10.18653/v1/D19-1250 . URL https://www.aclweb.org/anthology/D19-1250 .
[48] Fabio Petroni, Patrick Lewis, Aleksandra Piktus, Tim Rocktäschel, Yuxiang Wu, Alexander H. Miller, and Sebastian Riedel. How context affects language models’ factual predictions. In Automated Knowledge Base Construction , 2020. URL https://openreview.net/forum?id=025X0zPfn .
[49] Alec Radford, Karthik Narasimhan, Tim Salimans, and Ilya Sutskever. Improving Language Understanding by Generative Pre-Training, 2018. URL https://s3-us-west-2.amazonaws.com/openai-assets/research-covers/language-unsupervised/language_understanding_paper.pdf .
[50] Alec Radford, Jeff Wu, Rewon Child, David Luan, Dario Amodei, and Ilya Sutskever. Language models are unsupervised multitask learners, 2019. URL https://d4mucfpksywv.cloudfront.net/better-language-models/language_models_are_unsupervised_multitask_learners.pdf .
[51] Colin Raffel, Noam Shazeer, Adam Roberts, Katherine Lee, Sharan Narang, Michael Matena, Yanqi Zhou, Wei Li, and Peter J. Liu. Exploring the limits of transfer learning with a unified text-to-text transformer. arXiv e-prints , 2019. URL https://arxiv.org/abs/1910.10683 .
[52] Adam Roberts, Colin Raffel, and Noam Shazeer. How much knowledge can you pack into the parameters of a language model? arXiv e-prints , 2020. URL https://arxiv.org/abs/2002.08910 .
[53] Stephen Robertson and Hugo Zaragoza. The probabilistic relevance framework: Bm25 and beyond. Found. Trends Inf. Retr. , 3(4):333–389, April 2009. ISSN 1554-0669. doi: 10.1561/1500000019 . URL https://doi.org/10.1561/1500000019 .
[54] Irene Solaiman, Miles Brundage, Jack Clark, Amanda Askell, Ariel Herbert-Voss, Jeff Wu, Alec Radford, and Jian-Bing Wang. Release strategies and the social impacts of language models. ArXiv , abs/1908.09203, 2019.
[55] Sainbayar Sukhbaatar, Arthur Szlam, Jason Weston, and Rob Fergus. End-to-end memory networks. In C. Cortes, N. D. Lawrence, D. D. Lee, M. Sugiyama, and R. Garnett, editors, Advances in Neural Information Processing Systems 28 , pages 2440–2448. Curran Associates, Inc., 2015. URL http://papers.nips.cc/paper/5846-end-to-end-memory-networks.pdf .
[56] James Thorne, Andreas Vlachos, Christos Christodoulopoulos, and Arpit Mittal. FEVER: a large-scale dataset for fact extraction and VERification. In Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers) , pages 809–819, New Orleans, Louisiana, June 2018. Association for Computational Linguistics. doi: 10.18653/v1/N18-1074 . URL https://www.aclweb.org/anthology/N18-1074 .
[57] James H. Thorne and Andreas Vlachos. Avoiding catastrophic forgetting in mitigating model biases in sentence-pair classification with elastic weight consolidation. ArXiv , abs/2004.14366, 2020. URL https://arxiv.org/abs/2004.14366 .
[58] Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Ł ukasz Kaiser, and Illia Polosukhin. Attention is all you need. In I. Guyon, U. V. Luxburg, S. Bengio, H. Wallach, R. Fergus, S. Vishwanathan, and R. Garnett, editors, Advances in Neural Information Processing Systems 30 , pages 5998–6008. Curran Associates, Inc., 2017. URL http://papers.nips.cc/paper/7181-attention-is-all-you-need.pdf .
[59] Ashwin Vijayakumar, Michael Cogswell, Ramprasaath Selvaraju, Qing Sun, Stefan Lee, David Crandall, and Dhruv Batra. Diverse beam search for improved description of complex scenes. AAAI Conference on Artificial Intelligence , 2018. URL https://www.aaai.org/ocs/index.php/AAAI/AAAI18/paper/view/17329 .
[60] Alex Wang, Amanpreet Singh, Julian Michael, Felix Hill, Omer Levy, and Samuel Bowman. GLUE: A multi-task benchmark and analysis platform for natural language understanding. In Proceedings of the 2018 EMNLP Workshop BlackboxNLP: Analyzing and Interpreting Neural Networks for NLP , pages 353–355, Brussels, Belgium, November 2018a. Association for Computational Linguistics. doi: 10.18653/v1/W18-5446 . URL https://www.aclweb.org/anthology/W18-5446 .
[61] Alex Wang, Yada Pruksachatkun, Nikita Nangia, Amanpreet Singh, Julian Michael, Felix Hill, Omer Levy, and Samuel Bowman. SuperGLUE: A Stickier Benchmark for General-Purpose Language Understanding Systems. In H. Wallach, H. Larochelle, A. Beygelzimer, F. d\textquotesingle Alché-Buc, E. Fox, and R. Garnett, editors, Advances in Neural Information Processing Systems 32 , pages 3261–3275. Curran Associates, Inc., 2019. URL https://arxiv.org/abs/1905.00537 .
[62] Shuohang Wang, Mo Yu, Xiaoxiao Guo, Zhiguo Wang, Tim Klinger, Wei Zhang, Shiyu Chang, Gerry Tesauro, Bowen Zhou, and Jing Jiang. R 3 {}^{\mbox{3}} : Reinforced ranker-reader for open-domain question answering. In Sheila A. McIlraith and Kilian Q. Weinberger, editors, Proceedings of the Thirty-Second AAAI Conference on Artificial Intelligence, (AAAI-18), the 30th innovative Applications of Artificial Intelligence (IAAI-18), and the 8th AAAI Symposium on Educational Advances in Artificial Intelligence (EAAI-18), New Orleans, Louisiana, USA, February 2-7, 2018 , pages 5981–5988. AAAI Press, 2018b. URL https://www.aaai.org/ocs/index.php/AAAI/AAAI18/paper/view/16712 .
[63] Shuohang Wang, Mo Yu, Jing Jiang, Wei Zhang, Xiaoxiao Guo, Shiyu Chang, Zhiguo Wang, Tim Klinger, Gerald Tesauro, and Murray Campbell. Evidence aggregation for answer re-ranking in open-domain question answering. In ICLR , 2018c. URL https://openreview.net/forum?id=rJl3yM-Ab .
[64] Jason Weston, Sumit Chopra, and Antoine Bordes. Memory networks. In Yoshua Bengio and Yann LeCun, editors, 3rd International Conference on Learning Representations, ICLR 2015, San Diego, CA, USA, May 7-9, 2015, Conference Track Proceedings , 2015. URL http://arxiv.org/abs/1410.3916 .
[65] Jason Weston, Emily Dinan, and Alexander Miller. Retrieve and refine: Improved sequence generation models for dialogue. In Proceedings of the 2018 EMNLP Workshop SCAI: The 2nd International Workshop on Search-Oriented Conversational AI , pages 87–92, Brussels, Belgium, October 2018. Association for Computational Linguistics. doi: 10.18653/v1/W18-5713 . URL https://www.aclweb.org/anthology/W18-5713 .
[66] Thomas Wolf, Lysandre Debut, Victor Sanh, Julien Chaumond, Clement Delangue, Anthony Moi, Pierric Cistac, Tim Rault, Rémi Louf, Morgan Funtowicz, Joe Davison, Sam Shleifer, Patrick von Platen, Clara Ma, Yacine Jernite, Julien Plu, Canwen Xu, Teven Le Scao, Sylvain Gugger, Mariama Drame, Quentin Lhoest, and Alexander M. Rush. Huggingface’s transformers: State-of-the-art natural language processing. ArXiv , abs/1910.03771, 2019.
[67] Shiyue Zhang and Mohit Bansal. Addressing semantic drift in question generation for semi-supervised question answering. In Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP) , pages 2495–2509, Hong Kong, China, November 2019. Association for Computational Linguistics. doi: 10.18653/v1/D19-1253 . URL https://www.aclweb.org/anthology/D19-1253 .
[68] Wanjun Zhong, Jingjing Xu, Duyu Tang, Zenan Xu, Nan Duan, Ming Zhou, Jiahai Wang, and Jian Yin. Reasoning over semantic-level graph for fact checking. ArXiv , abs/1909.03745, 2019. URL https://arxiv.org/abs/1909.03745 .
Appendix A Implementation Details
附录 A 实现细节
For Open-domain QA we report test numbers using 15 retrieved documents for RAG-Token models. For RAG-Sequence models, we report test results using 50 retrieved documents, and we use the Thorough Decoding approach since answers are generally short. We use greedy decoding for QA as we did not find beam search improved results. For Open-MSMarco and Jeopardy question generation, we report test numbers using ten retrieved documents for both RAG-Token and RAG-Sequence, and we also train a BART-large model as a baseline. We use a beam size of four, and use the Fast Decoding approach for RAG-Sequence models, as Thorough Decoding did not improve performance.
开放域 QA 上,RAG-Token 测试报告使用 15 篇检索文档;RAG-Sequence 使用 50 篇,并因答案通常较短而采用 Thorough Decoding。QA 用贪心解码,因我们未发现束搜索能提升结果。Open-MSMarco 与 Jeopardy 问题生成上,两种 RAG 均报告使用 10 篇检索文档,并另训 BART-large 作基线。束大小为 4;RAG-Sequence 用 Fast Decoding,因 Thorough Decoding 未再提升表现。
Appendix B Human Evaluation
附录 B 人工评估
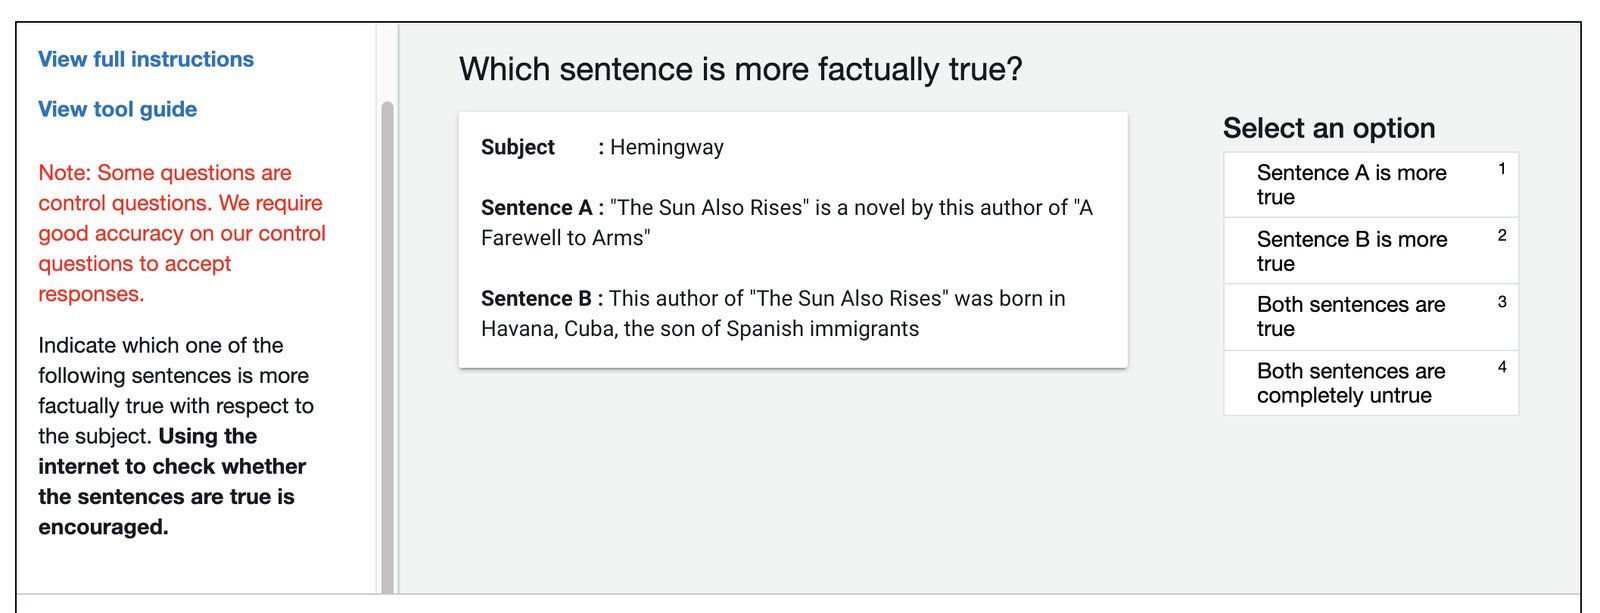
Figure 4: Annotation interface for human evaluation of factuality. A pop-out for detailed instructions and a worked example appear when clicking "view tool guide".
图 4:事实性人工评估的标注界面。点击 “view tool guide” 会弹出详细说明与示范例。
Figure 4 shows the user interface for human evaluation. To avoid any biases for screen position, which model corresponded to sentence A and sentence B was randomly selected for each example. Annotators were encouraged to research the topic using the internet, and were given detailed instructions and worked examples in a full instructions tab. We included some gold sentences in order to assess the accuracy of the annotators. Two annotators did not perform well on these examples and their annotations were removed from the results.
图 4 展示人工评估界面。为避免屏幕位置偏见,每个样例中哪个模型对应句子 A/B 随机选定。鼓励标注者用互联网查证主题,并在完整说明页提供详细指令与示范。我们加入部分金标句以评估标注者准确度;两名标注者在这些例子上表现不佳,其标注已从结果中剔除。
Appendix C Training setup Details
附录 C 训练设置细节
We train all RAG models and BART baselines using Fairseq [45].[^2] We train with mixed precision floating point arithmetic [40], distributing training across 8, 32GB NVIDIA V100 GPUs, though training and inference can be run on one GPU. We find that doing Maximum Inner Product Search with FAISS is sufficiently fast on CPU, so we store document index vectors on CPU, requiring GB of CPU memory for all of Wikipedia. After submission, We have ported our code to HuggingFace Transformers [66][^3], which achieves equivalent performance to the previous version but is a cleaner and easier to use implementation. This version is also open-sourced. We also compress the document index using FAISS’s compression tools, reducing the CPU memory requirement to 36GB. Scripts to run experiments with RAG can be found at https://github.com/huggingface/transformers/blob/master/examples/rag/README.md and an interactive demo of a RAG model can be found at https://huggingface.co/rag/
所有 RAG 模型与 BART 基线均用 Fairseq [45] 训练。[^2] 我们使用混合精度浮点运算 [40],在 8 块 32GB NVIDIA V100 GPU 上分布式训练,不过训练与推理也可在单 GPU 上运行。我们发现用 FAISS 做最大内积搜索在 CPU 上已足够快,因而把文档索引向量放在 CPU,整份维基百科约需 GB CPU 内存。投稿后,我们已把代码移植到 HuggingFace Transformers [66][^3],性能与先前版本相当,实现更干净易用,且已开源。我们还用 FAISS 压缩工具压缩文档索引,把 CPU 内存需求降到 36GB。用 RAG 跑实验的脚本见 https://github.com/huggingface/transformers/blob/master/examples/rag/README.md ,交互演示见 https://huggingface.co/rag/
Appendix D Further Details on Open-Domain QA
附录 D 开放域 QA 的更多细节
For open-domain QA, multiple answer annotations are often available for a given question. These answer annotations are exploited by extractive models during training as typically all the answer annotations are used to find matches within documents when preparing training data. For RAG, we also make use of multiple annotation examples for Natural Questions and WebQuestions by training the model with each pair separately, leading to a small increase in accuracy. For TriviaQA, there are often many valid answers to a given question, some of which are not suitable training targets, such as emoji or spelling variants. For TriviaQA, we filter out answer candidates if they do not occur in top 1000 documents for the query.
开放域 QA 中,同一问题常有多条答案标注。抽取式模型训练时通常会利用全部答案标注,在文档中找匹配以准备训练数据。对 RAG,我们在 Natural Questions 与 WebQuestions 上也利用多标注:把每个 对分开训练,准确率略有提升。TriviaQA 上同一问题常有许多合法答案,其中有些不宜作训练目标(如 emoji 或拼写变体)。对 TriviaQA,若答案候选未出现在该查询的 top 1000 文档中,则过滤掉。
CuratedTrec preprocessing
The answers for CuratedTrec are given in the form of regular expressions, which has been suggested as a reason why it is unsuitable for answer-generation models [20]. To overcome this, we use a pre-processing step where we first retrieve the top 1000 documents for each query, and use the answer that most frequently matches the regex pattern as the supervision target. If no matches are found, we resort to a simple heuristic: generate all possible permutations for each regex, replacing non-deterministic symbols in the regex nested tree structure with a whitespace.
CuratedTrec 预处理
CuratedTrec 的答案以正则表达式给出,有人据此认为它不适合答案生成模型 [20]。为克服这一点,我们先做预处理:对每个查询检索 top 1000 文档,取与正则匹配最频繁的答案作为监督目标。若无匹配,则退回简单启发式:生成正则的所有可能排列,把正则嵌套树中的非确定性符号替换为空格。
TriviaQA Evaluation setups
The open-domain QA community customarily uses public development datasets as test datasets, as test data for QA datasets is often restricted and dedicated to reading compehension purposes. We report our results using the datasets splits used in DPR [26], which are consistent with common practice in Open-domain QA. For TriviaQA, this test dataset is the public TriviaQA Web Development split. [52] used the TriviaQA official Wikipedia test set instead. [14] follow this convention in order to compare with [52] (See appendix of [14]). We report results on both test sets to enable fair comparison to both approaches. We find that our performance is much higher using the official Wiki test set, rather than the more conventional open-domain test set, which we attribute to the official Wiki test set questions being simpler to answer from Wikipedia.
TriviaQA 评估设置
开放域 QA 社区习惯把公开开发集当测试集用,因为 QA 数据集的测试数据常受限、专供阅读理解。我们按 DPR [26] 所用划分报告结果,与开放域 QA 常见做法一致。对 TriviaQA,该测试集是公开的 TriviaQA Web Development 划分。[52] 改用 TriviaQA 官方维基百科测试集。[14] 为与 [52] 比较也沿用该约定(见 [14] 附录)。我们在两个测试集上都报告结果,以便与两种做法公平比较。我们发现官方 Wiki 测试集上的分数远高于更常用的开放域测试集,归因于官方 Wiki 测试集问题更容易从维基百科作答。
Appendix E Further Details on FEVER
附录 E FEVER 的更多细节
For FEVER classification, we follow the practice from [32], and first re-generate the claim, and then classify using the representation of the final hidden state, before finally marginalizing across documents to obtain the class probabilities. The FEVER task traditionally has two sub-tasks. The first is to classify the claim as either "Supported", "Refuted" or "Not Enough Info", which is the task we explore in the main paper. FEVER’s other sub-task involves extracting sentences from Wikipedia as evidence supporting the classification prediction. As FEVER uses a different Wikipedia dump to us, directly tackling this task is not straightforward. We hope to address this in future work.
FEVER 分类上,我们沿用 [32] 的做法:先重新生成论断,再用最终隐状态的表示分类,最后跨文档边缘化得到类别概率。FEVER 传统上有两个子任务。其一是把论断分为 “Supported”“Refuted” 或 “Not Enough Info”,即正文探索的任务。另一子任务是从维基百科抽取句子作为分类预测的证据。由于 FEVER 使用的维基百科转储与我们不同,直接做该任务并不直接。我们希望在未来工作中处理。
Appendix F Null Document Probabilities
附录 F 空文档概率
We experimented with adding "Null document" mechanism to RAG, similar to REALM [20] in order to model cases where no useful information could be retrieved for a given input. Here, if documents were retrieved, we would additionally "retrieve" an empty document and predict a logit for the null document, before marginalizing over predictions. We explored modelling this null document logit by learning (i) a document embedding for the null document, (ii) a static learnt bias term, or (iii) a neural network to predict the logit. We did not find that these improved performance, so in the interests of simplicity, we omit them. For Open MS-MARCO, where useful retrieved documents cannot always be retrieved, we observe that the model learns to always retrieve a particular set of documents for questions that are less likely to benefit from retrieval, suggesting that null document mechanisms may not be necessary for RAG.
我们尝试过给 RAG 加入类似 REALM [20] 的“空文档”机制,以建模给定输入时检索不到有用信息的情形。若检索了 篇文档,我们额外“检索”一篇空文档并预测其 logit,再对 个预测边缘化。我们探索过用 (i) 为空文档学习文档嵌入、(ii) 静态可学习偏置,或 (iii) 神经网络预测该 logit。这些未带来提升,为简洁起见省略。对 Open MS-MARCO——有时检索不到有用文档——我们观察到模型会学到:对不太可能受益于检索的问题,总检索某一固定文档集合,提示 RAG 或许不必空文档机制。
Appendix G Parameters
附录 G 参数量
Our RAG models contain the trainable parameters for the BERT-base query and document encoder of DPR, with 110M parameters each (although we do not train the document encoder ourselves) and 406M trainable parameters from BART-large, 406M parameters, making a total of 626M trainable parameters. The best performing "closed-book" (parametric only) open-domain QA model is T5-11B with 11 Billion trainable parameters. The T5 model with the closest number of parameters to our models is T5-large (770M parameters), which achieves a score of 28.9 EM on Natural Questions [52], substantially below the 44.5 that RAG-Sequence achieves, indicating that hybrid parametric/non-parametric models require far fewer trainable parameters for strong open-domain QA performance. The non-parametric memory index does not consist of trainable parameters, but does consists of 21M 728 dimensional vectors, consisting of 15.3B values. These can be easily be stored at 8-bit floating point precision to manage memory and disk footprints.
我们的 RAG 模型含 DPR 的 BERT-base 查询与文档编码器可训练参数,各 1.1 亿(尽管我们不训练文档编码器),以及 BART-large 的 4.06 亿可训练参数,合计 6.26 亿可训练参数。表现最好的“闭卷”(纯参数)开放域 QA 模型是含 110 亿可训练参数的 T5-11B。与我们参数量最接近的 T5 是 T5-large(7.7 亿参数),在 Natural Questions 上 EM 为 28.9 [52],远低于 RAG-Sequence 的 44.5,表明混合参数/非参数模型用少得多的可训练参数即可取得强开放域 QA 表现。非参数记忆索引不含可训练参数,但由 2100 万个 728 维向量组成,共 153 亿个数值;可用 8 位浮点精度存储以控制内存与磁盘占用。
Appendix H Retrieval Collapse
附录 H 检索坍塌
In preliminary experiments, we observed that for some tasks such as story generation [11], the retrieval component would “collapse” and learn to retrieve the same documents regardless of the input. In these cases, once retrieval had collapsed, the generator would learn to ignore the documents, and the RAG model would perform equivalently to BART. The collapse could be due to a less-explicit requirement for factual knowledge in some tasks, or the longer target sequences, which could result in less informative gradients for the retriever. [46] also found spurious retrieval results when optimizing a retrieval component in order to improve performance on downstream tasks.
初步实验中,我们观察到:在故事生成 [11] 等任务上,检索组件会“坍塌”,学到无论输入如何都检索相同文档。一旦检索坍塌,生成器会学着忽略文档,RAG 表现就与 BART 相当。坍塌可能因为某些任务对事实知识的需求不那么显式,或目标序列更长导致给检索器的梯度信息更少。[46] 在优化检索组件以提升下游任务时,也发现过虚假检索结果。
Appendix I Number of instances per dataset
附录 I 各数据集实例数
The number of training, development and test datapoints in each of our datasets is shown in Table 7.
各数据集的训练、开发与测试样本数见表 7。
| Task | Train | Development | Test |
|---|---|---|---|
| Natural Questions | 79169 | 8758 | 3611 |
| TriviaQA | 78786 | 8838 | 11314 |
| WebQuestions | 3418 | 362 | 2033 |
| CuratedTrec | 635 | 134 | 635 |
| Jeopardy Question Generation | 97392 | 13714 | 26849 |
| MS-MARCO | 153726 | 12468 | 101093* |
| FEVER-3-way | 145450 | 10000 | 10000 |
| FEVER-2-way | 96966 | 6666 | 6666 |
Table 7: Number of instances in the datasets used. *A hidden subset of this data is used for evaluation
| Task | Train | Development | Test |
|---|---|---|---|
| Natural Questions | 79169 | 8758 | 3611 |
| TriviaQA | 78786 | 8838 | 11314 |
| WebQuestions | 3418 | 362 | 2033 |
| CuratedTrec | 635 | 134 | 635 |
| Jeopardy Question Generation | 97392 | 13714 | 26849 |
| MS-MARCO | 153726 | 12468 | 101093* |
| FEVER-3-way | 145450 | 10000 | 10000 |
| FEVER-2-way | 96966 | 6666 | 6666 |
表 7:所用数据集的实例数。*评估使用其中隐藏子集。