Understanding deep learning requires rethinking generalization
Understanding deep learning requires rethinking generalization
理解深度学习,需要重新思考泛化
Chiyuan Zhang*
Massachusetts Institute of Technology
chiyuan@mit.edu
Samy Bengio
Google Brain
bengio@google.com
Moritz Hardt
Google Brain
mrtz@google.com
Benjamin Recht†
University of California, Berkeley
brecht@berkeley.edu
Oriol Vinyals
Google DeepMind
vinyals@google.com
*Work performed while interning at Google Brain.
†Work performed at Google Brain.
Abstract
摘要
Despite their massive size, successful deep artificial neural networks can exhibit a remarkably small difference between training and test performance. Conventional wisdom attributes small generalization error either to properties of the model family, or to the regularization techniques used during training.
尽管规模庞大,一些成功的深度人工神经网络仍然可以让训练表现和测试表现相差很小。按常见说法,泛化误差小,要么是因为模型族本身的性质,要么是因为训练时用了正则技术。
Through extensive systematic experiments, we show how these traditional approaches fail to explain why large neural networks generalize well in practice. Specifically, our experiments establish that state-of-the-art convolutional networks for image classification trained with stochastic gradient methods easily fit a random labeling of the training data. This phenomenon is qualitatively unaffected by explicit regularization, and occurs even if we replace the true images by completely unstructured random noise. We corroborate these experimental findings with a theoretical construction showing that simple depth two neural networks already have perfect finite sample expressivity as soon as the number of parameters exceeds the number of data points as it usually does in practice.
通过大量系统实验,我们说明这些传统思路解释不了为什么大型神经网络在实践中泛化得很好。具体而言,实验表明,用随机梯度方法训练的、用于图像分类的先进卷积网络,可以轻易拟合训练集上的随机标记。这一现象几乎不受显式正则的影响,即便把真实图像换成完全没有结构的随机噪声,同样会发生。我们还给出一个理论构造来印证这些实验:只要参数个数超过数据点数——实践中通常如此——简单的两层神经网络就已经具有完备的有限样本表达能力。
We interpret our experimental findings by comparison with traditional models.
我们把这些实验发现与传统模型加以对照,并据此给出解释。
1 Introduction
1 引言
Deep artificial neural networks often have far more trainable model parameters than the number of samples they are trained on. Nonetheless, some of these models exhibit remarkably small generalization error, i.e., difference between “training error” and “test error”. At the same time, it is certainly easy to come up with natural model architectures that generalize poorly. What is it then that distinguishes neural networks that generalize well from those that don’t? A satisfying answer to this question would not only help to make neural networks more interpretable, but it might also lead to more principled and reliable model architecture design.
深度人工神经网络的可训练参数,常常远远多于用来训练它们的样本数。尽管如此,其中一些模型的泛化误差仍然非常小,也就是“训练误差”和“测试误差”相差无几。与此同时,要找出泛化很差的自然模型结构,也并不困难。那么,究竟是什么把泛化得好的神经网络和泛化得不好的区分开来?如果这个问题有令人满意的答案,将不仅有助于让神经网络更容易解释,也可能导向更有原则、更可靠的结构的设计。
To answer such a question, statistical learning theory has proposed a number of different complexity measures that are capable of controlling generalization error. These include VC dimension (Vapnik, 1998), Rademacher complexity (Bartlett & Mendelson, 2003), and uniform stability (Mukherjee et al., 2002; Bousquet & Elisseeff, 2002; Poggio et al., 2004). Moreover, when the number of parameters is large, theory suggests that some form of regularization is needed to ensure small generalization error. Regularization may also be implicit as is the case with early stopping.
为了回答这类问题,统计学习理论提出了若干能够约束泛化误差的复杂度度量,其中包括 VC 维(Vapnik, 1998)、Rademacher 复杂度(Bartlett & Mendelson, 2003)以及一致稳定性(Mukherjee et al., 2002; Bousquet & Elisseeff, 2002; Poggio et al., 2004)。此外,当参数很多时,理论还认为需要某种形式的正则,才能保证泛化误差较小。正则也可以是隐式的,例如早停。
1.1 Our contributions
1.1 我们的贡献
In this work, we problematize the traditional view of generalization by showing that it is incapable of distinguishing between different neural networks that have radically different generalization performance.
在这项工作中,我们把关于泛化的传统看法推到了问题面前:它无法把泛化表现截然不同的神经网络区分开来。
Randomization tests. At the heart of our methodology is a variant of the well-known randomization test from non-parametric statistics (Edgington & Onghena, 2007). In a first set of experiments, we train several standard architectures on a copy of the data where the true labels were replaced by random labels. Our central finding can be summarized as:
随机化检验。 我们方法的核心,是非参数统计中著名的随机化检验的一个变体(Edgington & Onghena, 2007)。在第一组实验里,我们在一份把真实标签换成随机标签的数据副本上,训练若干标准结构。中心发现可以概括为:
Deep neural networks easily fit random labels.
深度神经网络可以轻易拟合随机标签。
More precisely, when trained on a completely random labeling of the true data, neural networks achieve 0 training error. The test error, of course, is no better than random chance as there is no correlation between the training labels and the test labels. In other words, by randomizing labels alone we can force the generalization error of a model to jump up considerably without changing the model, its size, hyperparameters, or the optimizer. We establish this fact for several different standard architectures trained on the CIFAR10 and ImageNet classification benchmarks. While simple to state, this observation has profound implications from a statistical learning perspective:
更准确地说,当在真实数据的完全随机标记上训练时,神经网络可以把训练误差做到 0。测试误差当然不会好过随机猜测,因为训练标签和测试标签之间已经没有相关。换句话说,仅仅随机化标签,我们就可以在不改变模型、规模、超参数或优化器的前提下,迫使一个模型的泛化误差大幅上升。我们在 CIFAR10 和 ImageNet 分类基准上,对若干不同的标准结构都证实了这一点。这话虽然说起来简单,从统计学习的角度看,含义却很深:
- The effective capacity of neural networks is sufficient for memorizing the entire data set.
- 神经网络的有效容量,足以记住整个数据集。
- Even optimization on random labels remains easy. In fact, training time increases only by a small constant factor compared with training on the true labels.
- 即便在随机标签上做优化,仍然很容易。事实上,与在真实标签上训练相比,训练时间往往只增加一个不大的常数因子。
- Randomizing labels is solely a data transformation, leaving all other properties of the learning problem unchanged.
- 随机化标签只是一种数据变换,学习问题的其他性质都保持不变。
Extending on this first set of experiments, we also replace the true images by completely random pixels (e.g., Gaussian noise) and observe that convolutional neural networks continue to fit the data with zero training error. This shows that despite their structure, convolutional neural nets can fit random noise. We furthermore vary the amount of randomization, interpolating smoothly between the case of no noise and complete noise. This leads to a range of intermediate learning problems where there remains some level of signal in the labels. We observe a steady deterioration of the generalization error as we increase the noise level. This shows that neural networks are able to capture the remaining signal in the data, while at the same time fit the noisy part using brute-force.
在第一组实验的延伸中,我们还把真实图像换成完全随机的像素(例如高斯噪声),并观察到卷积神经网络仍然能以零训练误差拟合数据。这说明,尽管卷积网有结构,它们仍然可以拟合随机噪声。我们进一步改变随机化的程度,在没有噪声和完全噪声之间平滑插值。这样得到一系列中间学习问题,标签里还残留着不同程度的信号。随着噪声水平上升,我们看到泛化误差稳定变差。这说明神经网络既能抓住数据中剩下的信号,又能用蛮力拟合噪声部分。
We discuss in further detail below how these observations rule out all of VC-dimension, Rademacher complexity, and uniform stability as possible explanations for the generalization performance of state-of-the-art neural networks.
下文会更细致地讨论,这些观察如何排除了用 VC 维、Rademacher 复杂度和一致稳定性,来解释先进神经网络泛化表现的可能。
The role of explicit regularization. If the model architecture itself isn’t a sufficient regularizer, it remains to see how much explicit regularization helps. We show that explicit forms of regularization, such as weight decay, dropout, and data augmentation, do not adequately explain the generalization error of neural networks. Put differently:
显式正则的作用。 如果模型结构本身还不足以充当正则,那就还要看显式正则到底帮了多少。我们说明,权重衰减、dropout 和数据增强这类显式正则,并不足以解释神经网络的泛化误差。换句话说:
Explicit regularization may improve generalization performance, but is neither necessary nor by itself sufficient for controlling generalization error.
显式正则或许能改善泛化表现,但既非必要,也不足以单独管住泛化误差。
In contrast with classical convex empirical risk minimization, where explicit regularization is necessary to rule out trivial solutions, we found that regularization plays a rather different role in deep learning. It appears to be more of a tuning parameter that often helps improve the final test error of a model, but the absence of all regularization does not necessarily imply poor generalization error. As reported by Krizhevsky et al. (2012), -regularization (weight decay) sometimes even helps optimization, illustrating its poorly understood nature in deep learning.
这与经典的凸经验风险最小化不同:在那里,显式正则是排除平凡解所必需的。我们发现,正则在深度学习里扮演的角色相当不同。它看起来更像一个调节参数,常常有助于改善模型的最终测试误差,但去掉全部正则,并不必然意味着泛化误差很差。正如 Krizhevsky et al. (2012) 所报告的, 正则(权重衰减)有时甚至对优化有帮助,这也说明它在深度学习中的性质仍被理解得很不够。
Finite sample expressivity. We complement our empirical observations with a theoretical construction showing that generically large neural networks can express any labeling of the training data. More formally, we exhibit a very simple two-layer ReLU network with parameters that can express any labeling of any sample of size in dimensions. A previous construction due to Livni et al. (2014) achieved a similar result with far more parameters, namely, . While our depth 2 network inevitably has large width, we can also come up with a depth network in which each layer has only parameters.
有限样本表达能力。 作为对经验观察的补充,我们给出一个理论构造,说明一般而言规模较大的神经网络可以表达训练集上的任意标记。更形式地说,我们展示了一个非常简单的两层 ReLU 网络,只用 个参数,就能表达任意大小为 、维度为 的样本上的任意标记。Livni et al. (2014) 先前的构造达到了类似结论,但参数要多得多,是 。我们的深度为 2 的网络宽度必然很大,但也可以构造深度为 的网络,使每一层只有 个参数。
While prior expressivity results focused on what functions neural nets can represent over the entire domain, we focus instead on the expressivity of neural nets with regards to a finite sample. In contrast to existing depth separations (Delalleau & Bengio, 2011; Eldan & Shamir, 2016; Telgarsky, 2016; Cohen & Shashua, 2016) in function space, our result shows that even depth-2 networks of linear size can already represent any labeling of the training data.
先前关于表达能力的结果,关注的是神经网络在整个定义域上能表示哪些函数;我们则转而关注神经网络关于有限样本的表达能力。与函数空间中已有的深度分离结果(Delalleau & Bengio, 2011; Eldan & Shamir, 2016; Telgarsky, 2016; Cohen & Shashua, 2016)不同,我们的结果表明,即便是线性规模的深度为 2 的网络,已经能够表示训练集上的任意标记。
The role of implicit regularization. While explicit regularizers like dropout and weight-decay may not be essential for generalization, it is certainly the case that not all models that fit the training data well generalize well. Indeed, in neural networks, we almost always choose our model as the output of running stochastic gradient descent. Appealing to linear models, we analyze how SGD acts as an implicit regularizer. For linear models, SGD always converges to a solution with small norm. Hence, the algorithm itself is implicitly regularizing the solution. Indeed, we show on small data sets that even Gaussian kernel methods can generalize well with no regularization. Though this doesn’t explain why certain architectures generalize better than other architectures, it does suggest that more investigation is needed to understand exactly what the properties are inherited by models that were trained using SGD.
隐式正则的作用。 尽管 dropout 和权重衰减这类显式正则对泛化未必是根本的,但显然并非所有能很好拟合训练数据的模型都会泛化得好。事实上,在神经网络里,我们几乎总是把模型取成随机梯度下降跑出来的那个解。借助线性模型,我们分析了 SGD 如何充当隐式正则。对线性模型,SGD 总是收敛到范数较小的解。因此,算法本身就在对解做隐式正则。的确,我们在小型数据集上说明,即便是高斯核方法,不加正则也可以泛化得很好。这并不能解释为什么某些结构比另一些结构泛化更好,但它确实表明,还需要更多研究,才能确切理解由 SGD 训练得到的模型究竟继承了哪些性质。
1.2 Related work
1.2 相关工作
Hardt et al. (2016) give an upper bound on the generalization error of a model trained with stochastic gradient descent in terms of the number of steps gradient descent took. Their analysis goes through the notion of uniform stability (Bousquet & Elisseeff, 2002). As we point out in this work, uniform stability of a learning algorithm is independent of the labeling of the training data. Hence, the concept is not strong enough to distinguish between the models trained on the true labels (small generalization error) and models trained on random labels (high generalization error). This also highlights why the analysis of Hardt et al. (2016) for non-convex optimization was rather pessimistic, allowing only a very few passes over the data. Our results show that even empirically training neural networks is not uniformly stable for many passes over the data. Consequently, a weaker stability notion is necessary to make further progress along this direction.
Hardt et al. (2016) 用随机梯度下降所走的步数,给用该方法训练出的模型的泛化误差上了界。他们的分析借助了一致稳定性这一概念(Bousquet & Elisseeff, 2002)。正如我们在本文中指出的,一个学习算法的一致稳定性与训练集的标记无关。因此,这一概念还不够强,无法把在真实标签上训练的模型(泛化误差小)和在随机标签上训练的模型(泛化误差大)区分开。这也说明了为什么 Hardt et al. (2016) 对非凸优化的分析相当悲观,只允许对数据做很少几次遍历。我们的结果表明,即便从经验上看,用多次遍历来训练神经网络也并不是一致稳定的。因此,要沿这条路继续推进,需要一种更弱的稳定性概念。
There has been much work on the representational power of neural networks, starting from universal approximation theorems for multi-layer perceptrons (Cybenko, 1989; Mhaskar, 1993; Delalleau & Bengio, 2011; Mhaskar & Poggio, 2016; Eldan & Shamir, 2016; Telgarsky, 2016; Cohen & Shashua, 2016). All of these results are at the population level characterizing which mathematical functions certain families of neural networks can express over the entire domain. We instead study the representational power of neural networks for a finite sample of size . This leads to a very simple proof that even -sized two-layer perceptrons have universal finite-sample expressivity.
关于神经网络表示能力的工作已经很多,可追溯到多层感知机的万能逼近定理(Cybenko, 1989; Mhaskar, 1993; Delalleau & Bengio, 2011; Mhaskar & Poggio, 2016; Eldan & Shamir, 2016; Telgarsky, 2016; Cohen & Shashua, 2016)。这些结果都是在总体层面上,刻画某些神经网络族能在整个定义域上表示哪些数学函数。我们则研究神经网络对大小为 的有限样本的表示能力。由此可以相当简单地证明,即便是规模为 的两层感知机,也具有万能的有限样本表达能力。
Bartlett (1998) proved bounds on the fat shattering dimension of multilayer perceptrons with sigmoid activations in terms of the -norm of the weights at each node. This important result gives a generalization bound for neural nets that is independent of the network size. However, for RELU networks the -norm is no longer informative. This leads to the question of whether there is a different form of capacity control that bounds generalization error for large neural nets. This question was raised in a thought-provoking work by Neyshabur et al. (2014), who argued through experiments that network size is not the main form of capacity control for neural networks. An analogy to matrix factorization illustrated the importance of implicit regularization.
Bartlett (1998) 用每个节点权重的 范数,证明了带 sigmoid 激活的多层感知机的 fat-shattering 维上界。这一重要结果给出了与网络规模无关的神经网络泛化界。然而对 ReLU 网络来说, 范数不再提供有用信息。这就引出一个问题:是否存在另一种容量控制形式,能够约束大型神经网络的泛化误差。Neyshabur et al. (2014) 在一篇发人深省的工作中提出了这个问题,他们通过实验主张,网络规模并不是神经网络容量控制的主要形式。对矩阵分解的类比,则说明了隐式正则的重要性。
2 Effective capacity of neural networks
2 神经网络的有效容量
Our goal is to understand the effective model capacity of feed-forward neural networks. Toward this goal, we choose a methodology inspired by non-parametric randomization tests. Specifically, we take a candidate architecture and train it both on the true data and on a copy of the data in which the true labels were replaced by random labels. In the second case, there is no longer any relationship between the instances and the class labels. As a result, learning is impossible. Intuition suggests that this impossibility should manifest itself clearly during training, e.g., by training not converging or slowing down substantially. To our surprise, several properties of the training process for multiple standard achitectures is largely unaffected by this transformation of the labels. This poses a conceptual challenge. Whatever justification we had for expecting a small generalization error to begin with must no longer apply to the case of random labels.
我们的目标是理解前馈神经网络的有效模型容量。为此,我们采用了一种受非参数随机化检验启发的方法。具体来说,我们取一种候选结构,既在真实数据上训练,也在一份把真实标签换成随机标签的数据副本上训练。在第二种情形里,实例和类别标签之间已经没有任何关系。因此,学习是不可能的。直觉会认为,这种不可能性应当在训练过程中清楚地表现出来,例如训练不收敛,或明显变慢。令我们意外的是,对多种标准结构而言,训练过程的若干性质几乎不受这种标签变换的影响。这构成了一个概念上的挑战:我们原先用来期待较小泛化误差的那些理由,现在必须不再适用于随机标签的情形。
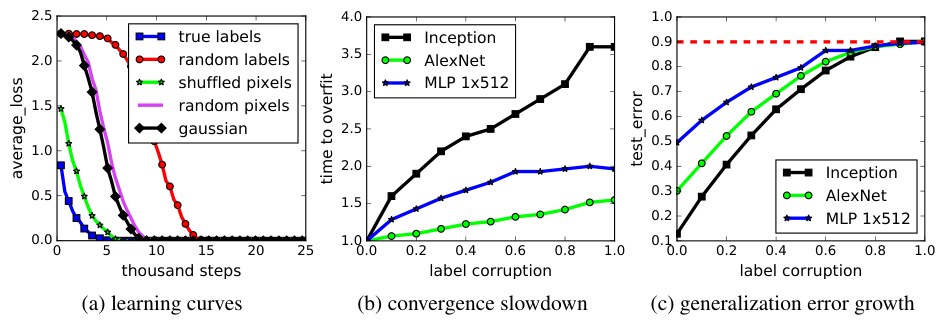
Figure 1: Fitting random labels and random pixels on CIFAR10. (a) shows the training loss of various experiment settings decaying with the training steps. (b) shows the relative convergence time with different label corruption ratio. (c) shows the test error (also the generalization error since training error is 0) under different label corruptions.
图 1:在 CIFAR10 上拟合随机标签和随机像素。(a) 显示各种实验设置下训练损失随训练步数衰减的情况。(b) 显示不同标签污染比例下的相对收敛时间。(c) 显示不同标签污染下的测试误差(由于训练误差为 0,这也就是泛化误差)。
To gain further insight into this phenomenon, we experiment with different levels of randomization exploring the continuum between no label noise and completely corrupted labels. We also try out different randomizations of the inputs (rather than labels), arriving at the same general conclusion.
为了进一步理解这一现象,我们尝试不同程度的随机化,探查从没有标签噪声到标签被完全破坏之间的连续区间。我们也试了对输入(而不是标签)做不同的随机化,并得到了同样的总体结论。
The experiments are run on two image classification datasets, the CIFAR10 dataset (Krizhevsky & Hinton, 2009) and the ImageNet (Russakovsky et al., 2015) ILSVRC 2012 dataset. We test the Inception V3 (Szegedy et al., 2016) architecture on ImageNet and a smaller version of Inception, Alexnet (Krizhevsky et al., 2012), and MLPs on CIFAR10. Please see Section A in the appendix for more details of the experimental setup.
实验在两个图像分类数据集上进行:CIFAR10 数据集(Krizhevsky & Hinton, 2009)和 ImageNet(Russakovsky et al., 2015)的 ILSVRC 2012 数据集。我们在 ImageNet 上测试 Inception V3(Szegedy et al., 2016)结构,在 CIFAR10 上测试一个较小的 Inception、Alexnet(Krizhevsky et al., 2012)以及多层感知机。实验设置的更多细节见附录 A。
2.1 Fitting random labels and pixels
2.1 拟合随机标签和随机像素
We run our experiments with the following modifications of the labels and input images:
我们按如下方式修改标签和输入图像,并据此做实验:
- True labels: the original dataset without modification.
- 真实标签:不做修改的原始数据集。
- Partially corrupted labels: independently with probability , the label of each image is corrupted as a uniform random class.
- 部分污染的标签:每个图像的标签以概率 独立地被污染成一个均匀随机的类别。
- Random labels: all the labels are replaced with random ones.
- 随机标签:全部标签都被换成随机标签。
- Shuffled pixels: a random permutation of the pixels is chosen and then the same permutation is applied to all the images in both training and test set.
- 打乱像素:选定像素的一个随机置换,然后把同一置换应用到训练集和测试集的所有图像上。
- Random pixels: a different random permutation is applied to each image independently.
- 随机像素:对每张图像独立地应用一个不同的随机置换。
- Gaussian: A Gaussian distribution (with matching mean and variance to the original image dataset) is used to generate random pixels for each image.
- 高斯:用一个高斯分布(均值和方差与原始图像数据集相匹配)为每张图像生成随机像素。
Surprisingly, stochastic gradient descent with unchanged hyperparameter settings can optimize the weights to fit to random labels perfectly, even though the random labels completely destroy the relationship between images and labels. We further break the structure of the images by shuffling the image pixels, and even completely re-sampling random pixels from a Gaussian distribution. But the networks we tested are still able to fit.
令人惊讶的是,随机梯度下降在超参数设置不变的情况下,仍然可以把权重优化到完美拟合随机标签,尽管随机标签已经彻底破坏了图像和标签之间的关系。我们进一步打乱图像像素来破坏图像结构,甚至从高斯分布中完全重新采样随机像素。但我们测试的网络仍然能够拟合。
Figure 1a shows the learning curves of the Inception model on the CIFAR10 dataset under various settings. We expect the objective function to take longer to start decreasing on random labels because initially the label assignments for every training sample is uncorrelated. Therefore, large predictions errors are back-propagated to make large gradients for parameter updates. However, since the random labels are fixed and consistent across epochs, the network starts fitting after going through the training set multiple times. We find the following observations for fitting random labels very interesting: a) we do not need to change the learning rate schedule; b) once the fitting starts, it converges quickly; c) it converges to (over)fit the training set perfectly. Also note that “random pixels” and “Gaussian” start converging faster than “random labels”. This might be because with random pixels, the inputs are more separated from each other than natural images that originally belong to the same category, therefore, easier to build a network for arbitrary label assignments.
图 1a 给出了 Inception 模型在 CIFAR10 数据集上、各种设置下的学习曲线。我们预期目标函数在随机标签上会更晚才开始下降,因为一开始每个训练样本的标签赋值都是不相关的。因此,较大的预测误差会被反向传播,产生较大的参数更新梯度。然而,由于随机标签在各个 epoch 之间是固定且一致的,网络在多次遍历训练集之后就开始拟合。关于拟合随机标签,我们觉得下面这些观察很有意思:a) 我们不需要改学习率日程;b) 一旦开始拟合,收敛就很快;c) 它会收敛到(过度)完美拟合训练集。另外请注意,“随机像素”和“高斯”开始收敛的时间比“随机标签”更早。这可能是因为,与原本同属一类的自然图像相比,随机像素使各个输入彼此分得更开,因此更容易为任意标签赋值构造一个网络。
On the CIFAR10 dataset, Alexnet and MLPs all converge to zero loss on the training set. The shaded rows in Table 1 show the exact numbers and experimental setup. We also tested random labels on the ImageNet dataset. As shown in the last three rows of Table 2 in the appendix, although it does not reach the perfect 100% top-1 accuracy, 95.20% accuracy is still very surprising for a million random labels from 1000 categories. Note that we did not do any hyperparameter tuning when switching from the true labels to random labels. It is likely that with some modification of the hyperparameters, perfect accuracy could be achieved on random labels. The network also manages to reach 90% top-1 accuracy even with explicit regularizers turned on.
在 CIFAR10 数据集上,Alexnet 和多层感知机都收敛到训练集上的零损失。表 1 中的阴影行给出了确切数字和实验设置。我们也在 ImageNet 数据集上测试了随机标签。如附录中表 2 的最后三行所示,虽然没有达到完美的 100% top-1 准确率,但对来自 1000 类的约一百万个随机标签仍有 95.20% 的准确率,这已经相当令人惊讶。请注意,从真实标签换成随机标签时,我们没有做任何超参数调节。若对超参数做一些修改,很可能可以在随机标签上达到完美准确率。即便打开显式正则,该网络也仍然能达到约 90% 的 top-1 准确率。
Partially corrupted labels. We further inspect the behavior of neural network training with a varying level of label corruptions from 0 (no corruption) to 1 (complete random labels) on the CIFAR10 dataset. The networks fit the corrupted training set perfectly for all the cases. Figure 1b shows the slowdown of the convergence time with increasing level of label noises. Figure 1c depicts the test errors after convergence. Since the training errors are always zero, the test errors are the same as generalization errors. As the noise level approaches 1, the generalization errors converge to 90% — the performance of random guessing on CIFAR10.
部分污染的标签。 我们进一步考察,在 CIFAR10 数据集上,把标签污染程度从 0(无污染)变到 1(完全随机标签)时,神经网络训练的行为。在所有情形下,网络都能完美拟合被污染的训练集。图 1b 显示,随着标签噪声水平上升,收敛时间变慢。图 1c 描绘收敛后的测试误差。由于训练误差始终为零,测试误差就等于泛化误差。当噪声水平接近 1 时,泛化误差收敛到 90%——这正是在 CIFAR10 上随机猜测的表现。
2.2 Implications
2.2 含义
In light of our randomization experiments, we discuss how our findings pose a challenge for several traditional approaches for reasoning about generalization.
根据这些随机化实验,我们讨论这些发现如何对若干传统的泛化论证方式提出挑战。
Rademacher complexity and VC-dimension. Rademacher complexity is commonly used and flexible complexity measure of a hypothesis class. The empirical Rademacher complexity of a hypothesis class on a dataset is defined as
Rademacher 复杂度与 VC 维。 Rademacher 复杂度是一种常用且灵活的假设类复杂度度量。假设类 在数据集 上的经验 Rademacher 复杂度定义为
where are i.i.d. uniform random variables. This definition closely resembles our randomization test. Specifically, measures ability of to fit random binary label assignments. While we consider multiclass problems, it is straightforward to consider related binary classification problems for which the same experimental observations hold. Since our randomization tests suggest that many neural networks fit the training set with random labels perfectly, we expect that for the corresponding model class . This is, of course, a trivial upper bound on the Rademacher complexity that does not lead to useful generalization bounds in realistic settings. A similar reasoning applies to VC-dimension and its continuous analog fat-shattering dimension, unless we further restrict the network. While Bartlett (1998) proves a bound on the fat-shattering dimension in terms of norm bounds on the weights of the network, this bound does not apply to the ReLU networks that we consider here. This result was generalized to other norms by Neyshabur et al. (2015), but even these do not seem to explain the generalization behavior that we observe.
其中 是独立同分布的均匀随机变量。这一定义与我们的随机化检验非常相似。具体来说, 衡量的是 拟合随机 二值标签赋值的能力。虽然我们考虑的是多类问题,但不难转到相关的二分类问题,并且同样的实验观察仍然成立。由于随机化检验表明许多神经网络能完美拟合带随机标签的训练集,我们预期相应模型类 满足 。这当然只是 Rademacher 复杂度一个平凡的上界,在现实设定中给不出有用的泛化界。类似的推理也适用于 VC 维及其连续类似物 fat-shattering 维,除非我们进一步限制网络。虽然 Bartlett (1998) 用网络权重的 范数界证明了 fat-shattering 维的一个上界,但该界并不适用于我们这里考虑的 ReLU 网络。Neyshabur et al. (2015) 把这一结果推广到了其他范数,但即便这些结果,也似乎解释不了我们观察到的泛化行为。
Uniform stability. Stepping away from complexity measures of the hypothesis class, we can instead consider properties of the algorithm used for training. This is commonly done with some notion of stability, such as uniform stability (Bousquet & Elisseeff, 2002). Uniform stability of an algorithm measures how sensitive the algorithm is to the replacement of a single example. However, it is solely a property of the algorithm, which does not take into account specifics of the data or the distribution of the labels. It is possible to define weaker notions of stability (Mukherjee et al., 2002; Poggio et al., 2004; Shalev-Shwartz et al., 2010). The weakest stability measure is directly equivalent to bounding generalization error and does take the data into account. However, it has been difficult to utilize this weaker stability notion effectively.
一致稳定性。 如果我们暂时离开假设类的复杂度度量,也可以转而考虑所用训练算法的性质。这通常借助某种稳定性概念来做,例如一致稳定性(Bousquet & Elisseeff, 2002)。算法 的一致稳定性衡量的是该算法对替换单个样本有多敏感。然而,它仅仅是算法本身的性质,并不考虑数据的具体情况或标签的分布。也可以定义更弱的稳定性概念(Mukherjee et al., 2002; Poggio et al., 2004; Shalev-Shwartz et al., 2010)。最弱的稳定性度量直接等价于给泛化误差上界,并且确实把数据考虑在内。然而,要有效利用这种更弱的稳定性概念,一直相当困难。
3 The role of regularization
3 正则的作用
Most of our randomization tests are performed with explicit regularization turned off. Regularizers are the standard tool in theory and practice to mitigate overfitting in the regime when there are more parameters than data points (Vapnik, 1998). The basic idea is that although the original hypothesis is too large to generalize well, regularizers help confine learning to a subset of the hypothesis space with manageable complexity. By adding an explicit regularizer, say by penalizing the norm of the optimal solution, the effective Rademacher complexity of the possible solutions is dramatically reduced.
我们的大多数随机化检验都是在关掉显式正则的情况下做的。在参数多于数据点的区间里,正则是理论和实践中用来缓解过拟合的标准工具(Vapnik, 1998)。基本想法是:虽然原来的假设空间太大,不能很好地泛化,但正则可以帮助把学习限制在一个复杂度可控的假设空间子集上。通过加入显式正则,比如说惩罚最优解的范数,可能解的有效 Rademacher 复杂度会被大幅降低。
As we will see, in deep learning, explicit regularization seems to play a rather different role. As the bottom rows of Table 2 in the appendix show, even with dropout and weight decay, InceptionV3 is still able to fit the random training set extremely well if not perfectly. Although not shown explicitly, on CIFAR10, both Inception and MLPs still fit perfectly the random training set with weight decay turned on. However, AlexNet with weight decay turned on fails to converge on random labels. To investigate the role of regularization in deep learning, we explicitly compare behavior of deep nets learning with and without regularizers.
我们将看到,在深度学习中,显式正则扮演的角色似乎相当不同。如附录中表 2 的底部几行所示,即便打开 dropout 和权重衰减,InceptionV3 仍然能极好地、即便不是完美地拟合随机训练集。虽然没有显式展示,在 CIFAR10 上,打开权重衰减后,Inception 和多层感知机仍然能完美拟合随机训练集。然而,打开权重衰减的 AlexNet 在随机标签上无法收敛。为了考察正则在深度学习中的作用,我们显式比较了带正则和不带正则时深度网络的学习行为。
Instead of doing a full survey of all kinds of regularization techniques introduced for deep learning, we simply take several commonly used network architectures, and compare the behavior when turning off the equipped regularizers. The following regularizers are covered:
我们并不打算全面综述深度学习中引入的各类正则技术,而只是取几种常用的网络结构,比较关掉其自带正则之后的行为。覆盖的正则如下:
- Data augmentation: augment the training set via domain-specific transformations. For image data, commonly used transformations include random cropping, random perturbation of brightness, saturation, hue and contrast.
- 数据增强:通过领域特定的变换来扩充训练集。对图像数据,常用变换包括随机裁剪,以及对亮度、饱和度、色调和对比度的随机扰动。
- Weight decay: equivalent to a regularizer on the weights; also equivalent to a hard constrain of the weights to an Euclidean ball, with the radius decided by the amount of weight decay.
- 权重衰减:等价于对权重的 正则;也等价于把权重硬约束在一个欧氏球内,半径由权重衰减的量决定。
- Dropout (Srivastava et al., 2014): mask out each element of a layer output randomly with a given dropout probability. Only the Inception V3 for ImageNet uses dropout in our experiments.
- Dropout(Srivastava et al., 2014):以给定的 dropout 概率随机把一层输出的各个元素掩盖掉。在我们的实验中,只有用于 ImageNet 的 Inception V3 使用了 dropout。
| model | # params | random crop | weight decay | train accuracy | test accuracy |
|---|---|---|---|---|---|
| Inception | 1,649,402 | yes | yes | 100.0 | 89.05 |
| yes | no | 100.0 | 89.31 | ||
| no | yes | 100.0 | 86.03 | ||
| no | no | 100.0 | 85.75 | ||
| (fitting random labels) | no | no | 100.0 | 9.78 | |
| Inception w/o BatchNorm | 1,649,402 | no | yes | 100.0 | 83.00 |
| no | no | 100.0 | 82.00 | ||
| (fitting random labels) | no | no | 100.0 | 10.12 | |
| Alexnet | 1,387,786 | yes | yes | 99.90 | 81.22 |
| yes | no | 99.82 | 79.66 | ||
| no | yes | 100.0 | 77.36 | ||
| no | no | 100.0 | 76.07 | ||
| (fitting random labels) | no | no | 99.82 | 9.86 | |
| MLP 3x512 | 1,735,178 | no | yes | 100.0 | 53.35 |
| no | no | 100.0 | 52.39 | ||
| (fitting random labels) | no | no | 100.0 | 10.48 | |
| MLP 1x512 | 1,209,866 | no | yes | 99.80 | 50.39 |
| no | no | 100.0 | 50.51 | ||
| (fitting random labels) | no | no | 99.34 | 10.61 |
Table 1: The training and test accuracy (in percentage) of various models on the CIFAR10 dataset. Performance with and without data augmentation and weight decay are compared. The results of fitting random labels are also included.
| 模型 | 参数量 | 随机裁剪 | 权重衰减 | 训练准确率 | 测试准确率 |
|---|---|---|---|---|---|
| Inception | 1,649,402 | 是 | 是 | 100.0 | 89.05 |
| 是 | 否 | 100.0 | 89.31 | ||
| 否 | 是 | 100.0 | 86.03 | ||
| 否 | 否 | 100.0 | 85.75 | ||
| (拟合随机标签) | 否 | 否 | 100.0 | 9.78 | |
| 不含批归一化的 Inception | 1,649,402 | 否 | 是 | 100.0 | 83.00 |
| 否 | 否 | 100.0 | 82.00 | ||
| (拟合随机标签) | 否 | 否 | 100.0 | 10.12 | |
| Alexnet | 1,387,786 | 是 | 是 | 99.90 | 81.22 |
| 是 | 否 | 99.82 | 79.66 | ||
| 否 | 是 | 100.0 | 77.36 | ||
| 否 | 否 | 100.0 | 76.07 | ||
| (拟合随机标签) | 否 | 否 | 99.82 | 9.86 | |
| MLP 3x512 | 1,735,178 | 否 | 是 | 100.0 | 53.35 |
| 否 | 否 | 100.0 | 52.39 | ||
| (拟合随机标签) | 否 | 否 | 100.0 | 10.48 | |
| MLP 1x512 | 1,209,866 | 否 | 是 | 99.80 | 50.39 |
| 否 | 否 | 100.0 | 50.51 | ||
| (拟合随机标签) | 否 | 否 | 99.34 | 10.61 |
表 1:各种模型在 CIFAR10 数据集上的训练和测试准确率(百分比)。比较了有无数据增强和权重衰减时的表现,也包括拟合随机标签的结果。
Table 1 shows the results of Inception, Alexnet and MLPs on CIFAR10, toggling the use of data augmentation and weight decay. Both regularization techniques help to improve the generalization performance, but even with all of the regularizers turned off, all of the models still generalize very well.
表 1 给出了 Inception、Alexnet 和多层感知机在 CIFAR10 上、打开或关闭数据增强与权重衰减时的结果。两种正则技术都有助于改善泛化表现,但即便关掉所有正则,这些模型仍然都能泛化得很好。
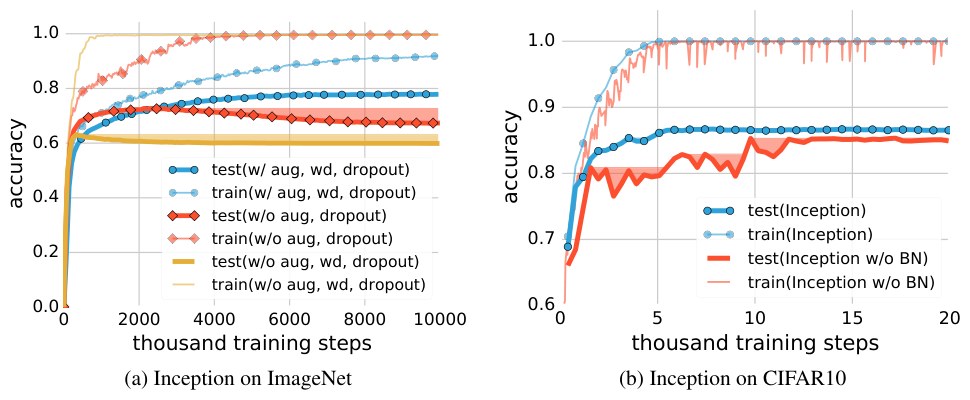
Figure 2: Effects of implicit regularizers on generalization performance. aug is data augmentation, wd is weight decay, BN is batch normalization. The shaded areas are the cumulative best test accuracy, as an indicator of potential performance gain of early stopping. (a) early stopping could potentially improve generalization when other regularizers are absent. (b) early stopping is not necessarily helpful on CIFAR10, but batch normalization stablize the training process and improves generalization.
图 2:隐式正则对泛化表现的影响。aug 表示数据增强,wd 表示权重衰减,BN 表示批归一化。阴影区域是累积的最佳测试准确率,用来指示早停可能带来的性能增益。(a) 在缺少其他正则时,早停有可能改善泛化。(b) 在 CIFAR10 上,早停未必有帮助,但批归一化能稳定训练过程并改善泛化。
Table 2 in the appendix shows a similar experiment on the ImageNet dataset. A 18% top-1 accuracy drop is observed when we turn off all the regularizers. Specifically, the top-1 accuracy without regularization is 59.80%, while random guessing only achieves 0.1% top-1 accuracy on ImageNet. More strikingly, with data-augmentation on but other explicit regularizers off, Inception is able to achieve a top-1 accuracy of 72.95%. Indeed, it seems like the ability to augment the data using known symmetries is significantly more powerful than just tuning weight decay or preventing low training error.
附录中的表 2 给出了在 ImageNet 数据集上的类似实验。关掉所有正则后,观察到 top-1 准确率下降了 18 个百分点。具体来说,没有正则时的 top-1 准确率是 59.80%,而在 ImageNet 上随机猜测只能达到 0.1% 的 top-1 准确率。更引人注目的是,只打开数据增强、关掉其他显式正则时,Inception 仍能达到 72.95% 的 top-1 准确率。的确,利用已知对称性来增强数据的能力,似乎比仅仅调节权重衰减、或防止训练误差过低,要有力得多。
Inception achieves 80.38% top-5 accuracy without regularization, while the reported number of the winner of ILSVRC 2012 (Krizhevsky et al., 2012) achieved 83.6%. So while regularization is important, bigger gains can be achieved by simply changing the model architecture. It is difficult to say that the regularizers count as a fundamental phase change in the generalization capability of deep nets.
在没有正则时,Inception 达到了 80.38% 的 top-5 准确率,而 ILSVRC 2012 优胜者(Krizhevsky et al., 2012)报告的数字是 83.6%。因此,尽管正则重要,仅仅改变模型结构就能带来更大的提升。很难说这些正则构成了深度网络泛化能力的一次根本性转变。
3.1 Implicit regularizations
3.1 隐式正则
Early stopping was shown to implicitly regularize on some convex learning problems (Yao et al., 2007; Lin et al., 2016). In Table 2 in the appendix, we show in parentheses the best test accuracy along the training process. It confirms that early stopping could potentially[^1] improve the generalization performance. Figure 2a shows the training and testing accuracy on ImageNet. The shaded area indicate the accumulative best test accuracy, as a reference of potential performance gain for early stopping. However, on the CIFAR10 dataset, we do not observe any potential benefit of early stopping.
早停已被证明能在某些凸学习问题上起隐式正则的作用(Yao et al., 2007; Lin et al., 2016)。在附录的表 2 中,我们在括号里给出了训练过程中的最佳测试准确率。这证实了早停有可能[^1]改善泛化表现。图 2a 给出了 ImageNet 上的训练和测试准确率。阴影区域表示累积的最佳测试准确率,作为早停可能带来的性能增益的参考。然而,在 CIFAR10 数据集上,我们没有观察到早停有任何潜在好处。
Batch normalization (Ioffe & Szegedy, 2015) is an operator that normalizes the layer responses within each mini-batch. It has been widely adopted in many modern neural network architectures such as Inception (Szegedy et al., 2016) and Residual Networks (He et al., 2016). Although not explicitly designed for regularization, batch normalization is usually found to improve the generalization performance. The Inception architecture uses a lot of batch normalization layers. To test the impact of batch normalization, we create a “Inception w/o BatchNorm” architecture that is exactly the same as Inception in Figure 3, except with all the batch normalization layers removed. Figure 2b compares the learning curves of the two variants of Inception on CIFAR10, with all the explicit regularizers turned off. The normalization operator helps stablize the learning dynamics, but the impact on the generalization performance is only . The exact accuracy is also listed in the section “Inception w/o BatchNorm” of Table 1.
批归一化(Ioffe & Szegedy, 2015)是一种在每个小批量内部对层响应做归一化的运算。它已被许多现代神经网络结构广泛采用,例如 Inception(Szegedy et al., 2016)和残差网络(He et al., 2016)。尽管并非显式为正则而设计,人们通常发现批归一化能改善泛化表现。Inception 结构使用了大量批归一化层。为了测试批归一化的影响,我们构造了一个“不含批归一化的 Inception”结构,它与图 3 中的 Inception 完全相同,只是去掉了所有批归一化层。图 2b 比较了这两种 Inception 变体在 CIFAR10 上的学习曲线,此时所有显式正则都已关掉。归一化运算有助于稳定学习动态,但对泛化表现的影响只有 。确切准确率也列在表 1 的“不含批归一化的 Inception”一节中。
In summary, our observations on both explicit and implicit regularizers are consistently suggesting that regularizers, when properly tuned, could help to improve the generalization performance. However, it is unlikely that the regularizers are the fundamental reason for generalization, as the networks continue to perform well after all the regularizers removed.
总之,我们对显式和隐式正则的观察都一致表明:正则在适当调节时,可以帮助改善泛化表现。然而,正则不太可能是泛化的根本原因,因为去掉全部正则之后,网络仍然表现很好。
4 Finite-sample expressivity
4 有限样本表达能力
Much effort has gone into characterizing the expressivity of neural networks, e.g, Cybenko (1989); Mhaskar (1993); Delalleau & Bengio (2011); Mhaskar & Poggio (2016); Eldan & Shamir (2016); Telgarsky (2016); Cohen & Shashua (2016). Almost all of these results are at the “population level” showing what functions of the entire domain can and cannot be represented by certain classes of neural networks with the same number of parameters. For example, it is known that at the population level depth is generically more powerful than depth .
刻画神经网络表达能力的工作已经很多,例如 Cybenko (1989); Mhaskar (1993); Delalleau & Bengio (2011); Mhaskar & Poggio (2016); Eldan & Shamir (2016); Telgarsky (2016); Cohen & Shashua (2016)。这些结果几乎都在“总体层面”上,说明参数数量相同的某些神经网络类,能够以及不能够表示整个定义域上的哪些函数。例如,已知在总体层面上,深度 一般要比深度 更有表达力。
We argue that what is more relevant in practice is the expressive power of neural networks on a finite sample of size . It is possible to transfer population level results to finite sample results using uniform convergence theorems. However, such uniform convergence bounds would require the sample size to be polynomially large in the dimension of the input and exponential in the depth of the network, posing a clearly unrealistic requirement in practice.
我们主张,实践中更相关的是神经网络在大小为 的有限样本上的表达能力。可以借助一致收敛定理,把总体层面的结果转到有限样本上。然而,这类一致收敛界会要求样本量在输入维度上多项式地大、在网络深度上指数地大,这在实践中显然不现实。
We instead directly analyze the finite-sample expressivity of neural networks, noting that this dramatically simplifies the picture. Specifically, as soon as the number of parameters of a networks is greater than , even simple two-layer neural networks can represent any function of the input sample. We say that a neural network can represent any function of a sample of size in dimensions if for every sample with and every function , there exists a setting of the weights of such that for every .
我们转而直接分析神经网络的有限样本表达能力,并指出这会极大简化图景。具体来说,一旦网络的参数个数 大于 ,即便简单的两层神经网络也能表示输入样本上的任意函数。我们说一个神经网络 能够表示 维空间中大小为 的样本上的任意函数,如果对每一个满足 的样本 ,以及每一个函数 ,都存在 的一组权重设置,使得对每个 都有 。
Theorem 1. There exists a two-layer neural network with ReLU activations and weights that can represent any function on a sample of size in dimensions.
定理 1. 存在一个带 ReLU 激活、具有 个权重的两层神经网络,能够表示 维空间中大小为 的样本上的任意函数。
The proof is given in Section C in the appendix, where we also discuss how to achieve width with depth . We remark that it’s a simple exercise to give bounds on the weights of the coefficient vectors in our construction. Lemma 1 gives a bound on the smallest eigenvalue of the matrix . This can be used to give reasonable bounds on the weight of the solution .
证明见附录 C,我们在那里也讨论了如何用深度 达到宽度 。顺便指出,对我们构造中系数向量的权重给出上界,只是一道简单的练习。引理 1 给出了矩阵 最小特征值的一个界。它可以用来给解 的权重一个合理的上界。
5 Implicit regularization: an appeal to linear models
5 隐式正则:向线性模型求助
Although deep neural nets remain mysterious for many reasons, we note in this section that it is not necessarily easy to understand the source of generalization for linear models either. Indeed, it is useful to appeal to the simple case of linear models to see if there are parallel insights that can help us better understand neural networks.
深度神经网络在许多方面仍然神秘,但我们在这一节指出,要理解线性模型泛化的来源,也未必容易。的确,求助于线性模型这一简单情形,看看是否存在可以更好地帮助我们理解神经网络的平行洞察,是有益的。
Suppose we collect distinct data points where are -dimensional feature vectors and are labels. Letting denote a nonnegative loss function with , consider the empirical risk minimization (ERM) problem
假设我们收集了 个互不相同的数据点 ,其中 是 维特征向量, 是标签。设 是一个非负损失函数,且 ,考虑经验风险最小化(ERM)问题
If , then we can fit any labeling. But is it then possible to generalize with such a rich model class and no explicit regularization?
如果 ,我们就可以拟合任意标记。但在如此丰富的模型类、又没有显式正则的情况下,还可能泛化吗?
Let denote the data matrix whose -th row is . If has rank , then the system of equations has an infinite number of solutions regardless of the right hand side. We can find a global minimum in the ERM problem (2) by simply solving this linear system.
设 表示第 行为 的 数据矩阵。如果 的秩为 ,那么无论右端是什么,方程组 都有无穷多解。我们只需解这个线性系统,就能找到 ERM 问题 (2) 的一个全局最小点。
But do all global minima generalize equally well? Is there a way to determine when one global minimum will generalize whereas another will not? One popular way to understand quality of minima is the curvature of the loss function at the solution. But in the linear case, the curvature of all optimal solutions is the same (Choromanska et al., 2015). To see this, note that in the case when is a scalar,
但是否所有全局最小点都同样好地泛化?有没有办法判断何时一个全局最小点会泛化,而另一个不会?理解最小点质量的一种流行方式,是看解处损失函数的曲率。但在线性情形下,所有最优解的曲率都是相同的(Choromanska et al., 2015)。为看到这一点,注意当 是标量时,
A similar formula can be found when is vector valued. In particular, the Hessian is not a function of the choice of . Moreover, the Hessian is degenerate at all global optimal solutions.
当 是向量值时,也可以找到类似公式。特别地,Hessian 并不是 的函数。此外,在所有全局最优解处,Hessian 都是退化的。
If curvature doesn’t distinguish global minima, what does? A promising direction is to consider the workhorse algorithm, stochastic gradient descent (SGD), and inspect which solution SGD converges to. Since the SGD update takes the form where is the step size and is the prediction error loss. If , we must have that the solution has the form for some coefficients . Hence, if we run SGD we have that lies in the span of the data points. If we also perfectly interpolate the labels we have . Enforcing both of these identities, this reduces to the single equation
如果曲率区分不了全局最小点,那什么可以?一个有希望的方向,是考虑主力算法随机梯度下降(SGD),并考察 SGD 收敛到哪一个解。由于 SGD 更新的形式是 ,其中 是步长, 是预测误差损失。如果 ,解必然具有 的形式,其中 是某些系数。因此,若运行 SGD,我们就有 ,它落在数据点张成的空间里。如果我们同时还完美插值了标签,则有 。同时加上这两个等式,就化成单一方程
which has a unique solution. Note that this equation only depends on the dot-products between the data points . We have thus derived the “kernel trick” (Schölkopf et al., 2001)—albeit in a roundabout fashion.
它有唯一解。注意,这个方程只依赖于数据点 之间的点积。我们就这样——尽管绕了一圈——导出了“核技巧”(Schölkopf et al., 2001)。
We can therefore perfectly fit any set of labels by forming the Gram matrix (aka the kernel matrix) on the data and solving the linear system for . This is an linear system that can be solved on standard workstations whenever is less than a hundred thousand, as is the case for small benchmarks like CIFAR10 and MNIST.
因此,我们可以通过在数据上形成 Gram 矩阵(也就是核矩阵),并求解线性系统 来得到 ,从而完美拟合任意一组标签。这是一个 线性系统,只要 小于十万,就可以在普通工作站上求解,CIFAR10 和 MNIST 这类小型基准正是如此。
Quite surprisingly, fitting the training labels exactly yields excellent performance for convex models. On MNIST with no preprocessing, we are able to achieve a test error of 1.2% by simply solving (3). Note that this is not exactly simple as the kernel matrix requires 30GB to store in memory. Nonetheless, this system can be solved in under 3 minutes in on a commodity workstation with 24 cores and 256 GB of RAM with a conventional LAPACK call. By first applying a Gabor wavelet transform to the data and then solving (3), the error on MNIST drops to 0.6%. Surprisingly, adding regularization does not improve either model’s performance!
相当令人惊讶的是,对凸模型而言,精确拟合训练标签就能得到很好的表现。在没有预处理的 MNIST 上,我们只需求解 (3),就能达到 1.2% 的测试误差。这并非完全简单,因为核矩阵在内存中需要 30GB。尽管如此,在一台带 24 核和 256 GB 内存的普通工作站上,用常规的 LAPACK 调用,这个系统可以在 3 分钟内解完。若先对数据做 Gabor 小波变换再求解 (3),MNIST 上的误差会降到 0.6%。令人惊讶的是,加入正则并不能改善这两个模型的表现!
Similar results follow for CIFAR10. Simply applying a Gaussian kernel on pixels and using no regularization achieves 46% test error. By preprocessing with a random convolutional neural net with 32,000 random filters, this test error drops to 17% error[^2]. Adding regularization further reduces this number to 15% error. Note that this is without any data augmentation.
CIFAR10 上也有类似结果。只在像素上应用高斯核、不加正则,测试误差是 46%。若用一个带 32,000 个随机滤波器的随机卷积神经网络做预处理,测试误差降到 17%[^2]。再加上 正则,这一数字进一步降到 15%。注意这都没有使用数据增强。
Note that this kernel solution has an appealing interpretation in terms of implicit regularization. Simple algebra reveals that it is equivalent to the minimum -norm solution of . That is, out of all models that exactly fit the data, SGD will often converge to the solution with minimum norm. It is very easy to construct solutions of that don’t generalize: for example, one could fit a Gaussian kernel to data and place the centers at random points. Another simple example would be to force the data to fit random labels on the test data. In both cases, the norm of the solution is significantly larger than the minimum norm solution.
需要指出,这个核解在隐式正则的意义上有一个很有吸引力的解释。简单的代数运算表明,它等价于 的最小 范数解。也就是说,在所有精确拟合数据的模型中,SGD 往往会收敛到范数最小的那个解。构造不泛化的 的解非常容易:例如,可以把高斯核的中心放在随机点上来拟合数据。另一个简单例子是强迫数据去拟合测试数据上的随机标签。在这两种情形里,解的范数都显著大于最小范数解。
Unfortunately, this notion of minimum norm is not predictive of generalization performance. For example, returning to the MNIST example, the -norm of the minimum norm solution with no preprocessing is approximately 220. With wavelet preprocessing, the norm jumps to 390. Yet the test error drops by a factor of 2. So while this minimum-norm intuition may provide some guidance to new algorithm design, it is only a very small piece of the generalization story.
不幸的是,最小范数这一概念并不能预测泛化表现。例如,回到 MNIST 的例子,没有预处理时最小范数解的 范数大约是 220。加上小波预处理后,范数升到 390。然而测试误差却降了一半。因此,尽管这种最小范数的直觉或许能为新算法设计提供一些指引,它也只是泛化故事中很小的一部分。
6 Conclusion
6 结论
In this work we presented a simple experimental framework for defining and understanding a notion of effective capacity of machine learning models. The experiments we conducted emphasize that the effective capacity of several successful neural network architectures is large enough to shatter the training data. Consequently, these models are in principle rich enough to memorize the training data. This situation poses a conceptual challenge to statistical learning theory as traditional measures of model complexity struggle to explain the generalization ability of large artificial neural networks.
在这项工作中,我们提出了一个简单的实验框架,用来定义并理解机器学习模型的有效容量。我们做的实验强调:若干成功的神经网络结构,其有效容量已经大到足以打散(shatter)训练数据。因此,这些模型原则上已经丰富到可以记住训练数据。这一局面给统计学习理论提出了概念上的挑战,因为传统的模型复杂度度量难以解释大型人工神经网络的泛化能力。
We argue that we have yet to discover a precise formal measure under which these enormous models are simple. Another insight resulting from our experiments is that optimization continues to be empirically easy even if the resulting model does not generalize. This shows that the reasons for why optimization is empirically easy must be different from the true cause of generalization.
我们主张,还没有发现一种精确的形式化度量,能说明这些巨大的模型在何种意义下是简单的。我们的实验还带来另一个洞察:即便得到的模型并不泛化,优化在经验上仍然可以很容易。这说明,优化在经验上容易的原因,必定不同于泛化的真正原因。
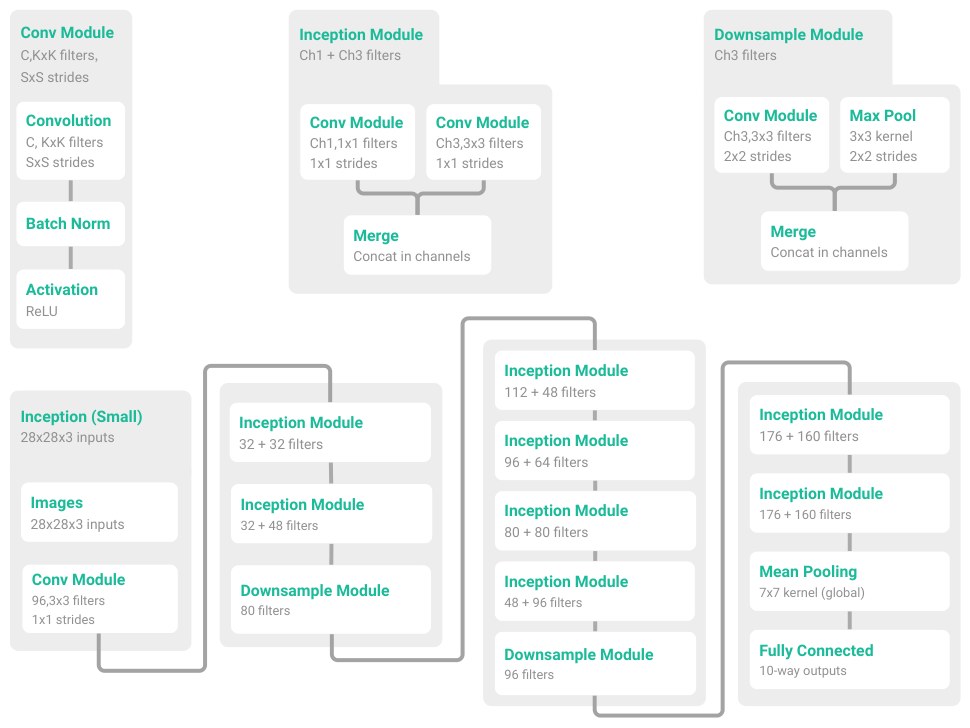
Figure 3: The small Inception model adapted for the CIFAR10 dataset. On the left we show the Conv module, the Inception module and the Downsample module, which are used to construct the Inception architecture on the right.
图 3:为 CIFAR10 数据集改写的小型 Inception 模型。左边给出卷积模块、Inception 模块和下采样模块,右边用它们构成 Inception 结构。
Appendix A Experimental setup
附录 A 实验设置
We focus on two image classification datasets, the CIFAR10 dataset (Krizhevsky & Hinton, 2009) and the ImageNet (Russakovsky et al., 2015) ILSVRC 2012 dataset.
我们关注两个图像分类数据集:CIFAR10 数据集(Krizhevsky & Hinton, 2009)和 ImageNet(Russakovsky et al., 2015)的 ILSVRC 2012 数据集。
The CIFAR10 dataset contains 50,000 training and 10,000 validation images, split into 10 classes. Each image is of size 32x32, with 3 color channels. We divide the pixel values by 255 to scale them into , crop from the center to get 28x28 inputs, and then normalize them by subtracting the mean and dividing the adjusted standard deviation independently for each image with the per_image_whitening function in TensorFlow (Abadi et al., 2015).
CIFAR10 数据集包含 50,000 张训练图像和 10,000 张验证图像,分成 10 类。每张图像大小为 32x32,有 3 个颜色通道。我们将像素值除以 255,缩放到 ,从中心裁出 28x28 的输入,然后对每张图像独立地减去均值、再除以调整后的标准差,使用的是 TensorFlow(Abadi et al., 2015)中的 per_image_whitening 函数。
For the experiment on CIFAR10, we test a simplified Inception (Szegedy et al., 2016) and Alexnet (Krizhevsky et al., 2012) by adapting the architectures to smaller input image sizes. We also test standard multi-layer perceptrons (MLPs) with various number of hidden layers.
在 CIFAR10 的实验中,我们测试了为较小输入图像尺寸改写的简化 Inception(Szegedy et al., 2016)和 Alexnet(Krizhevsky et al., 2012)。我们也测试了具有不同隐层数的标准多层感知机(MLP)。
The small Inception model uses a combination of 1x1 and 3x3 convolution pathways. The detailed architecture is illustrated in Figure 3. The small Alexnet is constructed by two (convolution 5x5 max-pool 3x3 local-response-normalization) modules followed by two fully connected layers with 384 and 192 hidden units, respectively. Finally a 10-way linear layer is used for prediction. The MLPs use fully connected layers. MLP 1x512 means one hidden layer with 512 hidden units. All of the architectures use standard rectified linear activation functions (ReLU).
小型 Inception 模型结合了 1x1 和 3x3 卷积通路。详细结构见图 3。小型 Alexnet 由两个(卷积 5x5 最大池化 3x3 局部响应归一化)模块构成,后面接两个分别有 384 和 192 个隐单元的全连接层。最后用一个 10 路线性层做预测。多层感知机使用全连接层。MLP 1x512 表示一个有 512 个隐单元的隐层。所有结构都使用标准的修正线性激活函数(ReLU)。
For all experiments on CIFAR10, we train using SGD with a momentum parameter of 0.9. An initial learning rate of 0.1 (for small Inception) or 0.01 (for small Alexnet and MLPs) are used, with a decay factor of 0.95 per training epoch. Unless otherwise specified, for the experiments with randomized labels or pixels, we train the networks without weight decay, dropout, or other forms of explicit regularization. Section 3 discusses the effects of various regularizers on fitting the networks and generalization.
CIFAR10 上的全部实验都用动量参数为 0.9 的 SGD 训练。初始学习率对小型 Inception 取 0.1,对小型 Alexnet 和多层感知机取 0.01,每个训练 epoch 的衰减因子为 0.95。除非另有说明,在随机化标签或像素的实验中,我们训练网络时不使用权重衰减、dropout 或其他形式的显式正则。第 3 节讨论了各种正则对拟合网络以及泛化的影响。
The ImageNet dataset contains 1,281,167 training and 50,000 validation images, split into 1000 classes. Each image is resized to 299x299 with 3 color channels. In the experiment on ImageNet, we use the Inception V3 (Szegedy et al., 2016) architecture and reuse the data preprocessing and experimental setup from the TensorFlow package. The data pipeline is extended to allow disabling of data augmentation and feeding random labels that are consistent across epochs. We run the ImageNet experiment in a distributed asynchronized SGD system with 50 workers.
ImageNet 数据集包含 1,281,167 张训练图像和 50,000 张验证图像,分成 1000 类。每张图像被调整到 299x299,有 3 个颜色通道。在 ImageNet 实验中,我们使用 Inception V3(Szegedy et al., 2016)结构,并复用 TensorFlow 包中的数据预处理和实验设置。数据流水线被扩展,以允许关闭数据增强,并馈入在各个 epoch 之间保持一致的随机标签。我们在一个有 50 个 worker 的分布式异步 SGD 系统中运行 ImageNet 实验。
Appendix B Detailed results on ImageNet
附录 B ImageNet 上的详细结果
| data aug | dropout | weight decay | top-1 train | top-5 train | top-1 test | top-5 test |
|---|---|---|---|---|---|---|
| ImageNet 1000 classes with the original labels | ||||||
| yes | yes | yes | 92.18 | 99.21 | 77.84 | 93.92 |
| yes | no | no | 92.33 | 99.17 | 72.95 | 90.43 |
| no | no | yes | 90.60 | 100.0 | 67.18 (72.57) | 86.44 (91.31) |
| no | no | no | 99.53 | 100.0 | 59.80 (63.16) | 80.38 (84.49) |
| Alexnet (Krizhevsky et al., 2012) | — | — | — | — | — | 83.6 |
| ImageNet 1000 classes with random labels | ||||||
| no | yes | yes | 91.18 | 97.95 | 0.09 | 0.49 |
| no | no | yes | 87.81 | 96.15 | 0.12 | 0.50 |
| no | no | no | 95.20 | 99.14 | 0.11 | 0.56 |
Table 2: The top-1 and top-5 accuracy (in percentage) of the Inception v3 model on the ImageNet dataset. We compare the training and test accuracy with various regularization turned on and off, for both true labels and random labels. The original reported top-5 accuracy of the Alexnet on ILSVRC 2012 is also listed for reference. The numbers in parentheses are the best test accuracy during training, as a reference for potential performance gain of early stopping.
| 数据增强 | dropout | 权重衰减 | top-1 训练 | top-5 训练 | top-1 测试 | top-5 测试 |
|---|---|---|---|---|---|---|
| ImageNet 1000 类,原始标签 | ||||||
| 是 | 是 | 是 | 92.18 | 99.21 | 77.84 | 93.92 |
| 是 | 否 | 否 | 92.33 | 99.17 | 72.95 | 90.43 |
| 否 | 否 | 是 | 90.60 | 100.0 | 67.18 (72.57) | 86.44 (91.31) |
| 否 | 否 | 否 | 99.53 | 100.0 | 59.80 (63.16) | 80.38 (84.49) |
| Alexnet(Krizhevsky et al., 2012) | — | — | — | — | — | 83.6 |
| ImageNet 1000 类,随机标签 | ||||||
| 否 | 是 | 是 | 91.18 | 97.95 | 0.09 | 0.49 |
| 否 | 否 | 是 | 87.81 | 96.15 | 0.12 | 0.50 |
| 否 | 否 | 否 | 95.20 | 99.14 | 0.11 | 0.56 |
表 2:Inception v3 模型在 ImageNet 数据集上的 top-1 和 top-5 准确率(百分比)。我们比较了打开和关闭各种正则时、分别在真实标签和随机标签上的训练与测试准确率。作为参考,也列出了 Alexnet 在 ILSVRC 2012 上原先报告的 top-5 准确率。括号中的数字是训练过程中的最佳测试准确率,作为早停可能带来的性能增益的参考。
Table 2 shows the performance on Imagenet with true labels and random labels, respectively.
表 2 分别给出了在 ImageNet 上使用真实标签和随机标签时的表现。
Appendix C Proof of Theorem 1
附录 C 定理 1 的证明
Lemma 1. For any two interleaving sequences of real numbers , the matrix has full rank. Its smallest eigenvalue is .
引理 1. 对任意两组交错的 个实数 , 矩阵 满秩。它的最小特征值是 。
Proof. By its definition, the matrix is lower triangular, that is, all entries with vanish. A basic linear algebra fact states that a lower-triangular matrix has full rank if and only if all of the entries on the diagional are nonzero. Since, , we have that . Hence, is invertible. The second claim follows directly from the fact that a lower-triangular matrix has all its eigenvalues on the main diagonal. This in turn follows from the first fact, since can have lower rank only if equals one of the diagonal values.
证明. 按定义,矩阵 是下三角的,也就是说所有 的元素都为零。线性代数的一个基本事实是:下三角矩阵满秩,当且仅当对角线上的元素都不为零。由于 ,我们有 。因此 可逆。第二个断言直接来自另一事实:下三角矩阵的全部特征值都在主对角线上。而这又可由第一个事实推出,因为只有当 等于某个对角元时, 才会降秩。
Proof of Theorem 1. For weight vectors and , consider the function ,
定理 1 的证明. 对权重向量 和 ,考虑函数 ,
It is easy to see that can be expressed by a depth 2 network with ReLU activations.
很容易看出, 可以用一个带 ReLU 激活的深度为 2 的网络来表达。
Now, fix a sample of size and a target vector . To prove the theorem, we need to find weights so that for all .
现在,固定一个大小为 的样本 和一个目标向量 。要证明该定理,我们需要找到权重 ,使得对所有 都有 。
First, choose and such that with we have the interleaving property . This is possible since all 's are distinct. Next, consider the set of equations in the unknowns ,
首先,选择 和 ,使得在 时具有交错性质 。由于所有 互不相同,这是可以做到的。接下来,考虑关于 个未知量 的 个方程,
We have , where is the matrix we encountered in Lemma 1. We chose and so that the lemma applies and hence has full rank. We can now solve the linear system to find suitable weights .
我们有 ,其中 就是引理 1 中遇到的那个矩阵。我们选择的 和 使该引理适用,因此 满秩。现在可以求解线性系统 ,以找到合适的权重 。
While the construction in the previous proof has inevitably high width given that the depth is 2, it is possible to trade width for depth. The construction is as follows. With the notation from the proof and assuming w.l.o.g. that , partition the interval into disjoint intervals so that each interval contains points. At layer , apply the construction from the proof to all points in . This requires nodes at level . This construction results in a circuit of width and depth which so far has outputs (one from each layer). It remains to implement a multiplexer which selects one of the outputs based on which interval a given input falls into. This boils down to implementing one (approximate) indicator function for each interval and outputting , where is the output of layer . This results in a single output circuit. Implementing a single indicator function requires constant size and depth with ReLU activiations. Hence, the final size of the construction is and the depth is for some constant . Setting gives the next corollary.
前面的证明中的构造,在深度为 2 的前提下宽度必然很大,但宽度和深度是可以互换的。构造如下。沿用证明中的记号,并不妨假设 ,把区间 划分成 个互不相交的区间 ,使每个区间 包含 个点。在第 层,对 中的所有点应用证明中的构造。这在第 层需要 个节点。这一构造得到一个宽度为 、深度为 的电路,到这一步它有 个输出(每层一个)。还需要实现一个多路选择器,根据给定输入 落入哪个区间,选出这 个输出中的一个。这归结为为每个区间 实现一个(近似的)指示函数 ,并输出 ,其中 是第 层的输出。这样就得到一个单输出电路。用 ReLU 激活实现单个指示函数只需要常数规模和常数深度。因此,最终构造的规模是 ,深度是 ,其中 是某个常数。令 ,就得到下面的推论。
Corollary 1. For every , there exists neural network with ReLU activations of depth , width and weights that can represent any function on a sample of size in dimensions.
推论 1. 对每个 ,都存在一个带 ReLU 激活、深度为 、宽度为 、权重个数为 的神经网络,能够表示 维空间中大小为 的样本上的任意函数。
Appendix D Results of implicit regularization for linear models
附录 D 线性模型隐式正则的结果
| data set | pre-processing | test error |
|---|---|---|
| MNIST | none | 1.2% |
| MNIST | gabor filters | 0.6% |
| CIFAR10 | none | 46% |
| CIFAR10 | random conv-net | 17% |
Table 3: Generalizing with kernels. The test error associated with solving the kernel equation (3) on small benchmarks. Note that changing the preprocessing can significantly change the resulting test error.
| 数据集 | 预处理 | 测试误差 |
|---|---|---|
| MNIST | 无 | 1.2% |
| MNIST | Gabor 滤波器 | 0.6% |
| CIFAR10 | 无 | 46% |
| CIFAR10 | 随机卷积网 | 17% |
表 3:用核方法泛化。在小型基准上求解核方程 (3) 得到的测试误差。注意,改变预处理会显著改变所得测试误差。
Table 3 list the experiment results of linear models described in Section 5.
表 3 列出了第 5 节所描述的线性模型的实验结果。
Appendix E Fitting random labels with explicit regularization
附录 E 用显式正则拟合随机标签
In Section 3, we showed that it is difficult to say that commonly used explicit regularizers count as a fundamental phase change in the generalization capability of deep nets. In this appendix, we add some experiments to investigate how explicit regularizers affect the ability to fit random labels.
在第 3 节中,我们说明了很难把常用的显式正则说成是深度网络泛化能力的一次根本性转变。在本附录中,我们补充一些实验,考察显式正则如何影响拟合随机标签的能力。
| Model | Regularizer | Training Accuracy |
|---|---|---|
| Inception | Weight decay | 100% |
| Alexnet | Weight decay | Failed to converge |
| MLP 3x512 | Weight decay | 100% |
| MLP 1x512 | Weight decay | 99.21% |
| Inception | Random Cropping[^3] | 99.93% |
| Inception | Augmentation[^4] | 99.28% |
Table 4: Results on fitting random labels on the CIFAR10 dataset with weight decay and data augmentation.
| 模型 | 正则 | 训练准确率 |
|---|---|---|
| Inception | 权重衰减 | 100% |
| Alexnet | 权重衰减 | 未能收敛 |
| MLP 3x512 | 权重衰减 | 100% |
| MLP 1x512 | 权重衰减 | 99.21% |
| Inception | 随机裁剪[^3] | 99.93% |
| Inception | 数据增强[^4] | 99.28% |
表 4:在 CIFAR10 数据集上,用权重衰减和数据增强拟合随机标签的结果。
From Table 4, we can see that for weight decay using the default coefficient for each model, except Alexnet, all other models are still able to fit random labels. We also tested random cropping and data augmentation with the Inception architecture. By changing the default weight decay factor from 0.95 to 0.999, and running for more epochs, we observe overfitting to random labels in both cases. It is expected to take longer to converge because data augmentation explodes the training set size (though many samples are not i.i.d. any more).
由表 4 可见,对各模型使用默认系数的权重衰减时,除 Alexnet 外,其他模型仍然能够拟合随机标签。我们也用 Inception 结构测试了随机裁剪和数据增强。把默认的权重衰减因子从 0.95 改成 0.999,并运行更多 epoch 之后,我们在这两种情形下都观察到了对随机标签的过拟合。收敛需要更长时间是预期之中的,因为数据增强会把训练集规模急剧放大(尽管许多样本已经不再是独立同分布的)。
Footnotes
脚注
[^1] We say “potentially” because to make this statement rigorous, we need to have another isolated test set and test the performance there when we choose early stopping point on the first test set (acting like a validation set).
[^1] 我们说“有可能”,是因为要把这句话说严格,还需要另有一个隔离的测试集:在第一个测试集(相当于验证集)上选定早停点后,再到那个隔离测试集上去测表现。
[^2] This conv-net is the Coates & Ng (2012) net, but with the filters selected at random instead of with k-means.
[^2] 这个卷积网是 Coates & Ng (2012) 的网络,但滤波器是随机选取的,而不是用 k-means 选取的。
[^3] In random cropping and augmentation, a new randomly modified image is used in each epoch, but the (randomly assigned) labels are kept consistent for all the epochs. The “training accuracy” means a slightly different thing here as the training set is different in each epoch. The global average of the online accuracy at each mini-batch on the augmented samples is reported here.
[^3] 在随机裁剪和数据增强中,每个 epoch 都使用一张新的随机修改图像,但(随机指定的)标签在所有 epoch 中保持一致。这里的“训练准确率”含义略有不同,因为每个 epoch 的训练集都不同。这里报告的是在增强样本上、每个小批量的在线准确率的全局平均。
[^4] Data augmentation includes random left-right flipping and random rotation up to 25 degrees.
[^4] 数据增强包括随机左右翻转,以及最大 25 度的随机旋转。
References
参考文献
Martı́n Abadi, Ashish Agarwal, Paul Barham, Eugene Brevdo, Zhifeng Chen, Craig Citro, Greg S. Corrado, Andy Davis, Jeffrey Dean, Matthieu Devin, Sanjay Ghemawat, Ian Goodfellow, Andrew Harp, Geoffrey Irving, Michael Isard, Yangqing Jia, Rafal Jozefowicz, Lukasz Kaiser, Manjunath Kudlur, Josh Levenberg, Dan Mané, Rajat Monga, Sherry Moore, Derek Murray, Chris Olah, Mike Schuster, Jonathon Shlens, Benoit Steiner, Ilya Sutskever, Kunal Talwar, Paul Tucker, Vincent Vanhoucke, Vijay Vasudevan, Fernanda Viégas, Oriol Vinyals, Pete Warden, Martin Wattenberg, Martin Wicke, Yuan Yu, and Xiaoqiang Zheng. TensorFlow: Large-scale machine learning on heterogeneous systems, 2015. URL http://tensorflow.org/. Software available from tensorflow.org.
Peter L Bartlett. The Sample Complexity of Pattern Classification with Neural Networks - The Size of the Weights is More Important than the Size of the Network. IEEE Trans. Information Theory, 1998.
Peter L Bartlett and Shahar Mendelson. Rademacher and gaussian complexities: risk bounds and structural results. Journal of Machine Learning Research, 3:463–482, March 2003.
Olivier Bousquet and André Elisseeff. Stability and generalization. Journal of Machine Learning Research, 2:499–526, March 2002.
Anna Choromanska, Mikael Henaff, Michael Mathieu, Gérard Ben Arous, and Yann LeCun. The loss surfaces of multilayer networks. In AISTATS, 2015.
Adam Coates and Andrew Y. Ng. Learning feature representations with k-means. In Neural Networks: Tricks of the Trade, Reloaded. Springer, 2012.
Nadav Cohen and Amnon Shashua. Convolutional Rectifier Networks as Generalized Tensor Decompositions. In ICML, 2016.
G Cybenko. Approximation by superposition of sigmoidal functions. Mathematics of Control, Signals and Systems, 2(4):303–314, 1989.
Olivier Delalleau and Yoshua Bengio. Shallow vs. Deep Sum-Product Networks. In Advances in Neural Information Processing Systems, 2011.
E. Edgington and P. Onghena. Randomization Tests. Statistics: A Series of Textbooks and Monographs. Taylor & Francis, 2007. ISBN 9781584885894.
Ronen Eldan and Ohad Shamir. The Power of Depth for Feedforward Neural Networks. In COLT, 2016.
Moritz Hardt, Benjamin Recht, and Yoram Singer. Train faster, generalize better: Stability of stochastic gradient descent. In ICML, 2016.
Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep Residual Learning for Image Recognition. In CVPR, 2016.
Sergey Ioffe and Christian Szegedy. Batch Normalization: Accelerating Deep Network Training by Reducing Internal Covariate Shift. In ICML, 2015.
Alex Krizhevsky and Geoffrey Hinton. Learning multiple layers of features from tiny images. Technical report, Department of Computer Science, University of Toronto, 2009.
Alex Krizhevsky, Ilya Sutskever, and Geoffrey E Hinton. ImageNet Classification with Deep Convolutional Neural Networks. In Advances in Neural Information Processing Systems, 2012.
Junhong Lin, Raffaello Camoriano, and Lorenzo Rosasco. Generalization Properties and Implicit Regularization for Multiple Passes SGM. In ICML, 2016.
Roi Livni, Shai Shalev-Shwartz, and Ohad Shamir. On the computational efficiency of training neural networks. In Advances in Neural Information Processing Systems, 2014.
Hrushikesh Mhaskar and Tomaso A. Poggio. Deep vs. shallow networks : An approximation theory perspective. CoRR, abs/1608.03287, 2016. URL http://arxiv.org/abs/1608.03287.
Hrushikesh Narhar Mhaskar. Approximation properties of a multilayered feedforward artificial neural network. Advances in Computational Mathematics, 1(1):61–80, 1993.
Sayan Mukherjee, Partha Niyogi, Tomaso Poggio, and Ryan Rifkin. Statistical learning: Stability is sufficient for generalization and necessary and sufficient for consistency of empirical risk minimization. Technical Report AI Memo 2002-024, Massachusetts Institute of Technology, 2002.
Behnam Neyshabur, Ryota Tomioka, and Nathan Srebro. In search of the real inductive bias: On the role of implicit regularization in deep learning. CoRR, abs/1412.6614, 2014.
Behnam Neyshabur, Ryota Tomioka, and Nathan Srebro. Norm-Based Capacity Control in Neural Networks. In COLT, pp. 1376–1401, 2015.
Tomaso Poggio, Ryan Rifkin, Sayan Mukherjee, and Partha Niyogi. General conditions for predictivity in learning theory. Nature, 428(6981):419–422, 2004.
Olga Russakovsky, Jia Deng, Hao Su, Jonathan Krause, Sanjeev Satheesh, Sean Ma, Zhiheng Huang, Andrej Karpathy, Aditya Khosla, Michael Bernstein, Alexander C. Berg, and Li FeiFei. Imagenet large scale visual recognition challenge. International Journal of Computer Vision, 115(3):211–252, 2015. ISSN 1573-1405. doi: 10.1007/s11263-015-0816-y.
Bernhard Schölkopf, Ralf Herbrich, and Alex J Smola. A generalized representer theorem. In COLT, 2001.
Shai Shalev-Shwartz, Ohad Shamir, Nathan Srebro, and Karthik Sridharan. Learnability, stability and uniform convergence. Journal of Machine Learning Research, 11:2635–2670, October 2010.
Nitish Srivastava, Geoffrey E Hinton, Alex Krizhevsky, Ilya Sutskever, and Ruslan Salakhutdinov. Dropout: a simple way to prevent neural networks from overfitting. Journal of Machine Learning Research, 15(1):1929–1958, 2014.
Christian Szegedy, Vincent Vanhoucke, Sergey Ioffe, Jonathon Shlens, and Zbigniew Wojna. Rethinking the inception architecture for computer vision. In CVPR, pp. 2818–2826, 2016. doi: 10.1109/CVPR.2016.308.
Matus Telgarsky. Benefits of depth in neural networks. In COLT, 2016.
Vladimir N. Vapnik. Statistical Learning Theory. Adaptive and learning systems for signal processing, communications, and control. Wiley, 1998.
Yuan Yao, Lorenzo Rosasco, and Andrea Caponnetto. On early stopping in gradient descent learning. Constructive Approximation, 26(2):289–315, 2007.