ResNeXt:在深度和宽度之外,把基数当成第三维
Aggregated Residual Transformations for Deep Neural Networks
深度神经网络的聚合残差变换
Saining Xie Affiliation: UC San Diego Ross Girshick Affiliation: Facebook AI Research {s9xie,ztu}@ucsd.edu{rbg,pdollar,kaiminghe}@fb.com Piotr Dollár Affiliation: Facebook AI Research {s9xie,ztu}@ucsd.edu{rbg,pdollar,kaiminghe}@fb.com Zhuowen Tu Affiliation: UC San Diego Kaiming He Affiliation: Facebook AI Research {s9xie,ztu}@ucsd.edu{rbg,pdollar,kaiminghe}@fb.com
Abstract
摘要
We present a simple, highly modularized network architecture for image classification. Our network is constructed by repeating a building block that aggregates a set of transformations with the same topology. Our simple design results in a homogeneous, multi-branch architecture that has only a few hyper-parameters to set. This strategy exposes a new dimension, which we call ‘‘cardinality’’ (the size of the set of transformations), as an essential factor in addition to the dimensions of depth and width. On the ImageNet-1K dataset, we empirically show that even under the restricted condition of maintaining complexity, increasing cardinality is able to improve classification accuracy. Moreover, increasing cardinality is more effective than going deeper or wider when we increase the capacity. Our models, named ResNeXt, are the foundations of our entry to the ILSVRC 2016 classification task in which we secured 2nd place. We further investigate ResNeXt on an ImageNet-5K set and the COCO detection set, also showing better results than its ResNet counterpart. The code and models are publicly available online[^1].
我们提出一种简单且高度模块化的图像分类网络架构。网络由重复的构建块组成,每个构建块聚合一组拓扑相同的变换。该简洁设计得到同质的多分支结构,只需设定少数超参数。这一策略揭示出一个新维度——我们称之为「基数」(cardinality,即变换集合的大小)——它与深度、宽度一样是关键因素。在 ImageNet-1K 上,我们经验表明:即便在保持复杂度不变的受限条件下,增大基数也能提升分类精度;在扩大容量时,增大基数比加深或加宽更有效。我们的模型命名为 ResNeXt,是我们参加 ILSVRC 2016 分类任务并获得第二名的基础。我们还在 ImageNet-5K 与 COCO 检测集上考察 ResNeXt,同样优于对应的 ResNet。代码与模型已公开[^1]。
1 Introduction
1 引言
Research on visual recognition is undergoing a transition from “feature engineering” to “network engineering” LeCun1989; Krizhevsky2012; Zeiler2014; Sermanet2014; Simonyan2015; Szegedy2015; He2016. In contrast to traditional hand-designed features (e.g., SIFT Lowe2004 and HOG Dalal2005), features learned by neural networks from large-scale data Russakovsky2015 require minimal human involvement during training, and can be transferred to a variety of recognition tasks Donahue2014; Girshick2014; Long2015. Nevertheless, human effort has been shifted to designing better network architectures for learning representations.
视觉识别研究正从「特征工程」转向「网络工程」LeCun1989;Krizhevsky2012;Zeiler2014;Sermanet2014;Simonyan2015;Szegedy2015;He2016。相对传统手工特征(例如 SIFT Lowe2004 与 HOG Dalal2005),神经网络从大规模数据 Russakovsky2015 学到的特征在训练中几乎不需人工介入,并可迁移到多种识别任务 Donahue2014;Girshick2014;Long2015。然而,人力已转移到设计更好的网络架构以学习表示。
Designing architectures becomes increasingly difficult with the growing number of hyper-parameters (width[^2], filter sizes, strides, etc.), especially when there are many layers. The VGG-nets Simonyan2015 exhibit a simple yet effective strategy of constructing very deep networks: stacking building blocks of the same shape. This strategy is inherited by ResNets He2016 which stack modules of the same topology. This simple rule reduces the free choices of hyper-parameters, and depth is exposed as an essential dimension in neural networks. Moreover, we argue that the simplicity of this rule may reduce the risk of over-adapting the hyper-parameters to a specific dataset. The robustness of VGG-nets and ResNets has been proven by various visual recognition tasks Donahue2014; Girshick2014; Girshick2015; Long2015; Pinheiro2015; He2016 and by non-visual tasks involving speech Xiong2016; Oord2016 and language Conneau2016; Wu2016; Kalchbrenner2016.
随着超参数(宽度[^2]、滤波器大小、步长,等)增多,尤其层数很多时,架构设计越来越难。VGG-nets Simonyan2015 展示了一种构造很深网络的简单有效策略:堆叠形状相同的构建块。ResNets He2016 继承了这一策略,堆叠拓扑相同的模块。该简单规则减少了超参数的自由选择,并把深度暴露为神经网络的关键维度。此外,我们认为这一规则的简洁性可能降低超参数过度适配某一数据集的风险。VGG-nets 与 ResNets 的鲁棒性已在多种视觉识别任务 Donahue2014;Girshick2014;Girshick2015;Long2015;Pinheiro2015;He2016 以及语音 Xiong2016;Oord2016 与语言 Conneau2016;Wu2016;Kalchbrenner2016 等非视觉任务中得到验证。
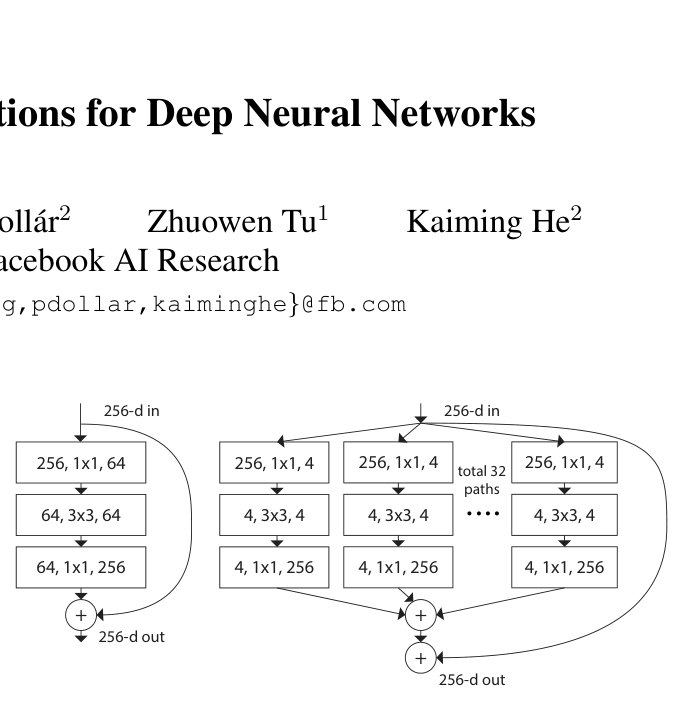
Figure 1: Left: A block of ResNet He2016. Right: A block of ResNeXt with cardinality , with roughly the same complexity. A layer is shown as (# in channels, filter size, # out channels).
图 1:左:ResNet He2016 的一个块。右:基数 、复杂度大致相同的 ResNeXt 块。一层表示为(输入通道数,滤波器大小,输出通道数)。
Unlike VGG-nets, the family of Inception models Szegedy2015; Ioffe2015; Szegedy2016a; Szegedy2016 have demonstrated that carefully designed topologies are able to achieve compelling accuracy with low theoretical complexity. The Inception models have evolved over time Szegedy2015; Szegedy2016a, but an important common property is a split-transform-merge strategy. In an Inception module, the input is split into a few lower-dimensional embeddings (by 11 convolutions), transformed by a set of specialized filters (33, 55, etc.), and merged by concatenation. It can be shown that the solution space of this architecture is a strict subspace of the solution space of a single large layer (e.g., 55) operating on a high-dimensional embedding. The split-transform-merge behavior of Inception modules is expected to approach the representational power of large and dense layers, but at a considerably lower computational complexity.
与 VGG-nets 不同,Inception 模型族 Szegedy2015;Ioffe2015;Szegedy2016a;Szegedy2016 表明:仔细设计的拓扑能以较低理论复杂度达到有竞争力的精度。Inception 模型随时间演进 Szegedy2015;Szegedy2016a,但一个重要共性是 分裂—变换—合并 策略。在 Inception 模块中,输入被分裂为若干低维嵌入(由 11 卷积),经一组专用滤波器(33、55,等)变换,再经拼接合并。可以证明,该架构的解空间是在高维嵌入上操作的单个大层(例如 55)解空间的严格子空间。Inception 模块的分裂—变换—合并行为有望接近大且稠密层的表示能力,但计算复杂度显著更低。
Despite good accuracy, the realization of Inception models has been accompanied with a series of complicating factors — the filter numbers and sizes are tailored for each individual transformation, and the modules are customized stage-by-stage. Although careful combinations of these components yield excellent neural network recipes, it is in general unclear how to adapt the Inception architectures to new datasets/tasks, especially when there are many factors and hyper-parameters to be designed.
尽管精度不错,Inception 模型的实现伴随着一系列复杂因素——各变换的滤波器数量与大小被单独定制,模块也按阶段定制。虽然这些组件的仔细组合能产出优秀的神经网络配方,但总体而言不清楚如何把 Inception 架构适配到新数据集/任务,尤其当有许多因素与超参数需要设计时。
In this paper, we present a simple architecture which adopts VGG/ResNets’ strategy of repeating layers, while exploiting the split-transform-merge strategy in an easy, extensible way. A module in our network performs a set of transformations, each on a low-dimensional embedding, whose outputs are aggregated by summation. We pursuit a simple realization of this idea — the transformations to be aggregated are all of the same topology (e.g., Fig. 1 (right)). This design allows us to extend to any large number of transformations without specialized designs.
本文提出一种简单架构:采用 VGG/ResNets 的重复层策略,同时以易扩展的方式利用分裂—变换—合并策略。网络中的模块对一组变换各自在低维嵌入上执行,再将输出求和聚合。我们追求该想法的简单实现——待聚合的变换全部拓扑相同(例如 图 1(右))。这一设计使我们能扩展到任意多的变换,而无需专门设计。
Interestingly, under this simplified situation we show that our model has two other equivalent forms (Fig. 3). The reformulation in Fig. 3(b) appears similar to the Inception-ResNet module Szegedy2016 in that it concatenates multiple paths; but our module differs from all existing Inception modules in that all our paths share the same topology and thus the number of paths can be easily isolated as a factor to be investigated. In a more succinct reformulation, our module can be reshaped by Krizhevsky et al.’s grouped convolutions Krizhevsky2012 (Fig. 3(c)), which, however, had been developed as an engineering compromise.
有趣的是,在这一简化情形下,我们的模型还有另外两种等价形式(图 3)。图 3(b) 的改写看起来类似 Inception-ResNet 模块 Szegedy2016,因为它拼接多条路径;但我们的模块与所有现有 Inception 模块不同之处在于:所有路径共享相同拓扑,因而路径数可轻松隔离为一个待考察因素。在更简洁的改写中,我们的模块可用 Krizhevsky et al. 的分组卷积 Krizhevsky2012 重塑(图 3(c)),而后者当初只是工程折中。
We empirically demonstrate that our aggregated transformations outperform the original ResNet module, even under the restricted condition of maintaining computational complexity and model size — e.g., Fig. 1(right) is designed to keep the FLOPs complexity and number of parameters of Fig. 1(left). We emphasize that while it is relatively easy to increase accuracy by increasing capacity (going deeper or wider), methods that increase accuracy while maintaining (or reducing) complexity are rare in the literature.
我们经验表明:即便在保持计算复杂度与模型规模的受限条件下,聚合变换也优于原版 ResNet 模块——例如 图 1(右)被设计为保持图 1(左)的 FLOPs 复杂度与参数量。我们强调:通过增大容量(加深或加宽)来提升精度相对容易,而在保持(或降低)复杂度的同时提升精度的方法在文献中并不多见。
Our method indicates that cardinality (the size of the set of transformations) is a concrete, measurable dimension that is of central importance, in addition to the dimensions of width and depth. Experiments demonstrate that increasing cardinality is a more effective way of gaining accuracy than going deeper or wider, especially when depth and width starts to give diminishing returns for existing models.
我们的方法表明,基数(变换集合的大小)是一个具体、可度量、且至关重要的维度,与宽度和深度并列。实验表明,增大基数比加深或加宽更能有效提升精度,尤其当现有模型的深度与宽度已开始收益递减时。
Our neural networks, named ResNeXt (suggesting the next dimension), outperform ResNet-101/152 He2016, ResNet-200 He2016a, Inception-v3 Szegedy2016a, and Inception-ResNet-v2 Szegedy2016 on the ImageNet classification dataset. In particular, a 101-layer ResNeXt is able to achieve better accuracy than ResNet-200 He2016a but has only 50% complexity. Moreover, ResNeXt exhibits considerably simpler designs than all Inception models. ResNeXt was the foundation of our submission to the ILSVRC 2016 classification task, in which we secured second place. This paper further evaluates ResNeXt on a larger ImageNet-5K set and the COCO object detection dataset Lin2014, showing consistently better accuracy than its ResNet counterparts. We expect that ResNeXt will also generalize well to other visual (and non-visual) recognition tasks.
我们的神经网络命名为 ResNeXt(暗示 下一个 维度),在 ImageNet 分类数据集上优于 ResNet-101/152 He2016、ResNet-200 He2016a、Inception-v3 Szegedy2016a 与 Inception-ResNet-v2 Szegedy2016。特别是,101 层 ResNeXt 能达到优于 ResNet-200 He2016a 的精度,但复杂度仅约 50%。此外,ResNeXt 的设计远比所有 Inception 模型简单。ResNeXt 是我们提交 ILSVRC 2016 分类任务并获第二名的基础。本文还在更大的 ImageNet-5K 集合与 COCO 目标检测数据集 Lin2014 上评估 ResNeXt,同样优于对应 ResNet。我们预期 ResNeXt 也能很好泛化到其他视觉(及非视觉)识别任务。
2 Related Work
2 相关工作
Multi-branch convolutional networks. The Inception models Szegedy2015; Ioffe2015; Szegedy2016a; Szegedy2016 are successful multi-branch architectures where each branch is carefully customized. ResNets He2016 can be thought of as two-branch networks where one branch is the identity mapping. Deep neural decision forests Kontschieder2015 are tree-patterned multi-branch networks with learned splitting functions.
多分支卷积网络。Inception 模型 Szegedy2015;Ioffe2015;Szegedy2016a;Szegedy2016 是成功的多分支架构,各分支被仔细定制。ResNets He2016 可视为两分支网络,其中一支是恒等映射。深度神经决策森林 Kontschieder2015 是带有可学习分裂函数的树状多分支网络。
Grouped convolutions. The use of grouped convolutions dates back to the AlexNet paper Krizhevsky2012, if not earlier. The motivation given by Krizhevsky et al. Krizhevsky2012 is for distributing the model over two GPUs. Grouped convolutions are supported by Caffe Jia2014, Torch Collobert2002, and other libraries, mainly for compatibility of AlexNet. To the best of our knowledge, there has been little evidence on exploiting grouped convolutions to improve accuracy. A special case of grouped convolutions is channel-wise convolutions in which the number of groups is equal to the number of channels. Channel-wise convolutions are part of the separable convolutions in Sifre2014.
分组卷积。分组卷积的使用至少可追溯到 AlexNet 论文 Krizhevsky2012。Krizhevsky et al. Krizhevsky2012 给出的动机是把模型分布到两块 GPU。Caffe Jia2014、Torch Collobert2002 及其他库支持分组卷积,主要是为了兼容 AlexNet。据我们所知,几乎没有证据表明利用分组卷积来提升精度。分组卷积的一个特例是通道卷积,即组数等于通道数。通道卷积是 Sifre2014 中可分离卷积的一部分。
Compressing convolutional networks. Decomposition (at spatial Denton2014; Jaderberg2014 and/or channel Denton2014; Kim2016; Ioannou2016 level) is a widely adopted technique to reduce redundancy of deep convolutional networks and accelerate/compress them. Ioannou et al. Ioannou2016 present a “root”-patterned network for reducing computation, and branches in the root are realized by grouped convolutions. These methods Denton2014; Jaderberg2014; Kim2016; Ioannou2016 have shown elegant compromise of accuracy with lower complexity and smaller model sizes. Instead of compression, our method is an architecture that empirically shows stronger representational power.
压缩卷积网络。分解(在空间 Denton2014;Jaderberg2014 和/或通道 Denton2014;Kim2016;Ioannou2016 层面)是降低深度卷积网络冗余并加速/压缩的常用技术。Ioannou et al. Ioannou2016 提出「根」状网络以减少计算,根中的分支由分组卷积实现。这些方法 Denton2014;Jaderberg2014;Kim2016;Ioannou2016 在较低复杂度与更小模型下展现了优雅的精度折中。我们的方法不是压缩,而是经验上展示更强表示能力的架构。
Ensembling. Averaging a set of independently trained networks is an effective solution to improving accuracy Krizhevsky2012, widely adopted in recognition competitions Russakovsky2015. Veit et al. Veit2016 interpret a single ResNet as an ensemble of shallower networks, which results from ResNet’s additive behaviors He2016a. Our method harnesses additions to aggregate a set of transformations. But we argue that it is imprecise to view our method as ensembling, because the members to be aggregated are trained jointly, not independently.
集成。平均一组独立训练的网络是提升精度的有效方案 Krizhevsky2012,在识别竞赛中广泛采用 Russakovsky2015。Veit et al. Veit2016 把单个 ResNet 解释为较浅网络的集成,这源于 ResNet 的加法行为 He2016a。我们的方法用加法聚合一组变换。但我们认为不宜把本方法视为集成,因为被聚合的成员是联合训练而非独立训练的。
3 Method
3 方法
3.1 Template
3.1 模板
We adopt a highly modularized design following VGG/ResNets. Our network consists of a stack of residual blocks. These blocks have the same topology, and are subject to two simple rules inspired by VGG/ResNets: (i) if producing spatial maps of the same size, the blocks share the same hyper-parameters (width and filter sizes), and (ii) each time when the spatial map is downsampled by a factor of 2, the width of the blocks is multiplied by a factor of 2. The second rule ensures that the computational complexity, in terms of FLOPs (floating-point operations, in # of multiply-adds), is roughly the same for all blocks.
我们沿用 VGG/ResNets 的高度模块化设计。网络由残差块堆叠而成。这些块拓扑相同,并遵循受 VGG/ResNets 启发的两条简单规则:(i) 若产生相同大小的空间特征图,则块共享相同超参数(宽度与滤波器大小);(ii) 每当空间特征图按因子 2 下采样时,块的宽度也乘以因子 2。第二条规则保证以 FLOPs(浮点运算,乘加次数)衡量的计算复杂度在所有块上大致相同。
With these two rules, we only need to design a template module, and all modules in a network can be determined accordingly. So these two rules greatly narrow down the design space and allow us to focus on a few key factors. The networks constructed by these rules are in Table 1.
有了这两条规则,我们只需设计一个模板模块,网络中所有模块即可据此确定。因此这两条规则大大缩小了设计空间,使我们能聚焦少数关键因素。按这些规则构造的网络见表 1。
| stage | output | ResNet-50 | ResNeXt-50 (324d) |
|---|---|---|---|
| conv1 | 112112 | 77, 64, stride 2 | 77, 64, stride 2 |
| conv2 | 5656 | 33 max pool, stride 2 | 33 max pool, stride 2 |
| \left[\begin{array}[]{l}\text{1\times1, 64}\\[-0.85005pt] \text{3\times3, 64}\\[-0.85005pt] \text{1\times1, 256}\end{array}\right]3 | \left[\begin{array}[]{l}\text{1\times1, 128}\\[-0.85005pt] \text{3\timesC=32}\\[-0.85005pt] \text{1\times1, 256}\\ \end{array}\right]3 | ||
| conv3 | 2828 | \left[\begin{array}[]{l}\text{1\times1, 128}\\[-0.85005pt] \text{3\times3, 128}\\[-0.85005pt] \text{1\times1, 512}\end{array}\right]4 | \left[\begin{array}[]{l}\text{1\times1, 256}\\[-0.85005pt] \text{3\timesC=32}\\[-0.85005pt] \text{1\times1, 512}\\ \end{array}\right]4 |
| conv4 | 1414 | \left[\begin{array}[]{l}\text{1\times1, 256}\\[-0.85005pt] \text{3\times3, 256}\\[-0.85005pt] \text{1\times1, 1024}\end{array}\right]6 | \left[\begin{array}[]{l}\text{1\times1, 512}\\[-0.85005pt] \text{3\timesC=32}\\[-0.85005pt] \text{1\times1, 1024}\\ \end{array}\right]6 |
| conv5 | 77 | \left[\begin{array}[]{l}\text{1\times1, 512}\\[-0.85005pt] \text{3\times3, 512}\\[-0.85005pt] \text{1\times1, 2048}\end{array}\right]3 | \left[\begin{array}[]{l}\text{1\times1, 1024}\\[-0.85005pt] \text{3\timesC=32}\\[-0.85005pt] \text{1\times1, 2048}\\ \end{array}\right]3 |
| 11 | global average pool | global average pool | |
| 1000-d fc, softmax | 1000-d fc, softmax | ||
| # params. | 25.5 | 25.0 | |
| FLOPs | 4.1 | 4.2 |
Table 1: (Left) ResNet-50. (Right) ResNeXt-50 with a 324d template (using the reformulation in Fig. 3(c)). Inside the brackets are the shape of a residual block, and outside the brackets is the number of stacked blocks on a stage. “=32” suggests grouped convolutions Krizhevsky2012 with 32 groups. The numbers of parameters and FLOPs are similar between these two models.
| stage | output | ResNet-50 | ResNeXt-50 (324d) |
|---|---|---|---|
| conv1 | 112112 | 77, 64, stride 2 | 77, 64, stride 2 |
| conv2 | 5656 | 33 max pool, stride 2 | 33 max pool, stride 2 |
| \left[\begin{array}[]{l}\text{1\times1, 64}\\[-0.85005pt] \text{3\times3, 64}\\[-0.85005pt] \text{1\times1, 256}\end{array}\right]3 | \left[\begin{array}[]{l}\text{1\times1, 128}\\[-0.85005pt] \text{3\timesC=32}\\[-0.85005pt] \text{1\times1, 256}\\ \end{array}\right]3 | ||
| conv3 | 2828 | \left[\begin{array}[]{l}\text{1\times1, 128}\\[-0.85005pt] \text{3\times3, 128}\\[-0.85005pt] \text{1\times1, 512}\end{array}\right]4 | \left[\begin{array}[]{l}\text{1\times1, 256}\\[-0.85005pt] \text{3\timesC=32}\\[-0.85005pt] \text{1\times1, 512}\\ \end{array}\right]4 |
| conv4 | 1414 | \left[\begin{array}[]{l}\text{1\times1, 256}\\[-0.85005pt] \text{3\times3, 256}\\[-0.85005pt] \text{1\times1, 1024}\end{array}\right]6 | \left[\begin{array}[]{l}\text{1\times1, 512}\\[-0.85005pt] \text{3\timesC=32}\\[-0.85005pt] \text{1\times1, 1024}\\ \end{array}\right]6 |
| conv5 | 77 | \left[\begin{array}[]{l}\text{1\times1, 512}\\[-0.85005pt] \text{3\times3, 512}\\[-0.85005pt] \text{1\times1, 2048}\end{array}\right]3 | \left[\begin{array}[]{l}\text{1\times1, 1024}\\[-0.85005pt] \text{3\timesC=32}\\[-0.85005pt] \text{1\times1, 2048}\\ \end{array}\right]3 |
| 11 | global average pool | global average pool | |
| 1000-d fc, softmax | 1000-d fc, softmax | ||
| # params. | 25.5 | 25.0 | |
| FLOPs | 4.1 | 4.2 |
表 1:(左)ResNet-50。(右)采用图 3(c) 改写的 324d 模板 ResNeXt-50。括号内是残差块形状,括号外是该阶段堆叠块数。「=32」表示 32 组的分组卷积 Krizhevsky2012。两模型的参数量与 FLOPs 相近。
3.2 Revisiting Simple Neurons
3.2 重访简单神经元
The simplest neurons in artificial neural networks perform inner product (weighted sum), which is the elementary transformation done by fully-connected and convolutional layers. Inner product can be thought of as a form of aggregating transformation:
人工神经网络中最简单的神经元执行内积(加权和),这是全连接层与卷积层所做的基本变换。内积可视为一种聚合变换:
where is a -channel input vector to the neuron and is a filter’s weight for the -th channel. This operation (usually including some output non-linearity) is referred to as a “neuron”. See Fig. 2.
其中 是神经元的 通道输入向量, 是滤波器对第 通道的权重。该运算(通常含某种输出非线性)被称为「神经元」。见图 2。
The above operation can be recast as a combination of splitting, transforming, and aggregating. (i) Splitting: the vector is sliced as a low-dimensional embedding, and in the above, it is a single-dimension subspace . (ii) Transforming: the low-dimensional representation is transformed, and in the above, it is simply scaled: . (iii) Aggregating: the transformations in all embeddings are aggregated by .
上述运算可改写为 分裂、变换与聚合 的组合。(i) 分裂:向量 被切为低维嵌入;上式中即单维子空间 。(ii) 变换:对低维表示做变换;上式中即简单缩放 。(iii) 聚合:所有嵌入上的变换由 聚合。
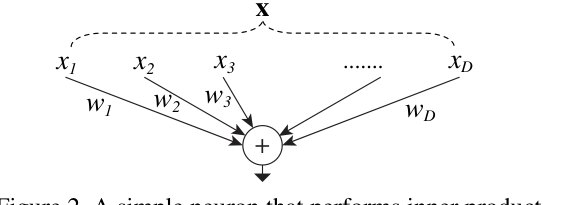
Figure 2: A simple neuron that performs inner product.
图 2:执行内积的简单神经元。
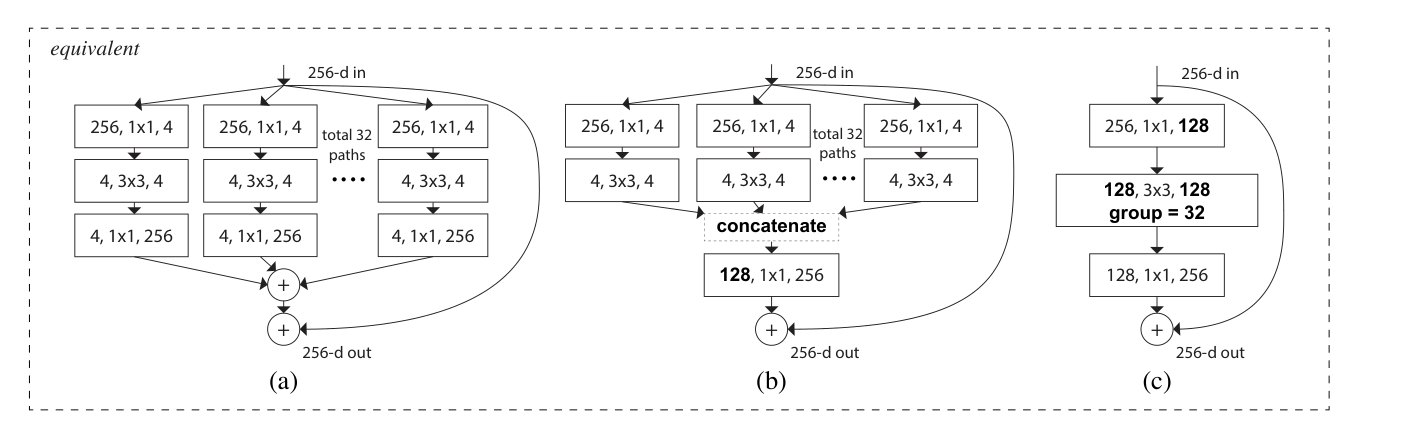
Figure 3: Equivalent building blocks of ResNeXt. (a): Aggregated residual transformations, the same as Fig. 1 right. (b): A block equivalent to (a), implemented as early concatenation. (c): A block equivalent to (a,b), implemented as grouped convolutions Krizhevsky2012. Notations in bold text highlight the reformulation changes. A layer is denoted as (# input channels, filter size, # output channels).
图 3:ResNeXt 的等价构建块。(a):聚合残差变换,与图 1 右相同。(b):与 (a) 等价的块,实现为早期拼接。(c):与 (a,b) 等价的块,实现为分组卷积 Krizhevsky2012。粗体文字标出改写变化。一层记为(输入通道数,滤波器大小,输出通道数)。
3.3 Aggregated Transformations
3.3 聚合变换
Given the above analysis of a simple neuron, we consider replacing the elementary transformation () with a more generic function, which in itself can also be a network. In contrast to “Network-in-Network” Lin2014a that turns out to increase the dimension of depth, we show that our “Network-in-Neuron” expands along a new dimension.
基于上述对简单神经元的分析,我们考虑把基本变换()替换为更通用的函数,而该函数本身也可以是一个网络。与最终增大深度维度的「Network-in-Network」Lin2014a 不同,我们表明「Network-in-Neuron」沿一个新维度扩展。
Formally, we present aggregated transformations as:
形式上,我们将聚合变换写为:
where can be an arbitrary function. Analogous to a simple neuron, should project into an (optionally low-dimensional) embedding and then transform it.
其中 可以是任意函数。类比简单神经元, 应将 投影到(可选的低维)嵌入,再加以变换。
In Eqn.(2), is the size of the set of transformations to be aggregated. We refer to as cardinality Cantor1884. In Eqn.(2) is in a position similar to in Eqn.(1), but need not equal and can be an arbitrary number. While the dimension of width is related to the number of simple transformations (inner product), we argue that the dimension of cardinality controls the number of more complex transformations. We show by experiments that cardinality is an essential dimension and can be more effective than the dimensions of width and depth.
在式 (2) 中, 是待聚合变换集合的大小。我们称 为 基数 Cantor1884。式 (2) 中 的位置类似式 (1) 中的 ,但 不必等于 ,可以为任意数。宽度维度与简单变换(内积)的数量相关,而我们认为基数维度控制更复杂变换的数量。实验表明基数是关键维度,可以比宽度与深度更有效。
In this paper, we consider a simple way of designing the transformation functions: all ’s have the same topology. This extends the VGG-style strategy of repeating layers of the same shape, which is helpful for isolating a few factors and extending to any large number of transformations. We set the individual transformation to be the bottleneck-shaped architecture He2016, as illustrated in Fig. 1 (right). In this case, the first 11 layer in each produces the low-dimensional embedding.
本文考虑一种简单的变换函数设计:所有 拓扑相同。这扩展了 VGG 式重复同形层的策略,有助于隔离少数因素并扩展到任意多的变换。我们将单个变换 设为瓶颈形状架构 He2016,如图 1(右)所示。此时每个 中的第一个 11 层产生低维嵌入。
The aggregated transformation in Eqn.(2) serves as the residual function He2016 (Fig. 1 right):
式 (2) 中的聚合变换作为残差函数 He2016(图 1 右):
where is the output.
其中 是输出。
Relation to Inception-ResNet. Some tensor manipulations show that the module in Fig. 1(right) (also shown in Fig. 3(a)) is equivalent to Fig. 3(b).[^3] Fig. 3(b) appears similar to the Inception-ResNet Szegedy2016 block in that it involves branching and concatenating in the residual function. But unlike all Inception or Inception-ResNet modules, we share the same topology among the multiple paths. Our module requires minimal extra effort designing each path.
与 Inception-ResNet 的关系。一些张量操作表明,图 1(右)中的模块(亦见图 3(a))等价于图 3(b)。[^3] 图 3(b) 看起来类似 Inception-ResNet Szegedy2016 块,因为它在残差函数中涉及分支与拼接。但与所有 Inception 或 Inception-ResNet 模块不同,我们在多条路径间共享相同拓扑。我们的模块几乎不需为每条路径额外设计。
Relation to Grouped Convolutions. The above module becomes more succinct using the notation of grouped convolutions Krizhevsky2012.[^4] This reformulation is illustrated in Fig. 3(c). All the low-dimensional embeddings (the first 11 layers) can be replaced by a single, wider layer (e.g., 11, 128-d in Fig 3(c)). Splitting is essentially done by the grouped convolutional layer when it divides its input channels into groups. The grouped convolutional layer in Fig. 3(c) performs 32 groups of convolutions whose input and output channels are 4-dimensional. The grouped convolutional layer concatenates them as the outputs of the layer. The block in Fig. 3(c) looks like the original bottleneck residual block in Fig. 1(left), except that Fig. 3(c) is a wider but sparsely connected module.
与分组卷积的关系。用 分组卷积 Krizhevsky2012 的记号,上述模块更加简洁。[^4] 该改写见图 3(c)。所有低维嵌入(第一个 11 层)可替换为单个更宽的层(例如 图 3(c) 中的 11、128-d)。当分组卷积层把输入通道分成若干组时,本质上完成了分裂。图 3(c) 中的分组卷积层执行 32 组卷积,其输入与输出通道均为 4 维,再将它们拼接为该层输出。图 3(c) 的块看起来像图 1(左)的原版瓶颈残差块,只是图 3(c) 是更宽但稀疏连接的模块。
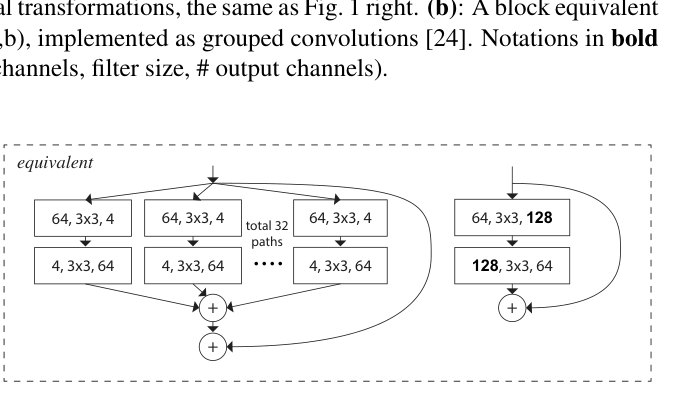
Figure 4: (Left): Aggregating transformations of depth . (Right): An equivalent block, which is trivially wider.
图 4:(左):深度 的聚合变换。(右):一个等价块,实际上只是更宽。
We note that the reformulations produce nontrivial topologies only when the block has depth 3. If the block has depth 2 (e.g., the basic block in He2016), the reformulations lead to trivially a wide, dense module. See the illustration in Fig. 4.
我们注意到,仅当块深度 3 时,这些改写才产生非平凡拓扑。若块深度 2(例如 He2016 中的基本块),改写只得到平凡的宽而稠密模块。见图 4。
Discussion. We note that although we present reformulations that exhibit concatenation (Fig. 3(b)) or grouped convolutions (Fig. 3(c)), such reformulations are not always applicable for the general form of Eqn.(3), e.g., if the transformation takes arbitrary forms and are heterogenous. We choose to use homogenous forms in this paper because they are simpler and extensible. Under this simplified case, grouped convolutions in the form of Fig. 3(c) are helpful for easing implementation.
讨论。我们指出:尽管给出了展现拼接(图 3(b))或分组卷积(图 3(c))的改写,此类改写并不总适用于式 (3) 的一般形式,例如 当变换 取任意形式且异质时。本文选择同质形式,因为更简单且可扩展。在此简化情形下,图 3(c) 形式的分组卷积有助于简化实现。
3.4 Model Capacity
3.4 模型容量
Our experiments in the next section will show that our models improve accuracy when maintaining the model complexity and number of parameters. This is not only interesting in practice, but more importantly, the complexity and number of parameters represent inherent capacity of models and thus are often investigated as fundamental properties of deep networks Eigen2013a.
下一节实验将表明:在保持模型复杂度与参数量时,我们的模型仍能提升精度。这不仅在实践中有趣,更重要的是,复杂度与参数量代表模型的固有容量,因而常被作为深度网络的基本性质加以研究 Eigen2013a。
When we evaluate different cardinalities while preserving complexity, we want to minimize the modification of other hyper-parameters. We choose to adjust the width of the bottleneck (e.g., 4-d in Fig 1(right)), because it can be isolated from the input and output of the block. This strategy introduces no change to other hyper-parameters (depth or input/output width of blocks), so is helpful for us to focus on the impact of cardinality.
在保持复杂度评估不同基数 时,我们希望尽量少改其他超参数。我们选择调节瓶颈宽度(例如 图 1(右)中的 4-d),因为它可与块的输入/输出隔离。该策略不改变其他超参数(深度或块的输入/输出宽度),有助于我们聚焦基数的影响。
In Fig. 1(left), the original ResNet bottleneck block He2016 has 70k parameters and proportional FLOPs (on the same feature map size). With bottleneck width , our template in Fig. 1(right) has:
在图 1(左)中,原版 ResNet 瓶颈块 He2016 约有 70k 参数及成比例的 FLOPs(在相同特征图大小上)。瓶颈宽度为 时,图 1(右)的模板有:
parameters and proportional FLOPs. When and , Eqn.(4) 70k. Table 2 shows the relationship between cardinality and bottleneck width .
参数及成比例的 FLOPs。当 且 时,式 (4) 70k。表 2 给出基数 与瓶颈宽度 的关系。
Because we adopt the two rules in Sec. 3.1, the above approximate equality is valid between a ResNet bottleneck block and our ResNeXt on all stages (except for the subsampling layers where the feature maps size changes). Table 1 compares the original ResNet-50 and our ResNeXt-50 that is of similar capacity.[^5] We note that the complexity can only be preserved approximately, but the difference of the complexity is minor and does not bias our results.
由于采用 3.1 节的两条规则,上述近似相等在所有阶段的 ResNet 瓶颈块与我们的 ResNeXt 之间成立(特征图大小改变的下采样层除外)。表 1 比较了原版 ResNet-50 与容量相近的 ResNeXt-50。[^5] 我们指出复杂度只能近似保持,但差异很小,不会偏向我们的结果。
| cardinality | 1 | 2 | 4 | 8 | 32 |
|---|---|---|---|---|---|
| width of bottleneck | 64 | 40 | 24 | 14 | 4 |
| width of group conv. | 64 | 80 | 96 | 112 | 128 |
Table 2: Relations between cardinality and width (for the template of conv2), with roughly preserved complexity on a residual block. The number of parameters is 70k for the template of conv2. The number of FLOPs is 0.22 billion (# params5656 for conv2).
| cardinality | 1 | 2 | 4 | 8 | 32 |
|---|---|---|---|---|---|
| width of bottleneck | 64 | 40 | 24 | 14 | 4 |
| width of group conv. | 64 | 80 | 96 | 112 | 128 |
表 2:基数与宽度的关系(针对 conv2 模板),残差块上大致保持复杂度。conv2 模板参数量约 70k。FLOPs 约 0.22 billion(# params5656,针对 conv2)。
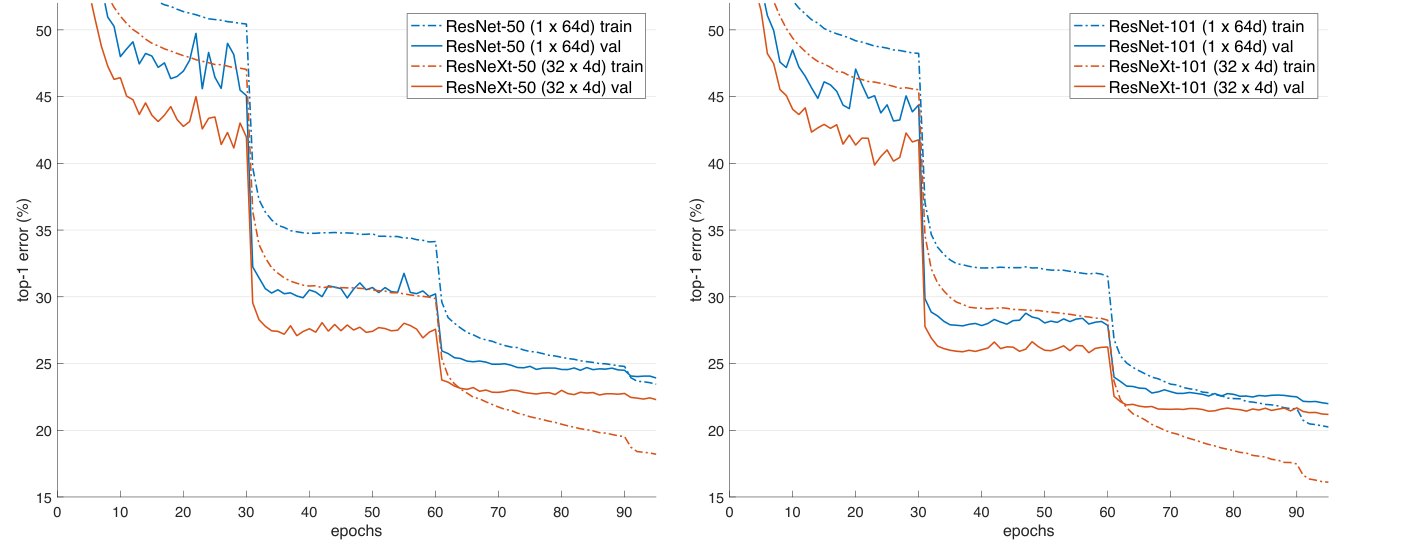
Figure 5: Training curves on ImageNet-1K. (Left): ResNet/ResNeXt-50 with preserved complexity (4.1 billion FLOPs, 25 million parameters); (Right): ResNet/ResNeXt-101 with preserved complexity (7.8 billion FLOPs, 44 million parameters).
图 5:ImageNet-1K 上的训练曲线。(左):保持复杂度的 ResNet/ResNeXt-50(4.1 billion FLOPs,25 million 参数);(右):保持复杂度的 ResNet/ResNeXt-101(7.8 billion FLOPs,44 million 参数)。
4 Implementation details
4 实现细节
Our implementation follows He2016 and the publicly available code of fb.resnet.torch Gross2016. On the ImageNet dataset, the input image is 224224 randomly cropped from a resized image using the scale and aspect ratio augmentation of Szegedy2015 implemented by Gross2016. The shortcuts are identity connections except for those increasing dimensions which are projections (type B in He2016). Downsampling of conv3, 4, and 5 is done by stride-2 convolutions in the 33 layer of the first block in each stage, as suggested in Gross2016. We use SGD with a mini-batch size of 256 on 8 GPUs (32 per GPU). The weight decay is 0.0001 and the momentum is 0.9. We start from a learning rate of 0.1, and divide it by 10 for three times using the schedule in Gross2016. We adopt the weight initialization of He2015. In all ablation comparisons, we evaluate the error on the single 224224 center crop from an image whose shorter side is 256.
我们的实现遵循 He2016 与公开代码 fb.resnet.torch Gross2016。在 ImageNet 上,输入图像为从缩放图像中按 Szegedy2015 的尺度与长宽比增强(由 Gross2016 实现)随机裁剪的 224224。捷径为恒等连接,维数增加处为投影(He2016 中的 B 型)。conv3、4、5 的下采样由各阶段第一个块中 33 层的 stride-2 卷积完成,如 Gross2016 所建议。我们使用 SGD,8 GPU 上 mini-batch 为 256(每 GPU 32)。权重衰减 0.0001,动量 0.9。学习率从 0.1 起步,按 Gross2016 的日程三次除以 10。采用 He2015 的权重初始化。所有消融比较中,我们在短边为 256 的图像上评估单个 224224 中心裁剪的误差。
Our models are realized by the form of Fig. 3(c). We perform batch normalization (BN) Ioffe2015 right after the convolutions in Fig. 3(c).[^6] ReLU is performed right after each BN, expect for the output of the block where ReLU is performed after the adding to the shortcut, following He2016.
我们的模型以图 3(c) 的形式实现。在图 3(c) 的卷积之后立即做批归一化(BN)Ioffe2015。[^6] 每次 BN 后立即做 ReLU,块输出除外——该处 ReLU 在与捷径相加之后进行,遵循 He2016。
We note that the three forms in Fig. 3 are strictly equivalent, when BN and ReLU are appropriately addressed as mentioned above. We have trained all three forms and obtained the same results. We choose to implement by Fig. 3(c) because it is more succinct and faster than the other two forms.
我们指出:当 BN 与 ReLU 按上述恰当处理后,图 3 的三种形式严格等价。我们训练了全部三种形式并得到相同结果。选择实现图 3(c) 是因为它比另两种更简洁、更快。
5 Experiments
5 实验
5.1 Experiments on ImageNet-1K
5.1 ImageNet-1K 实验
We conduct ablation experiments on the 1000-class ImageNet classification task Russakovsky2015. We follow He2016 to construct 50-layer and 101-layer residual networks. We simply replace all blocks in ResNet-50/101 with our blocks.
我们在 1000 类 ImageNet 分类任务 Russakovsky2015 上进行消融实验。遵循 He2016 构造 50 层与 101 层残差网络,并简单地把 ResNet-50/101 中的所有块替换为我们的块。
Notations. Because we adopt the two rules in Sec. 3.1, it is sufficient for us to refer to an architecture by the template. For example, Table 1 shows a ResNeXt-50 constructed by a template with cardinality and bottleneck width 4d (Fig. 3). This network is denoted as ResNeXt-50 (324d) for simplicity. We note that the input/output width of the template is fixed as 256-d (Fig. 3), and all widths are doubled each time when the feature map is subsampled (see Table 1).
记号。由于采用 3.1 节的两条规则,用模板即可指代一个架构。例如,表 1 给出由基数 、瓶颈宽度 4d 的模板(图 3)构造的 ResNeXt-50。该网络简记为 ResNeXt-50(324d)。模板的输入/输出宽度固定为 256-d(图 3),特征图每次下采样时所有宽度加倍(见表 1)。
Cardinality vs. Width. We first evaluate the trade-off between cardinality and bottleneck width, under preserved complexity as listed in Table 2. Table 3 shows the results and Fig. 5 shows the curves of error vs. epochs. Comparing with ResNet-50 (Table 3 top and Fig. 5 left), the 324d ResNeXt-50 has a validation error of 22.2%, which is 1.7% lower than the ResNet baseline’s 23.9%. With cardinality increasing from 1 to 32 while keeping complexity, the error rate keeps reducing. Furthermore, the 324d ResNeXt also has a much lower training error than the ResNet counterpart, suggesting that the gains are not from regularization but from stronger representations.
基数 对 宽度。我们首先按表 2 在保持复杂度下评估基数 与瓶颈宽度的权衡。表 3 给出结果,图 5 给出误差随 epoch 的曲线。与 ResNet-50(表 3 上与图 5 左)相比,324d ResNeXt-50 验证误差为 22.2%,比 ResNet 基线的 23.9% 低 1.7%。在保持复杂度下把 从 1 增到 32,误差持续下降。此外,324d ResNeXt 的训练误差也远低于对应 ResNet,说明收益并非来自正则化,而是来自更强的表示。
Similar trends are observed in the case of ResNet-101 (Fig. 5 right, Table 3 bottom), where the 324d ResNeXt-101 outperforms the ResNet-101 counterpart by 0.8%. Although this improvement of validation error is smaller than that of the 50-layer case, the improvement of training error is still big (20% for ResNet-101 and 16% for 324d ResNeXt-101, Fig. 5 right). In fact, more training data will enlarge the gap of validation error, as we show on an ImageNet-5K set in the next subsection.
在 ResNet-101 情形下观察到类似趋势(图 5 右,表 3 下):324d ResNeXt-101 比对应 ResNet-101 优 0.8%。虽验证误差改进小于 50 层情形,训练误差改进仍然很大(ResNet-101 为 20%,324d ResNeXt-101 为 16%,图 5 右)。事实上,更多训练数据会放大验证误差差距,如下一小节 ImageNet-5K 所示。
Table 3 also suggests that with complexity preserved, increasing cardinality at the price of reducing width starts to show saturating accuracy when the bottleneck width is small. We argue that it is not worthwhile to keep reducing width in such a trade-off. So we adopt a bottleneck width no smaller than 4d in the following.
表 3 还表明:在保持复杂度时,以减小宽度为代价增大基数,当瓶颈宽度较小时精度开始饱和。我们认为在这种权衡中继续减小宽度并不值得。因此下文采用不小于 4d 的瓶颈宽度。
| setting | top-1 error (%) | |
|---|---|---|
| ResNet-50 | 1 64d | 23.9 |
| ResNeXt-50 | 2 40d | 23.0 |
| ResNeXt-50 | 4 24d | 22.6 |
| ResNeXt-50 | 8 14d | 22.3 |
| ResNeXt-50 | 32 4d | 22.2 |
| ResNet-101 | 1 64d | 22.0 |
| ResNeXt-101 | 2 40d | 21.7 |
| ResNeXt-101 | 4 24d | 21.4 |
| ResNeXt-101 | 8 14d | 21.3 |
| ResNeXt-101 | 32 4d | 21.2 |
Table 3: Ablation experiments on ImageNet-1K. (Top): ResNet-50 with preserved complexity (4.1 billion FLOPs); (Bottom): ResNet-101 with preserved complexity (7.8 billion FLOPs). The error rate is evaluated on the single crop of 224224 pixels.
| setting | top-1 error (%) | |
|---|---|---|
| ResNet-50 | 1 64d | 23.9 |
| ResNeXt-50 | 2 40d | 23.0 |
| ResNeXt-50 | 4 24d | 22.6 |
| ResNeXt-50 | 8 14d | 22.3 |
| ResNeXt-50 | 32 4d | 22.2 |
| ResNet-101 | 1 64d | 22.0 |
| ResNeXt-101 | 2 40d | 21.7 |
| ResNeXt-101 | 4 24d | 21.4 |
| ResNeXt-101 | 8 14d | 21.3 |
| ResNeXt-101 | 32 4d | 21.2 |
表 3:ImageNet-1K 消融实验。(上):保持复杂度的 ResNet-50(4.1 billion FLOPs);(下):保持复杂度的 ResNet-101(7.8 billion FLOPs)。误差在单个 224224 裁剪上评估。
| setting | top-1 err (%) | top-5 err (%) | |
|---|---|---|---|
| 1 complexity references: | |||
| ResNet-101 | 1 64d | 22.0 | 6.0 |
| ResNeXt-101 | 32 4d | 21.2 | 5.6 |
| 2 complexity models follow: | |||
| ResNet-200 He2016a | 1 64d | 21.7 | 5.8 |
| ResNet-101, wider | 1 100d | 21.3 | 5.7 |
| ResNeXt-101 | 2 64d | 20.7 | 5.5 |
| ResNeXt-101 | 64 4d | 20.4 | 5.3 |
Table 4: Comparisons on ImageNet-1K when the number of FLOPs is increased to 2 of ResNet-101’s. The error rate is evaluated on the single crop of 224224 pixels. The highlighted factors are the factors that increase complexity.
| setting | top-1 err (%) | top-5 err (%) | |
|---|---|---|---|
| 1 complexity references: | |||
| ResNet-101 | 1 64d | 22.0 | 6.0 |
| ResNeXt-101 | 32 4d | 21.2 | 5.6 |
| 2 complexity models follow: | |||
| ResNet-200 He2016a | 1 64d | 21.7 | 5.8 |
| ResNet-101, wider | 1 100d | 21.3 | 5.7 |
| ResNeXt-101 | 2 64d | 20.7 | 5.5 |
| ResNeXt-101 | 64 4d | 20.4 | 5.3 |
表 4:当 FLOPs 增至 ResNet-101 的 2 时在 ImageNet-1K 上的比较。误差在单个 224224 裁剪上评估。高亮因子是增大复杂度的因子。
Increasing Cardinality vs. Deeper/Wider. Next we investigate increasing complexity by increasing cardinality or increasing depth or width. The following comparison can also be viewed as with reference to 2 FLOPs of the ResNet-101 baseline. We compare the following variants that have 15 billion FLOPs. (i) Going deeper to 200 layers. We adopt the ResNet-200 He2016a implemented in Gross2016. (ii) Going wider by increasing the bottleneck width. (iii) Increasing cardinality by doubling .
增大基数 对 加深/加宽。接下来考察通过增大基数 或加深/加宽来增大复杂度。下列比较也可视为相对 ResNet-101 基线 2 FLOPs。我们比较约有 15 billion FLOPs 的变体。(i) 加深到 200 层。采用 Gross2016 实现的 ResNet-200 He2016a。(ii) 加宽,增大瓶颈宽度。(iii) 增大基数,把 加倍。
Table 4 shows that increasing complexity by 2 consistently reduces error vs. the ResNet-101 baseline (22.0%). But the improvement is small when going deeper (ResNet-200, by 0.3%) or wider (wider ResNet-101, by 0.7%).
表 4 表明:把复杂度增至 2 相对 ResNet-101 基线(22.0%)持续降低误差。但加深(ResNet-200,0.3%)或加宽(更宽 ResNet-101,0.7%)时改进较小。
On the contrary, increasing cardinality shows much better results than going deeper or wider. The 264d ResNeXt-101 (i.e., doubling on 164d ResNet-101 baseline and keeping the width) reduces the top-1 error by 1.3% to 20.7%. The 644d ResNeXt-101 (i.e., doubling on 324d ResNeXt-101 and keeping the width) reduces the top-1 error to 20.4%.
相反,增大基数 比加深或加宽效果好得多。264d ResNeXt-101(即 在 164d ResNet-101 基线上把 加倍并保持宽度)把 top-1 误差降低 1.3% 至 20.7%。644d ResNeXt-101(即 在 324d ResNeXt-101 上把 加倍并保持宽度)把 top-1 误差降至 20.4%。
We also note that 324d ResNet-101 (21.2%) performs better than the deeper ResNet-200 and the wider ResNet-101, even though it has only 50% complexity. This again shows that cardinality is a more effective dimension than the dimensions of depth and width.
我们还指出:即便复杂度仅约 50%,324d ResNeXt-101(21.2%)仍优于更深的 ResNet-200 与更宽的 ResNet-101。这再次表明基数是比深度与宽度更有效的维度。
Residual connections. The following table shows the effects of the residual (shortcut) connections:
残差连接。 下表给出残差(捷径)连接的影响:
Removing shortcuts from the ResNeXt-50 increases the error by 3.9 points to 26.1%. Removing shortcuts from its ResNet-50 counterpart is much worse (31.2%). These comparisons suggest that the residual connections are helpful for optimization, whereas aggregated transformations are stronger representations, as shown by the fact that they perform consistently better than their counterparts with or without residual connections.
从 ResNeXt-50 去掉捷径,误差升高 3.9 个百分点至 26.1%。从对应 ResNet-50 去掉捷径更糟(31.2%)。这些比较表明残差连接有助于优化,而聚合变换则是更强的表示——无论有无残差连接,它们都始终优于对应模型。
Performance. For simplicity we use Torch’s built-in grouped convolution implementation, without special optimization. We note that this implementation was brute-force and not parallelization-friendly. On 8 GPUs of NVIDIA M40, training 324d ResNeXt-101 in Table 3 takes 0.95s per mini-batch, vs. 0.70s of ResNet-101 baseline that has similar FLOPs. We argue that this is a reasonable overhead. We expect carefully engineered lower-level implementation (e.g., in CUDA) will reduce this overhead. We also expect that the inference time on CPUs will present less overhead. Training the 2complexity model (644d ResNeXt-101) takes 1.7s per mini-batch and 10 days total on 8 GPUs.
性能。 为简单起见我们使用 Torch 内置分组卷积实现,未做特殊优化。该实现较为暴力且不利于并行。在 8 块 NVIDIA M40 上,训练表 3 中的 324d ResNeXt-101 每 mini-batch 需 0.95s,而 FLOPs 相近的 ResNet-101 基线为 0.70s。我们认为这是合理的开销。预期精心设计的底层实现(例如 CUDA)会降低该开销。也预期 CPU 上推理开销更小。训练 2复杂度模型(644d ResNeXt-101)每 mini-batch 1.7s,8 GPU 上共约 10 天。
Comparisons with state-of-the-art results. Table 5 shows more results of single-crop testing on the ImageNet validation set. In addition to testing a 224224 crop, we also evaluate a 320320 crop following He2016a. Our results compare favorably with ResNet, Inception-v3/v4, and Inception-ResNet-v2, achieving a single-crop top-5 error rate of 4.4%. In addition, our architecture design is much simpler than all Inception models, and requires considerably fewer hyper-parameters to be set by hand.
与当时最优结果比较。 表 5 给出 ImageNet 验证集上更多单裁剪测试结果。除 224224 裁剪外,我们还按 He2016a 评估 320320 裁剪。我们的结果优于 ResNet、Inception-v3/v4 与 Inception-ResNet-v2,单裁剪 top-5 误差达到 4.4%。此外,我们的架构设计远比所有 Inception 模型简单,需手工设定的超参数少得多。
ResNeXt is the foundation of our entries to the ILSVRC 2016 classification task, in which we achieved 2 place. We note that many models (including ours) start to get saturated on this dataset after using multi-scale and/or multi-crop testing. We had a single-model top-1/top-5 error rates of 17.7%/3.7% using the multi-scale dense testing in He2016, on par with Inception-ResNet-v2’s single-model results of 17.8%/3.7% that adopts multi-scale, multi-crop testing. We had an ensemble result of 3.03% top-5 error on the test set, on par with the winner’s 2.99% and Inception-v4/Inception-ResNet-v2’s 3.08% Szegedy2016.
ResNeXt 是我们参加 ILSVRC 2016 分类任务并获第 2 名的基础。我们指出:许多模型(包括我们的)在使用多尺度和/或多裁剪测试后,在该数据集上开始饱和。用 He2016 的多尺度稠密测试,我们的单模型 top-1/top-5 误差为 17.7%/3.7%,与采用多尺度、多裁剪测试的 Inception-ResNet-v2 单模型 17.8%/3.7% 相当。集成结果在测试集上 top-5 误差 3.03%,与冠军的 2.99% 以及 Inception-v4/Inception-ResNet-v2 的 3.08% Szegedy2016 相当。
| 224224 | 320320 / 299299 | |||
|---|---|---|---|---|
| top-1 err | top-5 err | top-1 err | top-5 err | |
| ResNet-101 He2016 | 22.0 | 6.0 | - | - |
| ResNet-200 He2016a | 21.7 | 5.8 | 20.1 | 4.8 |
| Inception-v3 Szegedy2016a | - | - | 21.2 | 5.6 |
| Inception-v4 Szegedy2016 | - | - | 20.0 | 5.0 |
| Inception-ResNet-v2 Szegedy2016 | - | - | 19.9 | 4.9 |
| ResNeXt-101 (64 4d) | 20.4 | 5.3 | 19.1 | 4.4 |
Table 5: State-of-the-art models on the ImageNet-1K validation set (single-crop testing). The test size of ResNet/ResNeXt is 224224 and 320320 as in He2016a and of the Inception models is 299299.
| 224224 | 320320 / 299299 | |||
|---|---|---|---|---|
| top-1 err | top-5 err | top-1 err | top-5 err | |
| ResNet-101 He2016 | 22.0 | 6.0 | - | - |
| ResNet-200 He2016a | 21.7 | 5.8 | 20.1 | 4.8 |
| Inception-v3 Szegedy2016a | - | - | 21.2 | 5.6 |
| Inception-v4 Szegedy2016 | - | - | 20.0 | 5.0 |
| Inception-ResNet-v2 Szegedy2016 | - | - | 19.9 | 4.9 |
| ResNeXt-101 (64 4d) | 20.4 | 5.3 | 19.1 | 4.4 |
表 5:ImageNet-1K 验证集上的当时最优模型(单裁剪测试)。ResNet/ResNeXt 测试尺寸为 He2016a 中的 224224 与 320320;Inception 模型为 299299。
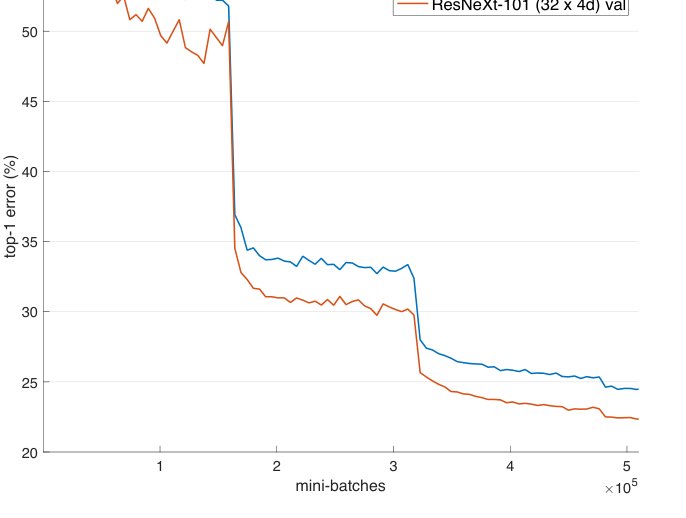
Figure 6: ImageNet-5K experiments. Models are trained on the 5K set and evaluated on the original 1K validation set, plotted as a 1K-way classification task. ResNeXt and its ResNet counterpart have similar complexity.
图 6:ImageNet-5K 实验。模型在 5K 集上训练,在原始 1K 验证集上评估,画成 1K 路分类任务。ResNeXt 与对应 ResNet 复杂度相近。
| 5K-way classification | 1K-way classification | ||||
|---|---|---|---|---|---|
| setting | top-1 | top-5 | top-1 | top-5 | |
| ResNet-50 | 1 64d | 45.5 | 19.4 | 27.1 | 8.2 |
| ResNeXt-50 | 32 4d | 42.3 | 16.8 | 24.4 | 6.6 |
| ResNet-101 | 1 64d | 42.4 | 16.9 | 24.2 | 6.8 |
| ResNeXt-101 | 32 4d | 40.1 | 15.1 | 22.2 | 5.7 |
Table 6: Error (%) on ImageNet-5K. The models are trained on ImageNet-5K and tested on the ImageNet-1K val set, treated as a 5K-way classification task or a 1K-way classification task at test time. ResNeXt and its ResNet counterpart have similar complexity. The error is evaluated on the single crop of 224224 pixels.
| 5K-way classification | 1K-way classification | ||||
|---|---|---|---|---|---|
| setting | top-1 | top-5 | top-1 | top-5 | |
| ResNet-50 | 1 64d | 45.5 | 19.4 | 27.1 | 8.2 |
| ResNeXt-50 | 32 4d | 42.3 | 16.8 | 24.4 | 6.6 |
| ResNet-101 | 1 64d | 42.4 | 16.9 | 24.2 | 6.8 |
| ResNeXt-101 | 32 4d | 40.1 | 15.1 | 22.2 | 5.7 |
表 6:ImageNet-5K 上的误差(%)。模型在 ImageNet-5K 上训练,在 ImageNet-1K 验证集上测试,测试时分别视为 5K 路或 1K 路分类。ResNeXt 与对应 ResNet 复杂度相近。误差在单个 224224 裁剪上评估。
5.2 Experiments on ImageNet-5K
5.2 ImageNet-5K 实验
The performance on ImageNet-1K appears to saturate. But we argue that this is not because of the capability of the models but because of the complexity of the dataset. Next we evaluate our models on a larger ImageNet subset that has 5000 categories.
ImageNet-1K 上的表现似乎趋于饱和。但我们认为这并非因为模型能力,而是因为数据集复杂度。接下来我们在有 5000 类的更大 ImageNet 子集上评估模型。
Our 5K dataset is a subset of the full ImageNet-22K set Russakovsky2015. The 5000 categories consist of the original ImageNet-1K categories and additional 4000 categories that have the largest number of images in the full ImageNet set. The 5K set has 6.8 million images, about 5 of the 1K set. There is no official train/val split available, so we opt to evaluate on the original ImageNet-1K validation set. On this 1K-class val set, the models can be evaluated as a 5K-way classification task (all labels predicted to be the other 4K classes are automatically erroneous) or as a 1K-way classification task (softmax is applied only on the 1K classes) at test time.
我们的 5K 数据集是完整 ImageNet-22K 集 Russakovsky2015 的子集。5000 类由原 ImageNet-1K 类加上完整 ImageNet 中图像数最多的另外 4000 类组成。5K 集有 680 万图像,约为 1K 集的 5。没有官方 train/val 划分,因此我们选择在原始 ImageNet-1K 验证集上评估。在该 1K 类验证集上,模型可在测试时评估为 5K 路分类任务(预测到另外 4K 类的标签自动算错),或评估为 1K 路分类任务(softmax 仅在 1K 类上计算)。
The implementation details are the same as in Sec. 4. The 5K-training models are all trained from scratch, and are trained for the same number of mini-batches as the 1K-training models (so 1/5 epochs). Table 6 and Fig. 6 show the comparisons under preserved complexity. ResNeXt-50 reduces the 5K-way top-1 error by 3.2% comparing with ResNet-50, and ResNetXt-101 reduces the 5K-way top-1 error by 2.3% comparing with ResNet-101. Similar gaps are observed on the 1K-way error. These demonstrate the stronger representational power of ResNeXt.
实现细节与第 4 节相同。5K 训练模型均从零训练,且与 1K 训练模型使用相同数量的 mini-batch(因此 epoch 数为 1/5)。表 6 与图 6 给出保持复杂度下的比较。相对 ResNet-50,ResNeXt-50 把 5K 路 top-1 误差降低 3.2%;相对 ResNet-101,ResNeXt-101 降低 2.3%。1K 路误差上观察到类似差距。这些表明 ResNeXt 具有更强的表示能力。
Moreover, we find that the models trained on the 5K set (with 1K-way error 22.2%/5.7% in Table 6) perform competitively comparing with those trained on the 1K set (21.2%/5.6% in Table 3), evaluated on the same 1K-way classification task on the validation set. This result is achieved without increasing the training time (due to the same number of mini-batches) and without fine-tuning. We argue that this is a promising result, given that the training task of classifying 5K categories is a more challenging one.
此外,我们发现在 5K 集上训练的模型(表 6 中 1K 路误差 22.2%/5.7%)与在 1K 集上训练的模型(表 3 中 21.2%/5.6%)在同一验证集的同一 1K 路分类任务上表现相当。该结果在未增加训练时间(因 mini-batch 数相同)且未经微调的情况下取得。鉴于把 5K 类分类作为训练任务更具挑战性,我们认为这是一个有希望的结果。
5.3 Experiments on CIFAR
5.3 CIFAR 实验
We conduct more experiments on CIFAR-10 and 100 datasets Krizhevsky2009. We use the architectures as in He2016 and replace the basic residual block by the bottleneck template of \left[\begin{array}[]{c}\text{1\times1, 64}\\[-1.00006pt] \text{3\times3, 64}\\[-1.00006pt] \text{1\times1, 256}\end{array}\right]. Our networks start with a single 33 conv layer, followed by 3 stages each having 3 residual blocks, and end with average pooling and a fully-connected classifier (total 29-layer deep), following He2016. We adopt the same translation and flipping data augmentation as He2016. Implementation details are in the appendix.
我们在 CIFAR-10 与 100 数据集 Krizhevsky2009 上做更多实验。采用 He2016 中的架构,并把基本残差块替换为瓶颈模板 \left[\begin{array}[]{c}\text{1\times1, 64}\\[-1.00006pt] \text{3\times3, 64}\\[-1.00006pt] \text{1\times1, 256}\end{array}\right]。网络以单个 33 卷积层开始,随后 3 个阶段各有 3 个残差块,以平均池化与全连接分类器结束(共 29 层深),遵循 He2016。数据增强采用与 He2016 相同的平移与翻转。实现细节见附录。
We compare two cases of increasing complexity based on the above baseline: (i) increase cardinality and fix all widths, or (ii) increase width of the bottleneck and fix cardinality . We train and evaluate a series of networks under these changes. Fig. 7 shows the comparisons of test error rates vs. model sizes. We find that increasing cardinality is more effective than increasing width, consistent to what we have observed on ImageNet-1K. Table 7 shows the results and model sizes, comparing with the Wide ResNet Zagoruyko2016a which is the best published record. Our model with a similar model size (34.4M) shows results better than Wide ResNet. Our larger method achieves 3.58% test error (average of 10 runs) on CIFAR-10 and 17.31% on CIFAR-100. To the best of our knowledge, these are the state-of-the-art results (with similar data augmentation) in the literature including unpublished technical reports.
我们基于上述基线比较两种增大复杂度的情形:(i) 增大基数 并固定所有宽度,或 (ii) 增大 瓶颈宽度并固定基数 。在这些变化下训练并评估一系列网络。图 7 给出测试误差对模型规模的比较。我们发现增大基数比增大宽度更有效,与 ImageNet-1K 上的观察一致。表 7 给出结果与模型规模,并与当时最佳公开记录 Wide ResNet Zagoruyko2016a 比较。相近规模(34.4M)的我们的模型优于 Wide ResNet。更大模型在 CIFAR-10 上达到 3.58% 测试误差(10 次运行平均),在 CIFAR-100 上达到 17.31%。据我们所知,在相似数据增强下,这些是文献中(含未发表技术报告)的当时最优结果。
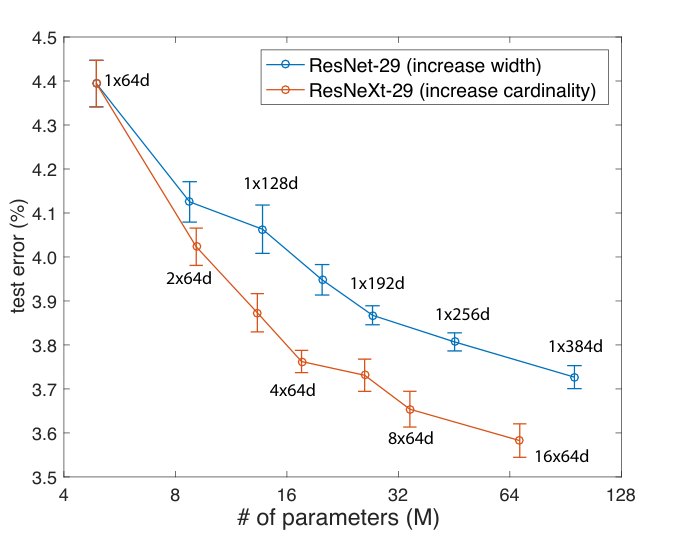
Figure 7: Test error vs. model size on CIFAR-10. The results are computed with 10 runs, shown with standard error bars. The labels show the settings of the templates.
图 7:CIFAR-10 上测试误差 对 模型规模。结果为 10 次运行,带标准误差条。标签显示模板设置。
| # params | CIFAR-10 | CIFAR-100 | |
|---|---|---|---|
| Wide ResNet Zagoruyko2016a | 36.5M | 4.17 | 20.50 |
| ResNeXt-29, 864d | 34.4M | 3.65 | 17.77 |
| ResNeXt-29, 1664d | 68.1M | 3.58 | 17.31 |
Table 7: Test error (%) and model size on CIFAR. Our results are the average of 10 runs.
| # params | CIFAR-10 | CIFAR-100 | |
|---|---|---|---|
| Wide ResNet Zagoruyko2016a | 36.5M | 4.17 | 20.50 |
| ResNeXt-29, 864d | 34.4M | 3.65 | 17.77 |
| ResNeXt-29, 1664d | 68.1M | 3.58 | 17.31 |
表 7:CIFAR 上的测试误差(%)与模型规模。我们的结果为 10 次运行平均。
| setting | setting | AP@0.5 | AP@0.5 | AP | AP | |
|---|---|---|---|---|---|---|
| setting | ||||||
| AP@0.5 | ||||||
| AP | ||||||
| ResNet-50 | 1 64d | 47.6 | 26.5 | |||
| ResNeXt-50 | 32 4d | 49.7 | 27.5 | |||
| ResNet-101 | 1 64d | 51.1 | 29.8 | |||
| ResNeXt-101 | 32 4d | 51.9 | 30.0 |
| setting |
|---|
| AP@0.5 |
|---|
| AP |
|---|
Table 8: Object detection results on the COCO minival set. ResNeXt and its ResNet counterpart have similar complexity.
| setting | setting | AP@0.5 | AP@0.5 | AP | AP | |
|---|---|---|---|---|---|---|
| setting | ||||||
| AP@0.5 | ||||||
| AP | ||||||
| ResNet-50 | 1 64d | 47.6 | 26.5 | |||
| ResNeXt-50 | 32 4d | 49.7 | 27.5 | |||
| ResNet-101 | 1 64d | 51.1 | 29.8 | |||
| ResNeXt-101 | 32 4d | 51.9 | 30.0 |
| setting |
|---|
| AP@0.5 |
|---|
| AP |
|---|
表 8:COCO minival 集上的目标检测结果。ResNeXt 与对应 ResNet 复杂度相近。
5.4 Experiments on COCO object detection
5.4 COCO 目标检测实验
Next we evaluate the generalizability on the COCO object detection set Lin2014. We train the models on the 80k training set plus a 35k val subset and evaluate on a 5k val subset (called minival), following Bell2016. We evaluate the COCO-style Average Precision (AP) as well as AP@IoU=0.5 Lin2014. We adopt the basic Faster R-CNN Ren2015 and follow He2016 to plug ResNet/ResNeXt into it. The models are pre-trained on ImageNet-1K and fine-tuned on the detection set. Implementation details are in the appendix.
接下来我们在 COCO 目标检测集 Lin2014 上评估泛化性。在 80k 训练集加 35k 验证子集上训练,在 5k 验证子集(称为 minival)上评估,遵循 Bell2016。我们评估 COCO 风格平均精度(AP)以及 AP@IoU=0.5 Lin2014。采用基本 Faster R-CNN Ren2015,并按 He2016 把 ResNet/ResNeXt 插入其中。模型在 ImageNet-1K 上预训练,再在检测集上微调。实现细节见附录。
Table 8 shows the comparisons. On the 50-layer baseline, ResNeXt improves AP@0.5 by 2.1% and AP by 1.0%, without increasing complexity. ResNeXt shows smaller improvements on the 101-layer baseline. We conjecture that more training data will lead to a larger gap, as observed on the ImageNet-5K set.
表 8 给出比较。在 50 层基线上,ResNeXt 在不增加复杂度的情况下把 AP@0.5 提升 2.1%、AP 提升 1.0%。在 101 层基线上改进较小。我们推测更多训练数据会带来更大差距,如 ImageNet-5K 上所见。
It is also worth noting that recently ResNeXt has been adopted in Mask R-CNN he2017mask that achieves state-of-the-art results on COCO instance segmentation and object detection tasks.
还值得指出:近期 ResNeXt 已被 Mask R-CNN he2017mask 采用,并在 COCO 实例分割与目标检测任务上取得当时最优结果。
Acknowledgment
致谢
S.X. and Z.T.’s research was partly supported by NSF IIS-1618477. The authors would like to thank Tsung-Yi Lin and Priya Goyal for valuable discussions.
S.X. 与 Z.T. 的研究部分得到 NSF IIS-1618477 支持。作者感谢 Tsung-Yi Lin 与 Priya Goyal 的宝贵讨论。
Appendix A Implementation Details: CIFAR
附录 A 实现细节:CIFAR
We train the models on the 50k training set and evaluate on the 10k test set. The input image is 3232 randomly cropped from a zero-padded 4040 image or its flipping, following He2016. No other data augmentation is used. The first layer is 33 conv with 64 filters. There are 3 stages each having 3 residual blocks, and the output map size is 32, 16, and 8 for each stage He2016. The network ends with a global average pooling and a fully-connected layer. Width is increased by 2 when the stage changes (downsampling), as in Sec. 3.1. The models are trained on 8 GPUs with a mini-batch size of 128, with a weight decay of 0.0005 and a momentum of 0.9. We start with a learning rate of 0.1 and train the models for 300 epochs, reducing the learning rate at the 150-th and 225-th epoch. Other implementation details are as in Gross2016.
我们在 50k 训练集上训练,在 10k 测试集上评估。输入图像为从零填充的 4040 图像或其翻转中随机裁剪的 3232,遵循 He2016。不使用其他数据增强。第一层为 64 个滤波器的 33 卷积。共 3 个阶段,各有 3 个残差块,各阶段输出图大小为 32、16 与 8 He2016。网络以全局平均池化与全连接层结束。阶段切换(下采样)时宽度加倍,如 3.1 节。模型在 8 GPU 上训练,mini-batch 128,权重衰减 0.0005,动量 0.9。学习率从 0.1 起步,训练 300 个 epoch,在第 150 与 225 个 epoch 降低学习率。其他实现细节同 Gross2016。
Appendix B Implementation Details: Object Detection
附录 B 实现细节:目标检测
We adopt the Faster R-CNN system Ren2015. For simplicity we do not share the features between RPN and Fast R-CNN. In the RPN step, we train on 8 GPUs with each GPU holding 2 images per mini-batch and 256 anchors per image. We train the RPN step for 120k mini-batches at a learning rate of 0.02 and next 60k at 0.002. In the Fast R-CNN step, we train on 8 GPUs with each GPU holding 1 image and 64 regions per mini-batch. We train the Fast R-CNN step for 120k mini-batches at a learning rate of 0.005 and next 60k at 0.0005, We use a weight decay of 0.0001 and a momentum of 0.9. Other implementation details are as in https://github.com/rbgirshick/py-faster-rcnn.
我们采用 Faster R-CNN 系统 Ren2015。为简单起见,RPN 与 Fast R-CNN 不共享特征。在 RPN 步骤中,8 GPU 训练,每 GPU 每 mini-batch 2 张图、每图 256 个锚点。RPN 先以学习率 0.02 训练 120k mini-batch,再以 0.002 训练 60k。在 Fast R-CNN 步骤中,8 GPU 训练,每 GPU 每 mini-batch 1 张图、64 个区域。Fast R-CNN 先以学习率 0.005 训练 120k mini-batch,再以 0.0005 训练 60k。权重衰减 0.0001,动量 0.9。其他实现细节见 https://github.com/rbgirshick/py-faster-rcnn。
References
参考文献
(1) S. Bell, C. L. Zitnick, K. Bala, and R. Girshick. Inside-outside net: Detecting objects in context with skip pooling and recurrent neural networks. In CVPR , 2016.
(2) G. Cantor. Über unendliche, lineare punktmannichfaltigkeiten, arbeiten zur mengenlehre aus den jahren 1872-1884. 1884.
(3) R. Collobert, S. Bengio, and J. Mariéthoz. Torch: a modular machine learning software library. Technical report, Idiap, 2002.
(4) A. Conneau, H. Schwenk, L. Barrault, and Y. Lecun. Very deep convolutional networks for natural language processing. arXiv:1606.01781 , 2016.
(5) N. Dalal and B. Triggs. Histograms of oriented gradients for human detection. In CVPR , 2005.
(6) E. Denton, W. Zaremba, J. Bruna, Y. LeCun, and R. Fergus. Exploiting linear structure within convolutional networks for efficient evaluation. In NIPS , 2014.
(7) J. Donahue, Y. Jia, O. Vinyals, J. Hoffman, N. Zhang, E. Tzeng, and T. Darrell. Decaf: A deep convolutional activation feature for generic visual recognition. In ICML , 2014.
(8) D. Eigen, J. Rolfe, R. Fergus, and Y. LeCun. Understanding deep architectures using a recursive convolutional network. arXiv:1312.1847 , 2013.
(9) R. Girshick. Fast R-CNN. In ICCV , 2015.
(10) R. Girshick, J. Donahue, T. Darrell, and J. Malik. Rich feature hierarchies for accurate object detection and semantic segmentation. In CVPR , 2014.
(11) S. Gross and M. Wilber. Training and investigating Residual Nets. https://github.com/facebook/fb.resnet.torch , 2016.
(12) K. He, G. Gkioxari, P. Dollár, and R. Girshick. Mask R-CNN. arXiv:1703.06870 , 2017.
(13) K. He, X. Zhang, S. Ren, and J. Sun. Delving deep into rectifiers: Surpassing human-level performance on imagenet classification. In ICCV , 2015.
(14) K. He, X. Zhang, S. Ren, and J. Sun. Deep residual learning for image recognition. In CVPR , 2016.
(15) K. He, X. Zhang, S. Ren, and J. Sun. Identity mappings in deep residual networks. In ECCV , 2016.
(16) Y. Ioannou, D. Robertson, R. Cipolla, and A. Criminisi. Deep roots: Improving cnn efficiency with hierarchical filter groups. arXiv:1605.06489 , 2016.
(17) S. Ioffe and C. Szegedy. Batch normalization: Accelerating deep network training by reducing internal covariate shift. In ICML , 2015.
(18) M. Jaderberg, A. Vedaldi, and A. Zisserman. Speeding up convolutional neural networks with low rank expansions. In BMVC , 2014.
(19) Y. Jia, E. Shelhamer, J. Donahue, S. Karayev, J. Long, R. Girshick, S. Guadarrama, and T. Darrell. Caffe: Convolutional architecture for fast feature embedding. arXiv:1408.5093 , 2014.
(20) N. Kalchbrenner, L. Espeholt, K. Simonyan, A. v. d. Oord, A. Graves, and K. Kavukcuoglu. Neural machine translation in linear time. arXiv:1610.10099 , 2016.
(21) Y.-D. Kim, E. Park, S. Yoo, T. Choi, L. Yang, and D. Shin. Compression of deep convolutional neural networks for fast and low power mobile applications. In ICLR , 2016.
(22) P. Kontschieder, M. Fiterau, A. Criminisi, and S. R. Bulò. Deep convolutional neural decision forests. In ICCV , 2015.
(23) A. Krizhevsky. Learning multiple layers of features from tiny images. Tech Report , 2009.
(24) A. Krizhevsky, I. Sutskever, and G. Hinton. Imagenet classification with deep convolutional neural networks. In NIPS , 2012.
(25) Y. LeCun, B. Boser, J. S. Denker, D. Henderson, R. E. Howard, W. Hubbard, and L. D. Jackel. Backpropagation applied to handwritten zip code recognition. Neural computation , 1989.
(26) M. Lin, Q. Chen, and S. Yan. Network in network. In ICLR , 2014.
(27) T.-Y. Lin, M. Maire, S. Belongie, J. Hays, P. Perona, D. Ramanan, P. Dollár, and C. L. Zitnick. Microsoft COCO: Common objects in context. In ECCV . 2014.
(28) J. Long, E. Shelhamer, and T. Darrell. Fully convolutional networks for semantic segmentation. In CVPR , 2015.
(29) D. G. Lowe. Distinctive image features from scale-invariant keypoints. IJCV , 2004.
(30) A. Oord, S. Dieleman, H. Zen, K. Simonyan, O. Vinyals, A. Graves, N. Kalchbrenner, A. Senior, and K. Kavukcuoglu. Wavenet: A generative model for raw audio. arXiv:1609.03499 , 2016.
(31) P. O. Pinheiro, R. Collobert, and P. Dollar. Learning to segment object candidates. In NIPS , 2015.
(32) S. Ren, K. He, R. Girshick, and J. Sun. Faster R-CNN: Towards real-time object detection with region proposal networks. In NIPS , 2015.
(33) O. Russakovsky, J. Deng, H. Su, J. Krause, S. Satheesh, S. Ma, Z. Huang, A. Karpathy, A. Khosla, M. Bernstein, A. C. Berg, and L. Fei-Fei. ImageNet Large Scale Visual Recognition Challenge. IJCV , 2015.
(34) P. Sermanet, D. Eigen, X. Zhang, M. Mathieu, R. Fergus, and Y. LeCun. Overfeat: Integrated recognition, localization and detection using convolutional networks. In ICLR , 2014.
(35) L. Sifre and S. Mallat. Rigid-motion scattering for texture classification. arXiv:1403.1687 , 2014.
(36) K. Simonyan and A. Zisserman. Very deep convolutional networks for large-scale image recognition. In ICLR , 2015.
(37) C. Szegedy, S. Ioffe, and V. Vanhoucke. Inception-v4, inception-resnet and the impact of residual connections on learning. In ICLR Workshop , 2016.
(38) C. Szegedy, W. Liu, Y. Jia, P. Sermanet, S. Reed, D. Anguelov, D. Erhan, V. Vanhoucke, and A. Rabinovich. Going deeper with convolutions. In CVPR , 2015.
(39) C. Szegedy, V. Vanhoucke, S. Ioffe, J. Shlens, and Z. Wojna. Rethinking the inception architecture for computer vision. In CVPR , 2016.
(40) A. Veit, M. Wilber, and S. Belongie. Residual networks behave like ensembles of relatively shallow network. In NIPS , 2016.
(41) Y. Wu, M. Schuster, Z. Chen, Q. V. Le, M. Norouzi, W. Macherey, M. Krikun, Y. Cao, Q. Gao, K. Macherey, et al. Google’s neural machine translation system: Bridging the gap between human and machine translation. arXiv:1609.08144 , 2016.
(42) W. Xiong, J. Droppo, X. Huang, F. Seide, M. Seltzer, A. Stolcke, D. Yu, and G. Zweig. The Microsoft 2016 Conversational Speech Recognition System. arXiv:1609.03528 , 2016.
(43) S. Zagoruyko and N. Komodakis. Wide residual networks. In BMVC , 2016.
(44) M. D. Zeiler and R. Fergus. Visualizing and understanding convolutional neural networks. In ECCV , 2014.