Reformer: The Efficient Transformer
Reformer: The Efficient Transformer
Nikita KitaevU.C. Berkeley & Google Research kitaev@cs.berkeley.edu Thanks: Equal Contribution Łukasz KaiserGoogle Research {lukaszkaiser,levskaya }@google.com Anselm LevskayaGoogle Research
Abstract
摘要
Large Transformer models routinely achieve state-of-the-art results on a number of tasks but training these models can be prohibitively costly, especially on long sequences. We introduce two techniques to improve the efficiency of Transformers. For one, we replace dot-product attention by one that uses locality-sensitive hashing, changing its complexity from O() to O(), where is the length of the sequence. Furthermore, we use reversible residual layers instead of the standard residuals, which allows storing activations only once in the training process instead of times, where is the number of layers. The resulting model, the Reformer, performs on par with Transformer models while being much more memory-efficient and much faster on long sequences.
大型 Transformer 在多项任务上常拿下最好结果,但训练代价往往过高,长序列尤甚。本文提出两项技巧提升 Transformer 效率。其一,用基于局部敏感哈希(LSH)的注意力取代点积注意力,把复杂度从 降到 ,其中 为序列长度。其二,用可逆残差层替代标准残差,使训练过程只需存储一次激活,而不必按层数 存 份。合成后的模型 Reformer 与 Transformer 表现相当,却更省显存,且在长序列上明显更快。
1 Introduction
1 引言
The Transformer architecture (Vaswani et al. 2017) is widely used in natural language processing and yields state-of-the-art results on a number of tasks. To obtain these results, researchers have resorted to training ever larger Transformer models. The number of parameters exceeds 0.5B per layer in the largest configuration reported in (Shazeer et al. 2018) while the number of layers goes up to 64 in (Al-Rfou et al. 2018). Transformer models are also used on increasingly long sequences. Up to 11 thousand tokens of text in a single example were processed in (Liu et al. 2018) and when processing other modalities, like music (Huang et al. 2018) and images (Parmar et al. 2018), even longer sequences are commonplace. These large-scale long-sequence models yield great results but strain resources to the point where some argue that this trend is breaking NLP research[^1]. Many large Transformer models can only realistically be trained in large industrial research laboratories and such models trained with model parallelism cannot even be fine-tuned on a single GPU as their memory requirements demand a multi-accelerator hardware setup even for a single training step.
Transformer 架构(Vaswani et al. 2017)在自然语言处理中广泛使用,并在多项任务上取得最好结果。为拿到这些结果,研究者不断训练更大的 Transformer。单层参数量在(Shazeer et al. 2018)最大配置中已超过 0.5B,层数在(Al-Rfou et al. 2018)中可达 64。Transformer 也越来越多地用于更长序列:(Liu et al. 2018)单例可处理约一万一千个文本 token;处理音乐(Huang et al. 2018)与图像(Parmar et al. 2018)等模态时,序列往往更长。这类大规模长序列模型效果好,却把资源绷得很紧,甚至有人认为这一趋势正在拖垮 NLP 研究[^1]。许多大型 Transformer 实际上只能在大型工业研究实验室训练;经模型并行训出的模型甚至无法在单卡上微调,因为单步训练的显存需求就要求多加速器硬件。
Do large Transformer models fundamentally require such huge resources or are they simply inefficient? Consider the following calculation: the 0.5B parameters used in the largest reported Transformer layer account for 2GB of memory. Activations for 64K tokens with embedding size 1024 and batch size 8 account for B floats, requiring another 2GB of memory. If our memory use was only per-layer, then we should fairly easily fit a large Transformer even on sequences of length 64K on a single accelerator. Further, the whole corpus used to train BERT only requires 17GB to store. Why is it then that we cannot even fine-tune these models on single machines?
大型 Transformer 是否本质上就需要如此巨大的资源,还是只是不够高效?考虑如下估算:已报道的最大 Transformer 层用 0.5B 参数,约占 2GB 显存。长度为 64K、嵌入维 1024、batch 为 8 时,激活约为 B 个浮点数,再占 2GB。若显存只按层计,即便 64K 长度的大型 Transformer 也应能放进单加速器。再者,训练 BERT 的整份语料存盘也只需 17GB。那为什么连单机微调都做不到?
The above estimate includes only per-layer memory and input activations cost and does not take into account the following major sources of memory use in the Transformer.
上述估算只计入每层显存与输入激活,尚未覆盖 Transformer 中以下几项主要显存开销。
- • Memory in a model with layers is -times larger than in a single-layer model due to the fact that activations need to be stored for back-propagation.
- • 由于反向传播需要保存激活, 层模型的显存约为单层模型的 倍。
- • Since the depth of intermediate feed-forward layers is often much larger than the depth of attention activations, it accounts for a large fraction of memory use.
- • 前馈中间层深度 往往远大于注意力激活深度 ,因此占据很大一部分显存。
- • Attention on sequences of length is O() in both computational and memory complexity, so even for a single sequence of K tokens can exhaust accelerator memory.
- • 长度 上的注意力在计算与显存复杂度上都是 ,即便单条 K token 序列也可能耗尽加速器显存。
We introduce the Reformer model which solves these problems using the following techniques:
我们提出 Reformer,用以下技巧解决上述问题:
- • Reversible layers, first introduced in Gomez et al. 2017, enable storing only a single copy of activations in the whole model, so the factor disappears.
- • 可逆层(Gomez et al. 2017 首先提出)使整个模型只需保存一份激活副本,从而消去 倍因子。
- • Splitting activations inside feed-forward layers and processing them in chunks removes the factor and saves memory inside feed-forward layers.
- • 将前馈层内激活切块处理,消去 因子,节省前馈层显存。
- • Approximate attention computation based on locality-sensitive hashing replaces the O() factor in attention layers with O() and so allows operating on long sequences.
- • 基于局部敏感哈希的近似注意力,把注意力层中的 换成 ,从而能处理长序列。
We study these techniques and show that they have negligible impact on the training process compared to the standard Transformer. Splitting activations in fact only affects the implementation; it is numerically identical to the layers used in the Transformer. Applying reversible residuals instead of the standard ones does change the model but has a negligible effect on training in all configurations we experimented with. Finally, locality-sensitive hashing in attention is a more major change that can influence the training dynamics, depending on the number of concurrent hashes used. We study this parameter and find a value which is both efficient to use and yields results very close to full attention.
我们研究这些技巧,并表明相对标准 Transformer,它们对训练过程影响可忽略。切块激活其实只影响实现,数值上与 Transformer 所用层相同。用可逆残差替代标准残差会改变模型,但在我们试过的全部配置里对训练影响可忽略。最后,注意力中的局部敏感哈希改动更大,可能影响训练动态,取决于并行哈希数。我们研究该超参,找到既高效、又与全注意力结果非常接近的取值。
We experiment on a synthetic task, a text task (enwik8) with sequences of length 64K and an image generation task (imagenet-64 generation) with sequences of length 12K. In both cases we show that Reformer matches the results obtained with full Transformer but runs much faster, especially on the text task, and with orders of magnitude better memory efficiency.
我们在合成任务、长度 64K 的文本任务(enwik8)以及长度 12K 的图像生成任务(imagenet-64 生成)上实验。两种情形下 Reformer 都匹配全量 Transformer 的结果,但运行更快——尤其在文本任务上——且显存效率高出数量级。
2 Locality-sensitive Hashing Attention
2 局部敏感哈希注意力
Dot-product attention.
The standard attention used in the Transformer is the scaled dot-product attention (Vaswani et al. 2017). The input consists of queries and keys of dimension , and values of dimension . The dot products of the query with all keys are computed, scaled by , and a softmax function is applied to obtain the weights on the values. In practice, the attention function on a set of queries is computed simultaneously, packed together into a matrix . Assuming the keys and values are also packed together into matrices and , the matrix of outputs is defined as:
点积注意力。
Transformer 使用的标准注意力是缩放点积注意力(Vaswani et al. 2017)。输入包括维数为 的查询与键,以及维数为 的值。计算查询与全部键的点积,再除以 缩放,经 softmax 得到作用在值上的权重。实践中对一组查询同时算注意力,并打包成矩阵 。设键与值也分别打包为矩阵 与 ,则输出矩阵定义为:
Multi-head attention.
In the Transformer, instead of performing a single attention function with -dimensional keys, values and queries, one linearly projects the queries, keys and values times with different, learned linear projections to , and dimensions, respectively. Attention is applied to each of these projected versions of queries, keys and values in parallel, yielding -dimensional output values. These are concatenated and once again projected, resulting in the final values. This mechanism is known as multi-head attention.
多头注意力。
在 Transformer 中,不是用 维的键、值与查询做一次注意力,而是用不同的可学习线性投影把查询、键、值各投影 次,分别到 、 与 维。对这些投影版本并行做注意力,得到 维输出;再拼接并投影一次,得到最终值。该机制称为多头注意力。
Memory-efficient attention.
To calculate the memory use of the attention mechanism, let us focus on the attention computation from Equation 1. Let us assume that Q, K and V all have the shape . The main issue is the term , which has the shape . In the experimental section we train a model on sequences of length – in this case, even at batch-size of 1, this is a matrix, which in 32-bit floats would take 16GB of memory. This is impractical and has hindered the use of the Transformer for long sequences. But it is important to note that the matrix does not need to be fully materialized in memory. The attention can indeed be computed for each query separately, only calculating once in memory, and then re-computing it on the backward pass when needed for gradients. This way of computing attention may be less efficient but it only uses memory proportional to . We use this memory-efficient implementation of attention to run the full-attention baselines presented in the experimental section.
省显存的注意力。
为估算注意力机制的显存,关注公式 1 中的注意力计算。设 、、 形状均为 。主要问题在于 ,形状为 。实验部分我们在长度 的序列上训练——即便 batch 为 1,这也是 矩阵,用 32 位浮点约占 16GB 显存。这不现实,也阻碍了 Transformer 用于长序列。但须注意, 矩阵不必完整物化在显存中。确实可以对每个查询 单独算注意力,一次只在显存中计算 ,反向时需要梯度再重算。这种实现可能更慢,但显存与长度成正比。我们用该省显存实现对实验部分的全注意力基线。
Where do Q, K, V come from?
The multi-head attention described above operates on keys, queries and values, but usually we are only given a single tensor of activations A of the shape – e.g., coming from embedding the tokens in a sentence into vectors. To build Q, K and V from A, the Transformer uses 3 different linear layers projecting A into Q, K and V with different parameters. For models with LSH attention, we want queries and keys (Q and K) to be identical. This is easily achieved by using the same linear layer to go from A to Q and K, and a separate one for V. We call a model that behaves like this a shared-QK Transformer. It turns out that sharing QK does not affect the performance of Transformer, even if we additionally normalize the length of the keys K, as we show in the experimental Section 5.
、、 从何而来?
上文多头注意力作用在键、查询与值上,但通常只给定形状为 的激活张量 ——例如把句子中的 token 嵌入成向量。为从 构造 、、,Transformer 用三个不同线性层、不同参数把 投影到 、、。对带 LSH 注意力的模型,我们希望查询与键( 与 )相同。做法很简单:从 到 与 用同一线性层, 另用一层。我们称这种模型为共享 QK 的 Transformer。实验表明共享 QK 不影响 Transformer 表现,即便额外对键 做长度归一化也成立,见第 5 节实验。
Hashing attention.
For the LSH attention, we start with two tensors, Q=K and V of the shape . We keep the multi-head mechanism intact and focus on the attention computation from Equation 1. As already mentioned, the main issue is the term , which has the shape . But note that we are actually only interested in . Since softmax is dominated by the largest elements, for each query we only need to focus on the keys in K that are closest to . For example, if K is of length 64K, for each we could only consider a small subset of, say, the or closest keys. That is much more efficient, but how can we find the nearest neighbors among the keys?
哈希注意力。
对 LSH 注意力,我们从两个张量出发: 与 ,形状为 。多头机制保持不变,聚焦公式 1 的注意力计算。如前所述,主要问题是形状为 的 。但我们真正关心的是 。由于 softmax 由最大元素主导,对每个查询 只需关注 中与 最近的那些键。例如 长度为 64K 时,每个 可只考虑约 或 个最近邻键。这样高效得多,但如何在键中找最近邻?
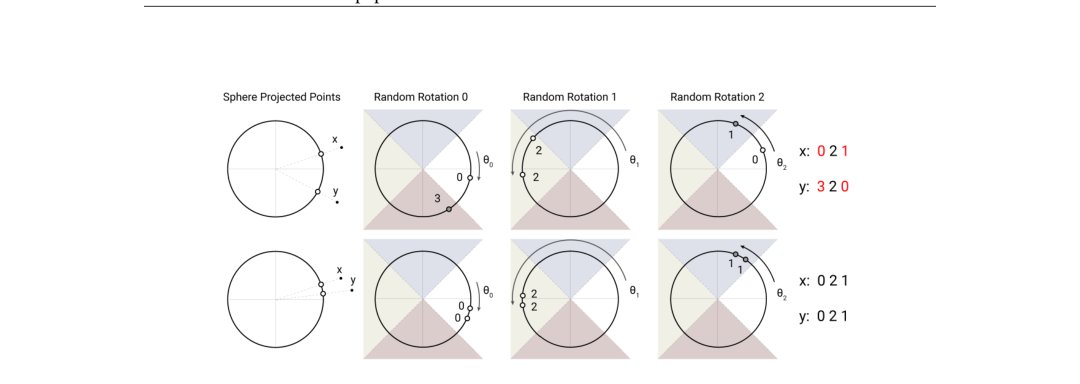
Figure 1: An angular locality sensitive hash uses random rotations of spherically projected points to establish buckets by an argmax over signed axes projections. In this highly simplified 2D depiction, two points and are unlikely to share the same hash buckets (above) for the three different angular hashes unless their spherical projections are close to one another (below).
图 1:角局部敏感哈希通过对球面投影点做随机旋转,再对带符号轴投影取 argmax,从而划分桶。在该高度简化的二维示意中,除非两点 与 的球面投影彼此靠近(下),否则它们不太可能在三种不同角哈希下落入同一哈希桶(上)。
Locality sensitive hashing.
The problem of finding nearest neighbors quickly in high-dimensional spaces can be solved by locality-sensitive hashing (LSH). A hashing scheme that assigns each vector to a hash is called locality-sensitive if nearby vectors get the same hash with high probability and distant ones do not. In our case, we actually only require that nearby vectors get the same hash with high probability and that hash-buckets are of similar size with high probability.
局部敏感哈希。
在高维空间快速找最近邻可用局部敏感哈希(LSH)。若哈希方案把每个向量 映到哈希 ,且邻近向量以高概率得相同哈希、远距离向量则否,则称该方案局部敏感。我们这里其实只要求邻近向量以高概率同哈希,且哈希桶大小以高概率相近。
We achieve this by employing random projections as follows (see Figure 1). To get hashes, we first fix a random matrix of size . We then define where denotes the concatenation of two vectors. This method is a known LSH scheme (Andoni et al. 2015) and is easy to implement and apply to batches of vectors.
做法是采用如下随机投影(见图 1)。为得到 个哈希,先固定大小为 的随机矩阵 ,再定义 ,其中 表示两向量拼接。这是已知的 LSH 方案(Andoni et al. 2015),易于实现并对向量 batch 应用。
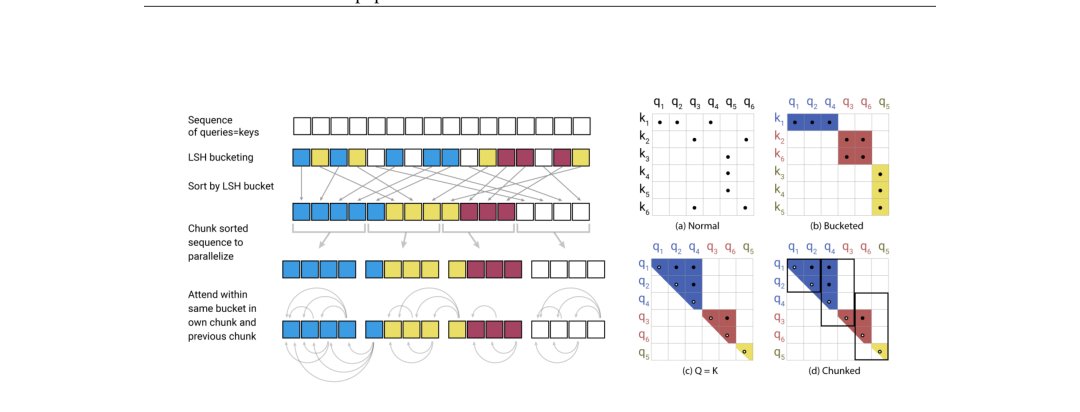
Figure 2: Simplified depiction of LSH Attention showing the hash-bucketing, sorting, and chunking steps and the resulting causal attentions. (a-d) Attention matrices for these varieties of attention.
图 2:LSH 注意力的简化示意,展示哈希分桶、排序与分块步骤,以及由此得到的因果注意力。(a–d) 为这些注意力变体的注意力矩阵。
LSH attention.
Knowing our LSH scheme and the general idea of hashing attention, we will now formalize the LSH attention we use in this paper. We first rewrite the equation for normal attention, (1), for a single query position at a time:
LSH 注意力。
在了解 LSH 方案与哈希注意力的一般想法后,我们形式化本文所用的 LSH 注意力。先把普通注意力公式 (1) 改写为每次只针对单个查询位置 :
We introduce the notation to represent the set that the query at position attends to, and to denote the partition function (i.e. the normalizing term in the softmax). For clarity, we also omit scaling by .
我们引入记号 表示位置 的查询所关注的集合, 表示配分函数(即 softmax 中的归一化项)。为清晰起见,也省略了除以 的缩放。
For batching purposes we typically perform attention over a larger set while masking out elements not in :
为便于批处理,通常在更大的集合 上做注意力,并对不在 中的元素做掩码:
$$o_{i}=\sum_{j\in\widetilde{\mathcal{P}}{i}}\exp\left(q{i}\cdot k_{j}-m(j,\mathcal{P}{i})-z(i,\mathcal{P}{i})\right)v_{j}\quad\text{ where }\ m(j,\mathcal{P}{i})=\begin{cases}\infty&\text{if }j\notin\mathcal{P}{i}\
0&\text{otherwise}\end{cases} \tag{3}$$
Now we turn to LSH attention, which we can think of in terms of restricting the set of target items a query position can attend to, by only allowing attention within a single hash bucket.
现在转到 LSH 注意力:可把它理解为限制查询位置 可关注的目标集合 ,只允许在同一哈希桶内做注意力。
Figure 2(a-b) shows a schematic comparison of full-attention with a hashed variant. Part (a) depicts that the attention matrix for full attention is typically sparse, but the computation does not take advantage of this sparsity. In (b), the queries and keys have been sorted according to their hash bucket. Since similar items fall in the same bucket with high probability, the full attention pattern can be approximated by only allowing attention within each bucket.
图 2(a-b) 示意比较了全注意力与哈希变体。图 (a) 表明全注意力矩阵通常稀疏,但计算并未利用该稀疏性。图 (b) 中查询与键已按哈希桶排序。由于相似项以高概率落入同一桶,只需允许桶内注意力即可近似全注意力模式。
Hash buckets in this formulation tend to be uneven in size, which makes it difficult to batch across buckets. Moreover, the number of queries and the number of keys within a bucket may be unequal – in fact, it is possible for a bucket to contain many queries but no keys. To alleviate these issues, we first ensure that by setting . Next, we sort the queries by bucket number and, within each bucket, by sequence position; this defines a permutation where after sorting. In the sorted attention matrix, pairs from the same bucket will cluster near the diagonal (as depicted in Figure 2c). We can follow a batching approach where chunks of consecutive queries (after sorting) attend to each other, and one chunk back (Figure 2d). Following our earlier notation, this corresponds to setting:
该表述下哈希桶大小往往不均匀,难以跨桶批处理。而且桶内查询数与键数可能不等——甚至可能出现桶中查询很多却没有键。为缓解这些问题,我们先令 ,从而保证 。接着按桶号、桶内再按序列位置对查询排序;这定义了排序后 的置换。在排序后的注意力矩阵中,同桶的对会聚在对角线附近(如图 2c)。可采用批处理:排序后每 个连续查询彼此关注,并再关注前一块(图 2d)。按先前记号,这对应于:
If , then . In practice we set (where is the sequence length). The average bucket size is , and we assume that the probability of a bucket growing to twice that size is sufficiently low. The overall process of LSH attention is summarized in Figure 2.
若 ,则 。实践中设 ( 为序列长度)。平均桶大小为 ,我们假定桶涨到两倍大小的概率足够低。LSH 注意力整体流程总结于图 2。
Multi-round LSH attention.
With hashing, there is always a small probability that similar items nevertheless fall in different buckets. This probability can be reduced by doing multiple rounds of hashing with distinct hash functions , such that:
多轮 LSH 注意力。
使用哈希时,相似项仍有小概率落入不同桶。可通过 个不同哈希函数 做多轮哈希来降低该概率,使得:
The multi-round case essentially involves performing LSH attention times in parallel; the details of the procedure are described in in Appendix A.
多轮情形本质上是并行执行 次 LSH 注意力;细节见附录 A。
Causal masking for shared-QK attention.
In a Transformer decoder, masking (denoted by in Equation 3) is used to prevent positions from attending into the future. To implement masking in LSH attention, we associate every query/key vector with a position index, re-order the position indices using the same permutations used to sort the query/key vectors, and then use a comparison operation to compute the mask.
共享 QK 注意力的因果掩码。
在 Transformer 解码器中,掩码(公式 3 中的 )用于阻止位置关注未来。为在 LSH 注意力中实现掩码,我们给每个查询/键向量关联位置下标,用排序查询/键时同一置换重排位置下标,再用比较运算计算掩码。
While attention to the future is not allowed, typical implementations of the Transformer do allow a position to attend to itself. Such behavior is undesirable in a shared-QK formulation because the dot-product of a query vector with itself will almost always be greater than the dot product of a query vector with a vector at another position. We therefore modify the masking to forbid a token from attending to itself, except in situations where a token has no other valid attention targets (e.g. the first token in a sequence).
虽然不允许关注未来,典型 Transformer 实现确实允许位置关注自身。在共享 QK 设定下这不受欢迎,因为查询与自身的点积几乎总大于与其他位置的点积。因此我们修改掩码,禁止 token 关注自身,除非该 token 没有其他合法关注目标(例如序列的第一个 token)。
| Attention Type | Memory Complexity | Time Complexity |
|---|---|---|
| Scaled Dot-Product | ||
| Memory-Efficient | ||
| LSH Attention |
Table 1: Memory and time complexity of attention variants. We write for length, for batch size, for the number of heads, for the number of LSH chunks, for the number of hash repetitions.
| 注意力类型 | 显存复杂度 | 时间复杂度 |
|---|---|---|
| 缩放点积 | ||
| 省显存 | ||
| LSH 注意力 |
表 1:各注意力变体的显存与时间复杂度。 为长度, 为 batch 大小, 为头数, 为 LSH 块数, 为哈希重复次数。
2.1 Analysis on a synthetic task
2.1 合成任务上的分析
To verify the performance of LSH attention and study its behavior, we start with the following synthetic task: duplicate a sequence of symbols. In this task, each training and testing example has the form where is a sequence of symbols ranging from to (we use in our experiments). An example with the word of length is given below.
为验证 LSH 注意力表现并研究其行为,我们从如下合成任务开始:复制一串符号。每个训练与测试样本形如 ,其中 是取值 到 的符号序列(实验取 )。下面给出 的示例。
To study LSH attention, we train a language model on examples of the above form where each is of length (so the whole input is of length ). As this is a language modeling task, we always predict the next symbol given all the previous ones, but we mask the loss and accuracy to only consider positions in the second half of the input, i.e., those that can actually be predicted.
为研究 LSH 注意力,我们在上述形式的样本上训练语言模型,其中每个 长 (故整段输入 长 )。作为语言建模任务,我们总是在给定全部前文的条件下预测下一符号,但对损失与准确率做掩码,只计输入后半段——即真正可预测的那些位置。
The above task can be solved perfectly (to accuracy 100% and loss 0) by a 1-layer Transformer model. Note though, that it requires non-local attention lookups, so it cannot be solved by any model relying on sparse attention with a limited span. To make it easy and fast to train but similar to models used in NLP, we use a 1-layer Transformer with and heads. We train it for 150K steps in different settings: with full attention, LSH attention with , and .
上述任务可被 1 层 Transformer 完美解决(准确率 100%、损失 0)。但须注意它需要非局部的注意力查找,因此任何依赖有限跨度稀疏注意力的模型都解不了。为使训练轻快且接近 NLP 中常用模型,我们用 、4 个头的 1 层 Transformer,在 4 种设定下各训 150K 步:全注意力,以及 、、 的 LSH 注意力。
| Full Attention | LSH- | LSH- | LSH- | LSH- | |
|---|---|---|---|---|---|
| Full Attention | 100% | 94.8% | 92.5% | 76.9% | 52.5% |
| LSH- | 0.8% | 100% | 99.9% | 99.4% | 91.9% |
| LSH- | 0.8% | 100% | 99.9% | 98.1% | 86.8% |
| LSH- | 0.8% | 99.9% | 99.6% | 94.8% | 77.9% |
Table 2: Accuracies on the duplication task of a 1-layer Transformer model with full attention and with locality-sensitive hashing attention using different number of parallel hashes.
| 全注意力 | LSH- | LSH- | LSH- | LSH- | |
|---|---|---|---|---|---|
| 全注意力 | 100% | 94.8% | 92.5% | 76.9% | 52.5% |
| LSH- | 0.8% | 100% | 99.9% | 99.4% | 91.9% |
| LSH- | 0.8% | 100% | 99.9% | 98.1% | 86.8% |
| LSH- | 0.8% | 99.9% | 99.6% | 94.8% | 77.9% |
表 2:复制任务上,1 层 Transformer 在全注意力与不同并行哈希数的局部敏感哈希注意力下的准确率。
From the results summarized in Table 2 we see that a model trained with full attention can be immediately used with LSH attention, but at some loss of accuracy. When trained from scratch with LSH attention, the model trained with 4 hashes achieves almost perfect accuracy as well. Interestingly, the accuracy becomes perfect when evaluated with 8 hashes. It goes down when evaluated with 2 or 1 hashes. Models trained with less hashes show worse results but even the model trained with just 1 hash performs almost perfectly when evaluated with 8 hashes.
由表 2 汇总结果可见:用全注意力训练的模型可立即配上 LSH 注意力使用,但准确率会有损失。从零用 LSH 训练时,4 哈希模型也几乎达到完美准确率。有趣的是,用 8 哈希评估时准确率变为完美;用 2 或 1 哈希评估则下降。哈希更少的模型结果较差,但即便只用 1 哈希训练的模型,在用 8 哈希评估时也几乎完美。
3 Reversible Transformer
3 可逆 Transformer
As the above section shows, the complexity of attention can be reduced from square in length to linear, provided an approximation is acceptable. But it is clear from Table 1 that each field starts with a term: the , or alternatively cost cannot be avoided. Indeed, the activations before each layer are already of the size , so the memory use of the whole model with layers is at least . Even worse: inside the feed-forward layers of Transformer this goes up to . In a big Transformer it is usual to set and so with this again would use an impractical of memory
如上节所示,若接受近似,注意力复杂度可从长度平方降到近似线性。但表 1 清楚显示每个量都以 开头:,或等价地 的代价无法避免。的确,每层前的激活已是 ,因此 层整模显存至少为 。更糟的是:在 Transformer 前馈层内可升到 。大型 Transformer 常设 、,若 ,又会用掉不切实际的 16GB 显存。
In this section, we show how to reduce this cost by first dealing with the part of the term using reversible layers and then showing how chunking can allow us to handle the problem. The effects of each of these approaches on memory and time complexity are summarized in Table 3.
本节说明如何先用可逆层处理该项中的 ,再说明切块如何应对 问题。各做法对显存与时间复杂度的影响汇总于表 3。
RevNets.
Reversible residual networks were introduced by Gomez et al. 2017 where it was shown that they can replace ResNets for image classification. The main idea is to allow the activations at any given layer to be recovered from the activations at the following layer, using only the model parameters. Rather than having to checkpoint intermediate values for use in the backward pass, layers can be reversed one-by-one as back-propagation proceeds from the output of the network to its input. Whereas a normal residual layer performs a function that operates on a single input and produces a single output and has the form , a reversible layer works on pairs of inputs/outputs: , and follows the equations:
RevNet。
可逆残差网络由 Gomez et al. 2017 提出,并表明可替代用于图像分类的 ResNet。核心想法是:任意层的激活可仅用模型参数从下一层激活恢复。不必为反向传播检查点保存中间值,反向从网络输出走向输入时,可逐层反演。普通残差层对单输入单输出执行 ,形如 ;可逆层作用于输入/输出对:,并遵循:
A layer can be reversed by subtracting (rather than adding) the residuals:
通过减去(而非加上)残差即可反演一层:
Reversible Transformer.
We apply the RevNet idea to the Transformer by combining the attention and feed-forward layers inside the revnet block. In the notation above, F becomes an attention layer while G becomes the feed-forward layer. Note that Layer Normalization (Ba et al. 2016) is moved inside the residual blocks.
可逆 Transformer。
我们把 RevNet 思想用于 Transformer:把注意力与前馈层组合进 revnet 块。在上述记号中, 为注意力层, 为前馈层。注意 Layer Normalization(Ba et al. 2016)移入残差块内部。
The reversible Transformer does not need to store activations in each layer and so gets rid of the term. In Section 5 we show that it performs the same as the normal Transformer when using the same number of parameters; we achieve this by having both and have size .
可逆 Transformer 不必在每层存储激活,从而消去 项。第 5 节表明在参数量相同时其表现与普通 Transformer 相当;我们通过令 与 均为 大小做到这一点。
Chunking.
While reversibility covers the term, the thicker layers can still use a lot of memory. The feed-forward layer in particular can use intermediate vectors of dimensionality or higher. However, computations in feed-forward layers are completely independent across positions in a sequence, so the computation can be split into chunks:
切块。
可逆性覆盖了 项,但更厚的层仍可能很吃显存。尤其前馈层可能使用 或更高维的中间向量。不过前馈层计算在序列各位置完全独立,因此可切成 块:
This layer is typically batched by performing operations for all positions in parallel, but operating on one chunk at a time can reduce memory. The reverse computation in (8) and the backward pass are also chunked. In addition to the feed-forward layers, for models with large vocabulary (more than word types) we also chunk the log-probabilities at the output and calculate the loss for sections of the sequence at a time.
该层通常对所有位置并行批处理;改为每次一块可降低显存。(8) 中的反向计算与反向传播同样切块。除前馈层外,对大词表(词型数多于 )模型,我们也对输出对数概率切块,并按序列片段计算损失。
Chunking, large batches and parameter reuse.
With chunking and reversible layers the memory we use for activations in the whole network is independent of the number of layers. The same is not true for parameters though as their number grows with the number of layers. This problem is remedied though because we can swap layer parameters to and from CPU memory when this layer is not computing. In a standard Transformer this would be inefficient because memory transfer to CPU is slow. The batch size multiplied by length in Reformer is much larger though and therefore the amount of compute done with the parameters amortizes the cost of their transfer.
切块、大 batch 与参数复用。
有了切块与可逆层,整网用于激活的显存与层数无关。参数则不然,其数量随层数增长。补救办法是:某层不在计算时,可把该层参数换入/换出 CPU 内存。在标准 Transformer 中这往往低效,因为向 CPU 传参很慢。但 Reformer 中 batch 乘长度大得多,参数上的计算量足以摊销传输成本。
| Model Type | Memory Complexity | Time Complexity |
|---|---|---|
| Transformer | ||
| Reversible Transformer | ||
| Chunked Reversible Transformer | ||
| LSH Transformer | ||
| Reformer |
Table 3: Memory and time complexity of Transformer variants. We write and for model depth and assume ; stands for batch size, for length, for the number of layers. We assume so and we write .
| 模型类型 | 显存复杂度 | 时间复杂度 |
|---|---|---|
| Transformer | ||
| 可逆 Transformer | ||
| 切块可逆 Transformer | ||
| LSH Transformer | ||
| Reformer |
表 3:各 Transformer 变体的显存与时间复杂度。、 为模型深度,并假定 ; 为 batch 大小, 为长度, 为层数。假定 ,故 ,并记 。
4 Related Work
4 相关工作
The Transformer model introduced in (Vaswani et al. 2017) has been used widely in natural language tasks and further extended to model diverse data such as music scores (Huang et al. 2018), and images (Parmar et al. 2018; Ramachandran et al. 2019). Most notably, this model class has been applied successfully in the self-supervised training of extremely large language models (Devlin et al. 2018; Radford et al. 2019).
(Vaswani et al. 2017)提出的 Transformer 已广泛用于自然语言任务,并扩展到乐谱(Huang et al. 2018)、图像(Parmar et al. 2018;Ramachandran et al. 2019)等多样数据。尤为重要的是,该类模型已成功用于极大规模语言模型的自监督训练(Devlin et al. 2018;Radford et al. 2019)。
Given the enormous computational requirements of state of the art sequence models, there has been increasing interest in finding methods to reduce the memory footprint and computational requirements of Transformer models. In addition to standard methods such as precision reduction and gradient checkpointing (Sohoni et al. 2019), more efficient versions of the Transformer model’s self-attention mechanism (Sukhbaatar et al. 2019a; Sukhbaatar et al. 2019b) have also recently been explored.
鉴于最强序列模型的巨大算力需求,降低 Transformer 显存与计算需求的方法越来越受关注。除精度降低与梯度检查点(Sohoni et al. 2019)等标准手段外,更高效的自注意力机制变体(Sukhbaatar et al. 2019a;Sukhbaatar et al. 2019b)近来也被探索。
In particular, leveraging sparsity in the attention layers has proved fruitful. OpenAI introduced the sparse Transformer (Child et al. 2019) which exploits a factorized sparse representation of attention. Using product-key attention to increase the key space has also been used to reduce memory requirements in the feed-forward layers with no loss in performance (Lample et al. 2019).
尤其是,利用注意力层稀疏性被证明富有成效。OpenAI 提出稀疏 Transformer(Child et al. 2019),利用分解的稀疏注意力表示。用乘积键注意力扩大键空间,也已用于在不损失性能的前提下降低前馈层显存需求(Lample et al. 2019)。
Locality-sensitive hashing (LSH) has, to our knowledge, not been directly applied to Transformer attention layers before. But previous work using external memory with neural networks has dealt with memories of large sizes. The original implementation of memory networks (Weston et al. 2014) and later work on scaling it (Bordes et al. 2015; Chandar et al. 2016) used memory with size in the millions. The cost of doing so is that the memory must be fixed prior to training. Moreover, since during the beginning of training the model is unlikely to query the memory correctly, strong supervision is used to encourage the model to query memory locations that are useful. These hints are either given as additional supervising information by the task or determined heuristically as in Hill et al. 2015. The requirement that the memory be fixed before has been removed in Santoro et al. 2016 at the cost of memory size and later alleviated by Rae et al. 2016. The last paper considered memory lookups with approximate nearest neighbors including both LSH and random kd-trees, but only for lookups in external memory.
据我们所知,局部敏感哈希(LSH)此前尚未直接用于 Transformer 注意力层。但使用外部记忆的神经网络先前工作已处理百万级规模记忆。记忆网络原始实现(Weston et al. 2014)及后续扩展(Bordes et al. 2015;Chandar et al. 2016)使用百万级记忆,代价是记忆须在训练前固定。而且训练初期模型不太可能正确查询记忆,因此使用强监督鼓励模型查询有用位置。这些提示或由任务额外给出,或如 Hill et al. 2015 启发式确定。Santoro et al. 2016 去掉了训练前固定记忆的要求,代价是记忆规模;Rae et al. 2016 后来缓解了这一点。后者考虑了含 LSH 与随机 kd 树在内的近似最近邻记忆查找,但仅针对外部记忆查找。
5 Experiments
5 实验
In this section we present experimental results demonstrating the techniques described above. We analyze the techniques one-by-one to make clear which combinations have impact on performance. We start by showing that reversible layers and shared query-key spaces do not impact performance, then proceed to analyze hashing attention and finally the full Reformer model.
本节给出上述技巧的实验结果。我们逐项分析,以分清哪些组合影响性能。先表明可逆层与共享查询-键空间不影响性能,再分析哈希注意力,最后是完整 Reformer。
We ran our experiments on the imagenet64 and enwik8-64K tasks, where the latter is a variant of enwik8 that is chunked into subsequences of tokens. We use 3-layer models for our ablations so as to make it tractable to compare with the regular Transformer, which has high memory usage and performs full attention. All experiments have , , , and a total batch size of 8 sequences. We used the Adafactor optimizer (Shazeer & Stern 2018) for training these models. We also evaluate on the WMT 2014 English-to-German translation task, following the hyperparameters of Vaswani et al. 2017. Training for all experiments was parallelized across 8 devices (8 GPUs or 8 TPU v3 cores). Code for training our models is made publicly available.[^2]
实验在 imagenet64 与 enwik8-64K 上完成,后者是把 enwik8 切成 token 子序列的变体。消融用 3 层模型,以便与显存高、做全量 注意力的常规 Transformer 可比。全部实验取 ,,,总 batch 为 8 条序列。训练用 Adafactor 优化器(Shazeer & Stern 2018)。我们也在 WMT 2014 英译德上评估,超参跟随 Vaswani et al. 2017。全部实验跨 8 设备并行(8 GPU 或 8 个 TPU v3 核)。训练代码已公开。[^2]
Effect of sharing QK.
We first consider the effect of shared-QK attention on a regular Transformer model. Shared-QK attention sets and prevents tokens from attending to themselves (except when no other context is available). In the left part of Figure 3, we plot perplexity curves for both regular and shared-QK attention. A shared query-key space does not perform worse than regular attention; in fact, for enwik8 it appears to train slightly faster. In other words, we are not sacrificing accuracy by switching to shared-QK attention.
共享 QK 的影响。
我们先考察共享 QK 注意力对常规 Transformer 的影响。共享 QK 设 ,并阻止 token 关注自身(除非没有其他上下文)。图 3 左绘出常规与共享 QK 注意力的困惑度曲线。共享查询-键空间并不比常规注意力差;在 enwik8 上甚至略快。换言之,改用共享 QK 并未牺牲准确率。
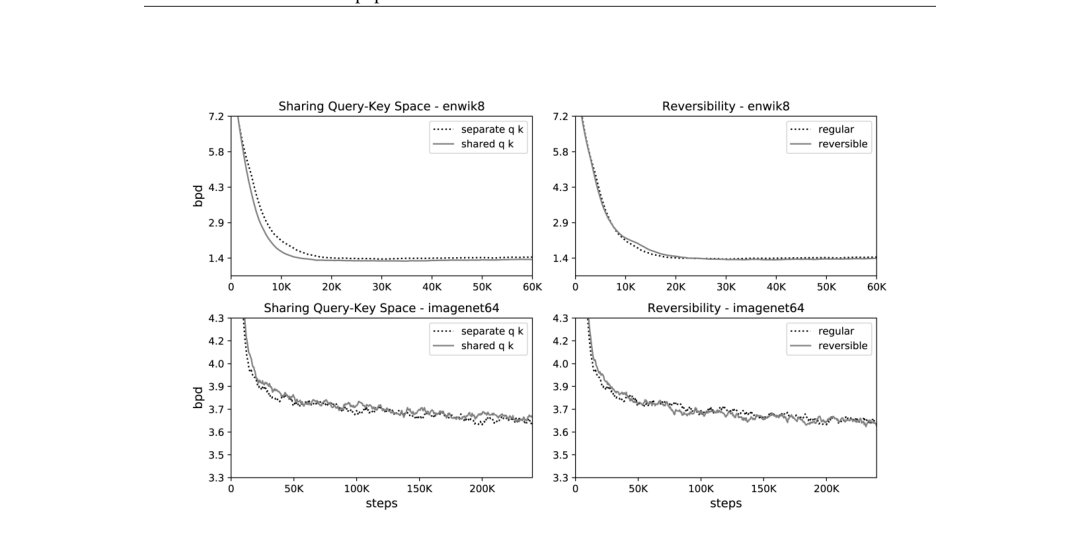
Figure 3: Effect of shared query-key space (left) and reversibility (right) on performance on enwik8 and imagenet64 training. The curves show bits per dim on held-out data.
图 3:共享查询-键空间(左)与可逆性(右)对 enwik8 与 imagenet64 训练表现的影响。曲线为留出集上的 bits per dim。
| sacreBLEU | |||
|---|---|---|---|
| Model | BLEU | Uncased[^3] | Cased[^4] |
| Vaswani et al. 2017, base model | 27.3 | ||
| Vaswani et al. 2017, big | 28.4 | ||
| Ott et al. 2018, big | 29.3 | ||
| Reversible Transformer (base, 100K steps) | 27.6 | 27.4 | 26.9 |
| Reversible Transformer (base, 500K steps, no weight sharing) | 28.0 | 27.9 | 27.4 |
| Reversible Transformer (big, 300K steps, no weight sharing) | 29.1 | 28.9 | 28.4 |
Table 4: BLEU scores on newstest2014 for WMT English-German (En–De). We additionally report detokenized BLEU scores as computed by sacreBLEU (Post 2018).
| sacreBLEU | |||
|---|---|---|---|
| 模型 | BLEU | Uncased[^3] | Cased[^4] |
| Vaswani et al. 2017,base | 27.3 | ||
| Vaswani et al. 2017,big | 28.4 | ||
| Ott et al. 2018,big | 29.3 | ||
| 可逆 Transformer(base,100K 步) | 27.6 | 27.4 | 26.9 |
| 可逆 Transformer(base,500K 步,无权重共享) | 28.0 | 27.9 | 27.4 |
| 可逆 Transformer(big,300K 步,无权重共享) | 29.1 | 28.9 | 28.4 |
表 4:WMT 英德(En–De)newstest2014 上的 BLEU。另报告由 sacreBLEU(Post 2018)计算的去分词 BLEU。
Effect of reversible layers.
In the two plots on the right in Figure 3, we compare a regular Transformer per Vaswani et al. 2017 with the reversible one describe in Section 3. The two models have identical parameter counts, and the learning curves likewise appear to be nearly the same. These results show that the memory savings in the reversible Transformer do not come at the expense of accuracy.
可逆层的影响。
图 3 右侧两图比较 Vaswani et al. 2017 的常规 Transformer 与第 3 节所述可逆版本。两模型参数量相同,学习曲线也几乎一致。结果表明可逆 Transformer 的显存节省不以准确率为代价。
Reversible layers in machine translation.
We also evaluate reversible layers in the context of an encoder-decoder Transformer model for machine translation from English to German. We start by making both the encoder and the decoder fully reversible in the Transformer-base architecture, and see that the resulting model performs comparably to Vaswani et al. 2017 when trained for 100K steps. We also evaluate training for a greater number of steps and with a larger model. Reformer models are very memory-efficient, so for the latter two experiments we do not need to save memory by sharing embedding and output projection weight matrices throughout the model. Results are shown in Table 4. We do not apply LSH attention in this setting because examples are single sentences, and sentences tend to be relatively short. Our typical LSH attention configuration uses chunks of 128 tokens after hashing and sorting, whereas the examples in the WMT14 test set are all shorter than 128 tokens.
机器翻译中的可逆层。
我们还在英译德的编码器-解码器 Transformer 中评估可逆层。先在 Transformer-base 上令编码器与解码器都完全可逆,训练 100K 步时与 Vaswani et al. 2017 相当。我们也评估了更长训练与更大模型。Reformer 非常省显存,因此后两实验不必靠全模型共享嵌入与输出投影权重矩阵来省显存。结果见表 4。此设定未用 LSH 注意力,因为样本是单句,句子相对较短。我们典型的 LSH 配置在哈希排序后使用 128 token 的块,而 WMT14 测试集例句均短于 128 token。
LSH attention in Transformer.
LSH attention is an approximation for full attention that, as evidenced in Figure 4, becomes more accurate as the number of hashes increases. At , it already almost matches full attention. The computational cost of a model grows with the number of hashes, so this hyperparameter can be adjusted depending on the available compute budget. Additionally, as in Table 2, the number of hashes can be increased at evaluation time to produce more accurate results. On the right half of Figure 5, we plot the speed of different attention types vs. the sequence length, while holding the total number of tokens fixed. We see that while regular attention becomes slower at longer sequence length, LSH attention speed remains flat.
Transformer 中的 LSH 注意力。
LSH 注意力是全注意力的近似;如图 4 所示,哈希轮数增加时更准确。在 时已几乎匹配全注意力。计算成本随哈希数增长,该超参可按算力预算调节。此外,如表 2,评估时也可增加哈希数以得到更准结果。图 5 右半在固定总 token 数下,绘制不同注意力类型速度相对序列长度的变化。可见常规注意力在更长序列上变慢,而 LSH 注意力速度保持平坦。
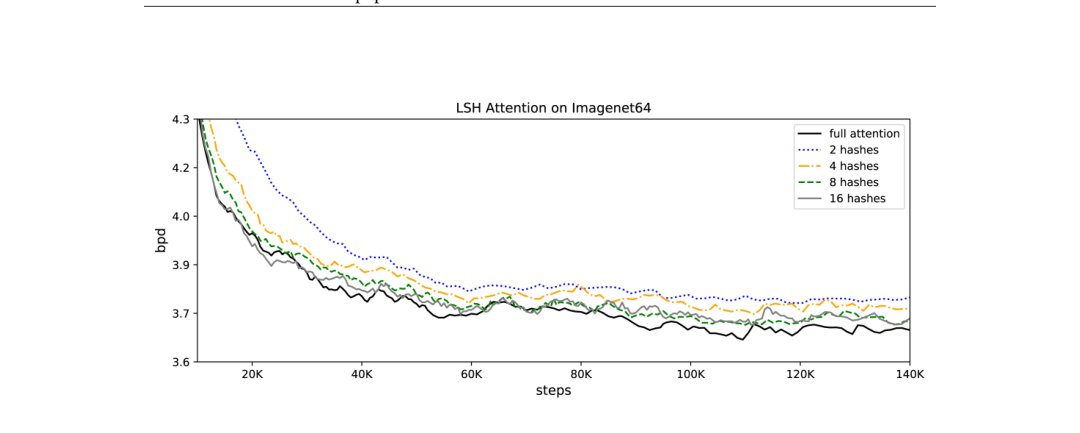
Figure 4: LSH attention performance as a function of hashing rounds on imagenet64.
图 4:imagenet64 上 LSH 注意力表现随哈希轮数的变化。
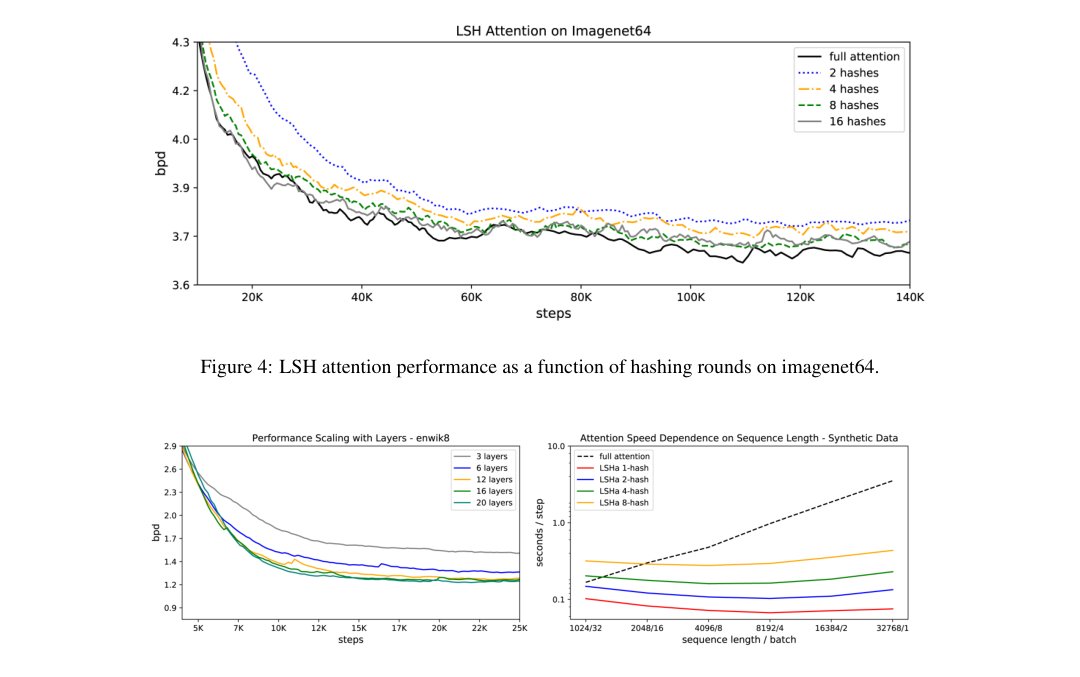
Figure 5: Left: LSH attention performance as a function of number of layers on enwik8. Right: Speed of attention evaluation as a function of input length for full- and LSH- attention.
图 5:左:enwik8 上 LSH 注意力表现随层数变化。右:全注意力与 LSH 注意力评估速度随输入长度变化。
Large Reformer models.
To verify that the Reformer can indeed fit large models on a single core and train fast on long sequences, we train up to 20-layer big Reformers on enwik8 and imagenet64. As can be seen in Figure 5, these models fit into memory and train. We were not able to train Transformer baselines in this case as they are too slow and memory-hungry, but we see clear improvement with the number of layers. A 12-layer model on enwik8 trained for 20K steps with a dropout rate of 0.1 achieves 1.19 bits/dim on the test set. We also trained a 12-layer Reformer model for longer with further tuning and improvements and we reached 1.05 bits/dim on the enwiki8 test set.
大型 Reformer。
为验证 Reformer 确实能在单核上装下大模型并在长序列上训得快,我们在 enwik8 与 imagenet64 上训练最多 20 层的大型 Reformer。如图 5 所示,这些模型能装进显存并完成训练。此情形下我们未能训练 Transformer 基线——它们太慢、太吃显存——但可见随层数增加有清晰提升。enwik8 上 12 层模型训练 20K 步、dropout 0.1,测试集达到 1.19 bits/dim。我们也对 12 层 Reformer 做了更长训练与进一步调参,enwiki8 测试集达到 1.05 bits/dim。
6 Conclusion
6 结论
Reformer combines the modeling capacity of a Transformer with an architecture that can be executed efficiently on long sequences and with small memory use even for models with a large number of layers. We believe that this will help large, richly-parameterized Transformer models become more widespread and accessible. Also, the ability to handle long sequences opens the way for the use of the Reformer on many generative tasks. In addition to generating very long coherent text, the Reformer can bring the power of Transformer models to other domains like time-series forecasting, music, image and video generation.
Reformer 把 Transformer 的建模能力与可在长序列上高效执行、即便层数很多也显存占用很小的架构结合起来。我们相信这将帮助大型、参数丰富的 Transformer 更普及、更易用。同时,处理长序列的能力为 Reformer 用于众多生成任务打开道路。除生成很长的连贯文本外,Reformer 也能把 Transformer 的力量带到时间序列预测、音乐、图像与视频生成等领域。
References
参考文献
Al-Rfou et al. (2018) Rami Al-Rfou, Dokook Choe, Noah Constant, Mandy Guo, and Llion Jones. Character-level language modeling with deeper self-attention. CoRR , abs/1808.04444, 2018. URL http://arxiv.org/abs/1808.04444 .
Andoni et al. (2015) Alexandr Andoni, Piotr Indyk, Thijs Laarhoven, Ilya P. Razenshteyn, and Ludwig Schmidt. Practical and optimal LSH for angular distance. CoRR , abs/1509.02897, 2015. URL http://arxiv.org/abs/1509.02897 .
Ba et al. (2016) Jimmy Lei Ba, Jamie Ryan Kiros, and Geoffrey E Hinton. Layer normalization. arXiv preprint arXiv:1607.06450 , 2016. URL http://arxiv.org/abs/1607.06450 .
Bordes et al. (2015) Antoine Bordes, Nicolas Usunier, Sumit Chopra, and Jason Weston. Large-scale simple question answering with memory networks. CoRR , abs/1506.02075, 2015. URL http://arxiv.org/abs/1506.02075 .
Chandar et al. (2016) Sarath Chandar, Sungjin Ahn, Hugo Larochelle, Pascal Vincent, Gerald Tesauro, and Yoshua Bengio. Hierarchical memory networks. arXiv preprint arXiv:1605.07427 , 2016.
Child et al. (2019) Rewon Child, Scott Gray, Alec Radford, and Ilya Sutskever. Generating long sequences with sparse transformers. URL https://openai.com/blog/sparse-transformers , 2019.
Devlin et al. (2018) Jacob Devlin, Ming-Wei Chang, Kenton Lee, and Kristina Toutanova. BERT: pre-training of deep bidirectional transformers for language understanding. CoRR , abs/1810.04805, 2018. URL http://arxiv.org/abs/1810.04805 .
Gomez et al. (2017) Aidan N Gomez, Mengye Ren, Raquel Urtasun, and Roger B Grosse. The reversible residual network: Backpropagation without storing activations. In Advances in neural information processing systems , pp. 2214–2224, 2017.
Hill et al. (2015) Felix Hill, Antoine Bordes, Sumit Chopra, and Jason Weston. The goldilocks principle: Reading children’s books with explicit memory representations. CoRR , abs/1511.02301, 2015. URL http://arxiv.org/abs/1511.02301 .
Huang et al. (2018) Cheng-Zhi Anna Huang, Ashish Vaswani, Jakob Uszkoreit, Noam Shazeer, Curtis Hawthorne, Andrew M Dai, Matthew D Hoffman, and Douglas Eck. Music transformer: Generating music with long-term structure. arXiv preprint arXiv:1809.04281 , 2018.
Lample et al. (2019) Guillaume Lample, Alexandre Sablayrolles, Marc’Aurelio Ranzato, Ludovic Denoyer, and Hervé Jégou. Large memory layers with product keys. CoRR , abs/1907.05242, 2019. URL http://arxiv.org/abs/1907.05242 .
Liu et al. (2018) Peter J. Liu, Mohammad Saleh, Etienne Pot, Ben Goodrich, Ryan Sepassi, Lukasz Kaiser, and Noam Shazeer. Generating wikipedia by summarizing long sequences. CoRR , abs/1801.10198, 2018. URL http://arxiv.org/abs/1801.10198 .
Ott et al. (2018) Myle Ott, Sergey Edunov, David Grangier, and Michael Auli. Scaling neural machine translation. In Proceedings of the Third Conference on Machine Translation: Research Papers , pp. 1–9, Brussels, Belgium, October 2018. Association for Computational Linguistics. doi: 10.18653/v1/W18-6301 . URL https://www.aclweb.org/anthology/W18-6301 .
Parmar et al. (2018) Niki Parmar, Ashish Vaswani, Jakob Uszkoreit, Lukasz Kaiser, Noam Shazeer, and Alexander Ku. Image transformer. CoRR , abs/1802.05751, 2018. URL http://arxiv.org/abs/1802.05751 .
Post (2018) Matt Post. A call for clarity in reporting BLEU scores. In Proceedings of the Third Conference on Machine Translation: Research Papers , pp. 186–191, Belgium, Brussels, October 2018. Association for Computational Linguistics. URL https://www.aclweb.org/anthology/W18-6319 .
Radford et al. (2019) Alec Radford, Jeff Wu, Rewon Child, David Luan, Dario Amodei, and Ilya Sutskever. Language models are unsupervised multitask learners. 2019.
Rae et al. (2016) Jack W Rae, Jonathan J Hunt, Tim Harley, Ivo Danihelka, Andrew Senior, Greg Wayne, Alex Graves, and Timothy P Lillicrap. Scaling memory-augmented neural networks with sparse reads and writes. In Advances in Neural Information Processing Systems, (NIPS) , 2016.
Ramachandran et al. (2019) Prajit Ramachandran, Niki Parmar, Ashish Vaswani, Irwan Bello, Anselm Levskaya, and Jonathon Shlens. Stand-alone self-attention in vision models. CoRR , abs/1906.05909, 2019. URL http://arxiv.org/abs/1906.05909 .
Santoro et al. (2016) Adam Santoro, Sergey Bartunov, Matthew Botvinick, Daan Wierstra, and Timothy P. Lillicrap. One-shot learning with memory-augmented neural networks. CoRR , abs/1605.06065, 2016. URL http://arxiv.org/abs/1605.06065 .
Shazeer & Stern (2018) Noam Shazeer and Mitchell Stern. Adafactor: Adaptive learning rates with sublinear memory cost. CoRR , abs/1804.04235, 2018. URL http://arxiv.org/abs/1804.04235 .
Shazeer et al. (2018) Noam Shazeer, Youlong Cheng, Niki Parmar, Dustin Tran, Ashish Vaswani, Penporn Koanantakool, Peter Hawkins, HyoukJoong Lee, Mingsheng Hong, Cliff Young, Ryan Sepassi, and Blake Hechtman. Mesh-tensorflow: Deep learning for supercomputers. CoRR , abs/1811.02084, 2018. URL http://arxiv.org/abs/1811.02084 .
Sohoni et al. (2019) Nimit Sharad Sohoni, Christopher Richard Aberger, Megan Leszczynski, Jian Zhang, and Christopher Ré. Low-memory neural network training: A technical report. CoRR , abs/1904.10631, 2019. URL http://arxiv.org/abs/1904.10631 .
Sukhbaatar et al. (2019a) Sainbayar Sukhbaatar, Edouard Grave, Piotr Bojanowski, and Armand Joulin. Adaptive attention span in transformers. CoRR , abs/1905.07799, 2019a. URL http://arxiv.org/abs/1905.07799 .
Sukhbaatar et al. (2019b) Sainbayar Sukhbaatar, Edouard Grave, Guillaume Lample, Hervé Jégou, and Armand Joulin. Augmenting self-attention with persistent memory. CoRR , abs/1907.01470, 2019b. URL http://arxiv.org/abs/1907.01470 .
Vaswani et al. (2017) Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N. Gomez, Lukasz Kaiser, and Illia Polosukhin. Attention is all you need. CoRR , 2017. URL http://arxiv.org/abs/1706.03762 .
Weston et al. (2014) Jason Weston, Sumit Chopra, and Antoine Bordes. Memory networks. CoRR , abs/1410.3916, 2014. URL http://arxiv.org/abs/1410.3916 .
Appendix A Multi-round LSH Attention
附录 A 多轮 LSH 注意力
In this section we describe in more detail the multi-hash version of our LSH attention mechanism. We first repeat Equation (3) from the main text, which describes a general formulation of attention with sparsity:
本节更详细描述我们 LSH 注意力机制的多哈希版本。先重复正文公式 (3),它给出带稀疏性的注意力一般形式:
$$o_{i}=\sum_{j\in\widetilde{\mathcal{P}}{i}}\exp\left(q{i}\cdot k_{j}-m(j,\mathcal{P}{i})-z(i,\mathcal{P}{i})\right)v_{j}\quad\text{ where }\ m(j,\mathcal{P}{i})=\begin{cases}\infty&\text{if }j\notin\mathcal{P}{i}\
0&\text{otherwise}\end{cases} \tag{3}$$
In the multi-round case, a query position can attend to key positions as defined in (6), which we also repeat here:
多轮情形下,查询位置 可关注的键位置 由 (6) 定义,这里一并重复:
For batching purposes, attention is performed on chunks of sorted queries/keys:
为便于批处理,注意力在排序后的查询/键块上执行:
Combining (3) and (6) gives:
合并 (3) 与 (6) 得到:
$$\displaystyle o_{i} \ \displaystyle=\sum_{j\in\widetilde{\mathcal{P}}{i}}\exp\left(q{i}\cdot k_{j}-m(j,\mathcal{P}{i})-z(i,\mathcal{P}{i})\right)v_{j} \ \displaystyle=\sum_{r=1}^{n_{rounds}}\exp\left(z(i,\mathcal{P}^{(r)}{i})-z(i,\mathcal{P}{i})\right)\sum_{j\in\widetilde{\mathcal{P}}^{(r)}{i}}\frac{1}{N{i,j}}\exp\left(q_{i}\cdot k_{j}-m(j,\mathcal{P}^{(r)}{i})-z(i,\mathcal{P}^{(r)}{i})\right)v_{j} \ \displaystyle=\sum_{r=1}^{n_{rounds}}\exp\left(z(i,\mathcal{P}^{(r)}{i})-z(i,\mathcal{P}{i})\right)o^{(r)}{i} \ \displaystyle o^{(r)}{i} \ \displaystyle=\sum_{j\in\widetilde{\mathcal{P}}^{(r)}{i}}\exp\left(q{i}\cdot k_{j}-m^{(r)}{i,j}-z(i,\mathcal{P}^{(r)}{i})\right)v_{j} \ \displaystyle\text{where }N_{i,j}=\left|\left{r^{\prime}:j\in\mathcal{P}^{(r^{\prime})}{i}\right}\right|\text{ and }m^{(r)}{i,j}=\begin{cases}\infty&\text{if }j\notin\mathcal{P}^{(r)}{i}\
10^{5}&\text{if }i=j\
\log N{i,j}&\text{otherwise}\end{cases} \tag{12}$$
Each round of LSH attention produces a vector that can be computed independently from other rounds, except for the inclusion of a term to avoid double-counting elements when constructing the union of sets. In our implementation we fold the factor into the masking term .
每轮 LSH 注意力产生向量 ,可与其他轮独立计算,只是引入 项以免在构造 并集时重复计数。实现中我们把 折入掩码项 。
We also modify to introduce a special case for . This case is added because causal masking in a standard Transformer allows position to attend to itself, which is not desirable in a shared-QK formulation. We set the mask to a large but finite value to disallow attention-in-place, except in the situation where a token has no other valid attention targets. For example, the first token in a sequence attends only to itself, because no prior context is available.
我们还修改 ,为 引入特例。原因是标准 Transformer 的因果掩码允许位置 关注自身,这在共享 QK 设定下不受欢迎。我们把掩码设为一个很大但有限的值以禁止原地注意力,除非该 token 没有其他合法关注目标。例如序列第一个 token 只关注自身,因为没有先验上下文。