Density estimation using Real NVP
Density estimation using Real NVP
用 Real NVP 做密度估计
Laurent Dinh † † thanks: Work was done when author was at Google Brain. Affiliation: Montreal Institute for Learning Algorithms Affiliation: University of Montreal Affiliation: Montreal, QC H3T1J4 Jascha Sohl-Dickstein Affiliation: Google Brain Samy Bengio Affiliation: Google Brain
Abstract
摘要
Unsupervised learning of probabilistic models is a central yet challenging problem in machine learning. Specifically, designing models with tractable learning, sampling, inference and evaluation is crucial in solving this task. We extend the space of such models using real-valued non-volume preserving (real NVP) transformations, a set of powerful, stably invertible, and learnable transformations, resulting in an unsupervised learning algorithm with exact log-likelihood computation, exact and efficient sampling, exact and efficient inference of latent variables, and an interpretable latent space. We demonstrate its ability to model natural images on four datasets through sampling, log-likelihood evaluation, and latent variable manipulations.
概率模型的无监督学习是机器学习中的核心难题。具体而言,设计出学习、采样、推断与评估都可处理的模型,对解决该任务至关重要。我们用实值非体积保持(real NVP)变换扩展这类模型:这是一组表达能力强、稳定可逆且可学习的变换,由此得到可精确计算对数似然、精确且高效采样、精确且高效推断潜变量,并具有可解释潜空间的无监督算法。我们在四个数据集上通过采样、对数似然评估与潜变量操作,展示其对自然图像建模的能力。
1 Introduction
1 引言
The domain of representation learning has undergone tremendous advances due to improved supervised learning techniques. However, unsupervised learning has the potential to leverage large pools of unlabeled data, and extend these advances to modalities that are otherwise impractical or impossible.
表征学习因监督学习技术的进步而取得巨大进展。然而,无监督学习有望利用大量未标注数据,并把这些进展拓展到否则不切实际或不可能的模态。
One principled approach to unsupervised learning is generative probabilistic modeling. Not only do generative probabilistic models have the ability to create novel content, they also have a wide range of reconstruction related applications including inpainting [61, 46, 59], denoising [3], colorization [71], and super-resolution [9].
无监督学习的一条原则性路径是生成式概率建模。生成式概率模型不仅能创造新内容,还在补全 [61, 46, 59]、去噪 [3]、上色 [71] 与超分辨 [9] 等重建相关应用中有广泛用途。
As data of interest are generally high-dimensional and highly structured, the challenge in this domain is building models that are powerful enough to capture its complexity yet still trainable. We address this challenge by introducing real-valued non-volume preserving (real NVP) transformations, a tractable yet expressive approach to modeling high-dimensional data.
感兴趣的数据通常高维且高度结构化,难点在于构建既足够强大以刻画其复杂度、又仍可训练的模型。我们通过引入实值非体积保持(real NVP)变换来应对这一挑战:这是一种对高维数据既可处理又富有表达力的建模路径。
This model can perform efficient and exact inference, sampling and log-density estimation of data points. Moreover, the architecture presented in this paper enables exact and efficient reconstruction of input images from the hierarchical features extracted by this model.
该模型可对数据点做高效且精确的推断、采样与对数密度估计。此外,本文架构还能从该模型提取的层级特征中精确且高效地重建输入图像。
2 Related work
2 相关工作
| Data space | Latent space | ||
|---|---|---|---|
| Inference | |||
| Generation |
Figure 1: Real NVP learns an invertible, stable, mapping between a data distribution and a latent distribution (typically a Gaussian). Here we show a mapping that has been learned on a toy 2-d dataset. The function maps samples from the data distribution in the upper left into approximate samples from the latent distribution, in the upper right. This corresponds to exact inference of the latent state given the data. The inverse function, , maps samples from the latent distribution in the lower right into approximate samples from the data distribution in the lower left. This corresponds to exact generation of samples from the model. The transformation of grid lines in and space is additionally illustrated for both and .
| 数据空间 | 潜空间 | ||
|---|---|---|---|
| 推断 | |||
| 生成 |
图 1:Real NVP 学习数据分布 与潜分布 (通常为高斯)之间可逆、稳定的映射。图中展示在二维玩具数据上学到的映射。函数 把左上角数据分布中的样本 映到右上角潜分布的近似样本 ,对应给定数据时潜状态的精确推断。逆函数 把右下角潜分布样本 映到左下角数据分布的近似样本 ,对应从模型精确生成样本。图中还分别对 与 画出了 与 空间中网格线的变换。
Substantial work on probabilistic generative models has focused on training models using maximum likelihood. One class of maximum likelihood models are those described by probabilistic undirected graphs, such as Restricted Boltzmann Machines [58] and Deep Boltzmann Machines [53]. These models are trained by taking advantage of the conditional independence property of their bipartite structure to allow efficient exact or approximate posterior inference on latent variables. However, because of the intractability of the associated marginal distribution over latent variables, their training, evaluation, and sampling procedures necessitate the use of approximations like Mean Field inference and Markov Chain Monte Carlo, whose convergence time for such complex models remains undetermined, often resulting in generation of highly correlated samples. Furthermore, these approximations can often hinder their performance [7].
大量概率生成模型工作聚焦于用最大似然训练。一类最大似然模型由概率无向图描述,例如受限玻尔兹曼机 [58] 与深度玻尔兹曼机 [53]。它们利用二分结构的条件独立性,对潜变量做高效精确或近似后验推断。但由于潜变量边际分布不可处理,其训练、评估与采样需要均值场推断与马尔可夫链蒙特卡洛等近似;这类复杂模型的收敛时间仍不确定,常产生高度相关的样本。这些近似也常削弱其表现 [7]。
Directed graphical models are instead defined in terms of an ancestral sampling procedure, which is appealing both for its conceptual and computational simplicity. They lack, however, the conditional independence structure of undirected models, making exact and approximate posterior inference on latent variables cumbersome [56]. Recent advances in stochastic variational inference [27] and amortized inference [13, 43, 35, 49], allowed efficient approximate inference and learning of deep directed graphical models by maximizing a variational lower bound on the log-likelihood [45]. In particular, the variational autoencoder algorithm [35, 49] simultaneously learns a generative network, that maps gaussian latent variables to samples , and a matched approximate inference network that maps samples to a semantically meaningful latent representation , by exploiting the reparametrization trick [68]. Its success in leveraging recent advances in backpropagation [51, 39] in deep neural networks resulted in its adoption for several applications ranging from speech synthesis [12] to language modeling [8]. Still, the approximation in the inference process limits its ability to learn high dimensional deep representations, motivating recent work in improving approximate inference [42, 48, 55, 63, 10, 59, 34].
有向图模型则由祖先采样过程定义,概念与计算都更简洁。但它们缺少无向模型的条件独立结构,使潜变量的精确与近似后验推断变得繁琐 [56]。随机变分推断 [27] 与摊销推断 [13, 43, 35, 49] 的进展,使人们可通过最大化对数似然的变分下界,对深度有向图模型做高效近似推断与学习 [45]。尤其是变分自编码器算法 [35, 49],同时学习把高斯潜变量 映到样本 的生成网络,以及把样本 映到语义有意义潜表征 的匹配近似推断网络,并利用重参数技巧 [68]。它成功借力深度网络中的反向传播 [51, 39],被用于语音合成 [12] 到语言建模 [8] 等多种应用。不过,推断过程中的近似限制了其学习高维深度表征的能力,也催生了改进近似推断的后续工作 [42, 48, 55, 63, 10, 59, 34]。
Such approximations can be avoided altogether by abstaining from using latent variables. Auto-regressive models [18, 6, 37, 20] can implement this strategy while typically retaining a great deal of flexibility. This class of algorithms tractably models the joint distribution by decomposing it into a product of conditionals using the probability chain rule according to a fixed ordering over dimensions, simplifying log-likelihood evaluation and sampling. Recent work in this line of research has taken advantage of recent advances in recurrent networks [51], in particular long-short term memory [26], and residual networks [25, 24] in order to learn state-of-the-art generative image models [61, 46] and language models [32]. The ordering of the dimensions, although often arbitrary, can be critical to the training of the model [66]. The sequential nature of this model limits its computational efficiency. For example, its sampling procedure is sequential and non-parallelizable, which can become cumbersome in applications like speech and music synthesis, or real-time rendering.. Additionally, there is no natural latent representation associated with autoregressive models, and they have not yet been shown to be useful for semi-supervised learning.
也可以干脆不用潜变量来避免这类近似。自回归模型 [18, 6, 37, 20] 通常在保持很大灵活性的同时实现这一策略。该类算法按维度上的固定顺序,用概率链式法则把联合分布分解为条件分布之积,从而简化对数似然评估与采样。近期工作借力循环网络 [51]——尤其是长短期记忆 [26]——以及残差网络 [25, 24],学到了当时最强的生成图像模型 [61, 46] 与语言模型 [32]。维度顺序虽常任意,但对训练可能至关重要 [66]。模型的串行性限制了计算效率:例如采样过程串行且不可并行,在语音、音乐合成或实时渲染等应用中会很麻烦。此外,自回归模型没有自然的潜表征,也尚未被证明对半监督学习有用。
Generative Adversarial Networks (GANs) [21] on the other hand can train any differentiable generative network by avoiding the maximum likelihood principle altogether. Instead, the generative network is associated with a discriminator network whose task is to distinguish between samples and real data. Rather than using an intractable log-likelihood, this discriminator network provides the training signal in an adversarial fashion. Successfully trained GAN models [21, 15, 47] can consistently generate sharp and realistically looking samples [38]. However, metrics that measure the diversity in the generated samples are currently intractable [62, 22, 30]. Additionally, instability in their training process [47] requires careful hyperparameter tuning to avoid diverging behavior.
另一方面,生成对抗网络(GAN)[21] 通过完全避开最大似然原则,可训练任意可微生成网络。生成网络与一个任务为区分样本与真实数据的判别网络配对;判别网络以对抗方式提供训练信号,而不使用不可处理的对数似然。训练成功的 GAN 模型 [21, 15, 47] 能稳定生成清晰且看起来真实的样本 [38]。然而,度量生成样本多样性的指标目前仍不可处理 [62, 22, 30]。此外,训练过程的不稳定 [47] 需要仔细调超参以免发散。
Training such a generative network that maps latent variable to a sample does not in theory require a discriminator network as in GANs, or approximate inference as in variational autoencoders. Indeed, if is bijective, it can be trained through maximum likelihood using the change of variable formula:
训练把潜变量 映到样本 的生成网络 ,理论上并不需要像 GAN 那样的判别网络,或像变分自编码器那样的近似推断。若 双射,便可用变量替换公式按最大似然训练:
This formula has been discussed in several papers including the maximum likelihood formulation of independent components analysis (ICA) [4, 28], gaussianization [14, 11] and deep density models [5, 50, 17, 3]. As the existence proof of nonlinear ICA solutions [29] suggests, auto-regressive models can be seen as tractable instance of maximum likelihood nonlinear ICA, where the residual corresponds to the independent components. However, naive application of the change of variable formula produces models which are computationally expensive and poorly conditioned, and so large scale models of this type have not entered general use.
该公式在多篇论文中讨论过,包括独立成分分析(ICA)的最大似然表述 [4, 28]、高斯化 [14, 11] 与深度密度模型 [5, 50, 17, 3]。非线性 ICA 解的存在性证明 [29] 表明,自回归模型可视为最大似然非线性 ICA 的可处理实例,其中残差对应独立成分。然而,天真套用变量替换公式会得到计算昂贵且病态的模型,因此这类大规模模型尚未进入通用实践。
3 Model definition
3 模型定义
In this paper, we will tackle the problem of learning highly nonlinear models in high-dimensional continuous spaces through maximum likelihood. In order to optimize the log-likelihood, we introduce a more flexible class of architectures that enables the computation of log-likelihood on continuous data using the change of variable formula. Building on our previous work in [17], we define a powerful class of bijective functions which enable exact and tractable density evaluation and exact and tractable inference. Moreover, the resulting cost function does not to rely on a fixed form reconstruction cost such as square error [38, 47], and generates sharper samples as a result. Also, this flexibility helps us leverage recent advances in batch normalization [31] and residual networks [24, 25] to define a very deep multi-scale architecture with multiple levels of abstraction.
本文通过最大似然学习高维连续空间中的高度非线性模型。为优化对数似然,我们引入更灵活的一类架构,使连续数据可用变量替换公式计算对数似然。在先前工作 [17] 基础上,我们定义一类强大的双射函数,支持精确且可处理的密度评估与精确且可处理的推断。所得代价函数不必依赖平方误差这类固定形式重建代价 [38, 47],因而样本更锐利。这种灵活性也帮助我们利用批归一化 [31] 与残差网络 [24, 25] 的近期进展,定义具有多层抽象的极深多尺度架构。
3.1 Change of variable formula
3.1 变量替换公式
Given an observed data variable , a simple prior probability distribution on a latent variable , and a bijection (with ), the change of variable formula defines a model distribution on by
给定观测数据变量 、潜变量 上的简单先验 ,以及双射 (),变量替换公式在 上定义模型分布为
where is the Jacobian of at .
其中 是 在 处的雅可比。
Exact samples from the resulting distribution can be generated by using the inverse transform sampling rule [16]. A sample is drawn in the latent space, and its inverse image generates a sample in the original space. Computing the density on a point is accomplished by computing the density of its image and multiplying by the associated Jacobian determinant . See also Figure 1. Exact and efficient inference enables the accurate and fast evaluation of the model.
所得分布的精确样本可用逆变换采样规则 [16] 生成:在潜空间抽取 ,其逆像 即原空间中的样本。点 上的密度等于其像 的密度乘以相应雅可比行列式 。亦见图 1。精确且高效的推断使模型评估既准又快。
3.2 Coupling layers
3.2 耦合层
(a) Forward propagation
(a) 前向传播
Computing the Jacobian of functions with high-dimensional domain and codomain and computing the determinants of large matrices are in general computationally very expensive. This combined with the restriction to bijective functions makes Equation 2 appear impractical for modeling arbitrary distributions.
计算高维定义域与陪域上函数的雅可比,以及大型矩阵的行列式,一般计算代价很高。再叠加必须双射的限制,公式 2 看似难以用来建模任意分布。
As shown however in [17], by careful design of the function , a bijective model can be learned which is both tractable and extremely flexible. As computing the Jacobian determinant of the transformation is crucial to effectively train using this principle, this work exploits the simple observation that the determinant of a triangular matrix can be efficiently computed as the product of its diagonal terms.
但如 [17] 所示,仔细设计函数 ,可以学到既可处理又极灵活的双射模型。按该原则有效训练的关键是计算变换的雅可比行列式,本文利用一个简单事实:三角矩阵的行列式可高效算成对角元之积。
We will build a flexible and tractable bijective function by stacking a sequence of simple bijections. In each simple bijection, part of the input vector is updated using a function which is simple to invert, but which depends on the remainder of the input vector in a complex way. We refer to each of these simple bijections as an affine coupling layer. Given a dimensional input and , the output of an affine coupling layer follows the equations
我们将堆叠一系列简单双射,构成灵活且可处理的双射函数。每个简单双射中,输入向量的一部分由一个易于求逆、但以复杂方式依赖其余输入分量的函数来更新。称每个这样的简单双射为仿射耦合层。给定 维输入 与 ,仿射耦合层的输出 满足
where and stand for scale and translation, and are functions from , and is the Hadamard product or element-wise product (see Figure 2(a)).
其中 与 分别表示缩放与平移,是从 的函数, 为 Hadamard 积或逐元乘积(见图 2(a))。
3.3 Properties
3.3 性质
The Jacobian of this transformation is
该变换的雅可比为
$$\displaystyle\frac{\partial y}{\partial x^{T}}=\left[\begin{array}[]{cc}{\mathbb{I}}{d}&0\
\frac{\partial y{d+1:D}}{\partial x_{1:d}^{T}}&\diag\big(\exp\left[s\left(x_{1:d}\right)\right]\big)\end{array}\right],$$
where is the diagonal matrix whose diagonal elements correspond to the vector . Given the observation that this Jacobian is triangular, we can efficiently compute its determinant as . Since computing the Jacobian determinant of the coupling layer operation does not involve computing the Jacobian of or , those functions can be arbitrarily complex. We will make them deep convolutional neural networks. Note that the hidden layers of and can have more features than their input and output layers.
其中 是对角元对应向量 的对角矩阵。由于该雅可比为三角阵,其行列式可高效算成 。耦合层运算的雅可比行列式计算不涉及 或 的雅可比,因此这些函数可以任意复杂。我们将把它们做成深度卷积网络。注意 与 的隐层特征数可以多于其输入与输出层。
Another interesting property of these coupling layers in the context of defining probabilistic models is their invertibility. Indeed, computing the inverse is no more complex than the forward propagation (see Figure 2(b)),
在定义概率模型的语境下,这些耦合层的另一有趣性质是可逆性。的确,求逆并不比前向传播更复杂(见图 2(b)),
$$\displaystyle\begin{cases}y_{1:d}&=x_{1:d}\
y_{d+1:D}&=x_{d+1:D}\odot\exp\big(s(x_{1:d})\big)+t(x_{1:d})\end{cases} \ \displaystyle\Leftrightarrow\begin{cases}x_{1:d}&=y_{1:d}\
x_{d+1:D}&=\big(y_{d+1:D}-t(y_{1:d})\big)\odot\exp\big(-s(y_{1:d})\big),\end{cases} \tag{8}$$
meaning that sampling is as efficient as inference for this model. Note again that computing the inverse of the coupling layer does not require computing the inverse of or , so these functions can be arbitrarily complex and difficult to invert.
这意味着对该模型而言,采样与推断同样高效。再次注意,耦合层求逆不需要计算 或 的逆,因此这些函数可以任意复杂、难以求逆。
3.4 Masked convolution
3.4 掩码卷积
Partitioning can be implemented using a binary mask , and using the functional form for ,
划分可用二值掩码 实现,并对 使用如下函数形式,
We use two partitionings that exploit the local correlation structure of images: spatial checkerboard patterns, and channel-wise masking (see Figure 3). The spatial checkerboard pattern mask has value where the sum of spatial coordinates is odd, and otherwise. The channel-wise mask is for the first half of the channel dimensions and for the second half. For the models presented here, both and are rectified convolutional networks.
我们使用两种利用图像局部相关结构的划分:空间棋盘图案,以及按通道掩码(见图 3)。空间棋盘掩码在空间坐标之和为奇数处取 1,否则取 0。通道掩码 对前一半通道维取 1,对后一半取 0。本文模型中, 与 均为带 ReLU 的卷积网络。
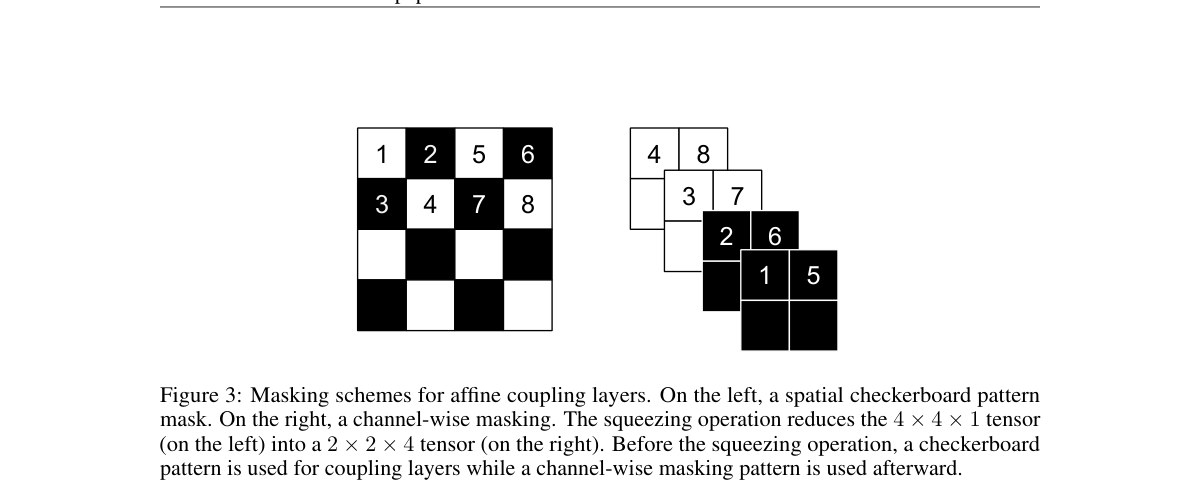
Figure 3: Masking schemes for affine coupling layers. On the left, a spatial checkerboard pattern mask. On the right, a channel-wise masking. The squeezing operation reduces the tensor (on the left) into a tensor (on the right). Before the squeezing operation, a checkerboard pattern is used for coupling layers while a channel-wise masking pattern is used afterward.
图 3:仿射耦合层的掩码方案。左侧为空间棋盘图案掩码;右侧为按通道掩码。挤压操作把左侧 张量变成右侧 张量。挤压前耦合层用棋盘图案,挤压后用通道掩码图案。
3.5 Combining coupling layers
3.5 组合耦合层
Although coupling layers can be powerful, their forward transformation leaves some components unchanged. This difficulty can be overcome by composing coupling layers in an alternating pattern, such that the components that are left unchanged in one coupling layer are updated in the next (see Figure 4(a)).
尽管耦合层可以很强,其前向变换仍使部分分量保持不变。可用交替模式堆叠耦合层来克服:一层中保持不变的分量在下一层被更新(见图 4(a))。
The Jacobian determinant of the resulting function remains tractable, relying on the fact that
所得函数的雅可比行列式仍可处理,因为
Similarly, its inverse can be computed easily as
类似地,其逆可轻易算得:
(a) In this alternating pattern, units which remain identical in one transformation are modified in the next.
(a) 在这种交替模式中,某次变换中保持不变的单元会在下一次变换中被修改。
3.6 Multi-scale architecture
3.6 多尺度架构
We implement a multi-scale architecture using a squeezing operation: for each channel, it divides the image into subsquares of shape , then reshapes them into subsquares of shape . The squeezing operation transforms an tensor into an tensor (see Figure 3), effectively trading spatial size for number of channels.
我们用挤压操作实现多尺度架构:对每个通道,把图像划成形状为 的子方块,再重塑为 。挤压把 张量变成 张量(见图 3),以空间尺寸换通道数。
At each scale, we combine several operations into a sequence: we first apply three coupling layers with alternating checkerboard masks, then perform a squeezing operation, and finally apply three more coupling layers with alternating channel-wise masking. The channel-wise masking is chosen so that the resulting partitioning is not redundant with the previous checkerboard masking (see Figure 3). For the final scale, we only apply four coupling layers with alternating checkerboard masks.
在每一尺度,我们把若干操作合成序列:先用交替棋盘掩码施加三个耦合层,再做一次挤压,最后用交替通道掩码再施加三个耦合层。通道掩码的选择使得所得划分与先前棋盘掩码不冗余(见图 3)。最后一尺度只施加四个交替棋盘掩码的耦合层。
Propagating a dimensional vector through all the coupling layers would be cumbersome, in terms of computational and memory cost, and in terms of the number of parameters that would need to be trained. For this reason we follow the design choice of [57] and factor out half of the dimensions at regular intervals (see Equation 15). We can define this operation recursively (see Figure 4(b)),
让 维向量贯穿所有耦合层,在计算、内存与需训练参数量上都会很沉重。因此我们沿用 [57] 的设计,每隔固定间隔抽出一半维度(见公式 15)。可递归定义该操作(见图 4(b)),
In our experiments, we use this operation for . The sequence of coupling-squeezing-coupling operations described above is performed per layer when computing (Equation 15). At each layer, as the spatial resolution is reduced, the number of hidden layer features in and is doubled. All variables which have been factored out at different scales are concatenated to obtain the final transformed output (Equation 17).
实验中对 使用该操作。计算 时执行上文耦合—挤压—耦合序列(公式 15)。每层空间分辨率降低时, 与 中隐层特征数翻倍。不同尺度抽出的变量拼接,得到最终变换输出(公式 17)。
As a consequence, the model must Gaussianize units which are factored out at a finer scale (in an earlier layer) before those which are factored out at a coarser scale (in a later layer). This results in the definition of intermediary levels of representation [53, 49] corresponding to more local, fine-grained features as shown in Appendix D.
因此,模型必须先把较细尺度(较早层)抽出的单元高斯化,再处理较粗尺度(较后层)抽出的单元。这定义了对应更局部、细粒度特征的中间层表征 [53, 49],如附录 D 所示。
Moreover, Gaussianizing and factoring out units in earlier layers has the practical benefit of distributing the loss function throughout the network, following the philosophy similar to guiding intermediate layers using intermediate classifiers [40]. It also reduces significantly the amount of computation and memory used by the model, allowing us to train larger models.
此外,在较早层高斯化并抽出单元,还有把损失函数分散到整网的实际好处,理念类似用中间分类器引导中间层 [40]。这也显著降低模型计算与内存,使我们能训练更大模型。
3.7 Batch normalization
3.7 批归一化
To further improve the propagation of training signal, we use deep residual networks [24, 25] with batch normalization [31] and weight normalization [2, 54] in and . As described in Appendix E we introduce and use a novel variant of batch normalization which is based on a running average over recent minibatches, and is thus more robust when training with very small minibatches.
为进一步改善训练信号传播,我们在 与 中使用带批归一化 [31] 与权重归一化 [2, 54] 的深度残差网络 [24, 25]。如附录 E 所述,我们引入并使用一种新的批归一化变体:基于近期小批量的滑动平均,因而在极小批量训练时更稳健。
We also use apply batch normalization to the whole coupling layer output. The effects of batch normalization are easily included in the Jacobian computation, since it acts as a linear rescaling on each dimension. That is, given the estimated batch statistics and , the rescaling function
我们还对整个耦合层输出施加批归一化。批归一化的效果易于纳入雅可比计算,因为它在每个维度上是线性重缩放。也就是说,给定估计的批量统计 与 ,重缩放函数
has a Jacobian determinant
的雅可比行列式为
This form of batch normalization can be seen as similar to reward normalization in deep reinforcement learning [44, 65].
这种批归一化形式可视为类似于深度强化学习中的奖励归一化 [44, 65]。
We found that the use of this technique not only allowed training with a deeper stack of coupling layers, but also alleviated the instability problem that practitioners often encounter when training conditional distributions with a scale parameter through a gradient-based approach.
我们发现该技术不仅允许训练更深的耦合层堆叠,还缓解了实践者在用基于梯度的方法训练带尺度参数的条件分布时常遇到的不稳定问题。
4 Experiments
4 实验
4.1 Procedure
4.1 流程
The algorithm described in Equation 2 shows how to learn distributions on unbounded space. In general, the data of interest have bounded magnitude. For examples, the pixel values of an image typically lie in after application of the recommended jittering procedure [64, 62]. In order to reduce the impact of boundary effects, we instead model the density of , where is picked here as . We take into account this transformation when computing log-likelihood and bits per dimension. We also augment the CIFAR-10, CelebA and LSUN datasets during training to also include horizontal flips of the training examples.
公式 2 给出的算法说明如何学习无界空间上的分布。一般而言,感兴趣的数据幅度有界。例如,按推荐的抖动流程 [64, 62] 处理后,图像像素通常落在 。为减轻边界效应,我们改为对 建模密度,此处取 。计算对数似然与每维比特数时计入该变换。训练时还对 CIFAR-10、CelebA 与 LSUN 做水平翻转增强。
We train our model on four natural image datasets: CIFAR-10 [36], Imagenet [52], Large-scale Scene Understanding (LSUN) [70], CelebFaces Attributes (CelebA) [41]. More specifically, we train on the downsampled to and versions of Imagenet [46]. For the LSUN dataset, we train on the bedroom, tower and church outdoor categories. The procedure for LSUN is the same as in [47]: we downsample the image so that the smallest side is pixels and take random crops of . For CelebA, we use the same procedure as in [38]: we take an approximately central crop of then resize it to .
我们在四个自然图像数据集上训练:CIFAR-10 [36]、Imagenet [52]、大规模场景理解(LSUN) [70]、名人脸属性(CelebA) [41]。更具体地,我们在下采样到 与 的 Imagenet 版本上训练 [46]。对 LSUN,我们在 bedroom、tower 与 church outdoor 类别上训练。LSUN 流程与 [47] 相同:把最短边下采样到 像素,再随机裁 。对 CelebA,流程与 [38] 相同:取约中心的 裁剪再缩放到 。
We use the multi-scale architecture described in Section 3.6 and use deep convolutional residual networks in the coupling layers with rectifier nonlinearity and skip-connections as suggested by [46]. To compute the scaling functions , we use a hyperbolic tangent function multiplied by a learned scale, whereas the translation function has an affine output. Our multi-scale architecture is repeated recursively until the input of the last recursion is a tensor. For datasets of images of size , we use residual blocks with hidden feature maps for the first coupling layers with checkerboard masking. Only residual blocks are used for images of size . We use a batch size of . For CIFAR-10, we use residual blocks, feature maps, and downscale only once. We optimize with ADAM [33] with default hyperparameters and use an regularization on the weight scale parameters with coefficient .
我们使用第 3.6 节的多尺度架构,并在耦合层中使用带整流非线性与跳跃连接的深度卷积残差网络,如 [46] 所建议。计算缩放函数 时,使用乘以可学习尺度的双曲正切;平移函数 为仿射输出。多尺度架构递归重复,直到最后一次递归的输入为 张量。对 图像,首批棋盘掩码耦合层使用带 个隐特征图的 个残差块; 图像只用 个残差块。批量大小为 。对 CIFAR-10,使用 个残差块、 个特征图,且只下采样一次。用默认超参的 ADAM [33] 优化,并对权重尺度参数施加系数 的 正则。
We set the prior to be an isotropic unit norm Gaussian. However, any distribution could be used for , including distributions that are also learned during training, such as from an auto-regressive model, or (with slight modifications to the training objective) a variational autoencoder.
我们将先验 设为各向同性单位高斯。不过 可用任意分布,包括训练中一并学习的分布,例如来自自回归模型,或(对训练目标稍作修改)变分自编码器。
4.2 Results
4.2 结果
| Dataset | PixelRNN [46] | Real NVP | Conv DRAW [22] | IAF-VAE [34] |
|---|---|---|---|---|
| CIFAR-10 | 3.00 | 3.49 | < 3.59 | < 3.28 |
| Imagenet () | 3.86 (3.83) | 4.28 (4.26) | < 4.40 (4.35) | |
| Imagenet () | 3.63 (3.57) | 3.98 (3.75) | < 4.10 (4.04) | |
| LSUN (bedroom) | 2.72 (2.70) | |||
| LSUN (tower) | 2.81 (2.78) | |||
| LSUN (church outdoor) | 3.08 (2.94) | |||
| CelebA | 3.02 (2.97) |
Table 1: Bits/dim results for CIFAR-10, Imagenet, LSUN datasets and CelebA. Test results for CIFAR-10 and validation results for Imagenet, LSUN and CelebA (with training results in parenthesis for reference).
| 数据集 | PixelRNN [46] | Real NVP | Conv DRAW [22] | IAF-VAE [34] |
|---|---|---|---|---|
| CIFAR-10 | 3.00 | 3.49 | < 3.59 | < 3.28 |
| Imagenet () | 3.86 (3.83) | 4.28 (4.26) | < 4.40 (4.35) | |
| Imagenet () | 3.63 (3.57) | 3.98 (3.75) | < 4.10 (4.04) | |
| LSUN (bedroom) | 2.72 (2.70) | |||
| LSUN (tower) | 2.81 (2.78) | |||
| LSUN (church outdoor) | 3.08 (2.94) | |||
| CelebA | 3.02 (2.97) |
表 1:CIFAR-10、Imagenet、LSUN 与 CelebA 的每维比特结果。CIFAR-10 为测试结果;Imagenet、LSUN 与 CelebA 为验证结果(括号内为训练结果供参考)。
We show in Table 1 that the number of bits per dimension, while not improving over the Pixel RNN [46] baseline, is competitive with other generative methods. As we notice that our performance increases with the number of parameters, larger models are likely to further improve performance. For CelebA and LSUN, the bits per dimension for the validation set was decreasing throughout training, so little overfitting is expected.
表 1 显示,每维比特数虽未超过 Pixel RNN [46] 基线,但与其他生成方法相比具有竞争力。我们注意到性能随参数量增加而提升,更大模型有望进一步改进。对 CelebA 与 LSUN,验证集每维比特在训练过程中持续下降,因此预期过拟合很少。
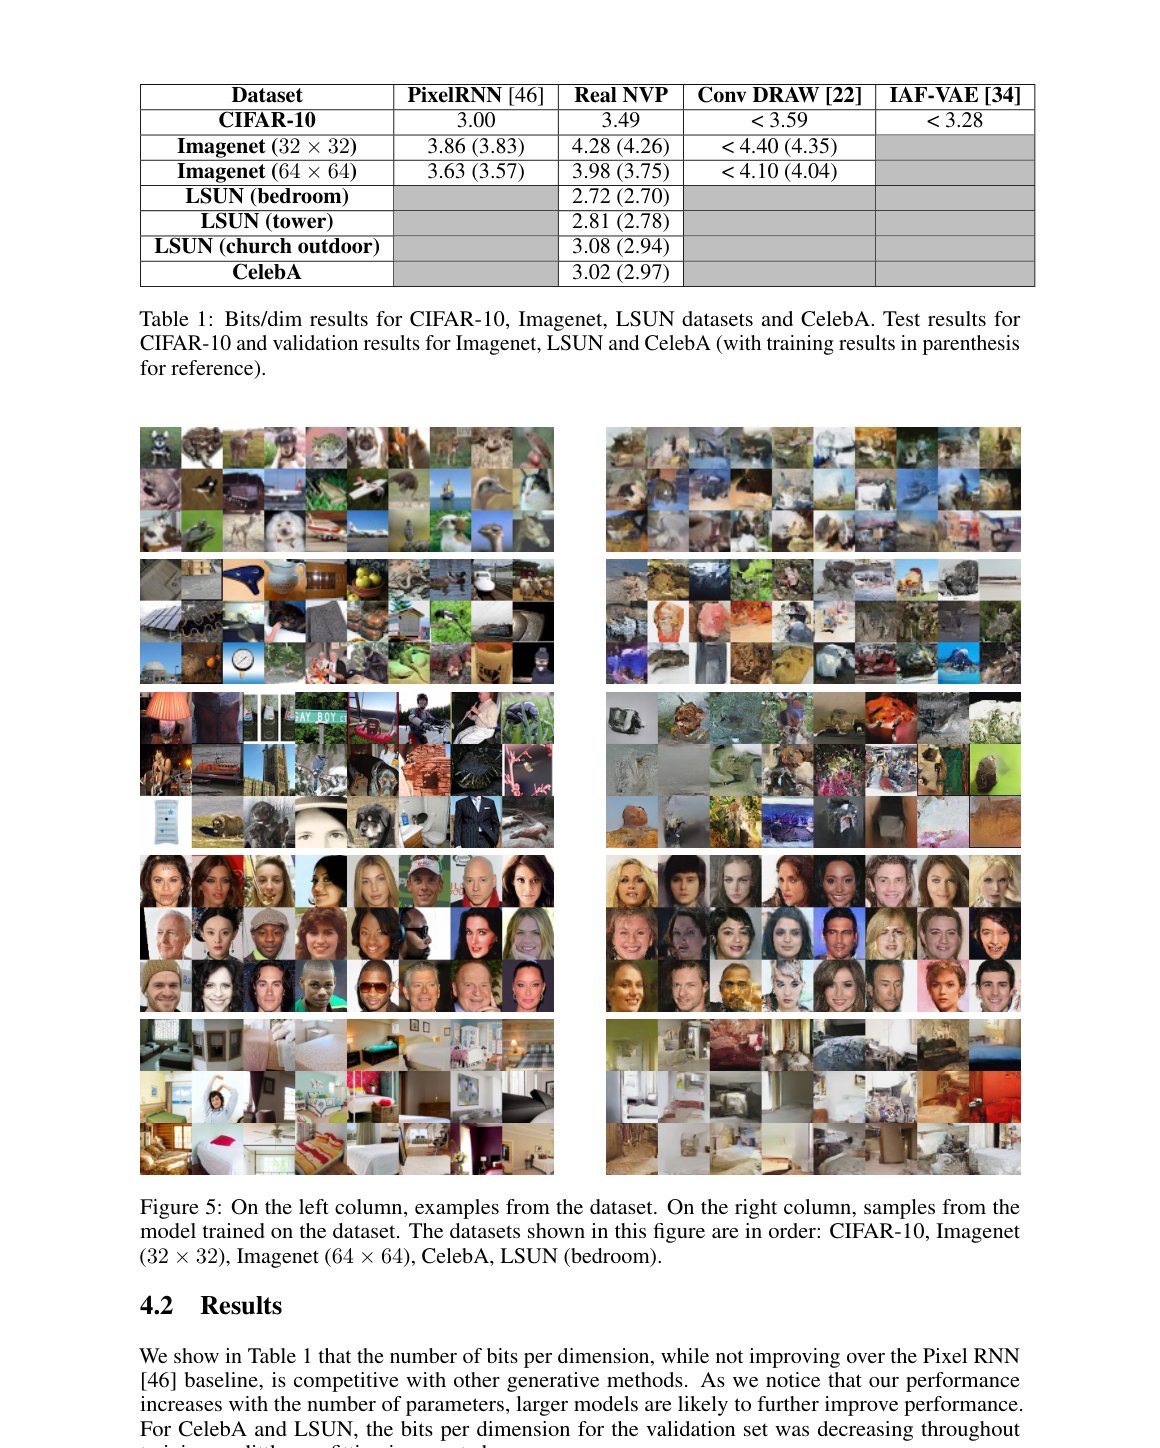
Figure 5: On the left column, examples from the dataset. On the right column, samples from the model trained on the dataset. The datasets shown in this figure are in order: CIFAR-10, Imagenet (), Imagenet (), CelebA, LSUN (bedroom).
图 5:左列为数据集中的例子;右列为在该数据集上训练的模型所采样本。图中数据集依次为:CIFAR-10、Imagenet()、Imagenet()、CelebA、LSUN(bedroom)。
We show in Figure 5 samples generated from the model with training examples from the dataset for comparison. As mentioned in [62, 22], maximum likelihood is a principle that values diversity over sample quality in a limited capacity setting. As a result, our model outputs sometimes highly improbable samples as we can notice especially on CelebA. As opposed to variational autoencoders, the samples generated from our model look not only globally coherent but also sharp. Our hypothesis is that as opposed to these models, real NVP does not rely on fixed form reconstruction cost like an norm which tends to reward capturing low frequency components more heavily than high frequency components. Unlike autoregressive models, sampling from our model is done very efficiently as it is parallelized over input dimensions. On Imagenet and LSUN, our model seems to have captured well the notion of background/foreground and lighting interactions such as luminosity and consistent light source direction for reflectance and shadows.
图 5 给出模型生成样本,并与训练集例子对照。如 [62, 22] 所述,在容量有限时,最大似然更看重多样性而非样本质量。因此模型有时会输出高度不可能的样本,在 CelebA 上尤为明显。与变分自编码器不同,我们的样本不仅全局连贯,而且锐利。我们的假设是:与这些模型不同,real NVP 不依赖 范数这类固定形式重建代价——后者往往更奖励捕捉低频分量而非高频分量。与自回归模型不同,我们的采样可在输入维度上并行,因而非常高效。在 Imagenet 与 LSUN 上,模型似乎较好捕捉了前景/背景概念,以及亮度、一致光源方向下的反射与阴影等光照交互。
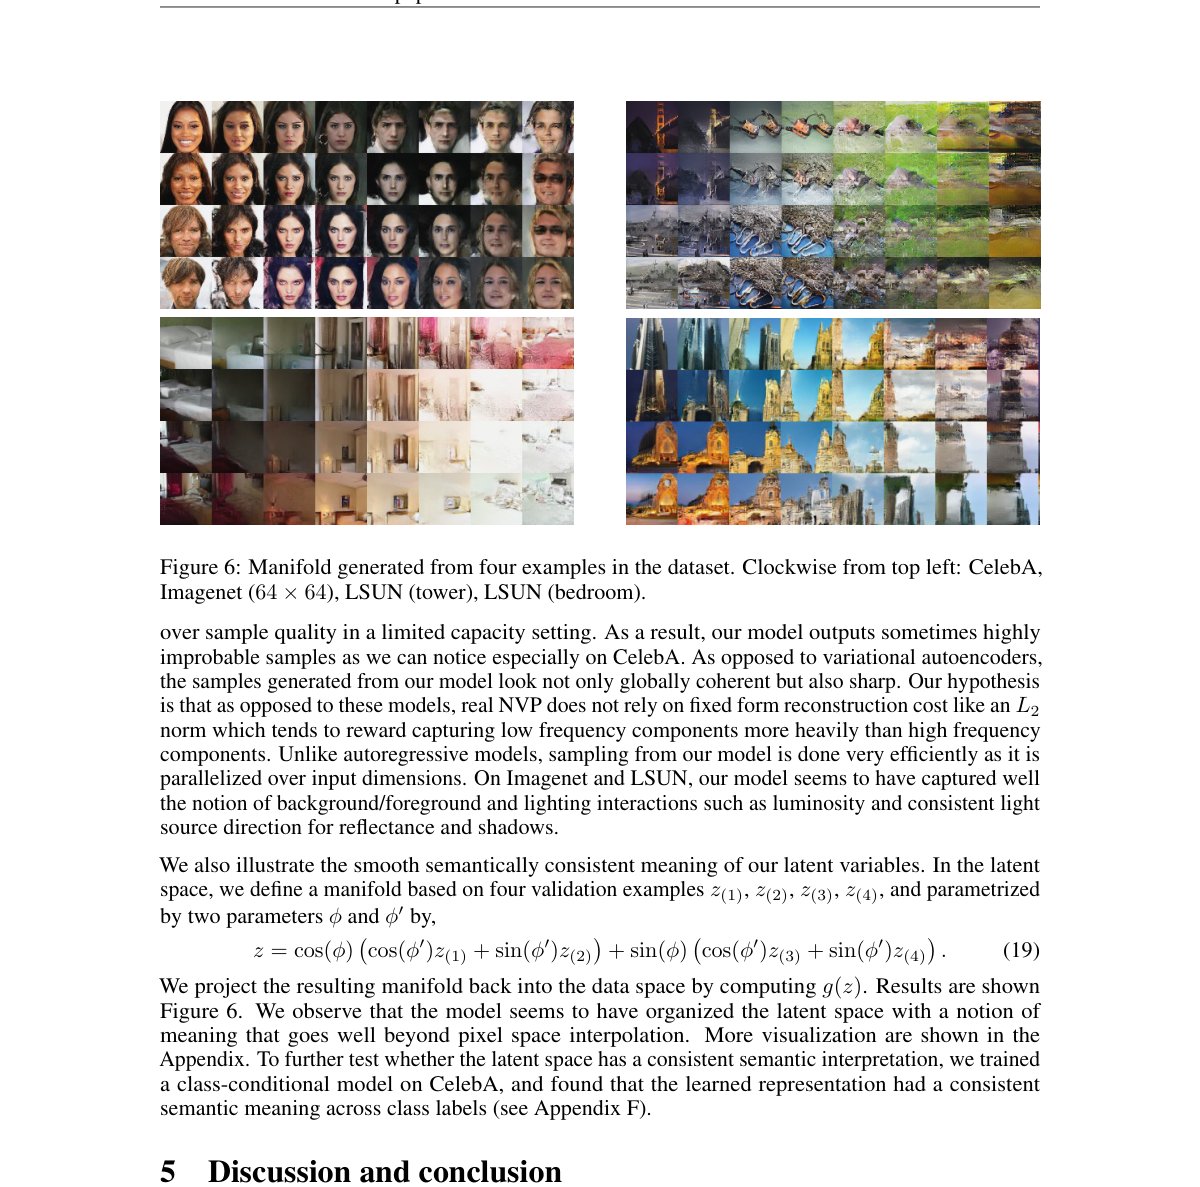
Figure 6: Manifold generated from four examples in the dataset. Clockwise from top left: CelebA, Imagenet (), LSUN (tower), LSUN (bedroom).
图 6:由数据集中四个例子生成的流形。自左上顺时针:CelebA、Imagenet()、LSUN(tower)、LSUN(bedroom)。
We also illustrate the smooth semantically consistent meaning of our latent variables. In the latent space, we define a manifold based on four validation examples , , , , and parametrized by two parameters and by,
我们还说明潜变量具有平滑且语义一致的含义。在潜空间中,基于四个验证例子 、、、,用两个参数 与 定义流形:
We project the resulting manifold back into the data space by computing . Results are shown Figure 6. We observe that the model seems to have organized the latent space with a notion of meaning that goes well beyond pixel space interpolation. More visualization are shown in the Appendix. To further test whether the latent space has a consistent semantic interpretation, we trained a class-conditional model on CelebA, and found that the learned representation had a consistent semantic meaning across class labels (see Appendix F).
通过计算 把所得流形投回数据空间。结果见图 6。我们观察到,模型对潜空间的组织所体现的语义远超像素空间插值。更多可视化见附录。为进一步检验潜空间是否具有一致的语义解释,我们在 CelebA 上训练了类别条件模型,发现所学表征在类别标签之间具有一致语义(见附录 F)。
5 Discussion and conclusion
5 讨论与结论
In this paper, we have defined a class of invertible functions with tractable Jacobian determinant, enabling exact and tractable log-likelihood evaluation, inference, and sampling. We have shown that this class of generative model achieves competitive performances, both in terms of sample quality and log-likelihood. Many avenues exist to further improve the functional form of the transformations, for instance by exploiting the latest advances in dilated convolutions [69] and residual networks architectures [60].
本文定义了一类雅可比行列式可处理的可逆函数,从而支持精确且可处理的对数似然评估、推断与采样。我们表明该类生成模型在样本质量与对数似然两方面均具竞争力。仍有许多途径可进一步改进变换的函数形式,例如利用膨胀卷积 [69] 与残差网络架构 [60] 的最新进展。
This paper presented a technique bridging the gap between auto-regressive models, variational autoencoders, and generative adversarial networks. Like auto-regressive models, it allows tractable and exact log-likelihood evaluation for training. It allows however a much more flexible functional form, similar to that in the generative model of variational autoencoders. This allows for fast and exact sampling from the model distribution. Like GANs, and unlike variational autoencoders, our technique does not require the use of a fixed form reconstruction cost, and instead defines a cost in terms of higher level features, generating sharper images. Finally, unlike both variational autoencoders and GANs, our technique is able to learn a semantically meaningful latent space which is as high dimensional as the input space. This may make the algorithm particularly well suited to semi-supervised learning tasks, as we hope to explore in future work.
本文提出的技术弥合了自回归模型、变分自编码器与生成对抗网络之间的差距。与自回归模型一样,它允许可处理且精确的对数似然评估以供训练;但其函数形式灵活得多,类似变分自编码器的生成模型,从而可从模型分布快速精确采样。与 GAN 一样、与变分自编码器不同,本技术不需要固定形式重建代价,而是以更高层特征定义代价,生成更锐利的图像。最后,与变分自编码器和 GAN 都不同,本技术能学到与输入空间同维、且语义有意义的潜空间。这可能使算法特别适于半监督任务,我们希望在未来工作中探索。
Real NVP generative models can additionally be conditioned on additional variables (for instance class labels) to create a structured output algorithm. More so, as the resulting class of invertible transformations can be treated as a probability distribution in a modular way, it can also be used to improve upon other probabilistic models like auto-regressive models and variational autoencoders. For variational autoencoders, these transformations could be used both to enable a more flexible reconstruction cost [38] and a more flexible stochastic inference distribution [48]. Probabilistic models in general can also benefit from batch normalization techniques as applied in this paper.
Real NVP 生成模型还可条件于额外变量(例如类别标签),以构成结构化输出算法。更进一步,所得可逆变换类可作为概率分布模块化使用,从而改进自回归模型与变分自编码器等其他概率模型。对变分自编码器,这些变换既可支持更灵活的重建代价 [38],也可支持更灵活的随机推断分布 [48]。一般概率模型也可受益于本文所用的批归一化技术。
The definition of powerful and trainable invertible functions can also benefit domains other than generative unsupervised learning. For example, in reinforcement learning, these invertible functions can help extend the set of functions for which an operation is tractable for continuous Q-learning [23] or find representation where local linear Gaussian approximations are more appropriate [67].
强大且可训练的可逆函数定义也可惠及生成式无监督学习以外的领域。例如在强化学习中,这些可逆函数有助于扩展连续 Q 学习中 可处理的函数集合 [23],或找到局部线性高斯近似更合适的表征 [67]。
6 Acknowledgments
6 致谢
The authors thank the developers of Tensorflow [1]. We thank Sherry Moore, David Andersen and Jon Shlens for their help in implementing the model. We thank Aäron van den Oord, Yann Dauphin, Kyle Kastner, Chelsea Finn, Maithra Raghu, David Warde-Farley, Daniel Jiwoong Im and Oriol Vinyals for fruitful discussions. Finally, we thank Ben Poole, Rafal Jozefowicz and George Dahl for their input on a draft of the paper.
作者感谢 Tensorflow [1] 的开发者。感谢 Sherry Moore、David Andersen 与 Jon Shlens 在实现模型上的帮助。感谢 Aäron van den Oord、Yann Dauphin、Kyle Kastner、Chelsea Finn、Maithra Raghu、David Warde-Farley、Daniel Jiwoong Im 与 Oriol Vinyals 的富有成效讨论。最后,感谢 Ben Poole、Rafal Jozefowicz 与 George Dahl 对论文草稿的意见。
References
参考文献
[1] Martın Abadi, Ashish Agarwal, Paul Barham, Eugene Brevdo, Zhifeng Chen, Craig Citro, Greg S Corrado, Andy Davis, Jeffrey Dean, Matthieu Devin, et al. Tensorflow: Large-scale machine learning on heterogeneous distributed systems. arXiv preprint arXiv:1603.04467 , 2016.
[2] Vijay Badrinarayanan, Bamdev Mishra, and Roberto Cipolla. Understanding symmetries in deep networks. arXiv preprint arXiv:1511.01029 , 2015.
[3] Johannes Ballé, Valero Laparra, and Eero P Simoncelli. Density modeling of images using a generalized normalization transformation. arXiv preprint arXiv:1511.06281 , 2015.
[4] Anthony J Bell and Terrence J Sejnowski. An information-maximization approach to blind separation and blind deconvolution. Neural computation , 7(6):1129–1159, 1995.
[5] Yoshua Bengio. Artificial neural networks and their application to sequence recognition. 1991.
[6] Yoshua Bengio and Samy Bengio. Modeling high-dimensional discrete data with multi-layer neural networks. In NIPS , volume 99, pages 400–406, 1999.
[7] Mathias Berglund and Tapani Raiko. Stochastic gradient estimate variance in contrastive divergence and persistent contrastive divergence. arXiv preprint arXiv:1312.6002 , 2013.
[8] Samuel R Bowman, Luke Vilnis, Oriol Vinyals, Andrew M Dai, Rafal Jozefowicz, and Samy Bengio. Generating sentences from a continuous space. arXiv preprint arXiv:1511.06349 , 2015.
[9] Joan Bruna, Pablo Sprechmann, and Yann LeCun. Super-resolution with deep convolutional sufficient statistics. arXiv preprint arXiv:1511.05666 , 2015.
[10] Yuri Burda, Roger Grosse, and Ruslan Salakhutdinov. Importance weighted autoencoders. arXiv preprint arXiv:1509.00519 , 2015.
[11] Scott Shaobing Chen and Ramesh A Gopinath. Gaussianization. In Advances in Neural Information Processing Systems , 2000.
[12] Junyoung Chung, Kyle Kastner, Laurent Dinh, Kratarth Goel, Aaron C Courville, and Yoshua Bengio. A recurrent latent variable model for sequential data. In Advances in neural information processing systems , pages 2962–2970, 2015.
[13] Peter Dayan, Geoffrey E Hinton, Radford M Neal, and Richard S Zemel. The helmholtz machine. Neural computation , 7(5):889–904, 1995.
[14] Gustavo Deco and Wilfried Brauer. Higher order statistical decorrelation without information loss. In G. Tesauro, D. S. Touretzky, and T. K. Leen, editors, Advances in Neural Information Processing Systems 7 , pages 247–254. MIT Press, 1995.
[15] Emily L. Denton, Soumith Chintala, Arthur Szlam, and Rob Fergus. Deep generative image models using a laplacian pyramid of adversarial networks. In Advances in Neural Information Processing Systems 28: Annual Conference on Neural Information Processing Systems 2015, December 7-12, 2015, Montreal, Quebec, Canada , pages 1486–1494, 2015.
[16] Luc Devroye. Sample-based non-uniform random variate generation. In Proceedings of the 18th conference on Winter simulation , pages 260–265. ACM, 1986.
[17] Laurent Dinh, David Krueger, and Yoshua Bengio. Nice: non-linear independent components estimation. arXiv preprint arXiv:1410.8516 , 2014.
[18] Brendan J Frey. Graphical models for machine learning and digital communication . MIT press, 1998.
[19] Leon A. Gatys, Alexander S. Ecker, and Matthias Bethge. Texture synthesis using convolutional neural networks. In Advances in Neural Information Processing Systems 28: Annual Conference on Neural Information Processing Systems 2015, December 7-12, 2015, Montreal, Quebec, Canada , pages 262–270, 2015.
[20] Mathieu Germain, Karol Gregor, Iain Murray, and Hugo Larochelle. MADE: masked autoencoder for distribution estimation. CoRR , abs/1502.03509, 2015.
[21] Ian J. Goodfellow, Jean Pouget-Abadie, Mehdi Mirza, Bing Xu, David Warde-Farley, Sherjil Ozair, Aaron C. Courville, and Yoshua Bengio. Generative adversarial nets. In Advances in Neural Information Processing Systems 27: Annual Conference on Neural Information Processing Systems 2014, December 8-13 2014, Montreal, Quebec, Canada , pages 2672–2680, 2014.
[22] Karol Gregor, Frederic Besse, Danilo Jimenez Rezende, Ivo Danihelka, and Daan Wierstra. Towards conceptual compression. arXiv preprint arXiv:1604.08772 , 2016.
[23] Shixiang Gu, Timothy Lillicrap, Ilya Sutskever, and Sergey Levine. Continuous deep q-learning with model-based acceleration. arXiv preprint arXiv:1603.00748 , 2016.
[24] Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recognition. CoRR , abs/1512.03385, 2015.
[25] Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Identity mappings in deep residual networks. CoRR , abs/1603.05027, 2016.
[26] Sepp Hochreiter and Jürgen Schmidhuber. Long short-term memory. Neural Computation , 9(8):1735–1780, 1997.
[27] Matthew D Hoffman, David M Blei, Chong Wang, and John Paisley. Stochastic variational inference. The Journal of Machine Learning Research , 14(1):1303–1347, 2013.
[28] Aapo Hyvärinen, Juha Karhunen, and Erkki Oja. Independent component analysis , volume 46. John Wiley & Sons, 2004.
[29] Aapo Hyvärinen and Petteri Pajunen. Nonlinear independent component analysis: Existence and uniqueness results. Neural Networks , 12(3):429–439, 1999.
[30] Daniel Jiwoong Im, Chris Dongjoo Kim, Hui Jiang, and Roland Memisevic. Generating images with recurrent adversarial networks. arXiv preprint arXiv:1602.05110 , 2016.
[31] Sergey Ioffe and Christian Szegedy. Batch normalization: Accelerating deep network training by reducing internal covariate shift. arXiv preprint arXiv:1502.03167 , 2015.
[32] Rafal Józefowicz, Oriol Vinyals, Mike Schuster, Noam Shazeer, and Yonghui Wu. Exploring the limits of language modeling. CoRR , abs/1602.02410, 2016.
[33] Diederik Kingma and Jimmy Ba. Adam: A method for stochastic optimization. arXiv preprint arXiv:1412.6980 , 2014.
[34] Diederik P Kingma, Tim Salimans, and Max Welling. Improving variational inference with inverse autoregressive flow. arXiv preprint arXiv:1606.04934 , 2016.
[35] Diederik P Kingma and Max Welling. Auto-encoding variational bayes. arXiv preprint arXiv:1312.6114 , 2013.
[36] Alex Krizhevsky and Geoffrey Hinton. Learning multiple layers of features from tiny images, 2009.
[37] Hugo Larochelle and Iain Murray. The neural autoregressive distribution estimator. In AISTATS , 2011.
[38] Anders Boesen Lindbo Larsen, Søren Kaae Sønderby, and Ole Winther. Autoencoding beyond pixels using a learned similarity metric. CoRR , abs/1512.09300, 2015.
[39] Yann A LeCun, Léon Bottou, Genevieve B Orr, and Klaus-Robert Müller. Efficient backprop. In Neural networks: Tricks of the trade , pages 9–48. Springer, 2012.
[40] Chen-Yu Lee, Saining Xie, Patrick Gallagher, Zhengyou Zhang, and Zhuowen Tu. Deeply-supervised nets. arXiv preprint arXiv:1409.5185 , 2014.
[41] Ziwei Liu, Ping Luo, Xiaogang Wang, and Xiaoou Tang. Deep learning face attributes in the wild. In Proceedings of International Conference on Computer Vision (ICCV) , December 2015.
[42] Lars Maaløe, Casper Kaae Sønderby, Søren Kaae Sønderby, and Ole Winther. Auxiliary deep generative models. arXiv preprint arXiv:1602.05473 , 2016.
[43] Andriy Mnih and Karol Gregor. Neural variational inference and learning in belief networks. arXiv preprint arXiv:1402.0030 , 2014.
[44] Volodymyr Mnih, Koray Kavukcuoglu, David Silver, Andrei A Rusu, Joel Veness, Marc G Bellemare, Alex Graves, Martin Riedmiller, Andreas K Fidjeland, Georg Ostrovski, et al. Human-level control through deep reinforcement learning. Nature , 518(7540):529–533, 2015.
[45] Radford M Neal and Geoffrey E Hinton. A view of the em algorithm that justifies incremental, sparse, and other variants. In Learning in graphical models , pages 355–368. Springer, 1998.
[46] Aaron van den Oord, Nal Kalchbrenner, and Koray Kavukcuoglu. Pixel recurrent neural networks. arXiv preprint arXiv:1601.06759 , 2016.
[47] Alec Radford, Luke Metz, and Soumith Chintala. Unsupervised representation learning with deep convolutional generative adversarial networks. CoRR , abs/1511.06434, 2015.
[48] Danilo Jimenez Rezende and Shakir Mohamed. Variational inference with normalizing flows. arXiv preprint arXiv:1505.05770 , 2015.
[49] Danilo Jimenez Rezende, Shakir Mohamed, and Daan Wierstra. Stochastic backpropagation and approximate inference in deep generative models. arXiv preprint arXiv:1401.4082 , 2014.
[50] Oren Rippel and Ryan Prescott Adams. High-dimensional probability estimation with deep density models. arXiv preprint arXiv:1302.5125 , 2013.
[51] David E Rumelhart, Geoffrey E Hinton, and Ronald J Williams. Learning representations by back-propagating errors. Cognitive modeling , 5(3):1, 1988.
[52] Olga Russakovsky, Jia Deng, Hao Su, Jonathan Krause, Sanjeev Satheesh, Sean Ma, Zhiheng Huang, Andrej Karpathy, Aditya Khosla, Michael Bernstein, et al. Imagenet large scale visual recognition challenge. International Journal of Computer Vision , 115(3):211–252, 2015.
[53] Ruslan Salakhutdinov and Geoffrey E Hinton. Deep boltzmann machines. In International conference on artificial intelligence and statistics , pages 448–455, 2009.
[54] Tim Salimans and Diederik P Kingma. Weight normalization: A simple reparameterization to accelerate training of deep neural networks. arXiv preprint arXiv:1602.07868 , 2016.
[55] Tim Salimans, Diederik P Kingma, and Max Welling. Markov chain monte carlo and variational inference: Bridging the gap. arXiv preprint arXiv:1410.6460 , 2014.
[56] Lawrence K Saul, Tommi Jaakkola, and Michael I Jordan. Mean field theory for sigmoid belief networks. Journal of artificial intelligence research , 4(1):61–76, 1996.
[57] Karen Simonyan and Andrew Zisserman. Very deep convolutional networks for large-scale image recognition. arXiv preprint arXiv:1409.1556 , 2014.
[58] Paul Smolensky. Information processing in dynamical systems: Foundations of harmony theory. Technical report, DTIC Document, 1986.
[59] Jascha Sohl-Dickstein, Eric A. Weiss, Niru Maheswaranathan, and Surya Ganguli. Deep unsupervised learning using nonequilibrium thermodynamics. In Proceedings of the 32nd International Conference on Machine Learning, ICML 2015, Lille, France, 6-11 July 2015 , pages 2256–2265, 2015.
[60] Sasha Targ, Diogo Almeida, and Kevin Lyman. Resnet in resnet: Generalizing residual architectures. CoRR , abs/1603.08029, 2016.
[61] Lucas Theis and Matthias Bethge. Generative image modeling using spatial lstms. In Advances in Neural Information Processing Systems , pages 1918–1926, 2015.
[62] Lucas Theis, Aäron Van Den Oord, and Matthias Bethge. A note on the evaluation of generative models. CoRR , abs/1511.01844, 2015.
[63] Dustin Tran, Rajesh Ranganath, and David M Blei. Variational gaussian process. arXiv preprint arXiv:1511.06499 , 2015.
[64] Benigno Uria, Iain Murray, and Hugo Larochelle. Rnade: The real-valued neural autoregressive density-estimator. In Advances in Neural Information Processing Systems , pages 2175–2183, 2013.
[65] Hado van Hasselt, Arthur Guez, Matteo Hessel, and David Silver. Learning functions across many orders of magnitudes. arXiv preprint arXiv:1602.07714 , 2016.
[66] Oriol Vinyals, Samy Bengio, and Manjunath Kudlur. Order matters: Sequence to sequence for sets. arXiv preprint arXiv:1511.06391 , 2015.
[67] Manuel Watter, Jost Springenberg, Joschka Boedecker, and Martin Riedmiller. Embed to control: A locally linear latent dynamics model for control from raw images. In Advances in Neural Information Processing Systems , pages 2728–2736, 2015.
[68] Ronald J Williams. Simple statistical gradient-following algorithms for connectionist reinforcement learning. Machine learning , 8(3-4):229–256, 1992.
[69] Fisher Yu and Vladlen Koltun. Multi-scale context aggregation by dilated convolutions. arXiv preprint arXiv:1511.07122 , 2015.
[70] Fisher Yu, Yinda Zhang, Shuran Song, Ari Seff, and Jianxiong Xiao. Construction of a large-scale image dataset using deep learning with humans in the loop. arXiv preprint arXiv:1506.03365 , 2015.
[71] Richard Zhang, Phillip Isola, and Alexei A Efros. Colorful image colorization. arXiv preprint arXiv:1603.08511 , 2016.
Appendix A Samples
附录 A 样本
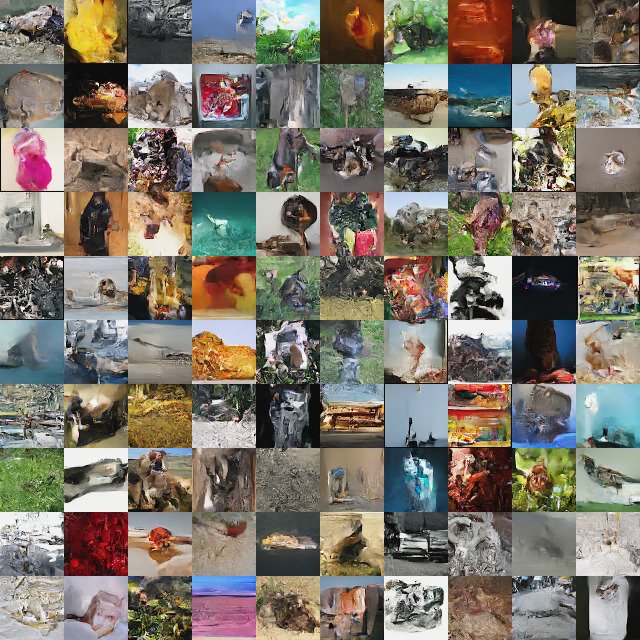
Figure 7: Samples from a model trained on Imagenet ().
图 7:在 Imagenet()上训练的模型所采样本。
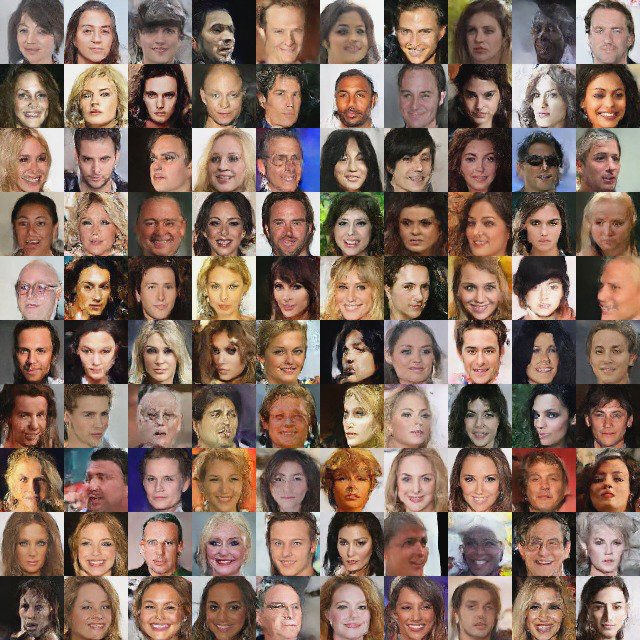
Figure 8: Samples from a model trained on CelebA.
图 8:在 CelebA 上训练的模型所采样本。
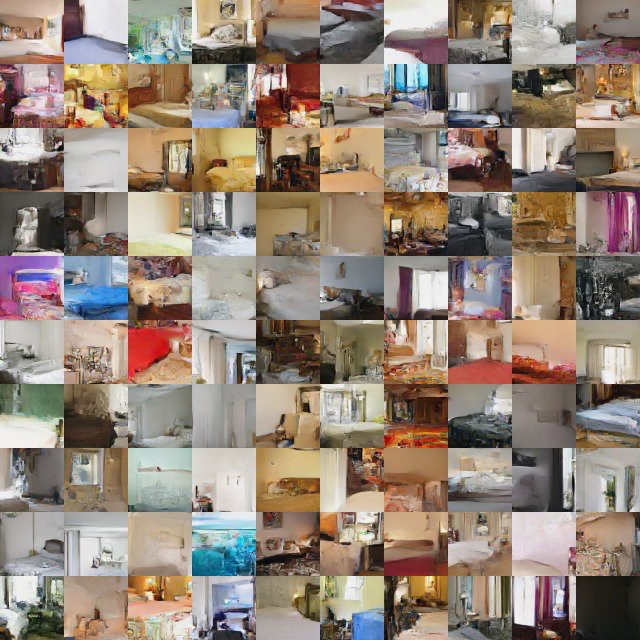
Figure 9: Samples from a model trained on LSUN (bedroom category).
图 9:在 LSUN(bedroom 类别)上训练的模型所采样本。
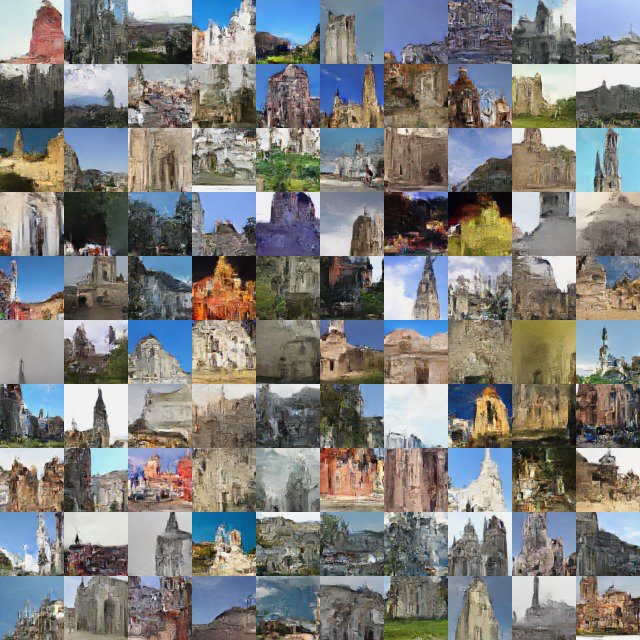
Figure 10: Samples from a model trained on LSUN (church outdoor category).
图 10:在 LSUN(church outdoor 类别)上训练的模型所采样本。
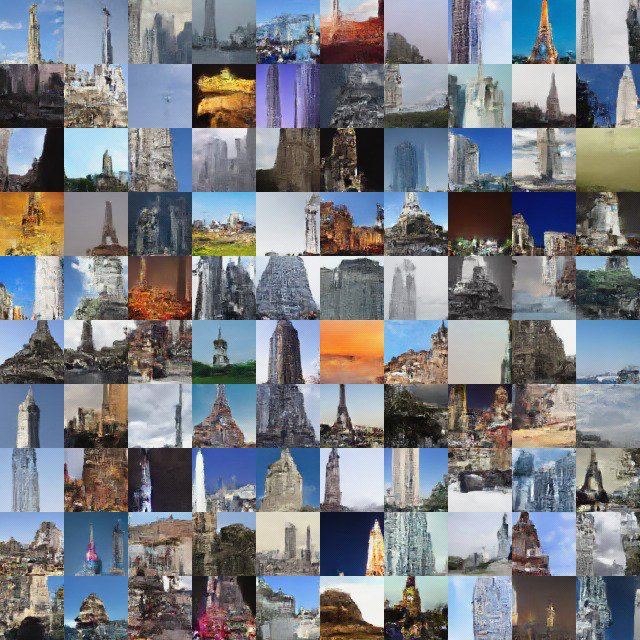
Figure 11: Samples from a model trained on LSUN (tower category).
图 11:在 LSUN(tower 类别)上训练的模型所采样本。
Appendix B Manifold
附录 B 流形
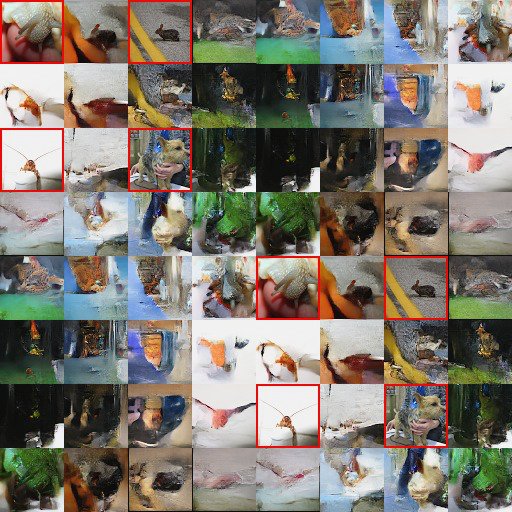
Figure 12: Manifold from a model trained on Imagenet (). Images with red borders are taken from the validation set, and define the manifold. The manifold was computed as described in Equation 20, where the x-axis corresponds to , and the y-axis to , and where .
图 12:在 Imagenet()上训练的模型所得流形。红框图像取自验证集,并定义该流形。流形按公式 20 计算,横轴对应 ,纵轴对应 ,且 。
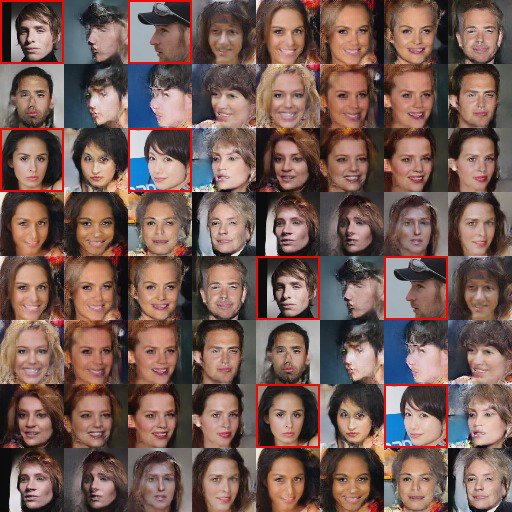
Figure 13: Manifold from a model trained on CelebA. Images with red borders are taken from the training set, and define the manifold. The manifold was computed as described in Equation 20, where the x-axis corresponds to , and the y-axis to , and where .
图 13:在 CelebA 上训练的模型所得流形。红框图像取自训练集,并定义该流形。流形按公式 20 计算,横轴对应 ,纵轴对应 ,且 。
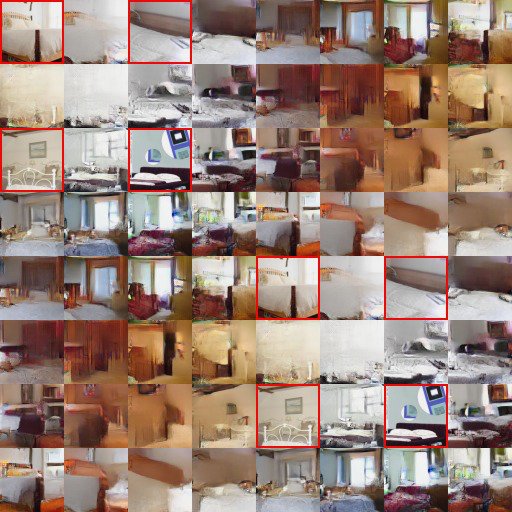
Figure 14: Manifold from a model trained on LSUN (bedroom category). Images with red borders are taken from the validation set, and define the manifold. The manifold was computed as described in Equation 20, where the x-axis corresponds to , and the y-axis to , and where .
图 14:在 LSUN(bedroom 类别)上训练的模型所得流形。红框图像取自验证集,并定义该流形。流形按公式 20 计算,横轴对应 ,纵轴对应 ,且 。
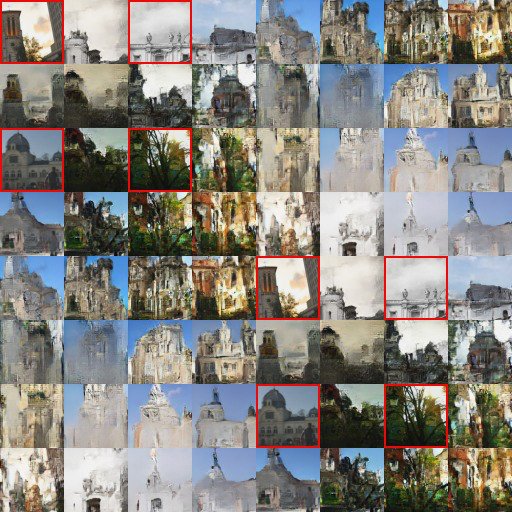
Figure 15: Manifold from a model trained on LSUN (church outdoor category). Images with red borders are taken from the validation set, and define the manifold. The manifold was computed as described in Equation 20, where the x-axis corresponds to , and the y-axis to , and where .
图 15:在 LSUN(church outdoor 类别)上训练的模型所得流形。红框图像取自验证集,并定义该流形。流形按公式 20 计算,横轴对应 ,纵轴对应 ,且 。
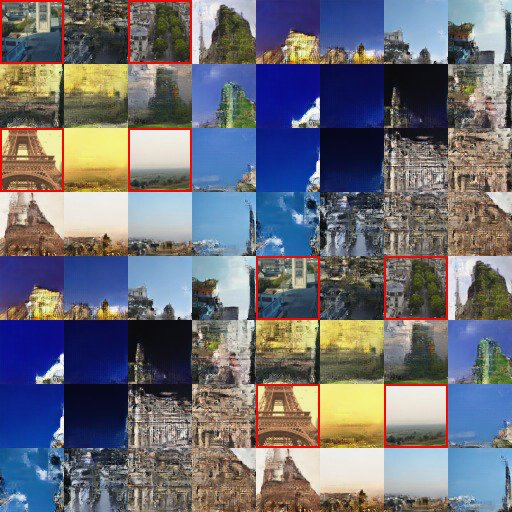
Figure 16: Manifold from a model trained on LSUN (tower category). Images with red borders are taken from the validation set, and define the manifold. The manifold was computed as described in Equation 20, where the x-axis corresponds to , and the y-axis to , and where .
图 16:在 LSUN(tower 类别)上训练的模型所得流形。红框图像取自验证集,并定义该流形。流形按公式 20 计算,横轴对应 ,纵轴对应 ,且 。
Appendix C Extrapolation
附录 C 外推
Inspired by the texture generation work by [19, 61] and extrapolation test with DCGAN [47], we also evaluate the statistics captured by our model by generating images twice or ten times as large as present in the dataset. As we can observe in the following figures, our model seems to successfully create a “texture” representation of the dataset while maintaining a spatial smoothness through the image. Our convolutional architecture is only aware of the position of considered pixel through edge effects in convolutions, therefore our model is similar to a stationary process. This also explains why these samples are more consistent in LSUN, where the training data was obtained using random crops.
受 [19, 61] 的纹理生成工作以及 DCGAN [47] 外推测试启发,我们还通过生成比数据集中图像大两倍或十倍的图像,来评估模型捕捉的统计量。如下图可见,模型似乎成功创建了数据集的“纹理”表征,同时在整幅图上保持空间平滑。我们的卷积架构仅通过卷积的边缘效应感知像素位置,因此模型类似平稳过程。这也解释了为何这些样本在 LSUN 上更一致——其训练数据由随机裁剪得到。
(a)
(a)
(a)
(a)
(a)
Appendix D Latent variables semantic
附录 D 潜变量语义
As in [22], we further try to grasp the semantic of our learned layers latent variables by doing ablation tests. We infer the latent variables and resample the lowest levels of latent variables from a standard gaussian, increasing the highest level affected by this resampling. As we can see in the following figures, the semantic of our latent space seems to be more on a graphic level rather than higher level concept. Although the heavy use of convolution improves learning by exploiting image prior knowledge, it is also likely to be responsible for this limitation.
与 [22] 类似,我们进一步通过对所学各层潜变量做消融,把握其语义。我们推断潜变量,并从标准高斯重采样最低层潜变量,逐步提高受该重采样影响的最高层。如下图可见,潜空间语义似乎更偏图形层面,而非更高层概念。大量使用卷积虽借图像先验改善学习,也可能造成这一局限。
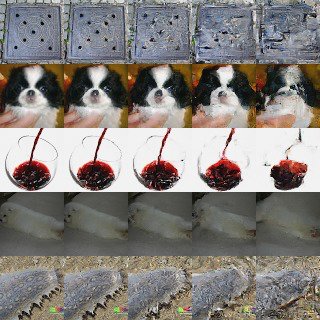
Figure 22: Conceptual compression from a model trained on Imagenet (). The leftmost column represent the original image, the subsequent columns were obtained by storing higher level latent variables and resampling the others, storing less and less as we go right. From left to right: , , , and of the latent variables are kept.
图 22:在 Imagenet()上训练的模型的概念压缩。最左列为原图,随后各列通过保留更高层潜变量并对其余重采样得到,越往右保留越少。自左至右:保留潜变量的 、、、 与 。
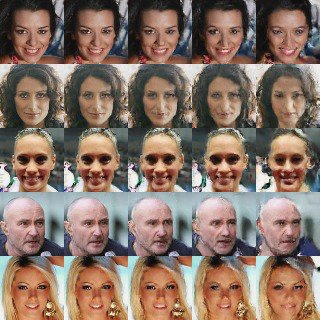
Figure 23: Conceptual compression from a model trained on CelebA. The leftmost column represent the original image, the subsequent columns were obtained by storing higher level latent variables and resampling the others, storing less and less as we go right. From left to right: , , , and of the latent variables are kept.
图 23:在 CelebA 上训练的模型的概念压缩。最左列为原图,随后各列通过保留更高层潜变量并对其余重采样得到,越往右保留越少。自左至右:保留潜变量的 、、、 与 。
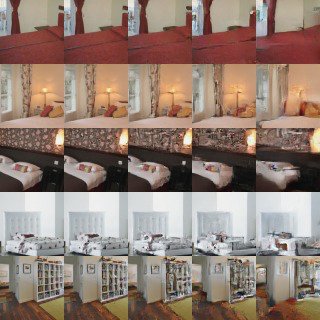
Figure 24: Conceptual compression from a model trained on LSUN (bedroom category). The leftmost column represent the original image, the subsequent columns were obtained by storing higher level latent variables and resampling the others, storing less and less as we go right. From left to right: , , , and of the latent variables are kept.
图 24:在 LSUN(bedroom 类别)上训练的模型的概念压缩。最左列为原图,随后各列通过保留更高层潜变量并对其余重采样得到,越往右保留越少。自左至右:保留潜变量的 、、、 与 。
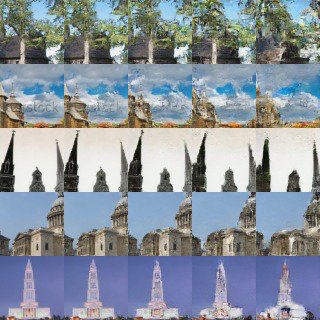
Figure 25: Conceptual compression from a model trained on LSUN (church outdoor category). The leftmost column represent the original image, the subsequent columns were obtained by storing higher level latent variables and resampling the others, storing less and less as we go right. From left to right: , , , and of the latent variables are kept.
图 25:在 LSUN(church outdoor 类别)上训练的模型的概念压缩。最左列为原图,随后各列通过保留更高层潜变量并对其余重采样得到,越往右保留越少。自左至右:保留潜变量的 、、、 与 。
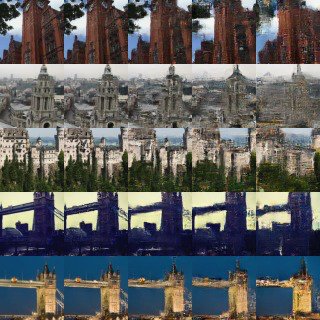
Figure 26: Conceptual compression from a model trained on LSUN (tower category). The leftmost column represent the original image, the subsequent columns were obtained by storing higher level latent variables and resampling the others, storing less and less as we go right. From left to right: , , , and of the latent variables are kept.
图 26:在 LSUN(tower 类别)上训练的模型的概念压缩。最左列为原图,随后各列通过保留更高层潜变量并对其余重采样得到,越往右保留越少。自左至右:保留潜变量的 、、、 与 。
Appendix E Batch normalization
附录 E 批归一化
We further experimented with batch normalization by using a weighted average of a moving average of the layer statistics and the current batch batch statistics ,
我们进一步实验批归一化:使用层统计滑动平均 与当前批量统计 的加权平均,
where is the momentum. When using , we only propagate gradient through the current batch statistics . We observe that using this lag helps the model train with very small minibatches.
其中 为动量。使用 时,梯度仅经当前批量统计 回传。我们观察到该滞后有助于模型在极小批量下训练。
We used batch normalization with a moving average for our results on CIFAR-10.
CIFAR-10 结果使用了带滑动平均的批归一化。
Appendix F Attribute change
附录 F 属性改变
Additionally, we exploit the attribute information in CelebA to build a conditional model, i.e. the invertible function from image to latent variable uses the labels in to define its parameters. In order to observe the information stored in the latent variables, we choose to encode a batch of images with their original attribute and decode them using a new set of attributes , build by shuffling the original attributes inside the batch. We obtain the new images .
此外,我们利用 CelebA 中的属性信息 构建条件模型,即从图像到潜变量的可逆函数 用标签 定义其参数。为观察潜变量中存储的信息,我们选择用原始属性 编码一批图像 ,再用批次内打乱得到的新属性集 解码。得到新图像 。
We observe that, although the faces are changed as to respect the new attributes, several properties remain unchanged like position and background.
我们观察到,尽管人脸会改变以符合新属性,位置与背景等若干性质仍保持不变。
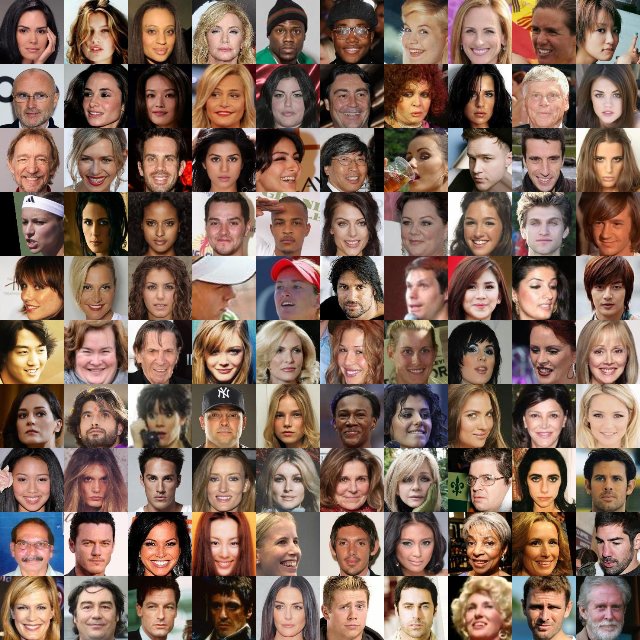
Figure 27: Examples from the CelebA dataset.
图 27:CelebA 数据集中的例子 。
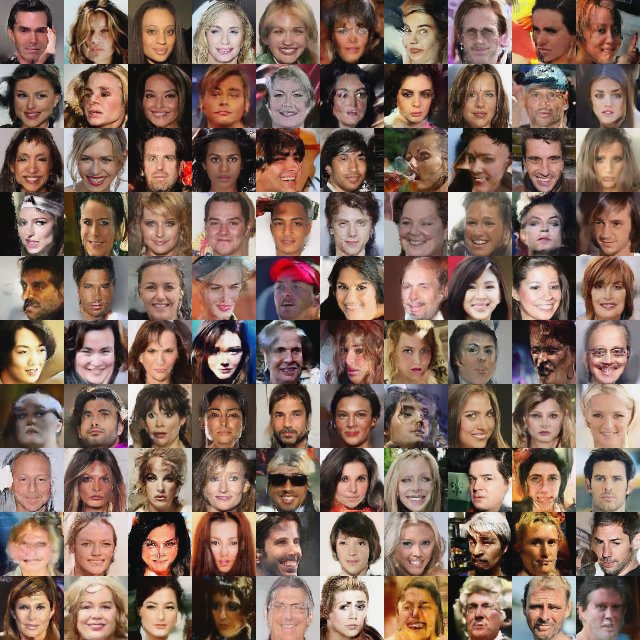
Figure 28: From a model trained on pairs of images and attributes from the CelebA dataset, we encode a batch of images with their original attributes before decoding them with a new set of attributes. We notice that the new images often share similar characteristics with those in Fig 27, including position and background.
图 28:对在 CelebA 图像—属性对上训练的模型,我们先用原始属性编码一批图像,再用新属性集解码。我们注意到新图像常与图 27 中图像共享位置与背景等相似特征。