RAFT: Recurrent All-Pairs Field Transforms for Optical Flow
RAFT: Recurrent All-Pairs Field Transforms for Optical Flow
RAFT:用于光流的循环全像素对场变换(Recurrent All-Pairs Field Transforms for Optical Flow)
Abstract
摘要
We introduce Recurrent All-Pairs Field Transforms (RAFT), a new deep network architecture for optical flow. RAFT extracts per-pixel features, builds multi-scale 4D correlation volumes for all pairs of pixels, and iteratively updates a flow field through a recurrent unit that performs lookups on the correlation volumes. RAFT achieves state-of-the-art performance. On KITTI, RAFT achieves an F1-all error of 5.10%, a 16% error reduction from the best published result (6.10%). On Sintel (final pass), RAFT obtains an end-point-error of 2.855 pixels, a 30% error reduction from the best published result (4.098 pixels). In addition, RAFT has strong cross-dataset generalization as well as high efficiency in inference time, training speed, and parameter count. Code is available at https://github.com/princeton-vl/RAFT.
我们提出循环全像素对场变换(Recurrent All-Pairs Field Transforms,RAFT),一种新的光流深度网络架构。RAFT 提取每像素特征,为所有像素对构建多尺度四维相关体积,再通过在相关体积上做查找的循环单元迭代更新流场。RAFT 达到了当时最优性能。在 KITTI 上,RAFT 的 F1-all 误差为 5.10%,相对此前最好的已发表结果(6.10%)降低了 16%。在 Sintel(final 通道)上,RAFT 的端点误差为 2.855 像素,相对此前最好结果(4.098 像素)降低了 30%。此外,RAFT 具有很强的跨数据集泛化能力,在推理时间、训练速度和参数量上也很高效率。代码见 https://github.com/princeton-vl/RAFT。
1 Introduction
1 引言
Optical flow is the task of estimating per-pixel motion between video frames. It is a long-standing vision problem that remains unsolved. The best systems are limited by difficulties including fast-moving objects, occlusions, motion blur, and textureless surfaces.
光流的任务是估计视频帧之间每个像素的运动。这是一个长期未解的视觉问题。现有最好系统仍受快速运动物体、遮挡、运动模糊和无纹理表面等因素制约。
Optical flow has traditionally been approached as a hand-crafted optimization problem over the space of dense displacement fields between a pair of images [21, 51, 13]. Generally, the optimization objective defines a trade-off between a data term which encourages the alignment of visually similar image regions and a regularization term which imposes priors on the plausibility of motion. Such an approach has achieved considerable success, but further progress has appeared challenging, due to the difficulties in hand-designing an optimization objective that is robust to a variety of corner cases.
传统上,光流被当作一对图像之间稠密位移场空间上的手工优化问题 [21, 51, 13]。优化目标一般在数据项与正则项之间折中:前者鼓励视觉相似区域对齐,后者对运动的合理性施加先验。这类方法取得了可观成功,但继续推进很难,因为要手工设计一个能应对各种边角情况的优化目标并不容易。
Recently, deep learning has been shown as a promising alternative to traditional methods. Deep learning can side-step formulating an optimization problem and train a network to directly predict flow. Current deep learning methods [25, 42, 22, 49, 20] have achieved performance comparable to the best traditional methods while being significantly faster at inference time. A key question for further research is designing effective architectures that perform better, train more easily and generalize well to novel scenes.
近来,深度学习被证明是传统方法的有希望替代。深度学习可以绕过显式优化问题,直接训练网络预测光流。当前的深度学习方法 [25, 42, 22, 49, 20] 已达到与最好传统方法相当的性能,同时推理快得多。进一步研究的关键问题是:设计性能更好、更易训练、对新场景泛化更好的有效架构。
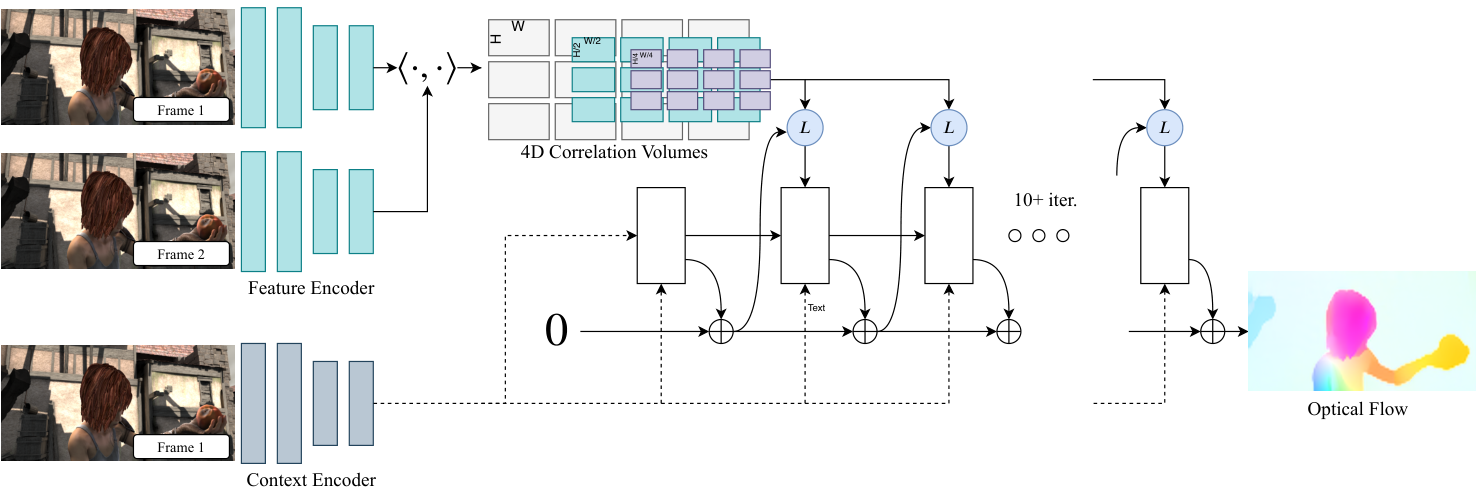
Figure 1: RAFT consists of 3 main components: (1) A feature encoder that extracts per-pixel features from both input images, along with a context encoder that extracts features from only . (2) A correlation layer which constructs a 4D correlation volume by taking the inner product of all pairs of feature vectors. The last 2-dimensions of the 4D volume are pooled at multiple scales to construct a set of multi-scale volumes. (3) An update operator which recurrently updates optical flow by using the current estimate to look up values from the set of correlation volumes.
图 1:RAFT 由三个主要部件组成:(1)特征编码器从两张输入图像提取每像素特征,另有一个上下文编码器只从 提取特征。(2)相关层对所有特征向量两两取内积,构造 的四维相关体积;再对四维体积的后两维做多尺度池化,得到一组多尺度体积。(3)更新算子利用当前估计在这组相关体积上查找,循环更新光流。
We introduce Recurrent All-Pairs Field Transforms (RAFT), a new deep network architecture for optical flow. RAFT enjoys the following strengths:
我们提出循环全像素对场变换(RAFT),一种新的光流深度网络架构。RAFT 具有以下优点:
- • State-of-the-art accuracy: On KITTI [18], RAFT achieves an F1-all error of 5.10%, a 16% error reduction from the best published result (6.10%). On Sintel [11] (final pass), RAFT obtains an end-point-error of 2.855 pixels, a 30% error reduction from the best published result (4.098 pixels).
- • Strong generalization: When trained only on synthetic data, RAFT achieves an end-point-error of 5.04 pixels on KITTI [18], a 40% error reduction from the best prior deep network trained on the same data (8.36 pixels).
- • High efficiency: RAFT processes videos at 10 frames per second on a 1080Ti GPU. It trains with 10X fewer iterations than other architectures. A smaller version of RAFT with 1/5 of the parameters runs at 20 frames per second while still outperforming all prior methods on Sintel.
- • 最优精度:在 KITTI [18] 上,RAFT 的 F1-all 误差为 5.10%,相对此前最好已发表结果(6.10%)降低 16%。在 Sintel [11](final 通道)上,RAFT 端点误差为 2.855 像素,相对此前最好结果(4.098 像素)降低 30%。
- • 强泛化:仅在合成数据上训练时,RAFT 在 KITTI [18] 上端点误差为 5.04 像素,相对在同样数据上训练的此前最好深度网络(8.36 像素)降低 40%。
- • 高效率:RAFT 在 1080Ti GPU 上处理 视频可达每秒 10 帧。训练迭代次数比其他架构少 10 倍。参数量约 1/5 的较小版本以每秒 20 帧运行,在 Sintel 上仍超过此前所有方法。
RAFT consists of three main components: (1) a feature encoder that extracts a feature vector for each pixel; (2) a correlation layer that produces a 4D correlation volume for all pairs of pixels, with subsequent pooling to produce lower resolution volumes; (3) a recurrent GRU-based update operator that retrieves values from the correlation volumes and iteratively updates a flow field initialized at zero. Fig. 1 illustrates the design of RAFT.
RAFT 由三个主要部件组成:(1)为每个像素提取特征向量的特征编码器;(2)为所有像素对生成四维相关体积、再经池化得到较低分辨率体积的相关层;(3)基于 GRU 的循环更新算子,从相关体积中取回数值,并从零初始化开始迭代更新流场。图 1 示意了 RAFT 的设计。
The RAFT architecture is motivated by traditional optimization-based approaches. The feature encoder extracts per-pixel features. The correlation layer computes visual similarity between pixels. The update operator mimics the steps of an iterative optimization algorithm. But unlike traditional approaches, features and motion priors are not handcrafted but learned—learned by the feature encoder and the update operator respectively.
RAFT 架构受到传统基于优化方法的启发。特征编码器提取每像素特征。相关层计算像素间视觉相似度。更新算子模仿迭代优化算法的步骤。但与传统方法不同,特征和运动先验都不是手工设计的——分别由特征编码器和更新算子学得。
The design of RAFT draws inspiration from many existing works but is substantially novel. First, RAFT maintains and updates a single fixed flow field at high resolution. This is different from the prevailing coarse-to-fine design in prior work [42, 49, 22, 23, 50], where flow is first estimated at low resolution and upsampled and refined at high resolution. By operating on a single high-resolution flow field, RAFT overcomes several limitations of a coarse-to-fine cascade: the difficulty of recovering from errors at coarse resolutions, the tendency to miss small fast-moving objects, and the many training iterations (often over 1M) typically required for training a multi-stage cascade.
RAFT 的设计从许多已有工作汲取灵感,但本质是新的。首先,RAFT 在高分辨率上维护并更新单一固定流场。这与此前工作中流行的由粗到细设计 [42, 49, 22, 23, 50] 不同:那些方法先在低分辨率估计光流,再上采样并在高分辨率细化。通过在单一高分辨率流场上操作,RAFT 克服了由粗到细级联的若干局限:难以从粗分辨率错误中恢复、容易漏掉小而快的物体,以及多阶段级联通常需要的大量训练迭代(常常超过 100 万次)。
Second, the update operator of RAFT is recurrent and lightweight. Many recent works [24, 42, 49, 22, 25] have included some form of iterative refinement, but do not tie the weights across iterations [42, 49, 22] and are therefore limited to a fixed number of iterations. To our knowledge, IRR [24] is the only deep learning approach [24] that is recurrent. It uses FlowNetS [15] or PWC-Net [42] as its recurrent unit. When using FlowNetS, it is limited by the size of the network (38M parameters) and is only applied up to 5 iterations. When using PWC-Net, iterations are limited by the number of pyramid levels. In contrast, our update operator has only 2.7M parameters and can be applied 100+ times during inference without divergence.
其次,RAFT 的更新算子是循环且轻量的。许多近期工作 [24, 42, 49, 22, 25] 包含某种迭代细化,但不在迭代间共享权重 [42, 49, 22],因此只能固定迭代次数。据我们所知,IRR [24] 是唯一循环的深度学习方法。它用 FlowNetS [15] 或 PWC-Net [42] 作为循环单元。用 FlowNetS 时受网络规模限制(3800 万参数),最多只能跑 5 次迭代;用 PWC-Net 时迭代次数受金字塔层数限制。相比之下,我们的更新算子只有 270 万参数,推理时可应用 100 次以上而不发散。
Third, the update operator has a novel design, which consists of a convolutional GRU that performs lookups on 4D multi-scale correlation volumes; in contrast, refinement modules in prior work typically use only plain convolution or correlation layers.
第三,更新算子的设计是新的:由在四维多尺度相关体积上做查找的卷积 GRU 组成;而此前工作的细化模块通常只用普通卷积或相关层。
We conduct experiments on Sintel[11] and KITTI[18]. Results show that RAFT achieves state-of-the-art performance on both datasets. In addition, we validate various design choices of RAFT through extensive ablation studies.
我们在 Sintel[11] 和 KITTI[18] 上做实验。结果表明 RAFT 在两个数据集上都达到最优。此外,我们通过大量消融验证了 RAFT 的各项设计选择。
2 Related Work
2 相关工作
Optical Flow as Energy Minimization Optical flow has traditionally been treated as an energy minimization problem which imposes a tradeoff between a data term and a regularization term. Horn and Schnuck [21] formulated optical flow as a continuous optimization problem using a variational framework, and were able to estimate a dense flow field by performing gradient steps. Black and Anandan[9] addressed problems with oversmoothing and noise sensitivity by introducing a robust estimation framework. TV-L1 [51] replaced the quadratic penalties with an L1 data term and total variation regularization, which allowed for motion discontinuities and was better equipped to handle outliers. Improvements have been made by defining better matching costs [45, 10] and regularization terms [38].
作为能量最小化的光流 光流传统上被当作在数据项与正则项之间折中的能量最小化问题。Horn 与 Schnuck [21] 用变分框架把光流表述为连续优化问题,通过梯度步估计稠密流场。Black 与 Anandan[9] 引入稳健估计框架,缓解过度平滑与噪声敏感。TV-L1 [51] 用 L1 数据项和全变分正则替换二次惩罚,允许运动不连续,也更适合处理离群点。后续工作通过更好的匹配代价 [45, 10] 和正则项 [38] 继续改进。
Such continuous formulations maintain a single estimate of optical flow which is refined at each iteration. To ensure a smooth objective function, a first order Taylor approximation is used to model the data term. As a result, they only work well for small displacements. To handle large displacements, the coarse-to-fine strategy is used, where an image pyramid is used to estimate large displacements at low resolution, then small displacements refined at high resolution. But this coarse-to-fine strategy may miss small fast-moving objects and have difficulty recovering from early mistakes. Like continuous methods, we maintain a single estimate of optical flow which is refined with each iteration. However, since we build correlation volumes for all pairs at both high resolution and low resolution, each local update uses information about both small and large displacements. In addition, instead of using a subpixel Taylor approximation of the data term, our update operator learns to propose the descent direction.
这类连续表述始终维护一份光流估计,每步迭代细化。为保证目标光滑,数据项用一阶泰勒近似建模,因此只对小位移效果好。为处理大位移,人们采用由粗到细策略:用图像金字塔在低分辨率估计大位移,再在高分辨率细化小位移。但这种策略可能漏掉小而快的物体,也难从早期错误中恢复。与连续方法一样,我们也维护并逐步细化单一光流估计。但由于我们在高、低分辨率上都为所有像素对建相关体积,每次局部更新同时利用小位移和大位移信息。此外,我们不用数据项的亚像素泰勒近似,而是让更新算子学习提出下降方向。
More recently, optical flow has also been approached as a discrete optimization problem [35, 13, 47] using a global objective. One challenge of this approach is the massive size of the search space, as each pixel can be reasonably paired with thousands of points in the other frame. Menez et al[35] pruned the search space using feature descriptors and approximated the global MAP estimate using message passing. Chen et al. [13] showed that by using the distance transform, solving the global optimization problem over the full space of flow fields is tractable. DCFlow [47] showed further improvements by using a neural network as a feature descriptor, and constructed a 4D cost volume over all pairs of features. The 4D cost volume was then processed using the Semi-Global Matching (SGM) algorithm [19]. Like DCFlow, we also constructed 4D cost volumes over learned features. However, instead of processing the cost volumes using SGM, we use a neural network to estimate flow. Our approach is end-to-end differentiable, meaning the feature encoder can be trained with the rest of the network to directly minimize the error of the final flow estimate. In contrast, DCFlow requires their network to be trained using an embedding loss between pixels; it cannot be trained directly on optical flow because their cost volume processing is not differentiable.
近来,光流也被表述为带全局目标的离散优化问题 [35, 13, 47]。挑战之一是搜索空间巨大:每个像素都可能合理对应另一帧中的数千个点。Menez 等[35] 用特征描述子剪枝搜索空间,并用消息传递近似全局 MAP。Chen 等 [13] 表明,借助距离变换,在整个流场空间上做全局优化是可行的。DCFlow [47] 进一步用神经网络作特征描述子,在所有特征对上构造四维代价体积,再用半全局匹配(SGM)算法 [19] 处理。与 DCFlow 一样,我们也在学习特征上构造四维代价体积。但我们不用 SGM,而是用神经网络估计光流。我们的方法端到端可微,特征编码器可以与网络其余部分一起训练,直接最小化最终流场误差。相比之下,DCFlow 需要用像素嵌入损失训练网络;因其代价体积处理不可微,无法直接在光流上训练。
Direct Flow Prediction Neural networks have been trained to directly predict optical flow between a pair of frames, side-stepping the optimization problem completely. Coarse-to-fine processing has emerged as a popular ingredient in many recent works [42, 50, 22, 23, 24, 49, 20, 8, 52]. In contrast, our method maintains and updates a single high-resolution flow field.
直接光流预测 神经网络被训练直接预测两帧之间的光流,完全绕过优化问题。由粗到细处理已成为许多近期工作的常见成分 [42, 50, 22, 23, 24, 49, 20, 8, 52]。相比之下,我们的方法维护并更新单一高分辨率流场。
Iterative Refinement for Optical Flow Many recent works have used iterative refinement to improve results on optical flow [25, 39, 42, 22, 49] and related tasks [29, 53, 44, 28]. Ilg et al. [25] applied iterative refinement to optical flow by stacking multiple FlowNetS and FlowNetC modules in series. SpyNet[39], PWC-Net[42], LiteFlowNet[22], and VCN [49] apply iterative refinement using coarse-to-fine pyramids. The main difference of these approaches from ours is that they do not share weights between iterations.
光流的迭代细化 许多近期工作用迭代细化改进光流 [25, 39, 42, 22, 49] 及相关任务 [29, 53, 44, 28]。Ilg 等 [25] 把多个 FlowNetS 与 FlowNetC 模块串起来做迭代细化。SpyNet[39]、PWC-Net[42]、LiteFlowNet[22] 和 VCN [49] 借助由粗到细金字塔做迭代细化。这些方法与我们的主要区别是:它们不在迭代间共享权重。
More closely related to our approach is IRR[24], which builds off of the FlownetS and PWC-Net architecture but shares weights between refinement networks. When using FlowNetS, it is limited by the size of the network (38M parameters) and is only applied up to 5 iterations. When using PWC-Net, iterations are limited by the number of pyramid levels. In contrast, we use a much simpler refinement module (2.7M parameters) which can be applied for 100+ iterations during inference without divergence. Our method also shares similarites with Devon [31], namely the construction of the cost volume without warping and fixed resolution updates. However, Devon does not have any recurrent unit. It also differs from ours regarding large displacements. Devon handles large displacements using a dilated cost volume while our approach pools the correlation volume at multiple resolutions.
与我们更接近的是 IRR[24],它基于 FlowNetS 与 PWC-Net 架构,但在细化网络间共享权重。用 FlowNetS 时受规模限制(3800 万参数),最多 5 次迭代;用 PWC-Net 时迭代受金字塔层数限制。我们用简单得多的细化模块(270 万参数),推理时可跑 100 次以上迭代而不发散。我们的方法也与 Devon [31] 有相似之处,即不经扭曲地构造代价体积,并在固定分辨率上更新。但 Devon 没有循环单元。处理大位移的方式也不同:Devon 用膨胀代价体积,我们则在多个分辨率上池化相关体积。
Our method also has ties to TrellisNet [5] and Deep Equilibrium Models (DEQ) [6]. Trellis net uses depth tied weights over a large number of layers, DEQ simulates an infinite number of layers by solving for the fixed point directly. TrellisNet and DEQ were designed for sequence modeling tasks, but we adopt the core idea of using a large number of weight-tied units. Our update operator uses a modified GRU block[14], which is similar to the LSTM block used in TrellisNet. We found that this structure allows our update operator to more easily converge to a fixed flow field.
我们的方法还与 TrellisNet [5] 和深度均衡模型(DEQ)[6] 有联系。TrellisNet 在大量层上使用深度共享权重,DEQ 通过直接求解不动点来模拟无限层。二者面向序列建模,但我们采纳了“使用大量权重共享单元”这一核心想法。我们的更新算子使用修改过的 GRU 块[14],与 TrellisNet 中的 LSTM 块类似。我们发现这种结构更有利于更新算子收敛到固定流场。
Learning to Optimize Many problems in vision can be formulated as an optimization problem. This has motivated several works to embed optimization problems into network architectures [4, 3, 43, 32, 44]. These works typically use a network to predict the inputs or parameters of the optimization problem, and then train the network weights by backpropogating the gradient through the solver, either implicitly[4, 3] or unrolling each step [32, 43]. However, this technique is limited to problems with an objective that can be easily defined.
学习去优化 视觉中许多问题可表述为优化问题。这促使若干工作把优化问题嵌入网络架构 [4, 3, 43, 32, 44]。这些工作通常用网络预测优化问题的输入或参数,再通过求解器反传梯度来训练网络权重,可以是隐式反传[4, 3] 或展开每一步 [32, 43]。但该技术受限于目标函数易于定义的问题。
Another approach is to learn iterative updates directly from data [1, 2]. These approaches are motivated by the fact that first order optimizers such as Primal Dual Hybrid Gradient (PDHG)[12] can be expressed as a sequence of iterative update steps. Instead of using an optimizer directly, Adler et al. [1] proposed building a network which mimics the updates of a first order algorithm. This approach has been applied to inverse problems such as image denoising [26], tomographic reconstruction [2], and novel view synthesis[17]. TVNet [16] implemented the TV-L1 algorithm as a computation graph, which enabled the training the TV-L1 parameters. However, TVNet operates directly based on intensity gradients instead of learned features, which limits the achievable accuracy on challenging datasets such as Sintel.
另一条路是直接从数据学习迭代更新 [1, 2]。其动机是:一阶优化器如原对偶混合梯度(PDHG)[12] 可写成一串迭代更新。Adler 等 [1] 不直接用优化器,而提出构建模仿一阶算法更新的网络。该方法已用于图像去噪 [26]、层析重建 [2] 和新视角合成[17] 等逆问题。TVNet [16] 把 TV-L1 算法实现为计算图,从而能训练 TV-L1 参数。但 TVNet 直接基于强度梯度而非学习特征操作,在 Sintel 这类有挑战的数据集上精度受限。
Our approach can be viewed as learning to optimize: our network uses a large number of update blocks to emulate the steps of a first-order optimization algorithm. However, unlike prior work, we never explicitly define a gradient with respect to some optimization objective. Instead, our network retrieves features from correlation volumes to propose the descent direction.
我们的方法可以看作学习去优化:网络用大量更新块来模拟一阶优化算法的步骤。但与此前工作不同,我们从不显式定义相对某个优化目标的梯度,而是从相关体积中取回特征来提出下降方向。
3 Approach
3 方法
Given a pair of consecutive RGB images, , , we estimate a dense displacement field which maps each pixel in to its corresponding coordinates in . An overview of our approach is given in Figure 1. Our method can be distilled down to three stages: (1) feature extraction, (2) computing visual similarity, and (3) iterative updates, where all stages are differentiable and composed into an end-to-end trainable architecture.
给定一对连续 RGB 图像 、,我们估计稠密位移场 ,把 中每个像素 映射到 中对应坐标 。方法概览见图 1。可概括为三阶段:(1)特征提取,(2)计算视觉相似度,(3)迭代更新;各阶段均可微,并组成端到端可训练架构。
3.1 Feature Extraction
3.1 特征提取
Features are extracted from the input images using a convolutional network. The feature encoder network is applied to both and and maps the input images to dense feature maps at a lower resolution. Our encoder, outputs features at 1/8 resolution where we set . The feature encoder consists of 6 residual blocks, 2 at 1/2 resolution, 2 at 1/4 resolution, and 2 at 1/8 resolution (more details in the supplemental material).
用卷积网络从输入图像提取特征。特征编码器同时作用于 和 ,把输入映射为较低分辨率的稠密特征图。我们的编码器 输出 1/8 分辨率特征 ,其中取 。特征编码器含 6 个残差块:1/2、1/4、1/8 分辨率各 2 个(更多细节见补充材料)。
We additionally use a context network. The context network extracts features only from the first input image . The architecture of the context network, is identical to the feature extraction network. Together, the feature network and the context network form the first stage of our approach, which only need to be performed once.
我们另外使用上下文网络。上下文网络只从第一张输入图像 提取特征。上下文网络 的架构与特征提取网络相同。特征网络 与上下文网络 一起构成方法的第一阶段,只需执行一次。
3.2 Computing Visual Similarity
3.2 计算视觉相似度
We compute visual similarity by constructing a full correlation volume between all pairs. Given image features and , the correlation volume is formed by taking the dot product between all pairs of feature vectors. The correlation volume, , can be efficiently computed as a single matrix multiplication.
我们通过为所有像素对构造完整相关体积来计算视觉相似度。给定图像特征 与 ,对所有特征向量两两取点积形成相关体积。相关体积 可高效地用一次矩阵乘法算得。
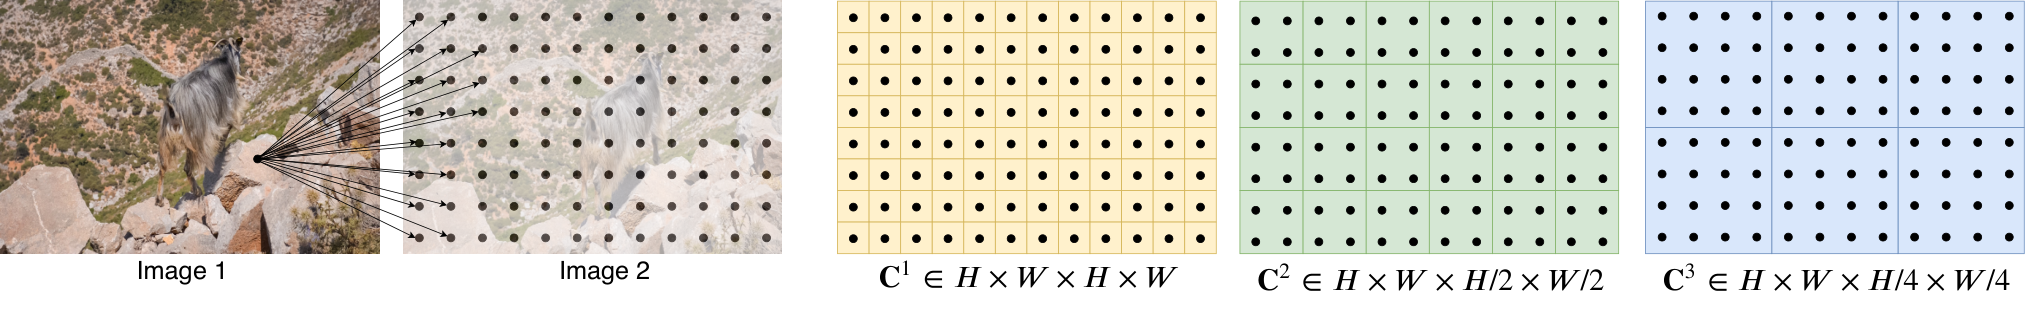
Figure 2: Building correlation volumes. Here we depict 2D slices of a full 4D volume. For a feature vector in , we take take the inner product with all pairs in , generating a 4D volume (each pixel in produces a 2D response map). The volume is pooled using average pooling with kernel sizes .
图 2:构建相关体积。这里画出完整四维体积的二维切片。对 中某个特征向量,与 中所有位置取内积,生成 的四维体积( 中每个像素对应一张二维响应图)。体积用核大小 做平均池化。
Correlation Pyramid: We construct a 4-layer pyramid by pooling the last two dimensions of the correlation volume with kernel sizes 1, 2, 4, and 8 and equivalent stride (Figure 2). Thus, volume has dimensions . The set of volumes gives information about both large and small displacements; however, by maintaining the first 2 dimensions (the dimensions) we maintain high resolution information, allowing our method to recover the motions of small fast-moving objects.
相关金字塔: 对相关体积的后两维分别用核大小 1、2、4、8 及相同步长做池化,构造四层金字塔 (图 2)。于是体积 的尺寸为 。这组体积同时提供大位移与小位移信息;同时保持前两维( 维)不变,从而保留高分辨率信息,使我们的方法能恢复小而快物体的运动。
Correlation Lookup: We define a lookup operator which generates a feature map by indexing from the correlation pyramid. Given a current estimate of optical flow , we map each pixel in to its estimated correspondence in : . We then define a local grid around
相关查找: 我们定义查找算子 ,通过从相关金字塔索引生成特征图。给定当前光流估计 ,把 中每个像素 映射到 中的估计对应点:。再在 周围定义局部网格
as the set of integer offsets which are within a radius of units of using the L1 distance. We use the local neighborhood to index from the correlation volume. Since is a grid of real numbers, we use bilinear sampling.
即与 的 L1 距离不超过半径 的整数偏移集合。我们用局部邻域 从相关体积中索引。由于 是实数网格,采用双线性采样。
We perform lookups on all levels of the pyramid, such that the correlation volume at level , , is indexed using the grid . A constant radius across levels means larger context at lower levels: for the lowest level, using a radius of 4 corresponds to a range of 256 pixels at the original resolution. The values from each level are then concatenated into a single feature map.
我们在金字塔所有层级上查找,使得第 层相关体积 用网格 索引。各层使用恒定半径意味着较低层有更大上下文:最低层 、半径 4 对应原分辨率约 256 像素范围。各层取值再拼接成单一特征图。
Efficient Computation for High Resolution Images: The all pairs correlation scales where is the number of pixels, but only needs to be computed once and is constant in the number of iterations . However, there exists an equivalent implementation of our approach which scales exploiting the linearity of the inner product and average pooling. Consider the cost volume at level , , and feature maps , :
高分辨率图像的高效计算: 全像素对相关的复杂度为 ( 为像素数),但只需计算一次,与迭代次数 无关。利用内积与平均池化的线性性,存在复杂度为 的等价实现。考虑第 层代价体积 以及特征图 、:
which is the average over the correlation response in the grid. This means that the value at can be computed as the inner product between the feature vector and pooled with kernel size .
即在 网格上相关响应的平均。这意味着 可写成特征向量 与经 核池化后的 的内积。
In this alternative implementation, we do not precompute the correlations, but instead precompute the pooled image feature maps. In each iteration, we compute each correlation value on demand—only when it is looked up. This gives a complexity of .
在该替代实现中,我们不预计算相关,而是预计算池化后的图像特征图。每次迭代只在被查找时按需计算相关值。复杂度为 。
We found empirically that precomputing all pairs is easy to implement and not a bottleneck, due to highly optimized matrix routines on GPUs—even for 1088x1920 videos it takes only 17% of total inference time. Note that we can always switch to the alternative implementation should it become a bottleneck.
经验上,预计算全像素对易于实现,且不是瓶颈——得益于 GPU 上高度优化的矩阵例程,即使对 1088×1920 视频也只占总推理时间的 17%。若成为瓶颈,随时可切换到替代实现。
3.3 Iterative Updates
3.3 迭代更新
Our update operator estimates a sequence of flow estimates from an initial starting point . With each iteration, it produces an update direction which is applied to the current estimate: .
我们的更新算子从初始点 估计一串流场 。每次迭代产生更新方向 ,并应用到当前估计:。
The update operator takes flow, correlation, and a latent hidden state as input, and outputs the update and an updated hidden state. The architecture of our update operator is designed to mimic the steps of an optimization algorithm. As such, we used tied weights across depth and use bounded activations to encourage convergence to a fixed point. The update operator is trained to perform updates such that the sequence converges to a fixed point .
更新算子以光流、相关和潜在隐状态为输入,输出更新 与更新后的隐状态。其架构设计用于模仿优化算法的步骤。因此我们在深度上共享权重,并用有界激活鼓励收敛到不动点。更新算子被训练为执行使序列收敛到不动点 的更新。
Initialization: By default, we initialize the flow field to 0 everywhere, but our iterative approach gives us the flexibility to experiment with alternatives. When applied to video, we test warm-start initialization, where optical flow from the previous pair of frames is forward projected to the next pair of frames with occlusion gaps filled in using nearest neighbor interpolation.
初始化: 默认把流场处处初始化为 0,但迭代方法让我们可以尝试替代方案。用于视频时,我们测试热启动初始化:把上一对帧的光流前向投影到下一对帧,遮挡空洞用最近邻插值填补。
Inputs: Given the current flow estimate , we use it to retrieve correlation features from the correlation pyramid as described in Sec. 3.2. The correlation features are then processed by 2 convolutional layers. Additionally, we apply 2 convolutional layers to the flow estimate itself to generate flow features. Finally, we directly inject the input from the context network. The input feature map is then taken as the concatenation of the correlation, flow, and context features.
输入: 给定当前流场估计 ,按第 3.2 节所述从相关金字塔取回相关特征,再经 2 层卷积处理。另外对流场估计本身施加 2 层卷积生成流场特征。最后直接注入上下文网络的输入。输入特征图取为相关、流场与上下文特征的拼接。
Update: A core component of the update operator is a gated activation unit based on the GRU cell, with fully connected layers replaced with convolutions:
更新: 更新算子的核心是基于 GRU 单元的门控激活,其中全连接层替换为卷积:
where is the concatenation of flow, correlation, and context features previously defined. We also experiment with a separable ConvGRU unit, where we replace the convolution with two GRUs: one with a convolution and one with a convolution to increase the receptive field without significantly increasing the size of the model.
其中 是前文定义的流场、相关与上下文特征的拼接。我们还实验了可分离 ConvGRU:用两个 GRU 替换 卷积,一个用 卷积,一个用 卷积,以在不明显增大模型的前提下扩大感受野。
Flow Prediction: The hidden state outputted by the GRU is passed through two convolutional layers to predict the flow update . The output flow is at 1/8 resolution of the input image. During training and evaluation, we upsample the predicted flow fields to match the resolution of the ground truth.
光流预测: GRU 输出的隐状态经两层卷积预测流场更新 。输出光流为输入图像 1/8 分辨率。训练与评估时,我们把预测流场上采样到与真值相同的分辨率。
Upsampling: The network outputs optical flow at 1/8 resolution. We upsample the optical flow to full resolution by taking the full resolution flow at each pixel to be the convex combination of a 3x3 grid of its coarse resolution neighbors. We use two convolutional layers to predict a mask and perform softmax over the weights of the 9 neighbors. The final high resolution flow field is found by using the mask to take a weighted combination over the neighborhood, then permuting and reshaping to a dimensional flow field. This layer can be directly implemented in PyTorch using the unfold function.
上采样: 网络输出 1/8 分辨率光流。上采样到全分辨率时,每个像素的全分辨率流取为其粗分辨率邻居 网格的凸组合。我们用两层卷积预测 掩码,并对 9 个邻居的权重做 softmax。最终高分辨率流场用该掩码对邻域做加权组合,再重排与变形为 维流场。该层可在 PyTorch 中用 unfold 函数直接实现。
3.4 Supervision
3.4 监督
We supervised our network on the distance between the predicted and ground truth flow over the full sequence of predictions, , with exponentially increasing weights. Given ground truth flow , the loss is defined as
我们在整条预测序列 上,对预测与真值光流的 距离做监督,权重指数递增。给定真值光流 ,损失定义为
where we set in our experiments.
实验中取 。
4 Experiments
4 实验
We evaluate RAFT on Sintel[11] and KITTI[18]. Following previous works, we pretrain our network on FlyingChairs[15] and FlyingThings[33], followed by dataset specific finetuning. Our method achieves state-of-the-art performance on both Sintel (both clean and final passes) and KITTI. Additionally, we test our method on 1080p video from the DAVIS dataset[37] to demonstrate that our method scales to videos of very high resolutions.
我们在 Sintel[11] 和 KITTI[18] 上评估 RAFT。沿用以往工作,先在 FlyingChairs[15] 与 FlyingThings[33] 上预训练,再做数据集特定微调。我们的方法在 Sintel(clean 与 final 通道)和 KITTI 上都达到最优。另外,我们在 DAVIS 数据集[37] 的 1080p 视频上测试,以表明方法可扩展到很高分辨率的视频。
Implementation Details: RAFT is implemented in PyTorch[36]. All modules are initialized from scratch with random weights. During training, we use the AdamW[30] optimizer and clip gradients to the range . Unless otherwise noted, we evaluate after 32 flow updates on Sintel and 24 on KITTI. For every update, , we only backpropgate the gradient through the branch, and zero the gradient through the branch as suggested by [20].
实现细节: RAFT 用 PyTorch[36] 实现。所有模块从零用随机权重初始化。训练使用 AdamW[30] 优化器,并将梯度裁剪到 。除非另有说明,Sintel 上评估时做 32 次流更新,KITTI 上做 24 次。每次更新 时,我们只通过 分支反传梯度,并按 [20] 的建议把经 分支的梯度置零。
Training Schedule: We train RAFT using two 2080Ti GPUs. We pretrain on FlyingThings for 100k iterations with a batch size of 12, then train for 100k iterations on FlyingThings3D with a batch size of 6. We finetune on Sintel for another 100k by combining data from Sintel[11], KITTI-2015 [34], and HD1K[27] similar to MaskFlowNet [52] and PWC-Net+ [41]. Finally, we finetune on KITTI-2015 for an additionally 50k iterations using the weights from the model finetuned on Sintel. Details on training and data augmentation are provided in the supplemental material. For comparison with prior work, we also include results from our model when finetuning only on Sintel and only on KITTI.
训练日程: 我们用两块 2080Ti GPU 训练 RAFT。先在 FlyingThings 上以 batch size 12 训练 10 万次迭代,再在 FlyingThings3D 上以 batch size 6 训练 10 万次。随后在 Sintel 上再微调 10 万次,数据混合方式类似 MaskFlowNet [52] 与 PWC-Net+ [41],来自 Sintel[11]、KITTI-2015 [34] 与 HD1K[27]。最后用 Sintel 微调后的权重,在 KITTI-2015 上再微调 5 万次。训练与数据增强细节见补充材料。为与先前工作对比,我们也报告仅在 Sintel 上微调、以及仅在 KITTI 上微调的结果。
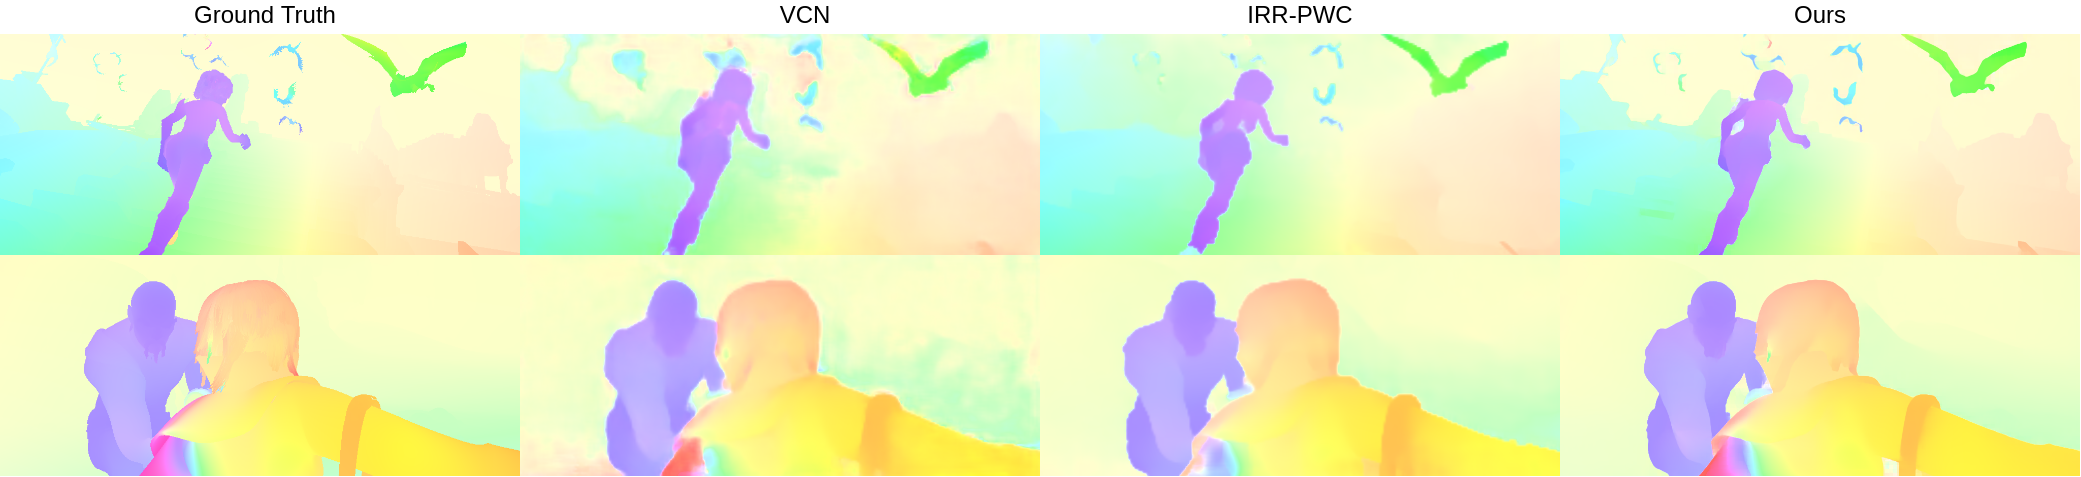
Figure 3: Flow predictions on the Sintel test set.
图 3:Sintel 测试集上的光流预测。
4.1 Sintel
We train our model using the FlyingChairsFlyingThings schedule and then evaluate on the Sintel dataset using the train split for validation. Results are shown in Table 1 and Figure 3, and we split results based on the data used for training. C + T means that the models are trained on FlyingChairs(C) and FlyingThings(T), while +ft indicates the model is finetuned on Sintel data. Like PWC-Net+[41] and MaskFlowNet [52] we include data from KITTI and HD1K when finetuning. We train 3 times with different seeds, and report results using the model with the median accuracy on the clean pass of Sintel (train).
我们按 FlyingChairsFlyingThings 日程训练模型,再在 Sintel 数据集上用训练集划分做验证。结果见表 1 与图 3,并按训练数据拆分报告。C + T 表示在 FlyingChairs(C) 与 FlyingThings(T) 上训练,+ft 表示在 Sintel 数据上微调。与 PWC-Net+[41] 和 MaskFlowNet [52] 一样,微调时纳入 KITTI 与 HD1K 数据。我们用不同随机种子训练 3 次,并报告在 Sintel(train)clean 通道上取中位精度的那个模型。
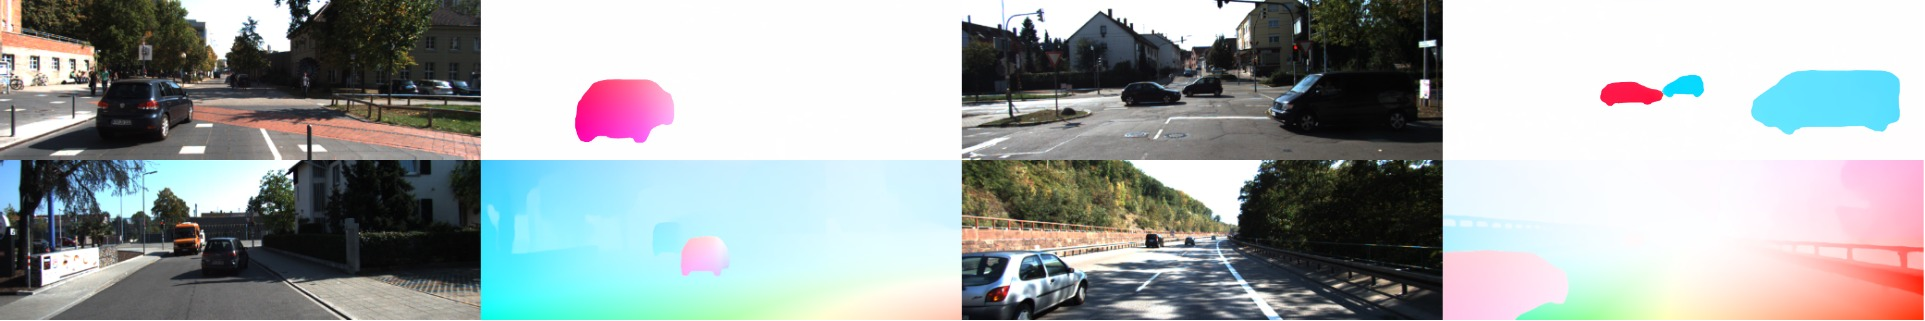
Figure 4: Flow predictions on the KITTI test set.
图 4:KITTI 测试集上的光流预测。
| Training Data | Method | Sintel (train) | KITTI-15 (train) | Sintel (test) | KITTI-15 (test) | |||
|---|---|---|---|---|---|---|---|---|
| Clean | Final | F1-epe | F1-all | Clean | Final | F1-all | ||
| - | FlowFields[7] | - | - | - | - | 3.75 | 5.81 | 15.31 |
| - | FlowFields++[40] | - | - | - | - | 2.94 | 5.49 | 14.82 |
| S | DCFlow[47] | - | - | - | - | 3.54 | 5.12 | 14.86 |
| S | MRFlow[46] | - | - | - | - | 2.53 | 5.38 | 12.19 |
| C + T | HD3[50] | 3.84 | 8.77 | 13.17 | 24.0 | - | - | - |
| LiteFlowNet[22] | 2.48 | 4.04 | 10.39 | 28.5 | - | - | - | |
| PWC-Net[42] | 2.55 | 3.93 | 10.35 | 33.7 | - | - | - | |
| LiteFlowNet2[23] | 2.24 | 3.78 | 8.97 | 25.9 | - | - | - | |
| VCN[49] | 2.21 | 3.68 | 8.36 | 25.1 | - | - | - | |
| MaskFlowNet[52] | 2.25 | 3.61 | - | 23.1 | - | - | - | |
| FlowNet2[25] | 2.02 | 3.541 | 10.08 | 30.0 | 3.96 | 6.02 | - | |
| Ours (small) | 2.21 | 3.35 | 7.51 | 26.9 | - | - | - | |
| Ours (2-view) | 1.43 | 2.71 | 5.04 | 17.4 | - | - | - | |
| C+T+S/K | FlowNet2 [25] | (1.45) | (2.01) | (2.30) | (6.8) | 4.16 | 5.74 | 11.48 |
| HD3 [50] | (1.87) | (1.17) | (1.31) | (4.1) | 4.79 | 4.67 | 6.55 | |
| IRR-PWC [24] | (1.92) | (2.51) | (1.63) | (5.3) | 3.84 | 4.58 | 7.65 | |
| ScopeFlow[8] | - | - | - | - | 3.59 | 4.10 | 6.82 | |
| Ours (2-view) | (0.77) | (1.20) | (0.64) | (1.5) | 2.08 | 3.41 | 5.27 | |
| C+T+S+K+H | LiteFlowNet22 [23] | (1.30) | (1.62) | (1.47) | (4.8) | 3.48 | 4.69 | 7.74 |
| PWC-Net+[41] | (1.71) | (2.34) | (1.50) | (5.3) | 3.45 | 4.60 | 7.72 | |
| VCN [49] | (1.66) | (2.24) | (1.16) | (4.1) | 2.81 | 4.40 | 6.30 | |
| MaskFlowNet[52] | - | - | - | - | 2.52 | 4.17 | 6.10 | |
| Ours (2-view) | (0.76) | (1.22) | (0.63) | (1.5) | 1.94 | 3.18 | 5.10 | |
| Ours (warm-start) | (0.77) | (1.27) | - | - | 1.61 | 2.86 | - |
Table 1: Results on Sintel and KITTI datasets. We test the generalization performance on Sintel(train) after training on FlyingChairs(C) and FlyingThing(T), and outperform all existing methods on both the clean and final pass. The bottom two sections show the performance of our model on public leaderboards after dataset specific finetuning. S/K includes methods which use only Sintel data for finetuning on Sintel and only KITTI data when finetuning on KITTI. +S+K+H includes methods which combine KITTI, HD1K, and Sintel data when finetuning on Sintel. Ours (warm-start) ranks 1st on both the Sintel clean and final passes, and 1st among all flow approaches on KITTI. (1FlowNet2 originally reported results on the disparity split of Sintel, 3.54 is the EPE when their model is evaluated on the standard data [22]. 2 [23] finds that HD1K data does not help significantly during Sintel finetuning and reports results without it. )
| 训练数据 | 方法 | Sintel (train) | KITTI-15 (train) | Sintel (test) | KITTI-15 (test) | |||
|---|---|---|---|---|---|---|---|---|
| Clean | Final | F1-epe | F1-all | Clean | Final | F1-all | ||
| - | FlowFields[7] | - | - | - | - | 3.75 | 5.81 | 15.31 |
| - | FlowFields++[40] | - | - | - | - | 2.94 | 5.49 | 14.82 |
| S | DCFlow[47] | - | - | - | - | 3.54 | 5.12 | 14.86 |
| S | MRFlow[46] | - | - | - | - | 2.53 | 5.38 | 12.19 |
| C + T | HD3[50] | 3.84 | 8.77 | 13.17 | 24.0 | - | - | - |
| LiteFlowNet[22] | 2.48 | 4.04 | 10.39 | 28.5 | - | - | - | |
| PWC-Net[42] | 2.55 | 3.93 | 10.35 | 33.7 | - | - | - | |
| LiteFlowNet2[23] | 2.24 | 3.78 | 8.97 | 25.9 | - | - | - | |
| VCN[49] | 2.21 | 3.68 | 8.36 | 25.1 | - | - | - | |
| MaskFlowNet[52] | 2.25 | 3.61 | - | 23.1 | - | - | - | |
| FlowNet2[25] | 2.02 | 3.541 | 10.08 | 30.0 | 3.96 | 6.02 | - | |
| Ours (small) | 2.21 | 3.35 | 7.51 | 26.9 | - | - | - | |
| Ours (2-view) | 1.43 | 2.71 | 5.04 | 17.4 | - | - | - | |
| C+T+S/K | FlowNet2 [25] | (1.45) | (2.01) | (2.30) | (6.8) | 4.16 | 5.74 | 11.48 |
| HD3 [50] | (1.87) | (1.17) | (1.31) | (4.1) | 4.79 | 4.67 | 6.55 | |
| IRR-PWC [24] | (1.92) | (2.51) | (1.63) | (5.3) | 3.84 | 4.58 | 7.65 | |
| ScopeFlow[8] | - | - | - | - | 3.59 | 4.10 | 6.82 | |
| Ours (2-view) | (0.77) | (1.20) | (0.64) | (1.5) | 2.08 | 3.41 | 5.27 | |
| C+T+S+K+H | LiteFlowNet22 [23] | (1.30) | (1.62) | (1.47) | (4.8) | 3.48 | 4.69 | 7.74 |
| PWC-Net+[41] | (1.71) | (2.34) | (1.50) | (5.3) | 3.45 | 4.60 | 7.72 | |
| VCN [49] | (1.66) | (2.24) | (1.16) | (4.1) | 2.81 | 4.40 | 6.30 | |
| MaskFlowNet[52] | - | - | - | - | 2.52 | 4.17 | 6.10 | |
| Ours (2-view) | (0.76) | (1.22) | (0.63) | (1.5) | 1.94 | 3.18 | 5.10 | |
| Ours (warm-start) | (0.77) | (1.27) | - | - | 1.61 | 2.86 | - |
表 1:Sintel 与 KITTI 数据集结果。在 FlyingChairs(C) 与 FlyingThings(T) 上训练后,在 Sintel(train) 上测试泛化,clean 与 final 通道均超过现有方法。底部两段给出数据集特定微调后在公开排行榜上的表现。S/K 表示在 Sintel 上微调时只用 Sintel 数据、在 KITTI 上微调时只用 KITTI 数据的方法。+S+K+H 表示在 Sintel 上微调时混合 KITTI、HD1K 与 Sintel 数据的方法。Ours (warm-start) 在 Sintel clean 与 final 通道均排第 1,并在 KITTI 所有光流方法中排第 1。(1 FlowNet2 原先报告的是 Sintel 视差划分上的结果,3.54 是其模型在标准数据上评估时的 EPE [22]。2 [23] 发现 HD1K 数据在 Sintel 微调中帮助不大,报告的是不含该数据的结果。)
When using C+T for training, our method outperforms all existing approaches, despite using a significantly shorter training schedule. Our method achieves an average EPE (end-point-error) of 1.43 on the Sintel(train) clean pass, which is a 29% lower error than FlowNet2. These results demonstrates good cross dataset generalization. One of the reasons for better generalization is the structure of our network. By constraining optical flow to be the product of a series of identical update steps, we force the network to learn an update operator which mimics the updates of a first-order descent algorithm. This constrains the search space, reduces the risk of over-fitting, and leads to faster training and better generalization.
用 C+T 训练时,尽管训练日程显著更短,我们的方法仍超过所有现有方法。在 Sintel(train) clean 通道上,平均端点误差(EPE)为 1.43,比 FlowNet2 低 29%。这些结果说明跨数据集泛化良好。泛化更好的原因之一是网络结构:把光流约束为一串相同更新步的产物,迫使网络学习模仿一阶下降算法的更新算子,从而缩小搜索空间、降低过拟合风险,并带来更快训练与更好泛化。
When evaluating on the Sintel(test) set, we finetune on the combined clean and final passes of the training set along with KITTI and HD1K data. Our method ranks 1st on both the Sintel clean and final passes, and outperforms all prior work by 0.9 pixels (36%) on the clean pass and 1.2 pixels (30%) on the final pass. We evaluate two versions of our model, Ours (two-frame) uses zero initialization, while Ours (warp-start) initializes flow by forward projecting the flow estimate from the previous frame. Since our method operates at a single resolution, we can initialize the flow estimate to utilize motion smoothness from past frames, which cannot be easily done using the coarse-to-fine model.
在 Sintel(test) 上评估时,我们在训练集 clean 与 final 通道的合并数据上微调,并加入 KITTI 与 HD1K。我们的方法在 Sintel clean 与 final 通道均排第 1,相对先前工作在 clean 上低 0.9 像素(36%)、在 final 上低 1.2 像素(30%)。我们评估两个版本:Ours(两帧)用零初始化,Ours(热启动)用上一帧流场的前向投影初始化。由于方法在单一分辨率上操作,可以利用过去帧的运动平滑性来初始化流估计,而这在由粗到细模型中不易做到。
4.2 KITTI
We also evaluate RAFT on KITTI and provide results in Table 1 and Figure 4. We first evaluate cross-dataset generalization by evaluating on the KITTI-15 (train) split after training on Chairs(C) and FlyingThings(T). Our method outperforms prior works by a large margin, improving EPE (end-point-error) from 8.36 to 5.04, which shows that the underlying structure of our network facilitates generalization. Our method ranks 1st on the KITTI leaderboard among all optical flow methods.
我们也在 KITTI 上评估 RAFT,结果见表 1 与图 4。先在 Chairs(C) 与 FlyingThings(T) 上训练后,在 KITTI-15(train)划分上评估跨数据集泛化。我们的方法大幅超过先前工作,把端点误差从 8.36 降到 5.04,说明网络的底层结构有利于泛化。在 KITTI 排行榜所有光流方法中,我们的方法排第 1。
4.3 Ablations
4.3 消融
We perform a set of ablation experiments to show the relative importance of each component. All ablated versions are trained on FlyingChairs(C) + FlyingThings(T). Results of the ablations are shown in Table 2. In each section of the table, we test a specific component of our approach in isolation, the settings which are used in our final model is underlined. Below we describe each of the experiments in more detail.
我们做一组消融实验,展示各部件的相对重要性。所有消融版本都在 FlyingChairs(C) + FlyingThings(T) 上训练。结果见表 2。表的每一段单独测试方法的一个组件,最终模型采用的设置加下划线。下面更详细说明各实验。
| Experiment | Method | Sintel (train) | KITTI-15 (train) | Parameters | ||
|---|---|---|---|---|---|---|
| Clean | Final | F1-epe | F1-all | |||
| Reference Model (bilinear upsampling), Training: 100k(C) 60k(T) | ||||||
| Update Op. | ConvGRU | 1.63 | 2.83 | 5.54 | 19.8 | 4.8M |
| Conv | 2.04 | 3.21 | 7.66 | 26.1 | 4.1M | |
| Tying | Tied Weights | 1.63 | 2.83 | 5.54 | 19.8 | 4.8M |
| Untied Weights | 1.96 | 3.20 | 7.64 | 24.1 | 32.5M | |
| Context | Context | 1.63 | 2.83 | 5.54 | 19.8 | 4.8M |
| No Context | 1.93 | 3.06 | 6.25 | 23.1 | 3.3M | |
| Feature Scale | Single-Scale | 1.63 | 2.83 | 5.54 | 19.8 | 4.8M |
| Multi-Scale | 2.08 | 3.12 | 6.91 | 23.2 | 6.6M | |
| Lookup Radius | 0 | 3.41 | 4.53 | 23.6 | 44.8 | 4.7M |
| 1 | 1.80 | 2.99 | 6.27 | 21.5 | 4.7M | |
| 2 | 1.78 | 2.82 | 5.84 | 21.1 | 4.8M | |
| 4 | 1.63 | 2.83 | 5.54 | 19.8 | 4.8M | |
| Correlation Pooling | No | 1.95 | 3.02 | 6.07 | 23.2 | 4.7M |
| Yes | 1.63 | 2.83 | 5.54 | 19.8 | 4.8M | |
| Correlation Range | 32px | 2.91 | 4.48 | 10.4 | 28.8 | 4.8M |
| 64px | 2.06 | 3.16 | 6.24 | 20.9 | 4.8M | |
| 128px | 1.64 | 2.81 | 6.00 | 19.9 | 4.8M | |
| All-Pairs | 1.63 | 2.83 | 5.54 | 19.8 | 4.8M | |
| Features for Refinement | Correlation | 1.63 | 2.83 | 5.54 | 19.8 | 4.8M |
| Warping | 2.27 | 3.73 | 11.83 | 32.1 | 2.8M | |
| Reference Model (convex upsampling), Training: 100k(C) 100k(T) | ||||||
| Upsampling | Convex | 1.43 | 2.71 | 5.04 | 17.4 | 5.3M |
| Bilinear | 1.60 | 2.79 | 5.17 | 19.2 | 4.8M | |
| Inference Updates | 1 | 4.04 | 5.45 | 15.30 | 44.5 | 5.3M |
| 3 | 2.14 | 3.52 | 8.98 | 29.9 | 5.3M | |
| 8 | 1.61 | 2.88 | 5.99 | 19.6 | 5.3M | |
| 32 | 1.43 | 2.71 | 5.00 | 17.4 | 5.3M | |
| 100 | 1.41 | 2.72 | 4.95 | 17.4 | 5.3M | |
| 200 | 1.40 | 2.73 | 4.94 | 17.4 | 5.3M |
Table 2: Ablation experiments. Settings used in our final model are underlined. See Sec. 4.3 for details.
| 实验 | 方法 | Sintel (train) | KITTI-15 (train) | 参数量 | ||
|---|---|---|---|---|---|---|
| Clean | Final | F1-epe | F1-all | |||
| 参考模型(双线性上采样),训练:100k(C) 60k(T) | ||||||
| 更新算子 | ConvGRU | 1.63 | 2.83 | 5.54 | 19.8 | 4.8M |
| Conv | 2.04 | 3.21 | 7.66 | 26.1 | 4.1M | |
| 权重共享 | 共享权重 | 1.63 | 2.83 | 5.54 | 19.8 | 4.8M |
| 不共享权重 | 1.96 | 3.20 | 7.64 | 24.1 | 32.5M | |
| 上下文 | 有上下文 | 1.63 | 2.83 | 5.54 | 19.8 | 4.8M |
| 无上下文 | 1.93 | 3.06 | 6.25 | 23.1 | 3.3M | |
| 特征尺度 | 单尺度 | 1.63 | 2.83 | 5.54 | 19.8 | 4.8M |
| 多尺度 | 2.08 | 3.12 | 6.91 | 23.2 | 6.6M | |
| 查找半径 | 0 | 3.41 | 4.53 | 23.6 | 44.8 | 4.7M |
| 1 | 1.80 | 2.99 | 6.27 | 21.5 | 4.7M | |
| 2 | 1.78 | 2.82 | 5.84 | 21.1 | 4.8M | |
| 4 | 1.63 | 2.83 | 5.54 | 19.8 | 4.8M | |
| 相关池化 | 否 | 1.95 | 3.02 | 6.07 | 23.2 | 4.7M |
| 是 | 1.63 | 2.83 | 5.54 | 19.8 | 4.8M | |
| 相关范围 | 32px | 2.91 | 4.48 | 10.4 | 28.8 | 4.8M |
| 64px | 2.06 | 3.16 | 6.24 | 20.9 | 4.8M | |
| 128px | 1.64 | 2.81 | 6.00 | 19.9 | 4.8M | |
| 全像素对 | 1.63 | 2.83 | 5.54 | 19.8 | 4.8M | |
| 细化用特征 | 相关 | 1.63 | 2.83 | 5.54 | 19.8 | 4.8M |
| 扭曲 | 2.27 | 3.73 | 11.83 | 32.1 | 2.8M | |
| 参考模型(凸组合上采样),训练:100k(C) 100k(T) | ||||||
| 上采样 | 凸组合 | 1.43 | 2.71 | 5.04 | 17.4 | 5.3M |
| 双线性 | 1.60 | 2.79 | 5.17 | 19.2 | 4.8M | |
| 推理更新次数 | 1 | 4.04 | 5.45 | 15.30 | 44.5 | 5.3M |
| 3 | 2.14 | 3.52 | 8.98 | 29.9 | 5.3M | |
| 8 | 1.61 | 2.88 | 5.99 | 19.6 | 5.3M | |
| 32 | 1.43 | 2.71 | 5.00 | 17.4 | 5.3M | |
| 100 | 1.41 | 2.72 | 4.95 | 17.4 | 5.3M | |
| 200 | 1.40 | 2.73 | 4.94 | 17.4 | 5.3M |
表 2:消融实验。最终模型采用的设置加下划线。细节见第 4.3 节。
Architecture of Update Operator: We use a gated activation unit based on the GRU cell. We experiment with replacing the convolutional GRU with a set of 3 convolutional layers with ReLU activation. We achieve better performance by using the GRU block, likely because the gated activation makes it easier for the sequence of flow estimates to converge.
更新算子架构: 我们使用基于 GRU 单元的门控激活。实验中用一组带 ReLU 的 3 层卷积替换卷积 GRU。使用 GRU 块效果更好,可能是因为门控激活更有利于流估计序列收敛。
Weight Tying: By default, we tied the weights across all instances of the update operator. Here, we test a version of our approach where each update operator learns a separate set of weights. Accuracy is better when weights are tied and the parameter count is significantly lower.
权重共享: 默认在所有更新算子实例间共享权重。这里测试每个更新算子学习独立权重的版本。共享权重时精度更好,参数量也显著更低。
Context: We test the importance of context by training a model with the context network removed. Without context, we still achieve good results, outperforming all existing works on both Sintel and KITTI. But context is helpful. Directly injecting image features into the update operator likely allows spatial information to be better aggregated within motion boundaries.
上下文: 通过去掉上下文网络来测试其重要性。没有上下文时,我们在 Sintel 与 KITTI 上仍超过所有现有工作,但上下文有帮助。把图像特征直接注入更新算子,可能让空间信息在运动边界内聚合得更好。
Feature Scale: By default, we extract features at a single resolution. We also try extracting features at multiple resolutions by building a correlation volume at each scale separately. Single resolution features simplifies the network architecture and allows fine-grained matching even at large displacements.
特征尺度: 默认在单一分辨率提取特征。我们也尝试在多个分辨率分别建相关体积来提取多尺度特征。单分辨率特征简化了网络结构,并允许即使在大位移下仍做细粒度匹配。
Lookup Radius: The lookup radius specifies the dimensions of the grid used in the lookup operation. When a radius of 0 is used, the correlation volume is retrieved at a single point. Surprisingly, we can still get a rough estimate of flow when the radius is 0, which means the network is learning to use 0’th order information. However, we see better results as the radius is increased.
查找半径: 查找半径指定查找操作所用网格的尺寸。半径为 0 时,只在单点取回相关体积。令人惊讶的是,半径为 0 时仍能得到粗略流估计,说明网络在利用零阶信息。不过半径增大后结果更好。
Correlation Pooling: We output features at a single resolution and then perform pooling to generate multiscale volumes. Here we test the impact when this pooling is removed. Results are better with pooling, because large and small displacements are both captured.
相关池化: 我们在单一分辨率输出特征,再池化生成多尺度体积。这里测试去掉池化的影响。有池化时结果更好,因为大位移与小位移都被捕获。
Correlation Range: Instead of all-pairs correlation, we also try constructing the correlation volume only for a local neighborhood around each pixel. We try a range of 32 pixels, 64 pixels, and 128 pixels. Overall we get the best results when the all-pairs are used, although a 128px range is sufficient to perform well on Sintel because most displacements fall within this range. That said, all-pairs is still preferable because it eliminates the need to specify a range. It is also more convenient to implement: it can be computed using matrix multiplication allowing our approach to be implemented entirely in PyTorch.
相关范围: 除全像素对相关外,我们也尝试只在每个像素的局部邻域内构造相关体积,范围分别取 32、64、128 像素。总体仍是全像素对最好,不过 128 像素范围在 Sintel 上已足够好,因为多数位移落在该范围内。即便如此,全像素对仍更可取:无需指定范围,实现也更方便——可用矩阵乘法计算,使整个方法能纯用 PyTorch 实现。
Features for Refinement: We compute visual similarity by building a correlation volume between all pairs of pixels. In this experiment, we try replacing the correlation volume with a warping layer, which uses the current estimate of optical flow to warp features from onto and then estimates the residual displacement. While warping is still competitive with prior work on Sintel, correlation performs significantly better, especially on KITTI.
细化用特征: 我们通过为所有像素对建相关体积来计算视觉相似度。本实验尝试用扭曲层替换相关体积:用当前光流估计把 的特征扭曲到 ,再估计残差位移。扭曲在 Sintel 上仍可与先前工作竞争,但相关显著更好,尤其在 KITTI 上。
Upsampling: RAFT outputs flow fields at 1/8 resolution. We compare bilinear upsampling to our learned upsampling module. The upsampling module produces better results, particularly near motion boundaries.
上采样: RAFT 输出 1/8 分辨率流场。我们比较双线性上采样与学习得到的上采样模块。上采样模块结果更好,尤其在运动边界附近。
Inference Updates: Although we unroll 12 updates during training, we can apply an arbitrary number of updates during inference. In Table 2 we provide numerical results for selected number of updates, and test an extreme case of 200 to show that our method doesn’t diverge. Our method quickly converges, surpassing PWC-Net after 3 updates and FlowNet2 after 6 updates, but continues to improve with more updates.
推理更新次数: 训练时虽展开 12 次更新,推理时可应用任意次数。表 2 给出若干更新次数的数值结果,并测试极端的 200 次以表明方法不发散。方法收敛很快:3 次更新就超过 PWC-Net,6 次超过 FlowNet2,更多更新仍继续改善。
4.4 Timing and Parameter Counts
4.4 耗时与参数量
Inference time and parameter counts are shown in Figure 5. Accuracy is determined by performance on the Sintel(train) final pass after training on FlyingChairs and FlyingThings (C+T). In these plots, we report accuracy and timing after 10 iterations, and we time our method using a GTX 1080Ti GPU. Parameters counts for other methods are taken as reported in their papers, and we report times when run on our hardware. RAFT is more efficient in terms of parameter count, inference time, and training iterations. Ours-S uses only 1M parameters, but outperforms PWC-Net and VCN which are more than 6x larger. We provide an additional table with numerical values for parameters, timing, and training iterations in the supplemental material.
推理时间与参数量见图 5。精度由在 FlyingChairs 与 FlyingThings(C+T)上训练后、Sintel(train) final 通道上的表现决定。图中报告 10 次迭代后的精度与耗时,并在 GTX 1080Ti GPU 上计时。其他方法的参数量取自其论文报告,耗时则在我们的硬件上重测。RAFT 在参数量、推理时间和训练迭代上都更高效。Ours-S 仅用 100 万参数,仍超过大 6 倍以上的 PWC-Net 与 VCN。补充材料中另有参数量、耗时与训练迭代的数值表。
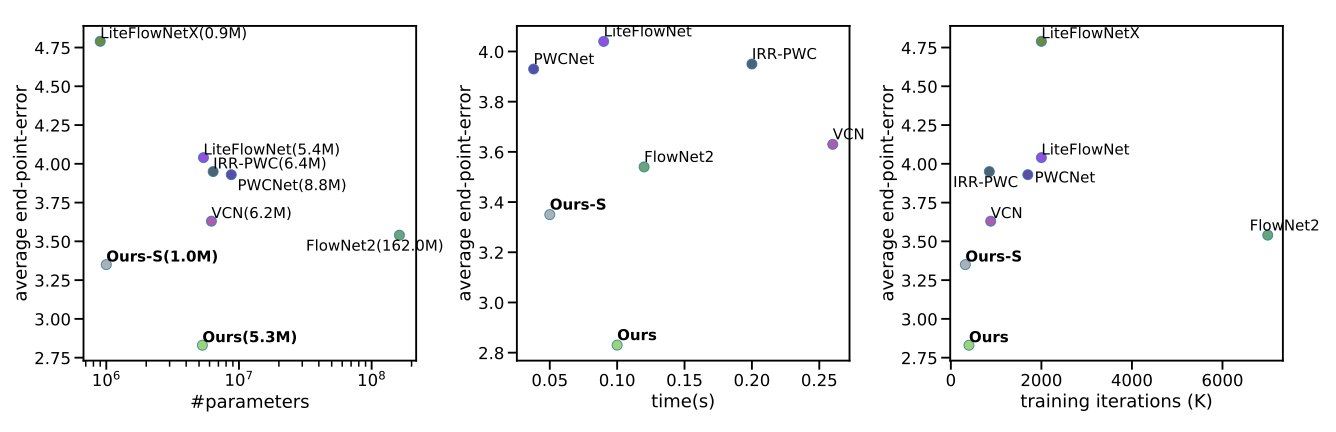
Figure 5: Plots comparing parameter counts, inference time, and training iterations vs. accuracy. Accuracy is measured by the EPE on the Sintel(train) final pass after training on C+T. Left: Parameter count vs. accuracy compared to other methods. RAFT is more parameter efficient while achieving lower EPE. Middle: Inference time vs. accuracy timed using our hardware Right: Training iterations vs. accuracy (taken as product of iterations and GPUs used).
图 5:参数量、推理时间、训练迭代次数与精度的对比图。精度以 C+T 训练后 Sintel(train) final 通道上的 EPE 衡量。左:相对其他方法的参数量 vs 精度。RAFT 参数更少且 EPE 更低。中:在我们硬件上测得的推理时间 vs 精度。右:训练迭代次数 vs 精度(取迭代次数与所用 GPU 数的乘积)。
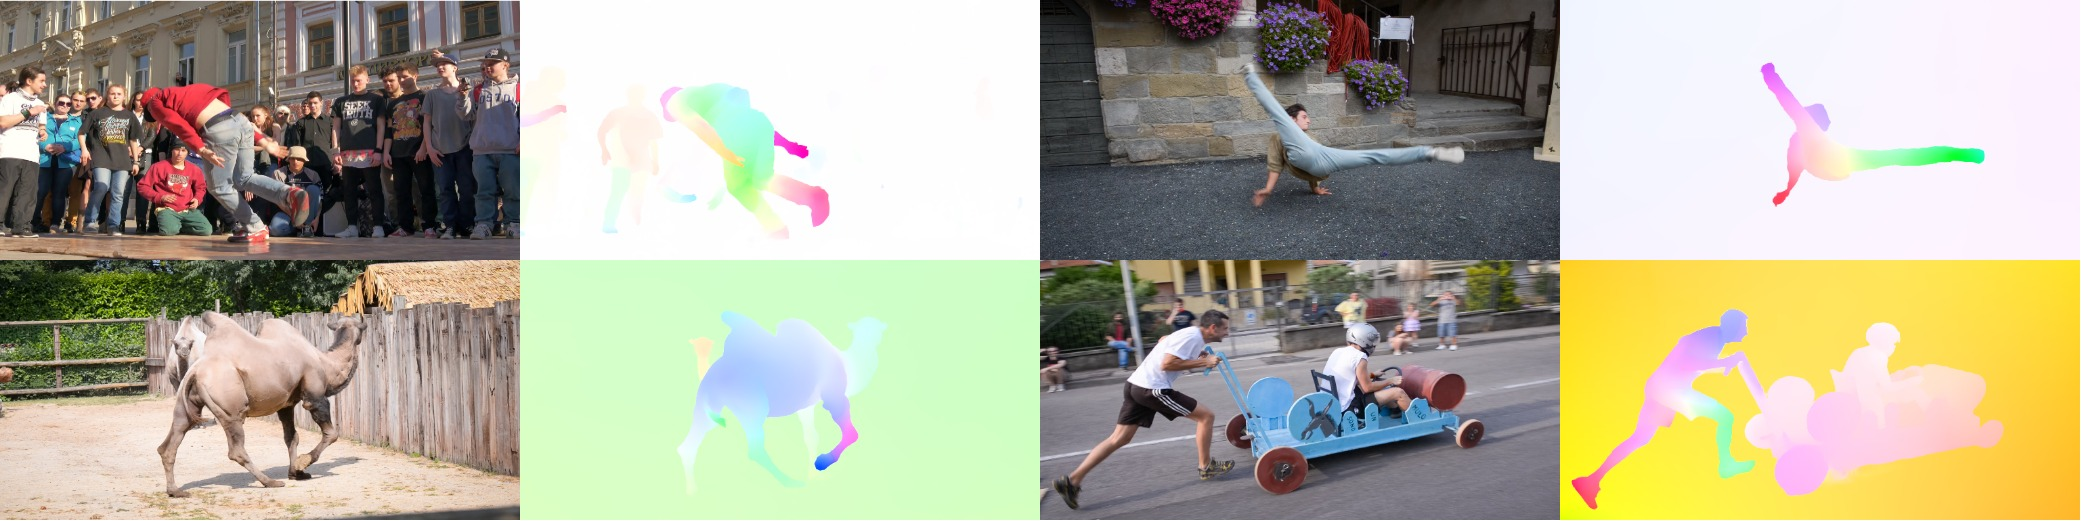
Figure 6: Results on 1080p (1088x1920) video from DAVIS (550 ms per frame).
图 6:DAVIS 1080p(1088×1920)视频上的结果(每帧 550 ms)。
4.5 Video of Very High Resolution
4.5 很高分辨率的视频
To demonstrate that our method scales well to videos of very high resolution we apply our network to HD video from the DAVIS[37] dataset. We use 1080p (1088x1920) resolution video and apply 12 iterations of our approach. Inference takes 550ms for 12 iterations on 1080p video, with all-pairs correlation taking 95ms. Fig. 6 visualizes example results on DAVIS.
为表明方法能良好扩展到很高分辨率视频,我们把网络应用到 DAVIS[37] 数据集的高清视频。使用 1080p(1088×1920)分辨率,做 12 次迭代。1080p 上 12 次迭代推理约 550 ms,其中全像素对相关占 95 ms。图 6 可视化 DAVIS 上的示例结果。
5 Conclusions
5 结论
We have proposed RAFT—Recurrent All-Pairs Field Transforms—a new end-to-end trainable model for optical flow. RAFT is unique in that it operates at a single resolution using a large number of lightweight, recurrent update operators. Our method achieves state-of-the-art accuracy across a diverse range of datasets, strong cross dataset generalization, and is efficient in terms of inference time, parameter count, and training iterations.
我们提出了 RAFT——循环全像素对场变换——一种新的端到端可训练光流模型。RAFT 的独特之处在于:在单一分辨率上操作,并使用大量轻量、循环的更新算子。我们的方法在多种数据集上达到最优精度,跨数据集泛化强,并在推理时间、参数量与训练迭代上都很高效。
Acknowledgments: This work was partially funded by the National Science Foundation under Grant No. 1617767.
致谢: 本工作部分由美国国家科学基金会资助,资助号 1617767。
References
参考文献
[1] Adler, J., Öktem, O.: Solving ill-posed inverse problems using iterative deep neural networks. Inverse Problems 33 (12), 124007 (2017)
[2] Adler, J., Öktem, O.: Learned primal-dual reconstruction. IEEE transactions on medical imaging 37 (6), 1322–1332 (2018)
[3] Agrawal, A., Amos, B., Barratt, S., Boyd, S., Diamond, S., Kolter, J.Z.: Differentiable convex optimization layers. In: Advances in Neural Information Processing Systems. pp. 9558–9570 (2019)
[4] Amos, B., Kolter, J.Z.: Optnet: Differentiable optimization as a layer in neural networks. In: Proceedings of the 34th International Conference on Machine Learning-Volume 70. pp. 136–145. JMLR. org (2017)
[5] Bai, S., Kolter, J.Z., Koltun, V.: Trellis networks for sequence modeling. arXiv preprint arXiv:1810.06682 (2018)
[6] Bai, S., Kolter, J.Z., Koltun, V.: Deep equilibrium models. In: Advances in Neural Information Processing Systems. pp. 688–699 (2019)
[7] Bailer, C., Taetz, B., Stricker, D.: Flow fields: Dense correspondence fields for highly accurate large displacement optical flow estimation. In: Proceedings of the IEEE international conference on computer vision. pp. 4015–4023 (2015)
[8] Bar-Haim, A., Wolf, L.: Scopeflow: Dynamic scene scoping for optical flow. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition. pp. 7998–8007 (2020)
[9] Black, M.J., Anandan, P.: A framework for the robust estimation of optical flow. In: 1993 (4th) International Conference on Computer Vision. pp. 231–236. IEEE (1993)
[10] Brox, T., Bregler, C., Malik, J.: Large displacement optical flow. In: 2009 IEEE Conference on Computer Vision and Pattern Recognition. pp. 41–48. IEEE (2009)
[11] Butler, D.J., Wulff, J., Stanley, G.B., Black, M.J.: A naturalistic open source movie for optical flow evaluation. In: European conference on computer vision. pp. 611–625. Springer (2012)
[12] Chambolle, A., Pock, T.: A first-order primal-dual algorithm for convex problems with applications to imaging. Journal of mathematical imaging and vision 40 (1), 120–145 (2011)
[13] Chen, Q., Koltun, V.: Full flow: Optical flow estimation by global optimization over regular grids. In: Proceedings of the IEEE conference on computer vision and pattern recognition. pp. 4706–4714 (2016)
[14] Cho, K., Van Merriënboer, B., Bahdanau, D., Bengio, Y.: On the properties of neural machine translation: Encoder-decoder approaches. arXiv preprint arXiv:1409.1259 (2014)
[15] Dosovitskiy, A., Fischer, P., Ilg, E., Hausser, P., Hazirbas, C., Golkov, V., Van Der Smagt, P., Cremers, D., Brox, T.: Flownet: Learning optical flow with convolutional networks. In: Proceedings of the IEEE international conference on computer vision. pp. 2758–2766 (2015)
[16] Fan, L., Huang, W., Gan, C., Ermon, S., Gong, B., Huang, J.: End-to-end learning of motion representation for video understanding. In: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition. pp. 6016–6025 (2018)
[17] Flynn, J., Broxton, M., Debevec, P., DuVall, M., Fyffe, G., Overbeck, R.S., Snavely, N., Tucker, R.: Deepview: High-quality view synthesis by learned gradient descent (2019)
[18] Geiger, A., Lenz, P., Stiller, C., Urtasun, R.: Vision meets robotics: The kitti dataset. The International Journal of Robotics Research 32 (11), 1231–1237 (2013)
[19] Hirschmuller, H.: Stereo processing by semiglobal matching and mutual information. IEEE Transactions on pattern analysis and machine intelligence 30 (2), 328–341 (2007)
[20] Hofinger, M., Bulò, S.R., Porzi, L., Knapitsch, A., Kontschieder, P.: Improving optical flow on a pyramidal level. In: ECCV (2020)
[21] Horn, B.K., Schunck, B.G.: Determining optical flow. In: Techniques and Applications of Image Understanding. vol. 281, pp. 319–331. International Society for Optics and Photonics (1981)
[22] Hui, T.W., Tang, X., Change Loy, C.: Liteflownet: A lightweight convolutional neural network for optical flow estimation. In: Proceedings of the IEEE conference on computer vision and pattern recognition. pp. 8981–8989 (2018)
[23] Hui, T.W., Tang, X., Loy, C.C.: A lightweight optical flow cnn–revisiting data fidelity and regularization. arXiv preprint arXiv:1903.07414 (2019)
[24] Hur, J., Roth, S.: Iterative residual refinement for joint optical flow and occlusion estimation. In: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition. pp. 5754–5763 (2019)
[25] Ilg, E., Mayer, N., Saikia, T., Keuper, M., Dosovitskiy, A., Brox, T.: Flownet 2.0: Evolution of optical flow estimation with deep networks. In: Proceedings of the IEEE conference on computer vision and pattern recognition. pp. 2462–2470 (2017)
[26] Kobler, E., Klatzer, T., Hammernik, K., Pock, T.: Variational networks: connecting variational methods and deep learning. In: German conference on pattern recognition. pp. 281–293. Springer (2017)
[27] Kondermann, D., Nair, R., Honauer, K., Krispin, K., Andrulis, J., Brock, A., Gussefeld, B., Rahimimoghaddam, M., Hofmann, S., Brenner, C., et al.: The hci benchmark suite: Stereo and flow ground truth with uncertainties for urban autonomous driving. In: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition Workshops. pp. 19–28 (2016)
[28] Li, X., Wu, J., Lin, Z., Liu, H., Zha, H.: Recurrent squeeze-and-excitation context aggregation net for single image deraining. In: Proceedings of the European Conference on Computer Vision (ECCV). pp. 254–269 (2018)
[29] Liang, Z., Feng, Y., Guo, Y., Liu, H., Chen, W., Qiao, L., Zhou, L., Zhang, J.: Learning for disparity estimation through feature constancy. In: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition. pp. 2811–2820 (2018)
[30] Loshchilov, I., Hutter, F.: Decoupled weight decay regularization. arXiv preprint arXiv:1711.05101 (2017)
[31] Lu, Y., Valmadre, J., Wang, H., Kannala, J., Harandi, M., Torr, P.: Devon: Deformable volume network for learning optical flow. In: The IEEE Winter Conference on Applications of Computer Vision. pp. 2705–2713 (2020)
[32] Lv, Z., Dellaert, F., Rehg, J.M., Geiger, A.: Taking a deeper look at the inverse compositional algorithm. In: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition. pp. 4581–4590 (2019)
[33] Mayer, N., Ilg, E., Hausser, P., Fischer, P., Cremers, D., Dosovitskiy, A., Brox, T.: A large dataset to train convolutional networks for disparity, optical flow, and scene flow estimation. In: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition. pp. 4040–4048 (2016)
[34] Menze, M., Geiger, A.: Object scene flow for autonomous vehicles. In: Proceedings of the IEEE conference on computer vision and pattern recognition. pp. 3061–3070 (2015)
[35] Menze, M., Heipke, C., Geiger, A.: Discrete optimization for optical flow. In: German Conference on Pattern Recognition. pp. 16–28. Springer (2015)
[36] Paszke, A., Gross, S., Chintala, S., Chanan, G., Yang, E., DeVito, Z., Lin, Z., Desmaison, A., Antiga, L., Lerer, A.: Automatic differentiation in pytorch (2017)
[37] Pont-Tuset, J., Perazzi, F., Caelles, S., Arbeláez, P., Sorkine-Hornung, A., Van Gool, L.: The 2017 davis challenge on video object segmentation. arXiv preprint arXiv:1704.00675 (2017)
[38] Ranftl, R., Bredies, K., Pock, T.: Non-local total generalized variation for optical flow estimation. In: European Conference on Computer Vision. pp. 439–454. Springer (2014)
[39] Ranjan, A., Black, M.J.: Optical flow estimation using a spatial pyramid network. In: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition. pp. 4161–4170 (2017)
[40] Schuster, R., Bailer, C., Wasenmüller, O., Stricker, D.: Flowfields++: Accurate optical flow correspondences meet robust interpolation. In: 2018 25th IEEE International Conference on Image Processing (ICIP). pp. 1463–1467. IEEE (2018)
[41] Sun, D., Yang, X., Liu, M.Y., Kautz, J.: Models matter, so does training: An empirical study of cnns for optical flow estimation. arXiv preprint arXiv:1809.05571 (2018)
[42] Sun, D., Yang, X., Liu, M.Y., Kautz, J.: Pwc-net: Cnns for optical flow using pyramid, warping, and cost volume. In: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition. pp. 8934–8943 (2018)
[43] Tang, C., Tan, P.: Ba-net: Dense bundle adjustment network. arXiv preprint arXiv:1806.04807 (2018)
[44] Teed, Z., Deng, J.: Deepv2d: Video to depth with differentiable structure from motion. arXiv preprint arXiv:1812.04605 (2018)
[45] Weinzaepfel, P., Revaud, J., Harchaoui, Z., Schmid, C.: Deepflow: Large displacement optical flow with deep matching. In: Proceedings of the IEEE international conference on computer vision. pp. 1385–1392 (2013)
[46] Wulff, J., Sevilla-Lara, L., Black, M.J.: Optical flow in mostly rigid scenes. In: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition. pp. 4671–4680 (2017)
[47] Xu, J., Ranftl, R., Koltun, V.: Accurate optical flow via direct cost volume processing. In: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition. pp. 1289–1297 (2017)
[48] Yang, G., Manela, J., Happold, M., Ramanan, D.: Hierarchical deep stereo matching on high-resolution images. In: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition. pp. 5515–5524 (2019)
[49] Yang, G., Ramanan, D.: Volumetric correspondence networks for optical flow. In: Advances in Neural Information Processing Systems. pp. 793–803 (2019)
[50] Yin, Z., Darrell, T., Yu, F.: Hierarchical discrete distribution decomposition for match density estimation. In: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition. pp. 6044–6053 (2019)
[51] Zach, C., Pock, T., Bischof, H.: A duality based approach for realtime tv-l 1 optical flow. In: Joint pattern recognition symposium. pp. 214–223. Springer (2007)
[52] Zhao, S., Sheng, Y., Dong, Y., Chang, E.I., Xu, Y., et al.: Maskflownet: Asymmetric feature matching with learnable occlusion mask. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition. pp. 6278–6287 (2020)
[53] Zhou, H., Ummenhofer, B., Brox, T.: Deeptam: Deep tracking and mapping. In: Proceedings of the European conference on computer vision (ECCV). pp. 822–838 (2018)
Appendix 0.A Network Architecture
附录 0.A 网络架构
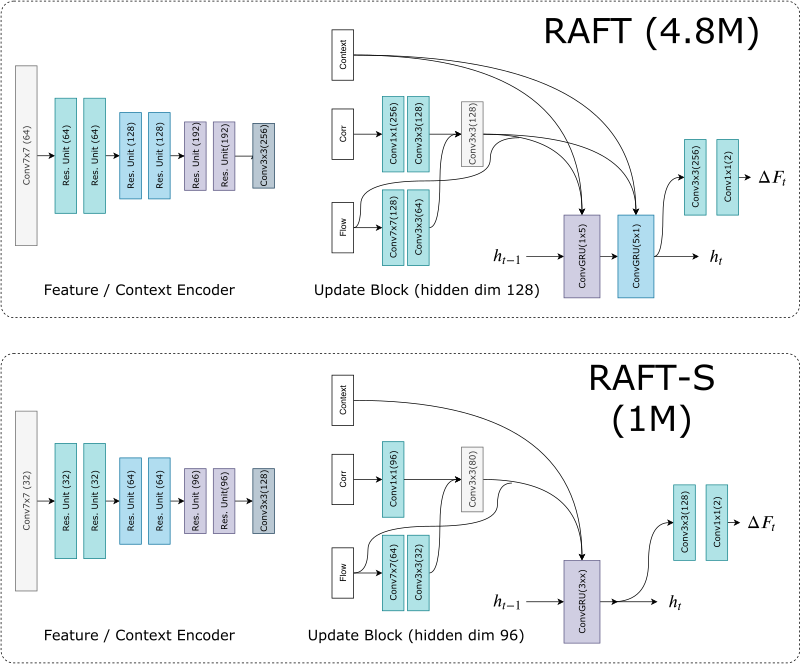
Figure 7: Network architecture details for the full 4.8M parameter model (5.3M with upsampling module) and the small 1.0M parameter model. The context and feature encoders have the same architecture, the only difference is that the feature encoder uses instance normalization while the context encoder uses batch normalization. In RAFT-S, we replace the residual units with bottleneck residual units. The update block takes in context features, correlation features, and flow features to update the latent hidden state. The updated hidden status is used to predict the flow update. The full model uses two convolutional GRU update blocks with 1x5 filters and 5x1 filters respectively, while the small model uses a single GRU with 3x3 filters.
图 7:完整 480 万参数模型(含上采样模块为 530 万)与小型 100 万参数模型的网络架构细节。上下文编码器与特征编码器架构相同,唯一区别是特征编码器使用实例归一化,上下文编码器使用批归一化。在 RAFT-S 中,残差单元替换为瓶颈残差单元。更新块接收上下文特征、相关特征与流场特征以更新潜在隐状态,再用更新后的隐状态预测流场更新。完整模型使用两个卷积 GRU 更新块,滤波器分别为 1×5 与 5×1;小模型使用单个 3×3 滤波器的 GRU。
Appendix 0.B Upsampling Module
附录 0.B 上采样模块
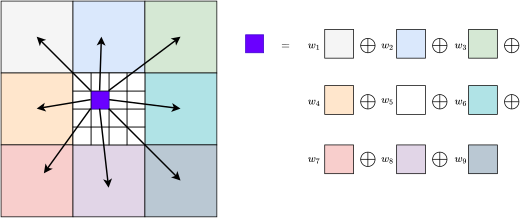
Figure 8: Illistration of the upsampling module. Each pixel of the high resolution flow field (small boxes) is taken to be the convex combination of its 9 coarse resolution neighbors using weights predicted by the network.
图 8:上采样模块示意。高分辨率流场的每个像素(小方块)取为其 9 个粗分辨率邻居的凸组合,权重由网络预测。
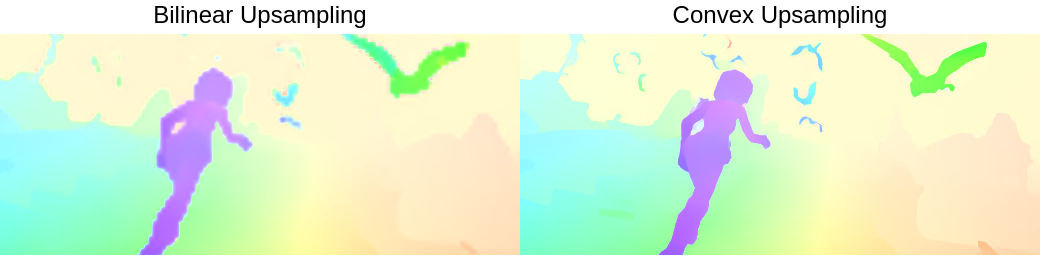
Figure 9: Our upsampling module improves accuracy near motion boundaries, and also allows RAFT to recover the flow of small fast moving objects such as the birds shown in the figure.
图 9:我们的上采样模块改善了运动边界附近的精度,也使 RAFT 能恢复图中飞鸟这类小而快物体的光流。
Appendix 0.C Training Details
附录 0.C 训练细节
| Stage | Weights | Training Data | Learning Rate | Batch Size (per GPU) | Weight Decay | Crop Size |
|---|---|---|---|---|---|---|
| Chairs | - | C | 4e-4 | 6 | 1e-4 | [368, 496] |
| Things | Chairs | T | 1.2e-4 | 3 | 1e-4 | [400, 720] |
| Sintel | Things | S+T+K+H | 1.2e-4 | 3 | 1e-5 | [368, 768] |
| KITTI | Sintel | K | 1e-4 | 3 | 1e-5 | [288, 960] |
Table 3: Details of the training schedule. Dataset abbreviations: C: FlyingChairs, T: FlyingThings, S: Sintel, K: KITTI-2015, H: HD1K. During the Sintel Finetuning phase, the dataset distribution is S(.71), T(.135), K(.135), H(.02).
| 阶段 | 权重 | 训练数据 | 学习率 | Batch Size(每 GPU) | 权重衰减 | 裁剪尺寸 |
|---|---|---|---|---|---|---|
| Chairs | - | C | 4e-4 | 6 | 1e-4 | [368, 496] |
| Things | Chairs | T | 1.2e-4 | 3 | 1e-4 | [400, 720] |
| Sintel | Things | S+T+K+H | 1.2e-4 | 3 | 1e-5 | [368, 768] |
| KITTI | Sintel | K | 1e-4 | 3 | 1e-5 | [288, 960] |
表 3:训练日程细节。数据集缩写:C:FlyingChairs,T:FlyingThings,S:Sintel,K:KITTI-2015,H:HD1K。Sintel 微调阶段的数据分布为 S(.71)、T(.135)、K(.135)、H(.02)。
Photometric Augmentation: We perform photometric augmentation by randomly perturbing brightness, contrast, saturation, and hue. We use the Torchvision ColorJitter with brightness 0.4, contrast 0.4, saturation 0.4, and hue 0.5/. On KITTI, we reduce the degree of augmentation to brightness 0.3, contrast 0.3, saturation 0.3, and hue 0.3/. With probablity 0.2, color augmentation is performed to each of the images independently.
光度增强: 通过随机扰动亮度、对比度、饱和度与色相做光度增强。使用 Torchvision ColorJitter,亮度 0.4、对比度 0.4、饱和度 0.4、色相 。在 KITTI 上减弱增强:亮度 0.3、对比度 0.3、饱和度 0.3、色相 。以概率 0.2 对两张图像分别独立做颜色增强。
Spatial Augmentation: We perform spatial augmentation by randomly rescaling and stretching the images. The degree of random scaling depends on the dataset. For FlyingChairs, we perform spatial augmentation in the range , FlyingThings , Sintel , and KITTI . Spatial augmentation is performed with probability 0.8.
空间增强: 通过随机缩放与拉伸图像做空间增强。随机缩放幅度取决于数据集:FlyingChairs 为 ,FlyingThings 为 ,Sintel 为 ,KITTI 为 。空间增强以概率 0.8 执行。
Occlusion Augmentation: Following HSM-Net [48], we also randomly erase rectangular regions in with probability 0.5 to simulate occlusions.
遮挡增强: 沿用 HSM-Net [48],以概率 0.5 在 中随机擦除矩形区域,以模拟遮挡。
Appendix 0.D Timing, Parameters, and Training Iterations
附录 0.D 耗时、参数量与训练迭代
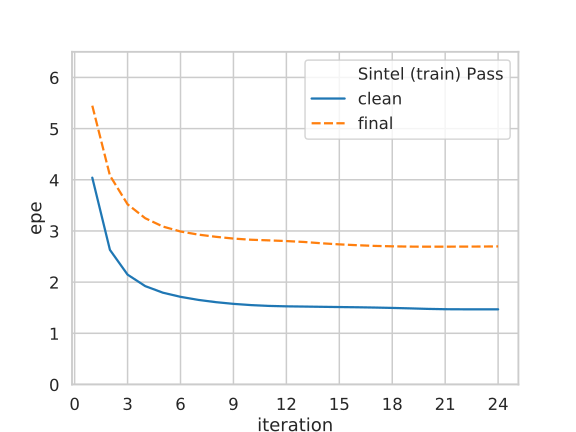
Figure 10: (Left) EPE on the Sintel set as a function of the number of iterations at inference time. (Right) Magnitude of each update averaged over all pixels indicating convergence to a fixed point .
图 10:(左)推理时迭代次数与 Sintel 集上 EPE 的关系。(右)每次更新的幅度 对所有像素取平均,表明收敛到不动点 。
| Method | Parameters (M) | Time (Reported) | Time (1080Ti) | Training Iter. (#GPUs) | Accuracy |
|---|---|---|---|---|---|
| LiteFlowNetX[22] | 0.9M | 0.03s | - | 2000k | 4.79 |
| LiteFlowNet[22] | 5.4M | 0.09s | 0.09s | 2000k | 4.04 |
| IRR-PWC[24] | 6.4M | - | 0.20s | 850k | 3.95 |
| PWCNet+[41] | 9.4M | 0.03s | 0.04s | 1700k | 3.93 |
| VCN[49] | 6.2M | 0.18s | 0.26s | 220k(4) | 3.63 |
| FlowNet2[25] | 162M | 0.12s | 0.11s | 7000k | 3.54 |
| Ours (small) | 1.0M | - | 0.05s | 160k(2) | 3.37 |
| Ours (mixed) | 5.3M | - | 0.10s | 240k(1) | 2.85 |
| Ours | 5.3M | - | 0.10s | 200k(2) | 2.83 |
Table 4: Parameter counts, inference time, training iterations, and accuracy on the Sintel (train) final pass. We report the timing and accuracy of our method after 10 updates using a GTX 1080Ti GPU. If possible, we download the code from the other methods and re-time using our machine. If the model is trained using more than one GPU, we report the number of GPUs used to train in parenthesis. We can also train RAFT using mixed precision training Ours(mixed) and achieve similar results while training on only a single GPU. Overall, RAFT requires fewer training iterations and parameters when compared to prior work.
| 方法 | 参数量 (M) | 耗时(报告) | 耗时(1080Ti) | 训练迭代(#GPU) | 精度 |
|---|---|---|---|---|---|
| LiteFlowNetX[22] | 0.9M | 0.03s | - | 2000k | 4.79 |
| LiteFlowNet[22] | 5.4M | 0.09s | 0.09s | 2000k | 4.04 |
| IRR-PWC[24] | 6.4M | - | 0.20s | 850k | 3.95 |
| PWCNet+[41] | 9.4M | 0.03s | 0.04s | 1700k | 3.93 |
| VCN[49] | 6.2M | 0.18s | 0.26s | 220k(4) | 3.63 |
| FlowNet2[25] | 162M | 0.12s | 0.11s | 7000k | 3.54 |
| Ours (small) | 1.0M | - | 0.05s | 160k(2) | 3.37 |
| Ours (mixed) | 5.3M | - | 0.10s | 240k(1) | 2.85 |
| Ours | 5.3M | - | 0.10s | 200k(2) | 2.83 |
表 4:Sintel(train)final 通道上的参数量、推理时间、训练迭代与精度。我们报告在 GTX 1080Ti 上做 10 次更新后的耗时与精度。若可能,从其他方法下载代码并在我们的机器上重测。若模型用多于一块 GPU 训练,括号中报告所用 GPU 数。我们也可用混合精度训练 RAFT(Ours(mixed)),在单卡上取得相近结果。总体而言,相对先前工作,RAFT 所需训练迭代与参数更少。