Prioritized Experience Replay:按 TD 误差优先回放,Atari 再提一档
Prioritized Experience Replay
优先经验回放
Tom Schaul John Quan Ioannis Antonoglou David Silver Affiliation: Google DeepMind Email: {schaul,johnquan,ioannisa,davidsilver}@google.com
Abstract
摘要
Experience replay lets online reinforcement learning agents remember and reuse experiences from the past. In prior work, experience transitions were uniformly sampled from a replay memory. However, this approach simply replays transitions at the same frequency that they were originally experienced, regardless of their significance. In this paper we develop a framework for prioritizing experience, so as to replay important transitions more frequently, and therefore learn more efficiently. We use prioritized experience replay in Deep Q-Networks (DQN), a reinforcement learning algorithm that achieved human-level performance across many Atari games. DQN with prioritized experience replay achieves a new state-of-the-art, outperforming DQN with uniform replay on 41 out of 49 games.
经验回放让在线强化学习智能体记住并复用过去的经验。此前工作从回放存储器中均匀采样经验转移。然而这种做法只是按原先遭遇的频率回放,并不区分重要性。本文提出一套优先化经验的框架,使重要转移被更频繁回放,从而学得更高效。我们将优先经验回放用于深度 Q 网络(DQN)——该算法已在多款 Atari 游戏上达到人类水平。带优先经验回放的 DQN 达到新的当时最优:在 49 款游戏中有 41 款超过均匀回放的 DQN。
1 Introduction
1 引言
Online reinforcement learning (RL) agents incrementally update their parameters (of the policy, value function or model) while they observe a stream of experience. In their simplest form, they discard incoming data immediately, after a single update. Two issues with this are (a) strongly correlated updates that break the i.i.d. assumption of many popular stochastic gradient-based algorithms, and (b) the rapid forgetting of possibly rare experiences that would be useful later on.
在线强化学习(RL)智能体在观察经验流的同时增量更新参数(策略、价值函数或模型)。最简单的形式下,数据在单次更新后即被丢弃。这带来两个问题:(a) 更新高度相关,破坏许多随机梯度算法依赖的独立同分布假设;(b) 可能稀有却日后有用的经验被迅速遗忘。
Experience replay (Lin, 1992) addresses both of these issues: with experience stored in a replay memory, it becomes possible to break the temporal correlations by mixing more and less recent experience for the updates, and rare experience will be used for more than just a single update. This was demonstrated in the Deep Q-Network (DQN) algorithm (Mnih et al., 2013; Mnih et al., 2015), which stabilized the training of a value function, represented by a deep neural network, by using experience replay. Specifically, DQN used a large sliding window replay memory, sampled from it uniformly at random, and revisited each transition[^1] eight times on average. In general, experience replay can reduce the amount of experience required to learn, and replace it with more computation and more memory – which are often cheaper resources than the RL agent’s interactions with its environment.
经验回放(Lin, 1992)同时应对这两点:经验存入回放存储器后,可混合较新与较旧的经验做更新以打破时间相关,稀有经验也不再只用一次。这一点在深度 Q 网络(DQN)算法(Mnih et al., 2013; Mnih et al., 2015)中得到验证:用经验回放稳定了深度神经网络表示的价值函数训练。具体地,DQN 使用大型滑动窗口回放存储器,从中均匀随机采样,平均每条转移[^1]被重访约八次。一般而言,经验回放能减少学会所需的交互量,代之以更多计算与内存——相对智能体与环境的交互,这两者往往更便宜。
In this paper, we investigate how prioritizing which transitions are replayed can make experience replay more efficient and effective than if all transitions are replayed uniformly. The key idea is that an RL agent can learn more effectively from some transitions than from others. Transitions may be more or less surprising, redundant, or task-relevant. Some transitions may not be immediately useful to the agent, but might become so when the agent competence increases (Schmidhuber, 1991). Experience replay liberates online learning agents from processing transitions in the exact order they are experienced. Prioritized replay further liberates agents from considering transitions with the same frequency that they are experienced.
本文研究:对回放哪些转移做优先化,能否比均匀回放更高效、更有效。核心想法是:智能体从某些转移上学到的东西比从另一些更多。转移可能更令人惊讶、更冗余或更与任务相关。有些转移当下未必有用,但智能体能力提升后可能变得有用(Schmidhuber, 1991)。经验回放使在线学习智能体不必按遭遇顺序处理转移;优先回放进一步使智能体不必按遭遇频率考虑转移。
In particular, we propose to more frequently replay transitions with high expected learning progress, as measured by the magnitude of their temporal-difference (TD) error. This prioritization can lead to a loss of diversity, which we alleviate with stochastic prioritization, and introduce bias, which we correct with importance sampling. Our resulting algorithms are robust and scalable, which we demonstrate on the Atari 2600 benchmark suite, where we obtain faster learning and state-of-the-art performance.
具体地,我们主张更频繁回放预期学习进度高的转移,并用时间差分(TD)误差的幅值来度量。这种优先化可能损失多样性,我们用随机优先化缓解;同时会引入偏差,我们用重要性采样纠正。所得算法稳健且可扩展;在 Atari 2600 基准上,我们获得更快学习与当时最优表现。
2 Background
2 背景
Numerous neuroscience studies have identified evidence of experience replay in the hippocampus of rodents, suggesting that sequences of prior experience are replayed, either during awake resting or sleep. Sequences associated with rewards appear to be replayed more frequently (Atherton et al., 2015; Ólafsdóttir et al., 2015; Foster & Wilson, 2006). Experiences with high magnitude TD error also appear to be replayed more often (Singer & Frank, 2009; McNamara et al., 2014).
大量神经科学研究在啮齿类海马中发现经验回放的证据,提示先前经验序列会在清醒休息或睡眠中被重放。与奖励相关的序列似乎回放更频繁(Atherton et al., 2015; Ólafsdóttir et al., 2015; Foster & Wilson, 2006)。TD 误差幅值大的经验也似乎更常被回放(Singer & Frank, 2009; McNamara et al., 2014)。
It is well-known that planning algorithms such as value iteration can be made more efficient by prioritizing updates in an appropriate order. Prioritized sweeping (Moore & Atkeson, 1993; Andre et al., 1998) selects which state to update next, prioritized according to the change in value, if that update was executed. The TD error provides one way to measure these priorities (van Seijen & Sutton, 2013). Our approach uses a similar prioritization method, but for model-free RL rather than model-based planning. Furthermore, we use a stochastic prioritization that is more robust when learning a function approximator from samples.
众所周知,价值迭代等规划算法若按合适顺序优先更新会更高效。优先扫描(Moore & Atkeson, 1993; Andre et al., 1998)按「若执行该更新则价值变化多大」选择下一状态。TD 误差是度量这类优先级的一种方式(van Seijen & Sutton, 2013)。我们的方法用类似优先化,但面向无模型 RL 而非基于模型的规划;并且采用随机优先化,在从样本学习函数逼近时更稳健。
TD-errors have also been used as a prioritization mechanism for determining where to focus resources, for example when choosing where to explore (White et al., 2014) or which features to select (Geramifard et al., 2011; Sun et al., 2011).
TD 误差也被用作资源投放的优先机制,例如决定探索何处(White et al., 2014)或选择哪些特征(Geramifard et al., 2011; Sun et al., 2011)。
In supervised learning, there are numerous techniques to deal with imbalanced datasets when class identities are known, including re-sampling, under-sampling and over-sampling techniques, possibly combined with ensemble methods (Galar et al., 2012, for a review, see). A recent paper introduced a form of re-sampling in the context of deep RL with experience replay (Narasimhan et al., 2015); the method separates experience into two buckets, one for positive and one for negative rewards, and then picks a fixed fraction from each to replay. This is only applicable in domains that (unlike ours) have a natural notion of ‘positive/negative’ experience. Furthermore, Hinton (2007) introduced a form of non-uniform sampling based on error, with an importance sampling correction, which led to a 3x speed-up on MNIST digit classification.
在监督学习中,类别身份已知时处理不平衡数据有许多技术,包括重采样、欠采样与过采样,并可能与集成方法结合(综述见 Galar et al., 2012)。近期有工作在带经验回放的深度 RL 中引入一种重采样(Narasimhan et al., 2015):把经验分成正奖励与负奖励两个桶,再按固定比例从各桶回放。这只适用于存在自然「正/负」经验划分的领域(与我们的设定不同)。此外,Hinton (2007) 提出基于误差的非均匀采样并做重要性采样校正,在 MNIST 数字分类上带来约 3 倍加速。
There have been several proposed methods for playing Atari with deep reinforcement learning, including deep Q-networks (DQN) (Mnih et al., 2013; Mnih et al., 2015; Guo et al., 2014; Stadie et al., 2015; Nair et al., 2015; Bellemare et al., 2016), and the Double DQN algorithm (van Hasselt et al., 2016), which is the current published state-of-the-art. Simultaneously with our work, an architectural innovation that separates advantages from the value function (see the co-submission by Wang et al., 2015) has also led to substantial improvements on the Atari benchmark.
用深度强化学习打 Atari 已有多种方法,包括深度 Q 网络(DQN)(Mnih et al., 2013; Mnih et al., 2015; Guo et al., 2014; Stadie et al., 2015; Nair et al., 2015; Bellemare et al., 2016),以及当时已发表的最优 Double DQN(van Hasselt et al., 2016)。与我们同期,把优势从价值函数中分离的架构创新(见 Wang et al., 2015 的共同投稿)也在 Atari 基准上带来显著提升。
3 Prioritized Replay
3 优先回放
Using a replay memory leads to design choices at two levels: which experiences to store, and which experiences to replay (and how to do so). This paper addresses only the latter: making the most effective use of the replay memory for learning, assuming that its contents are outside of our control (but see also Section 6).
使用回放存储器涉及两层设计选择:存哪些经验,以及回放哪些经验(如何回放)。本文只讨论后者:在假定存储器内容不受我们控制的前提下,最有效地利用回放存储器来学习(另见第 6 节)。
3.1 A Motivating Example
3.1 一个启发性例子
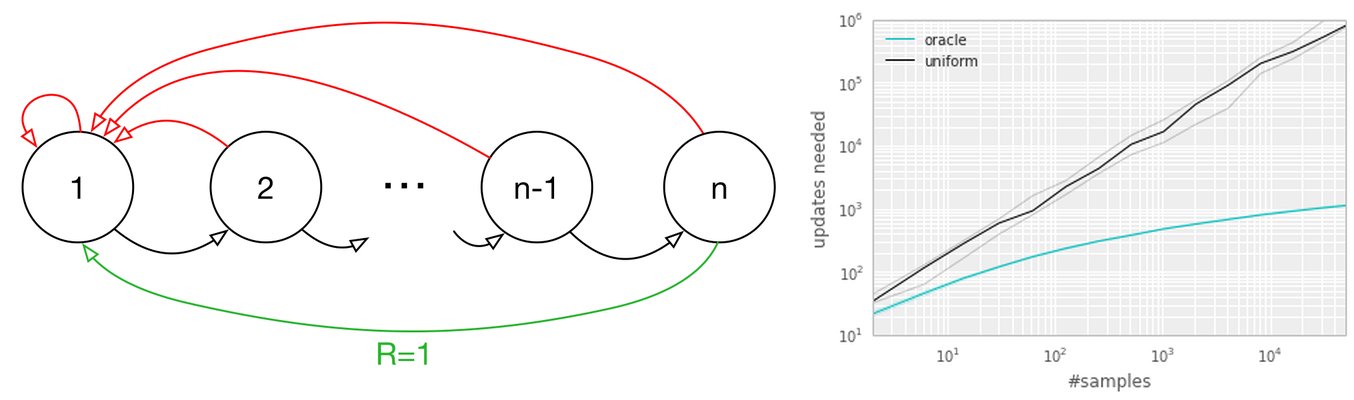
Figure 1: Left: Illustration of the ‘Blind Cliffwalk’ example domain: there are two actions, a ‘right’ and a ‘wrong’ one, and the episode is terminated whenever the agent takes the ‘wrong’ action (dashed red arrows). Taking the ‘right’ action progresses through a sequence of states (black arrows), at the end of which lies a final reward of (green arrow); reward is elsewhere. We chose a representation such that generalizing over what action is ‘right’ is not possible. Right: Median number of learning steps required to learn the value function as a function of the size of the total number of transitions in the replay memory. Note the log-log scale, which highlights the exponential speed-up from replaying with an oracle (bright blue), compared to uniform replay (black); faint lines are min/max values from 10 independent runs.
图 1:左:「盲悬崖行走」示例域示意:两个动作,一为「正确」、一为「错误」;智能体一走「错误」动作即终止(红色虚线箭头)。走「正确」动作则沿 个状态序列前进(黑色箭头),终点有奖励 1(绿色箭头);其余处奖励为 0。我们选取的表示使「哪个动作正确」无法泛化。右:学会价值函数所需学习步数中位数,相对回放存储器中转移总数。注意双对数坐标,突出用 oracle 回放(亮蓝)相对均匀回放(黑)的指数级加速;淡线为 10 次独立运行的最小/最大值。
To understand the potential gains of prioritization, we introduce an artificial ‘Blind Cliffwalk’ environment (described in Figure 1, left) that exemplifies the challenge of exploration when rewards are rare. With only states, the environment requires an exponential number of random steps until the first non-zero reward; to be precise, the chance that a random sequence of actions will lead to the reward is . Furthermore, the most relevant transitions (from rare successes) are hidden in a mass of highly redundant failure cases (similar to a bipedal robot falling over repeatedly, before it discovers how to walk).
为理解优先化的潜在收益,我们引入人工「盲悬崖行走」环境(见图 1 左),刻画奖励稀少时的探索挑战。仅有 个状态时,首次非零奖励前需要指数级随机步数;精确地说,随机动作序列碰到奖励的概率为 。此外,最相关的转移(来自稀有成功)淹没在大量高度冗余的失败案例中(类似双足机器人反复摔倒,才偶然发现如何走路)。
We use this example to highlight the difference between the learning times of two agents. Both agents perform Q-learning updates on transitions drawn from the same replay memory. The first agent replays transitions uniformly at random, while the second agent invokes an oracle to prioritize transitions. This oracle greedily selects the transition that maximally reduces the global loss in its current state (in hindsight, after the parameter update). For the details of the setup, see Appendix B.1. Figure 1 (right) shows that picking the transitions in a good order can lead to exponential speed-ups over uniform choice. Such an oracle is of course not realistic, yet the large gap motivates our search for a practical approach that improves on uniform random replay.
我们用该例子对比两个智能体的学习时间。两者都对同一回放存储器中的转移做 Q 学习更新。第一个智能体均匀随机回放;第二个调用 oracle 优先选择转移。该 oracle 贪婪地选「在当前状态下、事后看能最大幅度降低全局损失」的转移(参数更新之后)。设置细节见附录 B.1。图 1(右)表明:按好的顺序挑选转移,相对均匀选择可带来指数级加速。这样的 oracle 当然不现实,但巨大差距促使我们寻找能改进均匀随机回放的实用方法。
3.2 Prioritizing with TD-error
3.2 用 TD 误差做优先化
The central component of prioritized replay is the criterion by which the importance of each transition is measured. One idealised criterion would be the amount the RL agent can learn from a transition in its current state (expected learning progress). While this measure is not directly accessible, a reasonable proxy is the magnitude of a transition’s TD error , which indicates how ‘surprising’ or unexpected the transition is: specifically, how far the value is from its next-step bootstrap estimate (Andre et al., 1998). This is particularly suitable for incremental, online RL algorithms, such as SARSA or Q-learning, that already compute the TD-error and update the parameters in proportion to . The TD-error can be a poor estimate in some circumstances as well, e.g. when rewards are noisy; see Appendix A for a discussion of alternatives.
优先回放的核心是度量每条转移重要性的准则。理想准则是:智能体在当前状态下能从该转移学到多少(预期学习进度)。该量不可直接获得,合理代理是转移 TD 误差 的幅值,它指示转移有多「令人惊讶」或出乎意料:具体即价值距下一步自举估计有多远(Andre et al., 1998)。这对 SARSA 或 Q 学习等增量在线 RL 算法尤其合适——它们本就计算 TD 误差,并按 比例更新参数。某些情形下 TD 误差也可能是糟糕估计,例如奖励有噪声时;替代方案讨论见附录 A。
To demonstrate the potential effectiveness of prioritizing replay by TD error, we compare the uniform and oracle baselines in the Blind Cliffwalk to a ‘greedy TD-error prioritization’ algorithm. This algorithm stores the last encountered TD error along with each transition in the replay memory. The transition with the largest absolute TD error is replayed from the memory. A Q-learning update is applied to this transition, which updates the weights in proportion to the TD error. New transitions arrive without a known TD-error, so we put them at maximal priority in order to guarantee that all experience is seen at least once. Figure 2 (left), shows that this algorithm results in a substantial reduction in the effort required to solve the Blind Cliffwalk task.[^2]
为展示按 TD 误差优先回放的潜在效果,我们在盲悬崖行走上把均匀与 oracle 基线,与「贪婪 TD 误差优先化」算法对比。该算法把最近一次遇到的 TD 误差与每条转移一并存入回放存储器,回放绝对 TD 误差最大的转移,并对该转移做 Q 学习更新(按 TD 误差比例更新权重)。新转移尚无已知 TD 误差,我们赋予最大优先级,以保证所有经验至少被见一次。图 2(左)表明该算法显著减少解决盲悬崖行走所需的更新量。[^2]
Implementation: To scale to large memory sizes , we use a binary heap data structure for the priority queue, for which finding the maximum priority transition when sampling is and updating priorities (with the new TD-error after a learning step) is . See Appendix B.2.1 for more details.
实现:为扩展到大存储器规模 ,我们用二叉堆实现优先队列:采样时找最大优先级转移为 ,学习步后用新 TD 误差更新优先级为 。更多细节见附录 B.2.1。
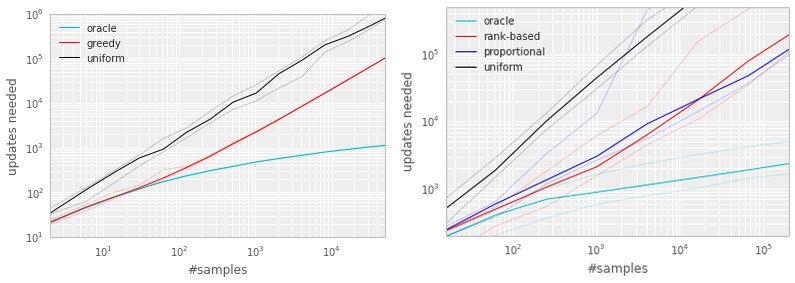
Figure 2: Median number of updates required for Q-learning to learn the value function on the Blind Cliffwalk example, as a function of the total number of transitions (only a single one of which was successful and saw the non-zero reward). Faint lines are min/max values from 10 random initializations. Black is uniform random replay, cyan uses the hindsight-oracle to select transitions, red and blue use prioritized replay (rank-based and proportional respectively). The results differ by multiple orders of magnitude, thus the need for a log-log plot. In both subplots it is evident that replaying experience in the right order makes an enormous difference to the number of updates required. See Appendix B.1 for details. Left: Tabular representation, greedy prioritization. Right: Linear function approximation, both variants of stochastic prioritization.
图 2:Q 学习在盲悬崖行走上学会价值函数所需更新次数中位数,相对转移总数(其中仅一条成功并见到非零奖励)。淡线为 10 次随机初始化的最小/最大值。黑为均匀随机回放,青为事后 oracle,红与蓝为优先回放(分别为基于秩与比例)。结果相差多个数量级,故用双对数图。两子图都清楚表明:按正确顺序回放经验,对所需更新次数影响巨大。细节见附录 B.1。左:表格表示,贪婪优先化。右:线性函数逼近,两种随机优先化变体。
3.3 Stochastic Prioritization
3.3 随机优先化
However, greedy TD-error prioritization has several issues. First, to avoid expensive sweeps over the entire replay memory, TD errors are only updated for the transitions that are replayed. One consequence is that transitions that have a low TD error on first visit may not be replayed for a long time (which means effectively never with a sliding window replay memory). Further, it is sensitive to noise spikes (e.g. when rewards are stochastic), which can be exacerbated by bootstrapping, where approximation errors appear as another source of noise. Finally, greedy prioritization focuses on a small subset of the experience: errors shrink slowly, especially when using function approximation, meaning that the initially high error transitions get replayed frequently. This lack of diversity that makes the system prone to over-fitting.
然而,贪婪 TD 误差优先化有若干问题。首先,为避免扫遍整个回放存储器的昂贵开销,TD 误差只对实际回放的转移更新。后果是:首次访问时 TD 误差低的转移可能长期不被回放(滑动窗口回放下实际等于永不)。其次,它对噪声尖峰敏感(例如随机奖励),自举会加剧这一点——逼近误差又成噪声源。最后,贪婪优先化聚焦经验的一小子集:误差收缩慢(尤其用函数逼近时),最初高误差的转移被反复回放。多样性不足使系统易过拟合。
To overcome these issues, we introduce a stochastic sampling method that interpolates between pure greedy prioritization and uniform random sampling. We ensure that the probability of being sampled is monotonic in a transition’s priority, while guaranteeing a non-zero probability even for the lowest-priority transition. Concretely, we define the probability of sampling transition as
为克服这些问题,我们引入在纯贪婪优先化与均匀随机采样之间插值的随机采样方法。我们保证被采样概率对转移优先级单调,同时即使最低优先级转移也有非零概率。具体地,定义采样转移 的概率为
where is the priority of transition . The exponent determines how much prioritization is used, with corresponding to the uniform case.
其中 为转移 的优先级。指数 决定优先化强度, 对应均匀情形。
The first variant we consider is the direct, proportional prioritization where , where is a small positive constant that prevents the edge-case of transitions not being revisited once their error is zero. The second variant is an indirect, rank-based prioritization where , where is the rank of transition when the replay memory is sorted according to . In this case, becomes a power-law distribution with exponent . Both distributions are monotonic in , but the latter is likely to be more robust, as it is insensitive to outliers. Both variants of stochastic prioritization lead to large speed-ups over the uniform baseline on the Cliffwalk task, as shown on Figure 2 (right).
我们考虑的第一变体是直接的比例优先化:, 为小正常数,避免误差为零后转移永不再访的边界情形。第二变体是间接的基于秩优先化:, 为按 排序时转移 的秩。此时 成为指数为 的幂律分布。两种分布都对 单调,后者对异常值更不敏感,可能更稳健。图 2(右)显示,两种随机优先化在悬崖行走上都相对均匀基线大幅加速。
Implementation: To efficiently sample from distribution (1), the complexity cannot depend on . For the rank-based variant, we can approximate the cumulative density function with a piecewise linear function with segments of equal probability. The segment boundaries can be precomputed (they change only when or change). At runtime, we sample a segment, and then sample uniformly among the transitions within it. This works particularly well in conjunction with a minibatch-based learning algorithm: choose to be the size of the minibatch, and sample exactly one transition from each segment – this is a form of stratified sampling that has the added advantage of balancing out the minibatch (there will always be exactly one transition with high magnitude , one with medium magnitude, etc). The proportional variant is different, also admits an efficient implementation based on a ‘sum-tree’ data structure (where every node is the sum of its children, with the priorities as the leaf nodes), which can be efficiently updated and sampled from. See Appendix B.2.1 for more additional details.
实现:要高效从分布 (1) 采样,复杂度不能依赖 。对基于秩的变体,可用 段等概率的分段线性函数逼近累积分布。段边界可预计算(仅当 或 变化时改变)。运行时先采样一段,再在段内均匀采样转移。这与基于小批量的学习算法特别合拍:取 为小批量大小,每段恰采一条——这是一种分层采样,还能平衡小批量(总有一条高 、一条中等,等等)。比例变体不同,也可用「求和树」高效实现(每个节点是其子之和,叶节点为优先级),可高效更新与采样。更多细节见附录 B.2.1。
3.4 Annealing the Bias
3.4 偏差的退火
The estimation of the expected value with stochastic updates relies on those updates corresponding to the same distribution as its expectation. Prioritized replay introduces bias because it changes this distribution in an uncontrolled fashion, and therefore changes the solution that the estimates will converge to (even if the policy and state distribution are fixed). We can correct this bias by using importance-sampling (IS) weights
用随机更新估计期望值,依赖这些更新与期望所对应的同一分布。优先回放以不受控方式改变该分布,因而引入偏差,也会改变估计最终收敛到的解(即便策略与状态分布固定)。可用重要性采样(IS)权重纠正该偏差
that fully compensates for the non-uniform probabilities if . These weights can be folded into the Q-learning update by using instead of (this is thus weighted IS, not ordinary IS, see e.g. Mahmood et al., 2014). For stability reasons, we always normalize weights by so that they only scale the update downwards.
当 时完全补偿非均匀概率 。这些权重可折进 Q 学习更新:用 代替 (因此是加权 IS,而非普通 IS,参见 Mahmood et al., 2014)。为稳定起见,我们总用 归一化权重,使它们只向下缩放更新。
In typical reinforcement learning scenarios, the unbiased nature of the updates is most important near convergence at the end of training, as the process is highly non-stationary anyway, due to changing policies, state distributions and bootstrap targets; we hypothesize that a small bias can be ignored in this context (see also Figure 12 in the appendix for a case study of full IS correction on Atari). We therefore exploit the flexibility of annealing the amount of importance-sampling correction over time, by defining a schedule on the exponent that reaches only at the end of learning. In practice, we linearly anneal from its initial value to . Note that the choice of this hyperparameter interacts with choice of prioritization exponent ; increasing both simultaneously prioritizes sampling more aggressively at the same time as correcting for it more strongly.
典型强化学习场景中,更新无偏在训练末近收敛时最重要——过程本就高度非平稳,因策略、状态分布与自举目标都在变;我们假设此情境下小偏差可忽略(附录图 12 有 Atari 上全量 IS 校正的案例)。因此我们利用对重要性采样校正量做退火的灵活性:定义指数 的日程,仅在学习结束时达到 1。实践中把 从其初值 线性退火到 1。注意该超参选择与优先化指数 相互作用:同时增大两者,会在更强力优先采样的同时更强力校正。
Importance sampling has another benefit when combined with prioritized replay in the context of non-linear function approximation (e.g. deep neural networks): here large steps can be very disruptive, because the first-order approximation of the gradient is only reliable locally, and have to be prevented with a smaller global step-size. In our approach instead, prioritization makes sure high-error transitions are seen many times, while the IS correction reduces the gradient magnitudes (and thus the effective step size in parameter space), and allowing the algorithm follow the curvature of highly non-linear optimization landscapes because the Taylor expansion is constantly re-approximated.
重要性采样与优先回放结合用于非线性函数逼近(如深度神经网络)时还有另一好处:大步长可能极具破坏性,因为梯度的一阶近似只在局部可靠,通常要用更小的全局步长来抑制。我们的做法中,优先化保证高误差转移被多次见到,同时 IS 校正减小梯度幅值(从而减小参数空间中的有效步长),并因泰勒展开被不断重新逼近,使算法能跟随高度非线性优化景观的曲率。
We combine our prioritized replay algorithm into a full-scale reinforcement learning agent, based on the state-of-the-art Double DQN algorithm. Our principal modification is to replace the uniform random sampling used by Double DQN with our stochastic prioritization and importance sampling methods (see Algorithm 1).
我们把优先回放算法并入完整规模强化学习智能体,基于当时最优的 Double DQN。主要改动是:用随机优先化与重要性采样(见算法 1)替换 Double DQN 的均匀随机采样。
1: Input: minibatch , step-size , replay period and size , exponents and , budget .
2: Initialize replay memory , ,
3: Observe and choose
4: for to do
5: Observe
6: Store transition in with maximal priority
7: if then
8: for to do
9: Sample transition
10: Compute importance-sampling weight
11: Compute TD-error
12: Update transition priority
13: Accumulate weight-change
14: end for
15: Update weights , reset
16: From time to time copy weights into target network
17: end if
18: Choose action
19: end for
Algorithm 1 Double DQN with proportional prioritization
1: 输入: 小批量 ,步长 ,回放周期 与大小 ,指数 与 ,预算 。
2: 初始化回放存储器 ,,
3: 观察 并选择
4: for to do
5: 观察
6: 以最大优先级 将转移 存入
7: if then
8: for to do
9: 按 采样转移
10: 计算重要性采样权重
11: 计算 TD 误差
12: 更新转移优先级
13: 累积权重变化
14: end for
15: 更新权重 ,重置
16: 不时把权重复制到目标网络
17: end if
18: 选择动作
19: end for
算法 1 带比例优先化的 Double DQN
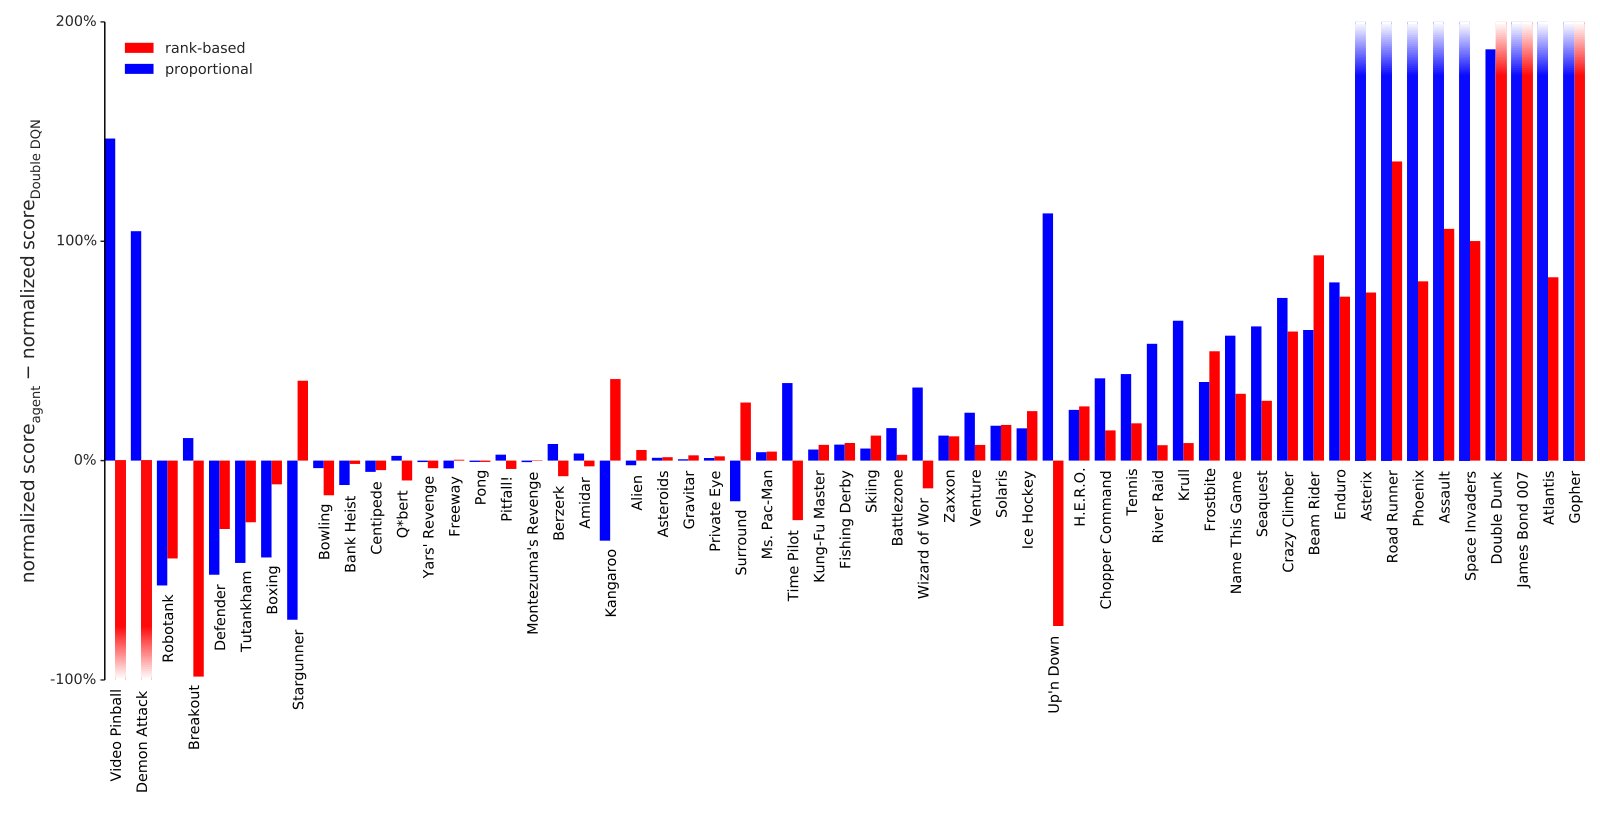
Figure 3: Difference in normalized score (the gap between random and human is ) on 57 games with human starts, comparing Double DQN with and without prioritized replay (rank-based variant in red, proportional in blue), showing substantial improvements in most games. Exact scores are in Table 6. See also Figure 9 where regular DQN is the baseline.
图 3:在 57 款游戏上、人类开局设定下,归一化分数差(随机到人类的差距为 ):比较有无优先回放的 Double DQN(红为基于秩,蓝为比例),多数游戏有显著提升。精确分数见表 6。另见图 9,以普通 DQN 为基线。
4 Atari Experiments
4 Atari 实验
With all these concepts in place, we now investigate to what extent replay with such prioritized sampling can improve performance in realistic problem domains. For this, we chose the collection of Atari benchmarks (Bellemare et al., 2012) with their end-to-end RL from vision setup, because they are popular and contain diverse sets of challenges, including delayed credit assignment, partial observability, and difficult function approximation (Mnih et al., 2015; van Hasselt et al., 2016). Our hypothesis is that prioritized replay is generally useful, so that it will make learning with experience replay more efficient without requiring careful problem-specific hyperparameter tuning.
概念齐备后,我们考察此类优先采样回放能在多大程度上改善现实问题域上的表现。为此选择 Atari 基准集合(Bellemare et al., 2012)及其端到端视觉强化学习设定:流行、挑战多样,包括延迟信用分配、部分可观测与困难的函数逼近(Mnih et al., 2015; van Hasselt et al., 2016)。我们的假设是优先回放普遍有用,因而能使带经验回放的学习更高效,而无需针对具体问题仔细调超参。
We consider two baseline algorithms that use uniform experience replay, namely the version of the DQN algorithm from the Nature paper (Mnih et al., 2015), and its recent extension Double DQN (van Hasselt et al., 2016) that substantially improved the state-of-the-art by reducing the over-estimation bias with Double Q-learning (van Hasselt, 2010). Throughout this paper we use the tuned version of the Double DQN algorithm. For this paper, the most relevant component of these baselines is the replay mechanism: all experienced transitions are stored in a sliding window memory that retains the last transitions. The algorithm processes minibatches of 32 transitions sampled uniformly from the memory. One minibatch update is done for each 4 new transitions entering the memory, so all experience is replayed 8 times on average. Rewards and TD-errors are clipped to fall within for stability reasons.
我们考虑两种使用均匀经验回放的基线算法:Nature 论文中的 DQN(Mnih et al., 2015),以及其近期扩展 Double DQN(van Hasselt et al., 2016)——后者用 Double Q-learning(van Hasselt, 2010)减轻过估计偏差,大幅抬高当时最优。全文使用调优版 Double DQN。对本工作最相关的组件是回放机制:所有经历过的转移存入滑动窗口存储器,保留最近 条。算法每次从存储器均匀采样 32 条转移的小批量。每进入 4 条新转移做一次小批量更新,故平均每条经验回放 8 次。为稳定起见,奖励与 TD 误差裁剪到 。
We use the identical neural network architecture, learning algorithm, replay memory and evaluation setup as for the baselines (see Appendix B.2). The only difference is the mechanism for sampling transitions from the replay memory, with is now done according to Algorithm 1 instead of uniformly. We compare the baselines to both variants of prioritized replay (rank-based and proportional).
我们使用与基线相同的神经网络架构、学习算法、回放存储器与评估设定(见附录 B.2)。唯一差别是从回放存储器采样转移的机制:现按算法 1 而非均匀。基线与两种优先回放变体(基于秩与比例)对比。
Only a single hyperparameter adjustment was necessary compared to the baseline: Given that prioritized replay picks high-error transitions more often, the typical gradient magnitudes are larger, so we reduced the step-size by a factor 4 compared to the (Double) DQN setup. For the and hyperparameters that are introduced by prioritization, we did a coarse grid search (evaluated on a subset of 8 games), and found the sweet spot to be , for the rank-based variant and , for the proportional variant. These choices are trading off aggressiveness with robustness, but it is easy to revert to a behavior closer to the baseline by reducing and/or increasing .
相对基线只需调整一个超参:优先回放更常挑高误差转移,典型梯度幅值更大,故相对(Double)DQN 设定把步长 缩小 4 倍。优先化引入的 与 ,我们在 8 款游戏子集上做粗网格搜索,发现甜点为:基于秩变体 、;比例变体 、。这些选择在激进与稳健间权衡;若减小 和/或增大 ,行为易回到更接近基线。
We produce the results by running each variant with a single hyperparameter setting across all games, as was done for the baselines. Our main evaluation metric is the quality of the best policy, in terms of average score per episode, given start states sampled from human traces (as introduced in Nair et al., 2015 and used in van Hasselt et al., 2016, which requires more robustness and generalization as the agent cannot rely on repeating a single memorized trajectory). These results are summarized in Table 1 and Figure 3, but full results and raw scores can be found in Tables 7 and 6 in the Appendix. A secondary metric is the learning speed, which we summarize on Figure 4, with more detailed learning curves on Figures 7 and 8.
与基线一样,各变体在全部游戏上用单一超参设置跑结果。主评估指标是最佳策略质量:以人类轨迹采样的开局状态下平均每局得分(Nair et al., 2015 引入,van Hasselt et al., 2016 使用;要求更强稳健性与泛化,因智能体不能靠重复一条死记硬背轨迹)。结果汇总于表 1 与图 3,完整结果与原始分数见附录表 7 与表 6。次要指标是学习速度,汇总于图 4,更细学习曲线见图 7 与图 8。
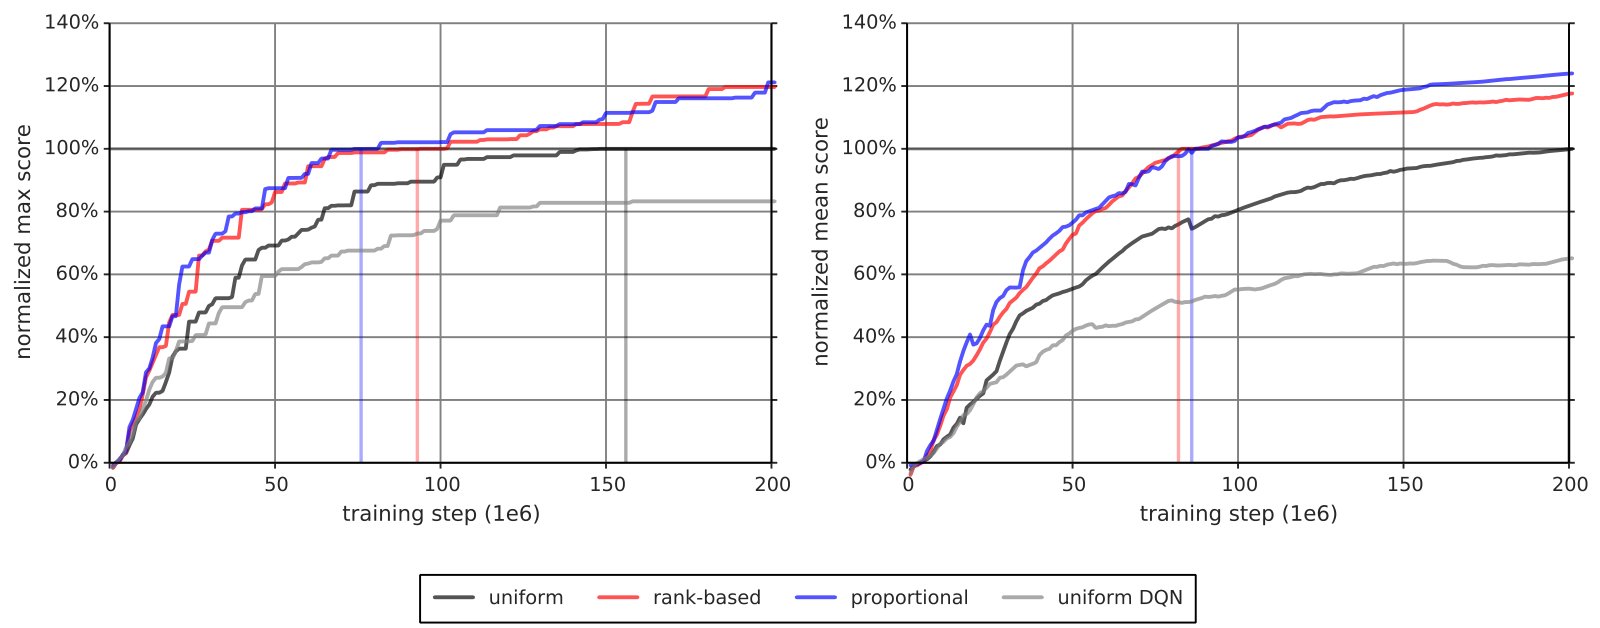
Figure 4: Summary plots of learning speed. Left: median over 57 games of the maximum baseline-normalized score achieved so far. The baseline-normalized score is calculated as in Equation 4 but using the maximum Double DQN score seen across training is used instead of the human score. The equivalence points are highlighted with dashed lines; those are the steps at which the curves reach 100%, (i.e., when the algorithm performs equivalently to Double DQN in terms of median over games). For rank-based and proportional prioritization these are at 47% and 38% of total training time. Right: Similar to the left, but using the mean instead of maximum, which captures cumulative performance rather than peak performance. Here rank-based and proportional prioritization reach the equivalence points at 41% and 43% of total training time, respectively. For the detailed learning curves that these plots summarize, see Figure 7.
图 4:学习速度汇总图。左:57 款游戏上「迄今最大基线归一化分数」的中位数。基线归一化分数按式 (4) 计算,但用人分换成训练中见过的最大 Double DQN 分数。虚线标出等价点:曲线达到 100% 的步数(即算法在游戏中位数上与 Double DQN 相当)。基于秩与比例优先化分别在总训练时间的 47% 与 38% 达到。右:类似左侧,但用均值代替最大值,刻画累积表现而非峰值。此处基于秩与比例分别在 41% 与 43% 总训练时间达到等价点。这些图所汇总的细学习曲线见图 7。
DQN Double DQN (tuned) baseline rank-based baseline rank-based proportional Median 48% 106% 111% 113% 128% Mean 122% 355% 418% 454% 551% baseline – 41 – 38 42 human 15 25 30 33 33 # games 49 49 57 57 57
Table 1: Summary of normalized scores. See Table 6 in the appendix for full results.
DQN 调优 Double DQN 基线 基于秩 基线 基于秩 比例 中位数 48% 106% 111% 113% 128% 均值 122% 355% 418% 454% 551% 基线 – 41 – 38 42 人类 15 25 30 33 33 游戏数 49 49 57 57 57
表 1:归一化分数汇总。完整结果见附录表 6。
We find that adding prioritized replay to DQN leads to a substantial improvement in score on 41 out of 49 games (compare columns 2 and 3 of Table 6 or Figure 9 in the appendix), with the median normalized performance across 49 games increasing from to . Furthermore, we find that the boost from prioritized experience replay is complementary to the one from introducing Double Q-learning into DQN: performance increases another notch, leading to the current state-of-the-art on the Atari benchmark (see Figure 3). Compared to Double DQN, the median performance across 57 games increased from to , and the mean performance from to bringing additional games such as River Raid, Seaquest and Surround to a human level for the first time, and making large jumps on others (e.g. Gopher, James Bond 007 or Space Invaders). Note that mean performance is not a very reliable metric because a single game (Video Pinball) has a dominant contribution. Prioritizing replay gives a performance boost on almost all games, and on aggregate, learning is twice as fast (see Figures 4 and 8). The learning curves on Figure 7 illustrate that while the two variants of prioritization usually lead to similar results, there are games where one of them remains close to the Double DQN baseline while the other one leads to a big boost, for example Double Dunk or Surround for the rank-based variant, and Alien, Asterix, Enduro, Phoenix or Space Invaders for the proportional variant. Another observation from the learning curves is that compared to the uniform baseline, prioritization is effective at reducing the delay until performance gets off the ground in games that otherwise suffer from such a delay, such as Battlezone, Zaxxon or Frostbite.
我们发现:给 DQN 加上优先回放,在 49 款游戏中有 41 款分数显著提升(对照表 6 第 2、3 列或附录图 9),49 款游戏归一化表现中位数从 48% 升至 106%。进一步发现,优先经验回放带来的提升与把 Double Q-learning 引入 DQN 的提升互补:表现再上一档,成为当时 Atari 基准最优(见图 3)。相对 Double DQN,57 款游戏中位数从 111% 升至 128%,均值从 418% 升至 551%,首次把 River Raid、Seaquest、Surround 等带到人类水平,并在另一些游戏上大幅跃升(如 Gopher、James Bond 007、Space Invaders)。注意均值不是很可靠的指标,因单款游戏(Video Pinball)贡献过大。优先回放几乎在所有游戏上带来提升,总体学习约快一倍(见图 4 与图 8)。图 7 的学习曲线说明:两种优先化变体通常结果相近,但也有游戏一种仍贴近 Double DQN 基线、另一种大幅提升——例如基于秩在 Double Dunk、Surround,比例在 Alien、Asterix、Enduro、Phoenix、Space Invaders。另一观察是:相对均匀基线,优先化能有效缩短那些否则起飞很慢的游戏中「表现迟迟起不来」的延迟,如 Battlezone、Zaxxon、Frostbite。
5 Discussion
5 讨论
In the head-to-head comparison between rank-based prioritization and proportional prioritization, we expected the rank-based variant to be more robust because it is not affected by outliers nor error magnitudes. Furthermore, its heavy-tail property also guarantees that samples will be diverse, and the stratified sampling from partitions of different errors will keep the total minibatch gradient at a stable magnitude throughout training. On the other hand, the ranks make the algorithm blind to the relative error scales, which could incur a performance drop when there is structure in the distribution of errors to be exploited, such as in sparse reward scenarios. Perhaps surprisingly, both variants perform similarly in practice; we suspect this is due to the heavy use of clipping (of rewards and TD-errors) in the DQN algorithm, which removes outliers. Monitoring the distribution of TD-errors as a function of time for a number of games (see Figure 10 in the appendix), and found that it becomes close to a heavy-tailed distribution as learning progresses, while still differing substantially across games; this empirically validates the form of Equation 1. Figure 11, in the appendix, shows how this distribution interacts with Equation 1 to produce the effective replay probabilities.
在基于秩与比例优先化的头对头比较中,我们预期基于秩更稳健:不受异常值与误差幅值影响;其重尾性质也保证样本多样,且按不同误差分区的分层采样能在训练全程把小批量总梯度幅值保持稳定。另一方面,秩使算法对相对误差尺度「看不见」,当误差分布有可利用结构(如稀疏奖励)时可能掉点。或许出人意料,实践中两变体表现相近;我们怀疑这是因为 DQN 大量使用裁剪(奖励与 TD 误差),去掉了异常值。我们监控若干游戏上 TD 误差分布随时间的变化(见附录图 10),发现随学习推进它接近重尾分布,同时各游戏间仍差异很大;这从经验上验证了式 (1) 的形式。附录图 11 展示该分布如何与式 (1) 相互作用,产生有效回放概率。
While doing this analysis, we stumbled upon another phenomenon (obvious in retrospect), namely that some fraction of the visited transitions are never replayed before they drop out of the sliding window memory, and many more are replayed for the first time only long after they are encountered. Also, uniform sampling is implicitly biased toward out-of-date transitions that were generated by a policy that has typically seen hundreds of thousands of updates since. Prioritized replay with its bonus for unseen transitions directly corrects the first of these issues, and also tends to help with the second one, as more recent transitions tend to have larger error – this is because old transitions will have had more opportunities to have them corrected, and because novel data tends to be less well predicted by the value function.
做该分析时,我们还撞上另一现象(事后看很显然):一部分访问过的转移在滑出滑动窗口存储器前从未被回放,更多转移则在遭遇很久之后才首次回放。均匀采样也隐式偏向过时转移——产生它们的策略通常已经过数十万次更新。带「未见转移加分」的优先回放直接纠正第一点,也往往有助于第二点:更新近的转移误差通常更大——因为旧转移有更多机会被纠正,且新数据往往更难被价值函数预测准。
We hypothesize that deep neural networks interact with prioritized replay in another interesting way. When we distinguish learning the value given a representation (i.e., the top layers) from learning an improved representation (i.e., the bottom layers), then transitions for which the representation is good will quickly reduce their error and then be replayed much less, increasing the learning focus on others where the representation is poor, thus putting more resources into distinguishing aliased states – if the observations and network capacity allow for it.
我们假设深度神经网络与优先回放还有另一有趣交互。若区分「给定表示学价值」(上层)与「学更好表示」(下层),则表示已经良好的转移会迅速缩小误差并较少被回放,学习焦点转向表示仍差的转移,从而把更多资源用于区分混淆状态——前提是观测与网络容量允许。
6 Extensions
6 扩展
Prioritized Supervised Learning: The analogous approach to prioritized replay in the context of supervised learning is to sample non-uniformly from the dataset, each sample using a priority based on its last-seen error. This can help focus the learning on those samples that can still be learned from, devoting additional resources to the (hard) boundary cases, somewhat similarly to boosting (Galar et al., 2012). Furthermore, if the dataset is imbalanced, we hypothesize that samples from the rare classes will be sampled disproportionately often, because their errors shrink less fast, and the chosen samples from the common classes will be those nearest to the decision boundaries, leading to an effect similar to hard negative mining (Felzenszwalb et al., 2008). To check whether these intuitions hold, we conducted a preliminary experiment on a class-imbalanced variant of the classical MNIST digit classification problem (LeCun et al., 1998), where we removed of the samples for digits in the training set, while leaving the test/validation sets untouched (i.e., those retain class balance). We compare two scenarios: in the informed case, we reweight the errors of the impoverished classes artificially (by a factor ), in the uninformed scenario, we provide no hint that the test distribution will differ from the training distribution. See Appendix B.3 for the details of the convolutional neural network training setup. Prioritized sampling (uninformed, with , ) outperforms the uninformed uniform baseline, and approaches the performance of the informed uniform baseline in terms of generalization (see Figure 5); again, prioritized training is also faster in terms of learning speed.
优先监督学习:监督学习情境下与优先回放类似的做法,是按上次见到的误差给样本定优先级,再非均匀采样数据集。这有助于把学习焦点放在仍能学到东西的样本上,把额外资源投向(困难的)边界案例,有点像提升(Galar et al., 2012)。进一步,若数据集不平衡,我们假设稀有类样本会被不成比例地更常采样——因其误差收缩更慢;常见类中被选中的则多靠近决策边界,效果类似难负例挖掘(Felzenszwalb et al., 2008)。为检验这些直觉,我们在经典 MNIST 数字分类(LeCun et al., 1998)的类别不平衡变体上做了初步实验:训练集中去掉数字 0–4 的 99% 样本,测试/验证集保持不动(仍类别平衡)。比较两种情形:知情情形下人为把稀缺类误差加权(因子 100);不知情情形不提示测试分布会不同于训练。卷积网络训练细节见附录 B.3。优先采样(不知情,,)超过不知情均匀基线,泛化上接近知情均匀基线(见图 5);优先训练在学习速度上也更快。
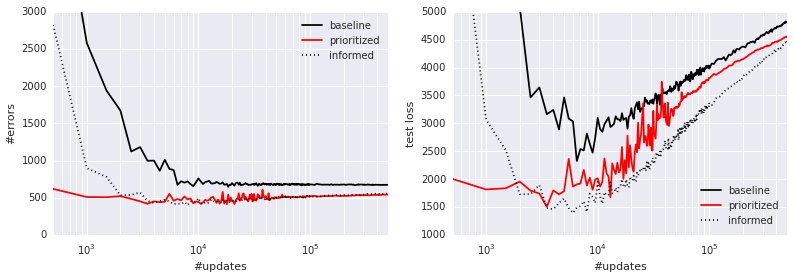
Figure 5: Classification errors as a function of supervised learning updates on severely class-imbalanced MNIST. Prioritized sampling improves performance, leading to comparable errors on the test set, and approaching the imbalance-informed performance (median of 3 random initializations). Left: Number of misclassified test set samples. Right: Test set loss, highlighting overfitting.
图 5:严重类别不平衡 MNIST 上,分类误差随监督学习更新次数变化。优先采样改善表现,使测试集误差可比,并接近「已知不平衡」时的表现(3 次随机初始化的中位数)。左:测试集误分类样本数。右:测试集损失,突出过拟合。
Off-policy Replay: Two standard approaches to off-policy RL are rejection sampling and using importance sampling ratios to correct for how likely a transition would have been on-policy. Our approach contains analogues to both these approaches, the replay probability and the IS-correction . It appears therefore natural to apply it to off-policy RL, if transitions are available in a replay memory. In particular, we recover weighted IS with , , and rejection sampling with , , , in the proportional variant. Our experiments indicate that intermediate variants, possibly with annealing or ranking, could be more useful in practice – especially when IS ratios introduce high variance, i.e., when the policy of interest differs substantially from the behavior policy in some states. Of course, off-policy correction is complementary to our prioritization based on expected learning progress, and the same framework can be used for a hybrid prioritization by defining , or some other sensible trade-off based on both and .
异策略回放:异策略 RL 的两种标准做法是拒绝采样,以及用重要性采样比 校正转移在策略上出现的可能性。我们的方法对两者都有对应物:回放概率 与 IS 校正 。因此,若回放存储器中已有转移,把它用到异策略 RL 似乎很自然。特别地,比例变体下:取 、、 即恢复加权 IS;取 、、 即拒绝采样。实验表明中间变体——可能带退火或排序——实践中可能更有用,尤其当 IS 比引入高方差时,即目标策略与行为策略在某些状态上差很多时。当然,异策略校正与基于预期学习进度的优先化互补;同一框架也可做混合优先化,例如定义 ,或其他同时基于 与 的合理折中。
Feedback for Exploration: An interesting side-effect of prioritized replay is that the total number that a transition will end up being replayed varies widely, and this gives a rough indication of how useful it was to the agent. This potentially valuable signal can be fed back to the exploration strategy that generates the transitions. For example, we could sample exploration hyperparameters (such as the fraction of random actions , the Boltzmann temperature, or the amount of of intrinsic reward to mix in) from a parametrized distribution at the beginning of each episode, monitor the usefulness of the experience via , and update the distribution toward generating more useful experience. Or, in a parallel system like the Gorila agent (Nair et al., 2015), it could guide resource allocation between a collection of concurrent but heterogeneous ‘actors’, each with different exploration hyperparameters.
探索反馈:优先回放的一个有趣副作用是:转移最终被回放的总次数 差异很大,这粗略指示它对智能体有多有用。这一潜在有价值信号可反馈给产生转移的探索策略。例如,可在每局开始时从参数化分布采样探索超参(如随机动作比例 、Boltzmann 温度、或混入的内在奖励量),用 监控经验有用性,再更新分布以产生更有用经验。或者,在像 Gorila 智能体(Nair et al., 2015)这样的并行系统中,它可指导一组并发但异构「执行器」之间的资源分配,各执行器探索超参不同。
Prioritized Memories: Considerations that help determine which transitions to replay are likely to also be relevant for determining which memories to store and when to erase them (e.g. when it becomes likely that they will never be replayed anymore). An explicit control over which memories to keep or erase can help reduce the required total memory size, because it reduces redundancy (frequently visited transitions will have low error, so many of them will be dropped), while automatically adjusting for what has been learned already (dropping many of the ‘easy’ transitions) and biasing the contents of the memory to where the errors remain high. This is a non-trivial aspect, because memory requirements for DQN are currently dominated by the size of the replay memory, no longer by the size of the neural network. Erasing is a more final decision than reducing the replay probability, thus an even stronger emphasis of diversity may be necessary, for example by tracking the age of each transitions and using it to modulate the priority in such a way as to preserve sufficient old experience to prevent cycles (Rosin & Belew, 1997, related to ‘hall of fame’ ideas in multi-agent literature,). The priority mechanism is also flexible enough to permit integrating experience from other sources, such as from a planner or from human expert trajectories (Guo et al., 2014), since knowing the source can be used to modulate each transition’s priority, e.g. in such a way as to preserve a sufficient fraction of external experience in memory.
优先记忆:有助于决定回放哪些转移的考量,多半也与决定存哪些记忆、何时擦除相关(例如当某条记忆很可能再也不会被回放)。对保留或擦除的显式控制有助于减小所需总内存:它降低冗余(频繁访问的转移误差低,许多会被丢掉),同时自动按「已学到什么」调整(丢掉许多「容易」转移),并把存储器内容偏向误差仍高之处。这点非平凡,因为 DQN 的内存需求目前由回放存储器主导,而不再由神经网络大小主导。擦除比降低回放概率更「终局」,因而可能更需要强调多样性,例如跟踪每条转移的年龄并用它调制优先级,以保留足够旧经验、防止循环(Rosin & Belew, 1997;与多智能体文献中的「名人堂」想法相关)。优先级机制也足够灵活,可整合其他来源的经验,如规划器或人类专家轨迹(Guo et al., 2014),因知道来源可用于调制各转移优先级,例如保证存储器中外部经验保持足够比例。
7 Conclusion
7 结论
This paper introduced prioritized replay, a method that can make learning from experience replay more efficient. We studied a couple of variants, devised implementations that scale to large replay memories, and found that prioritized replay speeds up learning by a factor 2 and leads to a new state-of-the-art of performance on the Atari benchmark. We laid out further variants and extensions that hold promise, namely for class-imbalanced supervised learning.
本文引入优先回放:一种使从经验回放中学习更高效的方法。我们研究了若干变体,设计了可扩展到大型回放存储器的实现,发现优先回放使学习加速约 2 倍,并在 Atari 基准上达到新的当时最优。我们还勾勒了更多有前景的变体与扩展,包括面向类别不平衡的监督学习。
Acknowledgments
We thank our Deepmind colleagues, in particular Hado van Hasselt, Joseph Modayil, Nicolas Heess, Marc Bellemare, Razvan Pascanu, Dharshan Kumaran, Daan Wierstra, Arthur Guez, Charles Blundell, Alex Pritzel, Alex Graves, Balaji Lakshminarayanan, Ziyu Wang, Nando de Freitas, Remi Munos and Geoff Hinton for insightful discussions and feedback.
致谢
感谢 DeepMind 同事,尤其是 Hado van Hasselt、Joseph Modayil、Nicolas Heess、Marc Bellemare、Razvan Pascanu、Dharshan Kumaran、Daan Wierstra、Arthur Guez、Charles Blundell、Alex Pritzel、Alex Graves、Balaji Lakshminarayanan、Ziyu Wang、Nando de Freitas、Remi Munos 与 Geoff Hinton 的深入讨论与反馈。
References
参考文献
Andre et al. (1998) Andre, David, Friedman, Nir, and Parr, Ronald. Generalized prioritized sweeping. In Advances in Neural Information Processing Systems . Citeseer, 1998.
Atherton et al. (2015) Atherton, Laura A, Dupret, David, and Mellor, Jack R. Memory trace replay: the shaping of memory consolidation by neuromodulation. Trends in neurosciences , 38(9):560–570, 2015.
Bellemare et al. (2012) Bellemare, Marc G, Naddaf, Yavar, Veness, Joel, and Bowling, Michael. The arcade learning environment: An evaluation platform for general agents. arXiv preprint arXiv:1207.4708 , 2012.
Bellemare et al. (2016) Bellemare, Marc G., Ostrovski, Georg, Guez, Arthur, Thomas, Philip S., and Munos, Rémi. Increasing the action gap: New operators for reinforcement learning. In Proceedings of the AAAI Conference on Artificial Intelligence , 2016. URL http://arxiv.org/abs/1512.04860 .
Collobert et al. (2011) Collobert, Ronan, Kavukcuoglu, Koray, and Farabet, Clément. Torch7: A matlab-like environment for machine learning. In BigLearn, NIPS Workshop , number EPFL-CONF-192376, 2011.
Diamond (1994) Diamond, Jared. Zebras and the Anna Karenina principle. Natural History , 103:4–4, 1994.
Felzenszwalb et al. (2008) Felzenszwalb, Pedro, McAllester, David, and Ramanan, Deva. A discriminatively trained, multiscale, deformable part model. In Computer Vision and Pattern Recognition, 2008. CVPR 2008. IEEE Conference on , pp. 1–8. IEEE, 2008.
Foster & Wilson (2006) Foster, David J and Wilson, Matthew A. Reverse replay of behavioural sequences in hippocampal place cells during the awake state. Nature , 440(7084):680–683, 2006.
Galar et al. (2012) Galar, Mikel, Fernandez, Alberto, Barrenechea, Edurne, Bustince, Humberto, and Herrera, Francisco. A review on ensembles for the class imbalance problem: bagging-, boosting-, and hybrid-based approaches. Systems, Man, and Cybernetics, Part C: Applications and Reviews, IEEE Transactions on , 42(4):463–484, 2012.
Geramifard et al. (2011) Geramifard, Alborz, Doshi, Finale, Redding, Joshua, Roy, Nicholas, and How, Jonathan. Online discovery of feature dependencies. In Proceedings of the 28th International Conference on Machine Learning (ICML-11) , pp. 881–888, 2011.
Guo et al. (2014) Guo, Xiaoxiao, Singh, Satinder, Lee, Honglak, Lewis, Richard L, and Wang, Xiaoshi. Deep Learning for Real-Time Atari Game Play Using Offline Monte-Carlo Tree Search Planning. In Ghahramani, Z., Welling, M., Cortes, C., Lawrence, N.D., and Weinberger, K.Q. (eds.), Advances in Neural Information Processing Systems 27 , pp. 3338–3346. Curran Associates, Inc., 2014.
Hinton (2007) Hinton, Geoffrey E. To recognize shapes, first learn to generate images. Progress in brain research , 165:535–547, 2007.
Kingma & Ba (2014) Kingma, Diederik P. and Ba, Jimmy. Adam: A method for stochastic optimization. CoRR , abs/1412.6980, 2014.
Lecun et al. (1998) Lecun, Y., Bottou, L., Bengio, Y., and Haffner, P. Gradient-based learning applied to document recognition. Proceedings of the IEEE , 86(11):2278–2324, Nov 1998. ISSN 0018-9219. doi: 10.1109/5.726791 .
LeCun et al. (1998) LeCun, Yann, Cortes, Corinna, and Burges, Christopher JC. The MNIST database of handwritten digits, 1998.
Lin (1992) Lin, Long-Ji. Self-improving reactive agents based on reinforcement learning, planning and teaching. Machine learning , 8(3-4):293–321, 1992.
Mahmood et al. (2014) Mahmood, A Rupam, van Hasselt, Hado P, and Sutton, Richard S. Weighted importance sampling for off-policy learning with linear function approximation. In Advances in Neural Information Processing Systems , pp. 3014–3022, 2014.
McNamara et al. (2014) McNamara, Colin G, Tejero-Cantero, Álvaro, Trouche, Stéphanie, Campo-Urriza, Natalia, and Dupret, David. Dopaminergic neurons promote hippocampal reactivation and spatial memory persistence. Nature neuroscience , 2014.
Mnih et al. (2013) Mnih, Volodymyr, Kavukcuoglu, Koray, Silver, David, Graves, Alex, Antonoglou, Ioannis, Wierstra, Daan, and Riedmiller, Martin. Playing atari with deep reinforcement learning. arXiv preprint arXiv:1312.5602 , 2013.
Mnih et al. (2015) Mnih, Volodymyr, Kavukcuoglu, Koray, Silver, David, Rusu, Andrei A, Veness, Joel, Bellemare, Marc G, Graves, Alex, Riedmiller, Martin, Fidjeland, Andreas K, Ostrovski, Georg, Petersen, Stig, Beattie, Charles, Sadik, Amir, Antonoglou, Ioannis, King, Helen, Kumaran, Dharshan, Wierstra, Daan, Legg, Shane, and Hassabis, Demis. Human-level control through deep reinforcement learning. Nature , 518(7540):529–533, 2015.
Moore & Atkeson (1993) Moore, Andrew W and Atkeson, Christopher G. Prioritized sweeping: Reinforcement learning with less data and less time. Machine Learning , 13(1):103–130, 1993.
Nair et al. (2015) Nair, Arun, Srinivasan, Praveen, Blackwell, Sam, Alcicek, Cagdas, Fearon, Rory, Maria, Alessandro De, Panneershelvam, Vedavyas, Suleyman, Mustafa, Beattie, Charles, Petersen, Stig, Legg, Shane, Mnih, Volodymyr, Kavukcuoglu, Koray, and Silver, David. Massively parallel methods for deep reinforcement learning. arXiv preprint arXiv:1507.04296 , 2015.
Narasimhan et al. (2015) Narasimhan, Karthik, Kulkarni, Tejas, and Barzilay, Regina. Language understanding for text-based games using deep reinforcement learning. In Conference on Empirical Methods in Natural Language Processing (EMNLP) , 2015.
Ólafsdóttir et al. (2015) Ólafsdóttir, H Freyja, Barry, Caswell, Saleem, Aman B, Hassabis, Demis, and Spiers, Hugo J. Hippocampal place cells construct reward related sequences through unexplored space. Elife , 4:e06063, 2015.
Riedmiller (1994) Riedmiller, Martin. Rprop-description and implementation details. 1994.
Rosin & Belew (1997) Rosin, Christopher D and Belew, Richard K. New methods for competitive coevolution. Evolutionary Computation , 5(1):1–29, 1997.
Schaul et al. (2013) Schaul, Tom, Zhang, Sixin, and Lecun, Yann. No more pesky learning rates. In Proceedings of the 30th International Conference on Machine Learning (ICML-13) , pp. 343–351, 2013.
Schmidhuber (1991) Schmidhuber, Jürgen. Curious model-building control systems. In Neural Networks, 1991. 1991 IEEE International Joint Conference on , pp. 1458–1463. IEEE, 1991.
Singer & Frank (2009) Singer, Annabelle C and Frank, Loren M. Rewarded outcomes enhance reactivation of experience in the hippocampus. Neuron , 64(6):910–921, 2009.
Stadie et al. (2015) Stadie, Bradly C, Levine, Sergey, and Abbeel, Pieter. Incentivizing exploration in reinforcement learning with deep predictive models. arXiv preprint arXiv:1507.00814 , 2015.
Sun et al. (2011) Sun, Yi, Ring, Mark, Schmidhuber, Jürgen, and Gomez, Faustino J. Incremental basis construction from temporal difference error. In Proceedings of the 28th International Conference on Machine Learning (ICML-11) , pp. 481–488, 2011.
van Hasselt (2010) van Hasselt, Hado. Double Q-learning. In Advances in Neural Information Processing Systems , pp. 2613–2621, 2010.
van Hasselt et al. (2016) van Hasselt, Hado, Guez, Arthur, and Silver, David. Deep Reinforcement Learning with Double Q-learning. In Proceedings of the Thirtieth AAAI Conference on Artificial Intelligence , 2016. URL http://arxiv.org/abs/1509.06461 .
van Seijen & Sutton (2013) van Seijen, Harm and Sutton, Richard. Planning by prioritized sweeping with small backups. In Proceedings of The 30th International Conference on Machine Learning , pp. 361–369, 2013.
Wang et al. (2015) Wang, Z., de Freitas, N., and Lanctot, M. Dueling network architectures for deep reinforcement learning. Technical report, 2015. URL http://arxiv.org/abs/1511.06581 .
Watkins & Dayan (1992) Watkins, Christopher JCH and Dayan, Peter. Q-learning. Machine learning , 8(3-4):279–292, 1992.
White et al. (2014) White, Adam, Modayil, Joseph, and Sutton, Richard S. Surprise and curiosity for big data robotics. In Workshops at the Twenty-Eighth AAAI Conference on Artificial Intelligence , 2014.
Appendix A Prioritization Variants
附录 A 优先化变体
The absolute TD-error is only one possible proxy for the ideal priority measure of expected learning progress. While it captures the scale of potential improvement, it ignores inherent stochasticity in rewards or transitions, as well as possible limitations from partial observability or FA capacity; in other words, it is problematic when there are unlearnable transitions. In that case, its derivative – which could be approximated by the difference between a transition’s current and the when it was last replayed[^3] – may be more useful. This measure is less immediately available, however, and is influenced by whatever was replayed in the meanwhile, which increases its variance. In preliminary experiments, we found it did not outperform , but this may say more about the class of (near-deterministic) environments we investigated, than about the measure itself.
绝对 TD 误差只是理想优先级度量(预期学习进度)的一种可能代理。它捕获潜在改进的尺度,却忽略奖励或转移中的固有随机性,以及部分可观测或函数逼近容量带来的限制;换言之,存在不可学习转移时会有问题。此时其导数——可用转移当前 与上次回放时 之差近似[^3]——可能更有用。该度量更不易直接获得,且受其间回放内容影响,方差更大。初步实验中它未超过 ,但这或许更多说明我们考察的(近确定性)环境类别,而非度量本身。
An orthogonal variant is to consider the norm of the weight-change induced by replaying a transition – this can be effective if the underlying optimizer employs adaptive step-sizes that reduce gradients in high-noise directions (Schaul et al., 2013; Kingma & Ba, 2014), thus placing the burden of distinguishing between learnable and unlearnable transitions on the optimizer.
一个正交变体是考虑回放一条转移所引起的权重变化范数——若底层优化器采用自适应步长、在高噪声方向减小梯度(Schaul et al., 2013; Kingma & Ba, 2014),这会有效,从而把区分可学习与不可学习转移的负担交给优化器。
It is possible to modulate prioritization by not treating positive TD-errors the same than negative ones; we can for example invoke the Anna Karenina principle (Diamond, 1994), interpreted to mean that there are many ways in which a transition can be less good than expected, but only one in which can be better, to introduce an asymmetry and prioritize positive TD-errors more than negative ones of equal magnitude, because the former are more likely to be informative. Such an asymmetry in replay frequency was also observed in rat studies (Singer & Frank, 2009). Again, our preliminary experiments with such variants were inconclusive.
也可以不把正、负 TD 误差一视同仁来调制优先化;例如可援引安娜·卡列尼娜原则(Diamond, 1994)——解读为:转移比预期差的方式很多,比预期好的方式只有一种——引入不对称,对同等幅值的正 TD 误差优先于负,因前者更可能信息量大。大鼠研究中也观察到回放频率的这种不对称(Singer & Frank, 2009)。同样,我们对此类变体的初步实验尚无定论。
The evidence from neuroscience suggest that a prioritization based on episodic return rather than expected learning progress may be useful too Atherton et al. (2015); Ólafsdóttir et al. (2015); Foster & Wilson (2006). For this case, we could boost the replay probabilities of entire episodes, instead of transitions, or boost individual transitions by their observed return-to-go (or even their value estimates).
神经科学证据提示:基于回合回报而非预期学习进度的优先化也可能有用 Atherton et al. (2015); Ólafsdóttir et al. (2015); Foster & Wilson (2006)。此时可提升整个回合而非单条转移的回放概率,或按观测到的回报至终点(甚至价值估计)提升单条转移。
For the issue of preserving sufficient diversity (to prevent overfitting, premature convergence or impoverished representations), there are alternative solutions to our choice of introducing stochasticity, for example, the priorities could be modulated by a novelty measure in observation space. Nothing prevents a hybrid approach where some fraction of the elements (of each minibatch) are sampled according to one priority measure and the rest according to another one, introducing additional diversity. An orthogonal idea is to increase priorities of transitions that have not been replayed for a while, by introducing an explicit staleness bonus that guarantees that every transition is revisited from time to time, with that chance increasing at the same rate as its last-seen TD-error becomes stale. In the simple case where this bonus grows linearly with time, this can be implemented at no additional cost by subtracting a quantity proportional to the global step-count from the new priority on any update.[^4]
关于保持足够多样性(防止过拟合、过早收敛或表示贫乏),除引入随机性外还有替代方案,例如用观测空间中的新颖性度量调制优先级。也不妨采用混合:小批量中一部分元素按一种优先级度量采样,其余按另一种,以增加多样性。一个正交想法是:对一段时间未回放的转移提高优先级,引入显式陈旧加分,保证每条转移偶尔被重访,且该概率随其上次 TD 误差变旧而增大。若该加分随时间线性增长,则可在任意更新时从新优先级中减去与全局步数成比例的量,无需额外开销实现。[^4]
In the particular case of RL with bootstrapping from value functions, it is possible to exploit the sequential structure of the replay memory using the following intuition: a transition that led to a large amount of learning (about its outgoing state) has the potential to change the bootstrapping target for all transitions leading into that state, and thus there is more to be learned about these. Of course we know at least one of these, namely the historic predecessor transition, and so boosting its priority makes it more likely to be revisited soon. Similarly to eligibility traces, this lets information trickle backward from a future outcome to the value estimates of the actions and states that led to it. In practice, we add of the current transition to predecessor transition’s priority, but only if the predecessor transition is not a terminal one. This idea is related to ‘reverse replay’ observed in rodents Foster & Wilson (2006), and to a recent extension of prioritized sweeping (van Seijen & Sutton, 2013).
在从价值函数自举的 RL 特例中,可利用回放存储器的序列结构,直觉如下:导致(关于其出边状态)大量学习的转移,有可能改变所有进入该状态的转移的自举目标,因而关于这些转移还有更多可学。我们至少知道其中一条,即历史上的前驱转移,提高其优先级使其更可能很快被重访。类似资格迹,这让信息从未来结果反向渗到导致它的动作与状态的价值估计。实践中,我们把当前转移的 加到前驱转移优先级上,但仅当前驱非终止转移时。该想法与啮齿类中观察到的「反向回放」Foster & Wilson (2006) 相关,也与优先扫描的近期扩展(van Seijen & Sutton, 2013)相关。
Appendix B Experimental Details
附录 B 实验细节
B.1 Blind Cliffwalk
B.1 盲悬崖行走
For the Blind Cliffwalk experiments (Section 3.1 and following), we use a straight-forward Q-learning (Watkins & Dayan, 1992) setup. The Q-values are represented using either a tabular look-up table, or a linear function approximator, in both cases represented . For each transition, we compute its TD-error using:
盲悬崖行走实验(第 3.1 节及后续)采用直接的 Q 学习(Watkins & Dayan, 1992)设定。Q 值用表格查找表或线性函数逼近表示,两种情形均写为 。对每条转移,用下式计算 TD 误差:
and update the parameters using stochastic gradient ascent:
并用随机梯度上升更新参数:
For the linear FA case we use a very simple encoding of state as a 1-hot vector (as for tabular), but concatenated with a constant bias feature of value 1. To make generalization across actions impossible, we alternate which action is ‘right’ and which one is ‘wrong’ for each state. All elements are initialized with small values near zero, .
线性函数逼近情形下,状态编码为极简的 one-hot 向量(与表格情形相同),再拼接值为 1 的常数偏置特征。为使跨动作泛化不可能,我们对每个状态轮换哪个动作是「正确」、哪个是「错误」。所有元素初始化为接近零的小值,。
We vary the size of the problem (number of states ) from 2 to 16. The discount factor is set to which keeps values on approximately the same scale independently of . This allows us to used a fixed step-size of in all experiments.
问题规模(状态数 )从 2 变到 16。折扣因子取 ,使价值大致与 无关地保持同尺度。这样全部实验可用固定步长 。
The replay memory is filled by exhaustively executing all possible sequences of actions until termination (in random order). This guarantees that exactly one sequence will succeed and hit the final reward, and all others will fail with zero reward. The replay memory contains all the relevant experience (the total number of transitions is ), at the frequency that it would be encountered when acting online with a random behavior policy. Given this, we can in principle learn until convergence by just increasing the amount of computation; here, convergence is defined as a mean-squared error (MSE) between the Q-value estimates and the ground truth below .
回放存储器通过穷尽执行全部 条可能动作序列直至终止(随机顺序)来填满。这保证恰有一条序列成功并碰到最终奖励,其余均以零奖励失败。回放存储器含全部相关经验(转移总数为 ),频率与在线用随机行为策略行动时会遇到的相同。在此前提下,原则上只需增加计算量即可学到收敛;此处收敛定义为 Q 值估计与真值的均方误差(MSE)低于 。
B.2 Atari Experiments
B.2 Atari 实验
B.2.1 Implementation Details
Prioritizing using a replay memory with transitions introduced some performance challenges. Here we describe a number of things we did to minimize additional run-time and memory overhead, extending the discussion in Section 3.
B.2.1 实现细节
在含 条转移的回放存储器上做优先化带来一些性能挑战。这里描述我们为尽量减小额外运行时间与内存开销所做的若干事项,延伸第 3 节的讨论。
Rank-based prioritization
Early experiments with Atari showed that maintaining a sorted data structure of transitions with constantly changing TD-errors dominated running time. Our final solution was to store transitions in a priority queue implemented with an array-based binary heap. The heap array was then directly used as an approximation of a sorted array, which is infrequently sorted once every steps to prevent the heap becoming too unbalanced. This is an unconventional use of a binary heap, however our tests on smaller environments showed learning was unaffected compared to using a perfectly sorted array. This is likely due to the last-seen TD-error only being a proxy for the usefulness of a transition and our use of stochastic prioritized sampling. A small improvement in running time came from avoiding excessive recalculation of partitions for the sampling distribution. We reused the same partition for values of that are close together and by updating and infrequently. Our final implementation for rank-based prioritization produced an additional 2%-4% increase in running time and negligible additional memory usage. This could be reduced further in a number of ways, e.g. with a more efficient heap implementation, but it was good enough for our experiments.
基于秩的优先化
Atari 上的早期实验表明:维护 条转移、且 TD 误差不断变化的有序数据结构会主导运行时间。最终方案是把转移存入用数组实现的二叉堆优先队列。堆数组随后直接当作有序数组的近似,每 步才不频繁地完整排序一次,以防堆过度失衡。这是对二叉堆的非常规用法,但我们在较小环境上的测试表明:相对完美有序数组,学习不受影响。这很可能是因为上次见到的 TD 误差只是转移有用性的代理,且我们使用随机优先采样。运行时间上的小幅改进来自避免过度重算采样分布的分区:对相近的 复用同一分区,并较少更新 与 。最终的基于秩实现大约只增加 2%–4% 运行时间,额外内存可忽略。还可用更高效堆实现等方式继续压缩,但对我们的实验已足够。
Proportional prioritization
The ‘sum-tree’ data structure used here is very similar in spirit to the array representation of a binary heap. However, instead of the usual heap property, the value of a parent node is the sum of its children. Leaf nodes store the transition priorities and the internal nodes are intermediate sums, with the parent node containing the sum over all priorities, . This provides a efficient way of calculating the cumulative sum of priorities, allowing updates and sampling. To sample a minibatch of size , the range is divided equally into ranges. Next, a value is uniformly sampled from each range. Finally the transitions that correspond to each of these sampled values are retrieved from the tree. Overhead is similar to rank-based prioritization.
比例优先化
此处所用「求和树」数据结构在精神上与二叉堆的数组表示很相近。不过,父节点值不是通常的堆性质,而是其子之和。叶节点存转移优先级,内部节点为中间和,根节点含全部优先级之和 。这提供了高效计算优先级累积和的方式,允许 更新与采样。要采大小为 的小批量,把区间 等分为 段;再从每段均匀采样一个值;最后从树中取出对应这些采样值的转移。开销与基于秩优先化相近。
As mentioned in Section 3.4, whenever importance sampling is used, all weights were scaled so that . We found that this worked better in practice as it kept all weights within a reasonable range, avoiding the possibility of extremely large updates. It is worth mentioning that this normalization interacts with annealing on : as approaches 1, the normalization constant grows, which reduces the effective average update in a similar way to annealing the step-size .
如第 3.4 节所述,一旦使用重要性采样,所有权重 都缩放使得 。我们发现实践中这样更好:把权重保持在合理范围,避免极大更新。值得一提的是,该归一化与 的退火相互作用: 接近 1 时归一化常数增大,会以类似退火步长 的方式减小有效平均更新。
B.2.2 Hyperparameters
Throughout this paper our baseline was DQN and the tuned version of Double DQN. We tuned hyperparameters over a subset of Atari games: Breakout, Pong, Ms. Pac-Man, Q*bert, Alien, Battlezone, Asterix. Table 2 lists the values tried and Table 3 lists the chosen parameters.
B.2.2 超参数
全文基线为 DQN 与调优版 Double DQN。我们在 Atari 游戏子集上调超参:Breakout、Pong、Ms. Pac-Man、Q*bert、Alien、Battlezone、Asterix。表 2 列出尝试的取值,表 3 列出最终选定参数。
Hyperparameter Range of values 0, 0.4, 0.5, 0.6, 0.7, 0.8 0, 0.4, 0.5, 0.6, 1
Table 2: Hyperparameters considered in experiments. Here .
超参数 取值范围 0, 0.4, 0.5, 0.6, 0.7, 0.8 0, 0.4, 0.5, 0.6, 1
表 2:实验中考虑的超参数。此处 。
DQN Double DQN (tuned) Hyperparameter baseline rank-based baseline rank-based proportional (priority) 0 0 0.7 0.6 (IS) 0 0 0 (step-size) 0.00025 0.00025
Table 3: Chosen hyperparameters for prioritized variants of DQN. Arrows indicate linear annealing, where the limiting value is reached at the end of training. Note the rank-based variant with DQN as the baseline is an early version without IS. Here, the bias introduced by prioritized replay was instead corrected by annealing to zero.
DQN 调优 Double DQN 超参数 基线 基于秩 基线 基于秩 比例 (优先) 0 0 0.7 0.6 (IS) 0 0 0 (步长) 0.00025 0.00025
表 3:DQN 优先化变体的选定超参数。箭头表示线性退火,极限值在训练结束时达到。注意以 DQN 为基线的基于秩变体是早期版本、无 IS;优先回放引入的偏差改为通过把 退火到零来纠正。
B.2.3 Evaluation
We evaluate our agents using the human starts evaluation method described in (van Hasselt et al., 2016). Human starts evaluation uses start states sampled randomly from human traces. The test evaluation that agents periodically undergo during training uses start states that are randomized by doing a random number of no-ops at the beginning of each episode. Human starts evaluation averages the score over 100 evaluations of 30 minutes of game time. All learning curve plots show scores under the test evaluation and were generated using the same code base, with the same random seed initializations.
B.2.3 评估
我们用(van Hasselt et al., 2016)所述的人类开局评估方法评估智能体。人类开局评估从人类轨迹中随机采样开局状态。训练中智能体周期性接受的测试评估,则通过在每局开始时做随机次数空操作来随机化开局。人类开局评估对 100 次、每次 30 分钟游戏时间的得分取平均。全部学习曲线图显示测试评估下的分数,并用同一代码库、同一随机种子初始化生成。
Table 4 and Table 5 show evaluation method differences and the used in the -greedy policy for each agent during evaluation. The agent evaluated with the human starts evaluation is the best agent found during training as in (van Hasselt et al., 2016).
表 4 与表 5 给出评估方法差异,以及各智能体评估时 -贪婪策略所用的 。人类开局评估所用智能体是训练中找到的最佳智能体,同(van Hasselt et al., 2016)。
Evaluation method Frames Emulator time Number of evaluations Agent start point Human starts 108,000 30 mins 100 human starts Test 500,000 139 mins 1 up to 30 random no-ops
Table 4: Evaluation method comparison.
评估方法 帧数 模拟器时间 评估次数 智能体开局点 人类开局 108,000 30 分钟 100 人类开局 测试 500,000 139 分钟 1 最多 30 次随机空操作
表 4:评估方法对比。
DQN Double DQN (tuned) Evaluation method baseline rank-based baseline rank-based proportional Human starts 0.05 0.01 0.001 0.001 0.001 Test 0.05 0.05 0.01 0.01 0.01
Table 5: The used in the -greedy policy for each agent, for each evaluation method.
DQN 调优 Double DQN 评估方法 基线 基于秩 基线 基于秩 比例 人类开局 0.05 0.01 0.001 0.001 0.001 测试 0.05 0.05 0.01 0.01 0.01
表 5:各智能体、各评估方法下 -贪婪策略所用的 。
Normalized score is calculated as in (van Hasselt et al., 2016):
归一化分数按(van Hasselt et al., 2016)计算:
Note the absolute value of the denominator is taken. This only affects Video Pinball where the random score is higher than the human score. Combined with a high agent score, Video Pinball has a large effect on the mean normalized score. We continue to use this so our normalized scores are comparable.
注意分母取了绝对值。这只影响 Video Pinball:该游戏随机分高于人类分。再叠加智能体高分,Video Pinball 对均值归一化分数影响很大。我们继续沿用该定义,以使归一化分数可比较。
B.3 Class-imbalanced MNIST
B.3 类别不平衡 MNIST
B.3.1 Dataset Setup
In our supervised learning setting we modified MNIST to obtain a new training dataset with a significant label imbalance. This new dataset was obtained by considering a small subset of the samples that correspond to the first 5 digits (0, 1, 2, 3, 4) and all of the samples that correspond to the remaining 5 labels (5, 6, 7, 8, 9). For each of the first 5 digits we randomly sampled 1% of the available examples, i.e., 1% of the available 0s, 1% of the available 1s etc. In the resulting dataset there are examples of all 10 different classes but it is highly imbalanced since there are 100 times more examples that correspond to the 5, 6, 7, 8, 9 classes than to the 0, 1, 2, 3, 4 ones. In all our experiments we used the original MNIST test dataset without removing any samples.
B.3.1 数据集设置
在监督学习设定中,我们修改 MNIST 以得到标签显著不平衡的新训练集:对前 5 个数字(0, 1, 2, 3, 4)只取少量样本,对其余 5 个标签(5, 6, 7, 8, 9)保留全部样本。对前 5 个数字各自随机采样可用样例的 1%,即可用 0 的 1%、可用 1 的 1% 等。所得数据集仍含全部 10 类,但高度不平衡:对应 5–9 的样例约为 0–4 的 100 倍。全部实验使用原始 MNIST 测试集,不删除任何样本。
The architecture of the feed-forward network used in the Prioritized Supervised Learning experiments.
Figure 6:
优先监督学习实验所用前馈网络架构。
图 6:
B.3.2 Training Setup
In our experiments we used a 4 layer feed-forward neural network with an architecture similar to that of LeNet5 (Lecun et al., 1998). This is a 2 layer convolutional neural network followed by 2 fully connected layers at the top. Each convolutional layer is comprised of a pure convolution followed by a rectifier non-linearity and a subsampling max pooling operation. The two fully-connected layers in the network are also separated by a rectifier non-linearity. The last layer is a softmax which is used to obtain a normalized distribution over the possible labels. The complete architecture is shown in Figure 6, and is implemented using Torch7 (Collobert et al., 2011). The model was trained using stochastic gradient descent with no momentum and a minibatch of size 60. In all our experiments we considered 6 different step-sizes (0.3, 0.1, 0.03, 0.01, 0.003 and 0.001) and for each case presented in this work, we selected the step-size that lead to the best (balanced) validation performance. We used the negative log-likelihood loss criterion and we ran experiments with both the weighted and unweighted version of the loss. In the weighted case the loss of the examples that correspond to the first 5 digits (0, 1, 2, 3, 4) was scaled by a factor of a 100 to accommodate the label imbalance in the training set described above.
B.3.2 训练设置
实验使用 4 层前馈神经网络,架构类似 LeNet5(Lecun et al., 1998):两层卷积网络,顶部接两层全连接。每个卷积层由纯卷积、整流非线性与下采样最大池化组成。两层全连接之间也隔以整流非线性。最后一层为 softmax,得到各类标签上的归一化分布。完整架构见图 6,用 Torch7 实现(Collobert et al., 2011)。模型用无动量随机梯度下降训练,小批量大小 60。全部实验考虑 6 种步长(0.3、0.1、0.03、0.01、0.003、0.001),对本文报告的每种情形,选取在(平衡)验证表现上最好的步长。损失为负对数似然;我们同时跑了加权与未加权版本。加权情形下,对应前 5 个数字(0–4)的样例损失乘以 100,以适配上述训练集标签不平衡。
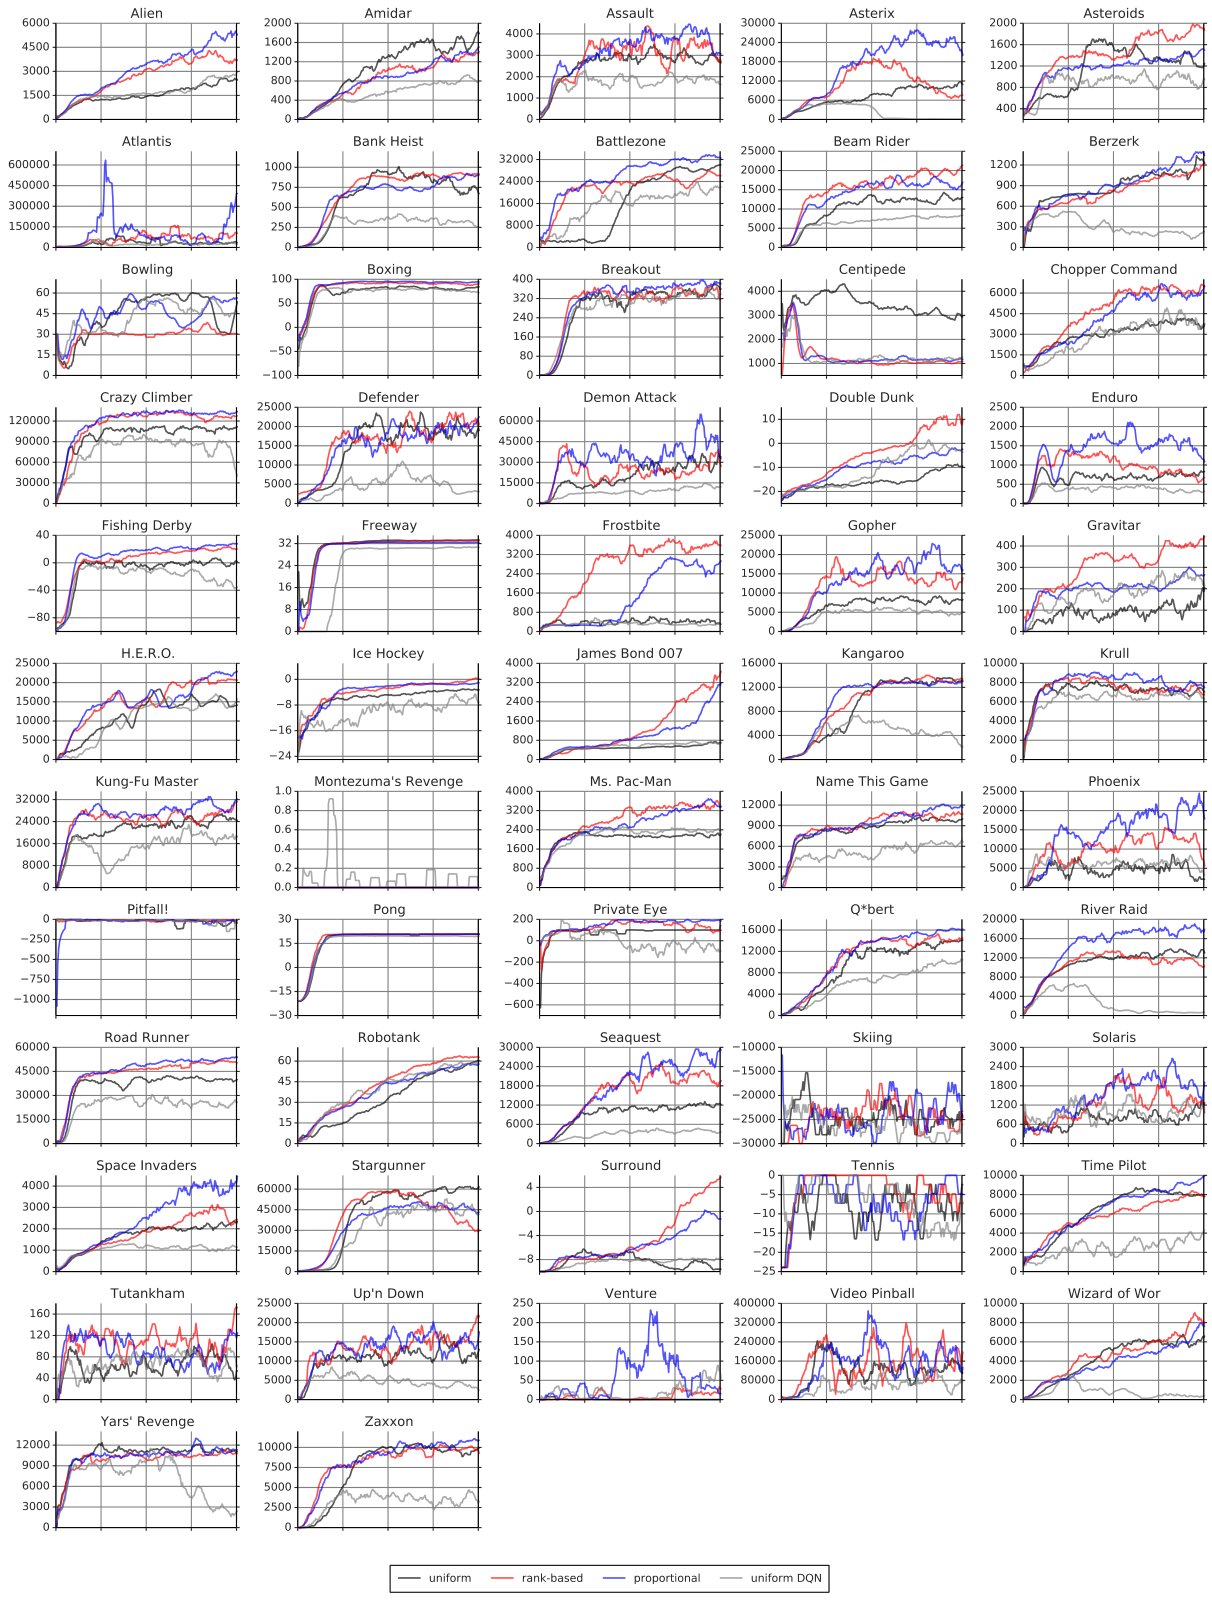
Figure 7: Learning curves (in raw score) for Double DQN (uniform baseline, in black), with rank-based prioritized replay (red), proportional prioritization (blue), for all 57 games of the Atari benchmark suite. Each curve corresponds to a single training run over 200 million unique frames, using test evaluation (see Section B.2.3), with a moving average smoothed over 10 points. Learning curves for the original DQN are in gray. See Figure 8 for a more detailed view on a subset of these.
图 7:Atari 基准全部 57 款游戏上,Double DQN(均匀基线,黑)、基于秩优先回放(红)、比例优先化(蓝)的学习曲线(原始分数)。每条曲线对应一次训练运行、2 亿独特帧,采用测试评估(见 B.2.3 节),移动平均平滑 10 个点。原始 DQN 学习曲线为灰色。子集的更细视图见图 8。
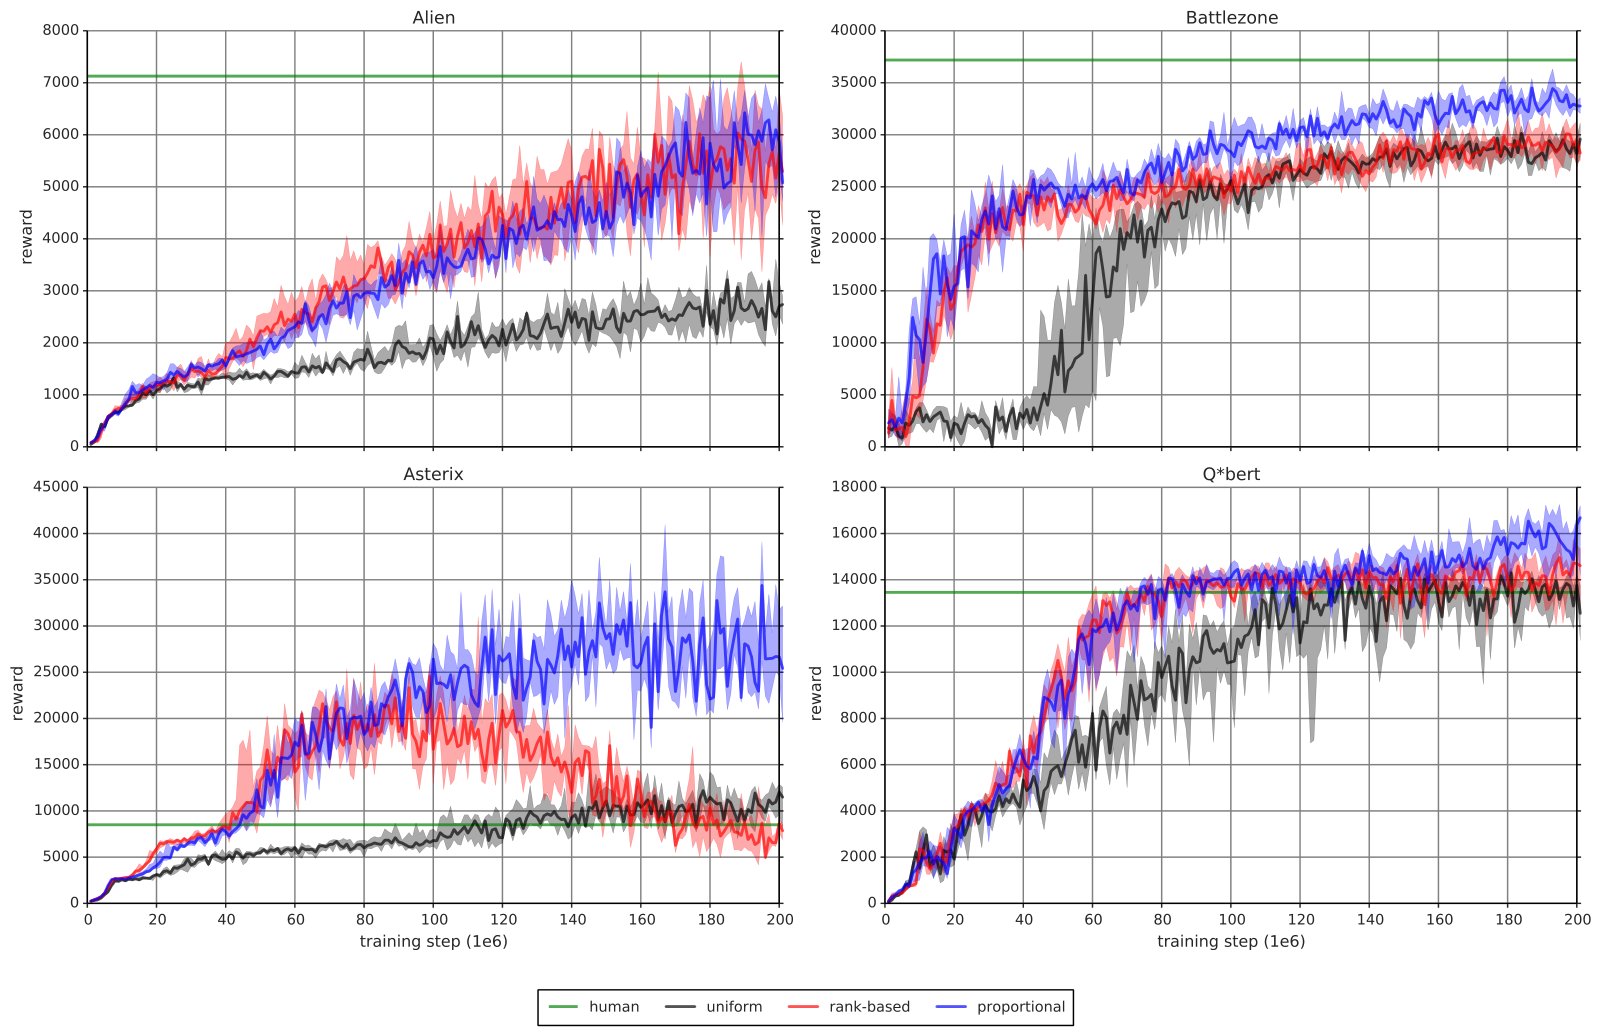
Figure 8: Detailed learning curves for rank-based (red) and proportional (blue) prioritization, as compared to the uniform Double DQN baseline (black) on a selection of games. The solid lines are the median scores, and the shaded area denotes the interquartile range across 8 random initializations. The dashed green lines are human scores. While the variability between runs is substantial, there are significant differences in final achieved score, and also in learning speed.
图 8:选定游戏上,基于秩(红)与比例(蓝)优先化相对均匀 Double DQN 基线(黑)的细学习曲线。实线为分数中位数,阴影为 8 次随机初始化的四分位距。绿色虚线为人类分数。尽管运行间变异很大,最终得分与学习速度仍有显著差异。
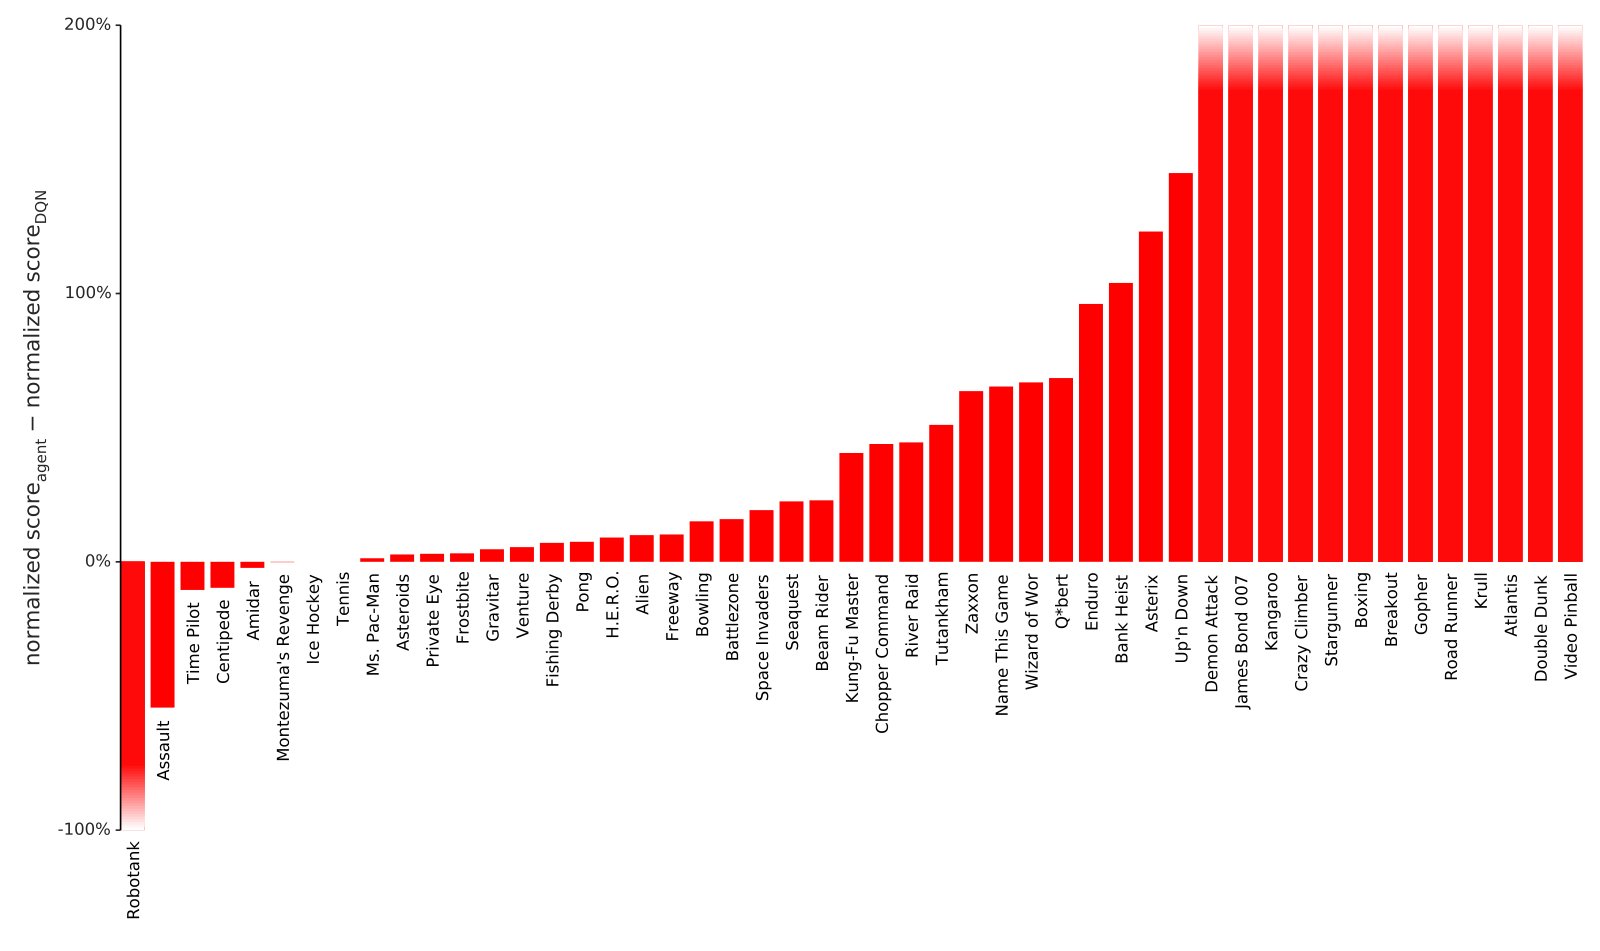
Figure 9: Difference in normalized score (the gap between random and human is ) on 49 games with human starts, comparing DQN with and without rank-based prioritized replay, showing substantial improvements in many games. Exact scores are in Table 6. See also Figure 3 where Double DQN is the baseline.
图 9:49 款游戏、人类开局设定下归一化分数差(随机到人类差距为 ):比较有无基于秩优先回放的 DQN,多数游戏有显著提升。精确分数见表 6。另见图 3,以 Double DQN 为基线。
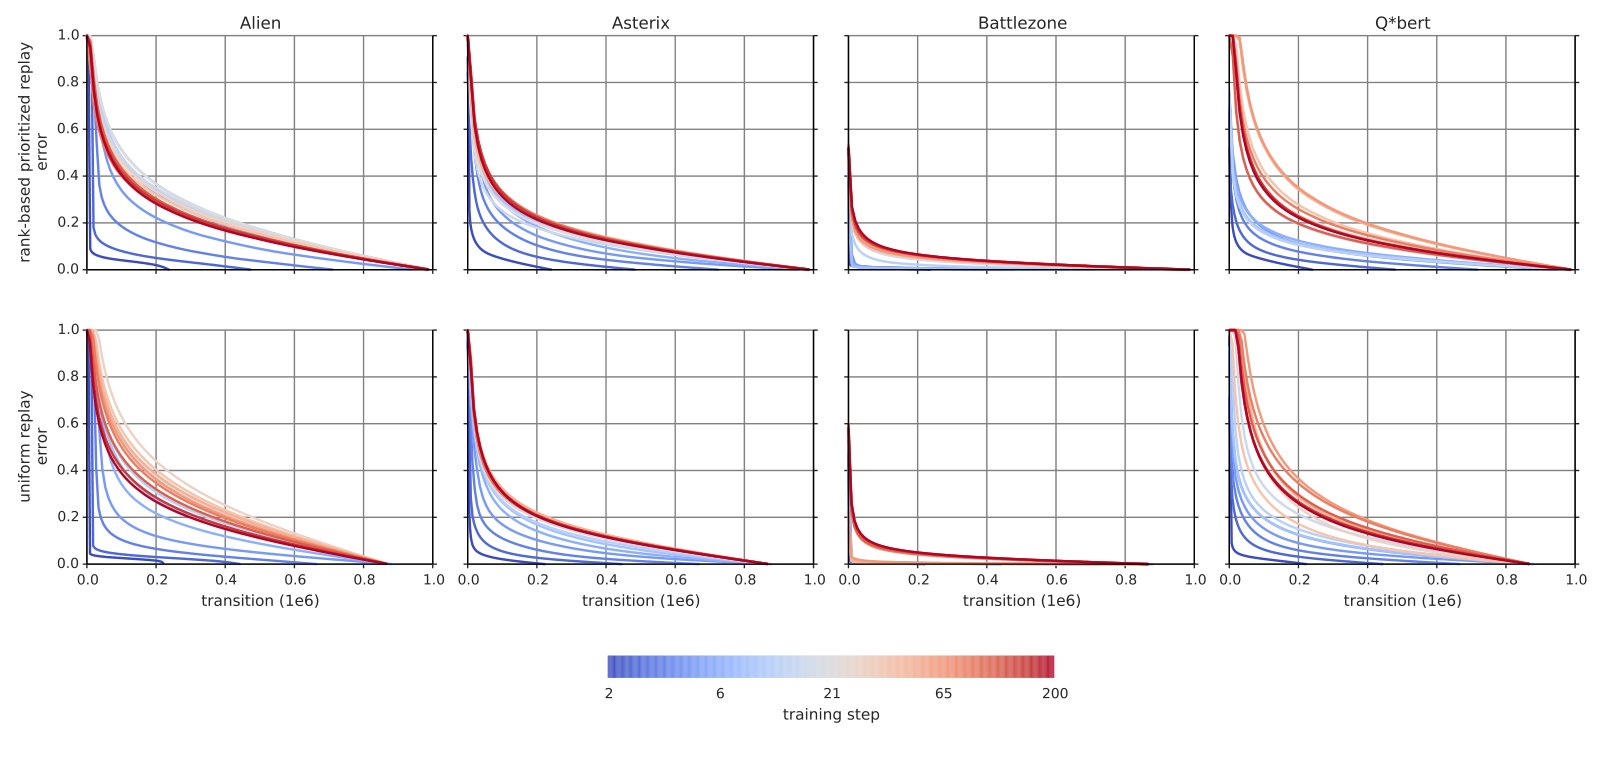
Figure 10: Visualization of the last-seen absolute TD-error for all transitions in the replay memory, sorted, for a selection of Atari games. The lines are color-coded by the time during learning, at a resolution of frames, with the coldest colors in the beginning and the warmest toward the end of training. We observe that in some games it starts quite peaked but quickly becomes spread out, following approximately a heavy-tailed distribution. This phenomenon happens for both rank-based prioritized replay (top) and uniform replay (bottom) but is faster for prioritized replay.
图 10:选定 Atari 游戏上,回放存储器中全部转移按上次见到的绝对 TD 误差排序的可视化。线条按学习时间着色,分辨率为 帧,冷色在训练初、暖色在训练末。我们观察到:有些游戏起初很尖峰,很快铺开,大致呈重尾分布。该现象在基于秩优先回放(上)与均匀回放(下)中都出现,但优先回放更快。
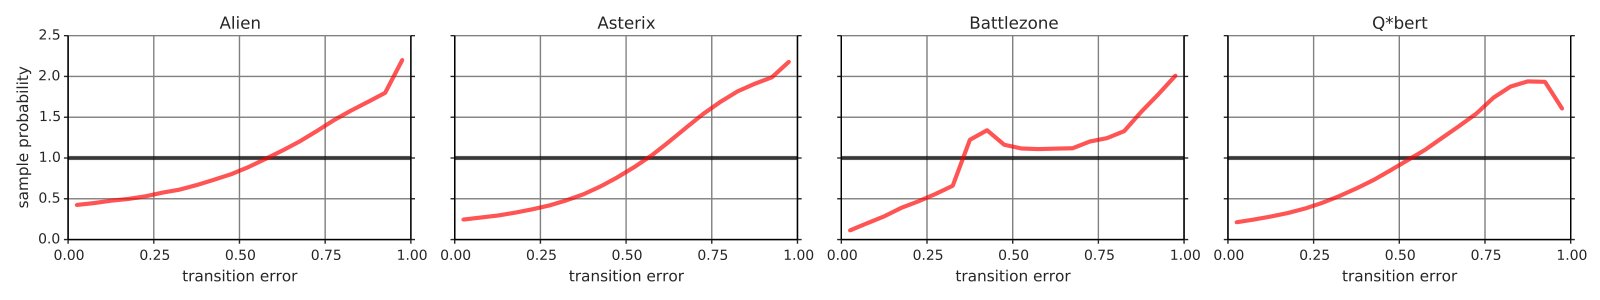
Figure 11: Effective replay probability, as a function of absolute TD-error, for the rank-based prioritized replay variant near the start of training. This shows the effect of Equation 1 with in practice, compared to the uniform baseline (dashed horizontal line). The effect is irregular, but qualitatively similar for a selection of games.
图 11:有效回放概率随绝对 TD 误差变化:基于秩优先回放变体在训练初期。展示式 (1) 取 的实际效果,对照均匀基线(水平虚线)。效果不规则,但在若干选定游戏上定性相似。
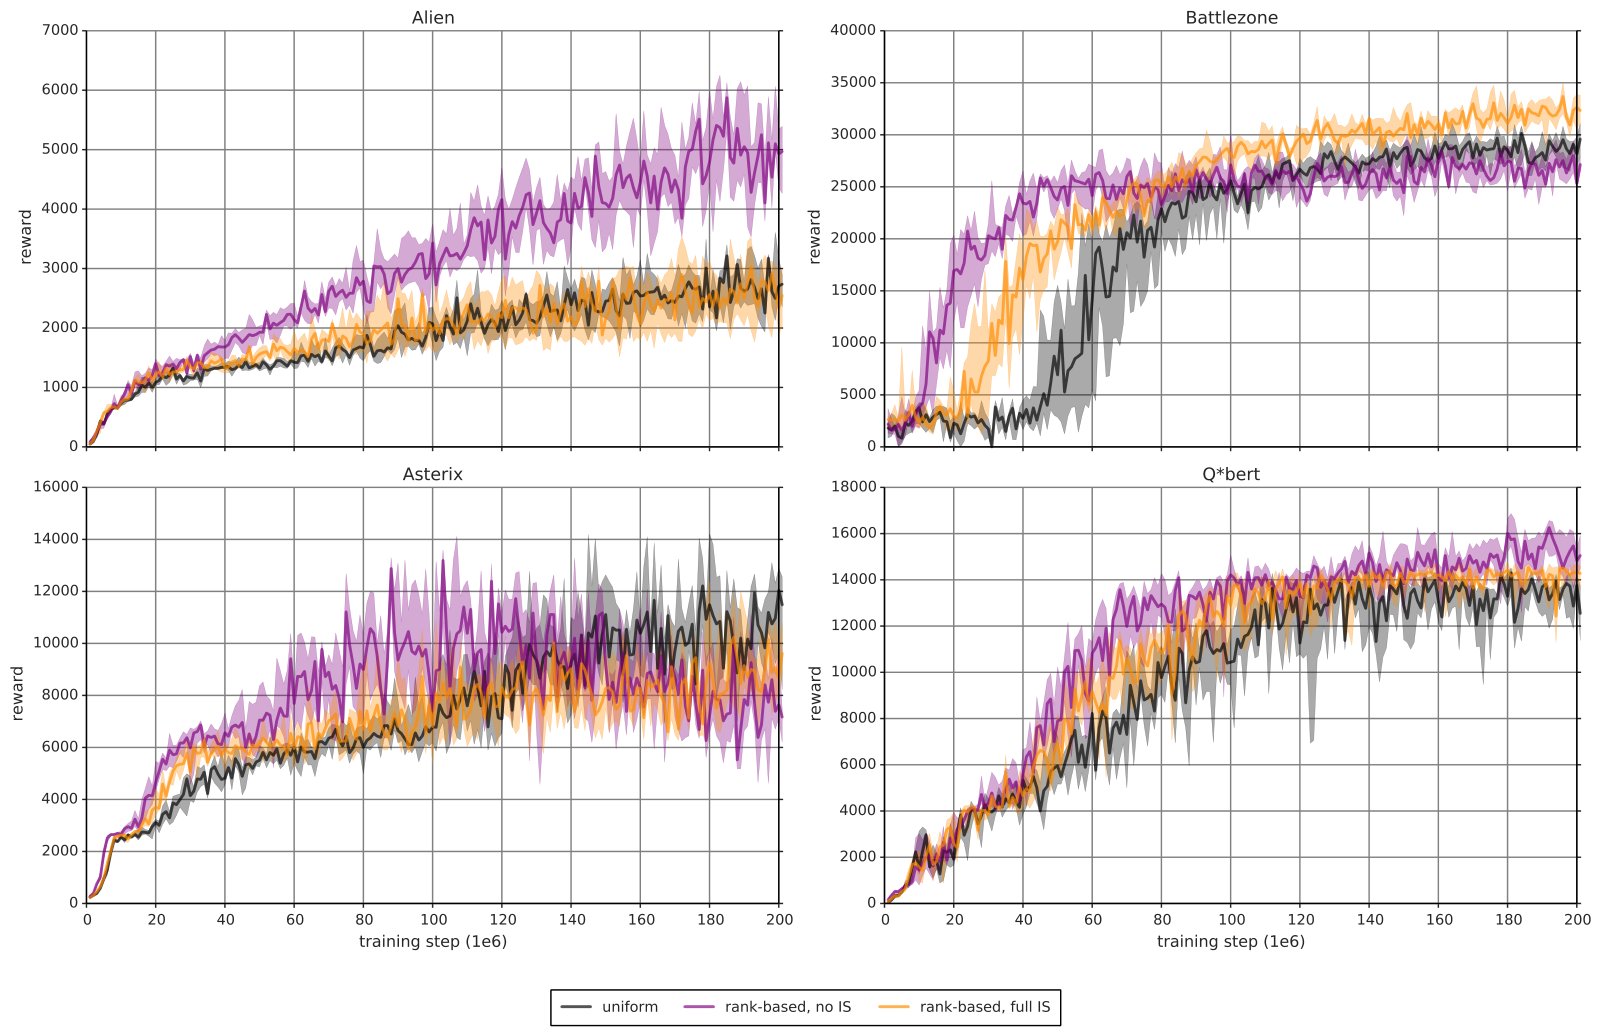
Figure 12: Effect of importance sampling: These learning curves (as in Figure 8) show how rank-based prioritization is affected by full importance-sampling correction (i.e., , in orange), as compared to the uniform baseline (black, ) and pure, uncorrected prioritized replay (violet, ), on a few selected games. The shaded area corresponds to the interquartile range. The step-size for full IS correction is the same as for uniform replay. For uncorrected prioritized replay, the step-size is reduced by a factor of 4. Compared to uncorrected prioritized replay, importance sampling makes learning less aggressive, leading on the one hand to slower initial learning, but on the other hand to a smaller risk of premature convergence and sometimes better ultimate results. Compared to uniform replay, fully corrected prioritization is on average better.
图 12:重要性采样的影响:这些学习曲线(同图 8)展示基于秩优先化如何受全量重要性采样校正影响(即 ,橙),对照均匀基线(黑,)与纯未校正优先回放(紫,),若干选定游戏。阴影为四分位距。全量 IS 校正的步长与均匀回放相同;未校正优先回放步长缩小 4 倍。相对未校正优先回放,重要性采样使学习不那么激进:一方面初期更慢,另一方面过早收敛风险更小,有时最终结果更好。相对均匀回放,经充分校正的优先化平均更优。
DQN Double DQN (tuned) Game baseline rank-based baseline rank-based proportional Alien 7% 17% 14% 19% 12% Amidar 8% 6% 10% 8% 14% Assault 685% 631% 1276% 1381% 1641% Asterix -1% 123% 226% 303% 431% Asteroids -0% 2% 1% 2% 2% Atlantis 478% 1480% 2335% 2419% 4425% Bank Heist 25% 129% 139% 137% 128% Battlezone 48% 63% 72% 75% 87% Beam Rider 57% 80% 117% 210% 176% Berzerk 22% 40% 33% 47% Bowling 5% 20% 31% 15% 27% Boxing 246% 641% 676% 665% 632% Breakout 1149% 1823% 1397% 1298% 1407% Centipede 22% 12% 23% 19% 18% Chopper Command 29% 73% 34% 48% 72% Crazy Climber 179% 429% 448% 507% 522% Defender 151% 207% 176% 155% Demon Attack 390% 596% 2152% 1888% 2256% Double Dunk -350% 669% 981% 2000% 1169% Enduro 68% 164% 158% 233% 239% Fishing Derby 91% 98% 98% 106% 105% Freeway 101% 111% 113% 113% 109% Frostbite 2% 5% 33% 83% 69% Gopher 120% 836% 728% 1679% 2792% Gravitar -1% 4% -2% 1% -1% H.E.R.O. 47% 56% 55% 80% 78% Ice Hockey 58% 58% 71% 93% 85% James Bond 007 94% 311% 161% 1172% 1038% Kangaroo 98% 339% 421% 458% 384% Krull 283% 1051% 590% 598% 653% Kung-Fu Master 56% 97% 146% 153% 151% Montezuma’s Revenge 1% 0% 0% 1% -0% Ms. Pac-Man 4% 5% 7% 11% 11% Name This Game 73% 138% 143% 173% 200% Phoenix 270% 202% 284% 474% Pitfall! 2% 3% -1% 5% Pong 102% 110% 111% 110% 110% Private Eye -1% 2% -2% 0% -1% Q*bert 37% 106% 91% 82% 93% River Raid 25% 70% 74% 81% 128% Road Runner 136% 854% 643% 780% 850% Robotank 863% 752% 872% 828% 815% Seaquest 6% 29% 36% 63% 97% Skiing -122% 33% 44% 38% Solaris -21% -14% 3% 2% Space Invaders 99% 118% 191% 291% 693% Stargunner 378% 660% 653% 689% 580% Surround 29% 77% 103% 58% Tennis 130% 130% 93% 110% 132% Time Pilot 100% 89% 140% 113% 176% Tutankham 16% 67% 63% 35% 17% Up’n Down 28% 173% 200% 125% 313% Venture 4% 9% 0% 7% 22% Video Pinball -5% 4042% 7221% 5727% 7367% Wizard of Wor -15% 52% 144% 131% 177% Yars’ Revenge 11% 10% 7% 10% Zaxxon 4% 68% 102% 113% 113%
Table 6: Normalized scores on 57 Atari games (random is , human is ), from a single training run each, using human starts evaluation (see Section B.2.3). Baselines are from van Hasselt et al. (2016), see Equation 4 for how normalized scores are calculated.
DQN 调优 Double DQN 游戏 基线 基于秩 基线 基于秩 比例
Alien 7% 17% 14% 19% 12% Amidar 8% 6% 10% 8% 14% Assault 685% 631% 1276% 1381% 1641% Asterix -1% 123% 226% 303% 431% Asteroids -0% 2% 1% 2% 2% Atlantis 478% 1480% 2335% 2419% 4425% Bank Heist 25% 129% 139% 137% 128% Battlezone 48% 63% 72% 75% 87% Beam Rider 57% 80% 117% 210% 176% Berzerk 22% 40% 33% 47% Bowling 5% 20% 31% 15% 27% Boxing 246% 641% 676% 665% 632% Breakout 1149% 1823% 1397% 1298% 1407% Centipede 22% 12% 23% 19% 18% Chopper Command 29% 73% 34% 48% 72% Crazy Climber 179% 429% 448% 507% 522% Defender 151% 207% 176% 155% Demon Attack 390% 596% 2152% 1888% 2256% Double Dunk -350% 669% 981% 2000% 1169% Enduro 68% 164% 158% 233% 239% Fishing Derby 91% 98% 98% 106% 105% Freeway 101% 111% 113% 113% 109% Frostbite 2% 5% 33% 83% 69% Gopher 120% 836% 728% 1679% 2792% Gravitar -1% 4% -2% 1% -1% H.E.R.O. 47% 56% 55% 80% 78% Ice Hockey 58% 58% 71% 93% 85% James Bond 007 94% 311% 161% 1172% 1038% Kangaroo 98% 339% 421% 458% 384% Krull 283% 1051% 590% 598% 653% Kung-Fu Master 56% 97% 146% 153% 151% Montezuma’s Revenge 1% 0% 0% 1% -0% Ms. Pac-Man 4% 5% 7% 11% 11% Name This Game 73% 138% 143% 173% 200% Phoenix 270% 202% 284% 474% Pitfall! 2% 3% -1% 5% Pong 102% 110% 111% 110% 110% Private Eye -1% 2% -2% 0% -1% Q*bert 37% 106% 91% 82% 93% River Raid 25% 70% 74% 81% 128% Road Runner 136% 854% 643% 780% 850% Robotank 863% 752% 872% 828% 815% Seaquest 6% 29% 36% 63% 97% Skiing -122% 33% 44% 38% Solaris -21% -14% 3% 2% Space Invaders 99% 118% 191% 291% 693% Stargunner 378% 660% 653% 689% 580% Surround 29% 77% 103% 58% Tennis 130% 130% 93% 110% 132% Time Pilot 100% 89% 140% 113% 176% Tutankham 16% 67% 63% 35% 17% Up’n Down 28% 173% 200% 125% 313% Venture 4% 9% 0% 7% 22% Video Pinball -5% 4042% 7221% 5727% 7367% Wizard of Wor -15% 52% 144% 131% 177% Yars’ Revenge 11% 10% 7% 10% Zaxxon 4% 68% 102% 113% 113%
表 6:57 款 Atari 游戏上的归一化分数(随机为 ,人类为 ),各一次训练运行,采用人类开局评估(见 B.2.3 节)。基线来自 van Hasselt et al. (2016);归一化分数计算见式 (4)。
DQN Double DQN (tuned) Game random human baseline Gorila rank-b. baseline rank-b. prop. Alien 128.3 6371.3 570.2 813.5 1191.0 1033.4 1334.7 900.5 Amidar 11.8 1540.4 133.4 189.2 98.9 169.1 129.1 218.4 Assault 166.9 628.9 3332.3 1195.8 3081.3 6060.8 6548.9 7748.5 Asterix 164.5 7536.0 124.5 3324.7 9199.5 16837.0 22484.5 31907.5 Asteroids 871.3 36517.3 697.1 933.6 1677.2 1193.2 1745.1 1654.0 Atlantis 13463.0 26575.0 76108.0 629166.5 207526.0 319688.0 330647.0 593642.0 Bank Heist 21.7 644.5 176.3 399.4 823.7 886.0 876.6 816.8 Battlezone 3560.0 33030.0 17560.0 19938.0 22250.0 24740.0 25520.0 29100.0 Beam Rider 254.6 14961.0 8672.4 3822.1 12041.9 17417.2 31181.3 26172.7 Berzerk 196.1 2237.5 644.0 1011.1 865.9 1165.6 Bowling 35.2 146.5 41.2 54.0 58.0 69.6 52.0 65.8 Boxing -1.5 9.6 25.8 74.2 69.6 73.5 72.3 68.6 Breakout 1.6 27.9 303.9 313.0 481.1 368.9 343.0 371.6 Centipede 1925.5 10321.9 3773.1 6296.9 2959.4 3853.5 3489.1 3421.9 Chopper Command 644.0 8930.0 3046.0 3191.8 6685.0 3495.0 4635.0 6604.0 Crazy Climber 9337.0 32667.0 50992.0 65451.0 109337.0 113782.0 127512.0 131086.0 Defender 1965.5 14296.0 20634.0 27510.0 23666.5 21093.5 Demon Attack 208.3 3442.8 12835.2 14880.1 19478.8 69803.4 61277.5 73185.8 Double Dunk -16.0 -14.4 -21.6 -11.3 -5.3 -0.3 16.0 2.7 Enduro -81.8 740.2 475.6 71.0 1265.6 1216.6 1831.0 1884.4 Fishing Derby -77.1 5.1 -2.3 4.6 3.5 3.2 9.8 9.2 Freeway 0.1 25.6 25.8 10.2 28.4 28.8 28.9 27.9 Frostbite 66.4 4202.8 157.4 426.6 288.7 1448.1 3510.0 2930.2 Gopher 250.0 2311.0 2731.8 4373.0 17478.2 15253.0 34858.8 57783.8 Gravitar 245.5 3116.0 216.5 538.4 351.0 200.5 269.5 218.0 H.E.R.O. 1580.3 25839.4 12952.5 8963.4 15150.9 14892.5 20889.9 20506.4 Ice Hockey -9.7 0.5 -3.8 -1.7 -3.8 -2.5 -0.2 -1.0 James Bond 007 33.5 368.5 348.5 444.0 1074.5 573.0 3961.0 3511.5 Kangaroo 100.0 2739.0 2696.0 1431.0 9053.0 11204.0 12185.0 10241.0 Krull 1151.9 2109.1 3864.0 6363.1 11209.5 6796.1 6872.8 7406.5 Kung-Fu Master 304.0 20786.8 11875.0 20620.0 20181.0 30207.0 31676.0 31244.0 Montezuma’s Revenge 25.0 4182.0 50.0 84.0 44.0 42.0 51.0 13.0 Ms. Pac-Man 197.8 15375.0 763.5 1263.0 964.7 1241.3 1865.9 1824.6 Name This Game 1747.8 6796.0 5439.9 9238.5 8738.5 8960.3 10497.6 11836.1 Phoenix 1134.4 6686.2 16107.8 12366.5 16903.6 27430.1 Pitfall! -348.8 5998.9 -193.7 -186.7 -427.0 -14.8 Pong -18.0 15.5 16.2 16.7 18.7 19.1 18.9 18.9 Private Eye 662.8 64169.1 298.2 2598.6 2202.3 -575.5 670.7 179.0 Q*bert 183.0 12085.0 4589.8 7089.8 12740.5 11020.8 9944.0 11277.0 River Raid 588.3 14382.2 4065.3 5310.3 10205.5 10838.4 11807.2 18184.4 Road Runner 200.0 6878.0 9264.0 43079.8 57207.0 43156.0 52264.0 56990.0 Robotank 2.4 8.9 58.5 61.8 51.3 59.1 56.2 55.4 Seaquest 215.5 40425.8 2793.9 10145.9 11848.8 14498.0 25463.7 39096.7 Skiing -15287.4 -3686.6 -29404.3 -11490.4 -10169.1 -10852.8 Solaris 2047.2 11032.6 134.6 810.0 2272.8 2238.2 Space Invaders 182.6 1464.9 1449.7 1183.3 1696.9 2628.7 3912.1 9063.0 Stargunner 697.0 9528.0 34081.0 14919.2 58946.0 58365.0 61582.0 51959.0 Surround -9.7 5.4 -5.3 1.9 5.9 -0.9 Tennis -21.4 -6.7 -2.3 -0.7 -2.3 -7.8 -5.3 -2.0 Time Pilot 3273.0 5650.0 5640.0 8267.8 5391.0 6608.0 5963.0 7448.0 Tutankham 12.7 138.3 32.4 118.5 96.5 92.2 56.9 33.6 Up’n Down 707.2 9896.1 3311.3 8747.7 16626.5 19086.9 12157.4 29443.7 Venture 18.0 1039.0 54.0 523.4 110.0 21.0 94.0 244.0 Video Pinball 20452.0 15641.1 20228.1 112093.4 214925.3 367823.7 295972.8 374886.9 Wizard of Wor 804.0 4556.0 246.0 10431.0 2755.0 6201.0 5727.0 7451.0 Yars’ Revenge 1476.9 47135.2 6626.7 6270.6 4687.4 5965.1 Zaxxon 475.0 8443.0 831.0 6159.4 5901.0 8593.0 9474.0 9501.0
Table 7: Raw scores obtained on the original 49 Atari games plus 8 additional games where available, evaluated on human starts. Human, random, DQN and tuned Double DQN scores are from van Hasselt et al. (2016). Note that the Gorila results from Nair et al. (2015) used much more data and computation, but the other methods are more directly comparable to each other in this respect.
DQN 调优 Double DQN 游戏 随机 人类 基线 Gorila 基于秩 基线 基于秩 比例
Alien 128.3 6371.3 570.2 813.5 1191.0 1033.4 1334.7 900.5 Amidar 11.8 1540.4 133.4 189.2 98.9 169.1 129.1 218.4 Assault 166.9 628.9 3332.3 1195.8 3081.3 6060.8 6548.9 7748.5 Asterix 164.5 7536.0 124.5 3324.7 9199.5 16837.0 22484.5 31907.5 Asteroids 871.3 36517.3 697.1 933.6 1677.2 1193.2 1745.1 1654.0 Atlantis 13463.0 26575.0 76108.0 629166.5 207526.0 319688.0 330647.0 593642.0 Bank Heist 21.7 644.5 176.3 399.4 823.7 886.0 876.6 816.8 Battlezone 3560.0 33030.0 17560.0 19938.0 22250.0 24740.0 25520.0 29100.0 Beam Rider 254.6 14961.0 8672.4 3822.1 12041.9 17417.2 31181.3 26172.7 Berzerk 196.1 2237.5 644.0 1011.1 865.9 1165.6 Bowling 35.2 146.5 41.2 54.0 58.0 69.6 52.0 65.8 Boxing -1.5 9.6 25.8 74.2 69.6 73.5 72.3 68.6 Breakout 1.6 27.9 303.9 313.0 481.1 368.9 343.0 371.6 Centipede 1925.5 10321.9 3773.1 6296.9 2959.4 3853.5 3489.1 3421.9 Chopper Command 644.0 8930.0 3046.0 3191.8 6685.0 3495.0 4635.0 6604.0 Crazy Climber 9337.0 32667.0 50992.0 65451.0 109337.0 113782.0 127512.0 131086.0 Defender 1965.5 14296.0 20634.0 27510.0 23666.5 21093.5 Demon Attack 208.3 3442.8 12835.2 14880.1 19478.8 69803.4 61277.5 73185.8 Double Dunk -16.0 -14.4 -21.6 -11.3 -5.3 -0.3 16.0 2.7 Enduro -81.8 740.2 475.6 71.0 1265.6 1216.6 1831.0 1884.4 Fishing Derby -77.1 5.1 -2.3 4.6 3.5 3.2 9.8 9.2 Freeway 0.1 25.6 25.8 10.2 28.4 28.8 28.9 27.9 Frostbite 66.4 4202.8 157.4 426.6 288.7 1448.1 3510.0 2930.2 Gopher 250.0 2311.0 2731.8 4373.0 17478.2 15253.0 34858.8 57783.8 Gravitar 245.5 3116.0 216.5 538.4 351.0 200.5 269.5 218.0 H.E.R.O. 1580.3 25839.4 12952.5 8963.4 15150.9 14892.5 20889.9 20506.4 Ice Hockey -9.7 0.5 -3.8 -1.7 -3.8 -2.5 -0.2 -1.0 James Bond 007 33.5 368.5 348.5 444.0 1074.5 573.0 3961.0 3511.5 Kangaroo 100.0 2739.0 2696.0 1431.0 9053.0 11204.0 12185.0 10241.0 Krull 1151.9 2109.1 3864.0 6363.1 11209.5 6796.1 6872.8 7406.5 Kung-Fu Master 304.0 20786.8 11875.0 20620.0 20181.0 30207.0 31676.0 31244.0 Montezuma’s Revenge 25.0 4182.0 50.0 84.0 44.0 42.0 51.0 13.0 Ms. Pac-Man 197.8 15375.0 763.5 1263.0 964.7 1241.3 1865.9 1824.6 Name This Game 1747.8 6796.0 5439.9 9238.5 8738.5 8960.3 10497.6 11836.1 Phoenix 1134.4 6686.2 16107.8 12366.5 16903.6 27430.1 Pitfall! -348.8 5998.9 -193.7 -186.7 -427.0 -14.8 Pong -18.0 15.5 16.2 16.7 18.7 19.1 18.9 18.9 Private Eye 662.8 64169.1 298.2 2598.6 2202.3 -575.5 670.7 179.0 Q*bert 183.0 12085.0 4589.8 7089.8 12740.5 11020.8 9944.0 11277.0 River Raid 588.3 14382.2 4065.3 5310.3 10205.5 10838.4 11807.2 18184.4 Road Runner 200.0 6878.0 9264.0 43079.8 57207.0 43156.0 52264.0 56990.0 Robotank 2.4 8.9 58.5 61.8 51.3 59.1 56.2 55.4 Seaquest 215.5 40425.8 2793.9 10145.9 11848.8 14498.0 25463.7 39096.7 Skiing -15287.4 -3686.6 -29404.3 -11490.4 -10169.1 -10852.8 Solaris 2047.2 11032.6 134.6 810.0 2272.8 2238.2 Space Invaders 182.6 1464.9 1449.7 1183.3 1696.9 2628.7 3912.1 9063.0 Stargunner 697.0 9528.0 34081.0 14919.2 58946.0 58365.0 61582.0 51959.0 Surround -9.7 5.4 -5.3 1.9 5.9 -0.9 Tennis -21.4 -6.7 -2.3 -0.7 -2.3 -7.8 -5.3 -2.0 Time Pilot 3273.0 5650.0 5640.0 8267.8 5391.0 6608.0 5963.0 7448.0 Tutankham 12.7 138.3 32.4 118.5 96.5 92.2 56.9 33.6 Up’n Down 707.2 9896.1 3311.3 8747.7 16626.5 19086.9 12157.4 29443.7 Venture 18.0 1039.0 54.0 523.4 110.0 21.0 94.0 244.0 Video Pinball 20452.0 15641.1 20228.1 112093.4 214925.3 367823.7 295972.8 374886.9 Wizard of Wor 804.0 4556.0 246.0 10431.0 2755.0 6201.0 5727.0 7451.0 Yars’ Revenge 1476.9 47135.2 6626.7 6270.6 4687.4 5965.1 Zaxxon 475.0 8443.0 831.0 6159.4 5901.0 8593.0 9474.0 9501.0
表 7:原始 49 款 Atari 游戏外加 8 款(若有)上的原始分数,按人类开局评估。人类、随机、DQN 与调优 Double DQN 分数来自 van Hasselt et al. (2016)。注意 Nair et al. (2015) 的 Gorila 结果使用了更多数据与计算,其余方法在此方面更可直接比较。