Get To The Point: Summarization with Pointer-Generator Networks
Get To The Point: Summarization with Pointer-Generator Networks
直入要点:用指针生成网络做摘要
Abigail See Affiliation: Stanford University Email: abisee@stanford.edu Peter J. Liu Affiliation: Google Brain Email: peterjliu@google.com Christopher D. Manning Affiliation: Stanford University Email: manning@stanford.edu
Abstract
摘要
Neural sequence-to-sequence models have provided a viable new approach for abstractive text summarization (meaning they are not restricted to simply selecting and rearranging passages from the original text). However, these models have two shortcomings: they are liable to reproduce factual details inaccurately, and they tend to repeat themselves. In this work we propose a novel architecture that augments the standard sequence-to-sequence attentional model in two orthogonal ways. First, we use a hybrid pointer-generator network that can copy words from the source text via pointing, which aids accurate reproduction of information, while retaining the ability to produce novel words through the generator. Second, we use coverage to keep track of what has been summarized, which discourages repetition. We apply our model to the CNN / Daily Mail summarization task, outperforming the current abstractive state-of-the-art by at least 2 ROUGE points.
神经序列到序列模型为抽象式文本摘要提供了一条可行的新路径(也就是说,它们不必只从原文里选取并重排片段)。不过这类模型有两个短板:容易把事实细节复述错,也容易自我重复。本文提出一种新架构,从两个彼此独立的方向增强标准的序列到序列注意力模型。第一,我们使用混合的指针生成网络,既能通过指向从源文本复制词语,从而更准确地复述信息,又能继续通过生成器写出原文中没有的新词。第二,我们用覆盖来跟踪已经摘要过的内容,从而抑制重复。我们把模型用在 CNN / Daily Mail 摘要任务上,比当时最好的抽象式结果至少高出 2 个 ROUGE 点。
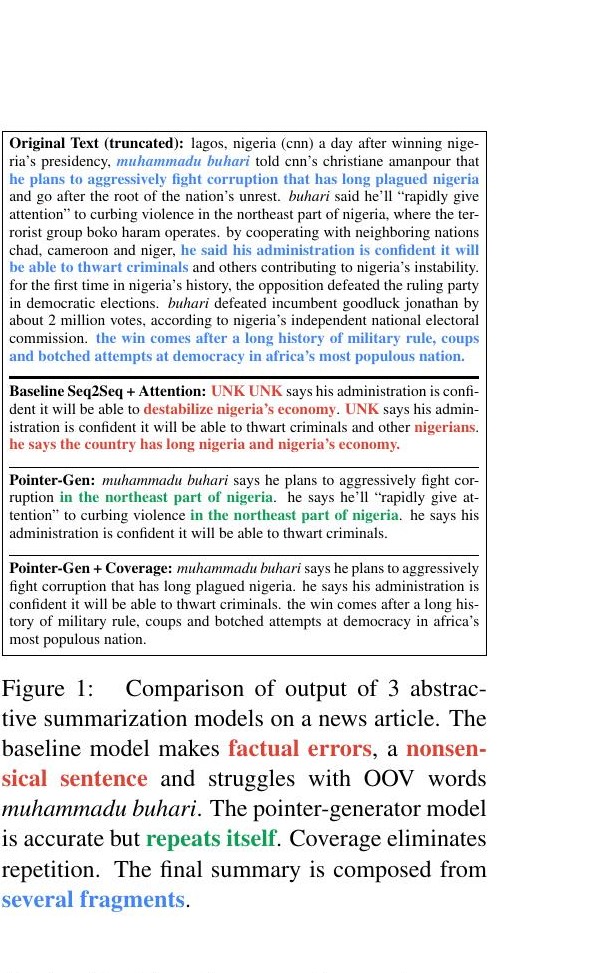
Original Text (truncated): lagos, nigeria (cnn) a day after winning nigeria’s presidency, muhammadu buhari told cnn’s christiane amanpour that he plans to aggressively fight corruption that has long plagued nigeria and go after the root of the nation’s unrest. buhari said he’ll “rapidly give attention” to curbing violence in the northeast part of nigeria, where the terrorist group boko haram operates. by cooperating with neighboring nations chad, cameroon and niger, he said his administration is confident it will be able to thwart criminals and others contributing to nigeria’s instability. for the first time in nigeria’s history, the opposition defeated the ruling party in democratic elections. buhari defeated incumbent goodluck jonathan by about 2 million votes, according to nigeria’s independent national electoral commission. the win comes after a long history of military rule, coups and botched attempts at democracy in africa’s most populous nation. Baseline Seq2Seq + Attention: UNK UNK says his administration is confident it will be able to destabilize nigeria’s economy. UNK says his administration is confident it will be able to thwart criminals and other nigerians. he says the country has long nigeria and nigeria’s economy. Pointer-Gen: muhammadu buhari says he plans to aggressively fight corruption in the northeast part of nigeria. he says he’ll “rapidly give attention” to curbing violence in the northeast part of nigeria. he says his administration is confident it will be able to thwart criminals. Pointer-Gen + Coverage: muhammadu buhari says he plans to aggressively fight corruption that has long plagued nigeria. he says his administration is confident it will be able to thwart criminals. the win comes after a long history of military rule, coups and botched attempts at democracy in africa’s most populous nation.
Original Text (truncated): lagos, nigeria (cnn) a day after winning nigeria’s presidency, muhammadu buhari told cnn’s christiane amanpour that he plans to aggressively fight corruption that has long plagued nigeria and go after the root of the nation’s unrest. buhari said he’ll “rapidly give attention” to curbing violence in the northeast part of nigeria, where the terrorist group boko haram operates. by cooperating with neighboring nations chad, cameroon and niger, he said his administration is confident it will be able to thwart criminals and others contributing to nigeria’s instability. for the first time in nigeria’s history, the opposition defeated the ruling party in democratic elections. buhari defeated incumbent goodluck jonathan by about 2 million votes, according to nigeria’s independent national electoral commission. the win comes after a long history of military rule, coups and botched attempts at democracy in africa’s most populous nation. Baseline Seq2Seq + Attention: UNK UNK says his administration is confident it will be able to destabilize nigeria’s economy. UNK says his administration is confident it will be able to thwart criminals and other nigerians. he says the country has long nigeria and nigeria’s economy. Pointer-Gen: muhammadu buhari says he plans to aggressively fight corruption in the northeast part of nigeria. he says he’ll “rapidly give attention” to curbing violence in the northeast part of nigeria. he says his administration is confident it will be able to thwart criminals. Pointer-Gen + Coverage: muhammadu buhari says he plans to aggressively fight corruption that has long plagued nigeria. he says his administration is confident it will be able to thwart criminals. the win comes after a long history of military rule, coups and botched attempts at democracy in africa’s most populous nation.
Figure 1: Comparison of output of 3 abstractive summarization models on a news article. The baseline model makes factual errors, a nonsensical sentence and struggles with OOV words muhammadu buhari. The pointer-generator model is accurate but repeats itself. Coverage eliminates repetition. The final summary is composed from several fragments.
图 1:三种抽象式摘要模型在同一篇新闻上的输出对比。基线模型会出现事实错误、不通顺的句子,并且难以处理未登录词 muhammadu buhari。指针生成模型内容准确,但会自我重复。覆盖机制消除了重复。最终摘要由若干片段拼接而成。
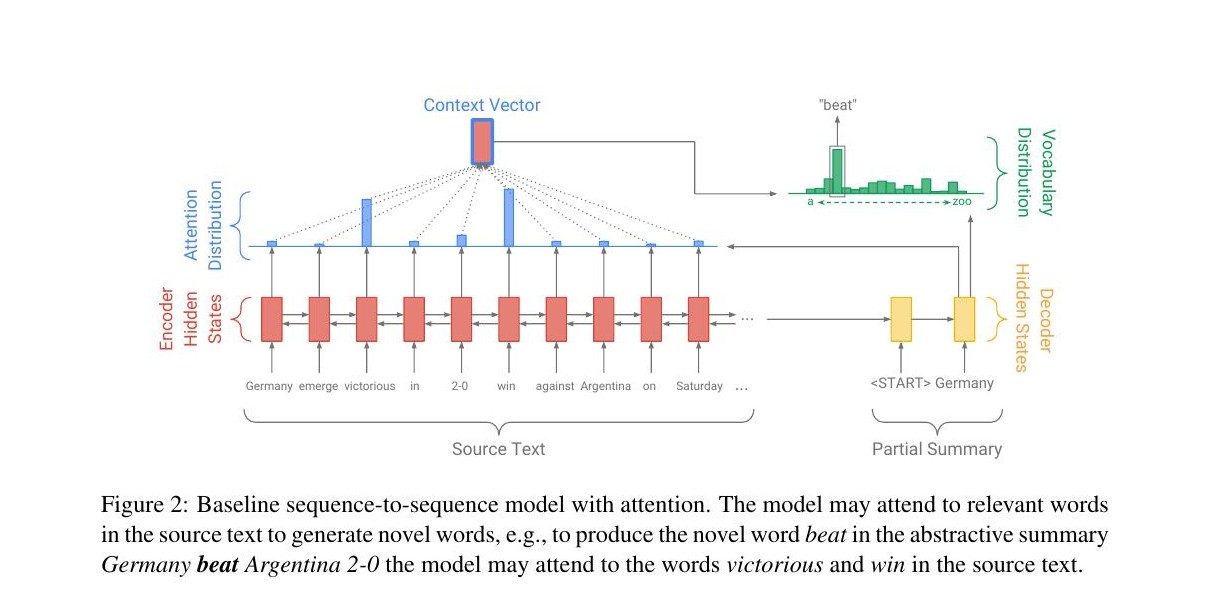
Figure 2: Baseline sequence-to-sequence model with attention. The model may attend to relevant words in the source text to generate novel words, e.g., to produce the novel word beat in the abstractive summary Germany beat Argentina 2-0 the model may attend to the words victorious and win in the source text.
图 2:带注意力的基线序列到序列模型。模型可以关注源文本中的相关词来生成新词。例如,要在抽象式摘要 Germany beat Argentina 2-0 中写出新词 beat,模型可能会关注源文本里的 victorious 和 win。
1 Introduction
1 引言
Summarization is the task of condensing a piece of text to a shorter version that contains the main information from the original. There are two broad approaches to summarization: extractive and abstractive. Extractive methods assemble summaries exclusively from passages (usually whole sentences) taken directly from the source text, while abstractive methods may generate novel words and phrases not featured in the source text – as a human-written abstract usually does. The extractive approach is easier, because copying large chunks of text from the source document ensures baseline levels of grammaticality and accuracy. On the other hand, sophisticated abilities that are crucial to high-quality summarization, such as paraphrasing, generalization, or the incorporation of real-world knowledge, are possible only in an abstractive framework (see Figure 5).
摘要的任务,是把一段文字压成更短的版本,同时保留原文的主要信息。大致有两种路径:抽取式和抽象式。抽取式方法只从源文本中取出片段(通常是整句)来拼成摘要;抽象式方法则可以写出源文本里没有出现过的新词和新短语——就像人写的文摘那样。抽取式更容易做,因为直接从原文复制大段文字,语法和准确性通常有基本保障。另一方面,高质量摘要所需要的复杂能力,例如释义、概括,或融入外部世界知识,只可能出现在抽象式框架里(见图 5)。
Due to the difficulty of abstractive summarization, the great majority of past work has been extractive Kupiec et al. 1995; Paice 1990; Saggion and Poibeau 2013. However, the recent success of sequence-to-sequence models Sutskever et al. 2014, in which recurrent neural networks (RNNs) both read and freely generate text, has made abstractive summarization viable Chopra et al. 2016; Nallapati et al. 2016; Rush et al. 2015; Zeng et al. 2016. Though these systems are promising, they exhibit undesirable behavior such as inaccurately reproducing factual details, an inability to deal with out-of-vocabulary (OOV) words, and repeating themselves (see Figure 1).
正因为抽象式摘要很难,以往绝大多数工作都是抽取式的(Kupiec 等,1995;Paice,1990;Saggion 与 Poibeau,2013)。不过,序列到序列模型(Sutskever 等,2014)近来取得成功:循环神经网络既可以读入文本,也可以自由生成文本,这使抽象式摘要变得可行(Chopra 等,2016;Nallapati 等,2016;Rush 等,2015;Zeng 等,2016)。这些系统虽然有前景,却也表现出一些不理想的行为:事实细节复述不准、无法处理未登录词(OOV),以及自我重复(见图 1)。
In this paper we present an architecture that addresses these three issues in the context of multi-sentence summaries. While most recent abstractive work has focused on headline generation tasks (reducing one or two sentences to a single headline), we believe that longer-text summarization is both more challenging (requiring higher levels of abstraction while avoiding repetition) and ultimately more useful. Therefore we apply our model to the recently-introduced CNN/Daily Mail dataset Hermann et al. 2015; Nallapati et al. 2016, which contains news articles (39 sentences on average) paired with multi-sentence summaries, and show that we outperform the state-of-the-art abstractive system by at least 2 ROUGE points.
本文提出一种架构,在多句摘要的设定下同时应对这三个问题。近期的抽象式工作大多聚焦标题生成(把一两句话压成一个标题);我们则认为,更长文本的摘要既更有挑战(既要更高程度的抽象,又要避免重复),也更有实际价值。因此我们把模型用在当时新发布的 CNN/Daily Mail 数据集上(Hermann 等,2015;Nallapati 等,2016):新闻正文平均 39 句,配有多句摘要。结果显示,我们比当时最好的抽象式系统至少高出 2 个 ROUGE 点。
Our hybrid pointer-generator network facilitates copying words from the source text via pointing Vinyals et al. 2015, which improves accuracy and handling of OOV words, while retaining the ability to generate new words. The network, which can be viewed as a balance between extractive and abstractive approaches, is similar to Gu et al. 2016’s Gu et al. 2016 CopyNet and Miao and Blunsom 2016’s Miao and Blunsom 2016 Forced-Attention Sentence Compression, that were applied to short-text summarization. We propose a novel variant of the coverage vector Tu et al. 2016 from Neural Machine Translation, which we use to track and control coverage of the source document. We show that coverage is remarkably effective for eliminating repetition.
我们的混合指针生成网络可以通过指向从源文本复制词语(Vinyals 等,2015),从而提升准确性并更好地处理未登录词,同时仍能生成新词。这个网络可以看成抽取式与抽象式之间的折中,与 Gu 等(2016)的 CopyNet,以及 Miao 与 Blunsom(2016)的 Forced-Attention Sentence Compression 相近,后两者当时主要用于短文本摘要。我们还对神经机器翻译中的覆盖向量(Tu 等,2016)提出一种新变体,用来跟踪并控制对源文档的覆盖。实验表明,覆盖机制在消除重复上非常有效。
2 Our Models
2 我们的模型
In this section we describe (1) our baseline sequence-to-sequence model, (2) our pointer-generator model, and (3) our coverage mechanism that can be added to either of the first two models. The code for our models is available online.[^1]
本节依次介绍(1)基线序列到序列模型,(2)指针生成模型,以及(3)可以加到前两者之上的覆盖机制。模型代码已在网上公开。[^1]
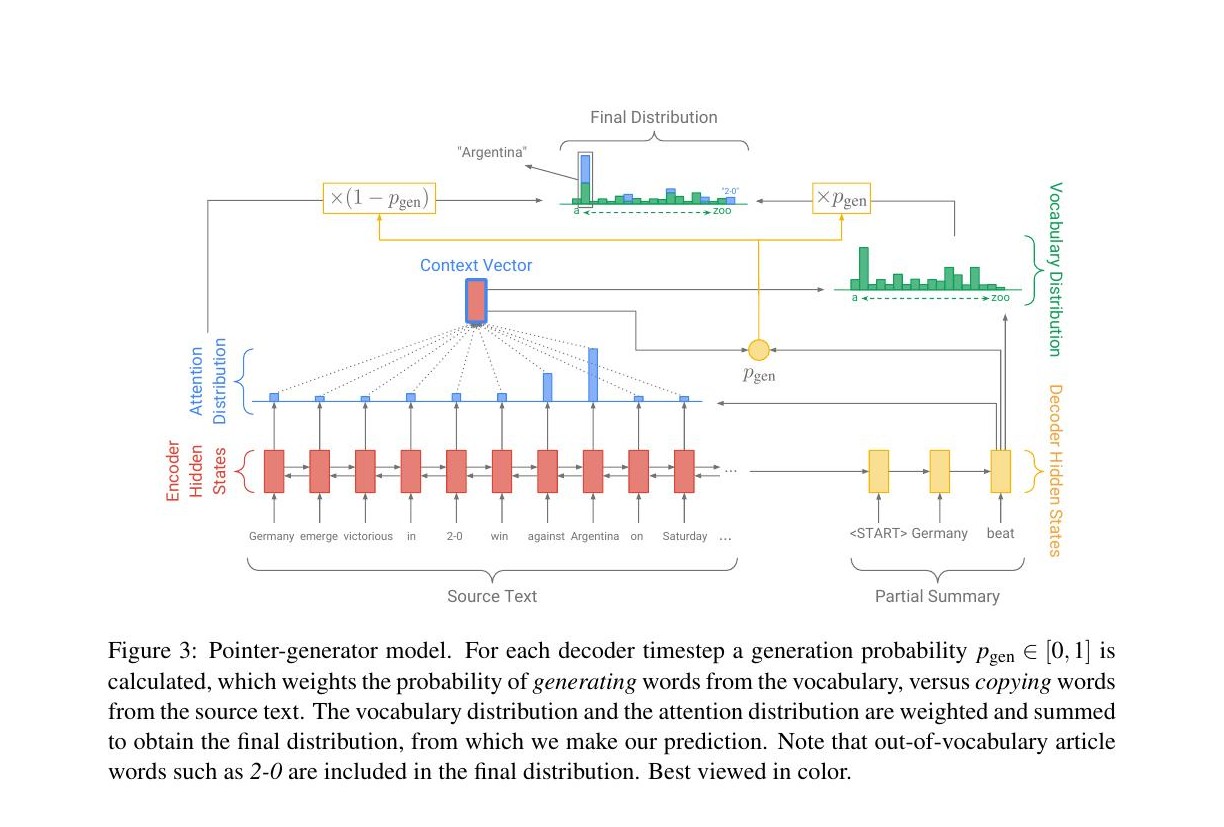
Figure 3: Pointer-generator model. For each decoder timestep a generation probability is calculated, which weights the probability of generating words from the vocabulary, versus copying words from the source text. The vocabulary distribution and the attention distribution are weighted and summed to obtain the final distribution, from which we make our prediction. Note that out-of-vocabulary article words such as 2-0 are included in the final distribution. Best viewed in color.
图 3:指针生成模型。在解码器的每个时间步,计算一个生成概率 ,用来权衡是从词表中生成词语,还是从源文本中复制词语。词表分布与注意力分布加权求和,得到最终分布,再据此做出预测。注意,像 2-0 这样的未登录文章词也会进入最终分布。建议查看彩色版本。
2.1 Sequence-to-sequence attentional model
2.1 带注意力的序列到序列模型
Our baseline model is similar to that of Nallapati et al. 2016 Nallapati et al. 2016, and is depicted in Figure 2. The tokens of the article are fed one-by-one into the encoder (a single-layer bidirectional LSTM), producing a sequence of encoder hidden states . On each step , the decoder (a single-layer unidirectional LSTM) receives the word embedding of the previous word (while training, this is the previous word of the reference summary; at test time it is the previous word emitted by the decoder), and has decoder state . The attention distribution is calculated as in Bahdanau et al. 2015 Bahdanau et al. 2015:
我们的基线模型与 Nallapati 等(2016)相近,结构见图 2。文章中的词元 逐个送入编码器(单层双向 LSTM),得到一串编码器隐状态 。在每个时间步 ,解码器(单层单向 LSTM)接收前一个词的词嵌入(训练时是参考摘要的前一个词;测试时是解码器刚刚写出的词),并具有解码器状态 。注意力分布 按 Bahdanau 等(2015)计算:
where , , and are learnable parameters. The attention distribution can be viewed as a probability distribution over the source words, that tells the decoder where to look to produce the next word. Next, the attention distribution is used to produce a weighted sum of the encoder hidden states, known as the context vector :
其中 、、 和 是可学习参数。注意力分布可以看成源词上的概率分布,告诉解码器接下来应该看哪里才能写出下一个词。随后,用注意力分布对编码器隐状态做加权求和,得到所谓的上下文向量 :
The context vector, which can be seen as a fixed-size representation of what has been read from the source for this step, is concatenated with the decoder state and fed through two linear layers to produce the vocabulary distribution :
上下文向量可以看成:本步从源文本中读到的内容的固定维度表示。它与解码器状态 拼接后,经过两层线性变换,得到词表分布 :
where , , and are learnable parameters. is a probability distribution over all words in the vocabulary, and provides us with our final distribution from which to predict words :
其中 、、 和 是可学习参数。 是词表中所有词上的概率分布,也就是我们用来预测词语 的最终分布:
During training, the loss for timestep is the negative log likelihood of the target word for that timestep:
训练时,时间步 的损失是该步目标词 的负对数似然:
and the overall loss for the whole sequence is:
整个序列的总体损失为:
2.2 Pointer-generator network
2.2 指针生成网络
Our pointer-generator network is a hybrid between our baseline and a pointer network Vinyals et al. 2015, as it allows both copying words via pointing, and generating words from a fixed vocabulary. In the pointer-generator model (depicted in Figure 3) the attention distribution and context vector are calculated as in section 2.1. In addition, the generation probability for timestep is calculated from the context vector , the decoder state and the decoder input :
指针生成网络是基线模型与指针网络(Vinyals 等,2015)的混合体:既可以靠指向来复制词语,也可以从固定词表中生成词语。在指针生成模型(见图 3)中,注意力分布 和上下文向量 的计算与 2.1 节相同。此外,时间步 的生成概率 由上下文向量 、解码器状态 和解码器输入 算出:
where vectors , , and scalar are learnable parameters and is the sigmoid function. Next, is used as a soft switch to choose between generating a word from the vocabulary by sampling from , or copying a word from the input sequence by sampling from the attention distribution . For each document let the extended vocabulary denote the union of the vocabulary, and all words appearing in the source document. We obtain the following probability distribution over the extended vocabulary:
其中向量 、、 以及标量 是可学习参数, 是 sigmoid 函数。接下来, 充当软开关:要么从 中采样,从词表生成一个词;要么从注意力分布 中采样,从输入序列复制一个词。对每篇文档,令扩展词表表示原词表与源文档中所有词的并集。我们得到扩展词表上的如下概率分布:
Note that if is an out-of-vocabulary (OOV) word, then is zero; similarly if does not appear in the source document, then is zero. The ability to produce OOV words is one of the primary advantages of pointer-generator models; by contrast models such as our baseline are restricted to their pre-set vocabulary.
注意,若 是未登录词(OOV),则 为零;同样,若 没有出现在源文档中,则 为零。能够写出未登录词,是指针生成模型的主要优势之一;相比之下,我们的基线这类模型只能使用预先设定的词表。
The loss function is as described in equations (6) and (7), but with respect to our modified probability distribution given in equation (9).
损失函数仍如公式 (6) 和 (7) 所述,只是其中的概率分布换成公式 (9) 给出的修正后的 。
2.3 Coverage mechanism
2.3 覆盖机制
Repetition is a common problem for sequence-to-sequence models Tu et al. 2016; Mi et al. 2016; Sankaran et al. 2016; Suzuki and Nagata 2016, and is especially pronounced when generating multi-sentence text (see Figure 1). We adapt the coverage model of Tu et al. 2016 Tu et al. 2016 to solve the problem. In our coverage model, we maintain a coverage vector , which is the sum of attention distributions over all previous decoder timesteps:
重复是序列到序列模型的常见问题(Tu 等,2016;Mi 等,2016;Sankaran 等,2016;Suzuki 与 Nagata,2016),在生成多句文本时尤其明显(见图 1)。我们改编 Tu 等(2016)的覆盖模型来解决这个问题。在覆盖模型中,我们维护一个覆盖向量 ,它是此前所有解码时间步注意力分布的总和:
Intuitively, is a (unnormalized) distribution over the source document words that represents the degree of coverage that those words have received from the attention mechanism so far. Note that is a zero vector, because on the first timestep, none of the source document has been covered.
直观上, 是源文档词语上的(未归一化)分布,表示到目前为止注意力机制对这些词的覆盖程度。注意 是零向量,因为第一步时源文档尚未被覆盖。
The coverage vector is used as extra input to the attention mechanism, changing equation (1) to:
覆盖向量会作为注意力机制的额外输入,从而把公式 (1) 改成:
where is a learnable parameter vector of same length as . This ensures that the attention mechanism’s current decision (choosing where to attend next) is informed by a reminder of its previous decisions (summarized in ). This should make it easier for the attention mechanism to avoid repeatedly attending to the same locations, and thus avoid generating repetitive text.
其中 是与 长度相同的可学习参数向量。这样,注意力机制当前的决策(下一步看哪里)就会被此前决策的提示所引导(这些决策汇总在 里)。这应能让注意力机制更不容易反复关注同一位置,从而避免生成重复文本。
We find it necessary (see section 5) to additionally define a coverage loss to penalize repeatedly attending to the same locations:
我们发现还有必要(见第 5 节)额外定义一个覆盖损失,用来惩罚反复关注同一位置:
Note that the coverage loss is bounded; in particular . Equation (12) differs from the coverage loss used in Machine Translation. In MT, we assume that there should be a roughly one-to-one translation ratio; accordingly the final coverage vector is penalized if it is more or less than 1. Our loss function is more flexible: because summarization should not require uniform coverage, we only penalize the overlap between each attention distribution and the coverage so far – preventing repeated attention. Finally, the coverage loss, reweighted by some hyperparameter , is added to the primary loss function to yield a new composite loss function:
注意覆盖损失是有上界的;特别地,。公式 (12) 与机器翻译中使用的覆盖损失不同。在机器翻译里,人们假定翻译大致是一对一的,因此若最终覆盖向量明显高于或低于 1,就会受到惩罚。我们的损失函数更灵活:摘要并不要求均匀覆盖,所以我们只惩罚每一步注意力分布与截至目前的覆盖之间的重叠——从而阻止重复关注。最后,覆盖损失再乘以超参数 ,加到主损失上,得到新的复合损失:
3 Related Work
3 相关工作
Neural abstractive summarization. Rush et al. 2015 Rush et al. 2015 were the first to apply modern neural networks to abstractive text summarization, achieving state-of-the-art performance on DUC-2004 and Gigaword, two sentence-level summarization datasets. Their approach, which is centered on the attention mechanism, has been augmented with recurrent decoders Chopra et al. 2016, Abstract Meaning Representations Takase et al. 2016, hierarchical networks Nallapati et al. 2016, variational autoencoders Miao and Blunsom 2016, and direct optimization of the performance metric Ranzato et al. 2016, further improving performance on those datasets.
神经抽象式摘要。 Rush 等(2015)最早把现代神经网络用于抽象式文本摘要,并在 DUC-2004 和 Gigaword 这两个句子级摘要数据集上取得了当时最好的结果。他们以注意力机制为核心的方法,随后被循环解码器(Chopra 等,2016)、抽象语义表示(Takase 等,2016)、层次网络(Nallapati 等,2016)、变分自编码器(Miao 与 Blunsom,2016)以及对性能指标的直接优化(Ranzato 等,2016)进一步增强,并继续提升了这些数据集上的表现。
However, large-scale datasets for summarization of longer text are rare. Nallapati et al. 2016 Nallapati et al. 2016 adapted the DeepMind question-answering dataset Hermann et al. 2015 for summarization, resulting in the CNN/Daily Mail dataset, and provided the first abstractive baselines. The same authors then published a neural extractive approach Nallapati et al. 2017, which uses hierarchical RNNs to select sentences, and found that it significantly outperformed their abstractive result with respect to the ROUGE metric. To our knowledge, these are the only two published results on the full dataset.
然而,面向更长文本摘要的大规模数据集并不多见。Nallapati 等(2016)把 DeepMind 问答数据集(Hermann 等,2015)改造成摘要数据,得到 CNN/Daily Mail 数据集,并给出了第一批抽象式基线。同一批作者随后发表了一种神经抽取式方法(Nallapati 等,2017),用层次 RNN 挑选句子,并发现就 ROUGE 指标而言,它显著超过了他们的抽象式结果。据我们所知,这是当时在完整数据集上仅有的两项已发表结果。
Prior to modern neural methods, abstractive summarization received less attention than extractive summarization, but Jing 2000 Jing 2000 explored cutting unimportant parts of sentences to create summaries, and Cheung and Penn 2014 Cheung and Penn 2014 explore sentence fusion using dependency trees.
在现代神经方法出现之前,抽象式摘要得到的关注少于抽取式。不过 Jing(2000)探讨过删去句子中不重要的部分来生成摘要,Cheung 与 Penn(2014)则用依存树做句子融合。
Pointer-generator networks. The pointer network Vinyals et al. 2015 is a sequence-to-sequence model that uses the soft attention distribution of Bahdanau et al. 2015 Bahdanau et al. 2015 to produce an output sequence consisting of elements from the input sequence. The pointer network has been used to create hybrid approaches for NMT Gulcehre et al. 2016, language modeling Merity et al. 2016, and summarization Gu et al. 2016; Gulcehre et al. 2016; Miao and Blunsom 2016; Nallapati et al. 2016; Zeng et al. 2016.
指针生成网络。 指针网络(Vinyals 等,2015)是一种序列到序列模型,它利用 Bahdanau 等(2015)的软注意力分布,生成一个完全由输入序列中元素组成的输出序列。指针网络已被用来构建神经机器翻译(Gulcehre 等,2016)、语言建模(Merity 等,2016)以及摘要(Gu 等,2016;Gulcehre 等,2016;Miao 与 Blunsom,2016;Nallapati 等,2016;Zeng 等,2016)中的混合方法。
Our approach is close to the Forced-Attention Sentence Compression model of Miao and Blunsom 2016 Miao and Blunsom 2016 and the CopyNet model of Gu et al. 2016 Gu et al. 2016, with some small differences: (i) We calculate an explicit switch probability , whereas Gu et al. induce competition through a shared softmax function. (ii) We recycle the attention distribution to serve as the copy distribution, but Gu et al. use two separate distributions. (iii) When a word appears multiple times in the source text, we sum probability mass from all corresponding parts of the attention distribution, whereas Miao and Blunsom do not. Our reasoning is that (i) calculating an explicit usefully enables us to raise or lower the probability of all generated words or all copy words at once, rather than individually, (ii) the two distributions serve such similar purposes that we find our simpler approach suffices, and (iii) we observe that the pointer mechanism often copies a word while attending to multiple occurrences of it in the source text.
我们的方法接近 Miao 与 Blunsom(2016)的 Forced-Attention Sentence Compression,以及 Gu 等(2016)的 CopyNet,但有几处细小差别:(i)我们显式计算开关概率 ,而 Gu 等人通过共享的 softmax 来诱导竞争。(ii)我们复用注意力分布作为复制分布,而 Gu 等人使用两个独立分布。(iii)当一个词在源文本中多次出现时,我们把注意力分布中所有对应位置的概率质量加总,而 Miao 与 Blunsom 没有这样做。我们的理由是:(i)显式计算 ,可以一次提高或降低所有生成词或所有复制词的概率,而不必逐个调整;(ii)这两个分布用途十分接近,我们发现更简单的做法已经够用;(iii)我们观察到,指针机制在复制某个词时,常常会同时关注源文本中该词的多处出现。
Our approach is considerably different from that of Gulcehre et al. 2016 and Nallapati et al. 2016. Those works train their pointer components to activate only for out-of-vocabulary words or named entities (whereas we allow our model to freely learn when to use the pointer), and they do not mix the probabilities from the copy distribution and the vocabulary distribution. We believe the mixture approach described here is better for abstractive summarization – in section 6 we show that the copy mechanism is vital for accurately reproducing rare but in-vocabulary words, and in section 7.2 we observe that the mixture model enables the language model and copy mechanism to work together to perform abstractive copying.
我们的方法与 Gulcehre 等(2016)以及 Nallapati 等(2016)有明显不同。那些工作把指针组件训练成只在未登录词或命名实体上激活(而我们允许模型自由学习何时使用指针),并且不把复制分布与词表分布的概率混合起来。我们认为本文描述的混合方式更适合抽象式摘要——第 6 节会说明,复制机制对准确复述那些虽在词表内但较为罕见的词至关重要;第 7.2 节还会看到,混合模型能让语言模型与复制机制一起工作,完成带有抽象意味的复制。
Coverage. Originating from Statistical Machine Translation Koehn 2009, coverage was adapted for NMT by Tu et al. 2016 Tu et al. 2016 and Mi et al. 2016 Mi et al. 2016, who both use a GRU to update the coverage vector each step. We find that a simpler approach – summing the attention distributions to obtain the coverage vector – suffices. In this respect our approach is similar to Xu et al. 2015 Xu et al. 2015, who apply a coverage-like method to image captioning, and Chen et al. 2016 Chen et al. 2016, who also incorporate a coverage mechanism (which they call ‘distraction’) as described in equation (11) into neural summarization of longer text.
覆盖。 覆盖源自统计机器翻译(Koehn,2009),后由 Tu 等(2016)和 Mi 等(2016)引入神经机器翻译;两者都用 GRU 在每一步更新覆盖向量。我们发现一种更简单的做法——把注意力分布直接加总得到覆盖向量——已经足够。在这一点上,我们的方法接近 Xu 等(2015)把类似覆盖的方法用于图像描述,也接近 Chen 等(2016)把公式 (11) 所述的覆盖机制(他们称为“分心”)引入更长文本的神经摘要。
Temporal attention is a related technique that has been applied to NMT Sankaran et al. 2016 and summarization Nallapati et al. 2016. In this approach, each attention distribution is divided by the sum of the previous, which effectively dampens repeated attention. We tried this method but found it too destructive, distorting the signal from the attention mechanism and reducing performance. We hypothesize that an early intervention method such as coverage is preferable to a post hoc method such as temporal attention – it is better to inform the attention mechanism to help it make better decisions, than to override its decisions altogether. This theory is supported by the large boost that coverage gives our ROUGE scores (see Table 1), compared to the smaller boost given by temporal attention for the same task Nallapati et al. 2016.
时间注意力是一种相关技术,已被用于神经机器翻译(Sankaran 等,2016)和摘要(Nallapati 等,2016)。这种方法把每个注意力分布除以此前各步之和,从而压低重复关注。我们尝试过这种方法,但发现它过于具有破坏性:会扭曲注意力机制的信号并降低性能。我们推测,像覆盖这样的早期干预,要比时间注意力这种事后修正更好——与其事后完全改写注意力的决定,不如事先告知注意力机制,帮助它做出更好的决定。表 1 中覆盖给 ROUGE 带来的大幅提升,相对 Nallapati 等(2016)在同一任务上时间注意力带来的较小提升,也支持这一判断。
4 Dataset
4 数据集
We use the CNN/Daily Mail dataset Hermann et al. 2015; Nallapati et al. 2016, which contains online news articles (781 tokens on average) paired with multi-sentence summaries (3.75 sentences or 56 tokens on average). We used scripts supplied by Nallapati et al. 2016 to obtain the same version of the the data, which has 287,226 training pairs, 13,368 validation pairs and 11,490 test pairs. Both the dataset’s published results Nallapati et al. 2016; Nallapati et al. 2017 use the anonymized version of the data, which has been pre-processed to replace each named entity, e.g., The United Nations, with its own unique identifier for the example pair, e.g., @entity5. By contrast, we operate directly on the original text (or non-anonymized version of the data),[^2] which we believe is the favorable problem to solve because it requires no pre-processing.
我们使用 CNN/Daily Mail 数据集(Hermann 等,2015;Nallapati 等,2016),其中在线新闻文章平均 781 个词元,配有多句摘要(平均 3.75 句,或 56 个词元)。我们使用 Nallapati 等(2016)提供的脚本得到同一版本的数据:287,226 对训练样本、13,368 对验证样本和 11,490 对测试样本。该数据集已发表的结果(Nallapati 等,2016;Nallapati 等,2017)都使用匿名化版本:预处理会把每个命名实体(例如 The United Nations)替换成该样本对中独有的标识符(例如 @entity5)。我们则直接在原文(或称数据的非匿名化版本)上操作,[^2] 我们认为这是更可取的问题设定,因为它不需要额外的预处理。
| ROUGE | METEOR | ||||
|---|---|---|---|---|---|
| 1 | 2 | L | exact match | + stem/syn/para | |
| abstractive model Nallapati et al. 2016* | 35.46 | 13.30 | 32.65 | - | - |
| seq-to-seq + attn baseline (150k vocab) | 30.49 | 11.17 | 28.08 | 11.65 | 12.86 |
| seq-to-seq + attn baseline (50k vocab) | 31.33 | 11.81 | 28.83 | 12.03 | 13.20 |
| pointer-generator | 36.44 | 15.66 | 33.42 | 15.35 | 16.65 |
| pointer-generator + coverage | 39.53 | 17.28 | 36.38 | 17.32 | 18.72 |
| lead-3 baseline (ours) | 40.34 | 17.70 | 36.57 | 20.48 | 22.21 |
| lead-3 baseline Nallapati et al. 2017* | 39.2 | 15.7 | 35.5 | - | - |
| extractive model Nallapati et al. 2017* | 39.6 | 16.2 | 35.3 | - | - |
Table 1: ROUGE F1 and METEOR scores on the test set. Models and baselines in the top half are abstractive, while those in the bottom half are extractive. Those marked with * were trained and evaluated on the anonymized dataset, and so are not strictly comparable to our results on the original text. All our ROUGE scores have a 95% confidence interval of at most as reported by the official ROUGE script. The METEOR improvement from the 50k baseline to the pointer-generator model, and from the pointer-generator to the pointer-generator+coverage model, were both found to be statistically significant using an approximate randomization test with .
| ROUGE | METEOR | ||||
|---|---|---|---|---|---|
| 1 | 2 | L | exact match | + stem/syn/para | |
| abstractive model Nallapati 等,2016* | 35.46 | 13.30 | 32.65 | - | - |
| seq-to-seq + attn baseline (150k vocab) | 30.49 | 11.17 | 28.08 | 11.65 | 12.86 |
| seq-to-seq + attn baseline (50k vocab) | 31.33 | 11.81 | 28.83 | 12.03 | 13.20 |
| pointer-generator | 36.44 | 15.66 | 33.42 | 15.35 | 16.65 |
| pointer-generator + coverage | 39.53 | 17.28 | 36.38 | 17.32 | 18.72 |
| lead-3 baseline (ours) | 40.34 | 17.70 | 36.57 | 20.48 | 22.21 |
| lead-3 baseline Nallapati 等,2017* | 39.2 | 15.7 | 35.5 | - | - |
| extractive model Nallapati 等,2017* | 39.6 | 16.2 | 35.3 | - | - |
表 1:测试集上的 ROUGE F1 与 METEOR 分数。上半部分的模型与基线是抽象式,下半部分是抽取式。标 * 的系统在匿名化数据集上训练和评估,因此与我们在原文上的结果并不严格可比。我们所有 ROUGE 分数由官方 ROUGE 脚本报告的 95% 置信区间至多为 。从 50k 词表基线到指针生成模型,以及从指针生成模型到指针生成+覆盖模型,METEOR 的提升均通过近似随机化检验,在 下具有统计显著性。
5 Experiments
5 实验
For all experiments, our model has 256-dimensional hidden states and 128-dimensional word embeddings. For the pointer-generator models, we use a vocabulary of 50k words for both source and target – note that due to the pointer network’s ability to handle OOV words, we can use a smaller vocabulary size than Nallapati et al. 2016’s Nallapati et al. 2016 150k source and 60k target vocabularies. For the baseline model, we also try a larger vocabulary size of 150k.
所有实验中,模型使用 256 维隐状态和 128 维词嵌入。指针生成模型的源端和目标端都使用 50k 词表——由于指针网络能够处理未登录词,我们可以使用比 Nallapati 等(2016)更小的词表(他们使用 150k 源词表和 60k 目标词表)。对基线模型,我们也尝试了 150k 的更大词表。
Note that the pointer and the coverage mechanism introduce very few additional parameters to the network: for the models with vocabulary size 50k, the baseline model has 21,499,600 parameters, the pointer-generator adds 1153 extra parameters (, , and in equation 8), and coverage adds 512 extra parameters ( in equation 11).
注意,指针和覆盖机制给网络增加的参数非常少:在词表大小为 50k 的模型中,基线有 21,499,600 个参数,指针生成只额外增加 1153 个参数(公式 8 中的 、、 和 ),覆盖再增加 512 个参数(公式 11 中的 )。
Unlike Nallapati et al. 2016, we do not pre-train the word embeddings – they are learned from scratch during training. We train using Adagrad Duchi et al. 2011 with learning rate 0.15 and an initial accumulator value of 0.1. (This was found to work best of Stochastic Gradient Descent, Adadelta, Momentum, Adam and RMSProp). We use gradient clipping with a maximum gradient norm of 2, but do not use any form of regularization. We use loss on the validation set to implement early stopping.
与 Nallapati 等(2016)不同,我们不预训练词嵌入,而是在训练过程中从头学习。优化使用 Adagrad(Duchi 等,2011),学习率 0.15,初始累加值为 0.1。(在随机梯度下降、Adadelta、Momentum、Adam 和 RMSProp 中,这一设置表现最好。)我们使用梯度裁剪,最大梯度范数为 2,但不使用任何形式的正则化。早停依据验证集损失。
During training and at test time we truncate the article to 400 tokens and limit the length of the summary to 100 tokens for training and 120 tokens at test time.[^3] This is done to expedite training and testing, but we also found that truncating the article can raise the performance of the model (see section 7.1 for more details). For training, we found it efficient to start with highly-truncated sequences, then raise the maximum length once converged. We train on a single Tesla K40m GPU with a batch size of 16. At test time our summaries are produced using beam search with beam size 4.
训练和测试时,我们把文章截断到 400 个词元;摘要长度在训练时限制为 100 个词元,测试时限制为 120 个词元。[^3] 这样做是为了加快训练和测试,不过我们也发现截断文章反而可能提高模型表现(详见 7.1 节)。训练时,我们先从高度截断的序列起步,收敛后再提高最大长度,这样更有效率。我们在单块 Tesla K40m GPU 上训练,批次大小为 16。测试时用束搜索生成摘要,束宽为 4。
We trained both our baseline models for about 600,000 iterations (33 epochs) – this is similar to the 35 epochs required by Nallapati et al. 2016’s Nallapati et al. 2016 best model. Training took 4 days and 14 hours for the 50k vocabulary model, and 8 days 21 hours for the 150k vocabulary model. We found the pointer-generator model quicker to train, requiring less than 230,000 training iterations (12.8 epochs); a total of 3 days and 4 hours. In particular, the pointer-generator model makes much quicker progress in the early phases of training. To obtain our final coverage model, we added the coverage mechanism with coverage loss weighted to (as described in equation 13), and trained for a further 3000 iterations (about 2 hours). In this time the coverage loss converged to about 0.2, down from an initial value of about 0.5. We also tried a more aggressive value of ; this reduced coverage loss but increased the primary loss function, thus we did not use it.
两个基线模型大约训练了 600,000 次迭代(33 个周期)——这与 Nallapati 等(2016)最佳模型所需的 35 个周期相近。50k 词表模型训练耗时 4 天 14 小时,150k 词表模型耗时 8 天 21 小时。我们发现指针生成模型训练更快,所需迭代不到 230,000 次(12.8 个周期),总共 3 天 4 小时。尤其在训练早期,指针生成模型进展明显更快。为得到最终的覆盖模型,我们加入覆盖机制,并把覆盖损失的权重设为 (见公式 13),再额外训练 3000 次迭代(约 2 小时)。在此期间,覆盖损失从最初的约 0.5 收敛到约 0.2。我们也试过更强的 :覆盖损失下降了,但主损失上升,因此没有采用。
We tried training the coverage model without the loss function, hoping that the attention mechanism may learn by itself not to attend repeatedly to the same locations, but we found this to be ineffective, with no discernible reduction in repetition. We also tried training with coverage from the first iteration rather than as a separate training phase, but found that in the early phase of training, the coverage objective interfered with the main objective, reducing overall performance.
我们曾尝试在没有覆盖损失的情况下训练覆盖模型,希望注意力机制能自己学会不要反复关注同一位置,但发现这没有效果,重复现象没有可辨别的减少。我们也试过从第一次迭代起就加入覆盖,而不是分成单独的训练阶段,但发现在训练早期,覆盖目标会干扰主目标,从而降低整体表现。
6 Results
6 结果
6.1 Preliminaries
6.1 预备说明
Our results are given in Table 1. We evaluate our models with the standard ROUGE metric Lin 2004b, reporting the F1 scores for ROUGE-1, ROUGE-2 and ROUGE-L (which respectively measure the word-overlap, bigram-overlap, and longest common sequence between the reference summary and the summary to be evaluated). We obtain our ROUGE scores using the pyrouge package.[^4] We also evaluate with the METEOR metric Denkowski and Lavie 2014, both in exact match mode (rewarding only exact matches between words) and full mode (which additionally rewards matching stems, synonyms and paraphrases).[^5]
结果见表 1。我们用标准的 ROUGE 指标(Lin,2004b)评估模型,报告 ROUGE-1、ROUGE-2 和 ROUGE-L 的 F1(分别衡量待评估摘要与参考摘要之间的词重叠、二元组重叠,以及最长公共子序列)。ROUGE 分数通过 pyrouge 包获得。[^4] 我们也用 METEOR 指标(Denkowski 与 Lavie,2014)评估,既报告精确匹配模式(只奖励完全相同的词),也报告完整模式(额外奖励词干、同义词和释义匹配)。[^5]
In addition to our own models, we also report the lead-3 baseline (which uses the first three sentences of the article as a summary), and compare to the only existing abstractive Nallapati et al. 2016 and extractive Nallapati et al. 2017 models on the full dataset. The output of our models is available online.[^6]
除了我们自己的模型,我们也报告 lead-3 基线(把文章的前三句当作摘要),并与完整数据集上当时仅有的抽象式模型(Nallapati 等,2016)和抽取式模型(Nallapati 等,2017)比较。我们模型的输出已在网上公开。[^6]
Given that we generate plain-text summaries but Nallapati et al. Nallapati et al. 2016; Nallapati et al. 2017 generate anonymized summaries (see Section 4), our ROUGE scores are not strictly comparable. There is evidence to suggest that the original-text dataset may result in higher ROUGE scores in general than the anonymized dataset – the lead-3 baseline is higher on the former than the latter. One possible explanation is that multi-word named entities lead to a higher rate of -gram overlap. Unfortunately, ROUGE is the only available means of comparison with Nallapati et al.’s work. Nevertheless, given that the disparity in the lead-3 scores is (+1.1 ROUGE-1, +2.0 ROUGE-2, +1.1 ROUGE-L) points respectively, and our best model scores exceed Nallapati et al. 2016 Nallapati et al. 2016 by (+4.07 ROUGE-1, +3.98 ROUGE-2, +3.73 ROUGE-L) points, we may estimate that we outperform the only previous abstractive system by at least 2 ROUGE points all-round.
由于我们生成的是纯文本摘要,而 Nallapati 等人(2016;2017)生成的是匿名化摘要(见第 4 节),双方的 ROUGE 分数并不严格可比。有证据表明,原文数据集上的 ROUGE 分数总体上可能高于匿名化数据集——lead-3 基线在前者上就更高。一种可能的解释是,由多个词组成的命名实体会提高 元组重叠率。可惜 ROUGE 是当时与 Nallapati 等人工作比较的唯一可用手段。尽管如此,考虑到 lead-3 分数的差距分别是(+1.1 ROUGE-1、+2.0 ROUGE-2、+1.1 ROUGE-L),而我们最佳模型相对 Nallapati 等(2016)的超出幅度是(+4.07 ROUGE-1、+3.98 ROUGE-2、+3.73 ROUGE-L),可以估计我们在各项上至少比此前唯一的抽象式系统高出 2 个 ROUGE 点。
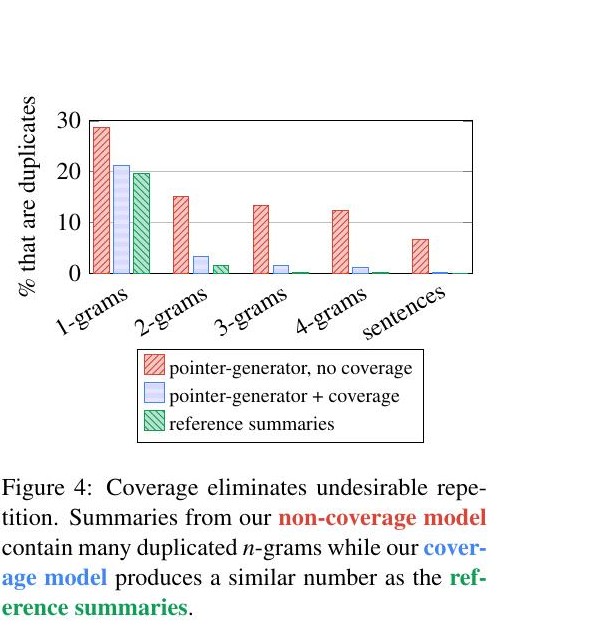
Figure 4: Coverage eliminates undesirable repetition. Summaries from our non-coverage model contain many duplicated -grams while our coverage model produces a similar number as the reference summaries.
图 4:覆盖机制消除了不受欢迎的重复。来自无覆盖模型的摘要含有大量重复的 元组,而覆盖模型产生的重复数量与参考摘要相近。
6.2 Observations
6.2 观察
We find that both our baseline models perform poorly with respect to ROUGE and METEOR, and in fact the larger vocabulary size (150k) does not seem to help. Even the better-performing baseline (with 50k vocabulary) produces summaries with several common problems. Factual details are frequently reproduced incorrectly, often replacing an uncommon (but in-vocabulary) word with a more-common alternative. For example in Figure 1, the baseline model appears to struggle with the rare word thwart, producing destabilize instead, which leads to the fabricated phrase destabilize nigeria’s economy. Even more catastrophically, the summaries sometimes devolve into repetitive nonsense, such as the third sentence produced by the baseline model in Figure 1. In addition, the baseline model can’t reproduce out-of-vocabulary words (such as muhammadu buhari in Figure 1). Further examples of all these problems are provided in the supplementary material.
我们发现两个基线模型在 ROUGE 和 METEOR 上都表现不佳,而且更大的词表(150k)似乎没有帮助。即便是表现更好的那个基线(50k 词表),生成的摘要也有几类常见问题。事实细节经常被错误复述,不常见(但仍在词表内)的词常常被更常见的替代词换掉。例如在图 1 中,基线模型似乎难以处理罕见词 thwart,改写成了 destabilize,进而编造出 destabilize nigeria’s economy 这样的说法。更糟的是,摘要有时会滑向重复的胡话,比如图 1 中基线模型写出的第三句。此外,基线模型无法复述未登录词(如图 1 中的 muhammadu buhari)。补充材料中还提供了这些问题的更多例子。
Our pointer-generator model achieves much better ROUGE and METEOR scores than the baseline, despite many fewer training epochs. The difference in the summaries is also marked: out-of-vocabulary words are handled easily, factual details are almost always copied correctly, and there are no fabrications (see Figure 1). However, repetition is still very common.
尽管训练周期少得多,指针生成模型的 ROUGE 和 METEOR 都明显高于基线。摘要本身的差别也很明显:未登录词可以轻松处理,事实细节几乎总是被正确复制,而且没有编造(见图 1)。不过,重复仍然非常常见。
Our pointer-generator model with coverage improves the ROUGE and METEOR scores further, convincingly surpassing the best abstractive model of Nallapati et al. 2016 Nallapati et al. 2016 by several ROUGE points. Despite the brevity of the coverage training phase (about 1% of the total training time), the repetition problem is almost completely eliminated, which can be seen both qualitatively (Figure 1) and quantitatively (Figure 4). However, our best model does not quite surpass the ROUGE scores of the lead-3 baseline, nor the current best extractive model Nallapati et al. 2017. We discuss this issue in section 7.1.
加入覆盖后的指针生成模型进一步提升了 ROUGE 和 METEOR,以几个 ROUGE 点的优势明确超过 Nallapati 等(2016)最好的抽象式模型。尽管覆盖训练阶段很短(约占全部训练时间的 1%),重复问题几乎被完全消除,这一点既能从定性例子中看出(图 1),也能从定量统计中看出(图 4)。不过,我们最好的模型仍没有超过 lead-3 基线的 ROUGE,也没有超过当时最好的抽取式模型(Nallapati 等,2017)。我们在 7.1 节讨论这个问题。
7 Discussion
7 讨论
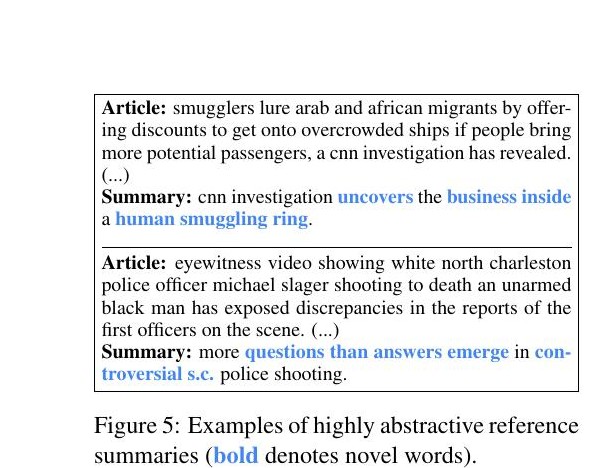
Article: smugglers lure arab and african migrants by offering discounts to get onto overcrowded ships if people bring more potential passengers, a cnn investigation has revealed. (…) Summary: cnn investigation uncovers the business inside a human smuggling ring. Article: eyewitness video showing white north charleston police officer michael slager shooting to death an unarmed black man has exposed discrepancies in the reports of the first officers on the scene. (…) Summary: more questions than answers emerge in controversial s.c. police shooting.
Article: smugglers lure arab and african migrants by offering discounts to get onto overcrowded ships if people bring more potential passengers, a cnn investigation has revealed. (…) Summary: cnn investigation uncovers the business inside a human smuggling ring. Article: eyewitness video showing white north charleston police officer michael slager shooting to death an unarmed black man has exposed discrepancies in the reports of the first officers on the scene. (…) Summary: more questions than answers emerge in controversial s.c. police shooting.
Figure 5: Examples of highly abstractive reference summaries (bold denotes novel words).
图 5:高度抽象的参考摘要示例(粗体表示原文中没有的新词)。
7.1 Comparison with extractive systems
7.1 与抽取式系统的比较
It is clear from Table 1 that extractive systems tend to achieve higher ROUGE scores than abstractive, and that the extractive lead-3 baseline is extremely strong (even the best extractive system beats it by only a small margin). We offer two possible explanations for these observations.
从表 1 可以清楚看出,抽取式系统的 ROUGE 往往高于抽象式,而且抽取式的 lead-3 基线非常强(即便最好的抽取式系统也只比它高出一点)。我们对这些观察提出两种可能的解释。
Firstly, news articles tend to be structured with the most important information at the start; this partially explains the strength of the lead-3 baseline. Indeed, we found that using only the first 400 tokens (about 20 sentences) of the article yielded significantly higher ROUGE scores than using the first 800 tokens.
第一,新闻文章往往把最重要的信息放在开头;这在一定程度上解释了 lead-3 基线为什么强。事实上,我们发现只使用文章的前 400 个词元(大约 20 句),得到的 ROUGE 显著高于使用前 800 个词元。
Secondly, the nature of the task and the ROUGE metric make extractive approaches and the lead-3 baseline difficult to beat. The choice of content for the reference summaries is quite subjective – sometimes the sentences form a self-contained summary; other times they simply showcase a few interesting details from the article. Given that the articles contain 39 sentences on average, there are many equally valid ways to choose 3 or 4 highlights in this style. Abstraction introduces even more options (choice of phrasing), further decreasing the likelihood of matching the reference summary. For example, smugglers profit from desperate migrants is a valid alternative abstractive summary for the first example in Figure 5, but it scores 0 ROUGE with respect to the reference summary. This inflexibility of ROUGE is exacerbated by only having one reference summary, which has been shown to lower ROUGE’s reliability compared to multiple reference summaries Lin 2004a.
第二,任务本身的性质以及 ROUGE 指标,使抽取式方法和 lead-3 基线很难被超越。参考摘要的选材相当主观——有时这几句话本身就能构成独立摘要,有时它们只是展示文章里几个有意思的细节。文章平均有 39 句,按这种风格选出 3 或 4 条要点,合理做法可以有很多种。抽象又引入了更多选择(措辞的选择),进一步降低了与参考摘要匹配的可能性。例如,smugglers profit from desperate migrants 对图 5 中的第一个例子是完全成立的另一种抽象式摘要,但相对参考摘要的 ROUGE 为 0。ROUGE 的这种不灵活,又因为只有一篇参考摘要而加剧;已有研究表明,与使用多篇参考摘要相比,单篇参考会降低 ROUGE 的可靠性(Lin,2004a)。
Due to the subjectivity of the task and thus the diversity of valid summaries, it seems that ROUGE rewards safe strategies such as selecting the first-appearing content, or preserving original phrasing. While the reference summaries do sometimes deviate from these techniques, those deviations are unpredictable enough that the safer strategy obtains higher ROUGE scores on average. This may explain why extractive systems tend to obtain higher ROUGE scores than abstractive, and even extractive systems do not significantly exceed the lead-3 baseline.
由于任务主观、合理摘要多样,ROUGE 似乎更奖励稳妥策略,例如选择最先出现的内容,或尽量保留原文措辞。参考摘要的确有时会偏离这些做法,但这些偏离难以预测,因此更稳妥的策略平均下来会得到更高的 ROUGE。这也许可以解释,为什么抽取式系统的 ROUGE 往往高于抽象式,甚至抽取式系统本身也难以显著超过 lead-3 基线。
To explore this issue further, we evaluated our systems with the METEOR metric, which rewards not only exact word matches, but also matching stems, synonyms and paraphrases (from a pre-defined list). We observe that all our models receive over 1 METEOR point boost by the inclusion of stem, synonym and paraphrase matching, indicating that they may be performing some abstraction. However, we again observe that the lead-3 baseline is not surpassed by our models. It may be that news article style makes the lead-3 baseline very strong with respect to any metric. We believe that investigating this issue further is an important direction for future work.
为进一步探讨这个问题,我们用 METEOR 评估系统:它不仅奖励完全匹配的词,也奖励匹配的词干、同义词和释义(来自预定义列表)。我们观察到,加入词干、同义词和释义匹配后,我们所有模型的 METEOR 都提高了 1 分以上,说明它们可能在做某种程度的抽象。不过我们再次看到,模型仍没有超过 lead-3 基线。也许新闻文体本身就让 lead-3 基线在任何指标上都非常强。我们认为,继续探究这个问题是未来工作的一个重要方向。
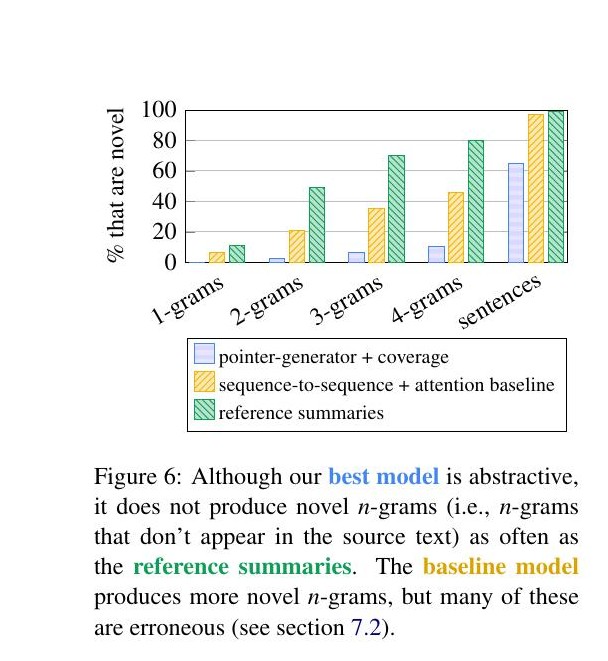
Figure 6: Although our best model is abstractive, it does not produce novel -grams (i.e., -grams that don’t appear in the source text) as often as the reference summaries. The baseline model produces more novel -grams, but many of these are erroneous (see section 7.2).
图 6:尽管我们的最佳模型是抽象式的,它产生新 元组(即源文本中没有出现过的 元组)的频率仍低于参考摘要。基线模型会产生更多新 元组,但其中有不少是错误的(见 7.2 节)。
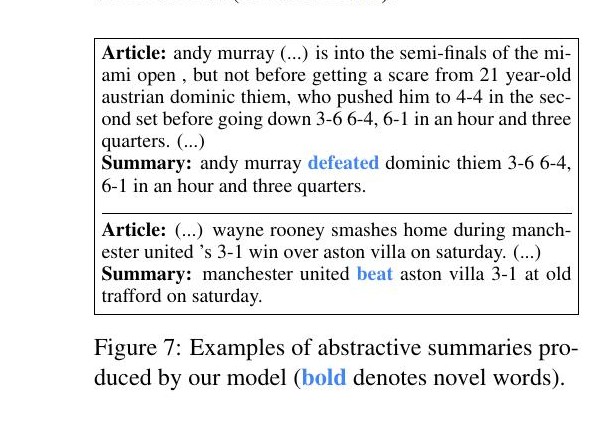
Article: andy murray (…) is into the semi-finals of the miami open , but not before getting a scare from 21 year-old austrian dominic thiem, who pushed him to 4-4 in the second set before going down 3-6 6-4, 6-1 in an hour and three quarters. (…) Summary: andy murray defeated dominic thiem 3-6 6-4, 6-1 in an hour and three quarters. Article: (…) wayne rooney smashes home during manchester united ’s 3-1 win over aston villa on saturday. (…) Summary: manchester united beat aston villa 3-1 at old trafford on saturday.
Article: andy murray (…) is into the semi-finals of the miami open , but not before getting a scare from 21 year-old austrian dominic thiem, who pushed him to 4-4 in the second set before going down 3-6 6-4, 6-1 in an hour and three quarters. (…) Summary: andy murray defeated dominic thiem 3-6 6-4, 6-1 in an hour and three quarters. Article: (…) wayne rooney smashes home during manchester united ’s 3-1 win over aston villa on saturday. (…) Summary: manchester united beat aston villa 3-1 at old trafford on saturday.
Figure 7: Examples of abstractive summaries produced by our model (bold denotes novel words).
图 7:我们模型产生的抽象式摘要示例(粗体表示原文中没有的新词)。
7.2 How abstractive is our model?
7.2 我们的模型有多抽象?
We have shown that our pointer mechanism makes our abstractive system more reliable, copying factual details correctly more often. But does the ease of copying make our system any less abstractive?
我们已经说明,指针机制让抽象式系统更可靠,更经常正确复制事实细节。可是,复制变得容易,会不会让系统变得不那么抽象?
Figure 6 shows that our final model’s summaries contain a much lower rate of novel -grams (i.e., those that don’t appear in the article) than the reference summaries, indicating a lower degree of abstraction. Note that the baseline model produces novel -grams more frequently – however, this statistic includes all the incorrectly copied words, UNK tokens and fabrications alongside the good instances of abstraction.
图 6 显示,我们最终模型的摘要中,新 元组(即文章里没有出现过的那些)比例远低于参考摘要,说明抽象程度更低。注意基线模型产生新 元组更频繁——不过这一统计既包括好的抽象实例,也包括错误复制的词、UNK 记号以及编造内容。
In particular, Figure 6 shows that our final model copies whole article sentences 35% of the time; by comparison the reference summaries do so only 1.3% of the time. This is a main area for improvement, as we would like our model to move beyond simple sentence extraction. However, we observe that the other 65% encompasses a range of abstractive techniques. Article sentences are truncated to form grammatically-correct shorter versions, and new sentences are composed by stitching together fragments. Unnecessary interjections, clauses and parenthesized phrases are sometimes omitted from copied passages. Some of these abilities are demonstrated in Figure 1, and the supplementary material contains more examples.
特别地,图 6 显示我们的最终模型有 35% 的时候整句复制原文;相比之下,参考摘要这样做的比例只有 1.3%。这是主要的改进空间,因为我们希望模型超越简单的句子抽取。不过我们也观察到,其余 65% 涵盖了一系列抽象手法。原文句子会被截短成语法正确的更短版本,新句子则由片段拼接而成。复制段落里不必要的插入语、从句和括号内容有时会被去掉。图 1 展示了其中一部分能力,补充材料中还有更多例子。
Figure 7 shows two examples of more impressive abstraction – both with similar structure. The dataset contains many sports stories whose summaries follow the X beat Y score on day template, which may explain why our model is most confidently abstractive on these examples. In general however, our model does not routinely produce summaries like those in Figure 7, and is not close to producing summaries like in Figure 5.
图 7 给出了两则更出色的抽象例子——二者结构相似。数据集里有许多体育报道,其摘要遵循 X beat Y score on day 这样的模板,这也许可以解释为什么模型在这些例子上抽象得最有把握。不过总体而言,我们的模型并不经常写出图 7 那样的摘要,更远未达到图 5 那种摘要的水平。
The value of the generation probability also gives a measure of the abstractiveness of our model. During training, starts with a value of about 0.30 then increases, converging to about 0.53 by the end of training. This indicates that the model first learns to mostly copy, then learns to generate about half the time. However at test time, is heavily skewed towards copying, with a mean value of 0.17. The disparity is likely due to the fact that during training, the model receives word-by-word supervision in the form of the reference summary, but at test time it does not. Nonetheless, the generator module is useful even when the model is copying. We find that is highest at times of uncertainty such as the beginning of sentences, the join between stitched-together fragments, and when producing periods that truncate a copied sentence. Our mixture model allows the network to copy while simultaneously consulting the language model – enabling operations like stitching and truncation to be performed with grammaticality. In any case, encouraging the pointer-generator model to write more abstractively, while retaining the accuracy advantages of the pointer module, is an exciting direction for future work.
生成概率 的取值也可以衡量模型的抽象程度。训练过程中, 一开始约为 0.30,随后上升,到训练结束时收敛到约 0.53。这说明模型先学会以复制为主,再学会大约一半时间进行生成。然而在测试时, 明显偏向复制,均值约为 0.17。这一差距很可能是因为:训练时模型能以参考摘要的形式获得逐词监督,测试时则没有。尽管如此,即便模型在复制,生成器模块仍然有用。我们发现, 在不确定的时刻最高,例如句子开头、片段拼接处,以及写出句号来截断所复制句子的时候。混合模型让网络在复制的同时查询语言模型——从而能以合乎语法的方式完成拼接和截断。无论如何,怎样在保留指针模块准确性优势的同时,促使指针生成模型写得更抽象,仍是一个令人兴奋的未来方向。
8 Conclusion
8 结论
In this work we presented a hybrid pointer-generator architecture with coverage, and showed that it reduces inaccuracies and repetition. We applied our model to a new and challenging long-text dataset, and significantly outperformed the abstractive state-of-the-art result. Our model exhibits many abstractive abilities, but attaining higher levels of abstraction remains an open research question.
本文提出了一种带覆盖机制的混合指针生成架构,并表明它可以减少不准确和重复。我们把模型用在一个新的、更具挑战的长文本数据集上,显著超过了当时最好的抽象式结果。模型已经展现出多种抽象能力,但如何达到更高程度的抽象,仍是有待研究的问题。
9 Acknowledgment
9 致谢
We thank the ACL reviewers for their helpful comments. This work was begun while the first author was an intern at Google Brain and continued at Stanford. Stanford University gratefully acknowledges the support of the DARPA DEFT Program AFRL contract no. FA8750-13-2-0040. Any opinions in this material are those of the authors alone.
我们感谢 ACL 审稿人的有益意见。本工作在第一作者于 Google Brain 实习期间启动,并在斯坦福大学继续完成。斯坦福大学衷心感谢 DARPA DEFT 项目的支持,空军研究室合同编号 FA8750-13-2-0040。文中任何观点仅代表作者本人。
References
参考文献
Bahdanau et al. (2015) Dzmitry Bahdanau, Kyunghyun Cho, and Yoshua Bengio. 2015. Neural machine translation by jointly learning to align and translate. In International Conference on Learning Representations .
Chen et al. (2016) Qian Chen, Xiaodan Zhu, Zhenhua Ling, Si Wei, and Hui Jiang. 2016. Distraction-based neural networks for modeling documents. In International Joint Conference on Artificial Intelligence .
Cheung and Penn (2014) Jackie Chi Kit Cheung and Gerald Penn. 2014. Unsupervised sentence enhancement for automatic summarization. In Empirical Methods in Natural Language Processing .
Chopra et al. (2016) Sumit Chopra, Michael Auli, and Alexander M Rush. 2016. Abstractive sentence summarization with attentive recurrent neural networks. In North American Chapter of the Association for Computational Linguistics .
Denkowski and Lavie (2014) Michael Denkowski and Alon Lavie. 2014. Meteor universal: Language specific translation evaluation for any target language. In EACL 2014 Workshop on Statistical Machine Translation .
Duchi et al. (2011) John Duchi, Elad Hazan, and Yoram Singer. 2011. Adaptive subgradient methods for online learning and stochastic optimization. Journal of Machine Learning Research 12:2121–2159.
Gu et al. (2016) Jiatao Gu, Zhengdong Lu, Hang Li, and Victor OK Li. 2016. Incorporating copying mechanism in sequence-to-sequence learning. In Association for Computational Linguistics .
Gulcehre et al. (2016) Caglar Gulcehre, Sungjin Ahn, Ramesh Nallapati, Bowen Zhou, and Yoshua Bengio. 2016. Pointing the unknown words. In Association for Computational Linguistics .
Hermann et al. (2015) Karl Moritz Hermann, Tomas Kocisky, Edward Grefenstette, Lasse Espeholt, Will Kay, Mustafa Suleyman, and Phil Blunsom. 2015. Teaching machines to read and comprehend. In Neural Information Processing Systems .
Jing (2000) Hongyan Jing. 2000. Sentence reduction for automatic text summarization. In Applied natural language processing .
Koehn (2009) Philipp Koehn. 2009. Statistical machine translation . Cambridge University Press.
Kupiec et al. (1995) Julian Kupiec, Jan Pedersen, and Francine Chen. 1995. A trainable document summarizer. In International ACM SIGIR conference on Research and development in information retrieval .
Lin (2004a) Chin-Yew Lin. 2004a. Looking for a few good metrics: Automatic summarization evaluation-how many samples are enough? In NACSIS/NII Test Collection for Information Retrieval (NTCIR) Workshop .
Lin (2004b) Chin-Yew Lin. 2004b. Rouge: A package for automatic evaluation of summaries. In Text summarization branches out: ACL workshop .
Merity et al. (2016) Stephen Merity, Caiming Xiong, James Bradbury, and Richard Socher. 2016. Pointer sentinel mixture models. In NIPS 2016 Workshop on Multi-class and Multi-label Learning in Extremely Large Label Spaces .
Mi et al. (2016) Haitao Mi, Baskaran Sankaran, Zhiguo Wang, and Abe Ittycheriah. 2016. Coverage embedding models for neural machine translation. In Empirical Methods in Natural Language Processing .
Miao and Blunsom (2016) Yishu Miao and Phil Blunsom. 2016. Language as a latent variable: Discrete generative models for sentence compression. In Empirical Methods in Natural Language Processing .
Nallapati et al. (2017) Ramesh Nallapati, Feifei Zhai, and Bowen Zhou. 2017. SummaRuNNer: A recurrent neural network based sequence model for extractive summarization of documents. In Association for the Advancement of Artificial Intelligence .
Nallapati et al. (2016) Ramesh Nallapati, Bowen Zhou, Cicero dos Santos, Çaglar Gulçehre, and Bing Xiang. 2016. Abstractive text summarization using sequence-to-sequence RNNs and beyond. In Computational Natural Language Learning .
Paice (1990) Chris D Paice. 1990. Constructing literature abstracts by computer: techniques and prospects. Information Processing & Management 26(1):171–186.
Ranzato et al. (2016) Marc’Aurelio Ranzato, Sumit Chopra, Michael Auli, and Wojciech Zaremba. 2016. Sequence level training with recurrent neural networks. In International Conference on Learning Representations .
Rush et al. (2015) Alexander M Rush, Sumit Chopra, and Jason Weston. 2015. A neural attention model for abstractive sentence summarization. In Empirical Methods in Natural Language Processing .
Saggion and Poibeau (2013) Horacio Saggion and Thierry Poibeau. 2013. Automatic text summarization: Past, present and future. In Multi-source, Multilingual Information Extraction and Summarization , Springer, pages 3–21.
Sankaran et al. (2016) Baskaran Sankaran, Haitao Mi, Yaser Al-Onaizan, and Abe Ittycheriah. 2016. Temporal attention model for neural machine translation. arXiv preprint arXiv:1608.02927 .
Sutskever et al. (2014) Ilya Sutskever, Oriol Vinyals, and Quoc V Le. 2014. Sequence to sequence learning with neural networks. In Neural Information Processing Systems .
Suzuki and Nagata (2016) Jun Suzuki and Masaaki Nagata. 2016. RNN-based encoder-decoder approach with word frequency estimation. arXiv preprint arXiv:1701.00138 .
Takase et al. (2016) Sho Takase, Jun Suzuki, Naoaki Okazaki, Tsutomu Hirao, and Masaaki Nagata. 2016. Neural headline generation on abstract meaning representation. In Empirical Methods in Natural Language Processing .
Tu et al. (2016) Zhaopeng Tu, Zhengdong Lu, Yang Liu, Xiaohua Liu, and Hang Li. 2016. Modeling coverage for neural machine translation. In Association for Computational Linguistics .
Vinyals et al. (2015) Oriol Vinyals, Meire Fortunato, and Navdeep Jaitly. 2015. Pointer networks. In Neural Information Processing Systems .
Xu et al. (2015) Kelvin Xu, Jimmy Ba, Ryan Kiros, Kyunghyun Cho, Aaron C Courville, Ruslan Salakhutdinov, Richard S Zemel, and Yoshua Bengio. 2015. Show, attend and tell: Neural image caption generation with visual attention. In International Conference on Machine Learning .
Zeng et al. (2016) Wenyuan Zeng, Wenjie Luo, Sanja Fidler, and Raquel Urtasun. 2016. Efficient summarization with read-again and copy mechanism. arXiv preprint arXiv:1611.03382 .
Supplementary Material
补充材料
This appendix provides examples from the test set, with side-by-side comparisons of the reference summaries and the summaries produced by our models. In each example:
本附录给出测试集中的例子,并并排比较参考摘要与我们各模型生成的摘要。在每个例子中:
- • italics denote out-of-vocabulary words
- • 斜体表示未登录词
- • red denotes factual errors in the summaries
- • 红色表示摘要中的事实错误
- • green shadingintensity represents the value of the generation probability
- • 绿色深浅表示生成概率 的取值
- • yellow shadingintensity represents final value of the coverage vector at the end of final model’s summarization process.
- • 黄色深浅表示最终模型完成摘要后,覆盖向量的终值
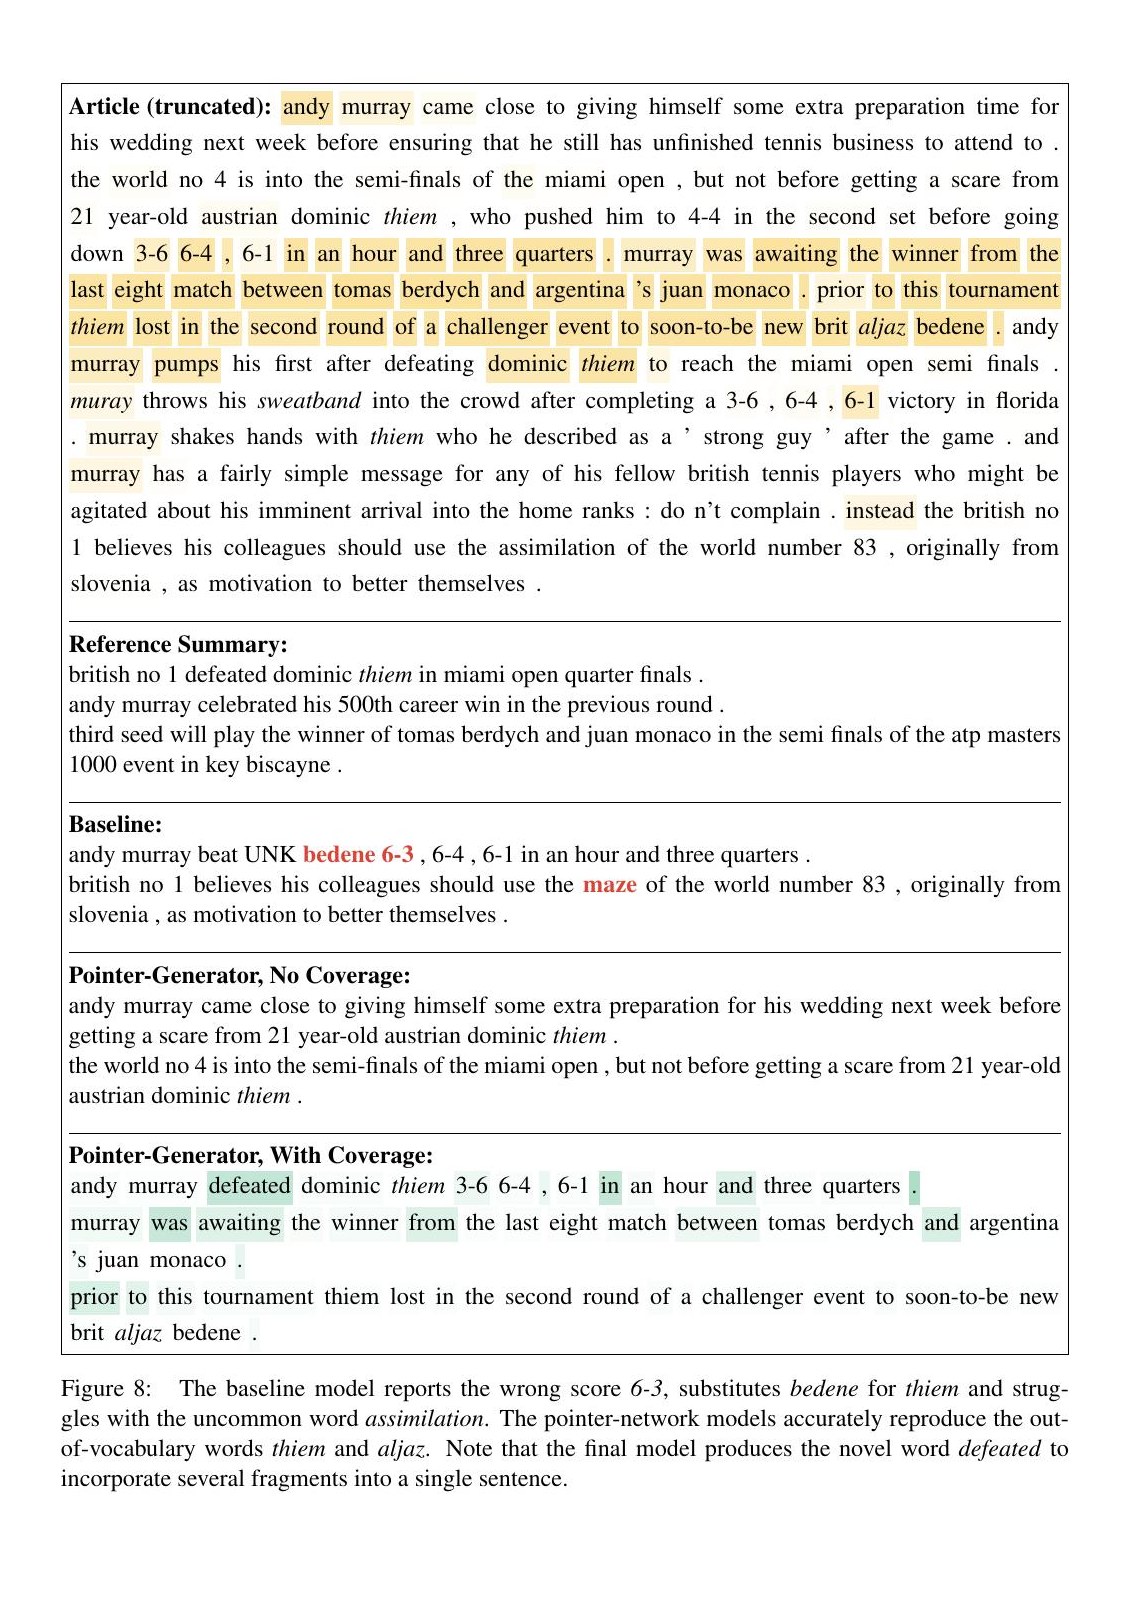
Article (truncated): andy murray came close to giving himself some extra preparation time for his wedding next week before ensuring that he still has unfinished tennis business to attend to . the world no 4 is into the semi-finals of the miami open , but not before getting a scare from 21 year-old austrian dominic thiem , who pushed him to 4-4 in the second set before going down 3-6 6-4 , 6-1 in an hour and three quarters . murray was awaiting the winner from the last eight match between tomas berdych and argentina ’s juan monaco . prior to this tournament thiem lost in the second round of a challenger event to soon-to-be new brit aljaz bedene . andy murray pumps his first after defeating dominic thiem to reach the miami open semi finals . muray throws his sweatband into the crowd after completing a 3-6 , 6-4 , 6-1 victory in florida . murray shakes hands with thiem who he described as a ’ strong guy ’ after the game . and murray has a fairly simple message for any of his fellow british tennis players who might be agitated about his imminent arrival into the home ranks : do n’t complain . instead the british no 1 believes his colleagues should use the assimilation of the world number 83 , originally from slovenia , as motivation to better themselves . Reference Summary: british no 1 defeated dominic thiem in miami open quarter finals . andy murray celebrated his 500th career win in the previous round . third seed will play the winner of tomas berdych and juan monaco in the semi finals of the atp masters 1000 event in key biscayne . Baseline: andy murray beat UNK bedene 6-3 , 6-4 , 6-1 in an hour and three quarters . british no 1 believes his colleagues should use the maze of the world number 83 , originally from slovenia , as motivation to better themselves . Pointer-Generator, No Coverage: andy murray came close to giving himself some extra preparation for his wedding next week before getting a scare from 21 year-old austrian dominic thiem . the world no 4 is into the semi-finals of the miami open , but not before getting a scare from 21 year-old austrian dominic thiem . Pointer-Generator, With Coverage: andy murray defeated dominic thiem 3-6 6-4 , 6-1 in an hour and three quarters . murray was awaiting the winner from the last eight match between tomas berdych and argentina ’s juan monaco . prior to this tournament thiem lost in the second round of a challenger event to soon-to-be new brit aljaz bedene .
Article (truncated): andy murray came close to giving himself some extra preparation time for his wedding next week before ensuring that he still has unfinished tennis business to attend to . the world no 4 is into the semi-finals of the miami open , but not before getting a scare from 21 year-old austrian dominic thiem , who pushed him to 4-4 in the second set before going down 3-6 6-4 , 6-1 in an hour and three quarters . murray was awaiting the winner from the last eight match between tomas berdych and argentina ’s juan monaco . prior to this tournament thiem lost in the second round of a challenger event to soon-to-be new brit aljaz bedene . andy murray pumps his first after defeating dominic thiem to reach the miami open semi finals . muray throws his sweatband into the crowd after completing a 3-6 , 6-4 , 6-1 victory in florida . murray shakes hands with thiem who he described as a ’ strong guy ’ after the game . and murray has a fairly simple message for any of his fellow british tennis players who might be agitated about his imminent arrival into the home ranks : do n’t complain . instead the british no 1 believes his colleagues should use the assimilation of the world number 83 , originally from slovenia , as motivation to better themselves . Reference Summary: british no 1 defeated dominic thiem in miami open quarter finals . andy murray celebrated his 500th career win in the previous round . third seed will play the winner of tomas berdych and juan monaco in the semi finals of the atp masters 1000 event in key biscayne . Baseline: andy murray beat UNK bedene 6-3 , 6-4 , 6-1 in an hour and three quarters . british no 1 believes his colleagues should use the maze of the world number 83 , originally from slovenia , as motivation to better themselves . Pointer-Generator, No Coverage: andy murray came close to giving himself some extra preparation for his wedding next week before getting a scare from 21 year-old austrian dominic thiem . the world no 4 is into the semi-finals of the miami open , but not before getting a scare from 21 year-old austrian dominic thiem . Pointer-Generator, With Coverage: andy murray defeated dominic thiem 3-6 6-4 , 6-1 in an hour and three quarters . murray was awaiting the winner from the last eight match between tomas berdych and argentina ’s juan monaco . prior to this tournament thiem lost in the second round of a challenger event to soon-to-be new brit aljaz bedene .
Figure 8: The baseline model reports the wrong score 6-3, substitutes bedene for thiem and struggles with the uncommon word assimilation. The pointer-network models accurately reproduce the out-of-vocabulary words thiem and aljaz. Note that the final model produces the novel word defeated to incorporate several fragments into a single sentence.
图 8:基线模型报告了错误比分 6-3,用 bedene 替换了 thiem,并且难以处理不常见词 assimilation。指针网络模型准确复述了未登录词 thiem 和 aljaz。注意最终模型写出了新词 defeated,把若干片段并入一句。
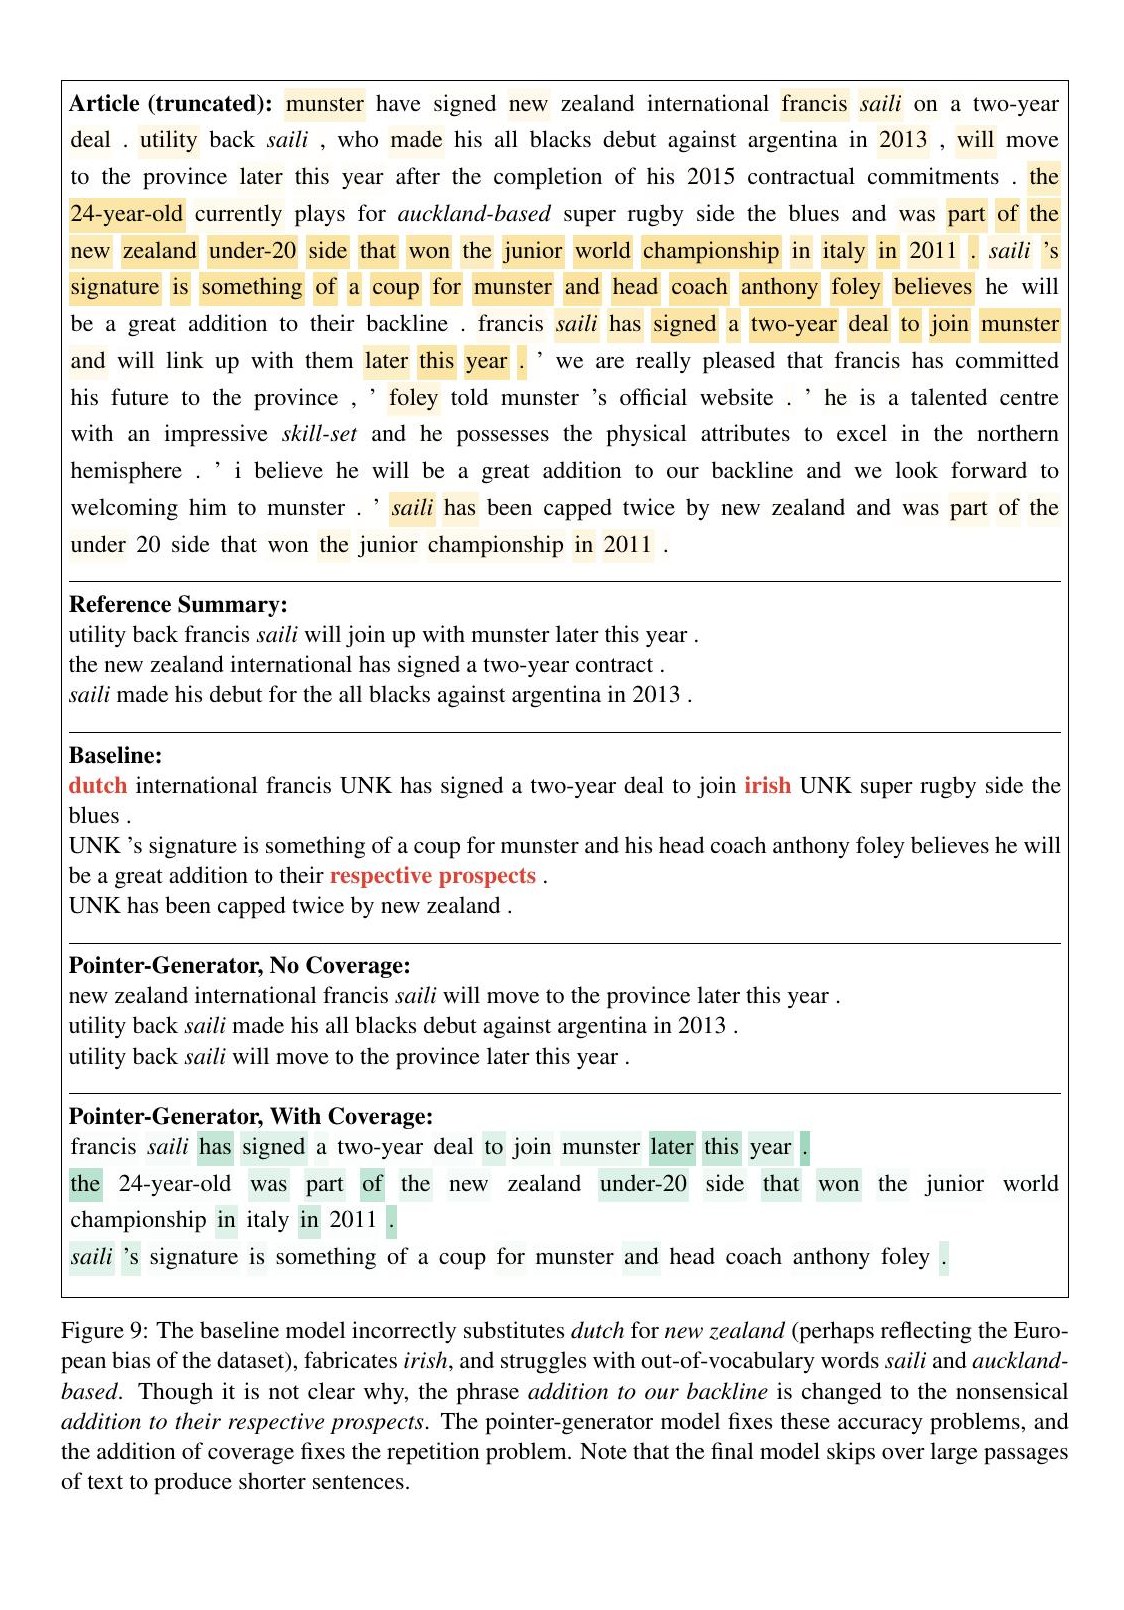
Article (truncated): munster have signed new zealand international francis saili on a two-year deal . utility back saili , who made his all blacks debut against argentina in 2013 , will move to the province later this year after the completion of his 2015 contractual commitments . the 24-year-old currently plays for auckland-based super rugby side the blues and was part of the new zealand under-20 side that won the junior world championship in italy in 2011 . saili ’s signature is something of a coup for munster and head coach anthony foley believes he will be a great addition to their backline . francis saili has signed a two-year deal to join munster and will link up with them later this year . ’ we are really pleased that francis has committed his future to the province , ’ foley told munster ’s official website . ’ he is a talented centre with an impressive skill-set and he possesses the physical attributes to excel in the northern hemisphere . ’ i believe he will be a great addition to our backline and we look forward to welcoming him to munster . ’ saili has been capped twice by new zealand and was part of the under 20 side that won the junior championship in 2011 . Reference Summary: utility back francis saili will join up with munster later this year . the new zealand international has signed a two-year contract . saili made his debut for the all blacks against argentina in 2013 . Baseline: dutch international francis UNK has signed a two-year deal to join irish UNK super rugby side the blues . UNK ’s signature is something of a coup for munster and his head coach anthony foley believes he will be a great addition to their respective prospects . UNK has been capped twice by new zealand . Pointer-Generator, No Coverage: new zealand international francis saili will move to the province later this year . utility back saili made his all blacks debut against argentina in 2013 . utility back saili will move to the province later this year . Pointer-Generator, With Coverage: francis saili has signed a two-year deal to join munster later this year . the 24-year-old was part of the new zealand under-20 side that won the junior world championship in italy in 2011 . saili ’s signature is something of a coup for munster and head coach anthony foley .
Article (truncated): munster have signed new zealand international francis saili on a two-year deal . utility back saili , who made his all blacks debut against argentina in 2013 , will move to the province later this year after the completion of his 2015 contractual commitments . the 24-year-old currently plays for auckland-based super rugby side the blues and was part of the new zealand under-20 side that won the junior world championship in italy in 2011 . saili ’s signature is something of a coup for munster and head coach anthony foley believes he will be a great addition to their backline . francis saili has signed a two-year deal to join munster and will link up with them later this year . ’ we are really pleased that francis has committed his future to the province , ’ foley told munster ’s official website . ’ he is a talented centre with an impressive skill-set and he possesses the physical attributes to excel in the northern hemisphere . ’ i believe he will be a great addition to our backline and we look forward to welcoming him to munster . ’ saili has been capped twice by new zealand and was part of the under 20 side that won the junior championship in 2011 . Reference Summary: utility back francis saili will join up with munster later this year . the new zealand international has signed a two-year contract . saili made his debut for the all blacks against argentina in 2013 . Baseline: dutch international francis UNK has signed a two-year deal to join irish UNK super rugby side the blues . UNK ’s signature is something of a coup for munster and his head coach anthony foley believes he will be a great addition to their respective prospects . UNK has been capped twice by new zealand . Pointer-Generator, No Coverage: new zealand international francis saili will move to the province later this year . utility back saili made his all blacks debut against argentina in 2013 . utility back saili will move to the province later this year . Pointer-Generator, With Coverage: francis saili has signed a two-year deal to join munster later this year . the 24-year-old was part of the new zealand under-20 side that won the junior world championship in italy in 2011 . saili ’s signature is something of a coup for munster and head coach anthony foley .
Figure 9: The baseline model incorrectly substitutes dutch for new zealand (perhaps reflecting the European bias of the dataset), fabricates irish, and struggles with out-of-vocabulary words saili and auckland-based. Though it is not clear why, the phrase addition to our backline is changed to the nonsensical addition to their respective prospects. The pointer-generator model fixes these accuracy problems, and the addition of coverage fixes the repetition problem. Note that the final model skips over large passages of text to produce shorter sentences.
图 9:基线模型错误地把 new zealand 换成 dutch(也许反映了数据集的欧洲偏向),编造了 irish,并且难以处理未登录词 saili 和 auckland-based。不清楚出于什么原因,短语 addition to our backline 被改成了不通的 addition to their respective prospects。指针生成模型纠正了这些准确性问题,加入覆盖后又解决了重复问题。注意最终模型会跳过大段文字,写出更短的句子。
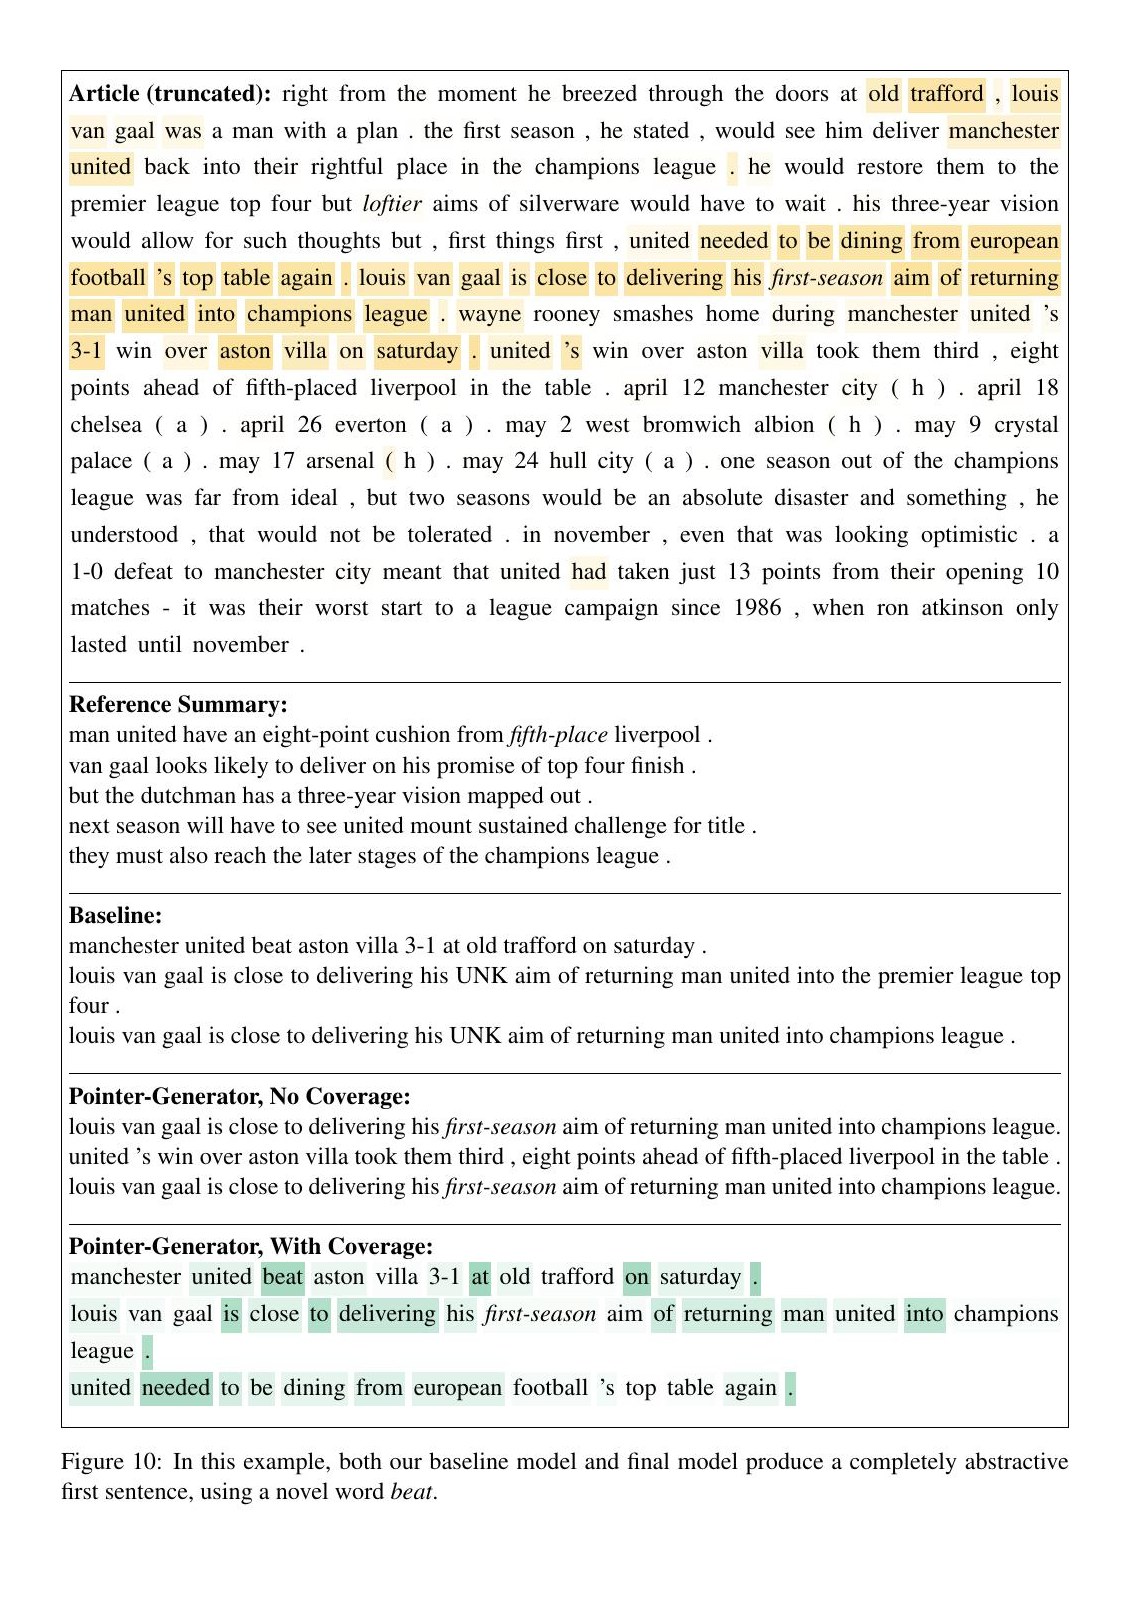
Article (truncated): right from the moment he breezed through the doors at old trafford , louis van gaal was a man with a plan . the first season , he stated , would see him deliver manchester united back into their rightful place in the champions league . he would restore them to the premier league top four but loftier aims of silverware would have to wait . his three-year vision would allow for such thoughts but , first things first , united needed to be dining from european football ’s top table again . louis van gaal is close to delivering his first-season aim of returning man united into champions league . wayne rooney smashes home during manchester united ’s 3-1 win over aston villa on saturday . united ’s win over aston villa took them third , eight points ahead of fifth-placed liverpool in the table . april 12 manchester city ( h ) . april 18 chelsea ( a ) . april 26 everton ( a ) . may 2 west bromwich albion ( h ) . may 9 crystal palace ( a ) . may 17 arsenal ( h ) . may 24 hull city ( a ) . one season out of the champions league was far from ideal , but two seasons would be an absolute disaster and something , he understood , that would not be tolerated . in november , even that was looking optimistic . a 1-0 defeat to manchester city meant that united had taken just 13 points from their opening 10 matches - it was their worst start to a league campaign since 1986 , when ron atkinson only lasted until november . Reference Summary: man united have an eight-point cushion from fifth-place liverpool . van gaal looks likely to deliver on his promise of top four finish . but the dutchman has a three-year vision mapped out . next season will have to see united mount sustained challenge for title . they must also reach the later stages of the champions league . Baseline: manchester united beat aston villa 3-1 at old trafford on saturday . louis van gaal is close to delivering his UNK aim of returning man united into the premier league top four . louis van gaal is close to delivering his UNK aim of returning man united into champions league . Pointer-Generator, No Coverage: louis van gaal is close to delivering his first-season aim of returning man united into champions league. united ’s win over aston villa took them third , eight points ahead of fifth-placed liverpool in the table . louis van gaal is close to delivering his first-season aim of returning man united into champions league. Pointer-Generator, With Coverage: manchester united beat aston villa 3-1 at old trafford on saturday . louis van gaal is close to delivering his first-season aim of returning man united into champions league . united needed to be dining from european football ’s top table again .
Article (truncated): right from the moment he breezed through the doors at old trafford , louis van gaal was a man with a plan . the first season , he stated , would see him deliver manchester united back into their rightful place in the champions league . he would restore them to the premier league top four but loftier aims of silverware would have to wait . his three-year vision would allow for such thoughts but , first things first , united needed to be dining from european football ’s top table again . louis van gaal is close to delivering his first-season aim of returning man united into champions league . wayne rooney smashes home during manchester united ’s 3-1 win over aston villa on saturday . united ’s win over aston villa took them third , eight points ahead of fifth-placed liverpool in the table . april 12 manchester city ( h ) . april 18 chelsea ( a ) . april 26 everton ( a ) . may 2 west bromwich albion ( h ) . may 9 crystal palace ( a ) . may 17 arsenal ( h ) . may 24 hull city ( a ) . one season out of the champions league was far from ideal , but two seasons would be an absolute disaster and something , he understood , that would not be tolerated . in november , even that was looking optimistic . a 1-0 defeat to manchester city meant that united had taken just 13 points from their opening 10 matches - it was their worst start to a league campaign since 1986 , when ron atkinson only lasted until november . Reference Summary: man united have an eight-point cushion from fifth-place liverpool . van gaal looks likely to deliver on his promise of top four finish . but the dutchman has a three-year vision mapped out . next season will have to see united mount sustained challenge for title . they must also reach the later stages of the champions league . Baseline: manchester united beat aston villa 3-1 at old trafford on saturday . louis van gaal is close to delivering his UNK aim of returning man united into the premier league top four . louis van gaal is close to delivering his UNK aim of returning man united into champions league . Pointer-Generator, No Coverage: louis van gaal is close to delivering his first-season aim of returning man united into champions league. united ’s win over aston villa took them third , eight points ahead of fifth-placed liverpool in the table . louis van gaal is close to delivering his first-season aim of returning man united into champions league. Pointer-Generator, With Coverage: manchester united beat aston villa 3-1 at old trafford on saturday . louis van gaal is close to delivering his first-season aim of returning man united into champions league . united needed to be dining from european football ’s top table again .
Figure 10: In this example, both our baseline model and final model produce a completely abstractive first sentence, using a novel word beat.
图 10:在这个例子中,基线模型和最终模型都写出了完全抽象的第一句,并使用了新词 beat。
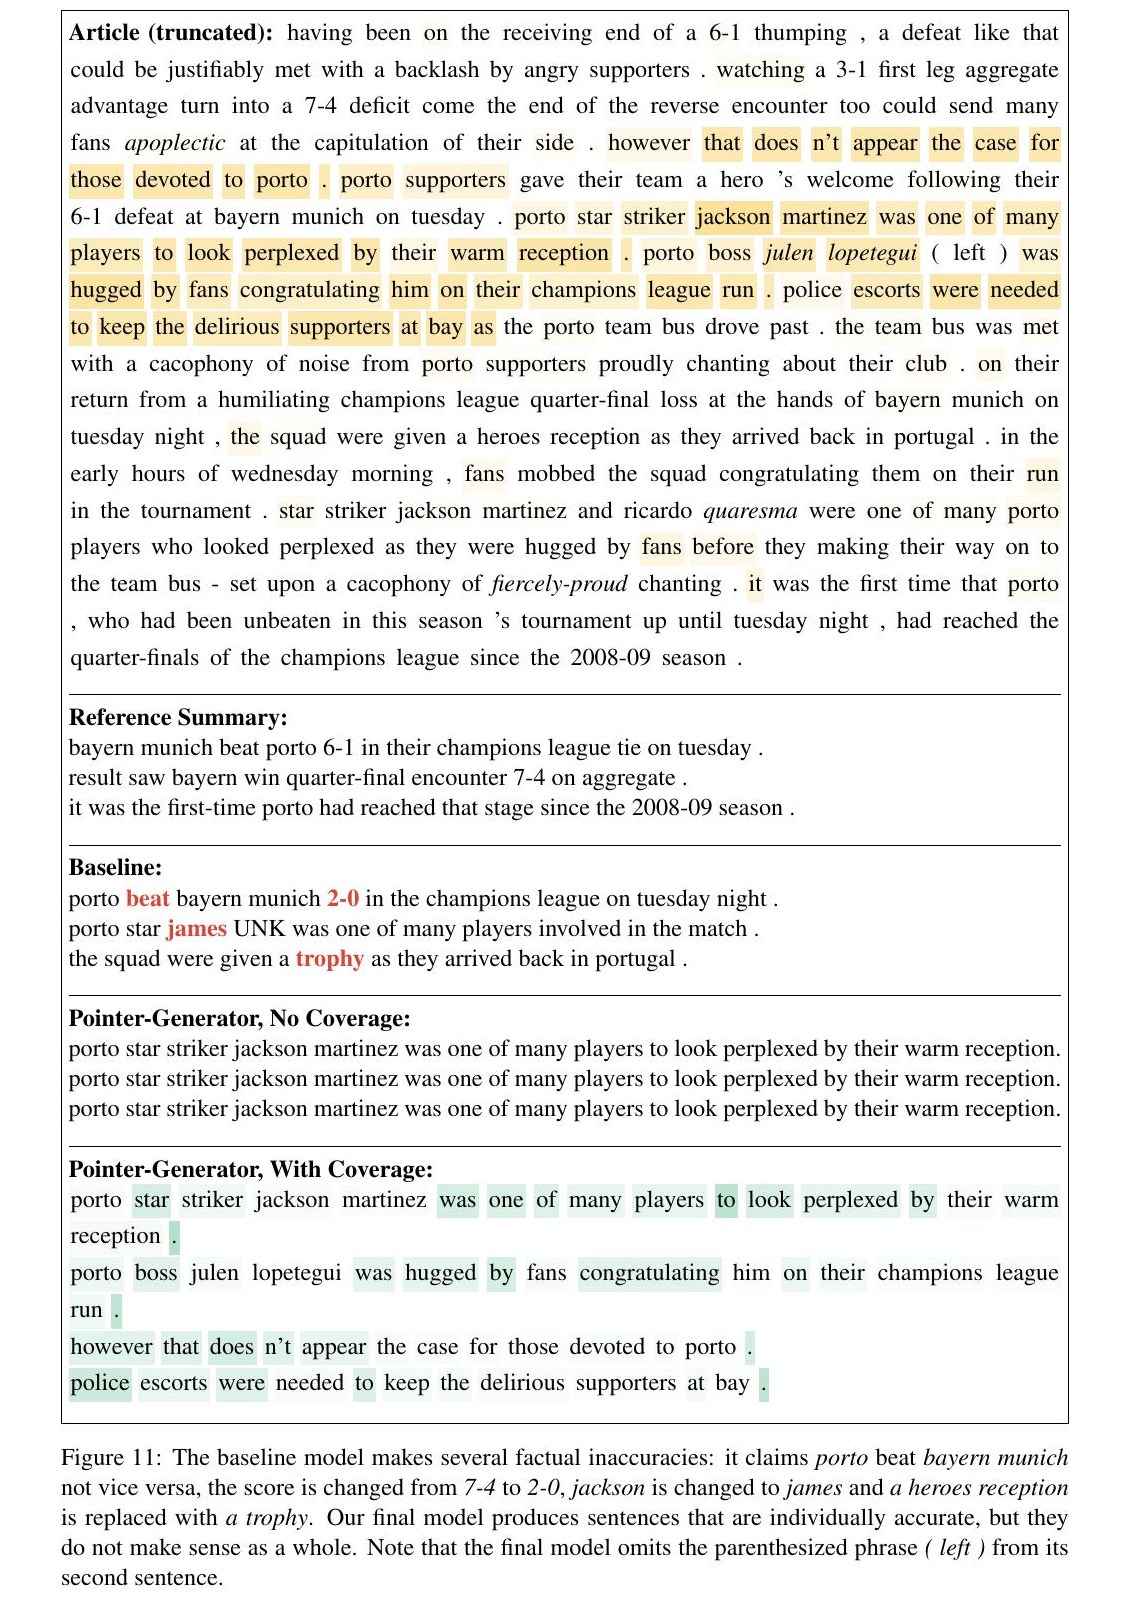
Article (truncated): having been on the receiving end of a 6-1 thumping , a defeat like that could be justifiably met with a backlash by angry supporters . watching a 3-1 first leg aggregate advantage turn into a 7-4 deficit come the end of the reverse encounter too could send many fans apoplectic at the capitulation of their side . however that does n’t appear the case for those devoted to porto . porto supporters gave their team a hero ’s welcome following their 6-1 defeat at bayern munich on tuesday . porto star striker jackson martinez was one of many players to look perplexed by their warm reception . porto boss julen lopetegui ( left ) was hugged by fans congratulating him on their champions league run . police escorts were needed to keep the delirious supporters at bay as the porto team bus drove past . the team bus was met with a cacophony of noise from porto supporters proudly chanting about their club . on their return from a humiliating champions league quarter-final loss at the hands of bayern munich on tuesday night , the squad were given a heroes reception as they arrived back in portugal . in the early hours of wednesday morning , fans mobbed the squad congratulating them on their run in the tournament . star striker jackson martinez and ricardo quaresma were one of many porto players who looked perplexed as they were hugged by fans before they making their way on to the team bus - set upon a cacophony of fiercely-proud chanting . it was the first time that porto , who had been unbeaten in this season ’s tournament up until tuesday night , had reached the quarter-finals of the champions league since the 2008-09 season . Reference Summary: bayern munich beat porto 6-1 in their champions league tie on tuesday . result saw bayern win quarter-final encounter 7-4 on aggregate . it was the first-time porto had reached that stage since the 2008-09 season . Baseline: porto beat bayern munich 2-0 in the champions league on tuesday night . porto star james UNK was one of many players involved in the match . the squad were given a trophy as they arrived back in portugal . Pointer-Generator, No Coverage: porto star striker jackson martinez was one of many players to look perplexed by their warm reception. porto star striker jackson martinez was one of many players to look perplexed by their warm reception. porto star striker jackson martinez was one of many players to look perplexed by their warm reception. Pointer-Generator, With Coverage: porto star striker jackson martinez was one of many players to look perplexed by their warm reception . porto boss julen lopetegui was hugged by fans congratulating him on their champions league run . however that does n’t appear the case for those devoted to porto . police escorts were needed to keep the delirious supporters at bay .
Article (truncated): having been on the receiving end of a 6-1 thumping , a defeat like that could be justifiably met with a backlash by angry supporters . watching a 3-1 first leg aggregate advantage turn into a 7-4 deficit come the end of the reverse encounter too could send many fans apoplectic at the capitulation of their side . however that does n’t appear the case for those devoted to porto . porto supporters gave their team a hero ’s welcome following their 6-1 defeat at bayern munich on tuesday . porto star striker jackson martinez was one of many players to look perplexed by their warm reception . porto boss julen lopetegui ( left ) was hugged by fans congratulating him on their champions league run . police escorts were needed to keep the delirious supporters at bay as the porto team bus drove past . the team bus was met with a cacophony of noise from porto supporters proudly chanting about their club . on their return from a humiliating champions league quarter-final loss at the hands of bayern munich on tuesday night , the squad were given a heroes reception as they arrived back in portugal . in the early hours of wednesday morning , fans mobbed the squad congratulating them on their run in the tournament . star striker jackson martinez and ricardo quaresma were one of many porto players who looked perplexed as they were hugged by fans before they making their way on to the team bus - set upon a cacophony of fiercely-proud chanting . it was the first time that porto , who had been unbeaten in this season ’s tournament up until tuesday night , had reached the quarter-finals of the champions league since the 2008-09 season . Reference Summary: bayern munich beat porto 6-1 in their champions league tie on tuesday . result saw bayern win quarter-final encounter 7-4 on aggregate . it was the first-time porto had reached that stage since the 2008-09 season . Baseline: porto beat bayern munich 2-0 in the champions league on tuesday night . porto star james UNK was one of many players involved in the match . the squad were given a trophy as they arrived back in portugal . Pointer-Generator, No Coverage: porto star striker jackson martinez was one of many players to look perplexed by their warm reception. porto star striker jackson martinez was one of many players to look perplexed by their warm reception. porto star striker jackson martinez was one of many players to look perplexed by their warm reception. Pointer-Generator, With Coverage: porto star striker jackson martinez was one of many players to look perplexed by their warm reception . porto boss julen lopetegui was hugged by fans congratulating him on their champions league run . however that does n’t appear the case for those devoted to porto . police escorts were needed to keep the delirious supporters at bay .
Figure 11: The baseline model makes several factual inaccuracies: it claims porto beat bayern munich not vice versa, the score is changed from 7-4 to 2-0, jackson is changed to james and a heroes reception is replaced with a trophy. Our final model produces sentences that are individually accurate, but they do not make sense as a whole. Note that the final model omits the parenthesized phrase ( left ) from its second sentence.
图 11:基线模型出现了多处事实错误:它声称是 porto 击败了 bayern munich 而不是相反,比分从 7-4 改成了 2-0,jackson 被改成 james,a heroes reception 被换成 a trophy。我们的最终模型写出的句子单独看是准确的,但合在一起并不能构成连贯的整体。注意最终模型在第二句中省略了括号里的 ( left )。
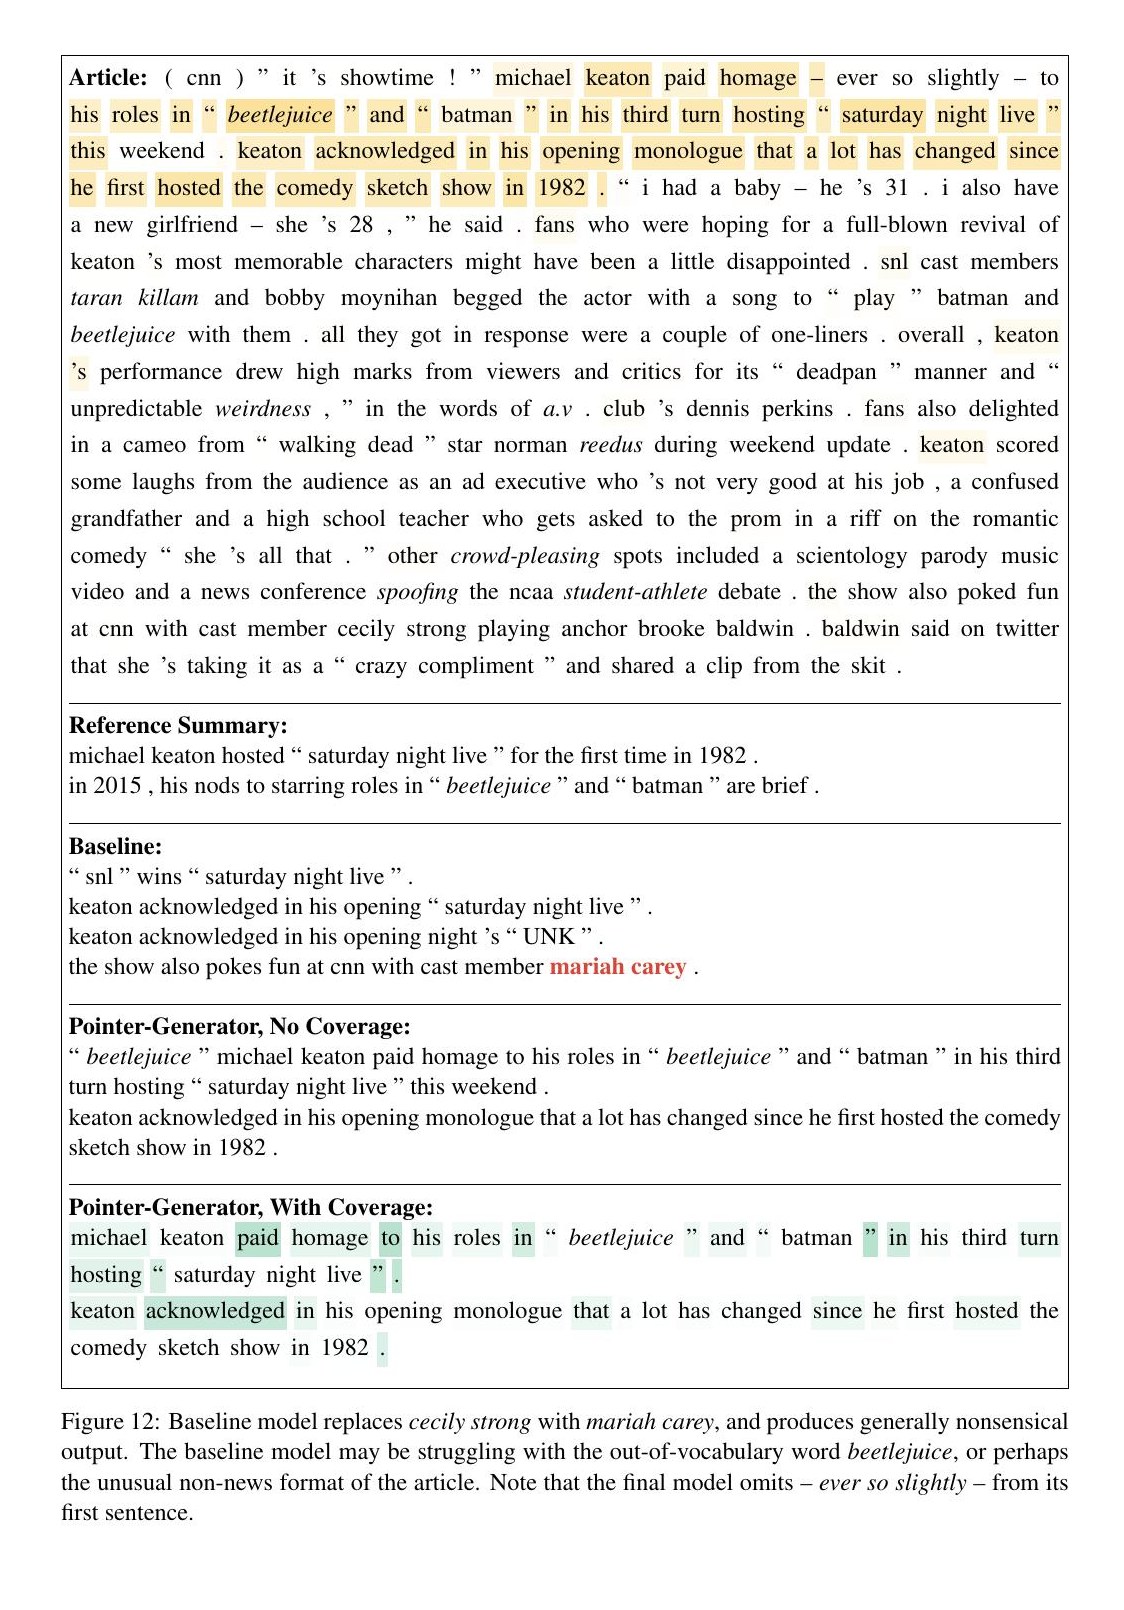
Article: ( cnn ) ” it ’s showtime ! ” michael keaton paid homage – ever so slightly – to his roles in “ beetlejuice ” and “ batman ” in his third turn hosting “ saturday night live ” this weekend . keaton acknowledged in his opening monologue that a lot has changed since he first hosted the comedy sketch show in 1982 . “ i had a baby – he ’s 31 . i also have a new girlfriend – she ’s 28 , ” he said . fans who were hoping for a full-blown revival of keaton ’s most memorable characters might have been a little disappointed . snl cast members taran killam and bobby moynihan begged the actor with a song to “ play ” batman and beetlejuice with them . all they got in response were a couple of one-liners . overall , keaton ’s performance drew high marks from viewers and critics for its “ deadpan ” manner and “ unpredictable weirdness , ” in the words of a.v . club ’s dennis perkins . fans also delighted in a cameo from “ walking dead ” star norman reedus during weekend update . keaton scored some laughs from the audience as an ad executive who ’s not very good at his job , a confused grandfather and a high school teacher who gets asked to the prom in a riff on the romantic comedy “ she ’s all that . ” other crowd-pleasing spots included a scientology parody music video and a news conference spoofing the ncaa student-athlete debate . the show also poked fun at cnn with cast member cecily strong playing anchor brooke baldwin . baldwin said on twitter that she ’s taking it as a “ crazy compliment ” and shared a clip from the skit . Reference Summary: michael keaton hosted “ saturday night live ” for the first time in 1982 . in 2015 , his nods to starring roles in “ beetlejuice ” and “ batman ” are brief . Baseline: “ snl ” wins “ saturday night live ” . keaton acknowledged in his opening “ saturday night live ” . keaton acknowledged in his opening night ’s “ UNK ” . the show also pokes fun at cnn with cast member mariah carey . Pointer-Generator, No Coverage: “ beetlejuice ” michael keaton paid homage to his roles in “ beetlejuice ” and “ batman ” in his third turn hosting “ saturday night live ” this weekend . keaton acknowledged in his opening monologue that a lot has changed since he first hosted the comedy sketch show in 1982 . Pointer-Generator, With Coverage: michael keaton paid homage to his roles in “ beetlejuice ” and “ batman ” in his third turn hosting “ saturday night live ” . keaton acknowledged in his opening monologue that a lot has changed since he first hosted the comedy sketch show in 1982 .
Article: ( cnn ) ” it ’s showtime ! ” michael keaton paid homage – ever so slightly – to his roles in “ beetlejuice ” and “ batman ” in his third turn hosting “ saturday night live ” this weekend . keaton acknowledged in his opening monologue that a lot has changed since he first hosted the comedy sketch show in 1982 . “ i had a baby – he ’s 31 . i also have a new girlfriend – she ’s 28 , ” he said . fans who were hoping for a full-blown revival of keaton ’s most memorable characters might have been a little disappointed . snl cast members taran killam and bobby moynihan begged the actor with a song to “ play ” batman and beetlejuice with them . all they got in response were a couple of one-liners . overall , keaton ’s performance drew high marks from viewers and critics for its “ deadpan ” manner and “ unpredictable weirdness , ” in the words of a.v . club ’s dennis perkins . fans also delighted in a cameo from “ walking dead ” star norman reedus during weekend update . keaton scored some laughs from the audience as an ad executive who ’s not very good at his job , a confused grandfather and a high school teacher who gets asked to the prom in a riff on the romantic comedy “ she ’s all that . ” other crowd-pleasing spots included a scientology parody music video and a news conference spoofing the ncaa student-athlete debate . the show also poked fun at cnn with cast member cecily strong playing anchor brooke baldwin . baldwin said on twitter that she ’s taking it as a “ crazy compliment ” and shared a clip from the skit . Reference Summary: michael keaton hosted “ saturday night live ” for the first time in 1982 . in 2015 , his nods to starring roles in “ beetlejuice ” and “ batman ” are brief . Baseline: “ snl ” wins “ saturday night live ” . keaton acknowledged in his opening “ saturday night live ” . keaton acknowledged in his opening night ’s “ UNK ” . the show also pokes fun at cnn with cast member mariah carey . Pointer-Generator, No Coverage: “ beetlejuice ” michael keaton paid homage to his roles in “ beetlejuice ” and “ batman ” in his third turn hosting “ saturday night live ” this weekend . keaton acknowledged in his opening monologue that a lot has changed since he first hosted the comedy sketch show in 1982 . Pointer-Generator, With Coverage: michael keaton paid homage to his roles in “ beetlejuice ” and “ batman ” in his third turn hosting “ saturday night live ” . keaton acknowledged in his opening monologue that a lot has changed since he first hosted the comedy sketch show in 1982 .
Figure 12: Baseline model replaces cecily strong with mariah carey, and produces generally nonsensical output. The baseline model may be struggling with the out-of-vocabulary word beetlejuice, or perhaps the unusual non-news format of the article. Note that the final model omits – ever so slightly – from its first sentence.
图 12:基线模型把 cecily strong 换成了 mariah carey,整体输出也往往不通。基线模型可能是在为难未登录词 beetlejuice,也可能是不适应这篇非新闻体裁的文章。注意最终模型在第一句中省略了 – ever so slightly –。
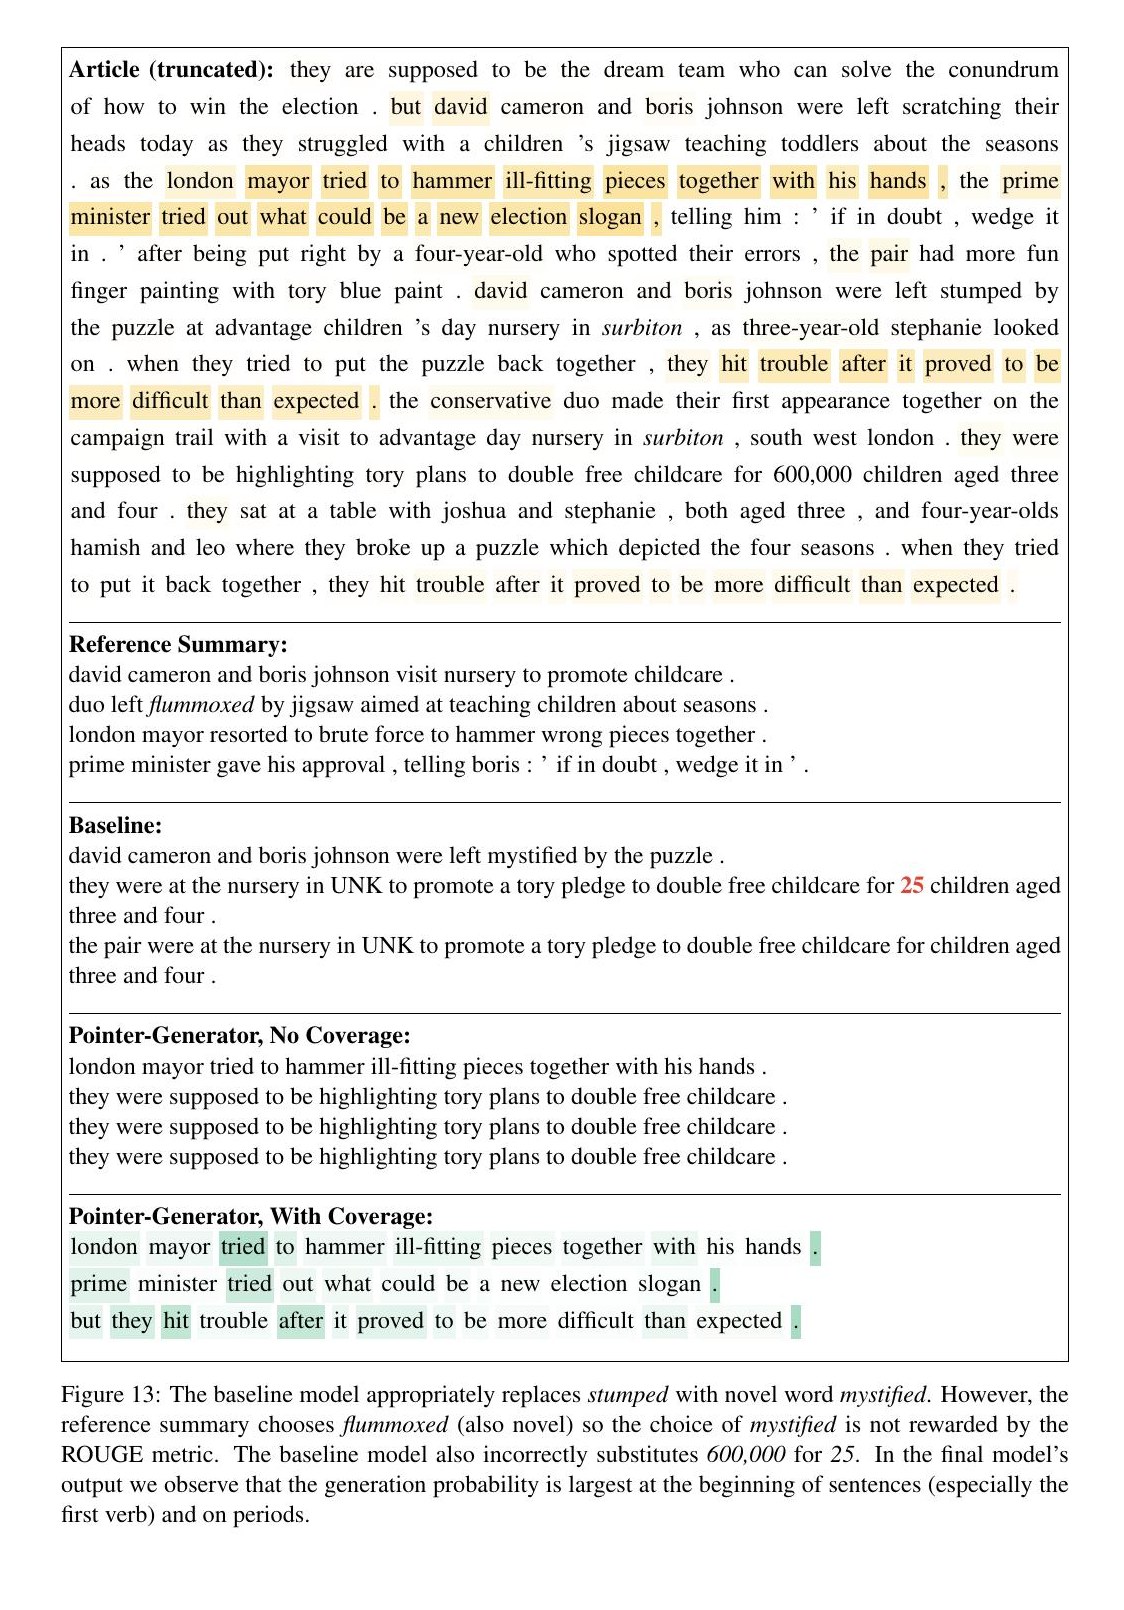
Article (truncated): they are supposed to be the dream team who can solve the conundrum of how to win the election . but david cameron and boris johnson were left scratching their heads today as they struggled with a children ’s jigsaw teaching toddlers about the seasons . as the london mayor tried to hammer ill-fitting pieces together with his hands , the prime minister tried out what could be a new election slogan , telling him : ’ if in doubt , wedge it in . ’ after being put right by a four-year-old who spotted their errors , the pair had more fun finger painting with tory blue paint . david cameron and boris johnson were left stumped by the puzzle at advantage children ’s day nursery in surbiton , as three-year-old stephanie looked on . when they tried to put the puzzle back together , they hit trouble after it proved to be more difficult than expected . the conservative duo made their first appearance together on the campaign trail with a visit to advantage day nursery in surbiton , south west london . they were supposed to be highlighting tory plans to double free childcare for 600,000 children aged three and four . they sat at a table with joshua and stephanie , both aged three , and four-year-olds hamish and leo where they broke up a puzzle which depicted the four seasons . when they tried to put it back together , they hit trouble after it proved to be more difficult than expected . Reference Summary: david cameron and boris johnson visit nursery to promote childcare . duo left flummoxed by jigsaw aimed at teaching children about seasons . london mayor resorted to brute force to hammer wrong pieces together . prime minister gave his approval , telling boris : ’ if in doubt , wedge it in ’ . Baseline: david cameron and boris johnson were left mystified by the puzzle . they were at the nursery in UNK to promote a tory pledge to double free childcare for 25 children aged three and four . the pair were at the nursery in UNK to promote a tory pledge to double free childcare for children aged three and four . Pointer-Generator, No Coverage: london mayor tried to hammer ill-fitting pieces together with his hands . they were supposed to be highlighting tory plans to double free childcare . they were supposed to be highlighting tory plans to double free childcare . they were supposed to be highlighting tory plans to double free childcare . Pointer-Generator, With Coverage: london mayor tried to hammer ill-fitting pieces together with his hands . prime minister tried out what could be a new election slogan . but they hit trouble after it proved to be more difficult than expected .
Article (truncated): they are supposed to be the dream team who can solve the conundrum of how to win the election . but david cameron and boris johnson were left scratching their heads today as they struggled with a children ’s jigsaw teaching toddlers about the seasons . as the london mayor tried to hammer ill-fitting pieces together with his hands , the prime minister tried out what could be a new election slogan , telling him : ’ if in doubt , wedge it in . ’ after being put right by a four-year-old who spotted their errors , the pair had more fun finger painting with tory blue paint . david cameron and boris johnson were left stumped by the puzzle at advantage children ’s day nursery in surbiton , as three-year-old stephanie looked on . when they tried to put the puzzle back together , they hit trouble after it proved to be more difficult than expected . the conservative duo made their first appearance together on the campaign trail with a visit to advantage day nursery in surbiton , south west london . they were supposed to be highlighting tory plans to double free childcare for 600,000 children aged three and four . they sat at a table with joshua and stephanie , both aged three , and four-year-olds hamish and leo where they broke up a puzzle which depicted the four seasons . when they tried to put it back together , they hit trouble after it proved to be more difficult than expected . Reference Summary: david cameron and boris johnson visit nursery to promote childcare . duo left flummoxed by jigsaw aimed at teaching children about seasons . london mayor resorted to brute force to hammer wrong pieces together . prime minister gave his approval , telling boris : ’ if in doubt , wedge it in ’ . Baseline: david cameron and boris johnson were left mystified by the puzzle . they were at the nursery in UNK to promote a tory pledge to double free childcare for 25 children aged three and four . the pair were at the nursery in UNK to promote a tory pledge to double free childcare for children aged three and four . Pointer-Generator, No Coverage: london mayor tried to hammer ill-fitting pieces together with his hands . they were supposed to be highlighting tory plans to double free childcare . they were supposed to be highlighting tory plans to double free childcare . they were supposed to be highlighting tory plans to double free childcare . Pointer-Generator, With Coverage: london mayor tried to hammer ill-fitting pieces together with his hands . prime minister tried out what could be a new election slogan . but they hit trouble after it proved to be more difficult than expected .
Figure 13: The baseline model appropriately replaces stumped with novel word mystified. However, the reference summary chooses flummoxed (also novel) so the choice of mystified is not rewarded by the ROUGE metric. The baseline model also incorrectly substitutes 600,000 for 25. In the final model’s output we observe that the generation probability is largest at the beginning of sentences (especially the first verb) and on periods.
图 13:基线模型恰当地用新词 mystified 替换了 stumped。不过参考摘要选择的是(同样为新词的)flummoxed,因此 mystified 这一选择并不能从 ROUGE 指标中得到奖励。基线模型还错误地把 600,000 换成了 25。在最终模型的输出中,我们看到生成概率在句子开头(尤其是第一个动词)以及句号上最大。
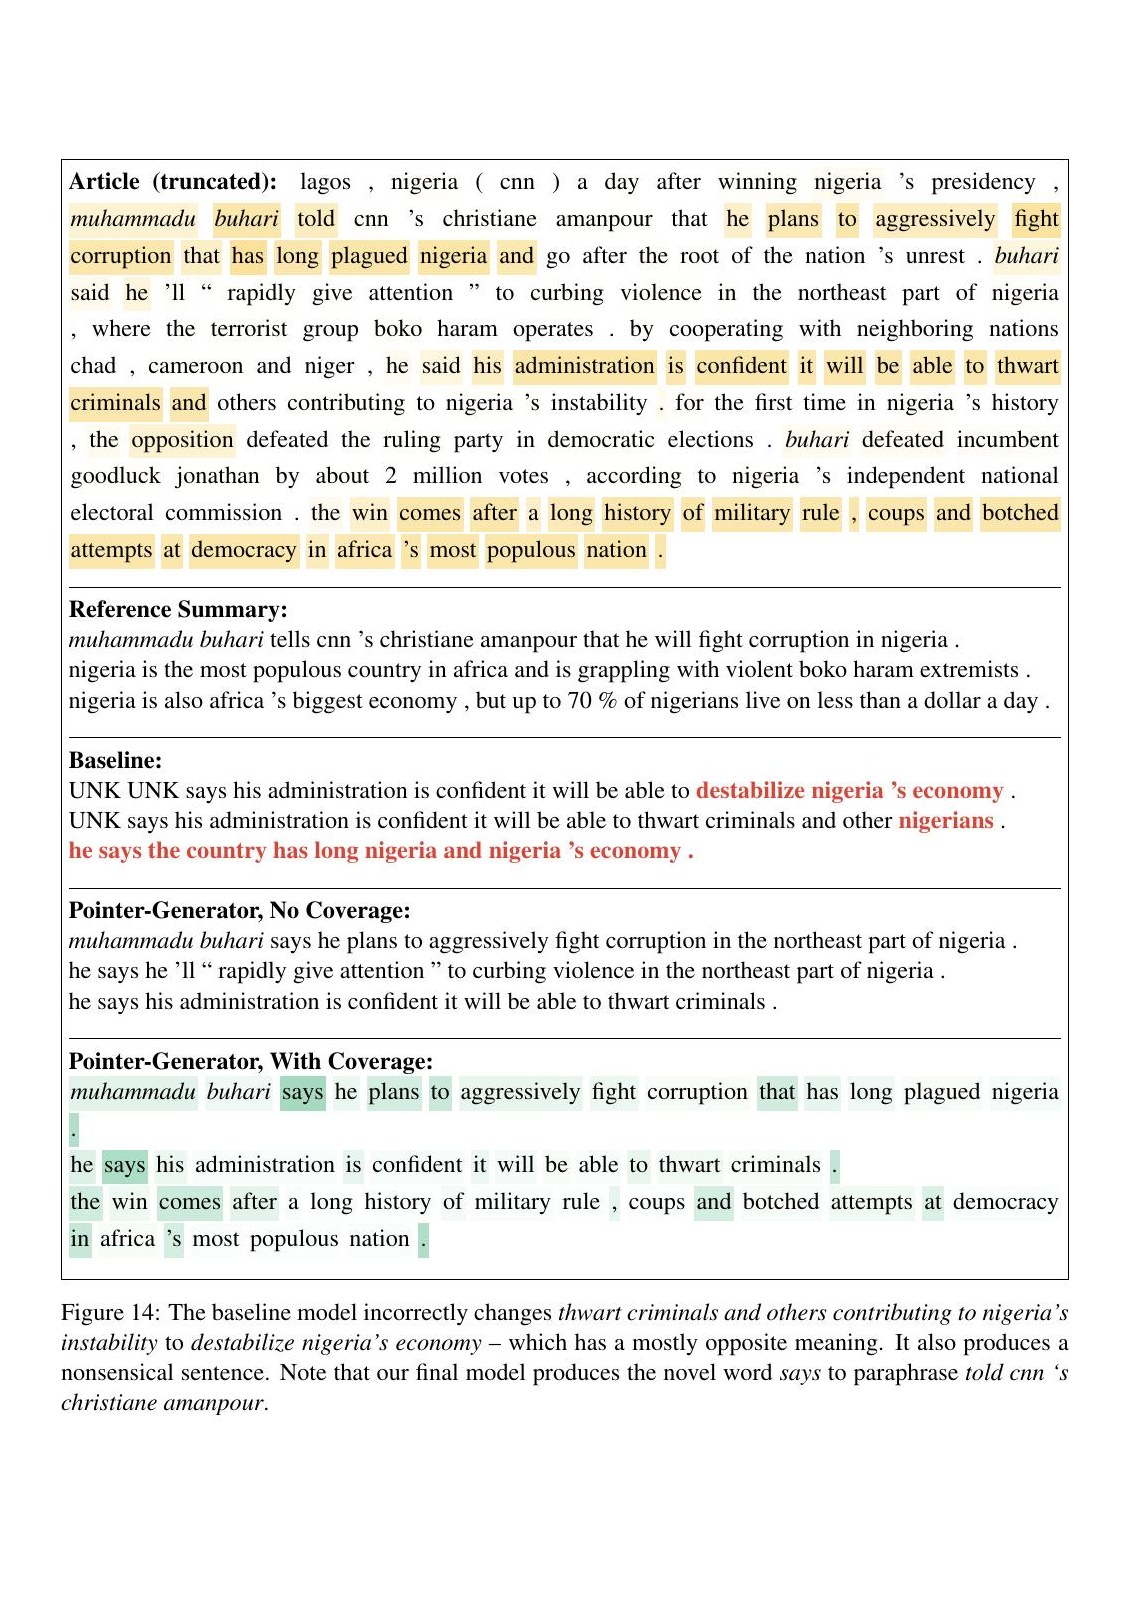
Article (truncated): lagos , nigeria ( cnn ) a day after winning nigeria ’s presidency , muhammadu buhari told cnn ’s christiane amanpour that he plans to aggressively fight corruption that has long plagued nigeria and go after the root of the nation ’s unrest . buhari said he ’ll “ rapidly give attention ” to curbing violence in the northeast part of nigeria , where the terrorist group boko haram operates . by cooperating with neighboring nations chad , cameroon and niger , he said his administration is confident it will be able to thwart criminals and others contributing to nigeria ’s instability . for the first time in nigeria ’s history , the opposition defeated the ruling party in democratic elections . buhari defeated incumbent goodluck jonathan by about 2 million votes , according to nigeria ’s independent national electoral commission . the win comes after a long history of military rule , coups and botched attempts at democracy in africa ’s most populous nation . Reference Summary: muhammadu buhari tells cnn ’s christiane amanpour that he will fight corruption in nigeria . nigeria is the most populous country in africa and is grappling with violent boko haram extremists . nigeria is also africa ’s biggest economy , but up to 70 % of nigerians live on less than a dollar a day . Baseline: UNK UNK says his administration is confident it will be able to destabilize nigeria ’s economy . UNK says his administration is confident it will be able to thwart criminals and other nigerians . he says the country has long nigeria and nigeria ’s economy . Pointer-Generator, No Coverage: muhammadu buhari says he plans to aggressively fight corruption in the northeast part of nigeria . he says he ’ll “ rapidly give attention ” to curbing violence in the northeast part of nigeria . he says his administration is confident it will be able to thwart criminals . Pointer-Generator, With Coverage: muhammadu buhari says he plans to aggressively fight corruption that has long plagued nigeria . he says his administration is confident it will be able to thwart criminals . the win comes after a long history of military rule , coups and botched attempts at democracy in africa ’s most populous nation .
Article (truncated): lagos , nigeria ( cnn ) a day after winning nigeria ’s presidency , muhammadu buhari told cnn ’s christiane amanpour that he plans to aggressively fight corruption that has long plagued nigeria and go after the root of the nation ’s unrest . buhari said he ’ll “ rapidly give attention ” to curbing violence in the northeast part of nigeria , where the terrorist group boko haram operates . by cooperating with neighboring nations chad , cameroon and niger , he said his administration is confident it will be able to thwart criminals and others contributing to nigeria ’s instability . for the first time in nigeria ’s history , the opposition defeated the ruling party in democratic elections . buhari defeated incumbent goodluck jonathan by about 2 million votes , according to nigeria ’s independent national electoral commission . the win comes after a long history of military rule , coups and botched attempts at democracy in africa ’s most populous nation . Reference Summary: muhammadu buhari tells cnn ’s christiane amanpour that he will fight corruption in nigeria . nigeria is the most populous country in africa and is grappling with violent boko haram extremists . nigeria is also africa ’s biggest economy , but up to 70 % of nigerians live on less than a dollar a day . Baseline: UNK UNK says his administration is confident it will be able to destabilize nigeria ’s economy . UNK says his administration is confident it will be able to thwart criminals and other nigerians . he says the country has long nigeria and nigeria ’s economy . Pointer-Generator, No Coverage: muhammadu buhari says he plans to aggressively fight corruption in the northeast part of nigeria . he says he ’ll “ rapidly give attention ” to curbing violence in the northeast part of nigeria . he says his administration is confident it will be able to thwart criminals . Pointer-Generator, With Coverage: muhammadu buhari says he plans to aggressively fight corruption that has long plagued nigeria . he says his administration is confident it will be able to thwart criminals . the win comes after a long history of military rule , coups and botched attempts at democracy in africa ’s most populous nation .
Figure 14: The baseline model incorrectly changes thwart criminals and others contributing to nigeria’s instability to destabilize nigeria’s economy – which has a mostly opposite meaning. It also produces a nonsensical sentence. Note that our final model produces the novel word says to paraphrase told cnn ‘s christiane amanpour.
图 14:基线模型错误地把 thwart criminals and others contributing to nigeria’s instability 改成 destabilize nigeria’s economy——意思几乎相反。它还写出了一个不通的句子。注意我们的最终模型用新词 says 来改写 told cnn ‘s christiane amanpour。
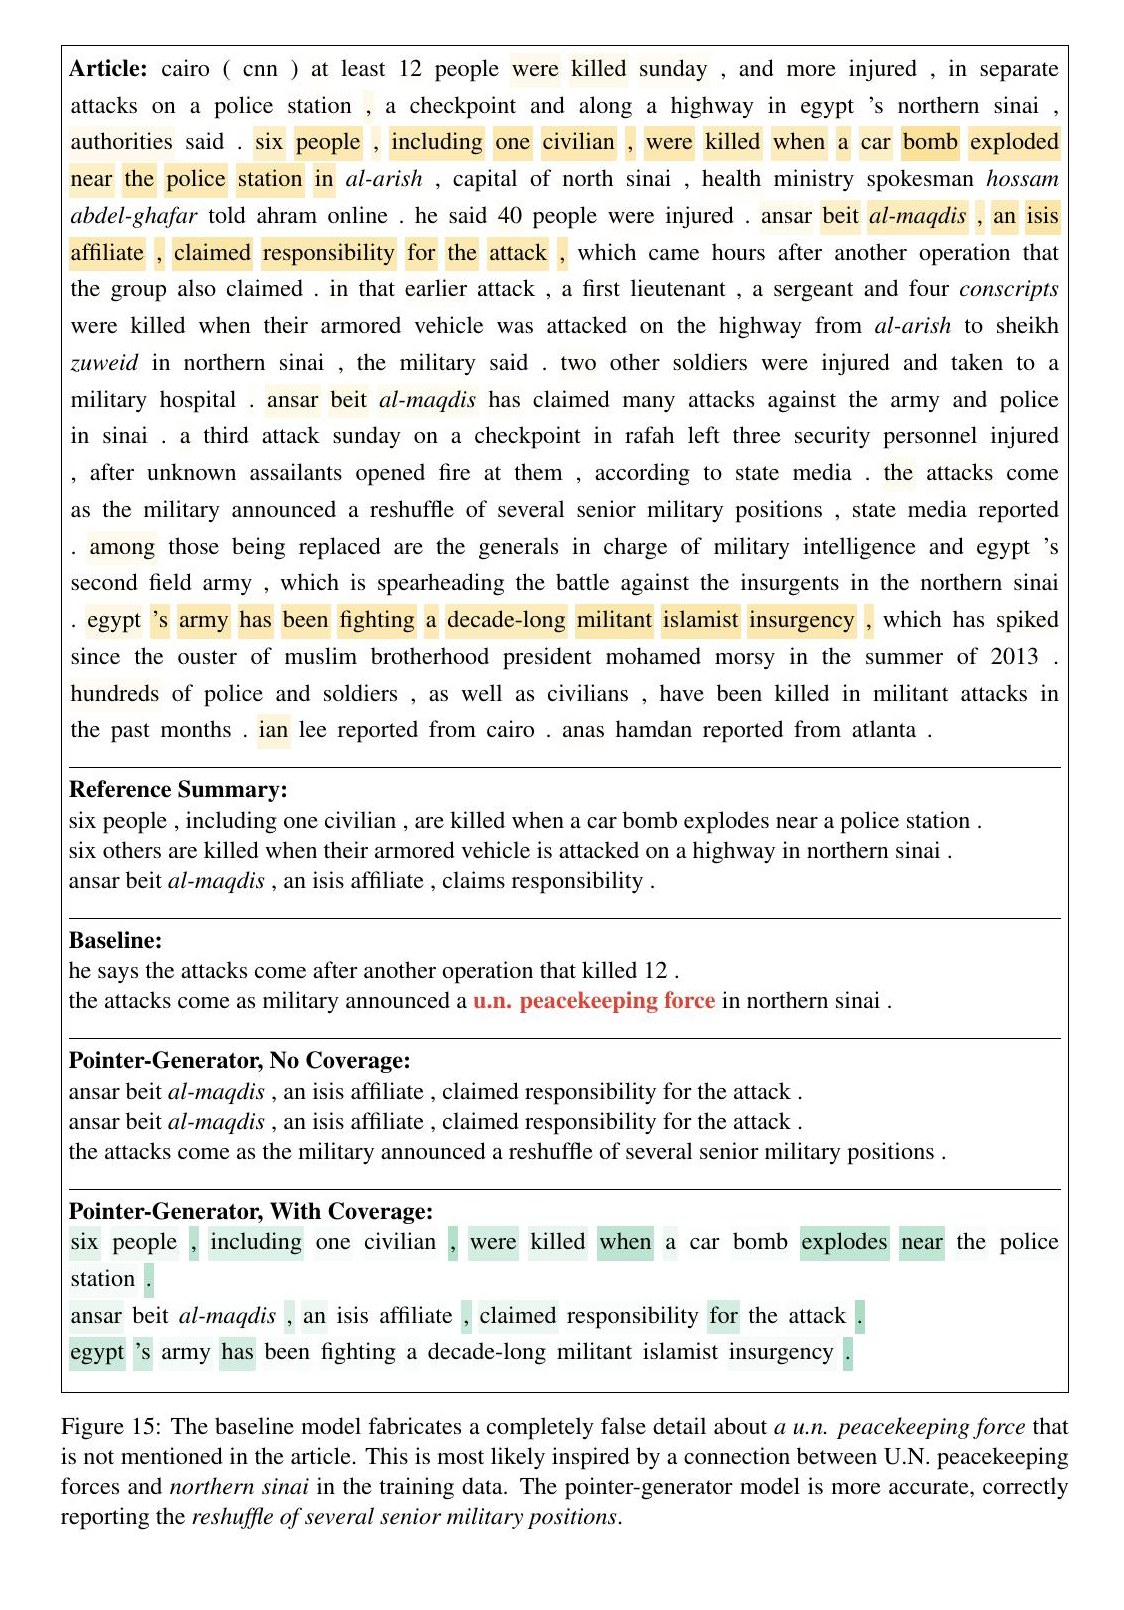
Article: cairo ( cnn ) at least 12 people were killed sunday , and more injured , in separate attacks on a police station , a checkpoint and along a highway in egypt ’s northern sinai , authorities said . six people , including one civilian , were killed when a car bomb exploded near the police station in al-arish , capital of north sinai , health ministry spokesman hossam abdel-ghafar told ahram online . he said 40 people were injured . ansar beit al-maqdis , an isis affiliate , claimed responsibility for the attack , which came hours after another operation that the group also claimed . in that earlier attack , a first lieutenant , a sergeant and four conscripts were killed when their armored vehicle was attacked on the highway from al-arish to sheikh zuweid in northern sinai , the military said . two other soldiers were injured and taken to a military hospital . ansar beit al-maqdis has claimed many attacks against the army and police in sinai . a third attack sunday on a checkpoint in rafah left three security personnel injured , after unknown assailants opened fire at them , according to state media . the attacks come as the military announced a reshuffle of several senior military positions , state media reported . among those being replaced are the generals in charge of military intelligence and egypt ’s second field army , which is spearheading the battle against the insurgents in the northern sinai . egypt ’s army has been fighting a decade-long militant islamist insurgency , which has spiked since the ouster of muslim brotherhood president mohamed morsy in the summer of 2013 . hundreds of police and soldiers , as well as civilians , have been killed in militant attacks in the past months . ian lee reported from cairo . anas hamdan reported from atlanta . Reference Summary: six people , including one civilian , are killed when a car bomb explodes near a police station . six others are killed when their armored vehicle is attacked on a highway in northern sinai . ansar beit al-maqdis , an isis affiliate , claims responsibility . Baseline: he says the attacks come after another operation that killed 12 . the attacks come as military announced a u.n. peacekeeping force in northern sinai . Pointer-Generator, No Coverage: ansar beit al-maqdis , an isis affiliate , claimed responsibility for the attack . ansar beit al-maqdis , an isis affiliate , claimed responsibility for the attack . the attacks come as the military announced a reshuffle of several senior military positions . Pointer-Generator, With Coverage: six people , including one civilian , were killed when a car bomb explodes near the police station . ansar beit al-maqdis , an isis affiliate , claimed responsibility for the attack . egypt ’s army has been fighting a decade-long militant islamist insurgency .
Article: cairo ( cnn ) at least 12 people were killed sunday , and more injured , in separate attacks on a police station , a checkpoint and along a highway in egypt ’s northern sinai , authorities said . six people , including one civilian , were killed when a car bomb exploded near the police station in al-arish , capital of north sinai , health ministry spokesman hossam abdel-ghafar told ahram online . he said 40 people were injured . ansar beit al-maqdis , an isis affiliate , claimed responsibility for the attack , which came hours after another operation that the group also claimed . in that earlier attack , a first lieutenant , a sergeant and four conscripts were killed when their armored vehicle was attacked on the highway from al-arish to sheikh zuweid in northern sinai , the military said . two other soldiers were injured and taken to a military hospital . ansar beit al-maqdis has claimed many attacks against the army and police in sinai . a third attack sunday on a checkpoint in rafah left three security personnel injured , after unknown assailants opened fire at them , according to state media . the attacks come as the military announced a reshuffle of several senior military positions , state media reported . among those being replaced are the generals in charge of military intelligence and egypt ’s second field army , which is spearheading the battle against the insurgents in the northern sinai . egypt ’s army has been fighting a decade-long militant islamist insurgency , which has spiked since the ouster of muslim brotherhood president mohamed morsy in the summer of 2013 . hundreds of police and soldiers , as well as civilians , have been killed in militant attacks in the past months . ian lee reported from cairo . anas hamdan reported from atlanta . Reference Summary: six people , including one civilian , are killed when a car bomb explodes near a police station . six others are killed when their armored vehicle is attacked on a highway in northern sinai . ansar beit al-maqdis , an isis affiliate , claims responsibility . Baseline: he says the attacks come after another operation that killed 12 . the attacks come as military announced a u.n. peacekeeping force in northern sinai . Pointer-Generator, No Coverage: ansar beit al-maqdis , an isis affiliate , claimed responsibility for the attack . ansar beit al-maqdis , an isis affiliate , claimed responsibility for the attack . the attacks come as the military announced a reshuffle of several senior military positions . Pointer-Generator, With Coverage: six people , including one civilian , were killed when a car bomb explodes near the police station . ansar beit al-maqdis , an isis affiliate , claimed responsibility for the attack . egypt ’s army has been fighting a decade-long militant islamist insurgency .
Figure 15: The baseline model fabricates a completely false detail about a u.n. peacekeeping force that is not mentioned in the article. This is most likely inspired by a connection between U.N. peacekeeping forces and northern sinai in the training data. The pointer-generator model is more accurate, correctly reporting the reshuffle of several senior military positions.
图 15:基线模型编造了一个原文完全没有提到的虚假细节:a u.n. peacekeeping force。这很可能是因为训练数据里联合国维和部队与 northern sinai 有过关联。指针生成模型更准确,正确报告了 reshuffle of several senior military positions。