Playing Atari with Deep Reinforcement Learning
Playing Atari with Deep Reinforcement Learning
用深度强化学习玩 Atari 游戏
Abstract
摘要
We present the first deep learning model to successfully learn control policies directly from high-dimensional sensory input using reinforcement learning. The model is a convolutional neural network, trained with a variant of Q-learning, whose input is raw pixels and whose output is a value function estimating future rewards. We apply our method to seven Atari 2600 games from the Arcade Learning Environment, with no adjustment of the architecture or learning algorithm. We find that it outperforms all previous approaches on six of the games and surpasses a human expert on three of them.
我们提出了第一个借助强化学习、直接从高维感官输入中成功学会控制策略的深度学习模型。该模型是一个用 Q 学习(Q-learning)变体训练的卷积神经网络,输入是原始像素,输出是估计未来奖励的价值函数。我们把这一方法应用到街机学习环境(Arcade Learning Environment)中的七款 Atari 2600 游戏上,没有对架构或学习算法做任何调整。结果发现,它在其中六款游戏上超过了此前所有方法,并在其中三款上超过了人类专家。
1 Introduction
1 引言
Learning to control agents directly from high-dimensional sensory inputs like vision and speech is one of the long-standing challenges of reinforcement learning (RL). Most successful RL applications that operate on these domains have relied on hand-crafted features combined with linear value functions or policy representations. Clearly, the performance of such systems heavily relies on the quality of the feature representation.
直接从视觉、语音这类高维感官输入中学会控制智能体,是强化学习(reinforcement learning,RL)长期以来的挑战之一。在这些领域取得成功的 RL 应用,大多依赖人工设计的特征,再配合线性的价值函数或策略表示。显然,这类系统的性能在很大程度上取决于特征表示的质量。
Recent advances in deep learning have made it possible to extract high-level features from raw sensory data, leading to breakthroughs in computer vision [11, 22, 16] and speech recognition [6, 7]. These methods utilise a range of neural network architectures, including convolutional networks, multilayer perceptrons, restricted Boltzmann machines and recurrent neural networks, and have exploited both supervised and unsupervised learning. It seems natural to ask whether similar techniques could also be beneficial for RL with sensory data.
深度学习近来的进展使得从原始感官数据中提取高层特征成为可能,推动了计算机视觉 [11, 22, 16] 和语音识别 [6, 7] 的突破。这些方法使用了一系列神经网络架构,包括卷积网络、多层感知机、受限玻尔兹曼机和循环神经网络,并同时利用了监督学习和无监督学习。很自然的问题是:类似的技术是否也能让基于感官数据的 RL 受益?
However reinforcement learning presents several challenges from a deep learning perspective. Firstly, most successful deep learning applications to date have required large amounts of hand-labelled training data. RL algorithms, on the other hand, must be able to learn from a scalar reward signal that is frequently sparse, noisy and delayed. The delay between actions and resulting rewards, which can be thousands of timesteps long, seems particularly daunting when compared to the direct association between inputs and targets found in supervised learning. Another issue is that most deep learning algorithms assume the data samples to be independent, while in reinforcement learning one typically encounters sequences of highly correlated states. Furthermore, in RL the data distribution changes as the algorithm learns new behaviours, which can be problematic for deep learning methods that assume a fixed underlying distribution.
然而,从深度学习的角度看,强化学习带来了几项挑战。首先,迄今为止大多数成功的深度学习应用都需要大量人工标注的训练数据。而 RL 算法必须能够从一个标量奖励信号中学习,这个信号往往是稀疏的、有噪声的,而且是延迟的。动作与其带来的奖励之间的延迟可能长达数千个时间步,与监督学习中输入和目标之间的直接对应相比,这一点尤其令人生畏。另一个问题是,大多数深度学习算法假设数据样本相互独立,而强化学习中通常遇到的是高度相关的状态序列。此外,在 RL 中,数据分布会随着算法学到新的行为而变化,这对假设底层分布固定的深度学习方法来说可能是个问题。
This paper demonstrates that a convolutional neural network can overcome these challenges to learn successful control policies from raw video data in complex RL environments. The network is trained with a variant of the Q-learning [26] algorithm, with stochastic gradient descent to update the weights. To alleviate the problems of correlated data and non-stationary distributions, we use an experience replay mechanism [13] which randomly samples previous transitions, and thereby smooths the training distribution over many past behaviors.
本文表明,卷积神经网络能够克服这些挑战,在复杂的 RL 环境中从原始视频数据学到成功的控制策略。网络用 Q 学习 [26] 算法的一个变体训练,用随机梯度下降更新权重。为了缓解数据相关和分布不平稳的问题,我们使用经验回放(experience replay)机制 [13]:随机采样以前的状态转移,从而在许多过去的行为上平滑训练分布。
We apply our approach to a range of Atari 2600 games implemented in The Arcade Learning Environment (ALE) [3]. Atari 2600 is a challenging RL testbed that presents agents with a high dimensional visual input ( RGB video at 60Hz) and a diverse and interesting set of tasks that were designed to be difficult for humans players. Our goal is to create a single neural network agent that is able to successfully learn to play as many of the games as possible. The network was not provided with any game-specific information or hand-designed visual features, and was not privy to the internal state of the emulator; it learned from nothing but the video input, the reward and terminal signals, and the set of possible actions—just as a human player would. Furthermore the network architecture and all hyperparameters used for training were kept constant across the games. So far the network has outperformed all previous RL algorithms on six of the seven games we have attempted and surpassed an expert human player on three of them. Figure 1 provides sample screenshots from five of the games used for training.
我们把这一方法应用到街机学习环境(ALE)[3] 实现的一系列 Atari 2600 游戏上。Atari 2600 是一个有挑战性的 RL 测试平台:它给智能体提供高维视觉输入(60Hz 的 RGB 视频),以及一组多样而有趣、本就设计得让人类玩家觉得困难的任务。我们的目标是做出单个神经网络智能体,让它学会玩尽可能多的游戏。网络没有得到任何针对具体游戏的信息或人工设计的视觉特征,也无法获知模拟器的内部状态;它只从视频输入、奖励和终止信号以及可选动作集合中学习,和人类玩家一样。此外,网络架构和训练用的所有超参数在各个游戏间都保持不变。到目前为止,在我们尝试的七款游戏中,网络在六款上超过了此前所有 RL 算法,并在其中三款上超过了人类专家玩家。图 1 给出了训练所用五款游戏的截图示例。
Figure 1: Screen shots from five Atari 2600 Games: (Left-to-right) Pong, Breakout, Space Invaders, Seaquest, Beam Rider
图 1:五款 Atari 2600 游戏的截图:(从左到右)Pong、Breakout、Space Invaders、Seaquest、Beam Rider
2 Background
2 背景
We consider tasks in which an agent interacts with an environment , in this case the Atari emulator, in a sequence of actions, observations and rewards. At each time-step the agent selects an action from the set of legal game actions, . The action is passed to the emulator and modifies its internal state and the game score. In general may be stochastic. The emulator’s internal state is not observed by the agent; instead it observes an image from the emulator, which is a vector of raw pixel values representing the current screen. In addition it receives a reward representing the change in game score. Note that in general the game score may depend on the whole prior sequence of actions and observations; feedback about an action may only be received after many thousands of time-steps have elapsed.
我们考虑这样一类任务:智能体通过一连串动作、观测和奖励,与环境 (这里是 Atari 模拟器)交互。每个时间步,智能体从合法的游戏动作集合 中选择一个动作 。动作被传给模拟器,改变它的内部状态和游戏得分。一般来说 可能是随机的。智能体观测不到模拟器的内部状态,只能观测到模拟器给出的图像 ,即表示当前屏幕的原始像素值向量。此外,它还会收到表示游戏得分变化的奖励 。注意,一般来说游戏得分可能取决于之前整个动作和观测序列;关于某个动作的反馈,可能要过数千个时间步才能收到。
Since the agent only observes images of the current screen, the task is partially observed and many emulator states are perceptually aliased, i.e. it is impossible to fully understand the current situation from only the current screen . We therefore consider sequences of actions and observations, , and learn game strategies that depend upon these sequences. All sequences in the emulator are assumed to terminate in a finite number of time-steps. This formalism gives rise to a large but finite Markov decision process (MDP) in which each sequence is a distinct state. As a result, we can apply standard reinforcement learning methods for MDPs, simply by using the complete sequence as the state representation at time .
由于智能体只能观测当前屏幕的图像,这个任务是部分可观测的,许多模拟器状态在感知上无法区分(perceptually aliased),也就是说,仅凭当前屏幕 无法完全理解当前局面。因此我们考虑动作和观测的序列 ,并学习依赖于这些序列的游戏策略。模拟器中的所有序列都假定在有限个时间步内终止。这一形式化给出了一个庞大但有限的马尔可夫决策过程(Markov decision process,MDP),其中每个序列都是一个不同的状态。因此,只要把完整序列 作为时刻 的状态表示,就可以对 MDP 应用标准的强化学习方法。
The goal of the agent is to interact with the emulator by selecting actions in a way that maximises future rewards. We make the standard assumption that future rewards are discounted by a factor of per time-step, and define the future discounted return at time as , where is the time-step at which the game terminates. We define the optimal action-value function as the maximum expected return achievable by following any strategy, after seeing some sequence and then taking some action , , where is a policy mapping sequences to actions (or distributions over actions).
智能体的目标是通过选择动作与模拟器交互,使未来奖励最大化。我们采用标准假设:未来奖励每个时间步按因子 折扣,并把时刻 的未来折扣回报(return)定义为 ,其中 是游戏终止的时间步。我们把最优动作价值函数(action-value function) 定义为:在看到某个序列 并采取某个动作 之后,遵循任意策略所能达到的最大期望回报,,其中 是把序列映射到动作(或动作上的分布)的策略。
The optimal action-value function obeys an important identity known as the Bellman equation. This is based on the following intuition: if the optimal value of the sequence at the next time-step was known for all possible actions , then the optimal strategy is to select the action maximising the expected value of ,
最优动作价值函数满足一个重要的恒等式,称为贝尔曼方程(Bellman equation)。其直觉如下:如果下一时间步的序列 对所有可能动作 的最优价值 都已知,那么最优策略就是选择使 的期望值最大的动作 :
The basic idea behind many reinforcement learning algorithms is to estimate the action-value function, by using the Bellman equation as an iterative update, . Such value iteration algorithms converge to the optimal action-value function, as [23]. In practice, this basic approach is totally impractical, because the action-value function is estimated separately for each sequence, without any generalisation. Instead, it is common to use a function approximator to estimate the action-value function, . In the reinforcement learning community this is typically a linear function approximator, but sometimes a non-linear function approximator is used instead, such as a neural network. We refer to a neural network function approximator with weights as a Q-network. A Q-network can be trained by minimising a sequence of loss functions that changes at each iteration ,
许多强化学习算法背后的基本思路,是把贝尔曼方程当作迭代更新来估计动作价值函数:。这类价值迭代(value iteration)算法会收敛到最优动作价值函数,即当 时 [23]。实际上,这种基本方法完全不可行,因为它对每个序列分别估计动作价值函数,没有任何泛化。通常的做法是用函数逼近器来估计动作价值函数,。强化学习领域一般使用线性函数逼近器,但有时也会改用非线性函数逼近器,例如神经网络。我们把权重为 的神经网络函数逼近器称为 Q 网络(Q-network)。Q 网络可以通过最小化一系列在每次迭代 时变化的损失函数 来训练:
where is the target for iteration and is a probability distribution over sequences and actions that we refer to as the behaviour distribution. The parameters from the previous iteration are held fixed when optimising the loss function . Note that the targets depend on the network weights; this is in contrast with the targets used for supervised learning, which are fixed before learning begins. Differentiating the loss function with respect to the weights we arrive at the following gradient,
其中 是第 次迭代的目标, 是序列 和动作 上的概率分布,我们称之为行为分布(behaviour distribution)。优化损失函数 时,上一次迭代的参数 保持固定。注意,这里的目标依赖于网络权重;这与监督学习不同,监督学习的目标在学习开始前就已固定。对损失函数求关于权重的导数,得到如下梯度:
Rather than computing the full expectations in the above gradient, it is often computationally expedient to optimise the loss function by stochastic gradient descent. If the weights are updated after every time-step, and the expectations are replaced by single samples from the behaviour distribution and the emulator respectively, then we arrive at the familiar Q-learning algorithm [26].
与其计算上述梯度中的完整期望,用随机梯度下降优化损失函数在计算上往往更方便。如果每个时间步都更新权重,并分别用来自行为分布 和模拟器 的单个样本代替期望,就得到了熟悉的 Q 学习算法 [26]。
Note that this algorithm is model-free: it solves the reinforcement learning task directly using samples from the emulator , without explicitly constructing an estimate of . It is also off-policy: it learns about the greedy strategy , while following a behaviour distribution that ensures adequate exploration of the state space. In practice, the behaviour distribution is often selected by an -greedy strategy that follows the greedy strategy with probability and selects a random action with probability .
注意,这个算法是无模型(model-free)的:它直接用来自模拟器 的样本求解强化学习任务,而不显式构建对 的估计。它也是离策略(off-policy)的:它学习的是贪心策略 ,遵循的却是一个能充分探索状态空间的行为分布。实践中,行为分布通常按 贪心(-greedy)策略选取:以 的概率遵循贪心策略,以 的概率随机选择动作。
3 Related Work
3 相关工作
Perhaps the best-known success story of reinforcement learning is TD-gammon, a backgammon-playing program which learnt entirely by reinforcement learning and self-play, and achieved a super-human level of play [24]. TD-gammon used a model-free reinforcement learning algorithm similar to Q-learning, and approximated the value function using a multi-layer perceptron with one hidden layer¹.
强化学习最著名的成功案例,或许是 TD-gammon:一个完全通过强化学习和自我对弈学会玩西洋双陆棋(backgammon)的程序,达到了超越人类的水平 [24]。TD-gammon 使用了一种与 Q 学习类似的无模型强化学习算法,并用只有一个隐藏层的多层感知机逼近价值函数¹。
¹ In fact TD-Gammon approximated the state value function rather than the action-value function , and learnt on-policy directly from the self-play games
¹ 实际上,TD-Gammon 逼近的是状态价值函数 而不是动作价值函数 ,并且是直接从自我对弈的棋局中同策略(on-policy)地学习。
However, early attempts to follow up on TD-gammon, including applications of the same method to chess, Go and checkers were less successful. This led to a widespread belief that the TD-gammon approach was a special case that only worked in backgammon, perhaps because the stochasticity in the dice rolls helps explore the state space and also makes the value function particularly smooth [19].
然而,早期沿着 TD-gammon 继续推进的尝试,包括把同样的方法用于国际象棋、围棋和西洋跳棋,都不太成功。这让人们普遍认为 TD-gammon 的方法是一个特例,只在西洋双陆棋上有效;原因可能是掷骰子带来的随机性有助于探索状态空间,也让价值函数特别平滑 [19]。
Furthermore, it was shown that combining model-free reinforcement learning algorithms such as Q-learning with non-linear function approximators [25], or indeed with off-policy learning [1] could cause the Q-network to diverge. Subsequently, the majority of work in reinforcement learning focused on linear function approximators with better convergence guarantees [25].
此外,已有研究表明,把 Q 学习这类无模型强化学习算法与非线性函数逼近器结合 [25],或者与离策略学习结合 [1],都可能导致 Q 网络发散。此后,强化学习的大多数工作都转向了收敛保证更好的线性函数逼近器 [25]。
More recently, there has been a revival of interest in combining deep learning with reinforcement learning. Deep neural networks have been used to estimate the environment ; restricted Boltzmann machines have been used to estimate the value function [21]; or the policy [9]. In addition, the divergence issues with Q-learning have been partially addressed by gradient temporal-difference methods. These methods are proven to converge when evaluating a fixed policy with a nonlinear function approximator [14]; or when learning a control policy with linear function approximation using a restricted variant of Q-learning [15]. However, these methods have not yet been extended to nonlinear control.
最近,把深度学习与强化学习结合的兴趣重新兴起。深度神经网络被用来估计环境 ;受限玻尔兹曼机被用来估计价值函数 [21] 或策略 [9]。此外,梯度时序差分(gradient temporal-difference)方法部分解决了 Q 学习的发散问题。这些方法已被证明,在用非线性函数逼近器评估固定策略时 [14],或在用受限的 Q 学习变体和线性函数逼近学习控制策略时 [15],是收敛的。不过,这些方法还没有扩展到非线性控制。
Perhaps the most similar prior work to our own approach is neural fitted Q-learning (NFQ) [20]. NFQ optimises the sequence of loss functions in Equation 2, using the RPROP algorithm to update the parameters of the Q-network. However, it uses a batch update that has a computational cost per iteration that is proportional to the size of the data set, whereas we consider stochastic gradient updates that have a low constant cost per iteration and scale to large data-sets. NFQ has also been successfully applied to simple real-world control tasks using purely visual input, by first using deep autoencoders to learn a low dimensional representation of the task, and then applying NFQ to this representation [12]. In contrast our approach applies reinforcement learning end-to-end, directly from the visual inputs; as a result it may learn features that are directly relevant to discriminating action-values. Q-learning has also previously been combined with experience replay and a simple neural network [13], but again starting with a low-dimensional state rather than raw visual inputs.
与我们的方法最相似的先前工作,或许是神经拟合 Q 学习(neural fitted Q-learning,NFQ)[20]。NFQ 优化式 2 中的那一系列损失函数,用 RPROP 算法更新 Q 网络的参数。然而,它使用批量更新,每次迭代的计算成本与数据集大小成正比;而我们采用随机梯度更新,每次迭代的成本是一个较低的常数,可以扩展到大数据集。NFQ 也已成功用于只有视觉输入的简单真实世界控制任务:先用深度自编码器学习任务的低维表示,再在这个表示上应用 NFQ [12]。相比之下,我们的方法直接从视觉输入端到端地应用强化学习,因而可能学到与区分动作价值直接相关的特征。此前也有工作把 Q 学习与经验回放和一个简单的神经网络结合起来 [13],但同样是从低维状态而不是原始视觉输入出发。
The use of the Atari 2600 emulator as a reinforcement learning platform was introduced by [3], who applied standard reinforcement learning algorithms with linear function approximation and generic visual features. Subsequently, results were improved by using a larger number of features, and using tug-of-war hashing to randomly project the features into a lower-dimensional space [2]. The HyperNEAT evolutionary architecture [8] has also been applied to the Atari platform, where it was used to evolve (separately, for each distinct game) a neural network representing a strategy for that game. When trained repeatedly against deterministic sequences using the emulator’s reset facility, these strategies were able to exploit design flaws in several Atari games.
把 Atari 2600 模拟器用作强化学习平台始于 [3],该工作用线性函数逼近和通用视觉特征应用了标准强化学习算法。随后,通过使用更多特征,并用拔河哈希(tug-of-war hashing)把特征随机投影到低维空间,结果得到了改进 [2]。HyperNEAT 演化架构 [8] 也被用于 Atari 平台,为每款游戏分别演化出一个表示该游戏策略的神经网络。借助模拟器的重置功能,针对确定性序列反复训练后,这些策略能够利用好几款 Atari 游戏中的设计缺陷。
4 Deep Reinforcement Learning
4 深度强化学习
Recent breakthroughs in computer vision and speech recognition have relied on efficiently training deep neural networks on very large training sets. The most successful approaches are trained directly from the raw inputs, using lightweight updates based on stochastic gradient descent. By feeding sufficient data into deep neural networks, it is often possible to learn better representations than handcrafted features [11]. These successes motivate our approach to reinforcement learning. Our goal is to connect a reinforcement learning algorithm to a deep neural network which operates directly on RGB images and efficiently process training data by using stochastic gradient updates.
计算机视觉和语音识别近来的突破,依赖于在非常大的训练集上高效训练深度神经网络。最成功的方法都直接从原始输入训练,使用基于随机梯度下降的轻量更新。只要给深度神经网络输入足够多的数据,往往就能学到比人工特征更好的表示 [11]。这些成功启发了我们在强化学习上的做法。我们的目标是把强化学习算法与一个直接处理 RGB 图像的深度神经网络连接起来,并用随机梯度更新高效地处理训练数据。
Tesauro’s TD-Gammon architecture provides a starting point for such an approach. This architecture updates the parameters of a network that estimates the value function, directly from on-policy samples of experience, , drawn from the algorithm’s interactions with the environment (or by self-play, in the case of backgammon). Since this approach was able to outperform the best human backgammon players 20 years ago, it is natural to wonder whether two decades of hardware improvements, coupled with modern deep neural network architectures and scalable RL algorithms might produce significant progress.
Tesauro 的 TD-Gammon 架构为这样的方法提供了起点。这一架构直接用经验的同策略样本 更新估计价值函数的网络参数,这些样本来自算法与环境的交互(在西洋双陆棋中则来自自我对弈)。既然这种方法在 20 年前就能胜过最好的人类双陆棋玩家,人们自然会想:二十年的硬件进步,加上现代深度神经网络架构和可扩展的 RL 算法,或许能带来重大进展。
In contrast to TD-Gammon and similar online approaches, we utilize a technique known as experience replay [13] where we store the agent’s experiences at each time-step, in a data-set , pooled over many episodes into a replay memory. During the inner loop of the algorithm, we apply Q-learning updates, or minibatch updates, to samples of experience, , drawn at random from the pool of stored samples. After performing experience replay, the agent selects and executes an action according to an -greedy policy. Since using histories of arbitrary length as inputs to a neural network can be difficult, our Q-function instead works on fixed length representation of histories produced by a function . The full algorithm, which we call deep Q-learning, is presented in Algorithm 1.
与 TD-Gammon 及类似的在线方法不同,我们使用一种称为经验回放的技术 [13]:把智能体在每个时间步的经验 存进数据集 ,许多回合(episode)的经验汇集在一起,构成回放记忆(replay memory)。在算法的内循环中,我们从存储的样本池中随机抽取经验样本 ,对其应用 Q 学习更新或小批量更新。完成经验回放后,智能体按 贪心策略选择并执行一个动作。由于把任意长度的历史作为神经网络输入比较困难,我们的 Q 函数改为作用在由函数 产生的固定长度历史表示上。完整算法称为深度 Q 学习(deep Q-learning),见算法 1。
This approach has several advantages over standard online Q-learning [23]. First, each step of experience is potentially used in many weight updates, which allows for greater data efficiency. Second, learning directly from consecutive samples is inefficient, due to the strong correlations between the samples; randomizing the samples breaks these correlations and therefore reduces the variance of the updates. Third, when learning on-policy the current parameters determine the next data sample that the parameters are trained on. For example, if the maximizing action is to move left then the training samples will be dominated by samples from the left-hand side; if the maximizing action then switches to the right then the training distribution will also switch. It is easy to see how unwanted feedback loops may arise and the parameters could get stuck in a poor local minimum, or even diverge catastrophically [25]. By using experience replay the behavior distribution is averaged over many of its previous states, smoothing out learning and avoiding oscillations or divergence in the parameters. Note that when learning by experience replay, it is necessary to learn off-policy (because our current parameters are different to those used to generate the sample), which motivates the choice of Q-learning.
与标准的在线 Q 学习 [23] 相比,这种方法有几项优点。第一,每一步经验都可能被用于多次权重更新,数据效率更高。第二,样本之间相关性很强,直接从连续样本中学习效率很低;把样本随机化能打破这些相关性,从而降低更新的方差。第三,同策略学习时,当前参数决定了下一批用来训练参数的数据样本。例如,如果使价值最大的动作是向左移动,训练样本就会以左侧的样本为主;如果使价值最大的动作随后变成向右,训练分布也会随之切换。不难看出,这可能产生不希望出现的反馈回路,参数可能卡在很差的局部极小值,甚至灾难性地发散 [25]。使用经验回放后,行为分布是在之前许多状态上取平均的,这让学习更平滑,避免了参数的振荡或发散。注意,用经验回放学习时,必须采用离策略学习(因为当前参数与生成样本时所用的参数不同),这也是选择 Q 学习的原因。
In practice, our algorithm only stores the last experience tuples in the replay memory, and samples uniformly at random from when performing updates. This approach is in some respects limited since the memory buffer does not differentiate important transitions and always overwrites with recent transitions due to the finite memory size . Similarly, the uniform sampling gives equal importance to all transitions in the replay memory. A more sophisticated sampling strategy might emphasize transitions from which we can learn the most, similar to prioritized sweeping [17].
实践中,我们的算法只在回放记忆中保存最近的 个经验元组,更新时从 中均匀随机采样。这种做法在某些方面有局限:记忆缓冲区不区分重要的状态转移,并且由于记忆容量 有限,总是用最新的转移覆盖旧的。同样,均匀采样给回放记忆中的所有转移以同等的重要性。更精巧的采样策略可以侧重那些最能让我们学到东西的转移,类似于优先清扫(prioritized sweeping)[17]。
Algorithm 1 Deep Q-learning with Experience Replay
- Initialize replay memory to capacity
- Initialize action-value function with random weights
- for episode do
- Initialise sequence and preprocessed sequenced
- for do
- With probability select a random action
- otherwise select
- Execute action in emulator and observe reward and image
- Set and preprocess
- Store transition in
- Sample random minibatch of transitions from
- Set
- Perform a gradient descent step on according to equation 3
- end for
- end for
算法 1 带经验回放的深度 Q 学习
- 把回放记忆 初始化为容量
- 用随机权重初始化动作价值函数
- for 回合 do
- 初始化序列 和预处理后的序列
- for do
- 以概率 随机选择一个动作
- 否则选择
- 在模拟器中执行动作 ,观测奖励 和图像
- 令 ,并预处理得到
- 把转移 存入
- 从 中随机采样一个小批量的转移
- 令
- 按式 3 对 做一步梯度下降
- end for
- end for
4.1 Preprocessing and Model Architecture
4.1 预处理和模型架构
Working directly with raw Atari frames, which are pixel images with a 128 color palette, can be computationally demanding, so we apply a basic preprocessing step aimed at reducing the input dimensionality. The raw frames are preprocessed by first converting their RGB representation to gray-scale and down-sampling it to a image. The final input representation is obtained by cropping an region of the image that roughly captures the playing area. The final cropping stage is only required because we use the GPU implementation of 2D convolutions from [11], which expects square inputs. For the experiments in this paper, the function from algorithm 1 applies this preprocessing to the last frames of a history and stacks them to produce the input to the -function.
原始 Atari 帧是 像素、128 色调色板的图像,直接处理的计算量很大,所以我们做了一个简单的预处理步骤来降低输入维度。原始帧先从 RGB 表示转为灰度,再下采样为 的图像。最终的输入表示是从图像中裁出一块大致覆盖游戏区域的 区域。之所以需要最后这一步裁剪,只是因为我们使用的是 [11] 中二维卷积的 GPU 实现,它要求输入是正方形。在本文的实验中,算法 1 中的函数 对历史中的最后 帧做这种预处理,再把它们堆叠起来作为 函数的输入。
There are several possible ways of parameterizing using a neural network. Since maps history-action pairs to scalar estimates of their Q-value, the history and the action have been used as inputs to the neural network by some previous approaches [20, 12]. The main drawback of this type of architecture is that a separate forward pass is required to compute the Q-value of each action, resulting in a cost that scales linearly with the number of actions. We instead use an architecture in which there is a separate output unit for each possible action, and only the state representation is an input to the neural network. The outputs correspond to the predicted Q-values of the individual action for the input state. The main advantage of this type of architecture is the ability to compute Q-values for all possible actions in a given state with only a single forward pass through the network.
用神经网络参数化 有几种可能的方式。由于 把“历史-动作”对映射为对其 Q 值的标量估计,一些先前的方法把历史和动作都作为神经网络的输入 [20, 12]。这类架构的主要缺点是,计算每个动作的 Q 值都需要单独做一次前向传播,成本随动作数量线性增长。我们改用另一种架构:每个可能的动作都有一个单独的输出单元,只有状态表示作为神经网络的输入。各输出对应输入状态下各个动作的预测 Q 值。这类架构的主要优点是,只需对网络做一次前向传播,就能算出给定状态下所有可能动作的 Q 值。
We now describe the exact architecture used for all seven Atari games. The input to the neural network consists is an image produced by . The first hidden layer convolves filters with stride with the input image and applies a rectifier nonlinearity [10, 18]. The second hidden layer convolves filters with stride , again followed by a rectifier nonlinearity. The final hidden layer is fully-connected and consists of rectifier units. The output layer is a fully-connected linear layer with a single output for each valid action. The number of valid actions varied between and on the games we considered. We refer to convolutional networks trained with our approach as Deep Q-Networks (DQN).
下面介绍七款 Atari 游戏统一使用的具体架构。神经网络的输入是由 产生的 图像。第一个隐藏层用 个步长为 的 滤波器对输入图像做卷积,并施加整流非线性 [10, 18]。第二个隐藏层用 个步长为 的 滤波器做卷积,同样接整流非线性。最后一个隐藏层是全连接层,由 个整流单元组成。输出层是一个全连接的线性层,每个有效动作对应一个输出。在我们考虑的游戏中,有效动作的数量在 到 之间。我们把用这种方法训练的卷积网络称为深度 Q 网络(Deep Q-Networks,DQN)。
5 Experiments
5 实验
So far, we have performed experiments on seven popular ATARI games – Beam Rider, Breakout, Enduro, Pong, Q*bert, Seaquest, Space Invaders. We use the same network architecture, learning algorithm and hyperparameters settings across all seven games, showing that our approach is robust enough to work on a variety of games without incorporating game-specific information. While we evaluated our agents on the real and unmodified games, we made one change to the reward structure of the games during training only. Since the scale of scores varies greatly from game to game, we fixed all positive rewards to be and all negative rewards to be , leaving rewards unchanged. Clipping the rewards in this manner limits the scale of the error derivatives and makes it easier to use the same learning rate across multiple games. At the same time, it could affect the performance of our agent since it cannot differentiate between rewards of different magnitude.
到目前为止,我们在七款流行的 Atari 游戏上做了实验:Beam Rider、Breakout、Enduro、Pong、Q*bert、Seaquest 和 Space Invaders。七款游戏使用相同的网络架构、学习算法和超参数设置,表明我们的方法足够稳健,无需引入针对具体游戏的信息就能适用于多种游戏。我们在真实、未经修改的游戏上评估智能体,但只在训练期间对游戏的奖励结构做了一处修改。由于不同游戏的得分尺度差异很大,我们把所有正奖励固定为 ,所有负奖励固定为 ,奖励为 时保持不变。这样裁剪奖励限制了误差导数的尺度,更容易在多个游戏中使用同一个学习率。同时,这可能影响智能体的表现,因为它无法区分大小不同的奖励。
In these experiments, we used the RMSProp algorithm with minibatches of size 32. The behavior policy during training was -greedy with annealed linearly from to over the first million frames, and fixed at thereafter. We trained for a total of million frames and used a replay memory of one million most recent frames.
这些实验中,我们使用小批量大小为 32 的 RMSProp 算法。训练期间的行为策略是 贪心策略, 在前一百万帧内从 线性退火到 ,之后固定为 。我们总共训练了 万帧,回放记忆保存最近的一百万帧。
Following previous approaches to playing Atari games, we also use a simple frame-skipping technique [3]. More precisely, the agent sees and selects actions on every frame instead of every frame, and its last action is repeated on skipped frames. Since running the emulator forward for one step requires much less computation than having the agent select an action, this technique allows the agent to play roughly times more games without significantly increasing the runtime. We use for all games except Space Invaders where we noticed that using makes the lasers invisible because of the period at which they blink. We used to make the lasers visible and this change was the only difference in hyperparameter values between any of the games.
沿用先前玩 Atari 游戏的方法,我们也使用一种简单的跳帧(frame-skipping)技术 [3]。具体来说,智能体每隔 帧才观测并选择一次动作,而不是每帧都这样做,被跳过的帧上重复执行上一个动作。由于让模拟器前进一步所需的计算远少于让智能体选择一个动作,这一技术让智能体在运行时间没有明显增加的情况下,能多玩大约 倍的游戏。除 Space Invaders 外,所有游戏都使用 ;在 Space Invaders 中我们注意到,由于激光闪烁的周期,使用 会让激光不可见。我们用 让激光可见,这是各游戏之间超参数取值的唯一差别。
5.1 Training and Stability
5.1 训练与稳定性
In supervised learning, one can easily track the performance of a model during training by evaluating it on the training and validation sets. In reinforcement learning, however, accurately evaluating the progress of an agent during training can be challenging. Since our evaluation metric, as suggested by [3], is the total reward the agent collects in an episode or game averaged over a number of games, we periodically compute it during training. The average total reward metric tends to be very noisy because small changes to the weights of a policy can lead to large changes in the distribution of states the policy visits . The leftmost two plots in figure 2 show how the average total reward evolves during training on the games Seaquest and Breakout. Both averaged reward plots are indeed quite noisy, giving one the impression that the learning algorithm is not making steady progress. Another, more stable, metric is the policy’s estimated action-value function , which provides an estimate of how much discounted reward the agent can obtain by following its policy from any given state. We collect a fixed set of states by running a random policy before training starts and track the average of the maximum² predicted for these states. The two rightmost plots in figure 2 show that average predicted increases much more smoothly than the average total reward obtained by the agent and plotting the same metrics on the other five games produces similarly smooth curves. In addition to seeing relatively smooth improvement to predicted during training we did not experience any divergence issues in any of our experiments. This suggests that, despite lacking any theoretical convergence guarantees, our method is able to train large neural networks using a reinforcement learning signal and stochastic gradient descent in a stable manner.
在监督学习中,只要在训练集和验证集上评估模型,就能方便地跟踪训练期间的模型性能。而在强化学习中,准确评估智能体在训练中的进展可能很困难。按照 [3] 的建议,我们的评估指标是智能体在一个回合或一局游戏中获得的总奖励在若干局游戏上的平均值,我们在训练期间定期计算这一指标。平均总奖励指标往往噪声很大,因为策略权重的微小变化可能导致策略访问的状态分布发生很大变化。图 2 最左边的两幅图展示了在 Seaquest 和 Breakout 上训练时平均总奖励的变化。两幅平均奖励曲线确实噪声很大,给人一种学习算法没有稳步进展的印象。另一个更稳定的指标是策略的估计动作价值函数 ,它估计智能体从任一给定状态出发、遵循其策略所能获得的折扣奖励。我们在训练开始前运行一个随机策略,收集一组固定的状态,并跟踪这些状态上最大²预测 的平均值。图 2 最右边的两幅图显示,平均预测 的增长比智能体获得的平均总奖励平滑得多;在其他五款游戏上画出同样的指标,也得到类似的平滑曲线。除了看到预测 在训练中相对平滑地提升,我们在所有实验中都没有遇到任何发散问题。这表明,尽管没有任何理论上的收敛保证,我们的方法能够用强化学习信号和随机梯度下降稳定地训练大型神经网络。
² The maximum for each state is taken over the possible actions.
² 每个状态上的最大值是在所有可能动作上取的。
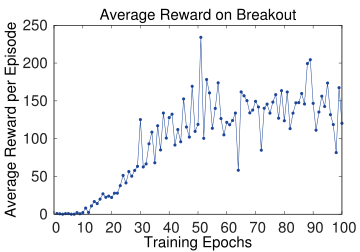
Figure 2: The two plots on the left show average reward per episode on Breakout and Seaquest respectively during training. The statistics were computed by running an -greedy policy with for 10000 steps. The two plots on the right show the average maximum predicted action-value of a held out set of states on Breakout and Seaquest respectively. One epoch corresponds to 50000 minibatch weight updates or roughly 30 minutes of training time.
图 2:左边两幅图分别是 Breakout 和 Seaquest 训练期间每回合的平均奖励。这些统计量通过运行 的 贪心策略 10000 步算得。右边两幅图分别是 Breakout 和 Seaquest 上一组留出状态的平均最大预测动作价值。一个轮次(epoch)对应 50000 次小批量权重更新,约合 30 分钟的训练时间。
5.2 Visualizing the Value Function
5.2 价值函数的可视化
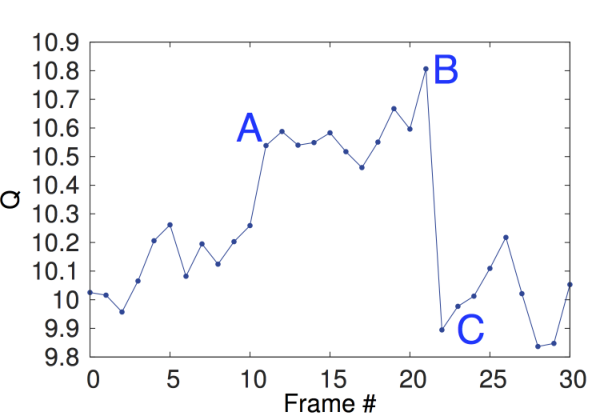
Figure 3 shows a visualization of the learned value function on the game Seaquest. The figure shows that the predicted value jumps after an enemy appears on the left of the screen (point A). The agent then fires a torpedo at the enemy and the predicted value peaks as the torpedo is about to hit the enemy (point B). Finally, the value falls to roughly its original value after the enemy disappears (point C). Figure 3 demonstrates that our method is able to learn how the value function evolves for a reasonably complex sequence of events.
图 3 展示了 Seaquest 游戏中学到的价值函数。图中显示,敌人出现在屏幕左侧之后(A 点),预测价值跳升。随后智能体向敌人发射鱼雷,鱼雷即将击中敌人时预测价值达到峰值(B 点)。最后,敌人消失后,价值大致回落到原来的水平(C 点)。图 3 表明,我们的方法能够学到价值函数如何随一连串相当复杂的事件而变化。
Figure 3: The leftmost plot shows the predicted value function for a 30 frame segment of the game Seaquest. The three screenshots correspond to the frames labeled by A, B, and C respectively.
图 3:最左边的图是 Seaquest 游戏中一段 30 帧片段的预测价值函数。三张截图分别对应标为 A、B、C 的帧。
5.3 Main Evaluation
5.3 主要评估
We compare our results with the best performing methods from the RL literature [3, 4]. The method labeled Sarsa used the Sarsa algorithm to learn linear policies on several different feature sets hand-engineered for the Atari task and we report the score for the best performing feature set [3]. Contingency used the same basic approach as Sarsa but augmented the feature sets with a learned representation of the parts of the screen that are under the agent’s control [4]. Note that both of these methods incorporate significant prior knowledge about the visual problem by using background subtraction and treating each of the 128 colors as a separate channel. Since many of the Atari games use one distinct color for each type of object, treating each color as a separate channel can be similar to producing a separate binary map encoding the presence of each object type. In contrast, our agents only receive the raw RGB screenshots as input and must learn to detect objects on their own.
我们把结果与 RL 文献中表现最好的方法 [3, 4] 进行比较。标为 Sarsa 的方法用 Sarsa 算法,在几组为 Atari 任务人工设计的特征集上学习线性策略,我们报告其中表现最好的特征集的得分 [3]。Contingency 使用与 Sarsa 相同的基本方法,但在特征集中加入了一种学到的表示,用于刻画屏幕上受智能体控制的部分 [4]。注意,这两种方法都通过背景减除、把 128 种颜色各自当作单独通道,引入了大量关于视觉问题的先验知识。由于许多 Atari 游戏对每类物体使用一种不同的颜色,把每种颜色当作单独通道,就类似于为每类物体生成一张单独的二值图来编码它是否存在。相比之下,我们的智能体只接收原始 RGB 截图作为输入,必须自己学会检测物体。
In addition to the learned agents, we also report scores for an expert human game player and a policy that selects actions uniformly at random. The human performance is the median reward achieved after around two hours of playing each game. Note that our reported human scores are much higher than the ones in Bellemare et al. [3]. For the learned methods, we follow the evaluation strategy used in Bellemare et al. [3, 5] and report the average score obtained by running an -greedy policy with for a fixed number of steps. The first five rows of table 1 show the per-game average scores on all games. Our approach (labeled DQN) outperforms the other learning methods by a substantial margin on all seven games despite incorporating almost no prior knowledge about the inputs.
除了学习型智能体,我们还报告了人类专家玩家和均匀随机选择动作的策略的得分。人类表现是每款游戏玩了约两小时后所得奖励的中位数。注意,我们报告的人类得分比 Bellemare 等人 [3] 的高得多。对于学习型方法,我们遵循 Bellemare 等人 [3, 5] 的评估方式,报告运行 的 贪心策略固定步数所得的平均分。表 1 前五行给出了所有游戏上的逐游戏平均得分。我们的方法(标为 DQN)几乎没有引入关于输入的先验知识,却在全部七款游戏上大幅超过其他学习方法。
| B. Rider | Breakout | Enduro | Pong | Q*bert | Seaquest | S. Invaders | |
|---|---|---|---|---|---|---|---|
| Random | |||||||
| Sarsa [3] | |||||||
| Contingency [4] | |||||||
| DQN | 4092 | 168 | 470 | 20 | 1952 | 1705 | 581 |
| Human | |||||||
| HNeat Best [8] | 1720 | ||||||
| HNeat Pixel [8] | |||||||
| DQN Best | 5184 | 225 | 661 | 21 | 4500 | 1740 |
Table 1: The upper table compares average total reward for various learning methods by running an -greedy policy with for a fixed number of steps. The lower table reports results of the single best performing episode for HNeat and DQN. HNeat produces deterministic policies that always get the same score while DQN used an -greedy policy with .
| B. Rider | Breakout | Enduro | Pong | Q*bert | Seaquest | S. Invaders | |
|---|---|---|---|---|---|---|---|
| 随机 | |||||||
| Sarsa [3] | |||||||
| Contingency [4] | |||||||
| DQN | 4092 | 168 | 470 | 20 | 1952 | 1705 | 581 |
| 人类 | |||||||
| HNeat Best [8] | 1720 | ||||||
| HNeat Pixel [8] | |||||||
| DQN Best | 5184 | 225 | 661 | 21 | 4500 | 1740 |
表 1:上半部分比较各学习方法运行 的 贪心策略固定步数所得的平均总奖励。下半部分报告 HNeat 和 DQN 表现最好的单个回合的结果。HNeat 产生的是确定性策略,每次得分都相同;DQN 使用的是 的 贪心策略。
We also include a comparison to the evolutionary policy search approach from [8] in the last three rows of table 1. We report two sets of results for this method. The HNeat Best score reflects the results obtained by using a hand-engineered object detector algorithm that outputs the locations and types of objects on the Atari screen. The HNeat Pixel score is obtained by using the special 8 color channel representation of the Atari emulator that represents an object label map at each channel. This method relies heavily on finding a deterministic sequence of states that represents a successful exploit. It is unlikely that strategies learnt in this way will generalize to random perturbations; therefore the algorithm was only evaluated on the highest scoring single episode. In contrast, our algorithm is evaluated on -greedy control sequences, and must therefore generalize across a wide variety of possible situations. Nevertheless, we show that on all the games, except Space Invaders, not only our max evaluation results (row ), but also our average results (row ) achieve better performance.
我们还在表 1 最后三行与 [8] 中的演化策略搜索方法做了比较。我们报告了该方法的两组结果。HNeat Best 得分是使用一个人工设计的物体检测算法得到的结果,该算法输出 Atari 屏幕上物体的位置和类型。HNeat Pixel 得分是使用 Atari 模拟器特殊的 8 色通道表示得到的,每个通道表示一张物体标签图。这种方法高度依赖于找到一个代表成功“漏洞利用”的确定性状态序列。这样学到的策略不太可能泛化到随机扰动,因此该算法只在得分最高的单个回合上评估。相比之下,我们的算法是在 贪心控制序列上评估的,因此必须在各种可能的情况下泛化。尽管如此,我们表明,在除 Space Invaders 以外的所有游戏上,不仅我们的最大值评估结果(第 行),连平均结果(第 行)也取得了更好的成绩。
Finally, we show that our method achieves better performance than an expert human player on Breakout, Enduro and Pong and it achieves close to human performance on Beam Rider. The games Q*bert, Seaquest, Space Invaders, on which we are far from human performance, are more challenging because they require the network to find a strategy that extends over long time scales.
最后,我们表明,我们的方法在 Breakout、Enduro 和 Pong 上超过了人类专家玩家,在 Beam Rider 上接近人类水平。Q*bert、Seaquest 和 Space Invaders 这几款游戏上我们离人类水平还很远,它们更具挑战性,因为需要网络找到一个跨越很长时间尺度的策略。
6 Conclusion
6 结论
This paper introduced a new deep learning model for reinforcement learning, and demonstrated its ability to master difficult control policies for Atari 2600 computer games, using only raw pixels as input. We also presented a variant of online Q-learning that combines stochastic minibatch updates with experience replay memory to ease the training of deep networks for RL. Our approach gave state-of-the-art results in six of the seven games it was tested on, with no adjustment of the architecture or hyperparameters.
本文为强化学习提出了一个新的深度学习模型,并展示了它只用原始像素作为输入,就能掌握 Atari 2600 电子游戏中困难的控制策略。我们还提出了在线 Q 学习的一个变体,把随机小批量更新与经验回放记忆结合起来,让深度网络更容易用于 RL 训练。在没有调整架构或超参数的情况下,我们的方法在测试的七款游戏中有六款取得了最先进的结果。
References
参考文献
[1] Leemon Baird. Residual algorithms: Reinforcement learning with function approximation. In Proceedings of the 12th International Conference on Machine Learning (ICML 1995), pages 30–37. Morgan Kaufmann, 1995.
[2] Marc Bellemare, Joel Veness, and Michael Bowling. Sketch-based linear value function approximation. In Advances in Neural Information Processing Systems 25, pages 2222–2230, 2012.
[3] Marc G Bellemare, Yavar Naddaf, Joel Veness, and Michael Bowling. The arcade learning environment: An evaluation platform for general agents. Journal of Artificial Intelligence Research, 47:253–279, 2013.
[4] Marc G Bellemare, Joel Veness, and Michael Bowling. Investigating contingency awareness using atari 2600 games. In AAAI, 2012.
[5] Marc G. Bellemare, Joel Veness, and Michael Bowling. Bayesian learning of recursively factored environments. In Proceedings of the Thirtieth International Conference on Machine Learning (ICML 2013), pages 1211–1219, 2013.
[6] George E. Dahl, Dong Yu, Li Deng, and Alex Acero. Context-dependent pre-trained deep neural networks for large-vocabulary speech recognition. Audio, Speech, and Language Processing, IEEE Transactions on, 20(1):30 –42, January 2012.
[7] Alex Graves, Abdel-rahman Mohamed, and Geoffrey E. Hinton. Speech recognition with deep recurrent neural networks. In Proc. ICASSP, 2013.
[8] Matthew Hausknecht, Risto Miikkulainen, and Peter Stone. A neuro-evolution approach to general atari game playing. 2013.
[9] Nicolas Heess, David Silver, and Yee Whye Teh. Actor-critic reinforcement learning with energy-based policies. In European Workshop on Reinforcement Learning, page 43, 2012.
[10] Kevin Jarrett, Koray Kavukcuoglu, Marc’Aurelio Ranzato, and Yann LeCun. What is the best multi-stage architecture for object recognition? In Proc. International Conference on Computer Vision and Pattern Recognition (CVPR 2009), pages 2146–2153. IEEE, 2009.
[11] Alex Krizhevsky, Ilya Sutskever, and Geoff Hinton. Imagenet classification with deep convolutional neural networks. In Advances in Neural Information Processing Systems 25, pages 1106–1114, 2012.
[12] Sascha Lange and Martin Riedmiller. Deep auto-encoder neural networks in reinforcement learning. In Neural Networks (IJCNN), The 2010 International Joint Conference on, pages 1–8. IEEE, 2010.
[13] Long-Ji Lin. Reinforcement learning for robots using neural networks. Technical report, DTIC Document, 1993.
[14] Hamid Maei, Csaba Szepesvari, Shalabh Bhatnagar, Doina Precup, David Silver, and Rich Sutton. Convergent Temporal-Difference Learning with Arbitrary Smooth Function Approximation. In Advances in Neural Information Processing Systems 22, pages 1204–1212, 2009.
[15] Hamid Maei, Csaba Szepesvári, Shalabh Bhatnagar, and Richard S. Sutton. Toward off-policy learning control with function approximation. In Proceedings of the 27th International Conference on Machine Learning (ICML 2010), pages 719–726, 2010.
[16] Volodymyr Mnih. Machine Learning for Aerial Image Labeling. PhD thesis, University of Toronto, 2013.
[17] Andrew Moore and Chris Atkeson. Prioritized sweeping: Reinforcement learning with less data and less real time. Machine Learning, 13:103–130, 1993.
[18] Vinod Nair and Geoffrey E Hinton. Rectified linear units improve restricted boltzmann machines. In Proceedings of the 27th International Conference on Machine Learning (ICML 2010), pages 807–814, 2010.
[19] Jordan B. Pollack and Alan D. Blair. Why did td-gammon work. In Advances in Neural Information Processing Systems 9, pages 10–16, 1996.
[20] Martin Riedmiller. Neural fitted q iteration–first experiences with a data efficient neural reinforcement learning method. In Machine Learning: ECML 2005, pages 317–328. Springer, 2005.
[21] Brian Sallans and Geoffrey E. Hinton. Reinforcement learning with factored states and actions. Journal of Machine Learning Research, 5:1063–1088, 2004.
[22] Pierre Sermanet, Koray Kavukcuoglu, Soumith Chintala, and Yann LeCun. Pedestrian detection with unsupervised multi-stage feature learning. In Proc. International Conference on Computer Vision and Pattern Recognition (CVPR 2013). IEEE, 2013.
[23] Richard Sutton and Andrew Barto. Reinforcement Learning: An Introduction. MIT Press, 1998.
[24] Gerald Tesauro. Temporal difference learning and td-gammon. Communications of the ACM, 38(3):58–68, 1995.
[25] John N Tsitsiklis and Benjamin Van Roy. An analysis of temporal-difference learning with function approximation. Automatic Control, IEEE Transactions on, 42(5):674–690, 1997.
[26] Christopher JCH Watkins and Peter Dayan. Q-learning. Machine learning, 8(3-4):279–292, 1992.