Pixel Recurrent Neural Networks
Pixel Recurrent Neural Networks
Aäron van den Oord AVDNOORD@GOOGLE.COM
Nal Kalchbrenner NALK@GOOGLE.COM
Koray Kavukcuoglu KORAYK@GOOGLE.COM
Google DeepMind
Proceedings of the 33^{rd} International Conference on Machine Learning, New York, NY, USA, 2016. JMLR: W&CP volume 48. Copyright 2016 by the author(s).
Abstract
Modeling the distribution of natural images is a landmark problem in unsupervised learning. This task requires an image model that is at once expressive, tractable and scalable. We present a deep neural network that sequentially predicts the pixels in an image along the two spatial dimensions. Our method models the discrete probability of the raw pixel values and encodes the complete set of dependencies in the image. Architectural novelties include fast two-dimensional recurrent layers and an effective use of residual connections in deep recurrent networks. We achieve log-likelihood scores on natural images that are considerably better than the previous state of the art. Our main results also provide benchmarks on the diverse ImageNet dataset. Samples generated from the model appear crisp, varied and globally coherent.
对自然图像的分布建模,是无监督学习里的一个标志性问题。这项任务要求图像模型同时具备表达力、可计算性和可扩展性。我们提出一种深度神经网络,沿两个空间方向依次预测图像中的像素。该方法对原始像素值的离散概率建模,并编码图像中的全部依赖关系。结构上的新意包括快速的二维循环层,以及在深层循环网络中有效使用残差连接。我们在自然图像上得到的对数似然,明显优于此前的最好结果。主要结果还在多样的 ImageNet 数据集上提供了基准。由模型生成的样本显得清晰、多样,并且在整体上连贯。
1. Introduction
Generative image modeling is a central problem in unsupervised learning. Probabilistic density models can be used for a wide variety of tasks that range from image compression and forms of reconstruction such as image inpainting (e.g., see Figure 1) and deblurring, to generation of new images. When the model is conditioned on external information, possible applications also include creating images based on text descriptions or simulating future frames in a planning task. One of the great advantages in generative modeling is that there are practically endless amounts of image data available to learn from. However, because images are high dimensional and highly structured, estimating the distribution of natural images is extremely challenging.
生成式图像建模是无监督学习的一个核心问题。概率密度模型可用于许多任务,从图像压缩和图像补全(例如见图 1)、去模糊一类重建,到生成新的图像。若模型再以外部信息为条件,应用还可以包括根据文本描述生成图像,或在规划任务中模拟未来帧。生成式建模的一大优点是,几乎有无穷尽的图像数据可供学习。不过,图像维度高、结构性强,估计自然图像的分布极其困难。
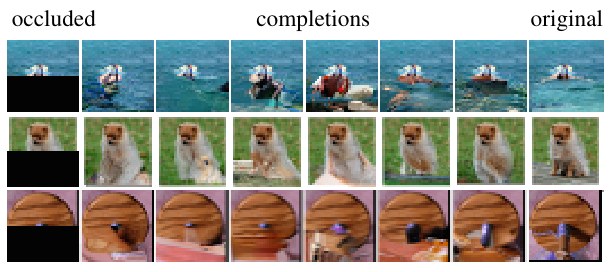
Figure 1. Image completions sampled from a PixelRNN.
图 1. 从 PixelRNN 中采样得到的图像补全结果。
One of the most important obstacles in generative modeling is building complex and expressive models that are also tractable and scalable. This trade-off has resulted in a large variety of generative models, each having their advantages. Most work focuses on stochastic latent variable models such as VAE's (Rezende et al., 2014; Kingma & Welling, 2013) that aim to extract meaningful representations, but often come with an intractable inference step that can hinder their performance.
生成式建模最重要的障碍之一,是既要做出复杂、有表达力的模型,又要保证可计算、可扩展。这一权衡带来了种类繁多的生成模型,各有优点。大多数工作关注随机潜变量模型,例如 VAE(Rezende et al., 2014; Kingma & Welling, 2013),目标是提取有意义的表示,但往往伴随着不可精确计算的推断步骤,可能妨碍最终表现。
One effective approach to tractably model a joint distribution of the pixels in the image is to cast it as a product of conditional distributions; this approach has been adopted in autoregressive models such as NADE (Larochelle & Murray, 2011) and fully visible sigmoid belief networks (Neal, 1992). The factorization turns the joint modeling problem into a sequence problem, where one learns to predict the next pixel given all the previously generated pixels. But to model the highly nonlinear and long-range correlations between pixels and the complex conditional distributions that result, a highly expressive sequence model is necessary.
要可计算地建模图像像素的联合分布,一条有效的路是把它写成条件分布的乘积;自回归模型如 NADE(Larochelle & Murray, 2011)以及完全可见的 sigmoid 信念网络(Neal, 1992)就采用了这种方法。这样的分解把联合建模变成了序列问题:在已经生成的全部像素条件下,学习预测下一个像素。但要刻画像素之间高度非线性且跨度很大的相关,以及由此产生的复杂条件分布,就需要一个表达力很强的序列模型。
Recurrent Neural Networks (RNN) are powerful models that offer a compact, shared parametrization of a series of conditional distributions. RNNs have been shown to excel at hard sequence problems ranging from handwriting generation (Graves, 2013), to character prediction (Sutskever et al., 2011) and to machine translation (Kalchbrenner & Blunsom, 2013). A two-dimensional RNN has produced very promising results in modeling grayscale images and textures (Theis & Bethge, 2015).
循环神经网络(RNN)是一类强大的模型,能用紧凑、共享的参数化来表示一串条件分布。RNN 已在许多困难的序列问题上表现突出,从手写生成(Graves, 2013)、字符预测(Sutskever et al., 2011)到机器翻译(Kalchbrenner & Blunsom, 2013)。二维 RNN 在灰度图像和纹理建模上也取得了很有希望的结果(Theis & Bethge, 2015)。
In this paper we advance two-dimensional RNNs and apply them to large-scale modeling of natural images. The resulting PixelRNNs are composed of up to twelve, fast two-dimensional Long Short-Term Memory (LSTM) layers. These layers use LSTM units in their state (Hochreiter & Schmidhuber, 1997; Graves & Schmidhuber, 2009) and adopt a convolution to compute at once all the states along one of the spatial dimensions of the data. We design two types of these layers. The first type is the Row LSTM layer where the convolution is applied along each row; a similar technique is described in (Stollenga et al., 2015). The second type is the Diagonal BiLSTM layer where the convolution is applied in a novel fashion along the diagonals of the image. The networks also incorporate residual connections (He et al., 2015) around LSTM layers; we observe that this helps with training of the PixelRNN for up to twelve layers of depth.
本文推进二维 RNN,并把它们用于大规模的自然图像建模。得到的 PixelRNN 最多由十二个快速的二维长短期记忆(LSTM)层组成。这些层在状态中使用 LSTM 单元(Hochreiter & Schmidhuber, 1997; Graves & Schmidhuber, 2009),并采用卷积,沿数据的一个空间方向一次性计算全部状态。我们设计了两类这样的层。第一类是 Row LSTM 层,卷积沿每一行进行;类似做法见(Stollenga et al., 2015)。第二类是 Diagonal BiLSTM 层,卷积以一种新的方式沿图像的对角线进行。网络还在 LSTM 层周围加入残差连接(He et al., 2015);我们观察到,这有助于把 PixelRNN 训到十二层深。
We also consider a second, simplified architecture which shares the same core components as the PixelRNN. We observe that Convolutional Neural Networks (CNN) can also be used as sequence model with a fixed dependency range, by using Masked convolutions. The PixelCNN architecture is a fully convolutional network of fifteen layers that preserves the spatial resolution of its input throughout the layers and outputs a conditional distribution at each location.
我们还考虑了第二种简化结构,它与 PixelRNN 共用核心组件。我们观察到,通过使用掩码卷积,卷积神经网络(CNN)也可以作为依赖范围固定的序列模型。PixelCNN 是一个十五层的全卷积网络,各层都保持输入的空间分辨率,并在每个位置输出一个条件分布。
Both PixelRNN and PixelCNN capture the full generality of pixel inter-dependencies without introducing independence assumptions as in e.g., latent variable models. The dependencies are also maintained between the RGB color values within each individual pixel. Furthermore, in contrast to previous approaches that model the pixels as continuous values (e.g., Theis & Bethge (2015); Gregor et al. (2014)), we model the pixels as discrete values using a multinomial distribution implemented with a simple softmax layer. We observe that this approach gives both representational and training advantages for our models.
PixelRNN 和 PixelCNN 都能刻画像素相互依赖的全部一般性,而不像潜变量模型那样引入独立性假设。每个像素内部的 RGB 颜色值之间的依赖同样被保留。此外,与此前把像素当成连续值来建模的做法不同(例如 Theis & Bethge (2015); Gregor et al. (2014)),我们把像素当成离散值,用一层简单的 softmax 实现多项分布。我们观察到,这种方法在表示和训练上都对我们的模型有利。
The contributions of the paper are as follows. In Section 3 we design two types of PixelRNNs corresponding to the two types of LSTM layers; we describe the purely convolutional PixelCNN that is our fastest architecture; and we design a Multi-Scale version of the PixelRNN. In Section 5 we show the relative benefits of using the discrete softmax distribution in our models and of adopting residual connections for the LSTM layers. Next we test the models on MNIST and on CIFAR-10 and show that they obtain log-likelihood scores that are considerably better than previous results. We also provide results for the large-scale ImageNet dataset resized to both and pixels; to our knowledge likelihood values from generative models have not previously been reported on this dataset. Finally, we give a qualitative evaluation of the samples generated from the PixelRNNs.
本文的贡献如下。在第 3 节,我们针对两类 LSTM 层设计了两种 PixelRNN;描述了作为最快结构的纯卷积 PixelCNN;并设计了 PixelRNN 的多尺度版本。在第 5 节,我们展示了在模型中使用离散 softmax 分布,以及在 LSTM 层中采用残差连接的相对好处。随后我们在 MNIST 和 CIFAR-10 上测试这些模型,表明它们得到的对数似然明显优于已有结果。我们还给出了把大规模 ImageNet 数据集缩放到 和 像素后的结果;据我们所知,此前还没有在该数据集上报告过生成模型的似然值。最后,我们对 PixelRNN 生成的样本做了定性评价。
2. Model
Our aim is to estimate a distribution over natural images that can be used to tractably compute the likelihood of images and to generate new ones. The network scans the image one row at a time and one pixel at a time within each row. For each pixel it predicts the conditional distribution over the possible pixel values given the scanned context. Figure 2 illustrates this process. The joint distribution over the image pixels is factorized into a product of conditional distributions. The parameters used in the predictions are shared across all pixel positions in the image.
我们的目标是估计自然图像上的一个分布,从而可以计算图像的似然,并生成新的图像。网络一次扫描一行,并在每一行内一次处理一个像素。对每个像素,它在已扫描上下文的条件下,预测可能像素值的条件分布。图 2 展示了这一过程。图像像素上的联合分布被分解成条件分布的乘积。预测所用的参数在图像的所有像素位置上共享。
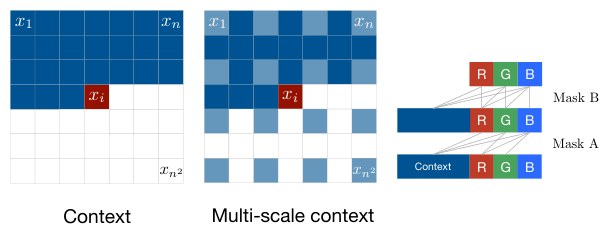
Figure 2. Left: To generate pixel one conditions on all the previously generated pixels left and above of . Center: To generate a pixel in the multi-scale case we can also condition on the subsampled image pixels (in light blue). Right: Diagram of the connectivity inside a masked convolution. In the first layer, each of the RGB channels is connected to previous channels and to the context, but is not connected to itself. In subsequent layers, the channels are also connected to themselves.
图 2. 左:生成像素 时,以 左方和上方所有已经生成的像素为条件。中:在多尺度情形下生成一个像素时,还可以以下采样图像中的像素为条件(浅蓝色)。右:掩码卷积内部连接的示意图。在第一层,每个 RGB 通道连接到先前的通道以及上下文,但不连接到自身。在后续层中,通道也可以连接到自身。
To capture the generation process, Theis & Bethge (2015) propose to use a two-dimensional LSTM network (Graves & Schmidhuber, 2009) that starts at the top left pixel and proceeds towards the bottom right pixel. The advantage of the LSTM network is that it effectively handles long-range dependencies that are central to object and scene understanding. The two-dimensional structure ensures that the signals are well propagated both in the left-to-right and top-to-bottom directions.
为了刻画生成过程,Theis & Bethge (2015) 提出使用二维 LSTM 网络(Graves & Schmidhuber, 2009),从左上角像素出发,推进到右下角像素。LSTM 网络的优点是能有效处理对物体和场景理解至关重要的长程依赖。二维结构确保信号既能从左到右、也能从上到下很好地传播。
In this section we first focus on the form of the distribution, whereas the next section will be devoted to describing the architectural innovations inside PixelRNN.
本节我们首先关注分布的形式,下一节再专门描述 PixelRNN 内部的结构创新。
2.1. Generating an Image Pixel by Pixel
The goal is to assign a probability to each image formed of pixels. We can write the image as a one-dimensional sequence where pixels are taken from the image row by row. To estimate the joint distribution we write it as the product of the conditional distributions over the pixels:
目标是给由 个像素组成的每张图像 赋一个概率 。我们可以把图像 写成一维序列 ,其中像素按行从图像中取出。为了估计联合分布 ,我们把它写成各像素条件分布的乘积:
The value is the probability of the -th pixel given all the previous pixels . The generation proceeds row by row and pixel by pixel. Figure 2 (Left) illustrates the conditioning scheme.
值 是在所有先前像素 给定时,第 个像素 的概率。生成按行进行,并在一行之内逐个像素进行。图 2(左)展示了这一条件化方案。
Each pixel is in turn jointly determined by three values, one for each of the color channels Red, Green and Blue (RGB). We rewrite the distribution as the following product:
每个像素 又由三个值共同决定,分别对应红、绿、蓝(RGB)三个颜色通道。我们把分布 改写成如下乘积:
Each of the colors is thus conditioned on the other channels as well as on all the previously generated pixels.
这样,每一种颜色都以其他通道以及所有已经生成的像素为条件。
Note that during training and evaluation the distributions over the pixel values are computed in parallel, while the generation of an image is sequential.
需要注意的是,在训练和评估时,像素值上的分布是并行计算的,而生成一张图像则是顺序进行的。
2.2. Pixels as Discrete Variables
Previous approaches use a continuous distribution for the values of the pixels in the image (e.g. Theis & Bethge (2015); Uria et al. (2014)). By contrast we model as a discrete distribution, with every conditional distribution in Equation 2 being a multinomial that is modeled with a softmax layer. Each channel variable simply takes one of 256 distinct values. The discrete distribution is representationally simple and has the advantage of being arbitrarily multimodal without prior on the shape (see Fig. 6). Experimentally we also find the discrete distribution to be easy to learn and to produce better performance compared to a continuous distribution (Section 5).
此前的方法对图像中的像素值使用连续分布(例如 Theis & Bethge (2015); Uria et al. (2014))。与此相对,我们把 建成离散分布,方程 2 中的每个条件分布都是用 softmax 层建模的多项分布。每个通道变量 只取 256 个不同值中的一个。离散分布在表示上简单,其优点是不必对形状施加先验,就可以任意多峰(见图 6)。实验上我们还发现,离散分布容易学习,并且与连续分布相比能得到更好的表现(第 5 节)。
3. Pixel Recurrent Neural Networks
In this section we describe the architectural components that compose the PixelRNN. In Sections 3.1 and 3.2, we describe the two types of LSTM layers that use convolutions to compute at once the states along one of the spatial dimensions. In Section 3.3 we describe how to incorporate residual connections to improve the training of a PixelRNN with many LSTM layers. In Section 3.4 we describe the softmax layer that computes the discrete joint distribution of the colors and the masking technique that ensures the proper conditioning scheme. In Section 3.5 we describe the PixelCNN architecture. Finally in Section 3.6 we describe the multi-scale architecture.
本节我们描述组成 PixelRNN 的结构组件。在第 3.1 和 3.2 节,我们描述两类 LSTM 层,它们用卷积沿一个空间方向一次性计算状态。在第 3.3 节,我们描述如何加入残差连接,以改善带有许多 LSTM 层的 PixelRNN 的训练。在第 3.4 节,我们描述计算颜色离散联合分布的 softmax 层,以及确保正确条件化方案的掩码技术。在第 3.5 节,我们描述 PixelCNN 结构。最后在第 3.6 节,我们描述多尺度结构。
3.1. Row LSTM
The Row LSTM is a unidirectional layer that processes the image row by row from top to bottom computing features for a whole row at once; the computation is performed with a one-dimensional convolution. For a pixel the layer captures a roughly triangular context above the pixel as shown in Figure 4 (center). The kernel of the one-dimensional convolution has size where ; the larger the value of the broader the context that is captured. The weight sharing in the convolution ensures translation invariance of the computed features along each row.
Row LSTM 是一种单向层,从上到下逐行处理图像,并一次性计算整行的特征;计算用一维卷积完成。对像素 ,该层捕捉到像素上方大致呈三角形的上下文,如图 4(中)所示。一维卷积核的大小为 ,其中 ; 越大,捕捉到的上下文越宽。卷积中的权值共享保证了所计算特征沿每一行的平移不变性。
The computation proceeds as follows. An LSTM layer has an input-to-state component and a recurrent state-to-state component that together determine the four gates inside the LSTM core. To enhance parallelization in the Row LSTM the input-to-state component is first computed for the entire two-dimensional input map; for this a convolution is used to follow the row-wise orientation of the LSTM itself. The convolution is masked to include only the valid context (see Section 3.4) and produces a tensor of size , representing the four gate vectors for each position in the input map, where is the number of output feature maps.
计算过程如下。一个 LSTM 层有一个输入到状态的分量和一个循环的状态到状态分量,二者共同决定 LSTM 核心里的四个门。为了增强 Row LSTM 中的并行,输入到状态的分量先对整个二维输入特征图计算;为此使用 卷积,以与 LSTM 本身的按行方向一致。卷积经过掩码,只包含合法上下文(见第 3.4 节),并产生大小为 的张量,表示输入图每个位置上的四个门向量,其中 是输出特征图的数量。
To compute one step of the state-to-state component of the LSTM layer, one is given the previous hidden and cell states and , each of size . The new hidden and cell states , are obtained as follows:
要计算 LSTM 层状态到状态分量的一步,给定先前的隐状态和细胞状态 与 ,每个大小为 。新的隐状态和细胞状态 、 按如下方式得到:
$$\begin{aligned}
[\mathbf{o}_i, \mathbf{f}_i, \mathbf{i}_i, \mathbf{g}i] &= \sigma(\mathbf{K}^{ss} \circledast \mathbf{h}{i-1} + \mathbf{K}^{is} \circledast \mathbf{x}_i) \
\mathbf{c}_i &= \mathbf{f}i \odot \mathbf{c}{i-1} + \mathbf{i}_i \odot \mathbf{g}_i \
\mathbf{h}_i &= \mathbf{o}_i \odot \tanh(\mathbf{c}_i)
\end{aligned} \tag{3}$$
where of size is row of the input map, and represents the convolution operation and the element-wise multiplication. The weights and are the kernel weights for the state-to-state and the input-to-state components, where the latter is precomputed as described above. In the case of the output, forget and input gates , and , the activation is the logistic sigmoid function, whereas for the content gate , is the function. Each step computes at once the new state for an entire row of the input map. Because the Row LSTM has a triangular receptive field (Figure 4), it is unable to capture the entire available context.
其中大小为 的 是输入图的第 行, 表示卷积运算, 表示逐元素乘法。权值 和 分别是状态到状态和输入到状态分量的卷积核权值,后者按上文所述预先计算。对输出门、遗忘门和输入门 、 和 ,激活 是 logistic sigmoid 函数;对内容门 , 则是 函数。每一步一次性计算输入图整行的新状态。由于 Row LSTM 具有三角形感受野(图 4),它无法捕捉全部可用上下文。
3.2. Diagonal BiLSTM
The Diagonal BiLSTM is designed to both parallelize the computation and to capture the entire available context for any image size. Each of the two directions of the layer scans the image in a diagonal fashion starting from a corner at the top and reaching the opposite corner at the bottom. Each step in the computation computes at once the LSTM state along a diagonal in the image. Figure 4 (right) illustrates the computation and the resulting receptive field.
Diagonal BiLSTM 的设计既是为了并行计算,也是为了在任意图像尺寸下捕捉全部可用上下文。该层的两个方向都以对角方式扫描图像,从上方的一个角出发,到达下方的对角。计算中的每一步一次性计算图像一条对角线上的 LSTM 状态。图 4(右)展示了这一计算以及由此得到的感受野。
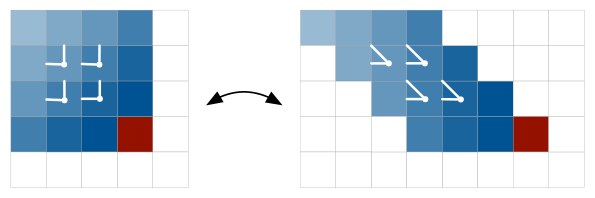
Figure 3. In the Diagonal BiLSTM, to allow for parallelization along the diagonals, the input map is skewed by offseting each row by one position with respect to the previous row. When the spatial layer is computed left to right and column by column, the output map is shifted back into the original size. The convolution uses a kernel of size .
图 3. 在 Diagonal BiLSTM 中,为了沿对角线并行,输入图通过把每一行相对于上一行偏移一个位置而被倾斜。当空间层从左到右、按列计算时,输出图再被移回原来的大小。卷积使用大小为 的核。
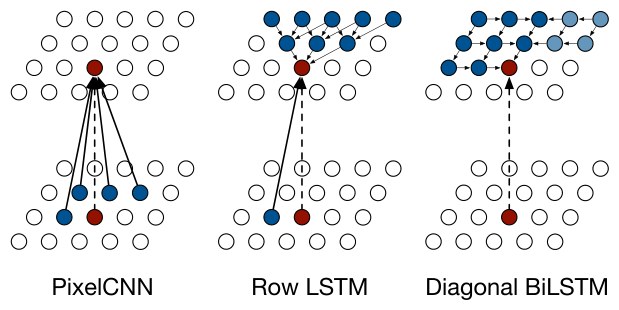
Figure 4. Visualization of the input-to-state and state-to-state mappings for the three proposed architectures.
图 4. 所提出的三种结构中,输入到状态和状态到状态映射的可视化。
The diagonal computation proceeds as follows. We first skew the input map into a space that makes it easy to apply convolutions along diagonals. The skewing operation offsets each row of the input map by one position with respect to the previous row, as illustrated in Figure 3; this results in a map of size . At this point we can compute the input-to-state and state-to-state components of the Diagonal BiLSTM. For each of the two directions, the input-to-state component is simply a convolution that contributes to the four gates in the LSTM core; the operation generates a tensor. The state-to-state recurrent component is then computed with a column-wise convolution that has a kernel of size . The step takes the previous hidden and cell states, combines the contribution of the input-to-state component and produces the next hidden and cell states, as defined in Equation 3. The output feature map is then skewed back into an map by removing the offset positions. This computation is repeated for each of the two directions. Given the two output maps, to prevent the layer from seeing future pixels, the right output map is then shifted down by one row and added to the left output map.
对角计算过程如下。我们首先把输入图倾斜到一个便于沿对角线做卷积的空间。倾斜操作把输入图的每一行相对于上一行偏移一个位置,如图 3 所示;这得到大小为 的特征图。此时就可以计算 Diagonal BiLSTM 的输入到状态和状态到状态分量。对两个方向中的每一个,输入到状态分量只是一个为 LSTM 核心中四个门做贡献的 卷积 ;该运算产生一个 张量。状态到状态的循环分量随后用核大小为 的按列卷积 计算。这一步取先前的隐状态和细胞状态,结合输入到状态分量的贡献,并按方程 3 产生下一隐状态和细胞状态。输出特征图再通过去掉偏移位置,被倾斜回 的图。这一计算对两个方向各自重复一次。得到两张输出图后,为了防止该层看到未来像素,再把右侧输出图下移一行,加到左侧输出图上。
Besides reaching the full dependency field, the Diagonal BiLSTM has the additional advantage that it uses a convolutional kernel of size that processes a minimal amount of information at each step yielding a highly nonlinear computation. Kernel sizes larger than are not particularly useful as they do not broaden the already global receptive field of the Diagonal BiLSTM.
除了达到完整的依赖范围,Diagonal BiLSTM 还有一个额外优点:它使用大小为 的卷积核,每一步只处理最少量的信息,从而得到高度非线性的计算。比 更大的核并无特别用处,因为它们并不能拓宽 Diagonal BiLSTM 已经全局的感受野。
3.3. Residual Connections
We train PixelRNNs of up to twelve layers of depth. As a means to both increase convergence speed and propagate signals more directly through the network, we deploy residual connections (He et al., 2015) from one LSTM layer to the next. Figure 5 shows a diagram of the residual blocks. The input map to the PixelRNN LSTM layer has features. The input-to-state component reduces the number of features by producing features per gate. After applying the recurrent layer, the output map is upsampled back to features per position via a convolution and the input map is added to the output map. This method is related to previous approaches that use gating along the depth of the recurrent network (Kalchbrenner et al., 2015; Zhang et al., 2016), but has the advantage of not requiring additional gates. Apart from residual connections, one can also use learnable skip connections from each layer to the output. In the experiments we evaluate the relative effectiveness of residual and layer-to-output skip connections.
我们训练深度最多十二层的 PixelRNN。为了既加快收敛,又让信号更直接地在网络中传播,我们在相邻 LSTM 层之间部署残差连接(He et al., 2015)。图 5 给出了残差块的示意图。进入 PixelRNN LSTM 层的输入图有 个特征。输入到状态的分量通过为每个门产生 个特征来减少特征数。在应用循环层之后,输出图经由 卷积上采样回每个位置 个特征,再把输入图加到输出图上。这种方法与先前在循环网络深度方向上使用门控的做法有关(Kalchbrenner et al., 2015; Zhang et al., 2016),但其优点是不需要额外的门。除了残差连接,还可以使用从每一层到输出的可学习 skip 连接。在实验中,我们评估残差连接和层到输出 skip 连接的相对效果。
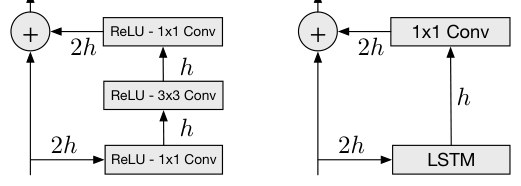
Figure 5. Residual blocks for a PixelCNN (left) and PixelRNNs.
图 5. PixelCNN(左)和 PixelRNN 的残差块。
3.4. Masked Convolution
The features for each input position at every layer in the network are split into three parts, each corresponding to one of the RGB channels. When predicting the R channel for the current pixel , only the generated pixels left and above of can be used as context. When predicting the G channel, the value of the R channel can also be used as context in addition to the previously generated pixels. Likewise, for the B channel, the values of both the R and G channels can be used. To restrict connections in the network to these dependencies, we apply a mask to the input-to-state convolutions and to other purely convolutional layers in a PixelRNN.
网络每一层中,每个输入位置上的 个特征被分成三部分,分别对应 RGB 通道之一。在预测当前像素 的 R 通道时,只能把 左方和上方已经生成的像素当作上下文。在预测 G 通道时,除了先前已生成的像素,还可以把 R 通道的值当作上下文。同样,对 B 通道,R 和 G 两个通道的值都可以使用。为了把网络中的连接限制在这些依赖上,我们向 PixelRNN 中的输入到状态卷积以及其他纯卷积层施加掩码。
We use two types of masks that we indicate with mask A and mask B, as shown in Figure 2 (Right). Mask A is applied only to the first convolutional layer in a PixelRNN and restricts the connections to those neighboring pixels and to those colors in the current pixels that have already been predicted. On the other hand, mask B is applied to all the subsequent input-to-state convolutional transitions and relaxes the restrictions of mask A by also allowing the connection from a color to itself. The masks can be easily implemented by zeroing out the corresponding weights in the input-to-state convolutions after each update. Similar masks have also been used in variational autoencoders (Gregor et al., 2014; Germain et al., 2015).
我们使用两类掩码,分别记为 mask A 和 mask B,如图 2(右)所示。Mask A 只应用于 PixelRNN 的第一个卷积层,并把连接限制到那些已经预测过的邻近像素,以及当前像素中已经预测过的颜色。另一方面,mask B 应用于随后所有的输入到状态卷积转移,并通过允许一种颜色连接到自身,放宽 mask A 的限制。这些掩码可以很容易地实现:在每次更新后,把输入到状态卷积中相应的权值置零。类似的掩码也曾用于变分自编码器(Gregor et al., 2014; Germain et al., 2015)。
3.5. PixelCNN
The Row and Diagonal LSTM layers have a potentially unbounded dependency range within their receptive field. This comes with a computational cost as each state needs to be computed sequentially. One simple workaround is to make the receptive field large, but not unbounded. We can use standard convolutional layers to capture a bounded receptive field and compute features for all pixel positions at once. The PixelCNN uses multiple convolutional layers that preserve the spatial resolution; pooling layers are not used. Masks are adopted in the convolutions to avoid seeing the future context; masks have previously also been used in non-convolutional models such as MADE (Germain et al., 2015). Note that the advantage of parallelization of the PixelCNN over the PixelRNN is only available during training or during evaluating of test images. The image generation process is sequential for both kinds of networks, as each sampled pixel needs to be given as input back into the network.
Row LSTM 和 Diagonal LSTM 层在其感受野内具有可能无界的依赖范围。这带来了计算代价,因为每个状态都需要顺序计算。一个简单的变通办法是让感受野很大,但并非无界。我们可以用标准卷积层来捕捉有界感受野,并一次性计算所有像素位置的特征。PixelCNN 使用多层保持空间分辨率的卷积;不使用池化层。卷积中采用掩码,以避免看到未来的上下文;掩码此前也已用于非卷积模型,例如 MADE(Germain et al., 2015)。需要注意的是,PixelCNN 相对 PixelRNN 的并行优势,只在训练或评估测试图像时存在。两类网络的图像生成过程都是顺序的,因为每个采样得到的像素都需要再作为输入送回网络。
3.6. Multi-Scale PixelRNN
The Multi-Scale PixelRNN is composed of an unconditional PixelRNN and one or more conditional PixelRNNs. The unconditional network first generates in the standard way a smaller image that is subsampled from the original image. The conditional network then takes the image as an additional input and generates a larger image, as shown in Figure 2 (Middle).
多尺度 PixelRNN 由一个无条件 PixelRNN 和一个或多个条件 PixelRNN 组成。无条件网络首先按标准方式生成一张从原图下采样得到的较小的 图像。条件网络随后把这张 图像作为额外输入,生成更大的 图像,如图 2(中)所示。
The conditional network is similar to a standard PixelRNN, but each of its layers is biased with an upsampled version of the small image. The upsampling and biasing processes are defined as follows. In the upsampling process, one uses a convolutional network with deconvolutional layers to construct an enlarged feature map of size , where is the number of features in the output map of the upsampling network. Then, in the biasing process, for each layer in the conditional PixelRNN, one simply maps the conditioning map into a map that is added to the input-to-state map of the corresponding layer; this is performed using a unmasked convolution. The larger image is then generated as usual.
条件网络与标准 PixelRNN 相似,但其每一层都用这张较小的 图像的上采样版本来偏置。上采样和偏置过程定义如下。在上采样过程中,使用带反卷积层的卷积网络构造一张放大的、大小为 的特征图,其中 是上采样网络输出图中的特征数。然后,在偏置过程中,对条件 PixelRNN 的每一层,只需把 的条件图映射成一张 的图,并加到相应层的输入到状态图上;这用一个无掩码的 卷积完成。随后再按通常方式生成较大的 图像。
4. Specifications of Models
In this section we give the specifications of the PixelRNNs used in the experiments. We have four types of networks: the PixelRNN based on Row LSTM, the one based on Diagonal BiLSTM, the fully convolutional one and the Multi-Scale one.
本节给出实验中所用 PixelRNN 的规格。我们有四类网络:基于 Row LSTM 的 PixelRNN、基于 Diagonal BiLSTM 的 PixelRNN、全卷积网络,以及多尺度网络。
Table 1. Details of the architectures. In the LSTM architectures i-s and s-s stand for input-state and state-state convolutions.
| PixelCNN | Row LSTM | Diagonal BiLSTM | |
|---|---|---|---|
| 7 × 7 conv mask A | 7 × 7 conv mask A | 7 × 7 conv mask A | |
| Multiple residual blocks: (see fig 5) | Multiple residual blocks: (see fig 5) | Multiple residual blocks: (see fig 5) | |
| Conv 3 × 3 mask B | Row LSTM, i-s: 3 × 1 mask B; s-s: 3 × 1 no mask | Diagonal BiLSTM, i-s: 1 × 1 mask B; s-s: 1 × 2 no mask | |
| ReLU followed by 1 × 1 conv, mask B (2 layers) | ReLU followed by 1 × 1 conv, mask B (2 layers) | ReLU followed by 1 × 1 conv, mask B (2 layers) | |
| 256-way Softmax for each RGB color (Natural images) or Sigmoid (MNIST) | 256-way Softmax for each RGB color (Natural images) or Sigmoid (MNIST) | 256-way Softmax for each RGB color (Natural images) or Sigmoid (MNIST) |
表 1. 各结构的细节。在 LSTM 结构中,i-s 和 s-s 分别表示输入到状态和状态到状态的卷积。
| PixelCNN | Row LSTM | Diagonal BiLSTM | |
|---|---|---|---|
| 7 × 7 conv mask A | 7 × 7 conv mask A | 7 × 7 conv mask A | |
| 多个残差块:(见图 5) | 多个残差块:(见图 5) | 多个残差块:(见图 5) | |
| Conv 3 × 3 mask B | Row LSTM,i-s:3 × 1 mask B;s-s:3 × 1 无掩码 | Diagonal BiLSTM,i-s:1 × 1 mask B;s-s:1 × 2 无掩码 | |
| ReLU,后接 1 × 1 conv,mask B(2 层) | ReLU,后接 1 × 1 conv,mask B(2 层) | ReLU,后接 1 × 1 conv,mask B(2 层) | |
| 每个 RGB 颜色的 256 路 Softmax(自然图像)或 Sigmoid(MNIST) | 每个 RGB 颜色的 256 路 Softmax(自然图像)或 Sigmoid(MNIST) | 每个 RGB 颜色的 256 路 Softmax(自然图像)或 Sigmoid(MNIST) |
Table 1 specifies each layer in the single-scale networks. The first layer is a convolution that uses the mask of type A. The two types of LSTM networks then use a variable number of recurrent layers. The input-to-state convolution in this layer uses a mask of type B, whereas the state-to-state convolution is not masked. The PixelCNN uses convolutions of size with a mask of type B. The top feature map is then passed through a couple of layers consisting of a Rectified Linear Unit (ReLU) and a convolution. For the CIFAR-10 and ImageNet experiments, these layers have 1024 feature maps; for the MNIST experiment, the layers have 32 feature maps. Residual and layer-to-output connections are used across the layers of all three networks.
表 1 给出了单尺度网络中每一层的规格。第一层是使用 A 类掩码的 卷积。随后,两类 LSTM 网络使用数量可变的循环层。该层中的输入到状态卷积使用 B 类掩码,而状态到状态卷积不加掩码。PixelCNN 使用大小为 、带 B 类掩码的卷积。顶层特征图随后经过由修正线性单元(ReLU)和 卷积组成的若干层。对 CIFAR-10 和 ImageNet 实验,这些层有 1024 张特征图;对 MNIST 实验,这些层有 32 张特征图。三类网络的各层都使用残差连接和层到输出的连接。
The networks used in the experiments have the following hyperparameters. For MNIST we use a Diagonal BiLSTM with 7 layers and a value of (Section 3.3 and Figure 5 right). For CIFAR-10 the Row and Diagonal BiLSTMs have 12 layers and a number of units. The PixelCNN has 15 layers and . For ImageNet we adopt a 12 layer Row LSTM with units and for ImageNet we use a 4 layer Row LSTM with units; the latter model does not use residual connections.
实验中所用网络的超参数如下。对 MNIST,我们使用 7 层、 的 Diagonal BiLSTM(第 3.3 节和图 5 右)。对 CIFAR-10,Row LSTM 和 Diagonal BiLSTM 为 12 层, 个单元。PixelCNN 为 15 层,。对 ImageNet,我们采用 12 层、 个单元的 Row LSTM;对 ImageNet,我们使用 4 层、 个单元的 Row LSTM;后一个模型不使用残差连接。
5. Experiments
In this section we describe our experiments and results. We begin by describing the way we evaluate and compare our results. In Section 5.2 we give details about the training. Then we give results on the relative effectiveness of architectural components and our best results on the MNIST, CIFAR-10 and ImageNet datasets.
本节描述我们的实验和结果。我们先说明如何评估和比较结果。第 5.2 节给出训练细节。随后给出各结构组件相对效果的结果,以及我们在 MNIST、CIFAR-10 和 ImageNet 数据集上的最好结果。
5.1. Evaluation
All our models are trained and evaluated on the log-likelihood loss function coming from a discrete distribution. Although natural image data is usually modeled with continuous distributions using density functions, we can compare our results with previous art in the following way. In the literature it is currently best practice to add real-valued noise to the pixel values to dequantize the data when using density functions (Uria et al., 2013). When uniform noise is added (with values in the interval ), then the log-likelihoods of continuous and discrete models are directly comparable (Theis et al., 2015). In our case, we can use the values from the discrete distribution as a piecewise-uniform continuous function that has a constant value for every interval , . This corresponding distribution will have the same log-likelihood (on data with added noise) as the original discrete distribution (on discrete data).
我们所有模型的训练和评估,都使用来自离散分布的对数似然损失函数。尽管自然图像数据通常用密度函数以连续分布来建模,我们仍可用如下方式与已有工作比较。文献中目前的通行做法是:在使用密度函数时,向像素值加入实值噪声以对数据去量化(Uria et al., 2013)。当加入取值位于区间 的均匀噪声时,连续模型和离散模型的对数似然可以直接比较(Theis et al., 2015)。在我们的情形中,可以把离散分布的取值当成一个分段均匀的连续函数,它在每个区间 , 上取常数。这一对应分布(在加入噪声的数据上)将与原来的离散分布(在离散数据上)具有相同的对数似然。
For MNIST we report the negative log-likelihood in nats as it is common practice in literature. For CIFAR-10 and ImageNet we report negative log-likelihoods in bits per dimension. The total discrete log-likelihood is normalized by the dimensionality of the images (e.g., for CIFAR-10). These numbers are interpretable as the number of bits that a compression scheme based on this model would need to compress every RGB color value (van den Oord & Schrauwen, 2014b; Theis et al., 2015); in practice there is also a small overhead due to arithmetic coding.
对 MNIST,我们按文献中的惯例,以 nats 报告负对数似然。对 CIFAR-10 和 ImageNet,我们以每维比特数报告负对数似然。总的离散对数似然按图像的维度归一化(例如,CIFAR-10 为 )。这些数字可以理解为:基于该模型的压缩方案压缩每个 RGB 颜色值所需的比特数(van den Oord & Schrauwen, 2014b; Theis et al., 2015);实践中由于算术编码还会有少量开销。
5.2. Training Details
Our models are trained on GPUs using the Torch toolbox. From the different parameter update rules tried, RMSProp gives best convergence performance and is used for all experiments. The learning rate schedules were manually set for every dataset to the highest values that allowed fast convergence. The batch sizes also vary for different datasets. For smaller datasets such as MNIST and CIFAR-10 we use smaller batch sizes of 16 images as this seems to regularize the models. For ImageNet we use as large a batch size as allowed by the GPU memory; this corresponds to 64 images/batch for ImageNet, and 32 images/batch for ImageNet. Apart from scaling and centering the images at the input of the network, we don't use any other preprocessing or augmentation. For the multinomial loss function we use the raw pixel color values as categories. For all the PixelRNN models, we learn the initial recurrent state of the network.
我们的模型用 Torch 工具箱在 GPU 上训练。在尝试过的不同参数更新规则中,RMSProp 的收敛表现最好,并用于全部实验。每个数据集的学习率日程都是手动设定的,取能允许快速收敛的最高值。不同数据集的批量大小也不同。对 MNIST 和 CIFAR-10 这类较小的数据集,我们使用 16 张图像的较小批量,因为这似乎能对模型起到正则作用。对 ImageNet,我们使用 GPU 内存所允许的尽可能大的批量;这对应于 ImageNet 每批 64 张, ImageNet 每批 32 张。除了在网络输入处对图像做缩放和中心化外,我们不使用任何其他预处理或增强。对多项损失函数,我们把原始像素颜色值当作类别。对所有 PixelRNN 模型,我们学习网络的初始循环状态。
5.3. Discrete Softmax Distribution
Apart from being intuitive and easy to implement, we find that using a softmax on discrete pixel values instead of a mixture density approach on continuous pixel values gives better results. For the Row LSTM model with a softmax output distribution we obtain 3.06 bits/dim on the CIFAR-10 validation set. For the same model with a Mixture of Conditional Gaussian Scale Mixtures (MCGSM) (Theis & Bethge, 2015) we obtain 3.22 bits/dim.
除了直观、易于实现之外,我们发现:对离散像素值使用 softmax,而不是对连续像素值使用混合密度方法,能得到更好的结果。对带 softmax 输出分布的 Row LSTM 模型,我们在 CIFAR-10 验证集上得到 3.06 bits/dim。对同一模型,若改用条件高斯尺度混合(MCGSM)(Theis & Bethge, 2015),则得到 3.22 bits/dim。
In Figure 6 we show a few softmax activations from the model. Although we don't embed prior information about the meaning or relations of the 256 color categories, e.g. that pixel values 51 and 52 are neighbors, the distributions predicted by the model are meaningful and can be multimodal, skewed, peaked or long tailed. Also note that values 0 and 255 often get a much higher probability as they are more frequent. Another advantage of the discrete distribution is that we do not worry about parts of the distribution mass lying outside the interval , which is something that typically happens with continuous distributions.
在图 6 中,我们展示了模型的几个 softmax 激活。尽管我们没有嵌入关于这 256 个颜色类别含义或关系的先验信息,例如像素值 51 和 52 是相邻的,模型预测出的分布仍然是有意义的,并且可以是多峰、偏斜、尖峰或长尾的。还应注意,0 和 255 这两个值往往得到高得多的概率,因为它们更常见。离散分布的另一个优点是,我们不必担心一部分分布质量落在区间 之外,而这在连续分布中通常会发生。
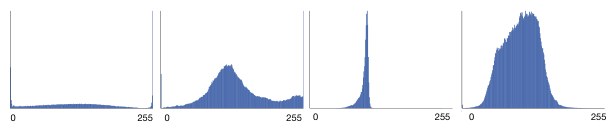
Figure 6. Example softmax activations from the model. The left-most shows the distribution of the first pixel red value (first value to sample).
图 6. 模型的 softmax 激活示例。最左侧给出第一个像素红色值(第一个要采样的值)的分布。
5.4. Residual Connections
Another core component of the networks is residual connections. In Table 2 we show the results of having residual connections, having standard skip connections or having both, in the 12-layer CIFAR-10 Row LSTM model. We see that using residual connections is as effective as using skip connections; using both is also effective and preserves the advantage.
网络的另一个核心组件是残差连接。在表 2 中,我们给出了在 12 层 CIFAR-10 Row LSTM 模型中,分别使用残差连接、使用标准 skip 连接,或两者都用的结果。可以看到,使用残差连接与使用 skip 连接同样有效;两者一起用也有效,并保留了这一优势。
Table 2. Effect of residual and skip connections in the Row LSTM network evaluated on the Cifar-10 validation set in bits/dim.
| No skip | Skip | |
|---|---|---|
| No residual: | 3.22 | 3.09 |
| Residual: | 3.07 | 3.06 |
表 2. Row LSTM 网络中残差连接和 skip 连接的效果,在 Cifar-10 验证集上以 bits/dim 评估。
| 无 skip | 有 skip | |
|---|---|---|
| 无残差: | 3.22 | 3.09 |
| 有残差: | 3.07 | 3.06 |
When using both the residual and skip connections, we see in Table 3 that performance of the Row LSTM improves with increased depth. This holds for up to the 12 LSTM layers that we tried.
在同时使用残差连接和 skip 连接时,我们在表 3 中看到,Row LSTM 的表现随深度增加而提高。这一趋势一直持续到我们所尝试的 12 个 LSTM 层。
Table 3. Effect of the number of layers on the negative log likelihood evaluated on the CIFAR-10 validation set (bits/dim).
| # layers: | 1 | 2 | 3 | 6 | 9 | 12 |
|---|---|---|---|---|---|---|
| NLL: | 3.30 | 3.20 | 3.17 | 3.09 | 3.08 | 3.06 |
表 3. 层数对负对数似然的影响,在 CIFAR-10 验证集上评估(bits/dim)。
| 层数: | 1 | 2 | 3 | 6 | 9 | 12 |
|---|---|---|---|---|---|---|
| NLL: | 3.30 | 3.20 | 3.17 | 3.09 | 3.08 | 3.06 |
5.5. MNIST
Although the goal of our work was to model natural images on a large scale, we also tried our model on the binary version (Salakhutdinov & Murray, 2008) of MNIST (LeCun et al., 1998) as it is a good sanity check and there is a lot of previous art on this dataset to compare with. In Table 4 we report the performance of the Diagonal BiLSTM model and that of previous published results. To our knowledge this is the best reported result on MNIST so far.
尽管我们工作的目标是在大规模上对自然图像建模,我们也在 MNIST(LeCun et al., 1998)的二元版本(Salakhutdinov & Murray, 2008)上尝试了我们的模型,因为这是一次很好的健全性检查,而且该数据集上有许多已有工作可以比较。在表 4 中,我们报告 Diagonal BiLSTM 模型的表现以及此前已发表的结果。据我们所知,这是迄今在 MNIST 上报告过的最好结果。
5.6. CIFAR-10
Next we test our models on the CIFAR-10 dataset (Krizhevsky, 2009). Table 5 lists the results of our models and that of previously published approaches. For the proposed networks, the Diagonal BiLSTM has the best performance, followed by the Row LSTM and the PixelCNN. This coincides with the size of the respective receptive fields: the Diagonal BiLSTM has a global view, the Row LSTM has a partially occluded view and the PixelCNN sees the fewest pixels in the context. This suggests that effectively capturing a large receptive field is important. Figure 7 (left) shows CIFAR-10 samples generated from the Diagonal BiLSTM.
接下来我们在 CIFAR-10 数据集(Krizhevsky, 2009)上测试模型。表 5 列出了我们的模型以及此前已发表方法的结果。在所提出的网络中,Diagonal BiLSTM 表现最好,其次是 Row LSTM 和 PixelCNN。这与各自感受野的大小一致:Diagonal BiLSTM 具有全局视野,Row LSTM 的视野被部分遮挡,而 PixelCNN 在上下文中看到的像素最少。这表明,有效捕捉大的感受野很重要。图 7(左)给出了由 Diagonal BiLSTM 生成的 CIFAR-10 样本。
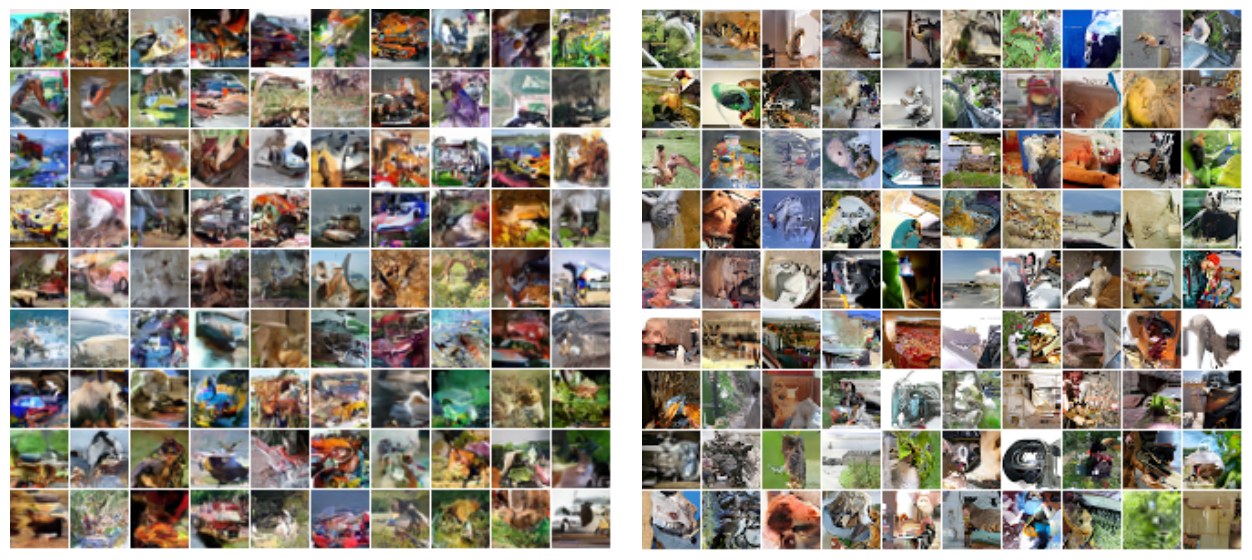
Figure 7. Samples from models trained on CIFAR-10 (left) and ImageNet 32x32 (right) images. In general we can see that the models capture local spatial dependencies relatively well. The ImageNet model seems to be better at capturing more global structures than the CIFAR-10 model. The ImageNet model was larger and trained on much more data, which explains the qualitative difference in samples.
图 7. 在 CIFAR-10(左)和 ImageNet 32x32(右)图像上训练的模型所生成的样本。总体上看,模型对局部空间依赖捕捉得比较好。ImageNet 模型似乎比 CIFAR-10 模型更善于捕捉更全局的结构。ImageNet 模型更大,并且在多得多的数据上训练,这可以解释样本在质上的差异。
Table 4. Test set performance of different models on MNIST in nats (negative log-likelihood). Prior results taken from [1] (Salakhutdinov & Hinton, 2009), [2] (Murray & Salakhutdinov, 2009), [3] (Uria et al., 2014), [4] (Raiko et al., 2014), [5] (Rezende et al., 2014), [6] (Salimans et al., 2015), [7] (Gregor et al., 2014), [8] (Germain et al., 2015), [9] (Gregor et al., 2015).
| Model | NLL Test |
|---|---|
| DBM 2hl [1]: | ≈ 84.62 |
| DBN 2hl [2]: | ≈ 84.55 |
| NADE [3]: | 88.33 |
| EoNADE 2hl (128 orderings) [3]: | 85.10 |
| EoNADE-5 2hl (128 orderings) [4]: | 84.68 |
| DLGM [5]: | ≈ 86.60 |
| DLGM 8 leapfrog steps [6]: | ≈ 85.51 |
| DARN 1hl [7]: | ≈ 84.13 |
| MADE 2hl (32 masks) [8]: | 86.64 |
| DRAW [9]: | ≤ 80.97 |
| PixelCNN: | 81.30 |
| Row LSTM: | 80.54 |
| Diagonal BiLSTM (1 layer, ): | 80.75 |
| Diagonal BiLSTM (7 layers, ): | 79.20 |
表 4. 不同模型在 MNIST 测试集上的表现,单位为 nats(负对数似然)。先前结果取自 [1](Salakhutdinov & Hinton, 2009),[2](Murray & Salakhutdinov, 2009),[3](Uria et al., 2014),[4](Raiko et al., 2014),[5](Rezende et al., 2014),[6](Salimans et al., 2015),[7](Gregor et al., 2014),[8](Germain et al., 2015),[9](Gregor et al., 2015)。
| 模型 | NLL 测试 |
|---|---|
| DBM 2hl [1]: | ≈ 84.62 |
| DBN 2hl [2]: | ≈ 84.55 |
| NADE [3]: | 88.33 |
| EoNADE 2hl(128 种排序)[3]: | 85.10 |
| EoNADE-5 2hl(128 种排序)[4]: | 84.68 |
| DLGM [5]: | ≈ 86.60 |
| DLGM 8 步 leapfrog [6]: | ≈ 85.51 |
| DARN 1hl [7]: | ≈ 84.13 |
| MADE 2hl(32 个掩码)[8]: | 86.64 |
| DRAW [9]: | ≤ 80.97 |
| PixelCNN: | 81.30 |
| Row LSTM: | 80.54 |
| Diagonal BiLSTM(1 层,): | 80.75 |
| Diagonal BiLSTM(7 层,): | 79.20 |
Table 5. Test set performance of different models on CIFAR-10 in bits/dim. For our models we give training performance in brackets. [1] (Dinh et al., 2014), [2] (Sohl-Dickstein et al., 2015), [3] (van den Oord & Schrauwen, 2014a), [4] personal communication (Theis & Bethge, 2015).
| Model | NLL Test (Train) |
|---|---|
| Uniform Distribution: | 8.00 |
| Multivariate Gaussian: | 4.70 |
| NICE [1]: | 4.48 |
| Deep Diffusion [2]: | 4.20 |
| Deep GMMs [3]: | 4.00 |
| RIDE [4]: | 3.47 |
| PixelCNN: | 3.14 (3.08) |
| Row LSTM: | 3.07 (3.00) |
| Diagonal BiLSTM: | 3.00 (2.93) |
表 5. 不同模型在 CIFAR-10 测试集上的表现,单位为 bits/dim。对我们的模型,括号中给出训练表现。[1](Dinh et al., 2014),[2](Sohl-Dickstein et al., 2015),[3](van den Oord & Schrauwen, 2014a),[4] 个人通信(Theis & Bethge, 2015)。
| 模型 | NLL 测试(训练) |
|---|---|
| 均匀分布: | 8.00 |
| 多元高斯: | 4.70 |
| NICE [1]: | 4.48 |
| Deep Diffusion [2]: | 4.20 |
| Deep GMMs [3]: | 4.00 |
| RIDE [4]: | 3.47 |
| PixelCNN: | 3.14 (3.08) |
| Row LSTM: | 3.07 (3.00) |
| Diagonal BiLSTM: | 3.00 (2.93) |
Table 6. Negative log-likelihood performance on and ImageNet in bits/dim.
| Image size | NLL Validation (Train) |
|---|---|
| 32x32: | 3.86 (3.83) |
| 64x64: | 3.63 (3.57) |
表 6. 在 和 ImageNet 上的负对数似然表现,单位为 bits/dim。
| 图像尺寸 | NLL 验证(训练) |
|---|---|
| 32x32: | 3.86 (3.83) |
| 64x64: | 3.63 (3.57) |
5.7. ImageNet
Although to our knowledge the are no published results on the ILSVRC ImageNet dataset (Russakovsky et al., 2015) that we can compare our models with, we give our ImageNet log-likelihood performance in Table 6. On ImageNet the current PixelRNNs do not appear to overfit, as we saw that their validation performance improved with size and depth. The main constraint on model size are currently computation time and GPU memory.
尽管据我们所知,在 ILSVRC ImageNet 数据集(Russakovsky et al., 2015)上还没有已发表的结果可供与我们的模型比较,我们仍在表 6 中给出我们在 ImageNet 上的对数似然表现。在 ImageNet 上,当前的 PixelRNN 看上去没有过拟合,因为我们看到它们的验证表现随模型规模和深度而提高。目前限制模型规模的主要因素是计算时间和 GPU 内存。
Note that the ImageNet models are in general less compressible than the CIFAR-10 images. ImageNet has greater variety of images, and the CIFAR-10 images were most likely resized with a different algorithm than the one we used for ImageNet images. The ImageNet images are less blurry, which means neighboring pixels are less correlated to each other and thus less predictable. Because the downsampling method can influence the compression performance, we will release the used downsampled images.
需要注意的是,ImageNet 模型所对应的图像总体比 CIFAR-10 图像更难压缩。ImageNet 的图像种类更多,而且 CIFAR-10 图像很可能是用与我们处理 ImageNet 图像不同的算法缩放的。ImageNet 图像不那么模糊,这意味着相邻像素之间的相关性更弱,因而更难预测。由于下采样方法会影响压缩表现,我们将发布所使用的下采样图像。
Figure 7 (right) shows samples drawn from our model trained on ImageNet. Figure 8 shows samples from the same model with and without multi-scale conditioning. Finally, we also show image completions sampled from the model in Figure 9.
图 7(右)给出了从我们在 ImageNet 上训练的模型中抽取的 样本。图 8 给出了同一模型在有和没有多尺度条件时的 样本。最后,我们还在图 9 中给出了从该模型采样得到的图像补全。
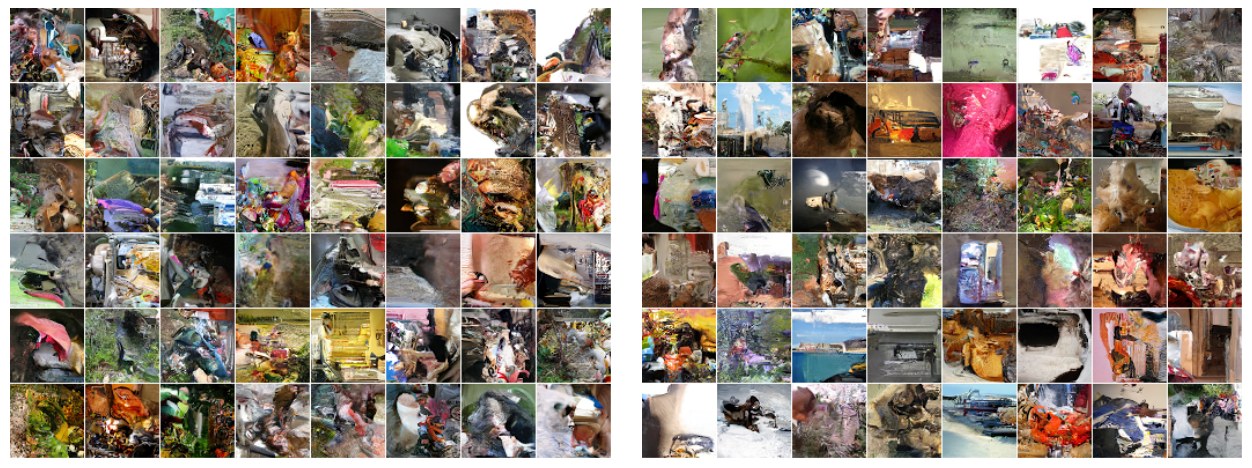
Figure 8. Samples from models trained on ImageNet 64x64 images. Left: normal model, right: multi-scale model. The single-scale model trained on 64x64 images is less able to capture global structure than the 32x32 model. The multi-scale model seems to resolve this problem. Although these models get similar performance in log-likelihood, the samples on the right do seem globally more coherent.
图 8. 在 ImageNet 64x64 图像上训练的模型所生成的样本。左:普通模型,右:多尺度模型。在 64x64 图像上训练的单尺度模型,不如 32x32 模型善于捕捉全局结构。多尺度模型似乎解决了这一问题。尽管这些模型在对数似然上的表现相近,右侧的样本在整体上确实显得更连贯。
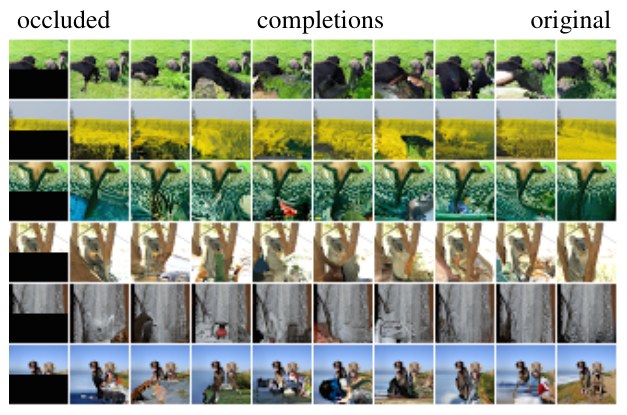
Figure 9. Image completions sampled from a model that was trained on 32x32 ImageNet images. Note that diversity of the completions is high, which can be attributed to the log-likelihood loss function used in this generative model, as it encourages models with high entropy. As these are sampled from the model, we can easily generate millions of different completions. It is also interesting to see that textures such as water, wood and shrubbery are also inputed relative well (see Figure 1).
图 9. 从在 32x32 ImageNet 图像上训练的模型中采样得到的图像补全。注意补全的多样性很高,这可以归因于该生成模型所用的对数似然损失函数,因为它鼓励高熵的模型。由于这些是从模型中采样得到的,我们可以很容易地生成数百万种不同的补全。同样有意思的是,水面、木头和灌木一类纹理也补得比较好(见图 1)。
6. Conclusion
In this paper we significantly improve and build upon deep recurrent neural networks as generative models for natural images. We have described novel two-dimensional LSTM layers: the Row LSTM and the Diagonal BiLSTM, that scale more easily to larger datasets. The models were trained to model the raw RGB pixel values. We treated the pixel values as discrete random variables by using a softmax layer in the conditional distributions. We employed masked convolutions to allow PixelRNNs to model full dependencies between the color channels. We proposed and evaluated architectural improvements in these models resulting in PixelRNNs with up to 12 LSTM layers.
在本文中,我们显著改进并以深度循环神经网络作为自然图像生成模型继续推进。我们描述了新颖的二维 LSTM 层:Row LSTM 和 Diagonal BiLSTM,它们更容易扩展到更大的数据集。这些模型被训练来对原始 RGB 像素值建模。我们通过在条件分布中使用 softmax 层,把像素值当成离散随机变量。我们采用掩码卷积,使 PixelRNN 能够对颜色通道之间的全部依赖建模。我们提出并评估了这些模型中的结构改进,得到了最多 12 个 LSTM 层的 PixelRNN。
We have shown that the PixelRNNs significantly improve the state of the art on the MNIST and CIFAR-10 datasets. We also provide new benchmarks for generative image modeling on the ImageNet dataset. Based on the samples and completions drawn from the models we can conclude that the PixelRNNs are able to model both spatially local and long-range correlations and are able to produce images that are sharp and coherent. Given that these models improve as we make them larger and that there is practically unlimited data available to train on, more computation and larger models are likely to further improve the results.
我们已经表明,PixelRNN 在 MNIST 和 CIFAR-10 数据集上显著改进了当时最好的结果。我们还为 ImageNet 数据集上的生成式图像建模提供了新的基准。根据从模型中抽取的样本和补全,可以认为 PixelRNN 既能建模空间上的局部相关,也能建模长程相关,并能够生成清晰且连贯的图像。鉴于这些模型在做得更大时还会提高,而且几乎有无限的数据可供训练,更多的计算和更大的模型很可能进一步改进结果。
Acknowledgements
The authors would like to thank Shakir Mohamed and Guillaume Desjardins for helpful input on this paper and Lucas Theis, Alex Graves, Karen Simonyan, Lasse Espeholt, Danilo Rezende, Karol Gregor and Ivo Danihelka for insightful discussions.
作者感谢 Shakir Mohamed 和 Guillaume Desjardins 对本文的有益意见,并感谢 Lucas Theis、Alex Graves、Karen Simonyan、Lasse Espeholt、Danilo Rezende、Karol Gregor 和 Ivo Danihelka 富有启发的讨论。
References
Dinh, Laurent, Krueger, David, and Bengio, Yoshua. NICE: Non-linear independent components estimation. arXiv preprint arXiv:1410.8516, 2014.
Germain, Mathieu, Gregor, Karol, Murray, Iain, and Larochelle, Hugo. MADE: Masked autoencoder for distribution estimation. arXiv preprint arXiv:1502.03509, 2015.
Graves, Alex. Generating sequences with recurrent neural networks. arXiv preprint arXiv:1308.0850, 2013.
Graves, Alex and Schmidhuber, Jürgen. Offline handwriting recognition with multidimensional recurrent neural networks. In Advances in Neural Information Processing Systems, 2009.
Gregor, Karol, Danihelka, Ivo, Mnih, Andriy, Blundell, Charles, and Wierstra, Daan. Deep autoregressive networks. In Proceedings of the 31st International Conference on Machine Learning, 2014.
Gregor, Karol, Danihelka, Ivo, Graves, Alex, and Wierstra, Daan. DRAW: A recurrent neural network for image generation. Proceedings of the 32nd International Conference on Machine Learning, 2015.
He, Kaiming, Zhang, Xiangyu, Ren, Shaoqing, and Sun, Jian. Deep residual learning for image recognition. arXiv preprint arXiv:1512.03385, 2015.
Hochreiter, Sepp and Schmidhuber, Jürgen. Long short-term memory. Neural computation, 1997.
Kalchbrenner, Nal and Blunsom, Phil. Recurrent continuous translation models. In Proceedings of the 2013 Conference on Empirical Methods in Natural Language Processing, 2013.
Kalchbrenner, Nal, Danihelka, Ivo, and Graves, Alex. Grid long short-term memory. arXiv preprint arXiv:1507.01526, 2015.
Kingma, Diederik P and Welling, Max. Auto-encoding variational bayes. arXiv preprint arXiv:1312.6114, 2013.
Krizhevsky, Alex. Learning multiple layers of features from tiny images. 2009.
Larochelle, Hugo and Murray, Iain. The neural autoregressive distribution estimator. The Journal of Machine Learning Research, 2011.
LeCun, Yann, Bottou, Léon, Bengio, Yoshua, and Haffner, Patrick. Gradient-based learning applied to document recognition. Proceedings of the IEEE, 1998.
Murray, Iain and Salakhutdinov, Ruslan R. Evaluating probabilities under high-dimensional latent variable models. In Advances in Neural Information Processing Systems, 2009.
Neal, Radford M. Connectionist learning of belief networks. Artificial intelligence, 1992.
Raiko, Tapani, Li, Yao, Cho, Kyunghyun, and Bengio, Yoshua. Iterative neural autoregressive distribution estimator NADE-k. In Advances in Neural Information Processing Systems, 2014.
Rezende, Danilo J, Mohamed, Shakir, and Wierstra, Daan. Stochastic backpropagation and approximate inference in deep generative models. In Proceedings of the 31st International Conference on Machine Learning, 2014.
Russakovsky, Olga, Deng, Jia, Su, Hao, Krause, Jonathan, Satheesh, Sanjeev, Ma, Sean, Huang, Zhiheng, Karpathy, Andrej, Khosla, Aditya, Bernstein, Michael, Berg, Alexander C., and Fei-Fei, Li. ImageNet Large Scale Visual Recognition Challenge. International Journal of Computer Vision (IJCV), 2015.
Salakhutdinov, Ruslan and Hinton, Geoffrey E. Deep boltzmann machines. In International Conference on Artificial Intelligence and Statistics, 2009.
Salakhutdinov, Ruslan and Murray, Iain. On the quantitative analysis of deep belief networks. In Proceedings of the 25th international conference on Machine learning, 2008.
Salimans, Tim, Kingma, Diederik P, and Welling, Max. Markov chain monte carlo and variational inference: Bridging the gap. Proceedings of the 32nd International Conference on Machine Learning, 2015.
Sohl-Dickstein, Jascha, Weiss, Eric A., Maheswaranathan, Niru, and Ganguli, Surya. Deep unsupervised learning using nonequilibrium thermodynamics. Proceedings of the 32nd International Conference on Machine Learning, 2015.
Stollenga, Marijn F, Byeon, Wonmin, Liwicki, Marcus, and Schmidhuber, Juergen. Parallel multi-dimensional lstm, with application to fast biomedical volumetric image segmentation. In Advances in Neural Information Processing Systems 28. 2015.
Sutskever, Ilya, Martens, James, and Hinton, Geoffrey E. Generating text with recurrent neural networks. In Proceedings of the 28th International Conference on Machine Learning, 2011.
Theis, Lucas and Bethge, Matthias. Generative image modeling using spatial LSTMs. In Advances in Neural Information Processing Systems, 2015.
Theis, Lucas, van den Oord, Aäron, and Bethge, Matthias. A note on the evaluation of generative models. arXiv preprint arXiv:1511.01844, 2015.
Uria, Benigno, Murray, Iain, and Larochelle, Hugo. RNADE: The real-valued neural autoregressive density-estimator. In Advances in Neural Information Processing Systems, 2013.
Uria, Benigno, Murray, Iain, and Larochelle, Hugo. A deep and tractable density estimator. In Proceedings of the 31st International Conference on Machine Learning, 2014.
van den Oord, Aäron and Schrauwen, Benjamin. Factoring variations in natural images with deep gaussian mixture models. In Advances in Neural Information Processing Systems, 2014a.
van den Oord, Aäron and Schrauwen, Benjamin. The student-t mixture as a natural image patch prior with application to image compression. The Journal of Machine Learning Research, 2014b.
Zhang, Yu, Chen, Guoguo, Yu, Dong, Yao, Kaisheng, Khudanpur, Sanjeev, and Glass, James. Highway long short-term memory RNNs for distant speech recognition. In Proceedings of the International Conference on Acoustics, Speech and Signal Processing, 2016.