Image-to-Image Translation with Conditional Adversarial Networks
Image-to-Image Translation with Conditional Adversarial Networks
条件对抗网络的图像到图像翻译(Image-to-Image Translation with Conditional Adversarial Networks)
Phillip Isola Jun-Yan Zhu Tinghui Zhou Alexei A. Efros Affiliation: Berkeley AI Research (BAIR) Laboratory, UC Berkeley Email: {isola,junyanz,tinghuiz,efros}@eecs.berkeley.edu
Phillip Isola Jun-Yan Zhu Tinghui Zhou Alexei A. Efros
所属机构:Berkeley AI Research (BAIR) Laboratory,UC Berkeley
邮箱:{isola,junyanz,tinghuiz,efros}@eecs.berkeley.edu
Abstract
摘要
We investigate conditional adversarial networks as a general-purpose solution to image-to-image translation problems. These networks not only learn the mapping from input image to output image, but also learn a loss function to train this mapping. This makes it possible to apply the same generic approach to problems that traditionally would require very different loss formulations. We demonstrate that this approach is effective at synthesizing photos from label maps, reconstructing objects from edge maps, and colorizing images, among other tasks. Indeed, since the release of the pix2pix software associated with this paper, a large number of internet users (many of them artists) have posted their own experiments with our system, further demonstrating its wide applicability and ease of adoption without the need for parameter tweaking. As a community, we no longer hand-engineer our mapping functions, and this work suggests we can achieve reasonable results without hand-engineering our loss functions either.
我们研究条件对抗网络,将其作为图像到图像翻译问题的通用解法。这类网络不仅学习从输入图像到输出图像的映射,还学习用于训练该映射的损失函数。因此,同一套通用方法可以用于传统上需要截然不同损失形式的问题。我们表明,该方法能有效地从标签图合成照片、从边缘图重建物体、以及图像着色等任务。事实上,自与本文配套的 pix2pix 软件发布以来,大量互联网用户(其中许多是艺术家)已发布他们用本系统做的实验,进一步说明其适用面广、易于采用,且往往不必调参。作为一个社区,我们已不再手工设计映射函数;本工作表明,不手工设计损失函数也可能得到合理结果。
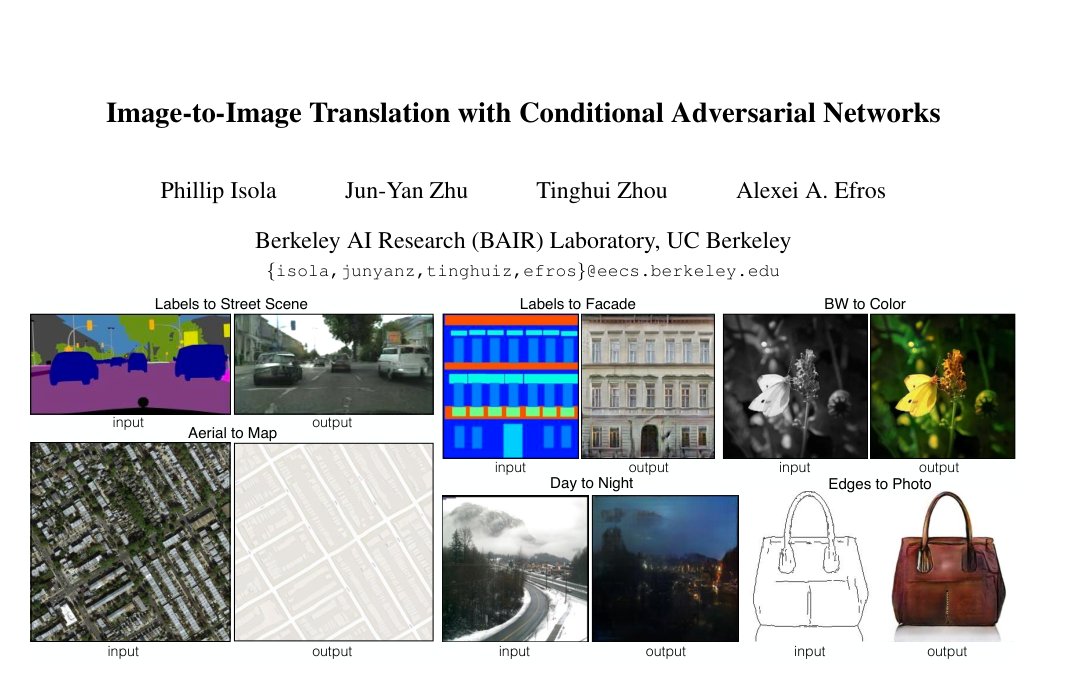
Figure 1: Many problems in image processing, graphics, and vision involve translating an input image into a corresponding output image. These problems are often treated with application-specific algorithms, even though the setting is always the same: map pixels to pixels. Conditional adversarial nets are a general-purpose solution that appears to work well on a wide variety of these problems. Here we show results of the method on several. In each case we use the same architecture and objective, and simply train on different data.
图 1:图像处理、图形学与视觉中的许多问题,都涉及把输入图像翻译成对应的输出图像。这些问题往往各用专用算法处理,尽管设定总是一样:像素映射到像素。条件对抗网络是一种通用解法,似乎在这类问题上广泛有效。这里展示本方法在若干任务上的结果。每种情形我们使用相同的架构与目标,只是在不同数据上训练。
1 Introduction
1 引言
Many problems in image processing, computer graphics, and computer vision can be posed as “translating” an input image into a corresponding output image. Just as a concept may be expressed in either English or French, a scene may be rendered as an RGB image, a gradient field, an edge map, a semantic label map, etc. In analogy to automatic language translation, we define automatic image-to-image translation as the task of translating one possible representation of a scene into another, given sufficient training data (see Figure 1). Traditionally, each of these tasks has been tackled with separate, special-purpose machinery (e.g., [16, 25, 20, 9, 11, 53, 33, 39, 18, 58, 62]), despite the fact that the setting is always the same: predict pixels from pixels. Our goal in this paper is to develop a common framework for all these problems.
图像处理、计算机图形和计算机视觉方面的许多问题都可以作为将输入图像“转换”成相应的输出图像。 正如一个概念可以用英语或法语表达一样,一个场景也可以作为RGB图像,梯度字段,边缘地图,语义标签地图等来渲染. 与自动语言翻译相类比,我们把自动的图像到图像翻译 定义为将一个场景的一种可能表现转化为另一个场景的任务,因为培训数据充足(见图1)。 传统上,这些任务都用单独的特殊用途机械(如[16,25,20,9,11,53,33,39,18,58,62])来处理,尽管设置总是相同的:从像素中预测像素. 我们本文件的目标是为所有这些问题制定一个共同框架。
The community has already taken significant steps in this direction, with convolutional neural nets (CNNs) becoming the common workhorse behind a wide variety of image prediction problems. CNNs learn to minimize a loss function – an objective that scores the quality of results – and although the learning process is automatic, a lot of manual effort still goes into designing effective losses. In other words, we still have to tell the CNN what we wish it to minimize. But, just like King Midas, we must be careful what we wish for! If we take a naive approach and ask the CNN to minimize the Euclidean distance between predicted and ground truth pixels, it will tend to produce blurry results [43, 62]. This is because Euclidean distance is minimized by averaging all plausible outputs, which causes blurring. Coming up with loss functions that force the CNN to do what we really want – e.g., output sharp, realistic images – is an open problem and generally requires expert knowledge.
社区已经朝这个方向采取了重大步骤,卷积神经网成为各种图像预测问题背后的共同工作马。 CNN学习将损失函数最小化 — — 一个对结果质量进行评分的目标 — — 尽管学习过程是自动的,但很多人工努力仍然在设计有效的损失. 换句话说,我们仍然要告诉CNN 我们希望它能最小化。 但是,就像米达斯国王一样,我们必须小心我们所希望的! 如果我们采取天真的方法,要求CNN将预测的和地面的真理像素之间的欧几里得距离降到最小,这往往会产生模糊的结果[43,62]. 这是因为欧几利得的距离通过平均所有可能的产出而最小化,从而导致模糊。 即将出现的丢失功能迫使CNN做我们真正想要的事 — — 比如输出尖锐、现实的图像 — — 是一个公开的问题,一般需要专家的知识。
It would be highly desirable if we could instead specify only a high-level goal, like “make the output indistinguishable from reality”, and then automatically learn a loss function appropriate for satisfying this goal. Fortunately, this is exactly what is done by the recently proposed Generative Adversarial Networks (GANs) [24, 13, 44, 52, 63]. GANs learn a loss that tries to classify if the output image is real or fake, while simultaneously training a generative model to minimize this loss. Blurry images will not be tolerated since they look obviously fake. Because GANs learn a loss that adapts to the data, they can be applied to a multitude of tasks that traditionally would require very different kinds of loss functions.
如果我们能够只具体说明一个高级别目标,如“使产出与现实无法区分”,然后自动学习一个适合满足这一目标的损失功能,那将是非常可取的。 所幸的是,这正是最近提议的基因辅助网络[24、13、44、52、63]所做的。 GANs学习到一个损失,试图对输出图像是否真实或是假的进行分类,同时训练一个生成模型来尽量减少这种损失. 模糊的图像是不会被容忍的,因为它们看起来明显是假的。 由于GANs学习了一种适应数据的损失,它们可以应用于传统上需要非常不同的损失功能的多种任务.
In this paper, we explore GANs in the conditional setting. Just as GANs learn a generative model of data, conditional GANs (cGANs) learn a conditional generative model [24]. This makes cGANs suitable for image-to-image translation tasks, where we condition on an input image and generate a corresponding output image.
在本文中,我们在有条件的环境下探索GANs. 正如GANs学习了数据的生成模型一样,有条件的GANs(cGANs)学习了有条件的生成模型[24]. 这使得cGANs适合图像到图像的翻译任务,在那里我们以输入图像为条件并生成相应的输出图像.
GANs have been vigorously studied in the last two years and many of the techniques we explore in this paper have been previously proposed. Nonetheless, earlier papers have focused on specific applications, and it has remained unclear how effective image-conditional GANs can be as a general-purpose solution for image-to-image translation. Our primary contribution is to demonstrate that on a wide variety of problems, conditional GANs produce reasonable results. Our second contribution is to present a simple framework sufficient to achieve good results, and to analyze the effects of several important architectural choices. Code is available at https://github.com/phillipi/pix2pix.
在过去两年中,全球网络得到了大力研究,我们在本文件中探索的许多技术是先前提出的。 尽管如此,先前的论文侧重于具体的应用,目前仍不清楚图像条件GANs作为图像到图像翻译的通用解决方案能够有多大效果. 我们的主要贡献是表明,在各种各样的问题上,有条件的GAN产生合理的结果。 我们的第二项贡献是提出一个足以取得良好结果的简单框架,并分析若干重要建筑选择的效果。 代码见https://github.com/phillipi/pix2pix.
2 Related work
2 相关工作
Structured losses for image modeling Image-to-image translation problems are often formulated as per-pixel classification or regression (e.g., [39, 58, 28, 35, 62]). These formulations treat the output space as “unstructured” in the sense that each output pixel is considered conditionally independent from all others given the input image. Conditional GANs instead learn a structured loss. Structured losses penalize the joint configuration of the output. A large body of literature has considered losses of this kind, with methods including conditional random fields [10], the SSIM metric [56], feature matching [15], nonparametric losses [37], the convolutional pseudo-prior [57], and losses based on matching covariance statistics [30]. The conditional GAN is different in that the loss is learned, and can, in theory, penalize any possible structure that differs between output and target.
图像模型的刻度损失 图像到图像的翻译问题往往按照每像素分类或回归来表述(例如[39,58,28,35,62]). 这些配方将输出空间视为“非结构化”的,即每个输出像素在条件上与所有其他输入图像独立。 有条件的GANs反而学习到一个“结构化损失”。 结构化损失会惩罚产出的联合配置. 大量文献考虑了这种损失 73. 方法包括有条件的随机字段 [10],SSIM rim [56],特征匹配 [15],非参数损失 [37],革命性伪序 [57],以及基于匹配共变统计的损失 [30]. 有条件的GAN是不同的,因为损失是学到的,理论上可以惩罚输出与目标之间任何可能不同的结构.
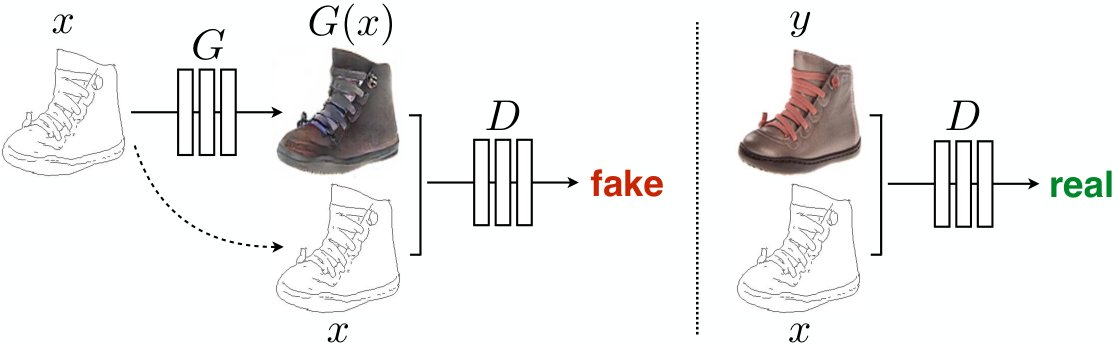
Figure 2: Training a conditional GAN to map edgesphoto. The discriminator, , learns to classify between fake (synthesized by the generator) and real {edge, photo} tuples. The generator, , learns to fool the discriminator. Unlike an unconditional GAN, both the generator and discriminator observe the input edge map.
图2:培训有条件的GAN绘制边缘图 照片. 歧视者 学会了将假(由生成者合成)和真{对接,照片}Tuples分类. 发电机学会欺骗歧视者。 与无条件的GAN不同,生成者和歧视者都观察输入边缘图.
Conditional GANs We are not the first to apply GANs in the conditional setting. Prior and concurrent works have conditioned GANs on discrete labels [41, 23, 13], text [46], and, indeed, images. The image-conditional models have tackled image prediction from a normal map [55], future frame prediction [40], product photo generation [59], and image generation from sparse annotations [31, 48] (c.f. [47] for an autoregressive approach to the same problem). Several other papers have also used GANs for image-to-image mappings, but only applied the GAN unconditionally, relying on other terms (such as L2 regression) to force the output to be conditioned on the input. These papers have achieved impressive results on inpainting [43], future state prediction [64], image manipulation guided by user constraints [65], style transfer [38], and superresolution [36]. Each of the methods was tailored for a specific application. Our framework differs in that nothing is application-specific. This makes our setup considerably simpler than most others.
** 有条件的加纳** 我们并非第一个在有条件的情况下适用GANs。 先前和同时进行的工程都将GANs设定在离散标签[41、23、13]、文本[46]以及事实上的图像上。 图像条件模型处理的是普通地图的图像预测[55]、未来帧预测[40]、产品照片生成[59],以及从零散的说明31、48中生成图像,以便采用自动递归方法处理同一问题。 另有多篇论文也使用GANs进行图像到图像映射,但仅无条件应用GAN,依靠其他术语(如L2回归)迫使输出以输入为条件. 这些文件在油漆[43],未来状态预测[64],以用户限制为指导的图像操纵[65],样式传输[38]和超级分辨率[36]方面取得了令人印象深刻的成果. 每种方法都适合具体应用。 我们的框架不同,没有任何具体应用。 这使得我们的设置比大多数其它的要简单得多.
Our method also differs from the prior works in several architectural choices for the generator and discriminator. Unlike past work, for our generator we use a “U-Net”-based architecture [50], and for our discriminator we use a convolutional “PatchGAN” classifier, which only penalizes structure at the scale of image patches. A similar PatchGAN architecture was previously proposed in [38] to capture local style statistics. Here we show that this approach is effective on a wider range of problems, and we investigate the effect of changing the patch size.
我们的方法也与先前的作品不同,在几个建筑选择中,发电机和歧视者. 与过去的工作不同,对于我们的生成偃师,我们使用一个基于“U-Net”的架构[50],对于我们的歧义者,我们使用一个演化的“PatchGAN”分类器,它只会在图像补丁的规模上惩罚结构。 之前在[38]中曾提出过类似的PatchGAN架构,以获取本地风格统计. 在这里,我们表明这种方法在更广泛的问题上是有效的,我们调查改变补丁尺寸的影响。
3 Method
3 方法
GANs are generative models that learn a mapping from random noise vector to output image , [24]. In contrast, conditional GANs learn a mapping from observed image and random noise vector , to , . The generator is trained to produce outputs that cannot be distinguished from “real” images by an adversarially trained discriminator, , which is trained to do as well as possible at detecting the generator’s “fakes”. This training procedure is diagrammed in Figure 2.
GANs是遗传模型,从随机噪声矢量到输出图像,[24]学习绘图. 相比之下,有条件的GAN从观测到的图像和随机噪声矢量学习到,. 发电机受过培训,能够产生无法与受过对抗训练的歧视性人的 " 真实 " 图像区分开来的产出。 这一训练流程见图2。
3.1 Objective
3.1 目标函数
The objective of a conditional GAN can be expressed as
有条件的GAN的目标可以表示为:
where tries to minimize this objective against an adversarial that tries to maximize it, i.e. .
第号试图将这一目标最小化于对抗性第号试图将其最大化,即第号。
To test the importance of conditioning the discriminator, we also compare to an unconditional variant in which the discriminator does not observe :
为了检验对歧视者的定性的重要性,我们还比较了一种无条件的变体,即歧视者没有遵守:
Previous approaches have found it beneficial to mix the GAN objective with a more traditional loss, such as L2 distance [43]. The discriminator’s job remains unchanged, but the generator is tasked to not only fool the discriminator but also to be near the ground truth output in an L2 sense. We also explore this option, using L1 distance rather than L2 as L1 encourages less blurring:
以前的做法认为,将GAN目标与L2距离[43]等较传统的损失相混合是有益的。 歧视者的工作没有改变,但生成者的任务不仅是愚弄歧视者,而且还要在L2意义上接近地面的真相输出。 我们还探索这个选项,使用L1距离而不是L2,因为L1鼓励减少模糊:
Our final objective is
我们的最终目标是
Without , the net could still learn a mapping from to , but would produce deterministic outputs, and therefore fail to match any distribution other than a delta function. Past conditional GANs have acknowledged this and provided Gaussian noise as an input to the generator, in addition to (e.g., [55]). In initial experiments, we did not find this strategy effective – the generator simply learned to ignore the noise – which is consistent with Mathieu et al. [40]. Instead, for our final models, we provide noise only in the form of dropout, applied on several layers of our generator at both training and test time. Despite the dropout noise, we observe only minor stochasticity in the output of our nets. Designing conditional GANs that produce highly stochastic output, and thereby capture the full entropy of the conditional distributions they model, is an important question left open by the present work.
没有,网络仍然可以从到学习映射,但会产生决定性的输出,因此无法匹配三角函数以外的任何分布. 过去有条件的GAN已经承认这一点,除了(例如,[55])外,还提供了高斯噪声作为生成器的输入. 在最初的实验中,我们发现这个策略并不有效 — — 发电机只是学会了忽略噪音 — — 这与Mathieu等人(40)是一致的. 相反,对于我们的最后模型来说,我们只以辍学的形式提供噪音,在培训和测试时间都应用在发电机的几层上。 尽管有噪音,但我们看到我们的网的产量只有轻微的杂乱无章。 设计能产生高度弹性输出的有条件的GAN,从而捕捉到它们模型的有条件分布的全 en,是目前作品留下的重要问题.
3.2 Network architectures
3.2 网络架构
We adapt our generator and discriminator architectures from those in [44]. Both generator and discriminator use modules of the form convolution-BatchNorm-ReLu [29]. Details of the architecture are provided in the supplemental materials online, with key features discussed below.
我们从[44]中调整我们的发电机和歧视性建筑。 生成者和歧视者都使用形式convolution-BatchNorm-ReLu[29]的模块. 在线补充材料中提供了该架构的细节,下文将讨论主要特点。
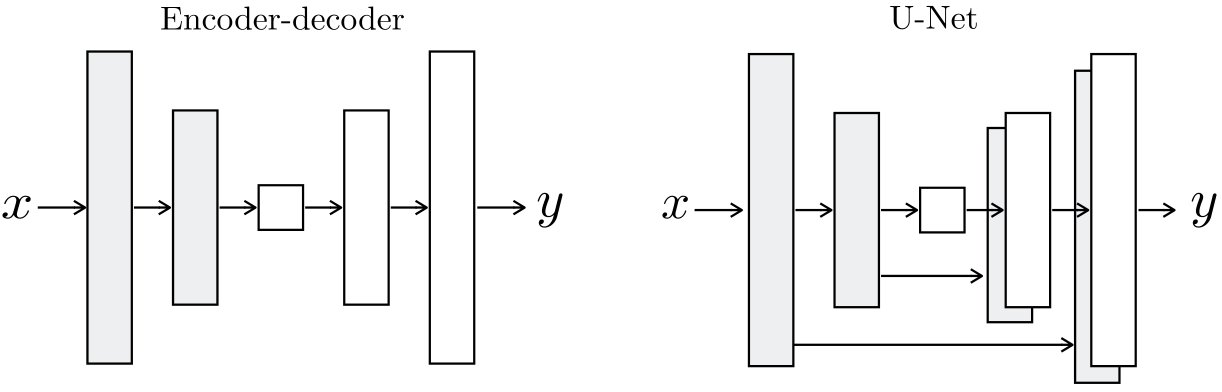
Figure 3: Two choices for the architecture of the generator. The “U-Net” [50] is an encoder-decoder with skip connections between mirrored layers in the encoder and decoder stacks.
图3:生成器结构的两个选择。 “U-Net”[50]是一个编码器-解码器,在编码器和解码器堆栈的镜像层之间有跳过连接。
3.2.1 Generator with skips
A defining feature of image-to-image translation problems is that they map a high resolution input grid to a high resolution output grid. In addition, for the problems we consider, the input and output differ in surface appearance, but both are renderings of the same underlying structure. Therefore, structure in the input is roughly aligned with structure in the output. We design the generator architecture around these considerations.
3.2.1 带有跳跃的发电机
图像到图像翻译问题的一个决定性特征是它们将高分辨率输入网格映射到高分辨率输出网格上. 此外,对于我们所考虑的问题,输入和输出在表面外观上有所不同,但两者都是同样基础结构的渲染. 因此,投入中的结构大致与产出中的结构一致。 我们围绕这些考虑设计了生成器结构。
Many previous solutions [43, 55, 30, 64, 59] to problems in this area have used an encoder-decoder network [26]. In such a network, the input is passed through a series of layers that progressively downsample, until a bottleneck layer, at which point the process is reversed. Such a network requires that all information flow pass through all the layers, including the bottleneck. For many image translation problems, there is a great deal of low-level information shared between the input and output, and it would be desirable to shuttle this information directly across the net. For example, in the case of image colorization, the input and output share the location of prominent edges.
许多先前的解决方案[43,55,30,64,59]都使用了编码器-解码器网络[26]. 在这样的网络中,输入会通过一系列逐渐下降的层层传递,直到瓶颈层,此时过程被逆转. 这种网络要求所有的信息流通过所有层次,包括瓶颈。 对于许多图像翻译问题,输入和输出之间共享了大量的低级信息,最好将这些信息直接穿网穿梭. 例如,在图像色化的情况下,输入和输出共享显著边缘的位置.
To give the generator a means to circumvent the bottleneck for information like this, we add skip connections, following the general shape of a “U-Net” [50]. Specifically, we add skip connections between each layer and layer , where is the total number of layers. Each skip connection simply concatenates all channels at layer with those at layer .
为了让生成器能够绕过这种信息的瓶颈,我们按照“U-Net”的一般形状联合国宪章添加跳过连接[50]。 具体地说,我们增加了每层和每层之间的跳过连接,其中是各层的总数. 每个跳过连接只需将层中的所有通道与层的通道组合起来.
3.2.2 Markovian discriminator (PatchGAN)
It is well known that the L2 loss – and L1, see Figure 4 – produces blurry results on image generation problems [34]. Although these losses fail to encourage high-frequency crispness, in many cases they nonetheless accurately capture the low frequencies. For problems where this is the case, we do not need an entirely new framework to enforce correctness at the low frequencies. L1 will already do.
3.2.2 马尔科维亚歧视者(PatchGAN)
众所周知,L2损失 — — 和L1,见图4 — — 对图像生成问题产生模糊的结果[34]. 虽然这些损失未能鼓励高频脆度,但在许多情况下,它们准确地记录了低频。 对于出现这种情况的问题,我们不需要一个全新的框架来强制低频率的正确性。 L1已经准备好了
This motivates restricting the GAN discriminator to only model high-frequency structure, relying on an L1 term to force low-frequency correctness (Eqn. 4). In order to model high-frequencies, it is sufficient to restrict our attention to the structure in local image patches. Therefore, we design a discriminator architecture – which we term a PatchGAN – that only penalizes structure at the scale of patches. This discriminator tries to classify if each patch in an image is real or fake. We run this discriminator convolutionally across the image, averaging all responses to provide the ultimate output of .
这促使GAN歧视者仅限于模式高频结构,依赖L1术语强制低频正确性(Eqn.4). 为了模型化高频,就足以将我们的注意力限制在局部图像补丁的结构上. 因此,我们设计了一种歧视建筑 — — 我们称之为PatchGAN — — 它只会在补丁的规模上惩罚结构。 这个歧视者试图将图像中的每个补丁都归为真或假. 平均所有反应, 提供的最终产出。
In Section 4.4, we demonstrate that can be much smaller than the full size of the image and still produce high quality results. This is advantageous because a smaller PatchGAN has fewer parameters, runs faster, and can be applied to arbitrarily large images.
在第4.4节中,我们表明,可以大大小于图像的全部尺寸,并且仍然产生高质量的结果。 这是有利的,因为较小的PatchGAN的参数较少,运行速度更快,可以被应用到任意的大型图像上.
Such a discriminator effectively models the image as a Markov random field, assuming independence between pixels separated by more than a patch diameter. This connection was previously explored in [38], and is also the common assumption in models of texture [17, 21] and style [16, 25, 22, 37]. Therefore, our PatchGAN can be understood as a form of texture/style loss.
这种歧义论者有效地将图像模拟为马尔科夫随机场,假设在像素之间以超过补丁直径分隔独立. 以前在[38]中探讨过这种联系,也是纹理[17,21]和样式[16,25,22,37]模型中常见的假设. 因此,我们的PatchGAN可以被理解为一种纹理/风格的丢失.
3.3 Optimization and inference
3.3 优化与推理
To optimize our networks, we follow the standard approach from [24]: we alternate between one gradient descent step on , then one step on . As suggested in the original GAN paper, rather than training to minimize , we instead train to maximize [24]. In addition, we divide the objective by while optimizing , which slows down the rate at which learns relative to . We use minibatch SGD and apply the Adam solver [32], with a learning rate of , and momentum parameters , .
为了优化我们的网络,我们遵循从[24]开始的标准方法:我们在上交替一个梯度下降步骤,然后在上交替一个步骤。 正如最初的GAN文件所建议,我们不是培训以尽量减少,而是培训最大限度地增加[24]。 此外,我们将目标除以,同时优化,使相对于学习的速度放慢. 我们使用小批量SGD并应用亚当解析器[32],学习速率为,动力参数为,.
At inference time, we run the generator net in exactly the same manner as during the training phase. This differs from the usual protocol in that we apply dropout at test time, and we apply batch normalization [29] using the statistics of the test batch, rather than aggregated statistics of the training batch. This approach to batch normalization, when the batch size is set to 1, has been termed “instance normalization” and has been demonstrated to be effective at image generation tasks [54]. In our experiments, we use batch sizes between 1 and 10 depending on the experiment.
推理,我们运行发电机网的方式与培训阶段完全相同。 这与通常的协议不同,因为我们在测试时适用退学,我们利用测试批次的统计,而不是培训批次的汇总统计,实行批归一化[29]. 这种分批归一化的办法,当分批量定为1时,被称为“分批归一化”,并证明对图像生成任务有效[54]。 在我们的实验中,我们根据实验的不同使用1到10之间的批量尺寸.
4 Experiments
4 实验
To explore the generality of conditional GANs, we test the method on a variety of tasks and datasets, including both graphics tasks, like photo generation, and vision tasks, like semantic segmentation:
为了探索有条件的GANs的通用性,我们用多种任务和数据集测试方法,包括图形任务,如照片生成,和视觉任务,如语义分割:
- • Semantic labelsphoto, trained on the Cityscapes dataset [12].
- • Architectural labelsphoto, trained on CMP Facades [45].
- • Mapaerial photo, trained on data scraped from Google Maps.
- • BWcolor photos, trained on [51].
- • Edgesphoto, trained on data from [65] and [60]; binary edges generated using the HED edge detector [58] plus postprocessing.
- • Sketchphoto: tests edgesphoto models on human-drawn sketches from [19].
- • Daynight, trained on [33].
- • Thermalcolor photos, trained on data from [27].
- • Photo with missing pixelsinpainted photo, trained on Paris StreetView from [14].
- 语义标签 照片 *,接受Cityscapes数据集培训[12]。
- Architectural labels 照片,经过关于CMP Facades的培训[45]。
• 地图航空照片,接受从Google地图刮去的数据培训。 - BW 彩色照片,经过[51]培训。
- Edges 照片,培训数据来自[65]和[60];使用HED边缘探测器生成的二进制边[58]+后处理。
- Sketch 照片:测试边缘 照片模型上的人类绘制草图来自[19].
• 第日夜*,接受[33]次训练。 - 热彩色照片,接受来自[27]的数据培训。
· 缺少像素的图片 印有照片,从[14]到巴黎街电视台受训.
Details of training on each of these datasets are provided in the supplemental materials online. In all cases, the input and output are simply 1-3 channel images. Qualitative results are shown in Figures 8, 9, 11, 10, 13, 14, 15, 16, 17, 18, 19, 20. Several failure cases are highlighted in Figure 21. More comprehensive results are available at https://phillipi.github.io/pix2pix/.
关于每个数据集的培训详情见在线补充材料。 在所有情况下,输入和输出只是1-3通道图像. 定性结果见图8、9、11、10、13、14、15、16、17、18、19、20。 图21突出显示一些失败案例。 更全面的结果见https://phillipi.github.io/pix2pix/。
Data requirements and speed We note that decent results can often be obtained even on small datasets. Our facade training set consists of just 400 images (see results in Figure 14), and the day to night training set consists of only 91 unique webcams (see results in Figure 15). On datasets of this size, training can be very fast: for example, the results shown in Figure 14 took less than two hours of training on a single Pascal Titan X GPU. At test time, all models run in well under a second on this GPU.
** 数据要求和速度** 我们注意到,即使是在小型数据集上,也往往能够取得良好结果。 我们的外观训练集只有400个图像(见图14中的结果),日间到夜间训练集只有91个独特的网络摄像头(见图15中的结果). 在这种大小的数据集上,训练可以非常快:例如,图14显示的结果在单个Pascal Titan X GPU上用了不到两个小时的训练. 在测试时间,所有模型 运行在很短的秒 这个GPU。
| Input | Ground truth | L1 | cGAN | L1 + cGAN |
|---|---|---|---|---|
Figure 4: Different losses induce different quality of results. Each column shows results trained under a different loss. Please see https://phillipi.github.io/pix2pix/ for additional examples.
| 投入 | 事实 | L1 | 瞭 语 | L1 + cGAN 常规 |
|---|---|---|---|---|
图4:不同损失导致不同质量的结果。 每栏显示在不同的损失下培训的结果。 请参看https://phillipi.github.io/pix2pix/ 其他例子。
4.1 Evaluation metrics
4.1 评价指标
Evaluating the quality of synthesized images is an open and difficult problem [52]. Traditional metrics such as per-pixel mean-squared error do not assess joint statistics of the result, and therefore do not measure the very structure that structured losses aim to capture.
评估合成图像的质量是一个公开和困难的问题[52]. 传统的度量标准,如每像素平均方差误差,不能评估结果的联合统计,因此不能衡量结构化损失旨在捕捉的结构。
To more holistically evaluate the visual quality of our results, we employ two tactics. First, we run “real vs. fake” perceptual studies on Amazon Mechanical Turk (AMT). For graphics problems like colorization and photo generation, plausibility to a human observer is often the ultimate goal. Therefore, we test our map generation, aerial photo generation, and image colorization using this approach.
为了更全面地评估我们成果的视觉质量,我们采用了两种战术。 首先,我们对亚马逊机械土耳其公司(AMT)进行“真实对假”概念研究。 对于色彩化和照片生成等图形问题,对人类观察者的可信度往往是最终目标. 因此,我们用这种方法测试我们的地图生成、空中照片生成和图像色化。
Second, we measure whether or not our synthesized cityscapes are realistic enough that off-the-shelf recognition system can recognize the objects in them. This metric is similar to the “inception score” from [52], the object detection evaluation in [55], and the “semantic interpretability” measures in [62] and [42].
第二,我们衡量我们合成的城市景观是否现实,以至于现成的识别系统能够识别其中的物体. 这一度量法类似于[52]的"感应分数",[55]中的物体检测评价,[62]和[42]中的"语义解释"度量法.
AMT perceptual studies For our AMT experiments, we followed the protocol from [62]: Turkers were presented with a series of trials that pitted a “real” image against a “fake” image generated by our algorithm. On each trial, each image appeared for 1 second, after which the images disappeared and Turkers were given unlimited time to respond as to which was fake. The first 10 images of each session were practice and Turkers were given feedback. No feedback was provided on the 40 trials of the main experiment. Each session tested just one algorithm at a time, and Turkers were not allowed to complete more than one session. Turkers evaluated each algorithm. Unlike [62], we did not include vigilance trials. For our colorization experiments, the real and fake images were generated from the same grayscale input. For mapaerial photo, the real and fake images were not generated from the same input, in order to make the task more difficult and avoid floor-level results. For mapaerial photo, we trained on resolution images, but exploited fully-convolutional translation (described above) to test on images, which were then downsampled and presented to Turkers at resolution. For colorization, we trained and tested on resolution images and presented the results to Turkers at this same resolution.
** AMT概念研究** 对于我们的AMT实验,我们遵循了[62]: 向突厥人介绍了一系列试验,将“真实的”图像与我们算法产生的“假的”图像进行对比。 在每次审判中,每个图像都出现1秒,之后图像消失,突厥人得到无限时间来回应哪些是假的. 每次会议头10个图像是实践,向土耳其人提供了反馈。 对主要试验的40次试验没有反馈。 每个会话一次只测试一个算法,突厥人不得完成一个以上的会话.Turkers评价了每个算法. 与[62]不同,我们没有包括警戒审判。 在我们的色彩化实验中,真实的和假的图像都是由同样的灰度输入产生的. 对于地图航空照片,真实的和假的图像并不是由相同的输入生成的,以便让任务更加困难,避免下层结果. 对于地图的航空照片,我们接受了关于分辨率图像的培训,但利用了完全革命性翻译(见上文)来测试图像,然后在分辨率上对图像进行下取样并提交突厥人. 为了配色,我们对分辨率图像进行了培训和测试,并在这个分辨率上向土耳其人介绍了结果.
“FCN-score” While quantitative evaluation of generative models is known to be challenging, recent works [52, 55, 62, 42] have tried using pre-trained semantic classifiers to measure the discriminability of the generated stimuli as a pseudo-metric. The intuition is that if the generated images are realistic, classifiers trained on real images will be able to classify the synthesized image correctly as well. To this end, we adopt the popular FCN-8s [39] architecture for semantic segmentation, and train it on the cityscapes dataset. We then score synthesized photos by the classification accuracy against the labels these photos were synthesized from.
** “FCN分数”** 虽然对生成模型的定量评价已知具有挑战性,但近代作品[52,55,62,42]尝试使用预先训练的语义分类器来测量生成的刺激作为伪度量的区别性. 直觉是,如果生成的图像是现实的,在真实图像上受过训练的分类者也能正确分类合成的图像. 为此,我们采用了流行的FCN-8s [39] 语义分割结构,并在城市景观数据集上对其进行培训. 然后我们根据这些照片的标签 分类精度来合成照片
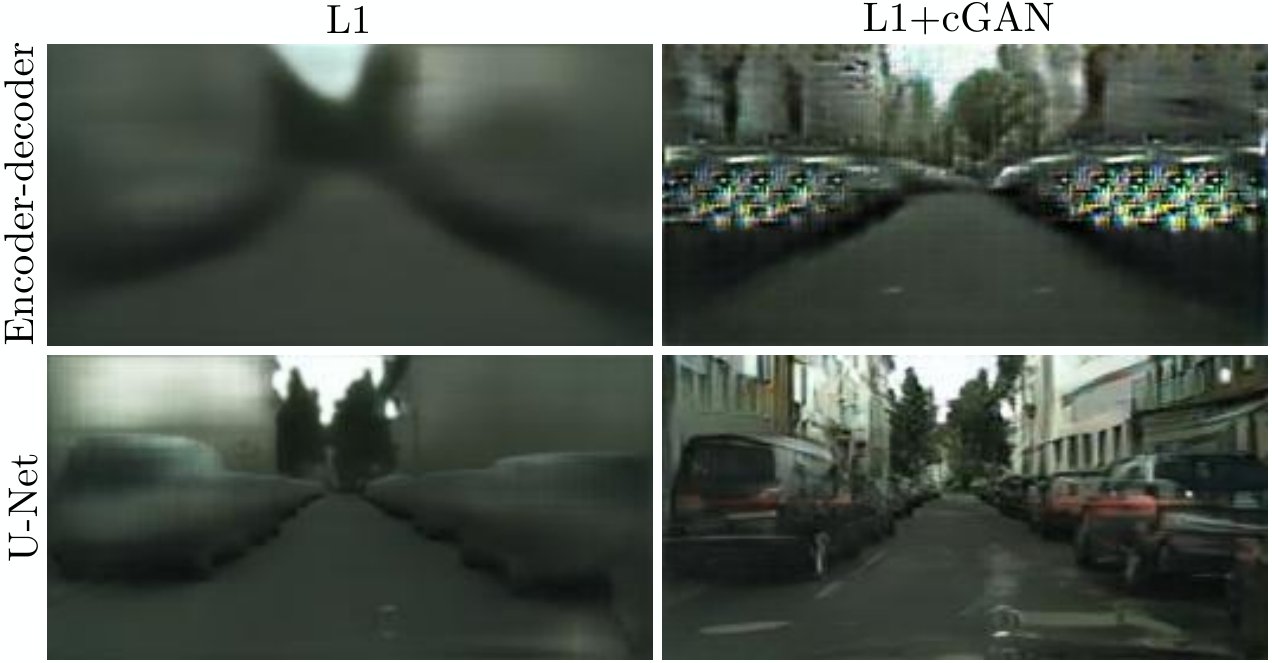
Figure 5: Adding skip connections to an encoder-decoder to create a “U-Net” results in much higher quality results.
的。
| L1 | 11 | 1616 | 7070 | 286286 |
|---|---|---|---|---|
Figure 6: Patch size variations. Uncertainty in the output manifests itself differently for different loss functions. Uncertain regions become blurry and desaturated under L1. The 1x1 PixelGAN encourages greater color diversity but has no effect on spatial statistics. The 16x16 PatchGAN creates locally sharp results, but also leads to tiling artifacts beyond the scale it can observe. The 7070 PatchGAN forces outputs that are sharp, even if incorrect, in both the spatial and spectral (colorfulness) dimensions. The full 286286 ImageGAN produces results that are visually similar to the 7070 PatchGAN, but somewhat lower quality according to our FCN-score metric (Table 3). Please see https://phillipi.github.io/pix2pix/ for additional examples.
| L1 | 11 | 1616 | 7070 | 286286 |
|---|---|---|---|---|
图6:补丁尺寸变化。 产出的不确定性对不同的损失函数的表现不同。 根据L1,不确定的区域变得模糊和不饱和。 1x1像素GAN鼓励更大的颜色多样性,但对空间统计没有影响. 16x16 PatchGAN在局部产生尖锐的效果,但也导致其能观测到的比尺度更大的嵌板文物. 7070 PatchGAN在空间和光谱(颜色)维度上都具有尖锐的输出,即使不正确。 完整的28的指标为286 ImageGAN,其结果在视觉上与70的 70 PatchGAN相似,但根据我们的FCN分数衡量标准,质量略低(表3)。 请参看https://phillipi.github.io/pix2pix/ 其他例子。
| Loss | Per-pixel acc. | Per-class acc. | Class IOU |
|---|---|---|---|
| L1 | 0.42 | 0.15 | 0.11 |
| GAN | 0.22 | 0.05 | 0.01 |
| cGAN | 0.57 | 0.22 | 0.16 |
| L1+GAN | 0.64 | 0.20 | 0.15 |
| L1+cGAN | 0.66 | 0.23 | 0.17 |
| Ground truth | 0.80 | 0.26 | 0.21 |
Table 1: FCN-scores for different losses, evaluated on Cityscapes labelsphotos.
| ** 损失** | 页:1 | 页:1 | ** 类别 |
|---|---|---|---|
| ** L1** 翻译: | 0.42 | 0.15 | 0.11 |
| ** 加纳** | 0.22 | 0.05 | 0.01 |
| 页:1 | 0.57 | 0.22 | 0.16 |
| ** L1+GAN** (中文(简体) ). | 0.64 | 0.20 | 0.15 |
| ** L1+cGAN** (单位:千美元) | 页:1 | 页:1 | 0.17 (单位:千美元) |
| 事实真相** | 0.80 | 0.26 | 0.21 |
表1:不同损失的FCN分数,在Cityscapes标签照片上评价.
| Loss | Per-pixel acc. | Per-class acc. | Class IOU |
|---|---|---|---|
| Encoder-decoder (L1) | 0.35 | 0.12 | 0.08 |
| Encoder-decoder (L1+cGAN) | 0.29 | 0.09 | 0.05 |
| U-net (L1) | 0.48 | 0.18 | 0.13 |
| U-net (L1+cGAN) | 0.55 | 0.20 | 0.14 |
Table 2: FCN-scores for different generator architectures (and objectives), evaluated on Cityscapes labelsphotos. (U-net (L1-cGAN) scores differ from those reported in other tables since batch size was 10 for this experiment and 1 for other tables, and random variation between training runs.)
| ** 损失** | 页:1 | 页:1 | ** 类IOU** |
|---|---|---|---|
| ** 编码器-解码札(L1)** | 0.35 | 0.12 | 0.08 |
| ** 编码器-解码器(L1+cGAN)** | 0.29 | 0.09 | 0.05 |
| ** U-net | 0.48 | 0.18 | 0.13 |
| ** U网(L1+cGAN)** | 0.55 (单位:千美元) | 页:1 | 页:1 |
表2:不同生成架构(和目标)的FCN评分,在Cityscapes标签照片上评价. (U视情况(L1-cGAN)的 我叫分数不同于其他表格中报告的分数,因为这次试验的批量尺寸为10分,其他表格为1分,培训运行之间随机变化。 )
| Discriminator | |||
|---|---|---|---|
| receptive field | Per-pixel acc. | Per-class acc. | Class IOU |
| 11 | 0.39 | 0.15 | 0.10 |
| 1616 | 0.65 | 0.21 | 0.17 |
| 7070 | 0.66 | 0.23 | 0.17 |
| 286286 | 0.42 | 0.16 | 0.11 |
Table 3: FCN-scores for different receptive field sizes of the discriminator, evaluated on Cityscapes labelsphotos. Note that input images are pixels and larger receptive fields are padded with zeros.
| ** 歧视者** | |||
|---|---|---|---|
| ** 接受领域** | 页:1 | 页:1 | ** 类别 |
| 11 | 0.39 | 0.15 | 0.10 |
| 1616 | 0.65 | 0.21 | 0.17 (单位:千美元) |
| 7070 | 页:1 | 页:1 | 0.17 (单位:千美元) |
| 286286 | 0.42 | 0.16 | 0.11 |
表 3:可以作为歧视者不同可接受字段大小的FCN分数,在Cityscapes标签照片上评价. 注意输入图像为像素,较大的可接受字段为零加码.
| Histogram intersection | |||
|---|---|---|---|
| against ground truth | |||
| Loss | L | a | b |
| L1 | 0.81 | 0.69 | 0.70 |
| cGAN | 0.87 | 0.74 | 0.84 |
| L1+cGAN | 0.86 | 0.84 | 0.82 |
| PixelGAN | 0.83 | 0.68 | 0.78 |
(a)
| 直方图交叉点 | |||
|---|---|---|---|
| 反之于地判 | |||
| ** 损失** | L | a | b |
| ** L1** 翻译: | 0.81 | 0.69 | 0.70 |
| 页:1 | 页:1 | 0.74 | 页:1 |
| ** L1+cGAN** (单位:千美元) | 0.86 | 页:1 | 0.82 |
| ** 像素GAN** | 0.83 | 0.68 | 0.78 |
(a)
4.2 Analysis of the objective function
4.2 目标函数分析
Which components of the objective in Eqn. 4 are important? We run ablation studies to isolate the effect of the L1 term, the GAN term, and to compare using a discriminator conditioned on the input (cGAN, Eqn. 1) against using an unconditional discriminator (GAN, Eqn. 2).
Eqn.4中的目标的哪些组成部分很重要? 我们进行减肥研究,以隔离L1术语GAN术语的影响,并使用以输入为条件的歧义(cGAN, Eqn. 1)与使用无条件歧义(GAN, Eqn. 2)进行比较.
Figure 4 shows the qualitative effects of these variations on two labelsphoto problems. L1 alone leads to reasonable but blurry results. The cGAN alone (setting in Eqn. 4) gives much sharper results but introduces visual artifacts on certain applications. Adding both terms together (with ) reduces these artifacts.
图4显示了这些变化对两个标签照片问题的质量影响。 L1单导致合理但模糊的结果. 光是cGAN(在Eqn. 4中设定)就会产生更尖锐的结果,但在某些应用上引入了视觉文物. 将这两个术语加在一起(与一起)会减少这些文物.
We quantify these observations using the FCN-score on the cityscapes labelsphoto task (Table 1): the GAN-based objectives achieve higher scores, indicating that the synthesized images include more recognizable structure. We also test the effect of removing conditioning from the discriminator (labeled as GAN). In this case, the loss does not penalize mismatch between the input and output; it only cares that the output look realistic. This variant results in poor performance; examining the results reveals that the generator collapsed into producing nearly the exact same output regardless of input photograph. Clearly, it is important, in this case, that the loss measure the quality of the match between input and output, and indeed cGAN performs much better than GAN. Note, however, that adding an L1 term also encourages that the output respect the input, since the L1 loss penalizes the distance between ground truth outputs, which correctly match the input, and synthesized outputs, which may not. Correspondingly, L1+GAN is also effective at creating realistic renderings that respect the input label maps. Combining all terms, L1+cGAN, performs similarly well.
我们使用市景标注照片任务的FCN分数来量化这些观测结果(表1):基于GAN的目标实现更高的分数,表明合成的图像包含更可识别的结构. 我们还测试从歧视者身上去除条件的效果(标记为GAN). 在这种情况下,损失并不惩罚输入和输出之间的不匹配;它只关心输出看起来是现实的. 这种变体导致性能不佳;对结果的审查显示,发电机崩溃后产生几乎完全相同的输出,不管输入照片如何。 显然,在这种情况下,损失必须衡量输入和输出之间的匹配质量,而事实上,cGAN的表现要好于GAN。 然而,请注意,增加一个L1术语也鼓励产出尊重输入,因为L1损失会惩罚真值输出(与输入正确匹配)与综合输出(可能不会)之间的距离. 相应地,L1+GAN也有效地创造了尊重输入标签地图的现实渲染. 组合所有术语,L1+cGAN,同样表现良好.
Colorfulness A striking effect of conditional GANs is that they produce sharp images, hallucinating spatial structure even where it does not exist in the input label map. One might imagine cGANs have a similar effect on “sharpening” in the spectral dimension – i.e. making images more colorful. Just as L1 will incentivize a blur when it is uncertain where exactly to locate an edge, it will also incentivize an average, grayish color when it is uncertain which of several plausible color values a pixel should take on. Specially, L1 will be minimized by choosing the median of the conditional probability density function over possible colors. An adversarial loss, on the other hand, can in principle become aware that grayish outputs are unrealistic, and encourage matching the true color distribution [24]. In Figure 7, we investigate whether our cGANs actually achieve this effect on the Cityscapes dataset. The plots show the marginal distributions over output color values in Lab color space. The ground truth distributions are shown with a dotted line. It is apparent that L1 leads to a narrower distribution than the ground truth, confirming the hypothesis that L1 encourages average, grayish colors. Using a cGAN, on the other hand, pushes the output distribution closer to the ground truth.
页:1 有条件的GAN的一个惊人效果是它们产生尖锐的图像,即使输入标签图中不存在,也会产生幻觉空间结构. 人们也许可以想象cGANs对光谱维度的“吸附”具有类似的效果,即使图像更加多彩。 正如L1会激励一个模糊的,当它不能确切地定位一个边缘时,它也会激励一个平均的,灰色的颜色,当它不能确定一个像素应该承担的几种可能颜色的值时。 特别是,L1将通过选择条件概率密度函数的中位数而不是可能的颜色来最小化. 另一方面,对抗性的损失原则上可以意识到灰色输出是不现实的,并鼓励匹配真实的颜色分布[24]. 在图7中,我们调查我们的cGAN在Cityscapes数据集上是否真正实现了这种效果. 地图显示Lab彩色空间中输出色值的边际分布. 真值分布以点行显示. 很明显,L1导致比地面真理更窄的分布,证实了L1鼓励平均,灰色的颜色的假设. 另一方面,使用cGAN将输出分布推向更接近地面真相.
4.3 Analysis of the generator architecture
4.3 生成器架构分析
A U-Net architecture allows low-level information to shortcut across the network. Does this lead to better results? Figure 5 and Table 2 compare the U-Net against an encoder-decoder on cityscape generation. The encoder-decoder is created simply by severing the skip connections in the U-Net. The encoder-decoder is unable to learn to generate realistic images in our experiments. The advantages of the U-Net appear not to be specific to conditional GANs: when both U-Net and encoder-decoder are trained with an L1 loss, the U-Net again achieves the superior results.
一个U-Net架构允许低级信息跨网络快捷. 这是否会导致更好的结果? 图5和表2比较了U-Net与城市景观生成的编码器-解码器. 编码器-解码器只是通过切断U-Net中的跳过连接来创建的. 编码器-解码器无法在我们的实验中学习生成现实的图像. U-Net的优点似乎并不特指有条件的GANs:当U-Net和编码器-解码器都以L1损失来训练时,U-Net再次实现了优异的结果.
4.4 From PixelGANs to PatchGANs to ImageGANs
4.4 从 PixelGAN 到 PatchGAN 再到 ImageGAN
We test the effect of varying the patch size of our discriminator receptive fields, from a “PixelGAN” to a full ‘‘ImageGAN”[^1]. Figure 6 shows qualitative results of this analysis and Table 3 quantifies the effects using the FCN-score. Note that elsewhere in this paper, unless specified, all experiments use PatchGANs, and for this section all experiments use an L1+cGAN loss.
我们测试我们歧视者接受字段的补丁大小从“像素GAN”到“像素GAN”[^1]的变化效果。 图6显示了这一分析的定性结果,表3用FCN分数对效果进行了量化。 请注意,本文件其他部分,除非具体说明,所有实验都使用 PatchGANs,对于本节,所有实验都使用L1+cGAN损失.
The PixelGAN has no effect on spatial sharpness but does increase the colorfulness of the results (quantified in Figure 7). For example, the bus in Figure 6 is painted gray when the net is trained with an L1 loss, but becomes red with the PixelGAN loss. Color histogram matching is a common problem in image processing [49], and PixelGANs may be a promising lightweight solution.
PixelGAN对空间锐度没有影响,但确实增加了结果的色彩(在图7中量化). 例如,图6中的公交车在用L1损失行使其训练时被涂成灰色,但随着像素GAN损失而变为红色. 彩色直方图匹配是通过其图像处理常见的问题[49],而像素GANs可能是一个很有希望的轻量级解决方案.
Using a PatchGAN is sufficient to promote sharp outputs, and achieves good FCN-scores, but also leads to tiling artifacts. The PatchGAN alleviates these artifacts and achieves slightly better scores. Scaling beyond this, to the full ImageGAN, does not appear to improve the visual quality of the results, and in fact gets a considerably lower FCN-score (Table 3). This may be because the ImageGAN has many more parameters and greater depth than the PatchGAN, and may be harder to train.
使用 PatchGAN就足以促进锐利的输出,并实现了良好的FCN分数,但也会导致堆积的文物.PatchGAN缓解了这些文物,并取得了略好的分数. 此外,扩展至完整的 ImageGAN,似乎没有提高结果的视觉质量,事实上,FCN得分要低得多(表3)。 这可能是因为ImageGAN比 PatchGAN有更多的参数和更大的深度,并且可能更难训练.
Fully-convolutional translation An advantage of the PatchGAN is that a fixed-size patch discriminator can be applied to arbitrarily large images. We may also apply the generator convolutionally, on larger images than those on which it was trained. We test this on the mapaerial photo task. After training a generator on images, we test it on images. The results in Figure 8 demonstrate the effectiveness of this approach.
** 革命翻译** PatchGAN的一个优点是,固定大小的补丁歧视剂可以应用于任意的大图像. 我们还可以在比它所训练的更大图像上逐步应用发电机。 我们在地图空中摄影任务上测试这个. 经过对一台发电机进行图像的培训,我们在图像上进行了测试. 图8的结果显示了这一办法的有效性。
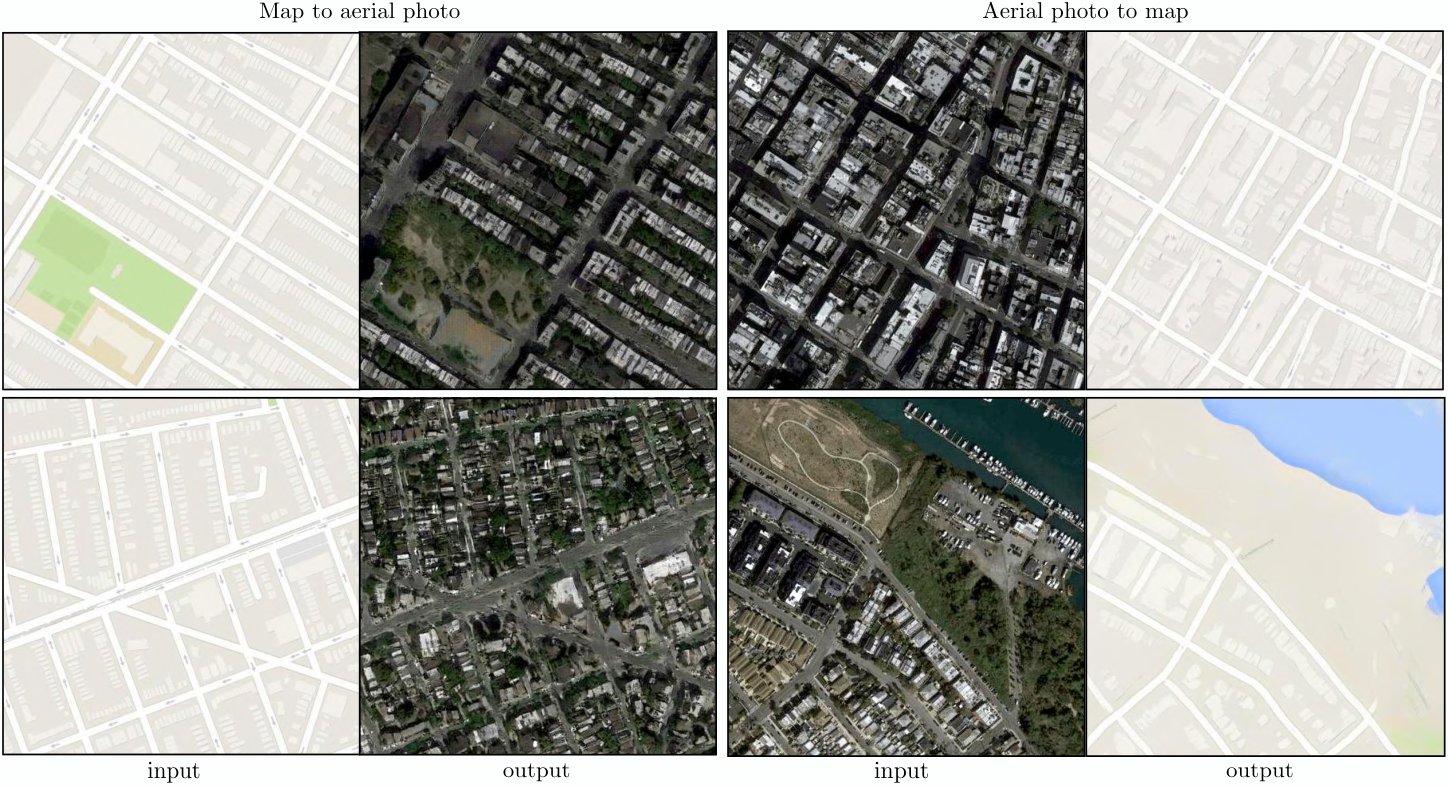
Figure 8: Example results on Google Maps at 512x512 resolution (model was trained on images at resolution, and run convolutionally on the larger images at test time). Contrast adjusted for clarity.
图8:关于Google地图在512x512分辨率上的示例结果(模型在分辨率上接受了图像培训,并在测试时对较大的图像进行演化运行). 为清晰度调整对比度.
| Classification | Ours | ||
|---|---|---|---|
| L2 [62] | (rebal.) [62] | (L1 + cGAN) | Ground truth |
Figure 9: Colorization results of conditional GANs versus the L2 regression from [62] and the full method (classification with rebalancing) from [64]. The cGANs can produce compelling colorizations (first two rows), but have a common failure mode of producing a grayscale or desaturated result (last row).
| 分类 | 我们的 | ||
|---|---|---|---|
| L2 [62] (英语). | (转录) [62] | (L1 + cGAN) (韩语). | 事实 |
图9:有条件的GANs与L2回归的配色结果从[62],全方法(分类与再平衡)从[64]. cGAN可以产生令人信服的色化(前两行),但有一个常见的失败模式,即产生灰度或脱饱和的结果(最后一行).
| Input | Ground truth | L1 | cGAN |
|---|---|---|---|
Figure 10: Applying a conditional GAN to semantic segmentation. The cGAN produces sharp images that look at glance like the ground truth, but in fact include many small, hallucinated objects.
| 投入 | 事实 | L1 | 集中注意 |
|---|---|---|---|
图10 有条件的GAN适用于语义分割. CGAN产生尖锐的图像,视线类似地面真理,但实际上包括许多小的,幻觉的物体.
| Photo Map | Map Photo | |
|---|---|---|
| Loss | % Turkers labeled real | % Turkers labeled real |
| L1 | 2.8% 1.0% | 0.8% 0.3% |
| L1+cGAN | 6.1% 1.3% | 18.9% 2.5% |
Table 4: AMT “real vs fake” test on mapsaerial photos.
| 地图** | 的整个图照片 | |
|---|---|---|
| ** 损失** | 被贴 然后被贴上标签的突厥人百分比 | 被贴 然后被贴上标签的突厥人百分比 |
| ** L1** 翻译: | 2.8% 1.0% | 0.8% 0.3% |
| ** L1+cGAN** (单位:千美元) | 6.1% 1.3% | 18.9% 2.5% |
表4:地图航空照片上的AMT“真实与假”测试。
| Method | % Turkers labeled real |
|---|---|
| L2 regression from [62] | 16.3% 2.4% |
| Zhang et al. 2016 [62] | 27.8% 2.7% |
| Ours | 22.5% 1.6% |
Table 5: AMT “real vs fake” test on colorization.
| ** 方法** | 被贴上标签的突厥人百分比 |
|---|---|
| 的案例[62]的L2回归 | 16.3% 2.4% |
| ** 张等 2016 [62] ** | 27.8% 2.7% |
| ** 我们** | 22.5% 1.6% |
表5 Castle:关于彩色化的AMT“真实再一次”测试。
4.5 Perceptual validation
4.5 感知验证
We validate the perceptual realism of our results on the tasks of mapaerial photograph and grayscalecolor. Results of our AMT experiment for mapphoto are given in Table 4. The aerial photos generated by our method fooled participants on of trials, significantly above the L1 baseline, which produces blurry results and nearly never fooled participants. In contrast, in the photomap direction our method only fooled participants on % of trials, and this was not significantly different than the performance of the L1 baseline (based on bootstrap test). This may be because minor structural errors are more visible in maps, which have rigid geometry, than in aerial photographs, which are more chaotic.
我们验证了我们对地图空中照片和灰度的颜色任务结果的感知现实主义。 地图照片的AMT实验结果见表4。 使用我们的方法制作的空中照片在试验中欺骗了参与者,大大高于L1基线,结果模糊不清,几乎从未愚弄参与者。 相比之下,在照片的地图方向中,我们的方法只在的试验中愚弄了参与者,这与L1基线的性能(基于靴子试验)没有显著区别。 这可能是因为小的结构错误在有刚性几何的地图中比在航空照片中更明显,这些照片更混乱.
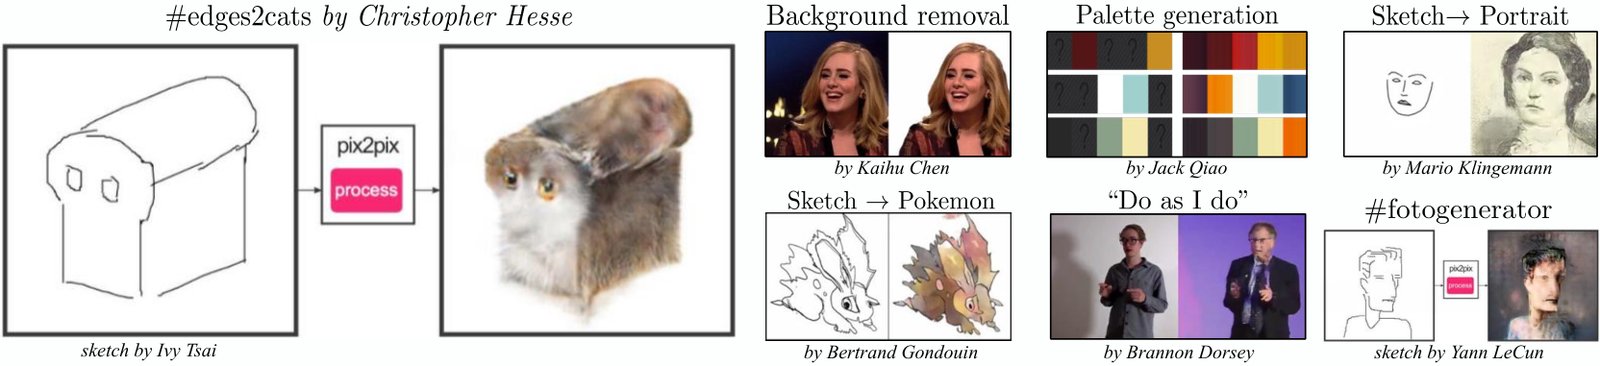
Figure 11: Example applications developed by online community based on our pix2pix codebase: #edges2cats [3] by Christopher Hesse, Background removal [6] by Kaihu Chen, Palette generation [5] by Jack Qiao, Sketch Portrait [7] by Mario Klingemann, Sketch Pokemon [1] by Bertrand Gondouin, “Do As I Do” pose transfer [2] by Brannon Dorsey, and #fotogenerator by Bosman et al. [4].
图11:在线社区根据我们的pix2pix码库开发的示例应用程序: *# *# *# *# *# *# *# *# * * [3] Christopher Christopher Christopher Christopher Christopher Christopher Christopher Christopher Christopher Christopher Christopher Christopher Christopher Christopher Christopher hu hu hu hu Bran Bran *# *# *# *# *# *# *# *# Mario Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand *# Bertrand *# *# *# *# *# *# *# *# *# *# *# *# *# *# Bertrand *# *# *# *# *# *# *# *# Bertrand *# *# *# *# Bertrand *# Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand Bertrand
We trained colorization on ImageNet [51], and tested on the test split introduced by [62, 35]. Our method, with L1+cGAN loss, fooled participants on of trials (Table 5). We also tested the results of [62] and a variant of their method that used an L2 loss (see [62] for details). The conditional GAN scored similarly to the L2 variant of [62] (difference insignificant by bootstrap test), but fell short of [62]’s full method, which fooled participants on of trials in our experiment. We note that their method was specifically engineered to do well on colorization.
我们在ImageNet[51]上训练了彩色化,并在[62,35]引入的测试分法上进行了测试. 由于L1+cGAN的损失,我们的方法在的试验中欺骗了参与者(表5)。 我们还测试了[62]的结果以及使用L2损失(详情见[62])的方法的一个变体。 有条件的GAN的得分与L2变体[62]相似(通过靴子试验,差分微不足道),但是没有达到[62]的全方位方法,这愚弄了我们实验中的的参与者. 我们注意到,他们专门设计的方法是为了在色化方面做得好。
4.6 Semantic segmentation
4.6 语义分割
Conditional GANs appear to be effective on problems where the output is highly detailed or photographic, as is common in image processing and graphics tasks. What about vision problems, like semantic segmentation, where the output is instead less complex than the input?
有条件的GAN似乎在输出高度详细或摄影的问题上有效,这在图像处理和图形任务中很常见. 视觉问题呢,比如语义分割, 输出比输入更不复杂?
To begin to test this, we train a cGAN (with/without L1 loss) on cityscape photolabels. Figure 10 shows qualitative results, and quantitative classification accuracies are reported in Table 6. Interestingly, cGANs, trained without the L1 loss, are able to solve this problem at a reasonable degree of accuracy. To our knowledge, this is the first demonstration of GANs successfully generating ‘‘labels”, which are nearly discrete, rather than ‘‘images”, with their continuous-valued variation[^2]. Although cGANs achieve some success, they are far from the best available method for solving this problem: simply using L1 regression gets better scores than using a cGAN, as shown in Table 6. We argue that for vision problems, the goal (i.e. predicting output close to the ground truth) may be less ambiguous than graphics tasks, and reconstruction losses like L1 are mostly sufficient.
为了开始测试,我们在城市景观照片标签上培训一个cGAN(有/没有L1损失). 图10显示的是定性结果,表6报告了定量分类的速率。 有趣的是,训练有素的cGAN没有L1损失,能够以合理的准确度解决这个问题. 据我们所知,这是GANs成功生成“标签”的首次演示,这些标签几乎是离散的,而不是“图像”及其持续价值的变异[^2]。 虽然cGANs取得了一些成功,但它们远非解决问题的最佳可用方法:简单的使用L1回归得到比使用cGAN更好的分数,如表6所示. 我们主张,对于视觉问题,目标(即预测接近真值的输出)可能比图形任务不那么模糊,像L1这样的重建损失大多足够.
| Loss | Per-pixel acc. | Per-class acc. | Class IOU |
|---|---|---|---|
| L1 | 0.86 | 0.42 | 0.35 |
| cGAN | 0.74 | 0.28 | 0.22 |
| L1+cGAN | 0.83 | 0.36 | 0.29 |
Table 6: Performance of photolabels on cityscapes.
| ** 损失** | 页:1 | 页:1 | ** 类别 |
|---|---|---|---|
| 家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,家,,家,家,的,,家,家,家,家,,,,家,,,,,,,,,,,,,,,,,,的,,,,,,,,,,,,,,,,,,,,,,,,,,,,,的,,,,,,,,,,,,,,,,,,,,,, | ** 0.86 ** (单位:千美元) | 页:1 | 页:1 |
| 页:1 | 0.74 | 0.28 | 0.22 |
| ** L1+cG 等一下,请检查date=中的日期值 (帮助) | 0.83 | 0.36 | 0.29 |
表6:照片标签在城市景观上的性能.
4.7 Community-driven Research
4.7 社区驱动的研究
Since the initial release of the paper and our pix2pix codebase, the Twitter community, including computer vision and graphics practitioners as well as visual artists, have successfully applied our framework to a variety of novel image-to-image translation tasks, far beyond the scope of the original paper. Figure 11 and Figure 12 show just a few examples from the #pix2pix hashtag, including Background removal, Palette generation, Sketch Portrait, SketchPokemon, ”Do as I Do” pose transfer, Learning to see: Gloomy Sunday, as well as the bizarrely popular #edges2cats and #fotogenerator.
自从论文和我们的pix2pix代码库首次发布以来,包括计算机视觉和图形从业者以及视觉艺术家在内的Twitter社区成功地将我们的框架应用于各种新颖的图像到图像翻译任务,远远超出了原始论文的范围. 图11和图12仅显示了#pix2pix标签上的几个例子,包括背景清除,Palette生成,SketchPortrait,SketchPokemon,“做像我做的那样”构成转移,学习看:寒冷的星期日,以及奇异流行的#edges2cats和#fotgenerator.
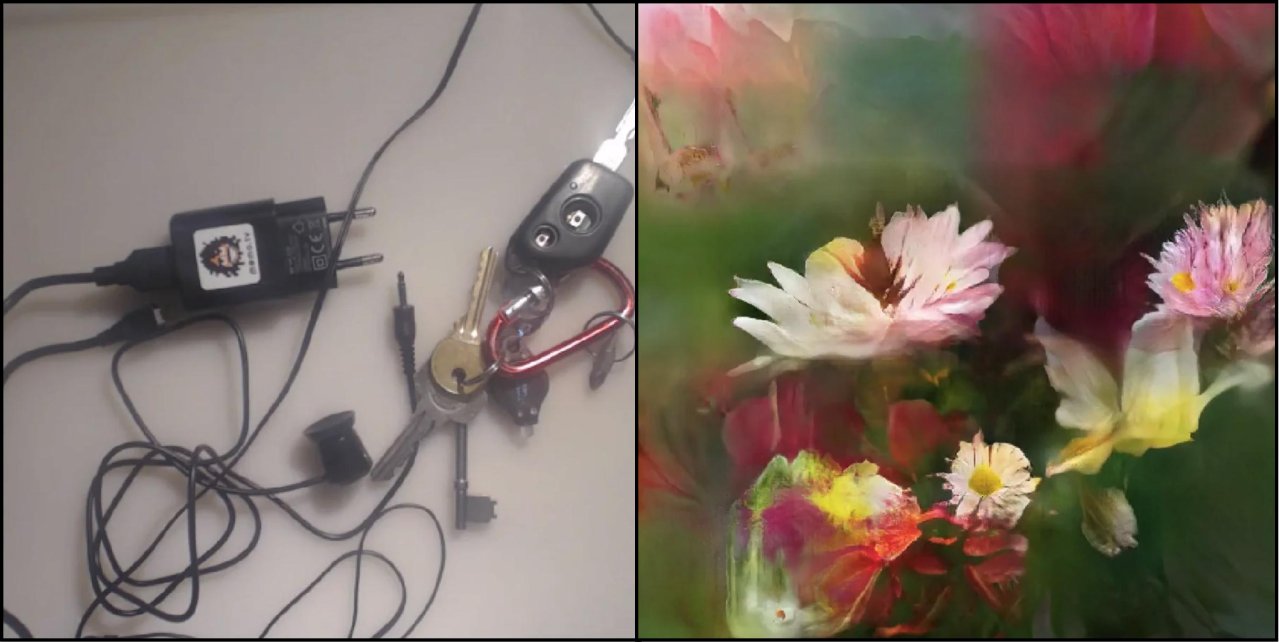
Figure 12: Learning to see: Gloomy Sunday: An interactive artistic demo developed by Memo Akten [8] based on our pix2pix codebase. Please click the image to play the video in a browser.
图12:学习看:寒冷的星期日:Memo Akten[8]根据我们的pix2pix代码库开发的交互式艺术演示. 请点击图像在浏览器中播放视频 。
Note that these applications are creative projects, were not obtained in controlled, scientific conditions, and may rely on some modifications to the pix2pix code we released. Nonetheless, they demonstrate the promise of our approach as a generic commodity tool for image-to-image translation problems.
注意这些应用是创造性的项目,不是在受控的科学条件下获得的,可能依赖于对我们发布的pix2pix代码的一些修改. 然而,它们表明,我们作为图像到图像翻译问题的通用商品工具的做法很有希望。
5 Conclusion
5 结论
The results in this paper suggest that conditional adversarial networks are a promising approach for many image-to-image translation tasks, especially those involving highly structured graphical outputs. These networks learn a loss adapted to the task and data at hand, which makes them applicable in a wide variety of settings.
本文的结果表明,条件对抗性网络对于许多图像到图像的翻译任务来说是一个很有希望的办法,特别是那些涉及高度结构化的图形输出的任务. 这些网络学习了一种适合手头任务和数据的损失,使其适用于各种环境。
Acknowledgments:
We thank Richard Zhang, Deepak Pathak, and Shubham Tulsiani for helpful discussions, Saining Xie for help with the HED edge detector, and the online community for exploring many applications and suggesting improvements. Thanks to Christopher Hesse, Memo Akten, Kaihu Chen, Jack Qiao, Mario Klingemann, Brannon Dorsey, Gerda Bosman, Ivy Tsai, and Yann LeCun for allowing the use of their creations in Figure 11 and Figure 12. This work was supported in part by NSF SMA-1514512, NGA NURI, IARPA via Air Force Research Laboratory, Intel Corp, Berkeley Deep Drive, and hardware donations by Nvidia. J.-Y.Z. is supported by the Facebook Graduate Fellowship. Disclaimer: The views and conclusions contained herein are those of the authors and should not be interpreted as necessarily representing the official policies or endorsements, either expressed or implied, of IARPA, AFRL or the U.S. Government.
承认:
我们感谢理查德·张、迪帕克·帕塔克和舒卜哈姆·图尔西安尼进行了有益的讨论、赛宁谢为HED边缘探测器提供了帮助,并感谢在线社区探索了许多应用并提出改进建议。 感谢克里斯托主持了克里斯托弗·黑森,梅莫·阿克滕,陈凯虎,杰克·邱,马里奥·克林格曼,布兰农·多尔西,格尔达·博斯曼,艾薇·蔡,以及延恩·勒昆允许使用他们在图11和图12中的创作. 这项工作部分得到了NSF SMA-1514512,NGA NURI,IARPA通过空军研究实验室,英特尔公司,伯克利深驱动器,以及Nvidia的硬件捐赠的支持. J.-Y.Z.得到Facebook研究生研究金的支持。 免责声明:本文所载观点和结论是作者的观点和结论,不应被解释为必然代表IARPA、AFRL或美国政府表示或暗示的官方政策或认可。
| Input | Ground truth | Output | Input | Ground truth | Output |
|---|---|---|---|---|---|
Figure 13: Example results of our method on Cityscapes labelsphoto, compared to ground truth.
| 投入 | 事实 | 产出 | 投入 | 事实 | 产出 |
|---|---|---|---|---|---|
图13:我们的方法在Cityscapes标签上取得的例子结果 照片,与地面真相比较.
| Input | Ground truth | Output | Input | Ground truth | Output |
|---|---|---|---|---|---|
Figure 14: Example results of our method on facades labelsphoto, compared to ground truth.
| o 投入 | 事实 | 产出 | 投入 | 事实 | 产出 |
|---|---|---|---|---|---|
图14:我们的方法在外观标签上的示例结果 照片,与地面真相相比.
| Input | Ground truth | Output | Input | Ground truth | Output |
|---|---|---|---|---|---|
Figure 15: Example results of our method on daynight, compared to ground truth.
| 投入 | 事实 | 产出 | 投入 | 事实 | 产出 |
|---|---|---|---|---|---|
图15:日间晚间我们的方法与地面真相比较的示例结果.
| Input | Ground truth | Output | Input | Ground truth | Output |
|---|---|---|---|---|---|
Figure 16: Example results of our method on automatically detected edgeshandbags, compared to ground truth.
| 茁壮精神 | 事实 | 产出 | 投入 | 事实 | 产出 |
|---|---|---|---|---|---|
图16:我们的方法在鳖
| Input | Ground truth | Output | Input | Ground truth | Output |
|---|---|---|---|---|---|
Figure 17: Example results of our method on automatically detected edgesshoes, compared to ground truth.
| 投入 | 事实 | 产出 | 60. 投入 | 事实 | 产出 |
|---|---|---|---|---|---|
图17:我们的方法在自动检测到的鞋缘上,与真值性相比的示例结果.
| Input | Output | Input | Output | Input | Output |
|---|---|---|---|---|---|
Figure 18: Additional results of the edgesphoto models applied to human-drawn sketches from [19]. Note that the models were trained on automatically detected edges, but generalize to human drawings
| 投入 | 产出 | 投入 | 产出 | 投入 | 产出 |
|---|---|---|---|---|---|
图18:从[19] 我们应该用到人类绘画草图的 XMATH0XX 边缘照片模型的额外结果. 注意这些模型是用自动检测到的边缘来训练的,但一般化于人类的图画
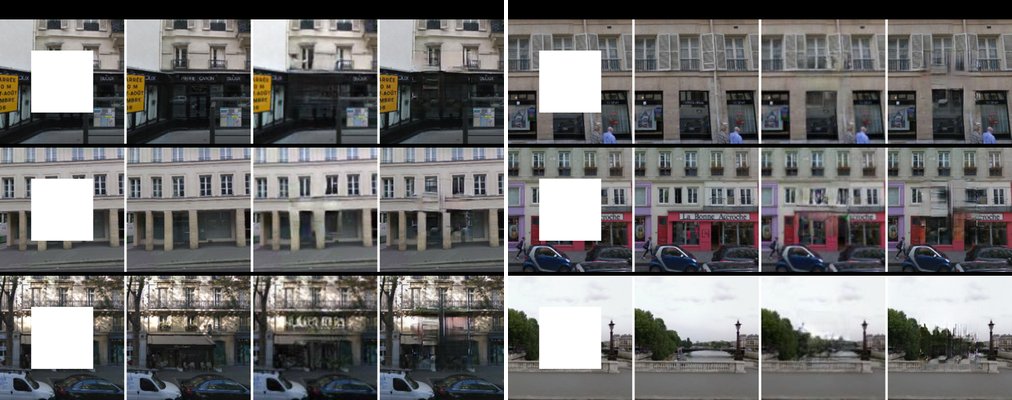
Figure 19: Example results on photo inpainting, compared to [43], on the Paris StreetView dataset [14]. This experiment demonstrates that the U-net architecture can be effective even when the predicted pixels are not geometrically aligned with the information in the input – the information used to fill in the central hole has to be found in the periphery of these photos.
图19:巴黎街View数据集图片涂装的示例结果,与[43]相比[14]. 这个实验表明,即使预测的像素与输入中的信息不几何对齐,U-net架构也能有效——填充中央孔的信息必须在这些照片的外围找到.
| Input | Ground truth | Output | Input | Ground truth | Output |
|---|---|---|---|---|---|
Figure 20: Example results on translating thermal images to RGB photos, on the dataset from [27].
| 投入 | 事实 | 产出 | 投入 | 事实 | 产出 |
|---|---|---|---|---|---|
图20:将热图像转换成RGB照片的示例结果,数据集为[27].
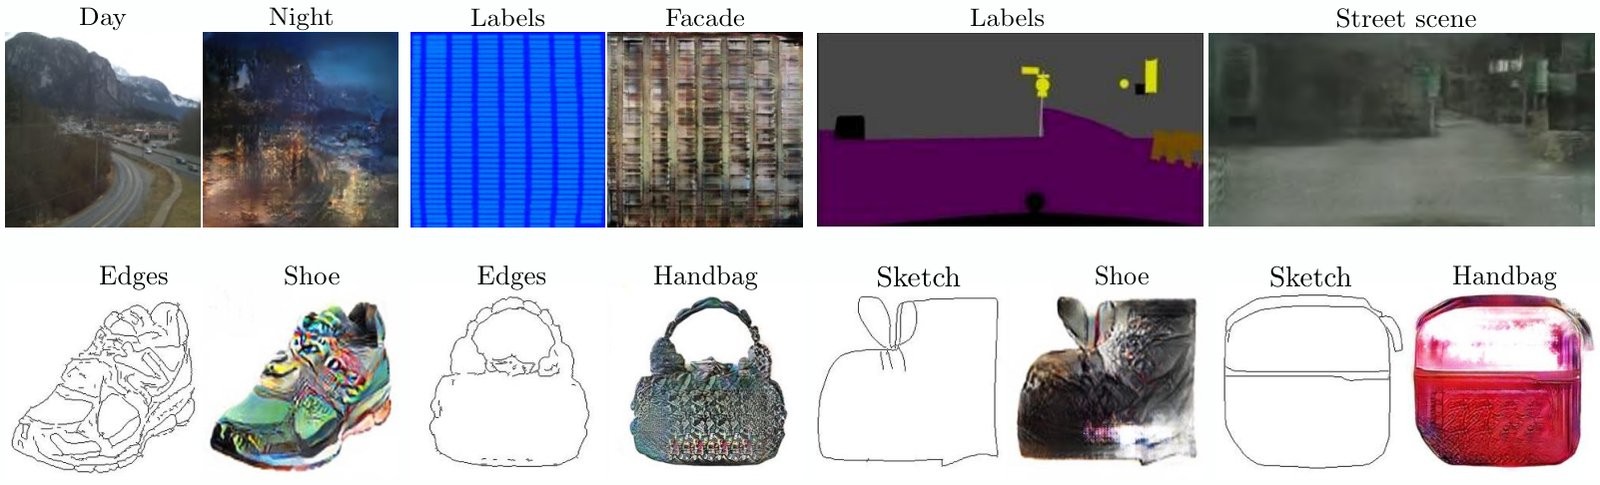
Figure 21: Example failure cases. Each pair of images shows input on the left and output on the right. These examples are selected as some of the worst results on our tasks. Common failures include artifacts in regions where the input image is sparse, and difficulty in handling unusual inputs. Please see https://phillipi.github.io/pix2pix/ for more comprehensive results.
图21:失败案例实例。 每对图像显示左侧输入,右侧输出. 这些例子被选作我们任务中最糟糕的一些结果。 常见的失败包括输入图像稀少地区的文物,以及处理异常输入的困难. 请参看https://phillipi.github.io/pix2pix/,了解更全面的结果.
References
参考文献
(1) Bertrand gondouin. https://twitter.com/bgondouin/status/818571935529377792 . Accessed, 2017-04-21.
(2) Brannon dorsey. https://twitter.com/brannondorsey/status/806283494041223168 . Accessed, 2017-04-21.
(3) Christopher hesse. https://affinelayer.com/pixsrv/ . Accessed: 2017-04-21.
(4) Gerda bosman, tom kenter, rolf jagerman, and daan gosman. https://dekennisvannu.nl/site/artikel/Help-ons-kunstmatige-intelligentie-testen/9163 . Accessed: 2017-08-31.
(5) Jack qiao. http://colormind.io/blog/ . Accessed: 2017-04-21.
(6) Kaihu chen. http://www.terraai.org/imageops/index.html . Accessed, 2017-04-21.
(7) Mario klingemann. https://twitter.com/quasimondo/status/826065030944870400 . Accessed, 2017-04-21.
(8) Memo akten. https://vimeo.com/260612034 . Accessed, 2018-11-07.
(9) A. Buades, B. Coll, and J.-M. Morel. A non-local algorithm for image denoising. In CVPR , 2005.
(10) L.-C. Chen, G. Papandreou, I. Kokkinos, K. Murphy, and A. L. Yuille. Semantic image segmentation with deep convolutional nets and fully connected crfs. In ICLR , 2015.
(11) T. Chen, M.-M. Cheng, P. Tan, A. Shamir, and S.-M. Hu. Sketch2photo: internet image montage. ACM Transactions on Graphics (TOG) , 28(5):124, 2009.
(12) M. Cordts, M. Omran, S. Ramos, T. Rehfeld, M. Enzweiler, R. Benenson, U. Franke, S. Roth, and B. Schiele. The cityscapes dataset for semantic urban scene understanding. In CVPR , 2016.
(13) E. Denton, S. Chintala, A. Szlam, and R. Fergus. Deep generative image models using a laplacian pyramid of adversarial networks. In NIPS , 2015.
(14) C. Doersch, S. Singh, A. Gupta, J. Sivic, and A. Efros. What makes paris look like paris? ACM Transactions on Graphics , 31(4), 2012.
(15) A. Dosovitskiy and T. Brox. Generating images with perceptual similarity metrics based on deep networks. In NIPS , 2016.
(16) A. A. Efros and W. T. Freeman. Image quilting for texture synthesis and transfer. In SIGGRAPH , 2001.
(17) A. A. Efros and T. K. Leung. Texture synthesis by non-parametric sampling. In ICCV , 1999.
(18) D. Eigen and R. Fergus. Predicting depth, surface normals and semantic labels with a common multi-scale convolutional architecture. In ICCV , 2015.
(19) M. Eitz, J. Hays, and M. Alexa. How do humans sketch objects? In SIGGRAPH , 2012.
(20) R. Fergus, B. Singh, A. Hertzmann, S. T. Roweis, and W. T. Freeman. Removing camera shake from a single photograph. ACM Transactions on Graphics (TOG) , 25(3):787–794, 2006.
(21) L. A. Gatys, A. S. Ecker, and M. Bethge. Texture synthesis using convolutional neural networks. In NIPS , 2015.
(22) L. A. Gatys, A. S. Ecker, and M. Bethge. Image style transfer using convolutional neural networks. CVPR , 2016.
(23) J. Gauthier. Conditional generative adversarial nets for convolutional face generation. Class Project for Stanford CS231N: Convolutional Neural Networks for Visual Recognition, Winter semester , (5):2, 2014.
(24) I. Goodfellow, J. Pouget-Abadie, M. Mirza, B. Xu, D. Warde-Farley, S. Ozair, A. Courville, and Y. Bengio. Generative adversarial nets. In NIPS , 2014.
(25) A. Hertzmann, C. E. Jacobs, N. Oliver, B. Curless, and D. H. Salesin. Image analogies. In SIGGRAPH , 2001.
(26) G. E. Hinton and R. R. Salakhutdinov. Reducing the dimensionality of data with neural networks. Science , 313(5786):504–507, 2006.
(27) S. Hwang, J. Park, N. Kim, Y. Choi, and I. So Kweon. Multispectral pedestrian detection: Benchmark dataset and baseline. In CVPR , 2015.
(28) S. Iizuka, E. Simo-Serra, and H. Ishikawa. Let there be Color!: Joint End-to-end Learning of Global and Local Image Priors for Automatic Image Colorization with Simultaneous Classification. ACM Transactions on Graphics (TOG) , 35(4), 2016.
(29) S. Ioffe and C. Szegedy. Batch normalization: Accelerating deep network training by reducing internal covariate shift. In ICML , 2015.
(30) J. Johnson, A. Alahi, and L. Fei-Fei. Perceptual losses for real-time style transfer and super-resolution. In ECCV , 2016.
(31) L. Karacan, Z. Akata, A. Erdem, and E. Erdem. Learning to generate images of outdoor scenes from attributes and semantic layouts. arXiv preprint arXiv:1612.00215 , 2016.
(32) D. Kingma and J. Ba. Adam: A method for stochastic optimization. ICLR , 2015.
(33) P.-Y. Laffont, Z. Ren, X. Tao, C. Qian, and J. Hays. Transient attributes for high-level understanding and editing of outdoor scenes. ACM Transactions on Graphics (TOG) , 33(4):149, 2014.
(34) A. B. L. Larsen, S. K. Sønderby, and O. Winther. Autoencoding beyond pixels using a learned similarity metric. In ICML , 2016.
(35) G. Larsson, M. Maire, and G. Shakhnarovich. Learning representations for automatic colorization. ECCV , 2016.
(36) C. Ledig, L. Theis, F. Huszar, J. Caballero, A. Aitken, A. Tejani, J. Totz, Z. Wang, and W. Shi. Photo-realistic single image super-resolution using a generative adversarial network. In CVPR , 2017.
(37) C. Li and M. Wand. Combining markov random fields and convolutional neural networks for image synthesis. CVPR , 2016.
(38) C. Li and M. Wand. Precomputed real-time texture synthesis with markovian generative adversarial networks. ECCV , 2016.
(39) J. Long, E. Shelhamer, and T. Darrell. Fully convolutional networks for semantic segmentation. In CVPR , 2015.
(40) M. Mathieu, C. Couprie, and Y. LeCun. Deep multi-scale video prediction beyond mean square error. ICLR , 2016.
(41) M. Mirza and S. Osindero. Conditional generative adversarial nets. arXiv preprint arXiv:1411.1784 , 2014.
(42) A. Owens, P. Isola, J. McDermott, A. Torralba, E. H. Adelson, and W. T. Freeman. Visually indicated sounds. In CVPR , 2016.
(43) D. Pathak, P. Krahenbuhl, J. Donahue, T. Darrell, and A. A. Efros. Context encoders: Feature learning by inpainting. In CVPR , 2016.
(44) A. Radford, L. Metz, and S. Chintala. Unsupervised representation learning with deep convolutional generative adversarial networks. In ICLR , 2016.
(45) R. Š. Radim Tyleček. Spatial pattern templates for recognition of objects with regular structure. In German Conference on Pattern Recognition , 2013.
(46) S. Reed, Z. Akata, X. Yan, L. Logeswaran, B. Schiele, and H. Lee. Generative adversarial text to image synthesis. In ICML , 2016.
(47) S. Reed, A. van den Oord, N. Kalchbrenner, V. Bapst, M. Botvinick, and N. de Freitas. Generating interpretable images with controllable structure. In ICLR Workshop , 2017.
(48) S. E. Reed, Z. Akata, S. Mohan, S. Tenka, B. Schiele, and H. Lee. Learning what and where to draw. In NIPS , 2016.
(49) E. Reinhard, M. Ashikhmin, B. Gooch, and P. Shirley. Color transfer between images. IEEE Computer Graphics and Applications , 21:34–41, 2001.
(50) O. Ronneberger, P. Fischer, and T. Brox. U-net: Convolutional networks for biomedical image segmentation. In MICCAI , 2015.
(51) O. Russakovsky, J. Deng, H. Su, J. Krause, S. Satheesh, S. Ma, Z. Huang, A. Karpathy, A. Khosla, M. Bernstein, et al. Imagenet large scale visual recognition challenge. International Journal of Computer Vision , 115(3):211–252, 2015.
(52) T. Salimans, I. Goodfellow, W. Zaremba, V. Cheung, A. Radford, and X. Chen. Improved techniques for training gans. In NIPS , 2016.
(53) Y. Shih, S. Paris, F. Durand, and W. T. Freeman. Data-driven hallucination of different times of day from a single outdoor photo. ACM Transactions on Graphics (TOG) , 32(6):200, 2013.
(54) D. Ulyanov, A. Vedaldi, and V. Lempitsky. Instance normalization: The missing ingredient for fast stylization. arXiv preprint arXiv:1607.08022 , 2016.
(55) X. Wang and A. Gupta. Generative image modeling using style and structure adversarial networks. In ECCV , 2016.
(56) Z. Wang, A. C. Bovik, H. R. Sheikh, and E. P. Simoncelli. Image quality assessment: from error visibility to structural similarity. IEEE Transactions on Image Processing , 13(4):600–612, 2004.
(57) S. Xie, X. Huang, and Z. Tu. Top-down learning for structured labeling with convolutional pseudoprior. In ECCV , 2015.
(58) S. Xie and Z. Tu. Holistically-nested edge detection. In ICCV , 2015.
(59) D. Yoo, N. Kim, S. Park, A. S. Paek, and I. S. Kweon. Pixel-level domain transfer. ECCV , 2016.
(60) A. Yu and K. Grauman. Fine-Grained Visual Comparisons with Local Learning. In CVPR , 2014.
(61) A. Yu and K. Grauman. Fine-grained visual comparisons with local learning. In CVPR , 2014.
(62) R. Zhang, P. Isola, and A. A. Efros. Colorful image colorization. ECCV , 2016.
(63) J. Zhao, M. Mathieu, and Y. LeCun. Energy-based generative adversarial network. In ICLR , 2017.
(64) Y. Zhou and T. L. Berg. Learning temporal transformations from time-lapse videos. In ECCV , 2016.
(65) J.-Y. Zhu, P. Krähenbühl, E. Shechtman, and A. A. Efros. Generative visual manipulation on the natural image manifold. In ECCV , 2016.
6 Appendix
6 附录
6.1 Network architectures
6.1 网络架构
We adapt our network architectures from those in [44]. Code for the models is available at https://github.com/phillipi/pix2pix.
我们从[44]中调整我们的网络结构。 这些模型的代码见https://github.com/phillipi/pix2pix。
Let Ck denote a Convolution-BatchNorm-ReLU layer with k filters. CDk denotes a Convolution-BatchNorm-Dropout-ReLU layer with a dropout rate of . All convolutions are spatial filters applied with stride 2. Convolutions in the encoder, and in the discriminator, downsample by a factor of 2, whereas in the decoder they upsample by a factor of 2.
让 Ck 表示带有 k 过滤器的 Convolution-BatchNorm-ReLU 层 。 CDk表示一个Convolution-BatchNorm-Dropout-ReLU层,辍学率为. 所有演化器都是应用有步态2的空间滤波器. 编码器中的革命,以及歧视器中的革命,以2为因数,而解码器中的革命,则以2为因数。
6.1.1 Generator architectures
The encoder-decoder architecture consists of: **encoder:**C64-C128-C256-C512-C512-C512-C512-C512 **decoder:**CD512-CD512-CD512-C512-C256-C128-C64
6.1.1 生成器结构
编码器-解码器架构包括:编码器:C64-C128-C256-C512-C512-C512-C512-C512编码器:CD512-CD512-CD512-C512-C25-C128-C64
After the last layer in the decoder, a convolution is applied to map to the number of output channels (3 in general, except in colorization, where it is 2), followed by a Tanh function. As an exception to the above notation, BatchNorm is not applied to the first C64 layer in the encoder. All ReLUs in the encoder are leaky, with slope 0.2, while ReLUs in the decoder are not leaky.
在解码器的最后一层之后,对输出通道的数量进行映射(一般为3个,除色化,是2个),然后是Tanh函数. 作为上述注解的例外,BatchNorm不适用于编码器中的第一个C64层. 编码器中的所有ReLU都是漏气的,坡度0.2,而解码器中的ReLU不是漏气的.
The U-Net architecture is identical except with skip connections between each layer in the encoder and layer in the decoder, where is the total number of layers. The skip connections concatenate activations from layer to layer . This changes the number of channels in the decoder:
U-Net架构完全相同,除了编码器中每层和解码器中之间的跳过连接,其中是层的总数. 跳过连接连结激活从到。 更改解码器中的频道数 :
**U-Net decoder:**CD512-CD1024-CD1024-C1024-C1024-C512 -C256-C128
** U-Net解码器**:CD512-CD1024-CD1024-C1024-C512-C256-C128
6.1.2 Discriminator architectures
The discriminator architecture is: C64-C128-C256-C512
6.1.2 歧视者建筑
歧视者建筑为:C的可能性为:C64-C128-C256-C512
After the last layer, a convolution is applied to map to a 1-dimensional output, followed by a Sigmoid function. As an exception to the above notation, BatchNorm is not applied to the first C64 layer. All ReLUs are leaky, with slope 0.2.
在最后一层之后,一个演化应用到映射到一个1维输出,然后是Sigmoid函数. 作为上述注解的例外,BatchNorm不适用于第一C64层. 所有ReLU都是漏气的,有斜0.2.
All other discriminators follow the same basic architecture, with depth varied to modify the receptive field size:
所有其他歧视者都遵循同样的基本结构,深度各异,以修改可接受的字段大小:
discriminator: C64-C128 (note, in this special case, all convolutions are spatial filters) discriminator: C64-C128 discriminator: C64-C128-C256-C512-C512-C512
歧视者: C64-C128(注意,在此特殊情况下,所有演化都是空间滤波器)歧视者: C64-C128歧视者: C64-C128-C256-C512-C512
6.2 Training details
6.2 训练细节
Random jitter was applied by resizing the input images to and then randomly cropping back to size .
通过将输入图像的大小调整为,然后随机裁剪回大小的大小来应用随机快感.
All networks were trained from scratch. Weights were initialized from a Gaussian distribution with mean 0 and standard deviation 0.02.
所有网络都是从零开始训练的。 重量从高斯分布中初始化,平均值为0,标准偏差为0.02.
Cityscapes labelsphoto 2975 training images from the Cityscapes training set [12], trained for 200 epochs, with random jitter and mirroring. We used the Cityscapes validation set for testing. To compare the U-net against an encoder-decoder, we used a batch size of 10, whereas for the objective function experiments we used batch size 1. We find that batch size 1 produces better results for the U-net, but is inappropriate for the encoder-decoder. This is because we apply batchnorm on all layers of our network, and for batch size 1 this operation zeros the activations on the bottleneck layer. The U-net can skip over the bottleneck, but the encoder-decoder cannot, and so the encoder-decoder requires a batch size greater than 1. Note, an alternative strategy is to remove batchnorm from the bottleneck layer. See errata for more details.
Cityscapes标签为照片 来自Cityscapes训练集的2975个训练影像[12],训练对象为200个世纪,随机抖动和镜像. 我们用城市景观验证系统测试 为了比较U网与编码器-解码器,我们使用了10的批量尺寸,而对于目标函数实验,我们使用了1的批量尺寸. 我们发现,批量尺寸1对U网产生更好的效果,但对编码器-解码器是不合适的. 这是因为我们在网络的各个层都应用批量规范,对于批量尺寸1,这个操作将瓶颈层上的激活点零. U网可以跳过瓶颈,但编码器-解码器不能,因此编码器-解码器需要大于1的批量尺寸. 注意,另一种策略是去除瓶颈层的批量规范. 详情请参见worthata。
Architectural labelsphoto 400 training images from [45], trained for 200 epochs, batch size 1, with random jitter and mirroring. Data were split into train and test randomly.
** Architectural labels 照片** 400张训练图像来自[45],为200个时代训练,批量尺寸1,随机抖动和镜像. 数据被分为列车和随机测试.
Mapsaerial photograph 1096 training images scraped from Google Maps, trained for 200 epochs, batch size 1, with random jitter and mirroring. Images were sampled from in and around New York City. Data were then split into train and test about the median latitude of the sampling region (with a buffer region added to ensure that no training pixel appeared in the test set).
Maps 航空照片 1096训练图像从Google地图中刮去,为200个纪元训练,批号1,随机抖动和镜像. 对纽约市内外的图像进行了取样。 随后数据被分为列车和测试关于采样区域中位纬度的数据(同时添加一个缓冲区域以确保测试集中没有出现训练像素).
BWcolor 1.2 million training images (Imagenet training set [51]), trained for epochs, batch size 4, with only mirroring, no random jitter. Tested on subset of Imagenet val set, following protocol of [62] and [35].
BW彩色 120万张训练图像(Imagnet training set [51]),为时代训练,批量尺寸4,只有镜像,没有随机颤动. 在Imagenet val集子集上测试,遵循[62]和[35]的协议.
Edgesshoes 50k training images from UT Zappos50K dataset [61] trained for 15 epochs, batch size 4. Data were split into train and test randomly.
** Edges鞋子** 来自UT Zappos50K数据集的50k训练图像[61] 为15个世纪训练,批量大小为4. 数据被分为列车和随机测试.
EdgesHandbag 137K Amazon Handbag images from [65], trained for 15 epochs, batch size 4. Data were split into train and test randomly.
以及各大块头的图象。 数据被分为列车和随机测试.
Daynight 17823 training images extracted from 91 webcams, from [33] trained for 17 epochs, batch size 4, with random jitter and mirroring. We use 91 webcams as training, and 10 webcams for test.
** Day 夜** 从91个网络相机中提取的17823个训练图像,从[33] 训练17个世纪,批量尺寸4,随机抖动和镜像. 我们使用91个网络摄像头作为训练,10个网络摄像头作为测试.
Thermalcolor photos 36609 training images from set 00–05 of [27], trained for 10 epochs, batch size 4. Images from set 06-11 are used for testing.
热 彩色照片 36609 训练图像,来自[27]的00-05套,为10个纪元训练,批号为4. 06-11集的图像用于测试.
Photo with missing pixelsinpainted photo 14900 training images from [14], trained for 25 epochs, batch size 4, and tested on 100 held out images following the split of [43].
** 图中缺少像素的图像印印照片 ** 14900 训练图像 来自 [14] ,为25个纪元训练,批量尺寸为 4, 并在[43] 拆分后对 100 个固定图像进行测试。
6.3 Errata
6.3 勘误
For all experiments reported in this paper with batch size 1, the activations of the bottleneck layer are zeroed by the batchnorm operation, effectively making the innermost layer skipped. This issue can be fixed by removing batchnorm from this layer, as has been done in the public code. We observe little difference with this change and therefore leave the experiments as is in the paper.
对于本文中报告的具有批量尺寸1的所有实验,瓶颈层的激活被批量规范操作零化,有效使最内层跳过. 正如公共代码中所做的那样,这个问题可以通过从这个层中去掉批号来固定. 我们观察到这一变化没有什么不同,因此不象文件那样进行实验。
6.4 Change log
6.4 变更日志
arXiv v2 Reran generator architecture comparisons (Section 4.3) with batch size equal to 10 rather than 1, so that bottleneck layer is not zeroed (see Errata). Reran FCN-scores with minor details cleaned up (results saved losslessly as pngs, removed unecessary downsampling). FCN-scores computed using scripts at https://github.com/phillipi/pix2pix/tree/ master/scripts/eval_cityscapes, commit d7e7b8b. Updated several figures and text. Added additional results on thermalcolor photos and inpainting, as well as community contributions.
** arXiv v2 ** Reran 生成器架构比较(第4.3节),批量大小等于10而非1,因此瓶颈层不被零化(见Errata). 清理了小细节的Reran FCN-scounts(结果如png一样白白节省,去掉了不必要的下取样). 在https://github.com/phillipi/pix2pix/tree/master/scripts/eval cityscapes上使用脚本计算的FCN-分数,承诺d7e7b8b. 更新了若干数字和文本。 增加了热彩色照片和油漆以及社区贡献方面的额外成果。
arXiv v3 Added additional results on community contributions. Fixed minor typos.
页:1 在社区捐款方面增加了额外成果。 固定小伤寒.