The Perceptron: A Probabilistic Model for Information Storage and Organization in the Brain
Psychological Review, Vol. 65, No. 6, 1958, pp. 386–408
《心理学评论》(Psychological Review),第 65 卷第 6 期,1958 年,第 386–408 页
The Perceptron: A Probabilistic Model for Information Storage and Organization in the Brain¹
感知机:大脑中信息存储与组织的概率模型¹
If we are eventually to understand the capability of higher organisms for perceptual recognition, generalization, recall, and thinking, we must first have answers to three fundamental questions:
- How is information about the physical world sensed, or detected, by the biological system?
- In what form is information stored, or remembered?
- How does information contained in storage, or in memory, influence recognition and behavior?
如果我们最终要理解高等生物在知觉识别、泛化、回忆和思维方面的能力,就必须先回答三个基本问题:
- 关于物理世界的信息是如何被生物系统感知或检测到的?
- 信息以什么形式被存储或记住?
- 存储中或记忆中的信息如何影响识别和行为?
The first of these questions is in the province of sensory physiology, and is the only one for which appreciable understanding has been achieved. This article will be concerned primarily with the second and third questions, which are still subject to a vast amount of speculation, and where the few relevant facts currently supplied by neurophysiology have not yet been integrated into an acceptable theory.
第一个问题属于感觉生理学的领域,也是三个问题中唯一已经取得相当理解的一个。本文主要讨论第二和第三个问题:它们仍有大量推测成分,而神经生理学目前提供的少数相关事实,还没有被整合进一个可以接受的理论。
With regard to the second question, two alternative positions have been maintained. The first suggests that storage of sensory information is in the form of coded representations or images, with some sort of one-to-one mapping between the sensory stimulus and the stored pattern. According to this hypothesis, if one understood the code or "wiring diagram" of the nervous system, one should, in principle, be able to discover exactly what an organism remembers by reconstructing the original sensory patterns from the "memory traces" which they have left, much as we might develop a photographic negative, or translate the pattern of electrical charges in the "memory" of a digital computer. This hypothesis is appealing in its simplicity and ready intelligibility, and a large family of theoretical brain models has been developed around the idea of a coded, representational memory (2, 3, 9, 14). The alternative approach, which stems from the tradition of British empiricism, hazards the guess that the images of stimuli may never really be recorded at all, and that the central nervous system simply acts as an intricate switching network, where retention takes the form of new connections, or pathways, between centers of activity. In many of the more recent developments of this position (Hebb's "cell assembly," and Hull's "cortical anticipatory goal response," for example) the "responses" which are associated to stimuli may be entirely contained within the CNS itself. In this case the response represents an "idea" rather than an action. The important feature of this approach is that there is never any simple mapping of the stimulus into memory, according to some code which would permit its later reconstruction. Whatever information is retained must somehow be stored as a preference for a particular response; i.e., the information is contained in connections or associations rather than topographic representations. (The term response, for the remainder of this presentation, should be understood to mean any distinguishable state of the organism, which may or may not involve externally detectable muscular activity. The activation of some nucleus of cells in the central nervous system, for example, can constitute a response, according to this definition.)
关于第二个问题,存在两种对立的立场。第一种认为,感觉信息以编码表征或图像的形式存储,感觉刺激与所存储的模式之间存在某种一一映射。按照这一假说,如果我们理解了神经系统的编码或“接线图”,原则上就应该能够从感觉模式留下的“记忆痕迹”中重建出原始感觉模式,从而准确发现一个生物记住了什么,就像冲洗一张照相底片,或者解读数字计算机“存储器”中的电荷模式一样。这一假说因其简单易懂而颇具吸引力,围绕编码式、表征式记忆的观念已经发展出一大批理论性的大脑模型(2, 3, 9, 14)。另一种思路源于英国经验主义传统,它大胆推测:刺激的图像也许根本从未被真正记录下来,中枢神经系统只是充当一个复杂的开关网络,记忆的保持表现为各活动中心之间形成新的连接或通路。在这一立场较新的许多发展中(例如赫布的“细胞集合”和赫尔的“皮层预期目标反应”),与刺激相联结的“反应”可能完全包含在中枢神经系统内部。这时,反应代表的是一个“观念”而非一个动作。这种思路的重要特点在于:刺激从来不会按照某种允许日后重建的编码被简单地映射到记忆中。无论保留下什么信息,都必须以对某个特定反应的偏好的形式存储;也就是说,信息包含在连接或联想之中,而不是包含在地形式的表征之中。(在本文余下部分,反应一词应理解为生物的任何可区分状态,它可以涉及、也可以不涉及外部可检测的肌肉活动。按照这一定义,例如中枢神经系统中某个细胞核团的激活,就可以构成一个反应。)
Corresponding to these two positions on the method of information retention, there exist two hypotheses with regard to the third question, the manner in which stored information exerts its influence on current activity. The "coded memory theorists" are forced to conclude that recognition of any stimulus involves the matching or systematic comparison of the contents of storage with incoming sensory patterns, in order to determine whether the current stimulus has been seen before, and to determine the appropriate response from the organism. The theorists in the empiricist tradition, on the other hand, have essentially combined the answer to the third question with their answer to the second: since the stored information takes the form of new connections, or transmission channels in the nervous system (or the creation of conditions which are functionally equivalent to new connections), it follows that the new stimuli will make use of these new pathways which have been created, automatically activating the appropriate response without requiring any separate process for their recognition or identification.
与关于信息保持方式的这两种立场相对应,关于第三个问题,即所存储的信息以何种方式影响当前活动,也存在两种假说。“编码记忆论者”不得不得出这样的结论:对任何刺激的识别,都涉及把存储内容与传入的感觉模式进行匹配或系统比较,以确定当前刺激是否曾经见过,并确定生物应作出的适当反应。另一方面,经验主义传统的理论家基本上把第三个问题的答案与第二个问题的答案合而为一:既然所存储的信息表现为神经系统中新的连接或传输通道(或者形成在功能上等价于新连接的条件),那么新的刺激就会利用这些已经形成的新通路,自动激活适当的反应,而不需要任何单独的识别或辨认过程。
The theory to be presented here takes the empiricist, or "connectionist" position with regard to these questions. The theory has been developed for a hypothetical nervous system, or machine, called a perceptron. The perceptron is designed to illustrate some of the fundamental properties of intelligent systems in general, without becoming too deeply enmeshed in the special, and frequently unknown, conditions which hold for particular biological organisms. The analogy between the perceptron and biological systems should be readily apparent to the reader.
这里要介绍的理论,在这些问题上采取经验主义的或“联结主义”的立场。这一理论是为一种假想的神经系统或机器而发展的,我们称之为感知机(perceptron)。感知机旨在说明一般智能系统的某些基本性质,而不过深地陷入特定生物体所特有的、往往还不为人知的条件之中。感知机与生物系统之间的类比,读者应当一望即知。
During the last few decades, the development of symbolic logic, digital computers, and switching theory has impressed many theorists with the functional similarity between a neuron and the simple on-off units of which computers are constructed, and has provided the analytical methods necessary for representing highly complex logical functions in terms of such elements. The result has been a profusion of brain models which amount simply to logical contrivances for performing particular algorithms (representing "recall," stimulus comparison, transformation, and various kinds of analysis) in response to sequences of stimuli—e.g., Rashevsky (14), McCulloch (10), McCulloch & Pitts (11), Culbertson (2), Kleene (8), and Minsky (13). A relatively small number of theorists, like Ashby (1) and von Neumann (17, 18), have been concerned with the problems of how an imperfect neural network, containing many random connections, can be made to perform reliably those functions which might be represented by idealized wiring diagrams. Unfortunately, the language of symbolic logic and Boolean algebra is less well suited for such investigations. The need for a suitable language for the mathematical analysis of events in systems where only the gross organization can be characterized, and the precise structure is unknown, has led the author to formulate the current model in terms of probability theory rather than symbolic logic.
在过去几十年间,符号逻辑、数字计算机和开关理论的发展,使许多理论家注意到神经元与构成计算机的简单开关单元在功能上的相似性,也提供了用这类元件表示高度复杂的逻辑函数所需的分析方法。其结果是涌现出大量大脑模型,它们只不过是一些逻辑装置,用来针对刺激序列执行特定的算法(代表“回忆”、刺激比较、变换以及各种分析)——例如 Rashevsky (14)、McCulloch (10)、McCulloch & Pitts (11)、Culbertson (2)、Kleene (8) 和 Minsky (13)。只有为数相对较少的理论家,如 Ashby (1) 和冯·诺伊曼 (17, 18),关注过这样的问题:一个含有许多随机连接的不完善神经网络,如何才能可靠地执行那些可以用理想化接线图表示的功能。遗憾的是,符号逻辑和布尔代数的语言不太适合这类研究。对于只能刻画其大体组织、而不知其精确结构的系统,需要一种合适的语言来对其中的事件进行数学分析;正是这一需要,促使作者用概率论而不是符号逻辑来表述现在的模型。
The theorists referred to above were chiefly concerned with the question of how such functions as perception and recall might be achieved by a deterministic physical system of any sort, rather than how this is actually done by the brain. The models which have been produced all fail in some important respects (absence of equipotentiality, lack of neuroeconomy, excessive specificity of connections and synchronization requirements, unrealistic specificity of stimuli sufficient for cell firing, postulation of variables or functional features with no known neurological correlates, etc.) to correspond to a biological system. The proponents of this line of approach have maintained that, once it has been shown how a physical system of any variety might be made to perceive and recognize stimuli, or perform other brainlike functions, it would require only a refinement or modification of existing principles to understand the working of a more realistic nervous system, and to eliminate the shortcomings mentioned above. The writer takes the position, on the other hand, that these shortcomings are such that a mere refinement or improvement of the principles already suggested can never account for biological intelligence; a difference in principle is clearly indicated. The theory of statistical separability (Cf. 15), which is to be summarized here, appears to offer a solution in principle to all of these difficulties.
上面提到的理论家主要关心的是:任何一种确定性的物理系统如何能够实现知觉和回忆这类功能,而不是大脑实际上如何实现它们。已经提出的模型在若干重要方面都无法与生物系统相对应(缺乏等势性,缺乏神经经济性,对连接和同步的要求过于特定,足以使细胞放电的刺激特异性不切实际,假设了没有已知神经学对应物的变量或功能特征,等等)。这一路线的支持者主张:一旦表明了任何一种物理系统如何能被做成感知和识别刺激,或执行其他类脑功能,那么只需对现有原理加以完善或修改,就能理解更真实的神经系统如何工作,并消除上述缺陷。作者则持相反的立场:这些缺陷的性质决定了,仅仅完善或改进已经提出的原理,永远无法解释生物智能;显然需要原理上的不同。这里要概述的统计可分性理论(参见 15),似乎为所有这些困难提供了原理上的解决办法。
Those theorists—Hebb (7), Milner (12), Eccles (4), Hayek (6)—who have been more directly concerned with the biological nervous system and its activity in a natural environment, rather than with formally analogous machines, have generally been less exact in their formulations and far from rigorous in their analysis, so that it is frequently hard to assess whether or not the systems that they describe could actually work in a realistic nervous system, and what the necessary and sufficient conditions might be. Here again, the lack of an analytic language comparable in proficiency to the Boolean algebra of the network analysts has been one of the main obstacles. The contributions of this group should perhaps be considered as suggestions of what to look for and investigate, rather than as finished theoretical systems in their own right. Seen from this viewpoint, the most suggestive work, from the standpoint of the following theory, is that of Hebb and Hayek.
另一些理论家——Hebb (7)、Milner (12)、Eccles (4)、Hayek (6)——更直接地关注生物神经系统及其在自然环境中的活动,而不是形式上类似的机器;他们的表述通常不够精确,分析也远不严格,因此往往很难判断他们所描述的系统能否在真实的神经系统中实际运作,以及其充分必要条件是什么。这里,同样缺乏一种在效能上可与网络分析者的布尔代数相比的分析语言,这是主要障碍之一。这一派的贡献或许应当被看作关于该寻找和研究什么的建议,而不是本身已经完成的理论体系。从这个角度看,就下文的理论而言,最有启发性的工作是赫布和哈耶克的工作。
The position, elaborated by Hebb (7), Hayek (6), Uttley (16), and Ashby (1), in particular, upon which the theory of the perceptron is based, can be summarized by the following assumptions:
The physical connections of the nervous system which are involved in learning and recognition are not identical from one organism to another. At birth, the construction of the most important networks is largely random, subject to a minimum number of genetic constraints.
The original system of connected cells is capable of a certain amount of plasticity; after a period of neural activity, the probability that a stimulus applied to one set of cells will cause a response in some other set is likely to change, due to some relatively long-lasting changes in the neurons themselves.
Through exposure to a large sample of stimuli, those which are most "similar" (in some sense which must be defined in terms of the particular physical system) will tend to form pathways to the same sets of responding cells. Those which are markedly "dissimilar" will tend to develop connections to different sets of responding cells.
The application of positive and/or negative reinforcement (or stimuli which serve this function) may facilitate or hinder whatever formation of connections is currently in progress.
Similarity, in such a system, is represented at some level of the nervous system by a tendency of similar stimuli to activate the same sets of cells. Similarity is not a necessary attribute of particular formal or geometrical classes of stimuli, but depends on the physical organization of the perceiving system, an organization which evolves through interaction with a given environment. The structure of the system, as well as the ecology of the stimulus-environment, will affect, and will largely determine, the classes of "things" into which the perceptual world is divided.
感知机理论所依据的立场,特别是由 Hebb (7)、Hayek (6)、Uttley (16) 和 Ashby (1) 所阐发的立场,可以概括为以下假设:
神经系统中参与学习和识别的物理连接,在不同个体之间并不相同。出生时,最重要的那些网络的构造在很大程度上是随机的,只受到最少量的遗传约束。
最初的相互连接的细胞系统具有一定程度的可塑性;经过一段时间的神经活动后,由于神经元自身发生某些相对持久的变化,施加于一组细胞的刺激在另一组细胞中引起反应的概率很可能发生改变。
在接触大量刺激样本的过程中,那些最“相似”的刺激(其含义须根据特定的物理系统来定义)倾向于形成通向同一组反应细胞的通路;那些明显“不相似”的刺激则倾向于发展出通向不同组反应细胞的连接。
施加正强化和/或负强化(或起这种作用的刺激),可以促进或阻碍当时正在进行的连接形成。
在这样的系统中,相似性在神经系统的某个层次上表现为相似刺激激活同一组细胞的倾向。相似性并不是某些形式类别或几何类别的刺激必然具有的属性,而是取决于感知系统的物理组织,而这种组织是在与给定环境的相互作用中演化出来的。系统的结构以及刺激环境的生态,将影响并在很大程度上决定知觉世界被划分成哪些“事物”类别。
¹ The development of this theory has been carried out at the Cornell Aeronautical Laboratory, Inc., under the sponsorship of the Office of Naval Research, Contract Nonr-2381(00). This article is primarily an adaptation of material reported in Ref. 15, which constitutes the first full report on the program.
¹ 这一理论是在美国海军研究办公室资助下(合同号 Nonr-2381(00)),于康奈尔航空实验室公司完成的。本文主要改编自参考文献 15 中报告的材料,该文献是这一项目的第一份完整报告。
The Organization of a Perceptron
感知机的组织
The organization of a typical photoperceptron (a perceptron responding to optical patterns as stimuli) is shown in Fig. 1. The rules of its organization are as follows:
Stimuli impinge on a retina of sensory units (S-points), which are assumed to respond on an all-or-nothing basis, in some models, or with a pulse amplitude or frequency proportional to the stimulus intensity, in other models. In the models considered here, an all-or-nothing response will be assumed.
Impulses are transmitted to a set of association cells (A-units) in a "projection area" (). This projection area may be omitted in some models, where the retina is connected directly to the association area (). The cells in the projection area each receive a number of connections from the sensory points. The set of S-points transmitting impulses to a particular A-unit will be called the origin points of that A-unit. These origin points may be either excitatory or inhibitory in their effect on the A-unit. If the algebraic sum of excitatory and inhibitory impulse intensities is equal to or greater than the threshold () of the A-unit, then the A-unit fires, again on an all-or-nothing basis (or, in some models, which will not be considered here, with a frequency which depends on the net value of the impulses received). The origin points of the A-units in the projection area tend to be clustered or focalized, about some central point, corresponding to each A-unit. The number of origin points falls off exponentially as the retinal distance from the central point for the A-unit in question increases. (Such a distribution seems to be supported by physiological evidence, and serves an important functional purpose in contour detection.)
Between the projection area and the association area (), connections are assumed to be random. That is, each A-unit in the set receives some number of fibers from origin points in the set, but these origin points are scattered at random throughout the projection area. Apart from their connection distribution, the units are identical with the units, and respond under similar conditions.
The "responses," are cells (or sets of cells) which respond in much the same fashion as the A-units. Each response has a typically large number of origin points located at random in the set. The set of A-units transmitting impulses to a particular response will be called the source-set for that response. (The source-set of a response is identical to its set of origin points in the A-system.) The arrows in Fig. 1 indicate the direction of transmission through the network. Note that up to all connections are forward, and there is no feedback. When we come to the last set of connections, between and the R-units, connections are established in both directions. The rule governing feedback connections, in most models of the perceptron, can be either of the following alternatives:
(a) Each response has excitatory feedback connections to the cells in its own source-set, or
(b) Each response has inhibitory feedback connections to the complement of its own source-set (i.e., it tends to prohibit activity in any association cells which do not transmit to it).
一个典型的光感知机(以光学图案为刺激作出反应的感知机)的组织如图 1 所示。其组织规则如下:
刺激落在由感觉单元(S 点)组成的视网膜上。在某些模型中,假定这些单元以全或无的方式作出反应;在另一些模型中,则以与刺激强度成正比的脉冲幅度或频率作出反应。在这里考虑的模型中,假定为全或无的反应。
冲动被传送到“投射区”()中的一组联想细胞(A 单元)。在某些模型中可以省去这个投射区,让视网膜直接连接到联想区()。投射区中的每个细胞都从感觉点接收若干连接。向某个特定 A 单元传送冲动的那组 S 点,称为该 A 单元的起源点。这些起源点对 A 单元的作用可以是兴奋性的,也可以是抑制性的。如果兴奋性冲动强度与抑制性冲动强度的代数和等于或大于该 A 单元的阈值(),该 A 单元就放电,同样是全或无的(在某些这里不予考虑的模型中,则以取决于所接收冲动净值的频率放电)。投射区中 A 单元的起源点倾向于围绕与每个 A 单元相对应的某个中心点聚集或聚焦。随着与该 A 单元中心点的视网膜距离增大,起源点的数目呈指数下降。(这种分布似乎得到了生理学证据的支持,并在轮廓检测中起着重要的功能作用。)
假定投射区与联想区()之间的连接是随机的。也就是说, 集合中的每个 A 单元从 集合中的起源点接收若干纤维,但这些起源点随机散布在整个投射区。除了连接分布不同外, 单元与 单元完全相同,并在类似的条件下作出反应。
“反应” 是以与 A 单元大致相同的方式作出反应的细胞(或细胞集合)。每个反应通常有大量随机位于 集合中的起源点。向某个特定反应传送冲动的那组 A 单元,称为该反应的源集(source-set)。(一个反应的源集与它在 A 系统中的起源点集合是同一个东西。)图 1 中的箭头表示网络中的传输方向。注意,直到 为止,所有连接都是前向的,没有反馈。到了最后一组连接,即 与 R 单元之间,连接是双向建立的。在大多数感知机模型中,支配反馈连接的规则可以是以下两种之一:
(a) 每个反应对其自身源集中的细胞具有兴奋性反馈连接;或
(b) 每个反应对其自身源集的补集具有抑制性反馈连接(即它倾向于禁止任何不向它传送的联想细胞的活动)。
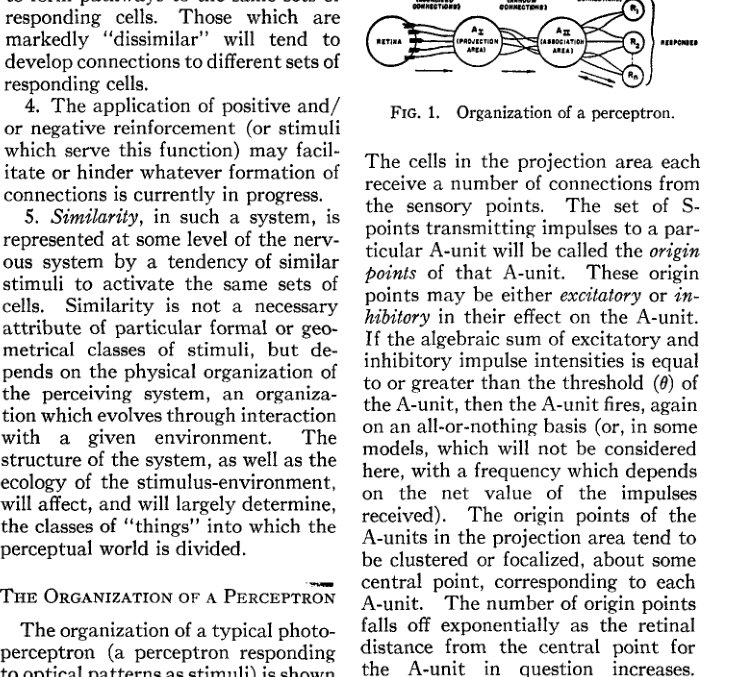
Fig. 1. Organization of a perceptron.
图 1. 感知机的组织。
The first of these rules seems more plausible anatomically, since the R-units might be located in the same cortical area as their respective source-sets, making mutual excitation between the R-units and the A-units of the appropriate source-set highly probable. The alternative rule (b) leads to a more readily analyzed system, however, and will therefore be assumed for most of the systems to be evaluated here.
第一条规则在解剖学上似乎更合理,因为 R 单元可能与各自的源集位于同一皮层区域,从而使 R 单元与相应源集中的 A 单元之间极有可能相互兴奋。不过,另一条规则 (b) 得到的系统更容易分析,因此这里要评估的大多数系统都将采用它。
Fig. 2A. Schematic representation of connections in a simple perceptron.
Fig. 2B. Venn diagram of the same perceptron (shading shows active sets for response).
图 2A. 一个简单感知机中连接的示意图。
图 2B. 同一感知机的维恩图(阴影表示 反应的活动集合)。
Figure 2 shows the organization of a simplified perceptron, which affords a convenient entry into the theory of statistical separability. After the theory has been developed for this simplified model, we will be in a better position to discuss the advantages of the system in Fig. 1. The feedback connections shown in Fig. 2 are inhibitory, and go to the complement of the source-set for the response from which they originate; consequently, this system is organized according to Rule b, above. The system shown here has only three stages, the first association stage having been eliminated. Each A-unit has a set of randomly located origin points in the retina. Such a system will form similarity concepts on the basis of coincident areas of stimuli, rather than by the similarity of contours or outlines. While such a system is at a disadvantage in many discrimination experiments, its capability is still quite impressive, as will be demonstrated presently. The system shown in Fig. 2 has only two responses, but there is clearly no limit on the number that might be included.
图 2 给出一个简化感知机的组织,它为进入统计可分性理论提供了便利的入口。在为这个简化模型建立起理论之后,我们就能更好地讨论图 1 中系统的优点。图 2 所示的反馈连接是抑制性的,通向其起源反应的源集的补集;因此,该系统是按上述规则 b 组织的。这里所示的系统只有三级,第一联想级已被省去。每个 A 单元在视网膜上有一组随机定位的起源点。这样的系统将根据刺激的重合区域而不是轮廓或外形的相似性来形成相似性概念。虽然这样的系统在许多辨别实验中处于不利地位,但它的能力仍然相当可观,下面马上就会说明。图 2 中的系统只有两个反应,但可以包含的反应数目显然没有限制。
The responses in a system organized in this fashion are mutually exclusive. If occurs, it will tend to inhibit , and will also inhibit the source-set for . Likewise, if should occur, it will tend to inhibit . If the total impulse received from all the A-units in one source-set is stronger or more frequent than the impulse received by the alternative (antagonistic) response, then the first response will tend to gain an advantage over the other, and will be the one which occurs. If such a system is to be capable of learning, then it must be possible to modify the A-units or their connections in such a way that stimuli of one class will tend to evoke a stronger impulse in the source-set than in the source-set, while stimuli of another (dissimilar) class will tend to evoke a stronger impulse in the source-set than in the source-set.
按这种方式组织的系统中,各反应是互斥的。如果 出现,它会倾向于抑制 ,并且也会抑制 的源集。同样,如果 出现,它会倾向于抑制 。如果从一个源集中所有 A 单元接收到的总冲动,比另一个(拮抗的)反应所接收到的冲动更强或更频繁,那么前一个反应就会倾向于取得对另一个反应的优势,并成为实际出现的反应。如果这样的系统要能够学习,就必须能够以如下方式修改 A 单元或其连接:使一类刺激倾向于在 的源集中引起比在 的源集中更强的冲动,而另一类(不相似的)刺激倾向于在 的源集中引起比在 的源集中更强的冲动。
It will be assumed that the impulses delivered by each A-unit can be characterized by a value, , which may be an amplitude, frequency, latency, or probability of completing transmission. If an A-unit has a high value, then all of its output impulses are considered to be more effective, more potent, or more likely to arrive at their endbulbs than impulses from an A-unit with a lower value. The value of an A-unit is considered to be a fairly stable characteristic, probably depending on the metabolic condition of the cell and the cell membrane, but it is not absolutely constant. It is assumed that, in general, periods of activity tend to increase a cell's value, while the value may decay (in some models) with inactivity. The most interesting models are those in which cells are assumed to compete for metabolic materials, the more active cells gaining at the expense of the less active cells. In such a system, if there is no activity, all cells will tend to remain in a relatively constant condition, and (regardless of activity) the net value of the system, taken in its entirety, will remain constant at all times. Three types of systems, which differ in their value dynamics, have been investigated quantitatively. Their principal logical features are compared in Table 1. In the alpha system, an active cell simply gains an increment of value for every impulse, and holds this gain indefinitely. In the beta system, each source-set is allowed a certain constant rate of gain, the increments being apportioned among the cells of the source-set in proportion to their activity. In the gamma system, active cells gain in value at the expense of the inactive cells of their source-set, so that the total value of a source-set is always constant.
我们假定,每个 A 单元发出的冲动可以用一个值(value) 来刻画,它可以是幅度、频率、潜伏期或完成传输的概率。如果一个 A 单元的值高,那么它的所有输出冲动都被认为比来自低值 A 单元的冲动更有效、更有力,或更有可能到达其末梢球。A 单元的值被认为是一个相当稳定的特性,大概取决于细胞及细胞膜的代谢状况,但并非绝对不变。一般假定,活动期倾向于提高细胞的值,而(在某些模型中)值会随不活动而衰减。最有意思的模型是这样一些模型:假定细胞彼此竞争代谢物质,较活跃的细胞以较不活跃的细胞为代价而获益。在这样的系统中,如果没有活动,所有细胞都会倾向于保持相对恒定的状态,并且(不论有无活动)整个系统的净值在任何时候都保持不变。我们定量研究了三类在值动力学上不同的系统,表 1 比较了它们的主要逻辑特征。在 alpha 系统中,活动细胞每发出一个冲动就获得一个值增量,并无限期地保持这一增益。在 beta 系统中,每个源集被允许以某个恒定速率获益,增量按活动程度分配给源集中的各细胞。在 gamma 系统中,活动细胞以其源集中不活动细胞为代价获得值,因此一个源集的总值始终不变。
| α-System (Uncompensated Gain System) | β-System (Constant Feed System) | γ-System (Parasitic Gain System) | |
|---|---|---|---|
| Total value-gain of source set per reinforcement | 0 | ||
| ΔV for A-units active for 1 unit of time | +1 | +1 | |
| ΔV for inactive A-units outside of dominant set | 0 | 0 | |
| ΔV for inactive A-units of dominant set | 0 | 0 | |
| Mean value of A-system | Increases with number of reinforcements | Increases with time | Constant |
| Difference between mean values of source-sets | Proportional to differences of reinforcement frequency | 0 | 0 |
Table 1. Comparison of Logical Characteristics of α, β, and γ Systems
Note: In the β and γ systems, the total value-change for any A-unit will be the sum of the ΔV's for all source-sets of which it is a member.
= Number of active units in source-set; = Total number of units in source-set; = Number of stimuli associated to response ; = Arbitrary constant
| α 系统(无补偿增益系统) | β 系统(恒定供给系统) | γ 系统(寄生增益系统) | |
|---|---|---|---|
| 每次强化中源集的总值增益 | 0 | ||
| 活动 1 个时间单位的 A 单元的 ΔV | +1 | +1 | |
| 优势集以外不活动 A 单元的 ΔV | 0 | 0 | |
| 优势集内不活动 A 单元的 ΔV | 0 | 0 | |
| A 系统的平均值 | 随强化次数增加 | 随时间增加 | 恒定 |
| 各源集平均值之差 | 与强化频率之差 成正比 | 0 | 0 |
表 1. α、β、γ 三类系统逻辑特征的比较
注:在 β 和 γ 系统中,任一 A 单元的总值变化,是它所属的所有源集的 ΔV 之和。
= 源集中活动单元的数目; = 源集中单元的总数; = 与反应 相联结的刺激数目; = 任意常数
For purposes of analysis, it is convenient to distinguish two phases in the response of the system to a stimulus (Fig. 3). In the predominant phase, some proportion of A-units (represented by solid dots in the figure) responds to the stimulus, but the R-units are still inactive. This phase is transient, and quickly gives way to the postdominant phase, in which one of the responses becomes active, inhibiting activity in the complement of its own source-set, and thus preventing the occurrence of any alternative response. The response which happens to become dominant is initially random, but if the A-units are reinforced (i.e., if the active units are allowed to gain in value), then when the same stimulus is presented again at a later time, the same response will have a stronger tendency to recur, and learning can be said to have taken place.
为了分析方便,可以把系统对刺激的反应区分为两个阶段(图 3)。在优势前阶段,一部分 A 单元(图中以实心圆点表示)对刺激作出反应,但 R 单元仍不活动。这一阶段是短暂的,很快就让位于优势后阶段:其中一个反应变得活跃,抑制其自身源集补集中的活动,从而阻止任何其他反应出现。碰巧成为优势的反应起初是随机的;但如果 A 单元得到强化(即允许活动单元获得值),那么当同一刺激在以后再次呈现时,同一反应会有更强的再现倾向,这时就可以说发生了学习。
Fig. 3A. Predominant phase. Inhibitory connections are not shown. Solid black units are active.
Fig. 3B. Postdominant phase. Dominant subset suppresses rival sets. Inhibitory connections shown only for .
Fig. 3. Phases of response to a stimulus.
图 3A. 优势前阶段。未画出抑制性连接。实心黑色单元为活动单元。
图 3B. 优势后阶段。优势子集压制竞争集合。只画出了 的抑制性连接。
图 3. 对刺激作出反应的各阶段。
Analysis of the Predominant Phase
优势前阶段的分析
The perceptrons considered here will always assume a fixed threshold, , for the activation of the A-units. Such a system will be called a fixed-threshold model, in contrast to a continuous transducer model, where the response of the A-unit is some continuous function of the impinging stimulus energy.
这里考虑的感知机总是假定 A 单元的激活阈值 是固定的。这样的系统称为固定阈值模型,与之相对的是连续换能器模型,后者中 A 单元的反应是所受刺激能量的某个连续函数。
In order to predict the learning curves of a fixed-threshold perceptron, two variables have been found to be of primary importance. They are defined as follows:
= the expected proportion of A-units activated by a stimulus of a given size,
= the conditional probability that an A-unit which responds to a given stimulus, , will also respond to another given stimulus, .
It can be shown (Rosenblatt, 15) that as the size of the retina is increased, the number of S-points () quickly ceases to be a significant parameter, and the values of and approach the value that they would have for a retina with infinitely many points. For a large retina, therefore, the equations are as follows:
where
and
= proportion of S-points activated by the stimulus
= number of excitatory connections to each A-unit
= number of inhibitory connections to each A-unit
= threshold of A-units.
(The quantities and are the excitatory and inhibitory components of the excitation received by the A-unit from the stimulus. If the algebraic sum is equal to or greater than , the A-unit is assumed to respond.)
为了预测固定阈值感知机的学习曲线,我们发现有两个变量最为重要。它们的定义如下:
= 给定大小的刺激所激活的 A 单元的期望比例;
= 对给定刺激 作出反应的 A 单元,也对另一给定刺激 作出反应的条件概率。
可以证明(Rosenblatt, 15),随着视网膜尺寸的增大,S 点的数目()很快就不再是一个重要参数, 和 的值趋近于视网膜具有无穷多个点时的值。因此,对于大视网膜,方程如下:
其中
并且
= 被刺激激活的 S 点的比例
= 每个 A 单元的兴奋性连接数
= 每个 A 单元的抑制性连接数
= A 单元的阈值。
( 和 分别是 A 单元从刺激所接收的兴奋中的兴奋性成分和抑制性成分。如果代数和 等于或大于 ,就假定该 A 单元作出反应。)(译注:(1) 式内层求和的下限在原刊中印作 ,按原样保留。)
where
and
= proportion of the S-points illuminated by the first stimulus, , which are not illuminated by
= proportion of the residual S-set (left over from the first stimulus) which is included in the second stimulus ().
The quantities , , and specify the two stimuli and their retinal overlap. and are, respectively, the numbers of excitatory and inhibitory origin points "lost" by the A-unit when stimulus is replaced by ; and are the numbers of excitatory and inhibitory origin points "gained" when stimulus is replaced by . The summations in Equation 2 are between the limits indicated, subject to the side condition .
其中
并且
= 被第一个刺激 照亮、但未被 照亮的 S 点所占的比例
= (第一个刺激之外)剩余 S 点集合中被包含在第二个刺激()中的比例。
、 和 这三个量确定了两个刺激及其在视网膜上的重叠。 和 分别是刺激 被 取代时,A 单元“失去”的兴奋性和抑制性起源点数目; 和 分别是刺激 被 取代时“获得”的兴奋性和抑制性起源点数目。方程 2 中的求和在所示上下限之间进行,并服从附加条件 。(译注:(2) 式第二个求和的下限原刊印作 ,按原样保留;原式分两行排印,此处合并为一行。)
Some of the most important characteristics of are illustrated in Fig. 4, which shows as a function of the retinal area illuminated (). Note that can be reduced in magnitude by either increasing the threshold, , or by increasing the proportion of inhibitory connections (). A comparison of Fig. 4b and 4c shows that if the excitation is about equal to the inhibition, the curves for as a function of are flattened out, so that there is little variation in for stimuli of different sizes. This fact is of great importance for systems which require to be close to an optimum value in order to perform properly.
的一些最重要特性见图 4,图中给出 作为被照亮视网膜面积()的函数。注意,提高阈值 或提高抑制性连接的比例(),都可以减小 的数值。比较图 4b 和 4c 可见,如果兴奋与抑制大致相等, 关于 的曲线就会变平,因而对于不同大小的刺激, 变化很小。对于需要 接近某个最佳值才能正常工作的系统,这一事实非常重要。
The behavior of is illustrated in Fig. 5 and 6. The curves in Fig. 5 can be compared with those for in Fig. 4. Note that as the threshold is increased, there is an even sharper reduction in the value of than was the case with . also decreases as the proportion of inhibitory connections increases, as does . Fig. 5, which is calculated for nonoverlapping stimuli, illustrates the fact that remains greater than zero even when the stimuli are completely disjunct, and illuminate no retinal points in common. In Fig. 6, the effect of varying amounts of overlap between the stimuli is shown. In all cases, the value of goes to unity as the stimuli approach perfect identity. For smaller stimuli (broken line curves), the value of is lower than for large stimuli. Similarly, the value is less for high thresholds than for low thresholds. The minimum value of will be equal to
In Fig. 6, corresponds to the curve for . Note that under these conditions the probability that the A-unit responds to both stimuli () is practically zero, except for stimuli which are quite close to identity. This condition can be of considerable help in discrimination learning.
的行为见图 5 和图 6。图 5 中的曲线可以与图 4 中 的曲线相比较。注意,随着阈值提高, 值的下降比 更加剧烈。与 一样, 也随抑制性连接比例的增加而减小。图 5 是针对不重叠刺激计算的,它表明即使两个刺激完全不相交、没有共同照亮任何视网膜点, 仍然大于零。图 6 给出了刺激间不同重叠程度的影响。在所有情形下,当两个刺激趋于完全相同时, 的值都趋于 1。对于较小的刺激(虚线曲线), 的值低于大刺激。同样,阈值高时该值比阈值低时小。 的最小值等于
在图 6 中, 对应于 的曲线。注意,在这些条件下,除非两个刺激非常接近相同,A 单元同时对两个刺激作出反应的概率()实际上为零。这一条件对辨别学习可能大有帮助。
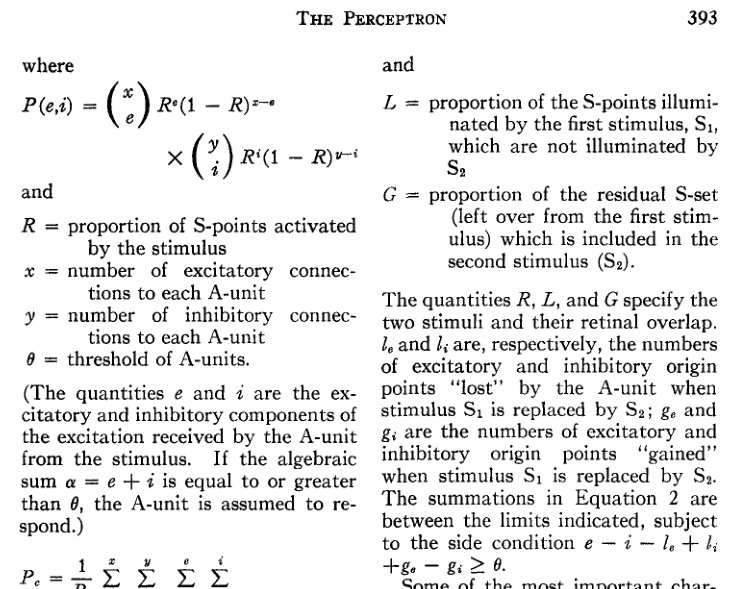
Fig. 4. as function of retinal area illuminated. [Panels: (a) effect of inhibitory-excitatory mixture, ; (b) variation with for , ; (c) variation with M and for mixtures about 50% inhibitory; solid lines are for , .]
图 4. 作为被照亮视网膜面积的函数。[分图:(a) 抑制—兴奋混合比例的影响,;(b) 当 、 时随 的变化;(c) 对约 50% 为抑制性的混合,随 M 和 的变化;实线对应 、。(M 按原图保留。)]
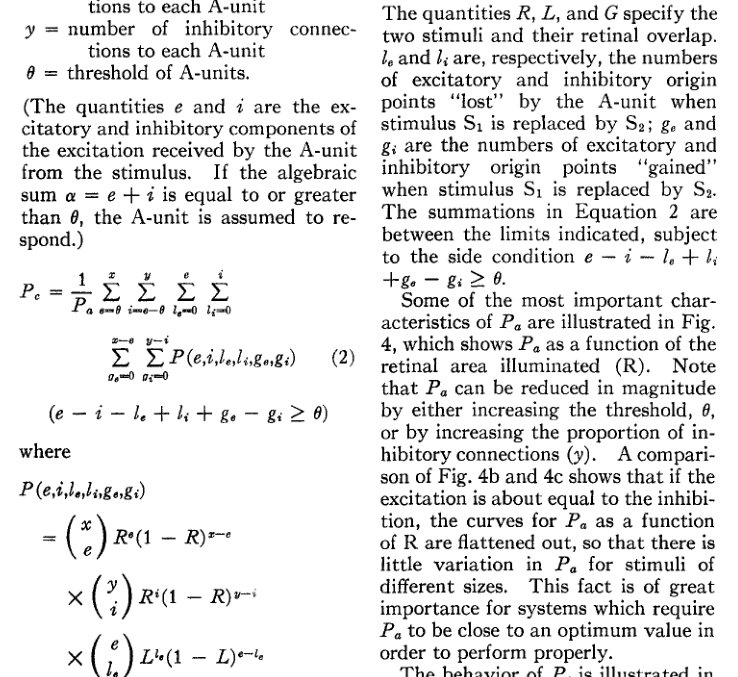
Fig. 5. as a function of , for nonoverlapping stimuli.
Fig. 6. as a function of . , . Solid lines: ; broken lines: .
图 5. 不重叠刺激下, 作为 的函数。
图 6. 作为 的函数。,。实线:;虚线:。
Mathematical Analysis of Learning in the Perceptron
感知机学习的数学分析
The response of the perceptron in the predominant phase, where some fraction of the A-units (scattered throughout the system) responds to the stimulus, quickly gives way to the postdominant response, in which activity is limited to a single source-set, the other sets being suppressed. Two possible systems have been studied for the determination of the "dominant" response, in the postdominant phase. In one (the mean-discriminating system, or -system), the response whose inputs have the greatest mean value responds first, gaining a slight advantage over the others, so that it quickly becomes dominant. In the second case (the sum-discriminating system, or -system), the response whose inputs have the greatest net value gains an advantage. In most cases, systems which respond to mean values have an advantage over systems which respond to sums, since the means are less influenced by random variations in from one source-set to another. In the case of the -system (see Table 1), however, the performance of the -system and -system become identical.
在优势前阶段,有一部分(散布于整个系统中的)A 单元对刺激作出反应;感知机的这种反应很快让位于优势后反应,此时活动局限于单个源集,其他集合受到压制。为了确定优势后阶段的“优势”反应,我们研究了两种可能的系统。在一种系统中(均值辨别系统,或 系统),输入平均值最大的反应最先作出反应,取得相对于其他反应的微弱优势,从而很快成为优势反应。在第二种情形中(总和辨别系统,或 系统),输入净值最大的反应取得优势。在大多数情形下,对均值作出反应的系统优于对总和作出反应的系统,因为均值受各源集之间 随机波动的影响较小。不过,在 系统(见表 1)的情形下, 系统和 系统的表现变得完全相同。
We have indicated that the perceptron is expected to learn, or to form associations, as a result of the changes in value that occur as a result of the activity of the association cells. In evaluating this learning, one of two types of hypothetical experiments can be considered. In the first case, the perceptron is exposed to some series of stimulus patterns (which might be presented in random positions on the retina) and is "forced" to give the desired response in each case. (This forcing of responses is assumed to be a prerogative of the experimenter. In experiments intended to evaluate trial-and-error learning, with more sophisticated perceptrons, the experimenter does not force the system to respond in the desired fashion, but merely applies positive reinforcement when the response happens to be correct, and negative reinforcement when the response is wrong.) In evaluating the learning which has taken place during this "learning series," the perceptron is assumed to be "frozen" in its current condition, no further value changes being allowed, and the same series of stimuli is presented again in precisely the same fashion, so that the stimuli fall on identical positions on the retina. The probability that the perceptron will show a bias towards the "correct" response (the one which has been previously reinforced during the learning series) in preference to any given alternative response is called , the probability of correct choice of response between two alternatives.
我们已经指出,由于联想细胞的活动引起值的变化,可以预期感知机会学习,即形成联想。在评估这种学习时,可以考虑两类假想实验中的一种。在第一类实验中,让感知机接触一系列刺激模式(它们可以呈现在视网膜上的随机位置),并在每种情况下“强制”它给出所需的反应。(这种对反应的强制被假定为实验者的特权。在用更复杂的感知机评估试错学习的实验中,实验者并不强制系统以所需方式作出反应,而只是在反应恰好正确时施加正强化,在反应错误时施加负强化。)在评估这一“学习序列”中所发生的学习时,假定感知机被“冻结”在当前状态,不再允许值发生变化,然后以完全相同的方式再次呈现同一系列刺激,使刺激落在视网膜上完全相同的位置。感知机表现出偏向“正确”反应(即在学习序列中曾被强化的反应)、而非任一给定其他反应的概率,记为 ,即在两个备选反应之间正确选择反应的概率。
In the second type of experiment, a learning series is presented exactly as before, but instead of evaluating the perceptron's performance using the same series of stimuli which were shown before, a new series is presented, in which stimuli may be drawn from the same classes that were previously experienced, but are not necessarily identical. This new test series is assumed to be composed of stimuli projected onto random retinal positions, which are chosen independently of the positions selected for the learning series. The stimuli of the test series may also differ in size or rotational position from the stimuli which were previously experienced. In this case, we are interested in the probability that the perceptron will give the correct response for the class of stimuli which is represented, regardless of whether the particular stimulus has been seen before or not. This probability is called , the probability of correct generalization. As with , is actually the probability that a bias will be found in favor of the proper response rather than any one alternative; only one pair of responses at a time is considered, and the fact that the response bias is correct in one pair does not mean that there may not be other pairs in which the bias favors the wrong response. The probability that the correct response will be preferred over all alternatives is designated or .
在第二类实验中,学习序列的呈现与前面完全一样;但评估感知机的表现时,不再使用先前呈现过的同一系列刺激,而是呈现一个新的系列,其中的刺激可以取自先前经历过的同一些类别,但不一定完全相同。假定这一新的测试系列由投射到随机视网膜位置上的刺激组成,这些位置的选取与学习序列所选位置相互独立。测试系列中的刺激在大小或旋转位置上也可以与先前经历过的刺激不同。在这种情形下,我们关心的是:无论某个特定刺激以前是否见过,感知机对所代表的那类刺激给出正确反应的概率。这一概率记为 ,即正确泛化的概率。与 一样, 实际上是发现偏向正确反应、而非任一个其他反应的偏差的概率;每次只考虑一对反应,在一对反应中偏差正确,并不意味着不存在偏差偏向错误反应的其他反应对。正确反应优于所有其他反应的概率记为 或 。
In all cases investigated, a single general equation gives a close approximation to and , if the appropriate constants are substituted. This equation is of the form:
where
= normal curve integral from to
and
If is the "correct" response, and is the alternative response under consideration, Equation 4 is the probability that will be preferred over after stimuli have been shown for each of the two responses, during the learning period. is the number of "effective" A-units in each source-set; that is, the number of A-units in either source-set which are not connected in common to both responses. Those units which are connected in common contribute equally to both sides of the value balance, and consequently do not affect the net bias towards one response or the other. is the number of active units in a source-set, which respond to the test stimulus, . is the probability that at least one of the effective units in the source-set of the correct response (designated, by convention, as the response) will be activated by the test stimulus, .
在所研究的一切情形中,只要代入适当的常数,一个通用方程就能很好地近似 和 。该方程的形式为:
其中
= 从 到 的正态曲线积分
并且
若 是“正确”反应, 是所考虑的另一反应,那么方程 4 就是:在学习期间为两个反应各呈现 个刺激之后, 优于 的概率。 是每个源集中“有效”A 单元的数目,即任一源集中不同时连接到两个反应的 A 单元的数目。那些共同连接的单元对值天平的两边贡献相等,因此不影响偏向某一反应的净偏差。 是一个源集中对测试刺激 作出反应的活动单元数。 是正确反应(按约定记为 反应)的源集中 个有效单元里至少有一个被测试刺激 激活的概率。
In the case of , the constant is always equal to zero, the other three constants being the same as for . The values of the four constants depend on the parameters of the physical nerve net (the perceptron) and also on the organization of the stimulus environment.
在 的情形下,常数 总是等于零,其他三个常数与 的相同。这四个常数的值取决于物理神经网络(感知机)的参数,也取决于刺激环境的组织。
The simplest cases to analyze are those in which the perceptron is shown stimuli drawn from an "ideal environment," consisting of randomly placed points of illumination, where there is no attempt to classify stimuli according to intrinsic similarity. Thus, in a typical learning experiment, we might show the perceptron 1,000 stimuli made up of random collections of illuminated retinal points, and we might arbitrarily reinforce as the "correct" response for the first 500 of these, and for the remaining 500. This environment is "ideal" only in the sense that we speak of an ideal gas in physics; it is a convenient artifact for purposes of analysis, and does not lead to the best performance from the perceptron. In the ideal environment situation, the constant is always equal to zero, so that, in the case of (where is also zero), the value of will be zero, and can never be any better than the random expectation of 0.5. The evaluation of for these conditions, however, throws some interesting light on the differences between the alpha, beta, and gamma systems (Table 1).
最容易分析的情形是:给感知机呈现的刺激取自一个“理想环境”,它由随机放置的光点组成,不试图按内在相似性对刺激分类。例如,在一个典型的学习实验中,我们可以给感知机呈现 1,000 个由随机的被照亮视网膜点集合构成的刺激,并任意地对其中前 500 个把 作为“正确”反应来强化,对其余 500 个强化 。这个环境之所以称为“理想的”,只是在物理学中说理想气体那种意义上;它是便于分析的人为设定,并不能使感知机达到最佳表现。在理想环境的情形下,常数 总是等于零,因此对于 (其中 也为零), 的值为零, 永远不可能好于随机期望值 0.5。不过,在这些条件下对 的评估,为 alpha、beta 和 gamma 系统(表 1)之间的差异提供了一些有趣的启示。
First consider the alpha system, which has the simplest dynamics of the three. In this system, whenever an A-unit is active for one unit of time, it gains one unit of value. We will assume an experiment, initially, in which (the number of stimuli associated to each response) is constant for all responses. In this case, for the sum system,
where = the fraction of responses connected to each A-unit. If the source-sets are disjunct, , where is the number of responses in the system. For the -system,
The reduction of to zero gives the -system a definite advantage over the -system. Typical learning curves for these systems are compared in Fig. 7 and 8. Figure 9 shows the effect of variations in upon the performance of the system.
先考虑 alpha 系统,它是三者中动力学最简单的。在这一系统中,A 单元每活动一个时间单位,就获得一个单位的值。我们首先假定这样一个实验:其中 (与每个反应相联结的刺激数)对所有反应都是常数。在这种情况下,对于总和系统,
其中 = 连接到每个 A 单元的反应所占的比例。如果各源集互不相交,则 ,其中 是系统中反应的数目。对于 系统,
降为零,使 系统相对于 系统具有明确的优势。图 7 和图 8 比较了这些系统的典型学习曲线。图 9 给出了 的变化对系统表现的影响。
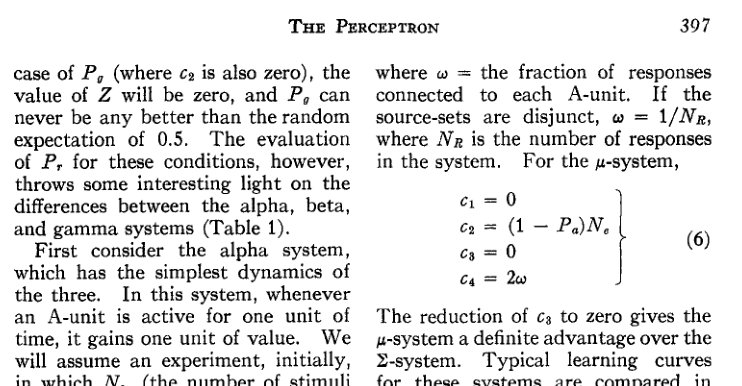
Fig. 7. as function of , for discrete subsets. (, . Ideal environment assumed.)
图 7. 离散子集情形下, 作为 的函数。(,。假定为理想环境。)
If , instead of being fixed, is treated as a random variable, so that the number of stimuli associated to each response is drawn separately from some distribution, then the performance of the -system is considerably poorer than the above equations indicate. Under these conditions, the constants for the -system are
where
= ratio of to
= number of responses in the system
= number of A-units in the system
= proportion of A-units common to and .
For this equation (and any others in which is treated as a random variable), it is necessary to define in Equation 4 as the expected value of this variable, over the set of all responses.
如果 不是固定的,而是被当作随机变量,即与每个反应相联结的刺激数分别从某个分布中抽取,那么 系统的表现会比上述方程所示的差得多。在这些条件下, 系统的常数为
其中
= 与 之比
= 系统中反应的数目
= 系统中 A 单元的数目
= 与 共有的 A 单元所占比例。
对于这个方程(以及任何把 当作随机变量的方程),必须把方程 4 中的 定义为该变量在所有反应上的期望值。
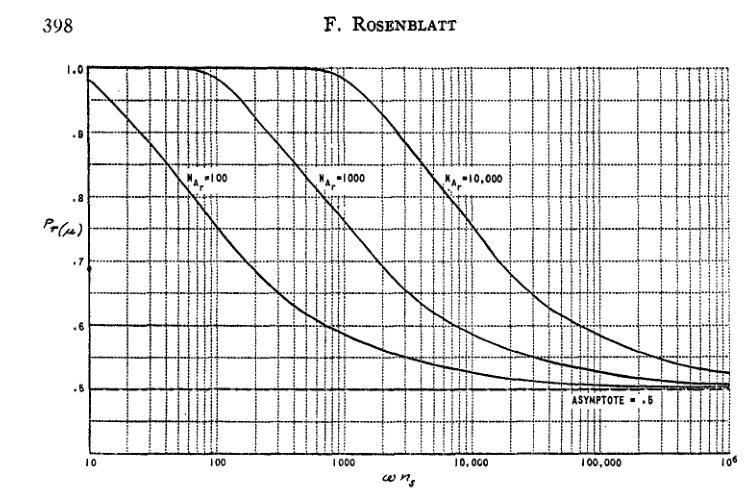
Fig. 8. as function of . (For , . Ideal environment assumed.)
图 8. 作为 的函数。(,。假定为理想环境。)
For the -system, there is an even greater deficit in performance, due to the fact that the net value continues to grow regardless of what happens to the system. The large net values of the subsets activated by a stimulus tend to amplify small statistical differences, causing an unreliable performance. The constants in this case (again for the -system) are
In both the alpha and beta systems, performance will be poorer for the sum-discriminating model than for the mean-discriminating case. In the gamma-system, however, it can be shown that ; i.e., it makes no difference in performance whether the -system or -system is used. Moreover, the constants for the -system, with variable , are identical to the constants for the alpha -system, with fixed (Equation 6). The performance of the three systems is compared in Fig. 10, which clearly demonstrates the advantage of the -system.
对于 系统,表现的亏损更大,因为无论系统发生什么,净值都会持续增长。被刺激激活的子集具有很大的净值,这倾向于放大微小的统计差异,造成不可靠的表现。这种情形下的常数(同样针对 系统)为
在 alpha 和 beta 系统中,总和辨别模型的表现都会比均值辨别的情形差。然而在 gamma 系统中,可以证明 ;也就是说,使用 系统还是 系统,对表现没有影响。此外, 可变时 系统的常数,与 固定时 alpha 系统的常数(方程 6)完全相同。图 10 比较了三种系统的表现,清楚地显示了 系统的优势。
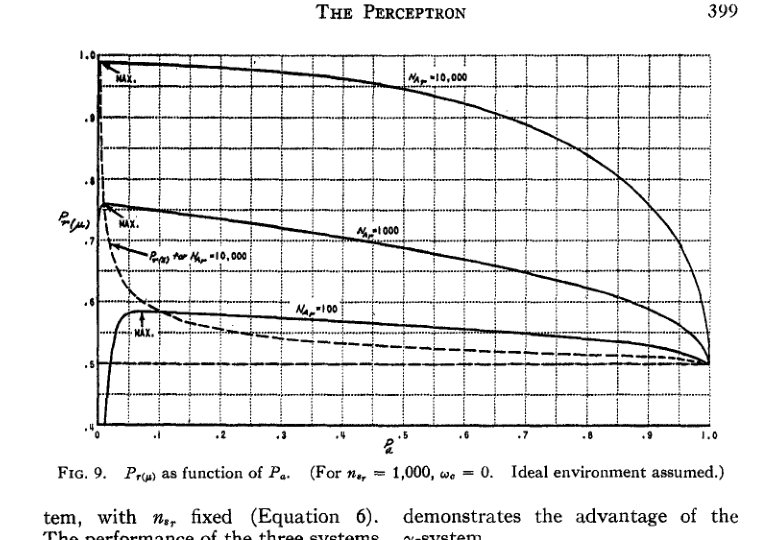
Fig. 9. as function of . (For , . Ideal environment assumed.)
Fig. 10. Comparison of , , and systems, for variable (, , , , ).
图 9. 作为 的函数。(,。假定为理想环境。)
图 10. 可变时 、、 三种系统的比较(,,,,)。
Let us now replace the "ideal environment" assumptions with a model for a "differentiated environment," in which several distinguishable classes of stimuli are present (such as squares, circles, and triangles, or the letters of the alphabet). If we then design an experiment in which the stimuli associated to each response are drawn from a different class, then the learning curves of the perceptron are drastically altered. The most important difference is that the constant (the coefficient of in the numerator of ) is no longer equal to zero, so that Equation 4 now has a nonrandom asymptote. Moreover, in the form for (the probability of correct generalization), where , the quantity remains greater than zero, and actually approaches the same asymptote as . Thus the equation for the perceptron's performance after infinite experience with each class of stimuli is identical for and :
This means that in the limit it makes no difference whether the perceptron has seen a particular test stimulus before or not; if the stimuli are drawn from a differentiated environment, the performance will be equally good in either case.
现在我们用“分化环境”模型来代替“理想环境”假设。在分化环境中存在若干可区分的刺激类别(如正方形、圆形和三角形,或字母表中的字母)。如果我们设计这样一个实验,使与每个反应相联结的刺激取自不同的类别,那么感知机的学习曲线就会发生剧烈变化。最重要的区别在于,常数 ( 的分子中 的系数)不再等于零,因此方程 4 现在具有一个非随机的渐近值。而且,在 (正确泛化的概率)的形式中,虽然 , 仍大于零, 实际上趋近于与 相同的渐近值。因此,在对每类刺激都有无限经验之后,感知机表现的方程对 和 是相同的:
这意味着,在极限情况下,感知机以前是否见过某个特定测试刺激并无区别;如果刺激取自分化环境,两种情况下的表现同样好。
In order to evaluate the performance of the system in a differentiated environment, it is necessary to define the quantity . This quantity is interpreted as the expected value of between pairs of stimuli drawn at random from classes and . In particular, is the expected value of between members of the same class, and is the expected value of between an stimulus drawn from Class 1 and an stimulus drawn from Class 2. is the expected value of between members of Class 1 and stimuli drawn at random from all other classes in the environment.
为了评估系统在分化环境中的表现,需要定义量 。它被解释为从类 和类 中随机抽取的刺激对之间 的期望值。特别地, 是同类成员之间 的期望值, 是取自类 1 的刺激 与取自类 2 的刺激 之间 的期望值。 是类 1 的成员与从环境中所有其他类别随机抽取的刺激之间 的期望值。
If , the limiting performance of the perceptron () will be better than chance, and learning of some response, , as the proper "generalization response" for members of Class 1 should eventually occur. If the above inequality is not met, then improvement over chance performance may not occur, and the Class 2 response is likely to occur instead. It can be shown (15) that for most simple geometrical forms, which we ordinarily regard as "similar," the required inequality can be met, if the parameters of the system are properly chosen.
如果 ,感知机的极限表现()将好于随机,最终应能学会把某个反应 作为类 1 成员的适当“泛化反应”。如果上述不等式不满足,表现可能无法超过随机水平,而且很可能出现类 2 的反应。可以证明(15),对于我们通常认为“相似”的大多数简单几何形状,只要系统参数选择得当,所需的不等式就能满足。
The equation for , for the sum-discriminating version of an -perceptron, in a differentiated environment where is fixed for all responses, will have the following expressions for the four coefficients:
where
and represent the variance of and measured over the set of possible test stimuli, , and
and represent the variance of and measured over the set of all A-units, .
= covariance of , which is assumed to be negligible.
对于 感知机的总和辨别版本,在 对所有反应都固定的分化环境中, 方程的四个系数表达式如下:
其中
和 表示 和 在所有可能测试刺激 上测得的方差;
和 表示 和 在所有 A 单元 上测得的方差;
= 的协方差,假定可以忽略。
(译注:(10) 式中 原刊印作 ;、 以及方括号的配对均按原刊照录,未作推断性修改。)
The variances which appear in these expressions have not yielded, thus far, to a precise analysis, and can be treated as empirical variables to be determined for the classes of stimuli in question. If the sigma is set equal to half the expected value of the variable, in each case, a conservative estimate can be obtained. When the stimuli of a given class are all of the same shape, and uniformly distributed over the retina, the subscript variances are equal to zero. will be represented by the same set of coefficients, except for , which is equal to zero, as usual.
For the mean-discriminating system, the coefficients are:
Some covariance terms, which are considered negligible, have been omitted here.
这些表达式中出现的方差,迄今还无法进行精确分析,可以当作经验变量,针对所讨论的刺激类别加以测定。如果在每种情形下都令 sigma 等于该变量期望值的一半,就能得到一个保守的估计。当某一类刺激都具有相同形状、并均匀分布在视网膜上时,下标为 的方差等于零。 由同一组系数表示,只是 照例等于零。
对于均值辨别系统,系数为:
这里省略了一些被认为可以忽略的协方差项。
A set of typical learning curves for the differentiated environment model is shown in Fig. 11, for the mean-discriminating system. The parameters are based on measurements for a square-circle discrimination problem. Note that the curves for and both approach the same asymptotes, as predicted. The values of these asymptotes can be obtained by substituting the proper coefficients in Equation 9. As the number of association cells in the system increases, the asymptotic learning limit rapidly approaches unity, so that for a system of several thousand cells, the errors in performance should be negligible on a problem as simple as the one illustrated here.
图 11 给出均值辨别系统在分化环境模型下的一组典型学习曲线,参数基于对正方形—圆形辨别问题的测量。注意,正如所预测的, 和 的曲线都趋近于相同的渐近值。把适当的系数代入方程 9,即可求得这些渐近值。随着系统中联想细胞数目的增加,渐近的学习极限迅速趋近于 1,因此对于一个有几千个细胞的系统,在像这里所示这样简单的问题上,表现中的错误应当可以忽略。
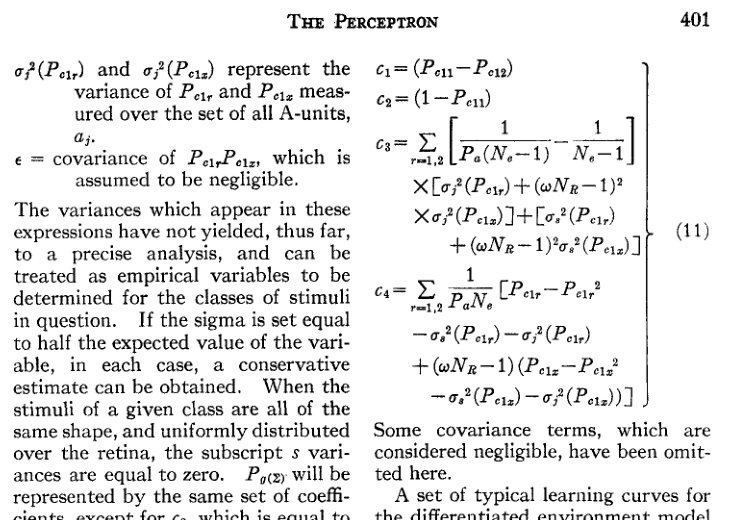
Fig. 11. and as function of . Parameters based on square-circle discrimination.
图 11. 和 作为 的函数。参数基于正方形—圆形辨别。
As the number of responses in the system increases, the performance becomes progressively poorer, if every response is made mutually exclusive of all alternatives. One method of avoiding this deterioration (described in detail in Rosenblatt, 15) is through the binary coding of responses. In this case, instead of representing 100 different stimulus patterns by 100 distinct, mutually exclusive responses, a limited number of discriminating features is found, each of which can be independently recognized as being present or absent, and consequently can be represented by a single pair of mutually exclusive responses. Given an ideal set of binary characteristics (such as dark, light; tall, short; straight, curved; etc.), 100 stimulus classes could be distinguished by the proper configuration of only seven response pairs. In a further modification of the system, a single response is capable of denoting by its activity or inactivity the presence or absence of each binary characteristic. The efficiency of such coding depends on the number of independently recognizable "earmarks" that can be found to differentiate stimuli. If the stimulus can be identified only in its entirety and is not amenable to such analysis, then ultimately a separate binary response pair, or bit, is required to denote the presence or absence of each stimulus class (e.g., "dog" or "not dog"), and nothing has been gained over a system where all responses are mutually exclusive.
如果每个反应都与所有其他反应互斥,那么随着系统中反应数目的增加,表现会越来越差。避免这种恶化的一种方法(详见 Rosenblatt, 15)是对反应进行二进制编码。这时,不再用 100 个不同的、互斥的反应来表示 100 种不同的刺激模式,而是找出数量有限的若干辨别特征,每个特征都能被独立地识别为存在或不存在,从而可以用单独一对互斥反应来表示。给定一组理想的二元特征(如暗、亮;高、矮;直、弯;等等),只需七对反应的适当组合就能区分 100 个刺激类别。在对系统的进一步修改中,单个反应就能以其活动与否来表示每个二元特征的存在与否。这种编码的效率,取决于能找到多少个可独立识别、用来区分刺激的“标记”。如果刺激只能作为整体来辨认、无法进行这种分析,那么最终就需要为每个刺激类别单独设一对二元反应,即一个比特,来表示该类别是否存在(例如“狗”或“非狗”),这与所有反应都互斥的系统相比毫无所得。
Bivalent Systems
双值系统
In all of the systems analyzed up to this point, the increments of value gained by an active A-unit, as a result of reinforcement or experience, have always been positive, in the sense that an active unit has always gained in its power to activate the responses to which it is connected. In the gamma-system, it is true that some units lose value, but these are always the inactive units, the active ones gaining in proportion to their rate of activity. In a bivalent system, two types of reinforcement are possible (positive and negative), and an active unit may either gain or lose in value, depending on the momentary state of affairs in the system. If the positive and negative reinforcement can be controlled by the application of external stimuli, they become essentially equivalent to "reward" and "punishment," and can be used in this sense by the experimenter. Under these conditions, a perceptron appears to be capable of trial-and-error learning. A bivalent system need not necessarily involve the application of reward and punishment, however. If a binary-coded response system is so organized that there is a single response or response-pair to represent each "bit," or stimulus characteristic that is learned, with positive feedback to its own source-set if the response is "on," and negative feedback (in the sense that active A-units will lose rather than gain in value) if the response is "off," then the system is still bivalent in its characteristics. Such a bivalent system is particularly efficient in reducing some of the bias effects (preference for the wrong response due to greater size or frequency of its associated stimuli) which plague the alternative systems.
在到目前为止分析过的所有系统中,活动 A 单元因强化或经验而获得的值增量总是正的,也就是说,活动单元激活其所连接反应的能力总是在增强。在 gamma 系统中,确实有些单元会失去值,但它们总是不活动的单元,活动单元则按其活动速率成比例地获得值。在双值系统中,可以有两种强化(正强化和负强化),活动单元可能获得值,也可能失去值,这取决于系统当时的状态。如果正强化和负强化可以通过施加外部刺激来控制,它们本质上就等价于“奖励”和“惩罚”,实验者可以在这个意义上使用它们。在这些条件下,感知机看来能够进行试错学习。不过,双值系统并不一定涉及奖励和惩罚的施加。如果一个二进制编码的反应系统是这样组织的:每个所学习的“比特”或刺激特征都由单个反应或一对反应来表示,反应为“开”时对其自身源集给予正反馈,为“关”时给予负反馈(意思是活动 A 单元将失去而不是获得值),那么该系统在特性上仍然是双值的。这样的双值系统在减少某些偏差效应方面特别有效,这些偏差效应(由于相联结的刺激更大或更频繁而偏好错误反应)困扰着其他系统。
Several forms of bivalent systems have been considered (15, Chap. VII). The most efficient of these has the following logical characteristics.
If the system is under a state of positive reinforcement, then a positive ΔV is added to the values of all active A-units in the source-sets of "on" responses, while a negative ΔV is added to the active units in the source-sets of "off" responses. If the system is currently under negative reinforcement, then a negative ΔV is added to all active units in the source-set of an "on" response, and a positive ΔV is added to active units in an "off" source-set. If the source-sets are disjunct (which is essential for this system to work properly), the equation for a bivalent -system has the same coefficients as the monovalent -system, for the -case (Equation 11).
我们考虑过几种形式的双值系统(15,第 VII 章)。其中最有效的一种具有如下逻辑特征。
如果系统处于正强化状态,就给“开”反应的源集中所有活动 A 单元的值加上一个正的 ΔV,同时给“关”反应的源集中的活动单元加上一个负的 ΔV。如果系统当前处于负强化之下,就给“开”反应源集中的所有活动单元加上负的 ΔV,给“关”源集中的活动单元加上正的 ΔV。如果各源集互不相交(这是该系统正常工作的必要条件),那么双值 系统的方程,与单值 系统在 情形下的方程(方程 11)具有相同的系数。
The performance curves for this system are shown in Fig. 12, where the asymptotic generalization probability attainable by the system is plotted for the same stimulus parameters that were used in Fig. 11. This is the probability that all bits in an -bit response pattern will be correct. Clearly, if a majority of correct responses is sufficient to identify a stimulus correctly, the performance will be better than these curves indicate.
该系统的表现曲线见图 12,图中针对与图 11 相同的刺激参数,画出了系统可达到的渐近泛化概率。这是一个 比特反应模式中所有比特都正确的概率。显然,如果多数反应正确就足以正确识别刺激,表现将好于这些曲线所示。
In a form of bivalent system which utilizes more plausible biological assumptions, A-units may be either excitatory or inhibitory in their effect on connected responses. A positive ΔV in this system corresponds to the incrementing of an excitatory unit, while a negative ΔV corresponds to the incrementing of an inhibitory unit. Such a system performs similarly to the one considered above, but can be shown to be less efficient.
Bivalent systems similar to those illustrated in Fig. 12 have been simulated in detail in a series of experiments with the IBM 704 computer at the Cornell Aeronautical Laboratory. The results have borne out the theory in all of its main predictions, and will be reported separately at a later time.
在另一种采用生物学上更合理假设的双值系统中,A 单元对所连接反应的作用可以是兴奋性的,也可以是抑制性的。在这种系统中,正的 ΔV 对应于一个兴奋性单元的增强,负的 ΔV 对应于一个抑制性单元的增强。这样的系统表现与上面所讨论的系统相似,但可以证明其效率较低。
与图 12 所示相似的双值系统,已在康奈尔航空实验室用 IBM 704 计算机进行的一系列实验中作了详细模拟。结果在所有主要预测上都证实了这一理论,详情将在以后另行报告。
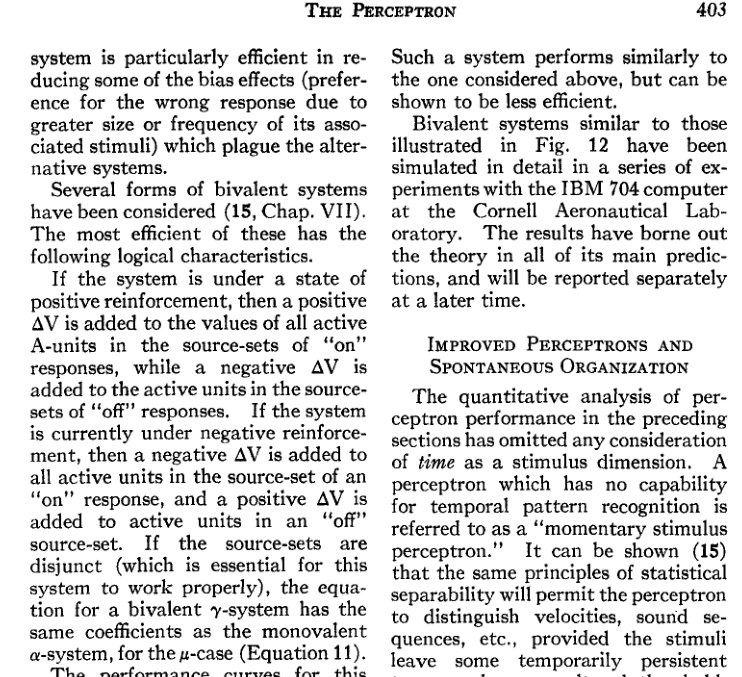
Fig. 12. for a bivalent binary system (same parameters as Fig. 11).
图 12. 双值二进制系统的 (参数与图 11 相同)。
Improved Perceptrons and Spontaneous Organization
改进的感知机与自发组织
The quantitative analysis of perceptron performance in the preceding sections has omitted any consideration of time as a stimulus dimension. A perceptron which has no capability for temporal pattern recognition is referred to as a "momentary stimulus perceptron." It can be shown (15) that the same principles of statistical separability will permit the perceptron to distinguish velocities, sound sequences, etc., provided the stimuli leave some temporarily persistent trace, such as an altered threshold, which causes the activity in the A-system at time to depend to some degree on the activity at time .
前面各节对感知机表现的定量分析,没有考虑时间作为刺激的一个维度。不具备时间模式识别能力的感知机,称为“瞬时刺激感知机”。可以证明(15),只要刺激留下某种暂时持续的痕迹(例如阈值的改变),使 A 系统在时刻 的活动在某种程度上取决于时刻 的活动,同样的统计可分性原理就能使感知机区分速度、声音序列等。
It has also been assumed that the origin points of A-units are completely random. It can be shown that by a suitable organization of origin points, in which the spatial distribution is constrained (as in the projection area origins shown in Fig. 1), the A-units will become particularly sensitive to the location of contours, and performance will be improved.
前面还假定了 A 单元的起源点是完全随机的。可以证明,通过对起源点作适当的组织、约束其空间分布(如图 1 中投射区的起源点那样),A 单元会对轮廓的位置特别敏感,表现也会得到改善。
In a recent development, which we hope to report in detail in the near future, it has been proven that if the values of the A-units are allowed to decay at a rate proportional to their magnitude, a striking new property emerges: the perceptron becomes capable of "spontaneous" concept formation. That is to say, if the system is exposed to a random series of stimuli from two "dissimilar" classes, and all of its responses are automatically reinforced without any regard to whether they are "right" or "wrong," the system will tend towards a stable terminal condition in which (for each binary response) the response will be "1" for members of one stimulus class, and "0" for members of the other class; i.e., the perceptron will spontaneously recognize the difference between the two classes. This phenomenon has been successfully demonstrated in simulation experiments, with the 704 computer.
在一项我们希望不久后详细报告的新进展中,已经证明:如果允许 A 单元的值以与其大小成正比的速率衰减,就会出现一个引人注目的新性质——感知机变得能够“自发地”形成概念。也就是说,如果让系统接触来自两个“不相似”类别的随机刺激序列,并且不管其反应“对”还是“错”都自动加以强化,系统就会趋向一个稳定的终态:在这一终态中(对每个二元反应而言),对一个刺激类别的成员,反应为“1”,对另一类别的成员,反应为“0”;也就是说,感知机会自发地识别出两个类别之间的差别。这一现象已在用 704 计算机进行的模拟实验中得到成功演示。
A perceptron, even with a single logical level of A-units and response units, can be shown to have a number of interesting properties in the field of selective recall and selective attention. These properties generally depend on the intersection of the source sets for different responses, and are elsewhere discussed in detail (15). By combining audio and photo inputs, it is possible to associate sounds, or auditory "names" to visual objects, and to get the perceptron to perform such selective responses as are designated by the command "Name the object on the left," or "Name the color of this stimulus."
可以证明,即使只有单一逻辑层次的 A 单元和反应单元,感知机在选择性回忆和选择性注意方面也具有若干有趣的性质。这些性质一般取决于不同反应的源集之间的交集,我们在别处有详细讨论(15)。把听觉输入与光学输入结合起来,就能把声音或听觉“名称”与视觉对象联系起来,并让感知机作出诸如“说出左边物体的名称”或“说出这个刺激的颜色”这类指令所规定的选择性反应。
The question may well be raised at this point of where the perceptron's capabilities actually stop. We have seen that the system described is sufficient for pattern recognition, associative learning, and such cognitive sets as are necessary for selective attention and selective recall. The system appears to be potentially capable of temporal pattern recognition, as well as spatial recognition, involving any sensory modality or combination of modalities. It can be shown that with proper reinforcement it will be capable of trial-and-error learning, and can learn to emit ordered sequences of responses, provided its own responses are fed back through sensory channels.
这时很自然会问:感知机的能力究竟止于何处?我们已经看到,所描述的系统足以进行模式识别、联想学习,以及选择性注意和选择性回忆所需的那些认知定势。该系统看来具有进行时间模式识别和空间识别的潜在能力,涉及任何感觉通道或通道的组合。可以证明,只要有适当的强化,它就能进行试错学习,并且只要它自己的反应经由感觉通道反馈回来,它就能学会发出有序的反应序列。
Does this mean that the perceptron is capable, without further modification in principle, of such higher order functions as are involved in human speech, communication, and thinking? Actually, the limit of the perceptron's capabilities seems to lie in the area of relative judgment, and the abstraction of relationships. In its "symbolic behavior," the perceptron shows some striking similarities to Goldstein's brain-damaged patients (5). Responses to definite, concrete stimuli can be learned, even when the proper response calls for the recognition of a number of simultaneous qualifying conditions (such as naming the color if the stimulus is on the left, the shape if it is on the right). As soon as the response calls for the recognition of a relationship between stimuli (such as "Name the object left of the square." or "Indicate the pattern that appeared before the circle."), however, the problem generally becomes excessively difficult for the perceptron. Statistical separability alone does not provide a sufficient basis for higher order abstraction. Some system, more advanced in principle than the perceptron, seems to be required at this point.
这是否意味着,感知机无需原理上的进一步修改,就能实现人类言语、交流和思维所涉及的那些高阶功能?实际上,感知机能力的极限似乎在于相对判断和关系抽象的领域。在其“符号行为”上,感知机与戈尔德施泰因(Goldstein)研究的脑损伤病人(5)有一些惊人的相似之处。对确定、具体的刺激的反应是可以学会的,即使正确的反应需要同时识别若干限定条件(例如刺激在左边时说出颜色,在右边时说出形状)。然而,一旦反应需要识别刺激之间的关系(例如“说出正方形左边的物体名称”或“指出在圆形之前出现的图案”),这个问题对感知机来说通常就变得过于困难。仅靠统计可分性,并不能为高阶抽象提供充分的基础。在这一点上,似乎需要某种在原理上比感知机更先进的系统。
Conclusions and Evaluation
结论与评价
The main conclusions of the theoretical study of the perceptron can be summarized as follows:
In an environment of random stimuli, a system consisting of randomly connected units, subject to the parametric constraints discussed above, can learn to associate specific responses to specific stimuli. Even if many stimuli are associated to each response, they can still be recognized with a better-than-chance probability, although they may resemble one another closely and may activate many of the same sensory inputs to the system.
In such an "ideal environment," the probability of a correct response diminishes towards its original random level as the number of stimuli learned increases.
In such an environment, no basis for generalization exists.
In a "differentiated environment," where each response is associated to a distinct class of mutually correlated, or "similar" stimuli, the probability that a learned association of some specific stimulus will be correctly retained typically approaches a better-than-chance asymptote as the number of stimuli learned by the system increases. This asymptote can be made arbitrarily close to unity by increasing the number of association cells in the system.
In the differentiated environment, the probability that a stimulus which has not been seen before will be correctly recognized and associated to its appropriate class (the probability of correct generalization) approaches the same asymptote as the probability of a correct response to a previously reinforced stimulus. This asymptote will be better than chance if the inequality is met, for the stimulus classes in question.
The performance of the system can be improved by the use of a contour-sensitive projection area, and by the use of a binary response system, in which each response, or "bit," corresponds to some independent feature or attribute of the stimulus.
Trial-and-error learning is possible in bivalent reinforcement systems.
Temporal organizations of both stimulus patterns and responses can be learned by a system which uses only an extension of the original principles of statistical separability, without introducing any major complications in the organization of the system.
The memory of the perceptron is distributed, in the sense that any association may make use of a large proportion of the cells in the system, and the removal of a portion of the association system would not have an appreciable effect on the performance of any one discrimination or association, but would begin to show up as a general deficit in all learned associations.
Simple cognitive sets, selective recall, and spontaneous recognition of the classes present in a given environment are possible. The recognition of relationships in space and time, however, seems to represent a limit to the perceptron's ability to form cognitive abstractions.
感知机理论研究的主要结论可以概括如下:
在随机刺激的环境中,一个由随机连接的单元组成、服从上述参数约束的系统,能够学会把特定反应与特定刺激联结起来。即使与每个反应相联结的刺激很多,它们仍然能以好于随机的概率被识别,尽管这些刺激可能彼此非常相似,并可能激活系统中许多相同的感觉输入。
在这样的“理想环境”中,随着所学刺激数目的增加,正确反应的概率会下降到其最初的随机水平。
在这样的环境中,不存在泛化的基础。
在“分化环境”中,每个反应都与一个由相互关联的或“相似的”刺激组成的独特类别相联结;随着系统所学刺激数目的增加,某个特定刺激的已学联想被正确保持的概率,通常趋近于一个好于随机的渐近值。通过增加系统中联想细胞的数目,可以使这个渐近值任意接近 1。
在分化环境中,一个以前未见过的刺激被正确识别并联结到其适当类别的概率(正确泛化的概率),趋近于与对先前强化过的刺激作出正确反应的概率相同的渐近值。对于所讨论的刺激类别,如果满足不等式 ,这个渐近值就会好于随机。
使用对轮廓敏感的投射区,以及使用二进制反应系统(其中每个反应或“比特”对应于刺激的某个独立特征或属性),可以改善系统的表现。
在双值强化系统中,试错学习是可能的。
刺激模式和反应在时间上的组织,都可以由一个仅仅扩展了统计可分性原有原理的系统学会,而无需在系统组织上引入任何重大的复杂性。
感知机的记忆是分布式的,其含义是:任何联想都可能用到系统中很大一部分细胞;移除联想系统的一部分,不会对任何一项辨别或联想的表现产生明显影响,而会开始表现为所有已学联想的普遍亏损。
简单的认知定势、选择性回忆,以及对给定环境中存在的类别的自发识别,都是可能的。然而,对空间和时间中关系的识别,似乎代表了感知机形成认知抽象的能力极限。
Psychologists, and learning theorists in particular, may now ask: "What has the present theory accomplished, beyond what has already been done in the quantitative theories of Hull, Bush and Mosteller, etc., or physiological theories such as Hebb's?" The present theory is still too primitive, of course, to be considered as a full-fledged rival of existing theories of human learning. Nonetheless, as a first approximation, its chief accomplishment might be stated as follows:
For a given mode of organization (, , or ; or ; monovalent or bivalent) the fundamental phenomena of learning, perceptual discrimination, and generalization can be predicted entirely from six basic physical parameters, namely:
: the number of excitatory connections per A-unit,
: the number of inhibitory connections per A-unit,
: the expected threshold of an A-unit,
: the proportion of R-units to which an A-unit is connected,
: the number of A-units in the system, and
: the number of R-units in the system.
(the number of sensory units) becomes important if it is very small. It is assumed that the system begins with all units in a uniform state of value; otherwise the initial value distribution would also be required. Each of the above parameters is a clearly defined physical variable, which is measurable in its own right, independently of the behavioral and perceptual phenomena which we are trying to predict.
心理学家,特别是学习理论家,现在可能会问:“除了赫尔(Hull)、布什与莫斯特勒(Bush and Mosteller)等人的定量理论,或赫布那样的生理学理论已经做到的之外,现在这个理论还取得了什么?”当然,现在的理论还太原始,不能被看作现有人类学习理论的成熟对手。尽管如此,作为一级近似,它的主要成就可以表述如下:
对于给定的组织方式(、 或 ; 或 ;单值或双值),学习、知觉辨别和泛化的基本现象,可以完全由六个基本物理参数预测,即:
:每个 A 单元的兴奋性连接数,
:每个 A 单元的抑制性连接数,
:A 单元的期望阈值,
:一个 A 单元所连接的 R 单元所占的比例,
:系统中 A 单元的数目,以及
:系统中 R 单元的数目。
(感觉单元的数目)在非常小时才变得重要。假定系统开始时所有单元都处于均匀的值状态;否则还需要知道初始的值分布。上述每个参数都是定义明确的物理变量,本身就可以测量,而与我们试图预测的行为现象和知觉现象无关。
As a direct consequence of its foundation on physical variables, the present system goes far beyond existing learning and behavior theories in three main points: parsimony, verifiability, and explanatory power and generality. Let us consider each of these points in turn.
- Parsimony. Essentially all of the basic variables and laws used in this system are already present in the structure of physical and biological science, so that we have found it necessary to postulate only one hypothetical variable (or construct) which we have called , the "value" of an association cell; this is a variable which must conform to certain functional characteristics which can clearly be stated, and which is assumed to have a potentially measurable physical correlate.
作为以物理变量为基础的直接结果,现在的系统在三个要点上远远超越了现有的学习理论和行为理论:简约性、可验证性,以及解释力和普遍性。我们依次考察这三点。
- 简约性。 本系统所用的基本变量和定律,基本上都已存在于物理科学和生物科学的结构之中,因此我们只需假设一个假想变量(或构念),即我们所称的 ,联想细胞的“值”;这个变量必须符合某些可以清楚陈述的功能特征,并被假定具有一个潜在可测量的物理对应物。
- Verifiability. Previous quantitative learning theories, apparently without exception, have had one important characteristic in common: they have all been based on measurements of behavior, in specified situations, using these measurements (after theoretical manipulation) to predict behavior in other situations. Such a procedure, in the last analysis, amounts to a process of curve fitting and extrapolation, in the hope that the constants which describe one set of curves will hold good for other curves in other situations. While such extrapolation is not necessarily circular, in the strict sense, it shares many of the logical difficulties of circularity, particularly when used as an "explanation" of behavior. Such extrapolation is difficult to justify in a new situation, and it has been shown that if the basic constants and parameters are to be derived anew for any situation in which they break down empirically (such as change from white rats to humans), then the basic "theory" is essentially irrefutable, just as any successful curve-fitting equation is irrefutable. It has, in fact, been widely conceded by psychologists that there is little point in trying to "disprove" any of the major learning theories in use today, since by extension, or a change in parameters, they have all proved capable of adapting to any specific empirical data. This is epitomized in the increasingly common attitude that a choice of theoretical model is mostly a matter of personal aesthetic preference or prejudice, each scientist being entitled to a favorite model of his own. In considering this approach, one is reminded of a remark attributed to Kistiakowsky, that "given seven parameters, I could fit an elephant." This is clearly not the case with a system in which the independent variables, or parameters, can be measured independently of the predicted behavior. In such a system, it is not possible to "force" a fit to empirical data, if the parameters in current use should lead to improper results. In the current theory, a failure to fit a curve in a new situation would be a clear indication that either the theory or the empirical measurements are wrong. Consequently, if such a theory does hold up for repeated tests, we can be considerably more confident of its validity and of its generality than in the case of a theory which must be hand-tailored to meet each situation.
- 可验证性。 以往的定量学习理论看来无一例外地具有一个重要的共同特征:它们都以在特定情境中对行为的测量为基础,再用这些测量(经过理论处理后)去预测其他情境中的行为。归根结底,这种程序相当于曲线拟合和外推,希望描述一组曲线的常数也适用于其他情境中的其他曲线。虽然严格说来这种外推不一定是循环论证,但它具有循环论证的许多逻辑困难,尤其是在被用作对行为的“解释”时。在新的情境中很难为这种外推辩护;而且已经表明,如果每当基本常数和参数在经验上失效时(例如从白鼠换成人类)都要重新推导它们,那么这个基本“理论”在本质上就是无法反驳的,正如任何成功的曲线拟合方程都无法反驳一样。事实上,心理学家普遍承认,试图“否证”当今使用的任何一个主要学习理论都没有多大意义,因为通过扩展或改变参数,它们都已证明能够适应任何特定的经验数据。这集中体现在一种日益普遍的态度上:选择理论模型主要是个人审美偏好或成见的问题,每个科学家都有权拥有自己钟爱的模型。考虑这种做法时,人们会想起据说是基斯佳科夫斯基(Kistiakowsky)说过的一句话:“给我七个参数,我就能拟合出一头大象。”对于一个其自变量或参数可以独立于所预测行为而测量的系统,情况显然并非如此。在这样的系统中,如果当前所用的参数导致不当的结果,就不可能“强行”拟合经验数据。在现在的理论中,在新情境中拟合曲线失败,就清楚地表明要么理论错了,要么经验测量错了。因此,如果这样一个理论确实经受住了反复检验,我们对其有效性和普遍性的信心,就会比对一个必须针对每种情境量身定做的理论大得多。
- Explanatory power and generality. The present theory, being derived from basic physical variables, is not specific to any one organism or learning situation. It can be generalized in principle to cover any form of behavior in any system for which the physical parameters are known. A theory of learning, constructed on these foundations, should be considerably more powerful than any which has previously been proposed. It would not only tell us what behavior might occur in any known organism, but would permit the synthesis of behaving systems, to meet special requirements. Other learning theories tend to become increasingly qualitative as they are generalized. Thus a set of equations describing the effects of reward on T-maze learning in a white rat reduces simply to a statement that rewarded behavior tends to occur with increasing probability, when we attempt to generalize it from any species and any situation. The theory which has been presented here loses none of its precision through generality.
- 解释力和普遍性。 现在的理论由基本物理变量推导而来,并不专属于任何一种生物或学习情境。原则上,它可以推广到涵盖任何已知物理参数的系统中的任何形式的行为。在这些基础上构建的学习理论,应当比以往提出的任何理论都强大得多。它不仅能告诉我们在任何已知生物中可能出现什么行为,还能让我们合成满足特殊要求的行为系统。其他学习理论在推广时往往变得越来越定性。例如,一组描述奖励对白鼠 T 迷宫学习之影响的方程,当我们试图把它推广到任何物种和任何情境时,就简单地化为这样一个陈述:受奖励的行为倾向于以越来越大的概率出现。这里提出的理论,并不会因普遍性而丧失任何精确性。
The theory proposed by Donald Hebb (7) attempts to avoid these difficulties of behavior-based models by showing how psychological functioning might be derived from neurophysiological theory. In his attempt to achieve this, Hebb's philosophy of approach seems close to our own, and his work has been a source of inspiration for much of what has been proposed here. Hebb, however, has never actually achieved a model by which behavior (or any psychological data) can be predicted from the physiological system. His physiology is more a suggestion as to the sort of organic substrate which might underlie behavior, and an attempt to show the plausibility of a bridge between biophysics and psychology.
唐纳德·赫布(7)提出的理论,试图通过说明心理功能如何能从神经生理学理论中推导出来,来避免基于行为的模型的这些困难。在这一尝试中,赫布的研究思路似乎与我们的相近,他的工作也是这里所提出的许多内容的灵感来源。然而,赫布从未真正建立起一个能够由生理系统预测行为(或任何心理学数据)的模型。他的生理学更像是关于可能构成行为基础的那类有机基质的一种设想,以及表明生物物理学与心理学之间存在一座桥梁的合理性的一种尝试。
The present theory represents the first actual completion of such a bridge. Through the use of the equations in the preceding sections, it is possible to predict learning curves from neurological variables, and likewise, to predict neurological variables from learning curves. How well this bridge stands up to repeated crossings remains to be seen. In the meantime, the theory reported here clearly demonstrates the feasibility and fruitfulness of a quantitative statistical approach to the organization of cognitive systems. By the study of systems such as the perceptron, it is hoped that those fundamental laws of organization which are common to all information handling systems, machines and men included, may eventually be understood.
现在的理论代表着第一次真正建成这样一座桥梁。利用前面各节中的方程,可以由神经学变量预测学习曲线,同样也可以由学习曲线预测神经学变量。这座桥梁经得起多少次反复通行,还有待观察。与此同时,这里报告的理论清楚地表明,用定量统计方法研究认知系统的组织是可行的,也是富有成果的。我们希望,通过研究感知机这样的系统,最终能够理解一切信息处理系统(包括机器和人)所共有的那些基本组织规律。
References
参考文献
- Ashby, W. R. Design for a brain. New York: Wiley, 1952.
- Culbertson, J. T. Consciousness and behavior. Dubuque, Iowa: Wm. C. Brown, 1950.
- Culbertson, J. T. Some uneconomical robots. In C. E. Shannon & J. McCarthy (Eds.), Automata studies. Princeton: Princeton Univer. Press, 1956. Pp. 99–116.
- Eccles, J. C. The neurophysiological basis of mind. Oxford: Clarendon, 1953.
- Goldstein, K. Human nature in the light of psychopathology. Cambridge: Harvard Univer. Press, 1940.
- Hayek, F. A. The sensory order. Chicago: Univer. Chicago Press, 1952.
- Hebb, D. O. The organization of behavior. New York: Wiley, 1949.
- Kleene, S. C. Representation of events in nerve nets and finite automata. In C. E. Shannon & J. McCarthy (Eds.), Automata studies. Princeton: Princeton Univer. Press, 1956. Pp. 3–41.
- Köhler, W. Relational determination in perception. In L. A. Jeffress (Ed.), Cerebral mechanisms in behavior. New York: Wiley, 1951. Pp. 200–243.
- McCulloch, W. S. Why the mind is in the head. In L. A. Jeffress (Ed.), Cerebral mechanisms in behavior. New York: Wiley, 1951. Pp. 42–111.
- McCulloch, W. S., & Pitts, W. A logical calculus of the ideas immanent in nervous activity. Bull. math. Biophysics, 1943, 5, 115–133.
- Milner, P. M. The cell assembly: Mark II. Psychol. Rev., 1957, 64, 242–252.
- Minsky, M. L. Some universal elements for finite automata. In C. E. Shannon & J. McCarthy (Eds.), Automata studies. Princeton: Princeton Univer. Press, 1956. Pp. 117–128.
- Rashevsky, N. Mathematical biophysics. Chicago: Univer. Chicago Press, 1938.
- Rosenblatt, F. The perceptron: A theory of statistical separability in cognitive systems. Buffalo: Cornell Aeronautical Laboratory, Inc. Rep. No. VG-1196-G-1, 1958.
- Uttley, A. M. Conditional probability machines and conditioned reflexes. In C. E. Shannon & J. McCarthy (Eds.), Automata studies. Princeton: Princeton Univer. Press, 1956. Pp. 253–275.
- von Neumann, J. The general and logical theory of automata. In L. A. Jeffress (Ed.), Cerebral mechanisms in behavior. New York: Wiley, 1951. Pp. 1–41.
- von Neumann, J. Probabilistic logics and the synthesis of reliable organisms from unreliable components. In C. E. Shannon & J. McCarthy (Eds.), Automata studies. Princeton: Princeton Univer. Press, 1956. Pp. 43–98.
(Received April 23, 1958)
- Ashby, W. R. Design for a brain. New York: Wiley, 1952.
- Culbertson, J. T. Consciousness and behavior. Dubuque, Iowa: Wm. C. Brown, 1950.
- Culbertson, J. T. Some uneconomical robots. In C. E. Shannon & J. McCarthy (Eds.), Automata studies. Princeton: Princeton Univer. Press, 1956. Pp. 99–116.
- Eccles, J. C. The neurophysiological basis of mind. Oxford: Clarendon, 1953.
- Goldstein, K. Human nature in the light of psychopathology. Cambridge: Harvard Univer. Press, 1940.
- Hayek, F. A. The sensory order. Chicago: Univer. Chicago Press, 1952.
- Hebb, D. O. The organization of behavior. New York: Wiley, 1949.
- Kleene, S. C. Representation of events in nerve nets and finite automata. In C. E. Shannon & J. McCarthy (Eds.), Automata studies. Princeton: Princeton Univer. Press, 1956. Pp. 3–41.
- Köhler, W. Relational determination in perception. In L. A. Jeffress (Ed.), Cerebral mechanisms in behavior. New York: Wiley, 1951. Pp. 200–243.
- McCulloch, W. S. Why the mind is in the head. In L. A. Jeffress (Ed.), Cerebral mechanisms in behavior. New York: Wiley, 1951. Pp. 42–111.
- McCulloch, W. S., & Pitts, W. A logical calculus of the ideas immanent in nervous activity. Bull. math. Biophysics, 1943, 5, 115–133.
- Milner, P. M. The cell assembly: Mark II. Psychol. Rev., 1957, 64, 242–252.
- Minsky, M. L. Some universal elements for finite automata. In C. E. Shannon & J. McCarthy (Eds.), Automata studies. Princeton: Princeton Univer. Press, 1956. Pp. 117–128.
- Rashevsky, N. Mathematical biophysics. Chicago: Univer. Chicago Press, 1938.
- Rosenblatt, F. The perceptron: A theory of statistical separability in cognitive systems. Buffalo: Cornell Aeronautical Laboratory, Inc. Rep. No. VG-1196-G-1, 1958.
- Uttley, A. M. Conditional probability machines and conditioned reflexes. In C. E. Shannon & J. McCarthy (Eds.), Automata studies. Princeton: Princeton Univer. Press, 1956. Pp. 253–275.
- von Neumann, J. The general and logical theory of automata. In L. A. Jeffress (Ed.), Cerebral mechanisms in behavior. New York: Wiley, 1951. Pp. 1–41.
- von Neumann, J. Probabilistic logics and the synthesis of reliable organisms from unreliable components. In C. E. Shannon & J. McCarthy (Eds.), Automata studies. Princeton: Princeton Univer. Press, 1956. Pp. 43–98.
(1958 年 4 月 23 日收稿)