Realtime Multi-Person 2D Pose Estimation using Part Affinity Fields
Realtime Multi-Person 2D Pose Estimation using Part Affinity Fields *
用部位亲和场进行实时多人二维姿态估计 *
*Video result: https://youtu.be/pW6nZXeWlGM
Abstract
摘要
We present an approach to efficiently detect the 2D pose of multiple people in an image. The approach uses a non-parametric representation, which we refer to as Part Affinity Fields (PAFs), to learn to associate body parts with individuals in the image. The architecture encodes global context, allowing a greedy bottom-up parsing step that maintains high accuracy while achieving realtime performance, irrespective of the number of people in the image. The architecture is designed to jointly learn part locations and their association via two branches of the same sequential prediction process. Our method placed first in the inaugural COCO 2016 keypoints challenge, and significantly exceeds the previous state-of-the-art result on the MPII Multi-Person benchmark, both in performance and efficiency.
我们提出一种方法,用于在图像中高效检测多个人的二维姿态。该方法使用一种非参数表示——我们称之为部位亲和场(Part Affinity Fields,PAFs)——来学习把身体部位与图像中的各个个体对应起来。这一结构能够编码全局上下文,从而允许采用贪心的自下而上解析步骤:在保持较高精度的同时实现实时性能,而且不随图像中的人数而变。该结构通过同一迭代预测过程中的两个分支,联合学习部位位置及其关联。我们的方法在首届 COCO 2016 关键点挑战中获得第一名,并在 MPII 多人基准上从性能和效率两方面都显著超过此前的最好结果。
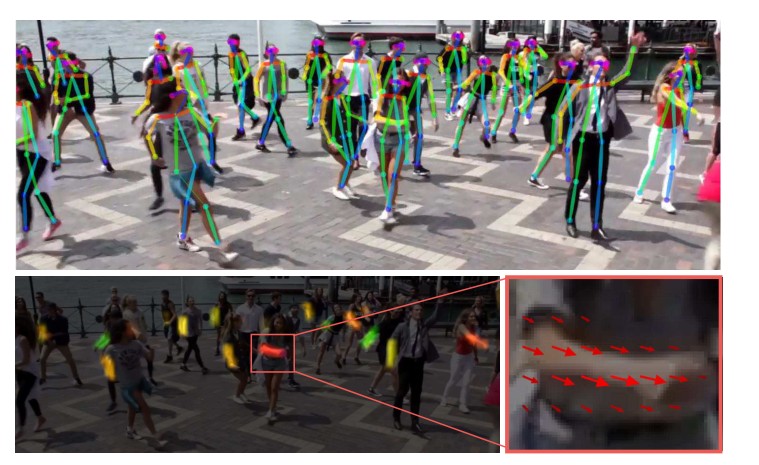
Figure 1. Top: Multi-person pose estimation. Body parts belonging to the same person are linked. Bottom left: Part Affinity Fields (PAFs) corresponding to the limb connecting right elbow and right wrist. The color encodes orientation. Bottom right: A zoomed in view of the predicted PAFs. At each pixel in the field, a 2D vector encodes the position and orientation of the limbs.
图 1. 上:多人姿态估计。属于同一个人的身体部位被连在一起。左下:对应右肘与右腕之间肢段的部位亲和场(PAFs)。颜色编码方向。右下:预测得到的 PAFs 的放大视图。场中每个像素处,一个二维向量编码肢段的位置和方向。
1. Introduction
1. 引言
Human 2D pose estimation—the problem of localizing anatomical keypoints or “parts”—has largely focused on finding body parts of individuals [8, 4, 3, 21, 33, 13, 25, 31, 6, 24]. Inferring the pose of multiple people in images, especially socially engaged individuals, presents a unique set of challenges. First, each image may contain an unknown number of people that can occur at any position or scale. Second, interactions between people induce complex spatial interference, due to contact, occlusion, and limb articulations, making association of parts difficult. Third, runtime complexity tends to grow with the number of people in the image, making realtime performance a challenge.
人体二维姿态估计——也就是定位解剖关键点或称“部位”的问题——以往主要集中在找出单个人的身体部位 [8, 4, 3, 21, 33, 13, 25, 31, 6, 24]。要推断图像中多个人的姿态,尤其是处于社交互动中的人,会带来一组独特的困难。第一,每张图像中的人数事先未知,人可能出现在任意位置、处于任意尺度。第二,人与人之间的互动会带来复杂的空间干扰:接触、遮挡和肢体交错都会让部位归属变得困难。第三,运行复杂度往往随图像中的人数增加,实时性能因此不易保证。
A common approach [23, 9, 27, 12, 19] is to employ a person detector and perform single-person pose estimation for each detection. These top-down approaches directly leverage existing techniques for single-person pose estimation [17, 31, 18, 28, 29, 7, 30, 5, 6, 20], but suffer from early commitment: if the person detector fails–as it is prone to do when people are in close proximity–there is no recourse to recovery. Furthermore, the runtime of these top-down approaches is proportional to the number of people: for each detection, a single-person pose estimator is run, and the more people there are, the greater the computational cost. In contrast, bottom-up approaches are attractive as they offer robustness to early commitment and have the potential to decouple runtime complexity from the number of people in the image. Yet, bottom-up approaches do not directly use global contextual cues from other body parts and other people. In practice, previous bottom-up methods [22, 11] do not retain the gains in efficiency as the final parse requires costly global inference. For example, the seminal work of Pishchulin et al. [22] proposed a bottom-up approach that jointly labeled part detection candidates and associated them to individual people. However, solving the integer linear programming problem over a fully connected graph is an NP-hard problem and the average processing time is on the order of hours. Insafutdinov et al. [11] built on [22] with stronger part detectors based on ResNet [10] and image-dependent pairwise scores, and vastly improved the runtime, but the method still takes several minutes per image, with a limit on the number of part proposals. The pairwise representations used in [11], are difficult to regress precisely and thus a separate logistic regression is required.
一种常见做法 [23, 9, 27, 12, 19] 是先使用行人检测器,再对每个检测框做单人姿态估计。这类自上而下的方法可以直接借用已有的单人姿态估计技术 [17, 31, 18, 28, 29, 7, 30, 5, 6, 20],但存在过早承诺的问题:一旦行人检测失败——在人靠得很近时这很常见——后面就没有补救余地。此外,这类自上而下方法的运行时间与人数成正比:每个检测框都要跑一次单人姿态估计,人越多,计算代价越大。相比之下,自下而上的方法更有吸引力,因为它们对过早承诺更有韧性,也有可能把运行复杂度与图像中的人数解开。不过,自下而上的方法并不能直接使用来自其他身体部位和其他人的全局上下文线索。实践中,以往的自下而上方法 [22, 11] 并没有把效率上的优势保住,因为最后的解析仍需要昂贵的全局推断。例如,Pishchulin 等人的开创性工作 [22] 提出一种自下而上方法,同时对部位检测候选做标注,并把它们归属到各个个体。然而,在全连接图上求解整数线性规划是 NP-hard 问题,平均处理时间要以小时计。Insafutdinov 等人 [11] 在 [22] 的基础上,采用基于 ResNet [10] 的更强部位检测器以及依赖于图像的成对分数,大幅改进了运行时间,但该方法每张图仍需数分钟,并且对部位候选数量有限制。[11] 中使用的成对表示很难精确回归,因此还需要单独做一次逻辑回归。
In this paper, we present an efficient method for multi-person pose estimation with state-of-the-art accuracy on multiple public benchmarks. We present the first bottom-up representation of association scores via Part Affinity Fields (PAFs), a set of 2D vector fields that encode the location and orientation of limbs over the image domain. We demonstrate that simultaneously inferring these bottom-up representations of detection and association encode global context sufficiently well to allow a greedy parse to achieve high-quality results, at a fraction of the computational cost. We have publically released the code for full reproducibility, presenting the first realtime system for multi-person 2D pose detection.
本文提出一种高效的多人姿态估计方法,在多个公开基准上达到当时最好的精度。我们首次用部位亲和场(PAFs)自下而上地表示关联分数:这是一组二维矢量场,在整张图像上编码肢段的位置和方向。我们表明,同时推断检测与关联这两种自下而上的表示,已经能够充分编码全局上下文,从而使贪心解析以远低得多的计算代价得到高质量结果。为了保证可完整复现,我们已经公开发布了代码,并给出了首个用于多人二维姿态检测的实时系统。
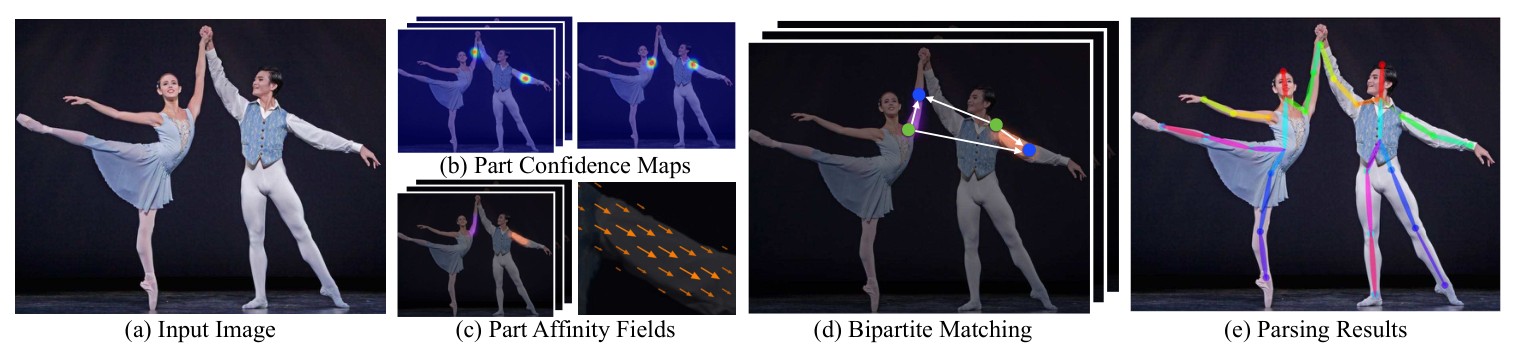
Figure 2. Overall pipeline. Our method takes the entire image as the input for a two-branch CNN to jointly predict confidence maps for body part detection, shown in (b), and part affinity fields for parts association, shown in (c). The parsing step performs a set of bipartite matchings to associate body parts candidates (d). We finally assemble them into full body poses for all people in the image (e).
图 2. 整体流程。方法以整张图像为输入,用双分支 CNN 同时预测用于身体部位检测的置信度图,见 (b),以及用于部位关联的部位亲和场,见 (c)。解析步骤通过一组二分图匹配来关联身体部位候选 (d)。最后把它们组装成图像中所有人的全身姿态 (e)。
2. Method
2. 方法
Fig. 2 illustrates the overall pipeline of our method. The system takes, as input, a color image of size (Fig. 2a) and produces, as output, the 2D locations of anatomical keypoints for each person in the image (Fig. 2e). First, a feed-forward network simultaneously predicts a set of 2D confidence maps of body part locations (Fig. 2b) and a set of 2D vector fields of part affinities, which encode the degree of association between parts (Fig. 2c). The set has confidence maps, one per part, where , . The set has vector fields, one per limb, where , , each image location in encodes a 2D vector (as shown in Fig. 1). Finally, the confidence maps and the affinity fields are parsed by greedy inference (Fig. 2d) to output the 2D keypoints for all people in the image.
图 2 展示了本方法的整体流程。系统的输入是一张大小为 的彩色图像(图 2a),输出则是图像中每个人解剖关键点的二维位置(图 2e)。首先,一个前馈网络同时预测一组表示身体部位位置的二维置信度图 (图 2b),以及一组表示部位亲和的二维矢量场 ,用来编码部位之间的关联程度(图 2c)。集合 含有 张置信度图,每种部位一张,其中 ,。集合 含有 个矢量场,每种肢段一个,其中 ,, 中每个图像位置编码一个二维向量(如图 1 所示)。最后,用贪心推断解析置信度图和亲和场(图 2d),输出图像中所有人的二维关键点。
We refer to part pairs as limbs for clarity, despite the fact that some pairs are not human limbs (e.g., the face).
为表述清楚,我们把部位对称为肢段,尽管有些部位对并不是人体肢体(例如面部)。
2.1. Simultaneous Detection and Association
2.1. 同时进行检测与关联
Our architecture, shown in Fig. 3, simultaneously predicts detection confidence maps and affinity fields that encode part-to-part association. The network is split into two branches: the top branch, shown in beige, predicts the confidence maps, and the bottom branch, shown in blue, predicts the affinity fields. Each branch is an iterative prediction architecture, following Wei et al. [31], which refines the predictions over successive stages, , with intermediate supervision at each stage.
我们的结构如图 3 所示,同时预测检测置信度图,以及编码部位与部位之间关联的亲和场。网络分成两个分支:上方米色分支预测置信度图,下方蓝色分支预测亲和场。每个分支都是一种迭代预测结构,沿用 Wei 等人 [31] 的做法,在相继的各个阶段 上逐步改进预测结果,并在每个阶段加入中间监督。
The image is first analyzed by a convolutional network (initialized by the first 10 layers of VGG-19 [26] and fine-tuned), generating a set of feature maps that is input to the first stage of each branch. At the first stage, the network produces a set of detection confidence maps and a set of part affinity fields , where and are the CNNs for inference at Stage 1. In each subsequent stage, the predictions from both branches in the previous stage, along with the original image features , are concatenated and used to produce refined predictions,
图像首先由一个卷积网络分析(用 VGG-19 [26] 的前 10 层初始化并做微调),得到一组特征图 ,作为每个分支第一阶段的输入。在第一阶段,网络产生一组检测置信度图 ,以及一组部位亲和场 ,其中 和 是第 1 阶段用于推断的 CNN。在此后的每个阶段,前一阶段两个分支的预测与原始图像特征 拼接在一起,用来产生更精细的预测,
where and are the CNNs for inference at Stage .
其中 和 是第 阶段用于推断的 CNN。
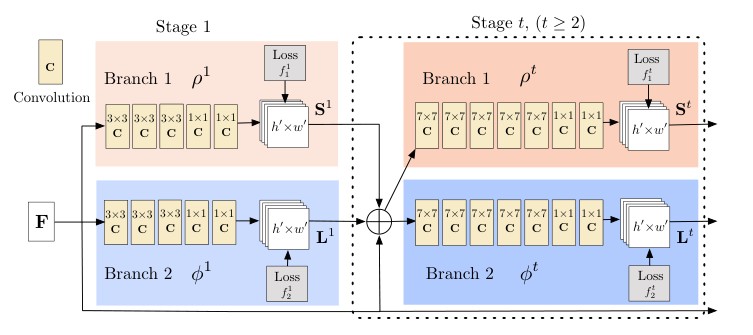
Figure 3. Architecture of the two-branch multi-stage CNN. Each stage in the first branch predicts confidence maps , and each stage in the second branch predicts PAFs . After each stage, the predictions from the two branches, along with the image features, are concatenated for next stage.
图 3. 双分支、多阶段 CNN 的结构。第一分支的每个阶段预测置信度图 ,第二分支的每个阶段预测 PAFs 。每个阶段之后,两个分支的预测与图像特征拼接,送入下一阶段。
Fig. 4 shows the refinement of the confidence maps and affinity fields across stages. To guide the network to iteratively predict confidence maps of body parts in the first branch and PAFs in the second branch, we apply two loss functions at the end of each stage, one at each branch respectively. We use an loss between the estimated predictions and the groundtruth maps and fields. Here, we weight the loss functions spatially to address a practical issue that some datasets do not completely label all people. Specifically, the loss functions at both branches at stage are:
图 4 展示了置信度图和亲和场在各个阶段上的逐步改进。为了引导网络在第一分支中迭代预测身体部位的置信度图,在第二分支中迭代预测 PAFs,我们在每个阶段末尾分别对两个分支各施加一个损失函数。我们在估计预测与真值图、真值场之间使用 损失。在此,我们对损失函数做空间加权,以应对一个实际问题:有些数据集并未把所有人都完整标注。具体而言,第 阶段两个分支上的损失函数为:
where is the groundtruth part confidence map, is the groundtruth part affinity vector field, is a binary mask with when the annotation is missing at an image location . The mask is used to avoid penalizing the true positive predictions during training. The intermediate supervision at each stage addresses the vanishing gradient problem by replenishing the gradient periodically [31]. The overall objective is
其中 是部位置信度图的真值, 是部位亲和矢量场的真值, 是一个二值掩膜:当图像位置 处缺少标注时,。使用该掩膜是为了在训练时避免惩罚本来正确的预测。每个阶段的中间监督通过周期性地补充梯度,来缓解梯度消失问题 [31]。总体目标为
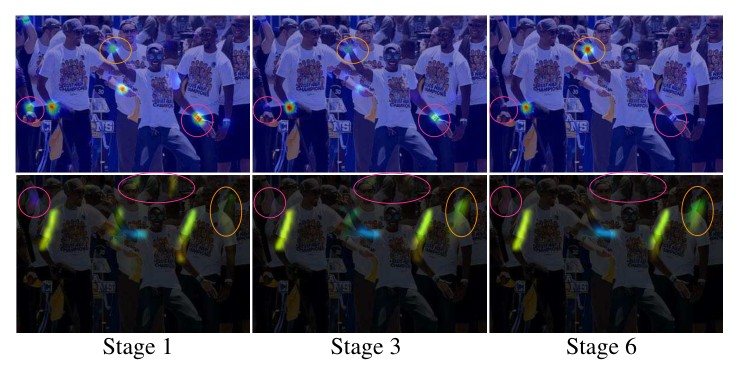
Figure 4. Confidence maps of the right wrist (first row) and PAFs (second row) of right forearm across stages. Although there is confusion between left and right body parts and limbs in early stages, the estimates are increasingly refined through global inference in later stages, as shown in the highlighted areas.
图 4. 各阶段中右腕的置信度图(第一行)以及右前臂的 PAFs(第二行)。尽管在早期阶段,左右身体部位和肢段会出现混淆,但如高亮区域所示,经过后期的全局推断,估计会逐步变得更精细。
2.2. Confidence Maps for Part Detection
2.2. 用于部位检测的置信度图
To evaluate in Eq. (5) during training, we generate the groundtruth confidence maps from the annotated 2D keypoints. Each confidence map is a 2D representation of the belief that a particular body part occurs at each pixel location. Ideally, if a single person occurs in the image, a single peak should exist in each confidence map if the corresponding part is visible; if multiple people occur, there should be a peak corresponding to each visible part for each person .
为了在训练时计算式 (5) 中的 ,我们根据已标注的二维关键点生成置信度图的真值 。每张置信度图都是一种二维表示,刻画某一特定身体部位出现在每个像素位置上的置信程度。理想情况下,如果图像中只有一个人,且对应部位可见,则每张置信度图中应只有一个峰值;如果有多个人,则对每个人 的每个可见部位 ,都应当有一个对应的峰值。
We first generate individual confidence maps for each person . Let be the groundtruth position of body part for person in the image. The value at location in is defined as,
我们首先为每个人 生成各自的置信度图 。设 为图像中第 个人的身体部位 的真值位置。则 在位置 处的取值定义为
where controls the spread of the peak. The groundtruth confidence map to be predicted by the network is an aggregation of the individual confidence maps via a max operator,
其中 控制峰值的展宽。网络所要预测的置信度图真值,由各人的置信度图通过取最大值汇合而成,
We take the maximum of the confidence maps instead of the average so that the precision of close by peaks remains distinct, as illustrated in the right figure. At test time, we predict confidence maps (as shown in the first row of Fig. 4), and obtain body part candidates by performing non-maximum suppression.
我们取置信度图的最大值而不是平均值,是为了让相距较近的峰值仍然能够彼此分开,如右侧插图所示。测试时,我们预测置信度图(如图 4 第一行所示),再通过非极大值抑制得到身体部位候选。
2.3. Part Affinity Fields for Part Association
2.3. 用于部位关联的部位亲和场
Given a set of detected body parts (shown as the red and blue points in Fig. 5a), how do we assemble them to form the full-body poses of an unknown number of people? We need a confidence measure of the association for each pair of body part detections, i.e., that they belong to the same person. One possible way to measure the association is to detect an additional midpoint between each pair of parts on a limb, and check for its incidence between candidate part detections, as shown in Fig. 5b. However, when people crowd together—as they are prone to do—these midpoints are likely to support false associations (shown as green lines in Fig. 5b). Such false associations arise due to two limitations in the representation: (1) it encodes only the position, and not the orientation, of each limb; (2) it reduces the region of support of a limb to a single point.
给定一组检测得到的身体部位(如图 5a 中的红点和蓝点所示),如何把它们组装成人数事先未知的全身姿态?我们需要对每一对身体部位检测给出关联置信度,也就是判断它们是否属于同一个人。一种可能的做法是,在肢段上每一对部位之间再检测一个中点,并检查该中点是否落在候选部位检测之间,如图 5b 所示。然而,当人们挤在一起时——而这又很常见——这些中点很容易支持错误关联(如图 5b 中的绿线所示)。这类错误关联来自该表示的两个局限:(1)它只编码每个肢段的位置,而不编码方向;(2)它把一个肢段的支撑区域压缩成了单个点。
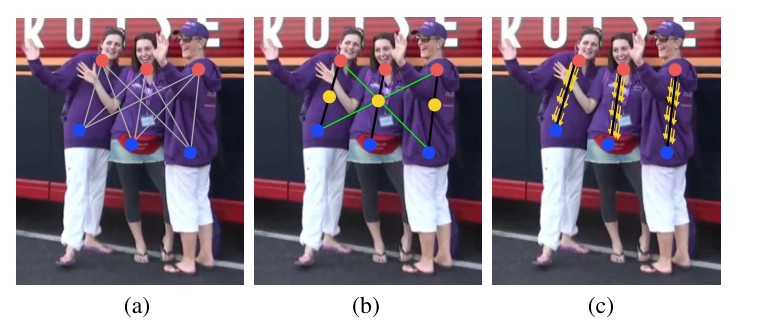
Figure 5. Part association strategies. (a) The body part detection candidates (red and blue dots) for two body part types and all connection candidates (grey lines). (b) The connection results using the midpoint (yellow dots) representation: correct connections (black lines) and incorrect connections (green lines) that also satisfy the incidence constraint. (c) The results using PAFs (yellow arrows). By encoding position and orientation over the support of the limb, PAFs eliminate false associations.
图 5. 部位关联策略。(a) 两类身体部位的检测候选(红点和蓝点)以及全部连接候选(灰线)。(b) 用中点(黄点)表示得到的连接结果:正确连接(黑线),以及同样满足入射约束的错误连接(绿线)。(c) 用 PAFs(黄箭头)得到的结果。通过在肢段支撑区域内同时编码位置和方向,PAFs 消除了错误关联。
To address these limitations, we present a novel feature representation called part affinity fields that preserves both location and orientation information across the region of support of the limb (as shown in Fig. 5c). The part affinity is a 2D vector field for each limb, also shown in Fig. 1d: for each pixel in the area belonging to a particular limb, a 2D vector encodes the direction that points from one part of the limb to the other. Each type of limb has a corresponding affinity field joining its two associated body parts.
为克服这些局限,我们提出一种新的特征表示,称为部位亲和场,它在肢段的整个支撑区域内同时保留位置和方向信息(如图 5c 所示)。部位亲和是每种肢段对应的一个二维矢量场,亦见图 1d:对属于某一特定肢段区域内的每个像素,一个二维向量编码从该肢段一端指向另一端的方向。每类肢段都有一个相应的亲和场,把与它关联的两个身体部位连接起来。
Consider a single limb shown in the figure below. Let and be the groundtruth positions of body parts and from the limb for person in the image. If a point lies on the limb, the value at is a unit vector that points from to ; for all other points, the vector is zero-valued.
考虑下图中的单个肢段。设 和 为图像中第 个人、肢段 上身体部位 与 的真值位置。若点 落在该肢段上,则 的取值是一个从 指向 的单位向量;对其余所有点,该向量为零。
To evaluate in Eq. 5 during training, we define the groundtruth part affinity vector field, , at an image point as
为了在训练时计算式 5 中的 ,我们把部位亲和矢量场的真值 在图像点 处定义为
Here, is the unit vector in the direction of the limb. The set of points on the limb is defined as those within a distance threshold of the line segment, i.e., those points for which
这里, 是沿肢段方向的单位向量。落在肢段上的点集,定义为与该线段距离不超过某一阈值的点,也就是满足下式的点
where the limb width is a distance in pixels, the limb length is , and is a vector perpendicular to .
其中肢段宽度 是以像素计的距离,肢段长度为 , 是与 垂直的向量。
The groundtruth part affinity field averages the affinity fields of all people in the image,
部位亲和场的真值,由图像中所有人的亲和场取平均得到,
where is the number of non-zero vectors at point across all people (i.e., the average at pixels where limbs of different people overlap).
其中 是在点 处、对所有 个人统计得到的非零向量个数(也就是在不同人的肢段发生重叠的像素上取平均)。
During testing, we measure association between candidate part detections by computing the line integral over the corresponding PAF, along the line segment connecting the candidate part locations. In other words, we measure the alignment of the predicted PAF with the candidate limb that would be formed by connecting the detected body parts. Specifically, for two candidate part locations and , we sample the predicted part affinity field, along the line segment to measure the confidence in their association:
测试时,我们沿着连接候选部位位置的线段,对相应的 PAF 做线积分,以此来度量候选部位检测之间的关联。换句话说,我们度量预测得到的 PAF 与由检测到的身体部位连接而成的候选肢段之间的对齐程度。具体而言,对两个候选部位位置 和 ,我们沿该线段对预测的部位亲和场 采样,以度量它们关联的置信度:
where interpolates the position of the two body parts and ,
其中 在两个身体部位 与 的位置之间做插值,
In practice, we approximate the integral by sampling and summing uniformly-spaced values of .
实践中,我们通过对均匀间隔的 取值采样并求和,来近似这一积分。
2.4. Multi-Person Parsing using PAFs
2.4. 用 PAFs 做多人解析
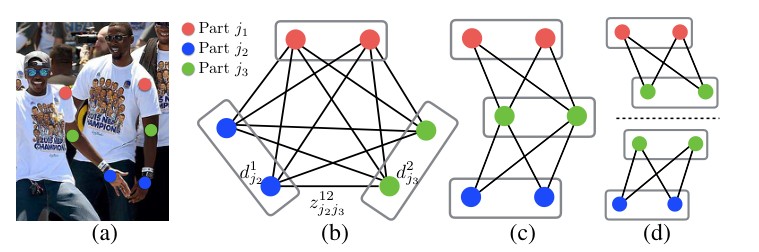
Figure 6. Graph matching. (a) Original image with part detections (b) -partite graph (c) Tree structure (d) A set of bipartite graphs
图 6. 图匹配。(a) 带有部位检测的原始图像 (b) 部图 (c) 树结构 (d) 一组二分图
We perform non-maximum suppression on the detection confidence maps to obtain a discrete set of part candidate locations. For each part, we may have several candidates, due to multiple people in the image or false positives (shown in Fig. 6b). These part candidates define a large set of possible limbs. We score each candidate limb using the line integral computation on the PAF, defined in Eq. 10. The problem of finding the optimal parse corresponds to a -dimensional matching problem that is known to be NP-Hard [32] (shown in Fig. 6c). In this paper, we present a greedy relaxation that consistently produces high-quality matches. We speculate the reason is that the pair-wise association scores implicitly encode global context, due to the large receptive field of the PAF network.
我们在检测置信度图上做非极大值抑制,得到一组离散的部位候选位置。对每种部位,可能会有多个候选,原因是图像中有多个人,或者出现了误检(如图 6b 所示)。这些部位候选定义了一大批可能的肢段。我们用式 10 中定义的、在 PAF 上的线积分来给每个候选肢段打分。寻找最优解析对应一个 维匹配问题,该问题已知是 NP-Hard 的 [32](如图 6c 所示)。本文给出一种贪心松弛,能够稳定地得到高质量匹配。我们推测,其原因在于:由于 PAF 网络具有很大的感受野,成对关联分数已经隐式地编码了全局上下文。
Formally, we first obtain a set of body part detection candidates for multiple people, where , with the number of candidates of part , and is the location of the -th detection candidate of body part . These part detection candidates still need to be associated with other parts from the same person—in other words, we need to find the pairs of part detections that are in fact connected limbs. We define a variable to indicate whether two detection candidates and are connected, and the goal is to find the optimal assignment for the set of all possible connections, .
形式上,我们首先得到多个人的一组身体部位检测候选 ,其中 , 是部位 的候选个数, 是身体部位 的第 个检测候选的位置。这些部位检测候选仍需要与来自同一个人的其他部位关联起来——也就是说,我们需要找出那些实际上构成肢段的部位检测对。我们定义变量 ,用来指示两个检测候选 与 是否相连;目标则是为所有可能连接的集合找出最优分配,该集合为 。
If we consider a single pair of parts and (e.g., neck and right hip) for the -th limb, finding the optimal association reduces to a maximum weight bipartite graph matching problem [32]. This case is shown in Fig. 5b. In this graph matching problem, nodes of the graph are the body part detection candidates and , and the edges are all possible connections between pairs of detection candidates. Additionally, each edge is weighted by Eq. 10—the part affinity aggregate. A matching in a bipartite graph is a subset of the edges chosen in such a way that no two edges share a node. Our goal is to find a matching with maximum weight for the chosen edges,
如果只考虑第 种肢段上的一对部位 和 (例如颈部和右髋),寻找最优关联就归结为最大权二分图匹配问题 [32]。这一情形如图 5b 所示。在该图匹配问题中,图的节点是身体部位检测候选 和 ,边则是检测候选对之间所有可能的连接。此外,每条边的权重由式 10 给出,也就是部位亲和的聚合值。二分图中的一个匹配,是选出的一个边子集,使得其中任意两条边都不共享顶点。我们的目标是为所选的边找到权重最大的匹配,
where is the overall weight of the matching from limb type , is the subset of for limb type , is the part affinity between parts and defined in Eq. 10. Eqs. 13 and 14 enforce no two edges share a node, i.e., no two limbs of the same type (e.g., left forearm) share a part. We can use the Hungarian algorithm [14] to obtain the optimal matching.
其中 是第 类肢段匹配的总权重, 是 中对应于肢段类型 的子集, 是式 10 中定义的、部位 与 之间的部位亲和。式 13 和式 14 约束任意两条边不得共享顶点,也就是同一类型的两个肢段(例如左前臂)不得共享一个部位。我们可以用匈牙利算法 [14] 求得最优匹配。
When it comes to finding the full body pose of multiple people, determining is a -dimensional matching problem. This problem is NP Hard [32] and many relaxations exist. In this work, we add two relaxations to the optimization, specialized to our domain. First, we choose a minimal number of edges to obtain a spanning tree skeleton of human pose rather than using the complete graph, as shown in Fig. 6c. Second, we further decompose the matching problem into a set of bipartite matching subproblems and determine the matching in adjacent tree nodes independently, as shown in Fig. 6d. We show detailed comparison results in Section 3.1, which demonstrate that minimal greedy inference well-approximate the global solution at a fraction of the computational cost. The reason is that the relationship between adjacent tree nodes is modeled explicitly by PAFs, but internally, the relationship between nonadjacent tree nodes is implicitly modeled by the CNN. This property emerges because the CNN is trained with a large receptive field, and PAFs from non-adjacent tree nodes also influence the predicted PAF.
要得到多个人的全身姿态,确定 是一个 维匹配问题。该问题是 NP Hard 的 [32],已有许多松弛方法。在本工作中,我们针对这一特定问题,给优化加上两项松弛。第一,我们只选用最少数量的边,得到人体姿态的一棵生成树骨架,而不是使用完全图,如图 6c 所示。第二,我们进一步把匹配问题分解为一组二分图匹配子问题,并独立地确定相邻树节点上的匹配,如图 6d 所示。我们在第 3.1 节给出详细对比,结果表明:这种最简的贪心推断能够很好地逼近全局解,而计算代价只是后者的一小部分。原因在于,相邻树节点之间的关系由 PAFs 显式建模,而在内部,不相邻树节点之间的关系则由 CNN 隐式建模。这一性质之所以出现,是因为 CNN 在很大的感受野上训练,并且来自不相邻树节点的 PAFs 也会影响所预测的 PAF。
With these two relaxations, the optimization is decomposed simply as:
有了这两项松弛,优化便可简单地分解为:
We therefore obtain the limb connection candidates for each limb type independently using Eqns. 12- 14. With all limb connection candidates, we can assemble the connections that share the same part detection candidates into full-body poses of multiple people. Our optimization scheme over the tree structure is orders of magnitude faster than the optimization over the fully connected graph [22, 11].
因此,我们用式 12–14 为每种肢段类型独立地得到肢段连接候选。有了全部肢段连接候选之后,就可以把共享同一部位检测候选的连接组装成多个人的全身姿态。我们在树结构上的优化方案,比在全连接图上的优化 [22, 11] 要快几个数量级。
3. Results
3. 结果
We evaluate our method on two benchmarks for multi-person pose estimation: (1) the MPII human multi-person dataset [2] and (2) the COCO 2016 keypoints challenge dataset [15]. These two datasets collect images in diverse scenarios that contain many real-world challenges such as crowding, scale variation, occlusion, and contact. Our approach set the state-of-the-art on the inaugural COCO 2016 keypoints challenge [1], and significantly exceeds the previous state-of-the-art result on the MPII multi-person benchmark. We also provide runtime analysis to quantify the efficiency of the system. Fig. 10 shows some qualitative results from our algorithm.
我们在两个多人姿态估计基准上评测本方法:(1)MPII 人体多人数据集 [2];(2)COCO 2016 关键点挑战数据集 [15]。这两个数据集收录了多样场景中的图像,包含拥挤、尺度变化、遮挡和接触等许多现实困难。我们的方法在首届 COCO 2016 关键点挑战 [1] 中达到当时最好成绩,并在 MPII 多人基准上显著超过此前的最好结果。我们还提供运行时间分析,以量化系统的效率。图 10 给出了本算法的一些定性结果。
| Method | Hea | Sho | Elb | Wri | Hip | Kne | Ank | mAP | s/image |
|---|---|---|---|---|---|---|---|---|---|
| Subset of 288 images as in [22] | |||||||||
| Deepcut [22] | 73.4 | 71.8 | 57.9 | 39.9 | 56.7 | 44.0 | 32.0 | 54.1 | 57995 |
| Iqbal et al. [12] | 70.0 | 65.2 | 56.4 | 46.1 | 52.7 | 47.9 | 44.5 | 54.7 | 10 |
| DeeperCut [11] | 87.9 | 84.0 | 71.9 | 63.9 | 68.8 | 63.8 | 58.1 | 71.2 | 230 |
| Ours | 93.7 | 91.4 | 81.4 | 72.5 | 77.7 | 73.0 | 68.1 | 79.7 | 0.005 |
| Full testing set | |||||||||
| DeeperCut [11] | 78.4 | 72.5 | 60.2 | 51.0 | 57.2 | 52.0 | 45.4 | 59.5 | 485 |
| Iqbal et al. [12] | 58.4 | 53.9 | 44.5 | 35.0 | 42.2 | 36.7 | 31.1 | 43.1 | 10 |
| Ours (one scale) | 89.0 | 84.9 | 74.9 | 64.2 | 71.0 | 65.6 | 58.1 | 72.5 | 0.005 |
| Ours | 91.2 | 87.6 | 77.7 | 66.8 | 75.4 | 68.9 | 61.7 | 75.6 | 0.005 |
Table 1. Results on the MPII dataset. Top: Comparison result on the testing subset. Middle: Comparison results on the whole testing set. Testing without scale search is denoted as “(one scale)”.
| 方法 | 头 | 肩 | 肘 | 腕 | 髋 | 膝 | 踝 | mAP | 秒/图 |
|---|---|---|---|---|---|---|---|---|---|
| 与 [22] 相同的 288 张图像子集 | |||||||||
| Deepcut [22] | 73.4 | 71.8 | 57.9 | 39.9 | 56.7 | 44.0 | 32.0 | 54.1 | 57995 |
| Iqbal et al. [12] | 70.0 | 65.2 | 56.4 | 46.1 | 52.7 | 47.9 | 44.5 | 54.7 | 10 |
| DeeperCut [11] | 87.9 | 84.0 | 71.9 | 63.9 | 68.8 | 63.8 | 58.1 | 71.2 | 230 |
| 本文 | 93.7 | 91.4 | 81.4 | 72.5 | 77.7 | 73.0 | 68.1 | 79.7 | 0.005 |
| 完整测试集 | |||||||||
| DeeperCut [11] | 78.4 | 72.5 | 60.2 | 51.0 | 57.2 | 52.0 | 45.4 | 59.5 | 485 |
| Iqbal et al. [12] | 58.4 | 53.9 | 44.5 | 35.0 | 42.2 | 36.7 | 31.1 | 43.1 | 10 |
| 本文(单一尺度) | 89.0 | 84.9 | 74.9 | 64.2 | 71.0 | 65.6 | 58.1 | 72.5 | 0.005 |
| 本文 | 91.2 | 87.6 | 77.7 | 66.8 | 75.4 | 68.9 | 61.7 | 75.6 | 0.005 |
表 1. MPII 数据集上的结果。上:在测试子集上的对比。中:在完整测试集上的对比。不做尺度搜索的测试记为“(单一尺度)”。
| Method | Hea | Sho | Elb | Wri | Hip | Kne | Ank | mAP | s/image |
|---|---|---|---|---|---|---|---|---|---|
| Fig. 6b | 91.8 | 90.8 | 80.6 | 69.5 | 78.9 | 71.4 | 63.8 | 78.3 | 362 |
| Fig. 6c | 92.2 | 90.8 | 80.2 | 69.2 | 78.5 | 70.7 | 62.6 | 77.6 | 43 |
| Fig. 6d | 92.0 | 90.7 | 80.0 | 69.4 | 78.4 | 70.1 | 62.3 | 77.4 | 0.005 |
| Fig. 6d (sep) | 92.4 | 90.4 | 80.9 | 70.8 | 79.5 | 73.1 | 66.5 | 79.1 | 0.005 |
Table 2. Comparison of different structures on our validation set.
| 方法 | 头 | 肩 | 肘 | 腕 | 髋 | 膝 | 踝 | mAP | 秒/图 |
|---|---|---|---|---|---|---|---|---|---|
| 图 6b | 91.8 | 90.8 | 80.6 | 69.5 | 78.9 | 71.4 | 63.8 | 78.3 | 362 |
| 图 6c | 92.2 | 90.8 | 80.2 | 69.2 | 78.5 | 70.7 | 62.6 | 77.6 | 43 |
| 图 6d | 92.0 | 90.7 | 80.0 | 69.4 | 78.4 | 70.1 | 62.3 | 77.4 | 0.005 |
| 图 6d(分开训练) | 92.4 | 90.4 | 80.9 | 70.8 | 79.5 | 73.1 | 66.5 | 79.1 | 0.005 |
表 2. 在我们的验证集上比较不同结构。
3.1. Results on the MPII Multi-Person Dataset
3.1. 在 MPII 多人数据集上的结果
For comparison on the MPII dataset, we use the toolkit [22] to measure mean Average Precision (mAP) of all body parts based on the PCKh threshold. Table 1 compares mAP performance between our method and other approaches on the same subset of 288 testing images as in [22], and the entire MPI testing set, and self-comparison on our own validation set. Besides these measures, we compare the average inference/optimization time per image in seconds. For the 288 images subset, our method outperforms previous state-of-the-art bottom-up methods [11] by 8.5% mAP. Remarkably, our inference time is 6 orders of magnitude less. We report a more detailed runtime analysis in Section 3.3. For the entire MPII testing set, our method without scale search already outperforms previous state-of-the-art methods by a large margin, i.e., 13% absolute increase on mAP. Using a 3 scale search (, and ) further increases the performance to 75.6% mAP. The mAP comparison with previous bottom-up approaches indicate the effectiveness of our novel feature representation, PAFs, to associate body parts. Based on the tree structure, our greedy parsing method achieves better accuracy than a graphcut optimization formula based on a fully connected graph structure [22, 11].
为在 MPII 数据集上做比较,我们使用工具包 [22],按 PCKh 阈值测量所有身体部位的平均精度均值(mAP)。表 1 比较了本方法与其他方法在与 [22] 相同的 288 张测试图像子集上的 mAP,以及在整个 MPII 测试集上的结果,并在我们自己的验证集上做了自身对比。除这些指标外,我们还比较了每张图像平均推断/优化时间(以秒计)。在 288 张图像的子集上,本方法比此前最好的自下而上方法 [11] 高出 8.5 个百分点的 mAP。更突出的是,我们的推断时间要少 6 个数量级。更详细的运行时间分析见第 3.3 节。在整个 MPII 测试集上,即使不做尺度搜索,本方法也已经大幅超过此前的最好方法,也就是 mAP 绝对提高 13 个百分点。使用 3 个尺度的搜索(、 和 )后,性能进一步提高到 75.6% mAP。与以往自下而上方法的 mAP 对比表明,我们这种新的特征表示——PAFs——在关联身体部位上是有效的。基于树结构,我们的贪心解析方法比基于全连接图结构的图割优化形式 [22, 11] 取得了更高的精度。
In Table 2, we show comparison results on different skeleton structures as shown in Fig. 6 on our validation set, i.e., 343 images excluded from the MPII training set. We train our model based on a fully connected graph, and compare results by selecting all edges (Fig. 6b, approximately solved by Integer Linear Programming), and minimal tree edges (Fig. 6c, approximately solved by Integer Linear Programming, and Fig. 6d, solved by the greedy algorithm presented in this paper). Their similar performance shows that it suffices to use minimal edges. We trained another model that only learns the minimal edges to fully utilize the network capacity—the method presented in this paper—that is denoted as Fig. 6d (sep). This approach outperforms Fig. 6c and even Fig. 6b, while maintaining efficiency. The reason is that the much smaller number of part association channels (13 edges of a tree vs 91 edges of a graph) makes it easier for training convergence.
表 2 给出了在我们的验证集上、按图 6 所示不同骨架结构得到的对比结果;该验证集是从 MPII 训练集中排除的 343 张图像。我们在全连接图的基础上训练模型,并比较选用全部边(图 6b,用整数线性规划近似求解)以及最少量的树边(图 6c,用整数线性规划近似求解;图 6d,用本文提出的贪心算法求解)时的结果。它们表现相近,说明只用最少量的边就足够了。我们另外训练了一个只学习最少量边的模型,以充分利用网络容量——也就是本文给出的方法——记为图 6d(分开训练)。这一做法超过了图 6c,甚至超过了图 6b,同时仍保持高效。原因在于,部位关联通道的数量少得多(树的 13 条边,相对图的 91 条边),训练也更容易收敛。
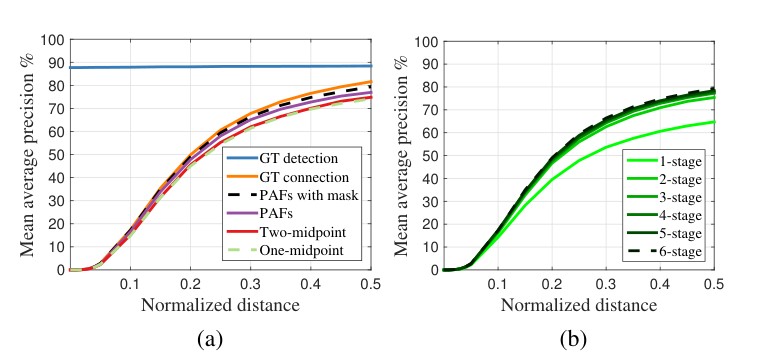
Figure 7. mAP curves over different PCKh threshold on MPII validation set. (a) mAP curves of self-comparison experiments. (b) mAP curves of PAFs across stages.
图 7. MPII 验证集上、在不同 PCKh 阈值下的 mAP 曲线。(a) 自身对比实验的 mAP 曲线。(b) 各阶段 PAFs 的 mAP 曲线。
Fig. 7a shows an ablation analysis on our validation set. For the threshold of PCKh-0.5, the result using PAFs outperforms the results using the midpoint representation, specifically, it is 2.9% higher than one-midpoint and 2.3% higher than two intermediate points. The PAFs, which encodes both position and orientation information of human limbs, is better able to distinguish the common cross-over cases, e.g., overlapping arms. Training with masks of unlabeled persons further improves the performance by 2.3% because it avoids penalizing the true positive prediction in the loss during training. If we use the ground-truth keypoint location with our parsing algorithm, we can obtain a mAP of 88.3%. In Fig. 7a, the mAP of our parsing with GT detection is constant across different PCKh thresholds due to no localization error. Using GT connection with our keypoint detection achieves a mAP of 81.6%. It is notable that our parsing algorithm based on PAFs achieves a similar mAP as using GT connections (79.4% vs 81.6%). This indicates parsing based on PAFs is quite robust in associating correct part detections. Fig. 7b shows a comparison of performance across stages. The mAP increases monotonically with the iterative refinement framework. Fig. 4 shows the qualitative improvement of the predictions over stages.
图 7a 给出了在我们验证集上的消融分析。在 PCKh-0.5 阈值下,使用 PAFs 的结果优于使用中点表示的结果:具体来说,比单中点高 2.9 个百分点,比两个中间点高 2.3 个百分点。PAFs 同时编码人体肢段的位置和方向信息,因而更能分辨常见的交叉情形,例如重叠的手臂。用未标注人的掩膜来训练,还可以再提高 2.3 个百分点,因为它避免了在训练损失中惩罚本来正确的预测。如果把真值关键点位置交给我们的解析算法,可以得到 88.3% 的 mAP。在图 7a 中,用真值检测再加以我们的解析,其 mAP 在不同 PCKh 阈值下保持不变,因为没有定位误差。用真值连接再配合我们的关键点检测,可以得到 81.6% 的 mAP。值得注意的是,基于 PAFs 的解析算法得到的 mAP 与使用真值连接十分接近(79.4% 对 81.6%)。这表明基于 PAFs 的解析在关联正确的部位检测时相当稳健。图 7b 比较了不同阶段的性能。在迭代改进框架下,mAP 单调上升。图 4 展示了预测结果随阶段推进的定性改进。
3.2. Results on the COCO Keypoints Challenge
3.2. 在 COCO 关键点挑战上的结果
The COCO training set consists of over 100K person instances labeled with over 1 million total keypoints (i.e. body parts). The testing set contains “test-challenge”, “test-dev” and “test-standard” subsets, which have roughly 20K images each. The COCO evaluation defines the object keypoint similarity (OKS) and uses the mean average precision (AP) over 10 OKS thresholds as main competition metric [1]. The OKS plays the same role as the IoU in object detection. It is calculated from scale of the person and the distance between predicted points and GT points. Table 3 shows results from top teams in the challenge. It is noteworthy that our method has lower accuracy than the top-down methods on people of smaller scales (AP). The reason is that our method has to deal with a much larger scale range spanned by all people in the image in one shot. In contrast, top-down methods can rescale the patch of each detected area to a larger size and thus suffer less degradation at smaller scales.
COCO 训练集包含超过 10 万个人体实例,共标注了超过 100 万个关键点(也就是身体部位)。测试集包含 “test-challenge”、“test-dev” 和 “test-standard” 三个子集,每个大约有 2 万张图像。COCO 评测定义了目标关键点相似度(OKS),并以 10 个 OKS 阈值上的平均精度均值(AP)作为主要竞赛指标 [1]。OKS 的作用类似于目标检测中的 IoU。它由人的尺度以及预测点与真值点之间的距离计算得到。表 3 给出了挑战中领先队伍的结果。值得注意的是,在较小尺度的人上(AP),本方法的精度低于自上而下的方法。原因是,本方法必须一次性处理图像中所有人所跨越的、大得多的尺度范围。相比之下,自上而下的方法可以把每个检测区域的图像块放大到更大尺寸,因而在较小尺度上的性能下降更少。
| Team | AP | AP | AP | AP | AP |
|---|---|---|---|---|---|
| Test-challenge | |||||
| Ours | 60.5 | 83.4 | 66.4 | 55.1 | 68.1 |
| G-RMI [19] | 59.8 | 81.0 | 65.1 | 56.7 | 66.7 |
| DL-61 | 53.3 | 75.1 | 48.5 | 55.5 | 54.8 |
| R4D | 49.7 | 74.3 | 54.5 | 45.6 | 55.6 |
| Test-dev | |||||
| Ours | 61.8 | 84.9 | 67.5 | 57.1 | 68.2 |
| G-RMI [19] | 60.5 | 82.2 | 66.2 | 57.6 | 66.6 |
| DL-61 | 54.4 | 75.3 | 50.9 | 58.3 | 54.3 |
| R4D | 51.4 | 75.0 | 55.9 | 47.4 | 56.7 |
Table 3. Results on the COCO 2016 keypoint challenge. Top: results on test-challenge. Bottom: results on test-dev (top methods only). AP is for OKS , AP is for large scale persons.
| 队伍 | AP | AP | AP | AP | AP |
|---|---|---|---|---|---|
| Test-challenge | |||||
| 本文 | 60.5 | 83.4 | 66.4 | 55.1 | 68.1 |
| G-RMI [19] | 59.8 | 81.0 | 65.1 | 56.7 | 66.7 |
| DL-61 | 53.3 | 75.1 | 48.5 | 55.5 | 54.8 |
| R4D | 49.7 | 74.3 | 54.5 | 45.6 | 55.6 |
| Test-dev | |||||
| 本文 | 61.8 | 84.9 | 67.5 | 57.1 | 68.2 |
| G-RMI [19] | 60.5 | 82.2 | 66.2 | 57.6 | 66.6 |
| DL-61 | 54.4 | 75.3 | 50.9 | 58.3 | 54.3 |
| R4D | 51.4 | 75.0 | 55.9 | 47.4 | 56.7 |
表 3. COCO 2016 关键点挑战上的结果。上:test-challenge 上的结果。下:test-dev 上的结果(仅列出领先方法)。AP 对应 OKS ,AP 对应大尺度的人。
| Method | AP | AP | AP | AP | AP |
|---|---|---|---|---|---|
| GT Bbox + CPM [11] | 62.7 | 86.0 | 69.3 | 58.5 | 70.6 |
| SSD [16] + CPM [11] | 52.7 | 71.1 | 57.2 | 47.0 | 64.2 |
| Ours - 6 stages | 58.4 | 81.5 | 62.6 | 54.4 | 65.1 |
| + CPM refinement | 61.0 | 84.9 | 67.5 | 56.3 | 69.3 |
Table 4. Self-comparison experiments on the COCO validation set.
| 方法 | AP | AP | AP | AP | AP |
|---|---|---|---|---|---|
| 真值框 + CPM [11] | 62.7 | 86.0 | 69.3 | 58.5 | 70.6 |
| SSD [16] + CPM [11] | 52.7 | 71.1 | 57.2 | 47.0 | 64.2 |
| 本文,6 个阶段 | 58.4 | 81.5 | 62.6 | 54.4 | 65.1 |
| + CPM 精细化 | 61.0 | 84.9 | 67.5 | 56.3 | 69.3 |
表 4. 在 COCO 验证集上的自身对比实验。
In Table 4, we report self-comparisons on a subset of the COCO validation set, i.e., 1160 images that are randomly selected. If we use the GT bounding box and a single person CPM [31], we can achieve a upper-bound for the top-down approach using CPM, which is 62.7% AP. If we use the state-of-the-art object detector, Single Shot MultiBox Detector (SSD)[16], the performance drops 10%. This comparison indicates the performance of top-down approaches rely heavily on the person detector. In contrast, our bottom-up method achieves 58.4% AP. If we refine the results of our method by applying a single person CPM on each rescaled region of the estimated persons parsed by our method, we gain an 2.6% overall AP increase. Note that we only update estimations on predictions that both methods agree well enough, resulting in improved precision and recall. We expect a larger scale search can further improve the performance of our bottom-up method. Fig. 8 shows a breakdown of errors of our method on the COCO validation set. Most of the false positives come from imprecise localization, other than background confusion. This indicates there is more improvement space in capturing spatial dependencies than in recognizing body parts appearances.
表 4 给出了在 COCO 验证集一个子集上的自身对比,也就是随机选出的 1160 张图像。如果使用真值边界框再加上单人 CPM [31],可以得到用 CPM 做自上而下方法时的上界,即 62.7% AP。如果改用当时最好的目标检测器 Single Shot MultiBox Detector(SSD)[16],性能会下降 10 个百分点。这一对比说明,自上而下方法的表现在很大程度上依赖于行人检测器。相比之下,我们的自下而上方法达到 58.4% AP。如果在本方法解析得到的每个人的缩放区域上再施加单人 CPM,对结果做精细化,总体 AP 还能提高 2.6 个百分点。需要说明的是,我们只在两种方法足够一致的预测上更新估计,从而同时提高了精度和召回。我们预期,更大范围的尺度搜索还能进一步提高这种自下而上方法的性能。图 8 给出了本方法在 COCO 验证集上的误差分解。大多数误检来自定位不够精确,而不是把背景当成了人体。这说明,在刻画空间依赖方面,比在识别身体部位外观方面,还有更大的改进余地。
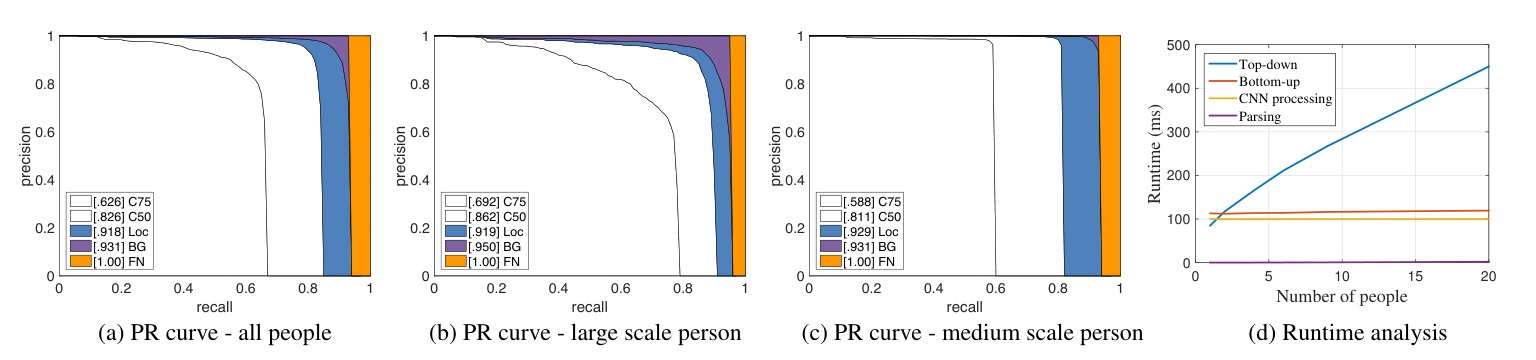
Figure 8. AP performance on COCO validation set in (a), (b), and (c) for Section 3.2, and runtime analysis in (d) for Section 3.3.
图 8. (a)、(b)、(c) 给出第 3.2 节在 COCO 验证集上的 AP 表现,(d) 给出第 3.3 节的运行时间分析。
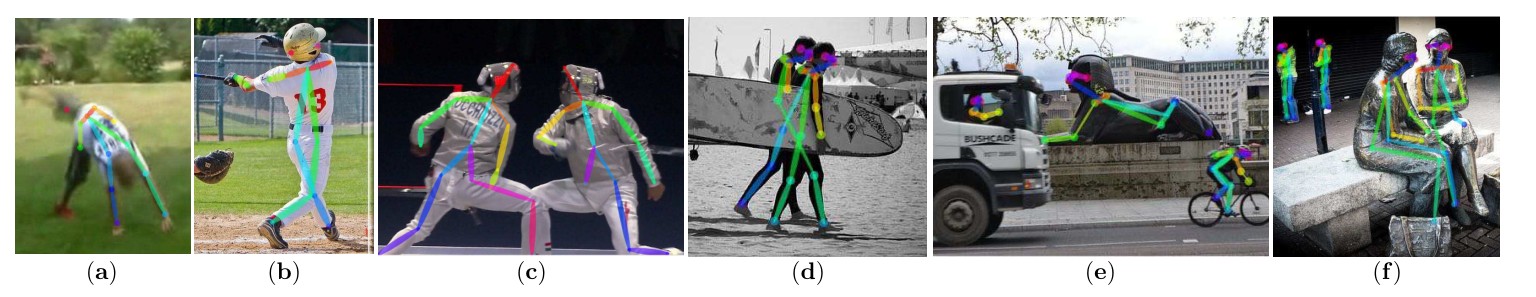
Figure 9. Common failure cases: (a) rare pose or appearance, (b) missing or false parts detection, (c) overlapping parts, i.e., part detections shared by two persons, (d) wrong connection associating parts from two persons, (e-f): false positives on statues or animals.
图 9. 常见失败情形:(a) 罕见姿态或外观,(b) 部位检测缺失或错误,(c) 部位重叠,即两个检测结果被两个人共用,(d) 错误连接,把两个人的部位关联到一起,(e-f):在雕像或动物上出现的误检。
3.3. Runtime Analysis
3.3. 运行时间分析
To analyze the runtime performance of our method, we collect videos with a varying number of people. The original frame size is , which we resize to during testing to fit in GPU memory. The runtime analysis is performed on a laptop with one NVIDIA GeForce GTX-1080 GPU. In Fig. 8d, we use person detection and single-person CPM as a top-down comparison, where the runtime is roughly proportional to the number of people in the image. In contrast, the runtime of our bottom-up approach increases relatively slowly with the increasing number of people. The runtime consists of two major parts: (1) CNN processing time whose runtime complexity is , constant with varying number of people; (2) Multi-person parsing time whose runtime complexity is , where represents the number of people. However, the parsing time does not significantly influence the overall runtime because it is two orders of magnitude less than the CNN processing time, e.g., for 9 people, the parsing takes 0.58 ms while CNN takes 99.6 ms. Our method has achieved the speed of 8.8 fps for a video with 19 people.
为分析本方法的运行时间,我们采集了人数不等的视频。原始帧大小为 ,测试时将其缩放到 ,以便放入 GPU 显存。运行时间分析在一台配备一块 NVIDIA GeForce GTX-1080 GPU 的笔记本电脑上完成。在图 8d 中,我们用行人检测加单人 CPM 作为自上而下的对照,其运行时间大致与图像中的人数成正比。相比之下,我们这种自下而上方法的运行时间随人数增加上升得相对缓慢。运行时间由两大部分组成:(1)CNN 处理时间,其复杂度为 ,不随人数变化;(2)多人解析时间,其复杂度为 ,其中 表示人数。不过,解析时间并不会显著影响总体运行时间,因为它比 CNN 处理时间小两个数量级:例如,在 9 个人时,解析只需 0.58 毫秒,而 CNN 需要 99.6 毫秒。对于一段有 19 个人的视频,本方法达到了 8.8 帧每秒。
4. Discussion
4. 讨论
Moments of social significance, more than anything else, compel people to produce photographs and videos. Our photo collections tend to capture moments of personal significance: birthdays, weddings, vacations, pilgrimages, sports events, graduations, family portraits, and so on. To enable machines to interpret the significance of such photographs, they need to have an understanding of people in images. Machines, endowed with such perception in realtime, would be able to react to and even participate in the individual and social behavior of people.
最能促使人们去拍摄照片和视频的,莫过于那些具有社交意义的时刻。我们的相册往往记录着对个人而言意义重大的瞬间:生日、婚礼、旅行、朝圣、体育赛事、毕业典礼、全家福,等等。要想让机器理解这类照片的意义,它们需要理解图像中的人。若机器具备这样的实时感知能力,便能够对人们的个体与社交行为作出反应,甚至参与其中。
In this paper, we consider a critical component of such perception: realtime algorithms to detect the 2D pose of multiple people in images. We present an explicit nonparametric representation of the keypoints association that encodes both position and orientation of human limbs. Second, we design an architecture for jointly learning parts detection and parts association. Third, we demonstrate that a greedy parsing algorithm is sufficient to produce high-quality parses of body poses, that maintains efficiency even as the number of people in the image increases. We show representative failure cases in Fig. 9. We have publicly released our code (including the trained models) to ensure full reproducibility and to encourage future research in the area.
在本文中,我们讨论这种感知里的一个关键部分:在图像中实时检测多个人二维姿态的算法。我们提出一种显式的非参数表示,用来刻画关键点关联,并同时编码人体肢段的位置和方向。第二,我们设计了一种结构,用于联合学习部位检测和部位关联。第三,我们表明,贪心解析算法已足以得到高质量的人体姿态解析,并且即使图像中人数增加,仍能保持效率。图 9 给出了一些有代表性的失败情形。我们已经公开发布了代码(包括训练好的模型),以保证可完整复现,并推动这一方向的后续研究。
Acknowledgements
致谢
We acknowledge the effort from the authors of the MPII and COCO human pose datasets. These datasets make 2D human pose estimation in the wild possible. This research was supported in part by ONR Grants N00014-15-1-2358 and N00014-14-1-0595.
我们感谢 MPII 与 COCO 人体姿态数据集的作者所付出的努力。正是这些数据集,使野外环境下的二维人体姿态估计成为可能。本研究部分得到 ONR 资助 N00014-15-1-2358 与 N00014-14-1-0595 的支持。
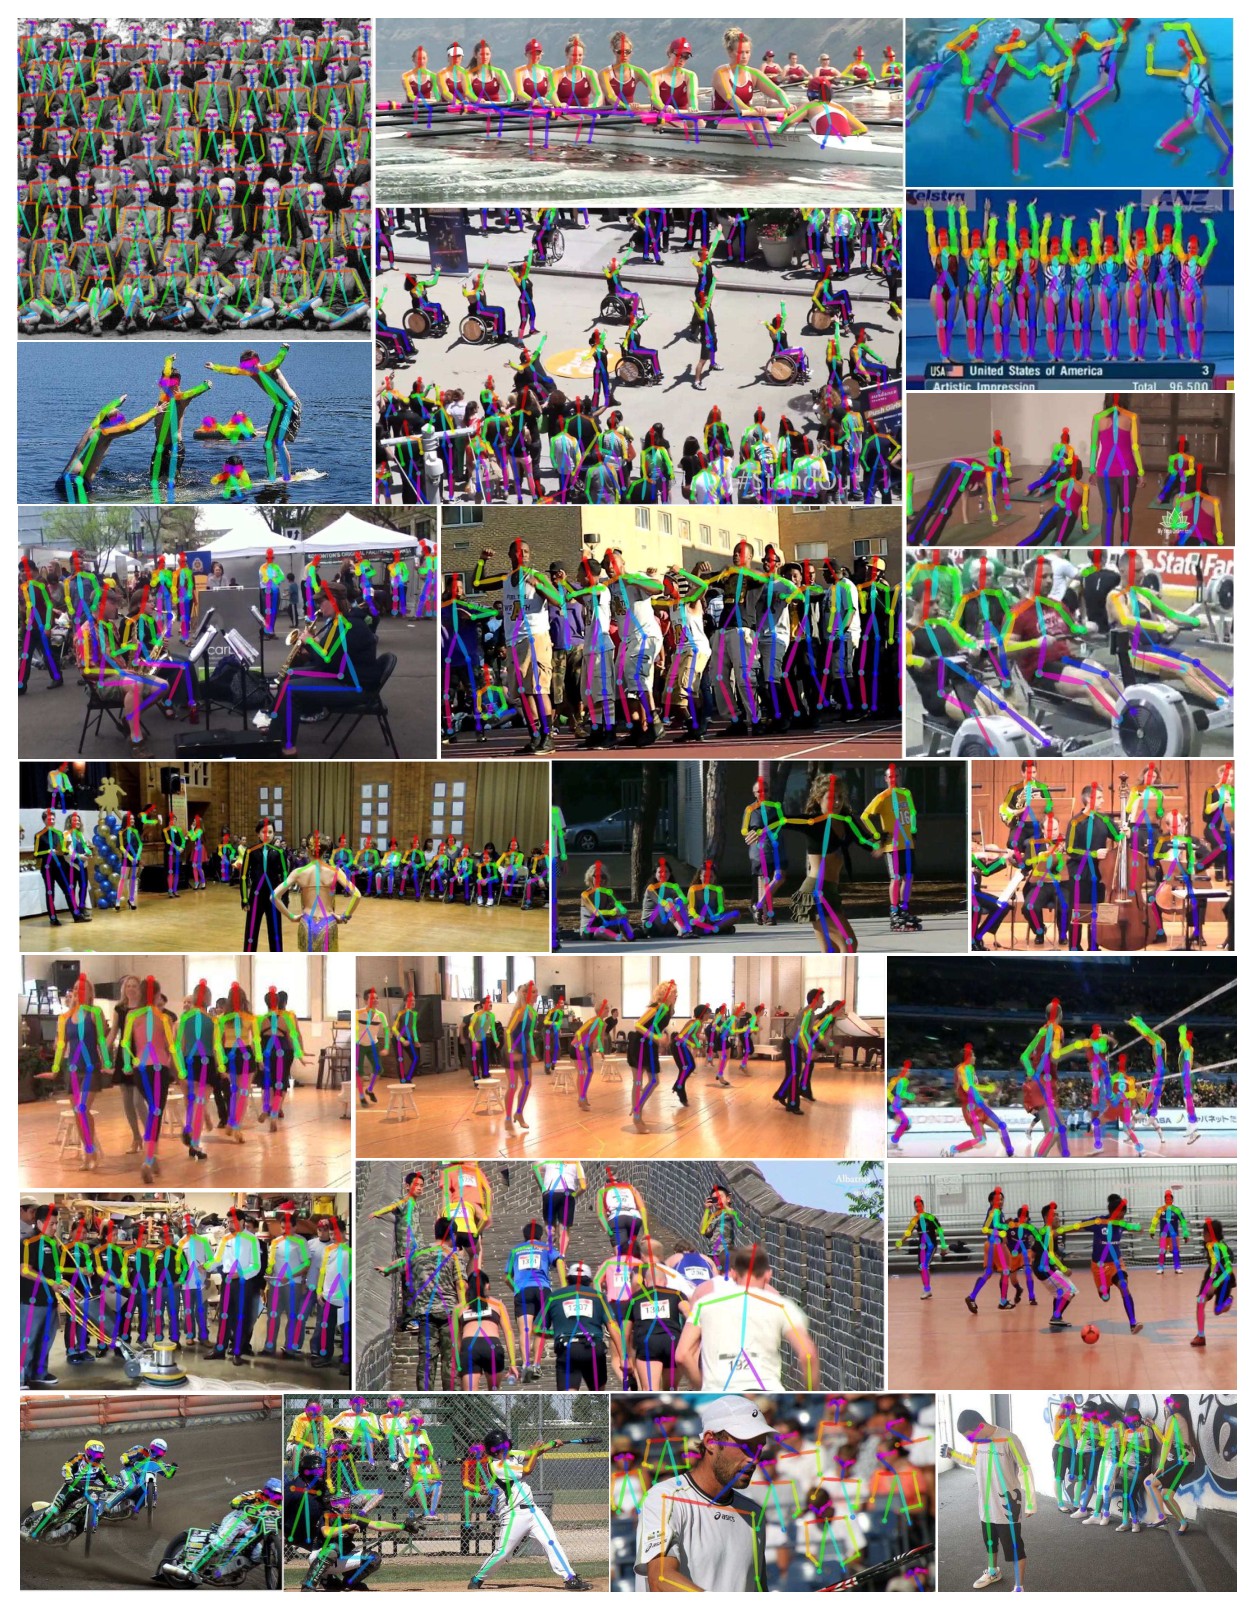
Figure 10. Results containing viewpoint and appearance variation, occlusion, crowding, contact, and other common imaging artifacts.
图 10. 包含视角与外观变化、遮挡、拥挤、接触以及其他常见成像干扰的结果。
References
参考文献
[1] MSCOCO keypoint evaluation metric. http://mscoco.org/dataset/#keypoints-eval. 5, 6
[2] M. Andriluka, L. Pishchulin, P. Gehler, and B. Schiele. 2D human pose estimation: new benchmark and state of the art analysis. In CVPR, 2014. 5
[3] M. Andriluka, S. Roth, and B. Schiele. Pictorial structures revisited: people detection and articulated pose estimation. In CVPR, 2009. 1
[4] M. Andriluka, S. Roth, and B. Schiele. Monocular 3D pose estimation and tracking by detection. In CVPR, 2010. 1
[5] V. Belagiannis and A. Zisserman. Recurrent human pose estimation. In 12th IEEE International Conference and Workshops on Automatic Face and Gesture Recognition (FG), 2017. 1
[6] A. Bulat and G. Tzimiropoulos. Human pose estimation via convolutional part heatmap regression. In ECCV, 2016. 1
[7] X. Chen and A. Yuille. Articulated pose estimation by a graphical model with image dependent pairwise relations. In NIPS, 2014. 1
[8] P. F. Felzenszwalb and D. P. Huttenlocher. Pictorial structures for object recognition. In IJCV, 2005. 1
[9] G. Gkioxari, B. Hariharan, R. Girshick, and J. Malik. Using k-poselets for detecting people and localizing their keypoints. In CVPR, 2014. 1
[10] K. He, X. Zhang, S. Ren, and J. Sun. Deep residual learning for image recognition. In CVPR, 2016. 1
[11] E. Insafutdinov, L. Pishchulin, B. Andres, M. Andriluka, and B. Schiele. Deepercut: A deeper, stronger, and faster multi-person pose estimation model. In ECCV, 2016. 1, 5, 6
[12] U. Iqbal and J. Gall. Multi-person pose estimation with local joint-to-person associations. In ECCV Workshops, Crowd Understanding, 2016. 1, 5
[13] S. Johnson and M. Everingham. Clustered pose and nonlinear appearance models for human pose estimation. In BMVC, 2010. 1
[14] H. W. Kuhn. The hungarian method for the assignment problem. In Naval research logistics quarterly. Wiley Online Library, 1955. 5
[15] T.-Y. Lin, M. Maire, S. Belongie, J. Hays, P. Perona, D. Ramanan, P. Dollár, and C. L. Zitnick. Microsoft COCO: common objects in context. In ECCV, 2014. 5
[16] W. Liu, D. Anguelov, D. Erhan, C. Szegedy, and S. Reed. Ssd: Single shot multibox detector. In ECCV, 2016. 6
[17] A. Newell, K. Yang, and J. Deng. Stacked hourglass networks for human pose estimation. In ECCV, 2016. 1
[18] W. Ouyang, X. Chu, and X. Wang. Multi-source deep learning for human pose estimation. In CVPR, 2014. 1
[19] G. Papandreou, T. Zhu, N. Kanazawa, A. Toshev, J. Tompson, C. Bregler, and K. Murphy. Towards accurate multi-person pose estimation in the wild. arXiv preprint arXiv:1701.01779, 2017. 1, 6
[20] T. Pfister, J. Charles, and A. Zisserman. Flowing convnets for human pose estimation in videos. In ICCV, 2015. 1
[21] L. Pishchulin, M. Andriluka, P. Gehler, and B. Schiele. Poselet conditioned pictorial structures. In CVPR, 2013. 1
[22] L. Pishchulin, E. Insafutdinov, S. Tang, B. Andres, M. Andriluka, P. Gehler, and B. Schiele. Deepcut: Joint subset partition and labeling for multi person pose estimation. In CVPR, 2016. 1, 5
[23] L. Pishchulin, A. Jain, M. Andriluka, T. Thormählen, and B. Schiele. Articulated people detection and pose estimation: Reshaping the future. In CVPR, 2012. 1
[24] V. Ramakrishna, D. Munoz, M. Hebert, J. A. Bagnell, and Y. Sheikh. Pose machines: Articulated pose estimation via inference machines. In ECCV, 2014. 1
[25] D. Ramanan, D. A. Forsyth, and A. Zisserman. Strike a Pose: Tracking people by finding stylized poses. In CVPR, 2005. 1
[26] K. Simonyan and A. Zisserman. Very deep convolutional networks for large-scale image recognition. In ICLR, 2015. 2
[27] M. Sun and S. Savarese. Articulated part-based model for joint object detection and pose estimation. In ICCV, 2011. 1
[28] J. Tompson, R. Goroshin, A. Jain, Y. LeCun, and C. Bregler. Efficient object localization using convolutional networks. In CVPR, 2015. 1
[29] J. J. Tompson, A. Jain, Y. LeCun, and C. Bregler. Joint training of a convolutional network and a graphical model for human pose estimation. In NIPS, 2014. 1
[30] A. Toshev and C. Szegedy. Deeppose: Human pose estimation via deep neural networks. In CVPR, 2014. 1
[31] S.-E. Wei, V. Ramakrishna, T. Kanade, and Y. Sheikh. Convolutional pose machines. In CVPR, 2016. 1, 2, 3, 6
[32] D. B. West et al. Introduction to graph theory, volume 2. Prentice hall Upper Saddle River, 2001. 4, 5
[33] Y. Yang and D. Ramanan. Articulated human detection with flexible mixtures of parts. In TPAMI, 2013. 1