The Curious Case of Neural Text Degeneration
The Curious Case of Neural Text Degeneration
神经文本退化的奇特情形
Ari Holtzman†‡ Jan Buys§† Li Du† Maxwell Forbes†‡ Yejin Choi†‡
†Paul G. Allen School of Computer Science & Engineering, University of Washington
‡Allen Institute for Artificial Intelligence
§Department of Computer Science, University of Cape Town
{ahai,dul2,mbforbes,yejin}@cs.washington.edu, jbuys@cs.uct.ac.za
Abstract
摘要
Despite considerable advances in neural language modeling, it remains an open question what the best decoding strategy is for text generation from a language model (e.g. to generate a story). The counter-intuitive empirical observation is that even though the use of likelihood as training objective leads to high quality models for a broad range of language understanding tasks, maximization-based decoding methods such as beam search lead to degeneration — output text that is bland, incoherent, or gets stuck in repetitive loops.
尽管神经语言建模已经取得了可观进展,从语言模型生成文本(例如写一个故事)时最好的解码策略是什么,仍然是一个开放问题。一个与直觉相反的经验观察是:虽然用似然作为训练目标,能在广泛的语言理解任务上得到高质量模型,但束搜索这类基于最大化的解码方法,却会带来退化(degeneration)——生成的文本平淡、不连贯,或者陷入重复循环。
To address this we propose Nucleus Sampling, a simple but effective method to draw considerably higher quality text out of neural language models than previous decoding strategies. Our approach avoids text degeneration by truncating the unreliable tail of the probability distribution, sampling from the dynamic nucleus of tokens containing the vast majority of the probability mass.
为应对这一问题,我们提出核采样(Nucleus Sampling):这是一种简单而有效的方法,能从神经语言模型中抽出比以往解码策略质量明显更高的文本。我们的做法是截掉概率分布中不可靠的尾巴,改从包含绝大部分概率质量的动态“核”中采样,从而避免文本退化。
To properly examine current maximization-based and stochastic decoding methods, we compare generations from each of these methods to the distribution of human text along several axes such as likelihood, diversity, and repetition. Our results show that (1) maximization is an inappropriate decoding objective for open-ended text generation, (2) the probability distributions of the best current language models have an unreliable tail which needs to be truncated during generation and (3) Nucleus Sampling is currently the best available decoding strategy for generating long-form text that is both high-quality — as measured by human evaluation — and as diverse as human-written text.
为了妥善考察当前基于最大化的解码方法以及随机解码方法,我们沿着似然、多样性和重复等多个轴,把各种方法生成的文本与人类文本的分布加以比较。结果表明:(1)最大化并不是开放式文本生成合适的解码目标;(2)当前最好的语言模型,其概率分布有一条不可靠的尾巴,生成时需要截掉;(3)就生成既高质量(以人工评估衡量)又与人类文本同样多样的长文本而言,核采样是目前最好的解码策略。
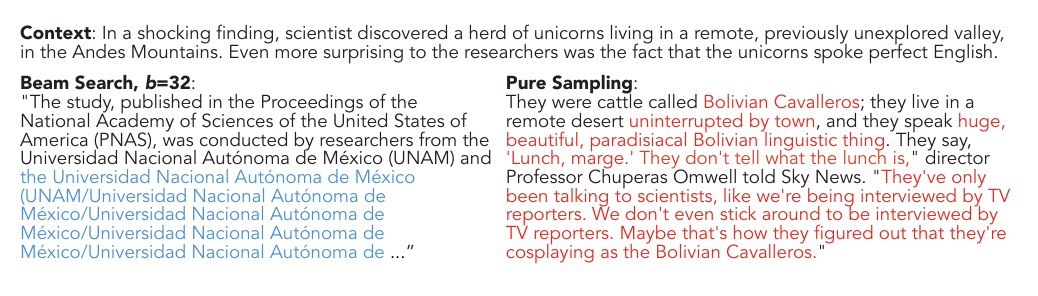
Figure 1: Even with substantial human context and the powerful GPT-2 Large language model, Beam Search (size 32) leads to degenerate repetition (highlighted in blue) while pure sampling leads to incoherent gibberish (highlighted in red). When , both GPT-2 Large and XL (774M and 1542M parameters, respectively) prefer to stop generating immediately after the given context.
图 1:即便有相当长的人类上文,并使用很强的 GPT-2 Large 语言模型,束搜索(大小为 32)仍会导致退化性的重复(蓝色标出),而纯采样则会产生不连贯的胡话(红色标出)。当 时,GPT-2 Large 和 XL(参数量分别为 774M 和 1542M)都更倾向于在给定上文之后立刻停止生成。
1 Introduction
1 引言
On February 14th 2019, OpenAI surprised the scientific community with an impressively high-quality article about Ovid’s Unicorn, written by GPT-2.[^1] Notably, the top-quality generations obtained from the model rely on randomness in the decoding method, in particular through top- sampling that samples the next word from the top most probable choices (Fan et al., 2018; Holtzman et al., 2018; Radford et al., 2019), instead of aiming to decode text that maximizes likelihood.
2019 年 2 月 14 日,OpenAI 用 GPT-2 写出一篇关于 Ovid’s Unicorn、质量令人印象深刻的文章,让科学界吃了一惊。[^1] 值得注意的是,从该模型得到的高质量生成,依赖于解码方法中的随机性,尤其是 top- 采样:下一步只从概率最高的 个词里抽样(Fan et al., 2018; Holtzman et al., 2018; Radford et al., 2019),而不是去解码使似然最大化的文本。
In fact, decoding strategies that optimize for output with high probability, such as beam search, lead to text that is incredibly degenerate, even when using state-of-the-art models such as GPT-2 Large, as shown in Figure 1. This may seem counter-intuitive, as one would expect that good models would assign higher probability to more human-like, grammatical text. Indeed, language models do generally assign high scores to well-formed text, yet the highest scores for longer texts are often generic, repetitive, and awkward. Figure 2 exposes how different the distribution of probabilities assigned to beam search decoded text and naturally occurring text really are.
事实上,像束搜索这样优化高概率输出的解码策略,即使使用 GPT-2 Large 这类当时最强的模型,也会生成极度退化的文本,如图 1 所示。这看起来可能有违直觉,因为人们会以为好模型会给更像人写的、合乎语法的文本更高的概率。语言模型的确通常会给形式良好的文本打高分,可是对较长文本而言,最高的分数往往对应的是泛泛、重复而又别扭的文字。图 2 揭示了:束搜索解码文本与自然出现的文本,二者被赋予的概率分布究竟有多么不同。
Perhaps equally surprising is the right side of Figure 1, which shows that pure sampling — sampling directly from the probabilities predicted by the model — results in text that is incoherent and almost unrelated to the context. Why is text produced by pure sampling so degenerate? In this work we show that the “unreliable tail” is to blame. This unreliable tail is composed of tens of thousands of candidate tokens with relatively low probability that are over-represented in the aggregate.
也许同样出人意料的是图 1 的右侧:纯采样——直接按模型预测的概率抽样——得到的文本不连贯,几乎与上文无关。为什么纯采样产生的文本会如此退化?本文表明,问题出在“不可靠的尾巴”上。这条不可靠的尾巴由成千上万个概率相对较低的候选词组成,它们在合计时被过度代表了。
To overcome these issues we introduce Nucleus Sampling (§3.1). The key intuition of Nucleus Sampling is that the vast majority of probability mass at each time step is concentrated in the nucleus, a small subset of the vocabulary that tends to range between one and a thousand candidates. Instead of relying on a fixed top-, or using a temperature parameter to control the shape of the distribution without sufficiently suppressing the unreliable tail, we propose sampling from the top- portion of the probability mass, expanding and contracting the candidate pool dynamically.
为克服这些问题,我们引入核采样(Nucleus Sampling,第 3.1 节)。核采样的关键直觉是:在每一步,绝大部分概率质量都集中在核里,即词汇表中通常只有一个到一千个候选的一小撮词。我们不再依赖固定的 top-,也不再用温度参数去改变分布形状却又不足以压住那条不可靠的尾巴,而是建议从概率质量的 top- 部分中采样,让候选集合动态地扩大或收缩。
In order to compare current methods to Nucleus Sampling, we compare various distributional properties of generated text to the reference distribution, such as the likelihood of veering into repetition and the perplexity of generated text.
为了把现有方法与核采样加以比较,我们把生成文本的多种分布性质与参考分布对照,例如陷入重复的可能性,以及生成文本的困惑度。
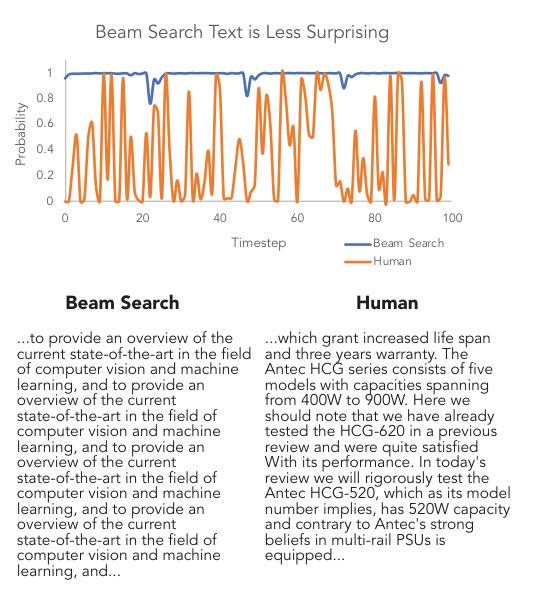
Figure 2: The probability assigned to tokens generated by Beam Search and humans, given the same context. Note the increased variance that characterizes human text, in contrast with the endless repetition of text decoded by Beam Search.
图 2:在相同上文下,束搜索与人类所生成词被赋予的概率。请注意人类文本特有的更大波动,与束搜索解码文本没完没了的重复形成对照。
The latter reveals that text generated by maximization or top- sampling is too probable, indicating a lack of diversity and divergence in vocabulary usage from the human distribution. On the other hand, pure sampling produces text that is significantly less likely than the gold, corresponding to lower generation quality.
后者表明,用最大化或 top- 采样生成的文本过于可能,说明多样性不足,用词也偏离了人类分布。另一方面,纯采样产生的文本明显不如黄金文本可能,对应着更低的生成质量。
Vocabulary usage and Self-BLEU (Zhu et al., 2018) statistics reveal that high values of are needed to make top- sampling match human statistics. Yet, generations based on high values of often have high variance in likelihood, hinting at qualitatively observable incoherency issues. Nucleus Sampling can easily match reference perplexity through tuning the value of , avoiding the incoherence caused by setting high enough to match distributional statistics.
词汇使用和 Self-BLEU(Zhu et al., 2018)统计表明,要使 top- 采样贴近人类统计量,需要很大的 。可是基于很大 的生成,似然往往波动很大,暗示在定性上可以观察到不连贯的问题。核采样只需调节 ,就能轻易贴近参考困惑度,从而避免为了匹配分布统计而把 设得太高所带来的不连贯。
Finally, we perform Human Unified with Statistical Evaluation (Hashimoto et al., 2019, HUSE;) to jointly assess the overall quality and diversity of the decoding strategies, which cannot be captured using either human or automatic evaluation alone. The HUSE evaluation demonstrates that Nucleus Sampling is the best overall decoding strategy. We include generated examples for qualitative analysis – see Figure 3 for a representative example, and further examples in the appendix.[^2]
最后,我们用 Human Unified with Statistical Evaluation(Hashimoto et al., 2019,HUSE)来综合评估各解码策略的总体质量与多样性,这是单靠人工或自动评估无法把握的。HUSE 评估表明,核采样是总体最好的解码策略。我们还收入生成样例供定性分析——图 3 给出一个有代表性的例子,更多例子见附录。[^2]
[^2]: Code and all generations are available at https://github.com/ari-holtzman/degen
[^2]: 代码与全部生成结果见 https://github.com/ari-holtzman/degen
2 Background
2 背景
2.1 Text Generation Decoding Strategies
2.1 文本生成的解码策略
A number of recent works have alluded to the disadvantages of generation by maximization, which tend to generate output with high grammaticality but low diversity (Kulikov et al., 2019; Holtzman et al., 2018; Fan et al., 2018). Generative Adversarial Networks (GANs) have been a prominent research direction (Yu et al., 2017; Xu et al., 2018), but recent work has shown that when quality and diversity are considered jointly, GAN-generated text fails to outperform generations from language models (Caccia et al., 2018; Tevet et al., 2019; Semeniuta et al., 2018). Work on neural dialog systems have proposed methods for diverse beam search, using a task-specific diversity scoring function or constraining beam hypotheses to be sufficiently different (Li et al., 2016a; Vijayakumar et al., 2018; Kulikov et al., 2019; Pal et al., 2006). While such utility functions encourage desirable properties in generations, they do not remove the need to choose an appropriate decoding strategy, and we believe that Nucleus Sampling will have complementary advantages in such approaches. Finally, Welleck et al. (2020) begin to address the problem of neural text degeneration through an “unlikelihood loss”, which decreases training loss on repeated tokens and thus implicitly reduces gradients on frequent tokens as well. Our focus is on exposing neural text degeneration and providing a decoding solution that can be used with arbitrary models, but future work will likely combine training-time and inference-time solutions.
近来已有不少工作提到按最大化来生成的缺点:这样得到的输出往往语法较好,但多样性不足(Kulikov et al., 2019; Holtzman et al., 2018; Fan et al., 2018)。生成对抗网络(GAN)一度是突出的研究方向(Yu et al., 2017; Xu et al., 2018),但最近的工作表明,当同时考虑质量与多样性时,GAN 生成的文本并不能超过语言模型的生成(Caccia et al., 2018; Tevet et al., 2019; Semeniuta et al., 2018)。神经对话系统方面的工作提出了多种多样束搜索,使用任务相关的多样性打分,或约束各束假设彼此足够不同(Li et al., 2016a; Vijayakumar et al., 2018; Kulikov et al., 2019; Pal et al., 2006)。这类效用函数虽能鼓励生成具有某些合意性质,但并不能免除选择合适解码策略的需要;我们相信,核采样在这些方法中还会有互补的好处。最后,Welleck et al.(2020)开始用“反似然损失(unlikelihood loss)”来应对神经文本退化:它降低重复词上的训练损失,从而也隐式减小频繁词上的梯度。我们的重点是揭示神经文本退化,并给出一种可与任意模型一起使用的解码方案,但后续工作很可能会把训练阶段与推断阶段的方案结合起来。
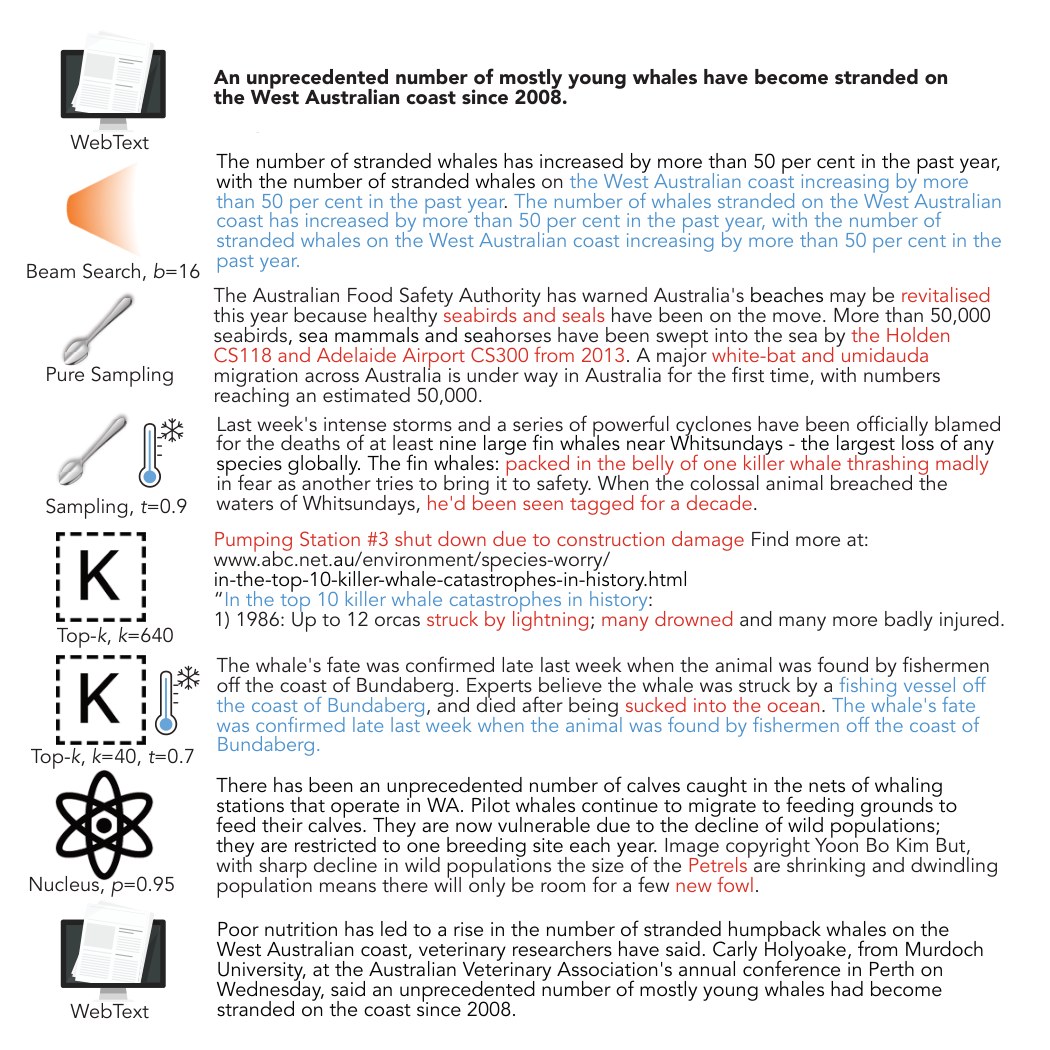
Figure 3: Example generations continuing an initial sentence. Maximization and top- truncation methods lead to copious repetition (highlighted in blue), while sampling with and without temperature tends to lead to incoherence (highlighted in red). Nucleus Sampling largely avoids both issues.
图 3:续写同一句起始句的生成样例。最大化方法和 top- 截断方法会产生大量重复(蓝色标出),而带或不带温度的采样则往往导致不连贯(红色标出)。核采样在很大程度上避开了这两类问题。
2.2 Open-ended vs directed generation
2.2 开放式生成与定向生成
Many text generation tasks are defined through (input, output) pairs, such that the output is a constrained transformation of the input. Example applications include machine translation (Bahdanau et al., 2015), data-to-text generation (Wiseman et al., 2017), and summarization (Nallapati et al., 2016). We refer to these tasks as directed generation. Typically encoder-decoder architectures are used, often with an attention mechanism (Bahdanau et al., 2015; Luong et al., 2015) or using attention-based architectures such as the Transformer (Vaswani et al., 2017). Generation is usually performed using beam search; since output is tightly scoped by the input, repetition and genericness are not as problematic. Still, similar issues have been reported when using large beam sizes (Koehn & Knowles, 2017) and more recently with exact inference (Stahlberg & Byrne, 2019), a counter-intuitive observation since more comprehensive search helps maximize probability.
许多文本生成任务是通过(输入,输出)对来定义的,输出是对输入的一种受约束的变换。例如机器翻译(Bahdanau et al., 2015)、数据到文本生成(Wiseman et al., 2017)以及摘要(Nallapati et al., 2016)。我们把这些任务称为定向生成。通常使用编码器–解码器结构,并常常配上注意力机制(Bahdanau et al., 2015; Luong et al., 2015),或采用 Transformer 这类基于注意力的结构(Vaswani et al., 2017)。生成一般用束搜索;由于输出被输入紧紧框定,重复和泛泛而谈不那么成问题。不过,在束宽很大时仍有类似问题被报告过(Koehn & Knowles, 2017),最近在精确推断中也有报告(Stahlberg & Byrne, 2019)。这有违直觉,因为更全面的搜索本应更有助于最大化概率。
Open-ended generation, which includes conditional story generation and contextual text continuation (as in Figure 1), has recently become a promising research direction due to significant advances in neural language models (Clark et al., 2018; Holtzman et al., 2018; Fan et al., 2018; Peng et al., 2018; Radford et al., 2019). While the input context restricts the space of acceptable output generations, there is a considerable degree of freedom in what can plausibly come next, unlike in directed generation settings. Our work addresses the challenges faced by neural text generation with this increased level of freedom, but we note that some tasks, such as goal-oriented dialog, may fall somewhere in between open-ended and directed generation.
开放式生成包括有条件的故事生成和带上下文的文本续写(如图 1),由于神经语言模型的显著进展,近来已成为一个有前景的研究方向(Clark et al., 2018; Holtzman et al., 2018; Fan et al., 2018; Peng et al., 2018; Radford et al., 2019)。输入上下文虽然限制了可接受的输出空间,但与定向生成不同,接下来什么算合理,仍有相当大的自由度。我们的工作针对的是神经文本生成在这种更大自由度下面临的挑战;不过我们也指出,有些任务,例如目标导向对话,可能介于开放式生成与定向生成之间。
3 Language Model Decoding
3 语言模型解码
Given an input text passage as context, the task of open-ended generation is to generate text that forms a coherent continuation from the given context. More formally, given a sequence of tokens as context, the task is to generate the next continuation tokens to obtain the completed sequence . We assume that models compute using the common left-to-right decomposition of the text probability,
给定一段输入文本作为上文,开放式生成的任务是写出与该上文连贯相接的续写。更形式地说,给定由 个词 组成的上文,任务是再生成接下来的 个续写词,得到完整序列 。我们假定模型用文本概率常见的从左到右分解来计算 ,
which is used to generate the generation token-by-token using a particular decoding strategy.
并据此按某种特定的解码策略逐词生成。
Maximization-based decoding
The most commonly used decoding objective, in particular for directed generation, is maximization-based decoding. Assuming that the model assigns higher probability to higher quality text, these decoding strategies search for the continuation with the highest likelihood. Since finding the optimum argmax sequence from recurrent neural language models or Transformers is not tractable (Chen et al., 2018), common practice is to use beam search (Li et al., 2016b; Shen et al., 2017; Wiseman et al., 2017). However, several recent studies on open-ended generation have reported that maximization-based decoding does not lead to high quality text (Fan et al., 2018; Holtzman et al., 2018).
基于最大化的解码
最常用的解码目标,尤其是在定向生成中,是基于最大化的解码。假定模型会给更高质量的文本赋予更高概率,这类解码策略便去搜索似然最高的续写。由于从循环神经语言模型或 Transformer 中找到最优的 argmax 序列并不可行(Chen et al., 2018),常见做法是使用束搜索(Li et al., 2016b; Shen et al., 2017; Wiseman et al., 2017)。然而,若干关于开放式生成的近期研究已经报告,基于最大化的解码并不能得到高质量文本(Fan et al., 2018; Holtzman et al., 2018)。
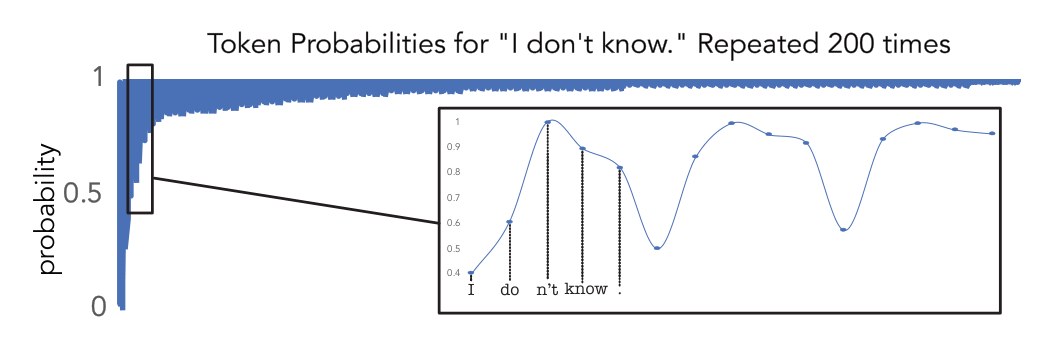
Figure 4: The probability of a repeated phrase increases with each repetition, creating a positive feedback loop. We found this effect to hold for the vast majority of phrases we tested, regardless of phrase length or if the phrases were sampled randomly rather than taken from human text.
图 4:一个重复短语的概率会随每次重复而上升,从而形成正反馈回路。我们发现,对所测试的绝大多数短语,无论长短,也无论短语是随机抽样还是取自人类文本,这一效应都成立。
3.1 Nucleus Sampling
3.1 核采样
We propose a new stochastic decoding method: Nucleus Sampling. The key idea is to use the shape of the probability distribution to determine the set of tokens to be sampled from. Given a distribution , we define its top- vocabulary as the smallest set such that
我们提出一种新的随机解码方法:核采样。其关键想法是,用概率分布的形状来决定从哪些词里采样。给定分布 ,我们把它的 top- 词表 定义成满足下式的最小集合:
Let . The original distribution is re-scaled to a new distribution, from which the next word is sampled:
令 。原分布被重新缩放到一个新分布,下一步的词即从这个新分布中抽出:
$$P^{\prime}(x|x_{1:i-1})=\left{\begin{array}[]{ll}P(x|x_{1:i-1})/p^{\prime}&\mbox{if }x\in V^{(p)}\
0&\mbox{otherwise.}\end{array}\right. \tag{3}$$
In practice this means selecting the highest probability tokens whose cumulative probability mass exceeds the pre-chosen threshold . The size of the sampling set will adjust dynamically based on the shape of the probability distribution at each time step. For high values of , this is a small subset of vocabulary that takes up vast majority of the probability mass — the nucleus.
实践中,这就是选出累积概率质量超过预先选定阈值 的那些最高概率词。采样集合的大小会在每一步根据概率分布的形状动态调整。当 较大时,这只是词汇表中占绝大部分概率质量的一小部分——也就是核。
3.2 Top-k Sampling
3.2 Top-k 采样
Top- sampling has recently become a popular alternative sampling procedure (Fan et al., 2018; Holtzman et al., 2018; Radford et al., 2019). Nucleus Sampling and top- both sample from truncated Neural LM distributions, differing only in the strategy of where to truncate. Choosing where to truncate can be interpreted as determining the generative model’s trustworthy prediction zone.
Top- 采样近来成为一种流行的替代抽样程序(Fan et al., 2018; Holtzman et al., 2018; Radford et al., 2019)。核采样与 top- 都是从截断后的神经语言模型分布中抽样,差别只在于在何处截断。选择截断位置,可以理解为判定生成模型可信的预测区域。
At each time step, the top possible next tokens are sampled from according to their relative probabilities. Formally, given a distribution , we define its top- vocabulary as the set of size which maximizes . Let . The distribution is then re-scaled as in equation 3, and sampling is performed based on that distribution. Note that the scaling factor can vary wildly at each time-step, in contrast to Nucleus Sampling.
在每一步,从概率最高的 个可能下一词中,按其相对概率抽样。形式地说,给定分布 ,把它的 top- 词表 定义成大小为 、使 最大的集合。令 。随后按公式 (3) 重新缩放分布,并在该分布上抽样。需要注意,缩放因子 在每一步都可能剧烈变化,这与核采样不同。
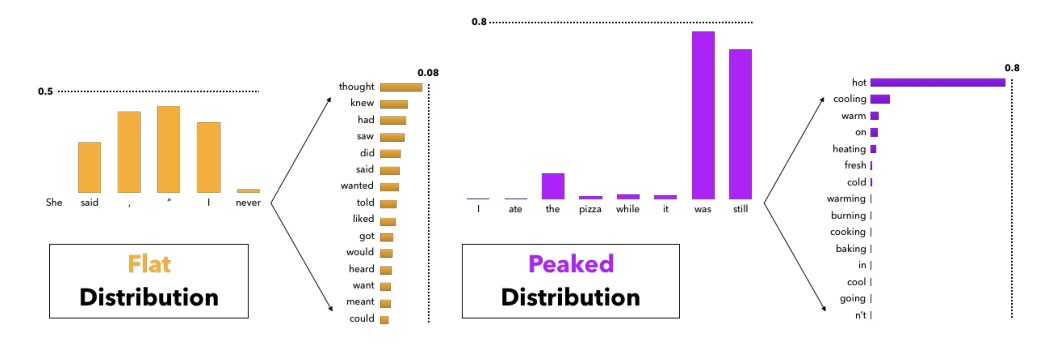
Figure 5: The probability mass assigned to partial human sentences. Flat distributions lead to many moderately probable tokens, while peaked distributions concentrate most probability mass into just a few tokens. The presence of flat distributions makes the use of a small in top- sampling problematic, while the presence of peaked distributions makes large ’s problematic.
图 5:部分人类句子所分到的概率质量。平坦的分布会留下许多中等概率的词,而尖锐的分布则把大部分概率质量集中在少数几个词上。平坦分布的存在,使得 top- 采样使用很小的 会成问题;尖锐分布的存在,又使得很大的 成问题。
Difficulty in choosing a suitable value of
While top- sampling leads to considerably higher quality text than either beam search or sampling from the full distribution, the use of a constant is sub-optimal across varying contexts. As illustrated on the left of Figure 5, in some contexts the head of the next word distribution can be flat across tens or hundreds of reasonable options (e.g. nouns or verbs in generic contexts), while in other contexts most of the probability mass is concentrated in one or a small number of tokens, as on the right of the figure. Therefore if is small, in some contexts there is a risk of generating bland or generic text, while if is large the top- vocabulary will include inappropriate candidates which will have their probability of being sampled increased by the renormalization. Under Nucleus Sampling, the number of candidates considered rises and falls dynamically, corresponding to the changes in the model’s confidence region over the vocabulary which top- sampling fails to capture for any one choice of .
难以选到合适的
尽管 top- 采样得到的文本质量远高于束搜索或从完整分布中采样,但在不同上下文中使用恒定的 并不是最优的。如图 5 左侧所示,在有些上下文里,下一词分布的头部可以在几十乃至上百个合理选项上都很平坦(例如泛泛语境中的名词或动词);而在另一些上下文里,大部分概率质量集中在一个或少数几个词上,如图右侧。因此,若 很小,有些上下文就有生成平淡或泛泛文本的风险;若 很大,top- 词表又会纳入不合适的候选,这些候选在重新归一化后被抽中的概率还会上升。在核采样下,所考虑的候选数量会动态增减,与模型在词汇表上置信区域的变化相对应,而这是任意一个固定 的 top- 采样都把握不住的。
3.3 Sampling with Temperature
3.3 带温度的采样
Another common approach to sampling-based generation is to shape a probability distribution through temperature (Ackley et al., 1985). Temperature sampling has been applied widely to text generation (Ficler & Goldberg, 2017; Fan et al., 2018; Caccia et al., 2018). Given the logits and temperature , the softmax is re-estimated as
另一种常见的基于采样的生成做法,是用温度来塑造概率分布(Ackley et al., 1985)。温度采样已被广泛应用于文本生成(Ficler & Goldberg, 2017; Fan et al., 2018; Caccia et al., 2018)。给定 logits 和温度 ,softmax 被重新估计为
Setting skews the distribution towards high probability events, which implicitly lowers the mass in the tail distribution. Low temperature sampling has also been used to partially alleviate the issues of top- sampling discussed above, by shaping the distribution before top- sampling (Radford et al., 2018; Fan et al., 2018). However, recent analysis has shown that, while lowering the temperature improves generation quality, it comes at the cost of decreasing diversity (Caccia et al., 2018; Hashimoto et al., 2019).
把 设在 会使分布偏向高概率事件,从而隐含地压低尾巴上的质量。低温采样也被用来部分缓解上文讨论的 top- 采样问题,办法是在做 top- 采样之前先塑造分布(Radford et al., 2018; Fan et al., 2018)。然而最近的分析表明,虽然降低温度能改进生成质量,代价却是多样性下降(Caccia et al., 2018; Hashimoto et al., 2019)。
4 Likelihood Evaluation
4 似然评估
4.1 Experimental Setup
4.1 实验设置
While many neural network architectures have been proposed for language modeling, including LSTMs (Sundermeyer et al., 2012) and convolutional networks (Dauphin et al., 2017), the Transformer architecture (Vaswani et al., 2017) has been the most successful in the extremely large-scale training setups in recent literature (Radford et al., 2018; Radford et al., 2019). In this study we use the Generatively Pre-trained Transformer, version 2 (Radford et al., 2019, GPT2;), which was trained on WebText, a 40GB collection of text scraped from the web.[^3] We perform experiments using the Large model (762M parameters). Our analysis is based on generating 5,000 text passages, which end upon reaching an end-of-document token or a maximum length of 200 tokens. Texts are generated conditionally, conditioned on the initial paragraph (restricted to 1-40 tokens) of documents in the held-out portion of WebText, except where otherwise mentioned.
尽管已有许多神经网络结构被用于语言建模,包括 LSTM(Sundermeyer et al., 2012)和卷积网络(Dauphin et al., 2017),在近期文献的超大规模训练设置中最成功的还是 Transformer 结构(Vaswani et al., 2017; Radford et al., 2018; Radford et al., 2019)。本研究使用第二版 Generatively Pre-trained Transformer(Radford et al., 2019,GPT-2),它在 WebText 上训练,这是一套从网上抓取、约 40GB 的文本集合。[^3] 实验使用 Large 模型(7.62 亿参数)。我们的分析基于生成 5,000 段文本:遇到文档结束符或达到 200 个词的最大长度即停止。文本是有条件生成的,条件是 WebText 留出部分中各文档的首段(限制为 1–40 个词),除非另有说明。
[^3]: Available at https://github.com/openai/gpt-2-output-dataset
| Method | Perplexity | Self-BLEU4 | Zipf Coefficient | Repetition % | HUSE |
|---|---|---|---|---|---|
| Human | 12.38 | 0.31 | 0.93 | 0.28 | - |
| Greedy | 1.50 | 0.50 | 1.00 | 73.66 | - |
| Beam, b=16 | 1.48 | 0.44 | 0.94 | 28.94 | - |
| Stochastic Beam, b=16 | 19.20 | 0.28 | 0.91 | 0.32 | - |
| Pure Sampling | 22.73 | 0.28 | 0.93 | 0.22 | 0.67 |
| Sampling, =0.9 | 10.25 | 0.35 | 0.96 | 0.66 | 0.79 |
| Top-=40 | 6.88 | 0.39 | 0.96 | 0.78 | 0.19 |
| Top-=640 | 13.82 | 0.32 | 0.96 | 0.28 | 0.94 |
| Top-=40, =0.7 | 3.48 | 0.44 | 1.00 | 8.86 | 0.08 |
| Nucleus =0.95 | 13.13 | 0.32 | 0.95 | 0.36 | 0.97 |
Table 1: Main results for comparing all decoding methods with selected parameters of each method. The numbers closest to human scores are in bold except for HUSE (Hashimoto et al., 2019), a combined human and statistical evaluation, where the highest (best) value is bolded. For Top- and Nucleus Sampling, HUSE is computed with interpolation rather than truncation (see §6.1).
| Method | Perplexity | Self-BLEU4 | Zipf Coefficient | Repetition % | HUSE |
|---|---|---|---|---|---|
| Human | 12.38 | 0.31 | 0.93 | 0.28 | - |
| Greedy | 1.50 | 0.50 | 1.00 | 73.66 | - |
| Beam, b=16 | 1.48 | 0.44 | 0.94 | 28.94 | - |
| Stochastic Beam, b=16 | 19.20 | 0.28 | 0.91 | 0.32 | - |
| Pure Sampling | 22.73 | 0.28 | 0.93 | 0.22 | 0.67 |
| Sampling, =0.9 | 10.25 | 0.35 | 0.96 | 0.66 | 0.79 |
| Top-=40 | 6.88 | 0.39 | 0.96 | 0.78 | 0.19 |
| Top-=640 | 13.82 | 0.32 | 0.96 | 0.28 | 0.94 |
| Top-=40, =0.7 | 3.48 | 0.44 | 1.00 | 8.86 | 0.08 |
| Nucleus =0.95 | 13.13 | 0.32 | 0.95 | 0.36 | 0.97 |
表 1:各解码方法在选定参数下的主要比较结果。除 HUSE(Hashimoto et al., 2019)这一结合人工与统计的评估取最高(最好)值加粗外,其余加粗的是最接近人类分数的数字。对 Top- 和核采样,HUSE 是用插值而非截断来计算的(见第 6.1 节)。
4.2 Perplexity
4.2 困惑度
Our first evaluation is to compute the perplexity of generated text using various decoding strategies, according to the model that is being generated from. We compare these perplexities against that of the gold text (Figure 6). Importantly, we argue that the optimal generation strategy should produce text which has a perplexity close to that of the gold text: Even though the model has the ability to generate text that has lower perplexity (higher probability), such text tends to have low diversity and get stuck in repetition loops, as shown in §5 and illustrated in Figure 4.
我们的第一项评估,是按正在用于生成的那个模型,计算各种解码策略所生成文本的困惑度,并与黄金文本的困惑度比较(图 6)。重要的是,我们认为最优的生成策略应产生困惑度接近黄金文本的文本:尽管模型有能力生成困惑度更低(概率更高)的文本,这类文本往往多样性不足,并容易陷入重复循环,如第 5 节所示,并在图 4 中有所体现。
We see that perplexity of text obtained from pure sampling is worse than the perplexity of the gold. This indicates that the model is confusing itself: sampling too many unlikely tokens and creating context that makes it difficult to recover the human distribution of text, as in Figure 1. Yet, setting the temperature lower creates diversity and repetition issues, as we shall see in §5. Even with our relatively fine-grained parameter sweep, Nucleus Sampling obtains closest perplexity to human text, as shown in Table 1.
可以看到,纯采样得到的文本,其困惑度差于黄金文本。这表明模型在把自己绕糊涂:抽了太多不太可能的词,造成的上下文让它很难回到人类文本的分布,正如图 1 那样。可是把温度调低,又会带来多样性和重复方面的问题,我们将在第 5 节看到。即便我们做了相对细致的参数扫描,核采样得到的困惑度仍最接近人类文本,见表 1。
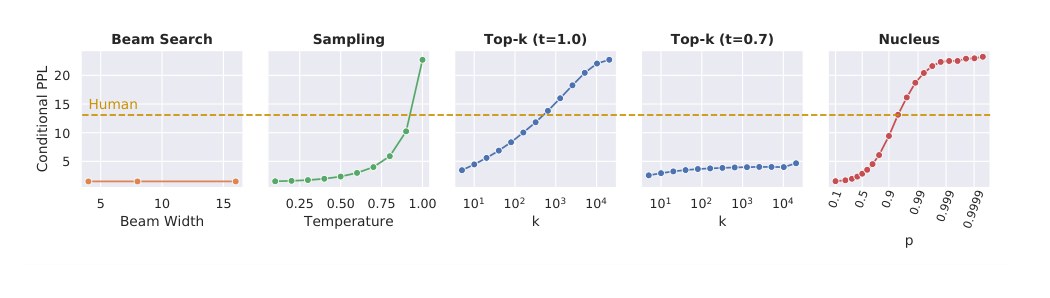
Figure 6: Perplexities of generations from various decoding methods. Note that beam search has unnaturally low perplexities. A similar effect is seen using a temperature of with top- as in both Radford et al. (2019) and Fan et al. (2018). Sampling, Top-, and Nucleus can all be calibrated to human perplexities, but the first two face coherency issues when their parameters are set this high.
图 6:各种解码方法生成文本的困惑度。请注意束搜索具有不自然的低困惑度。用温度为 的 top-,如 Radford et al.(2019)和 Fan et al.(2018)中那样,也会看到类似效应。采样、Top- 和核采样都可以校准到接近人类的困惑度,但前两者在参数设得这么高时会面临连贯性问题。
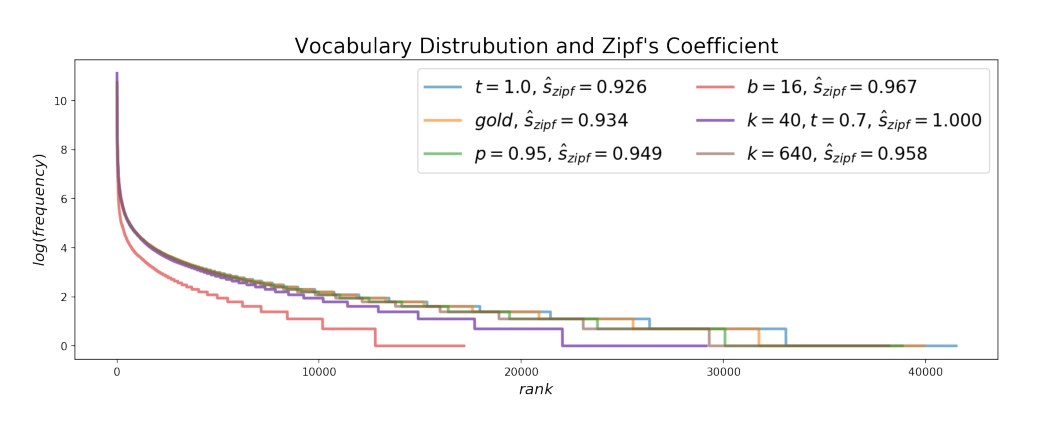
Figure 7: A rank-frequency plot of the distributional differences between -gram frequencies of human and machine text. Sampling and Nucleus Sampling are by far the closest to the human distribution, while Beam Search clearly follows a very different distribution than natural language.
图 7:人类文本与机器文本 -gram 频率分布差异的秩–频次图。采样和核采样与人类分布远为接近,而束搜索显然遵循与自然语言很不相同的分布。
4.3 Natural Language Does Not Maximize Probability
4.3 自然语言并不最大化概率
One might wonder if the issue with maximization is a search error, i.e., there are higher quality sentences to which the model assigns higher probability than to the decoded ones, beam search has just failed to find them. Yet Figures 2 & 6 show that the per-token probability of natural text is, on average, much lower than text generated by beam search. Natural language rarely remains in a high probability zone for multiple consecutive time steps, instead veering into lower-probability but more informative tokens. Nor does natural language tend to fall into repetition loops, even though the model tends to assign high probability to this, as seen in Figure 4.
或许有人会问:最大化的问题是不是一种搜索错误,也就是说,存在一些更高质量的句子,模型给它们的概率高于已解码出的句子,只是束搜索没找到它们。然而图 2 和图 6 表明,自然文本的逐词概率平均来看远低于束搜索生成的文本。自然语言很少在连续多步里一直停在高概率区域,反而会拐向概率较低但信息量更大的词。自然语言也不容易陷入重复循环,尽管模型往往给这种循环很高的概率,如图 4 所示。
Why is human-written text not the most probable text? We conjecture that this is an intrinsic property of human language. Language models that assign probabilities one word at a time without a global model of the text will have trouble capturing this effect. Grice’s Maxims of Communication (Grice, 1975) show that people optimize against stating the obvious. Thus, making every word as predictable as possible will be disfavored. This makes solving the problem simply by training larger models or improving neural architectures using standard per-word learning objectives unlikely: such models are forced to favor the lowest common denominator, rather than informative language.
为什么人写的文本不是最可能的文本?我们猜想,这是人类语言的一种内在性质。那些一次只给一个词赋概率、而没有对全文做全局建模的语言模型,将难以把握这一效应。Grice 的交际准则(Grice, 1975)表明,人们会避免去说显而易见的话。因此,把每一个词都变得尽可能可预测,反而会被排斥。这也使得仅仅靠训练更大的模型,或用标准的逐词学习目标去改进神经网络结构,不太可能解决问题:这类模型被迫去迎合最小公约数,而不是信息丰富的语言。
5 Distributional Statistical Evaluation
5 分布统计评估
5.1 Zipf Distribution Analysis
5.1 Zipf 分布分析
In order to compare generations to the reference text, we begin by analyzing their use of vocabulary. Zipf’s law suggests that there is an exponential relationship between the rank of a word and its frequency in text. The Zipfian coefficient can be used to compare the distribution in a given text to a theoretically perfect exponential curve, where (Piantadosi, 2014). Figure 7 shows the vocabulary distributions along with estimated Zipf coefficients for selected parameters of different decoding methods. As expected, pure sampling is the closest to the human distribution, followed by Nucleus Sampling. The visualization of the distribution shows that pure sampling slightly overestimates the use of rare words, likely one reason why pure sampling also has higher perplexity than human text. Furthermore, lower temperature sampling avoids sampling these rare words from the tail, which is why it has been used in some recent work (Fan et al., 2018; Radford et al., 2019).
为了把生成结果与参考文本比较,我们先分析它们的用词。Zipf 定律表明,一个词的秩次与它在文本中的频率之间存在指数关系。Zipf 系数 可用来把给定文本中的分布与理论上完美的指数曲线比较,后者对应 (Piantadosi, 2014)。图 7 给出了不同解码方法在选定参数下的词汇分布,以及估计出的 Zipf 系数。正如所料,纯采样最接近人类分布,其次是核采样。分布的可视化表明,纯采样略微高估了罕见词的使用,这很可能也是纯采样困惑度高于人类文本的原因之一。此外,较低温度的采样会避免从尾巴里抽出这些罕见词,这也是一些近期工作采用它的原因(Fan et al., 2018; Radford et al., 2019)。
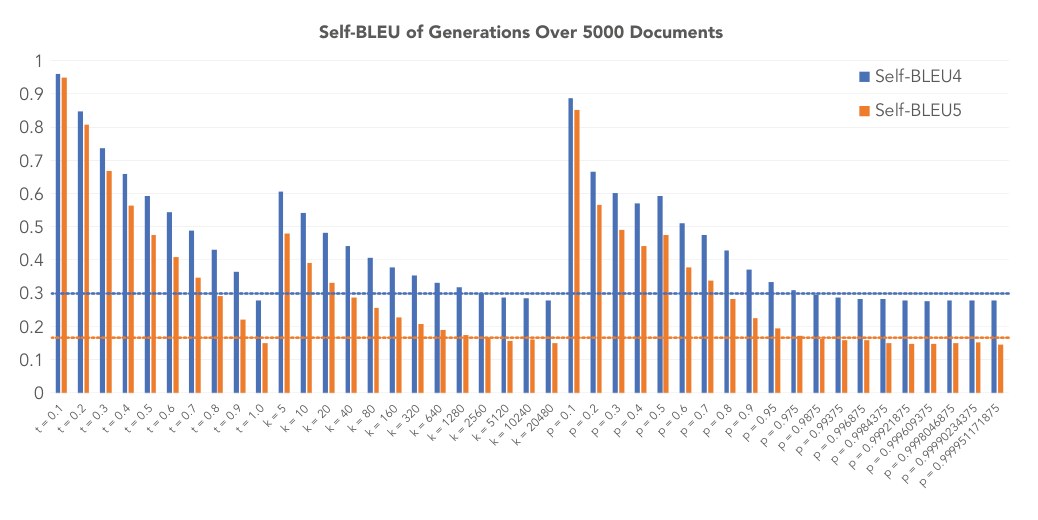
Figure 8: Self-BLEU calculated on the unconditional generations produced by stochastic decoding methods; lower Self-BLEU scores imply higher diversity. Horizontal blue and orange lines represent human self-BLEU scores. Note how common values of and result in high self-similarity, whereas “normal” values of closely match the human distribution of text.
图 8:在随机解码方法的无条件生成上计算的 Self-BLEU;更低的 Self-BLEU 意味着更高的多样性。蓝色和橙色水平线表示人类的 Self-BLEU 分数。请注意,常见的 和 会导致很高的自相似,而“通常”的 则与人类文本分布非常接近。
5.2 Self-BLEU
We follow previous work and compute Self-BLEU (Zhu et al., 2018) as a metric of diversity. Self-BLEU is calculated by computing the BLEU score of each generated document using all other generations in the evaluation set as references. Due to the expense of computing such an operation, we sample 1000 generations, each of which is compared with all 4999 other generations as references. A lower Self-BLEU score implies higher diversity. Figure 8 shows that Self-BLEU results largely follow that of the Zipfian distribution analysis as a diversity measure. It is worth noting that very high values of and are needed to get close to the reference distribution, though these result in unnaturally high perplexity (§4).
我们沿用已有工作,用 Self-BLEU(Zhu et al., 2018)作为多样性指标。计算 Self-BLEU 时,对评估集中的每一篇生成文档,把其余所有生成当作参考来算 BLEU。由于这一运算开销较大,我们抽取 1000 篇生成,每一篇都与其余 4999 篇生成作为参考来比较。Self-BLEU 越低,多样性越高。图 8 表明,Self-BLEU 作为多样性度量,大体与 Zipf 分布分析一致。值得注意的是,要把 和 设得非常高,才能接近参考分布,尽管这又会导致不自然的高困惑度(第 4 节)。
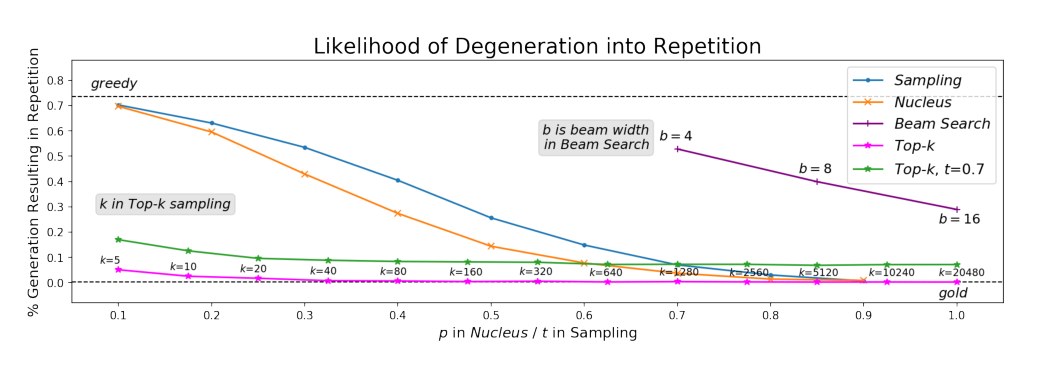
Figure 9: We visualize how often different decoding methods get “stuck” in loops within the first 200 tokens. A phrase (minimum length 2) is considered a repetition when it repeats at least three times at the end of the generation. We label points with their parameter values except for and which follow the x-axis. Values of greater than 100 are rarely used in practice and values of are usually in ; therefore Nucleus Sampling is far closer to the human distribution in its usual parameter range. Sampling with temperatures lower than 0.9 severely increase repetition. Finally, although beam search becomes less repetitive according to this metric as beam width increases, this is largely because average length gets shorter as increases (see Appendix A).
图 9:我们可视化不同解码方法在前 200 个词内陷入循环的频率。一个短语(最短长度为 2)若在生成结尾至少重复三次,即视为一次重复。除 和 沿横轴变化外,我们在点旁标出参数值。实践中很少使用大于 100 的 , 通常取 ;因此核采样在其常用参数范围内远更接近人类分布。温度低于 0.9 的采样会严重增加重复。最后,虽然按这一指标,束搜索会随束宽增大而显得不那么重复,但这在很大程度上是因为平均长度随 增大而变短(见附录 A)。
5.3 Repetition
5.3 重复
One attribute of text quality that we can quantify is repetition. Figure 9 shows that Nucleus Sampling and top- sampling have the least repetition for reasonable parameter ranges. Generations from temperature sampling have more repetition unless very high temperatures are used, which we have shown negatively affects coherence (as measured by high perplexity). Further, all stochastic methods face repetition issues when their tuning parameters are set too low, which tends to over-truncate, mimicking greedy search. Therefore we conclude that only Nucleus Sampling satisfies all the distributional criteria for desirable generations.
文本质量中有一项可以量化的属性是重复。图 9 表明,在合理的参数范围内,核采样和 top- 采样的重复最少。温度采样的生成重复更多,除非使用非常高的温度,而我们已经表明这会损害连贯性(表现为很高的困惑度)。此外,当调节参数设得过低时,所有随机方法都会出现重复问题,因为这往往会截得太死,变得像贪心搜索。因此我们的结论是:只有核采样满足对理想生成的全部分布准则。
6 Human Evaluation
6 人工评估
6.1 Human Unified with Statistical Evaluation (HUSE)
6.1 人工与统计统一评估(HUSE)
Statistical evaluations are unable to measure the coherence of generated text properly. While the metrics in previous sections gave us vital insights into the different decoding methods we compare, human evaluation is still required to get a full measure of the quality of the generated text. However, pure human evaluation does not take into account the diversity of the generated text; therefore we use HUSE (Hashimoto et al., 2019) to combine human and statistical evaluation. HUSE is computed by training a discriminator to distinguish between text drawn from the human and model distributions, based on only two features: The probability assigned by the language model, and human judgements of typicality of generations. Text that is close to the human distribution in terms of quality and diversity should perform well on both likelihood evaluation and human judgements.
统计评估无法很好地衡量生成文本的连贯性。前面各节的指标虽然为我们比较的不同解码方法提供了重要认识,但要全面衡量生成文本的质量,仍需要人工评估。不过,纯粹的人工评估并不考虑生成文本的多样性;因此我们使用 HUSE(Hashimoto et al., 2019)来把人工评估与统计评估结合起来。HUSE 的计算方式是训练一个判别器,仅用两个特征来区分来自人类分布和模型分布的文本:语言模型赋予的概率,以及人对生成典型程度的判断。在质量和多样性上都接近人类分布的文本,应在似然评估和人工判断上都表现良好。
As explored in the previous sections, the current best-performing decoding methods rely on truncation of the probability distribution, which yields a probability of 0 for the vast majority of potential tokens. Initial exploration of applying HUSE directly led to top- and Nucleus Sampling receiving scores of nearly 0 due to truncation, despite humans favoring these methods. As a proxy, when generating the text used to compute HUSE, we interpolate (with mass ) the original probability distribution with the top- and Nucleus Sampling distribution, smoothing the truncated distribution.
如前几节所探讨的,当前表现最好的解码方法依赖于对概率分布的截断,这会让绝大多数潜在词的概率变为 0。初步尝试直接计算 HUSE 时,top- 和核采样几乎得到 0 分,原因就是截断,尽管人更偏好这些方法。作为折中,在生成用于计算 HUSE 的文本时,我们把原来的概率分布与 top- 及核采样分布做插值(质量为 0.1),从而把被截断的分布加以平滑。
For each decoding algorithm we annotate 200 generations for typicality, with each generation receiving 20 annotations from 20 different annotators. This results in a total of 4000 annotations per a decoding scheme. We use a KNN classifier to compute HUSE, as in the original paper, with neighbors, which we found led to the higher accuracy in discrimination. The results in Table 1 shows that Nucleus Sampling obtains the highest HUSE score, with Top- sampling performing second best.
对每种解码算法,我们为 200 段生成标注典型程度,每段生成由 20 名不同标注者给出 20 次标注,因而每种解码方案共有 4000 条标注。与原论文一样,我们用 KNN 分类器计算 HUSE,取 个近邻,我们发现这样能提高判别准确率。表 1 的结果表明,核采样得到最高的 HUSE 分数,Top- 采样次之。
6.2 Qualitative Analysis
6.2 定性分析
Figure 3 shows representative example generations. Unsurprisingly, beam search gets stuck in a repetition loop it cannot escape. Of the stochastic decoding schemes, the output of full sampling is clearly the hardest to understand, even inventing a new word “umidauda”, apparently a species of bird. The generation produced by Nucleus Sampling isn’t perfect – the model appears to confuse whales with birds, and begins writing about those instead. Yet, top- sampling immediately veers off into an unrelated event. When top- sampling is combined with a temperature of 0.7, as is commonly done (Radford et al., 2019; Fan et al., 2018), the output devolves into repetition, exhibiting the classic issues of low-temperature decoding. More generations are available in Appendix B.
图 3 给出了有代表性的生成样例。毫不意外,束搜索会陷入它无法逃出的重复循环。在随机解码方案中,完整采样的输出显然最难理解,甚至还发明了一个新词 “umidauda”,好像是某种鸟。核采样的生成也并非完美——模型似乎把鲸鱼和鸟搞混了,并转而去写那些鸟。但 top- 采样会立刻偏到一件无关的事情上。当 top- 采样与温度为 0.7 结合使用,就像常见做法那样(Radford et al., 2019; Fan et al., 2018),输出又会退化成重复,表现出低温解码的典型问题。更多生成见附录 B。
7 Conclusion
7 结论
This paper provided a deep analysis into the properties of the most common decoding methods for open-ended language generation. We have shown that likelihood maximizing decoding causes repetition and overly generic language usage, while sampling methods without truncation risk sampling from the low-confidence tail of a model’s predicted distribution. Further, we proposed Nucleus Sampling as a solution that captures the region of confidence of language models effectively. In future work, we wish to dynamically characterize this region of confidence and include a more semantic utility function to guide the decoding process.
本文深入分析了开放式语言生成中最常见的解码方法的性质。我们表明,最大化似然的解码会造成重复和过于泛泛的用词,而不做截断的采样方法则有从模型预测分布的低置信尾巴里抽样的风险。进而,我们提出核采样,作为有效抓住语言模型置信区域的一种方案。在后续工作中,我们希望动态刻画这一置信区域,并纳入更偏语义的效用函数来引导解码过程。
Acknowledgments
致谢
This research was supported in part by NSF (IIS-1524371), the National Science Foundation Graduate Research Fellowship under Grant No. DGE1256082, DARPA CwC through ARO (W911NF15-1- 0543), DARPA MCS program through NIWC Pacific (N66001-19-2-4031), the South African Centre for Artificial Intelligence Research, and the Allen Institute for AI.
本研究部分得到 NSF(IIS-1524371)、国家科学基金会研究生研究奖学金(批准号 DGE1256082)、经由 ARO 的 DARPA CwC(W911NF15-1-0543)、经由 NIWC Pacific 的 DARPA MCS 项目(N66001-19-2-4031)、南非人工智能研究中心以及 Allen Institute for AI 的支持。
References
参考文献
Ackley et al. (1985) David H Ackley, Geoffrey E Hinton, and Terrence J Sejnowski. A learning algorithm for boltzmann machines. Cognitive science , 9(1):147–169, 1985.
Bahdanau et al. (2015) Dzmitry Bahdanau, Kyunghyun Cho, and Yoshua Bengio. Neural machine translation by jointly learning to align and translate. Proceedings of the 2015 International Conference on Learning Representations , 2015.
Caccia et al. (2018) Massimo Caccia, Lucas Caccia, William Fedus, Hugo Larochelle, Joelle Pineau, and Laurent Charlin. Language gans falling short. In Critiquing and Correcting Trends in Machine Learning: NeurIPS 2018 Workshop , 2018. URL http://arxiv.org/abs/1811.02549 .
Chen et al. (2018) Yining Chen, Sorcha Gilroy, Andreas Maletti, Jonathan May, and Kevin Knight. Recurrent neural networks as weighted language recognizers. In Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers) , pp. 2261–2271, New Orleans, Louisiana, June 2018.
Clark et al. (2018) Elizabeth Clark, Yangfeng Ji, and Noah A. Smith. Neural text generation in stories using entity representations as context. In Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers) , pp. 2250–2260, New Orleans, Louisiana, June 2018.
Dauphin et al. (2017) Yann N Dauphin, Angela Fan, Michael Auli, and David Grangier. Language modeling with gated convolutional networks. In Proceedings of the 34th International Conference on Machine Learning , pp. 933–941, 2017.
Fan et al. (2018) Angela Fan, Mike Lewis, and Yann Dauphin. Hierarchical neural story generation. In Proceedings of the 56th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) , volume 1, pp. 889–898, 2018.
Ficler & Goldberg (2017) Jessica Ficler and Yoav Goldberg. Controlling linguistic style aspects in neural language generation. In Proceedings of the Workshop on Stylistic Variation , pp. 94–104, 2017.
Grice (1975) H Paul Grice. Logic and conversation. In P Cole and J L Morgan (eds.), Speech Acts , volume 3 of Syntax and Semantics , pp. 41–58. Academic Press, 1975.
Hashimoto et al. (2019) Tatsunori B. Hashimoto, Hugh Zhang, and Percy Liang. Unifying human and statistical evaluation for natural language generation. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies , 2019.
Holtzman et al. (2018) Ari Holtzman, Jan Buys, Maxwell Forbes, Antoine Bosselut, David Golub, and Yejin Choi. Learning to write with cooperative discriminators. In Proceedings of the Association for Computational Linguistics , 2018.
Koehn & Knowles (2017) Philipp Koehn and Rebecca Knowles. Six challenges for neural machine translation. In Proceedings of the First Workshop on Neural Machine Translation , pp. 28–39, 2017.
Kulikov et al. (2019) Ilya Kulikov, Alexander H Miller, Kyunghyun Cho, and Jason Weston. Importance of search and evaluation strategies in neural dialogue modeling. International Conference on Natural Language Generation , 2019.
Li et al. (2016a) Jiwei Li, Will Monroe, and Dan Jurafsky. A simple, fast diverse decoding algorithm for neural generation. arXiv preprint arXiv:1611.08562 , 2016a.
Li et al. (2016b) Jiwei Li, Will Monroe, Alan Ritter, Dan Jurafsky, Michel Galley, and Jianfeng Gao. Deep reinforcement learning for dialogue generation. In Proceedings of the 2016 Conference on Empirical Methods in Natural Language Processing , pp. 1192–1202, 2016b.
Luong et al. (2015) Thang Luong, Hieu Pham, and Christopher D Manning. Effective approaches to attention-based neural machine translation. In Proceedings of the 2015 Conference on Empirical Methods in Natural Language Processing , pp. 1412–1421, 2015.
Nallapati et al. (2016) Ramesh Nallapati, Bowen Zhou, Cicero dos Santos, Caglar Gulcehre, and Bing Xiang. Abstractive text summarization using sequence-to-sequence rnns and beyond. In Proceedings of The 20th SIGNLL Conference on Computational Natural Language Learning , pp. 280–290, 2016.
Pal et al. (2006) Chris Pal, Charles Sutton, and Andrew McCallum. Sparse forward-backward using minimum divergence beams for fast training of conditional random fields. In 2006 IEEE International Conference on Acoustics Speech and Signal Processing Proceedings , volume 5, May 2006.
Peng et al. (2018) Nanyun Peng, Marjan Ghazvininejad, Jonathan May, and Kevin Knight. Towards controllable story generation. In Proceedings of the First Workshop on Storytelling , pp. 43–49, New Orleans, Louisiana, June 2018. doi: 10.18653/v1/W18-1505 .
Piantadosi (2014) Steven T Piantadosi. Zipf’s word frequency law in natural language: A critical review and future directions. Psychonomic bulletin & review , 21(5):1112–1130, 2014.
Radford et al. (2018) Alec Radford, Karthik Narasimhan, Tim Salimans, and Ilya Sutskever. Improving language understanding by generative pre-training, 2018. URL https://s3-us-west-2.amazonaws.com/openai-assets/research-covers/language-unsupervised/language_understanding_paper.pdf . Unpublished manuscript.
Radford et al. (2019) Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei, and Ilya Sutskever. Language models are unsupervised multitask learners, February 2019. URL https://d4mucfpksywv.cloudfront.net/better-language-models/language_models_are_unsupervised_multitask_learners.pdf . Unpublished manuscript.
Semeniuta et al. (2018) Stanislau Semeniuta, Aliaksei Severyn, and Sylvain Gelly. On accurate evaluation of gans for language generation. arXiv preprint arXiv:1806.04936 , 2018.
Shen et al. (2017) Tianxiao Shen, Tao Lei, Regina Barzilay, and Tommi Jaakkola. Style transfer from non-parallel text by cross-alignment. In Advances in neural information processing systems , pp. 6830–6841, 2017.
Stahlberg & Byrne (2019) Felix Stahlberg and Bill Byrne. On nmt search errors and model errors: Cat got your tongue? In Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP) , pp. 3347–3353, 2019.
Sundermeyer et al. (2012) Martin Sundermeyer, Ralf Schlüter, and Hermann Ney. Lstm neural networks for language modeling. In Thirteenth annual conference of the international speech communication association , 2012.
Tevet et al. (2019) Guy Tevet, Gavriel Habib, Vered Shwartz, and Jonathan Berant. Evaluating text gans as language models. Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) , pp. 2241–2247, 2019.
Vaswani et al. (2017) Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Łukasz Kaiser, and Illia Polosukhin. Attention is all you need. In Advances in Neural Information Processing Systems , pp. 5998–6008, 2017.
Vijayakumar et al. (2018) Ashwin K. Vijayakumar, Michael Cogswell, Ramprasaath R. Selvaraju, Qing Sun, Stefan Lee, David Crandall, and Dhruv Batra. Diverse beam search for improved description of complex scenes. In Thirty-Second AAAI Conference on Artificial Intelligence , 2018.
Welleck et al. (2020) Sean Welleck, Ilia Kulikov, Stephen Roller, Emily Dinan, Kyunghyun Cho, and Jason Weston. Neural text generation with unlikelihood training. In Proceedings of the International Conference on Learning Representations (ICLR) , 2020.
Wiseman et al. (2017) Sam Wiseman, Stuart Shieber, and Alexander Rush. Challenges in data-to-document generation. In Proceedings of the 2017 Conference on Empirical Methods in Natural Language Processing , pp. 2253–2263, Copenhagen, Denmark, September 2017.
Xu et al. (2018) Jingjing Xu, Xuancheng Ren, Junyang Lin, and Xu Sun. Diversity-promoting gan: A cross-entropy based generative adversarial network for diversified text generation. In Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing , pp. 3940–3949, Brussels, Belgium, oct 2018.
Yu et al. (2017) Lantao Yu, Weinan Zhang, Jun Wang, and Yong Yu. Seqgan: Sequence generative adversarial nets with policy gradient. In AAAI , 2017.
Zhu et al. (2018) Yaoming Zhu, Sidi Lu, Lei Zheng, Jiaxian Guo, Weinan Zhang, Jun Wang, and Yong Yu. Texygen: A benchmarking platform for text generation models. SIGIR , 2018.
Appendix A Beam Width Effect
附录 A 束宽的影响
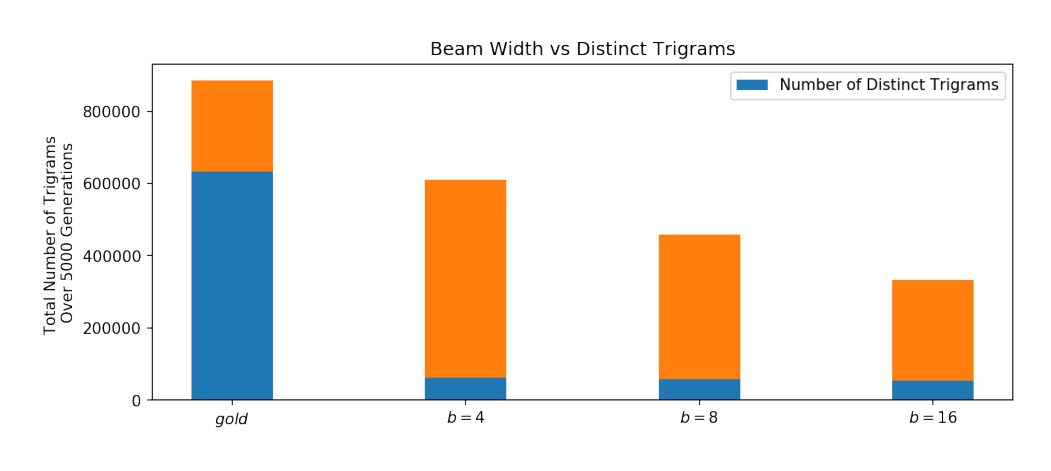
Figure 10: The total number of trigrams produced by Beam Search with varying beam widths, with gold (human) data for comparison. Note how the average length of generations goes down linearly with beam width, while the number of distinct trigrams stays constant and extremely low in comparison to gold data.
图 10:不同束宽下束搜索产生的三元组总数,并与黄金(人类)数据对照。请注意,生成的平均长度随束宽线性下降,而互异三元组的数量几乎不变,并且与黄金数据相比极低。
Appendix B Example generations
附录 B 生成样例
We include a set of examples for further qualitative comparison.
我们另附一组例子,供进一步的定性比较。
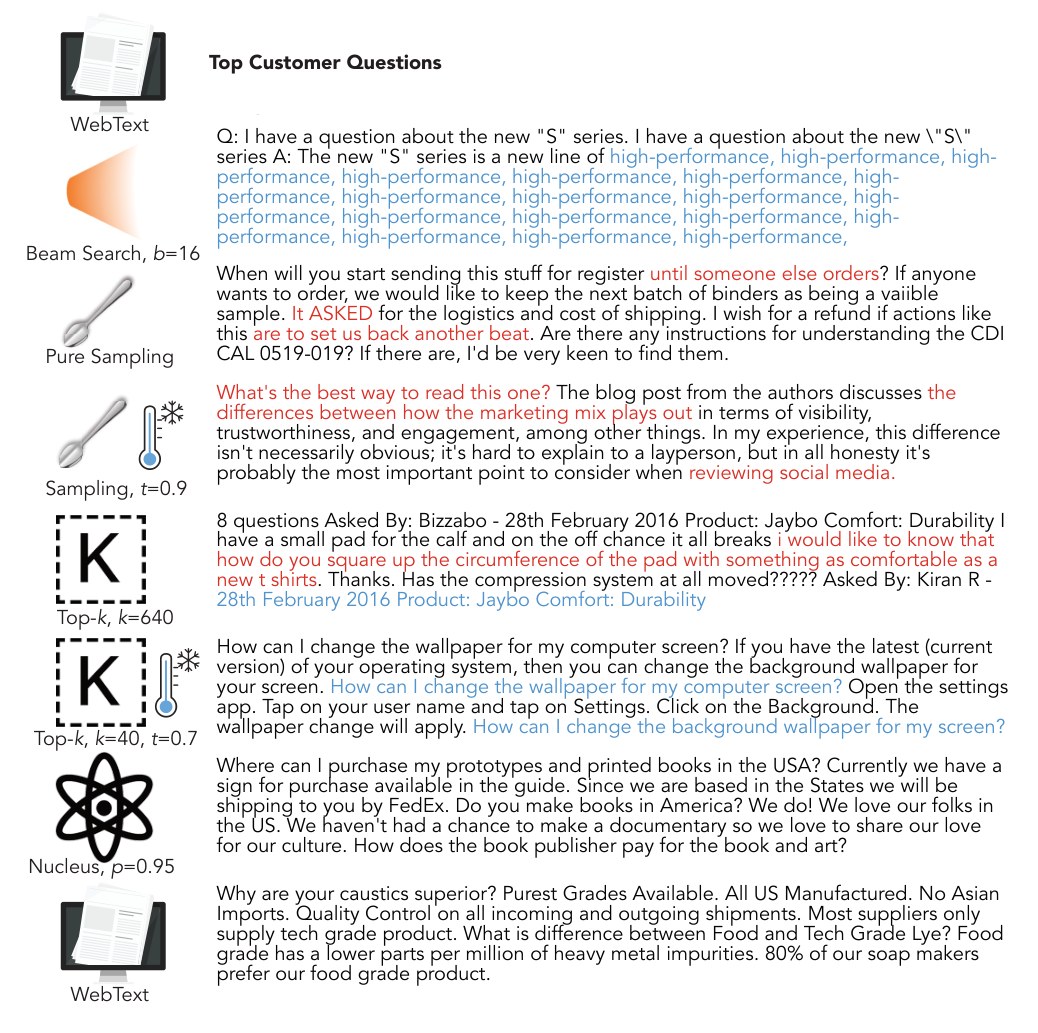
Figure 11: More example generations from an initial tag line. All generations available at https://github.com/ari-holtzman/degen
图 11:以一句起始标语续写的更多生成样例。全部生成见 https://github.com/ari-holtzman/degen
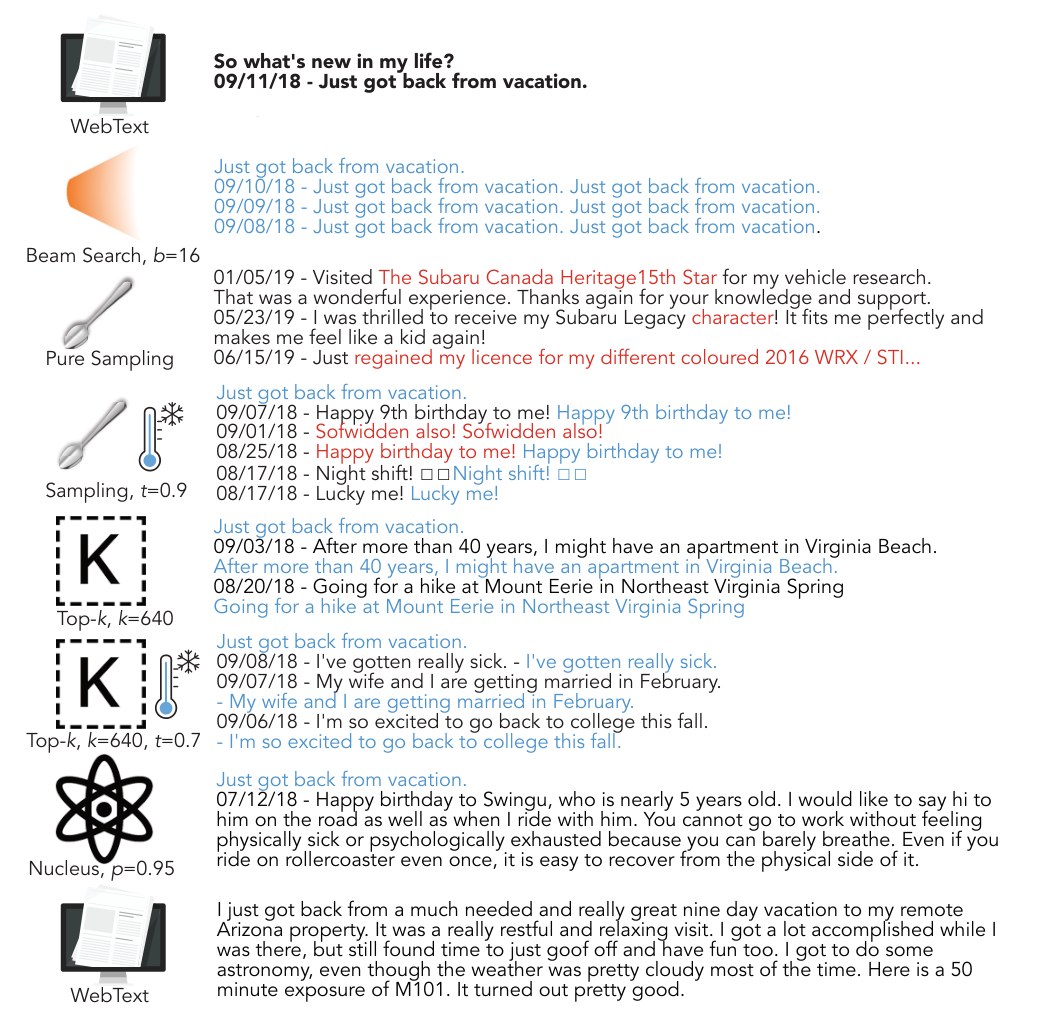
Figure 12: More example generations from an initial tag line. Note that Pure Sampling and Nucleus Sampling is the only algorithms that can escape the repetition loop, with Nucleus Sampling’s generation far closer in style to the ground truth text. All generations available at https://github.com/ari-holtzman/degen
图 12:以一句起始标语续写的更多生成样例。请注意,纯采样和核采样是唯一能逃出重复循环的算法,而核采样的生成在风格上远更接近真实文本。全部生成见 https://github.com/ari-holtzman/degen
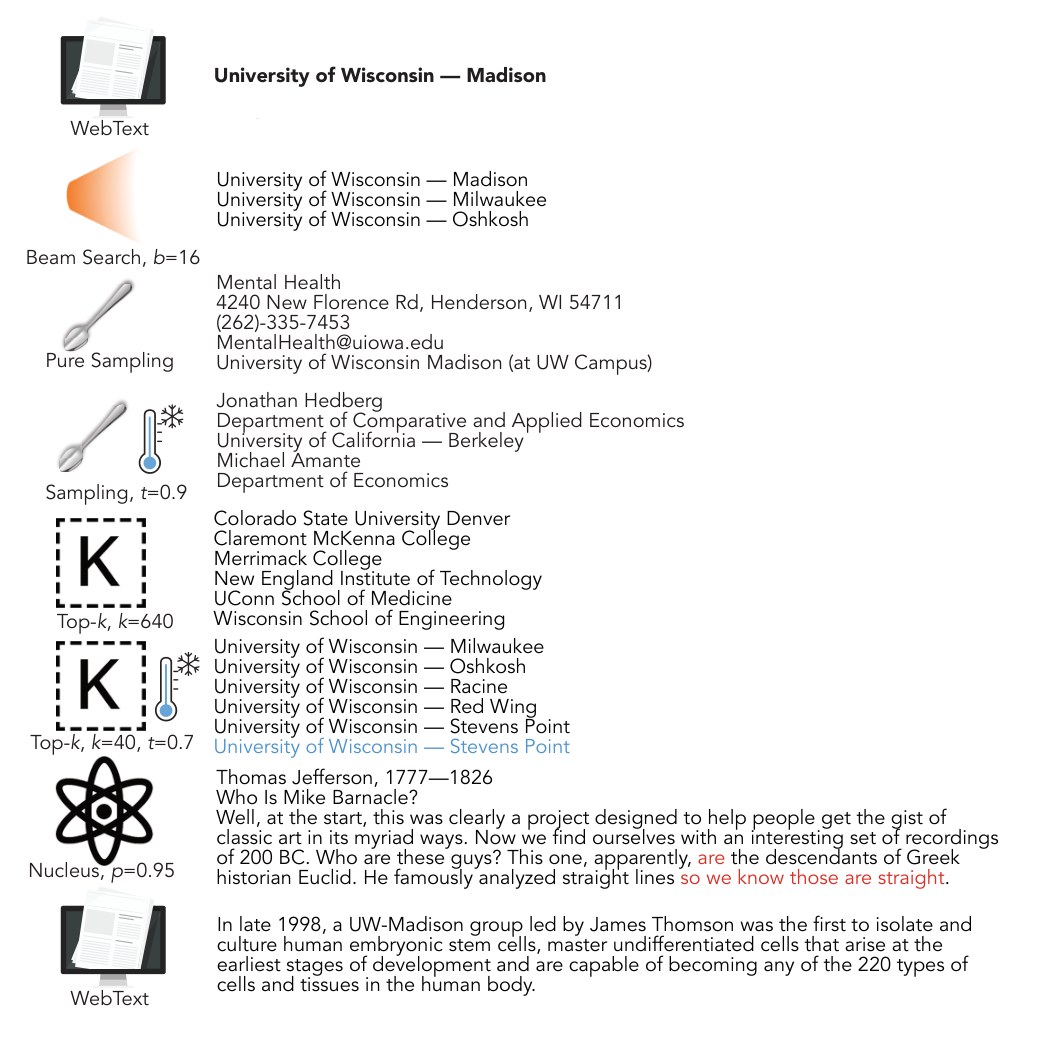
Figure 13: More example generations from an initial tag line. All generations available at https://github.com/ari-holtzman/degen
图 13:以一句起始标语续写的更多生成样例。全部生成见 https://github.com/ari-holtzman/degen