Generative Modeling by Estimating Gradients of the Data Distribution
Generative Modeling by Estimating Gradients of the Data Distribution
通过估计数据分布的梯度来做生成建模
Yang Song Affiliation: Stanford University Email: yangsong@cs.stanford.edu Stefano Ermon Affiliation: Stanford University Email: ermon@cs.stanford.edu
Abstract
摘要
We introduce a new generative model where samples are produced via Langevin dynamics using gradients of the data distribution estimated with score matching. Because gradients can be ill-defined and hard to estimate when the data resides on low-dimensional manifolds, we perturb the data with different levels of Gaussian noise, and jointly estimate the corresponding scores, i.e., the vector fields of gradients of the perturbed data distribution for all noise levels. For sampling, we propose an annealed Langevin dynamics where we use gradients corresponding to gradually decreasing noise levels as the sampling process gets closer to the data manifold. Our framework allows flexible model architectures, requires no sampling during training or the use of adversarial methods, and provides a learning objective that can be used for principled model comparisons. Our models produce samples comparable to GANs on MNIST, CelebA and CIFAR-10 datasets, achieving a new state-of-the-art inception score of 8.87 on CIFAR-10. Additionally, we demonstrate that our models learn effective representations via image inpainting experiments.
我们提出一种新的生成模型:先用分数匹配估计数据分布的梯度,再用 Langevin 动力学依此产生样本。数据若落在低维流形上,梯度可能没有良好定义,也不容易估准。于是我们给数据加上不同强度的高斯噪声,并同时估计所有这些扰动分布的分数,也就是各噪声水平下扰动数据分布梯度所构成的向量场。采样时,我们提出一种退火 Langevin 动力学:随着采样过程逐渐靠近数据流形,改用对应噪声水平逐步降低的梯度。这一框架对模型结构限制很少,训练时不必采样,也不必使用对抗方法,而且给出的学习目标可以用来对模型做有原则的比较。模型在 MNIST、CelebA 和 CIFAR-10 上给出的样本与 GAN 相当,并在 CIFAR-10 上把 Inception 分数做到当时无条件生成的最高水平 8.87。我们还用图像补全实验说明,模型学到了有效的表示。
1 Introduction
1 引言
Generative models have many applications in machine learning. To list a few, they have been used to generate high-fidelity images [26, 6], synthesize realistic speech and music fragments [58], improve the performance of semi-supervised learning [28, 10], detect adversarial examples and other anomalous data [54], imitation learning [22], and explore promising states in reinforcement learning [41]. Recent progress is mainly driven by two approaches: likelihood-based methods [17, 29, 11, 60] and generative adversarial networks (GAN [15]). The former uses log-likelihood (or a suitable surrogate) as the training objective, while the latter uses adversarial training to minimize -divergences [40] or integral probability metrics [2, 55] between model and data distributions.
生成模型在机器学习里有许多用途。举例来说,它们被用来生成高保真图像 [26, 6],合成听起来真实的语音和音乐片段 [58],提升半监督学习的表现 [28, 10],检测对抗样本和其他异常数据 [54],做模仿学习 [22],以及在强化学习里探索有希望的状态 [41]。近来的进展主要来自两条路线:基于似然的方法 [17, 29, 11, 60],以及生成对抗网络(GAN [15])。前者用对数似然(或合适的替代目标)来训练,后者用对抗训练去最小化模型分布与数据分布之间的 -散度 [40] 或积分概率度量 [2, 55]。
Although likelihood-based models and GANs have achieved great success, they have some intrinsic limitations. For example, likelihood-based models either have to use specialized architectures to build a normalized probability model (e.g., autoregressive models, flow models), or use surrogate losses (e.g., the evidence lower bound used in variational auto-encoders [29], contrastive divergence in energy-based models [21]) for training. GANs avoid some of the limitations of likelihood-based models, but their training can be unstable due to the adversarial training procedure. In addition, the GAN objective is not suitable for evaluating and comparing different GAN models. While other objectives exist for generative modeling, such as noise contrastive estimation [19] and minimum probability flow [50], these methods typically only work well for low-dimensional data.
基于似然的模型和 GAN 虽然成绩很好,但各自有内在限制。比如,基于似然的模型要么必须用专门结构来构造归一化的概率模型(例如自回归模型、流模型),要么只能用替代损失来训练(例如变分自编码器里的证据下界 [29],能量模型里的对比散度 [21])。GAN 避开了基于似然模型的一些限制,但对抗训练过程可能不稳定。此外,GAN 的目标也不适合用来评估和比较不同的 GAN 模型。生成建模还有噪声对比估计 [19] 和最小概率流 [50] 等其他目标,但这些方法通常只在低维数据上表现较好。
In this paper, we explore a new principle for generative modeling based on estimating and sampling from the (Stein) score [33] of the logarithmic data density, which is the gradient of the log-density function at the input data point. This is a vector field pointing in the direction where the log data density grows the most. We use a neural network trained with score matching [24] to learn this vector field from data. We then produce samples using Langevin dynamics, which approximately works by gradually moving a random initial sample to high density regions along the (estimated) vector field of scores. However, there are two main challenges with this approach. First, if the data distribution is supported on a low dimensional manifold—as it is often assumed for many real world datasets—the score will be undefined in the ambient space, and score matching will fail to provide a consistent score estimator. Second, the scarcity of training data in low data density regions, e.g., far from the manifold, hinders the accuracy of score estimation and slows down the mixing of Langevin dynamics sampling. Since Langevin dynamics will often be initialized in low-density regions of the data distribution, inaccurate score estimation in these regions will negatively affect the sampling process. Moreover, mixing can be difficult because of the need of traversing low density regions to transition between modes of the distribution.
本文探索一种新的生成建模原则:估计并沿着对数数据密度的(Stein)分数 [33] 来采样。这个分数就是对数密度函数在输入数据点处的梯度,是一个指向对数数据密度增长最快方向的向量场。我们用分数匹配 [24] 训练一个神经网络,从数据里学会这个向量场,再用 Langevin 动力学来产生样本——它大致是把一个随机的初始样本,沿着(估计出的)分数向量场,一步步挪到高密度区域。不过这条路有两个主要困难。第一,如果数据分布支撑在低维流形上——许多真实数据集都常被这样假设——分数在外围空间里就没有定义,分数匹配也无法给出一致的分数估计。第二,低数据密度区域(例如远离流形的地方)训练数据很少,既妨碍分数估计的精度,也拖慢 Langevin 动力学采样的混合。Langevin 动力学往往从数据分布的低密度区域起步,这些区域里分数估不准,采样过程就会受影响。此外,要在分布的不同模态之间跳转,必须穿过低密度区域,混合也会因此变得困难。
To tackle these two challenges, we propose to perturb the data with random Gaussian noise of various magnitudes. Adding random noise ensures the resulting distribution does not collapse to a low dimensional manifold. Large noise levels will produce samples in low density regions of the original (unperturbed) data distribution, thus improving score estimation. Crucially, we train a single score network conditioned on the noise level and estimate the scores at all noise magnitudes. We then propose an annealed version of Langevin dynamics, where we initially use scores corresponding to the highest noise level, and gradually anneal down the noise level until it is small enough to be indistinguishable from the original data distribution. Our sampling strategy is inspired by simulated annealing [30, 37] which heuristically improves optimization for multimodal landscapes.
为了同时应对这两个困难,我们提议用不同幅度的随机高斯噪声去扰动数据。加上随机噪声之后,得到的分布就不会塌缩到低维流形上。较大的噪声水平会在原先(未扰动)数据分布的低密度区域里产生样本,从而改善分数估计。关键在于,我们训练一个以噪声水平为条件的单一分数网络,同时估计所有噪声幅度下的分数。随后我们提出一种退火版的 Langevin 动力学:一开始使用最高噪声水平对应的分数,再逐步把噪声降到小到与原始数据分布无法区分。这一采样策略受到模拟退火 [30, 37] 的启发,后者可以启发式地改善多峰地形上的优化。
Our approach has several desirable properties. First, our objective is tractable for almost all parameterizations of the score networks without the need of special constraints or architectures, and can be optimized without adversarial training, MCMC sampling, or other approximations during training. The objective can also be used to quantitatively compare different models on the same dataset. Experimentally, we demonstrate the efficacy of our approach on MNIST, CelebA [34], and CIFAR-10 [31]. We show that the samples look comparable to those generated from modern likelihood-based models and GANs. On CIFAR-10, our model sets the new state-of-the-art inception score of 8.87 for unconditional generative models, and achieves a competitive FID score of 25.32. We show that the model learns meaningful representations of the data by image inpainting experiments.
我们的方法有几条好性质。第一,对几乎所有分数网络的参数化,目标都容易计算,不必施加特殊约束或结构,优化时也不需要对抗训练、MCMC 采样或训练过程中的其他近似。同一数据集上,这个目标还可以用来定量比较不同模型。实验上,我们在 MNIST、CelebA [34] 和 CIFAR-10 [31] 上验证了方法的效果。样本看起来与现代基于似然的模型和 GAN 生成的结果相当。在 CIFAR-10 上,我们的模型把无条件生成模型的 Inception 分数做到当时最高的 8.87,FID 为 25.32,也有竞争力。我们还通过图像补全实验说明,模型学到了有意义的数据表示。
2 Score-based generative modeling
2 基于分数的生成建模
Suppose our dataset consists of i.i.d. samples from an unknown data distribution . We define the score of a probability density to be . The score network is a neural network parameterized by , which will be trained to approximate the score of . The goal of generative modeling is to use the dataset to learn a model for generating new samples from . The framework of score-based generative modeling has two ingredients: score matching and Langevin dynamics.
设数据集由未知数据分布 的独立同分布样本 组成。我们把概率密度 的分数定义为 。分数网络 是由 参数化的神经网络,训练目标是逼近 的分数。生成建模的目标,是利用这份数据集学会一个能从 里产生新样本的模型。基于分数的生成建模包含两个要素:分数匹配和 Langevin 动力学。
2.1 Score matching for score estimation
2.1 用分数匹配来估计分数
Score matching [24] is originally designed for learning non-normalized statistical models based on i.i.d. samples from an unknown data distribution. Following [53], we repurpose it for score estimation. Using score matching, we can directly train a score network to estimate without training a model to estimate first. Different from the typical usage of score matching, we opt not to use the gradient of an energy-based model as the score network to avoid extra computation due to higher-order gradients. The objective minimizes , which can be shown equivalent to the following up to a constant
分数匹配 [24] 最初是为了根据未知数据分布的独立同分布样本,来学习未归一化的统计模型。我们沿用 [53] 的做法,把它改用来估计分数。借助分数匹配,我们可以直接训练分数网络 去估计 ,而不必先训练一个模型去估计 。和分数匹配的典型用法不同,我们不把能量模型的梯度当作分数网络,以免高阶梯度带来额外计算。目标是最小化 ,可以证明它与下式只差一个常数
where denotes the Jacobian of . As shown in [53], under some regularity conditions the minimizer of Eq. (3) (denoted as ) satisfies almost surely. In practice, the expectation over in Eq. (1) can be quickly estimated using data samples. However, score matching is not scalable to deep networks and high dimensional data [53] due to the computation of . Below we discuss two popular methods for large scale score matching.
其中 表示 的 Jacobi 矩阵。如 [53] 所示,在若干正则条件下,式 (3) 的最小化元(记为 )几乎处处满足 。实践中,式 (1) 里对 的期望可以用数据样本迅速估计。不过,由于要计算 ,分数匹配很难扩到深度网络和高维数据 [53]。下面讨论两种用于大规模分数匹配的常用方法。
Denoising score matching
Denoising score matching [61] is a variant of score matching that completely circumvents . It first perturbs the data point with a pre-specified noise distribution and then employs score matching to estimate the score of the perturbed data distribution . The objective was proved equivalent to the following:
去噪分数匹配
去噪分数匹配 [61] 是分数匹配的一种变体,可以完全绕开 。它先按预先指定的噪声分布 扰动数据点 ,再用分数匹配去估计扰动后数据分布 的分数。可以证明,该目标等价于下式:
As shown in [61], the optimal score network (denoted as ) that minimizes Eq. (2) satisfies almost surely. However, is true only when the noise is small enough such that .
如 [61] 所示,最小化式 (2) 的最优分数网络(记为 )几乎处处满足 。不过,只有当噪声足够小、使得 时, 才成立。
Sliced score matching
Sliced score matching [53] uses random projections to approximate in score matching. The objective is
切片分数匹配
切片分数匹配 [53] 用随机投影来近似分数匹配里的 。目标是
where is a simple distribution of random vectors, e.g., the multivariate standard normal. As shown in [53], the term can be efficiently computed by forward mode auto-differentiation. Unlike denoising score matching which estimates the scores of perturbed data, sliced score matching provides score estimation for the original unperturbed data distribution, but requires around four times more computations due to the forward mode auto-differentiation.
其中 是随机向量的一个简单分布,例如多元标准正态分布。如 [53] 所示, 这一项可以用前向模式自动微分高效计算。去噪分数匹配估计的是受扰动数据的分数,切片分数匹配则能为原始的未扰动数据分布提供分数估计,但由于要用前向模式自动微分,计算量大约多四倍。
2.2 Sampling with Langevin dynamics
2.2 用 Langevin 动力学采样
Langevin dynamics can produce samples from a probability density using only the score function . Given a fixed step size , and an initial value with being a prior distribution, the Langevin method recursively computes the following
Langevin 动力学可以只凭分数函数 ,就从概率密度 中产生样本。给定固定步长 ,以及来自某个先验分布 的初值 ,Langevin 方法递归计算下式
where . The distribution of equals when and , in which case becomes an exact sample from under some regularity conditions [62]. When and , a Metropolis-Hastings update is needed to correct the error of Eq. (4), but it can often be ignored in practice [9, 12, 39]. In this work, we assume this error is negligible when is small and is large.
其中 。当 且 时, 的分布等于 ,此时在若干正则条件下 就成为 的精确样本 [62]。当 且 时,需要一次 Metropolis-Hastings 更新来纠正式 (4) 的误差,但实践中常常可以忽略 [9, 12, 39]。本文假定,当 较小、 较大时,这一误差可以忽略。
Note that sampling from Eq. (4) only requires the score function . Therefore, in order to obtain samples from , we can first train our score network such that and then approximately obtain samples with Langevin dynamics using . This is the key idea of our framework of score-based generative modeling.
注意,从式 (4) 采样只需要分数函数 。因此,为了从 得到样本,我们可以先训练分数网络使 ,再把 代入 Langevin 动力学,近似地得到样本。这就是我们基于分数的生成建模框架的核心想法。
3 Challenges of score-based generative modeling
3 基于分数的生成建模面临的困难
In this section, we analyze more closely the idea of score-based generative modeling. We argue that there are two major obstacles that prevent a naïve application of this idea.
这一节我们更仔细地分析基于分数的生成建模。我们认为,若只是朴素地套用这一想法,会碰上两个主要障碍。
3.1 The manifold hypothesis
3.1 流形假设
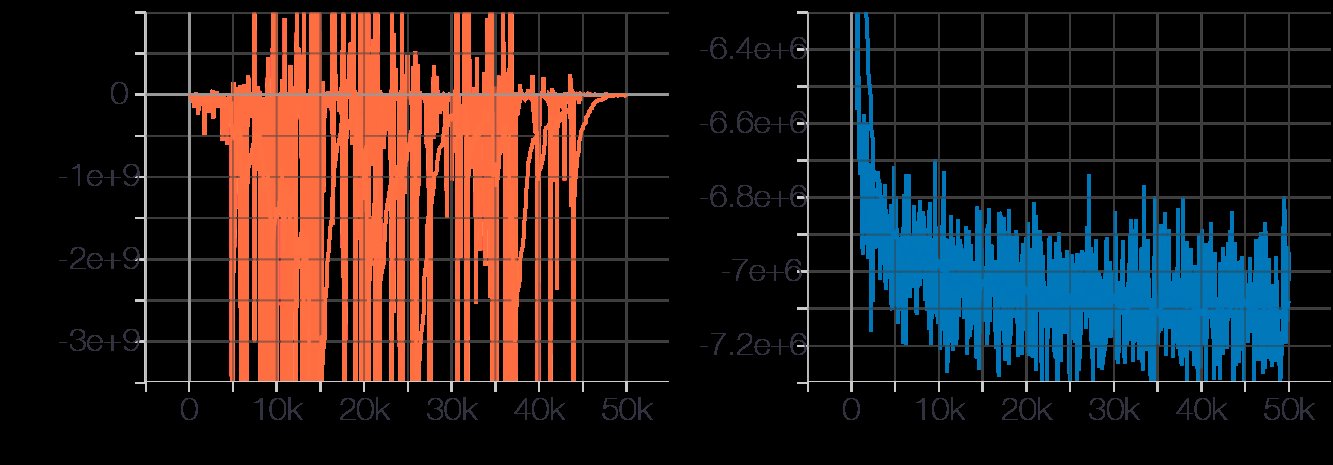
Figure 1: Left: Sliced score matching (SSM) loss w.r.t. iterations. No noise is added to data. Right: Same but data are perturbed with .
图 1:左:切片分数匹配(SSM)损失随迭代变化。数据未加噪声。右:同样设置,但数据被 扰动。
The manifold hypothesis states that data in the real world tend to concentrate on low dimensional manifolds embedded in a high dimensional space (a.k.a., the ambient space). This hypothesis empirically holds for many datasets, and has become the foundation of manifold learning [3, 47]. Under the manifold hypothesis, score-based generative models will face two key difficulties. First, since the score is a gradient taken in the ambient space, it is undefined when is confined to a low dimensional manifold. Second, the score matching objective Eq. (1) provides a consistent score estimator only when the support of the data distribution is the whole space (cf., Theorem 2 in [24]), and will be inconsistent when the data reside on a low-dimensional manifold.
流形假设认为,现实世界的数据往往集中在嵌入高维空间(也称为外围空间)的低维流形上。这一假设在许多数据集上都能得到经验支持,也已成为流形学习的基础 [3, 47]。在流形假设下,基于分数的生成模型会遇到两个关键困难。第一,分数 是在外围空间里取的梯度,一旦 被限制在低维流形上,它就没有定义。第二,分数匹配目标式 (1) 只有在数据分布的支撑是整个空间时,才给出一致的分数估计(参见 [24] 的定理 2);数据落在低维流形上时,估计就会不一致。
The negative effect of the manifold hypothesis on score estimation can be seen clearly from Fig. 1, where we train a ResNet (details in Appendix B.1) to estimate the data score on CIFAR-10. For fast training and faithful estimation of the data scores, we use the sliced score matching objective (Eq. (3)). As Fig. 1 (left) shows, when trained on the original CIFAR-10 images, the sliced score matching loss first decreases and then fluctuates irregularly. In contrast, if we perturb the data with a small Gaussian noise (such that the perturbed data distribution has full support over ), the loss curve will converge (right panel). Note that the Gaussian noise we impose is very small for images with pixel values in the range , and is almost indistinguishable to human eyes.
流形假设对分数估计的负面影响,从图 1 可以看得很清楚。我们在 CIFAR-10 上训练一个 ResNet(细节见附录 B.1)来估计数据分数。为了训练更快、对数据分数的估计也更忠实,我们使用切片分数匹配目标(式 (3))。如图 1(左)所示,在原始 CIFAR-10 图像上训练时,切片分数匹配损失先下降,随后不规则地波动。相反,如果用很小的高斯噪声扰动数据(使得扰动后的数据分布在 上有全支撑),损失曲线就会收敛(右图)。注意,我们施加的高斯噪声 对于像素值落在 的图像来说非常小,人眼几乎无法分辨。
3.2 Low data density regions
3.2 数据密度低的区域
The scarcity of data in low density regions can cause difficulties for both score estimation with score matching and MCMC sampling with Langevin dynamics.
低密度区域里数据稀少,既会给用分数匹配估计分数带来困难,也会给用 Langevin 动力学做 MCMC 采样带来困难。
3.2.1 Inaccurate score estimation with score matching
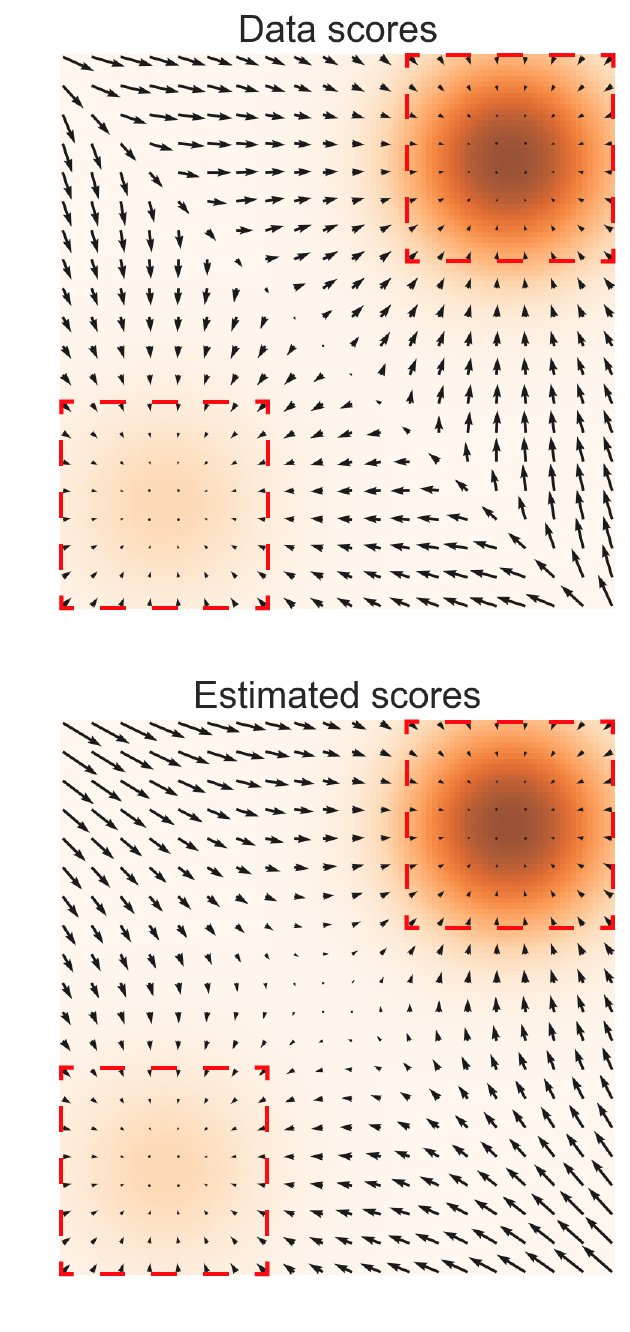
Figure 2: Left: ; Right: . The data density is encoded using an orange colormap: darker color implies higher density. Red rectangles highlight regions where .
3.2.1 用分数匹配估计分数时不够准
图 2:左:;右:。数据密度 用橙色颜色图编码:颜色越深表示密度越高。红色矩形标出 的区域。
In regions of low data density, score matching may not have enough evidence to estimate score functions accurately, due to the lack of data samples. To see this, recall from Section 2.1 that score matching minimizes the expected squared error of the score estimates, i.e., . In practice, the expectation w.r.t. the data distribution is always estimated using i.i.d. samples . Consider any region such that . In most cases , and score matching will not have sufficient data samples to estimate accurately for .
在数据密度低的区域,由于缺少数据样本,分数匹配可能没有足够证据把分数函数估准。为看清这一点,回顾第 2.1 节:分数匹配最小化的是分数估计的期望平方误差,即 。实践中,对数据分布的期望总是用独立同分布样本 来估计。考虑任意区域 ,使得 。多数情况下 ,分数匹配也就没有足够的数据样本,去把 处的 估准。
To demonstrate the negative effect of this, we provide the result of a toy experiment (details in Appendix B.1) in Fig. 2 where we use sliced score matching to estimate scores of a mixture of Gaussians . As the figure demonstrates, score estimation is only reliable in the immediate vicinity of the modes of , where the data density is high.
为说明这一点的负面影响,我们在图 2 中给出一个玩具实验的结果(细节见附录 B.1):用切片分数匹配去估计高斯混合 的分数。如图所示,分数估计只在 各个模态附近、数据密度高的地方才可靠。
3.2.2 Slow mixing of Langevin dynamics
When two modes of the data distribution are separated by low density regions, Langevin dynamics will not be able to correctly recover the relative weights of these two modes in reasonable time, and therefore might not converge to the true distribution. Our analyses of this are largely inspired by [63], which analyzed the same phenomenon in the context of density estimation with score matching.
3.2.2 Langevin 动力学混合缓慢
当数据分布的两个模态被低密度区域隔开时,Langevin 动力学无法在合理时间内正确恢复这两个模态的相对权重,因此可能不会收敛到真实分布。我们对这一点的分析很大程度上受到 [63] 的启发,该文在用分数匹配做密度估计的语境下分析过同一现象。
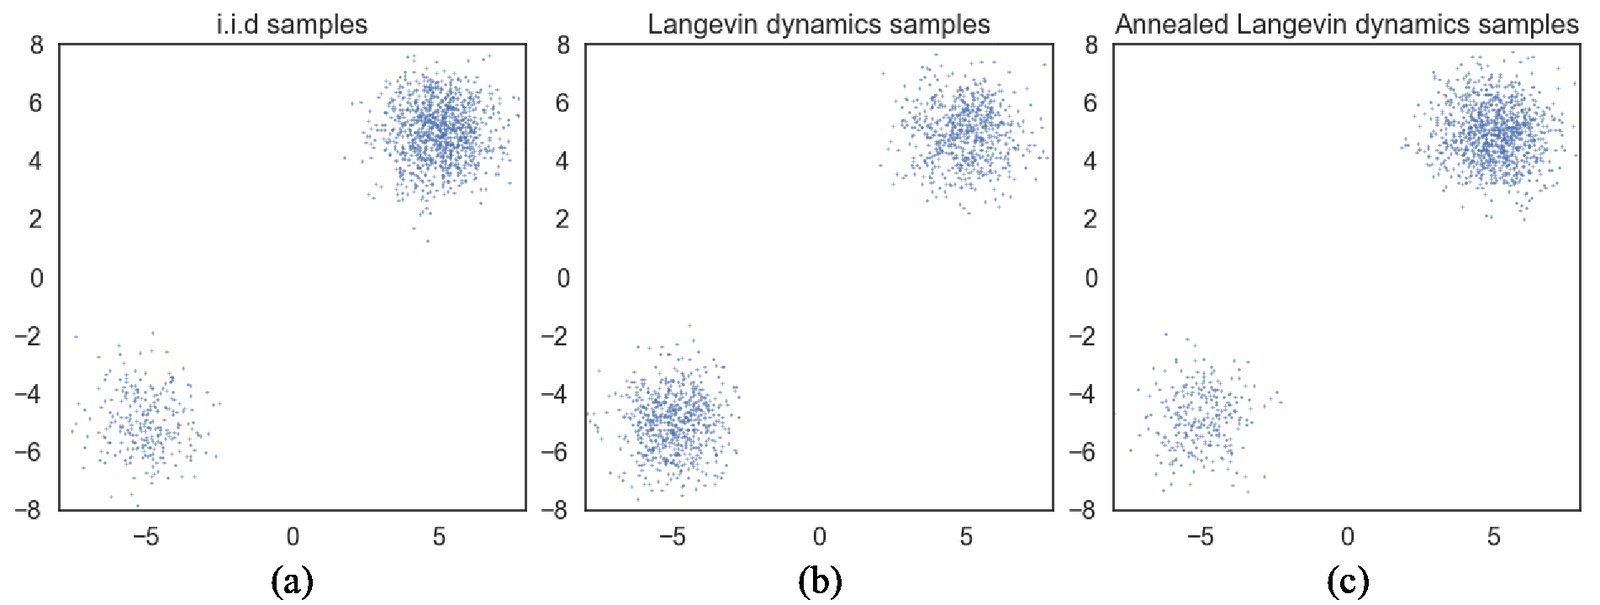
Figure 3: Samples from a mixture of Gaussian with different methods. (a) Exact sampling. (b) Sampling using Langevin dynamics with the exact scores. (c) Sampling using annealed Langevin dynamics with the exact scores. Clearly Langevin dynamics estimate the relative weights between the two modes incorrectly, while annealed Langevin dynamics recover the relative weights faithfully.
图 3:用不同方法从高斯混合中采样。(a) 精确采样。(b) 用精确分数做 Langevin 动力学采样。(c) 用精确分数做退火 Langevin 动力学采样。可以清楚地看到,Langevin 动力学把两个模态的相对权重估错了,而退火 Langevin 动力学能够忠实恢复相对权重。
Consider a mixture distribution , where and are normalized distributions with disjoint supports, and . In the support of , , and in the support of , . In either case, the score does not depend on . Since Langevin dynamics use to sample from , the samples obtained will not depend on . In practice, this analysis also holds when different modes have approximately disjoint supports—they may share the same support but be connected by regions of small data density. In this case, Langevin dynamics can produce correct samples in theory, but may require a very small step size and a very large number of steps to mix.
考虑混合分布 ,其中 和 是支撑不相交的归一化分布,且 。在 的支撑上,;在 的支撑上,。无论哪种情形,分数 都不依赖于 。既然 Langevin 动力学用 从 采样,得到的样本也就不会依赖于 。实践中,当不同模态的支撑只是近似不相交时——它们可能共享同一支撑,但由数据密度很小的区域相连——这一分析同样成立。此时 Langevin 动力学理论上仍能产生正确样本,但可能需要非常小的步长和非常多的步数才能混合。
To verify this analysis, we test Langevin dynamics sampling for the same mixture of Gaussian used in Section 3.2.1 and provide the results in Fig. 3. We use the ground truth scores when sampling with Langevin dynamics. Comparing Fig. 3(b) with (a), it is obvious that the samples from Langevin dynamics have incorrect relative density between the two modes, as predicted by our analysis.
为验证这一分析,我们在第 3.2.1 节用过的同一高斯混合上测试 Langevin 动力学采样,结果见图 3。用 Langevin 动力学采样时,我们使用真实分数。比较图 3(b) 与 (a),可以明显看出 Langevin 动力学给出的样本在两个模态之间的相对密度不正确,与我们的分析一致。
4 Noise Conditional Score Networks: learning and inference
4 噪声条件分数网络:学习与推断
We observe that perturbing data with random Gaussian noise makes the data distribution more amenable to score-based generative modeling. First, since the support of our Gaussian noise distribution is the whole space, the perturbed data will not be confined to a low dimensional manifold, which obviates difficulties from the manifold hypothesis and makes score estimation well-defined. Second, large Gaussian noise has the effect of filling low density regions in the original unperturbed data distribution; therefore score matching may get more training signal to improve score estimation. Furthermore, by using multiple noise levels we can obtain a sequence of noise-perturbed distributions that converge to the true data distribution. We can improve the mixing rate of Langevin dynamics on multimodal distributions by leveraging these intermediate distributions in the spirit of simulated annealing [30] and annealed importance sampling [37].
我们观察到,用随机高斯噪声扰动数据,会让数据分布更适合基于分数的生成建模。第一,我们所用高斯噪声的支撑是整个空间,受扰动的数据就不会被限制在低维流形上,从而避开流形假设带来的困难,也让分数估计有良好定义。第二,较大的高斯噪声会填补原先未扰动数据分布中的低密度区域,分数匹配因此能获得更多训练信号,从而改善分数估计。进一步地,使用多个噪声水平,可以得到一列收敛到真实数据分布的受噪声扰动的分布。我们可以借助这些中间分布,按模拟退火 [30] 和退火重要性采样 [37] 的精神,提高 Langevin 动力学在多峰分布上的混合速度。
Built upon this intuition, we propose to improve score-based generative modeling by 1) perturbing the data using various levels of noise; and 2) simultaneously estimating scores corresponding to all noise levels by training a single conditional score network. After training, when using Langevin dynamics to generate samples, we initially use scores corresponding to large noise, and gradually anneal down the noise level. This helps smoothly transfer the benefits of large noise levels to low noise levels where the perturbed data are almost indistinguishable from the original ones. In what follows, we will elaborate more on the details of our method, including the architecture of our score networks, the training objective, and the annealing schedule for Langevin dynamics.
基于这一直觉,我们提议从两方面改进基于分数的生成建模:1)用多种水平的噪声去扰动数据;2)训练一个条件分数网络,同时估计所有噪声水平对应的分数。训练完成后,用 Langevin 动力学生成样本时,我们先使用大噪声对应的分数,再逐步把噪声水平降下来。这样可以把大噪声水平带来的好处,平稳地转移到小噪声水平——此时受扰动的数据已经几乎与原始数据无法区分。下文将更详细地说明我们的方法,包括分数网络的结构、训练目标,以及 Langevin 动力学的退火日程。
4.1 Noise Conditional Score Networks
4.1 噪声条件分数网络
Let be a positive geometric sequence that satisfies . Let denote the perturbed data distribution. We choose the noise levels such that is large enough to mitigate the difficulties discussed in Section 3, and is small enough to minimize the effect on data. We aim to train a conditional score network to jointly estimate the scores of all perturbed data distributions, i.e., . Note that when . We call a Noise Conditional Score Network (NCSN).
设 是满足 的正几何序列。记 为受扰动的数据分布。我们选取噪声水平 ,使得 大到足以缓解第 3 节讨论的困难,而 小到对数据的影响可以尽量忽略。我们的目标是训练一个条件分数网络,联合估计所有受扰动数据分布的分数,也即 。注意当 时,。我们把 称为噪声条件分数网络(Noise Conditional Score Network,NCSN)。
Similar to likelihood-based generative models and GANs, the design of model architectures plays an important role in generating high quality samples. In this work, we mostly focus on architectures useful for image generation, and leave the architecture design for other domains as future work. Since the output of our noise conditional score network has the same shape as the input image , we draw inspiration from successful model architectures for dense prediction of images (e.g., semantic segmentation). In the experiments, our model combines the architecture design of U-Net [46] with dilated/atrous convolution [64, 65, 8]—both of which have been proved very successful in semantic segmentation. In addition, we adopt instance normalization in our score network, inspired by its superior performance in some image generation tasks [57, 13, 23], and we use a modified version of conditional instance normalization [13] to provide conditioning on . More details on our architecture can be found in Appendix A.
与基于似然的生成模型和 GAN 类似,模型结构设计对生成高质量样本很重要。本文主要关注有助于图像生成的结构,把其他领域的结构设计留作未来工作。由于噪声条件分数网络 的输出与输入图像 形状相同,我们从图像稠密预测(例如语义分割)中成功的模型结构汲取灵感。实验里,我们的模型 把 U-Net [46] 的结构设计与膨胀/空洞卷积 [64, 65, 8] 结合起来——两者在语义分割中都已被证明非常有效。此外,受其在某些图像生成任务中出色表现的启发 [57, 13, 23],我们在分数网络里采用实例归一化,并用改良版的条件实例归一化 [13] 来提供对 的条件。更多结构细节见附录 A。
4.2 Learning NCSNs via score matching
4.2 用分数匹配学习 NCSN
Both sliced and denoising score matching can train NCSNs. We adopt denoising score matching as it is slightly faster and naturally fits the task of estimating scores of noise-perturbed data distributions. However, we emphasize that empirically sliced score matching can train NCSNs as well as denoising score matching. We choose the noise distribution to be ; therefore . For a given , the denoising score matching objective (Eq. (2)) is
切片分数匹配和去噪分数匹配都可以训练 NCSN。我们采用去噪分数匹配,因为它稍快一些,而且天然契合估计受噪声扰动的数据分布分数这一任务。不过我们强调,经验上切片分数匹配训练 NCSN 的效果也可以与去噪分数匹配相当。我们把噪声分布取为 ,因此 。对给定的 ,去噪分数匹配目标(式 (2))是
Then, we combine Eq. (5) for all to get one unified objective
随后,我们把式 (5) 对所有 结合起来,得到一个统一目标
where is a coefficient function depending on . Assuming has enough capacity, minimizes Eq. (6) if and only if a.s. for all , because Eq. (6) is a conical combination of denoising score matching objectives.
其中 是依赖于 的系数函数。只要 容量足够, 最小化式 (6),当且仅当对所有 几乎处处有 ,因为式 (6) 是 个去噪分数匹配目标的圆锥组合。
There can be many possible choices of . Ideally, we hope that the values of for all are roughly of the same order of magnitude. Empirically, we observe that when the score networks are trained to optimality, we approximately have . This inspires us to choose . Because under this choice, we have . Since and , we can easily conclude that the order of magnitude of does not depend on .
可以有许多可能的选择。理想情况下,我们希望所有 上 的数值大致处于同一量级。经验上我们观察到,当分数网络被训练到最优时,近似有 。这启发我们取 。在这一选择下,。由于 且 ,不难得出 的量级不依赖于 。
We emphasize that our objective Eq. (6) requires no adversarial training, no surrogate losses, and no sampling from the score network during training (e.g., unlike contrastive divergence). Also, it does not require to have special architectures in order to be tractable. In addition, when and are fixed, it can be used to quantitatively compare different NCSNs.
我们强调,我们的目标式 (6) 不需要对抗训练,不需要替代损失,训练时也不必从分数网络中采样(例如,与对比散度不同)。它也不要求 必须具备特殊结构才能计算。此外,当 和 固定时,它可以用来定量比较不同的 NCSN。
4.3 NCSN inference via annealed Langevin dynamics
4.3 用退火 Langevin 动力学做 NCSN 推断
1: .
2: Initialize
3: for to do
4: is the step size.
5: for to do
6: Draw
7:
8: end for
9:
10: end for
11: return
Algorithm 1 Annealed Langevin dynamics.
1: .
2: 初始化
3: for to do
4: 是步长。
5: for to do
6: 抽取
7:
8: end for
9:
10: end for
11: return
算法 1 退火 Langevin 动力学。
After the NCSN is trained, we propose a sampling approach—annealed Langevin dynamics (Alg. 1)—to produced samples, inspired by simulated annealing [30] and annealed importance sampling [37]. As shown in Alg. 1, we start annealed Langevin dynamics by initializing the samples from some fixed prior distribution, e.g., uniform noise. Then, we run Langevin dynamics to sample from with step size . Next, we run Langevin dynamics to sample from , starting from the final samples of the previous simulation and using a reduced step size . We continue in this fashion, using the final samples of Langevin dynamics for as the initial samples of Langevin dynamic for , and tuning down the step size gradually with . Finally, we run Langevin dynamics to sample from , which is close to when .
NCSN 训练完成后,我们提出一种采样方法——退火 Langevin 动力学(算法 1)——来产生样本,其灵感来自模拟退火 [30] 和退火重要性采样 [37]。如算法 1 所示,退火 Langevin 动力学先从某个固定的先验分布初始化样本,例如均匀噪声。然后,我们用步长 运行 Langevin 动力学,从 中采样。接着,我们从上一轮模拟的最终样本出发,用缩小后的步长 运行 Langevin 动力学,从 中采样。我们按这种方式继续:把针对 的 Langevin 动力学的最终样本,当作针对 的 Langevin 动力学的初始样本,并按 逐步调小步长 。最后,我们运行 Langevin 动力学,从 中采样;当 时,它已接近 。
Since the distributions are all perturbed by Gaussian noise, their supports span the whole space and their scores are well-defined, avoiding difficulties from the manifold hypothesis. When is sufficiently large, the low density regions of become small and the modes become less isolated. As discussed previously, this can make score estimation more accurate, and the mixing of Langevin dynamics faster. We can therefore assume that Langevin dynamics produce good samples for . These samples are likely to come from high density regions of , which means they are also likely to reside in the high density regions of , given that and only slightly differ from each other. As score estimation and Langevin dynamics perform better in high density regions, samples from will serve as good initial samples for Langevin dynamics of . Similarly, provides good initial samples for , and finally we obtain samples of good quality from .
由于分布 都受到高斯噪声扰动,它们的支撑铺满整个空间,分数也有良好定义,从而避开了流形假设带来的困难。当 足够大时, 的低密度区域变小,各模态也不那么孤立。如前所述,这可以让分数估计更准,也让 Langevin 动力学混合得更快。因此可以假定 Langevin 动力学能为 产生较好的样本。这些样本很可能来自 的高密度区域,而 与 只稍有差别,它们因此也很可能落在 的高密度区域里。由于分数估计和 Langevin 动力学在高密度区域表现更好,来自 的样本就会成为 上 Langevin 动力学的良好初值。类似地, 为 提供良好初值,我们最终从 得到质量较好的样本。
There could be many possible ways of tuning according to in Alg. 1. Our choice is . The motivation is to fix the magnitude of the “signal-to-noise” ratio in Langevin dynamics. Note that . Recall that empirically we found when the score network is trained close to optimal, in which case . Therefore does not depend on .
在算法 1 里,根据 来调节 可以有许多方式。我们的选择是 。动机是固定 Langevin 动力学中“信噪比” 的幅度。注意 。回顾经验观察:当分数网络训练到接近最优时,,此时 。因此 ,不依赖于 。
To demonstrate the efficacy of our annealed Langevin dynamics, we provide a toy example where the goal is to sample from a mixture of Gaussian with two well-separated modes using only scores. We apply Alg. 1 to sample from the mixture of Gausssian used in Section 3.2. In the experiment, we choose to be a geometric progression, with , and . The results are provided in Fig. 3. Comparing Fig. 3 (b) against (c), annealed Langevin dynamics correctly recover the relative weights between the two modes whereas standard Langevin dynamics fail.
为展示退火 Langevin 动力学的效果,我们给出一个玩具例子:目标是只凭分数,从一个具有两个分离良好的模态的高斯混合中采样。我们对第 3.2 节使用的高斯混合应用算法 1。实验中,我们取 为几何级数,其中 ,,。结果见图 3。比较图 3 (b) 与 (c),退火 Langevin 动力学正确恢复了两个模态的相对权重,而标准 Langevin 动力学则失败了。
5 Experiments
5 实验
In this section, we demonstrate that our NCSNs are able to produce high quality image samples on several commonly used image datasets. In addition, we show that our models learn reasonable image representations by image inpainting experiments.
这一节我们展示,NCSN 能够在几个常用图像数据集上产生高质量的图像样本。此外,我们通过图像补全实验说明,模型学到了合理的图像表示。
Setup
We use MNIST, CelebA [34], and CIFAR-10 [31] datasets in our experiments. For CelebA, the images are first center-cropped to and then resized to . All images are rescaled so that pixel values are in . We choose different standard deviations such that is a geometric sequence with and . Note that Gaussian noise of is almost indistinguishable to human eyes for image data. When using annealed Langevin dynamics for image generation, we choose and , and use uniform noise as our initial samples. We found the results are robust w.r.t. the choice of , and between and generally works fine. We provide additional details on model architecture and settings in Appendix A and B.
设置
实验使用 MNIST、CelebA [34] 和 CIFAR-10 [31]。对 CelebA,图像先中心裁成 ,再调整到 。所有图像都重新缩放,使像素值落在 。我们选取 个不同的标准差,使 成为 、 的几何序列。注意,对图像数据而言, 的高斯噪声人眼几乎无法分辨。用退火 Langevin 动力学生成图像时,我们取 、,并以均匀噪声作为初始样本。我们发现结果对 的选择较为稳健, 取在 与 之间通常都能用。模型结构和更多设置见附录 A 和 B。
Table 1: Inception and FID scores for CIFAR-10
| Model | Inception | FID |
|---|---|---|
| CIFAR-10 Unconditional | ||
| PixelCNN [59] | ||
| PixelIQN [42] | ||
| EBM [12] | ||
| WGAN-GP [18] | ||
| MoLM [45] | ||
| SNGAN [36] | ||
| ProgressiveGAN [25] | - | |
| NCSN (Ours) | ||
| CIFAR-10 Conditional | ||
| EBM [12] | ||
| SNGAN [36] | ||
| BigGAN [6] |
表 1: CIFAR-10 上的 Inception 分数与 FID
| 模型 | Inception | FID |
|---|---|---|
| CIFAR-10 无条件 | ||
| PixelCNN [59] | ||
| PixelIQN [42] | ||
| EBM [12] | ||
| WGAN-GP [18] | ||
| MoLM [45] | ||
| SNGAN [36] | ||
| ProgressiveGAN [25] | - | |
| NCSN(本文) | ||
| CIFAR-10 有条件 | ||
| EBM [12] | ||
| SNGAN [36] | ||
| BigGAN [6] |
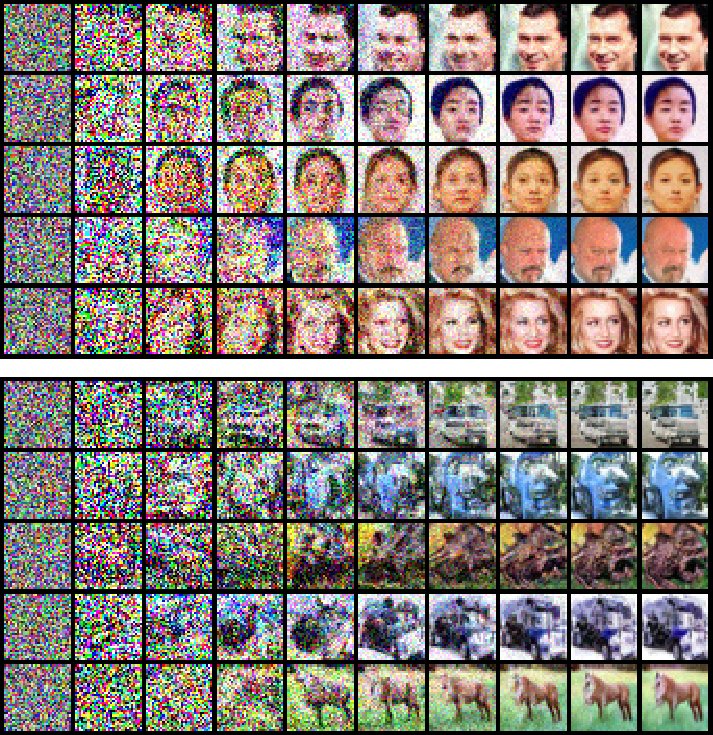
Figure 4: Intermediate samples of annealed Langevin dynamics.
图 4:退火 Langevin 动力学的中间样本。
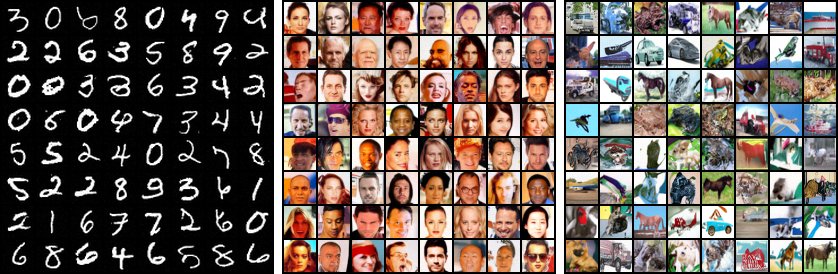
Figure 5: Uncurated samples on MNIST, CelebA, and CIFAR-10 datasets.
图 5:MNIST、CelebA 和 CIFAR-10 数据集上未经挑选的样本。
Image generation
In Fig. 5, we show uncurated samples from annealed Langevin dynamics for MNIST, CelebA and CIFAR-10. As shown by the samples, our generated images have higher or comparable quality to those from modern likelihood-based models and GANs. To intuit the procedure of annealed Langevin dynamics, we provide intermediate samples in Fig. 4, where each row shows how samples evolve from pure random noise to high quality images. More samples from our approach can be found in Appendix C. We also show the nearest neighbors of generated images in the training dataset in Appendix C.2, in order to demonstrate that our model is not simply memorizing training images. To show it is important to learn a conditional score network jointly for many noise levels and use annealed Langevin dynamics, we compare against a baseline approach where we only consider one noise level and use the vanilla Langevin dynamics sampling method. Although this small added noise helps circumvent the difficulty of the manifold hypothesis (as shown by Fig. 1, things will completely fail if no noise is added), it is not large enough to provide information on scores in regions of low data density. As a result, this baseline fails to generate reasonable images, as shown by samples in Appendix C.1.
图像生成
图 5 给出退火 Langevin 动力学在 MNIST、CelebA 和 CIFAR-10 上未经挑选的样本。从这些样本看,我们生成的图像质量高于或相当于现代基于似然的模型和 GAN。为了直观理解退火 Langevin 动力学的过程,我们在图 4 中给出中间样本,每一行展示样本如何从纯粹的随机噪声演变为高质量图像。更多来自本方法的样本见附录 C。我们还在附录 C.2 中展示生成图像在训练数据集里的最近邻,以说明模型并非只是在记忆训练图像。为说明联合学习一个覆盖多个噪声水平的条件分数网络、并使用退火 Langevin 动力学是重要的,我们对照了一种基线:只考虑单一噪声水平 ,并使用普通的 Langevin 动力学采样方法。尽管这点很小的附加噪声有助于绕开流形假设的困难(如图 1 所示,完全不加噪声会彻底失败),它仍不够大,无法提供低数据密度区域里的分数信息。因此,这一基线无法生成像样的图像,样本见附录 C.1。
For quantitative evaluation, we report inception [48] and FID [20] scores on CIFAR-10 in Tab. 1. As an unconditional model, we achieve the state-of-the-art inception score of 8.87, which is even better than most reported values for class-conditional generative models. Our FID score 25.32 on CIFAR-10 is also comparable to top existing models, such as SNGAN [36]. We omit scores on MNIST and CelebA as the scores on these two datasets are not widely reported, and different preprocessing (such as the center crop size of CelebA) can lead to numbers not directly comparable.
定量评估方面,我们在表 1 中报告 CIFAR-10 上的 Inception [48] 和 FID [20] 分数。作为一个无条件模型,我们把 Inception 分数做到当时最高的 8.87,甚至超过多数已报告的类别条件生成模型。我们在 CIFAR-10 上的 FID 分数 25.32 也与 SNGAN [36] 等现有顶尖模型相当。我们略去 MNIST 和 CelebA 上的分数,因为这两个数据集上的分数报告并不广泛,而且不同的预处理(例如 CelebA 的中心裁剪尺寸)会导致数字无法直接比较。
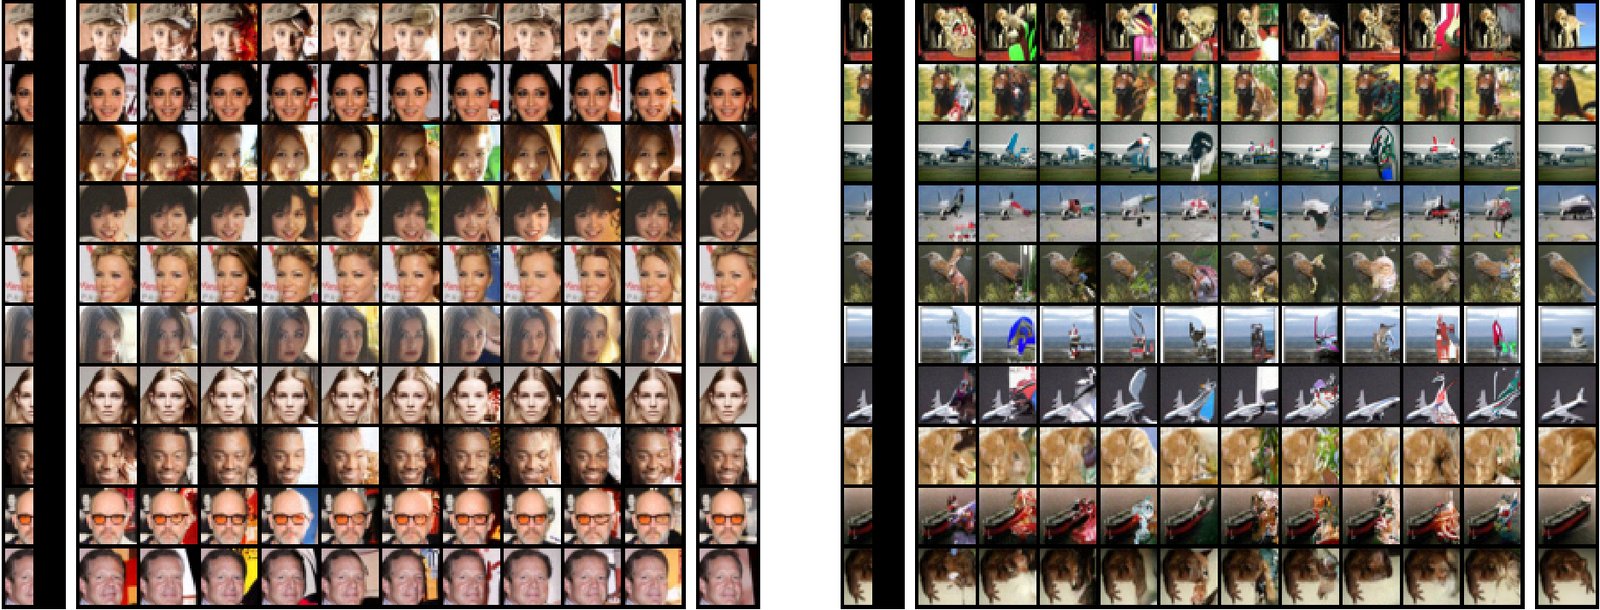
Figure 6: Image inpainting on CelebA (left) and CIFAR-10 (right). The leftmost column of each figure shows the occluded images, while the rightmost column shows the original images.
图 6:在 CelebA(左)和 CIFAR-10(右)上的图像补全。每张图最左边一列是被遮挡的图像,最右边一列是原始图像。
Image inpainting
In Fig. 6, we demonstrate that our score networks learn generalizable and semantically meaningful image representations that allow it to produce diverse image inpaintings. Note that some previous models such as PixelCNN can only impute images in the raster scan order. In contrast, our method can naturally handle images with occlusions of arbitrary shapes by a simple modification of the annealed Langevin dynamics procedure (details in Appendix B.3). We provide more image inpainting results in Appendix C.5.
图像补全
图 6 表明,我们的分数网络学到了可泛化、语义上有意义的图像表示,因而能够产生多样的图像补全结果。注意,此前一些模型如 PixelCNN 只能按光栅扫描顺序填补图像。相比之下,只需对退火 Langevin 动力学流程做简单修改(细节见附录 B.3),我们的方法就能自然处理任意形状遮挡的图像。更多图像补全结果见附录 C.5。
6 Related work
6 相关工作
Our approach has some similarities with methods that learn the transition operator of a Markov chain for sample generation [4, 51, 5, 16, 52]. For example, generative stochastic networks (GSN [4, 1]) use denoising autoencoders to train a Markov chain whose equilibrium distribution matches the data distribution. Similarly, our method trains the score function used in Langevin dynamics to sample from the data distribution. However, GSN often starts the chain very close to a training data point, and therefore requires the chain to transition quickly between different modes. In contrast, our annealed Langevin dynamics are initialized from unstructured noise. Nonequilibrium Thermodynamics (NET [51]) used a prescribed diffusion process to slowly transform data into random noise, and then learned to reverse this procedure by training an inverse diffusion. However, NET is not very scalable because it requires the diffusion process to have very small steps, and needs to simulate chains with thousands of steps at training time.
我们的方法与那些学习 Markov 链转移算子以生成样本的方法有一些相似之处 [4, 51, 5, 16, 52]。例如,生成随机网络(GSN [4, 1])用去噪自编码器训练一条 Markov 链,使其平衡分布与数据分布匹配。类似地,我们的方法训练的是 Langevin 动力学中使用的分数函数,以便从数据分布中采样。不过,GSN 常常让链条从非常靠近某个训练数据点的位置起步,因此要求链条能在不同模态之间快速转移。相反,我们的退火 Langevin 动力学从无结构的噪声初始化。非平衡热力学(NET [51])用一条预先指定的扩散过程,把数据缓慢变成随机噪声,再通过训练逆扩散来学习反转这一过程。不过 NET 不太容易扩规模,因为它要求扩散过程的步长非常小,并且在训练时需要模拟长达数千步的链条。
Previous approaches such as Infusion Training (IT [5]) and Variational Walkback (VW [16]) also employed different noise levels/temperatures for training transition operators of a Markov chain. Both IT and VW (as well as NET) train their models by maximizing the evidence lower bound of a suitable marginal likelihood. In practice, they tend to produce blurry image samples, similar to variational autoencoders. In contrast, our objective is based on score matching instead of likelihood, and we can produce images comparable to GANs.
此前如灌注训练(Infusion Training,IT [5])和变分回走(Variational Walkback,VW [16])等方法,也曾在训练 Markov 链转移算子时采用不同的噪声水平/温度。IT 和 VW(以及 NET)都通过最大化某个合适边际似然的证据下界来训练模型。实践中,它们往往像变分自编码器一样产生模糊的图像样本。相反,我们的目标基于分数匹配而不是似然,并且能够产生与 GAN 相当的图像。
There are several structural differences that further distinguish our approach from previous methods discussed above. First, we do not need to sample from a Markov chain during training. In contrast, the walkback procedure of GSNs needs multiple runs of the chain to generate “negative samples”. Other methods including NET, IT, and VW also need to simulate a Markov chain for every input to compute the training loss. This difference makes our approach more efficient and scalable for training deep models. Secondly, our training and sampling methods are decoupled from each other. For score estimation, both sliced and denoising score matching can be used. For sampling, any method based on scores is applicable, including Langevin dynamics and (potentially) Hamiltonian Monte Carlo [38]. Our framework allows arbitrary combinations of score estimators and (gradient-based) sampling approaches, whereas most previous methods tie the model to a specific Markov chain. Finally, our approach can be used to train energy-based models (EBM) by using the gradient of an energy-based model as the score model. In contrast, it is unclear how previous methods that learn transition operators of Markov chains can be directly used for training EBMs.
还有几处结构上的差异,使我们的方法进一步有别于上面讨论的已有方法。第一,我们在训练时不必从 Markov 链中采样。相反,GSN 的回走过程需要多次运行链条来生成“负样本”。NET、IT 和 VW 等方法,也需要对每个输入模拟一条 Markov 链才能计算训练损失。这一差别让我们的方法在训练深度模型时更高效、也更易于扩展。第二,我们的训练方法与采样方法是解耦的。估计分数时,切片分数匹配和去噪分数匹配都可以用;采样时,任何基于分数的方法都适用,包括 Langevin 动力学以及(潜在地)哈密顿蒙特卡洛 [38]。我们的框架允许分数估计器与(基于梯度的)采样方法任意组合,而多数已有方法则把模型绑定到一条特定的 Markov 链上。最后,我们的方法可以用来训练能量模型(EBM),只需把能量模型的梯度当作分数模型。相比之下,此前那些学习 Markov 链转移算子的方法,如何直接用于训练 EBM 并不清楚。
Score matching was originally proposed for learning EBMs. However, many existing methods based on score matching are either not scalable [24] or fail to produce samples of comparable quality to VAEs or GANs [27, 49]. To obtain better performance on training deep energy-based models, some recent works have resorted to contrastive divergence [21], and propose to sample with Langevin dynamics for both training and testing [12, 39]. However, unlike our approach, contrastive divergence uses the computationally expensive procedure of Langevin dynamics as an inner loop during training. The idea of combining annealing with denoising score matching has also been investigated in previous work under different contexts. In [14, 7, 66], different annealing schedules on the noise for training denoising autoencoders are proposed. However, their work is on learning representations for improving the performance of classification, instead of generative modeling. The method of denoising score matching can also be derived from the perspective of Bayes least squares [43, 44], using techniques of Stein’s Unbiased Risk Estimator [35, 56].
分数匹配最初是为学习 EBM 而提出的。不过,许多基于分数匹配的已有方法要么难以扩规模 [24],要么无法产生与 VAE 或 GAN 相当的样本 [27, 49]。为了在训练深度能量模型时获得更好表现,一些近期工作转而采用对比散度 [21],并提议在训练和测试时都用 Langevin 动力学采样 [12, 39]。不过,与我们的方法不同,对比散度把计算昂贵的 Langevin 动力学当作训练时的内层循环。把退火与去噪分数匹配结合起来的想法,此前也在不同语境下被研究过。[14, 7, 66] 提出了训练去噪自编码器时对噪声采用不同的退火日程。不过,他们的工作是学习表示以提升分类表现,而不是做生成建模。去噪分数匹配也可以从 Bayes 最小二乘的视角导出 [43, 44],并借助 Stein 无偏风险估计的技术 [35, 56]。
7 Conclusion
7 结论
We propose the framework of score-based generative modeling where we first estimate gradients of data densities via score matching, and then generate samples via Langevin dynamics. We analyze several challenges faced by a naïve application of this approach, and propose to tackle them by training Noise Conditional Score Networks (NCSN) and sampling with annealed Langevin dynamics. Our approach requires no adversarial training, no MCMC sampling during training, and no special model architectures. Experimentally, we show that our approach can generate high quality images that were previously only produced by the best likelihood-based models and GANs. We achieve the new state-of-the-art inception score on CIFAR-10, and an FID score comparable to SNGANs.
我们提出基于分数的生成建模框架:先用分数匹配估计数据密度的梯度,再用 Langevin 动力学生成样本。我们分析了朴素套用这一做法会面临的若干困难,并提议通过训练噪声条件分数网络(NCSN)、以及用退火 Langevin 动力学采样来应对它们。我们的方法不需要对抗训练,训练时不必做 MCMC 采样,也不需要特殊的模型结构。实验表明,我们的方法能够生成此前只有最好的基于似然的模型和 GAN 才能产生的高质量图像。我们在 CIFAR-10 上取得了新的最高 Inception 分数,FID 也与 SNGAN 相当。
Acknowledgements
致谢
Toyota Research Institute ("TRI") provided funds to assist the authors with their research but this article solely reflects the opinions and conclusions of its authors and not TRI or any other Toyota entity. This research was also supported by NSF (#1651565, #1522054, #1733686), ONR (N00014-19-1-2145), AFOSR (FA9550-19-1-0024).
References
参考文献
[1] G. Alain, Y. Bengio, L. Yao, J. Yosinski, E. Thibodeau-Laufer, S. Zhang, and P. Vincent. GSNs: generative stochastic networks. Information and Inference , 2016.
[2] M. Arjovsky, S. Chintala, and L. Bottou. Wasserstein generative adversarial networks. In D. Precup and Y. W. Teh, editors, Proceedings of the 34th International Conference on Machine Learning , volume 70 of Proceedings of Machine Learning Research , pages 214–223, International Convention Centre, Sydney, Australia, 06–11 Aug 2017. PMLR.
[3] M. Belkin and P. Niyogi. Laplacian eigenmaps for dimensionality reduction and data representation. Neural computation , 15(6):1373–1396, 2003.
[4] Y. Bengio, L. Yao, G. Alain, and P. Vincent. Generalized denoising auto-encoders as generative models. In Advances in neural information processing systems , pages 899–907, 2013.
[5] F. Bordes, S. Honari, and P. Vincent. Learning to generate samples from noise through infusion training. arXiv preprint arXiv:1703.06975 , 2017.
[6] A. Brock, J. Donahue, and K. Simonyan. Large scale GAN training for high fidelity natural image synthesis. In International Conference on Learning Representations , 2019.
[7] B. Chandra and R. K. Sharma. Adaptive noise schedule for denoising autoencoder. In International conference on neural information processing , pages 535–542. Springer, 2014.
[8] L.-C. Chen, G. Papandreou, I. Kokkinos, K. Murphy, and A. L. Yuille. Deeplab: Semantic image segmentation with deep convolutional nets, atrous convolution, and fully connected crfs. IEEE transactions on pattern analysis and machine intelligence , 40(4):834–848, 2017.
[9] T. Chen, E. Fox, and C. Guestrin. Stochastic gradient hamiltonian monte carlo. In International conference on machine learning , pages 1683–1691, 2014.
[10] Z. Dai, Z. Yang, F. Yang, W. W. Cohen, and R. R. Salakhutdinov. Good semi-supervised learning that requires a bad gan. In Advances in neural information processing systems , pages 6510–6520, 2017.
[11] L. Dinh, D. Krueger, and Y. Bengio. Nice: Non-linear independent components estimation. arXiv preprint arXiv:1410.8516 , 2014.
[12] Y. Du and I. Mordatch. Implicit generation and generalization in energy-based models. arXiv preprint arXiv:1903.08689 , 2019.
[13] V. Dumoulin, J. Shlens, and M. Kudlur. A learned representation for artistic style. In International Conference on Learning Representations 2017 , 2017.
[14] K. J. Geras and C. Sutton. Scheduled denoising autoencoders. arXiv preprint arXiv:1406.3269 , 2014.
[15] I. Goodfellow, J. Pouget-Abadie, M. Mirza, B. Xu, D. Warde-Farley, S. Ozair, A. Courville, and Y. Bengio. Generative adversarial nets. In Advances in neural information processing systems , pages 2672–2680, 2014.
[16] A. G. A. P. Goyal, N. R. Ke, S. Ganguli, and Y. Bengio. Variational walkback: Learning a transition operator as a stochastic recurrent net. In Advances in Neural Information Processing Systems , pages 4392–4402, 2017.
[17] A. Graves. Generating sequences with recurrent neural networks. arXiv preprint arXiv:1308.0850 , 2013.
[18] I. Gulrajani, F. Ahmed, M. Arjovsky, V. Dumoulin, and A. C. Courville. Improved training of wasserstein gans. In Advances in Neural Information Processing Systems , pages 5767–5777, 2017.
[19] M. Gutmann and A. Hyvärinen. Noise-contrastive estimation: A new estimation principle for unnormalized statistical models. In Proceedings of the Thirteenth International Conference on Artificial Intelligence and Statistics , pages 297–304, 2010.
[20] M. Heusel, H. Ramsauer, T. Unterthiner, B. Nessler, and S. Hochreiter. Gans trained by a two time-scale update rule converge to a local nash equilibrium. In Advances in Neural Information Processing Systems , pages 6626–6637, 2017.
[21] G. E. Hinton. Training products of experts by minimizing contrastive divergence. Neural computation , 14(8):1771–1800, 2002.
[22] J. Ho and S. Ermon. Generative adversarial imitation learning. In Advances in Neural Information Processing Systems , pages 4565–4573, 2016.
[23] X. Huang and S. Belongie. Arbitrary style transfer in real-time with adaptive instance normalization. In Proceedings of the IEEE International Conference on Computer Vision , pages 1501–1510, 2017.
[24] A. Hyvärinen. Estimation of non-normalized statistical models by score matching. Journal of Machine Learning Research , 6(Apr):695–709, 2005.
[25] T. Karras, T. Aila, S. Laine, and J. Lehtinen. Progressive growing of GANs for improved quality, stability, and variation. In International Conference on Learning Representations , 2018.
[26] T. Karras, S. Laine, and T. Aila. A style-based generator architecture for generative adversarial networks. arXiv preprint arXiv:1812.04948 , 2018.
[27] D. Kingma and Y. LeCun. Regularized estimation of image statistics by score matching. In Advances in Neural Information Processing Systems 23: 24th Annual Conference on Neural Information Processing Systems 2010, NIPS 2010 , 2010.
[28] D. P. Kingma, S. Mohamed, D. J. Rezende, and M. Welling. Semi-supervised learning with deep generative models. In Advances in neural information processing systems , pages 3581–3589, 2014.
[29] D. P. Kingma and M. Welling. Auto-encoding variational bayes. In ICLR , 2014.
[30] S. Kirkpatrick, C. D. Gelatt, and M. P. Vecchi. Optimization by simulated annealing. SCIENCE , 220(4598):671–680, 1983.
[31] A. Krizhevsky. Learning multiple layers of features from tiny images. Technical report, 2009.
[32] G. Lin, A. Milan, C. Shen, and I. Reid. Refinenet: Multi-path refinement networks for high-resolution semantic segmentation. In Proceedings of the IEEE conference on computer vision and pattern recognition , pages 1925–1934, 2017.
[33] Q. Liu, J. Lee, and M. Jordan. A kernelized stein discrepancy for goodness-of-fit tests. In International Conference on Machine Learning , pages 276–284, 2016.
[34] Z. Liu, P. Luo, X. Wang, and X. Tang. Deep learning face attributes in the wild. In Proceedings of International Conference on Computer Vision (ICCV) , 2015.
[35] K. Miyasawa. An empirical bayes estimator of the mean of a normal population. Bull. Inst. Internat. Statist , 38(181-188):1–2, 1961.
[36] T. Miyato, T. Kataoka, M. Koyama, and Y. Yoshida. Spectral normalization for generative adversarial networks. In International Conference on Learning Representations , 2018.
[37] R. M. Neal. Annealed importance sampling. Statistics and computing , 11(2):125–139, 2001.
[38] R. M. Neal. Mcmc using hamiltonian dynamics. arXiv preprint arXiv:1206.1901 , 2012.
[39] E. Nijkamp, M. Hill, T. Han, S.-C. Zhu, and Y. N. Wu. On the anatomy of mcmc-based maximum likelihood learning of energy-based models. arXiv preprint arXiv:1903.12370 , 2019.
[40] S. Nowozin, B. Cseke, and R. Tomioka. f-gan: Training generative neural samplers using variational divergence minimization. In Advances in neural information processing systems , pages 271–279, 2016.
[41] G. Ostrovski, M. G. Bellemare, A. van den Oord, and R. Munos. Count-based exploration with neural density models. In Proceedings of the 34th International Conference on Machine Learning-Volume 70 , pages 2721–2730. JMLR. org, 2017.
[42] G. Ostrovski, W. Dabney, and R. Munos. Autoregressive quantile networks for generative modeling. In ICML , volume 80 of Proceedings of Machine Learning Research , pages 3933–3942. PMLR, 2018.
[43] M. Raphan and E. P. Simoncelli. Learning to be bayesian without supervision. In Advances in neural information processing systems , pages 1145–1152, 2007.
[44] M. Raphan and E. P. Simoncelli. Least squares estimation without priors or supervision. Neural computation , 23(2):374–420, 2011.
[45] S. Ravuri, S. Mohamed, M. Rosca, and O. Vinyals. Learning implicit generative models with the method of learned moments. In J. Dy and A. Krause, editors, Proceedings of the 35th International Conference on Machine Learning , volume 80 of Proceedings of Machine Learning Research , pages 4314–4323, Stockholmsmässan, Stockholm Sweden, 10–15 Jul 2018. PMLR.
[46] O. Ronneberger, P.Fischer, and T. Brox. U-net: Convolutional networks for biomedical image segmentation. In Medical Image Computing and Computer-Assisted Intervention (MICCAI) , volume 9351 of LNCS , pages 234–241. Springer, 2015. (available on arXiv:1505.04597 [cs.CV]).
[47] S. T. Roweis and L. K. Saul. Nonlinear dimensionality reduction by locally linear embedding. science , 290(5500):2323–2326, 2000.
[48] T. Salimans, I. Goodfellow, W. Zaremba, V. Cheung, A. Radford, and X. Chen. Improved techniques for training gans. In Advances in neural information processing systems , pages 2234–2242, 2016.
[49] S. Saremi, A. Mehrjou, B. Schölkopf, and A. Hyvärinen. Deep energy estimator networks. arXiv preprint arXiv:1805.08306 , 2018.
[50] J. Sohl-Dickstein, P. Battaglino, and M. R. DeWeese. Minimum probability flow learning. arXiv preprint arXiv:0906.4779 , 2009.
[51] J. Sohl-Dickstein, E. Weiss, N. Maheswaranathan, and S. Ganguli. Deep unsupervised learning using nonequilibrium thermodynamics. In International Conference on Machine Learning , pages 2256–2265, 2015.
[52] J. Song, S. Zhao, and S. Ermon. A-nice-mc: Adversarial training for mcmc. In Advances in Neural Information Processing Systems , pages 5140–5150, 2017.
[53] Y. Song, S. Garg, J. Shi, and S. Ermon. Sliced score matching: A scalable approach to density and score estimation. In Proceedings of the Thirty-Fifth Conference on Uncertainty in Artificial Intelligence, UAI 2019, Tel Aviv, Israel, July 22-25, 2019 , page 204, 2019.
[54] Y. Song, T. Kim, S. Nowozin, S. Ermon, and N. Kushman. Pixeldefend: Leveraging generative models to understand and defend against adversarial examples. In International Conference on Learning Representations , 2018.
[55] B. K. Sriperumbudur, K. Fukumizu, A. Gretton, B. Schölkopf, and G. R. Lanckriet. On integral probability metrics, \ \backslash phi-divergences and binary classification. arXiv preprint arXiv:0901.2698 , 2009.
[56] C. M. Stein. Estimation of the mean of a multivariate normal distribution. The annals of Statistics , pages 1135–1151, 1981.
[57] D. Ulyanov, A. Vedaldi, and V. Lempitsky. Instance normalization: The missing ingredient for fast stylization. arXiv preprint arXiv:1607.08022 , 2016.
[58] A. van den Oord, S. Dieleman, H. Zen, K. Simonyan, O. Vinyals, A. Graves, N. Kalchbrenner, A. Senior, and K. Kavukcuoglu. Wavenet: A generative model for raw audio. In Arxiv , 2016.
[59] A. Van den Oord, N. Kalchbrenner, L. Espeholt, O. Vinyals, A. Graves, et al. Conditional image generation with pixelcnn decoders. In Advances in neural information processing systems , pages 4790–4798, 2016.
[60] A. Van Den Oord, N. Kalchbrenner, and K. Kavukcuoglu. Pixel recurrent neural networks. In Proceedings of the 33rd International Conference on International Conference on Machine Learning - Volume 48 , ICML’16, pages 1747–1756. JMLR.org, 2016.
[61] P. Vincent. A connection between score matching and denoising autoencoders. Neural computation , 23(7):1661–1674, 2011.
[62] M. Welling and Y. W. Teh. Bayesian learning via stochastic gradient langevin dynamics. In Proceedings of the 28th international conference on machine learning (ICML-11) , pages 681–688, 2011.
[63] L. Wenliang, D. Sutherland, H. Strathmann, and A. Gretton. Learning deep kernels for exponential family densities. In International Conference on Machine Learning , pages 6737–6746, 2019.
[64] F. Yu and V. Koltun. Multi-scale context aggregation by dilated convolutions. In International Conference on Learning Representations (ICLR) , 2016.
[65] F. Yu, V. Koltun, and T. Funkhouser. Dilated residual networks. In Computer Vision and Pattern Recognition (CVPR) , 2017.
[66] Q. Zhang and L. Zhang. Convolutional adaptive denoising autoencoders for hierarchical feature extraction. Frontiers of Computer Science , 12(6):1140–1148, 2018.
Appendix A Architectures
附录 A 网络结构
The architecture of our NCSNs used in the experiments has three important components: instance normalization, dilated convolutions and U-Net-type architectures. Below we give more background on them and discuss how we modified them to suit our purpose. For more comprehensive details and a reference implementation, we recommend the readers to check our publicly available code base. Our score networks are implemented in PyTorch. Code and checkpoints are available at https://github.com/ermongroup/ncsn.
实验中使用的 NCSN 结构有三个重要组成部分:实例归一化、膨胀卷积,以及 U-Net 类型的结构。下面我们补充它们的背景,并讨论我们如何修改它们以适应本文的目的。更完整的细节和参考实现,建议读者查看我们公开的代码库。分数网络用 PyTorch 实现。代码和检查点见 https://github.com/ermongroup/ncsn 。
A.1 Instance normalization
A.1 实例归一化
We use conditional instance normalization [13] so that takes account of when predicting the scores. In conditional instance normalization, a different set of scales and biases is used for different . More specifically, suppose is an input with feature maps. Let and denote the mean and standard deviation of the -th feature map of , taken along the spatial axes. Conditional instance normalization is achieved by
我们使用条件实例归一化 [13],使 在预测分数时把 考虑进去。在条件实例归一化中,不同的 使用不同的一组缩放和偏置。更具体地说,设 是具有 张特征图的输入。令 和 表示 第 张特征图沿空间轴计算的均值和标准差。条件实例归一化由下式实现
where and are learnable parameters, denotes the index of feature maps, and denotes the index of in .
其中 和 是可学习参数, 表示特征图的下标, 表示 在 中的下标。
However, one downside of instance normalization is that it completely removes the information of for different feature maps. This can lead to shifted colors in the generated images. To fix this issue, we propose a simple modification to conditional instance normalization. First, we compute the mean and standard deviation of ’s and denote them as and respectively. Then, we add another learnable parameter . The modified conditional instance normalization is defined as
不过,实例归一化有一个缺点:它会彻底去掉不同特征图上 的信息。这可能导致生成图像出现偏色。为了解决这个问题,我们给条件实例归一化提出一个简单修改。首先计算各 的均值和标准差,分别记为 和 。然后,再增加一个可学习参数 。修改后的条件实例归一化定义为
We abbreviate this modification of conditional instance normalization as CondInstanceNorm++. In our architecture, we add CondInstanceNorm++ before every convolutional layer and pooling layer.
我们把这种对条件实例归一化的修改简记为 CondInstanceNorm++。在我们的结构中,每个卷积层和池化层之前都会加上 CondInstanceNorm++。
A.2 Dilated convolutions
A.2 膨胀卷积
Dilated convolutions can be used to increase the size of receptive field while maintaining the resolution of feature maps. It has been shown very effective in semantic segmentation because they preserve the location information better using feature maps of larger resolutions. In our architecture design of NCSNs, we use it to replace all the subsampling layers except the first one.
膨胀卷积可以在保持特征图分辨率的同时增大感受野。它在语义分割中被证明非常有效,因为更大分辨率的特征图能更好地保留位置信息。在 NCSN 的结构设计中,我们用它替换除第一层以外的所有下采样层。
A.3 U-Net architecture
A.3 U-Net 结构
U-Net is an architecture with special skip connections. These skip connections help transfer lower level information in shallow layers to deeper layers of the network. Since the shallower layers often contain low level information such as location and shape, these skip connections help improve the result of semantic segmentation. For building , we use the architecture of RefineNet [32], a modern variant of U-Net that also incorporates ResNet designs. We refer the readers to [32] for a detailed description of the RefineNet architecture.
U-Net 是一种带有特殊跳跃连接的结构。这些跳跃连接有助于把浅层中的低层信息传到网络更深的层。由于较浅的层常常包含位置和形状等低层信息,这些跳跃连接有助于改善语义分割的结果。为了构造 ,我们使用 RefineNet [32] 的结构,这是 U-Net 的一种现代变体,同时也吸收了 ResNet 的设计。关于 RefineNet 结构的详细描述,请读者参阅 [32]。
In our experiments, we use a 4-cascaded RefineNet. We use pre-activation residual blocks. We remove all batch normalizations in the RefineNet architecture, and replace them with CondInstanceNorm++. We replace the max pooling layers in Refine Blocks with average pooling, as average pooling is reported to produce smoother images for image generation tasks such as style transfer. In addition, we also add CondInstanceNorm++ before each convolution and average pooling in the Refine Blocks, although no normalization is used in the original Refine Blocks. All activation functions are chosen to be ELU. As mentioned previously, we use dilated convolutions to replace the subsampling layers in residual blocks, except the first one. Following the common practice, we increase the dilation by a factor of 2 when proceeding to the next cascade. For CelebA and CIFAR-10 experiments, the number of filters for layers corresponding to the first cascade is 128, while the number of filters for other cascades are doubled. For MNIST experiments, the number of filters are halved.
实验中,我们使用 4 级级联的 RefineNet。我们采用预激活残差块。我们去掉 RefineNet 结构中的所有批归一化,并把它们替换成 CondInstanceNorm++。我们把 Refine Block 里的最大池化换成平均池化,因为有报告称平均池化在风格迁移等图像生成任务中能产生更平滑的图像。此外,尽管原始 Refine Block 不使用归一化,我们也在 Refine Block 里的每个卷积和平均池化之前加上 CondInstanceNorm++。所有激活函数都选用 ELU。如前所述,我们用膨胀卷积替换残差块中的下采样层,第一层除外。按常见做法,进入下一级级联时,膨胀率按 2 倍增加。对 CelebA 和 CIFAR-10 实验,第一级级联对应层的滤波器数量为 128,其他级联的滤波器数量加倍。MNIST 实验中,滤波器数量减半。
Appendix B Additional experimental details
附录 B 更多实验细节
B.1 Toy experiments
B.1 玩具实验
For the results in Fig. 1, we train a ResNet with sliced score matching on CIFAR-10. We use pre-activation residual blocks, and the ResNet is structured as an auto-encoder, where the encoder contains 5 residual blocks and the decoder mirrors the architecture of the encoder. The number of filters for each residual block of the encoder part is respectively 32, 64, 64, 128 and 128. The 2nd and 4th residual block of the encoder subsamples the feature maps by a factor of two. We use ELU activations throughout the network. We train the network with 50000 iterations using Adam optimizer and a batch size of 128 and learning rate of 0.001. The experiment was run on one Titan XP GPU.
对图 1 中的结果,我们在 CIFAR-10 上用切片分数匹配训练一个 ResNet。我们使用预激活残差块,并把 ResNet 做成自编码器结构:编码器包含 5 个残差块,解码器与编码器结构对称。编码器部分各个残差块的滤波器数量分别是 32、64、64、128 和 128。编码器的第 2 个和第 4 个残差块把特征图下采样两倍。整个网络使用 ELU 激活。我们用 Adam 优化器训练 50000 次迭代,批大小为 128,学习率为 0.001。实验在一块 Titan XP GPU 上运行。
For the results in Fig. 2, we choose . The score network is a 3-layer MLP with 128 hidden units and softplus activation functions. We train the score network with sliced score matching for 10000 iterations with Adam optimizer. The learning rate is 0.001, and the batch size is 128. The experiment was run on an Intel Core i7 GPU with 2.7GHz.
对图 2 中的结果,我们取 。分数网络是一个 3 层 MLP,隐单元数为 128,激活函数为 softplus。我们用切片分数匹配、Adam 优化器训练分数网络 10000 次迭代。学习率为 0.001,批大小为 128。实验在主频 2.7GHz 的 Intel Core i7 GPU 上运行。
For the results in Fig. 3, we use the same toy distribution . We generate 1280 samples for each subfigure of Fig. 3. The initial samples are all uniformly chosen in the square . For Langevin dynamics, we use and . For annealed Langevin dynamics, we use , and . We choose to be a geometric progression, with , and . Both Langevin methods use the ground-truth data score for sampling. The experiment was run on an Intel Core i7 GPU with 2.7GHz.
对图 3 中的结果,我们使用同一个玩具分布 。图 3 的每个子图生成 1280 个样本。初始样本都在正方形 上均匀选取。对 Langevin 动力学,我们取 、。对退火 Langevin 动力学,我们取 、、。我们取 为几何级数,其中 ,,。两种 Langevin 方法采样时都使用真实的数据分数。实验在主频 2.7GHz 的 Intel Core i7 GPU 上运行。
B.2 Image generation
B.2 图像生成
During training, we randomly flip the images in CelebA and CIFAR-10. All models are optimized by Adam with learning rate for a total of 200000 iterations. The batch size is fixed to 128. We save one checkpoint every 5000 iterations. For MNIST, we choose the last checkpoint at the 200000-th training iteration. For selecting our CIFAR-10 and CelebA models, we generate 1000 images for each checkpoint and choose the one with the smallest FID score computed on these 1000 images. Our image samples and results in Tab. 1 are from these checkpoints. Similar model selection procedures have been used in previous work, such as ProgressiveGAN [25].
训练时,我们对 CelebA 和 CIFAR-10 中的图像做随机翻转。所有模型都用学习率为 的 Adam 优化,共计 200000 次迭代。批大小固定为 128。我们每 5000 次迭代保存一次检查点。对 MNIST,我们选取第 200000 次训练迭代时的最后一个检查点。选取 CIFAR-10 和 CelebA 模型时,我们为每个检查点生成 1000 张图像,并选择在这 1000 张图像上算得 FID 最小的那个。我们的图像样本以及表 1 中的结果都来自这些检查点。类似的模型选择流程在此前工作中也用过,例如 ProgressiveGAN [25]。
The baseline model uses the same score network. The only difference is that the score network is only conditioned on one noise level . When sampling using Langevin dynamics, we use and .
基线模型使用同一个分数网络。唯一的差别是,分数网络只以单一噪声水平 为条件。用 Langevin 动力学采样时,我们取 、。
The models on MNIST were run with one Titan XP GPU, while the models on CelebA and CIFAR-10 used two Titan XP GPUs.
MNIST 上的模型用一块 Titan XP GPU 运行,CelebA 和 CIFAR-10 上的模型使用两块 Titan XP GPU。
B.3 Image inpainting
B.3 图像补全
We use the following Alg. 2 for image inpainting.
我们使用下面的算法 2 做图像补全。
1: is smallest step size; is the number of iteration for each noise level.
2: is a mask to indicate regions not occluded; is the given image.
3: Initialize
4: for to do
5: is the step size.
6: Draw
7:
8: for to do
9: Draw
10:
11:
12: end for
13:
14: end for
15: return
Algorithm 2 Inpainting with annealed Langevin dynamics.
1: 是最小步长; 是每个噪声水平的迭代次数。
2: 是用来标出未被遮挡区域的掩码; 是给定图像。
3: 初始化
4: for to do
5: 是步长。
6: 抽取
7:
8: for to do
9: 抽取
10:
11:
12: end for
13:
14: end for
15: return
算法 2 用退火 Langevin 动力学做图像补全。
The hyperparameters are the same as those of the annealed Langevin dynamics used for image generation.
超参数与用于图像生成的退火 Langevin 动力学相同。
Appendix C Samples
附录 C 样本
C.1 Samples from the baseline models
C.1 基线模型的样本
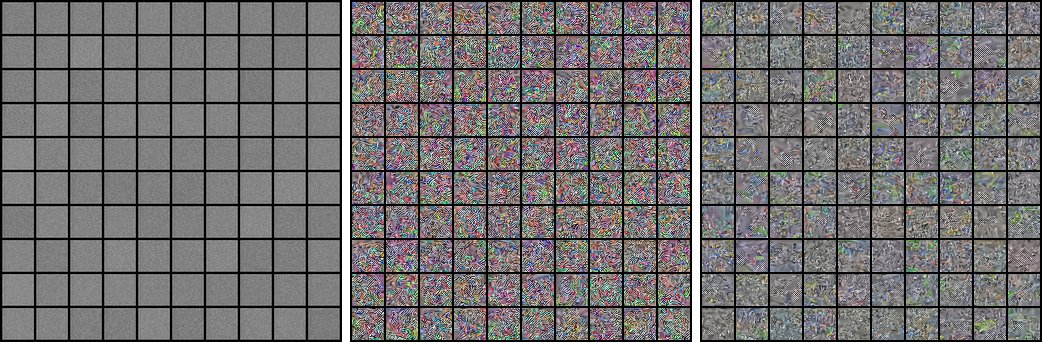
Figure 7: Uncurated samples on MNIST, CelebA, and CIFAR-10 datasets from the baseline model.
图 7:基线模型在 MNIST、CelebA 和 CIFAR-10 数据集上未经挑选的样本。
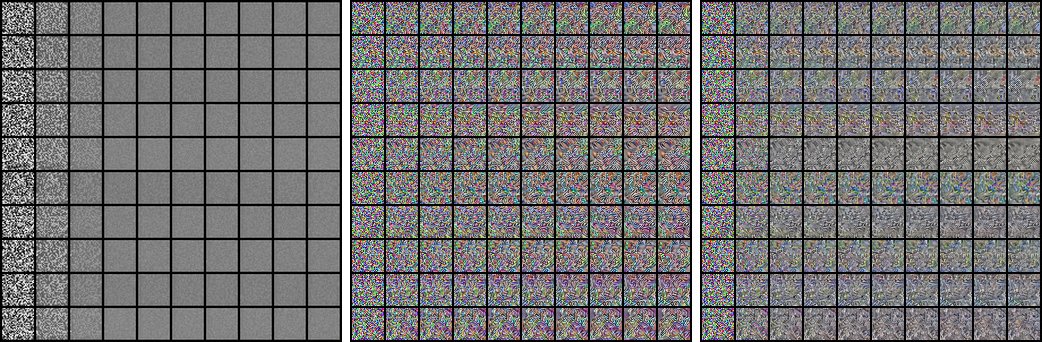
Figure 8: Intermediate samples from Langevin dynamics for the baseline model.
图 8:基线模型 Langevin 动力学的中间样本。
C.2 Nearest neighbors
C.2 最近邻
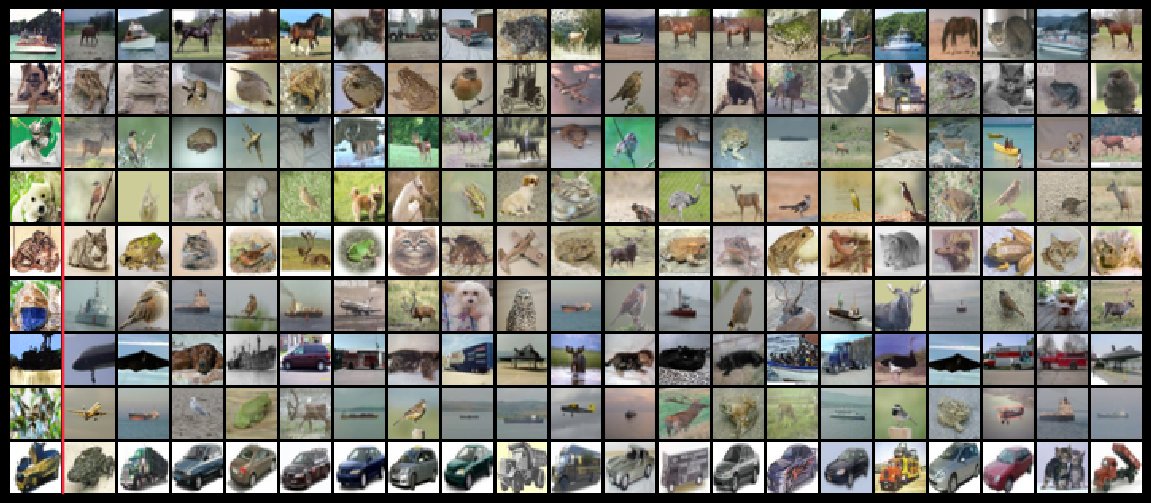
Figure 9: Nearest neighbors measured by the distance between images. Images on the left of the red vertical line are samples from NCSN. Images on the right are nearest neighbors in the training dataset.
图 9:按图像之间的 距离衡量的最近邻。红竖线左侧是来自 NCSN 的样本,右侧是训练数据集中的最近邻。
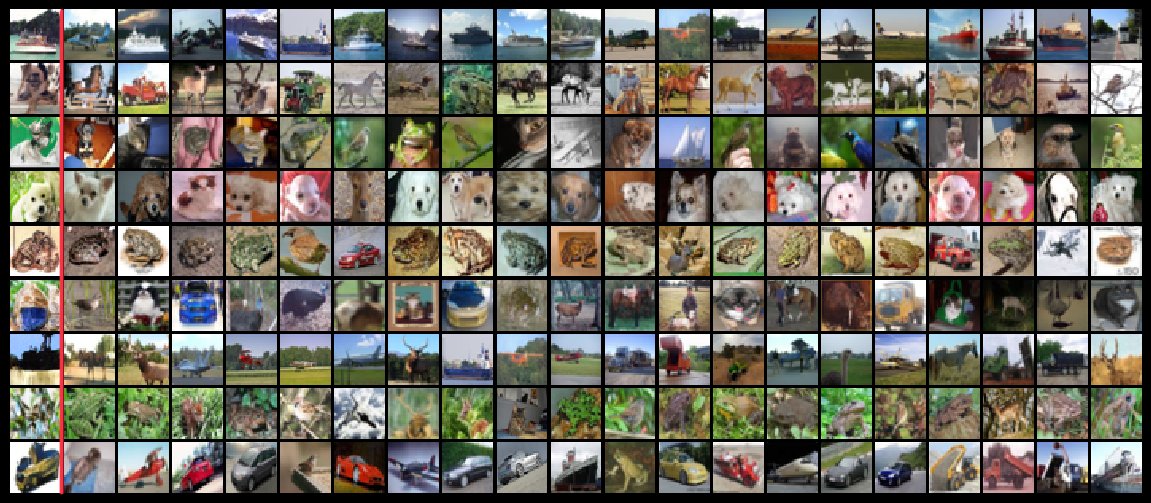
Figure 10: Nearest neighbors measured by the distance in the feature space of an Inception V3 network pretrained on ImageNet. Images on the left of the red vertical line are samples from NCSN. Images on the right are nearest neighbors in the training dataset.
图 10:按在 ImageNet 上预训练的 Inception V3 网络特征空间中的 距离衡量的最近邻。红竖线左侧是来自 NCSN 的样本,右侧是训练数据集中的最近邻。
C.3 Extended samples
C.3 更多样本
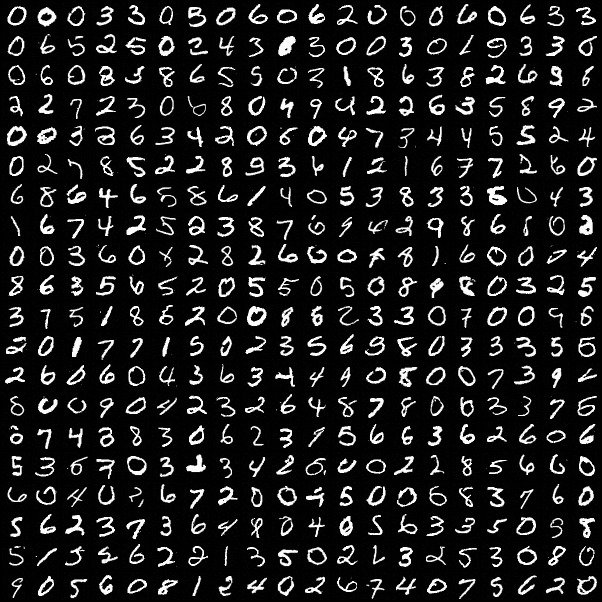
Figure 11: Extended MNIST samples
图 11:更多 MNIST 样本
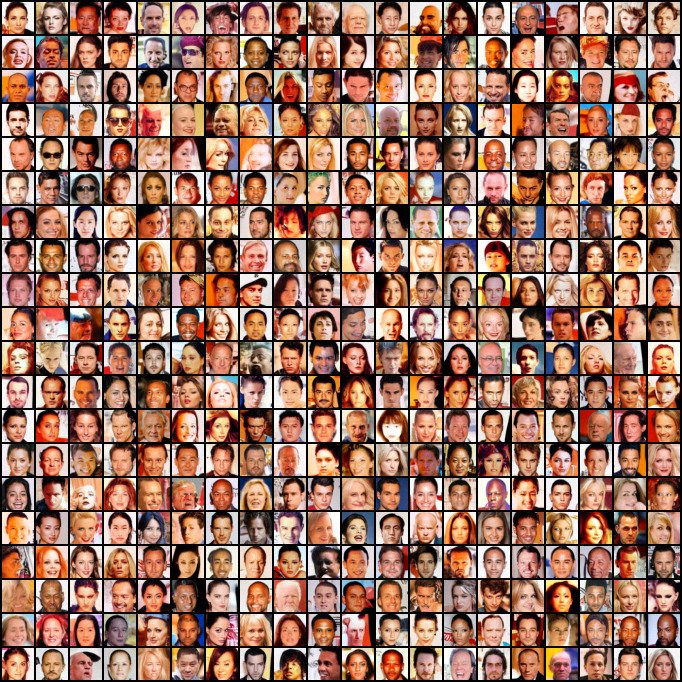
Figure 12: Extended CelebA samples
图 12:更多 CelebA 样本
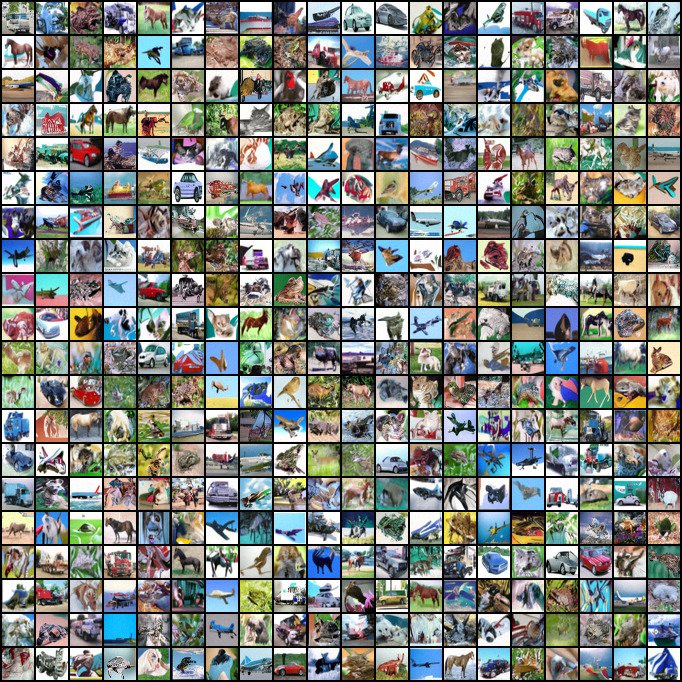
Figure 13: Extended CIFAR-10 samples
图 13:更多 CIFAR-10 样本
C.4 Extended intermediate samples from annealed Langevin dynamics
C.4 退火 Langevin 动力学的更多中间样本
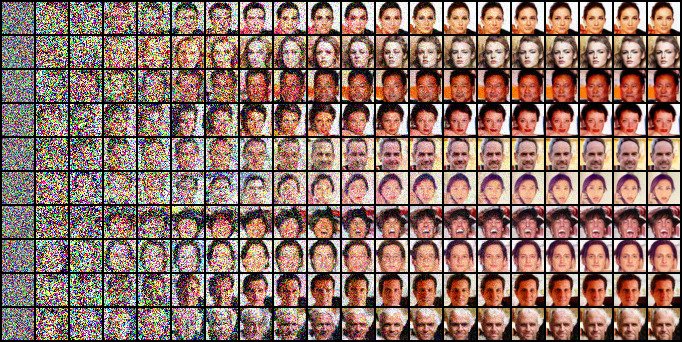
Figure 14: Extended intermediate samples from annealed Langevin dynamics for CelebA.
图 14:退火 Langevin 动力学在 CelebA 上的更多中间样本。
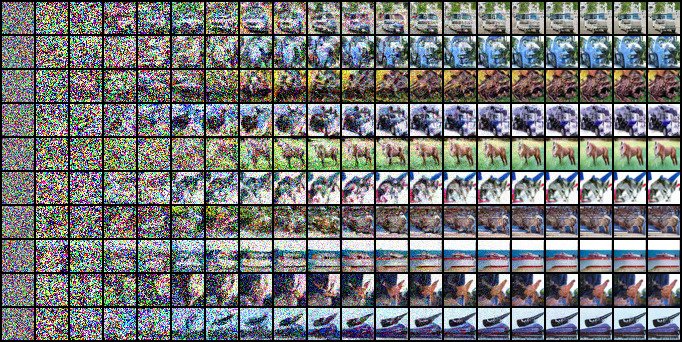
Figure 15: Extended intermediate samples from annealed Langevin dynamics for CelebA.
图 15:退火 Langevin 动力学在 CelebA 上的更多中间样本。
C.5 Extended image inpainting results
C.5 更多图像补全结果
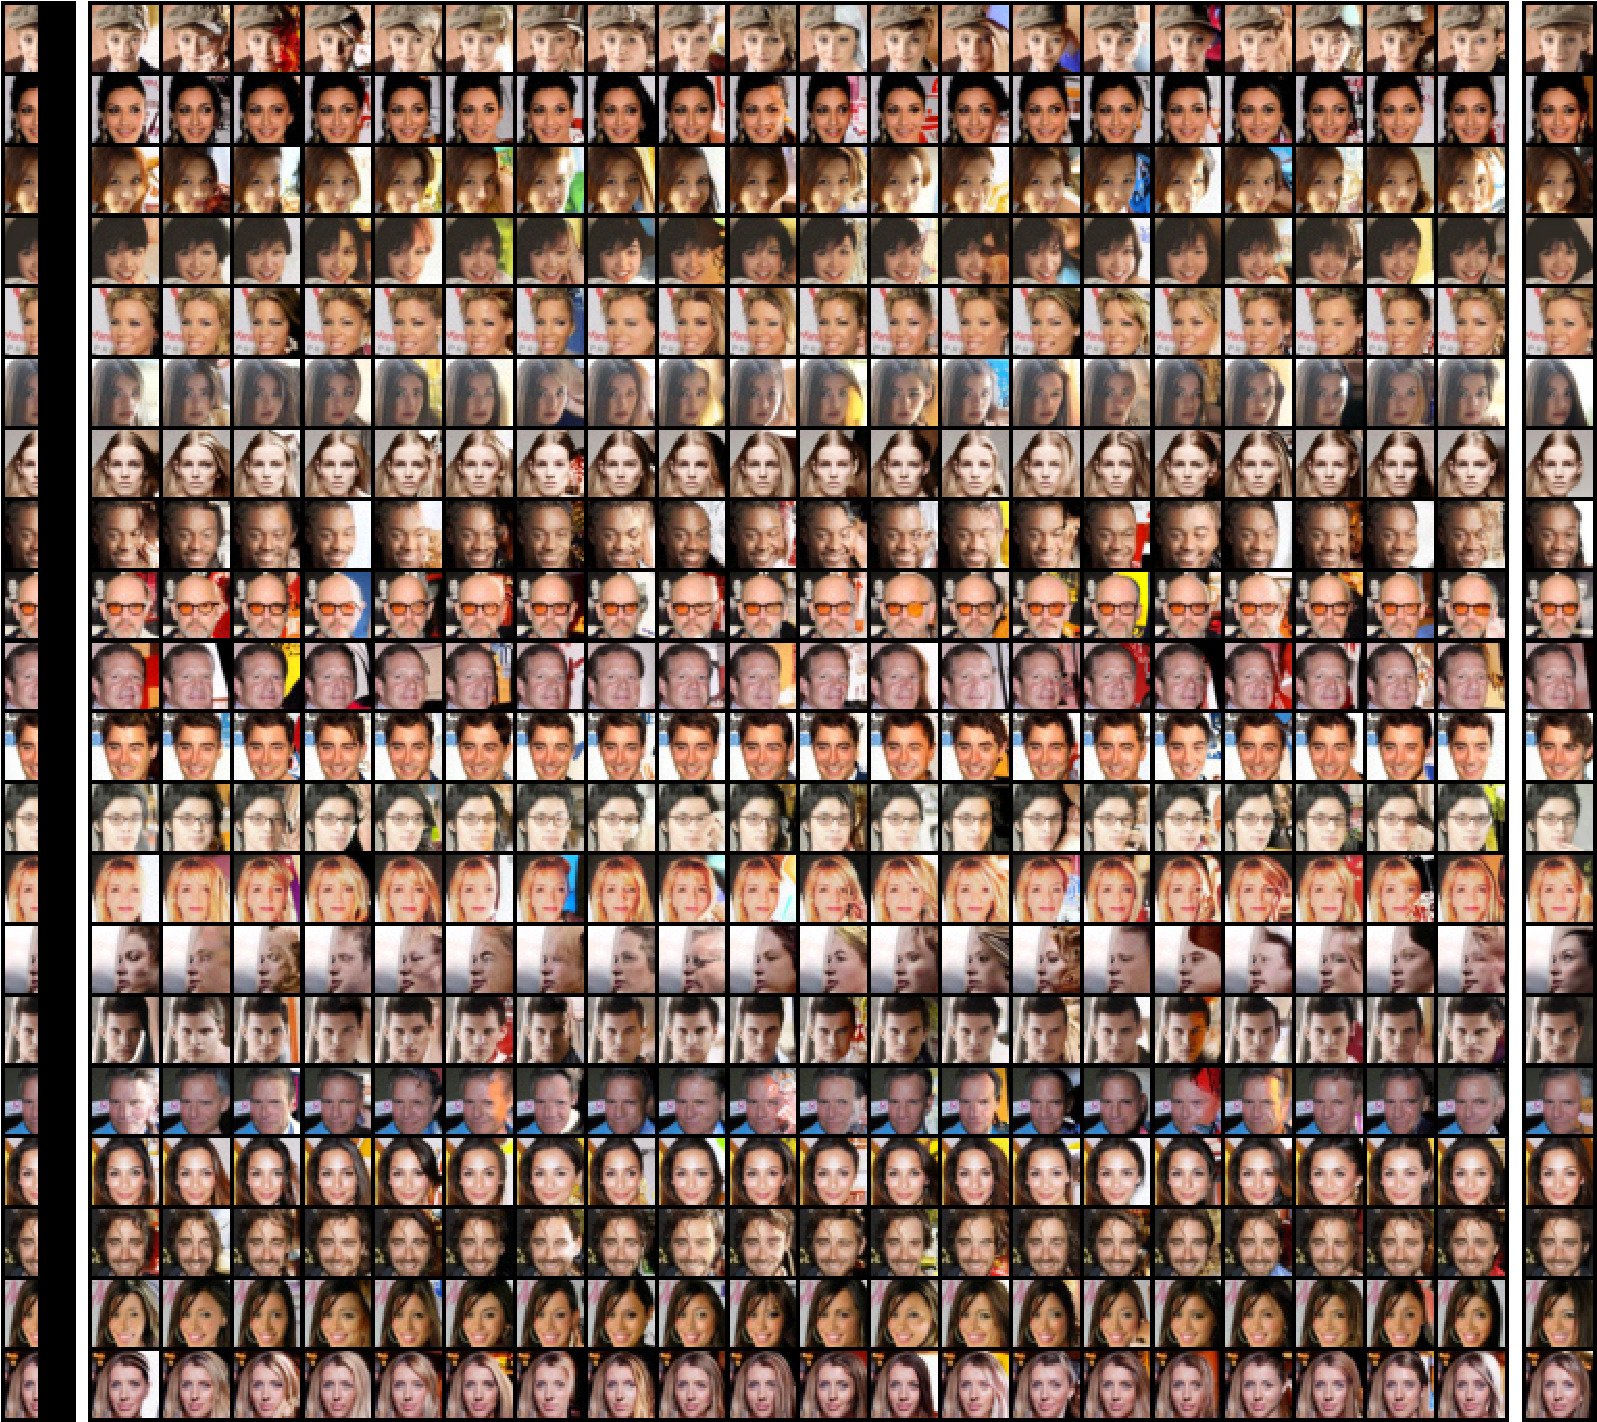
Figure 16: Extended image inpainting results for CelebA. The leftmost column of each figure shows the occluded images, while the rightmost column shows the original images.
图 16:CelebA 上更多的图像补全结果。每张图最左边一列是被遮挡的图像,最右边一列是原始图像。
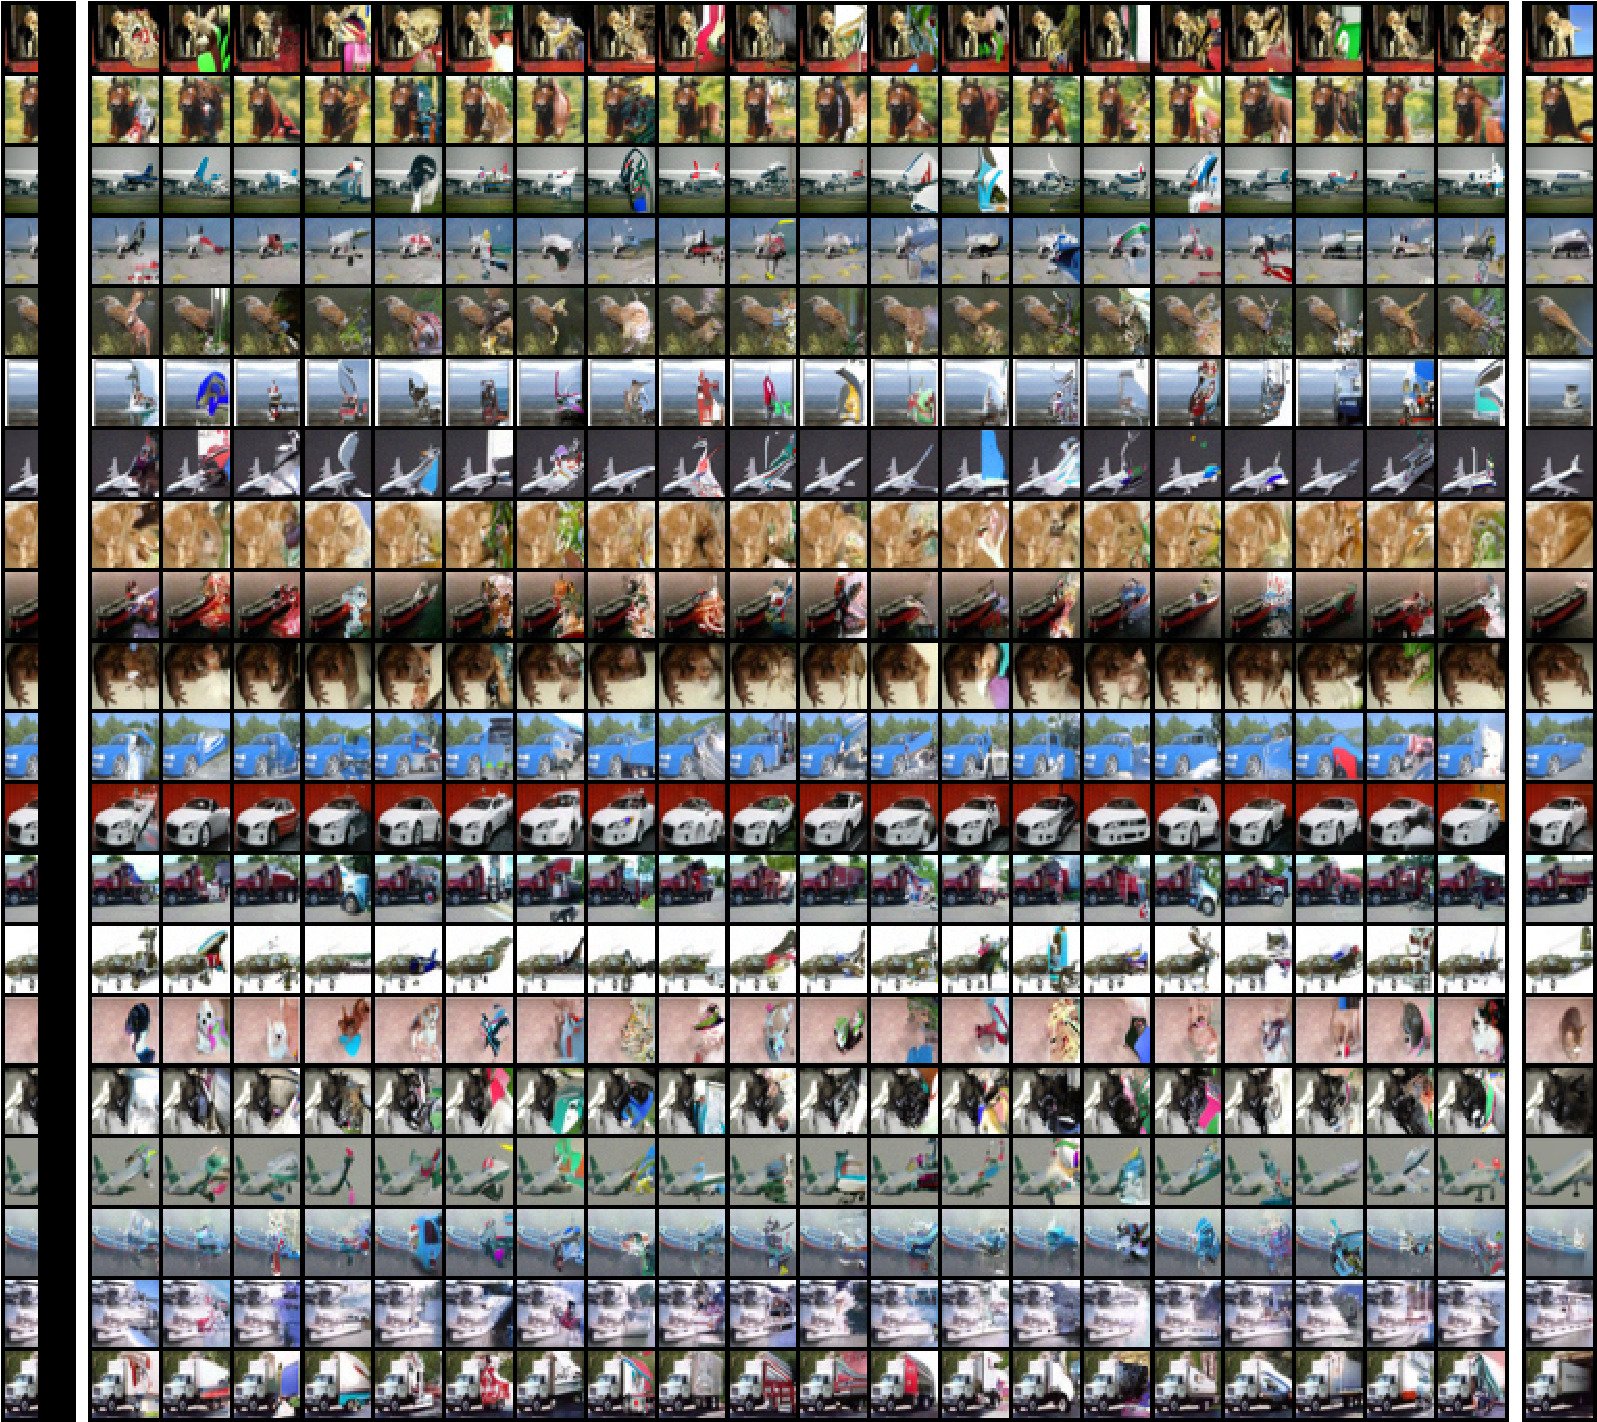
Figure 17: Extended image inpainting results for CIFAR-10. The leftmost column of each figure shows the occluded images, while the rightmost column shows the original images.
图 17:CIFAR-10 上更多的图像补全结果。每张图最左边一列是被遮挡的图像,最右边一列是原始图像。