Navigation World Models
Abstract
摘要
Navigation is a fundamental skill of agents with visual-motor capabilities. We introduce a Navigation World Model (NWM), a controllable video generation model that predicts future visual observations based on past observations and navigation actions. To capture complex environment dynamics, NWM employs a Conditional Diffusion Transformer (CDiT), trained on a diverse collection of egocentric videos of both human and robotic agents, and scaled up to 1 billion parameters. In familiar environments, NWM can plan navigation trajectories by simulating them and evaluating whether they achieve the desired goal. Unlike supervised navigation policies with fixed behavior, NWM can dynamically incorporate constraints during planning. Experiments demonstrate its effectiveness in planning trajectories from scratch or by ranking trajectories sampled from an external policy. Furthermore, NWM leverages its learned visual priors to imagine trajectories in unfamiliar environments from a single input image, making it a flexible and powerful tool for next-generation navigation systems[^1].
导航是具备视觉—运动能力的智能体的基本技能。我们提出导航世界模型(Navigation World Model,NWM):一种可控视频生成模型,根据过往观测与导航动作预测未来视觉观测。为刻画复杂环境动力学,NWM 采用条件扩散 Transformer(Conditional Diffusion Transformer,CDiT),在涵盖人类与机器人第一人称视频的多样数据上训练,并扩至 10 亿参数。在熟悉环境中,NWM 可通过仿真候选轨迹并评估是否到达目标来做导航规划。不同于行为固定的有监督导航策略,NWM 能在规划时动态引入约束。实验表明,它既能从零规划轨迹,也能对外部策略采样的轨迹做排序。此外,NWM 利用学到的视觉先验,仅凭单张输入图即可在陌生环境中「想象」轨迹,成为面向下一代导航系统的灵活工具。[^1]
1 Introduction
1 引言
Navigation is a fundamental skill for any organism with vision, playing a crucial role in survival by allowing agents to locate food, shelter, and avoid predators. In order to successfully navigate environments, smart agents primarily rely on vision, allowing them to construct representations of their surroundings to assess distances and capture landmarks in the environment, all useful for planning a navigation route.
导航对任何有视觉的生物都是基础能力:帮助定位食物与庇护所、躲避捕食者。成功导航主要依赖视觉,智能体借此构建环境表征、估计距离并抓住地标,从而规划路线。
When human agents plan, they often imagine their future trajectories considering constraints and counterfactuals. On the other hand, current state-of-the-art robotics navigation policies (Sridhar et al. 2024; Shah et al. 2023) are “hard-coded”, and after training, new constraints cannot be easily introduced (e.g. “no left turns”). Another limitation of current supervised visual navigation models is that they cannot dynamically allocate more computational resources to address hard problems. We aim to design a new model that can mitigate these issues.
人类规划时常在约束与反事实下想象未来轨迹。而当前前沿机器人导航策略(Sridhar et al. 2024;Shah et al. 2023)多为「硬编码」,训练结束后难以再加新约束(例如「禁止左转」)。另一局限是:有监督视觉导航模型无法按问题难度动态分配更多算力。我们希望设计一种能缓解这些问题的新模型。
In this work, we propose a Navigation World Model (NWM), trained to predict the future representation of a video frame based on past frame representation(s) and action(s) (see Figure (a)). NWM is trained on video footage and navigation actions collected from various robotic agents. After training, NWM is used to plan novel navigation trajectories by simulating potential navigation plans and verifying if they reach a target goal (see Figure (b)). To evaluate its navigation skills, we test NWM in known environments, assessing its ability to plan novel trajectories either independently or by ranking an external navigation policy. In the planning setup, we use NWM in a Model Predictive Control (MPC) framework, optimizing the action sequence that enables NWM to reach a target goal. In the ranking setup, we assume access to an existing navigation policy, such as NoMaD (Sridhar et al. 2024), which allows us to sample trajectories, simulate them using NWM, and select the best ones. Our NWM achieves state-of-the-art standalone performance and competitive results when combined with existing methods.
本文提出导航世界模型(NWM):根据过去帧表征与动作预测未来帧表征(见图 (a))。NWM 在多种机器人智能体采集的视频与导航动作上训练。训练后,通过仿真潜在导航方案并检验是否到达目标,即可规划新轨迹(见图 (b))。我们在已知环境中评测:既独立规划新轨迹,也对外部导航策略做排序。规划设定下,把 NWM 放进模型预测控制(MPC)框架,优化能使 NWM 到达目标的动作序列;排序设定下,借助 NoMaD(Sridhar et al. 2024)等已有策略采样轨迹,用 NWM 仿真并选出最优。独立使用时 NWM 达到当时最优表现,与现有方法结合时结果也具竞争力。
NWM is conceptually similar to recent diffusion-based world models for offline model-based reinforcement learning, such as DIAMOND (Alonso et al.) and GameNGen (Valevski et al. 2024). However, unlike these models, NWM is trained across a wide range of environments and embodiments, leveraging the diversity of navigation data from robotic and human agents. This allows us to train a large diffusion transformer model capable of scaling effectively with model size and data to adapt to multiple environments. Our approach also shares similarities with Novel View Synthesis (NVS) methods like NeRF (Mildenhall et al. 2021), Zero-1-2-3 (Liu et al. 2023), and GDC (Van Hoorick et al. 2024), from which we draw inspiration. However, unlike NVS approaches, our goal is to train a single model for navigation across diverse environments and model temporal dynamics from natural videos, without relying on 3D priors.
NWM 在概念上接近 DIAMOND(Alonso et al.)、GameNGen(Valevski et al. 2024)等面向离线基于模型强化学习的扩散世界模型。不同之处在于:NWM 跨大量环境与具身形态训练,充分利用机器人与人类导航数据的多样性,从而把大型扩散 Transformer 扩到可随规模与数据适配多环境。方法也与 NeRF(Mildenhall et al. 2021)、Zero-1-2-3(Liu et al. 2023)、GDC(Van Hoorick et al. 2024)等新视角合成(NVS)思路有共通处,但我们的目标是在多样环境中做导航的单一模型,并从自然视频学习时间动力学,而不依赖三维先验。
To learn a NWM, we propose a novel Conditional Diffusion Transformer (CDiT), trained to predict the next image state given past image states and actions as context. Unlike a DiT (Peebles and Xie 2023), CDiT’s computational complexity is linear with respect to the number of context frames, and it scales favorably for models trained up to parameters across diverse environments and embodiments, requiring fewer FLOPs compared to a standard DiT while achieving better future prediction results.
为学习 NWM,我们提出条件扩散 Transformer(CDiT):以过去图像状态与动作为上下文,预测下一图像状态。与 DiT(Peebles and Xie 2023)不同,CDiT 相对上下文帧数呈线性复杂度,在多样环境与具身形态上训到 参数时扩展良好,相对标准 DiT 约少 FLOPs,未来预测也更好。
In unknown environments, our results show that NWM benefits from training on unlabeled, action- and reward-free video data from Ego4D. Qualitatively, we observe improved video prediction and generation performance on single images (see Figure (c)). Quantitatively, with additional unlabeled data, NWM produces more accurate predictions when evaluated on the held-out Stanford Go (Hirose et al. 2018) dataset.
在未知环境中,结果表明:在 Ego4D 的无标注、无动作与奖励视频上训练有助于 NWM。定性上,单图条件下的视频预测与生成更优(见图 (c));定量上,加入无标注数据后,在留出的 Stanford Go(Hirose et al. 2018)上预测更准。
Our contributions are as follows. We introduce a Navigation World Model (NWM) and propose a novel Conditional Diffusion Transformer (CDiT), which scales efficiently up to parameters with significantly reduced computational requirements compared to standard DiT. We train CDiT on video footage and navigation actions from diverse robotic agents, enabling planning by simulating navigation plans independently or alongside external navigation policies, achieving state-of-the-art visual navigation performance. Finally, by training NWM on action- and reward-free video data, such as Ego4D, we demonstrate improved video prediction and generation performance in unseen environments.
贡献如下。我们提出导航世界模型(NWM)与可高效扩到 参数的条件扩散 Transformer(CDiT),相对标准 DiT 显著降低算力。在多样机器人视频与导航动作上训练 CDiT 后,可独立或配合外部策略通过仿真做规划,视觉导航表现达到当时最优。最后,在 Ego4D 等无动作、无奖励视频上继续训练,可提升未见环境中的视频预测与生成。
2 Related Work
2 相关工作
Goal conditioned visual navigation is an important task in robotics requiring both perception and planning skills (Sridhar et al. 2024; Shah et al.; Pathak et al. 2018; Mirowski et al. 2022; Chaplot et al.; Fu et al. 2022; Frey et al. 2023). Given context image(s) and an image specifying the navigation goals, goal-conditioned visual navigation models (Sridhar et al. 2024; Shah et al.) aim to generate a viable path towards the goal if the environment is known, or to explore it otherwise. Recent visual navigation methods like NoMaD (Sridhar et al. 2024) train a diffusion policy via behavior cloning and temporal distance objective to follow goals in the conditional setting or to explore new environments in the unconditional setting. Previous approaches like Active Neural SLAM (Chaplot et al.) used neural SLAM together with analytical planners to plan trajectories in the environment, while other approaches like (Chen et al.) learn policies via reinforcement learning. Here we show that world models can use exploratory data to plan or improve existing navigation policies.
目标条件视觉导航是机器人学中同时考验感知与规划的重要任务(Sridhar et al. 2024;Shah et al.;Pathak et al. 2018;Mirowski et al. 2022;Chaplot et al.;Fu et al. 2022;Frey et al. 2023)。给定上下文图像与目标图像,目标条件视觉导航模型(Sridhar et al. 2024;Shah et al.)在已知环境中生成可达路径,否则探索。近期如 NoMaD(Sridhar et al. 2024)用行为克隆与时间距离目标训练扩散策略:条件设定下跟随目标,无条件设定下探索新环境。更早的 Active Neural SLAM(Chaplot et al.)把神经 SLAM 与解析规划器结合在三维环境中规划;另有工作(Chen et al.)用强化学习学策略。本文说明:世界模型可利用探索数据来规划或改进已有导航策略。
Differently than in learning a policy, the goal of a world model (Ha and Schmidhuber 2018) is to simulate the environment, e.g. given the current state and action to predict the next state and an associated reward. Previous works have shown that jointly learning a policy and a world model can improve sample efficiency on Atari (Hafner et al. b; Hafner et al. a; Alonso et al.), simulated robotics environments (Seo et al. 2023), and even when applied to real world robots (Wu et al. 2023). More recently, Hansen et al. proposed to use a single world model that is shared across tasks by introducing action and task embeddings while Yang et al.; Lin et al. 2024b proposed to describe actions in language, and Bruce et al. 2024 proposed to learn latent actions. World models were also explored in the context of game simulation. DIAMOND (Alonso et al.) and GameNGen (Valevski et al. 2024) propose to use diffusion models to learn game engines of computer games like Atari and Doom. Our work is inspired by these works, and we aim to learn a single general diffusion video transformer that can be shared across many environments and different embodiments for navigation.
与学策略不同,世界模型(Ha and Schmidhuber 2018)的目标是仿真环境:给定当前状态与动作,预测下一状态与相应奖励。已有工作表明,联合学习策略与世界模型可提升 Atari(Hafner et al. b;Hafner et al. a;Alonso et al.)、仿真机器人环境(Seo et al. 2023)乃至真实机器人(Wu et al. 2023)上的样本效率。近来 Hansen et al. 提出用动作与任务嵌入共享统一的世界模型;Yang et al.、Lin et al. 2024b 用语言描述动作;Bruce et al. 2024 学习潜在动作。世界模型也用于游戏仿真:DIAMOND(Alonso et al.)与 GameNGen(Valevski et al. 2024)用扩散模型学习 Atari、Doom 等游戏引擎。我们受此启发,希望学一个可跨多环境、多具身形态共享的通用扩散视频 Transformer,专用于导航。
In computer vision, generating videos has been a long standing challenge (Kondratyuk et al.; Blattmann et al. 2023; Girdhar et al. 2023; Yu et al. 2023; Ho et al. 2022; Tulyakov et al. 2018b; Bar-Tal et al. 2024). Most recently, there has been tremendous progress with text-to-video synthesis with methods like Sora (Brooks et al. 2024) and MovieGen (Polyak et al. 2024). Past works proposed to control video synthesis given structured action-object class categories (Tulyakov et al. 2018a) or Action Graphs (Bar et al. 2021). Video generation models were previously used in reinforcement learning as rewards (Escontrela et al. 2024), pretraining methods (Tomar et al. 2024), for simulating and planning manipulation actions (Finn and Levine 2017; Liang et al. 2024) and for generating paths in indoor environments (Hirose et al. 2019b; Koh et al. 2021). Interestingly, diffusion models (Sohl-Dickstein et al. 2015; Ho et al. 2020) are useful both for video tasks like generation (Voleti et al. 2022) and prediction (Lin et al. 2024a), but also for view synthesis (Chan et al. 2023; Poole et al.; Tung et al. 2025). Differently, we use a conditional diffusion transformer to simulate trajectories for planning without explicit D representations or priors.
计算机视觉中,视频生成是长期难题(Kondratyuk et al.;Blattmann et al. 2023;Girdhar et al. 2023;Yu et al. 2023;Ho et al. 2022;Tulyakov et al. 2018b;Bar-Tal et al. 2024)。近来文生视频进展显著,如 Sora(Brooks et al. 2024)、MovieGen(Polyak et al. 2024)。过往工作曾用结构化动作—物体类别(Tulyakov et al. 2018a)或动作图(Bar et al. 2021)控制视频合成。视频生成也曾作强化学习奖励(Escontrela et al. 2024)、预训练(Tomar et al. 2024)、仿真与规划操作动作(Finn and Levine 2017;Liang et al. 2024),以及室内路径生成(Hirose et al. 2019b;Koh et al. 2021)。有趣的是,扩散模型(Sohl-Dickstein et al. 2015;Ho et al. 2020)既用于视频生成(Voleti et al. 2022)与预测(Lin et al. 2024a),也用于视角合成(Chan et al. 2023;Poole et al.;Tung et al. 2025)。不同的是,我们用条件扩散 Transformer 仿真轨迹以供规划,不显式依赖三维表征或先验。
3 Navigation World Models
3 导航世界模型
3.1 Formulation
3.1 形式化
Next, we turn to describe our NWM formulation. Intuitively, a NWM is a model that receives the current state of the world (e.g. an image observation) and a navigation action describing where to move and how to rotate. The model then produces the next state of the world with respect to the agent’s point of view.
下面给出 NWM 的形式化。直观上,NWM 接收世界当前状态(如一张图像观测)以及描述移动与旋转的导航动作,再从智能体视角生成下一状态。
We are given an egocentric video dataset together with agent navigation actions , such that is an image and is a navigation command given by translation parameter that controls the change in forward/backward and right/left motion, as well as that controls the change in yaw rotation angle.[^2]
给定第一人称视频数据集与智能体导航动作 ,其中 为图像, 为导航指令: 控制前后与左右平移, 控制偏航角变化。[^2]
The navigation actions can be fully observed (as in Habitat (Savva et al. 2019)), e.g. moving forward towards a wall will trigger a response from the environment based on physics, which will lead to the agent staying in place, whereas in other environments the navigation actions can be approximated based on the change in the agent’s location.
导航动作 可以完全可观测(如 Habitat,Savva et al. 2019)——例如朝墙前进会按物理触发环境响应、智能体原地不动;在其他环境中,动作也可由智能体位置变化近似得到。
Our goal is to learn a world model , a stochastic mapping from previous latent observation(s) and action to future latent state representation :
目标是学习世界模型 :从过去潜在观测 与动作 到未来潜在状态 的随机映射:
Where are the past visual observations encoded via a pretrained VAE (Blattmann et al. 2023). Using a VAE has the benefit of working with compressed latents, allowing to decode predictions back to pixel space for visualization.
其中 是经预训练 VAE(Blattmann et al. 2023)编码的过去 帧视觉观测。使用 VAE 可在压缩潜空间中工作,并把预测解码回像素以便可视化。
Due to the simplicity of this formulation, it can be naturally shared across environments and easily extended to more complex action spaces, like controlling a robotic arm. Different than Hafner et al. a, we aim to train a single world model across environments and embodiments, without using task or action embeddings like in Hansen et al..
该形式化足够简洁,可自然跨环境共享,也易扩展到更复杂动作空间(如控制机械臂)。与 Hafner et al. a 不同,我们希望跨环境与具身形态训练统一的世界模型,且不像 Hansen et al. 那样使用任务或动作嵌入。
The formulation in Equation 1 models action but does not allow control over the temporal dynamics. We extend this formulation with a time shift input , setting , thus now specifies the time change , used to determine how many steps should the model move into the future (or past). Hence, given a current state , we can randomly choose a timeshift and use the corresponding time shifted video frame as our next state . The navigation actions can then be approximated to be a summation from time to :
式 1 建模了动作,但未控制时间动力学。我们引入时间偏移 ,令 ,使 指定时间变化 ,决定模型向前(或向后)走多少步。于是对当前状态 ,可随机选 ,以对应时间偏移后的视频帧作为下一状态 。导航动作可近似为从 到 的累加:
This formulation allows learning both navigation actions, but also the environment temporal dynamics. In practice, we allow time shifts of up to seconds.
该形式化同时学习导航动作与环境时间动力学。实践中允许时间偏移达 秒。
One challenge that may arise is the entanglement of actions and time. For example, if reaching a specific location always occurs at a particular time, the model may learn to rely solely on time and ignore the subsequent actions, or vice versa. In practice, the data may contain natural counterfactuals—such as reaching the same area at different times. To encourage these natural counterfactuals, we sample multiple goals for each state during training. We further explore this approach in Section 4.
一个潜在难点是动作与时间纠缠:若到达某地点总在同一时刻发生,模型可能只依赖时间而忽略后续动作,或反之。实际数据中常有自然反事实——例如在不同时刻到达同一区域。为鼓励这类反事实,训练时对每个状态采样多个目标。第 4 节进一步讨论。
3.2 Diffusion Transformer as World Model
3.2 以扩散 Transformer 作世界模型
As mentioned in the previous section, we design as a stochastic mapping so it can simulate stochastic environments. This is achieved using a Conditional Diffusion Transformer (CDiT) model, described next.
如前所述,我们将 设计为随机映射,以便仿真随机环境。这通过下文的条件扩散 Transformer(CDiT)实现。
Conditional Diffusion Transformer Architecture. The architecture we use is a temporally autoregressive transformer model utilizing the efficient CDiT block (see Figure 2), which is applied times over the input sequence of latents with input action conditioning.
条件扩散 Transformer 结构。我们采用时间自回归 Transformer,对带动作条件的潜变量输入序列反复应用高效 CDiT 块(见图 2)共 次。
CDiT enables time-efficient autoregressive modeling by constraining the attention in the first attention block only to tokens from the target frame which is being denoised. To condition on tokens from past frames, we incorporate a cross-attention layer, such that every query token from the current target attends to tokens from past frames, which are used as keys and values. The cross-attention then contextualizes the representations using a skip connection layer.
CDiT 通过把第一注意力块的注意力约束到正在去噪的目标帧 token,实现时间高效的自回归建模。为条件于过去帧 token,我们加入交叉注意力:当前目标的每个查询 token 对过去帧 token(作键与值)做注意力,再经跳跃连接上下文化表征。
To condition on the navigation action , we first map each scalar to by extracting sine-cosine features, then applying a -layer MLP, and concatenating them into a single vector . We follow a similar process to map the timeshift to and the diffusion timestep to . Finally we sum all embeddings into a single vector used for conditioning:
为条件于导航动作 ,先把每个标量映到 (提取正余弦特征),再经两层 MLP,拼成单一向量 。对时间偏移 与扩散时间步 做类似映射,分别得 与 。最后相加得到条件向量:
is then fed to an AdaLN (Xu et al. 2019) block to generate scale and shift coefficients that modulate the Layer Normalization (Lei Ba et al. 2016) outputs, as well as the outputs of the attention layers. To train on unlabeled data, we simply omit explicit navigation actions when computing (see Eq. 3).
再送入 AdaLN(Xu et al. 2019)块,生成缩放与平移系数,调制 Layer Normalization(Lei Ba et al. 2016)输出以及注意力层输出。在无标注数据上训练时,计算 时省略显式导航动作(见式 3)。
An alternative approach is to simply use DiT (Peebles and Xie 2023), however, applying a DiT on the full input is computationally expensive. Denote the number of input tokens per frame, and the number of frames, and the token dimension. Scaled Multi-head Attention Layer (Vaswani 2017) complexity is dominated by the attention term , which is quadratic with context length. In contrast, our CDiT block is dominated by the cross-attention layer complexity , which is linear with respect to the context, allowing us to use longer context size. We analyze these two design choices in Section 4. CDiT resembles the original Transformer Block (Vaswani 2017), without applying expensive self-attention over the context tokens.
另一选择是直接用 DiT(Peebles and Xie 2023),但把完整输入送入 DiT 计算昂贵。记每帧 token 数为 、帧数为 、token 维为 ,缩放多头注意力(Vaswani 2017)复杂度由注意力项 主导,相对上下文长度二次。相比之下,CDiT 块由交叉注意力 主导,相对上下文线性,可用更长上下文。第 4 节分析这两种设计。CDiT 类似原始 Transformer 块(Vaswani 2017),但不对上下文 token 做昂贵的自注意力。
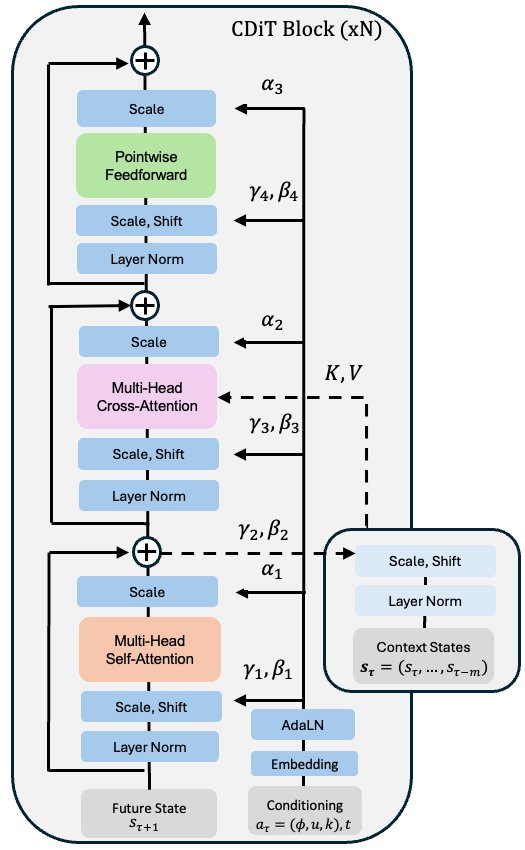
Figure 2: Conditional Diffusion Transformer (CDiT) Block. The block’s complexity is linear with the number of frames.
图 2:条件扩散 Transformer(CDiT)块。复杂度相对帧数线性。
Diffusion Training. In the forward process, noise is added to the target state according to a randomly chosen timestep . The noisy state can be defined as: , where is Gaussian noise, and is a noise schedule controlling the variance. As increases, converges to pure noise. The reverse process attempts to recover the original state representation from the noisy version , conditioned on the context , the current action , and the diffusion timestep . We define as the denoising neural network model parameterized by . We follow the same noise schedule and hyperparams of DiT (Peebles and Xie 2023).
扩散训练。前向过程按随机时间步 向目标状态 加噪。含噪状态可写为 ,其中 , 控制方差的噪声日程。 增大时 趋近纯噪声。反向过程试图从含噪版本 恢复原状态 ,并条件于上下文 、当前动作 与扩散时间步 。定义 为参数 的去噪网络。噪声日程与超参与 DiT(Peebles and Xie 2023)一致。
Training Objective. The model is trained to minimize the mean-squared between the clean and predicted target, aiming to learn the denoising process:
训练目标。模型最小化干净目标与预测之间的均方误差,以学习去噪过程:
In this objective, the timestep is sampled randomly to ensure that the model learns to denoise frames across varying levels of corruption. By minimizing this loss, the model learns to reconstruct from its noisy version , conditioned on the context and action , thereby enabling the generation of realistic future frames. Following (Peebles and Xie 2023), we also predict the covariance matrix of the noise and supervise it with the variational lower bound loss Nichol and Dhariwal 2021.
目标中时间步 随机采样,使模型学会在不同腐蚀程度下去噪。最小化该损失后,模型可从含噪版本 重建 ,并条件于 与 ,从而生成逼真的未来帧。遵循 Peebles and Xie 2023,我们也预测噪声协方差,并用变分下界损失 (Nichol and Dhariwal 2021)监督。
3.3 Navigation Planning with World Models
3.3 用世界模型做导航规划
Here we move to describe how to use a trained NWM to plan navigation trajectories. Intuitively, if our world model is familiar with an environment, we can use it to simulate navigation trajectories, and choose the ones which reach the goal. In an unknown, out of distribution environments, long term planning might rely on imagination.
本节说明如何用训好的 NWM 规划导航轨迹。直观上,若世界模型熟悉某环境,即可仿真导航轨迹并选出能到达目标者;在未知、分布外环境中,长期规划可能更多依赖「想象」。
Formally, given the latent encoding and navigation target , we look for a sequence of actions that maximizes the likelihood of reaching . Let represent the unnormalized score for reaching state with given the initial condition , actions , and states obtained by autoregressively rolling out the NWM: .
形式化地,给定潜在编码 与导航目标 ,寻找动作序列 以最大化到达 的似然。令 表示在初始条件 、动作 以及由 NWM 自回归展开得到的状态 下,用 到达 的未归一化分数。
We define the energy function , such that minimizing the energy corresponds to maximizing the unnormalized perceptual similarity score and following potential constraints on the states and actions:
定义能量函数 ,使最小化能量对应最大化未归一化感知相似度,并满足对状态与动作的潜在约束:
The similarity is computed by decoding and to pixels using a pretrained VAE decoder (Blattmann et al. 2023) and then measuring the perceptual similarity (Zhang et al. 2018a; Fu et al. 2024). Constraints like “never go left then right” can be encoded by constraining to be in a valid action set , and “never explore the edge of the cliff” by ensuring such states are in . denotes the indicator function that applies a large penalty if any action or state constraint is violated.
相似度做法:用预训练 VAE 解码器(Blattmann et al. 2023)把 与 解码到像素,再测感知相似度(Zhang et al. 2018a;Fu et al. 2024)。诸如「先左后右禁止」可通过把 约束在合法动作集 中编码;「勿探悬崖边」则要求状态 落在 。 为指示函数,一旦违反动作或状态约束即施加大惩罚。
The problem then reduces to finding the actions that minimize this energy function:
问题于是化为寻找最小化该能量的动作:
This objective can be reformulated as a Model Predictive Control (MPC) problem, and we optimize it using the Cross-Entropy Method (Rubinstein 1997), a simple derivative-free and population-based optimization method which was recently used with with world models for planning (Zhou et al. 2024). We include an overview of the Cross-Entropy Method and the full optimization technical details in Appendix 7.
该目标可改写为模型预测控制(MPC)问题,我们用交叉熵方法(Cross-Entropy Method,Rubinstein 1997)优化:这是无无导数、基于种群的优化器,近来也用于世界模型规划(Zhou et al. 2024)。交叉熵方法概览与完整优化细节见附录 7。
Ranking Navigation Trajectories. Assuming we have an existing navigation policy , we can use NWMs to rank sampled trajectories. Here we use NoMaD (Sridhar et al. 2024), a state-of-the-art navigation policy for robotic navigation. To rank trajectories, we draw multiple samples from and choose the one with the lowest energy, like in Eq. 5.
对导航轨迹排序。若已有导航策略 ,可用 NWM 对采样轨迹排序。这里用当时最优的机器人导航策略 NoMaD(Sridhar et al. 2024)。做法是从 多次采样,选能量最低者,如式 5。
4 Experiments and Results
4 实验与结果
We describe the experimental setting, our design choices, and compare NWM to previous approaches. Additional results are included in the Supplementary Material.
我们描述实验设定、设计选择,并与先前方法比较。更多结果见补充材料。
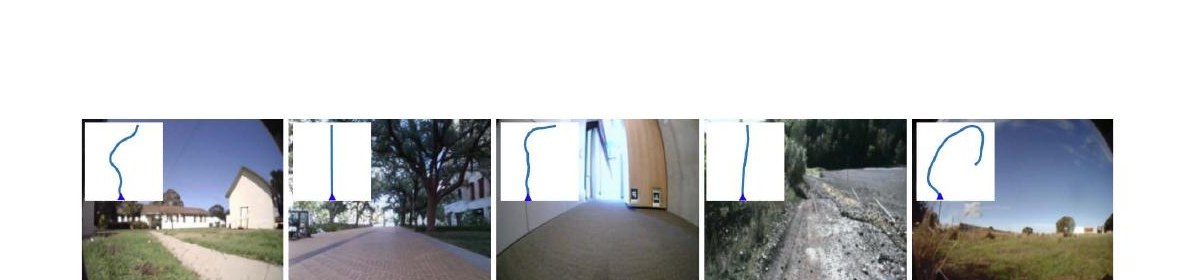
Figure 3: Following trajectories in known environments. We include qualitative video generation comparisons of different models following ground truth trajectories. Click on the image to play the video clip in a browser.
图 3:在已知环境中跟随轨迹。 我们给出不同模型跟随真值轨迹的定性视频生成对比。点击图像可在浏览器中播放片段。
| ablation | lpips | dreamsim | psnr |
|---|---|---|---|
| 1 | |||
| 2 #goals | |||
| 4 | 0.296 | 0.091 | 15.331 |
| 1 | |||
| 2 #context | |||
| 4 | 0.296 | 0.091 | 15.331 |
| time only | |||
| action only | |||
| action + time | 0.295 | 0.091 | 15.343 |
| model | diamond | NWM (ours) |
|---|---|---|
| FVD | 200.969 |
Table 1: Ablations of predicted goals per sample number, context size, and the use of action and time conditioning. We report prediction results seconds into the future on RECON.
| 消融 | lpips | dreamsim | psnr |
|---|---|---|---|
| 1 | |||
| 2 #goals | |||
| 4 | 0.296 | 0.091 | 15.331 |
| 1 | |||
| 2 #context | |||
| 4 | 0.296 | 0.091 | 15.331 |
| 仅时间 | |||
| 仅动作 | |||
| 动作 + 时间 | 0.295 | 0.091 | 15.343 |
| 模型 | diamond | NWM(本文) |
|---|---|---|
| FVD | 200.969 |
表 1:消融:每样本预测目标数、上下文长度,以及动作与时间条件的使用。在 RECON 上报告未来 4 秒预测结果。
4.1 Experimental Setting
4.1 实验设定
Datasets. For all robotics datasets (SCAND (Karnan et al. 2022), TartanDrive (Triest et al. 2022), RECON (Shah et al. 2021), and HuRoN (Hirose et al. 2023)), we have access to the location and rotation of robots, allowing us to infer relative actions compare to current location (see Eq. 2). To standardize the step size across agents, we divide the distance agents travel between frames by their average step size in meters, ensuring the action space is similar for different agents. We further filter out backward movements, following NoMaD (Sridhar et al. 2024). Additionally, we use unlabeled Ego4D (Grauman et al. 2022) videos, where the only action we consider is time shift. SCAND provides video footage of socially compliant navigation in diverse environments, TartanDrive focuses on off-road driving, RECON covers open-world navigation, HuRoN captures social interactions. We train on unlabeled Ego4D videos and GO Stanford (Hirose et al. 2018) serves as an unknown evaluation environment. For the full details, see Appendix 8.1.
数据集。 对所有机器人数据集(SCAND(Karnan et al. 2022)、TartanDrive(Triest et al. 2022)、RECON(Shah et al. 2021)、HuRoN(Hirose et al. 2023)),我们有位置与旋转,可相对当前位置推断动作(见式 2)。为跨智能体统一步长,把帧间行驶距离除以各自平均步长(米),使动作空间相近;并按 NoMaD(Sridhar et al. 2024)过滤后退运动。另用无标注 Ego4D(Grauman et al. 2022)视频,此时唯一动作是时间偏移。SCAND 覆盖多样环境中的社会合规导航,TartanDrive 侧重越野驾驶,RECON 覆盖开放世界导航,HuRoN 捕捉社交互动。无标注 Ego4D 用于训练;GO Stanford(Hirose et al. 2018)作未知评测环境。完整细节见附录 8.1。
Evaluation Metrics. We evaluate predicted navigation trajectories using Absolute Trajectory Error (ATE) for accuracy and Relative Pose Error (RPE) for pose consistency (Sturm et al. 2012). To check how semantically similar are world model predictions to ground truth images, we apply LPIPS (Zhang et al. 2018b) and DreamSim (Fu et al. 2024), measuring perceptual similarity by comparing deep features, and PSNR for pixel-level quality. For image and video synthesis quality, we use FID (Heusel et al. 2017) and FVD (Unterthiner et al. 2019) which evaluate the generated data distribution. See Appendix 8.1 for more details.
评测指标。 用绝对轨迹误差(ATE)衡量精度,相对位姿误差(RPE)衡量位姿一致性(Sturm et al. 2012)。为衡量世界模型预测与真值图像的语义相近程度,用 LPIPS(Zhang et al. 2018b)与 DreamSim(Fu et al. 2024)比较深层特征的感知相似度,并用 PSNR 衡量像素级质量。图像与视频合成质量用 FID(Heusel et al. 2017)与 FVD(Unterthiner et al. 2019)评估生成分布。详见附录 8.1。
Baselines. We consider all the following baselines.
基线。 我们考虑以下基线。
- • DIAMOND (Alonso et al.) is a diffusion world model based on the UNet (Ronneberger et al. 2015) architecture. We use DIAMOND in the offline-reinforcement learning setting following their public code. The diffusion model is trained to autoregressively predict at x resolution alongside an upsampler to obtrain x resolution predictions. To condition on continuous actions, we use a linear embedding layer.
- • DIAMOND(Alonso et al.)是基于 UNet(Ronneberger et al. 2015)的扩散世界模型。我们按其公开代码在离线强化学习设定下使用:扩散模型以 自回归预测,再经上采样得到 。连续动作用线性嵌入层条件化。
- • GNM (Shah et al. 2023) is a general goal-conditioned navigation policy trained on a dataset soup of robotic navigation datasets with a fully connected trajectory prediction network. GNM is trained on multiple datasets including SCAND, TartanDrive, GO Stanford, and RECON.
- • GNM(Shah et al. 2023)是在机器人导航数据集「汤」上训练的通用目标条件导航策略,用全连接网络预测轨迹。训练数据含 SCAND、TartanDrive、GO Stanford 与 RECON。
- • NoMaD (Sridhar et al. 2024) extends GNM using a diffusion policy for predicting trajectories for robot exploration and visual navigation. NoMaD is trained on the same datasets used by GNM and on HuRoN.
- • NoMaD(Sridhar et al. 2024)在 GNM 上扩展,用扩散策略预测机器人探索与视觉导航轨迹。训练数据与 GNM 相同,并加入 HuRoN。
Implementation Details. In the default experimental setting we use a CDiT-XL of parameters with context of frames, a total batch size of , and different navigation goals, leading to a final total batch size of . We use the Stable Diffusion (Blattmann et al. 2023) VAE tokenizer, similar as in DiT (Peebles and Xie 2023). We use the AdamW (Loshchilov 2017) optimizer with a learning rate of . After training, we sample times from each model to report mean and std results. XL sized model are trained on H100 machines, each with GPUs. Unless otherwise mentioned, we use the same setting as in DiT-*/2 models.
实现细节。 默认设定用 参数的 CDiT-XL,上下文 4 帧,总批大小 1024,并配 4 个不同导航目标,最终有效批大小 4096。VAE tokenizer 采用 Stable Diffusion(Blattmann et al. 2023),与 DiT(Peebles and Xie 2023)类似。优化器用 AdamW(Loshchilov 2017),学习率 。训练后每个模型采样 5 次报告均值与标准差。XL 规模在 8 台各 8 GPU 的 H100 机器上训练。除非另说明,设定与 DiT-*/2 一致。
4.2 Ablations
4.2 消融
Models are evaluated on single-step seconds future prediction on validation set trajectories on the known environment RECON. We evaluate the performance against the ground truth frame by measuring LPIPS, DreamSim, and PSNR. We provide qualitative examples in Figure 3.
模型在已知环境 RECON 的验证轨迹上做单步未来 4 秒预测,相对真值帧报告 LPIPS、DreamSim 与 PSNR。定性样例见图 3。
Model Size and CDiT. We compare CDiT (see Section 3.2) with a standard DiT in which all context tokens are fed as inputs. We hypothesize that for navigating known environments, the capacity of the model is the most important, and the results in Figure 6, indicate that CDiT indeed performs better with models of up to B parameters, while consuming less than FLOPs. Surprisingly, even with equal amount of parameters (e.g, CDiT-L compared to DiT-XL), CDiT is faster and performs better.
模型规模与 CDiT。将 CDiT(见 3.2 节)与把全部上下文 token 作输入的标准 DiT 对比。我们假设:在已知环境导航中,模型容量最关键;图 6 表明 CDiT 在高达 B 参数时表现更好,且 FLOPs 不到 。令人意外的是,即使参数量相当(如 CDiT-L 对 DiT-XL),CDiT 也快约 且效果更好。
Number of Goals. We train models with variable number of goal states given a fixed context, changing the number of goals from to . Each goal is randomly chosen between seconds window around the current state. The results reported in Table 1 indicate that using goals leads to significantly improved prediction performance in all metrics.
目标数量。固定上下文,把给定上下文下的目标状态数从 变到 。每个目标在当前状态前后 秒窗口内随机选取。表 1 显示用 个目标时,各项预测指标均显著更好。
Context Size. We train models while varying the number of conditioning frames from to (see Table 1). Unsurprisingly, more context helps, and with short context the model often “lose track”, leading to poor predictions.
上下文长度。条件帧数从 变到 (见表 1)。不出所料,更多上下文有帮助;短上下文时模型常「跟丢」,预测变差。
Time and Action Conditioning. We train our model with both time and action conditioning and test how much each input contributes to the prediction performance (we include the results in Table 1. We find that running the model with time only leads to poor performance, while not conditioning on time leads to small drop in performance as well. This confirms that both inputs are beneficial to the model.
时间与动作条件。同时用时间与动作条件训练,再分别检验各输入对预测的贡献(结果见表 1)。仅用时间时表现很差;去掉时间条件也会小幅下降。说明两者都有益。
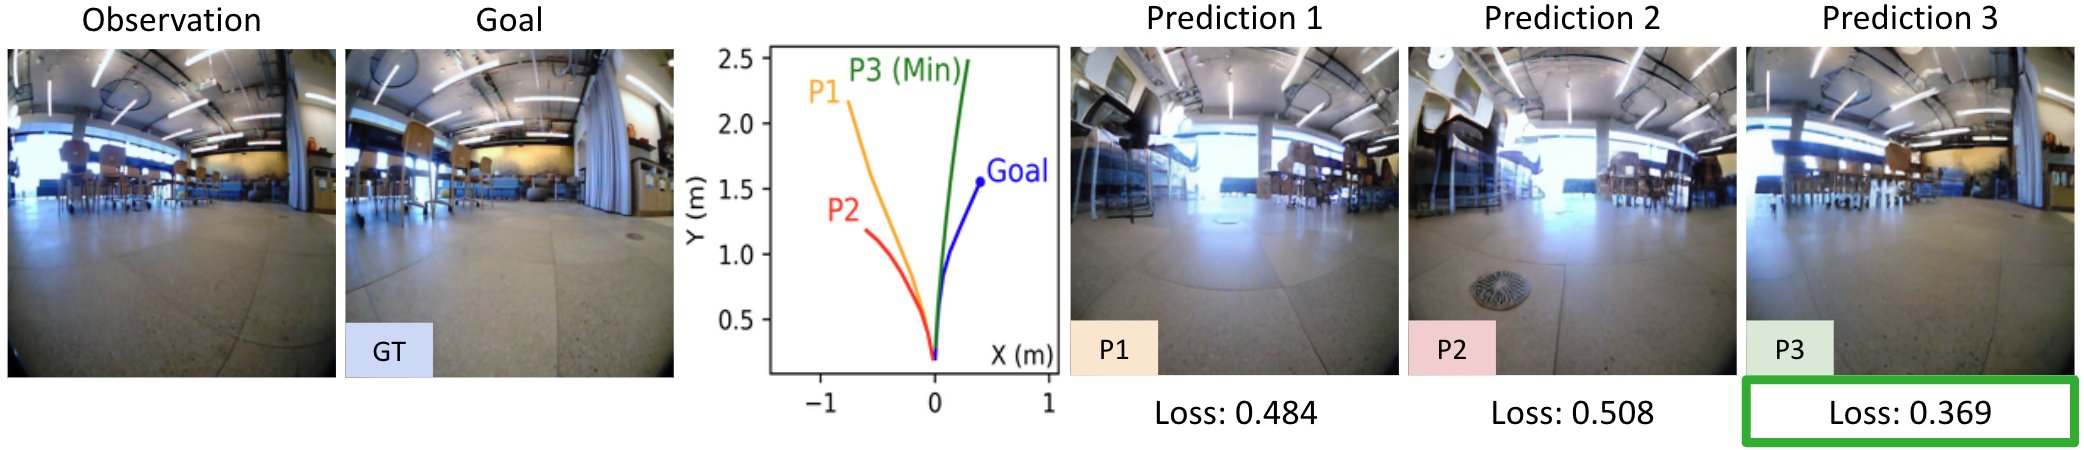
Figure 7: Ranking an external policy’s trajectories using NWM. To navigate from the observation image to the goal, we sample trajectories from NoMaD (Sridhar et al. 2024), simulate each of these trajectories using NWM, score them (see Equation 4), and rank them. With NWM we can accurately choose trajectories that are closer to the groundtruth trajectory. Click the image to play examples in a browser.
图 7:用 NWM 对外部策略轨迹排序。 从观测图导航到目标时,从 NoMaD(Sridhar et al. 2024)采样轨迹,用 NWM 仿真,按式 4 打分并排序。借助 NWM 可准确选出更接近真值轨迹者。点击图像可在浏览器中播放样例。
| model | ATE | RPE |
|---|---|---|
| GNM | ||
| NoMaD | ||
| NWM + NoMaD () | ||
| NWM + NoMaD () | ||
| NWM (planning) | 1.13 | 0.35 |
| model | Rel. | Rel. |
|---|---|---|
| forward first | ||
| left-right first | ||
| straight then forward |
Table 2: Goal Conditioned Visual Navigation. ATE and RPE results on RECON, predicting second trajectories. NWM achieves improved results on all metrics compared to previous approaches NoMaD (Sridhar et al. 2024) and GNM (Shah et al. 2023).
| 模型 | ATE | RPE |
|---|---|---|
| GNM | ||
| NoMaD | ||
| NWM + NoMaD () | ||
| NWM + NoMaD () | ||
| NWM(规划) | 1.13 | 0.35 |
| 模型 | Rel. | Rel. |
|---|---|---|
| 先前进 | ||
| 先左右 | ||
| 先直行再前进 |
表 2:目标条件视觉导航。 RECON 上预测 2 秒轨迹的 ATE 与 RPE。相对 NoMaD(Sridhar et al. 2024)与 GNM(Shah et al. 2023),NWM 在各项指标上均更优。
4.3 Video Prediction and Synthesis
4.3 视频预测与合成
We evaluate how well our model follows ground truth actions and predicts future states. The model is conditioned on the first image and context frames, then autoregressively predicts the next state using ground truth actions, feeding back each prediction. We compare predictions to ground truth images at , , , , and seconds, reporting FID and LPIPS on the RECON dataset. Figure 4 shows performance over time compared to DIAMOND at FPS and FPS, showing that NWM predictions are significantly more accurate than DIAMOND. Initially, the NWM FPS variant performs better, but after seconds, predictions degrade due to accumulated errors and loss of context and the FPS becomes superior. See qualitative examples in Figure 3.
我们评测模型跟随真值动作并预测未来状态的能力:以首帧与上下文帧为条件,用真值动作自回归预测下一状态,并把每次预测反馈回去。在 1、2、4、8、16 秒处与真值图比较,在 RECON 上报告 FID 与 LPIPS。图 4 给出相对 DIAMOND 在 4 FPS 与 1 FPS 下随时间的表现:NWM 预测明显更准。初期 1 FPS 变体更好,但约 8 秒后因误差累积与上下文丢失而变差,4 FPS 反而更优。定性样例见图 3。
Generation Quality. To evaluate video quality, we auto-regressively predict videos at FPS for seconds to create videos, while conditioning on ground truth actions. We then evaluate the quality of videos generated using FVD, compared to DIAMOND (Alonso et al.). The results in Figure 6 indicate that NWM outputs higher quality videos.
生成质量。 为评测视频质量,在真值动作条件下以 4 FPS 自回归预测 16 秒视频,用 FVD 与 DIAMOND(Alonso et al.)比较。图 6 表明 NWM 输出质量更高。
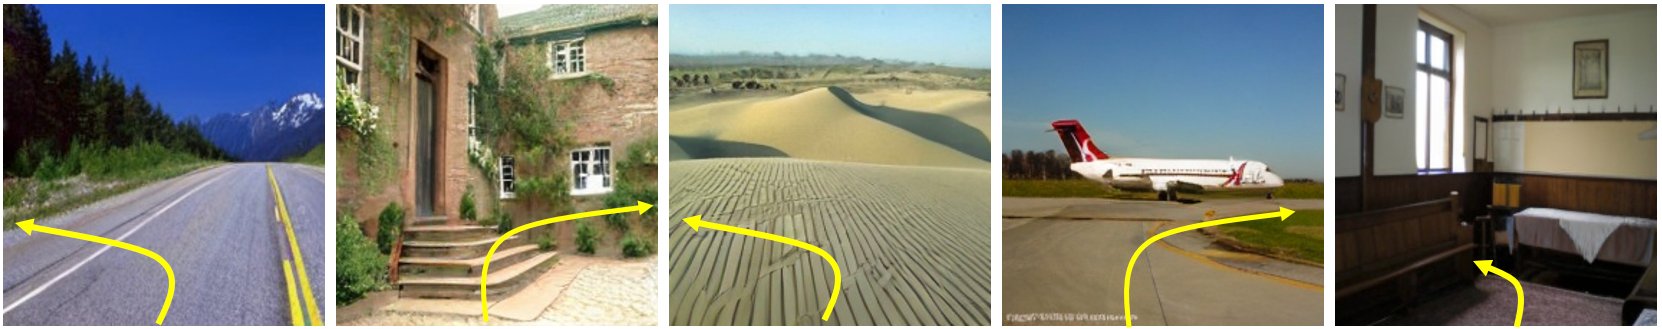
Figure 8: Navigating Unknown Environments. NWM is conditioned on a single image, and autoregressively predicts the next states given the associated actions (marked in yellow). Click on the image to play the video clip in a browser.
图 8:在未知环境中导航。 NWM 以单张图像为条件,按给定动作(黄标)自回归预测后续状态。点击图像可在浏览器中播放片段。
| data | unknown environment (Go Stanford) | known environment (RECON) | ||||
|---|---|---|---|---|---|---|
| lpips | dreamsim | psnr | lpips | dreamsim | psnr | |
| in-domain data | 0.295 | 0.091 | 15.343 | |||
| + Ego4D (unlabeled) | 0.652 | 0.464 | 11.083 |
Table 4: Training on additional unlabeled data improves performance on unseen environments. Reporting results on unknown environment (Go Stanford) and known one (RECON). Results reported by evaluating seconds into the future.
| 数据 | 未知环境(Go Stanford) | 已知环境(RECON) | ||||
|---|---|---|---|---|---|---|
| lpips | dreamsim | psnr | lpips | dreamsim | psnr | |
| 域内数据 | 0.295 | 0.091 | 15.343 | |||
| + Ego4D(无标注) | 0.652 | 0.464 | 11.083 |
表 4:额外无标注数据可提升未见环境表现。 在未知环境(Go Stanford)与已知环境(RECON)上报告未来 4 秒结果。
4.4 Planning Using a Navigation World Model
4.4 用导航世界模型规划
Next, we turn to describe experiments that measure how well can we navigate using a NWM. We include the full technical details of the experiments in Appendix 8.2.
下面报告用 NWM 导航的实验。完整技术细节见附录 8.2。
Standalone Planning. We demonstrate that NWM can be effectively used independently for goal-conditioned navigation. We condition it on past observations and a goal image, and use the Cross-Entropy Method to find a trajectory that minimizes the LPIPS similarity of the last predicted image to the goal image (see Equation 5). To rank an action sequence, we execute the NWM and measure LPIPS between the last state and the goal times to get an average score. We generate trajectories of length , with temporal shift of . We evaluate the model performance in Table 3. We find that using a NWM for planning leads to competitive results with state-of-the-art policies.
独立规划。 我们展示 NWM 可独立用于目标条件导航:以过去观测与目标图为条件,用交叉熵方法寻找使末帧预测与目标图 LPIPS 最小的轨迹(见式 5)。为给动作序列打分,执行 NWM 三次并平均末状态与目标的 LPIPS。生成长度 8、时间偏移 的轨迹。表 3 显示:用 NWM 规划可与当时最优策略竞争。
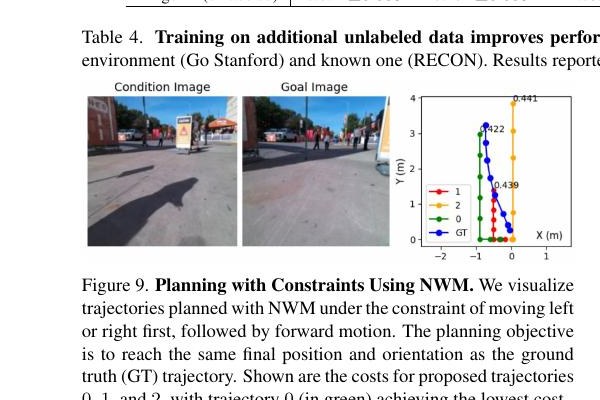
Figure 9: Planning with Constraints Using NWM. We visualize trajectories planned with NWM under the constraint of moving left or right first, followed by forward motion. The planning objective is to reach the same final position and orientation as the ground truth (GT) trajectory. Shown are the costs for proposed trajectories , , and , with trajectory (in green) achieving the lowest cost.
图 9:带约束的 NWM 规划。 可视化在「先左或先右、再前进」约束下由 NWM 规划的轨迹。规划目标是到达与真值(GT)相同的最终位置与朝向。图中给出候选轨迹 0、1、2 的代价,绿色轨迹 0 代价最低。
Planning with Constraints. World models allow planning under constraints—for example, requiring straight motion or a single turn. We show that NWM supports constraint-aware planning. In forward-first, the agent moves forward for 5 steps, then turns for 3. In left-right first, it turns for 3 steps before moving forward. In straight then forward, it moves straight for 3 steps, then forward. Constraints are enforced by zeroing out specific actions; e.g., in left-right first, forward motion is zeroed for the first 3 steps, and Standalone Planning optimizes the rest. We report the norm of the difference in final position and yaw relative to unconstrained planning. Results (Table 3) show NWM plans effectively under constraints, with only minor performance drops (see examples in Figure 9).
带约束规划。 世界模型可在约束下规划——例如要求直行或只转一次。我们展示 NWM 支持感知约束的规划。先前进:前 5 步前进,再转 3 步;先左右:先转 3 步再前进;先直行再前进:先直行 3 步再前进。约束通过对特定动作置零实现;例如 先左右 时前 3 步前进置零,其余由独立规划优化。报告相对无约束规划的最终位置与偏航差的范数。结果(表 3)表明 NWM 在约束下仍能有效规划,性能仅略降(样例见图 9)。
Using a Navigation World Model for Ranking. NWM can enhance existing navigation policies in a goal-conditioned navigation. Conditioning NoMaD on past observations and a goal image, we sample trajectories, each of length , and evaluate them by autoregressively following the actions using NWM. Finally, we rank each trajectory’s final prediction by measuring LPIPS similarity with the goal image (see Figure 7). We report ATE and RPE on all in-domain datasets (Table 3) and find that NWM-based trajectory ranking improves navigation performance, with more samples yielding better results.
用导航世界模型排序。在目标条件导航中,NWM 可增强已有策略:以过去观测与目标图条件化 NoMaD,采样 条长度 8 的轨迹,用 NWM 自回归跟随动作,再按末帧预测与目标图的 LPIPS 排序(见图 7)。在全部域内数据集上报告 ATE 与 RPE(表 3):基于 NWM 的轨迹排序能提升导航表现,样本越多越好。
4.5 Generalization to Unknown Environments
4.5 向未知环境泛化
Here we experiment with adding unlabeled data, and ask whether NWM can make predictions in new environments using imagination. In this experiment, we train a model on all in-domain datasets, as well as a susbet of unlabeled videos from Ego4D, where we only have access to the time-shift action. We train a CDiT-XL model and test it on the Go Stanford dataset as well as other random images. We report the results in Table 4, finding that training on unlabeled data leads to significantly better video predictions according to all metrics, including improved generation quality. We include qualitative examples in Figure 8. Compared to in-domain (Figure 3), the model breaks faster and expectedly hallucinates paths as it generates traversals of imagined environments.
本节实验加入无标注数据,并询问 NWM 能否靠「想象」在新环境中做预测。我们在全部域内数据以及 Ego4D 的无标注视频子集上训练(后者仅有时间偏移动作),用 CDiT-XL,并在 Go Stanford 及其他随机图像上测试。表 4 显示:无标注数据使各项视频预测指标显著更好,生成质量也提升。定性样例见图 8。相对域内(图 3),模型更快失真,并如预期地在想象环境中「幻觉」出路径。
5 Limitations
5 局限
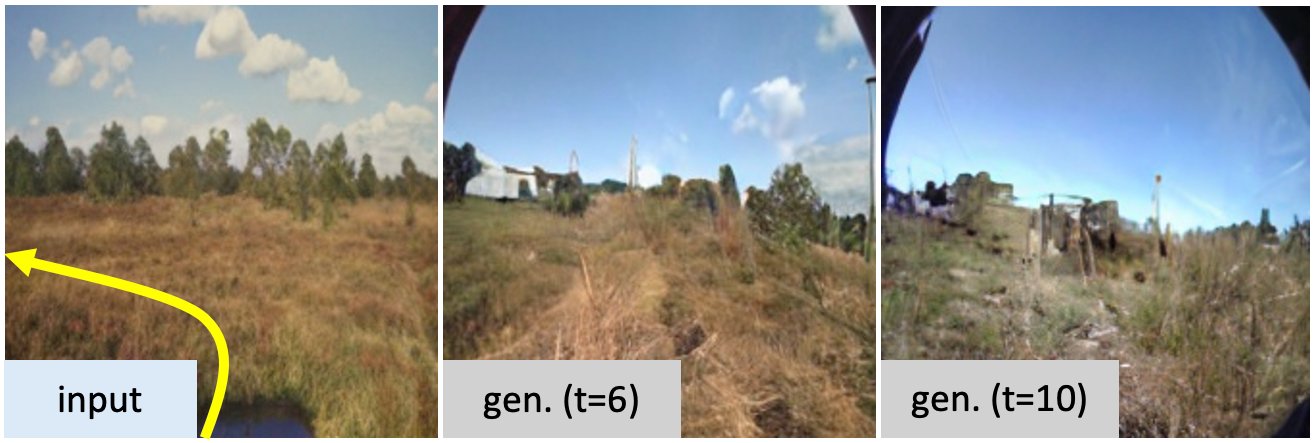
Figure 10: Limitations and Failure Cases. In unknown environments, a common failure case is mode collapse, where the model outputs slowly become more similar to data seen in training. Click on the image to play the video clip in a browser.
图 10:局限与失败案例。 在未知环境中,常见失败是模式崩溃:模型输出逐渐更像训练中见过的数据。点击图像可在浏览器中播放片段。
We identify multiple limitations. First, when applied to out of distribution data, the model tends to slowly lose context and generates next states that resemble the training data, a phenomena that was observed in image generation and is known as mode collapse (Thanh-Tung and Tran 2020; Srivastava et al. 2017). We include such an example in Figure 10. Second, while the model can plan, it struggles with simulating temporal dynamics like pedestrian motion (although in some cases it does). Both limitations are likely to be solved with longer context and more training data. Additionally, the model currently utilizes DoF navigation actions, but extending to DoF navigation and potentially more (like controlling the joints of a robotic arm) are possible as well, which we leave for future work.
我们指出若干局限。第一,用于分布外数据时,模型会慢慢丢失上下文,生成更像训练数据的下一状态——图像生成中亦常见,称为模式崩溃(Thanh-Tung and Tran 2020;Srivastava et al. 2017)。样例见图 10。第二,虽能规划,但对行人运动等时间动力学仿真仍吃力(个别情况可以)。两者都有望靠更长上下文与更多训练数据缓解。另外,当前模型用 3 自由度导航动作;扩展到 6 自由度乃至机械臂关节控制也是可能方向,留待未来工作。
6 Discussion
6 讨论
Our proposed Navigation World Model (NWM) offers a scalable, data-driven approach to learning world models for visual navigation; However, we are not exactly sure yet what representations enable this, as our NWM does not explicitly utilize a structured map of the environment. One idea, is that next frame prediction from an egocentric point of view can drive the emergence of allocentric representations Uria et al. 2022. Ultimately, our approach bridges learning from video, visual navigation, and model-based planning and could potentially open the door to self-supervised systems that not only perceive but can also plan to inform action.
所提导航世界模型(NWM)为视觉导航提供了可扩展、数据驱动的世界模型学习路径;不过我们尚不完全清楚支撑它的是何种表征——因为 NWM 并不显式使用结构化环境地图。一种想法是:第一人称下一帧预测可驱动异中心表征涌现(Uria et al. 2022)。总体而言,本方法衔接了视频学习、视觉导航与基于模型的规划,或可为既能感知又能规划以指导行动的自监督系统打开空间。
Acknowledgments. We thank Noriaki Hirose for his help with the HuRoN dataset and for sharing his insights, and to Manan Tomar, David Fan, Sonia Joseph, Angjoo Kanazawa, Ethan Weber, Nicolas Ballas, and the anonymous reviewers for their helpful discussions and feedback.
致谢。 感谢 Noriaki Hirose 在 HuRoN 数据集上的帮助与洞见,以及 Manan Tomar、David Fan、Sonia Joseph、Angjoo Kanazawa、Ethan Weber、Nicolas Ballas 与匿名审稿人的讨论与反馈。
References
参考文献
Supplementary Material
补充材料
The structure of the Appendix is as follows: we start by describing how we plan navigation trajectories via Standalone Planning in Section 7, and then include more experiments and results in Section 8.
附录结构如下:先在第 7 节说明如何用独立规划得到导航轨迹,再在第 8 节给出更多实验与结果。
(1) Eloi Alonso, Adam Jelley, Vincent Micheli, Anssi Kanervisto, Amos Storkey, Tim Pearce, and François Fleuret. Diffusion for world modeling: Visual details matter in atari. In Thirty-eighth Conference on Neural Information Processing Systems .
Bar et al. (2021) Amir Bar, Roei Herzig, Xiaolong Wang, Anna Rohrbach, Gal Chechik, Trevor Darrell, and Amir Globerson. Compositional video synthesis with action graphs. In International Conference on Machine Learning , pages 662–673. PMLR, 2021.
Bar-Tal et al. (2024) Omer Bar-Tal, Hila Chefer, Omer Tov, Charles Herrmann, Roni Paiss, Shiran Zada, Ariel Ephrat, Junhwa Hur, Guanghui Liu, Amit Raj, et al. Lumiere: A space-time diffusion model for video generation. arXiv preprint arXiv:2401.12945 , 2024.
Blattmann et al. (2023) Andreas Blattmann, Tim Dockhorn, Sumith Kulal, Daniel Mendelevitch, Maciej Kilian, Dominik Lorenz, Yam Levi, Zion English, Vikram Voleti, Adam Letts, et al. Stable video diffusion: Scaling latent video diffusion models to large datasets. arXiv preprint arXiv:2311.15127 , 2023.
Brooks et al. (2024) Tim Brooks, Bill Peebles, Connor Holmes, Will DePue, Yufei Guo, Li Jing, David Schnurr, Joe Taylor, Troy Luhman, Eric Luhman, et al. Video generation models as world simulators, 2024.
Bruce et al. (2024) Jake Bruce, Michael D Dennis, Ashley Edwards, Jack Parker-Holder, Yuge Shi, Edward Hughes, Matthew Lai, Aditi Mavalankar, Richie Steigerwald, Chris Apps, et al. Genie: Generative interactive environments. In Forty-first International Conference on Machine Learning , 2024.
Chan et al. (2023) Eric R. Chan, Koki Nagano, Matthew A. Chan, Alexander W. Bergman, Jeong Joon Park, Axel Levy, Miika Aittala, Shalini De Mello, Tero Karras, and Gordon Wetzstein. Generative novel view synthesis with 3d-aware diffusion models. In Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV) , pages 4217–4229, 2023.
(8) Devendra Singh Chaplot, Dhiraj Gandhi, Saurabh Gupta, Abhinav Gupta, and Ruslan Salakhutdinov. Learning to explore using active neural slam. In International Conference on Learning Representations .
(9) Tao Chen, Saurabh Gupta, and Abhinav Gupta. Learning exploration policies for navigation. In International Conference on Learning Representations .
Escontrela et al. (2024) Alejandro Escontrela, Ademi Adeniji, Wilson Yan, Ajay Jain, Xue Bin Peng, Ken Goldberg, Youngwoon Lee, Danijar Hafner, and Pieter Abbeel. Video prediction models as rewards for reinforcement learning. Advances in Neural Information Processing Systems , 36, 2024.
Finn and Levine (2017) Chelsea Finn and Sergey Levine. Deep visual foresight for planning robot motion. In 2017 IEEE International Conference on Robotics and Automation (ICRA) , pages 2786–2793. IEEE, 2017.
Frantar et al. (2022) Elias Frantar, Saleh Ashkboos, Torsten Hoefler, and Dan Alistarh. Gptq: Accurate post-training quantization for generative pre-trained transformers. arXiv preprint arXiv:2210.17323 , 2022.
Frey et al. (2023) J Frey, M Mattamala, N Chebrolu, C Cadena, M Fallon, and M Hutter. Fast traversability estimation for wild visual navigation. Robotics: Science and Systems Proceedings , 19, 2023.
Fu et al. (2024) Stephanie Fu, Netanel Tamir, Shobhita Sundaram, Lucy Chai, Richard Zhang, Tali Dekel, and Phillip Isola. Dreamsim: Learning new dimensions of human visual similarity using synthetic data. Advances in Neural Information Processing Systems , 36, 2024.
Fu et al. (2022) Zipeng Fu, Ashish Kumar, Ananye Agarwal, Haozhi Qi, Jitendra Malik, and Deepak Pathak. Coupling vision and proprioception for navigation of legged robots. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition , pages 17273–17283, 2022.
Gao et al. (2024) Junyu Gao, Xuan Yao, and Changsheng Xu. Fast-slow test-time adaptation for online vision-and-language navigation. In Proceedings of the 41st International Conference on Machine Learning , pages 14902–14919. PMLR, 2024.
Girdhar et al. (2023) Rohit Girdhar, Mannat Singh, Andrew Brown, Quentin Duval, Samaneh Azadi, Sai Saketh Rambhatla, Akbar Shah, Xi Yin, Devi Parikh, and Ishan Misra. Emu video: Factorizing text-to-video generation by explicit image conditioning. arXiv preprint arXiv:2311.10709 , 2023.
Grauman et al. (2022) Kristen Grauman, Andrew Westbury, Eugene Byrne, Zachary Chavis, Antonino Furnari, Rohit Girdhar, Jackson Hamburger, Hao Jiang, Miao Liu, Xingyu Liu, et al. Ego4d: Around the world in 3,000 hours of egocentric video. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition , pages 18995–19012, 2022.
Ha and Schmidhuber (2018) David Ha and Jürgen Schmidhuber. World models. arXiv preprint arXiv:1803.10122 , 2018.
Hafner et al. (a) Danijar Hafner, Timothy Lillicrap, Jimmy Ba, and Mohammad Norouzi. Dream to control: Learning behaviors by latent imagination. In International Conference on Learning Representations , a.
Hafner et al. (b) Danijar Hafner, Timothy P Lillicrap, Mohammad Norouzi, and Jimmy Ba. Mastering atari with discrete world models. In International Conference on Learning Representations , b.
(22) Nicklas Hansen, Hao Su, and Xiaolong Wang. Td-mpc2: Scalable, robust world models for continuous control. In The Twelfth International Conference on Learning Representations .
Heusel et al. (2017) Martin Heusel, Hubert Ramsauer, Thomas Unterthiner, Bernhard Nessler, and Sepp Hochreiter. Gans trained by a two time-scale update rule converge to a local nash equilibrium. Advances in neural information processing systems , 30, 2017.
Hirose et al. (2018) Noriaki Hirose, Amir Sadeghian, Marynel Vázquez, Patrick Goebel, and Silvio Savarese. Gonet: A semi-supervised deep learning approach for traversability estimation. In 2018 IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS) , pages 3044–3051. IEEE, 2018.
Hirose et al. (2019a) Noriaki Hirose, Amir Sadeghian, Fei Xia, Roberto Martín-Martín, and Silvio Savarese. Vunet: Dynamic scene view synthesis for traversability estimation using an rgb camera. IEEE Robotics and Automation Letters , 2019a.
Hirose et al. (2019b) Noriaki Hirose, Fei Xia, Roberto Martín-Martín, Amir Sadeghian, and Silvio Savarese. Deep visual mpc-policy learning for navigation. IEEE Robotics and Automation Letters , 4(4):3184–3191, 2019b.
Hirose et al. (2023) Noriaki Hirose, Dhruv Shah, Ajay Sridhar, and Sergey Levine. Sacson: Scalable autonomous control for social navigation. IEEE Robotics and Automation Letters , 2023.
Ho et al. (2020) Jonathan Ho, Ajay Jain, and Pieter Abbeel. Denoising diffusion probabilistic models. Advances in neural information processing systems , 33:6840–6851, 2020.
Ho et al. (2022) Jonathan Ho, William Chan, Chitwan Saharia, Jay Whang, Ruiqi Gao, Alexey Gritsenko, Diederik P Kingma, Ben Poole, Mohammad Norouzi, David J Fleet, et al. Imagen video: High definition video generation with diffusion models. arXiv preprint arXiv:2210.02303 , 2022.
Karnan et al. (2022) Haresh Karnan, Anirudh Nair, Xuesu Xiao, Garrett Warnell, Sören Pirk, Alexander Toshev, Justin Hart, Joydeep Biswas, and Peter Stone. Socially compliant navigation dataset (scand): A large-scale dataset of demonstrations for social navigation. IEEE Robotics and Automation Letters , 7(4):11807–11814, 2022.
Koh et al. (2021) Jing Yu Koh, Honglak Lee, Yinfei Yang, Jason Baldridge, and Peter Anderson. Pathdreamer: A world model for indoor navigation. In Proceedings of the IEEE/CVF International Conference on Computer Vision , pages 14738–14748, 2021.
(32) Dan Kondratyuk, Lijun Yu, Xiuye Gu, Jose Lezama, Jonathan Huang, Grant Schindler, Rachel Hornung, Vighnesh Birodkar, Jimmy Yan, Ming-Chang Chiu, et al. Videopoet: A large language model for zero-shot video generation. In Forty-first International Conference on Machine Learning .
Krizhevsky et al. (2012) Alex Krizhevsky, Ilya Sutskever, and Geoffrey E Hinton. Imagenet classification with deep convolutional neural networks. Advances in neural information processing systems , 25, 2012.
Lei Ba et al. (2016) Jimmy Lei Ba, Jamie Ryan Kiros, and Geoffrey E Hinton. Layer normalization. ArXiv e-prints , pages arXiv–1607, 2016.
Liang et al. (2024) Junbang Liang, Ruoshi Liu, Ege Ozguroglu, Sruthi Sudhakar, Achal Dave, Pavel Tokmakov, Shuran Song, and Carl Vondrick. Dreamitate: Real-world visuomotor policy learning via video generation, 2024.
Lin et al. (2024a) Han Lin, Tushar Nagarajan, Nicolas Ballas, Mido Assran, Mojtaba Komeili, Mohit Bansal, and Koustuv Sinha. Vedit: Latent prediction architecture for procedural video representation learning, 2024a.
Lin et al. (2024b) Jessy Lin, Yuqing Du, Olivia Watkins, Danijar Hafner, Pieter Abbeel, Dan Klein, and Anca Dragan. Learning to model the world with language, 2024b.
Liu et al. (2023) Ruoshi Liu, Rundi Wu, Basile Van Hoorick, Pavel Tokmakov, Sergey Zakharov, and Carl Vondrick. Zero-1-to-3: Zero-shot one image to 3d object. In Proceedings of the IEEE/CVF international conference on computer vision , pages 9298–9309, 2023.
Loshchilov (2017) I Loshchilov. Decoupled weight decay regularization. arXiv preprint arXiv:1711.05101 , 2017.
Mildenhall et al. (2021) Ben Mildenhall, Pratul P Srinivasan, Matthew Tancik, Jonathan T Barron, Ravi Ramamoorthi, and Ren Ng. Nerf: Representing scenes as neural radiance fields for view synthesis. Communications of the ACM , 65(1):99–106, 2021.
Mirowski et al. (2022) Piotr Mirowski, Razvan Pascanu, Fabio Viola, Hubert Soyer, Andy Ballard, Andrea Banino, Misha Denil, Ross Goroshin, Laurent Sifre, Koray Kavukcuoglu, et al. Learning to navigate in complex environments. In International Conference on Learning Representations , 2022.
Nichol and Dhariwal (2021) Alexander Quinn Nichol and Prafulla Dhariwal. Improved denoising diffusion probabilistic models. In Proceedings of the 38th International Conference on Machine Learning , pages 8162–8171. PMLR, 2021.
Pathak et al. (2018) Deepak Pathak, Parsa Mahmoudieh, Guanghao Luo, Pulkit Agrawal, Dian Chen, Yide Shentu, Evan Shelhamer, Jitendra Malik, Alexei A Efros, and Trevor Darrell. Zero-shot visual imitation. In Proceedings of the IEEE conference on computer vision and pattern recognition workshops , pages 2050–2053, 2018.
Peebles and Xie (2023) William Peebles and Saining Xie. Scalable diffusion models with transformers. In Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV) , pages 4195–4205, 2023.
Polyak et al. (2024) Adam Polyak, Amit Zohar, Andrew Brown, Andros Tjandra, Animesh Sinha, Ann Lee, Apoorv Vyas, Bowen Shi, Chih-Yao Ma, Ching-Yao Chuang, et al. Movie gen: A cast of media foundation models. arXiv preprint arXiv:2410.13720 , 2024.
(46) Ben Poole, Ajay Jain, Jonathan T Barron, and Ben Mildenhall. Dreamfusion: Text-to-3d using 2d diffusion. In The Eleventh International Conference on Learning Representations .
Ronneberger et al. (2015) Olaf Ronneberger, Philipp Fischer, and Thomas Brox. U-net: Convolutional networks for biomedical image segmentation. In Medical image computing and computer-assisted intervention–MICCAI 2015: 18th international conference, Munich, Germany, October 5-9, 2015, proceedings, part III 18 , pages 234–241. Springer, 2015.
Rubinstein (1997) Reuven Y Rubinstein. Optimization of computer simulation models with rare events. European Journal of Operational Research , 99(1):89–112, 1997.
Savva et al. (2019) Manolis Savva, Abhishek Kadian, Oleksandr Maksymets, Yili Zhao, Erik Wijmans, Bhavana Jain, Julian Straub, Jia Liu, Vladlen Koltun, Jitendra Malik, et al. Habitat: A platform for embodied ai research. In Proceedings of the IEEE/CVF international conference on computer vision , pages 9339–9347, 2019.
Seo et al. (2023) Younggyo Seo, Danijar Hafner, Hao Liu, Fangchen Liu, Stephen James, Kimin Lee, and Pieter Abbeel. Masked world models for visual control. In Conference on Robot Learning , pages 1332–1344. PMLR, 2023.
(51) Dhruv Shah, Ajay Sridhar, Nitish Dashora, Kyle Stachowicz, Kevin Black, Noriaki Hirose, and Sergey Levine. Vint: A foundation model for visual navigation. In 7th Annual Conference on Robot Learning .
Shah et al. (2021) Dhruv Shah, Benjamin Eysenbach, Gregory Kahn, Nicholas Rhinehart, and Sergey Levine. Rapid exploration for open-world navigation with latent goal models. arXiv preprint arXiv:2104.05859 , 2021.
Shah et al. (2023) Dhruv Shah, Ajay Sridhar, Arjun Bhorkar, Noriaki Hirose, and Sergey Levine. Gnm: A general navigation model to drive any robot. In 2023 IEEE International Conference on Robotics and Automation (ICRA) , pages 7226–7233. IEEE, 2023.
Sohl-Dickstein et al. (2015) Jascha Sohl-Dickstein, Eric Weiss, Niru Maheswaranathan, and Surya Ganguli. Deep unsupervised learning using nonequilibrium thermodynamics. In International conference on machine learning , pages 2256–2265. PMLR, 2015.
Sridhar et al. (2024) Ajay Sridhar, Dhruv Shah, Catherine Glossop, and Sergey Levine. Nomad: Goal masked diffusion policies for navigation and exploration. In 2024 IEEE International Conference on Robotics and Automation (ICRA) , pages 63–70. IEEE, 2024.
Srivastava et al. (2017) Akash Srivastava, Lazar Valkov, Chris Russell, Michael U Gutmann, and Charles Sutton. Veegan: Reducing mode collapse in gans using implicit variational learning. Advances in neural information processing systems , 30, 2017.
Sturm et al. (2012) Jürgen Sturm, Wolfram Burgard, and Daniel Cremers. Evaluating egomotion and structure-from-motion approaches using the tum rgb-d benchmark. In Proc. of the Workshop on Color-Depth Camera Fusion in Robotics at the IEEE/RJS International Conference on Intelligent Robot Systems (IROS) , page 6, 2012.
Thanh-Tung and Tran (2020) Hoang Thanh-Tung and Truyen Tran. Catastrophic forgetting and mode collapse in gans. In 2020 international joint conference on neural networks (ijcnn) , pages 1–10. IEEE, 2020.
Tomar et al. (2024) Manan Tomar, Philippe Hansen-Estruch, Philip Bachman, Alex Lamb, John Langford, Matthew E. Taylor, and Sergey Levine. Video occupancy models, 2024.
Triest et al. (2022) Samuel Triest, Matthew Sivaprakasam, Sean J Wang, Wenshan Wang, Aaron M Johnson, and Sebastian Scherer. Tartandrive: A large-scale dataset for learning off-road dynamics models. In 2022 International Conference on Robotics and Automation (ICRA) , pages 2546–2552. IEEE, 2022.
Tulyakov et al. (2018a) Sergey Tulyakov, Ming-Yu Liu, Xiaodong Yang, and Jan Kautz. MoCoGAN: Decomposing motion and content for video generation. In IEEE Conference on Computer Vision and Pattern Recognition (CVPR) , pages 1526–1535, 2018a.
Tulyakov et al. (2018b) Sergey Tulyakov, Ming-Yu Liu, Xiaodong Yang, and Jan Kautz. Mocogan: Decomposing motion and content for video generation. In Proceedings of the IEEE conference on computer vision and pattern recognition , pages 1526–1535, 2018b.
Tung et al. (2025) Joseph Tung, Gene Chou, Ruojin Cai, Guandao Yang, Kai Zhang, Gordon Wetzstein, Bharath Hariharan, and Noah Snavely. Megascenes: Scene-level view synthesis at scale. In Computer Vision – ECCV 2024 , pages 197–214, Cham, 2025. Springer Nature Switzerland.
Unterthiner et al. (2019) Thomas Unterthiner, Sjoerd van Steenkiste, Karol Kurach, Raphaël Marinier, Marcin Michalski, and Sylvain Gelly. Fvd: A new metric for video generation. 2019.
Uria et al. (2022) Benigno Uria, Borja Ibarz, Andrea Banino, Vinicius Zambaldi, Dharshan Kumaran, Demis Hassabis, Caswell Barry, and Charles Blundell. A model of egocentric to allocentric understanding in mammalian brains. bioRxiv , 2022.
Valevski et al. (2024) Dani Valevski, Yaniv Leviathan, Moab Arar, and Shlomi Fruchter. Diffusion models are real-time game engines. arXiv preprint arXiv:2408.14837 , 2024.
Van Hoorick et al. (2024) Basile Van Hoorick, Rundi Wu, Ege Ozguroglu, Kyle Sargent, Ruoshi Liu, Pavel Tokmakov, Achal Dave, Changxi Zheng, and Carl Vondrick. Generative camera dolly: Extreme monocular dynamic novel view synthesis. 2024.
Vaswani (2017) A Vaswani. Attention is all you need. Advances in Neural Information Processing Systems , 2017.
Voleti et al. (2022) Vikram Voleti, Alexia Jolicoeur-Martineau, and Chris Pal. Mcvd-masked conditional video diffusion for prediction, generation, and interpolation. Advances in neural information processing systems , 35:23371–23385, 2022.
Wang et al. (2024) Fu-Yun Wang, Zhaoyang Huang, Alexander Bergman, Dazhong Shen, Peng Gao, Michael Lingelbach, Keqiang Sun, Weikang Bian, Guanglu Song, Yu Liu, et al. Phased consistency models. Advances in Neural Information Processing Systems , 37:83951–84009, 2024.
Wu et al. (2023) Philipp Wu, Alejandro Escontrela, Danijar Hafner, Pieter Abbeel, and Ken Goldberg. Daydreamer: World models for physical robot learning. In Conference on robot learning , pages 2226–2240. PMLR, 2023.
Xu et al. (2019) Jingjing Xu, Xu Sun, Zhiyuan Zhang, Guangxiang Zhao, and Junyang Lin. Understanding and improving layer normalization, 2019.
(73) Sherry Yang, Yilun Du, Seyed Kamyar Seyed Ghasemipour, Jonathan Tompson, Leslie Pack Kaelbling, Dale Schuurmans, and Pieter Abbeel. Learning interactive real-world simulators. In The Twelfth International Conference on Learning Representations .
Yu et al. (2023) Lijun Yu, Yong Cheng, Kihyuk Sohn, José Lezama, Han Zhang, Huiwen Chang, Alexander G Hauptmann, Ming-Hsuan Yang, Yuan Hao, Irfan Essa, et al. Magvit: Masked generative video transformer. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition , pages 10459–10469, 2023.
Zhang et al. (2018a) Richard Zhang, Phillip Isola, Alexei A Efros, Eli Shechtman, and Oliver Wang. The unreasonable effectiveness of deep features as a perceptual metric. In CVPR , 2018a.
Zhang et al. (2018b) Richard Zhang, Phillip Isola, Alexei A Efros, Eli Shechtman, and Oliver Wang. The unreasonable effectiveness of deep features as a perceptual metric. In Proceedings of the IEEE conference on computer vision and pattern recognition , pages 586–595, 2018b.
Zhou et al. (2024) Gaoyue Zhou, Hengkai Pan, Yann LeCun, and Lerrel Pinto. Dino-wm: World models on pre-trained visual features enable zero-shot planning, 2024.
7 Standalone Planning Optimization
7 独立规划优化
As described in Section 3.3, we use a pretrained NWM to standalone-plan goal-conditioned navigation trajectories by optimizing Eq.5. Here, we provide additional details about the optimization using the Cross-Entropy Method (Rubinstein 1997) and the hyperparameters used. Full standalone navigation planning results are presented in Section 8.2.
如 3.3 节所述,我们用预训练 NWM 通过优化式 5 独立规划目标条件导航轨迹。这里补充交叉熵方法(Rubinstein 1997)的优化细节与超参。完整独立导航规划结果见 8.2 节。
We optimize trajectories using the Cross-Entropy Method, a gradient-free stochastic optimization technique for continuous optimization problems. This method iteratively updates a probability distribution to improve the likelihood of generating better solutions. In the unconstrained standalone planning scenario, we assume the trajectory is a straight line and optimize only its endpoint, represented by three variables: a single translation and yaw rotation . We then map this tuple into eight evenly spaced delta steps, applying the yaw rotation at the final step. The time interval between steps is fixed at seconds. The main steps of our optimization process are as follows:
我们用交叉熵方法优化轨迹:这是面向连续优化问题的无梯度随机优化技术,迭代更新概率分布以提高生成更优解的似然。无约束独立规划中,假设轨迹为直线,只优化终点,用三个变量表示:单一平移 与偏航 。再把该元组映射为八个均匀间隔的增量步,并在最后一步施加偏航。步间时间固定为 秒。主要步骤如下:
- • Initialization: Define a Gaussian distribution with mean and variance over the solution space.
- • 初始化:在解空间上定义高斯分布,均值 ,方差 。
- • Sampling: Generate candidate solutions by sampling from the current Gaussian distribution.
- • 采样:从当前高斯分布采样 个候选解。
- • Evaluation: Evaluate each candidate solution by simulating it using the NWM and measuring the LPIPS score between the simulation output and input goal images. Since NWM is stochastic, we evaluate each candidate solution times and average to obtain a final score.
- • 评估:用 NWM 仿真每个候选,测量仿真输出与输入目标图的 LPIPS。因 NWM 随机,每个候选评估 次并取平均得最终分数。
- • Selection: Select a subset of the best-performing solutions based on the LPIPS scores.
- • 选择:按 LPIPS 选出表现最好的子集。
- • Update: Adjust the parameters of the distribution to increase the probability of generating solutions similar to the top-performing ones. This step minimizes the cross-entropy between the old and updated distributions.
- • 更新:调整分布参数,提高生成与顶尖解相似的解的概率。该步最小化旧分布与更新分布之间的交叉熵。
- • Iteration: Repeat the sampling, evaluation, selection, and update steps until a stopping criterion (e.g. convergence or iteration limit) is met.
- • 迭代:重复采样、评估、选择与更新,直到满足停止准则(如收敛或达到迭代上限)。
For simplicity, we run the optimization process for a single iteration, which we found effective for short-horizon planning of two seconds, though further improvements are possible with more iterations. When navigation constraints are applied, parts of the trajectory are zeroed out to respect these constraints. For instance, in the ”forward-first” scenario, the translation action is for the first five steps and for the last three steps.
为简化,我们只跑一轮优化——对两秒短时程规划已足够有效,更多迭代仍有提升空间。施加导航约束时,轨迹相应部分置零。例如「先前进」情形下,前五步平移为 ,后三步为 。
| unknown environment | known environments | ||||
|---|---|---|---|---|---|
| data | Go Stanford | RECON | HuRoN | SCAND | TartanDrive |
| in-domain data | |||||
| + Ego4D (unlabeled) |
Table 5: Training on additional unlabeled data improves performance on unseen environments. Reporting results on unknown environment (Go Stanford) and known one (RECON). Results reported by evaluating LPIPS seconds into the future.
| 未知环境 | 已知环境 | ||||
|---|---|---|---|---|---|
| 数据 | Go Stanford | RECON | HuRoN | SCAND | TartanDrive |
| 域内数据 | |||||
| + Ego4D(无标注) |
表 5:额外无标注数据可提升未见环境表现。 在未知环境(Go Stanford)与已知环境(RECON)上报告未来 4 秒 LPIPS。
8 Experiments and Results
8 实验与结果
8.1 Experimental Study
8.1 实验研究
We elaborate on the metrics and datasets used.
我们详述所用指标与数据集。
Evaluation Metrics. We describe the evaluation metrics used to assess predicted navigation trajectories and the quality of images generated by our NWM.
评测指标。 下面说明用于评估预测导航轨迹与 NWM 生成图像质量的指标。
For visual navigation performance, Absolute Trajectory Error (ATE) measures the overall accuracy of trajectory estimation by computing the Euclidean distance between corresponding points in the estimated and ground-truth trajectories. Relative Pose Error (RPE) evaluates the consistency of consecutive poses by calculating the error in relative transformations between them (Sturm et al. 2012).
视觉导航方面,绝对轨迹误差(ATE)通过估计轨迹与真值轨迹对应点的欧氏距离衡量整体精度;相对位姿误差(RPE)计算连续位姿间相对变换误差,衡量一致性(Sturm et al. 2012)。
To more rigorously assess the semantics in the world model outputs, we use Learned Perceptual Image Patch Similarity (LPIPS) and DreamSim (Fu et al. 2024), which evaluate perceptual similarity by comparing deep features from a neural network (Zhang et al. 2018a). LPIPS, in particular, uses AlexNet (Krizhevsky et al. 2012) to focus on human perception of structural differences. Additionally, we use Peak Signal-to-Noise Ratio (PSNR) to quantify the pixel-level quality of generated images by measuring the ratio of maximum pixel value to error, with higher values indicating better quality.
为更严格评估世界模型输出的语义,使用学习感知图像块相似度(LPIPS)与 DreamSim(Fu et al. 2024):二者比较神经网络深层特征的感知相似度(Zhang et al. 2018a)。LPIPS 尤其借助 AlexNet(Krizhevsky et al. 2012)关注人对结构差异的感知。另用峰值信噪比(PSNR)以最大像素值与误差之比量化生成图的像素级质量,越高越好。
To study image and video synthesis quality, we use Fréchet Inception Distance (FID) and Fréchet Video Distance (FVD), which compare the feature distributions of real and generated images or videos. Lower FID and FVD scores indicate higher visual quality (Heusel et al. 2017; Unterthiner et al. 2019).
图像与视频合成质量用 Fréchet Inception Distance(FID)与 Fréchet Video Distance(FVD),比较真实与生成图像/视频的特征分布。FID、FVD 越低,视觉质量越高(Heusel et al. 2017;Unterthiner et al. 2019)。
Datasets. For all robotics datasets, we have access to the location and rotation of the robots, and we use this to infer the actions as the delta in location and rotation. We remove all backward movement which can be jittery following NoMaD (Sridhar et al. 2024), thereby splitting the data to forward walking segments for SCAND (Karnan et al. 2022), TartanDrive (Triest et al. 2022), RECON (Shah et al. 2021), and HuRoN (Hirose et al. 2023). We also utilize unlabeled Ego4D videos, where we only use time shift as action. Next, we describe each individual dataset.
数据集。 对所有机器人数据集,我们有位置与旋转,据此用位置与旋转增量推断动作。按 NoMaD(Sridhar et al. 2024)去掉可能抖动的后退运动,从而把 SCAND(Karnan et al. 2022)、TartanDrive(Triest et al. 2022)、RECON(Shah et al. 2021)、HuRoN(Hirose et al. 2023)切成向前行走片段。另用无标注 Ego4D 视频,仅以时间偏移为动作。各数据集如下。
- • SCAND (Karnan et al. 2022) is a robotics dataset consisting of socially compliant navigation demonstrations using a wheeled Clearpath Jackal and a legged Boston Dynamics Spot. SCAND has demonstrations in both indoor and outdoor settings at UT Austin. The dataset consists of hours, trajectories, miles of data and we use the corresponding camera poses. We use video segments for training and video segments for testing. Used for training and evaluation.
- • SCAND(Karnan et al. 2022)是社会合规导航演示数据集,使用轮式 Clearpath Jackal 与腿式 Boston Dynamics Spot,覆盖 UT Austin 室内外场景。约 小时、 条轨迹、 英里,并提供对应相机位姿。训练用 段视频,测试 段。用于训练与评测。
- • TartanDrive (Triest et al. 2022) is an outdoor off-roading driving dataset collected using a modified Yamaha Viking ATV in Pittsburgh. The dataset consists of hours and trajectories. We use video segments for training and video segments for testing.
- • TartanDrive(Triest et al. 2022)是匹兹堡用改装 Yamaha Viking ATV 采集的户外越野驾驶数据,约 小时、 条轨迹。训练 段,测试 段。
- • RECON (Shah et al. 2021) is an outdoor robotics dataset collected using a Clearpath Jackal UGV platform. The dataset consists of hours across open-world environments. We use video segments for training and video segments for testing. Used for training and evaluation.
- • RECON(Shah et al. 2021)是 Clearpath Jackal UGV 采集的户外机器人数据,跨 个开放世界环境约 小时。训练 段,测试 段。用于训练与评测。
- • HuRoN (Hirose et al. 2023) is a robotics dataset consisting of social interactions using a Robot Roomba in indoor settings collected at UC Berkeley. The dataset consists of over hours in different environments with human interactions. We use video segments for training and video segments for testing. Used for training and evaluation.
- • HuRoN(Hirose et al. 2023)是 UC Berkeley 室内用 Robot Roomba 采集的社交互动数据,超 小时、覆盖 个环境与 次人机交互。训练 段,测试 段。用于训练与评测。
- • GO Stanford (Hirose et al. 2018; Hirose et al. 2019a), a robotics datasets capturing the fisheye video footage of two different teleoperated robots, collected at at least different Stanford building with around hours of video footage. Due to the low resolution images, we only use it for out of domain evaluation.
- • GO Stanford(Hirose et al. 2018;Hirose et al. 2019a)记录至少 栋斯坦福建筑中两台遥操作机器人的鱼眼视频,约 小时。因分辨率较低,仅作域外评测。
- • Ego4D (Grauman et al. 2022) is a large-scale egocentric dataset consisting of hours across locations. Ego4D consists a variety of scenarios such as Arts Crafts, Cooking, Construction, Cleaning Laundry, and Grocery Shopping. We use only use videos which involve visual navigation such as Grocery Shopping and Jogging. We use a total videos of over hours for training only. Only used for unlabeled training unlabeled training. The videos we use are from the following Ego4D scenarios: “Skateboard/scooter”, “Roller skating”, “Football”, “Attending a festival or fair”, “Gardener”, “Mini golf”, “Riding motorcycle”, “Golfing”, “Cycling/jogging”, “Walking on street”, “Walking the dog/pet”, “Indoor Navigation (walking)”, “Working in outdoor store”, “Clothes/other shopping”, “Playing with pets”, “Grocery shopping indoors”, “Working out outside”, “Farmer”, “Bike”, “Flower Picking”, “Attending sporting events (watching and participating)”, “Drone flying”, “Attending a lecture/class”, “Hiking”, “Basketball”, “Gardening”, “Snow sledding”, “Going to the park”.
- • Ego4D(Grauman et al. 2022)是大规模第一人称数据集,跨 处地点约 小时,场景涵盖手工艺、烹饪、建筑、清洁洗衣、杂货购物等。我们只取涉及视觉导航的视频,如杂货购物与慢跑,共 段、逾 小时,仅用于无标注训练。所用场景包括:滑板/滑板车、轮滑、足球、参加节庆、园艺工、迷你高尔夫、骑摩托、高尔夫、骑行/慢跑、街上行走、遛狗、室内导航(步行)、户外商店工作、买衣物等、与宠物玩耍、室内杂货购物、户外锻炼、农事、骑车、采花、观看或参与体育赛事、无人机飞行、听课、徒步、篮球、园艺、雪橇、去公园。
Visual Navigation Evaluation Set. Our main finding when constructing visual navigation evaluation sets is that forward motion is highly prevalent, and if not carefully accounted for, it can dominate the evaluation data. To create diverse evaluation sets, we rank potential evaluation trajectories based on how well they can be predicted by simply moving forward. For each dataset, we select the examples that are least predictable by this heuristic and use them for evaluation.
视觉导航评测集。 构建评测集时的主要发现是:前进运动极为常见,若不仔细控制会主导评测数据。为得到多样评测集,我们按「仅靠前进能否预测」给候选轨迹打分,每个数据集取该启发式最难预测的 例作评测。
Time Prediction Evaluation Set. Predicting the future frame after seconds is more challenging than estimating a trajectory, as it requires both predicting the agent’s trajectory and its orientation in pixel space. Therefore, we do not impose additional diversity constraints. For each dataset, we randomly select test prediction examples.
时间预测评测集。 预测 秒后的未来帧比估计轨迹更难:既要预测智能体轨迹,也要在像素空间预测朝向。因此不再额外施加多样性约束。每个数据集随机选 个测试预测样例。
8.2 Experiments and Results
8.2 实验与结果
Training on Additional Unlabeled Data. We include results for additional known environments in Table 5 and Figure 11. We find that in known environments, models trained exclusively with in-domain data tend to perform better, likely because they are better tailored to the in-domain distribution. The only exception is the SCAND dataset, where dynamic objects (e.g. humans walking) are present. In this case, adding unlabeled data may help improve performance by providing additional diverse examples.
在额外无标注数据上训练。 表 5 与图 11 给出更多已知环境结果。我们发现:在已知环境中,仅用域内数据训练的模型通常更好,可能因为更贴合域内分布。唯一例外是 SCAND:存在行人等动态物体时,加入无标注数据或可凭更多样例提升表现。
Known Environments. We include additional visualization results of following trajectories using NWM in the known environments RECON (Figure 12), SCAND (Figure 13), HuRoN (Figure 14), and Tartan Drive (Figure 15). Additionally, we include full FVD comparison of DIAMOND and NWM in Table 6.
已知环境。 补充在已知环境中用 NWM 跟随轨迹的可视化:RECON(图 12)、SCAND(图 13)、HuRoN(图 14)、Tartan Drive(图 15)。DIAMOND 与 NWM 的完整 FVD 对比见表 6。
| dataset | DIAMOND | NWM (ours) |
|---|---|---|
| RECON | ||
| HuRoN | ||
| TartanDrive | ||
| SCAND |
Table 6: Comparison of Video Synthesis Quality. second videos generated at 4 FPS, reporting FVD (lower is better).
| 数据集 | DIAMOND | NWM(本文) |
|---|---|---|
| RECON | ||
| HuRoN | ||
| TartanDrive | ||
| SCAND |
表 6:视频合成质量对比。 以 4 FPS 生成 16 秒视频,报告 FVD(越低越好)。
| model | RECON | HuRoN | Tartan | SCAND | ||||
|---|---|---|---|---|---|---|---|---|
| ATE | RTE | ATE | RTE | ATE | RTE | ATE | RTE | |
| Forward | ||||||||
| GNM | ||||||||
| NoMaD | ||||||||
| NWM + NoMaD () | ||||||||
| NWM + NoMaD () | 1.79 | 3.68 | 0.95 | |||||
| NWM (only) | 1.13 | 0.35 | 5.63 | 1.18 | 1.28 | 0.33 |
Table 7: Goal Conditioned Visual Navigation. ATE and RPE results on on all in domain datasets, predicting trajectories of up to seconds. NWM achieves improved results on all metrics compared to previous approaches NoMaD (Sridhar et al. 2024) and GNM (Shah et al. 2023).
| 模型 | RECON | HuRoN | Tartan | SCAND | ||||
|---|---|---|---|---|---|---|---|---|
| ATE | RTE | ATE | RTE | ATE | RTE | ATE | RTE | |
| Forward | ||||||||
| GNM | ||||||||
| NoMaD | ||||||||
| NWM + NoMaD () | ||||||||
| NWM + NoMaD () | 1.79 | 3.68 | 0.95 | |||||
| NWM(仅) | 1.13 | 0.35 | 5.63 | 1.18 | 1.28 | 0.33 |
表 7:目标条件视觉导航。 全部域内数据集上预测最长 2 秒轨迹的 ATE 与 RPE。相对 NoMaD(Sridhar et al. 2024)与 GNM(Shah et al. 2023),NWM 在各项指标上均更优。
Planning (Ranking). Full goal-conditioned navigation results for all in-domain datasets are presented in Table 7. Compared to NoMaD, we observe consistent improvements when using NWM to select from a pool of trajectories, with further gains when selecting from a larger pool of . For Tartan Drive, we note that the dataset is heavily dominated by forward motion, as reflected in the results compared to the ”Forward” baseline, a prediction model that always selects forward-only motion.
规划(排序)。 全部域内数据集的完整目标条件导航结果见表 7。相对 NoMaD,用 NWM 从 条轨迹中挑选可稳定提升,从更大的 条池中挑选还能再涨。对 Tartan Drive,数据高度被前进运动主导,结果相对「Forward」基线(始终只预测前进)亦可看出这一点。
Standalone Planning. For standalone planning, we run the optimization procedure outlined in Section 7 for step, and evaluate each trajectories for 3 times. For all datasets, we initialize and to be 0, and and to be 0.1. We use different across each dataset: for RECON, for TartanDrive, for SCAND, and for HuRoN. We include the full standalone navigation planning results in Table 7. We find that using planning in the stand-alone setting performs better compared to other approaches, and specifically previous hard-coded policies.
独立规划。 独立规划按第 7 节流程跑 步,每条轨迹评估 3 次。各数据集将 、 初始化为 0,、 为 0.1;不同数据集用不同 :RECON 为 ,TartanDrive 为 ,SCAND 为 ,HuRoN 为 。完整独立导航规划结果见表 7。独立规划整体优于其他方法,尤其优于既往硬编码策略。
Real-World Applicability. A key bottleneck in deploying NWM in real-world robotics is inference speed. We evaluate methods to improve NWM efficiency and measure their impact on runtime. We focus on using NWM with a generative policy (Section 3.3) to rank four-second trajectories. Since trajectory evaluation is parallelizable, we analyze the runtime of simulating a single trajectory. We find that existing solutions can already enable real-time applications of NWM at 2-10HZ (Table 8).
现实可用性。 把 NWM 部署到真实机器人上的关键瓶颈是推理速度。我们评测若干加速手段及其对运行时的影响,重点看用生成式策略(3.3 节)对 条四秒轨迹排序。轨迹评估可并行,故分析仿真单条轨迹的耗时。已有方案已能让 NWM 以 2–10 Hz 用于实时应用(表 8)。
| NWM | +Time Skip | +Distillation. | +Quant. 4-bit |
|---|---|---|---|
| (est. Frantar et al. 2022) |
Table 8: Runtime (seconds) on an NVIDIA RTX 6000 Ada card.
| NWM | +时间跳跃 | +蒸馏 | +4-bit 量化 |
|---|---|---|---|
| (估计,Frantar et al. 2022) |
表 8:NVIDIA RTX 6000 Ada 上的运行时(秒)。
Inference time can be accelerated by composing every adjacent pair of actions (via Eq. 2) then simulating only future states instead of (“Time Skip”), which does not degrade navigation performance. Reducing the diffusion denoising steps from to by model distillation Wang et al. 2024 further speeds up inference with minor visual quality loss.[^3] Taken together, these two ideas can enable NWM to run in real time. Quantization to 4-bit, which we haven’t explored, can lead to a speedup without performance hit Frantar et al. 2022.
推理可通过按式 2 合并相邻动作对、只仿真 个而非 个未来状态(「时间跳跃」)加速,且不损害导航表现。再用模型蒸馏(Wang et al. 2024)把扩散去噪步从 降到 ,可进一步加速,视觉质量仅略降。[^3] 两者合用可使 NWM 接近实时。尚未探索的 4-bit 量化有望再带来约 加速且几乎无损(Frantar et al. 2022)。
Test-time adaptation. Test-time adaptation has shown to improve visual navigation Frey et al. 2023; Gao et al. 2024. What is the relation between planning using a world model and test-time adaptation? We hypothesize that the two ideas are orthogonal, and include test-time adaptation results. We consider a simplified adaptation approach by fine-tuning NWM for k steps on trajectories from an unknown environment. We show that this adaptation improves trajectory simulation in this environment (see “ours+TTA” in Table 9), where we also include additional baselines and ablations.
测试时适应。 测试时适应已被证明有助于视觉导航(Frey et al. 2023;Gao et al. 2024)。用世界模型规划与测试时适应是何关系?我们假设二者正交,并给出测试时适应结果:在未知环境轨迹上对 NWM 微调 k 步的简化适应方案。表 9 中「ours+TTA」显示该适应可改善该环境中的轨迹仿真;表中亦含额外基线与消融。
| CDiT-L | context 2 | action only | goals 2 | ours | ours + TTA |
|---|---|---|---|---|---|
| 0.650 |
Table 9: Results in unknown environment (“Go Stanford”). Reporting lpips on seconds future prediction. Lower is better.
| CDiT-L | 上下文 2 | 仅动作 | 目标 2 | 本文 | 本文 + TTA |
|---|---|---|---|---|---|
| 0.650 |
表 9:未知环境(Go Stanford)结果。报告未来 4 秒预测的 lpips,越低越好。
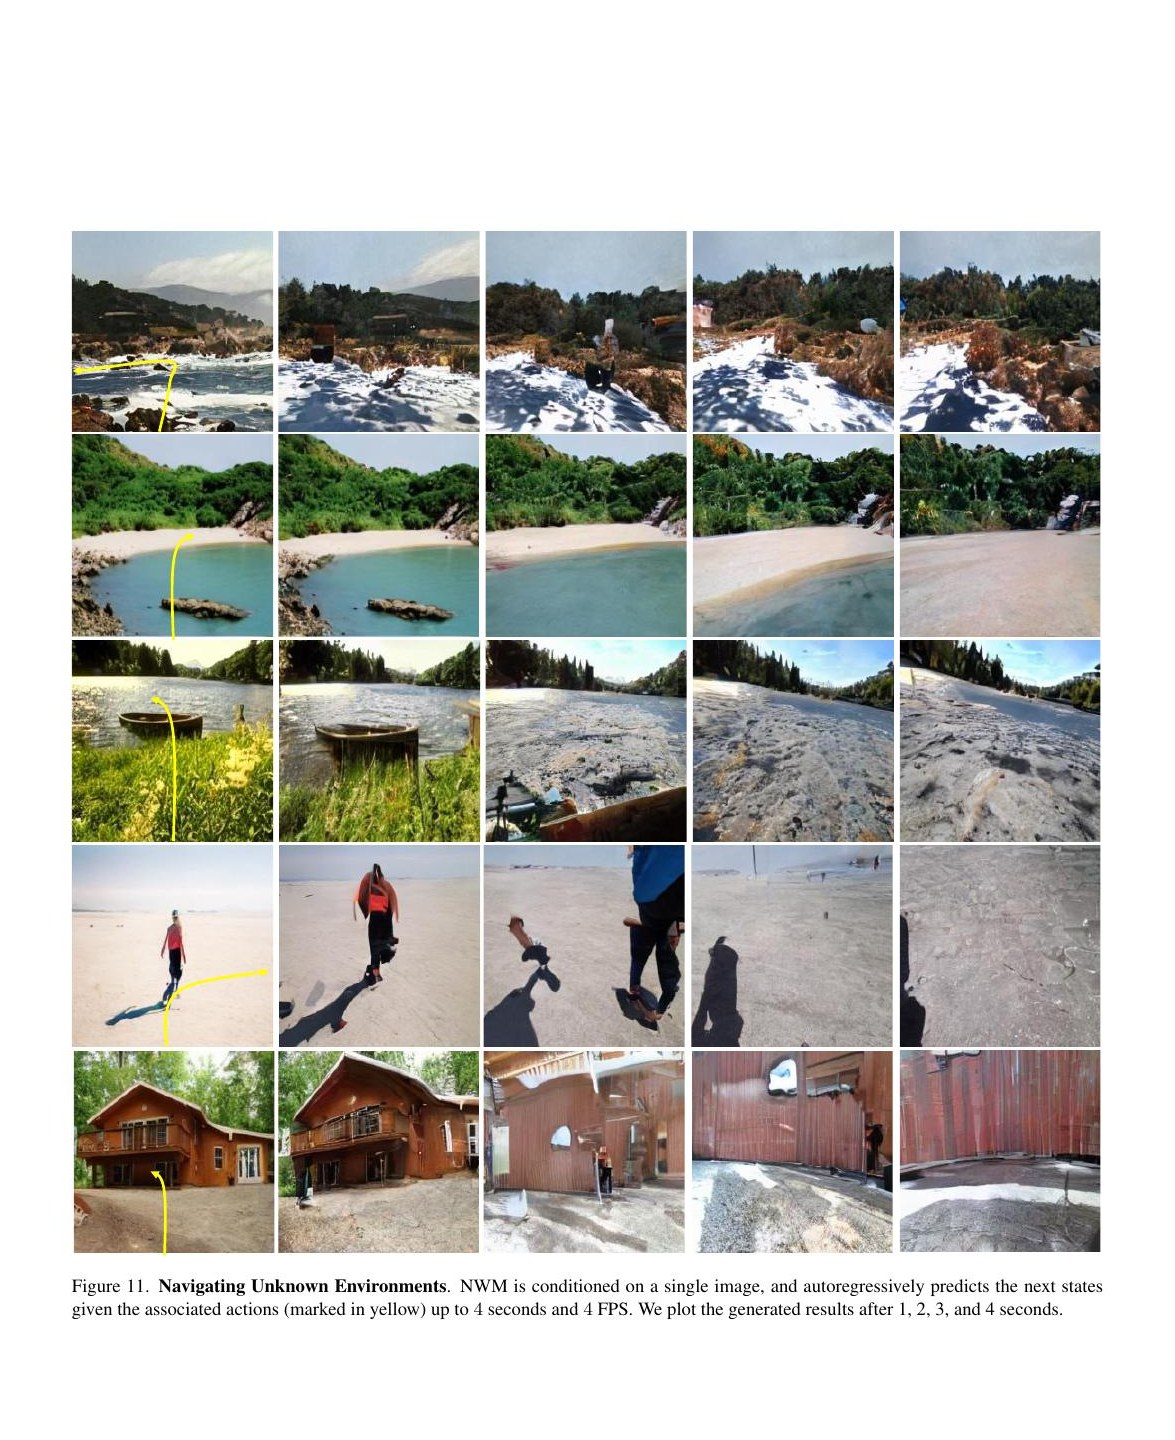
Figure 11: Navigating Unknown Environments. NWM is conditioned on a single image, and autoregressively predicts the next states given the associated actions (marked in yellow) up to seconds and FPS. We plot the generated results after 1, 2, 3, and 4 seconds.
图 11:在未知环境中导航。 NWM 以单张图像为条件,按给定动作(黄标)以 4 FPS 自回归预测最长 4 秒。绘制 1、2、3、4 秒处的生成结果。
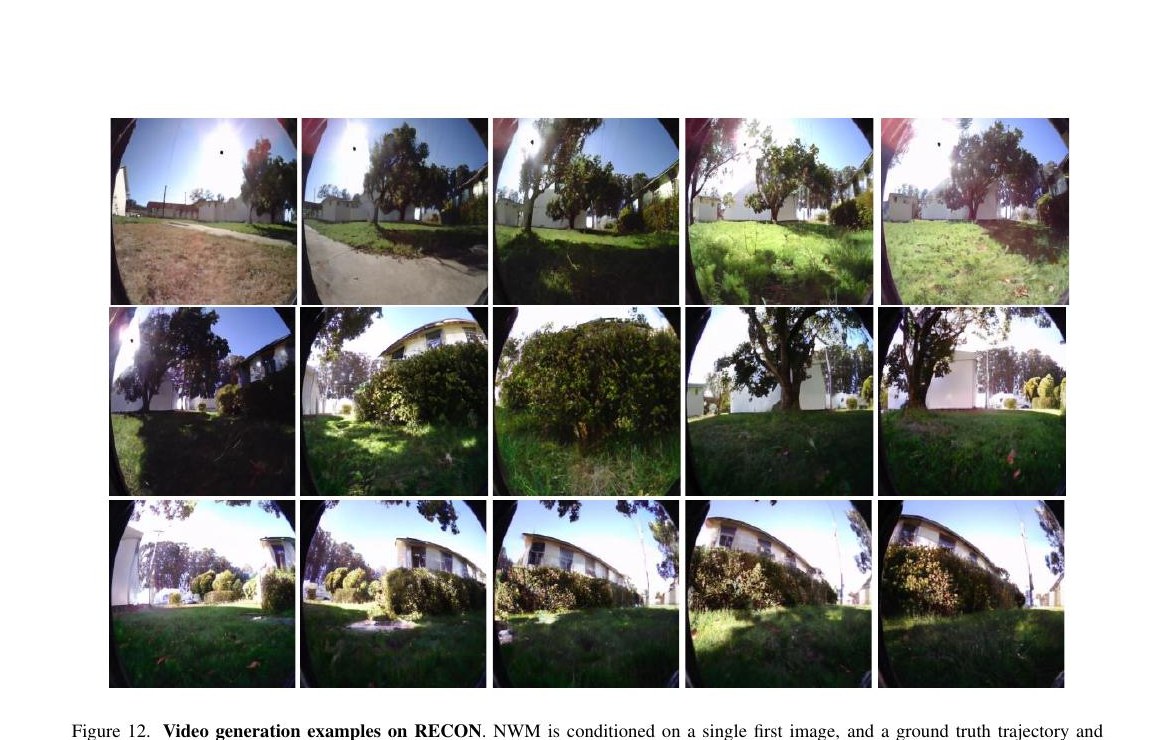
Figure 12: Video generation examples on RECON. NWM is conditioned on a single first image, and a ground truth trajectory and autoregressively predicts the next up to seconds at FPS. We plot the generated results from to seconds, every 1 second.
图 12:RECON 上的视频生成样例。 NWM 以首帧与真值轨迹为条件,以 4 FPS 自回归预测最长 16 秒。绘制 2 到 16 秒、每隔 1 秒的生成结果。
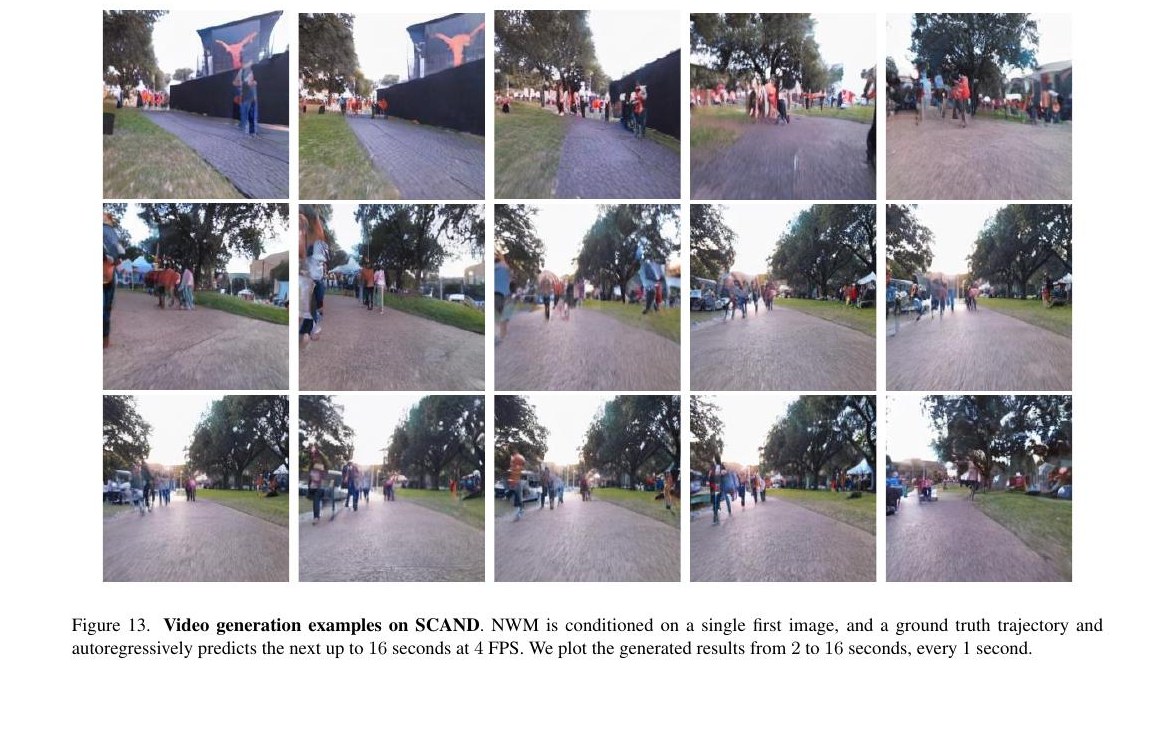
Figure 13: Video generation examples on SCAND. NWM is conditioned on a single first image, and a ground truth trajectory and autoregressively predicts the next up to seconds at FPS. We plot the generated results from to seconds, every 1 second.
图 13:SCAND 上的视频生成样例。 NWM 以首帧与真值轨迹为条件,以 4 FPS 自回归预测最长 16 秒。绘制 2 到 16 秒、每隔 1 秒的生成结果。
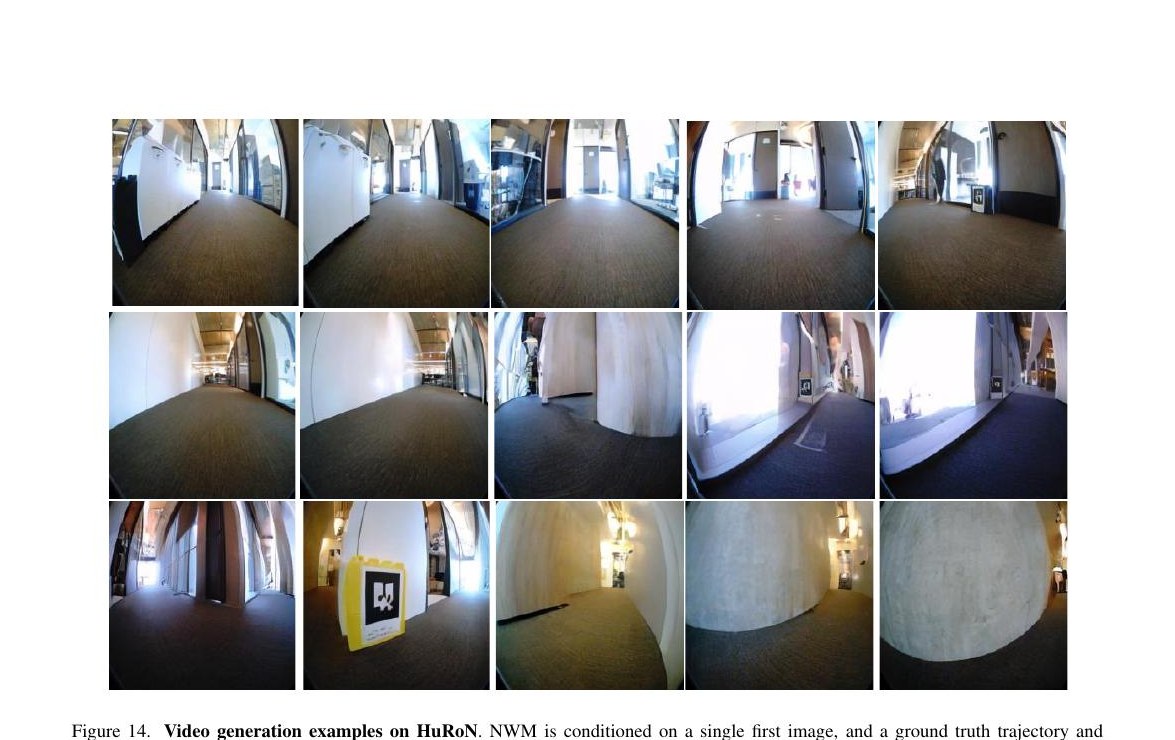
Figure 14: Video generation examples on HuRoN. NWM is conditioned on a single first image, and a ground truth trajectory and autoregressively predicts the next up to seconds at FPS. We plot the generated results from to seconds, every 1 second.
图 14:HuRoN 上的视频生成样例。 NWM 以首帧与真值轨迹为条件,以 4 FPS 自回归预测最长 16 秒。绘制 2 到 16 秒、每隔 1 秒的生成结果。
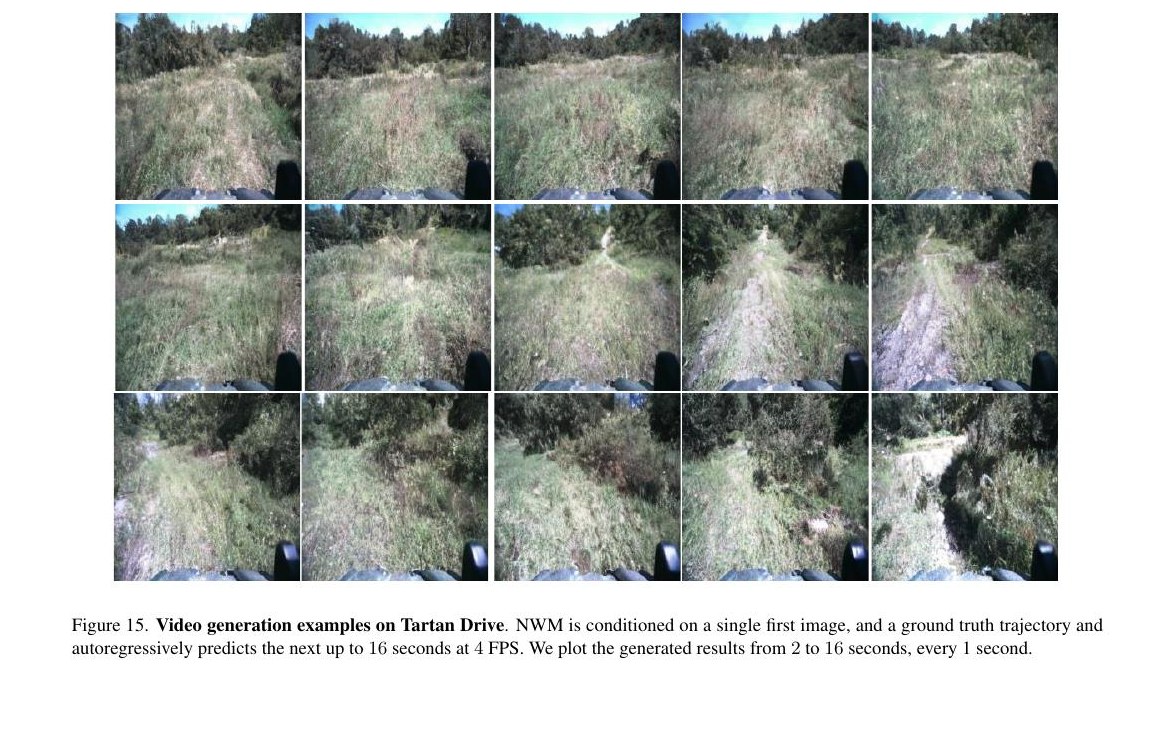
Figure 15: Video generation examples on Tartan Drive. NWM is conditioned on a single first image, and a ground truth trajectory and autoregressively predicts the next up to seconds at FPS. We plot the generated results from to seconds, every 1 second.
图 15:Tartan Drive 上的视频生成样例。 NWM 以首帧与真值轨迹为条件,以 4 FPS 自回归预测最长 16 秒。绘制 2 到 16 秒、每隔 1 秒的生成结果。