Native Sparse Attention: Hardware-Aligned and Natively Trainable Sparse Attention
001
Native Sparse Attention: Hardware-Aligned and Natively Trainable Sparse Attention
Native Sparse Attention:硬件对齐且原生可训练的稀疏注意力
Jingyang Yuan ∗1,2 , Huazuo Gao 1 , Damai Dai 1 , Junyu Luo 2 , Liang Zhao 1 , Zhengyan Zhang 1 , Zhenda Xie 1 , Y. X. Wei 1 , Lean Wang 1 , Zhiping Xiao 3 , Yuqing Wang 1 , Chong Ruan 1 , Ming Zhang 2 , Wenfeng Liang 1 , Wangding Zeng 1 1 DeepSeek-AI 2 Key Laboratory for Multimedia Information Processing, School of Computer Science, Peking University, PKU-Anker LLM Lab 3 University of Washington {yuanjy, mzhang_cs}@pku.edu.cn , {zengwangding, wenfeng.liang}@deepseek.com Corresponding author: Contribution during internship at DeepSeek-AI.
Abstract
摘要
Long-context modeling is crucial for next-generation language models, yet the high computational cost of standard attention mechanisms poses significant computational challenges. Sparse attention offers a promising direction for improving efficiency while maintaining model capabilities. We present NSA, a Natively trainable Sparse Attention mechanism that integrates algorithmic innovations with hardware-aligned optimizations to achieve efficient long-context modeling. NSA employs a dynamic hierarchical sparse strategy, combining coarse-grained token compression with fine-grained token selection to preserve both global context awareness and local precision. Our approach advances sparse attention design with two key innovations: (1) We achieve substantial speedups through arithmetic intensity-balanced algorithm design, with implementation optimizations for modern hardware. (2) We enable end-to-end training, reducing pretraining computation without sacrificing model performance. As shown in Figure 1, experiments show the model pretrained with NSA maintains or exceeds Full Attention models across general benchmarks, long-context tasks, and instruction-based reasoning. Meanwhile, NSA achieves substantial speedups over Full Attention on 64k-length sequences across decoding, forward propagation, and backward propagation, validating its efficiency throughout the model lifecycle.
长上下文建模对下一代语言模型至关重要,但标准注意力机制的高计算开销带来显著挑战。稀疏注意力在保持模型能力的同时提升效率,是一条有希望的方向。我们提出 NSA——一种原生可训练的稀疏注意力机制,将算法创新与硬件对齐优化结合,实现高效长上下文建模。NSA 采用动态分层稀疏策略,把粗粒度 token 压缩与细粒度 token 选择相结合,同时保留全局上下文感知与局部精度。本文在稀疏注意力设计上推进两点:(1)通过算术强度均衡的算法设计,并针对现代硬件做实现优化,获得可观加速;(2)支持端到端训练,在不牺牲模型性能的前提下降低预训练计算量。如图 1 所示,实验表明以 NSA 预训练的模型在通用基准、长上下文任务与基于指令的推理上达到或超过全注意力模型;同时在 64k 长度序列的解码、前向与反向传播上相对全注意力均有显著加速,验证了其在模型全生命周期中的效率。
1 Introduction
1 引言
Figure 1: Comparison of performance and efficiency between Full Attention model and our NSA. Left: Despite being sparse, NSA surpasses Full Attention baseline on average across general benchmarks, long-context tasks, and reasoning evaluation. Right: For 64k-length sequence processing, NSA achieves substantial computational speedup compared to Full Attention in all stages: decoding, forward propagation, and backward propagation.
图 1:全注意力模型与我们的 NSA 在性能与效率上的对比。左:尽管稀疏,NSA 在通用基准、长上下文任务与推理评测上的平均表现超过全注意力基线。右:在 64k 长度序列上,NSA 在解码、前向传播与反向传播各阶段相对全注意力均有显著计算加速。
The research community increasingly recognizes long-context modeling as a crucial capability for next-generation large language models, driven by diverse real-world applications ranging from in-depth reasoning (Zelikman et al., 2022; DeepSeek-AI, 2025), repository-level code generation (Zhang et al., 2023a; Zhang et al., ) and multi-turn autonomous agent systems (Park et al., 2023). Recent breakthroughs, including OpenAI’s o-series models, DeepSeek-R1 (DeepSeek-AI, 2025), and Gemini 1.5 Pro (Google et al., 2024), enabling models to process entire codebases, lengthy documents, maintain coherent multi-turn conversations over thousands of tokens, and perform complex reasoning across long-range dependencies. However, the high complexity (Zaheer et al., 2020) of vanilla Attention (Vaswani et al., 2017) mechanisms emerges as a critical latency bottleneck as sequence length increases. Theoretical estimates indicate that attention computation with softmax architectures accounts for 70–80% of total latency when decoding 64k-length contexts, underscoring the urgent need for more efficient attention mechanisms.
研究社区越来越把长上下文建模视为下一代大语言模型的关键能力,驱动因素包括深度推理(Zelikman et al., 2022; DeepSeek-AI, 2025)、仓库级代码生成(Zhang et al., 2023a; Zhang et al., )以及多轮自主智能体系统(Park et al., 2023)等现实应用。近期突破——OpenAI 的 o 系列、DeepSeek-R1(DeepSeek-AI, 2025)与 Gemini 1.5 Pro(Google et al., 2024)——使模型能够处理整库代码与长文档、在数千 token 上保持多轮连贯对话,并在长程依赖上做复杂推理。然而,随着序列变长,原始 Attention(Vaswani et al., 2017)的高复杂度(Zaheer et al., 2020)成为关键时延瓶颈。理论估计表明,解码 64k 上下文时,softmax 架构下的注意力计算约占总体时延的 70–80%,凸显了对更高效注意力机制的迫切需求。
A natural approach to efficient long-context modeling is to take advantage of the inherent sparsity of softmax attention (Ge et al., 2023; Jiang et al., 2023), where selectively computing critical query-key pairs can significantly reduce computational overhead while preserving performance. Recent advances demonstrate this potential through diverse strategies: KV-cache eviction methods (Zhang et al., 2023b; Li et al., 2024; Zhou et al., 2024), blockwise KV-cache selection methods (Tang et al., 2024; Xiao et al., 2024a; Gao et al., 2024), and sampling, clustering or hashing-based selection methods (Chen et al., 2024b; Liu et al., 2024; Desai et al., 2024). Despite these promising strategies, existing sparse attention methods often fall short in practical deployments. Many approaches fail to achieve speedups comparable to their theoretical gains; moreover, most methods lack effective training-time support to fully exploit the sparsity patterns of attention.
高效长上下文建模的自然思路是利用 softmax 注意力固有的稀疏性(Ge et al., 2023; Jiang et al., 2023):只选择性计算关键 query–key 对,就能在保性能的同时显著降低开销。近期工作从多种策略展示了潜力:KV-cache 驱逐(Zhang et al., 2023b; Li et al., 2024; Zhou et al., 2024)、分块 KV-cache 选择(Tang et al., 2024; Xiao et al., 2024a; Gao et al., 2024),以及基于采样、聚类或哈希的选择(Chen et al., 2024b; Liu et al., 2024; Desai et al., 2024)。尽管策略诱人,现有稀疏注意力在实际部署中常不尽如人意:许多方法达不到与理论增益相当的加速;多数也缺乏有效的训练期支持,难以充分挖掘注意力稀疏模式。
To address these limitations, the deployment of effective sparse attention must tackle two key challenges: (1) Hardware-aligned inference speedup: Converting theoretical computation reductions into actual speed improvements requires hardware-friendly algorithm design during both prefilling and decoding stages to mitigate memory access and hardware scheduling bottlenecks; (2) Training-aware algorithm design: Enabling end-to-end computation with trainable operators to reduce training costs while maintaining model performance. These requirements are crucial for real-world applications to achieve fast long-context inference or training. When considering both aspects, existing methods still exhibit a noticeable gap.
要部署有效的稀疏注意力,必须抓住两个关键挑战:(1)硬件对齐的推理加速:把理论计算量下降兑现为真实速度提升,需要在 prefilling 与 decoding 阶段都做硬件友好的算法设计,缓解访存与调度瓶颈;(2)面向训练的算法设计:用可训练算子做端到端计算,在保性能的同时降低训练成本。这两点对真实场景中的快速长上下文推理或训练都很关键。同时兼顾时,现有方法仍有明显缺口。
To achieve more effective and efficient sparse attention, we present NSA, a Natively trainable Sparse Attention architecture that integrates hierarchical token modeling. As shown in Figure 2, NSA reduces per-query computation by organizing keys and values into temporal blocks and processing them through three attention paths: compressed coarse-grained tokens, selectively retained fine-grained tokens, and sliding windows for local contextual information. Then we implement specialized kernels to maximize its practical efficiency. NSA introduces two core innovations corresponding to the key requirements above: (1) Hardware-aligned system: Optimize blockwise sparse attention for Tensor Core utilization and memory access, ensuring balanced arithmetic intensity. (2) Training-aware design: Enable stable end-to-end training through efficient algorithms and backward operators. This optimization enables NSA to support both efficient deployment and end-to-end training.
为得到更有效且高效的稀疏注意力,我们提出 NSA——一种融合分层 token 建模、原生可训练的稀疏注意力架构。如图 2 所示,NSA 将 key/value 组织成时间块,经三条注意力路径处理:压缩后的粗粒度 token、选择性保留的细粒度 token,以及用于局部上下文的滑动窗口,从而降低每个 query 的计算量。我们再实现专用 kernel 以最大化实际效率。对应上述需求,NSA 有两项核心创新:(1)硬件对齐系统:针对 Tensor Core 利用率与访存优化分块稀疏注意力,保证算术强度均衡;(2)面向训练的设计:通过高效算法与反向算子支持稳定端到端训练。由此 NSA 既能高效部署,也能端到端训练。
We evaluate NSA through comprehensive experiments on real-world language corpora. Pretraining on a 27B-parameter transformer backbone with 260B tokens, we assess NSA’s performance across general language evaluations, long-context evaluations, and chain-of-thought reasoning evaluation. We further compare the kernel speed on A100 GPUs with optimized Triton (Tillet et al., 2019) implementations. Experimental results demonstrate that NSA achieves comparable or superior performance to full attention baseline, while outperforming existing sparse attention approaches. Additionally, NSA delivers substantial speedups across decoding, forward, and backward stages compared to Full Attention, with the speedup ratio increasing for longer sequences. These results validate that our hierarchical sparse attention design effectively balances model capability and computational efficiency.
我们在真实语言语料上做了全面实验。在 27B 参数 transformer 骨干上用 260B token 预训练,在通用语言评测、长上下文评测与思维链推理评测上评估 NSA;并在 A100 上用优化过的 Triton(Tillet et al., 2019)实现比较 kernel 速度。结果表明,NSA 达到或超过全注意力基线,并优于现有稀疏注意力方法;相对全注意力,在解码、前向与反向阶段均有显著加速,且序列越长加速比越高。这些结果验证了分层稀疏注意力设计能有效平衡模型能力与计算效率。
2 Rethinking Sparse Attention Methods
2 重新思考稀疏注意力方法
Modern sparse attention methods have made significant strides in reducing the theoretical computational complexity of transformer models. However, most approaches predominantly apply sparsity during inference while retaining a pretrained Full Attention backbone, potentially introducing architectural bias that limits their ability to fully exploit sparse attention’s advantages. Before introducing our native sparse architecture, we systematically analyze these limitations through two critical lenses.
现代稀疏注意力在降低 transformer 理论计算复杂度上已有长足进展。但多数方法主要在推理期施加稀疏,骨干仍是预训练好的全注意力,可能引入架构偏差,限制充分挖掘稀疏注意力优势。在介绍我们的原生稀疏架构之前,我们从两个关键视角系统分析这些局限。
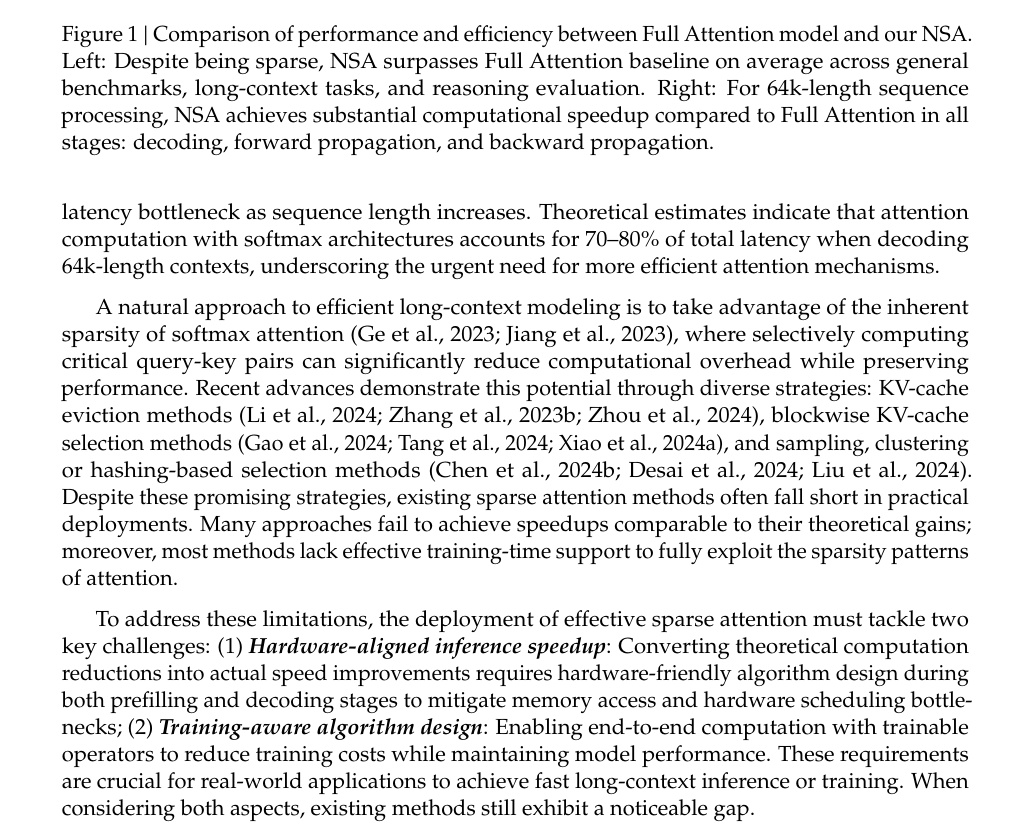
Figure 2: Overview of NSA’s architecture. Left: The framework processes input sequences through three parallel attention branches: For a given query, preceding keys and values are processed into compressed attention for coarse-grained patterns, selected attention for important token blocks, and sliding attention for local context. Right: Visualization of different attention patterns produced by each branch. Green areas indicate regions where attention scores need to be computed, while white areas represent regions that can be skipped.
图 2:NSA 架构总览。左:框架经三条并行注意力分支处理输入序列——对给定 query,先前的 key/value 分别进入压缩注意力(粗粒度模式)、选择注意力(重要 token 块)与滑动注意力(局部上下文)。右:各分支产生的注意力模式示意。绿色表示需要计算注意力分数的区域,白色表示可跳过的区域。
2.1 The Illusion of Efficient Inference
2.1 高效推理的幻觉
Despite achieving sparsity in attention computation, many methods fail to achieve corresponding reductions in inference latency, primarily due to two challenges:
尽管注意力计算已稀疏,许多方法仍无法相应降低推理时延,主要有两类挑战:
Phase-Restricted Sparsity. Methods such as H2O (Zhang et al., 2023b) apply sparsity during autoregressive decoding while requiring computationally intensive pre-processing (e.g. attention map calculation, index building) during prefilling. In contrast, approaches like MInference (Jiang et al., 2024) focus solely on prefilling sparsity. These methods fail to achieve acceleration across all inference stages, as at least one phase remains computational costs comparable to Full Attention. The phase specialization reduces the speedup ability of these methods in prefilling-dominated workloads like book summarization and code completion, or decoding-dominated workloads like long chain-of-thought (Wei et al., 2022) reasoning.
阶段受限的稀疏。 例如 H2O(Zhang et al., 2023b)在自回归解码时施加稀疏,但 prefilling 仍需高开销预处理(如注意力图计算、索引构建)。相反,MInference(Jiang et al., 2024)一类方法只关注 prefilling 稀疏。这些方法无法在全部推理阶段加速,至少有一个阶段计算开销仍接近全注意力。阶段特化削弱了它们在书籍摘要、代码补全等 prefilling 主导,或长思维链(Wei et al., 2022)推理等 decoding 主导工作负载上的加速能力。
Incompatibility with Advanced Attention Architecture. Some sparse attention methods fail to adapt to modern decoding efficient architectures like Mulitiple-Query Attention (MQA) (Shazeer, 2019) and Grouped-Query Attention (GQA) (Ainslie et al., 2023), which significantly reduced the memory access bottleneck during decoding by sharing KV across multiple query heads. For instance, in approaches like Quest (Tang et al., 2024), each attention head independently selects its KV-cache subset. Although it demonstrates consistent computation sparsity and memory access sparsity in Multi-Head Attention (MHA) models, it presents a different scenario in models based on architectures like GQA, where the memory access volume of KV-cache corresponds to the union of selections from all query heads within the same GQA group. This architectural characteristic means that while these methods can reduce computation operations, the required KV-cache memory access remains relatively high. This limitation forces a critical choice: while some sparse attention methods reduce computation, their scattered memory access pattern conflicts with efficient memory access design from advanced architectures.
与先进注意力架构不兼容。 部分稀疏注意力难以适配 MQA(Shazeer, 2019)、GQA(Ainslie et al., 2023)等现代高效解码架构——它们通过多 query 头共享 KV 大幅缓解解码访存瓶颈。例如 Quest(Tang et al., 2024)中每个注意力头独立选择 KV-cache 子集:在 MHA 模型上计算与访存稀疏性一致,但在 GQA 一类架构中,KV-cache 访存量对应同一 GQA 组内所有 query 头选择的并集。架构特性意味着这些方法虽能减少计算量,所需 KV-cache 访存仍偏高。这迫使艰难取舍:部分稀疏方法降低了计算,但其分散访存模式与先进架构的高效访存设计冲突。
These limitations arise because many existing sparse attention methods focus on KV-cache reduction or theoretical computation reduction, but struggle to achieve significant latency reduction in advanced frameworks or backends. This motivates us to develop algorithms that combine both advanced architectural and hardware-efficient implementation to fully leverage sparsity for improving model efficiency.
这些局限源于许多现有稀疏方法聚焦 KV-cache 削减或理论计算削减,却难以在先进框架或后端上显著降时延。这促使我们开发同时结合先进架构与硬件高效实现的算法,以充分用稀疏性提升模型效率。
2.2 The Myth of Trainable Sparsity
2.2 可训练稀疏的迷思
Our pursuit of native trainable sparse attention is motivated by two key insights from analyzing inference-only approaches: (1) Performance Degradation: Applying sparsity post-hoc forces models to deviate from their pretrained optimization trajectory. As demonstrated by Chen et al. (2024b), top 20% attention can only cover 70% of the total attention scores, rendering structures like retrieval heads in pretrained models vulnerable to pruning during inference. (2) Training Efficiency Demands: Efficient handling of long-sequence training is crucial for modern LLM development. This includes both pretraining on longer documents to enhance model capacity, and subsequent adaptation phases such as long-context fine-tuning and reinforcement learning. However, existing sparse attention methods primarily target inference, leaving the computational challenges in training largely unaddressed. This limitation hinders the development of more capable long-context models through efficient training. Additionally, efforts to adapt existing sparse attention for training also expose challenges:
我们追求原生可训练稀疏注意力,源于对仅推理方法的两点洞察:(1)性能退化:事后施加稀疏迫使模型偏离预训练优化轨迹。Chen et al.(2024b)表明,top 20% 注意力只能覆盖总注意力分数约 70%,使预训练模型中的检索头等结构在推理剪枝时易受损。(2)训练效率需求:高效处理长序列训练对现代 LLM 发展至关重要,既包括在更长文档上预训练以增强能力,也包括长上下文微调与强化学习等后续适应。但现有稀疏注意力主要面向推理,训练侧计算挑战大多未解,阻碍通过高效训练发展更强长上下文模型。此外,把现有稀疏注意力改造成可训练也会暴露挑战:
Non-Trainable Components. Discrete operations in methods like ClusterKV (Liu et al., 2024) (includes k-means clustering) and MagicPIG (Chen et al., 2024b) (includes SimHash-based selecting) create discontinuities in the computational graph. These non-trainable components prevent gradient flow through the token selection process, limiting the model’s ability to learn optimal sparse patterns.
不可训练组件。 ClusterKV(Liu et al., 2024)(含 k-means)与 MagicPIG(Chen et al., 2024b)(含基于 SimHash 的选择)等离散操作在计算图中造成不连续。这些不可训练组件阻断经 token 选择过程的梯度流,限制模型学习最优稀疏模式的能力。
Inefficient Back-propagation. Some theoretically trainable sparse attention methods suffer from practical training inefficiencies. Token-granular selection strategy used in approaches like HashAttention (Desai et al., 2024) leads to the need to load a large number of individual tokens from the KV cache during attention computation. This non-contiguous memory access prevents efficient adaptation of fast attention techniques like FlashAttention, which rely on contiguous memory access and blockwise computation to achieve high throughput. As a result, implementations are forced to fall back to low hardware utilization, significantly degrading training efficiency.
低效反向传播。 一些理论上可训练的稀疏注意力在实际训练中效率不佳。HashAttention(Desai et al., 2024)等采用的 token 粒度选择,使注意力计算需从 KV cache 加载大量零散 token。这种非连续访存妨碍高效适配 FlashAttention 等依赖连续访存与分块计算的快速注意力技术,实现被迫退回低硬件利用率,显著拖累训练效率。
2.3 Native Sparsity as an Imperative
2.3 原生稀疏成为必需
These limitations in inference efficiency and training viability motivate our fundamental redesign of sparse attention mechanisms. We propose NSA, a natively sparse attention framework that addresses both computational efficiency and training requirements. In the following sections, we detail the algorithmic design and operator implementation of NSA.
推理效率与训练可行性上的局限,促使我们从根本上重设计稀疏注意力。我们提出 NSA——同时面向计算效率与训练需求的原生稀疏注意力框架。后续各节详述 NSA 的算法设计与算子实现。
3 Methodology
3 方法
Our technical approach spans algorithm design and kernel optimization. In the following subsections, we first introduce the background of our methodology. Then we present the overall framework of NSA, followed by its key algorithmic components. Finally, we detail our hardware-optimized kernel design that maximizes practical efficiency.
我们的技术路径覆盖算法设计与 kernel 优化。以下先介绍方法背景,再给出 NSA 总体框架与关键算法组件,最后详述最大化实际效率的硬件优化 kernel 设计。
3.1 Background
3.1 背景
Attention Mechanism is widely used in language modeling where each query token computes relevance scores against all preceding keys to generate a weighted sum of values . Formally, for an input sequence of length , the attention operation is defined as:
注意力机制广泛用于语言建模:每个 query token 对所有先前 key 计算相关性分数,再对 value 做加权求和。形式上,对长度 的输入序列,注意力操作为:
where denotes the attention function:
其中 表示注意力函数:
Here, represents the attention weight between and , and is the feature dimension of keys. As sequence length increases, attention computation becomes increasingly dominant in the overall computational cost, presenting significant challenges for long-context processing.
这里 是 与 之间的注意力权重, 是 key 的特征维。随序列变长,注意力计算在总开销中越来越占主导,给长上下文处理带来显著挑战。
Arithmetic Intensity is the ratio of compute operations to memory accesses. It intrinsically shapes algorithm optimization on hardware. Each GPU has a critical arithmetic intensity determined by its peak compute capability and memory bandwidth, calculated as the ratio of these two hardware limits. For computation tasks, arithmetic intensity above this critical threshold becomes compute-bound (limited by GPU FLOPS), while below it becomes memory-bound (limited by memory bandwidth).
算术强度是计算操作数与访存次数之比,内在决定算法在硬件上的优化方向。每块 GPU 由其峰值算力与内存带宽之比确定临界算术强度。计算任务高于该阈值则受算力限制(受 GPU FLOPS 约束),低于则受访存限制(受内存带宽约束)。
Specifically for causal self-attention mechanism, during training and prefilling phases, batched matrix multiplications and attention computations exhibit high arithmetic intensity, making these stages compute-bound on modern accelerators. In contrast, auto-regressive decoding becomes memory-bandwidth constrained because it generates one token per forward pass while requiring loading the entire key-value cache, resulting in low arithmetic intensity. This leads to different optimization goals — reducing computation cost during training and prefilling, while reducing memory access during decoding.
具体到因果自注意力:训练与 prefilling 阶段,批量矩阵乘与注意力计算算术强度高,在现代加速器上多为算力受限;自回归解码则因每步只生成一个 token、却需加载整份 key–value cache,算术强度低,受内存带宽约束。于是优化目标不同——训练与 prefilling 侧重降计算成本,解码侧重降访存。
3.2 Overall Framework
3.2 总体框架
To leverage the potential of attention with natural sparse pattern, we propose replacing the original key-value pairs in Equation 1 with a more compact and information-dense set of representation key-value pairs given each query . Specifically, we formally define the optimized attention output as follows:
为利用注意力天然稀疏模式的潜力,我们提出用更紧凑、信息更密的表示 key–value 对 ,替换公式 1 中每个 query 对应的原始 key–value 对 。形式上将优化后的注意力输出定义为:
where are dynamically constructed based on the current query and the contextual memory . We can design various mapping strategies to get different categories of , and combine them as follows:
其中 依据当前 query 与上下文记忆 动态构造。我们可以设计多种映射策略得到不同类别的 ,再如下组合:
As illustrated in Figure 2, NSA have three mapping strategies , representing compression, selection, and sliding window for keys and values. is the gate score for corresponding strategy , derived from input features via an MLP and sigmoid activation. Let denote the total number of remapped keys/values:
如图 2 所示,NSA 有三种映射策略 ,分别表示对 key/value 的压缩、选择与滑动窗口。 是策略 的门控分数,由输入特征经 MLP 与 sigmoid 得到。记重映射后的 key/value 总数为 :
We maintain a high sparsity ratio by ensuring.
我们通过保证 维持高稀疏比。
3.3 Algorithm Design
3.3 算法设计
In this subsection, we introduce the design of our remapping strategies and : token compression, token selection, and sliding window.
本小节介绍重映射策略 与 的设计:token 压缩、token 选择与滑动窗口。
3.3.1 Token Compression
By aggregating sequential blocks of keys or values into block-level representations, we obtain compressed keys and values that capture the information of the entire block. Formally, the compressed key representation is defined as:
3.3.1 Token 压缩
通过将连续的 key 或 value 块聚合为块级表示,我们得到捕获整块信息的压缩 key 与 value。形式上将压缩 key 表示定义为:
where is the block length, is the sliding stride between adjacent blocks, and is a learnable MLP with intra-block position encoding to map keys in a block to a single compressed key. is tensor composed by compresion keys. Usually, we adopt to mitigate information fragmentation. An analogous formulation holds for the compressed value representation . Compressed representations capture coarser-grained higher-level semantic information and reduce computational burden of attention.
其中 是块长, 是相邻块之间的滑动步长, 是带块内位置编码的可学习 MLP,将块内 key 映射为单个压缩 key。 由压缩 key 组成。通常取 以减轻信息碎片化。压缩 value 表示 有类似形式。压缩表示捕获更粗粒度的高层语义,并降低注意力计算负担。
3.3.2 Token Selection
Using only compressed keys, values might lose important fine-grained information, motivating us to selectively preserve individual keys, values. Below we describe our efficient token selection mechanism that identifies and preserves the most relevant tokens with low computational overhead.
3.3.2 Token 选择
仅用压缩 key/value 可能丢失重要细粒度信息,促使我们选择性保留个别 key/value。下面描述以较低计算开销识别并保留最相关 token 的高效选择机制。
Blockwise Selection. Our selection strategy processes key and value sequences in spacial continuous blocks, motivated by two key factors: hardware efficiency considerations and inherent distribution patterns of attention scores. Blockwise selection is crucial to achieve efficient computation on modern GPUs. That is because modern GPU architectures exhibit significantly higher throughput for continuous block accesses compared to random index-based reads. Also, blockwise computation enables optimal utilization of Tensor Cores. This architectural characteristic has established blockwise memory access and computation as a fundamental principle in high-performance attention implementations, as exemplified by FlashAttention’s block-based design. Blockwise selection follows the inherent distribution patterns of attention scores. Prior works (Jiang et al., 2024) have shown that attention scores often exhibit spatial continuity, suggesting that neighboring keys tend to share similar importance levels. Our visualization in Section 6.2 also shows this spatial continuous pattern.
分块选择。 我们的选择策略按空间连续块处理 key/value 序列,动机有二:硬件效率,以及注意力分数的固有分布模式。分块选择对在现代 GPU 上高效计算至关重要。 因为现代 GPU 对连续块访问的吞吐显著高于随机按索引读取;分块计算也利于最优利用 Tensor Core。这一架构特性使分块访存与计算成为高性能注意力实现的基本原则,FlashAttention 的分块设计即是例证。分块选择也符合注意力分数的固有分布。 已有工作(Jiang et al., 2024)表明注意力分数常呈空间连续性,邻近 key 往往有相近重要性。第 6.2 节的可视化也呈现这种空间连续模式。
To implement blockwise selection, we first divide key, value sequences into selection blocks. To identify the most important blocks for attention computation, we need to assign importance scores to each block. Below we present our method for computing these block-level importance scores.
为实现分块选择,我们先将 key/value 序列划分为选择块。要识别对注意力计算最重要的块,需为每块赋重要性分数。下面给出计算块级重要性分数的方法。
Importance Score Computation. Computing block importance scores could introduce significant overhead. Fortunately, the attention computation of compression tokens produces intermediate attention scores that we can leverage to induce selection block importance scores, formulated as:
重要性分数计算。 直接算块重要性可能引入显著开销。幸运的是,压缩 token 的注意力计算会产生中间注意力分数,可用来诱导选择块重要性,形式化为:
where is the attention scores between and compression keys . Let denote the selection block size. When compression blocks and selection blocks share the same blocking scheme, i.e., , we can directly obtain the selection block importance scores by straightforwardly. For cases where the blocking schemes differ, we derive the importance scores for selection blocks according to their spatial relationship. Given and , we have:
其中 是 与压缩 key 之间的注意力分数。记选择块大小为 。当压缩块与选择块采用同一分块方案,即 时,可直接令 。若分块方案不同,则按空间关系推导选择块重要性。给定 且 ,有:
where denotes the indexing operator for accessing vector element. For models employing GQA or MQA where key-value caches are shared across query heads, consistent block selection across these heads has to be ensured to minimize KV cache loading during decoding. The shared importance scores across heads in a group are formally defined as:
其中 表示访问向量元素的索引算子。对采用 GQA 或 MQA、多 query 头共享 KV cache 的模型,必须保证这些头选择一致的块,以最小化解码时的 KV cache 加载。组内共享重要性分数形式定义为:
where in the superscript denotes the head index, and is the number of query heads in each group. This aggregation ensures consistent block selection across heads within the same group.
上标 表示头索引, 是每组内的 query 头数。该聚合保证同组内各头选择一致的块。
Top- Block Selection. After obtaining the selection block importance scores, We retain tokens within the top- sparse blocks ranked by block importance scores, formulated as:
Top- 块选择。 得到选择块重要性分数后,我们按块重要性排序保留 top- 稀疏块内的 token,形式化为:
where rank denotes the ranking position in descending order, with rank = 1 corresponding to the highest score, is the set of selected blocks’ indices, denotes the concatenation operation. is tensor composed by compresion keys. An analogous formulation applies to the fine-grained value . The selected keys and values then participate in the attention computation with as defined in Equation 5.
其中 rank 表示降序排名(rank = 1 对应最高分), 是被选块索引集合, 表示拼接。 由所选细粒度 key 组成。细粒度 value 有类似形式。所选 key/value 再按公式 5 与 参与注意力计算。
3.3.3 Sliding Window
In attention mechanisms, local patterns typically adapt faster and can dominate the learning process, potentially preventing the model from effectively learning from compression and selection tokens. To address this issue, we introduce a dedicated sliding window branch that explicitly handles local context, allowing other branches (compression and selection) to focus on learning their respective features without being shortcutted by local patterns. Specifically, we maintain recent tokens in a window , and isolate attention computations of different information sources (compression tokens, and selected tokens, sliding window) into separate branches. These branch outputs are then aggregated through a learned gating mechanism. To further prevent shortcut learning across attention branches with marginal computational overhead, we provide independent keys and values for three branches. This architectural design enables stable learning by preventing gradient interference between local and long-range pattern recognition, while introducing minimal overhead.
3.3.3 滑动窗口
在注意力机制中,局部模式通常适应更快,可能主导学习过程,妨碍模型有效学习压缩与选择 token。为此我们引入专用滑动窗口分支显式处理局部上下文,让压缩与选择分支专注各自特征、不被局部模式捷径绕过。具体地,我们在窗口 内保持近期 token ,并将不同信息源(压缩 token、选择 token、滑动窗口)的注意力计算隔离到独立分支,再经可学习门控聚合分支输出。为进一步防止跨分支捷径学习且只引入边缘计算开销,我们为三分支提供独立的 key/value。该架构通过避免局部与长程模式识别之间的梯度干扰来稳定学习,同时额外开销很小。
After obtaining all three categories of keys and values (; ; and ), we compute the final attention output following Equation 5. Together with the compression, selection, and sliding window mechanisms described above, this forms the complete algorithmic framework of NSA.
得到三类 key/value(;;以及 )后,按公式 5 计算最终注意力输出。连同上文压缩、选择与滑动窗口机制,构成 NSA 的完整算法框架。
3.4 Kernel Design
3.4 Kernel 设计
To achieve FlashAttention-level speedup during the training and prefilling, we implement hardware-aligned sparse attention kernels upon Triton. Given MHA is memory-intensive and inefficient for decoding, we focus on architectures with shared KV caches like GQA and MQA following the current state-of-the-art LLMs. While compression and sliding window attention computations are readily compatible with existing FlashAttention-2 kernels, we introduce the specialized kernel design for sparse selection attention. If we were to follow FlashAttention’s strategy of loading temporally continuous query blocks into SRAM, it would result in inefficient memory access since queries within a block may require disjoint KV blocks. To address this, our key optimization lies in a different query grouping strategy: for each position on the query sequence, we load all query heads within a GQA group (they share the same sparse KV blocks) into SRAM. Figure 3 illustrates our forward pass implementation. The proposed kernel architecture is characterized by the following key features:
为在训练与 prefilling 达到 FlashAttention 级加速,我们基于 Triton 实现硬件对齐的稀疏注意力 kernel。鉴于 MHA 访存密集、解码低效,我们聚焦当前主流 LLM 所采用的共享 KV cache 架构(如 GQA、MQA)。压缩与滑动窗口注意力计算可直接兼容现有 FlashAttention-2 kernel;我们为稀疏选择注意力引入专用 kernel 设计。若沿用 FlashAttention「把时间连续的 query 块载入 SRAM」的策略,会因同一块内 query 可能需要不相交的 KV 块而导致低效访存。为此,关键优化在于不同的 query 分组策略:对 query 序列上每个位置,把同一 GQA 组内所有 query 头(它们共享同一组稀疏 KV 块)载入 SRAM。图 3 展示前向实现。所提 kernel 架构有以下要点:
- Group-Centric Data Loading. For each inner loop, load all heads’ queries in the group at position and their shared sparse key/value block indices .
- 以组为中心的数据加载。每个内层循环载入位置 上组内所有头的 query 及其共享的稀疏 key/value 块索引 。
- Shared KV Fetching. In the inner loop, Sequentially load continuous key/value blocks indexed by into SRAM as to minimize memory loading, where is the kernel block size satisfying .
- 共享 KV 取数。内层循环按 顺序将连续 key/value 块载入 SRAM 为 ,以最小化访存,其中 kernel 块大小 满足 。
- Outer Loop on Grid. Since the inner-loop length (proportional to the selected block count ) remains nearly identical for different query blocks, we put query/output loops in Triton’s grid scheduler to simplify and optimize the kernel.
- 网格上的外层循环。由于内层循环长度(与所选块数 成正比)对不同 query 块几乎相同,我们将 query/输出循环放在 Triton 的网格调度器中,以简化并优化 kernel。
This design achieves near-optimal arithmetic intensity by (1) eliminating redundant KV transfers through group-wise sharing, and (2) balancing compute workloads across GPU streaming multiprocessors.
该设计通过(1)组内共享消除冗余 KV 传输,以及(2)在 GPU 流式多处理器间均衡计算负载,达到接近最优的算术强度。
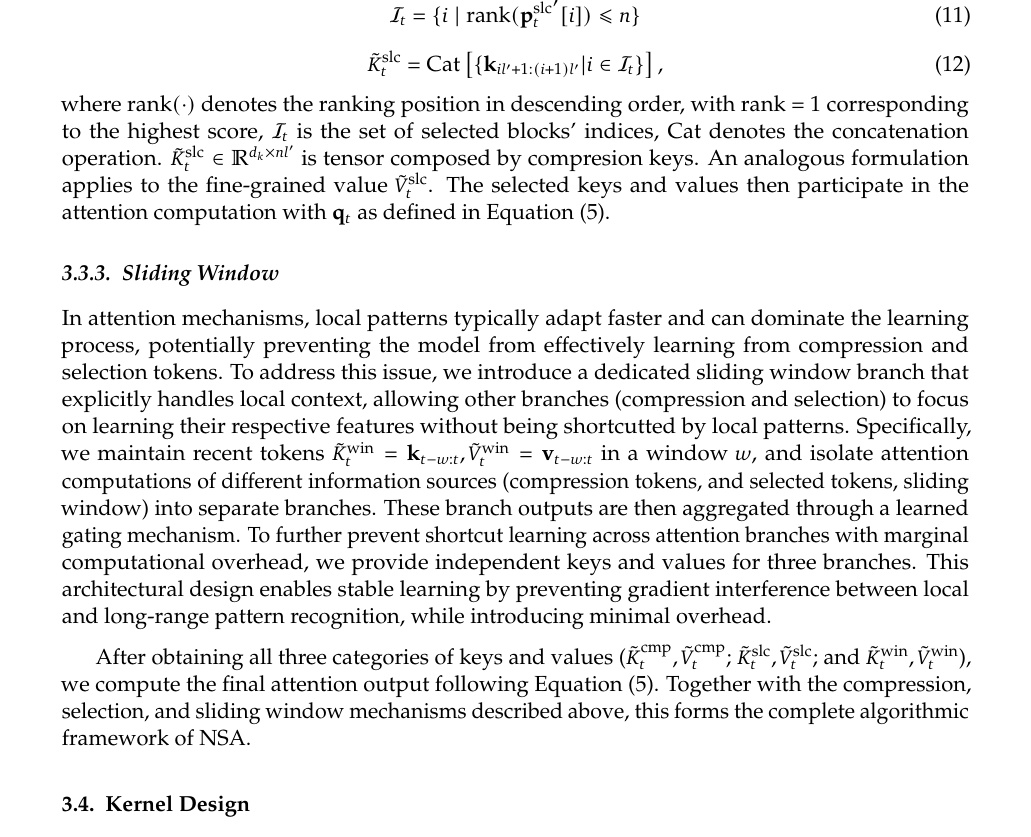
Figure 3: Kernel design for NSA. The kernel loads queries by GQA groups (Grid Loop), fetches corresponding sparse KV blocks (Inner Loop), and performs attention computation on SRAM. Green blocks indicate data on SRAM, while blue indicates data on HBM.
图 3:NSA 的 kernel 设计。kernel 按 GQA 组加载 query(网格循环),取对应稀疏 KV 块(内层循环),在 SRAM 上做注意力计算。绿色块表示位于 SRAM 的数据,蓝色表示位于 HBM 的数据。
4 Experiments
4 实验
We evaluate NSA through three lenses: (1) general benchmarks performance, (2) long-context benchmarks performance, and (3) chain-of-thought reasoning performance, comparing against Full Attention baseline and state-of-the-art sparse attention methods. We defer the efficiency analysis of our sparse computation paradigm to Section 5, where we provide detailed discussions on training and inference speed.
我们从三方面评估 NSA:(1)通用基准性能,(2)长上下文基准性能,(3)思维链推理性能,并与全注意力基线及先进稀疏注意力方法对比。稀疏计算范式的效率分析放到第 5 节,那里详述训练与推理速度。
4.1 Pretraining Setup
4.1 预训练设置
Following the common practice in state-of-the-art LLMs, our experiments adopt a backbone combining Grouped-Query Attention (GQA) and Mixture-of-Experts (MoE), featuring total parameters with active parameters. The model consists of 30 layers with a hidden dimension of 2560. For GQA, we set the number of groups to 4, with a total of 64 attention heads. For each head, the hidden dimensions of the query, key, and value are configured as and , respectively. For MoE, we utilize the DeepSeekMoE (Dai et al., 2024; DeepSeek-AI, 2024) structure, with 72 routed experts and 2 shared experts, and set the top-k experts to 6. To ensure training stability, the MoE in the first layer is replaced by an MLP in the form of SwiGLU. The proposed architecture achieves an effective trade-off between computation cost and model performance. For NSA, we set compression block size , sliding stride , selected block size , selected block count (including fixed activating the 1 initial block and 2 local blocks), and sliding window size . Both Full Attention and sparse attention models are pretrained on tokens of -length texts, followed by continued training and supervised fine-tuning on -length texts with YaRN (Peng et al., 2024) to achieve long-context adaptation. Both models are trained to full convergence to ensure fair comparison. As shown in Figure 4, the pretraining loss curve of our NSA and Full Attention baseline demonstrates stable and smooth decline, with NSA consistently outperforming the Full Attention model.
遵循当前主流 LLM 实践,实验采用结合 Grouped-Query Attention(GQA)与 Mixture-of-Experts(MoE)的骨干,总参数 、激活参数 。模型 30 层,隐维 2560。GQA 设 4 组、共 64 个注意力头;每头 query/key/value 隐维分别为 、。MoE 采用 DeepSeekMoE(Dai et al., 2024; DeepSeek-AI, 2024)结构,72 个路由专家与 2 个共享专家,top-k 取 6。为保证训练稳定,第一层 MoE 替换为 SwiGLU 形式的 MLP。该架构在计算成本与模型性能间取得有效折中。对 NSA,设压缩块长 、滑动步长 、选择块长 、选择块数 (含固定激活的 1 个初始块与 2 个局部块)、滑动窗口 。全注意力与稀疏注意力模型均在 个 长度文本上预训练,再经 YaRN(Peng et al., 2024)在 长度文本上继续训练与监督微调,完成长上下文适应。两模型均训练至充分收敛以保证公平对比。如图 4,NSA 与全注意力基线的预训练损失曲线稳定平滑下降,且 NSA 持续优于全注意力模型。
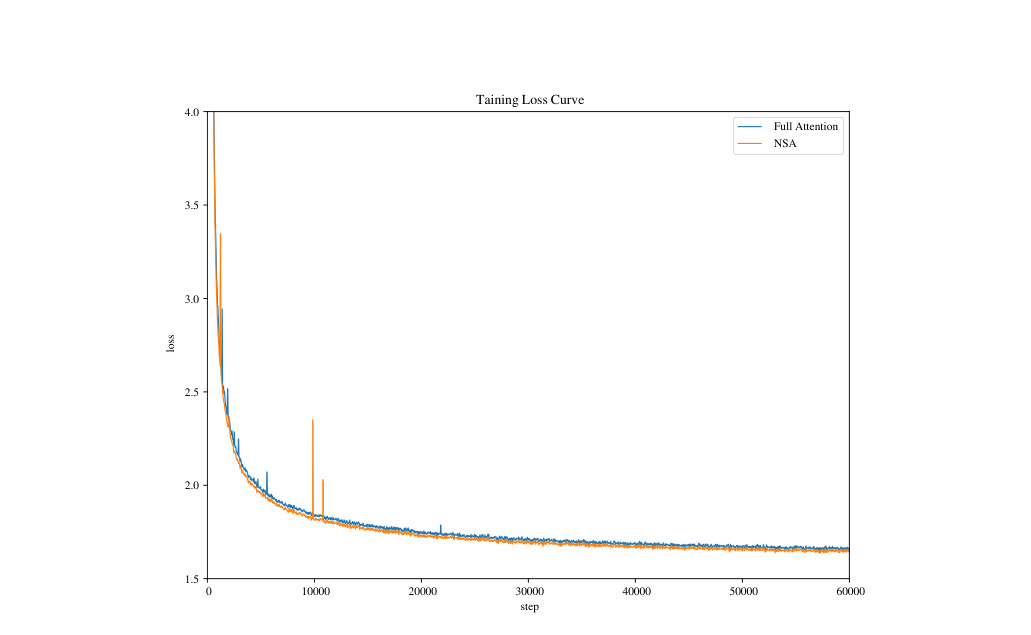
Figure 4: Pretraining loss comparison between Full Attention and our NSA on 27B-parameter model. Both models exhibit stable convergence, with NSA achieving lower loss values.
图 4:27B 参数模型上全注意力与我们的 NSA 的预训练损失对比。两模型均稳定收敛,NSA 达到更低损失。
| Model | MMLU | MMLU-PRO | CMMLU | BBH | GSM8K | MATH | DROP | MBPP | HumanEval | Avg. |
|---|---|---|---|---|---|---|---|---|---|---|
| Acc. 5-shot | Acc. 5-shot | Acc. 5-shot | Acc. 3-shot | Acc. 8-shot | Acc. 4-shot | F1 1-shot | Pass@1 3-shot | Pass@1 0-shot | ||
| Full Attn | 0.567 | 0.279 | 0.576 | 0.497 | 0.486 | 0.263 | 0.503 | 0.482 | 0.335 | 0.443 |
| NSA | 0.565 | 0.286 | 0.587 | 0.521 | 0.520 | 0.264 | 0.545 | 0.466 | 0.348 | 0.456 |
Table 1: Pretraining performance comparison between the full attention baseline and NSA on general benchmarks, across knowledge (MMLU, MMLU-PRO, CMMLU), reasoning (BBH, GSM8K, MATH, DROP), and coding (MBPP, HumanEval) tasks. NSA achieves superior average performance on most benchmarks despite high sparsity.
| Model | MMLU | MMLU-PRO | CMMLU | BBH | GSM8K | MATH | DROP | MBPP | HumanEval | Avg. |
|---|---|---|---|---|---|---|---|---|---|---|
| Acc. 5-shot | Acc. 5-shot | Acc. 5-shot | Acc. 3-shot | Acc. 8-shot | Acc. 4-shot | F1 1-shot | Pass@1 3-shot | Pass@1 0-shot | ||
| Full Attn | 0.567 | 0.279 | 0.576 | 0.497 | 0.486 | 0.263 | 0.503 | 0.482 | 0.335 | 0.443 |
| NSA | 0.565 | 0.286 | 0.587 | 0.521 | 0.520 | 0.264 | 0.545 | 0.466 | 0.348 | 0.456 |
表 1:全注意力基线与 NSA 在通用基准上的预训练性能对比,覆盖知识(MMLU、MMLU-PRO、CMMLU)、推理(BBH、GSM8K、MATH、DROP)与代码(MBPP、HumanEval)任务。尽管高度稀疏,NSA 在多数基准上取得更优平均表现。
4.2 Baselines Methods
4.2 基线方法
In addition to comparing with Full Attention, we evaluate several state-of-the-art inference-stage sparse attention methods: H2O (Zhang et al., 2023b), infLLM (Xiao et al., 2024a), Quest (Tang et al., 2024), and Exact-Top, which first computes full attention score and select the top- scores keys corresponding to each query and then calculates attention on these positions. These methods span diverse sparse attention paradigms, including KV-cache eviction, query-aware selection, and exact top- sparse selection.
除与全注意力对比外,我们还评估若干先进推理期稀疏注意力方法:H2O(Zhang et al., 2023b)、infLLM(Xiao et al., 2024a)、Quest(Tang et al., 2024),以及 Exact-Top——先算全注意力分数、再为每个 query 选 top- 分数对应的 key,并在这些位置上计算注意力。这些方法覆盖 KV-cache 驱逐、query 感知选择与精确 top- 稀疏选择等不同范式。
For general evaluation, where most samples have lengths within the local context window of sparse attention baselines, these methods are effectively equivalent to Full Attention. Therefore, we present only the comparison results between NSA and Full Attention baseline in this setting. In the long-context evaluation, we conduct comparisons across all baseline methods, with the sparsity of all sparse attention methods set to the same to ensure a fair comparison. For chain-of-thought reasoning evaluation, which requires long-text supervised fine-tuning, we limit our comparison to Full Attention, as sparse attention baselines do not support training.
在通用评测中,多数样本长度落在稀疏注意力基线的局部上下文窗口内,这些方法实际等价于全注意力,故该设定下仅报告 NSA 与全注意力对比。长上下文评测中我们比较全部基线,并将各稀疏方法稀疏度设为相同以保证公平。思维链推理评测需长文本监督微调,稀疏基线不支持训练,故仅与全注意力对比。
4.3 Performance Comparison
4.3 性能对比
| Model | SQA | MQA | Synthetic | Code | Avg. | ||||||
|---|---|---|---|---|---|---|---|---|---|---|---|
| MFQA-en | MFQA-zh | Qasper | HPQ | 2Wiki | GovRpt | Dur | PassR-en | PassR-zh | LCC | ||
| H2O | 0.428 | 0.429 | 0.308 | 0.112 | 0.101 | 0.231 | 0.208 | 0.704 | 0.421 | 0.092 | 0.303 |
| InfLLM | 0.474 | 0.517 | 0.356 | 0.306 | 0.250 | 0.277 | 0.257 | 0.766 | 0.486 | 0.143 | 0.383 |
| Quest | 0.495 | 0.561 | 0.365 | 0.295 | 0.245 | 0.293 | 0.257 | 0.792 | 0.478 | 0.135 | 0.392 |
| Exact-Top | 0.502 | 0.605 | 0.397 | 0.321 | 0.288 | 0.316 | 0.291 | 0.810 | 0.548 | 0.156 | 0.423 |
| Full Attn | 0.512 | 0.623 | 0.409 | 0.350 | 0.305 | 0.324 | 0.294 | 0.830 | 0.560 | 0.163 | 0.437 |
| NSA | 0.503 | 0.624 | 0.432 | 0.437 | 0.356 | 0.307 | 0.341 | 0.905 | 0.550 | 0.232 | 0.469 |
Table 2: Performance comparison between our NSA and baselines on LongBench, including subsets in single document QA, multi-document QA, synthetic and code task categories. NSA outperformed most of the baselines including Full Attention.
| Model | SQA | MQA | Synthetic | Code | Avg. | ||||||
|---|---|---|---|---|---|---|---|---|---|---|---|
| MFQA-en | MFQA-zh | Qasper | HPQ | 2Wiki | GovRpt | Dur | PassR-en | PassR-zh | LCC | ||
| H2O | 0.428 | 0.429 | 0.308 | 0.112 | 0.101 | 0.231 | 0.208 | 0.704 | 0.421 | 0.092 | 0.303 |
| InfLLM | 0.474 | 0.517 | 0.356 | 0.306 | 0.250 | 0.277 | 0.257 | 0.766 | 0.486 | 0.143 | 0.383 |
| Quest | 0.495 | 0.561 | 0.365 | 0.295 | 0.245 | 0.293 | 0.257 | 0.792 | 0.478 | 0.135 | 0.392 |
| Exact-Top | 0.502 | 0.605 | 0.397 | 0.321 | 0.288 | 0.316 | 0.291 | 0.810 | 0.548 | 0.156 | 0.423 |
| Full Attn | 0.512 | 0.623 | 0.409 | 0.350 | 0.305 | 0.324 | 0.294 | 0.830 | 0.560 | 0.163 | 0.437 |
| NSA | 0.503 | 0.624 | 0.432 | 0.437 | 0.356 | 0.307 | 0.341 | 0.905 | 0.550 | 0.232 | 0.469 |
表 2:NSA 与各基线在 LongBench 上的对比,含单文档 QA、多文档 QA、合成与代码任务子集。NSA 超过包括全注意力在内的多数基线。
General Evaluation. We evaluated the pretrained NSA and Full Attention baseline, on a comprehensive suite of benchmarks spanning knowledge, reasoning, and coding capabilities, including MMLU (Hendrycks et al., 2020), MMLU-PRO (Wang et al., 2024), CMMLU (Li et al., 2023), BBH (Suzgun et al., 2022), GSM8K (Cobbe et al., 2021), MATH (Hendrycks et al., 2020), DROP (Dua et al., 2019), MBPP (Austin et al., 2021), and HumanEval (Chen et al., 2021). The results are shown in Table 1. Despite its sparsity, NSA achieves superior overall performance, outperforming all baselines including Full Attention on 7 out of 9 metrics. This indicates that although NSA may not fully leverage its efficiency advantages on shorter sequences, it shows strong performance. Notably, NSA demonstrates significant gains in reasoning-related benchmarks (DROP: +0.042, GSM8K: +0.034), suggesting that our pretraining helps models to develop specialized attention mechanisms. This sparse attention pretraining mechanism forces model to focus on the most important information, potentially enhancing performance by filtering out noise from irrelevant attention pathways. The consistent performance across diverse evaluations also validates NSA’s robustness as a general-purpose architecture.
通用评测。 我们在覆盖知识、推理与代码能力的综合基准上评估预训练的 NSA 与全注意力基线,包括 MMLU(Hendrycks et al., 2020)、MMLU-PRO(Wang et al., 2024)、CMMLU(Li et al., 2023)、BBH(Suzgun et al., 2022)、GSM8K(Cobbe et al., 2021)、MATH(Hendrycks et al., 2020)、DROP(Dua et al., 2019)、MBPP(Austin et al., 2021)与 HumanEval(Chen et al., 2021)。结果见表 1。尽管稀疏,NSA 整体更优,在 9 项指标中有 7 项超过包括全注意力在内的全部基线。说明虽在短序列上未必充分兑现效率优势,NSA 仍表现强劲。值得注意的是,NSA 在推理相关基准上增益显著(DROP:+0.042,GSM8K:+0.034),提示预训练有助于形成专门化注意力机制。该稀疏注意力预训练迫使模型聚焦最重要信息,可能通过滤除无关注意力通路的噪声提升性能。跨多样评测的一致表现也验证了 NSA 作为通用架构的稳健性。
Long-Context Evaluation. As shown in Figure 5, NSA achieves perfect retrieval accuracy across all positions in 64k-context needle-in-a-haystack (Kamradt, 2023) test. This performance stems from our hierarchical sparse attention design, which combines compression tokens for efficient global context scanning, and selection tokens for precise local information retrieval. The coarse-grained compression identifies relevant context blocks at low computational cost, while the token-level attention on selected tokens ensures the preservation of critical fine-grained information. This design enables NSA to maintain both global awareness and local precision.
长上下文评测。 如图 5,NSA 在 64k 上下文的 needle-in-a-haystack(Kamradt, 2023)测试中于所有位置达到完美检索精度。这源于分层稀疏注意力设计:压缩 token 高效扫描全局上下文,选择 token 精确检索局部信息。粗粒度压缩以低计算成本定位相关上下文块,选中 token 上的 token 级注意力则保留关键细粒度信息。该设计使 NSA 同时保持全局感知与局部精度。
Figure 5: Needle-in-a-Haystack retrieval accuracy across context positions with 64k context length. NSA achieves perfect accuracy through its hierarchical sparse attention design.
图 5:64k 上下文长度下,跨上下文位置的 Needle-in-a-Haystack 检索精度。NSA 凭借分层稀疏注意力设计达到完美精度。
We also evaluate NSA on LongBench (Bai et al., 2023) against state-of-the-art sparse attention methods and Full Attention baseline. To ensure consistent sparsity, we set the token activated by each query in all sparse attention baselines to 2560 tokens, which corresponds to the average number of tokens activated in NSA when handling 32k sequence lengths. Following StreamLLM (Xiao et al., 2023), this token budget includes the leading 128 tokens and 512 local tokens. We exclude certain subsets from LongBench due to their low scores across all models, which may not provide meaningful comparisons. As shown in Table 2, NSA achieves the highest average score 0.469, outperforming all baselines (+0.032 over Full Attention and +0.046 over Exact-Top). This improvement arises from two key innovations: (1) our native sparse attention design, which enables end-to-end optimization of sparse patterns during pretraining, facilitates synchronized adaptation between the sparse attention module and other model components; and (2) the hierarchical sparse attention mechanism achieves a balance between local and global information processing.
我们还在 LongBench(Bai et al., 2023)上对比 NSA、先进稀疏注意力方法与全注意力基线。为保持稀疏度一致,将各稀疏基线中每个 query 激活的 token 数设为 2560,对应 NSA 处理 32k 序列时的平均激活 token 数。遵循 StreamLLM(Xiao et al., 2023),该 token 预算含前导 128 个与局部 512 个 token。因部分 LongBench 子集上各模型分数均很低、难以提供有意义对比,我们予以排除。如表 2,NSA 取得最高平均分 0.469,超过全部基线(相对全注意力 +0.032,相对 Exact-Top +0.046)。提升来自两点创新:(1)原生稀疏注意力设计使预训练期可端到端优化稀疏模式,促进稀疏注意力模块与其他组件同步适应;(2)分层稀疏注意力在局部与全局信息处理间取得平衡。
Notably, NSA demonstrates exceptional performance on tasks requiring complex reasoning over long contexts, achieving +0.087 and +0.051 improvements over Full Attention on multi-hop QA tasks (HPQ and 2Wiki), exceeding the performance of baselines on code understanding (LCC: +0.069), and outperforming other methods on passage retrieval (PassR-en: +0.075). These results validate NSA’s capability to handle diverse long-context challenges, with its natively pretrained sparse attention providing additional benefits in learning task-optimal patterns.
值得注意的是,NSA 在需要长上下文复杂推理的任务上表现突出:多跳 QA(HPQ 与 2Wiki)相对全注意力分别提升 +0.087 与 +0.051,代码理解(LCC:+0.069)超过各基线,段落检索(PassR-en:+0.075)也优于其他方法。这些结果验证了 NSA 应对多样长上下文挑战的能力,其原生预训练的稀疏注意力在学习任务最优模式上带来额外收益。
Chain-of-Thought Reasoning Evaluation. To evaluate NSA’s compatibility with advanced downstream training paradigms, we investigate its capacity to acquire chain-of-thought mathematical reasoning abilities via post-training. Given the limited effectiveness of reinforcement learning on smaller-scale models, we employ knowledge distillation from DeepSeek-R1, conducting supervised fine-tuning (SFT) with 10B tokens of 32k-length mathematical reasoning traces. This produces two comparable models: Full Attention-R (Full Attention baseline) and NSA-R (our sparse variant). We assess both models on the challenging American Invitational Mathematics Examination (AIME 24) benchmark. We use a sampling temperature of 0.7 and a top- value of 0.95 to generate 16 responses for each question and obtain the average score. To validate the impact of reasoning depth, we conduct experiments with two generation context limits: 8k and 16k tokens, measuring whether extended reasoning chains improve accuracy. Example comparisons of model predictions are provided in Appendix A.
思维链推理评测。 为评估 NSA 与先进下游训练范式的兼容性,我们考察它经后训练获得数学思维链推理能力的潜力。鉴于小规模模型上强化学习效果有限,我们从 DeepSeek-R1 做知识蒸馏,用 10B 个 32k 长度数学推理轨迹做监督微调(SFT),得到两可对比模型:Full Attention-R(全注意力基线)与 NSA-R(我们的稀疏变体)。在具有挑战性的美国数学邀请赛(AIME 24)基准上评估。采样温度 0.7、top- 0.95,每题生成 16 个回答取平均分。为验证推理深度影响,我们在 8k 与 16k 两种生成上下文上限下实验,衡量更长推理链是否提升准确率。模型预测示例见附录 A。
| Generation Token Limit | 8192 | 16384 |
|---|---|---|
| Full Attention-R | 0.046 | 0.092 |
| NSA-R | 0.121 | 0.146 |
Table 3: AIME Instruction-based Evaluating after supervised fine-tuning. Our NSA-R demonstrates better performance than Full Attention-R at both 8k and 16k sequence lengths
| Generation Token Limit | 8192 | 16384 |
|---|---|---|
| Full Attention-R | 0.046 | 0.092 |
| NSA-R | 0.121 | 0.146 |
表 3:监督微调后基于指令的 AIME 评测。NSA-R 在 8k 与 16k 序列长度上均优于 Full Attention-R。
As shown in Table 3, NSA-R achieves significantly higher accuracy than Full Attention-R under the 8k context setting (+0.075), with this advantage persisting at 16k contexts (+0.054). These results validate two key benefits of native sparse attention: (1) The pretrained sparse attention patterns enable efficient capture of long-range logical dependencies critical for complex mathematical derivations; (2) Our architecture’s hardware-aligned design maintains sufficient context density to support growing reasoning depth without catastrophic forgetting. The consistent outperformance across context lengths confirms sparse attention’s viability for advanced reasoning tasks when natively integrated into the training pipeline.
如表 3,NSA-R 在 8k 上下文设定下显著高于 Full Attention-R(+0.075),该优势在 16k 上下文仍保持(+0.054)。结果验证原生稀疏注意力的两点收益:(1)预训练稀疏注意力模式能高效捕获复杂数学推导所需的长程逻辑依赖;(2)架构的硬件对齐设计保持足够上下文密度,支持推理深度增长而不灾难性遗忘。跨上下文长度的持续领先确认:当原生融入训练流水线时,稀疏注意力对先进推理任务是可行的。
5 Efficiency Analysis
5 效率分析
We evaluate the computational efficiency of NSA against Full Attention on an 8-GPU A100 system. In efficiency analysis, we also configure the model with GQA group , heads per group , query/key dimension , and value dimension . Following the same settings in Section 4, we set NSA compression block size , sliding stride , selected block size , selected block count , and sliding window size .
我们在 8 卡 A100 系统上对比 NSA 与全注意力的计算效率。效率分析中模型同样配置 GQA 组数 、每组头数 、query/key 维 、value 维 。沿用第 4 节设定:NSA 压缩块长 、滑动步长 、选择块长 、选择块数 、滑动窗口 。
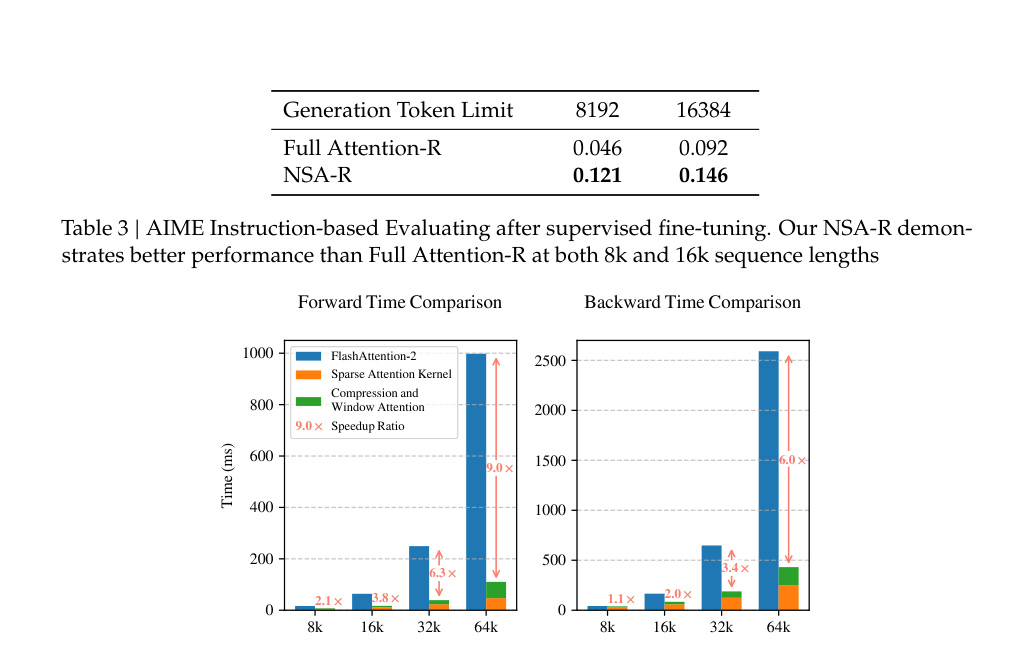
Figure 6: Comparison of Triton-based NSA kernel with Triton-based FlashAttention-2 kernel. Our implementation significantly reduces latency across all context lengths, with the improvement becoming more pronounced as input length increases.
图 6:基于 Triton 的 NSA kernel 与基于 Triton 的 FlashAttention-2 kernel 对比。我们的实现在各上下文长度上显著降低时延,且输入越长改进越明显。
5.1 Training Speed
5.1 训练速度
We compare the Triton-based implementations of our NSA attention and Full Attention with Triton-based FlashAttention-2 to ensure fair speed comparison across the same backend. As shown in Figure 6, our NSA achieves progressively greater speedups as context length increases, up to 9.0 forward and 6.0 backward speedup at 64k context-length. Notably, the speed advantage becomes more pronounced with longer sequences. This speedup stems from our hardware-aligned algorithm design to maximize the efficiency of sparse attention architecture: (1) The Blockwise memory access pattern maximizes Tensor Core utilization through coalesced loads, (2) The delicate loop scheduling in the kernel eliminates redundant KV transfers.
我们将基于 Triton 的 NSA 注意力与基于 Triton 的 FlashAttention-2 全注意力对比,以保证同一后端上的公平测速。如图 6,NSA 随上下文变长加速比逐步增大,在 64k 上下文可达前向 9.0、反向 6.0。序列越长,速度优势越明显。加速源于硬件对齐的算法设计以最大化稀疏注意力效率:(1)分块访存模式通过合并加载最大化 Tensor Core 利用率;(2)kernel 中精细的循环调度消除冗余 KV 传输。
| Context Length | 8192 | 16384 | 32768 | 65536 |
|---|---|---|---|---|
| Full Attention | 8192 | 16384 | 32768 | 65536 |
| NSA | 2048 | 2560 | 3584 | 5632 |
| Expected Speedup | 4 | 6.4 | 9.1 | 11.6 |
Table 4: Memory access volume (in equivalent number of tokens) per attention operation during decoding. Due to the low arithmetic intensity and memory-bound nature of decoding, the expected speedup is approximately linear with the volume of memory access.
| Context Length | 8192 | 16384 | 32768 | 65536 |
|---|---|---|---|---|
| Full Attention | 8192 | 16384 | 32768 | 65536 |
| NSA | 2048 | 2560 | 3584 | 5632 |
| Expected Speedup | 4 | 6.4 | 9.1 | 11.6 |
表 4:解码时每次注意力操作的访存量(等价 token 数)。由于解码算术强度低、受访存限制,期望加速比约与访存量成线性关系。
5.2 Decoding Speed
5.2 解码速度
The decoding speed of Attention is primarily determined by the memory access bottleneck, which is closely tied to the amount of KV cache loading. In each decoding step, Our NSA just needs to load at most compression tokens, selected tokens, and neighbor tokens, where is the cached sequence length. As shown in Table 4, our method exhibits a significant reduction in latency as the decoding length increases, achieving up to 11.6 speedup at 64k context-length. This advantage in memory access efficiency also amplifies with longer sequences.
注意力解码速度主要由访存瓶颈决定,与 KV cache 加载量密切相关。每步解码,NSA 至多只需加载 个压缩 token、 个选择 token 与 个邻近 token,其中 为已缓存序列长度。如表 4,随解码长度增加,方法显著降低时延,在 64k 上下文可达约 11.6 加速。该访存效率优势也随序列变长而放大。
6 Discussion
6 讨论
In this section, we reflect on the development process of NSA and discuss key insights gained from our exploration of different sparse attention strategies. While our approach demonstrates promising results, understanding the challenges encountered with alternative strategies and analyzing attention patterns provides valuable context for future research directions. We first examine challenges with alternative token selection strategies that motivated our design choices, followed by visualizations that offer insights into attention distribution patterns.
本节回顾 NSA 的研发过程,并讨论探索不同稀疏注意力策略时获得的关键洞见。尽管方法结果可观,理解替代策略遇到的挑战并分析注意力模式,对未来研究方向有价值。我们先考察促使我们设计选择的替代 token 选择策略所遇挑战,再通过可视化洞察注意力分布模式。
6.1 Challenges with Alternative Token Selection Strategies
6.1 替代 Token 选择策略的挑战
Before designing NSA, we explored adapting existing sparse attention methods to the training stage. However, these attempts encountered various challenges, prompting us to design a different sparse attention architecture:
设计 NSA 之前,我们探索过把现有稀疏注意力方法适配到训练阶段。这些尝试遇到多种挑战,促使我们设计不同的稀疏注意力架构:
Key-Clustering Based Strategies. We examined clustering-based strategies like ClusterKV (Liu et al., 2024). These methods store Keys and Values from the same cluster in contiguous memory regions. While theoretically feasible for training and inference, they face three significant challenges: (1) Non-trivial computational overhead introduced by dynamic clustering mechanisms; (2) Operator optimization difficulties exacerbated by inter-cluster imbalances, especially in Mixture-of-Experts (MoE) systems, where skewed Expert Parallelism (EP) group execution times lead to persistent load imbalances; (3) Implementation constraints arising from the need for mandatory periodic reclustering and chunk-sequential training protocols. These combined factors create substantial bottlenecks, significantly limiting their effectiveness for real-world deployment.
基于 Key 聚类的策略。 我们考察了 ClusterKV(Liu et al., 2024)一类聚类策略。它们把同簇的 Key/Value 存于连续内存区。理论上可训练与推理,但面临三点挑战:(1)动态聚类引入不可忽视的计算开销;(2)簇间不均衡加剧算子优化难度,尤其在 MoE 系统中,偏斜的专家并行(EP)组执行时间导致持续负载不均;(3)必须周期性重聚类与块序列训练协议带来实现约束。这些因素叠加形成实质瓶颈,显著限制真实部署效果。
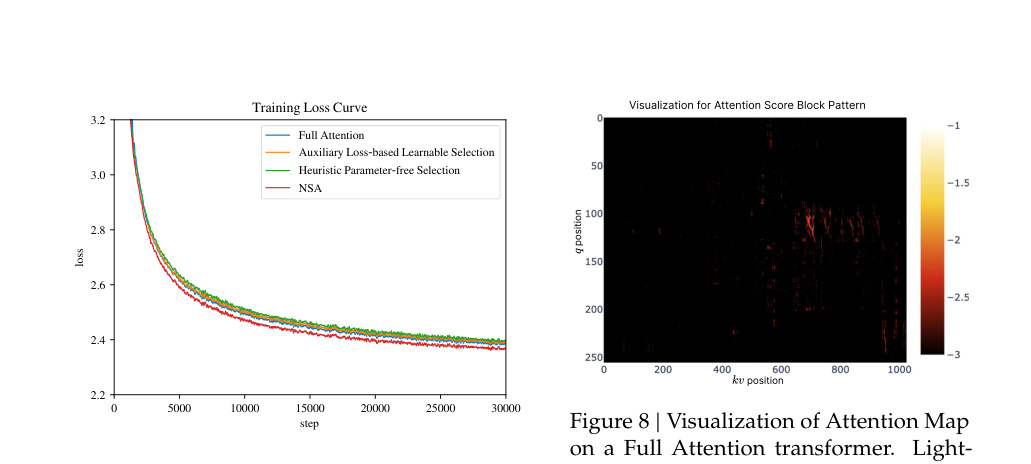
Figure 7: Compare training loss on a 3B-parameter model with Full Attention and different token selection strategies and. Our NSA achieves better performance.
图 7:在 3B 参数模型上,全注意力与不同 token 选择策略的训练损失对比。我们的 NSA 取得更好表现。
Other Blockwise Selection Strategies. We also considered blockwise key, value selection strategies different from NSA, such as Quest (Tang et al., 2024) and InfLLM (Xiao et al., 2024a). These methods rely on computing an importance score for each KV block and selecting the top- blocks based on their similarity with . However, existing methods face two critical issues: (1) Since the selection operation is non-differentiable, importance score computation based on neural networks relies on auxiliary loss, which increases operator overhead and often degrades model performance; (2) Heuristic parameter-free importance score computation strategy suffer from low recall rates, leading to suboptimal performance. We evaluate both approaches on a 3B-parameter model with similar architecture and compare their loss curve with NSA and Full Attention. For the auxiliary loss-based selection method, we introduce additional queries for each token and representative keys for each block to estimate the block importance scores. We compute block-level supervision signals by mean-pooling attention scores within each key block, and use KL divergence to supervise block importance prediction. We maintain individual query granularity instead of block-averaged queries to accommodate efficient decoding. This auxiliary loss-based importance estimation shares conceptual similarity with SeerAttention (Gao et al., 2024). For the heuristic parameter-free selection method, following the strategy of Quest, we implement direct selection using the product between queries and coordinate-wise min-max of the key chunks, without introducing additional parameters. We also explore a cold-start training approach where Full Attention is applied for the initial 1000 steps before transitioning to the heuristic blockwise selection. As shown in Figure 8, both methods exhibited inferior loss.
其他分块选择策略。 我们也考虑了与 NSA 不同的分块 key/value 选择,如 Quest(Tang et al., 2024)与 InfLLM(Xiao et al., 2024a)。这些方法为每个 KV 块算重要性分数,再按与 的相似度选 top- 块。但现有方法有两个关键问题:(1)选择操作不可微,基于神经网络的重要性计算依赖辅助损失,增加算子开销且常损害模型性能;(2)启发式无参重要性计算召回率低,导致次优表现。我们在架构相近的 3B 模型上评估两方法,并与 NSA、全注意力对比损失曲线。对基于辅助损失的选择,我们为每个 token 引入额外 query、为每块引入代表 key 以估计块重要性;对每块内注意力分数做均值池化得到块级监督信号,并用 KL 散度监督块重要性预测。我们保持单个 query 粒度而非块平均 query,以适配高效解码。该基于辅助损失的重要性估计在概念上类似 SeerAttention(Gao et al., 2024)。对启发式无参选择,遵循 Quest,用 query 与 key 块坐标逐维 min-max 的乘积直接选择,不引入额外参数。我们也探索冷启动:前 1000 步用全注意力,再切到启发式分块选择。如图 8,两方法损失均更差。
6.2 Visualization
6.2 可视化
To explore potential patterns in transformer attention distributions and seek inspiration for our design, we visualize the attention map from our pretrained 27B Full Attention model in Figure 8. The visualization reveals interesting patterns where attention scores tend to exhibit blockwise clustering characteristics, with nearby keys often showing similar attention scores. This observation inspired our design of NSA, suggesting that selecting key blocks based on spatial continuity might be a promising approach. The blockwise clustering phenomenon indicates that tokens adjacent in the sequence may share certain semantic relationships with query tokens, though the exact nature of these relationships requires further investigation. This observation motivated us to explore a sparse attention mechanism that operates on continuous token blocks rather than individual tokens, aiming to enhance computational efficiency and preserve high-attention patterns.
为探索 transformer 注意力分布中的潜在模式并为设计寻找启发,我们在图 8 可视化预训练 27B 全注意力模型的注意力图。可视化揭示有趣模式:注意力分数常呈分块聚类特征,邻近 key 往往有相近注意力分数。这一观察启发了 NSA 的设计,提示基于空间连续性选择 key 块或许可行。分块聚类现象表明序列相邻的 token 可能与 query token 共享某些语义关系,但其确切性质仍需进一步研究。这促使我们探索在连续 token 块而非单个 token 上运作的稀疏注意力,以期提升计算效率并保留高注意力模式。
7 Related Works
7 相关工作
We review existing approaches that improve the efficiency of attention computation through sparse attention. These methods can be broadly categorized into three groups based on their core strategies: (1) fixed sparse pattern, (2) dynamic token pruning, and (3) query-aware selection. We introduce several representative works from each category.
我们回顾通过稀疏注意力提升注意力计算效率的现有方法。按核心策略大致分为三类:(1)固定稀疏模式,(2)动态 token 剪枝,(3)query 感知选择。每类介绍若干代表工作。
7.1 Fixed Sparse Pattern
7.1 固定稀疏模式
SlidingWindow is a commonly used approach that allows the query to compute attention only within a fixed window. StreamingLLM (Xiao et al., 2023) combines attention sinks with local windows to process continuous text streams. MoA (Fu et al., 2024a) and DuoAttention (Xiao et al., 2024b) also adopt similar local and sink information for long sequence modeling. Longformer (Beltagy et al., 2020) interleaves local windowed attention with global tokens to process long sequences. Compared with them, our NSA does not rely on pre-defined sparse patterns, but learns the patterns automatically, unlocking the potential to utilize full context.
SlidingWindow 是常用做法,让 query 只在固定窗口内计算注意力。StreamingLLM(Xiao et al., 2023)把注意力汇(attention sinks)与局部窗口结合处理连续文本流。MoA(Fu et al., 2024a)与 DuoAttention(Xiao et al., 2024b)也采用类似局部与汇信息做长序列建模。Longformer(Beltagy et al., 2020)将局部窗口注意力与全局 token 交错以处理长序列。相较之下,NSA 不依赖预定义稀疏模式,而是自动学习模式,释放利用全文上下文的潜力。
7.2 Dynamic Token Pruning
7.2 动态 Token 剪枝
Some methods are designed to reduce memory and computation costs during inference through dynamic KV-cache pruning. H2O (Zhang et al., 2023b), BUZZ (Zhao et al., 2024), and SepLLM (Chen et al., 2024a) implement adaptive approaches to reduce KV-cache memory usage during decoding. These methods dynamically evict tokens deemed less important for future predictions. FastGen Ge et al. (2023) and HeadKV (Fu et al., 2024b) optimize computation by assigning different strategies to individual attention heads. SnapKV (Li et al., 2024) introduces a token pruning strategy that reduces the KV-cache by selectively retaining only the most crucial features, enabling efficient memory usage. Unlike these inference-focused approaches, our NSA incorporates sparsity natively during the training phase.
一些方法通过动态 KV-cache 剪枝降低推理期内存与计算。H2O(Zhang et al., 2023b)、BUZZ(Zhao et al., 2024)与 SepLLM(Chen et al., 2024a)用自适应方式降低解码时 KV-cache 内存,动态驱逐对未来预测较不重要的 token。FastGen(Ge et al., 2023)与 HeadKV(Fu et al., 2024b)为不同注意力头分配不同策略以优化计算。SnapKV(Li et al., 2024)引入 token 剪枝,选择性保留最关键特征以高效用内存。与这些面向推理的方法不同,NSA 在训练阶段就原生纳入稀疏。
7.3 Query-Aware Selection
7.3 Query 感知选择
Other works focus on query-dependent token selection methods to reduce attention computation while preserving attention quality. Quest (Tang et al., 2024) employs a blockwise selection strategy where each chunk’s importance is estimated by product between query and coordinate-wise min-max of the key chunks. InfLLM (Xiao et al., 2024a) combines fixed patterns with retrieval by maintaining attention sinks, local context, and retrievable chunks. This method selects representative keys from each chunk to estimate chunk importance. HashAttention (Desai et al., 2024) formulates pivotal token identification as a recommendation problem by mapping queries and keys to Hamming space using learned functions. ClusterKV (Liu et al., 2024) achieves sparsity by firstly clustering keys and then selecting the most relevant clusters for attention computation based on query-cluster similarity. MInference (Jiang et al., 2024) and TokenSelect (Wu et al., 2024) select KV pairs for computation based on token-level importance scoring. SeerAttention (Gao et al., 2024) separates queries and keys into spatial blocks and performs blockwise selection for efficient computation. Compared to these methods, our NSA achieves hardware-aligned sparse attention computation throughout the full model lifecycle, including training, prefilling, and decoding.
另一些工作聚焦依赖 query 的 token 选择,以在保注意力质量的同时降低计算。Quest(Tang et al., 2024)用分块选择:每块重要性由 query 与 key 块坐标逐维 min-max 的乘积估计。InfLLM(Xiao et al., 2024a)把固定模式与检索结合,保持注意力汇、局部上下文与可检索块,从每块选代表 key 估计块重要性。HashAttention(Desai et al., 2024)把关键 token 识别表述为推荐问题,用学习函数把 query/key 映到汉明空间。ClusterKV(Liu et al., 2024)先聚类 key,再按 query–簇相似度选最相关簇做注意力。MInference(Jiang et al., 2024)与 TokenSelect(Wu et al., 2024)按 token 级重要性选 KV 对。SeerAttention(Gao et al., 2024)把 query/key 分成空间块并做分块选择。相较这些方法,NSA 在训练、prefilling 与解码的全模型生命周期中实现硬件对齐的稀疏注意力计算。
8 Conclusion
8 结论
We present NSA, a hardware-aligned sparse attention architecture for efficient long-context modeling. By integrating hierarchical token compression with blockwise token selection within a trainable architecture, our architecture achieves accelerated training and inference while maintaining Full Attention performance. NSA advances the state-of-the-art by demonstrating general benchmark performance matches full-attention baselines, exceeding modeling capability in long-context evaluations, and enhanced reasoning ability, all accompanied by measurable reductions in computational latency and achieving significant speedup.
我们提出 NSA——面向高效长上下文建模的硬件对齐稀疏注意力架构。通过在可训练架构中融合分层 token 压缩与分块 token 选择,NSA 在保持全注意力性能的同时加速训练与推理。NSA 推进了前沿:通用基准匹配全注意力基线,长上下文评测上建模能力更强,推理能力提升,同时可测地降低计算时延并取得显著加速。
References
参考文献
Ainslie et al. (2023) J. Ainslie, J. Lee-Thorp, M. de Jong, Y. Zemlyanskiy, F. Lebrón, and S. Sanghai. Gqa: Training generalized multi-query transformer models from multi-head checkpoints. arXiv preprint arXiv:2305.13245 , 2023.
Austin et al. (2021) J. Austin, A. Odena, M. Nye, M. Bosma, H. Michalewski, D. Dohan, E. Jiang, C. Cai, M. Terry, Q. Le, et al. Program synthesis with large language models. arXiv preprint arXiv:2108.07732 , 2021.
Bai et al. (2023) Y. Bai, X. Lv, J. Zhang, H. Lyu, J. Tang, Z. Huang, Z. Du, X. Liu, A. Zeng, L. Hou, et al. Longbench: A bilingual, multitask benchmark for long context understanding. arXiv preprint arXiv:2308.14508 , 2023.
Beltagy et al. (2020) I. Beltagy, M. E. Peters, and A. Cohan. Longformer: The long-document transformer. arXiv preprint arXiv:2004.05150 , 2020.
Chen et al. (2024a) G. Chen, H. Shi, J. Li, Y. Gao, X. Ren, Y. Chen, X. Jiang, Z. Li, W. Liu, and C. Huang. Sepllm: Accelerate large language models by compressing one segment into one separator. arXiv preprint arXiv:2412.12094 , 2024a.
Chen et al. (2021) M. Chen, J. Tworek, H. Jun, Q. Yuan, H. P. D. O. Pinto, J. Kaplan, H. Edwards, Y. Burda, N. Joseph, G. Brockman, et al. Evaluating large language models trained on code. arXiv preprint arXiv:2107.03374 , 2021.
Chen et al. (2024b) Z. Chen, R. Sadhukhan, Z. Ye, Y. Zhou, J. Zhang, N. Nolte, Y. Tian, M. Douze, L. Bottou, Z. Jia, et al. Magicpig: Lsh sampling for efficient llm generation. arXiv preprint arXiv:2410.16179 , 2024b.
Cobbe et al. (2021) K. Cobbe, V. Kosaraju, M. Bavarian, M. Chen, H. Jun, L. Kaiser, M. Plappert, J. Tworek, J. Hilton, R. Nakano, et al. Training verifiers to solve math word problems, 2021. URL https://arxiv. org/abs/2110.14168 , 2021.
Dai et al. (2024) D. Dai, C. Deng, C. Zhao, R. Xu, H. Gao, D. Chen, J. Li, W. Zeng, X. Yu, Y. Wu, et al. Deepseekmoe: Towards ultimate expert specialization in mixture-of-experts language models. arXiv preprint arXiv:2401.06066 , 2024.
DeepSeek-AI (2024) DeepSeek-AI. Deepseek-v2: A strong, economical, and efficient mixture-of-experts language model. 2024. URL https://arxiv.org/abs/2405.04434 .
DeepSeek-AI (2025) DeepSeek-AI. Deepseek-r1: Incentivizing reasoning capability in llms via reinforcement learning, 2025. URL https://arxiv.org/abs/2501.12948 .
Desai et al. (2024) A. Desai, S. Yang, A. Cuadron, A. Klimovic, M. Zaharia, J. E. Gonzalez, and I. Stoica. Hashattention: Semantic sparsity for faster inference. arXiv preprint arXiv:2412.14468 , 2024.
Dua et al. (2019) D. Dua, Y. Wang, P. Dasigi, G. Stanovsky, S. Singh, and M. Gardner. Drop: A reading comprehension benchmark requiring discrete reasoning over paragraphs. arXiv preprint arXiv:1903.00161 , 2019.
Fu et al. (2024a) T. Fu, H. Huang, X. Ning, G. Zhang, B. Chen, T. Wu, H. Wang, Z. Huang, S. Li, S. Yan, et al. Moa: Mixture of sparse attention for automatic large language model compression. arXiv preprint arXiv:2406.14909 , 2024a.
Fu et al. (2024b) Y. Fu, Z. Cai, A. Asi, W. Xiong, Y. Dong, and W. Xiao. Not all heads matter: A head-level kv cache compression method with integrated retrieval and reasoning. arXiv preprint arXiv:2410.19258 , 2024b.
Gao et al. (2024) Y. Gao, Z. Zeng, D. Du, S. Cao, H. K.-H. So, T. Cao, F. Yang, and M. Yang. Seerattention: Learning intrinsic sparse attention in your llms. arXiv preprint arXiv:2410.13276 , 2024.
Ge et al. (2023) S. Ge, Y. Zhang, L. Liu, M. Zhang, J. Han, and J. Gao. Model tells you what to discard: Adaptive kv cache compression for llms. arXiv preprint arXiv:2310.01801 , 2023.
Google et al. (2024) G. T. Google, P. Georgiev, V. I. Lei, R. Burnell, L. Bai, A. Gulati, G. Tanzer, D. Vincent, Z. Pan, S. Wang, et al. Gemini 1.5: Unlocking multimodal understanding across millions of tokens of context. arXiv preprint arXiv:2403.05530 , 2024.
Hendrycks et al. (2020) D. Hendrycks, C. Burns, S. Basart, A. Zou, M. Mazeika, D. Song, and J. Steinhardt. Measuring massive multitask language understanding. arXiv preprint arXiv:2009.03300 , 2020.
Jiang et al. (2023) H. Jiang, Q. Wu, C.-Y. Lin, Y. Yang, and L. Qiu. Llmlingua: Compressing prompts for accelerated inference of large language models. arXiv preprint arXiv:2310.05736 , 2023.
Jiang et al. (2024) H. Jiang, Y. Li, C. Zhang, Q. Wu, X. Luo, S. Ahn, Z. Han, A. H. Abdi, D. Li, C.-Y. Lin, et al. Minference 1.0: Accelerating pre-filling for long-context llms via dynamic sparse attention. arXiv preprint arXiv:2407.02490 , 2024.
Kamradt (2023) G. Kamradt. LLMTest NeedleInAHaystack. GitHub repository, 2023. URL https://github.com/gkamradt/LLMTest_NeedleInAHaystack . Accessed: [Insert Access Date Here].
Li et al. (2023) H. Li, Y. Zhang, F. Koto, Y. Yang, H. Zhao, Y. Gong, N. Duan, and T. Baldwin. Cmmlu: Measuring massive multitask language understanding in chinese. arXiv preprint arXiv:2306.09212 , 2023.
Li et al. (2024) Y. Li, Y. Huang, B. Yang, B. Venkitesh, A. Locatelli, H. Ye, T. Cai, P. Lewis, and D. Chen. Snapkv: Llm knows what you are looking for before generation. arXiv preprint arXiv:2404.14469 , 2024.
Liu et al. (2024) G. Liu, C. Li, J. Zhao, C. Zhang, and M. Guo. Clusterkv: Manipulating llm kv cache in semantic space for recallable compression. arXiv preprint arXiv:2412.03213 , 2024.
Park et al. (2023) J. S. Park, J. C. O’Brien, C. J. Cai, M. R. Morris, P. Liang, and M. S. Bernstein. Generative agents: Interactive simulacra of human behavior. In S. Follmer, J. Han, J. Steimle, and N. H. Riche, editors, Proceedings of the 36th Annual ACM Symposium on User Interface Software and Technology, UIST 2023, San Francisco, CA, USA, 29 October 2023– 1 November 2023 , pages 2:1–2:22. ACM, 2023.
Peng et al. (2024) B. Peng, J. Quesnelle, H. Fan, and E. Shippole. Yarn: Efficient context window extension of large language models. In ICLR . OpenReview.net, 2024.
Shazeer (2019) N. Shazeer. Fast transformer decoding: One write-head is all you need. CoRR , abs/1911.02150, 2019.
Suzgun et al. (2022) M. Suzgun, N. Scales, N. Schärli, S. Gehrmann, Y. Tay, H. W. Chung, A. Chowdhery, Q. V. Le, E. H. Chi, D. Zhou, et al. Challenging big-bench tasks and whether chain-of-thought can solve them. arXiv preprint arXiv:2210.09261 , 2022.
Tang et al. (2024) J. Tang, Y. Zhao, K. Zhu, G. Xiao, B. Kasikci, and S. Han. Quest: Query-aware sparsity for efficient long-context llm inference. arXiv preprint arXiv:2406.10774 , 2024.
Tillet et al. (2019) P. Tillet, H.-T. Kung, and D. Cox. Triton: an intermediate language and compiler for tiled neural network computations. In Proceedings of the 3rd ACM SIGPLAN International Workshop on Machine Learning and Programming Languages , pages 10–19, 2019.
Vaswani et al. (2017) A. Vaswani, N. Shazeer, N. Parmar, J. Uszkoreit, L. Jones, A. N. Gomez, L. u. Kaiser, and I. Polosukhin. Attention is all you need. Advances in Neural Information Processing Systems , 2017.
Wang et al. (2024) Y. Wang, X. Ma, G. Zhang, Y. Ni, A. Chandra, S. Guo, W. Ren, A. Arulraj, X. He, Z. Jiang, et al. Mmlu-pro: A more robust and challenging multi-task language understanding benchmark. arXiv preprint arXiv:2406.01574 , 2024.
Wei et al. (2022) J. Wei, X. Wang, D. Schuurmans, M. Bosma, F. Xia, E. Chi, Q. V. Le, D. Zhou, et al. Chain-of-thought prompting elicits reasoning in large language models. Advances in neural information processing systems , 35:24824–24837, 2022.
Wu et al. (2024) W. Wu, Z. Pan, C. Wang, L. Chen, Y. Bai, K. Fu, Z. Wang, and H. Xiong. Tokenselect: Efficient long-context inference and length extrapolation for llms via dynamic token-level kv cache selection. arXiv preprint arXiv:2411.02886 , 2024.
Xiao et al. (2024a) C. Xiao, P. Zhang, X. Han, G. Xiao, Y. Lin, Z. Zhang, Z. Liu, and M. Sun. Infllm: Training-free long-context extrapolation for llms with an efficient context memory. In The Thirty-eighth Annual Conference on Neural Information Processing Systems , 2024a.
Xiao et al. (2023) G. Xiao, Y. Tian, B. Chen, S. Han, and M. Lewis. Efficient streaming language models with attention sinks. arXiv preprint arXiv:2309.17453 , 2023.
Xiao et al. (2024b) G. Xiao, J. Tang, J. Zuo, J. Guo, S. Yang, H. Tang, Y. Fu, and S. Han. Duoattention: Efficient long-context llm inference with retrieval and streaming heads. arXiv preprint arXiv:2410.10819 , 2024b.
Zaheer et al. (2020) M. Zaheer, G. Guruganesh, K. A. Dubey, J. Ainslie, C. Alberti, S. Ontanon, P. Pham, A. Ravula, Q. Wang, L. Yang, et al. Big bird: Transformers for longer sequences. Advances in neural information processing systems , 33:17283–17297, 2020.
Zelikman et al. (2022) E. Zelikman, Y. Wu, J. Mu, and N. D. Goodman. Star: Bootstrapping reasoning with reasoning. In S. Koyejo, S. Mohamed, A. Agarwal, D. Belgrave, K. Cho, and A. Oh, editors, Advances in Neural Information Processing Systems 35: Annual Conference on Neural Information Processing Systems 2022, NeurIPS 2022, New Orleans, LA, USA, November 28 – December 9, 2022 , 2022.
Zhang et al. (2023a) F. Zhang, B. Chen, Y. Zhang, J. Keung, J. Liu, D. Zan, Y. Mao, J. Lou, and W. Chen. Repocoder: Repository-level code completion through iterative retrieval and generation. In H. Bouamor, J. Pino, and K. Bali, editors, Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing, EMNLP 2023, Singapore, December 6–10, 2023 , pages 2471–2484. Association for Computational Linguistics, 2023a.
(42) K. Zhang, J. Li, G. Li, X. Shi, and Z. Jin. Codeagent: Enhancing code generation with tool-integrated agent systems for real-world repo-level coding challenges. In L. Ku, A. Martins, and V. Srikumar, editors, Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), ACL 2024, Bangkok, Thailand, August 11–16, 2024 , pages 13643–13658.
Zhang et al. (2023b) Z. Zhang, Y. Sheng, T. Zhou, T. Chen, L. Zheng, R. Cai, Z. Song, Y. Tian, C. Ré, C. Barrett, et al. H2o: Heavy-hitter oracle for efficient generative inference of large language models. Advances in Neural Information Processing Systems , 36:34661–34710, 2023b.
Zhao et al. (2024) J. Zhao, Z. Fang, S. Li, S. Yang, and S. He. Buzz: Beehive-structured sparse kv cache with segmented heavy hitters for efficient llm inference. arXiv preprint arXiv:2410.23079 , 2024.
Zhou et al. (2024) Z. Zhou, C. Li, X. Chen, S. Wang, Y. Chao, Z. Li, H. Wang, R. An, Q. Shi, Z. Tan, et al. Llm × \times mapreduce: Simplified long-sequence processing using large language models. arXiv preprint arXiv:2410.09342 , 2024.
Appendix A Example of AIME Results
附录 A AIME 结果示例
$$\begin{cases}\log_{2}(x)-\log_{2}(y)-\log_{2}(z)=\frac{1}{2}\
\log_{2}(y)-\log_{2}(x)-\log_{2}(z)=\frac{1}{3}\
\log_{2}(z)-\log_{2}(x)-\log_{2}(y)=\frac{1}{4}\end{cases}$$
$$\begin{cases}A-B-C=\frac{1}{2}\
B-A-C=\frac{1}{3}\
C-A-B=\frac{1}{4}\end{cases}$$