MobileNetV2: Inverted Residuals and Linear Bottlenecks
MobileNetV2: Inverted Residuals and Linear Bottlenecks
MobileNetV2:倒残差与线性瓶颈
Mark Sandler Andrew Howard Menglong Zhu Andrey Zhmoginov Liang-Chieh Chen Google Inc. {sandler, howarda, menglong, azhmogin, lcchen}@google.com
Abstract
摘要
In this paper we describe a new mobile architecture, MobileNetV2, that improves the state of the art performance of mobile models on multiple tasks and benchmarks as well as across a spectrum of different model sizes. We also describe efficient ways of applying these mobile models to object detection in a novel framework we call SSDLite. Additionally, we demonstrate how to build mobile semantic segmentation models through a reduced form of DeepLabv3 which we call Mobile DeepLabv3.
本文描述一种新的移动端架构 MobileNetV2:它在多项任务和基准上提升了移动模型的当时最优表现,并且覆盖一系列不同的模型规模。我们还说明如何在一种称为 SSDLite 的新框架里,把这些移动模型高效用于目标检测。此外,我们展示如何通过精简版 DeepLabv3(称为 Mobile DeepLabv3)构建移动端语义分割模型。
is based on an inverted residual structure where the shortcut connections are between the thin bottleneck layers. The intermediate expansion layer uses lightweight depthwise convolutions to filter features as a source of non-linearity. Additionally, we find that it is important to remove non-linearities in the narrow layers in order to maintain representational power. We demonstrate that this improves performance and provide an intuition that led to this design.
其基础是倒残差结构:捷径连接加在较窄的瓶颈层之间。中间的扩展层用轻量深度卷积过滤特征,作为非线性的来源。我们还发现,为了保持表征能力,有必要去掉窄层中的非线性。我们证明这一点能提升性能,并给出促成这一设计的直观理由。
Finally, our approach allows decoupling of the input/output domains from the expressiveness of the transformation, which provides a convenient framework for further analysis. We measure our performance on ImageNet Russakovsky:2015:ILS:2846547.2846559 classification, COCO object detection COCO, VOC image segmentation PASCAL. We evaluate the trade-offs between accuracy, and number of operations measured by multiply-adds (MAdd), as well as actual latency, and the number of parameters.
最后,我们的方法把输入/输出域与变换的表达能力分开,为进一步分析提供了方便的框架。我们在 ImageNet 分类、COCO 目标检测和 VOC 图像分割上衡量表现,并评估精度与乘法–加法次数(MAdd)、实际延迟以及参数量之间的权衡。
1 Introduction
1 引言
Neural networks have revolutionized many areas of machine intelligence, enabling superhuman accuracy for challenging image recognition tasks. However, the drive to improve accuracy often comes at a cost: modern state of the art networks require high computational resources beyond the capabilities of many mobile and embedded applications.
神经网络已经改变了机器智能的许多领域,使具有挑战性的图像识别任务达到超人类精度。然而,追求更高精度往往要付出代价:现代最优网络所需的计算资源,超出了许多移动和嵌入式应用的能力。
This paper introduces a new neural network architecture that is specifically tailored for mobile and resource constrained environments. Our network pushes the state of the art for mobile tailored computer vision models, by significantly decreasing the number of operations and memory needed while retaining the same accuracy.
本文提出一种专门面向移动和资源受限环境的神经网络架构。我们的网络显著减少了所需运算量和内存,同时保持相同精度,从而推进了面向移动端的计算机视觉模型。
Our main contribution is a novel layer module: the inverted residual with linear bottleneck. This module takes as an input a low-dimensional compressed representation which is first expanded to high dimension and filtered with a lightweight depthwise convolution. Features are subsequently projected back to a low-dimensional representation with a linear convolution. The official implementation is available as part of TensorFlow-Slim model library in MobilenetV2-implementation.
我们的主要贡献是一种新的层模块:带线性瓶颈的倒残差。该模块接收低维压缩表征,先扩展到高维,再用轻量深度卷积过滤,随后用线性卷积投影回低维表征。官方实现作为 TensorFlow-Slim 模型库的一部分发布,见 MobilenetV2-implementation。
This module can be efficiently implemented using standard operations in any modern framework and allows our models to beat state of the art along multiple performance points using standard benchmarks. Furthermore, this convolutional module is particularly suitable for mobile designs, because it allows to significantly reduce the memory footprint needed during inference by never fully materializing large intermediate tensors. This reduces the need for main memory access in many embedded hardware designs, that provide small amounts of very fast software controlled cache memory.
该模块可以用任何现代框架中的标准运算高效实现,并使我们的模型在多个性能点上、按标准基准超过当时最优。此外,这一卷积模块特别适合移动端设计,因为它在推理时不必完整物化大型中间张量,从而显著降低内存占用。许多嵌入式硬件只提供少量由软件控制的高速缓存,减少对主存的访问因此很重要。
2 Related Work
2 相关工作
Tuning deep neural architectures to strike an optimal balance between accuracy and performance has been an area of active research for the last several years. Both manual architecture search and improvements in training algorithms, carried out by numerous teams has lead to dramatic improvements over early designs such as AlexNet AlexNet, VGGNet VGGNet, GoogLeNet GoogleNet. , and ResNet ResNet. Recently there has been lots of progress in algorithmic architecture exploration included hyper-parameter optimization BergstraRandomSearch; BayesianOptimizationML; BayesianOptimizationDNN as well as various methods of network pruning BrainSurgeon; BrainDamage; Han2015; Han2016; Guo2016; LiPruning and connectivity learning ConnectivityLearning; BudgetedSuperNetworks. A substantial amount of work has also been dedicated to changing the connectivity structure of the internal convolutional blocks such as in ShuffleNet ShuffleNet2017 or introducing sparsity PowerOfSparsity and others SpatialBottleneck2016.
过去几年里,调节深度神经架构以在精度与性能之间取得最佳平衡,一直是活跃的研究方向。众多团队进行的手工架构搜索和训练算法改进,相对 AlexNet、VGGNet、GoogLeNet 和 ResNet 等早期设计带来了显著提升。最近,算法化的架构探索进展很多,包括超参数优化,以及各种网络剪枝和连接学习方法。也有大量工作改变内部卷积块的连接结构,例如 ShuffleNet,或引入稀疏性等。
Recently, LearningToLearnScale; GeneticCNN; EvolutionImageClassifiers; NAS_reinforcement, opened up a new direction of bringing optimization methods including genetic algorithms and reinforcement learning to architectural search. However one drawback is that the resulting networks end up very complex. In this paper, we pursue the goal of developing better intuition about how neural networks operate and use that to guide the simplest possible network design. Our approach should be seen as complimentary to the one described in LearningToLearnScale and related work. In this vein our approach is similar to those taken by ShuffleNet2017; SpatialBottleneck2016 and allows to further improve the performance, while providing a glimpse on its internal operation. Our network design is based on MobileNetV1 MobilenetV1. It retains its simplicity and does not require any special operators while significantly improves its accuracy, achieving state of the art on multiple image classification and detection tasks for mobile applications.
近来,把遗传算法和强化学习等优化方法引入架构搜索开辟了新方向。缺点是得到的网络往往非常复杂。本文希望更好地理解神经网络如何工作,并用这种直觉指导尽可能简单的网络设计。我们的方法应看作对 LearningToLearnScale 及相关工作的补充。在这一思路上,它与 ShuffleNet、SpatialBottleneck 等相近,既能进一步提升性能,也能让人看到内部运作的一斑。我们的网络设计基于 MobileNetV1,保留了它的简洁性,不需要任何特殊算子,同时显著提高精度,在多项面向移动应用的图像分类和检测任务上达到当时最优。
3 Preliminaries, discussion and intuition
3 预备知识、讨论与直觉
3.1 Depthwise Separable Convolutions
3.1 深度可分离卷积
Depthwise Separable Convolutions are a key building block for many efficient neural network architectures MobilenetV1; Chollet_2017_CVPR; ShuffleNet2017 and we use them in the present work as well. The basic idea is to replace a full convolutional operator with a factorized version that splits convolution into two separate layers. The first layer is called a depthwise convolution, it performs lightweight filtering by applying a single convolutional filter per input channel. The second layer is a convolution, called a pointwise convolution, which is responsible for building new features through computing linear combinations of the input channels.
深度可分离卷积是许多高效神经网络架构的关键构件,本文同样使用它们。基本想法是用分解版本替换完整卷积算子,把卷积拆成两层。第一层称为深度卷积,对每个输入通道施加一个卷积滤波器,做轻量过滤。第二层是 卷积,称为逐点卷积,通过计算输入通道的线性组合来构建新特征。
Standard convolution takes an input tensor , and applies convolutional kernel to produce an output tensor . Standard convolutional layers have the computational cost of .
标准卷积接收 的输入张量 ,施加卷积核 ,得到 的输出张量 。标准卷积层的计算代价是 。
Depthwise separable convolutions are a drop-in replacement for standard convolutional layers. Empirically they work almost as well as regular convolutions but only cost:
深度可分离卷积可以替换标准卷积层。经验上它们几乎与常规卷积一样好,但代价仅为:
which is the sum of the depthwise and pointwise convolutions. Effectively depthwise separable convolution reduces computation compared to traditional layers by almost a factor of [^1]. MobileNetV2 uses ( depthwise separable convolutions) so the computational cost is to times smaller than that of standard convolutions at only a small reduction in accuracy MobilenetV1.
也就是深度卷积与 逐点卷积之和。相对于传统层,深度可分离卷积几乎把计算量降低了 倍[^1]。MobileNetV2 使用 ( 深度可分离卷积),因此计算代价比标准卷积小 8 到 9 倍,精度只略有下降。
3.2 Linear Bottlenecks
3.2 线性瓶颈
Consider a deep neural network consisting of layers each of which has an activation tensor of dimensions . Throughout this section we will be discussing the basic properties of these activation tensors, which we will treat as containers of “pixels” with dimensions. Informally, for an input set of real images, we say that the set of layer activations (for any layer ) forms a “manifold of interest”. It has been long assumed that manifolds of interest in neural networks could be embedded in low-dimensional subspaces. In other words, when we look at all individual -channel pixels of a deep convolutional layer, the information encoded in those values actually lie in some manifold, which in turn is embeddable into a low-dimensional subspace[^2].
考虑一个由 层 组成的深度网络,每层有维度为 的激活张量。本节将讨论这些激活张量的基本性质,并把它们看作 个“像素”、每个像素有 维的容器。非正式地说,对于一组真实输入图像,我们称(任意层 的)层激活集合构成“感兴趣流形”。人们长期以来假定,神经网络中的感兴趣流形可以嵌入低维子空间。换句话说,当我们观察深度卷积层中所有单个 通道像素时,这些值所编码的信息实际上位于某个流形上,而该流形又能嵌入一个低维子空间[^2]。
At a first glance, such a fact could then be captured and exploited by simply reducing the dimensionality of a layer thus reducing the dimensionality of the operating space. This has been successfully exploited by MobileNetV1 MobilenetV1 to effectively trade off between computation and accuracy via a width multiplier parameter, and has been incorporated into efficient model designs of other networks as well ShuffleNet2017. Following that intuition, the width multiplier approach allows one to reduce the dimensionality of the activation space until the manifold of interest spans this entire space. However, this intuition breaks down when we recall that deep convolutional neural networks actually have non-linear per coordinate transformations, such as . For example, applied to a line in 1D space produces a ’ray’, where as in space, it generally results in a piece-wise linear curve with -joints.
乍看之下,这一事实似乎只需降低层的维度、从而降低工作空间的维度就能捕捉并利用。MobileNetV1 已成功用宽度乘数在计算与精度之间权衡,其他高效模型设计也吸收了这一点。按这种直觉,宽度乘数可以把激活空间的维度降到感兴趣流形刚好张满整个空间为止。然而,一旦记起深度卷积网络实际上有逐坐标的非线性变换(例如 ),这一直觉就站不住了。例如,把 作用到一维空间中的一条直线会得到一条“射线”;而在 中,它一般会得到带 个关节的分段线性曲线。
It is easy to see that in general if a result of a layer transformation has a non-zero volume , the points mapped to are obtained via a linear transformation of the input, thus indicating that the part of the input space corresponding to the full dimensional output, is limited to a linear transformation. In other words, deep networks only have the power of a linear classifier on the non-zero volume part of the output domain. We refer to supplemental material for a more formal statement.
不难看出,一般情形下,若层变换 的结果具有非零体积 ,则映射到 的点是通过输入的线性变换 得到的,这表明对应于满维输出的那部分输入空间,仅限于一次线性变换。换句话说,深度网络在输出域的非零体积部分上,只有线性分类器的能力。更形式的陈述见补充材料。
On the other hand, when collapses the channel, it inevitably loses information in that channel. However if we have lots of channels, and there is a a structure in the activation manifold that information might still be preserved in the other channels. In supplemental materials, we show that if the input manifold can be embedded into a significantly lower-dimensional subspace of the activation space then the transformation preserves the information while introducing the needed complexity into the set of expressible functions.
另一方面,当 把某个通道压塌时,它不可避免地丢失该通道中的信息。但如果通道很多,且激活流形具有结构,信息仍可能保存在其他通道里。补充材料表明:若输入流形可以嵌入激活空间中一个显著更低维的子空间,则 变换在引入所需复杂性的同时仍能保留信息。
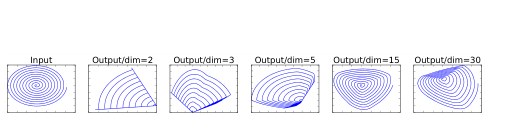
Figure 1: Examples of transformations of low-dimensional manifolds embedded in higher-dimensional spaces. In these examples the initial spiral is embedded into an -dimensional space using random matrix followed by , and then projected back to the 2D space using . In examples above result in information loss where certain points of the manifold collapse into each other, while for to the transformation is highly non-convex.
图 1: 对嵌入高维空间的低维流形所做变换的例子。这些例子里,初始螺旋线用随机矩阵 嵌入 维空间,再经过 ,然后用 投影回二维。上面的例子中, 会造成信息损失,流形上某些点会互相塌缩;而 到 时,变换高度非凸。
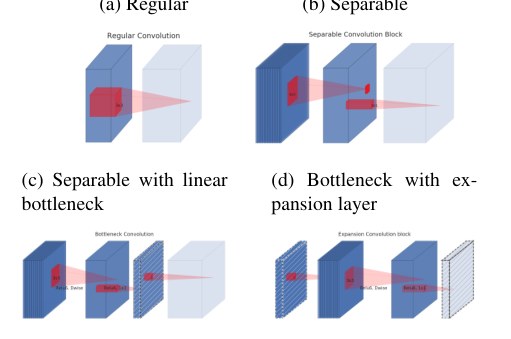
Figure 2: Evolution of separable convolution blocks. The diagonally hatched texture indicates layers that do not contain non-linearities. The last (lightly colored) layer indicates the beginning of the next block. Note: 2d and 2c are equivalent blocks when stacked. Best viewed in color.
图 2:可分离卷积块的演变。对角阴影纹理表示不含非线性的层。最后一层(浅色)表示下一块的开始。注意:堆叠时 2d 与 2c 是等价块。请看彩色图。
To summarize, we have highlighted two properties that are indicative of the requirement that the manifold of interest should lie in a low-dimensional subspace of the higher-dimensional activation space:
概括起来,我们强调了两点,它们表明感兴趣流形应当位于更高维激活空间的一个低维子空间中:
- If the manifold of interest remains non-zero volume after transformation, it corresponds to a linear transformation.
- 若感兴趣流形在 变换后仍保持非零体积,则它对应于一次线性变换。
- is capable of preserving complete information about the input manifold, but only if the input manifold lies in a low-dimensional subspace of the input space.
- 能够保留关于输入流形的完整信息,但仅当输入流形位于输入空间的一个低维子空间时。
These two insights provide us with an empirical hint for optimizing existing neural architectures: assuming the manifold of interest is low-dimensional we can capture this by inserting linear bottleneck layers into the convolutional blocks. Experimental evidence suggests that using linear layers is crucial as it prevents non-linearities from destroying too much information. In Section 6, we show empirically that using non-linear layers in bottlenecks indeed hurts the performance by several percent, further validating our hypothesis[^3]. We note that similar reports where non-linearity was helped were reported in DeepPyramidalNetworks where non-linearity was removed from the input of the traditional residual block and that lead to improved performance on CIFAR dataset.
这两点洞察为我们优化现有神经架构提供了经验提示:假定感兴趣流形是低维的,就可以通过在卷积块中插入线性瓶颈层来捕捉这一点。实验证据表明,使用线性层至关重要,因为它能防止非线性破坏过多信息。第 6 节我们经验上表明,在瓶颈中使用非线性层确实会使性能下降几个百分点,进一步验证了这一假设[^3]。我们注意到,DeepPyramidalNetworks 也报告过类似情况:从传统残差块的输入去掉非线性,在 CIFAR 上带来了更好的表现。
For the remainder of this paper we will be utilizing bottleneck convolutions. We will refer to the ratio between the size of the input bottleneck and the inner size as the expansion ratio.
本文余下部分将使用瓶颈卷积。我们把输入瓶颈大小与内部大小之比称为扩展比。
3.3 Inverted residuals
3.3 倒残差
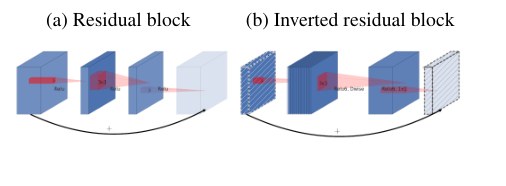
Figure 3: The difference between residual block [8, 30] and inverted residual. Diagonally hatched layers do not use non-linearities. We use thickness of each block to indicate its relative number of channels. Note how classical residuals connects the layers with high number of channels, whereas the inverted residuals connect the bottlenecks. Best viewed in color.
图 3:残差块与倒残差的差别。对角阴影的层不使用非线性。我们用每块的厚度表示相对通道数。注意,经典残差连接的是通道数多的层,而倒残差连接的是瓶颈。请看彩色图。
The bottleneck blocks appear similar to residual block where each block contains an input followed by several bottlenecks then followed by expansion ResNet. However, inspired by the intuition that the bottlenecks actually contain all the necessary information, while an expansion layer acts merely as an implementation detail that accompanies a non-linear transformation of the tensor, we use shortcuts directly between the bottlenecks. Figure 3 provides a schematic visualization of the difference in the designs. The motivation for inserting shortcuts is similar to that of classical residual connections: we want to improve the ability of a gradient to propagate across multiplier layers. However, the inverted design is considerably more memory efficient (see Section 4 for details), as well as works slightly better in our experiments.
瓶颈块看起来类似于残差块:每个块先接收输入,再经过若干瓶颈,最后再扩展。不过,受“必要信息其实都在瓶颈里、扩展层只是伴随张量非线性变换的实现细节”这一直觉启发,我们把捷径直接加在瓶颈之间。图 3 示意了两种设计的差别。插入捷径的动机与经典残差连接类似:我们希望改善梯度穿过多层的传播能力。然而倒过来的设计内存效率明显更高(细节见第 4 节),在我们的实验中也略好一些。
Running time and parameter count for bottleneck convolution
The basic implementation structure is illustrated in Table 1. For a block of size , expansion factor and kernel size with input channels and output channels, the total number of multiply add required is . Compared with (1) this expression has an extra term, as indeed we have an extra convolution, however the nature of our networks allows us to utilize much smaller input and output dimensions. In Table 3 we compare the needed sizes for each resolution between MobileNetV1, MobileNetV2 and ShuffleNet.
瓶颈卷积的运行时间与参数量
基本实现结构见表 1。对于大小为 、扩展因子为 、核大小为 、输入通道为 、输出通道为 的块,所需乘法–加法总数为 。与 (1) 相比,该式多了一项,因为确实多了一次 卷积;不过我们这类网络可以用小得多的输入和输出维度。表 3 比较了 MobileNetV1、MobileNetV2 和 ShuffleNet 在各分辨率下所需的大小。
3.4 Information flow interpretation
3.4 信息流解释
One interesting property of our architecture is that it provides a natural separation between the input/output domains of the building blocks (bottleneck layers), and the layer transformation – that is a non-linear function that converts input to the output. The former can be seen as the capacity of the network at each layer, whereas the latter as the expressiveness. This is in contrast with traditional convolutional blocks, both regular and separable, where both expressiveness and capacity are tangled together and are functions of the output layer depth.
我们架构的一个有趣性质是:它自然地把构建块的输入/输出域(瓶颈层)与层变换分开——后者是把输入转换成输出的非线性函数。前者可以看作网络在每一层的容量,后者则是表达能力。这与传统卷积块(无论常规还是可分离)不同:在那些块里,表达能力和容量缠在一起,都是输出层深度的函数。
In particular, in our case, when inner layer depth is the underlying convolution is the identity function thanks to the shortcut connection. When the expansion ratio is smaller than , this is a classical residual convolutional block ResNet; ResNext2016. However, for our purposes we show that expansion ratio greater than is the most useful.
特别地,在我们这里,当内部层深度为 时,由于捷径连接,底层卷积就是恒等函数。当扩展比小于 时,这就是经典的残差卷积块。不过就我们的目的而言,扩展比大于 最为有用。
This interpretation allows us to study the expressiveness of the network separately from its capacity and we believe that further exploration of this separation is warranted to provide a better understanding of the network properties.
这一解释让我们可以把网络的表达能力与容量分开研究。我们相信,进一步探索这种分离,有助于更好地理解网络性质。
4 Model Architecture
4 模型架构
Now we describe our architecture in detail. As discussed in the previous section the basic building block is a bottleneck depth-separable convolution with residuals. The detailed structure of this block is shown in Table 1. The architecture of MobileNetV2 contains the initial fully convolution layer with filters, followed by residual bottleneck layers described in the Table 2. We use as the non-linearity because of its robustness when used with low-precision computation MobilenetV1. We always use kernel size as is standard for modern networks, and utilize dropout and batch normalization during training.
现在详细描述我们的架构。如前一节所述,基本构建块是带残差的瓶颈深度可分离卷积。该块的详细结构见表 1。MobileNetV2 的架构包含一个带 个滤波器的初始全卷积层,随后是表 2 中描述的 19 个残差瓶颈层。非线性采用 ,因为它在低精度计算中更稳健。我们始终使用 核(这是现代网络的标准做法),并在训练时使用 dropout 和批归一化。
With the exception of the first layer, we use constant expansion rate throughout the network. In our experiments we find that expansion rates between and result in nearly identical performance curves, with smaller networks being better off with slightly smaller expansion rates and larger networks having slightly better performance with larger expansion rates.
除第一层外,我们在整个网络中使用恒定的扩展率。实验发现,扩展率在 到 之间时性能曲线几乎相同:较小的网络略受益于稍小的扩展率,较大的网络则略受益于稍大的扩展率。
For all our main experiments we use expansion factor of applied to the size of the input tensor. For example, for a bottleneck layer that takes -channel input tensor and produces a tensor with channels, the intermediate expansion layer is then channels.
在所有主要实验中,我们把扩展因子取为输入张量大小的 倍。例如,一个接收 通道输入、产生 通道输出的瓶颈层,其中间扩展层就是 通道。
| Input | Operator | Output |
|---|---|---|
| 1x1 , | ||
| 3x3 s=, | ||
| linear 1x1 |
Table 1: Bottleneck residual block transforming from to channels, with stride , and expansion factor .
| 输入 | 算子 | 输出 |
|---|---|---|
| 1x1 , | ||
| 3x3 s=, | ||
| 线性 1x1 |
表 1:把通道数从 变到 、步幅为 、扩展因子为 的瓶颈残差块。
| Input | Operator | ||||
|---|---|---|---|---|---|
| conv2d | - | 32 | 1 | 2 | |
| bottleneck | 1 | 16 | 1 | 1 | |
| bottleneck | 6 | 24 | 2 | 2 | |
| bottleneck | 6 | 32 | 3 | 2 | |
| bottleneck | 6 | 64 | 4 | 2 | |
| bottleneck | 6 | 96 | 3 | 1 | |
| bottleneck | 6 | 160 | 3 | 2 | |
| bottleneck | 6 | 320 | 1 | 1 | |
| conv2d 1x1 | - | 1280 | 1 | 1 | |
| avgpool 7x7 | - | - | 1 | - | |
| conv2d 1x1 | - | k | - |
Table 2: MobileNetV2 : Each line describes a sequence of 1 or more identical (modulo stride) layers, repeated times. All layers in the same sequence have the same number of output channels. The first layer of each sequence has a stride and all others use stride . All spatial convolutions use kernels. The expansion factor is always applied to the input size as described in Table 1.
| 输入 | 算子 | ||||
|---|---|---|---|---|---|
| conv2d | - | 32 | 1 | 2 | |
| bottleneck | 1 | 16 | 1 | 1 | |
| bottleneck | 6 | 24 | 2 | 2 | |
| bottleneck | 6 | 32 | 3 | 2 | |
| bottleneck | 6 | 64 | 4 | 2 | |
| bottleneck | 6 | 96 | 3 | 1 | |
| bottleneck | 6 | 160 | 3 | 2 | |
| bottleneck | 6 | 320 | 1 | 1 | |
| conv2d 1x1 | - | 1280 | 1 | 1 | |
| avgpool 7x7 | - | - | 1 | - | |
| conv2d 1x1 | - | k | - |
表 2:MobileNetV2:每一行描述 1 个或更多相同(步幅除外)的层,重复 次。同一序列中的所有层具有相同的输出通道数 。每个序列的第一层步幅为 ,其余层步幅为 。所有空间卷积使用 核。扩展因子 始终按表 1 所述作用于输入大小。
| Size | MobileNetV1 | MobileNetV2 | ShuffleNet |
|---|---|---|---|
| (2x,g=3) | |||
| 112x112 | 64/1600 | 16/400 | 32/800 |
| 56x56 | 128/800 | 32/200 | 48/300 |
| 28x28 | 256/400 | 64/100 | 400/600K |
| 14x14 | 512/200 | 160/62 | 800/310 |
| 7x7 | 1024/199 | 320/32 | 1600/156 |
| 1x1 | 1024/2 | 1280/2 | 1600/3 |
| max | 1600K | 400K | 600K |
Table 3: The max number of channels/memory (in Kb) that needs to be materialized at each spatial resolution for different architectures. We assume 16-bit floats for activations. For ShuffleNet, we use that matches the performance of MobileNetV1 and MobileNetV2. For the first layer of MobileNetV2 and ShuffleNet we can employ the trick described in Section 4 to reduce memory requirement. Even though ShuffleNet employs bottlenecks elsewhere, the non-bottleneck tensors still need to be materialized due to the presence of shortcuts between the non-bottleneck tensors.
| 大小 | MobileNetV1 | MobileNetV2 | ShuffleNet |
|---|---|---|---|
| (2x,g=3) | |||
| 112x112 | 64/1600 | 16/400 | 32/800 |
| 56x56 | 128/800 | 32/200 | 48/300 |
| 28x28 | 256/400 | 64/100 | 400/600K |
| 14x14 | 512/200 | 160/62 | 800/310 |
| 7x7 | 1024/199 | 320/32 | 1600/156 |
| 1x1 | 1024/2 | 1280/2 | 1600/3 |
| 最大 | 1600K | 400K | 600K |
表 3:不同架构在各空间分辨率下需要物化的最大通道数/内存(Kb)。激活值按 16 位浮点计算。对 ShuffleNet,我们使用与 MobileNetV1 和 MobileNetV2 性能相当的 。对 MobileNetV2 和 ShuffleNet 的第一层,可以采用第 4 节描述的技巧降低内存需求。尽管 ShuffleNet 在其他地方也使用瓶颈,但由于捷径连在非瓶颈张量之间,非瓶颈张量仍需物化。
Trade-off hyper parameters
As in MobilenetV1 we tailor our architecture to different performance points, by using the input image resolution and width multiplier as tunable hyper parameters, that can be adjusted depending on desired accuracy/performance trade-offs. Our primary network (width multiplier , ), has a computational cost of 300 million multiply-adds and uses 3.4 million parameters. We explore the performance trade offs, for input resolutions from to , and width multipliers of to . The network computational cost ranges from multiply adds to 585M MAdds, while the model size vary between 1.7M and 6.9M parameters.
权衡超参数
与 MobileNetV1 一样,我们用输入图像分辨率和宽度乘数作为可调超参数,按所需的精度/性能权衡来裁剪架构。主网络(宽度乘数 ,)的计算代价为 3 亿次乘法–加法,参数量 340 万。我们探索输入分辨率从 到 、宽度乘数从 到 的性能权衡。网络计算代价从 7 次乘法–加法到 5.85 亿 MAdd,模型大小则在 170 万到 690 万参数之间。
One minor implementation difference, with MobilenetV1 is that for multipliers less than one, we apply width multiplier to all layers except the very last convolutional layer. This improves performance for smaller models.
与 MobileNetV1 的一处细微实现差异是:当乘数小于 1 时,宽度乘数作用于除最后一层卷积外的所有层。这对较小模型有帮助。
5 Implementation Notes
5 实现说明
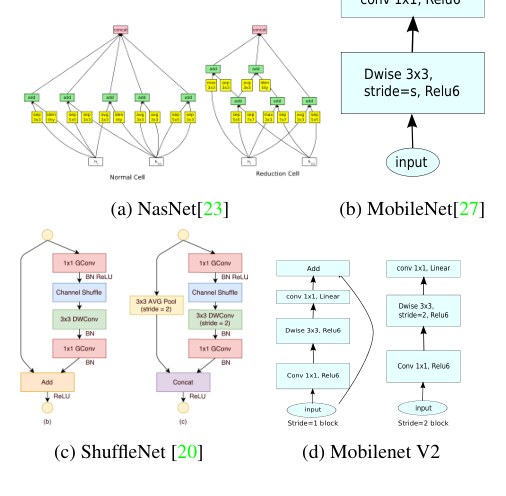
Figure 4: Comparison of convolutional blocks for different architectures. ShuffleNet uses Group Convolutions [20] and shuffling, it also uses conventional residual approach where inner blocks are narrower than output. ShuffleNet and NasNet illustrations are from respective papers.
图 4:不同架构卷积块的比较。ShuffleNet 使用分组卷积和通道混洗,并沿用内部块比输出更窄的传统残差做法。ShuffleNet 与 NasNet 的示意图来自各自论文。
5.1 Memory efficient inference
5.1 内存高效的推理
The inverted residual bottleneck layers allow a particularly memory efficient implementation which is very important for mobile applications. A standard efficient implementation of inference that uses for instance TensorFlowtensorflow2015-whitepaper or Caffe caffe, builds a directed acyclic compute hypergraph , consisting of edges representing the operations and nodes representing tensors of intermediate computation. The computation is scheduled in order to minimize the total number of tensors that needs to be stored in memory. In the most general case, it searches over all plausible computation orders and picks the one that minimizes
倒残差瓶颈层允许一种对移动应用非常重要的内存高效实现。例如 TensorFlow 或 Caffe 中常见的高效推理实现,会构建有向无环计算超图 ,边表示运算,节点表示中间计算的张量。调度计算是为了尽量减少需要存进内存的张量总数。最一般的情形是搜索所有合理的计算顺序 ,并选取使下式最小的那个:
where is the list of intermediate tensors that are connected to any of nodes, represents the size of the tensor and is the total amount of memory needed for internal storage during operation .
其中 是连接到 中任一节点的中间张量列表, 表示张量 的大小, 是运算 期间内部存储所需的总内存。
For graphs that have only trivial parallel structure (such as residual connection), there is only one non-trivial feasible computation order, and thus the total amount and a bound on the memory needed for inference on compute graph can be simplified:
对于只有平凡并行结构(例如残差连接)的图,只有一种非平凡的可行计算顺序,因此在计算图 上推理所需的内存总量及其上界可以简化为:
Or to restate, the amount of memory is simply the maximum total size of combined inputs and outputs across all operations. In what follows we show that if we treat a bottleneck residual block as a single operation (and treat inner convolution as a disposable tensor), the total amount of memory would be dominated by the size of bottleneck tensors, rather than the size of tensors that are internal to bottleneck (and much larger).
换句话说,内存量就是所有运算中输入与输出合计大小的最大值。下面我们说明:若把一个瓶颈残差块当作单一运算(并把内部卷积当作可丢弃张量),则总内存将由瓶颈张量的大小主导,而不是由瓶颈内部(大得多的)张量大小主导。
Bottleneck Residual Block
A bottleneck block operator shown in Figure 3(b) can be expressed as a composition of three operators , where is a linear transformation , is a non-linear per-channel transformation: , and is again a linear transformation to the output domain: .
瓶颈残差块
图 3(b) 所示的瓶颈块算子 可以写成三个算子的复合 ,其中 是线性变换 , 是逐通道的非线性变换:, 再次是到输出域的线性变换:。
For our networks , but the results apply to any per-channel transformation. Suppose the size of the input domain is and the size of the output domain is , then the memory required to compute can be as low as .
对我们的网络,,但结论适用于任何逐通道变换。设输入域大小为 、输出域大小为 ,则计算 所需内存可以低至 。
The algorithm is based on the fact that the inner tensor can be represented as concatenation of tensors, of size each and our function can then be represented as
该算法基于如下事实:内部张量 可以表示成 个大小各为 的张量的拼接,于是我们的函数可以写成
by accumulating the sum, we only require one intermediate block of size to be kept in memory at all times. Using we end up having to keep only a single channel of the intermediate representation at all times. The two constraints that enabled us to use this trick is (a) the fact that the inner transformation (which includes non-linearity and depthwise) is per-channel, and (b) the consecutive non-per-channel operators have significant ratio of the input size to the output. For most of the traditional neural networks, such trick would not produce a significant improvement.
通过累加求和,我们始终只需在内存中保留一块大小为 的中间块。取 时,就始终只需保留中间表征的单个通道。使我们能使用这一技巧的两个约束是:(a) 内部变换(包含非线性和深度卷积)是逐通道的;(b) 相邻的非逐通道算子在输入大小与输出大小之间有显著比例。对大多数传统神经网络,这一技巧不会带来明显改进。
We note that, the number of multiply-adds operators needed to compute using -way split is independent of , however in existing implementations we find that replacing one matrix multiplication with several smaller ones hurts runtime performance due to increased cache misses. We find that this approach is the most helpful to be used with being a small constant between and . It significantly reduces the memory requirement, but still allows one to utilize most of the efficiencies gained by using highly optimized matrix multiplication and convolution operators provided by deep learning frameworks. It remains to be seen if special framework level optimization may lead to further runtime improvements.
我们注意到,用 路拆分计算 所需的乘法–加法次数与 无关;但在现有实现中,用若干较小的矩阵乘法替换一次大的矩阵乘法,会因缓存未命中增加而损害运行时性能。我们发现,把 取成 2 到 5 之间的小常数时这一方法最有用。它显著降低内存需求,同时仍能利用深度学习框架提供的高度优化的矩阵乘法和卷积算子。特殊的框架级优化是否还能进一步改善运行时,仍有待观察。
6 Experiments
6 实验
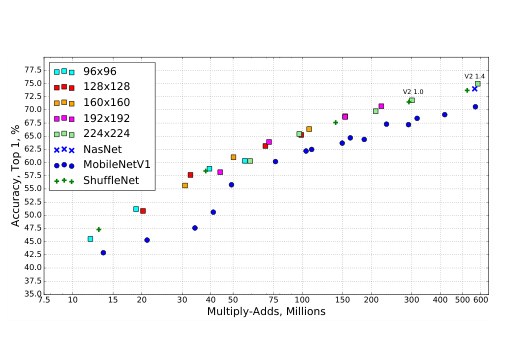
Figure 5: Performance curve of MobileNetV2 vs MobileNetV1, ShuffleNet, NAS. For our networks we use multipliers , , , for all resolutions, and additional for for . Best viewed in color.
图 5:MobileNetV2 相对 MobileNetV1、ShuffleNet、NAS 的性能曲线。对我们的网络,所有分辨率使用乘数 、、、,对 额外使用 。请看彩色图。
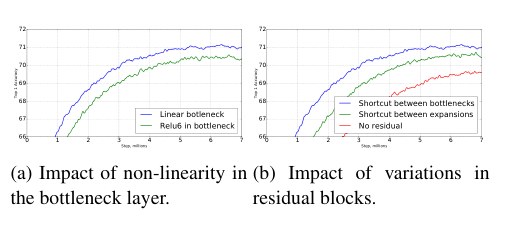
Figure 6: The impact of non-linearities and various types of shortcut (residual) connections.
图 6:非线性以及不同捷径(残差)连接方式的影响。
6.1 ImageNet Classification
6.1 ImageNet 分类
Training setup
We train our models using TensorFlowtensorflow2015-whitepaper. We use the standard RMSPropOptimizer with both decay and momentum set to . We use batch normalization after every layer, and the standard weight decay is set to . Following MobileNetV1MobilenetV1 setup we use initial learning rate of , and learning rate decay rate of per epoch. We use 16 GPU asynchronous workers, and a batch size of .
训练设置
我们用 TensorFlow 训练模型。优化器为标准 RMSPropOptimizer,衰减和动量都设为 。每一层之后使用批归一化,标准权重衰减设为 。沿用 MobileNetV1 的设置,初始学习率为 ,每轮衰减率为 。我们使用 16 个 GPU 异步 worker,批次大小为 。
Results
We compare our networks against MobileNetV1, ShuffleNet and NASNet-A models. The statistics of a few selected models is shown in Table 4 with the full performance graph shown in Figure 5.
结果
我们把网络与 MobileNetV1、ShuffleNet 和 NASNet-A 模型比较。若干选定模型的统计见表 4,完整性能图见图 5。
| Network | Top 1 | Params | MAdds | CPU |
|---|---|---|---|---|
| MobileNetV1 | 70.6 | 4.2M | 575M | 113ms |
| ShuffleNet (1.5) | 71.5 | 3.4M | 292M | - |
| ShuffleNet (x2) | 73.7 | 5.4M | 524M | - |
| NasNet-A | 74.0 | 5.3M | 564M | 183ms |
| MobileNetV2 | 72.0 | 3.4M | 300M | 75ms |
| MobileNetV2 (1.4) | 74.7 | 6.9M | 585M | 143ms |
Table 4: Performance on ImageNet, comparison for different networks. As is common practice for ops, we count the total number of Multiply-Adds. In the last column we report running time in milliseconds (ms) for a single large core of the Google Pixel 1 phone (using TF-Lite). We do not report ShuffleNet numbers as efficient group convolutions and shuffling are not yet supported.
| 网络 | Top 1 | 参数量 | MAdds | CPU |
|---|---|---|---|---|
| MobileNetV1 | 70.6 | 4.2M | 575M | 113ms |
| ShuffleNet (1.5) | 71.5 | 3.4M | 292M | - |
| ShuffleNet (x2) | 73.7 | 5.4M | 524M | - |
| NasNet-A | 74.0 | 5.3M | 564M | 183ms |
| MobileNetV2 | 72.0 | 3.4M | 300M | 75ms |
| MobileNetV2 (1.4) | 74.7 | 6.9M | 585M | 143ms |
表 4:ImageNet 上不同网络的性能比较。按惯例,运算量统计乘法–加法总数。最后一列是在 Google Pixel 1 手机的单个大核上(使用 TF-Lite)的运行时间(毫秒)。我们未报告 ShuffleNet 的时间,因为高效分组卷积和通道混洗尚未得到支持。
6.2 Object Detection
6.2 目标检测
We evaluate and compare the performance of MobileNetV2 and MobileNetV1 as feature extractors huang2016speed for object detection with a modified version of the Single Shot Detector (SSD) liu2016ssd on COCO dataset COCO. We also compare to YOLOv2 redmon2016yolo9000 and original SSD (with VGG-16 VGGNet as base network) as baselines. We do not compare performance with other architectures such as Faster-RCNN ren2015faster and RFCN dai2016rfcn since our focus is on mobile/real-time models.
我们把 MobileNetV2 和 MobileNetV1 作为特征提取器,用修改版 Single Shot Detector(SSD)在 COCO 数据集上评估并比较目标检测表现,同时以 YOLOv2 和原始 SSD(以 VGG-16 为骨干)作为基线。我们不与 Faster-RCNN 和 RFCN 等其他架构比较性能,因为关注点是移动/实时模型。
SSDLite: In this paper, we introduce a mobile friendly variant of regular SSD. We replace all the regular convolutions with separable convolutions (depthwise followed by projection) in SSD prediction layers. This design is in line with the overall design of MobileNets and is seen to be much more computationally efficient. We call this modified version SSDLite. Compared to regular SSD, SSDLite dramatically reduces both parameter count and computational cost as shown in Table 5.
SSDLite:本文引入一种更适合移动端的常规 SSD 变体。我们在 SSD 预测层中把所有常规卷积替换成可分离卷积(深度卷积后接 投影)。这一设计与 MobileNets 的整体思路一致,计算上也高效得多。我们把这一修改版称为 SSDLite。如表 5 所示,相对常规 SSD,SSDLite 显著减少了参数量和计算代价。
| Params | MAdds | |
|---|---|---|
| SSDliu2016ssd | 14.8M | 1.25B |
| SSDLite | 2.1M | 0.35B |
Table 5: Comparison of the size and the computational cost between SSD and SSDLite configured with MobileNetV2 and making predictions for classes.
| 参数量 | MAdds | |
|---|---|---|
| SSD | 14.8M | 1.25B |
| SSDLite | 2.1M | 0.35B |
表 5:与 MobileNetV2 搭配、预测 类时,SSD 与 SSDLite 在规模和计算代价上的比较。
For MobileNetV1, we follow the setup in huang2016speed. For MobileNetV2, the first layer of SSDLite is attached to the expansion of layer 15 (with output stride of 16). The second and the rest of SSDLite layers are attached on top of the last layer (with output stride of ). This setup is consistent with MobileNetV1 as all layers are attached to the feature map of the same output strides.
对 MobileNetV1,我们沿用已有设置。对 MobileNetV2,SSDLite 的第一层接到第 15 层的扩展输出(输出步幅为 16)。第二层及之后的 SSDLite 层接在最后一层之上(输出步幅为 )。这一设置与 MobileNetV1 一致,因为所有层都接到相同输出步幅的特征图上。
Both MobileNet models are trained and evaluated with Open Source TensorFlow Object Detection API detection-api. The input resolution of both models is . We benchmark and compare both mAP (COCO challenge metrics), number of parameters and number of Multiply-Adds. The results are shown in Table 6. MobileNetV2 SSDLite is not only the most efficient model, but also the most accurate of the three. Notably, MobileNetV2 SSDLite is more efficient and smaller while still outperforms YOLOv2 on COCO dataset.
两个 MobileNet 模型都用开源 TensorFlow Object Detection API 训练和评估,输入分辨率为 。我们比较 mAP(COCO 挑战指标)、参数量和乘法–加法次数,结果见表 6。MobileNetV2 SSDLite 不仅是三者中最高效的模型,也是其中最准确的。值得注意的是,MobileNetV2 SSDLite 效率约为 YOLOv2 的 、体积约为其 ,在 COCO 上仍超过 YOLOv2。
| Network | mAP | Params | MAdd | CPU |
|---|---|---|---|---|
| SSD300liu2016ssd | 23.2 | 36.1M | 35.2B | - |
| SSD512liu2016ssd | 26.8 | 36.1M | 99.5B | - |
| YOLOv2redmon2016yolo9000 | 21.6 | 50.7M | 17.5B | - |
| MNet V1 + SSDLite | 22.2 | 5.1M | 1.3B | 270ms |
| MNet V2 + SSDLite | 22.1 | 4.3M | 0.8B | 200ms |
Table 6: Performance comparison of MobileNetV2 + SSDLite and other realtime detectors on the COCO dataset object detection task. MobileNetV2 + SSDLite achieves competitive accuracy with significantly fewer parameters and smaller computational complexity. All models are trained on trainval35k and evaluated on test-dev. SSD/YOLOv2 numbers are from redmon2016yolo9000. The running time is reported for the large core of the Google Pixel 1 phone, using an internal version of the TF-Lite engine.
| 网络 | mAP | 参数量 | MAdd | CPU |
|---|---|---|---|---|
| SSD300 | 23.2 | 36.1M | 35.2B | - |
| SSD512 | 26.8 | 36.1M | 99.5B | - |
| YOLOv2 | 21.6 | 50.7M | 17.5B | - |
| MNet V1 + SSDLite | 22.2 | 5.1M | 1.3B | 270ms |
| MNet V2 + SSDLite | 22.1 | 4.3M | 0.8B | 200ms |
表 6:MobileNetV2 + SSDLite 与其他实时检测器在 COCO 目标检测任务上的性能比较。MobileNetV2 + SSDLite 以显著更少的参数和更小的计算复杂度达到有竞争力的精度。所有模型在 trainval35k 上训练,在 test-dev 上评估。SSD/YOLOv2 数字来自相应原文。运行时间是在 Google Pixel 1 手机的大核上、使用内部版 TF-Lite 引擎测得。
6.3 Semantic Segmentation
6.3 语义分割
In this section, we compare MobileNetV1 and MobileNetV2 models used as feature extractors with DeepLabv3 DeepLabV3 for the task of mobile semantic segmentation. DeepLabv3 adopts atrous convolution Holschneider1989real; Sermanet2013Overfeat; Papandreou2014untangling, a powerful tool to explicitly control the resolution of computed feature maps, and builds five parallel heads including (a) Atrous Spatial Pyramid Pooling module (ASPP) DeepLabV2 containing three convolutions with different atrous rates, (b) convolution head, and (c) Image-level features ParseNet. We denote by the ratio of input image spatial resolution to final output resolution, which is controlled by applying the atrous convolution properly. For semantic segmentation, we usually employ or for denser feature maps. We conduct the experiments on the PASCAL VOC 2012 dataset PASCAL, with extra annotated images from Hariharan2011semantic and evaluation metric mIOU.
本节比较把 MobileNetV1 和 MobileNetV2 作为特征提取器、与 DeepLabv3 搭配做移动端语义分割的表现。DeepLabv3 采用空洞卷积来显式控制计算特征图的分辨率,并构建五个并行头,包括:(a) 含三个不同空洞率 卷积的空洞空间金字塔池化模块(ASPP);(b) 卷积头;(c) 图像级特征。我们用 表示输入图像空间分辨率与最终输出分辨率之比,通过恰当使用空洞卷积来控制。语义分割通常采用 或 ,以得到更密的特征图。实验在 PASCAL VOC 2012 数据集上进行,并使用额外标注图像,评价指标为 mIOU。
To build a mobile model, we experimented with three design variations: (1) different feature extractors, (2) simplifying the DeepLabv3 heads for faster computation, and (3) different inference strategies for boosting the performance. Our results are summarized in Table 7. We have observed that: (a) the inference strategies, including multi-scale inputs and adding left-right flipped images, significantly increase the MAdds and thus are not suitable for on-device applications, (b) using is more efficient than , (c) MobileNetV1 is already a powerful feature extractor and only requires about times fewer MAdds than ResNet-101 ResNet (e.g., mIOU: 78.56 82.70, and MAdds: 941.9B 4870.6B), (d) it is more efficient to build DeepLabv3 heads on top of the second last feature map of MobileNetV2 than on the original last-layer feature map, since the second to last feature map contains channels instead of , and by doing so, we attain similar performance, but require about times fewer operations than the MobileNetV1 counterparts, and (e) DeepLabv3 heads are computationally expensive and removing the ASPP module significantly reduces the MAdds with only a slight performance degradation. In the end of the Table 7, we identify a potential candidate for on-device applications (in bold face), which attains mIOU and only requires B MAdds.
为构建移动模型,我们试验了三种设计变化:(1) 不同的特征提取器,(2) 简化 DeepLabv3 的头以加快计算,(3) 不同的推理策略以提升表现。结果汇总于表 7。我们观察到:(a) 包括多尺度输入和左右翻转图像在内的推理策略会显著增加 MAdds,因而不适合端侧应用;(b) 使用 比 更高效;(c) MobileNetV1 已经是很强的特征提取器,MAdds 大约只需 ResNet-101 的 到 (例如 mIOU:78.56 对 82.70,MAdds:941.9B 对 4870.6B);(d) 把 DeepLabv3 的头建在 MobileNetV2 倒数第二张特征图上,比建在原来的最后一层特征图上更高效,因为倒数第二张特征图有 个通道而不是 ,这样做能达到相近表现,运算量大约只需 MobileNetV1 对应设置的 ;(e) DeepLabv3 的头计算昂贵,去掉 ASPP 模块会显著减少 MAdds,性能只略有下降。表 7 末尾我们标出一个适合端侧应用的候选(加粗),它达到 mIOU,只需 B MAdds。
| Network | OS | ASPP | MF | mIOU | Params | MAdds |
|---|---|---|---|---|---|---|
| MNet V1 | 16 | ✓ | 75.29 | 11.15M | 14.25B | |
| 8 | ✓ | ✓ | 78.56 | 11.15M | 941.9B | |
| MNet V2* | 16 | ✓ | 75.70 | 4.52M | 5.8B | |
| 8 | ✓ | ✓ | 78.42 | 4.52M | 387B | |
| MNet V2* | 16 | 75.32 | 2.11M | 2.75B | ||
| 8 | ✓ | 77.33 | 2.11M | 152.6B | ||
| ResNet-101 | 16 | ✓ | 80.49 | 58.16M | 81.0B | |
| 8 | ✓ | ✓ | 82.70 | 58.16M | 4870.6B |
Table 7: MobileNet + DeepLabv3 inference strategy on the PASCAL VOC 2012 validation set. MNet V2*: Second last feature map is used for DeepLabv3 heads, which includes (1) Atrous Spatial Pyramid Pooling (ASPP) module, and (2) convolution as well as image-pooling feature. OS: output_stride that controls the output resolution of the segmentation map. MF: Multi-scale and left-right flipped inputs during test. All of the models have been pretrained on COCO. The potential candidate for on-device applications is shown in bold face. PASCAL images have dimension and atrous convolution allows us to control output feature resolution without increasing the number of parameters.
| 网络 | OS | ASPP | MF | mIOU | 参数量 | MAdds |
|---|---|---|---|---|---|---|
| MNet V1 | 16 | ✓ | 75.29 | 11.15M | 14.25B | |
| 8 | ✓ | ✓ | 78.56 | 11.15M | 941.9B | |
| MNet V2* | 16 | ✓ | 75.70 | 4.52M | 5.8B | |
| 8 | ✓ | ✓ | 78.42 | 4.52M | 387B | |
| MNet V2* | 16 | 75.32 | 2.11M | 2.75B | ||
| 8 | ✓ | 77.33 | 2.11M | 152.6B | ||
| ResNet-101 | 16 | ✓ | 80.49 | 58.16M | 81.0B | |
| 8 | ✓ | ✓ | 82.70 | 58.16M | 4870.6B |
表 7:MobileNet + DeepLabv3 在 PASCAL VOC 2012 验证集上的推理策略。MNet V2*:DeepLabv3 的头使用倒数第二张特征图,包括 (1) 空洞空间金字塔池化(ASPP)模块,以及 (2) 卷积和图像池化特征。OS:控制分割图输出分辨率的 output_stride。MF:测试时使用多尺度和左右翻转输入。所有模型都在 COCO 上预训练。适合端侧应用的候选以粗体标出。PASCAL 图像尺寸为 ,空洞卷积使我们能在不增加参数量的情况下控制输出特征分辨率。
6.4 Ablation study
6.4 消融实验
Inverted residual connections. The importance of residual connection has been studied extensively ResNet; ResNext2016; InceptionV4. The new result reported in this paper is that the shortcut connecting bottleneck perform better than shortcuts connecting the expanded layers (see Figure 6(b) for comparison).
倒残差连接。 残差连接的重要性已有大量研究。本文报告的新结果是:连接瓶颈的捷径比连接扩展层的捷径表现更好(比较见图 6(b))。
Importance of linear bottlenecks. The linear bottleneck models are strictly less powerful than models with non-linearities, because the activations can always operate in linear regime with appropriate changes to biases and scaling. However our experiments shown in Figure 6(a) indicate that linear bottlenecks improve performance, providing support that non-linearity destroys information in low-dimensional space.
线性瓶颈的重要性。 线性瓶颈模型在能力上严格弱于带非线性的模型,因为只要适当改变偏置和缩放,激活总可以工作在线性区间。然而图 6(a) 的实验表明,线性瓶颈能提升性能,这支持了“非线性会破坏低维空间中的信息”这一判断。
7 Conclusions and future work
7 结论与未来工作
We described a very simple network architecture that allowed us to build a family of highly efficient mobile models. Our basic building unit, has several properties that make it particularly suitable for mobile applications. It allows very memory-efficient inference and relies utilize standard operations present in all neural frameworks.
我们描述了一种非常简单的网络架构,用以构建一族高效的移动模型。基本构建单元有若干特别适合移动应用的性质:它允许非常节省内存的推理,并依赖所有神经框架中都有的标准运算。
For the ImageNet dataset, our architecture improves the state of the art for wide range of performance points.
在 ImageNet 数据集上,我们的架构在很宽的性能区间上提升了当时最优水平。
For object detection task, our network outperforms state-of-art realtime detectors on COCO dataset both in terms of accuracy and model complexity. Notably, our architecture combined with the SSDLite detection module is less computation and less parameters than YOLOv2.
在目标检测任务上,我们的网络在 COCO 数据集上同时在精度和模型复杂度上超过当时最优的实时检测器。值得注意的是,该架构与 SSDLite 检测模块结合后,计算量约为 YOLOv2 的 ,参数量约为其 。
On the theoretical side: the proposed convolutional block has a unique property that allows to separate the network expressiveness (encoded by expansion layers) from its capacity (encoded by bottleneck inputs). Exploring this is an important direction for future research.
在理论方面:所提出的卷积块有一个独特性质,可以把网络的表达能力(由扩展层编码)与容量(由瓶颈输入编码)分开。探索这一点是未来研究的重要方向。
Acknowledgments
We would like to thank Matt Streeter and Sergey Ioffe for their helpful feedback and discussion.
致谢
感谢 Matt Streeter 和 Sergey Ioffe 提供的有益反馈与讨论。
References
参考文献
[1] Olga Russakovsky, Jia Deng, Hao Su, Jonathan Krause, Sanjeev Satheesh, Sean Ma, Zhiheng Huang, Andrej Karpathy, Aditya Khosla, Michael Bernstein, Alexander C. Berg, and Li Fei-Fei. Imagenet large scale visual recognition challenge. Int. J. Comput. Vision , 115(3):211–252, December 2015.
[2] Tsung-Yi Lin, Michael Maire, Serge Belongie, James Hays, Pietro Perona, Deva Ramanan, Piotr Dollár, and C Lawrence Zitnick. Microsoft COCO: Common objects in context. In ECCV , 2014.
[3] Mark Everingham, S. M. Ali Eslami, Luc Van Gool, Christopher K. I. Williams, John Winn, and Andrew Zisserma. The pascal visual object classes challenge – a retrospective. IJCV , 2014.
[4] Mobilenetv2 source code. Available from https://github.com/tensorflow/models/tree/master/research/slim/nets/mobilenet .
[5] Alex Krizhevsky, Ilya Sutskever, and Geoffrey E. Hinton. Imagenet classification with deep convolutional neural networks. In Bartlett et al. [ 48 ] , pages 1106–1114.
[6] Karen Simonyan and Andrew Zisserman. Very deep convolutional networks for large-scale image recognition. CoRR , abs/1409.1556, 2014.
[7] Christian Szegedy, Wei Liu, Yangqing Jia, Pierre Sermanet, Scott E. Reed, Dragomir Anguelov, Dumitru Erhan, Vincent Vanhoucke, and Andrew Rabinovich. Going deeper with convolutions. In IEEE Conference on Computer Vision and Pattern Recognition, CVPR 2015, Boston, MA, USA, June 7-12, 2015 , pages 1–9. IEEE Computer Society, 2015.
[8] Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recognition. CoRR , abs/1512.03385, 2015.
[9] James Bergstra and Yoshua Bengio. Random search for hyper-parameter optimization. Journal of Machine Learning Research , 13:281–305, 2012.
[10] Jasper Snoek, Hugo Larochelle, and Ryan P. Adams. Practical bayesian optimization of machine learning algorithms. In Bartlett et al. [ 48 ] , pages 2960–2968.
[11] Jasper Snoek, Oren Rippel, Kevin Swersky, Ryan Kiros, Nadathur Satish, Narayanan Sundaram, Md. Mostofa Ali Patwary, Prabhat, and Ryan P. Adams. Scalable bayesian optimization using deep neural networks. In Francis R. Bach and David M. Blei, editors, Proceedings of the 32nd International Conference on Machine Learning, ICML 2015, Lille, France, 6-11 July 2015 , volume 37 of JMLR Workshop and Conference Proceedings , pages 2171–2180. JMLR.org, 2015.
[12] Babak Hassibi and David G. Stork. Second order derivatives for network pruning: Optimal brain surgeon. In Stephen Jose Hanson, Jack D. Cowan, and C. Lee Giles, editors, Advances in Neural Information Processing Systems 5, [NIPS Conference, Denver, Colorado, USA, November 30 - December 3, 1992] , pages 164–171. Morgan Kaufmann, 1992.
[13] Yann LeCun, John S. Denker, and Sara A. Solla. Optimal brain damage. In David S. Touretzky, editor, Advances in Neural Information Processing Systems 2, [NIPS Conference, Denver, Colorado, USA, November 27-30, 1989] , pages 598–605. Morgan Kaufmann, 1989.
[14] Song Han, Jeff Pool, John Tran, and William J. Dally. Learning both weights and connections for efficient neural network. In Corinna Cortes, Neil D. Lawrence, Daniel D. Lee, Masashi Sugiyama, and Roman Garnett, editors, Advances in Neural Information Processing Systems 28: Annual Conference on Neural Information Processing Systems 2015, December 7-12, 2015, Montreal, Quebec, Canada , pages 1135–1143, 2015.
[15] Song Han, Jeff Pool, Sharan Narang, Huizi Mao, Shijian Tang, Erich Elsen, Bryan Catanzaro, John Tran, and William J. Dally. DSD: regularizing deep neural networks with dense-sparse-dense training flow. CoRR , abs/1607.04381, 2016.
[16] Yiwen Guo, Anbang Yao, and Yurong Chen. Dynamic network surgery for efficient dnns. In Daniel D. Lee, Masashi Sugiyama, Ulrike von Luxburg, Isabelle Guyon, and Roman Garnett, editors, Advances in Neural Information Processing Systems 29: Annual Conference on Neural Information Processing Systems 2016, December 5-10, 2016, Barcelona, Spain , pages 1379–1387, 2016.
[17] Hao Li, Asim Kadav, Igor Durdanovic, Hanan Samet, and Hans Peter Graf. Pruning filters for efficient convnets. CoRR , abs/1608.08710, 2016.
[18] Karim Ahmed and Lorenzo Torresani. Connectivity learning in multi-branch networks. CoRR , abs/1709.09582, 2017.
[19] Tom Veniat and Ludovic Denoyer. Learning time-efficient deep architectures with budgeted super networks. CoRR , abs/1706.00046, 2017.
[20] Xiangyu Zhang, Xinyu Zhou, Mengxiao Lin, and Jian Sun. Shufflenet: An extremely efficient convolutional neural network for mobile devices. CoRR , abs/1707.01083, 2017.
[21] Soravit Changpinyo, Mark Sandler, and Andrey Zhmoginov. The power of sparsity in convolutional neural networks. CoRR , abs/1702.06257, 2017.
[22] Min Wang, Baoyuan Liu, and Hassan Foroosh. Design of efficient convolutional layers using single intra-channel convolution, topological subdivisioning and spatial ”bottleneck” structure. CoRR , abs/1608.04337, 2016.
[23] Barret Zoph, Vijay Vasudevan, Jonathon Shlens, and Quoc V. Le. Learning transferable architectures for scalable image recognition. CoRR , abs/1707.07012, 2017.
[24] Lingxi Xie and Alan L. Yuille. Genetic CNN. CoRR , abs/1703.01513, 2017.
[25] Esteban Real, Sherry Moore, Andrew Selle, Saurabh Saxena, Yutaka Leon Suematsu, Jie Tan, Quoc V. Le, and Alexey Kurakin. Large-scale evolution of image classifiers. In Doina Precup and Yee Whye Teh, editors, Proceedings of the 34th International Conference on Machine Learning, ICML 2017, Sydney, NSW, Australia, 6-11 August 2017 , volume 70 of Proceedings of Machine Learning Research , pages 2902–2911. PMLR, 2017.
[26] Barret Zoph and Quoc V. Le. Neural architecture search with reinforcement learning. CoRR , abs/1611.01578, 2016.
[27] Andrew G. Howard, Menglong Zhu, Bo Chen, Dmitry Kalenichenko, Weijun Wang, Tobias Weyand, Marco Andreetto, and Hartwig Adam. Mobilenets: Efficient convolutional neural networks for mobile vision applications. CoRR , abs/1704.04861, 2017.
[28] Francois Chollet. Xception: Deep learning with depthwise separable convolutions. In The IEEE Conference on Computer Vision and Pattern Recognition (CVPR) , July 2017.
[29] Dongyoon Han, Jiwhan Kim, and Junmo Kim. Deep pyramidal residual networks. CoRR , abs/1610.02915, 2016.
[30] Saining Xie, Ross B. Girshick, Piotr Dollár, Zhuowen Tu, and Kaiming He. Aggregated residual transformations for deep neural networks. CoRR , abs/1611.05431, 2016.
[31] Martín Abadi, Ashish Agarwal, Paul Barham, Eugene Brevdo, Zhifeng Chen, Craig Citro, Greg S. Corrado, Andy Davis, Jeffrey Dean, Matthieu Devin, Sanjay Ghemawat, Ian Goodfellow, Andrew Harp, Geoffrey Irving, Michael Isard, Yangqing Jia, Rafal Jozefowicz, Lukasz Kaiser, Manjunath Kudlur, Josh Levenberg, Dan Mané, Rajat Monga, Sherry Moore, Derek Murray, Chris Olah, Mike Schuster, Jonathon Shlens, Benoit Steiner, Ilya Sutskever, Kunal Talwar, Paul Tucker, Vincent Vanhoucke, Vijay Vasudevan, Fernanda Viégas, Oriol Vinyals, Pete Warden, Martin Wattenberg, Martin Wicke, Yuan Yu, and Xiaoqiang Zheng. TensorFlow: Large-scale machine learning on heterogeneous systems, 2015. Software available from tensorflow.org.
[32] Yangqing Jia, Evan Shelhamer, Jeff Donahue, Sergey Karayev, Jonathan Long, Ross Girshick, Sergio Guadarrama, and Trevor Darrell. Caffe: Convolutional architecture for fast feature embedding. arXiv preprint arXiv:1408.5093 , 2014.
[33] Jonathan Huang, Vivek Rathod, Chen Sun, Menglong Zhu, Anoop Korattikara, Alireza Fathi, Ian Fischer, Zbigniew Wojna, Yang Song, Sergio Guadarrama, et al. Speed/accuracy trade-offs for modern convolutional object detectors. In CVPR , 2017.
[34] Wei Liu, Dragomir Anguelov, Dumitru Erhan, Christian Szegedy, Scott Reed, Cheng-Yang Fu, and Alexander C Berg. Ssd: Single shot multibox detector. In ECCV , 2016.
[35] Joseph Redmon and Ali Farhadi. Yolo9000: Better, faster, stronger. arXiv preprint arXiv:1612.08242 , 2016.
[36] Shaoqing Ren, Kaiming He, Ross Girshick, and Jian Sun. Faster r-cnn: Towards real-time object detection with region proposal networks. In Advances in neural information processing systems , pages 91–99, 2015.
[37] Jifeng Dai, Yi Li, Kaiming He, and Jian Sun. R-fcn: Object detection via region-based fully convolutional networks. In Advances in neural information processing systems , pages 379–387, 2016.
[38] Jonathan Huang, Vivek Rathod, Derek Chow, Chen Sun, and Menglong Zhu. Tensorflow object detection api, 2017.
[39] Liang-Chieh Chen, George Papandreou, Florian Schroff, and Hartwig Adam. Rethinking atrous convolution for semantic image segmentation. CoRR , abs/1706.05587, 2017.
[40] Matthias Holschneider, Richard Kronland-Martinet, Jean Morlet, and Ph Tchamitchian. A real-time algorithm for signal analysis with the help of the wavelet transform. In Wavelets: Time-Frequency Methods and Phase Space , pages 289–297. 1989.
[41] Pierre Sermanet, David Eigen, Xiang Zhang, Michaël Mathieu, Rob Fergus, and Yann LeCun. Overfeat: Integrated recognition, localization and detection using convolutional networks. arXiv:1312.6229 , 2013.
[42] George Papandreou, Iasonas Kokkinos, and Pierre-Andre Savalle. Modeling local and global deformations in deep learning: Epitomic convolution, multiple instance learning, and sliding window detection. In CVPR , 2015.
[43] Liang-Chieh Chen, George Papandreou, Iasonas Kokkinos, Kevin Murphy, and Alan L Yuille. Deeplab: Semantic image segmentation with deep convolutional nets, atrous convolution, and fully connected crfs. TPAMI , 2017.
[44] Wei Liu, Andrew Rabinovich, and Alexander C. Berg. Parsenet: Looking wider to see better. CoRR , abs/1506.04579, 2015.
[45] Bharath Hariharan, Pablo Arbeláez, Lubomir Bourdev, Subhransu Maji, and Jitendra Malik. Semantic contours from inverse detectors. In ICCV , 2011.
[46] Christian Szegedy, Sergey Ioffe, and Vincent Vanhoucke. Inception-v4, inception-resnet and the impact of residual connections on learning. CoRR , abs/1602.07261, 2016.
[47] Guido Montúfar, Razvan Pascanu, Kyunghyun Cho, and Yoshua Bengio. On the number of linear regions of deep neural networks. In Proceedings of the 27th International Conference on Neural Information Processing Systems , NIPS’14, pages 2924–2932, Cambridge, MA, USA, 2014. MIT Press.
[48] Peter L. Bartlett, Fernando C. N. Pereira, Christopher J. C. Burges, Léon Bottou, and Kilian Q. Weinberger, editors. Advances in Neural Information Processing Systems 25: 26th Annual Conference on Neural Information Processing Systems 2012. Proceedings of a meeting held December 3-6, 2012, Lake Tahoe, Nevada, United States , 2012.
Appendix A Bottleneck transformation
附录 A 瓶颈变换
In this section we study the properties of an operator , where represents an -channel pixel, is an matrix and is an matrix. We argue that if , transformations of this form can only exploit non-linearity at the cost of losing information. In contrast, if , such transforms can be highly non-linear but still invertible with high probability (for the initial random weights).
本节研究算子 的性质,其中 表示一个 通道像素, 是 矩阵, 是 矩阵。我们指出:若 ,这种形式的变换只能以丢失信息为代价来利用非线性。相反,若 ,这类变换可以高度非线性,但在随机初始权重下仍以高概率可逆。
First we show that is an identity transformation for any point that lies in the interior of its image.
我们首先证明: 对其像的内部中的任何点都是恒等变换。
Lemma 1
Let . If a volume of is non-zero, then .
引理 1
*令 。若 的体积非零,则 。
Proof:
Let . First we note that if , then for all . Indeed, image of does not contain points with negative coordinates, and points with zero-valued coordinates can not be interior points. Therefore for each , as desired.
证明:
令 。首先注意到,若 ,则对所有 都有 。的确, 的像不包含带负坐标的点,而带零值坐标的点不可能是内点。因此对每个 ,都有 。
It follows that for an arbitrary composition of interleaved linear transformation and operators, if it preserves non-zero volume, that part of the input space that is preserved over such a composition is a linear transformation, and thus is likely to be a minor contributor to the power of deep networks. However, this is a fairly weak statement. Indeed, if the input manifold can be embedded into -dimensional manifold (out of dimensions total), the lemma is trivially true, since the starting volume is . In what follows we show that when the dimensionality of input manifold is significantly lower we can ensure that there will be no information loss.
由此可知,对任意交错的线性变换与 算子的复合,若它保持非零体积,则输入空间 中被这种复合保留下来的那部分是一次线性变换,因而多半不是深度网络能力的主要来源。不过这是一个相当弱的陈述。的确,若输入流形可以嵌入(总共 维中的) 维流形,引理就平凡成立,因为起始体积为 。下面我们说明:当输入流形的维数显著更低时,可以保证没有信息损失。
Since the nonlinearity is a surjective function mapping the entire ray to , using this nonlinearity in a neural network can result in information loss. Once collapses a subset of the input manifold to a smaller-dimensional output, the following network layers can no longer distinguish between collapsed input samples. In the following, we show that bottlenecks with sufficiently large expansion layers are resistant to information loss caused by the presence of activation functions.
由于 非线性是把整条射线 映射到 的满射,在神经网络中使用这一非线性可能导致信息损失。一旦 把输入流形的一个子集塌缩到更低维的输出,后续网络层就无法再区分这些被塌缩的输入样本。下面我们说明,带有足够大扩展层的瓶颈能够抵抗由 激活函数造成的信息损失。
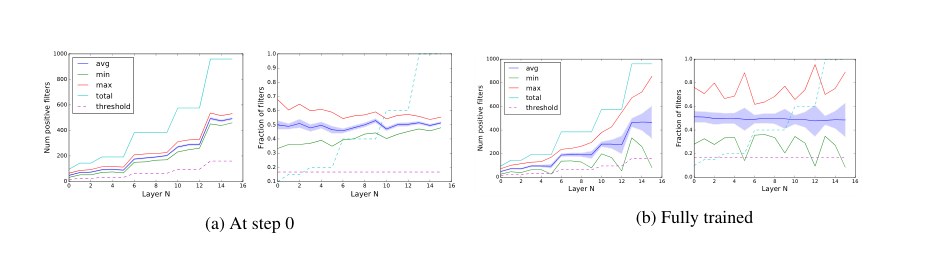
Figure 7: Distribution of activation patterns. The x-axis is the layer index, and we show minimum/maximum/average number of positive channels after each convolution with ReLU. y-axis is either absolute or relative number of channels. The "threshold" line indicates the ReLU invertibility threshold - that is the number of positive dimensions is higher than the input space. In our case this is 1/6 fraction of the channels. Note how at the beginning of the training on Figure 7a the distribution is much more tightly concentrated around the mean. After the training has finished (Figure 7b), the average hasn't changed but the standard deviation grew dramatically. Best viewed in color.
图 7:激活模式的分布。横轴是层序号,我们展示每层带 ReLU 的卷积之后正通道的最小/最大/平均值。纵轴是通道数的绝对值或相对值。“threshold”线表示 ReLU 可逆的阈值,也就是正维度数目高于输入空间的维数;在我们这里,这相当于通道数的 1/6。注意,训练开始时(图 7a)分布更紧密地集中在均值附近;训练结束后(图 7b),平均值几乎没变,但标准差显著增大。请看彩色图。
Lemma 2(Invertibility of ReLU)
Consider an operator , where is an matrix and . Let for some , then equation has a unique solution with respect to if and only if has at least non-zero values and there are linearly independent rows of that correspond to non-zero coordinates of .
引理 2(ReLU 的可逆性)
考虑算子 ,其中 是 矩阵,。设对某个 有 ,则方程 关于 有唯一解,当且仅当 至少有 个非零值,并且 中有 个线性无关的行对应于 的非零坐标。
Proof:
Denote the set of non-zero coordinates of as and let and be restrictions of and to the subspace defined by . If , we have where is under-determined with at least one solution , thus there are infinitely many solutions. Now consider the case of and let the rank of be . Suppose there is an additional solution such that , then we have , which cannot be satisfied unless .
证明:
把 的非零坐标集合记为 ,并令 和 为 和 在 所定义子空间上的限制。若 ,则有 ,其中 欠定且至少有一个解 ,因此有无穷多解。现在考虑 且 的秩为 的情形。假设另有解 使得 ,则 ,除非 ,否则无法成立。
One of the corollaries of this lemma says that if , we only need a small fraction of values of to be positive for to be invertible.
该引理的一个推论是:若 ,只需 中一小部分值为正, 就可以可逆。
The constraints of the lemma 2 can be empirically validated for real networks and real inputs and hence we can be assured that information is indeed preserved. We further show that with respect to initialization, we can be sure that these constraints are satisfied with high probability. Note that for random initialization the conditions of lemma 2 are satisfied due to initialization symmetries. However even for trained graphs these constraints can be empirically validated by running the network over valid inputs and verifying that all or most inputs are above the threshold. On Figure 7 we show how this distribution looks for different MobileNetV2 layers. At step the activation patterns concentrate around having half of the positive channel (as predicted by initialization symmetries). For fully trained network, while the standard deviation grew significantly, all but the two layers are still above the invertibility thresholds. We believe further study of this is warranted and might lead to helpful insights on network design.
引理 2 的约束可以在真实网络和真实输入上经验验证,因而我们可以确信信息确实被保留。我们进一步说明,就初始化而言,这些约束会以高概率得到满足。注意,随机初始化时,由于初始化对称性,引理 2 的条件是满足的。即便对训练后的图,也可以通过在有效输入上运行网络、验证全部或大多数输入高于阈值,来经验地验证这些约束。图 7 展示了这一分布在不同 MobileNetV2 层上的样子。第 0 步时,激活模式集中在大约一半通道为正(与初始化对称性的预测一致)。对完全训练的网络,尽管标准差显著增大,除两层外所有层仍高于可逆性阈值。我们相信这一点值得进一步研究,并可能对网络设计带来有益洞见。
Theorem 1
Let be a compact -dimensional submanifold of . Consider a family of functions from to parameterized by matrices . Let be a probability density on the space of all matrices that satisfies:
定理 1
设 是 的紧致 维子流形。考虑由 矩阵 参数化的一族函数 ,它们从 映到 。设 是所有矩阵空间 上的概率密度,并满足:
- • for any measure-zero subset;
- • 对任何测度为零的子集 ,有 ;
- • (a symmetry condition)for anyand anydiagonal matrixwith all diagonal elements being eitheror.
- • (对称性条件)对任何 以及任何对角元全为 或 的 对角矩阵 ,有 。
Then, the average -volume of the subset of that is collapsed by to a lower-dimensional manifold is
那么,被 塌缩到更低维流形的 的子集的平均 维体积为
where and
其中 ,并且
Proof:
For any with , let be a corresponding quadrant in . For any -dimensional submanifold , acts as a bijection on if has at least positive values[^4] and contracts otherwise. Also notice that the intersection of with is almost surely -dimensional. The average -volume of that is not collapsed by applying to is therefore given by:
证明:
对任意 且 ,令 为 中相应的卦限。对任何 维子流形 ,若 至少有 个正值,则 在 上是双射[^4],否则会收缩 。还要注意, 与 的交几乎必然是 维的。因此,对 施加 后不被塌缩的 的平均 维体积由下式给出:
where , is a step function and is a volume of the largest subset of that is mapped by to . Now let us calculate . Recalling that for any with , this average can be rewritten as . Noticing that the subset of mapped by to is also mapped by to , we immediately obtain and therefore . Substituting this and into Eq. 3 concludes the proof.
其中 , 是阶跃函数, 是 中被 映射到 的最大子集的体积。现在计算 。回忆对任何 且 都有 ,这一平均可以改写为 。注意到被 映射到 的 的子集,也被 映射到 ,我们立即得到 ,因此 。把这一点以及 代入公式 3,即完成证明。
Notice that for sufficiently large expansion layers with , the fraction of collapsed space can be bounded by:
注意,对足够大的扩展层 ,被塌缩空间的比例 可以界定为:
and therefore performs a nonlinear transformation while preserving information with high probability.
因此 在以高概率保留信息的同时执行非线性变换。
We discussed how bottlenecks can prevent manifold collapse, but increasing the size of the bottleneck expansion may also make it possible for the network to represent more complex functions. Following the main results of [47], one can show, for example, that for any integer and there exist a network of layers, each containing neurons and a bottleneck expansion of size such that it maps input volumes (linearly isomorphic to ) to the same output region . Any complex possibly nonlinear function attached to the network output would thus effectively compute function values for input linear regions.
我们讨论了瓶颈如何防止流形塌缩,但增大瓶颈扩展也可能使网络能够表示更复杂的函数。沿用已有主要结果,可以证明:例如对任何整数 和 ,存在一个由 个 层组成的网络,每层含 个神经元、瓶颈扩展大小为 ,它能把 个输入体积(线性同构于 )映射到同一输出区域 。接到网络输出上的任何复杂、可能非线性的函数,因而会有效地为 个输入线性区域计算函数值。
Appendix B Semantic segmentation visualization results
附录 B 语义分割可视化结果
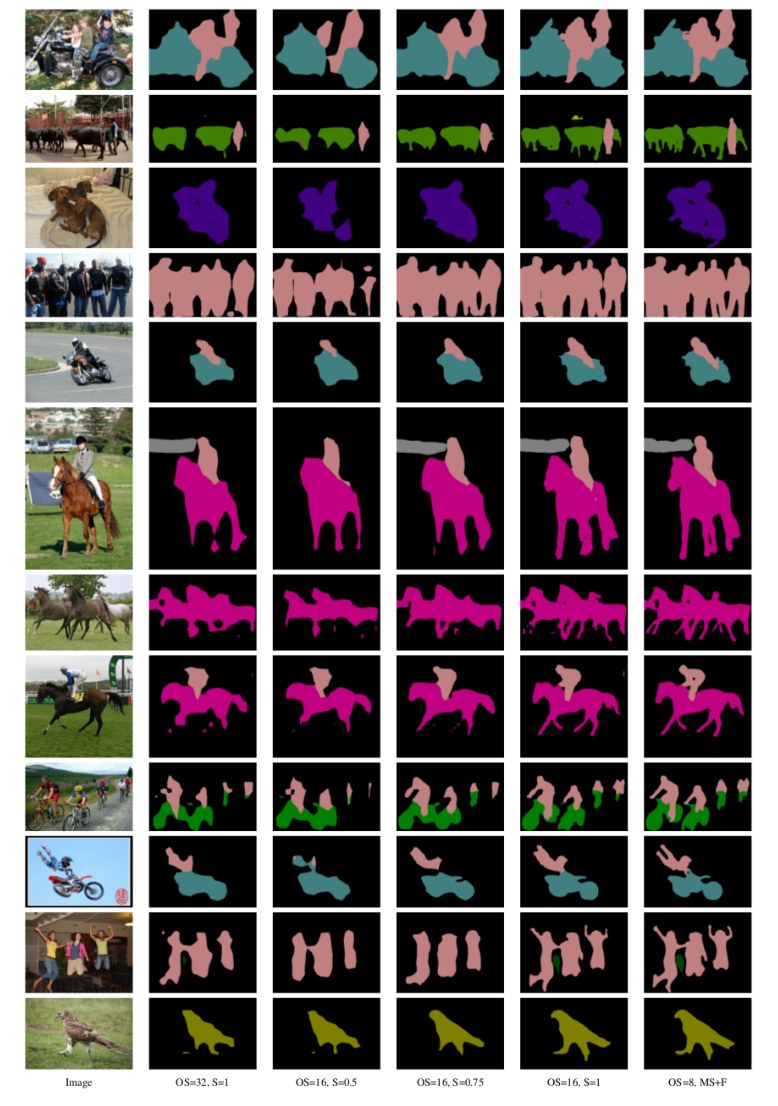
Figure 8: MobileNetv2 semantic segmentation visualization results on PASCAL VOC 2012 val set. OS: . S: single scale input. MS+F: Multi-scale inputs with scales = and left-right flipped inputs. Employing and single input scale = 1 attains a good trade-off between FLOPS and accuracy.
图 8:MobileNetV2 在 PASCAL VOC 2012 验证集上的语义分割可视化结果。OS:。S:单尺度输入。MS+F:多尺度输入,尺度为 ,并使用左右翻转输入。采用 且单一输入尺度为 1,能在浮点运算量和精度之间取得较好权衡。