MobileNets: Efficient Convolutional Neural Networks for Mobile Vision Applications
MobileNets: Efficient Convolutional Neural Networks for Mobile Vision Applications
MobileNets:面向移动视觉应用的高效卷积神经网络
Andrew G. Howard Menglong Zhu Bo Chen Dmitry Kalenichenko Affiliation: Weijun Wang Tobias Weyand Marco Andreetto Hartwig Adam Affiliation: Affiliation: Google Inc. Email: {howarda,menglong,bochen,dkalenichenko,weijunw,weyand,anm,hadam}@google.com
Abstract
摘要
We present a class of efficient models called MobileNets for mobile and embedded vision applications. MobileNets are based on a streamlined architecture that uses depthwise separable convolutions to build light weight deep neural networks. We introduce two simple global hyper-parameters that efficiently trade off between latency and accuracy. These hyper-parameters allow the model builder to choose the right sized model for their application based on the constraints of the problem. We present extensive experiments on resource and accuracy tradeoffs and show strong performance compared to other popular models on ImageNet classification. We then demonstrate the effectiveness of MobileNets across a wide range of applications and use cases including object detection, finegrain classification, face attributes and large scale geo-localization.
我们提出一类面向移动与嵌入式视觉应用的高效模型,称为 MobileNets。MobileNets 基于精简架构,用深度可分离卷积构建轻量深度神经网络。我们引入两个简单的全局超参数,以便在延迟与精度之间有效权衡。模型构建者可根据问题约束,借助这两个超参数选择合适规模的模型。我们给出了资源与精度权衡的大量实验,并在 ImageNet 分类上相对其他流行模型展现出较强表现。随后我们在目标检测、细粒度分类、人脸属性与大规模地理定位等多种应用与用例上验证了 MobileNets 的有效性。
1 Introduction
1 引言
Convolutional neural networks have become ubiquitous in computer vision ever since AlexNet krizhevsky2012imagenet popularized deep convolutional neural networks by winning the ImageNet Challenge: ILSVRC 2012 russakovsky2015imagenet. The general trend has been to make deeper and more complicated networks in order to achieve higher accuracy simonyan2014very; szegedy2015rethinking; szegedy2016inception; he2015deep. However, these advances to improve accuracy are not necessarily making networks more efficient with respect to size and speed. In many real world applications such as robotics, self-driving car and augmented reality, the recognition tasks need to be carried out in a timely fashion on a computationally limited platform.
自 AlexNet [krizhevsky2012imagenet] 凭借赢得 ImageNet 挑战赛 ILSVRC 2012 [russakovsky2015imagenet] 让深度卷积网络广为人知以来,卷积神经网络已成为计算机视觉中的标配。总体趋势是把网络做得更深、更复杂,以换取更高精度 [simonyan2014very; szegedy2015rethinking; szegedy2016inception; he2015deep]。然而,这些为了涨点而做的改进,并不必然让网络在体积与速度上更高效。机器人、自动驾驶、增强现实等许多现实应用,需要在算力受限的平台上及时完成识别任务。
This paper describes an efficient network architecture and a set of two hyper-parameters in order to build very small, low latency models that can be easily matched to the design requirements for mobile and embedded vision applications. Section 2 reviews prior work in building small models. Section 3 describes the MobileNet architecture and two hyper-parameters width multiplier and resolution multiplier to define smaller and more efficient MobileNets. Section 4 describes experiments on ImageNet as well a variety of different applications and use cases. Section 5 closes with a summary and conclusion.
本文描述一种高效网络架构以及一组(两个)超参数,用以构建非常小、低延迟的模型,从而容易匹配移动与嵌入式视觉应用的设计需求。第 2 节回顾构建小模型的先前工作。第 3 节描述 MobileNet 架构,以及用于定义更小、更高效 MobileNet 的两个超参数:宽度乘子与分辨率乘子。第 4 节给出 ImageNet 实验以及多种不同应用与用例。第 5 节总结并收束全文。
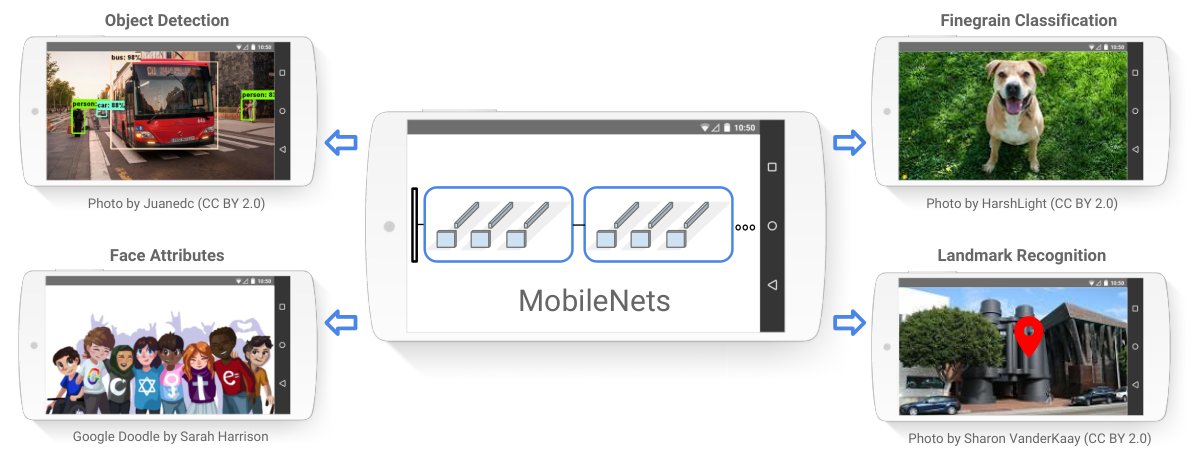
Figure 1: MobileNet models can be applied to various recognition tasks for efficient on device intelligence.
图 1:MobileNet 模型可应用于多种识别任务,实现高效的端侧智能。
2 Prior Work
2 相关工作
There has been rising interest in building small and efficient neural networks in the recent literature, e.g. jin2014flattened; wang2016factorized; iandola2016squeezenet; wu2015quantized; rastegari2016xnor. Many different approaches can be generally categorized into either compressing pretrained networks or training small networks directly. This paper proposes a class of network architectures that allows a model developer to specifically choose a small network that matches the resource restrictions (latency, size) for their application. MobileNets primarily focus on optimizing for latency but also yield small networks. Many papers on small networks focus only on size but do not consider speed.
近期文献对构建小而高效的神经网络兴趣上升,例如 [jin2014flattened; wang2016factorized; iandola2016squeezenet; wu2015quantized; rastegari2016xnor]。不同方法大体可分为压缩预训练网络,或直接训练小网络。本文提出一类网络架构,使模型开发者能够明确选择匹配其应用资源限制(延迟、体积)的小网络。MobileNets 主要优化延迟,同时也得到小网络。许多关于小网络的工作只关注体积,而不考虑速度。
MobileNets are built primarily from depthwise separable convolutions initially introduced in sifre2014rigid and subsequently used in Inception models ioffe2015batch to reduce the computation in the first few layers. Flattened networks jin2014flattened build a network out of fully factorized convolutions and showed the potential of extremely factorized networks. Independent of this current paper, Factorized Networkswang2016factorized introduces a similar factorized convolution as well as the use of topological connections. Subsequently, the Xception network chollet2016deep demonstrated how to scale up depthwise separable filters to out perform Inception V3 networks. Another small network is Squeezenet iandola2016squeezenet which uses a bottleneck approach to design a very small network. Other reduced computation networks include structured transform networks sindhwani2015structured and deep fried convnets yang2015deep.
MobileNets 主要基于深度可分离卷积构建;该运算最初在 [sifre2014rigid] 中提出,随后被 Inception 模型 [ioffe2015batch] 用于降低前几层的计算量。Flattened networks [jin2014flattened] 用完全分解的卷积搭建网络,展示了极度分解网络的潜力。与本文独立,Factorized Networks [wang2016factorized] 引入了类似的分解卷积以及拓扑连接的用法。随后,Xception 网络 [chollet2016deep] 展示了如何放大深度可分离滤波器以超越 Inception V3。另一类小网络是 SqueezeNet [iandola2016squeezenet],它用瓶颈设计得到非常小的网络。其他降低计算量的网络还包括 structured transform networks [sindhwani2015structured] 与 deep fried convnets [yang2015deep]。
A different approach for obtaining small networks is shrinking, factorizing or compressing pretrained networks. Compression based on product quantization wu2015quantized, hashing chen2015compressing, and pruning, vector quantization and Huffman coding han2015deep have been proposed in the literature. Additionally various factorizations have been proposed to speed up pretrained networks jaderberg2014speeding; lebedev2014speeding. Another method for training small networks is distillation hinton2015distilling which uses a larger network to teach a smaller network. It is complementary to our approach and is covered in some of our use cases in section 4. Another emerging approach is low bit networks courbariaux2014training; rastegari2016xnor; hubara2016quantized.
获得小网络的另一条路径是缩小、分解或压缩预训练网络。基于乘积量化 [wu2015quantized]、哈希 [chen2015compressing],以及剪枝、向量量化与霍夫曼编码 [han2015deep] 的压缩方法已有文献提出。此外也有多种分解方案用于加速预训练网络 [jaderberg2014speeding; lebedev2014speeding]。训练小网络的另一种方法是蒸馏 [hinton2015distilling],用较大网络教较小网络。它与我们的方法互补,并在第 4 节部分用例中涉及。另一类新兴方法是低比特网络 [courbariaux2014training; rastegari2016xnor; hubara2016quantized]。
3 MobileNet Architecture
3 MobileNet 架构
In this section we first describe the core layers that MobileNet is built on which are depthwise separable filters. We then describe the MobileNet network structure and conclude with descriptions of the two model shrinking hyper-parameters width multiplier and resolution multiplier.
本节首先描述构成 MobileNet 的核心层,即深度可分离滤波器;随后描述 MobileNet 网络结构;最后说明两个模型收缩超参数:宽度乘子与分辨率乘子。
3.1 Depthwise Separable Convolution
3.1 深度可分离卷积
The MobileNet model is based on depthwise separable convolutions which is a form of factorized convolutions which factorize a standard convolution into a depthwise convolution and a convolution called a pointwise convolution. For MobileNets the depthwise convolution applies a single filter to each input channel. The pointwise convolution then applies a convolution to combine the outputs the depthwise convolution. A standard convolution both filters and combines inputs into a new set of outputs in one step. The depthwise separable convolution splits this into two layers, a separate layer for filtering and a separate layer for combining. This factorization has the effect of drastically reducing computation and model size. Figure 2 shows how a standard convolution 2(a) is factorized into a depthwise convolution 2(b) and a pointwise convolution 2(c).
MobileNet 模型基于深度可分离卷积,这是一种分解卷积:把标准卷积分解为深度卷积与称为逐点卷积的 卷积。对 MobileNets 而言,深度卷积对每个输入通道施加一个滤波器;逐点卷积再用 卷积组合深度卷积的输出。标准卷积在一步内同时完成滤波与组合以产生新输出;深度可分离卷积将其拆成两层,一层负责滤波,一层负责组合。这种分解能大幅降低计算量与模型体积。图 2 展示了标准卷积 2(a) 如何被分解为深度卷积 2(b) 与 逐点卷积 2(c)。
A standard convolutional layer takes as input a feature map and produces a feature map where is the spatial width and height of a square input feature map[^1], is the number of input channels (input depth), is the spatial width and height of a square output feature map and is the number of output channel (output depth).
标准卷积层以 的特征图 为输入,产生 的特征图 ,其中 是方形输入特征图的空间宽高[^1], 是输入通道数(输入深度), 是方形输出特征图的空间宽高, 是输出通道数(输出深度)。
The standard convolutional layer is parameterized by convolution kernel of size where is the spatial dimension of the kernel assumed to be square and is number of input channels and is the number of output channels as defined previously.
标准卷积层由大小为 的卷积核 参数化,其中 是假定为正方形的核的空间尺寸, 与 分别为如前所述的输入、输出通道数。
The output feature map for standard convolution assuming stride one and padding is computed as:
在步幅为 1 且有填充时,标准卷积的输出特征图计算为:
Standard convolutions have the computational cost of:
标准卷积的计算代价为:
where the computational cost depends multiplicatively on the number of input channels , the number of output channels the kernel size and the feature map size . MobileNet models address each of these terms and their interactions. First it uses depthwise separable convolutions to break the interaction between the number of output channels and the size of the kernel.
其中计算代价乘性地依赖于输入通道数 、输出通道数 、核大小 以及特征图大小 。MobileNet 模型针对这些项及其相互作用分别处理。首先,它用深度可分离卷积打断输出通道数与核大小之间的耦合。
The standard convolution operation has the effect of filtering features based on the convolutional kernels and combining features in order to produce a new representation. The filtering and combination steps can be split into two steps via the use of factorized convolutions called depthwise separable convolutions for substantial reduction in computational cost.
标准卷积运算既按卷积核滤波特征,又组合特征以产生新表示。借助称为深度可分离卷积的分解卷积,可以把滤波与组合拆成两步,从而显著降低计算代价。
Depthwise separable convolution are made up of two layers: depthwise convolutions and pointwise convolutions. We use depthwise convolutions to apply a single filter per each input channel (input depth). Pointwise convolution, a simple convolution, is then used to create a linear combination of the output of the depthwise layer. MobileNets use both batchnorm and ReLU nonlinearities for both layers.
深度可分离卷积由两层组成:深度卷积与逐点卷积。我们用深度卷积对每个输入通道(输入深度)施加一个滤波器。随后用逐点卷积——即简单的 卷积——对深度层输出做线性组合。MobileNets 在这两层上都使用批归一化与 ReLU 非线性。
Depthwise convolution with one filter per input channel (input depth) can be written as:
每个输入通道(输入深度)一个滤波器的深度卷积可写为:
where is the depthwise convolutional kernel of size where the filter in is applied to the channel in to produce the channel of the filtered output feature map .
其中 是大小为 的深度卷积核, 中第 个滤波器作用于 的第 个通道,产生滤波后输出特征图 的第 个通道。
Depthwise convolution has a computational cost of:
深度卷积的计算代价为:
Depthwise convolution is extremely efficient relative to standard convolution. However it only filters input channels, it does not combine them to create new features. So an additional layer that computes a linear combination of the output of depthwise convolution via convolution is needed in order to generate these new features.
相对标准卷积,深度卷积极为高效。但它只滤波输入通道,并不把它们组合以产生新特征。因此还需要额外一层,通过 卷积对深度卷积输出做线性组合,以生成这些新特征。
The combination of depthwise convolution and (pointwise) convolution is called depthwise separable convolution which was originally introduced in sifre2014rigid.
深度卷积与 (逐点)卷积的组合称为深度可分离卷积,最初由 [sifre2014rigid] 引入。
Depthwise separable convolutions cost:
深度可分离卷积的代价为:
which is the sum of the depthwise and pointwise convolutions.
即深度卷积与 逐点卷积代价之和。
By expressing convolution as a two step process of filtering and combining we get a reduction in computation of:
把卷积表述为滤波与组合两步之后,计算量的削减比为:
MobileNet uses depthwise separable convolutions which uses between 8 to 9 times less computation than standard convolutions at only a small reduction in accuracy as seen in Section 4.
MobileNet 使用 深度可分离卷积,相对标准卷积大约少用 8 到 9 倍计算量,而精度仅小幅下降,见第 4 节。
(a) Standard Convolution Filters
(a)标准卷积滤波器
Additional factorization in spatial dimension such as in jin2014flattened; szegedy2015rethinking does not save much additional computation as very little computation is spent in depthwise convolutions.
像 [jin2014flattened; szegedy2015rethinking] 那样在空间维上进一步分解,并不会再省下多少计算,因为深度卷积本身占用的计算已经很少。
3.2 Network Structure and Training
3.2 网络结构与训练
The MobileNet structure is built on depthwise separable convolutions as mentioned in the previous section except for the first layer which is a full convolution. By defining the network in such simple terms we are able to easily explore network topologies to find a good network. The MobileNet architecture is defined in Table 1. All layers are followed by a batchnorm ioffe2015batch and ReLU nonlinearity with the exception of the final fully connected layer which has no nonlinearity and feeds into a softmax layer for classification. Figure 3 contrasts a layer with regular convolutions, batchnorm and ReLU nonlinearity to the factorized layer with depthwise convolution, pointwise convolution as well as batchnorm and ReLU after each convolutional layer. Down sampling is handled with strided convolution in the depthwise convolutions as well as in the first layer. A final average pooling reduces the spatial resolution to 1 before the fully connected layer. Counting depthwise and pointwise convolutions as separate layers, MobileNet has 28 layers.
如前一节所述,MobileNet 结构建立在深度可分离卷积之上,唯有第一层是完整卷积。以如此简单的方式定义网络,使我们能方便地探索拓扑以找到合适的网络。MobileNet 架构定义见表 1。除最终全连接层无非线性并送入 Softmax 做分类外,所有层后都接批归一化 [ioffe2015batch] 与 ReLU 非线性。图 3 对照了“常规卷积 + 批归一化 + ReLU”的层,与“深度卷积 + 逐点卷积、且每层卷积后都接批归一化与 ReLU”的分解层。下采样由深度卷积以及第一层中的跨步卷积完成。最终平均池化把空间分辨率降为 1,再接全连接层。若把深度卷积与逐点卷积计为单独层,MobileNet 共有 28 层。
It is not enough to simply define networks in terms of a small number of Mult-Adds. It is also important to make sure these operations can be efficiently implementable. For instance unstructured sparse matrix operations are not typically faster than dense matrix operations until a very high level of sparsity. Our model structure puts nearly all of the computation into dense convolutions. This can be implemented with highly optimized general matrix multiply (GEMM) functions. Often convolutions are implemented by a GEMM but require an initial reordering in memory called im2col in order to map it to a GEMM. For instance, this approach is used in the popular Caffe package jia2014caffe. convolutions do not require this reordering in memory and can be implemented directly with GEMM which is one of the most optimized numerical linear algebra algorithms. MobileNet spends of it’s computation time in convolutions which also has of the parameters as can be seen in Table 2. Nearly all of the additional parameters are in the fully connected layer.
仅用较少的乘加次数来定义网络还不够,还须确保这些运算能高效实现。例如,非结构化稀疏矩阵运算通常要到稀疏度很高时才比稠密运算更快。我们的模型结构几乎把全部计算放进稠密 卷积,可用高度优化的通用矩阵乘(GEMM)实现。卷积常常通过 GEMM 实现,但需要先做称为 im2col 的内存重排才能映射到 GEMM;例如流行的 Caffe 包 [jia2014caffe] 即如此。 卷积不需要这种重排,可直接用 GEMM 实现,而 GEMM 是数值线性代数中优化最充分的算法之一。如表 2 所示,MobileNet 约 95% 的计算时间花在 卷积上,参数也约占 75%。几乎其余参数都在全连接层。
MobileNet models were trained in TensorFlow abadi2015tensorflow using RMSprop tieleman2012lecture with asynchronous gradient descent similar to Inception V3 szegedy2015rethinking. However, contrary to training large models we use less regularization and data augmentation techniques because small models have less trouble with overfitting. When training MobileNets we do not use side heads or label smoothing and additionally reduce the amount image of distortions by limiting the size of small crops that are used in large Inception training szegedy2015rethinking. Additionally, we found that it was important to put very little or no weight decay (l2 regularization) on the depthwise filters since their are so few parameters in them. For the ImageNet benchmarks in the next section all models were trained with same training parameters regardless of the size of the model.
MobileNet 模型在 TensorFlow [abadi2015tensorflow] 中用 RMSprop [tieleman2012lecture] 训练,异步梯度下降设定类似 Inception V3 [szegedy2015rethinking]。不过与训练大模型相反,我们使用更少的正则与数据增强,因为小模型更不易过拟合。训练 MobileNets 时我们不用旁路头或标签平滑,并减少图像扰动:限制大 Inception 训练中使用的小裁剪尺寸 [szegedy2015rethinking]。此外我们发现,对深度滤波器施加很少或根本不施加权重衰减(L2 正则)很重要,因为它们参数极少。下一节 ImageNet 基准中,所有模型不论大小都用相同训练超参。
| Type / Stride | Filter Shape | Input Size |
|---|---|---|
| Conv / s2 | ||
| Conv dw / s1 | dw | |
| Conv / s1 | ||
| Conv dw / s2 | dw | |
| Conv / s1 | ||
| Conv dw / s1 | dw | |
| Conv / s1 | ||
| Conv dw / s2 | dw | |
| Conv / s1 | ||
| Conv dw / s1 | dw | |
| Conv / s1 | ||
| Conv dw / s2 | dw | |
| Conv / s1 | ||
| Conv dw / s1 | dw | |
| Conv / s1 | ||
| Conv dw / s2 | dw | |
| Conv / s1 | ||
| Conv dw / s2 | dw | |
| Conv / s1 | ||
| Avg Pool / s1 | Pool | |
| FC / s1 | ||
| Softmax / s1 | Classifier |
Table 1: MobileNet Body Architecture
| 类型 / 步幅 | 滤波器形状 | 输入尺寸 |
|---|---|---|
| Conv / s2 | ||
| Conv dw / s1 | dw | |
| Conv / s1 | ||
| Conv dw / s2 | dw | |
| Conv / s1 | ||
| Conv dw / s1 | dw | |
| Conv / s1 | ||
| Conv dw / s2 | dw | |
| Conv / s1 | ||
| Conv dw / s1 | dw | |
| Conv / s1 | ||
| Conv dw / s2 | dw | |
| Conv / s1 | ||
| Conv dw / s1 | dw | |
| Conv / s1 | ||
| Conv dw / s2 | dw | |
| Conv / s1 | ||
| Conv dw / s2 | dw | |
| Conv / s1 | ||
| Avg Pool / s1 | Pool | |
| FC / s1 | ||
| Softmax / s1 | Classifier |
表 1:MobileNet 主体架构
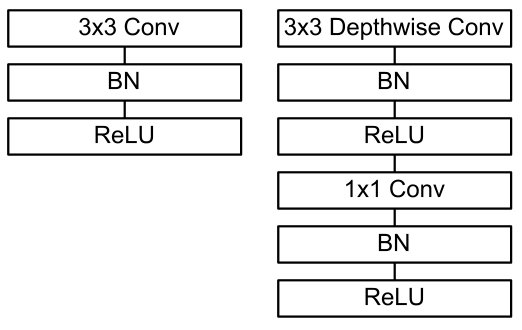
Figure 3: Left: Standard convolutional layer with batchnorm and ReLU. Right: Depthwise Separable convolutions with Depthwise and Pointwise layers followed by batchnorm and ReLU.
图 3:左:带批归一化与 ReLU 的标准卷积层。右:深度可分离卷积,深度层与逐点层后各接批归一化与 ReLU。
| Type | Mult-Adds | Parameters |
|---|---|---|
| Conv | 94.86% | 74.59% |
| Conv DW | 3.06% | 1.06% |
| Conv | 1.19% | 0.02% |
| Fully Connected | 0.18% | 24.33% |
Table 2: Resource Per Layer Type
| 类型 | 乘加 | 参数 |
|---|---|---|
| Conv | 94.86% | 74.59% |
| Conv DW | 3.06% | 1.06% |
| Conv | 1.19% | 0.02% |
| Fully Connected | 0.18% | 24.33% |
表 2:按层类型划分的资源占比
3.3 Width Multiplier: Thinner Models
3.3 宽度乘子:更瘦的模型
Although the base MobileNet architecture is already small and low latency, many times a specific use case or application may require the model to be smaller and faster. In order to construct these smaller and less computationally expensive models we introduce a very simple parameter called width multiplier. The role of the width multiplier is to thin a network uniformly at each layer. For a given layer and width multiplier , the number of input channels becomes and the number of output channels becomes .
尽管基础 MobileNet 架构已经小且低延迟,许多具体用例或应用仍可能要求模型更小、更快。为构建这些更小、计算更省的模型,我们引入一个非常简单的参数 ,称为宽度乘子。宽度乘子 的作用是在每一层均匀地“抽瘦”网络。对给定层与宽度乘子 ,输入通道数 变为 ,输出通道数 变为 。
The computational cost of a depthwise separable convolution with width multiplier is:
带宽度乘子 的深度可分离卷积计算代价为:
where with typical settings of 1, 0.75, 0.5 and 0.25. is the baseline MobileNet and are reduced MobileNets. Width multiplier has the effect of reducing computational cost and the number of parameters quadratically by roughly . Width multiplier can be applied to any model structure to define a new smaller model with a reasonable accuracy, latency and size trade off. It is used to define a new reduced structure that needs to be trained from scratch.
其中 ,典型取值为 1、0.75、0.5 与 0.25。 是基准 MobileNet, 是缩小版 MobileNet。宽度乘子使计算代价与参数量大致按 二次下降。宽度乘子可施加到任何模型结构上,以定义在精度、延迟与体积之间有合理权衡的新的更小模型。它用于定义需要从头训练的新的缩小结构。
3.4 Resolution Multiplier: Reduced Representation
3.4 分辨率乘子:降低表示分辨率
The second hyper-parameter to reduce the computational cost of a neural network is a resolution multiplier . We apply this to the input image and the internal representation of every layer is subsequently reduced by the same multiplier. In practice we implicitly set by setting the input resolution.
降低神经网络计算代价的第二个超参数是分辨率乘子 。我们把它施加到输入图像上,随后每一层的内部表示都按同一乘子缩小。实践中,我们通过设定输入分辨率来隐式设定 。
We can now express the computational cost for the core layers of our network as depthwise separable convolutions with width multiplier and resolution multiplier :
现在可以把网络核心层的计算代价写成带宽度乘子 与分辨率乘子 的深度可分离卷积:
where which is typically set implicitly so that the input resolution of the network is 224, 192, 160 or 128. is the baseline MobileNet and are reduced computation MobileNets. Resolution multiplier has the effect of reducing computational cost by .
其中 ,通常隐式设定以使网络输入分辨率为 224、192、160 或 128。 是基准 MobileNet, 是计算量更小的 MobileNet。分辨率乘子使计算代价按 下降。
As an example we can look at a typical layer in MobileNet and see how depthwise separable convolutions, width multiplier and resolution multiplier reduce the cost and parameters. Table 3 shows the computation and number of parameters for a layer as architecture shrinking methods are sequentially applied to the layer. The first row shows the Mult-Adds and parameters for a full convolutional layer with an input feature map of size with a kernel of size . We will look in detail in the next section at the trade offs between resources and accuracy.
作为例子,可以看 MobileNet 中典型的一层,观察深度可分离卷积、宽度乘子与分辨率乘子如何降低代价与参数。表 3 展示了在一层上依次施加架构收缩方法时的计算量与参数量。第一行给出输入特征图 、核 大小 的完整卷积层的乘加与参数。下一节将详细讨论资源与精度之间的权衡。
| Layer/Modification | Million | Million |
|---|---|---|
| Mult-Adds | Parameters | |
| Convolution | 462 | 2.36 |
| Depthwise Separable Conv | 52.3 | 0.27 |
| 29.6 | 0.15 | |
| 15.1 | 0.15 |
Table 3: Resource usage for modifications to standard convolution. Note that each row is a cumulative effect adding on top of the previous row. This example is for an internal MobileNet layer with , , , .
| 层/改动 | 百万 | 百万 |
|---|---|---|
| 乘加 | 参数 | |
| Convolution | 462 | 2.36 |
| Depthwise Separable Conv | 52.3 | 0.27 |
| 29.6 | 0.15 | |
| 15.1 | 0.15 |
表 3:对标准卷积逐步改动后的资源占用。注意每一行是在上一行之上的累计效果。本例对应内部 MobileNet 层,,,,。
4 Experiments
4 实验
In this section we first investigate the effects of depthwise convolutions as well as the choice of shrinking by reducing the width of the network rather than the number of layers. We then show the trade offs of reducing the network based on the two hyper-parameters: width multiplier and resolution multiplier and compare results to a number of popular models. We then investigate MobileNets applied to a number of different applications.
本节首先考察深度卷积的效果,以及选择通过减小网络宽度而非层数来收缩的做法。随后展示基于两个超参数——宽度乘子与分辨率乘子——缩小网络时的权衡,并与若干流行模型比较。接着考察 MobileNets 在多种不同应用上的表现。
4.1 Model Choices
4.1 模型选择
First we show results for MobileNet with depthwise separable convolutions compared to a model built with full convolutions. In Table 4 we see that using depthwise separable convolutions compared to full convolutions only reduces accuracy by on ImageNet was saving tremendously on mult-adds and parameters.
首先给出使用深度可分离卷积的 MobileNet 与使用完整卷积构建的模型的对比。表 4 显示,相对完整卷积,使用深度可分离卷积在 ImageNet 上精度仅下降 ,却大幅节省乘加与参数。
| Model | ImageNet | Million | Million |
|---|---|---|---|
| Accuracy | Mult-Adds | Parameters | |
| Conv MobileNet | 71.7% | 4866 | 29.3 |
| MobileNet | 70.6% | 569 | 4.2 |
Table 4: Depthwise Separable vs Full Convolution MobileNet
| 模型 | ImageNet | 百万 | 百万 |
|---|---|---|---|
| 精度 | 乘加 | 参数 | |
| Conv MobileNet | 71.7% | 4866 | 29.3 |
| MobileNet | 70.6% | 569 | 4.2 |
表 4:深度可分离卷积 vs 完整卷积 MobileNet
We next show results comparing thinner models with width multiplier to shallower models using less layers. To make MobileNet shallower, the layers of separable filters with feature size in Table 1 are removed. Table 5 shows that at similar computation and number of parameters, that making MobileNets thinner is better than making them shallower.
接下来比较用宽度乘子得到的更瘦模型,与减少层数得到的更浅模型。为使 MobileNet 变浅,去掉表 1 中特征尺寸为 的 5 层可分离滤波器。表 5 显示,在相近计算量与参数量下,把 MobileNet 做瘦比做浅好约 。
| Model | ImageNet | Million | Million |
|---|---|---|---|
| Accuracy | Mult-Adds | Parameters | |
| 0.75 MobileNet | 68.4% | 325 | 2.6 |
| Shallow MobileNet | 65.3% | 307 | 2.9 |
Table 5: Narrow vs Shallow MobileNet
| 模型 | ImageNet | 百万 | 百万 |
|---|---|---|---|
| 精度 | 乘加 | 参数 | |
| 0.75 MobileNet | 68.4% | 325 | 2.6 |
| Shallow MobileNet | 65.3% | 307 | 2.9 |
表 5:更窄 vs 更浅的 MobileNet
4.2 Model Shrinking Hyperparameters
4.2 模型收缩超参数
Table 6 shows the accuracy, computation and size trade offs of shrinking the MobileNet architecture with the width multiplier . Accuracy drops off smoothly until the architecture is made too small at .
表 6 展示用宽度乘子 收缩 MobileNet 架构时的精度、计算与体积权衡。精度平滑下降,直到 时架构过小。
| Width Multiplier | ImageNet | Million | Million |
|---|---|---|---|
| Accuracy | Mult-Adds | Parameters | |
| 1.0 MobileNet-224 | 70.6% | 569 | 4.2 |
| 0.75 MobileNet-224 | 68.4% | 325 | 2.6 |
| 0.5 MobileNet-224 | 63.7% | 149 | 1.3 |
| 0.25 MobileNet-224 | 50.6% | 41 | 0.5 |
Table 6: MobileNet Width Multiplier
| 宽度乘子 | ImageNet | 百万 | 百万 |
|---|---|---|---|
| 精度 | 乘加 | 参数 | |
| 1.0 MobileNet-224 | 70.6% | 569 | 4.2 |
| 0.75 MobileNet-224 | 68.4% | 325 | 2.6 |
| 0.5 MobileNet-224 | 63.7% | 149 | 1.3 |
| 0.25 MobileNet-224 | 50.6% | 41 | 0.5 |
表 6:MobileNet 宽度乘子
Table 7 shows the accuracy, computation and size trade offs for different resolution multipliers by training MobileNets with reduced input resolutions. Accuracy drops off smoothly across resolution.
表 7 展示以降低输入分辨率训练 MobileNet 时,不同分辨率乘子下的精度、计算与体积权衡。精度随分辨率平滑下降。
| Resolution | ImageNet | Million | Million |
|---|---|---|---|
| Accuracy | Mult-Adds | Parameters | |
| 1.0 MobileNet-224 | 70.6% | 569 | 4.2 |
| 1.0 MobileNet-192 | 69.1% | 418 | 4.2 |
| 1.0 MobileNet-160 | 67.2% | 290 | 4.2 |
| 1.0 MobileNet-128 | 64.4% | 186 | 4.2 |
Table 7: MobileNet Resolution
| 分辨率 | ImageNet | 百万 | 百万 |
|---|---|---|---|
| 精度 | 乘加 | 参数 | |
| 1.0 MobileNet-224 | 70.6% | 569 | 4.2 |
| 1.0 MobileNet-192 | 69.1% | 418 | 4.2 |
| 1.0 MobileNet-160 | 67.2% | 290 | 4.2 |
| 1.0 MobileNet-128 | 64.4% | 186 | 4.2 |
表 7:MobileNet 分辨率
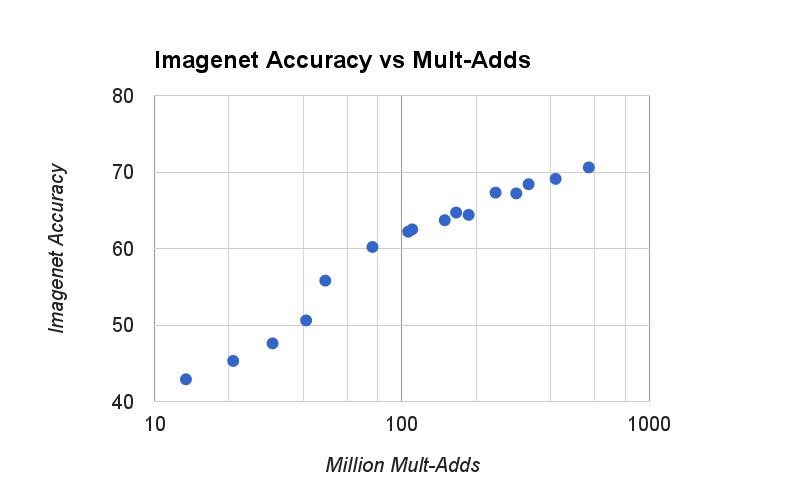
Figure 4: This figure shows the trade off between computation (Mult-Adds) and accuracy on the ImageNet benchmark. Note the log linear dependence between accuracy and computation.
图 4:本图展示 ImageNet 基准上计算量(乘加)与精度之间的权衡。注意精度与计算量呈对数线性关系。
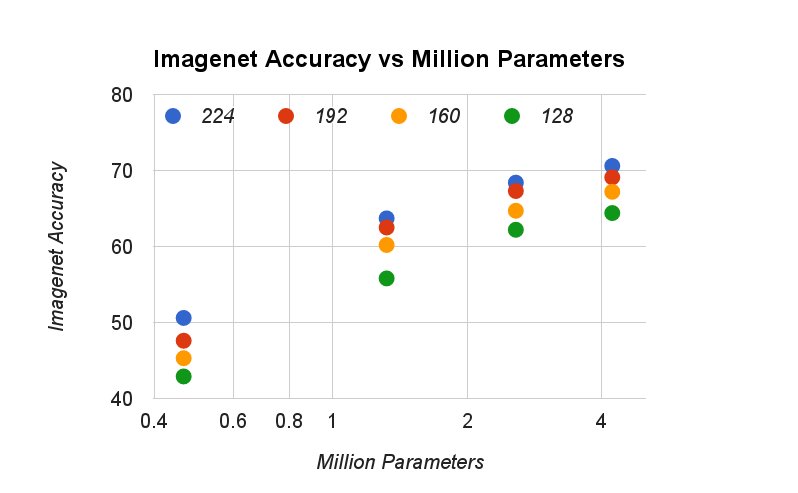
Figure 5: This figure shows the trade off between the number of parameters and accuracy on the ImageNet benchmark. The colors encode input resolutions. The number of parameters do not vary based on the input resolution.
图 5:本图展示 ImageNet 基准上参数量与精度之间的权衡。颜色编码输入分辨率。参数量不随输入分辨率变化。
Figure 4 shows the trade off between ImageNet Accuracy and computation for the 16 models made from the cross product of width multiplier and resolutions . Results are log linear with a jump when models get very small at .
图 4 展示由宽度乘子 与分辨率 叉积得到的 16 个模型在 ImageNet 精度与计算量之间的权衡。结果呈对数线性,在 的极小模型处出现跳跃。
Figure 5 shows the trade off between ImageNet Accuracy and number of parameters for the 16 models made from the cross product of width multiplier and resolutions .
图 5 展示由宽度乘子 与分辨率 叉积得到的 16 个模型在 ImageNet 精度与参数量之间的权衡。
Table 8 compares full MobileNet to the original GoogleNet szegedy2015going and VGG16 simonyan2014very. MobileNet is nearly as accurate as VGG16 while being 32 times smaller and 27 times less compute intensive. It is more accurate than GoogleNet while being smaller and more than 2.5 times less computation.
表 8 将完整 MobileNet 与原始 GoogLeNet [szegedy2015going] 及 VGG16 [simonyan2014very] 比较。MobileNet 精度接近 VGG16,同时体积约为其 1/32,计算量约为其 1/27。它比 GoogLeNet 更准,同时更小,计算量不到对方的 2.5 分之一还多。
Table 9 compares a reduced MobileNet with width multiplier and reduced resolution . Reduced MobileNet is better than AlexNet krizhevsky2012imagenet while being smaller and less compute than AlexNet. It is also better than Squeezenet iandola2016squeezenet at about the same size and less computation.
表 9 比较宽度乘子 、分辨率降至 的缩小版 MobileNet。缩小版 MobileNet 比 AlexNet [krizhevsky2012imagenet] 高约 ,同时体积约为其 ,计算量约为其 。相对 SqueezeNet [iandola2016squeezenet],在体积相近时高约 ,计算量约为其 。
| Model | ImageNet | Million | Million |
|---|---|---|---|
| Accuracy | Mult-Adds | Parameters | |
| 1.0 MobileNet-224 | 70.6% | 569 | 4.2 |
| GoogleNet | 69.8% | 1550 | 6.8 |
| VGG 16 | 71.5% | 15300 | 138 |
Table 8: MobileNet Comparison to Popular Models
| 模型 | ImageNet | 百万 | 百万 |
|---|---|---|---|
| 精度 | 乘加 | 参数 | |
| 1.0 MobileNet-224 | 70.6% | 569 | 4.2 |
| GoogleNet | 69.8% | 1550 | 6.8 |
| VGG 16 | 71.5% | 15300 | 138 |
表 8:MobileNet 与流行模型对比
| Model | ImageNet | Million | Million |
|---|---|---|---|
| Accuracy | Mult-Adds | Parameters | |
| 0.50 MobileNet-160 | 60.2% | 76 | 1.32 |
| Squeezenet | 57.5% | 1700 | 1.25 |
| AlexNet | 57.2% | 720 | 60 |
Table 9: Smaller MobileNet Comparison to Popular Models
| 模型 | ImageNet | 百万 | 百万 |
|---|---|---|---|
| 精度 | 乘加 | 参数 | |
| 0.50 MobileNet-160 | 60.2% | 76 | 1.32 |
| Squeezenet | 57.5% | 1700 | 1.25 |
| AlexNet | 57.2% | 720 | 60 |
表 9:更小 MobileNet 与流行模型对比
4.3 Fine Grained Recognition
4.3 细粒度识别
We train MobileNet for fine grained recognition on the Stanford Dogs dataset KhoslaYaoJayadevaprakashFeiFei_FGVC2011. We extend the approach of krause2015unreasonable and collect an even larger but noisy training set than krause2015unreasonable from the web. We use the noisy web data to pretrain a fine grained dog recognition model and then fine tune the model on the Stanford Dogs training set. Results on Stanford Dogs test set are in Table 10. MobileNet can almost achieve the state of the art results from krause2015unreasonable at greatly reduced computation and size.
我们在 Stanford Dogs 数据集 [KhoslaYaoJayadevaprakashFeiFei_FGVC2011] 上训练 MobileNet 做细粒度识别。我们扩展 [krause2015unreasonable] 的方法,从网络收集比其更大、但更嘈杂的训练集;用嘈杂网页数据预训练细粒度狗种识别模型,再在 Stanford Dogs 训练集上微调。测试集结果见表 10。MobileNet 几乎达到 [krause2015unreasonable] 的当时最好结果,而计算量与体积大幅降低。
| Model | Top-1 | Million | Million |
|---|---|---|---|
| Accuracy | Mult-Adds | Parameters | |
| Inception V3 krause2015unreasonable | 84% | 5000 | 23.2 |
| 1.0 MobileNet-224 | 83.3% | 569 | 3.3 |
| 0.75 MobileNet-224 | 81.9% | 325 | 1.9 |
| 1.0 MobileNet-192 | 81.9% | 418 | 3.3 |
| 0.75 MobileNet-192 | 80.5% | 239 | 1.9 |
Table 10: MobileNet for Stanford Dogs
| 模型 | Top-1 | 百万 | 百万 |
|---|---|---|---|
| 精度 | 乘加 | 参数 | |
| Inception V3 krause2015unreasonable | 84% | 5000 | 23.2 |
| 1.0 MobileNet-224 | 83.3% | 569 | 3.3 |
| 0.75 MobileNet-224 | 81.9% | 325 | 1.9 |
| 1.0 MobileNet-192 | 81.9% | 418 | 3.3 |
| 0.75 MobileNet-192 | 80.5% | 239 | 1.9 |
表 10:Stanford Dogs 上的 MobileNet
4.4 Large Scale Geolocalizaton
4.4 大规模地理定位
| Scale | Im2GPS hays2014large | PlaNet weyand2016planet | PlaNet |
|---|---|---|---|
| MobileNet | |||
| Continent (2500 km) | 51.9% | 77.6% | 79.3% |
| Country (750 km) | 35.4% | 64.0% | 60.3% |
| Region (200 km) | 32.1% | 51.1% | 45.2% |
| City (25 km) | 21.9% | 31.7% | 31.7% |
| Street (1 km) | 2.5% | 11.0% | 11.4% |
Table 11: Performance of PlaNet using the MobileNet architecture. Percentages are the fraction of the Im2GPS test dataset that were localized within a certain distance from the ground truth. The numbers for the original PlaNet model are based on an updated version that has an improved architecture and training dataset.
| 尺度 | Im2GPS hays2014large | PlaNet weyand2016planet | PlaNet |
|---|---|---|---|
| MobileNet | |||
| Continent (2500 km) | 51.9% | 77.6% | 79.3% |
| Country (750 km) | 35.4% | 64.0% | 60.3% |
| Region (200 km) | 32.1% | 51.1% | 45.2% |
| City (25 km) | 21.9% | 31.7% | 31.7% |
| Street (1 km) | 2.5% | 11.0% | 11.4% |
表 11:使用 MobileNet 架构的 PlaNet 表现。百分比为 Im2GPS 测试集中定位到距真值某距离以内的比例。原版 PlaNet 数字基于架构与训练数据已改进的更新版本。
PlaNet weyand2016planet casts the task of determining where on earth a photo was taken as a classification problem. The approach divides the earth into a grid of geographic cells that serve as the target classes and trains a convolutional neural network on millions of geo-tagged photos. PlaNet has been shown to successfully localize a large variety of photos and to outperform Im2GPS hays2008im2gps; hays2014large that addresses the same task.
PlaNet [weyand2016planet] 把判断一张照片在地球何处拍摄的任务写成分类问题:把地球划成地理单元格网格作为目标类别,在数百万带地理标签的照片上训练卷积神经网络。PlaNet 已显示能成功定位大量各类照片,并优于处理同一任务的 Im2GPS [hays2008im2gps; hays2014large]。
We re-train PlaNet using the MobileNet architecture on the same data. While the full PlaNet model based on the Inception V3 architecture szegedy2015rethinking has 52 million parameters and 5.74 billion mult-adds. The MobileNet model has only 13 million parameters with the usual 3 million for the body and 10 million for the final layer and 0.58 Million mult-adds. As shown in Tab. 11, the MobileNet version delivers only slightly decreased performance compared to PlaNet despite being much more compact. Moreover, it still outperforms Im2GPS by a large margin.
我们在相同数据上用 MobileNet 架构重新训练 PlaNet。基于 Inception V3 架构 [szegedy2015rethinking] 的完整 PlaNet 模型有 5200 万参数与 57.4 亿乘加;MobileNet 模型仅有 1300 万参数(主体通常约 300 万,最后一层约 1000 万)与 0.58 亿乘加。如表 11 所示,尽管紧凑得多,MobileNet 版本相对 PlaNet 性能仅略降,且仍大幅优于 Im2GPS。
4.5 Face Attributes
4.5 人脸属性
Another use-case for MobileNet is compressing large systems with unknown or esoteric training procedures. In a face attribute classification task, we demonstrate a synergistic relationship between MobileNet and distillation hinton2015distilling, a knowledge transfer technique for deep networks. We seek to reduce a large face attribute classifier with million parameters and million Mult-Adds. The classifier is trained on a multi-attribute dataset similar to YFCC100M thomee2016yfcc100m.
MobileNet 的另一用例是压缩训练流程未知或偏门的大型系统。在人脸属性分类任务上,我们展示 MobileNet 与蒸馏 [hinton2015distilling]——一种深度网络知识迁移技术——之间的协同。我们试图压缩一个有 百万参数、 百万乘加的大人脸属性分类器;该分类器在类似 YFCC100M [thomee2016yfcc100m] 的多属性数据集上训练。
We distill a face attribute classifier using the MobileNet architecture. Distillation hinton2015distilling works by training the classifier to emulate the outputs of a larger model[^2] instead of the ground-truth labels, hence enabling training from large (and potentially infinite) unlabeled datasets. Marrying the scalability of distillation training and the parsimonious parameterization of MobileNet, the end system not only requires no regularization (e.g. weight-decay and early-stopping), but also demonstrates enhanced performances. It is evident from Tab. 12 that the MobileNet-based classifier is resilient to aggressive model shrinking: it achieves a similar mean average precision across attributes (mean AP) as the in-house while consuming only the Multi-Adds.
我们用 MobileNet 架构蒸馏一个人脸属性分类器。蒸馏 [hinton2015distilling] 通过训练分类器去模仿更大模型的输出[^2],而非真值标签,从而能从大规模(乃至潜在无限)无标注数据训练。把蒸馏训练的可扩展性与 MobileNet 节俭的参数化结合起来,最终系统不仅不需要正则(如权重衰减与早停),还表现出更好的性能。由表 12 可见,基于 MobileNet 的分类器能承受激进的模型收缩:跨属性的平均平均精度(mean AP)与内部基线相近,而乘加仅约其 。
| Width Multiplier / | Mean | Million | Million |
|---|---|---|---|
| Resolution | AP | Mult-Adds | Parameters |
| 1.0 MobileNet-224 | 88.7% | 568 | 3.2 |
| 0.5 MobileNet-224 | 88.1% | 149 | 0.8 |
| 0.25 MobileNet-224 | 87.2% | 45 | 0.2 |
| 1.0 MobileNet-128 | 88.1% | 185 | 3.2 |
| 0.5 MobileNet-128 | 87.7% | 48 | 0.8 |
| 0.25 MobileNet-128 | 86.4% | 15 | 0.2 |
| Baseline | 86.9% | 1600 | 7.5 |
Table 12: Face attribute classification using the MobileNet architecture. Each row corresponds to a different hyper-parameter setting (width multiplier and image resolution).
| 宽度乘子 / | 平均 | 百万 | 百万 |
|---|---|---|---|
| 分辨率 | AP | 乘加 | 参数 |
| 1.0 MobileNet-224 | 88.7% | 568 | 3.2 |
| 0.5 MobileNet-224 | 88.1% | 149 | 0.8 |
| 0.25 MobileNet-224 | 87.2% | 45 | 0.2 |
| 1.0 MobileNet-128 | 88.1% | 185 | 3.2 |
| 0.5 MobileNet-128 | 87.7% | 48 | 0.8 |
| 0.25 MobileNet-128 | 86.4% | 15 | 0.2 |
| Baseline | 86.9% | 1600 | 7.5 |
表 12:使用 MobileNet 架构的人脸属性分类。每一行对应不同的超参数设定(宽度乘子 与图像分辨率)。
4.6 Object Detection
4.6 目标检测
MobileNet can also be deployed as an effective base network in modern object detection systems. We report results for MobileNet trained for object detection on COCO data based on the recent work that won the 2016 COCO challenge cocodetection2016. In table 13, MobileNet is compared to VGG and Inception V2 ioffe2015batch under both Faster-RCNN ren2015faster and SSD liu2015ssd framework. In our experiments, SSD is evaluated with 300 input resolution (SSD 300) and Faster-RCNN is compared with both 300 and 600 input resolution (Faster-RCNN 300, Faster-RCNN 600). The Faster-RCNN model evaluates 300 RPN proposal boxes per image. The models are trained on COCO train+val excluding 8k minival images and evaluated on minival. For both frameworks, MobileNet achieves comparable results to other networks with only a fraction of computational complexity and model size.
MobileNet 也可作为现代目标检测系统中的有效基干网络。我们报告基于赢得 2016 COCO 挑战的近期工作 [cocodetection2016]、在 COCO 数据上为检测训练的 MobileNet 结果。表 13 在 Faster R-CNN [ren2015faster] 与 SSD [liu2015ssd] 框架下,将 MobileNet 与 VGG 及 Inception V2 [ioffe2015batch] 比较。实验中,SSD 以 300 输入分辨率评估(SSD 300),Faster R-CNN 比较 300 与 600 两种输入分辨率(Faster-RCNN 300、Faster-RCNN 600)。Faster R-CNN 每图评估 300 个 RPN 提议框。模型在排除 8k minival 图像的 COCO train+val 上训练,在 minival 上评估。对两个框架,MobileNet 均取得与其他网络可比的结果,而计算复杂度与模型体积仅为其一小部分。
| Framework | Model | mAP | Billion | Million |
|---|---|---|---|---|
| Resolution | Mult-Adds | Parameters | ||
| deeplab-VGG | 21.1% | 34.9 | 33.1 | |
| SSD 300 | Inception V2 | 22.0% | 3.8 | 13.7 |
| MobileNet | 19.3% | 1.2 | 6.8 | |
| Faster-RCNN | VGG | 22.9% | 64.3 | 138.5 |
| 300 | Inception V2 | 15.4% | 118.2 | 13.3 |
| MobileNet | 16.4% | 25.2 | 6.1 | |
| Faster-RCNN | VGG | 25.7% | 149.6 | 138.5 |
| 600 | Inception V2 | 21.9% | 129.6 | 13.3 |
| Mobilenet | 19.8% | 30.5 | 6.1 |
Table 13: COCO object detection results comparison using different frameworks and network architectures. mAP is reported with COCO primary challenge metric (AP at IoU=0.50:0.05:0.95)
| 框架 | 模型 | mAP | 十亿 | 百万 |
|---|---|---|---|---|
| 分辨率 | 乘加 | 参数 | ||
| deeplab-VGG | 21.1% | 34.9 | 33.1 | |
| SSD 300 | Inception V2 | 22.0% | 3.8 | 13.7 |
| MobileNet | 19.3% | 1.2 | 6.8 | |
| Faster-RCNN | VGG | 22.9% | 64.3 | 138.5 |
| 300 | Inception V2 | 15.4% | 118.2 | 13.3 |
| MobileNet | 16.4% | 25.2 | 6.1 | |
| Faster-RCNN | VGG | 25.7% | 149.6 | 138.5 |
| 600 | Inception V2 | 21.9% | 129.6 | 13.3 |
| Mobilenet | 19.8% | 30.5 | 6.1 |
表 13:不同框架与网络架构下的 COCO 目标检测结果比较。mAP 按 COCO 主挑战指标报告(IoU=0.50:0.05:0.95 的 AP)
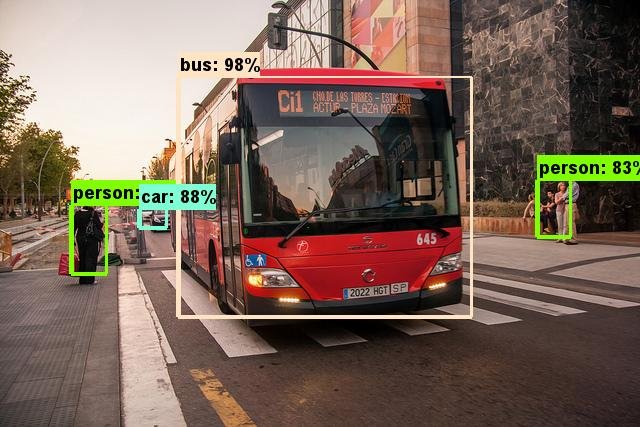
Figure 6: Example objection detection results using MobileNet SSD.
图 6:使用 MobileNet SSD 的目标检测结果示例。
4.7 Face Embeddings
4.7 人脸嵌入
The FaceNet model is a state of the art face recognition model schroff2015facenet. It builds face embeddings based on the triplet loss. To build a mobile FaceNet model we use distillation to train by minimizing the squared differences of the output of FaceNet and MobileNet on the training data. Results for very small MobileNet models can be found in table 14.
FaceNet 模型是当时先进的人脸识别模型 [schroff2015facenet]。它基于三元组损失构建人脸嵌入。为构建移动端 FaceNet 模型,我们用蒸馏训练:最小化训练集上 FaceNet 与 MobileNet 输出的平方差。极小 MobileNet 模型的结果见表 14。
| Model | 1e-4 | Million | Million |
|---|---|---|---|
| Accuracy | Mult-Adds | Parameters | |
| FaceNet schroff2015facenet | 83% | 1600 | 7.5 |
| 1.0 MobileNet-160 | 79.4% | 286 | 4.9 |
| 1.0 MobileNet-128 | 78.3% | 185 | 5.5 |
| 0.75 MobileNet-128 | 75.2% | 166 | 3.4 |
| 0.75 MobileNet-128 | 72.5% | 108 | 3.8 |
Table 14: MobileNet Distilled from FaceNet
| 模型 | 1e-4 | 百万 | 百万 |
|---|---|---|---|
| 精度 | 乘加 | 参数 | |
| FaceNet schroff2015facenet | 83% | 1600 | 7.5 |
| 1.0 MobileNet-160 | 79.4% | 286 | 4.9 |
| 1.0 MobileNet-128 | 78.3% | 185 | 5.5 |
| 0.75 MobileNet-128 | 75.2% | 166 | 3.4 |
| 0.75 MobileNet-128 | 72.5% | 108 | 3.8 |
表 14:从 FaceNet 蒸馏得到的 MobileNet
5 Conclusion
5 结论
We proposed a new model architecture called MobileNets based on depthwise separable convolutions. We investigated some of the important design decisions leading to an efficient model. We then demonstrated how to build smaller and faster MobileNets using width multiplier and resolution multiplier by trading off a reasonable amount of accuracy to reduce size and latency. We then compared different MobileNets to popular models demonstrating superior size, speed and accuracy characteristics. We concluded by demonstrating MobileNet’s effectiveness when applied to a wide variety of tasks. As a next step to help adoption and exploration of MobileNets, we plan on releasing models in Tensor Flow.
我们提出基于深度可分离卷积的新模型架构 MobileNets,考察了通向高效模型的若干重要设计决策,并展示如何用宽度乘子与分辨率乘子,在合理牺牲精度的前提下缩小体积、降低延迟,从而构建更小、更快的 MobileNet。随后将不同 MobileNet 与流行模型比较,展示更优的体积、速度与精度特性。最后在多种任务上验证了 MobileNet 的有效性。作为帮助采用与探索 MobileNets 的下一步,我们计划在 TensorFlow 中发布模型。
References
参考文献
(1) M. Abadi, A. Agarwal, P. Barham, E. Brevdo, Z. Chen, C. Citro, G. S. Corrado, A. Davis, J. Dean, M. Devin, et al. Tensorflow: Large-scale machine learning on heterogeneous systems, 2015. Software available from tensorflow. org , 1, 2015.
(2) W. Chen, J. T. Wilson, S. Tyree, K. Q. Weinberger, and Y. Chen. Compressing neural networks with the hashing trick. CoRR, abs/1504.04788 , 2015.
(3) F. Chollet. Xception: Deep learning with depthwise separable convolutions. arXiv preprint arXiv:1610.02357v2 , 2016.
(4) M. Courbariaux, J.-P. David, and Y. Bengio. Training deep neural networks with low precision multiplications. arXiv preprint arXiv:1412.7024 , 2014.
(5) S. Han, H. Mao, and W. J. Dally. Deep compression: Compressing deep neural network with pruning, trained quantization and huffman coding. CoRR, abs/1510.00149 , 2, 2015.
(6) J. Hays and A. Efros. IM2GPS: estimating geographic information from a single image. In Proceedings of the IEEE International Conference on Computer Vision and Pattern Recognition , 2008.
(7) J. Hays and A. Efros. Large-Scale Image Geolocalization. In J. Choi and G. Friedland, editors, Multimodal Location Estimation of Videos and Images . Springer, 2014.
(8) K. He, X. Zhang, S. Ren, and J. Sun. Deep residual learning for image recognition. arXiv preprint arXiv:1512.03385 , 2015.
(9) G. Hinton, O. Vinyals, and J. Dean. Distilling the knowledge in a neural network. arXiv preprint arXiv:1503.02531 , 2015.
(10) J. Huang, V. Rathod, C. Sun, M. Zhu, A. Korattikara, A. Fathi, I. Fischer, Z. Wojna, Y. Song, S. Guadarrama, et al. Speed/accuracy trade-offs for modern convolutional object detectors. arXiv preprint arXiv:1611.10012 , 2016.
(11) I. Hubara, M. Courbariaux, D. Soudry, R. El-Yaniv, and Y. Bengio. Quantized neural networks: Training neural networks with low precision weights and activations. arXiv preprint arXiv:1609.07061 , 2016.
(12) F. N. Iandola, M. W. Moskewicz, K. Ashraf, S. Han, W. J. Dally, and K. Keutzer. Squeezenet: Alexnet-level accuracy with 50x fewer parameters and¡ 1mb model size. arXiv preprint arXiv:1602.07360 , 2016.
(13) S. Ioffe and C. Szegedy. Batch normalization: Accelerating deep network training by reducing internal covariate shift. arXiv preprint arXiv:1502.03167 , 2015.
(14) M. Jaderberg, A. Vedaldi, and A. Zisserman. Speeding up convolutional neural networks with low rank expansions. arXiv preprint arXiv:1405.3866 , 2014.
(15) Y. Jia, E. Shelhamer, J. Donahue, S. Karayev, J. Long, R. Girshick, S. Guadarrama, and T. Darrell. Caffe: Convolutional architecture for fast feature embedding. arXiv preprint arXiv:1408.5093 , 2014.
(16) J. Jin, A. Dundar, and E. Culurciello. Flattened convolutional neural networks for feedforward acceleration. arXiv preprint arXiv:1412.5474 , 2014.
(17) A. Khosla, N. Jayadevaprakash, B. Yao, and L. Fei-Fei. Novel dataset for fine-grained image categorization. In First Workshop on Fine-Grained Visual Categorization, IEEE Conference on Computer Vision and Pattern Recognition , Colorado Springs, CO, June 2011.
(18) J. Krause, B. Sapp, A. Howard, H. Zhou, A. Toshev, T. Duerig, J. Philbin, and L. Fei-Fei. The unreasonable effectiveness of noisy data for fine-grained recognition. arXiv preprint arXiv:1511.06789 , 2015.
(19) A. Krizhevsky, I. Sutskever, and G. E. Hinton. Imagenet classification with deep convolutional neural networks. In Advances in neural information processing systems , pages 1097–1105, 2012.
(20) V. Lebedev, Y. Ganin, M. Rakhuba, I. Oseledets, and V. Lempitsky. Speeding-up convolutional neural networks using fine-tuned cp-decomposition. arXiv preprint arXiv:1412.6553 , 2014.
(21) W. Liu, D. Anguelov, D. Erhan, C. Szegedy, and S. Reed. Ssd: Single shot multibox detector. arXiv preprint arXiv:1512.02325 , 2015.
(22) M. Rastegari, V. Ordonez, J. Redmon, and A. Farhadi. Xnor-net: Imagenet classification using binary convolutional neural networks. arXiv preprint arXiv:1603.05279 , 2016.
(23) S. Ren, K. He, R. Girshick, and J. Sun. Faster r-cnn: Towards real-time object detection with region proposal networks. In Advances in neural information processing systems , pages 91–99, 2015.
(24) O. Russakovsky, J. Deng, H. Su, J. Krause, S. Satheesh, S. Ma, Z. Huang, A. Karpathy, A. Khosla, M. Bernstein, et al. Imagenet large scale visual recognition challenge. International Journal of Computer Vision , 115(3):211–252, 2015.
(25) F. Schroff, D. Kalenichenko, and J. Philbin. Facenet: A unified embedding for face recognition and clustering. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pages 815–823, 2015.
(26) L. Sifre. Rigid-motion scattering for image classification . PhD thesis, Ph. D. thesis, 2014.
(27) K. Simonyan and A. Zisserman. Very deep convolutional networks for large-scale image recognition. arXiv preprint arXiv:1409.1556 , 2014.
(28) V. Sindhwani, T. Sainath, and S. Kumar. Structured transforms for small-footprint deep learning. In Advances in Neural Information Processing Systems , pages 3088–3096, 2015.
(29) C. Szegedy, S. Ioffe, and V. Vanhoucke. Inception-v4, inception-resnet and the impact of residual connections on learning. arXiv preprint arXiv:1602.07261 , 2016.
(30) C. Szegedy, W. Liu, Y. Jia, P. Sermanet, S. Reed, D. Anguelov, D. Erhan, V. Vanhoucke, and A. Rabinovich. Going deeper with convolutions. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pages 1–9, 2015.
(31) C. Szegedy, V. Vanhoucke, S. Ioffe, J. Shlens, and Z. Wojna. Rethinking the inception architecture for computer vision. arXiv preprint arXiv:1512.00567 , 2015.
(32) B. Thomee, D. A. Shamma, G. Friedland, B. Elizalde, K. Ni, D. Poland, D. Borth, and L.-J. Li. Yfcc100m: The new data in multimedia research. Communications of the ACM , 59(2):64–73, 2016.
(33) T. Tieleman and G. Hinton. Lecture 6.5-rmsprop: Divide the gradient by a running average of its recent magnitude. COURSERA: Neural Networks for Machine Learning , 4(2), 2012.
(34) M. Wang, B. Liu, and H. Foroosh. Factorized convolutional neural networks. arXiv preprint arXiv:1608.04337 , 2016.
(35) T. Weyand, I. Kostrikov, and J. Philbin. PlaNet - Photo Geolocation with Convolutional Neural Networks. In European Conference on Computer Vision (ECCV) , 2016.
(36) J. Wu, C. Leng, Y. Wang, Q. Hu, and J. Cheng. Quantized convolutional neural networks for mobile devices. arXiv preprint arXiv:1512.06473 , 2015.
(37) Z. Yang, M. Moczulski, M. Denil, N. de Freitas, A. Smola, L. Song, and Z. Wang. Deep fried convnets. In Proceedings of the IEEE International Conference on Computer Vision , pages 1476–1483, 2015.