Mask R-CNN
Mask R-CNN
Abstract
摘要
We present a conceptually simple, flexible, and general framework for object instance segmentation. Our approach efficiently detects objects in an image while simultaneously generating a high-quality segmentation mask for each instance. The method, called Mask R-CNN, extends Faster R-CNN by adding a branch for predicting an object mask in parallel with the existing branch for bounding box recognition. Mask R-CNN is simple to train and adds only a small overhead to Faster R-CNN, running at 5 fps. Moreover, Mask R-CNN is easy to generalize to other tasks, e.g., allowing us to estimate human poses in the same framework. We show top results in all three tracks of the COCO suite of challenges, including instance segmentation, bounding-box object detection, and person keypoint detection. Without bells and whistles, Mask R-CNN outperforms all existing, single-model entries on every task, including the COCO 2016 challenge winners. We hope our simple and effective approach will serve as a solid baseline and help ease future research in instance-level recognition. Code has been made available at: https://github.com/facebookresearch/Detectron.
我们提出一个概念上简单、灵活且通用的物体实例分割框架。该方法在高效检测图像中物体的同时,为每个实例生成高质量的分割掩码。这一称作 Mask R-CNN 的方法,通过在已有的边界框识别分支之外并行增加一条预测物体掩码的分支,扩展了 Faster R-CNN。Mask R-CNN 易于训练,相对 Faster R-CNN 只增加很小的开销,运行速度为 5 fps。此外,Mask R-CNN 很容易推广到其他任务,例如在同一框架下估计人体姿态。我们在 COCO 挑战赛的全部三个赛道——实例分割、边界框物体检测和人体关键点检测——上都取得了最好结果。不加花哨技巧,Mask R-CNN 在每项任务上都超过了所有现有的单模型参赛结果,包括 COCO 2016 挑战赛的获胜者。我们希望这一简单有效的方法能成为坚实的基线,并有助于推动实例级识别的未来研究。代码已发布:https://github.com/facebookresearch/Detectron。
1 Introduction
1 引言
The vision community has rapidly improved object detection and semantic segmentation results over a short period of time. In large part, these advances have been driven by powerful baseline systems, such as the Fast/Faster R-CNN [12, 36] and Fully Convolutional Network (FCN) [30] frameworks for object detection and semantic segmentation, respectively. These methods are conceptually intuitive and offer flexibility and robustness, together with fast training and inference time. Our goal in this work is to develop a comparably enabling framework for instance segmentation.
视觉社区在短时间内迅速提升了物体检测和语义分割的结果。这些进展在很大程度上由强大的基线系统推动,例如分别用于物体检测和语义分割的 Fast/Faster R-CNN [12, 36] 与全卷积网络(FCN)[30] 框架。这些方法概念直观,灵活稳健,同时训练和推理速度快。本文的目标是为实例分割开发一个同样具有赋能作用的框架。
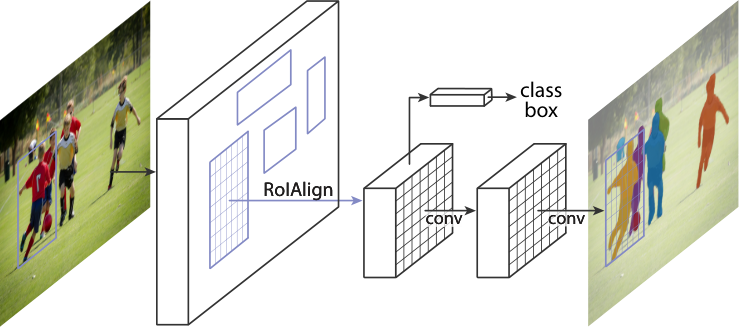
Figure 1: The Mask R-CNN framework for instance segmentation.
图 1:Mask R-CNN 实例分割框架。
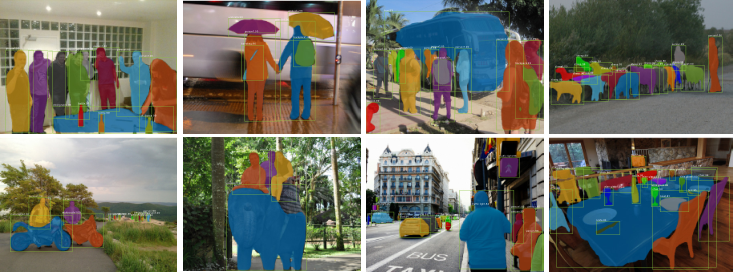
Figure 2: Mask R-CNN results on the COCO test set. These results are based on ResNet-101 [19], achieving a mask AP of 35.7 and running at 5 fps. Masks are shown in color, and bounding box, category, and confidences are also shown.
图 2:Mask R-CNN 在 COCO 测试集上的结果。这些结果基于 ResNet-101 [19],掩码 AP 达到 35.7,运行速度 5 fps。掩码以彩色显示,同时给出边界框、类别与置信度。
Instance segmentation is challenging because it requires the correct detection of all objects in an image while also precisely segmenting each instance. It therefore combines elements from the classical computer vision tasks of object detection, where the goal is to classify individual objects and localize each using a bounding box, and semantic segmentation, where the goal is to classify each pixel into a fixed set of categories without differentiating object instances.¹ Given this, one might expect a complex method is required to achieve good results. However, we show that a surprisingly simple, flexible, and fast system can surpass prior state-of-the-art instance segmentation results.
实例分割具有挑战性,因为它要求正确检测图像中的所有物体,同时精确分割每个实例。因此它结合了经典计算机视觉任务中物体检测(目标是对单个物体分类并用边界框定位)和语义分割(目标是把每个像素分到固定类别集合中、不区分物体实例)的要素。¹ 据此,人们可能预期需要复杂方法才能取得好结果。然而我们表明,一个出人意料地简单、灵活且快速的系统就能超越此前最好的实例分割结果。
1 There is a close relation between instance segmentation and pixel labeling, for example, each instance could be labeled as a unique category. However, the number of instances depends on the input image and also different images may have different numbers of instances of the same class. Thus it is hard to apply a fixed set of categories.
1 实例分割与像素标注关系密切,例如每个实例可标为唯一类别。但实例数目取决于输入图像,且不同图像中同一类的实例数也可能不同,因此难以套用固定的类别集合。
Our method, called Mask R-CNN, extends Faster R-CNN [36] by adding a branch for predicting segmentation masks on each Region of Interest (RoI), in parallel with the existing branch for classification and bounding box regression (Figure 1). The mask branch is a small FCN applied to each RoI, predicting a segmentation mask in a pixel-to-pixel manner. Mask R-CNN is simple to implement and train given the Faster R-CNN framework, which facilitates a wide range of flexible architecture designs. Additionally, the mask branch only adds a small computational overhead, enabling a fast system and rapid experimentation.
我们的方法称作 Mask R-CNN,它通过在每个感兴趣区域(RoI)上增加一条预测分割掩码的分支,并与已有的分类和边界框回归分支并行(图 1),扩展了 Faster R-CNN [36]。掩码分支是施加在每个 RoI 上的小型 FCN,以像素到像素的方式预测分割掩码。在 Faster R-CNN 框架下,Mask R-CNN 易于实现和训练,从而便于灵活的架构设计。此外,掩码分支只增加很小的计算开销,使系统保持快速并便于快速实验。
In principle Mask R-CNN is an intuitive extension of Faster R-CNN, yet constructing the mask branch properly is critical for good results. Most importantly, Faster R-CNN was not designed for pixel-to-pixel alignment between network inputs and outputs. This is most evident in how RoIPool [18, 12], the de facto core operation for attending to instances, performs coarse spatial quantization for feature extraction. To fix the misalignment, we propose a simple, quantization-free layer, called RoIAlign, that faithfully preserves exact spatial locations. Despite being a seemingly minor change, RoIAlign has a large impact: it improves mask accuracy by relative 10% to 50%, showing bigger gains under stricter localization metrics. Second, we found it essential to decouple mask and class prediction: we predict a binary mask for each class independently, without competition among classes, and rely on the network’s RoI classification branch to predict the category. In contrast, FCNs usually perform per-pixel multi-class categorization, which couples segmentation and classification, and based on our experiments works poorly for instance segmentation.
原则上 Mask R-CNN 是 Faster R-CNN 的直观扩展,但正确构造掩码分支对取得好结果至关重要。最重要的是,Faster R-CNN 并非为网络输入与输出之间的像素级对齐而设计。这一点在 RoIPool [18, 12]——关注实例时事实上的核心操作——为特征提取做粗粒度空间量化时最为明显。为修复错位,我们提出一个简单的、无量化层,称作 RoIAlign,它忠实地保留精确的空间位置。尽管看似改动很小,RoIAlign 影响很大:它使掩码准确率相对提升 10% 到 50%,在更严格的定位指标下收益更大。其次,我们发现解耦掩码与类别预测至关重要:我们为每个类别独立预测二值掩码,类别之间不竞争,并依赖网络的 RoI 分类分支预测类别。相比之下,FCN 通常做逐像素多类分类,把分割与分类耦合在一起,根据我们的实验,这对实例分割效果很差。
Without bells and whistles, Mask R-CNN surpasses all previous state-of-the-art single-model results on the COCO instance segmentation task [28], including the heavily-engineered entries from the 2016 competition winner. As a by-product, our method also excels on the COCO object detection task. In ablation experiments, we evaluate multiple basic instantiations, which allows us to demonstrate its robustness and analyze the effects of core factors.
不加花哨技巧,Mask R-CNN 在 COCO 实例分割任务 [28] 上超越了此前所有最好的单模型结果,包括 2016 年竞赛获胜者经过大量工程优化的参赛结果。作为副产品,我们的方法在 COCO 物体检测任务上也表现出色。在消融实验中,我们评估了多种基本实例化,从而展示其稳健性并分析核心因素的影响。
Our models can run at about 200ms per frame on a GPU, and training on COCO takes one to two days on a single 8-GPU machine. We believe the fast train and test speeds, together with the framework’s flexibility and accuracy, will benefit and ease future research on instance segmentation.
我们的模型在 GPU 上大约每帧 200ms,在单台 8-GPU 机器上训练 COCO 需要一到两天。我们相信,快速的训练与测试速度,连同框架的灵活性与准确率,将有益并便于未来的实例分割研究。
Finally, we showcase the generality of our framework via the task of human pose estimation on the COCO keypoint dataset [28]. By viewing each keypoint as a one-hot binary mask, with minimal modification Mask R-CNN can be applied to detect instance-specific poses. Mask R-CNN surpasses the winner of the 2016 COCO keypoint competition, and at the same time runs at 5 fps. Mask R-CNN, therefore, can be seen more broadly as a flexible framework for instance-level recognition and can be readily extended to more complex tasks.
最后,我们通过 COCO 关键点数据集 [28] 上的人体姿态估计任务展示框架的通用性。把每个关键点看作 one-hot 二值掩码,只需极少修改,Mask R-CNN 就能用于检测实例特定的姿态。Mask R-CNN 超越了 2016 年 COCO 关键点竞赛的获胜者,同时仍以 5 fps 运行。因此,Mask R-CNN 可以更广泛地视为实例级识别的灵活框架,并可方便地扩展到更复杂的任务。
We have released code to facilitate future research.
我们已发布代码以方便未来研究。
2 Related Work
2 相关工作
R-CNN:
The Region-based CNN (R-CNN) approach [13] to bounding-box object detection is to attend to a manageable number of candidate object regions [42, 20] and evaluate convolutional networks [25, 24] independently on each RoI. R-CNN was extended [18, 12] to allow attending to RoIs on feature maps using RoIPool, leading to fast speed and better accuracy. Faster R-CNN [36] advanced this stream by learning the attention mechanism with a Region Proposal Network (RPN). Faster R-CNN is flexible and robust to many follow-up improvements (e.g., [38, 27, 21]), and is the current leading framework in several benchmarks.
R-CNN:
基于区域的 CNN(R-CNN)方法 [13] 做边界框物体检测时,关注数量可控的候选物体区域 [42, 20],并在每个 RoI 上独立评估卷积网络 [25, 24]。R-CNN 经扩展 [18, 12] 后,可用 RoIPool 在特征图上关注 RoI,从而获得更快速度与更高准确率。Faster R-CNN [36] 通过区域提议网络(RPN)学习注意力机制,推进了这一脉络。Faster R-CNN 灵活稳健,能容纳许多后续改进(例如 [38, 27, 21]),并且是当前若干基准上的领先框架。
Instance Segmentation:
Driven by the effectiveness of R-CNN, many approaches to instance segmentation are based on segment proposals. Earlier methods [13, 15, 16, 9] resorted to bottom-up segments [42, 2]. DeepMask [33] and following works [34, 8] learn to propose segment candidates, which are then classified by Fast R-CNN. In these methods, segmentation precedes recognition, which is slow and less accurate. Likewise, Dai et al. [10] proposed a complex multiple-stage cascade that predicts segment proposals from bounding-box proposals, followed by classification. Instead, our method is based on parallel prediction of masks and class labels, which is simpler and more flexible.
实例分割:
受 R-CNN 有效性的推动,许多实例分割方法基于分割提议。早期方法 [13, 15, 16, 9] 求助于自下而上的分割 [42, 2]。DeepMask [33] 及后续工作 [34, 8] 学习提出分割候选,再用 Fast R-CNN 分类。在这些方法中,分割先于识别,既慢又不够准。同样,Dai 等人 [10] 提出复杂的多阶段级联:从边界框提议预测分割提议,再做分类。相反,我们的方法基于掩码与类别标签的并行预测,更简单也更灵活。
Most recently, Li et al. [26] combined the segment proposal system in [8] and object detection system in [11] for “fully convolutional instance segmentation” (FCIS). The common idea in [8, 11, 26] is to predict a set of position-sensitive output channels fully convolutionally. These channels simultaneously address object classes, boxes, and masks, making the system fast. But FCIS exhibits systematic errors on overlapping instances and creates spurious edges (Figure 6), showing that it is challenged by the fundamental difficulties of segmenting instances.
最近,Li 等人 [26] 把 [8] 中的分割提议系统与 [11] 中的物体检测系统结合起来,用于“全卷积实例分割”(FCIS)。[8, 11, 26] 的共同想法是以全卷积方式预测一组位置敏感的输出通道。这些通道同时处理物体类别、框和掩码,使系统很快。但 FCIS 在重叠实例上表现出系统性误差,并产生虚假边缘(图 6),说明它受到分割实例这一根本困难的挑战。
Another family of solutions [23, 4, 3, 29] to instance segmentation are driven by the success of semantic segmentation. Starting from per-pixel classification results (e.g., FCN outputs), these methods attempt to cut the pixels of the same category into different instances. In contrast to the segmentation-first strategy of these methods, Mask R-CNN is based on an instance-first strategy. We expect a deeper incorporation of both strategies will be studied in the future.
另一类实例分割方案 [23, 4, 3, 29] 由语义分割的成功所驱动。从逐像素分类结果(例如 FCN 输出)出发,这些方法试图把同一类别的像素切成不同实例。与这些方法的分割优先策略相反,Mask R-CNN 基于实例优先策略。我们预期未来会有对两种策略更深入的结合研究。
3 Mask R-CNN
Mask R-CNN is conceptually simple: Faster R-CNN has two outputs for each candidate object, a class label and a bounding-box offset; to this we add a third branch that outputs the object mask. Mask R-CNN is thus a natural and intuitive idea. But the additional mask output is distinct from the class and box outputs, requiring extraction of much finer spatial layout of an object. Next, we introduce the key elements of Mask R-CNN, including pixel-to-pixel alignment, which is the main missing piece of Fast/Faster R-CNN.
概念上,Mask R-CNN 很简单:Faster R-CNN 对每个候选物体有两个输出——类别标签和边界框偏移;我们再增加第三条分支,输出物体掩码。因此 Mask R-CNN 是自然而直观的想法。但额外的掩码输出与类别和框输出不同,需要提取物体精细得多的空间布局。接下来我们介绍 Mask R-CNN 的关键要素,包括像素到像素对齐——这是 Fast/Faster R-CNN 主要缺失的一块。
Faster R-CNN:
We begin by briefly reviewing the Faster R-CNN detector [36]. Faster R-CNN consists of two stages. The first stage, called a Region Proposal Network (RPN), proposes candidate object bounding boxes. The second stage, which is in essence Fast R-CNN [12], extracts features using RoIPool from each candidate box and performs classification and bounding-box regression. The features used by both stages can be shared for faster inference. We refer readers to [21] for latest, comprehensive comparisons between Faster R-CNN and other frameworks.
Faster R-CNN:
我们先简要回顾 Faster R-CNN 检测器 [36]。Faster R-CNN 由两个阶段组成。第一阶段称作区域提议网络(RPN),提出候选物体边界框。第二阶段本质上是 Fast R-CNN [12],用 RoIPool 从每个候选框提取特征,并做分类与边界框回归。两个阶段所用特征可以共享以加快推理。关于 Faster R-CNN 与其他框架的最新全面比较,我们请读者参阅 [21]。
Mask R-CNN:
Mask R-CNN adopts the same two-stage procedure, with an identical first stage (which is RPN). In the second stage, in parallel to predicting the class and box offset, Mask R-CNN also outputs a binary mask for each RoI. This is in contrast to most recent systems, where classification depends on mask predictions (e.g. [33, 10, 26]). Our approach follows the spirit of Fast R-CNN [12] that applies bounding-box classification and regression in parallel (which turned out to largely simplify the multi-stage pipeline of original R-CNN [13]).
Mask R-CNN:
Mask R-CNN 采用相同的两阶段流程,第一阶段相同(即 RPN)。在第二阶段,并行于预测类别和框偏移,Mask R-CNN 还为每个 RoI 输出一张二值掩码。这与最近大多数系统不同——那些系统中分类依赖于掩码预测(例如 [33, 10, 26])。我们的方法遵循 Fast R-CNN [12] 的精神:并行地做边界框分类与回归(事实证明这在很大程度上简化了原始 R-CNN [13] 的多阶段流水线)。
Formally, during training, we define a multi-task loss on each sampled RoI as . The classification loss and bounding-box loss are identical as those defined in [12]. The mask branch has a -dimensional output for each RoI, which encodes binary masks of resolution , one for each of the classes. To this we apply a per-pixel sigmoid, and define as the average binary cross-entropy loss. For an RoI associated with ground-truth class , is only defined on the -th mask (other mask outputs do not contribute to the loss).
形式上,训练时我们在每个采样 RoI 上定义多任务损失 。分类损失 与边界框损失 与 [12] 中定义的相同。掩码分支对每个 RoI 有 维输出,编码 张分辨率为 的二值掩码,每个类别一张。对此我们施加逐像素 sigmoid,并把 定义为平均二值交叉熵损失。对与真实类别 相关联的 RoI, 只定义在第 张掩码上(其他掩码输出不参与损失)。
Our definition of allows the network to generate masks for every class without competition among classes; we rely on the dedicated classification branch to predict the class label used to select the output mask. This decouples mask and class prediction. This is different from common practice when applying FCNs [30] to semantic segmentation, which typically uses a per-pixel softmax and a multinomial cross-entropy loss. In that case, masks across classes compete; in our case, with a per-pixel sigmoid and a binary loss, they do not. We show by experiments that this formulation is key for good instance segmentation results.
我们对 的定义使网络能为每个类别生成掩码而不在类别间竞争;我们依赖专门的分类分支预测用于选择输出掩码的类别标签。这解耦了掩码与类别预测。这与把 FCN [30] 用于语义分割时的常见做法不同——后者通常使用逐像素 softmax 和 多项交叉熵损失。那种情形下,各类掩码相互竞争;在我们这里,用逐像素 sigmoid 和 二值损失,它们不竞争。我们通过实验表明,这一表述对取得好的实例分割结果至关重要。
Mask Representation:
A mask encodes an input object’s spatial layout. Thus, unlike class labels or box offsets that are inevitably collapsed into short output vectors by fully-connected (fc) layers, extracting the spatial structure of masks can be addressed naturally by the pixel-to-pixel correspondence provided by convolutions.
掩码表示:
掩码编码输入物体的空间布局。因此,与不可避免地被全连接(fc)层压成短输出向量的类别标签或框偏移不同,提取掩码的空间结构可以自然地由卷积提供的像素到像素对应来处理。
Specifically, we predict an mask from each RoI using an FCN [30]. This allows each layer in the mask branch to maintain the explicit object spatial layout without collapsing it into a vector representation that lacks spatial dimensions. Unlike previous methods that resort to fc layers for mask prediction [33, 34, 10], our fully convolutional representation requires fewer parameters, and is more accurate as demonstrated by experiments.
具体而言,我们用 FCN [30] 从每个 RoI 预测一张 掩码。这使掩码分支中的每一层都能保持显式的 物体空间布局,而不会把它压成缺乏空间维度的向量表示。与以往求助于 fc 层做掩码预测的方法 [33, 34, 10] 不同,我们的全卷积表示所需参数更少,并且如实验所示更准确。
This pixel-to-pixel behavior requires our RoI features, which themselves are small feature maps, to be well aligned to faithfully preserve the explicit per-pixel spatial correspondence. This motivated us to develop the following RoIAlign layer that plays a key role in mask prediction.
这种像素到像素行为要求我们的 RoI 特征——本身是小特征图——对齐良好,以忠实地保留显式的逐像素空间对应。这促使我们开发了在掩码预测中起关键作用的如下 RoIAlign 层。
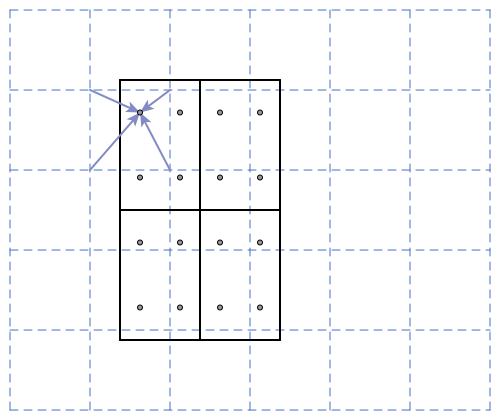
Figure 3: RoIAlign: The dashed grid represents a feature map, the solid lines an RoI (with 22 bins in this example), and the dots the 4 sampling points in each bin. RoIAlign computes the value of each sampling point by bilinear interpolation from the nearby grid points on the feature map. No quantization is performed on any coordinates involved in the RoI, its bins, or the sampling points.
图 3:RoIAlign:虚线网格表示特征图,实线表示一个 RoI(本例中为 2×2 个 bin),圆点表示每个 bin 中的 4 个采样点。RoIAlign 通过双线性插值从特征图上邻近网格点计算每个采样点的值。涉及 RoI、其 bin 或采样点的任何坐标都不做量化。
RoIAlign:
RoIPool [12] is a standard operation for extracting a small feature map (e.g., 77) from each RoI. RoIPool first quantizes a floating-number RoI to the discrete granularity of the feature map, this quantized RoI is then subdivided into spatial bins which are themselves quantized, and finally feature values covered by each bin are aggregated (usually by max pooling). Quantization is performed, e.g., on a continuous coordinate by computing , where 16 is a feature map stride and is rounding; likewise, quantization is performed when dividing into bins (e.g., 77). These quantizations introduce misalignments between the RoI and the extracted features. While this may not impact classification, which is robust to small translations, it has a large negative effect on predicting pixel-accurate masks.
RoIAlign:
RoIPool [12] 是从每个 RoI 提取小特征图(例如 7×7)的标准操作。RoIPool 首先把浮点 RoI 量化到特征图的离散粒度,再把这个量化后的 RoI 细分成空间 bin(这些 bin 本身也被量化),最后聚合每个 bin 覆盖的特征值(通常用最大池化)。量化例如对连续坐标 计算 ,其中 16 是特征图步长, 表示取整;划分 bin 时同样做量化(例如 7×7)。这些量化会在 RoI 与提取的特征之间引入错位。虽然这可能不影响对小平移稳健的分类,但对预测像素级精确的掩码有很大负面影响。
To address this, we propose an RoIAlign layer that removes the harsh quantization of RoIPool, properly aligning the extracted features with the input. Our proposed change is simple: we avoid any quantization of the RoI boundaries or bins (i.e., we use instead of ). We use bilinear interpolation [22] to compute the exact values of the input features at four regularly sampled locations in each RoI bin, and aggregate the result (using max or average), see Figure 3 for details. We note that the results are not sensitive to the exact sampling locations, or how many points are sampled, as long as no quantization is performed.
为解决这一问题,我们提出 RoIAlign 层,去掉 RoIPool 的生硬量化,使提取的特征与输入正确对齐。我们提出的改动很简单:避免对 RoI 边界或 bin 做任何量化(即使用 而非 )。我们用双线性插值 [22] 在每个 RoI bin 中四个规则采样位置计算输入特征的精确值,再聚合结果(用 max 或 average),细节见图 3。我们注意到,结果对精确采样位置或采样点数并不敏感,只要不做量化。
RoIAlign leads to large improvements as we show in §4.2. We also compare to the RoIWarp operation proposed in [10]. Unlike RoIAlign, RoIWarp overlooked the alignment issue and was implemented in [10] as quantizing RoI just like RoIPool. So even though RoIWarp also adopts bilinear resampling motivated by [22], it performs on par with RoIPool as shown by experiments (more details in Table 2c), demonstrating the crucial role of alignment.
如 §4.2 所示,RoIAlign 带来大幅改进。我们还与 [10] 提出的 RoIWarp 操作作了比较。与 RoIAlign 不同,RoIWarp 忽略了对齐问题,并在 [10] 中像 RoIPool 一样对 RoI 做量化。因此尽管 RoIWarp 也采用了受 [22] 启发的双线性重采样,实验表明它与 RoIPool 表现相当(更多细节见表 2c),说明对齐起着关键作用。
Network Architecture:
To demonstrate the generality of our approach, we instantiate Mask R-CNN with multiple architectures. For clarity, we differentiate between: (i) the convolutional backbone architecture used for feature extraction over an entire image, and (ii) the network head for bounding-box recognition (classification and regression) and mask prediction that is applied separately to each RoI.
网络架构:
为展示方法的通用性,我们用多种架构实例化 Mask R-CNN。为清晰起见,我们区分:(i) 用于在整幅图像上提取特征的卷积主干架构,以及 (ii) 分别施加于每个 RoI、用于边界框识别(分类与回归)和掩码预测的网络头。
We denote the backbone architecture using the nomenclature network-depth-features. We evaluate ResNet [19] and ResNeXt [45] networks of depth 50 or 101 layers. The original implementation of Faster R-CNN with ResNets [19] extracted features from the final convolutional layer of the 4-th stage, which we call C4. This backbone with ResNet-50, for example, is denoted by ResNet-50-C4. This is a common choice used in [19, 10, 21, 39].
我们用 network-depth-features 命名法表示主干架构。我们评估深度为 50 或 101 层的 ResNet [19] 与 ResNeXt [45] 网络。带 ResNet 的 Faster R-CNN 原始实现 [19] 从第 4 阶段的最后一层卷积提取特征,我们称之为 C4。例如带 ResNet-50 的这一主干记为 ResNet-50-C4。这是 [19, 10, 21, 39] 中的常见选择。
We also explore another more effective backbone recently proposed by Lin et al. [27], called a Feature Pyramid Network (FPN). FPN uses a top-down architecture with lateral connections to build an in-network feature pyramid from a single-scale input. Faster R-CNN with an FPN backbone extracts RoI features from different levels of the feature pyramid according to their scale, but otherwise the rest of the approach is similar to vanilla ResNet. Using a ResNet-FPN backbone for feature extraction with Mask R-CNN gives excellent gains in both accuracy and speed. For further details on FPN, we refer readers to [27].
我们还探索了 Lin 等人 [27] 近来提出的另一种更有效的主干,称作特征金字塔网络(FPN)。FPN 使用带横向连接的自上而下架构,从单尺度输入构建网络内特征金字塔。带 FPN 主干的 Faster R-CNN 根据尺度从特征金字塔的不同层级提取 RoI 特征,其余做法与普通 ResNet 类似。用 ResNet-FPN 主干为 Mask R-CNN 提取特征,在准确率与速度上都带来显著收益。关于 FPN 的更多细节,请读者参阅 [27]。
For the network head we closely follow architectures presented in previous work to which we add a fully convolutional mask prediction branch. Specifically, we extend the Faster R-CNN box heads from the ResNet [19] and FPN [27] papers. Details are shown in Figure 4. The head on the ResNet-C4 backbone includes the 5-th stage of ResNet (namely, the 9-layer ‘res5’ [19]), which is compute-intensive. For FPN, the backbone already includes res5 and thus allows for a more efficient head that uses fewer filters.
对网络头,我们密切遵循既往工作中给出的架构,并增加全卷积掩码预测分支。具体而言,我们扩展了 ResNet [19] 与 FPN [27] 论文中的 Faster R-CNN 框头。细节见图 4。ResNet-C4 主干上的头包含 ResNet 的第 5 阶段(即 9 层的 ‘res5’ [19]),计算量大。对 FPN,主干已包含 res5,因而允许使用滤波器更少的更高效的头。
We note that our mask branches have a straightforward structure. More complex designs have the potential to improve performance but are not the focus of this work.
我们注意到,掩码头结构直接明了。更复杂的设计有潜力提升性能,但不是本文重点。
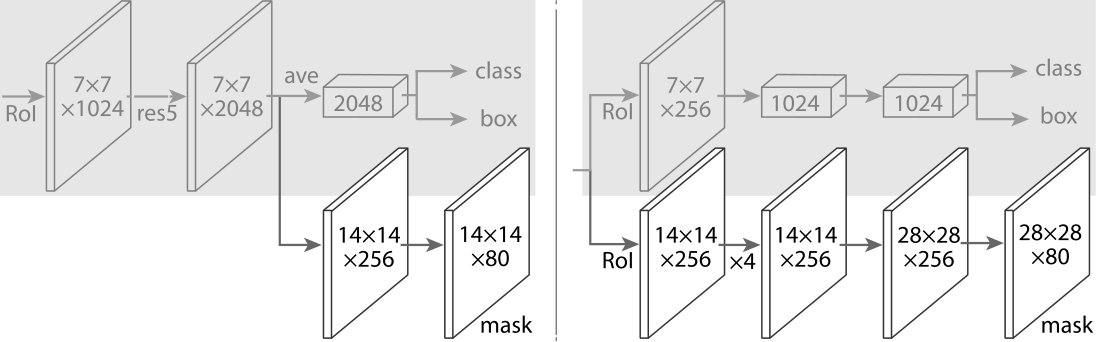
Figure 4: Head Architecture: We extend two existing Faster R-CNN heads [19, 27]. Left/Right panels show the heads for the ResNet C4 and FPN backbones, from [19] and [27], respectively, to which a mask branch is added. Numbers denote spatial resolution and channels. Arrows denote either conv, deconv, or fc layers as can be inferred from context (conv preserves spatial dimension while deconv increases it). All convs are 33, except the output conv which is 11, deconvs are 22 with stride 2, and we use ReLU [31] in hidden layers. Left: ‘res5’ denotes ResNet’s fifth stage, which for simplicity we altered so that the first conv operates on a 77 RoI with stride 1 (instead of 1414 / stride 2 as in [19]). Right: ‘4’ denotes a stack of four consecutive convs.
图 4:头架构:我们扩展了两个现有的 Faster R-CNN 头 [19, 27]。左/右面板分别显示来自 [19] 与 [27] 的 ResNet C4 与 FPN 主干的头,并增加了掩码分支。数字表示空间分辨率与通道数。箭头表示 conv、deconv 或 fc 层(可由上下文推断:conv 保持空间尺寸,deconv 增大尺寸)。除输出 conv 为 1×1 外,所有 conv 均为 3×3;deconv 为步长 2 的 2×2;隐层使用 ReLU [31]。左:‘res5’ 表示 ResNet 第五阶段,为简单起见我们做了改动,使第一个 conv 在步长 1 的 7×7 RoI 上操作(而非 [19] 中的 14×14/步长 2)。右:‘×4’ 表示四个连续 conv 的堆叠。
3.1 Implementation Details
3.1 实现细节
We set hyper-parameters following existing Fast/Faster R-CNN work [12, 36, 27]. Although these decisions were made for object detection in original papers [12, 36, 27], we found our instance segmentation system is robust to them.
我们按照现有 Fast/Faster R-CNN 工作 [12, 36, 27] 设置超参数。尽管这些决定在原论文 [12, 36, 27] 中是为物体检测做出的,我们发现实例分割系统对它们稳健。
Training:
As in Fast R-CNN, an RoI is considered positive if it has IoU with a ground-truth box of at least 0.5 and negative otherwise. The mask loss is defined only on positive RoIs. The mask target is the intersection between an RoI and its associated ground-truth mask.
训练:
与 Fast R-CNN 一样,若 RoI 与某个真实框的 IoU 至少为 0.5,则视为正样本,否则为负样本。掩码损失 只定义在正 RoI 上。掩码目标是 RoI 与其关联真实掩码的交集。
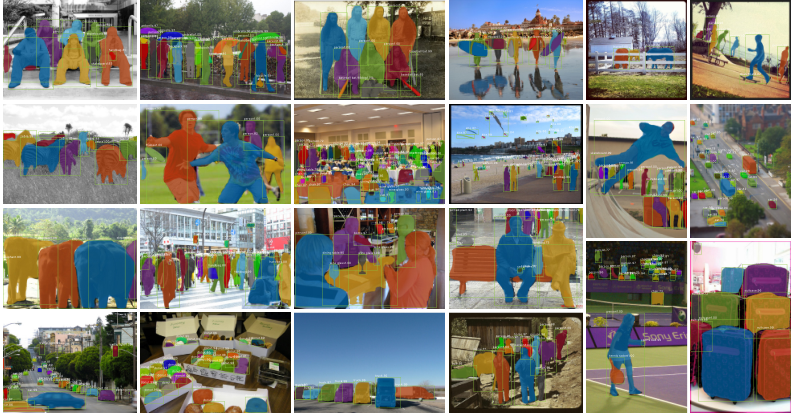
Figure 5: More results of Mask R-CNN on COCO test images, using ResNet-101-FPN and running at 5 fps, with 35.7 mask AP (Table 1).
图 5:Mask R-CNN 在 COCO 测试图像上的更多结果,使用 ResNet-101-FPN,5 fps,掩码 AP 35.7(表 1)。
| backbone | AP | AP50 | AP75 | APS | APM | APL | |
|---|---|---|---|---|---|---|---|
| MNC [10] | ResNet-101-C4 | 24.6 | 44.3 | 24.8 | 4.7 | 25.9 | 43.6 |
| FCIS [26] +OHEM | ResNet-101-C5-dilated | 29.2 | 49.5 | - | 7.1 | 31.3 | 50.0 |
| FCIS+++ [26] +OHEM | ResNet-101-C5-dilated | 33.6 | 54.5 | - | - | - | - |
| Mask R-CNN | ResNet-101-C4 | 33.1 | 54.9 | 34.8 | 12.1 | 35.6 | 51.1 |
| Mask R-CNN | ResNet-101-FPN | 35.7 | 58.0 | 37.8 | 15.5 | 38.1 | 52.4 |
| Mask R-CNN | ResNeXt-101-FPN | 37.1 | 60.0 | 39.4 | 16.9 | 39.9 | 53.5 |
Table 1: Instance segmentation mask AP on COCO test-dev. MNC [10] and FCIS [26] are the winners of the COCO 2015 and 2016 segmentation challenges, respectively. Without bells and whistles, Mask R-CNN outperforms the more complex FCIS+++, which includes multi-scale train/test, horizontal flip test, and OHEM [38]. All entries are single-model results.
| backbone | AP | AP50 | AP75 | APS | APM | APL | |
|---|---|---|---|---|---|---|---|
| MNC [10] | ResNet-101-C4 | 24.6 | 44.3 | 24.8 | 4.7 | 25.9 | 43.6 |
| FCIS [26] +OHEM | ResNet-101-C5-dilated | 29.2 | 49.5 | - | 7.1 | 31.3 | 50.0 |
| FCIS+++ [26] +OHEM | ResNet-101-C5-dilated | 33.6 | 54.5 | - | - | - | - |
| Mask R-CNN | ResNet-101-C4 | 33.1 | 54.9 | 34.8 | 12.1 | 35.6 | 51.1 |
| Mask R-CNN | ResNet-101-FPN | 35.7 | 58.0 | 37.8 | 15.5 | 38.1 | 52.4 |
| Mask R-CNN | ResNeXt-101-FPN | 37.1 | 60.0 | 39.4 | 16.9 | 39.9 | 53.5 |
表 1:COCO test-dev 上的实例分割 掩码 AP。MNC [10] 与 FCIS [26] 分别是 COCO 2015 与 2016 分割挑战的获胜者。不加花哨技巧,Mask R-CNN 超过了更复杂的 FCIS+++,后者包含多尺度训练/测试、水平翻转测试和 OHEM [38]。所有条目均为单模型结果。
We adopt image-centric training [12]. Images are resized such that their scale (shorter edge) is 800 pixels [27]. Each mini-batch has 2 images per GPU and each image has sampled RoIs, with a ratio of 1:3 of positive to negatives [12]. is 64 for the C4 backbone (as in [12, 36]) and 512 for FPN (as in [27]). We train on 8 GPUs (so effective mini-batch size is 16) for 160k iterations, with a learning rate of 0.02 which is decreased by 10 at the 120k iteration. We use a weight decay of 0.0001 and momentum of 0.9. With ResNeXt [45], we train with 1 image per GPU and the same number of iterations, with a starting learning rate of 0.01.
我们采用以图像为中心的训练 [12]。图像被缩放使其尺度(较短边)为 800 像素 [27]。每个小批量每 GPU 有 2 张图像,每张图像有 个采样 RoI,正负比为 1:3 [12]。对 C4 主干 为 64(如 [12, 36]),对 FPN 为 512(如 [27])。我们在 8 块 GPU 上训练(有效小批量大小为 16)160k 次迭代,学习率 0.02,在第 120k 次迭代时除以 10。权重衰减 0.0001,动量 0.9。对 ResNeXt [45],我们每 GPU 训练 1 张图像,迭代次数相同,起始学习率 0.01。
The RPN anchors span 5 scales and 3 aspect ratios, following [27]. For convenient ablation, RPN is trained separately and does not share features with Mask R-CNN, unless specified. For every entry in this paper, RPN and Mask R-CNN have the same backbones and so they are shareable.
RPN 锚点覆盖 5 个尺度与 3 种宽高比,遵循 [27]。为便于消融,除非另有说明,RPN 单独训练且不与 Mask R-CNN 共享特征。本文每条结果中,RPN 与 Mask R-CNN 使用相同主干,因而可以共享。
Inference:
At test time, the proposal number is 300 for the C4 backbone (as in [36]) and 1000 for FPN (as in [27]). We run the box prediction branch on these proposals, followed by non-maximum suppression [14]. The mask branch is then applied to the highest scoring 100 detection boxes. Although this differs from the parallel computation used in training, it speeds up inference and improves accuracy (due to the use of fewer, more accurate RoIs). The mask branch can predict masks per RoI, but we only use the -th mask, where is the predicted class by the classification branch. The floating-number mask output is then resized to the RoI size, and binarized at a threshold of 0.5.
推理:
测试时,C4 主干的提议数为 300(如 [36]),FPN 为 1000(如 [27])。我们在这些提议上运行框预测分支,再做非极大值抑制 [14]。随后把掩码分支施加到得分最高的 100 个检测框上。尽管这与训练时的并行计算不同,但能加快推理并提升准确率(因为使用了更少、更准确的 RoI)。掩码分支可为每个 RoI 预测 张掩码,但我们只使用第 张,其中 是分类分支预测的类别。 浮点掩码输出随后被缩放到 RoI 尺寸,并以 0.5 为阈值二值化。
Note that since we only compute masks on the top 100 detection boxes, Mask R-CNN adds a small overhead to its Faster R-CNN counterpart (e.g., 20% on typical models).
注意,由于我们只在得分最高的 100 个检测框上计算掩码,Mask R-CNN 相对其 Faster R-CNN 对应版本只增加很小开销(例如,典型模型上约 20%)。
4 Experiments: Instance Segmentation
4 实验:实例分割
We perform a thorough comparison of Mask R-CNN to the state of the art along with comprehensive ablations on the COCO dataset [28]. We report the standard COCO metrics including AP (averaged over IoU thresholds), AP50, AP75, and APS, APM, APL (AP at different scales). Unless noted, AP is evaluating using mask IoU. As in previous work [5, 27], we train using the union of 80k train images and a 35k subset of val images (trainval35k), and report ablations on the remaining 5k val images (minival). We also report results on test-dev [28].
我们在 COCO 数据集 [28] 上对 Mask R-CNN 与当时最先进方法进行全面比较,并做综合消融。我们报告标准 COCO 指标,包括 AP(在各 IoU 阈值上平均)、AP50、AP75,以及 APS、APM、APL(不同尺度上的 AP)。除非另有说明,AP 使用掩码 IoU 评估。与既往工作 [5, 27] 一样,我们用 80k 训练图像与 35k 验证子集(trainval35k)的并集训练,在剩余 5k 验证图像(minival)上报告消融,并在 test-dev [28] 上报告结果。
4.1 Main Results
4.1 主要结果
We compare Mask R-CNN to the state-of-the-art methods in instance segmentation in Table 1. All instantiations of our model outperform baseline variants of previous state-of-the-art models. This includes MNC [10] and FCIS [26], the winners of the COCO 2015 and 2016 segmentation challenges, respectively. Without bells and whistles, Mask R-CNN with ResNet-101-FPN backbone outperforms FCIS+++ [26], which includes multi-scale train/test, horizontal flip test, and online hard example mining (OHEM) [38]. While outside the scope of this work, we expect many such improvements to be applicable to ours.
我们在表 1 中把 Mask R-CNN 与实例分割当时最先进方法比较。我们模型的所有实例化都超过了既往最先进模型的基线变体。这包括分别是 COCO 2015 与 2016 分割挑战获胜者的 MNC [10] 与 FCIS [26]。不加花哨技巧,带 ResNet-101-FPN 主干的 Mask R-CNN 就超过了 FCIS+++ [26],后者包含多尺度训练/测试、水平翻转测试和在线难例挖掘(OHEM)[38]。虽不在本文范围内,我们预期许多这类改进也可用于我们的方法。
Mask R-CNN outputs are visualized in Figures 2 and 5. Mask R-CNN achieves good results even under challenging conditions. In Figure 6 we compare our Mask R-CNN baseline and FCIS+++ [26]. FCIS+++ exhibits systematic artifacts on overlapping instances, suggesting that it is challenged by the fundamental difficulty of instance segmentation. Mask R-CNN shows no such artifacts.
Mask R-CNN 的输出可视化见图 2 与图 5。即使在挑战性条件下,Mask R-CNN 也能取得好结果。图 6 比较了我们的 Mask R-CNN 基线与 FCIS+++ [26]。FCIS+++ 在重叠实例上表现出系统性伪影,说明它受到实例分割根本困难的挑战。Mask R-CNN 没有这类伪影。
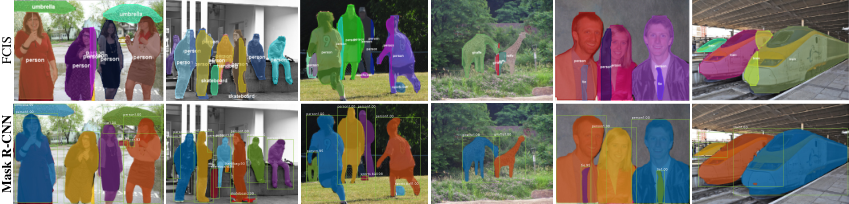
Figure 6: FCIS+++ [26] (top) vs. Mask R-CNN (bottom, ResNet-101-FPN). FCIS exhibits systematic artifacts on overlapping objects.
图 6:FCIS+++ [26](上)对比 Mask R-CNN(下,ResNet-101-FPN)。FCIS 在重叠物体上表现出系统性伪影。
| net-depth-features | AP | AP50 | AP75 |
|---|---|---|---|
| ResNet-50-C4 | 30.3 | 51.2 | 31.5 |
| ResNet-101-C4 | 32.7 | 54.2 | 34.3 |
| ResNet-50-FPN | 33.6 | 55.2 | 35.3 |
| ResNet-101-FPN | 35.4 | 57.3 | 37.5 |
| ResNeXt-101-FPN | 36.7 | 59.5 | 38.9 |
| AP | AP50 | AP75 | |
|---|---|---|---|
| softmax | 24.8 | 44.1 | 25.1 |
| sigmoid | 30.3 | 51.2 | 31.5 |
| +5.5 | +7.1 | +6.4 |
| align? | bilinear? | agg. | AP | AP50 | AP75 | |
|---|---|---|---|---|---|---|
| RoIPool [12] | max | 26.9 | 48.8 | 26.4 | ||
| RoIWarp [10] | ✓ | max | 27.2 | 49.2 | 27.1 | |
| ✓ | ave | 27.1 | 48.9 | 27.1 | ||
| RoIAlign | ✓ | ✓ | max | 30.2 | 51.0 | 31.8 |
| ✓ | ✓ | ave | 30.3 | 51.2 | 31.5 |
| AP | AP50 | AP75 | AP | AP | AP | |
|---|---|---|---|---|---|---|
| RoIPool | 23.6 | 46.5 | 21.6 | 28.2 | 52.7 | 26.9 |
| RoIAlign | 30.9 | 51.8 | 32.1 | 34.0 | 55.3 | 36.4 |
| +7.3 | + 5.3 | +10.5 | +5.8 | +2.6 | +9.5 |
| mask branch | AP | AP50 | AP75 | |
|---|---|---|---|---|
| MLP | fc: 10241024 | 31.5 | 53.7 | 32.8 |
| MLP | fc: 102410241024 | 31.5 | 54.0 | 32.6 |
| FCN | conv: 25625625625625680 | 33.6 | 55.2 | 35.3 |
(a) Backbone Architecture: Better backbones bring expected gains: deeper networks do better, FPN outperforms C4 features, and ResNeXt improves on ResNet.
| net-depth-features | AP | AP50 | AP75 |
|---|---|---|---|
| ResNet-50-C4 | 30.3 | 51.2 | 31.5 |
| ResNet-101-C4 | 32.7 | 54.2 | 34.3 |
| ResNet-50-FPN | 33.6 | 55.2 | 35.3 |
| ResNet-101-FPN | 35.4 | 57.3 | 37.5 |
| ResNeXt-101-FPN | 36.7 | 59.5 | 38.9 |
| AP | AP50 | AP75 | |
|---|---|---|---|
| softmax | 24.8 | 44.1 | 25.1 |
| sigmoid | 30.3 | 51.2 | 31.5 |
| +5.5 | +7.1 | +6.4 |
| align? | bilinear? | agg. | AP | AP50 | AP75 | |
|---|---|---|---|---|---|---|
| RoIPool [12] | max | 26.9 | 48.8 | 26.4 | ||
| RoIWarp [10] | ✓ | max | 27.2 | 49.2 | 27.1 | |
| ✓ | ave | 27.1 | 48.9 | 27.1 | ||
| RoIAlign | ✓ | ✓ | max | 30.2 | 51.0 | 31.8 |
| ✓ | ✓ | ave | 30.3 | 51.2 | 31.5 |
| AP | AP50 | AP75 | AP | AP | AP | |
|---|---|---|---|---|---|---|
| RoIPool | 23.6 | 46.5 | 21.6 | 28.2 | 52.7 | 26.9 |
| RoIAlign | 30.9 | 51.8 | 32.1 | 34.0 | 55.3 | 36.4 |
| +7.3 | + 5.3 | +10.5 | +5.8 | +2.6 | +9.5 |
| mask branch | AP | AP50 | AP75 | |
|---|---|---|---|---|
| MLP | fc: 10241024 | 31.5 | 53.7 | 32.8 |
| MLP | fc: 102410241024 | 31.5 | 54.0 | 32.6 |
| FCN | conv: 25625625625625680 | 33.6 | 55.2 | 35.3 |
(a) 主干架构:更好的主干带来预期收益:更深网络更好,FPN 优于 C4 特征,ResNeXt 优于 ResNet。
4.2 Ablation Experiments
4.2 消融实验
We run a number of ablations to analyze Mask R-CNN. Results are shown in Table 2 and discussed in detail next.
我们做若干消融来分析 Mask R-CNN。结果见表 2,下文详细讨论。
Architecture:
Table 2a shows Mask R-CNN with various backbones. It benefits from deeper networks (50 vs. 101) and advanced designs including FPN and ResNeXt. We note that not all frameworks automatically benefit from deeper or advanced networks (see benchmarking in [21]).
架构:
表 2a 展示了带各种主干的 Mask R-CNN。它受益于更深网络(50 对比 101)以及包括 FPN 和 ResNeXt 在内的先进设计。我们注意到,并非所有框架都会自动受益于更深或更先进的网络(见 [21] 中的基准测试)。
Multinomial vs. Independent Masks:
Mask R-CNN decouples mask and class prediction: as the existing box branch predicts the class label, we generate a mask for each class without competition among classes (by a per-pixel sigmoid and a binary loss). In Table 2b, we compare this to using a per-pixel softmax and a multinomial loss (as commonly used in FCN [30]). This alternative couples the tasks of mask and class prediction, and results in a severe loss in mask AP (5.5 points). This suggests that once the instance has been classified as a whole (by the box branch), it is sufficient to predict a binary mask without concern for the categories, which makes the model easier to train.
多项 对比 独立掩码:
Mask R-CNN 解耦掩码与类别预测:由于已有框分支预测类别标签,我们为每个类别生成掩码而不在类别间竞争(通过逐像素 sigmoid 和 二值损失)。在表 2b 中,我们把它与使用逐像素 softmax 和 多项损失(FCN [30] 中常用)比较。这一替代方案把掩码与类别预测任务耦合起来,导致掩码 AP 严重损失(5.5 点)。这表明一旦实例已被整体分类(由框分支),预测二值掩码而不关心类别就足够了,这使模型更易训练。
Class-Specific vs. Class-Agnostic Masks:
Our default instantiation predicts class-specific masks, i.e., one mask per class. Interestingly, Mask R-CNN with class-agnostic masks (i.e., predicting a single output regardless of class) is nearly as effective: it has 29.7 mask AP vs. 30.3 for the class-specific counterpart on ResNet-50-C4. This further highlights the division of labor in our approach which largely decouples classification and segmentation.
类别特定 对比 类别无关掩码:
我们的默认实例化预测类别特定掩码,即每个类别一张 掩码。有趣的是,带类别无关掩码(即无论类别如何只预测单一 输出)的 Mask R-CNN 几乎同样有效:在 ResNet-50-C4 上,它有 29.7 掩码 AP,而类别特定对应版本为 30.3。这进一步凸显了我们方法中分类与分割在很大程度上解耦的分工。
| backbone | AP | AP | AP | AP | AP | AP | |
|---|---|---|---|---|---|---|---|
| Faster R-CNN+++ [19] | ResNet-101-C4 | 34.9 | 55.7 | 37.4 | 15.6 | 38.7 | 50.9 |
| Faster R-CNN w FPN [27] | ResNet-101-FPN | 36.2 | 59.1 | 39.0 | 18.2 | 39.0 | 48.2 |
| Faster R-CNN by G-RMI [21] | Inception-ResNet-v2 [41] | 34.7 | 55.5 | 36.7 | 13.5 | 38.1 | 52.0 |
| Faster R-CNN w TDM [39] | Inception-ResNet-v2-TDM | 36.8 | 57.7 | 39.2 | 16.2 | 39.8 | 52.1 |
| Faster R-CNN, RoIAlign | ResNet-101-FPN | 37.3 | 59.6 | 40.3 | 19.8 | 40.2 | 48.8 |
| Mask R-CNN | ResNet-101-FPN | 38.2 | 60.3 | 41.7 | 20.1 | 41.1 | 50.2 |
| Mask R-CNN | ResNeXt-101-FPN | 39.8 | 62.3 | 43.4 | 22.1 | 43.2 | 51.2 |
Table 3: Object detection single-model results (bounding box AP), vs. state-of-the-art on test-dev. Mask R-CNN using ResNet-101-FPN outperforms the base variants of all previous state-of-the-art models (the mask output is ignored in these experiments). The gains of Mask R-CNN over [27] come from using RoIAlign (+1.1 AP), multitask training (+0.9 AP), and ResNeXt-101 (+1.6 AP).
| backbone | AP | AP | AP | AP | AP | AP | |
|---|---|---|---|---|---|---|---|
| Faster R-CNN+++ [19] | ResNet-101-C4 | 34.9 | 55.7 | 37.4 | 15.6 | 38.7 | 50.9 |
| Faster R-CNN w FPN [27] | ResNet-101-FPN | 36.2 | 59.1 | 39.0 | 18.2 | 39.0 | 48.2 |
| Faster R-CNN by G-RMI [21] | Inception-ResNet-v2 [41] | 34.7 | 55.5 | 36.7 | 13.5 | 38.1 | 52.0 |
| Faster R-CNN w TDM [39] | Inception-ResNet-v2-TDM | 36.8 | 57.7 | 39.2 | 16.2 | 39.8 | 52.1 |
| Faster R-CNN, RoIAlign | ResNet-101-FPN | 37.3 | 59.6 | 40.3 | 19.8 | 40.2 | 48.8 |
| Mask R-CNN | ResNet-101-FPN | 38.2 | 60.3 | 41.7 | 20.1 | 41.1 | 50.2 |
| Mask R-CNN | ResNeXt-101-FPN | 39.8 | 62.3 | 43.4 | 22.1 | 43.2 | 51.2 |
表 3:test-dev 上的物体检测单模型结果(边界框 AP),对比当时最先进。使用 ResNet-101-FPN 的 Mask R-CNN 超过所有既往最先进模型的基础变体(这些实验中忽略掩码输出)。Mask R-CNN 相对 [27] 的收益来自使用 RoIAlign(+1.1 AP)、多任务训练(+0.9 AP)以及 ResNeXt-101(+1.6 AP)。
RoIAlign:
An evaluation of our proposed RoIAlign layer is shown in Table 2c. For this experiment we use the ResNet-50-C4 backbone, which has stride 16. RoIAlign improves AP by about 3 points over RoIPool, with much of the gain coming at high IoU (AP75). RoIAlign is insensitive to max/average pool; we use average in the rest of the paper.
RoIAlign:
对我们提出的 RoIAlign 层的评估见表 2c。本实验使用步长为 16 的 ResNet-50-C4 主干。RoIAlign 相对 RoIPool 提升约 3 个 AP 点,大部分收益来自高 IoU(AP75)。RoIAlign 对 max/average 池化不敏感;本文其余部分使用 average。
Additionally, we compare with RoIWarp proposed in MNC [10] that also adopt bilinear sampling. As discussed in §3, RoIWarp still quantizes the RoI, losing alignment with the input. As can be seen in Table 2c, RoIWarp performs on par with RoIPool and much worse than RoIAlign. This highlights that proper alignment is key.
此外,我们与 MNC [10] 提出的也采用双线性采样的 RoIWarp 比较。如 §3 所讨论,RoIWarp 仍然量化 RoI,从而失去与输入的对齐。如表 2c 所示,RoIWarp 与 RoIPool 表现相当,远差于 RoIAlign。这凸显了正确对齐是关键。
We also evaluate RoIAlign with a ResNet-50-C5 backbone, which has an even larger stride of 32 pixels. We use the same head as in Figure 4 (right), as the res5 head is not applicable. Table 2d shows that RoIAlign improves mask AP by a massive 7.3 points, and mask AP75 by 10.5 points (50% relative improvement). Moreover, we note that with RoIAlign, using stride-32 C5 features (30.9 AP) is more accurate than using stride-16 C4 features (30.3 AP, Table 2c). RoIAlign largely resolves the long-standing challenge of using large-stride features for detection and segmentation.
我们还用 ResNet-50-C5 主干评估 RoIAlign,该主干有更大的 32 像素步长。我们使用与图 4(右)相同的头,因为 res5 头不适用。表 2d 显示 RoIAlign 把掩码 AP 大幅提升 7.3 点,掩码 AP75 提升 10.5 点(相对提升 50%)。此外我们注意到,有了 RoIAlign,使用步长 32 的 C5 特征(30.9 AP)比使用步长 16 的 C4 特征(30.3 AP,表 2c)更准确。RoIAlign 在很大程度上解决了用大步长特征做检测与分割这一长期挑战。
Finally, RoIAlign shows a gain of 1.5 mask AP and 0.5 box AP when used with FPN, which has finer multi-level strides. For keypoint detection that requires finer alignment, RoIAlign shows large gains even with FPN (Table 6).
最后,与 FPN(具有更细的多层级步长)一起使用时,RoIAlign 带来 1.5 掩码 AP 与 0.5 框 AP 的收益。对于需要对齐更精细的关键点检测,即使有 FPN,RoIAlign 仍显示大幅收益(表 6)。
Mask Branch:
Segmentation is a pixel-to-pixel task and we exploit the spatial layout of masks by using an FCN. In Table 2e, we compare multi-layer perceptrons (MLP) and FCNs, using a ResNet-50-FPN backbone. Using FCNs gives a 2.1 mask AP gain over MLPs. We note that we choose this backbone so that the conv layers of the FCN head are not pre-trained, for a fair comparison with MLP.
掩码分支:
分割是像素到像素任务,我们通过使用 FCN 利用掩码的空间布局。在表 2e 中,我们用 ResNet-50-FPN 主干比较多层感知机(MLP)与 FCN。使用 FCN 相对 MLP 带来 2.1 掩码 AP 收益。我们选择这一主干,使得 FCN 头的卷积层未经预训练,以便与 MLP 公平比较。
4.3 Bounding Box Detection Results
4.3 边界框检测结果
We compare Mask R-CNN to the state-of-the-art COCO bounding-box object detection in Table 3. For this result, even though the full Mask R-CNN model is trained, only the classification and box outputs are used at inference (the mask output is ignored). Mask R-CNN using ResNet-101-FPN outperforms the base variants of all previous state-of-the-art models, including the single-model variant of G-RMI [21], the winner of the COCO 2016 Detection Challenge. Using ResNeXt-101-FPN, Mask R-CNN further improves results, with a margin of 3.0 points box AP over the best previous single model entry from [39] (which used Inception-ResNet-v2-TDM).
我们在表 3 中把 Mask R-CNN 与 COCO 边界框物体检测的当时最先进结果比较。对此结果,尽管训练了完整 Mask R-CNN 模型,推理时只用分类与框输出(忽略掩码输出)。使用 ResNet-101-FPN 的 Mask R-CNN 超过所有既往最先进模型的基础变体,包括 COCO 2016 检测挑战获胜者 G-RMI [21] 的单模型变体。使用 ResNeXt-101-FPN,Mask R-CNN 进一步提升结果,比 [39] 中最佳既往单模型条目(使用 Inception-ResNet-v2-TDM)高 3.0 点框 AP。
As a further comparison, we trained a version of Mask R-CNN but without the mask branch, denoted by “Faster R-CNN, RoIAlign” in Table 3. This model performs better than the model presented in [27] due to RoIAlign. On the other hand, it is 0.9 points box AP lower than Mask R-CNN. This gap of Mask R-CNN on box detection is therefore due solely to the benefits of multi-task training.
作为进一步比较,我们训练了没有掩码分支的 Mask R-CNN 版本,在表 3 中记为 “Faster R-CNN, RoIAlign”。由于 RoIAlign,该模型优于 [27] 中给出的模型。另一方面,它比 Mask R-CNN 低 0.9 点框 AP。因此 Mask R-CNN 在框检测上的这一差距完全来自多任务训练的收益。
Lastly, we note that Mask R-CNN attains a small gap between its mask and box AP: e.g., 2.7 points between 37.1 (mask, Table 1) and 39.8 (box, Table 3). This indicates that our approach largely closes the gap between object detection and the more challenging instance segmentation task.
最后我们注意到,Mask R-CNN 的掩码 AP 与框 AP 差距很小:例如,表 1 的 37.1(掩码)与表 3 的 39.8(框)之间相差 2.7 点。这表明我们的方法在很大程度上弥合了物体检测与更具挑战性的实例分割任务之间的差距。
4.4 Timing
4.4 耗时
Inference:
We train a ResNet-101-FPN model that shares features between the RPN and Mask R-CNN stages, following the 4-step training of Faster R-CNN [36]. This model runs at 195ms per image on an Nvidia Tesla M40 GPU (plus 15ms CPU time resizing the outputs to the original resolution), and achieves statistically the same mask AP as the unshared one. We also report that the ResNet-101-C4 variant takes 400ms as it has a heavier box head (Figure 4), so we do not recommend using the C4 variant in practice.
推理:
我们按 Faster R-CNN [36] 的 4 步训练,训练一个在 RPN 与 Mask R-CNN 阶段之间共享特征的 ResNet-101-FPN 模型。该模型在 Nvidia Tesla M40 GPU 上每张图像运行 195ms(另加 15ms CPU 时间把输出缩放到原始分辨率),掩码 AP 与非共享版本在统计上相同。我们还报告 ResNet-101-C4 变体约需 400ms,因为它有更重的框头(图 4),因此我们不建议在实践中使用 C4 变体。
Although Mask R-CNN is fast, we note that our design is not optimized for speed, and better speed/accuracy trade-offs could be achieved [21], e.g., by varying image sizes and proposal numbers, which is beyond the scope of this paper.
尽管 Mask R-CNN 很快,我们注意到设计并未针对速度优化,可以取得更好的速度/准确率权衡 [21],例如通过改变图像尺寸与提议数,这超出本文范围。
Training:
Mask R-CNN is also fast to train. Training with ResNet-50-FPN on COCO trainval35k takes 32 hours in our synchronized 8-GPU implementation (0.72s per 16-image mini-batch), and 44 hours with ResNet-101-FPN. In fact, fast prototyping can be completed in less than one day when training on the train set. We hope such rapid training will remove a major hurdle in this area and encourage more people to perform research on this challenging topic.
训练:
Mask R-CNN 训练也很快。在我们同步的 8-GPU 实现中,用 ResNet-50-FPN 在 COCO trainval35k 上训练需 32 小时(每个 16 图像小批量 0.72s),用 ResNet-101-FPN 需 44 小时。实际上,在训练集上训练时,快速原型可在不到一天内完成。我们希望如此快速的训练能消除该领域的一大障碍,鼓励更多人研究这一挑战性课题。
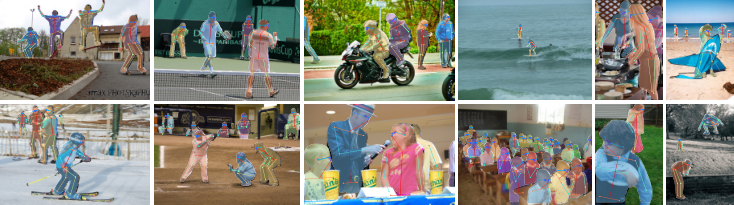
Figure 7: Keypoint detection results on COCO test using Mask R-CNN (ResNet-50-FPN), with person segmentation masks predicted from the same model. This model has a keypoint AP of 63.1 and runs at 5 fps.
图 7:用 Mask R-CNN(ResNet-50-FPN)在 COCO 测试上的关键点检测结果,同一模型还预测了人的分割掩码。该模型关键点 AP 为 63.1,运行速度 5 fps。
5 Mask R-CNN for Human Pose Estimation
5 用于人体姿态估计的 Mask R-CNN
Our framework can easily be extended to human pose estimation. We model a keypoint’s location as a one-hot mask, and adopt Mask R-CNN to predict masks, one for each of keypoint types (e.g., left shoulder, right elbow). This task helps demonstrate the flexibility of Mask R-CNN.
我们的框架可以很容易地扩展到人体姿态估计。我们把关键点位置建模为一热掩码,并采用 Mask R-CNN 预测 张掩码,每种关键点类型一张(例如左肩、右肘)。这一任务有助于展示 Mask R-CNN 的灵活性。
We note that minimal domain knowledge for human pose is exploited by our system, as the experiments are mainly to demonstrate the generality of the Mask R-CNN framework. We expect that domain knowledge (e.g., modeling structures [6]) will be complementary to our simple approach.
我们注意到系统几乎没有利用人体姿态的领域知识——实验主要是为了展示 Mask R-CNN 框架的通用性。我们预期领域知识(例如建模结构 [6])将与我们的简单方法互补。
Implementation Details:
We make minor modifications to the segmentation system when adapting it for keypoints. For each of the keypoints of an instance, the training target is a one-hot binary mask where only a single pixel is labeled as foreground. During training, for each visible ground-truth keypoint, we minimize the cross-entropy loss over an -way softmax output (which encourages a single point to be detected). We note that as in instance segmentation, the keypoints are still treated independently.
实现细节:
把分割系统适配到关键点时我们做少量修改。对实例的 个关键点中的每一个,训练目标是一张一热 二值掩码,其中只有单个像素标为前景。训练时,对每个可见的真实关键点,我们在 路 softmax 输出上最小化交叉熵损失(鼓励检测到单点)。我们注意到,与实例分割一样, 个关键点仍被独立处理。
We adopt the ResNet-FPN variant, and the keypoint head architecture is similar to that in Figure 4 (right). The keypoint head consists of a stack of eight 33 512-d conv layers, followed by a deconv layer and 2 bilinear upscaling, producing an output resolution of 5656. We found that a relatively high resolution output (compared to masks) is required for keypoint-level localization accuracy.
我们采用 ResNet-FPN 变体,关键点头架构与图 4(右)类似。关键点头由八个 3×3 512 维卷积层堆叠组成,后接一个反卷积层与 2× 双线性上采样,输出分辨率为 56×56。我们发现关键点级定位准确率需要相对较高的输出分辨率(与掩码相比)。
Models are trained on all COCO trainval35k images that contain annotated keypoints. To reduce overfitting, as this training set is smaller, we train using image scales randomly sampled from [640, 800] pixels; inference is on a single scale of 800 pixels. We train for 90k iterations, starting from a learning rate of 0.02 and reducing it by 10 at 60k and 80k iterations. We use bounding-box NMS with a threshold of 0.5. Other details are identical as in §3.1.
模型在所有含标注关键点的 COCO trainval35k 图像上训练。由于该训练集更小,为减少过拟合,我们用从 [640, 800] 像素随机采样的图像尺度训练;推理在单一 800 像素尺度上。我们训练 90k 次迭代,起始学习率 0.02,在 60k 与 80k 次迭代时除以 10。我们使用阈值为 0.5 的边界框 NMS。其余细节与 §3.1 相同。
| AP | AP | AP | AP | AP | |
|---|---|---|---|---|---|
| CMU-Pose+++ [6] | 61.8 | 84.9 | 67.5 | 57.1 | 68.2 |
| G-RMI [32]† | 62.4 | 84.0 | 68.5 | 59.1 | 68.1 |
| Mask R-CNN, keypoint-only | 62.7 | 87.0 | 68.4 | 57.4 | 71.1 |
| Mask R-CNN, keypoint & mask | 63.1 | 87.3 | 68.7 | 57.8 | 71.4 |
Table 4: Keypoint detection AP on COCO test-dev. Ours is a single model (ResNet-50-FPN) that runs at 5 fps. CMU-Pose+++ [6] is the 2016 competition winner that uses multi-scale testing, post-processing with CPM [44], and filtering with an object detector, adding a cumulative 5 points (clarified in personal communication). †: G-RMI was trained on COCO plus MPII [1] (25k images), using two models (Inception-ResNet-v2 for bounding box detection and ResNet-101 for keypoints).
| AP | AP | AP | AP | AP | |
|---|---|---|---|---|---|
| CMU-Pose+++ [6] | 61.8 | 84.9 | 67.5 | 57.1 | 68.2 |
| G-RMI [32]† | 62.4 | 84.0 | 68.5 | 59.1 | 68.1 |
| Mask R-CNN, keypoint-only | 62.7 | 87.0 | 68.4 | 57.4 | 71.1 |
| Mask R-CNN, keypoint & mask | 63.1 | 87.3 | 68.7 | 57.8 | 71.4 |
表 4:COCO test-dev 上的关键点检测 AP。我们的是单模型(ResNet-50-FPN),运行速度 5 fps。CMU-Pose+++ [6] 是 2016 竞赛获胜者,使用多尺度测试、用 CPM [44] 后处理,并用物体检测器过滤,累计增加约 5 点(私人通信澄清)。†:G-RMI 在 COCO 加上 MPII [1](25k 图像)上训练,使用两个模型(Inception-ResNet-v2 做边界框检测,ResNet-101 做关键点)。
Main Results and Ablations:
We evaluate the person keypoint AP (AP) and experiment with a ResNet-50-FPN backbone; more backbones will be studied in the appendix. Table 4 shows that our result (62.7 AP) is 0.9 points higher than the COCO 2016 keypoint detection winner [6] that uses a multi-stage processing pipeline (see caption of Table 4). Our method is considerably simpler and faster.
主要结果与消融:
我们评估人的关键点 AP(AP),并用 ResNet-50-FPN 主干做实验;更多主干将在附录中研究。表 4 显示我们的结果(62.7 AP)比使用多阶段处理流水线的 COCO 2016 关键点检测获胜者 [6] 高 0.9 点(见表 4 标题)。我们的方法明显更简单、更快。
| AP | AP | AP | |
|---|---|---|---|
| Faster R-CNN | 52.5 | - | - |
| Mask R-CNN, mask-only | 53.6 | 45.8 | - |
| Mask R-CNN, keypoint-only | 50.7 | - | 64.2 |
| Mask R-CNN, keypoint & mask | 52.0 | 45.1 | 64.7 |
Table 5: Multi-task learning of box, mask, and keypoint about the person category, evaluated on minival. All entries are trained on the same data for fair comparisons. The backbone is ResNet-50-FPN. The entries with 64.2 and 64.7 AP on minival have test-dev AP of 62.7 and 63.1, respectively (see Table 4).
| AP | AP | AP | |
|---|---|---|---|
| Faster R-CNN | 52.5 | - | - |
| Mask R-CNN, mask-only | 53.6 | 45.8 | - |
| Mask R-CNN, keypoint-only | 50.7 | - | 64.2 |
| Mask R-CNN, keypoint & mask | 52.0 | 45.1 | 64.7 |
表 5:关于 person 类别的框、掩码与关键点的多任务学习,在 minival 上评估。所有条目在相同数据上训练以便公平比较。主干为 ResNet-50-FPN。minival 上 AP 为 64.2 与 64.7 的条目在 test-dev 上分别为 62.7 与 63.1(见表 4)。
More importantly, we have a unified model that can simultaneously predict boxes, segments, and keypoints while running at 5 fps. Adding a segment branch (for the person category) improves the AP to 63.1 (Table 4) on test-dev. More ablations of multi-task learning on minival are in Table 5. Adding the mask branch to the box-only (i.e., Faster R-CNN) or keypoint-only versions consistently improves these tasks. However, adding the keypoint branch reduces the box/mask AP slightly, suggesting that while keypoint detection benefits from multitask training, it does not in turn help the other tasks. Nevertheless, learning all three tasks jointly enables a unified system to efficiently predict all outputs simultaneously (Figure 7).
更重要的是,我们有一个能同时预测框、分割与关键点的统一模型,并以 5 fps 运行。加入(针对 person 类别的)分割分支把 test-dev 上的 AP 提升到 63.1(表 4)。minival 上多任务学习的更多消融见表 5。把掩码分支加到仅框(即 Faster R-CNN)或仅关键点版本上,一致地提升这些任务。然而,加入关键点分支会略微降低框/掩码 AP,说明虽然关键点检测受益于多任务训练,它反过来并不帮助其他任务。尽管如此,联合学习三项任务使统一系统能高效地同时预测所有输出(图 7)。
| AP | AP | AP | AP | AP | |
|---|---|---|---|---|---|
| RoIPool | 59.8 | 86.2 | 66.7 | 55.1 | 67.4 |
| RoIAlign | 64.2 | 86.6 | 69.7 | 58.7 | 73.0 |
Table 6: RoIAlign vs. RoIPool for keypoint detection on minival. The backbone is ResNet-50-FPN.
| AP | AP | AP | AP | AP | |
|---|---|---|---|---|---|
| RoIPool | 59.8 | 86.2 | 66.7 | 55.1 | 67.4 |
| RoIAlign | 64.2 | 86.6 | 69.7 | 58.7 | 73.0 |
表 6:minival 上关键点检测的 RoIAlign 对比 RoIPool。主干为 ResNet-50-FPN。
We also investigate the effect of RoIAlign on keypoint detection (Table 6). Though this ResNet-50-FPN backbone has finer strides (e.g., 4 pixels on the finest level), RoIAlign still shows significant improvement over RoIPool and increases AP by 4.4 points. This is because keypoint detections are more sensitive to localization accuracy. This again indicates that alignment is essential for pixel-level localization, including masks and keypoints.
我们还研究 RoIAlign 对关键点检测的影响(表 6)。尽管这一 ResNet-50-FPN 主干有更细的步长(例如最细层级上 4 像素),RoIAlign 仍相对 RoIPool 显示显著改进,并把 AP 提高 4.4 点。这是因为关键点检测对定位准确率更敏感。这再次表明对齐对包括掩码与关键点在内的像素级定位至关重要。
Given the effectiveness of Mask R-CNN for extracting object bounding boxes, masks, and keypoints, we expect it be an effective framework for other instance-level tasks.
鉴于 Mask R-CNN 在提取物体边界框、掩码与关键点上的有效性,我们预期它会成为其他实例级任务的有效框架。
| training data | AP [val] | AP | AP50 | person | rider | car | truck | bus | train | mcycle | bicycle | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| InstanceCut [23] | fine + coarse | 15.8 | 13.0 | 27.9 | 10.0 | 8.0 | 23.7 | 14.0 | 19.5 | 15.2 | 9.3 | 4.7 |
| DWT [4] | fine | 19.8 | 15.6 | 30.0 | 15.1 | 11.7 | 32.9 | 17.1 | 20.4 | 15.0 | 7.9 | 4.9 |
| SAIS [17] | fine | - | 17.4 | 36.7 | 14.6 | 12.9 | 35.7 | 16.0 | 23.2 | 19.0 | 10.3 | 7.8 |
| DIN [3] | fine + coarse | - | 20.0 | 38.8 | 16.5 | 16.7 | 25.7 | 20.6 | 30.0 | 23.4 | 17.1 | 10.1 |
| SGN [29] | fine + coarse | 29.2 | 25.0 | 44.9 | 21.8 | 20.1 | 39.4 | 24.8 | 33.2 | 30.8 | 17.7 | 12.4 |
| Mask R-CNN | fine | 31.5 | 26.2 | 49.9 | 30.5 | 23.7 | 46.9 | 22.8 | 32.2 | 18.6 | 19.1 | 16.0 |
| Mask R-CNN | fine + COCO | 36.4 | 32.0 | 58.1 | 34.8 | 27.0 | 49.1 | 30.1 | 40.9 | 30.9 | 24.1 | 18.7 |
Table 7: Results on Cityscapes val (‘AP [val]’ column) and test (remaining columns) sets. Our method uses ResNet-50-FPN.
| training data | AP [val] | AP | AP50 | person | rider | car | truck | bus | train | mcycle | bicycle | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| InstanceCut [23] | fine + coarse | 15.8 | 13.0 | 27.9 | 10.0 | 8.0 | 23.7 | 14.0 | 19.5 | 15.2 | 9.3 | 4.7 |
| DWT [4] | fine | 19.8 | 15.6 | 30.0 | 15.1 | 11.7 | 32.9 | 17.1 | 20.4 | 15.0 | 7.9 | 4.9 |
| SAIS [17] | fine | - | 17.4 | 36.7 | 14.6 | 12.9 | 35.7 | 16.0 | 23.2 | 19.0 | 10.3 | 7.8 |
| DIN [3] | fine + coarse | - | 20.0 | 38.8 | 16.5 | 16.7 | 25.7 | 20.6 | 30.0 | 23.4 | 17.1 | 10.1 |
| SGN [29] | fine + coarse | 29.2 | 25.0 | 44.9 | 21.8 | 20.1 | 39.4 | 24.8 | 33.2 | 30.8 | 17.7 | 12.4 |
| Mask R-CNN | fine | 31.5 | 26.2 | 49.9 | 30.5 | 23.7 | 46.9 | 22.8 | 32.2 | 18.6 | 19.1 | 16.0 |
| Mask R-CNN | fine + COCO | 36.4 | 32.0 | 58.1 | 34.8 | 27.0 | 49.1 | 30.1 | 40.9 | 30.9 | 24.1 | 18.7 |
表 7:Cityscapes val(‘AP [val]’ 列)与 test(其余列)集上的结果。我们的方法使用 ResNet-50-FPN。
Appendix A: Experiments on Cityscapes
附录 A:Cityscapes 上的实验
We further report instance segmentation results on the Cityscapes [7] dataset. This dataset has fine annotations for 2975 train, 500 val, and 1525 test images. It has 20k coarse training images without instance annotations, which we do not use. All images are 20481024 pixels. The instance segmentation task involves 8 object categories, whose numbers of instances on the fine training set are:
我们进一步在 Cityscapes [7] 数据集上报告实例分割结果。该数据集对 2975 张训练、500 张验证与 1525 张测试图像有精细标注。它有 20k 张没有实例标注的粗训练图像,我们不使用。所有图像为 2048×1024 像素。实例分割任务涉及 8 个物体类别,它们在精细训练集上的实例数为:
Instance segmentation performance on this task is measured by the COCO-style mask AP (averaged over IoU thresholds); AP50 (i.e., mask AP at an IoU of 0.5) is also reported.
该任务上的实例分割性能用 COCO 风格掩码 AP(在各 IoU 阈值上平均)衡量;也报告 AP50(即 IoU 为 0.5 时的掩码 AP)。
Implementation:
We apply our Mask R-CNN models with the ResNet-FPN-50 backbone; we found the 101-layer counterpart performs similarly due to the small dataset size. We train with image scale (shorter side) randomly sampled from [800, 1024], which reduces overfitting; inference is on a single scale of 1024 pixels. We use a mini-batch size of 1 image per GPU (so 8 on 8 GPUs) and train the model for 24k iterations, starting from a learning rate of 0.01 and reducing it to 0.001 at 18k iterations. It takes 4 hours of training on a single 8-GPU machine under this setting.
实现:
我们用 ResNet-FPN-50 主干应用 Mask R-CNN 模型;由于数据集较小,我们发现 101 层对应版本表现相近。我们用从 [800, 1024] 随机采样的图像尺度(较短边)训练,以减少过拟合;推理在单一 1024 像素尺度上。我们使用每 GPU 1 张图像的小批量大小(因而 8 块 GPU 上为 8),训练模型 24k 次迭代,起始学习率 0.01,在 18k 次迭代时降到 0.001。在此设置下,单台 8-GPU 机器上训练约需 4 小时。
Results:
Table 7 compares our results to the state of the art on the val and test sets. Without using the coarse training set, our method achieves 26.2 AP on test, which is over 30% relative improvement over the previous best entry (DIN [3]), and is also better than the concurrent work of SGN’s 25.0 [29]. Both DIN and SGN use fine + coarse data. Compared to the best entry using fine data only (17.4 AP), we achieve a 50% improvement.
结果:
表 7 把我们的结果与 val 和 test 集上的当时最先进比较。不使用粗训练集,我们的方法在 test 上达到 26.2 AP,相对既往最佳条目(DIN [3])有超过 30% 的相对提升,也优于同期工作 SGN 的 25.0 [29]。DIN 与 SGN 都使用 fine + coarse 数据。与仅使用 fine 数据的最佳条目(17.4 AP)相比,我们实现了约 50% 的提升。
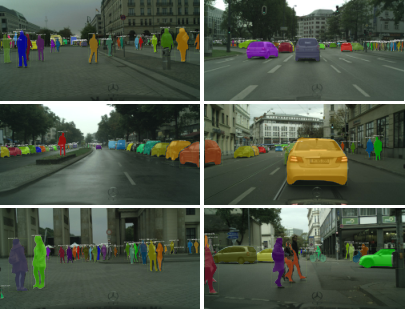
Figure 8: Mask R-CNN results on Cityscapes test (32.0 AP). The bottom-right image shows a failure prediction.
图 8:Cityscapes test 上的 Mask R-CNN 结果(32.0 AP)。右下图像显示一次失败预测。
For the person and car categories, the Cityscapes dataset exhibits a large number of within-category overlapping instances (on average 6 people and 9 cars per image). We argue that within-category overlap is a core difficulty of instance segmentation. Our method shows massive improvement on these two categories over the other best entries (relative 40% improvement on person from 21.8 to 30.5 and 20% improvement on car from 39.4 to 46.9), even though our method does not exploit the coarse data.
对 person 与 car 类别,Cityscapes 数据集表现出大量类内重叠实例(平均每张图像 6 个人与 9 辆车)。我们认为类内重叠是实例分割的核心困难。我们的方法在这两个类别上相对其他最佳条目有巨大提升(person 从 21.8 到 30.5,相对约 40%;car 从 39.4 到 46.9,相对约 20%),尽管我们的方法没有利用粗数据。
A main challenge of the Cityscapes dataset is training models in a low-data regime, particularly for the categories of truck, bus, and train, which have about 200-500 training samples each. To partially remedy this issue, we further report a result using COCO pre-training. To do this, we initialize the corresponding 7 categories in Cityscapes from a pre-trained COCO Mask R-CNN model (rider being randomly initialized). We fine-tune this model for 4k iterations in which the learning rate is reduced at 3k iterations, which takes 1 hour for training given the COCO model.
Cityscapes 数据集的一个主要挑战是在低数据制度下训练模型,特别是对分别约有 200–500 个训练样本的 truck、bus 与 train 类别。为部分缓解这一问题,我们进一步报告使用 COCO 预训练的结果。为此,我们从预训练的 COCO Mask R-CNN 模型初始化 Cityscapes 中对应的 7 个类别(rider 随机初始化)。我们把该模型微调 4k 次迭代,其中学习率在 3k 次迭代时降低,给定 COCO 模型后训练约需 1 小时。
The COCO pre-trained Mask R-CNN model achieves 32.0 AP on test, almost a 6 point improvement over the fine-only counterpart. This indicates the important role the amount of training data plays. It also suggests that methods on Cityscapes might be influenced by their low-shot learning performance. We show that using COCO pre-training is an effective strategy on this dataset.
COCO 预训练的 Mask R-CNN 模型在 test 上达到 32.0 AP,比仅用 fine 的对应版本几乎提升 6 点。这表明训练数据量起着重要作用。它还暗示 Cityscapes 上的方法可能受其少样本学习性能影响。我们表明使用 COCO 预训练是该数据集上的有效策略。
Finally, we observed a bias between the val and test AP, as is also observed from the results of [23, 4, 29]. We found that this bias is mainly caused by the truck, bus, and train categories, with the fine-only model having val/test AP of 28.8/22.8, 53.5/32.2, and 33.0/18.6, respectively. This suggests that there is a domain shift on these categories, which also have little training data. COCO pre-training helps to improve results the most on these categories; however, the domain shift persists with 38.0/30.1, 57.5/40.9, and 41.2/30.9 val/test AP, respectively. Note that for the person and car categories we do not see any such bias (val/test AP are within point).
最后,我们观察到 val 与 test AP 之间存在偏差,这在 [23, 4, 29] 的结果中也能看到。我们发现这一偏差主要来自 truck、bus 与 train 类别,仅用 fine 的模型 val/test AP 分别为 28.8/22.8、53.5/32.2 与 33.0/18.6。这表明这些类别存在域偏移,且训练数据也很少。COCO 预训练在这些类别上帮助最大;然而域偏移仍然存在,val/test AP 分别为 38.0/30.1、57.5/40.9 与 41.2/30.9。注意对 person 与 car 类别我们看不到这种偏差(val/test AP 在 点以内)。
Example results on Cityscapes are shown in Figure 8.
Cityscapes 上的示例结果见图 8。
Appendix B: Enhanced Results on COCO
附录 B:COCO 上的增强结果
As a general framework, Mask R-CNN is compatible with complementary techniques developed for detection/segmentation, including improvements made to Fast/Faster R-CNN and FCNs. In this appendix we describe some techniques that improve over our original results. Thanks to its generality and flexibility, Mask R-CNN was used as the framework by the three winning teams in the COCO 2017 instance segmentation competition, which all significantly outperformed the previous state of the art.
作为一个通用框架,Mask R-CNN 与为检测/分割开发的互补技术兼容,包括对 Fast/Faster R-CNN 与 FCN 的改进。在本附录中我们描述一些改进原始结果的技术。由于其通用性与灵活性,Mask R-CNN 被 COCO 2017 实例分割竞赛的三个获胜团队用作框架,它们都显著超过了既往最先进水平。
| description | backbone | AP | AP50 | AP75 | AP | AP | AP |
|---|---|---|---|---|---|---|---|
| original baseline | X-101-FPN | 36.7 | 59.5 | 38.9 | 39.6 | 61.5 | 43.2 |
| updated baseline | X-101-FPN | 37.0 | 59.7 | 39.0 | 40.5 | 63.0 | 43.7 |
| e2e training | X-101-FPN | 37.6 | 60.4 | 39.9 | 41.7 | 64.1 | 45.2 |
| ImageNet-5k | X-101-FPN | 38.6 | 61.7 | 40.9 | 42.7 | 65.1 | 46.6 |
| train-time augm. | X-101-FPN | 39.2 | 62.5 | 41.6 | 43.5 | 65.9 | 47.2 |
| deeper | X-152-FPN | 39.7 | 63.2 | 42.2 | 44.1 | 66.4 | 48.4 |
| Non-local [43] | X-152-FPN-NL | 40.3 | 64.4 | 42.8 | 45.0 | 67.8 | 48.9 |
| test-time augm. | X-152-FPN-NL | 41.8 | 66.0 | 44.8 | 47.3 | 69.3 | 51.5 |
Table 8: Enhanced detection results of Mask R-CNN on COCO minival. Each row adds an extra component to the above row. We denote ResNeXt model by ‘X’ for notational brevity.
| description | backbone | AP | AP50 | AP75 | AP | AP | AP |
|---|---|---|---|---|---|---|---|
| original baseline | X-101-FPN | 36.7 | 59.5 | 38.9 | 39.6 | 61.5 | 43.2 |
| updated baseline | X-101-FPN | 37.0 | 59.7 | 39.0 | 40.5 | 63.0 | 43.7 |
| e2e training | X-101-FPN | 37.6 | 60.4 | 39.9 | 41.7 | 64.1 | 45.2 |
| ImageNet-5k | X-101-FPN | 38.6 | 61.7 | 40.9 | 42.7 | 65.1 | 46.6 |
| train-time augm. | X-101-FPN | 39.2 | 62.5 | 41.6 | 43.5 | 65.9 | 47.2 |
| deeper | X-152-FPN | 39.7 | 63.2 | 42.2 | 44.1 | 66.4 | 48.4 |
| Non-local [43] | X-152-FPN-NL | 40.3 | 64.4 | 42.8 | 45.0 | 67.8 | 48.9 |
| test-time augm. | X-152-FPN-NL | 41.8 | 66.0 | 44.8 | 47.3 | 69.3 | 51.5 |
表 8:Mask R-CNN 在 COCO minival 上的增强检测结果。每一行在上一行基础上增加一个额外组件。为简洁起见,我们用 ‘X’ 表示 ResNeXt 模型。
Instance Segmentation and Object Detection
实例分割与物体检测
We report some enhanced results of Mask R-CNN in Table 8. Overall, the improvements increase mask AP 5.1 points (from 36.7 to 41.8) and box AP 7.7 points (from 39.6 to 47.3). Each model improvement increases both mask AP and box AP consistently, showing good generalization of the Mask R-CNN framework. We detail the improvements next. These results, along with future updates, can be reproduced by our released code at https://github.com/facebookresearch/Detectron, and can serve as higher baselines for future research.
我们在表 8 中报告 Mask R-CNN 的一些增强结果。总体而言,这些改进把掩码 AP 提高 5.1 点(从 36.7 到 41.8),框 AP 提高 7.7 点(从 39.6 到 47.3)。每项模型改进都一致地提升掩码 AP 与框 AP,显示 Mask R-CNN 框架良好的泛化性。我们接下来详述这些改进。这些结果以及未来更新可由我们发布的代码在 https://github.com/facebookresearch/Detectron 复现,并可作为未来研究的更高基线。
Updated baseline: We start with an updated baseline with a different set of hyper-parameters. We lengthen the training to 180k iterations, in which the learning rate is reduced by 10 at 120k and 160k iterations. We also change the NMS threshold to 0.5 (from a default value of 0.3). The updated baseline has 37.0 mask AP and 40.5 box AP.
更新基线: 我们从一组不同超参数的更新基线开始。我们把训练延长到 180k 次迭代,其中学习率在 120k 与 160k 次迭代时除以 10。我们还把 NMS 阈值改为 0.5(默认值 0.3)。更新基线有 37.0 掩码 AP 与 40.5 框 AP。
End-to-end training: All previous results used stage-wise training, i.e., training RPN as the first stage and Mask R-CNN as the second. Following [37], we evaluate end-to-end (‘e2e’) training that jointly trains RPN and Mask R-CNN. We adopt the ‘approximate’ version in [37] that only computes partial gradients in the RoIAlign layer by ignoring the gradient w.r.t. RoI coordinates. Table 8 shows that e2e training improves mask AP by 0.6 and box AP by 1.2.
端到端训练: 先前所有结果都使用分阶段训练,即先训练 RPN 作为第一阶段,再训练 Mask R-CNN 作为第二阶段。遵循 [37],我们评估联合训练 RPN 与 Mask R-CNN 的端到端(‘e2e’)训练。我们采用 [37] 中的‘近似’版本,在 RoIAlign 层中只计算部分梯度,忽略关于 RoI 坐标的梯度。表 8 显示 e2e 训练把掩码 AP 提高 0.6,框 AP 提高 1.2。
ImageNet-5k pre-training: Following [45], we experiment with models pre-trained on a 5k-class subset of ImageNet (in contrast to the standard 1k-class subset). This 5 increase in pre-training data improves both mask and box 1 AP. As a reference, [40] used 250 more images (300M) and reported a 2-3 box AP improvement on their baselines.
ImageNet-5k 预训练: 遵循 [45],我们用在 ImageNet 的 5k 类子集(相对于标准 1k 类子集)上预训练的模型做实验。预训练数据增加 5 倍使掩码与框各提升约 1 AP。作为参考,[40] 使用了约 250 倍更多图像(300M),并在其基线上报告了 2–3 框 AP 提升。
Train-time augmentation: Scale augmentation at train time further improves results. During training, we randomly sample a scale from [640, 800] pixels and we increase the number of iterations to 260k (with the learning rate reduced by 10 at 200k and 240k iterations). Train-time augmentation improves mask AP by 0.6 and box AP by 0.8.
训练时增强: 训练时的尺度增强进一步改进结果。训练期间,我们从 [640, 800] 像素随机采样尺度,并把迭代次数增加到 260k(学习率在 200k 与 240k 次迭代时除以 10)。训练时增强把掩码 AP 提高 0.6,框 AP 提高 0.8。
Model architecture: By upgrading the 101-layer ResNeXt to its 152-layer counterpart [19], we observe an increase of 0.5 mask AP and 0.6 box AP. This shows a deeper model can still improve results on COCO.
模型架构: 把 101 层 ResNeXt 升级到其 152 层对应版本 [19],我们观察到掩码 AP 增加 0.5、框 AP 增加 0.6。这表明更深模型仍能在 COCO 上改进结果。
Using the recently proposed non-local (NL) model [43], we achieve 40.3 mask AP and 45.0 box AP. This result is without test-time augmentation, and the method runs at 3fps on an Nvidia Tesla P100 GPU at test time.
使用近来提出的非局部(NL)模型 [43],我们达到 40.3 掩码 AP 与 45.0 框 AP。该结果不加测试时增强,方法在 Nvidia Tesla P100 GPU 上测试时以 3 fps 运行。
Test-time augmentation: We combine the model results evaluated using scales of [400, 1200] pixels with a step of 100 and on their horizontal flips. This gives us a single-model result of 41.8 mask AP and 47.3 box AP.
测试时增强: 我们结合用步长 100、尺度 [400, 1200] 像素及其水平翻转评估的模型结果。这给出单模型结果 41.8 掩码 AP 与 47.3 框 AP。
The above result is the foundation of our submission to the COCO 2017 competition (which also used an ensemble, not discussed here). The first three winning teams for the instance segmentation task were all reportedly based on an extension of the Mask R-CNN framework.
上述结果是我们提交 COCO 2017 竞赛的基础(竞赛中还使用了集成,此处不讨论)。据报告,实例分割任务的前三名获胜团队都基于 Mask R-CNN 框架的扩展。
| description | backbone | AP | AP | AP | AP | AP |
|---|---|---|---|---|---|---|
| original baseline | R-50-FPN | 64.2 | 86.6 | 69.7 | 58.7 | 73.0 |
| updated baseline | R-50-FPN | 65.1 | 86.6 | 70.9 | 59.9 | 73.6 |
| deeper | R-101-FPN | 66.1 | 87.7 | 71.7 | 60.5 | 75.0 |
| ResNeXt | X-101-FPN | 67.3 | 88.0 | 73.3 | 62.2 | 75.6 |
| data distillation [35] | X-101-FPN | 69.1 | 88.9 | 75.3 | 64.1 | 77.1 |
| test-time augm. | X-101-FPN | 70.4 | 89.3 | 76.8 | 65.8 | 78.1 |
Table 9: Enhanced keypoint results of Mask R-CNN on COCO minival. Each row adds an extra component to the above row. Here we use only keypoint annotations but no mask annotations. We denote ResNet by ‘R’ and ResNeXt by ‘X’ for brevity.
| description | backbone | AP | AP | AP | AP | AP |
|---|---|---|---|---|---|---|
| original baseline | R-50-FPN | 64.2 | 86.6 | 69.7 | 58.7 | 73.0 |
| updated baseline | R-50-FPN | 65.1 | 86.6 | 70.9 | 59.9 | 73.6 |
| deeper | R-101-FPN | 66.1 | 87.7 | 71.7 | 60.5 | 75.0 |
| ResNeXt | X-101-FPN | 67.3 | 88.0 | 73.3 | 62.2 | 75.6 |
| data distillation [35] | X-101-FPN | 69.1 | 88.9 | 75.3 | 64.1 | 77.1 |
| test-time augm. | X-101-FPN | 70.4 | 89.3 | 76.8 | 65.8 | 78.1 |
表 9:Mask R-CNN 在 COCO minival 上的增强关键点结果。每一行在上一行基础上增加一个额外组件。这里我们只用关键点标注,不用掩码标注。为简洁起见,用 ‘R’ 表示 ResNet,‘X’ 表示 ResNeXt。
Keypoint Detection
关键点检测
We report enhanced results of keypoint detection in Table 9. As an updated baseline, we extend the training schedule to 130k iterations in which the learning rate is reduced by 10 at 100k and 120k iterations. This improves AP by about 1 point. Replacing ResNet-50 with ResNet-101 and ResNeXt-101 increases AP to 66.1 and 67.3, respectively.
我们在表 9 中报告关键点检测的增强结果。作为更新基线,我们把训练日程延长到 130k 次迭代,其中学习率在 100k 与 120k 次迭代时除以 10。这把 AP 提高约 1 点。把 ResNet-50 替换为 ResNet-101 与 ResNeXt-101,分别把 AP 提高到 66.1 与 67.3。
With a recent method called data distillation [35], we are able to exploit the additional 120k unlabeled images provided by COCO. In brief, data distillation is a self-training strategy that uses a model trained on labeled data to predict annotations on unlabeled images, and in turn updates the model with these new annotations. Mask R-CNN provides an effective framework for such a self-training strategy. With data distillation, Mask R-CNN AP improve by 1.8 points to 69.1. We observe that Mask R-CNN can benefit from extra data, even if that data is unlabeled.
借助近来称作数据蒸馏 [35] 的方法,我们能够利用 COCO 提供的额外 120k 未标注图像。简言之,数据蒸馏是一种自训练策略:用在有标注数据上训练的模型预测未标注图像上的标注,再用这些新标注更新模型。Mask R-CNN 为这种自训练策略提供了有效框架。有了数据蒸馏,Mask R-CNN 的 AP 提高 1.8 点到 69.1。我们观察到,即使额外数据是未标注的,Mask R-CNN 也能从中受益。
By using the same test-time augmentation as used for instance segmentation, we further boost AP to 70.4.
通过使用与实例分割相同的测试时增强,我们进一步把 AP 提升到 70.4。
Acknowledgements:
We would like to acknowledge Ilija Radosavovic for contributions to code release and enhanced results, and the Caffe2 team for engineering support.
致谢:
我们感谢 Ilija Radosavovic 对代码发布与增强结果的贡献,以及 Caffe2 团队的工程支持。
References
参考文献
[1] M. Andriluka, L. Pishchulin, P. Gehler, and B. Schiele. 2D human pose estimation: New benchmark and state of the art analysis. In CVPR, 2014.
[2] P. Arbeláez, J. Pont-Tuset, J. T. Barron, F. Marques, and J. Malik. Multiscale combinatorial grouping. In CVPR, 2014.
[3] A. Arnab and P. H. Torr. Pixelwise instance segmentation with a dynamically instantiated network. In CVPR, 2017.
[4] M. Bai and R. Urtasun. Deep watershed transform for instance segmentation. In CVPR, 2017.
[5] S. Bell, C. L. Zitnick, K. Bala, and R. Girshick. Inside-outside net: Detecting objects in context with skip pooling and recurrent neural networks. In CVPR, 2016.
[6] Z. Cao, T. Simon, S.-E. Wei, and Y. Sheikh. Realtime multi-person 2d pose estimation using part affinity fields. In CVPR, 2017.
[7] M. Cordts, M. Omran, S. Ramos, T. Rehfeld, M. Enzweiler, R. Benenson, U. Franke, S. Roth, and B. Schiele. The Cityscapes dataset for semantic urban scene understanding. In CVPR, 2016.
[8] J. Dai, K. He, Y. Li, S. Ren, and J. Sun. Instance-sensitive fully convolutional networks. In ECCV, 2016.
[9] J. Dai, K. He, and J. Sun. Convolutional feature masking for joint object and stuff segmentation. In CVPR, 2015.
[10] J. Dai, K. He, and J. Sun. Instance-aware semantic segmentation via multi-task network cascades. In CVPR, 2016.
[11] J. Dai, Y. Li, K. He, and J. Sun. R-FCN: Object detection via region-based fully convolutional networks. In NIPS, 2016.
[12] R. Girshick. Fast R-CNN. In ICCV, 2015.
[13] R. Girshick, J. Donahue, T. Darrell, and J. Malik. Rich feature hierarchies for accurate object detection and semantic segmentation. In CVPR, 2014.
[14] R. Girshick, F. Iandola, T. Darrell, and J. Malik. Deformable part models are convolutional neural networks. In CVPR, 2015.
[15] B. Hariharan, P. Arbeláez, R. Girshick, and J. Malik. Simultaneous detection and segmentation. In ECCV. 2014.
[16] B. Hariharan, P. Arbeláez, R. Girshick, and J. Malik. Hypercolumns for object segmentation and fine-grained localization. In CVPR, 2015.
[17] Z. Hayder, X. He, and M. Salzmann. Shape-aware instance segmentation. In CVPR, 2017.
[18] K. He, X. Zhang, S. Ren, and J. Sun. Spatial pyramid pooling in deep convolutional networks for visual recognition. In ECCV. 2014.
[19] K. He, X. Zhang, S. Ren, and J. Sun. Deep residual learning for image recognition. In CVPR, 2016.
[20] J. Hosang, R. Benenson, P. Dollár, and B. Schiele. What makes for effective detection proposals? PAMI, 2015.
[21] J. Huang, V. Rathod, C. Sun, M. Zhu, A. Korattikara, A. Fathi, I. Fischer, Z. Wojna, Y. Song, S. Guadarrama, et al. Speed/accuracy trade-offs for modern convolutional object detectors. In CVPR, 2017.
[22] M. Jaderberg, K. Simonyan, A. Zisserman, and K. Kavukcuoglu. Spatial transformer networks. In NIPS, 2015.
[23] A. Kirillov, E. Levinkov, B. Andres, B. Savchynskyy, and C. Rother. Instancecut: from edges to instances with multicut. In CVPR, 2017.
[24] A. Krizhevsky, I. Sutskever, and G. Hinton. ImageNet classification with deep convolutional neural networks. In NIPS, 2012.
[25] Y. LeCun, B. Boser, J. S. Denker, D. Henderson, R. E. Howard, W. Hubbard, and L. D. Jackel. Backpropagation applied to handwritten zip code recognition. Neural computation, 1989.
[26] Y. Li, H. Qi, J. Dai, X. Ji, and Y. Wei. Fully convolutional instance-aware semantic segmentation. In CVPR, 2017.
[27] T.-Y. Lin, P. Dollár, R. Girshick, K. He, B. Hariharan, and S. Belongie. Feature pyramid networks for object detection. In CVPR, 2017.
[28] T.-Y. Lin, M. Maire, S. Belongie, J. Hays, P. Perona, D. Ramanan, P. Dollár, and C. L. Zitnick. Microsoft COCO: Common objects in context. In ECCV, 2014.
[29] S. Liu, J. Jia, S. Fidler, and R. Urtasun. SGN: Sequential grouping networks for instance segmentation. In ICCV, 2017.
[30] J. Long, E. Shelhamer, and T. Darrell. Fully convolutional networks for semantic segmentation. In CVPR, 2015.
[31] V. Nair and G. E. Hinton. Rectified linear units improve restricted boltzmann machines. In ICML, 2010.
[32] G. Papandreou, T. Zhu, N. Kanazawa, A. Toshev, J. Tompson, C. Bregler, and K. Murphy. Towards accurate multi-person pose estimation in the wild. In CVPR, 2017.
[33] P. O. Pinheiro, R. Collobert, and P. Dollar. Learning to segment object candidates. In NIPS, 2015.
[34] P. O. Pinheiro, T.-Y. Lin, R. Collobert, and P. Dollár. Learning to refine object segments. In ECCV, 2016.
[35] I. Radosavovic, P. Dollár, R. Girshick, G. Gkioxari, and K. He. Data distillation: Towards omni-supervised learning. arXiv:1712.04440, 2017.
[36] S. Ren, K. He, R. Girshick, and J. Sun. Faster R-CNN: Towards real-time object detection with region proposal networks. In NIPS, 2015.
[37] S. Ren, K. He, R. Girshick, and J. Sun. Faster R-CNN: Towards real-time object detection with region proposal networks. In TPAMI, 2017.
[38] A. Shrivastava, A. Gupta, and R. Girshick. Training region-based object detectors with online hard example mining. In CVPR, 2016.
[39] A. Shrivastava, R. Sukthankar, J. Malik, and A. Gupta. Beyond skip connections: Top-down modulation for object detection. arXiv:1612.06851, 2016.
[40] C. Sun, A. Shrivastava, S. Singh, and A. Gupta. Revisiting unreasonable effectiveness of data in deep learning era. In ICCV, 2017.
[41] C. Szegedy, S. Ioffe, and V. Vanhoucke. Inception-v4, inception-resnet and the impact of residual connections on learning. In ICLR Workshop, 2016.
[42] J. R. Uijlings, K. E. van de Sande, T. Gevers, and A. W. Smeulders. Selective search for object recognition. IJCV, 2013.
[43] X. Wang, R. Girshick, A. Gupta, and K. He. Non-local neural networks. arXiv:1711.07971, 2017.
[44] S.-E. Wei, V. Ramakrishna, T. Kanade, and Y. Sheikh. Convolutional pose machines. In CVPR, 2016.
[45] S. Xie, R. Girshick, P. Dollár, Z. Tu, and K. He. Aggregated residual transformations for deep neural networks. In CVPR, 2017.