Model-Agnostic Meta-Learning for Fast Adaptation of Deep Networks
Model-Agnostic Meta-Learning for Fast Adaptation of Deep Networks
模型无关元学习:深度网络的快速适应
Chelsea Finn Affiliation: University of California, Berkeley Correspondence to: cbfinn@eecs.berkeley.edu Pieter Abbeel Affiliation: University of California, Berkeley Affiliation: OpenAI Sergey Levine Affiliation: University of California, Berkeley
Abstract
摘要
We propose an algorithm for meta-learning that is model-agnostic, in the sense that it is compatible with any model trained with gradient descent and applicable to a variety of different learning problems, including classification, regression, and reinforcement learning. The goal of meta-learning is to train a model on a variety of learning tasks, such that it can solve new learning tasks using only a small number of training samples. In our approach, the parameters of the model are explicitly trained such that a small number of gradient steps with a small amount of training data from a new task will produce good generalization performance on that task. In effect, our method trains the model to be easy to fine-tune. We demonstrate that this approach leads to state-of-the-art performance on two few-shot image classification benchmarks, produces good results on few-shot regression, and accelerates fine-tuning for policy gradient reinforcement learning with neural network policies.
我们提出一种模型无关的元学习算法:凡可用梯度下降训练的模型均可配合,并适用于分类、回归与强化学习等多种问题。元学习的目标是在多种学习任务上训练模型,使其仅用少量训练样本就能解决新任务。我们的做法是显式训练模型参数,使在新任务上用少量数据做少量梯度步后,即可在该任务上获得良好泛化。效果上,方法把模型训成易于微调。我们证明该方法在两个小样本图像分类基准上达到当时前沿,在小样本回归上表现良好,并能加速带神经网络策略的策略梯度强化学习微调。
1 Introduction
1 引言
Keywords:
Learning quickly is a hallmark of human intelligence, whether it involves recognizing objects from a few examples or quickly learning new skills after just minutes of experience. Our artificial agents should be able to do the same, learning and adapting quickly from only a few examples, and continuing to adapt as more data becomes available. This kind of fast and flexible learning is challenging, since the agent must integrate its prior experience with a small amount of new information, while avoiding overfitting to the new data. Furthermore, the form of prior experience and new data will depend on the task. As such, for the greatest applicability, the mechanism for learning to learn (or meta-learning) should be general to the task and the form of computation required to complete the task.
关键词:
快速学习是人类智能的标志:无论是从少量例子识别物体,还是仅几分钟经验就学会新技能。人工智能体也应如此,只凭少量例子快速学习与适应,并随数据增多继续适应。这种快速灵活学习很难:智能体必须把先验经验与少量新信息结合,同时避免对新数据过拟合。先验经验与新数据的形式还取决于任务。因此,为获得最大适用性,「学会学习」(元学习)机制应对任务与完成任务所需的计算形式都保持通用。
In this work, we propose a meta-learning algorithm that is general and model-agnostic, in the sense that it can be directly applied to any learning problem and model that is trained with a gradient descent procedure. Our focus is on deep neural network models, but we illustrate how our approach can easily handle different architectures and different problem settings, including classification, regression, and policy gradient reinforcement learning, with minimal modification. In meta-learning, the goal of the trained model is to quickly learn a new task from a small amount of new data, and the model is trained by the meta-learner to be able to learn on a large number of different tasks. The key idea underlying our method is to train the model’s initial parameters such that the model has maximal performance on a new task after the parameters have been updated through one or more gradient steps computed with a small amount of data from that new task. Unlike prior meta-learning methods that learn an update function or learning rule (Schmidhuber 1987; Bengio et al. 1992; Andrychowicz et al. 2016; Ravi & Larochelle 2017), our algorithm does not expand the number of learned parameters nor place constraints on the model architecture (e.g. by requiring a recurrent model (Santoro et al. 2016) or a Siamese network (Koch 2015)), and it can be readily combined with fully connected, convolutional, or recurrent neural networks. It can also be used with a variety of loss functions, including differentiable supervised losses and non-differentiable reinforcement learning objectives.
本文提出一种通用且模型无关的元学习算法:可直接用于任何用梯度下降训练的学习问题与模型。我们聚焦深度神经网络,但说明该方法稍作修改即可处理不同架构与问题设定,包括分类、回归与策略梯度强化学习。元学习中,训练好的模型目标是从少量新数据快速学会新任务;元学习器则在大量不同任务上训练该能力。核心想法是训练模型的初始参数,使在新任务上用少量数据做一到多步梯度更新后性能最大。与学习更新函数或学习规则的先前元学习方法不同(Schmidhuber 1987;Bengio et al. 1992;Andrychowicz et al. 2016;Ravi & Larochelle 2017),我们的算法不增加所学参数数量,也不约束模型架构(例如不要求循环模型(Santoro et al. 2016)或孪生网络(Koch 2015)),可直接与全连接、卷积或循环网络结合,也可用多种损失函数,包括可微监督损失与不可微强化学习目标。
The process of training a model’s parameters such that a few gradient steps, or even a single gradient step, can produce good results on a new task can be viewed from a feature learning standpoint as building an internal representation that is broadly suitable for many tasks. If the internal representation is suitable to many tasks, simply fine-tuning the parameters slightly (e.g. by primarily modifying the top layer weights in a feedforward model) can produce good results. In effect, our procedure optimizes for models that are easy and fast to fine-tune, allowing the adaptation to happen in the right space for fast learning. From a dynamical systems standpoint, our learning process can be viewed as maximizing the sensitivity of the loss functions of new tasks with respect to the parameters: when the sensitivity is high, small local changes to the parameters can lead to large improvements in the task loss.
把模型参数训成「少量甚至单步梯度即可在新任务上取得好结果」,从特征学习角度看,是在构建对许多任务都大致合适的内部表示。若内部表示适用面广,只需略微微调参数(例如主要改前馈模型顶层权重)就能得到好结果。效果上,我们的过程优化「易且快可微调」的模型,让适应发生在利于快速学习的空间。从动力系统角度看,学习过程可视为最大化新任务损失对参数的敏感度:敏感度高时,参数的小局部变化即可大幅改善任务损失。
The primary contribution of this work is a simple model- and task-agnostic algorithm for meta-learning that trains a model’s parameters such that a small number of gradient updates will lead to fast learning on a new task. We demonstrate the algorithm on different model types, including fully connected and convolutional networks, and in several distinct domains, including few-shot regression, image classification, and reinforcement learning. Our evaluation shows that our meta-learning algorithm compares favorably to state-of-the-art one-shot learning methods designed specifically for supervised classification, while using fewer parameters, but that it can also be readily applied to regression and can accelerate reinforcement learning in the presence of task variability, substantially outperforming direct pretraining as initialization.
本文主要贡献是一种简单的模型与任务无关元学习算法:训练模型参数,使少量梯度更新即可在新任务上快速学习。我们在全连接与卷积等不同模型类型上,以及小样本回归、图像分类与强化学习等不同领域演示该算法。评估表明,相对专为监督分类设计的前沿单样本学习方法,我们的元学习算法表现相当或更好且参数更少,同时又可直接用于回归,并能在任务多变时加速强化学习,显著优于把直接预训练当初始化。
2 Model-Agnostic Meta-Learning
2 模型无关元学习
We aim to train models that can achieve rapid adaptation, a problem setting that is often formalized as few-shot learning. In this section, we will define the problem setup and present the general form of our algorithm.
我们旨在训练能快速适应的模型;该问题设定常形式化为小样本学习。本节定义问题设定并给出算法的一般形式。
2.1 Meta-Learning Problem Set-Up
2.1 元学习问题设定
The goal of few-shot meta-learning is to train a model that can quickly adapt to a new task using only a few datapoints and training iterations. To accomplish this, the model or learner is trained during a meta-learning phase on a set of tasks, such that the trained model can quickly adapt to new tasks using only a small number of examples or trials. In effect, the meta-learning problem treats entire tasks as training examples. In this section, we formalize this meta-learning problem setting in a general manner, including brief examples of different learning domains. We will discuss two different learning domains in detail in Section 3.
小样本元学习的目标是训练能仅用少量数据点与训练迭代就快速适应新任务的模型。为此,模型或学习器在元学习阶段于一组任务上训练,使训好的模型仅用少量例子或试验就能快速适应新任务。效果上,元学习问题把整个任务当作训练样本。本节以一般方式形式化该设定,并给出不同学习领域的简例。第 3 节将详细讨论两个不同学习领域。
We consider a model, denoted , that maps observations to outputs . During meta-learning, the model is trained to be able to adapt to a large or infinite number of tasks. Since we would like to apply our framework to a variety of learning problems, from classification to reinforcement learning, we introduce a generic notion of a learning task below. Formally, each task consists of a loss function , a distribution over initial observations , a transition distribution , and an episode length . In i.i.d. supervised learning problems, the length . The model may generate samples of length by choosing an output at each time . The loss , provides task-specific feedback, which might be in the form of a misclassification loss or a cost function in a Markov decision process.
考虑模型 ,把观测 映射到输出 。元学习阶段训练模型以能适应大量乃至无穷多任务。由于希望框架覆盖从分类到强化学习的多种问题,下面引入通用的学习任务概念。形式地,每个任务 由损失函数 、初始观测分布 、转移分布 与片段长度 组成。在 i.i.d. 监督学习中长度 。模型可在每个时刻 选择输出 以生成长度 的样本。损失 提供任务特定反馈,形式可以是误分类损失或马尔可夫决策过程中的代价函数。
In our meta-learning scenario, we consider a distribution over tasks that we want our model to be able to adapt to. In the -shot learning setting, the model is trained to learn a new task drawn from from only samples drawn from and feedback generated by . During meta-training, a task is sampled from , the model is trained with samples and feedback from the corresponding loss from , and then tested on new samples from . The model is then improved by considering how the test error on new data from changes with respect to the parameters. In effect, the test error on sampled tasks serves as the training error of the meta-learning process. At the end of meta-training, new tasks are sampled from , and meta-performance is measured by the model’s performance after learning from samples. Generally, tasks used for meta-testing are held out during meta-training.
在我们的元学习场景中,考虑希望模型能适应的任务分布 。在 -shot 设定下,模型被训练成:仅用从 抽出的 个样本以及由 产生的反馈 ,就学会从 抽出的新任务 。元训练时,从 采样任务 ,用 个样本与对应损失 训练模型,再在 的新样本上测试。随后根据相对参数的测试误差如何变化来改进模型 。效果上,采样任务 上的测试误差充当元学习过程的训练误差。元训练结束时,再从 采样新任务,用学完 个样本后的模型表现度量元性能。一般地,元测试所用任务在元训练中留出。
2.2 A Model-Agnostic Meta-Learning Algorithm
2.2 模型无关元学习算法
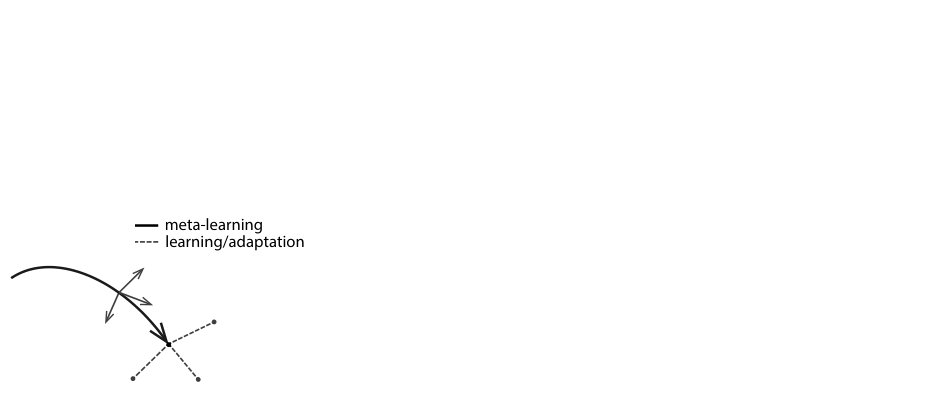
Figure 1: Diagram of our model-agnostic meta-learning algorithm (MAML), which optimizes for a representation that can quickly adapt to new tasks.
图 1:我们的模型无关元学习算法(MAML)示意图:优化可快速适应新任务的表示 。
In contrast to prior work, which has sought to train recurrent neural networks that ingest entire datasets (Santoro et al. 2016; Duan et al. 2016b) or feature embeddings that can be combined with nonparametric methods at test time (Vinyals et al. 2016; Koch 2015), we propose a method that can learn the parameters of any standard model via meta-learning in such a way as to prepare that model for fast adaptation. The intuition behind this approach is that some internal representations are more transferrable than others. For example, a neural network might learn internal features that are broadly applicable to all tasks in , rather than a single individual task. How can we encourage the emergence of such general-purpose representations? We take an explicit approach to this problem: since the model will be fine-tuned using a gradient-based learning rule on a new task, we will aim to learn a model in such a way that this gradient-based learning rule can make rapid progress on new tasks drawn from , without overfitting. In effect, we will aim to find model parameters that are sensitive to changes in the task, such that small changes in the parameters will produce large improvements on the loss function of any task drawn from , when altered in the direction of the gradient of that loss (see Figure 1). We make no assumption on the form of the model, other than to assume that it is parametrized by some parameter vector , and that the loss function is smooth enough in that we can use gradient-based learning techniques.
相对先前工作——训练吞下整份数据集的循环网络(Santoro et al. 2016;Duan et al. 2016b),或学习可在测试时与非参数方法结合的特征嵌入(Vinyals et al. 2016;Koch 2015)——我们提出一种方法:经由元学习得到任何标准模型的参数,使该模型为快速适应做好准备。直觉是:有些内部表示比另一些更可迁移。例如,网络可能学到对 中所有任务都大致适用的内部特征,而非只服务单个任务。如何鼓励这种通用表示出现?我们采取显式做法:既然模型会在新任务上用基于梯度的学习规则微调,我们就以「该规则能在从 抽取的新任务上快速进步且不过拟合」为目标来学习模型。效果上,我们寻找对任务变化敏感的模型参数:沿该任务损失的梯度方向稍改参数,就能大幅改善从 抽出的任一任务的损失(见图 1)。除假设模型由参数向量 参数化、且损失对 足够光滑以便用基于梯度的学习外,我们不对模型形式作假设。
Formally, we consider a model represented by a parametrized function with parameters . When adapting to a new task , the model’s parameters become . In our method, the updated parameter vector is computed using one or more gradient descent updates on task . For example, when using one gradient update,
形式地,考虑由参数化函数 表示、参数为 的模型。适应新任务 时,模型参数 变为 。在我们的方法中,更新后的参数向量 通过对任务 做一到多步梯度下降得到。例如,使用单次梯度更新时,
The step size may be fixed as a hyperparameter or meta-learned. For simplicity of notation, we will consider one gradient update for the rest of this section, but using multiple gradient updates is a straightforward extension.
步长 可作为超参数固定,也可被元学习。为记号简洁,本节余下只考虑一次梯度更新;使用多次梯度更新是直接推广。
The model parameters are trained by optimizing for the performance of with respect to across tasks sampled from . More concretely, the meta-objective is as follows:
模型参数通过优化 相对 、在从 采样的任务上的表现来训练。更具体地,元目标如下:
Note that the meta-optimization is performed over the model parameters , whereas the objective is computed using the updated model parameters . In effect, our proposed method aims to optimize the model parameters such that one or a small number of gradient steps on a new task will produce maximally effective behavior on that task.
注意元优化针对模型参数 进行,而目标用更新后的模型参数 计算。效果上,所提方法旨在优化模型参数,使在新任务上做一到少量梯度步即可产生该任务上尽可能有效的行为。
The meta-optimization across tasks is performed via stochastic gradient descent (SGD), such that the model parameters are updated as follows:
跨任务的元优化通过随机梯度下降(SGD)进行,模型参数 更新如下:
where is the meta step size. The full algorithm, in the general case, is outlined in Algorithm 1.
其中 为元步长。一般情形下的完整算法见算法 1。
0: : distribution over tasks
0: , : step size hyperparameters
1: randomly initialize
2: while not done do
3: Sample batch of tasks
4: for all do
5: Evaluate with respect to examples
6: Compute adapted parameters with gradient descent:
7: end for
8: Update
9: end while
Algorithm 1 Model-Agnostic Meta-Learning
0: :任务分布
0: ,:步长超参数
1: 随机初始化
2: while 未完成 do
3: 从 采样一批任务
4: for all do
5: 用 个例子计算
6: 用梯度下降计算适应参数:
7: end for
8: 更新
9: end while
算法 1 模型无关元学习
The MAML meta-gradient update involves a gradient through a gradient. Computationally, this requires an additional backward pass through to compute Hessian-vector products, which is supported by standard deep learning libraries such as TensorFlow (Abadi et al. 2016). In our experiments, we also include a comparison to dropping this backward pass and using a first-order approximation, which we discuss in Section 5.2.
MAML 的元梯度更新涉及「梯度的梯度」。计算上需要额外对 做一次反向传播以计算 Hessian–向量积,这由 TensorFlow(Abadi et al. 2016)等标准深度学习库支持。实验中我们也对比了丢掉这次反向传播、改用一阶近似的做法,见第 5.2 节。
3 Species of MAML
3 MAML 的具体形态
In this section, we discuss specific instantiations of our meta-learning algorithm for supervised learning and reinforcement learning. The domains differ in the form of loss function and in how data is generated by the task and presented to the model, but the same basic adaptation mechanism can be applied in both cases.
本节讨论元学习算法在监督学习与强化学习上的具体实例化。两领域在损失函数形式、任务如何生成数据并呈现给模型上不同,但同一基本适应机制均可应用。
3.1 Supervised Regression and Classification
3.1 监督回归与分类
Few-shot learning is well-studied in the domain of supervised tasks, where the goal is to learn a new function from only a few input/output pairs for that task, using prior data from similar tasks for meta-learning. For example, the goal might be to classify images of a Segway after seeing only one or a few examples of a Segway, with a model that has previously seen many other types of objects. Likewise, in few-shot regression, the goal is to predict the outputs of a continuous-valued function from only a few datapoints sampled from that function, after training on many functions with similar statistical properties.
小样本学习在监督任务领域研究充分:目标是仅用该任务的少量输入/输出对学会新函数,并利用来自相似任务的先验数据做元学习。例如,模型先前见过许多其他物体后,只看一个或几个赛格威例子就要学会分类赛格威图像。同样,小样本回归的目标是:在训过许多统计性质相似的函数后,仅用从某连续值函数采样的少量数据点预测其输出。
To formalize the supervised regression and classification problems in the context of the meta-learning definitions in Section 2.1, we can define the horizon and drop the timestep subscript on , since the model accepts a single input and produces a single output, rather than a sequence of inputs and outputs. The task generates i.i.d. observations from , and the task loss is represented by the error between the model’s output for and the corresponding target values for that observation and task.
为在第 2.1 节元学习定义下形式化监督回归与分类,可定义地平线 并去掉 的时间下标,因为模型接受单个输入并产生单个输出,而非输入输出序列。任务 从 生成 个 i.i.d. 观测 ,任务损失由模型对 的输出与该观测及任务对应的目标值 之间的误差表示。
Two common loss functions used for supervised classification and regression are cross-entropy and mean-squared error (MSE), which we will describe below; though, other supervised loss functions may be used as well. For regression tasks using mean-squared error, the loss takes the form:
监督分类与回归常用的两种损失是交叉熵与均方误差(MSE),下文描述;也可使用其他监督损失。对使用均方误差的回归任务,损失形式为:
where are an input/output pair sampled from task . In -shot regression tasks, input/output pairs are provided for learning for each task.
其中 是从任务 采样的输入/输出对。在 -shot 回归中,每个任务提供 个输入/输出对用于学习。
Similarly, for discrete classification tasks with a cross-entropy loss, the loss takes the form:
类似地,对带交叉熵损失的离散分类任务,损失形式为:
According to the conventional terminology, -shot classification tasks use input/output pairs from each class, for a total of data points for -way classification. Given a distribution over tasks , these loss functions can be directly inserted into the equations in Section 2.2 to perform meta-learning, as detailed in Algorithm 2.
按惯用术语,-shot 分类对每个类使用 个输入/输出对,-way 分类共 个数据点。给定任务分布 ,这些损失可直接代入第 2.2 节公式做元学习,详见算法 2。
0: : distribution over tasks
0: , : step size hyperparameters
1: randomly initialize
2: while not done do
3: Sample batch of tasks
4: for all do
5: Sample datapoints from
6: Evaluate using and in Equation (2) or (3)
7: Compute adapted parameters with gradient descent:
8: Sample datapoints from for the meta-update
9: end for
10: Update using each and in Equation 2 or 3
11: end while
Algorithm 2 MAML for Few-Shot Supervised Learning
0: :任务分布
0: ,:步长超参数
1: 随机初始化
2: while 未完成 do
3: 从 采样一批任务
4: for all do
5: 从 采样 个数据点
6: 用 与公式 (2) 或 (3) 中的 计算
7: 用梯度下降计算适应参数:
8: 从 再采样数据点 供元更新
9: end for
10: 用每个 与公式 2 或 3 中的 更新
11: end while
算法 2 面向小样本监督学习的 MAML
3.2 Reinforcement Learning
3.2 强化学习
In reinforcement learning (RL), the goal of few-shot meta-learning is to enable an agent to quickly acquire a policy for a new test task using only a small amount of experience in the test setting. A new task might involve achieving a new goal or succeeding on a previously trained goal in a new environment. For example, an agent might learn to quickly figure out how to navigate mazes so that, when faced with a new maze, it can determine how to reliably reach the exit with only a few samples. In this section, we will discuss how MAML can be applied to meta-learning for RL.
在强化学习(RL)中,小样本元学习的目标是让智能体仅用测试设定中的少量经验就快速获得新测试任务的策略。新任务可能是达成新目标,或在新环境中完成先前训练过的目标。例如,智能体可学会快速搞清如何走迷宫,从而面对新迷宫时只凭少量样本就可靠到达出口。本节讨论如何把 MAML 用于 RL 的元学习。
Each RL task contains an initial state distribution and a transition distribution , and the loss corresponds to the (negative) reward function . The entire task is therefore a Markov decision process (MDP) with horizon , where the learner is allowed to query a limited number of sample trajectories for few-shot learning. Any aspect of the MDP may change across tasks in . The model being learned, , is a policy that maps from states to a distribution over actions at each timestep . The loss for task and model takes the form
每个 RL 任务 含初始状态分布 与转移分布 ,损失 对应(负)奖励函数 。整个任务因此是地平线为 的马尔可夫决策过程(MDP),学习器被允许查询有限数量的样本轨迹做小样本学习。 中各任务的 MDP 任一方面都可变化。所学模型 是策略:在每个时刻 把状态 映射到动作 的分布。任务 与模型 的损失形式为
In -shot reinforcement learning, rollouts from and task , , and the corresponding rewards , may be used for adaptation on a new task . Since the expected reward is generally not differentiable due to unknown dynamics, we use policy gradient methods to estimate the gradient both for the model gradient update(s) and the meta-optimization. Since policy gradients are an on-policy algorithm, each additional gradient step during the adaptation of requires new samples from the current policy . We detail the algorithm in Algorithm 3. This algorithm has the same structure as Algorithm 2, with the principal difference being that steps 5 and 8 require sampling trajectories from the environment corresponding to task . Practical implementations of this method may also use a variety of improvements recently proposed for policy gradient algorithms, including state or action-dependent baselines and trust regions (Schulman et al. 2015).
在 -shot 强化学习中,可用来自 与任务 的 条 rollout 及对应奖励 在新任务 上做适应。由于未知动力学,期望奖励一般不可微,我们用策略梯度方法估计模型梯度更新与元优化的梯度。策略梯度是同策略算法,适应 时每多一步梯度都需要从当前策略 采新样本。算法细节见算法 3。结构与算法 2 相同,主要差别是第 5、8 步需从对应任务 的环境采样轨迹。实践实现还可采用策略梯度算法近期提出的多种改进,包括状态或动作相关基线与信赖域(Schulman et al. 2015)。
0: : distribution over tasks
0: , : step size hyperparameters
1: randomly initialize
2: while not done do
3: Sample batch of tasks
4: for all do
5: Sample trajectories using in
6: Evaluate using and in Equation 4
7: Compute adapted parameters with gradient descent:
8: Sample trajectories using in
9: end for
10: Update using each and in Equation 4
11: end while
Algorithm 3 MAML for Reinforcement Learning
0: :任务分布
0: ,:步长超参数
1: 随机初始化
2: while 未完成 do
3: 从 采样一批任务
4: for all do
5: 用 在 中采样 条轨迹
6: 用 与公式 4 中的 计算
7: 用梯度下降计算适应参数:
8: 用 在 中采样轨迹
9: end for
10: 用每个 与公式 4 中的 更新
11: end while
算法 3 面向强化学习的 MAML
4 Related Work
4 相关工作
The method that we propose in this paper addresses the general problem of meta-learning (Thrun & Pratt 1998; Schmidhuber 1987; Naik & Mammone 1992), which includes few-shot learning. A popular approach for meta-learning is to train a meta-learner that learns how to update the parameters of the learner’s model (Bengio et al. 1992; Schmidhuber 1992; Bengio et al. 1990). This approach has been applied to learning to optimize deep networks (Hochreiter et al. 2001; Andrychowicz et al. 2016; Li & Malik 2017), as well as for learning dynamically changing recurrent networks (Ha et al. 2017). One recent approach learns both the weight initialization and the optimizer, for few-shot image recognition (Ravi & Larochelle 2017). Unlike these methods, the MAML learner’s weights are updated using the gradient, rather than a learned update; our method does not introduce additional parameters for meta-learning nor require a particular learner architecture.
本文方法面向元学习的一般问题(Thrun & Pratt 1998;Schmidhuber 1987;Naik & Mammone 1992),其中包括小样本学习。流行做法是训练元学习器去学习如何更新学习器模型的参数(Bengio et al. 1992;Schmidhuber 1992;Bengio et al. 1990)。该方法已用于学习优化深度网络(Hochreiter et al. 2001;Andrychowicz et al. 2016;Li & Malik 2017),以及学习动态变化的循环网络(Ha et al. 2017)。近期一种方法同时学习权重初始化与优化器,用于小样本图像识别(Ravi & Larochelle 2017)。与这些方法不同,MAML 学习器的权重用梯度更新,而非学到的更新;我们的方法不为元学习引入额外参数,也不要求特定学习器架构。
Few-shot learning methods have also been developed for specific tasks such as generative modeling (Edwards & Storkey 2017; Rezende et al. 2016) and image recognition (Vinyals et al. 2016). One successful approach for few-shot classification is to learn to compare new examples in a learned metric space using e.g. Siamese networks (Koch 2015) or recurrence with attention mechanisms (Vinyals et al. 2016; Shyam et al. 2017; Snell et al. 2017). These approaches have generated some of the most successful results, but are difficult to directly extend to other problems, such as reinforcement learning. Our method, in contrast, is agnostic to the form of the model and to the particular learning task.
针对生成建模(Edwards & Storkey 2017;Rezende et al. 2016)与图像识别(Vinyals et al. 2016)等具体任务,也发展了小样本学习方法。小样本分类的成功路径之一是在学到的度量空间中比较新例子,例如用孪生网络(Koch 2015)或带注意力的循环(Vinyals et al. 2016;Shyam et al. 2017;Snell et al. 2017)。这些方法取得了一些最成功的结果,但难以直接扩展到强化学习等问题。相比之下,我们的方法对模型形式与具体学习任务均无关。
Another approach to meta-learning is to train memory-augmented models on many tasks, where the recurrent learner is trained to adapt to new tasks as it is rolled out. Such networks have been applied to few-shot image recognition (Santoro et al. 2016; Munkhdalai & Yu 2017) and learning “fast” reinforcement learning agents (Duan et al. 2016b; Wang et al. 2016). Our experiments show that our method outperforms the recurrent approach on few-shot classification. Furthermore, unlike these methods, our approach simply provides a good weight initialization and uses the same gradient descent update for both the learner and meta-update. As a result, it is straightforward to finetune the learner for additional gradient steps.
另一类元学习是在许多任务上训练记忆增强模型,循环学习器在展开时被训练去适应新任务。这类网络已用于小样本图像识别(Santoro et al. 2016;Munkhdalai & Yu 2017)以及学习「快速」强化学习智能体(Duan et al. 2016b;Wang et al. 2016)。实验表明我们的方法在小样本分类上优于循环方法。此外,与这些方法不同,我们的方法只提供良好权重初始化,并在学习器与元更新中使用同一梯度下降更新,因此易于再为额外梯度步微调学习器。
Our approach is also related to methods for initialization of deep networks. In computer vision, models pretrained on large-scale image classification have been shown to learn effective features for a range of problems (Donahue et al. 2014). In contrast, our method explicitly optimizes the model for fast adaptability, allowing it to adapt to new tasks with only a few examples. Our method can also be viewed as explicitly maximizing sensitivity of new task losses to the model parameters. A number of prior works have explored sensitivity in deep networks, often in the context of initialization (Saxe et al. 2014; Kirkpatrick et al. 2016). Most of these works have considered good random initializations, though a number of papers have addressed data-dependent initializers (Krähenbühl et al. 2016; Salimans & Kingma 2016), including learned initializations (Husken & Goerick 2000; Maclaurin et al. 2015). In contrast, our method explicitly trains the parameters for sensitivity on a given task distribution, allowing for extremely efficient adaptation for problems such as -shot learning and rapid reinforcement learning in only one or a few gradient steps.
我们的方法也与深度网络初始化相关。计算机视觉中,在大规模图像分类上预训练的模型已被证明能为一系列问题学到有效特征(Donahue et al. 2014)。相比之下,我们的方法显式优化模型以便快速适应,使其仅用少量例子就能适应新任务。也可把方法视为显式最大化新任务损失对模型参数的敏感度。已有若干工作探索深度网络中的敏感度,常在初始化语境下(Saxe et al. 2014;Kirkpatrick et al. 2016)。多数考虑良好随机初始化,也有论文讨论数据依赖初始化(Krähenbühl et al. 2016;Salimans & Kingma 2016),包括学到的初始化(Husken & Goerick 2000;Maclaurin et al. 2015)。相比之下,我们的方法在给定任务分布上显式训练参数的敏感度,使 -shot 学习与仅一到几步梯度的快速强化学习等问题能极高效适应。
5 Experimental Evaluation
5 实验评估

Figure 2: Few-shot adaptation for the simple regression task. Left: Note that MAML is able to estimate parts of the curve where there are no datapoints, indicating that the model has learned about the periodic structure of sine waves. Right: Fine-tuning of a model pretrained on the same distribution of tasks without MAML, with a tuned step size. Due to the often contradictory outputs on the pre-training tasks, this model is unable to recover a suitable representation and fails to extrapolate from the small number of test-time samples.
图 2:简单回归任务上的小样本适应。左:注意 MAML 能估计没有数据点的曲线部分,表明模型已学到正弦波的周期结构。右:在同一任务分布上预训练但未用 MAML 的模型微调,步长经调优。由于预训练任务上输出往往相互矛盾,该模型无法恢复合适表示,也难以从少量测试时样本外推。
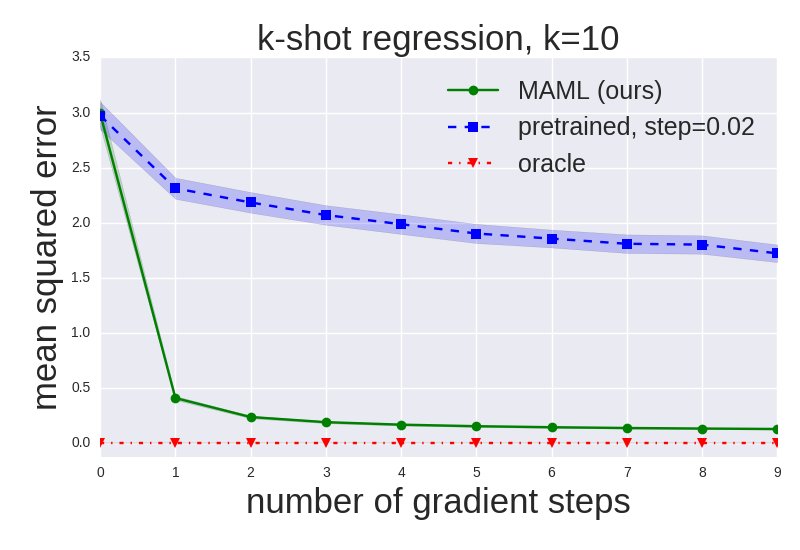
Figure 3: Quantitative sinusoid regression results showing the learning curve at meta test-time. Note that MAML continues to improve with additional gradient steps without overfitting to the extremely small dataset during meta-testing, achieving a loss that is substantially lower than the baseline fine-tuning approach.
图 3:正弦回归定量结果,展示元测试时的学习曲线。注意 MAML 在元测试期间用额外梯度步继续改进且不过拟合极小数据集,损失远低于基线微调方法。
The goal of our experimental evaluation is to answer the following questions: (1) Can MAML enable fast learning of new tasks? (2) Can MAML be used for meta-learning in multiple different domains, including supervised regression, classification, and reinforcement learning? (3) Can a model learned with MAML continue to improve with additional gradient updates and/or examples?
实验评估旨在回答:(1) MAML 能否实现新任务的快速学习?(2) MAML 能否用于多个不同领域的元学习,包括监督回归、分类与强化学习?(3) 用 MAML 学到的模型能否随额外梯度更新和/或例子继续改进?
All of the meta-learning problems that we consider require some amount of adaptation to new tasks at test-time. When possible, we compare our results to an oracle that receives the identity of the task (which is a problem-dependent representation) as an additional input, as an upper bound on the performance of the model. All of the experiments were performed using TensorFlow (Abadi et al. 2016), which allows for automatic differentiation through the gradient update(s) during meta-learning. The code is available online[^1].
我们考虑的全部元学习问题都需要在测试时对新任务做一定适应。可能时,我们与接收任务身份(问题相关表示)作为额外输入的预言机对比,作为模型性能上界。全部实验用 TensorFlow(Abadi et al. 2016)完成,可在元学习期间对梯度更新自动微分。代码在线可用[^1]。
5.1 Regression
5.1 回归
We start with a simple regression problem that illustrates the basic principles of MAML. Each task involves regressing from the input to the output of a sine wave, where the amplitude and phase of the sinusoid are varied between tasks. Thus, is continuous, where the amplitude varies within and the phase varies within , and the input and output both have a dimensionality of . During training and testing, datapoints are sampled uniformly from . The loss is the mean-squared error between the prediction and true value. The regressor is a neural network model with hidden layers of size with ReLU nonlinearities. When training with MAML, we use one gradient update with examples with a fixed step size , and use Adam as the meta-optimizer (Kingma & Ba 2015). The baselines are likewise trained with Adam. To evaluate performance, we fine-tune a single meta-learned model on varying numbers of examples, and compare performance to two baselines: (a) pretraining on all of the tasks, which entails training a network to regress to random sinusoid functions and then, at test-time, fine-tuning with gradient descent on the provided points, using an automatically tuned step size, and (b) an oracle which receives the true amplitude and phase as input. In Appendix C, we show comparisons to additional multi-task and adaptation methods.
我们从说明 MAML 基本原理的简单回归问题开始。每个任务是把输入回归到正弦波输出,振幅与相位在任务间变化。于是 连续:振幅在 、相位在 ,输入与输出维数均为 1。训练与测试时, 从 均匀采样。损失为预测 与真值的均方误差。回归器为带 2 个隐层、每层 40 单元、ReLU 非线性的神经网络。用 MAML 训练时,用 个例子做一次梯度更新,固定步长 ,元优化器用 Adam(Kingma & Ba 2015)。基线同样用 Adam 训练。评估时,在不同数量的 个例子上微调单个元学习模型,并与两个基线对比:(a) 在所有任务上预训练——即训练网络回归随机正弦函数,测试时在 个给定点上用自动调好的步长做梯度下降微调;(b) 接收真振幅与相位作为输入的预言机。附录 C 给出与更多多任务及适应方法的对比。
We evaluate performance by fine-tuning the model learned by MAML and the pretrained model on datapoints. During fine-tuning, each gradient step is computed using the same datapoints. The qualitative results, shown in Figure 2 and further expanded on in Appendix B show that the learned model is able to quickly adapt with only datapoints, shown as purple triangles, whereas the model that is pretrained using standard supervised learning on all tasks is unable to adequately adapt with so few datapoints without catastrophic overfitting. Crucially, when the datapoints are all in one half of the input range, the model trained with MAML can still infer the amplitude and phase in the other half of the range, demonstrating that the MAML trained model has learned to model the periodic nature of the sine wave. Furthermore, we observe both in the qualitative and quantitative results (Figure 3 and Appendix B) that the model learned with MAML continues to improve with additional gradient steps, despite being trained for maximal performance after one gradient step. This improvement suggests that MAML optimizes the parameters such that they lie in a region that is amenable to fast adaptation and is sensitive to loss functions from , as discussed in Section 2.2, rather than overfitting to parameters that only improve after one step.
我们在 个数据点上微调 MAML 学到的模型与预训练模型以评估性能。微调时每步梯度用同一组 个数据点计算。图 2 及附录 B 的定性结果显示:学到的模型仅用 5 个数据点(紫色三角)就能快速适应,而在所有任务上用标准监督学习预训练的模型在如此少的数据点下无法充分适应且易灾难性过拟合。关键的是,当 个数据点都落在输入范围的一半时,MAML 训练的模型仍能推断另一半的振幅与相位,说明 已学会建模正弦波的周期性。此外,定性与定量结果(图 3 与附录 B)都显示:尽管按单步梯度后的最大性能训练,MAML 学到的模型仍随额外梯度步继续改进。这表明 MAML 把参数优化到利于快速适应、并对 中损失敏感的区域(见第 2.2 节),而非过拟合到只在一步后才改进的参数 。
5.2 Classification
5.2 分类
| 5-way Accuracy | 20-way Accuracy | |||
|---|---|---|---|---|
| Omniglot (Lake et al. 2011) | 1-shot | 5-shot | 1-shot | 5-shot |
| MANN, no conv (Santoro et al. 2016) | – | – | ||
| MAML, no conv (ours) | – | – | ||
| Siamese nets (Koch 2015) | ||||
| matching nets (Vinyals et al. 2016) | ||||
| neural statistician (Edwards & Storkey 2017) | ||||
| memory mod. (Kaiser et al. 2017) | ||||
| MAML (ours) |
| 5-way Accuracy | ||
|---|---|---|
| MiniImagenet (Ravi & Larochelle 2017) | 1-shot | 5-shot |
| fine-tuning baseline | ||
| nearest neighbor baseline | ||
| matching nets (Vinyals et al. 2016) | ||
| meta-learner LSTM (Ravi & Larochelle 2017) | ||
| MAML, first order approx. (ours) | ||
| MAML (ours) |
Table 1: Few-shot classification on held-out Omniglot characters (top) and the MiniImagenet test set (bottom). MAML achieves results that are comparable to or outperform state-of-the-art convolutional and recurrent models. Siamese nets, matching nets, and the memory module approaches are all specific to classification, and are not directly applicable to regression or RL scenarios. The shows confidence intervals over tasks. Note that the Omniglot results may not be strictly comparable since the train/test splits used in the prior work were not available. The MiniImagenet evaluation of baseline methods and matching networks is from Ravi & Larochelle 2017.
| 5-way 精度 | 20-way 精度 | |||
|---|---|---|---|---|
| Omniglot(Lake et al. 2011) | 1-shot | 5-shot | 1-shot | 5-shot |
| MANN, no conv(Santoro et al. 2016) | – | – | ||
| MAML, no conv(本文) | – | – | ||
| Siamese nets(Koch 2015) | ||||
| matching nets(Vinyals et al. 2016) | ||||
| neural statistician(Edwards & Storkey 2017) | ||||
| memory mod.(Kaiser et al. 2017) | ||||
| MAML(本文) |
| 5-way 精度 | ||
|---|---|---|
| MiniImagenet(Ravi & Larochelle 2017) | 1-shot | 5-shot |
| fine-tuning baseline | ||
| nearest neighbor baseline | ||
| matching nets(Vinyals et al. 2016) | ||
| meta-learner LSTM(Ravi & Larochelle 2017) | ||
| MAML, first order approx.(本文) | ||
| MAML(本文) |
表 1:在留出 Omniglot 字符(上)与 MiniImagenet 测试集(下)上的小样本分类。MAML 达到与前沿卷积及循环模型相当或更好的结果。孪生网络、匹配网络与记忆模块方法均专为分类,不能直接用于回归或 RL。 为跨任务 95% 置信区间。注意 Omniglot 结果未必严格可比,因先前工作的训练/测试划分不可得。基线与匹配网络的 MiniImagenet 评估来自 Ravi & Larochelle 2017。
To evaluate MAML in comparison to prior meta-learning and few-shot learning algorithms, we applied our method to few-shot image recognition on the Omniglot (Lake et al. 2011) and MiniImagenet datasets. The Omniglot dataset consists of 20 instances of 1623 characters from 50 different alphabets. Each instance was drawn by a different person. The MiniImagenet dataset was proposed by Ravi & Larochelle 2017, and involves 64 training classes, 12 validation classes, and 24 test classes. The Omniglot and MiniImagenet image recognition tasks are the most common recently used few-shot learning benchmarks (Vinyals et al. 2016; Santoro et al. 2016; Ravi & Larochelle 2017). We follow the experimental protocol proposed by Vinyals et al. 2016, which involves fast learning of -way classification with 1 or 5 shots. The problem of -way classification is set up as follows: select unseen classes, provide the model with different instances of each of the classes, and evaluate the model’s ability to classify new instances within the classes. For Omniglot, we randomly select characters for training, irrespective of alphabet, and use the remaining for testing. The Omniglot dataset is augmented with rotations by multiples of degrees, as proposed by Santoro et al. 2016.
为把 MAML 与先前元学习及小样本学习算法对比,我们在 Omniglot(Lake et al. 2011)与 MiniImagenet 数据集上做小样本图像识别。Omniglot 含 50 种字母表共 1623 个字符,每字符 20 个实例,各由不同人书写。MiniImagenet 由 Ravi & Larochelle 2017 提出,含 64 训练类、12 验证类、24 测试类。Omniglot 与 MiniImagenet 图像识别是近来最常用的小样本学习基准(Vinyals et al. 2016;Santoro et al. 2016;Ravi & Larochelle 2017)。我们遵循 Vinyals et al. 2016 的实验协议:在 1 或 5 shot 下快速学习 -way 分类。-way 分类设定为:选 个未见类,给模型每类 个不同实例,评估其在这 类内对新实例分类的能力。对 Omniglot,我们随机选 1200 个字符训练(不论字母表),其余测试。按 Santoro et al. 2016 建议,用 90 度倍数旋转增强 Omniglot。
Our model follows the same architecture as the embedding function used by Vinyals et al. 2016, which has 4 modules with a convolutions and filters, followed by batch normalization (Ioffe & Szegedy 2015), a ReLU nonlinearity, and max-pooling. The Omniglot images are downsampled to , so the dimensionality of the last hidden layer is . As in the baseline classifier used by Vinyals et al. 2016, the last layer is fed into a softmax. For Omniglot, we used strided convolutions instead of max-pooling. For MiniImagenet, we used filters per layer to reduce overfitting, as done by (Ravi & Larochelle 2017). In order to also provide a fair comparison against memory-augmented neural networks (Santoro et al. 2016) and to test the flexibility of MAML, we also provide results for a non-convolutional network. For this, we use a network with hidden layers with sizes , , , , each including batch normalization and ReLU nonlinearities, followed by a linear layer and softmax. For all models, the loss function is the cross-entropy error between the predicted and true class. Additional hyperparameter details are included in Appendix A.1.
模型架构与 Vinyals et al. 2016 所用嵌入函数相同:4 个模块,各含 卷积与 64 个滤波器,后接批归一化(Ioffe & Szegedy 2015)、ReLU 与 最大池化。Omniglot 图像下采样到 ,最后隐层维数为 64。与 Vinyals et al. 2016 的基线分类器一样,最后一层接 softmax。对 Omniglot 用跨步卷积代替最大池化。对 MiniImagenet,按(Ravi & Larochelle 2017)每层用 32 个滤波器以减轻过拟合。为公平对比记忆增强网络(Santoro et al. 2016)并测试 MAML 灵活性,我们也给出非卷积网络结果:4 个隐层规模 256、128、64、64,各含批归一化与 ReLU,后接线性层与 softmax。所有模型损失为预测类与真类之间的交叉熵。更多超参见附录 A.1。
We present the results in Table 1. The convolutional model learned by MAML compares well to the state-of-the-art results on this task, narrowly outperforming the prior methods. Some of these existing methods, such as matching networks, Siamese networks, and memory models are designed with few-shot classification in mind, and are not readily applicable to domains such as reinforcement learning. Additionally, the model learned with MAML uses fewer overall parameters compared to matching networks and the meta-learner LSTM, since the algorithm does not introduce any additional parameters beyond the weights of the classifier itself. Compared to these prior methods, memory-augmented neural networks (Santoro et al. 2016) specifically, and recurrent meta-learning models in general, represent a more broadly applicable class of methods that, like MAML, can be used for other tasks such as reinforcement learning (Duan et al. 2016b; Wang et al. 2016). However, as shown in the comparison, MAML significantly outperforms memory-augmented networks and the meta-learner LSTM on 5-way Omniglot and MiniImagenet classification, both in the -shot and -shot case.
结果见表 1。MAML 学到的卷积模型在该任务上与当时前沿结果相当,略优于先前方法。匹配网络、孪生网络、记忆模型等现有方法专为小样本分类设计,不易直接用于强化学习等领域。此外,MAML 学到的模型总体参数少于匹配网络与元学习器 LSTM,因算法在分类器权重之外不引入额外参数。相对这些先前方法,记忆增强网络(Santoro et al. 2016)以及一般的循环元学习模型代表更广适用的一类方法,与 MAML 一样可用于强化学习等任务(Duan et al. 2016b;Wang et al. 2016)。但对比显示,在 5-way Omniglot 与 MiniImagenet 分类的 1-shot 与 5-shot 情形下,MAML 均显著优于记忆增强网络与元学习器 LSTM。
A significant computational expense in MAML comes from the use of second derivatives when backpropagating the meta-gradient through the gradient operator in the meta-objective (see Equation (1)). On MiniImagenet, we show a comparison to a first-order approximation of MAML, where these second derivatives are omitted. Note that the resulting method still computes the meta-gradient at the post-update parameter values , which provides for effective meta-learning. Surprisingly however, the performance of this method is nearly the same as that obtained with full second derivatives, suggesting that most of the improvement in MAML comes from the gradients of the objective at the post-update parameter values, rather than the second order updates from differentiating through the gradient update. Past work has observed that ReLU neural networks are locally almost linear (Goodfellow et al. 2015), which suggests that second derivatives may be close to zero in most cases, partially explaining the good performance of the first-order approximation. This approximation removes the need for computing Hessian-vector products in an additional backward pass, which we found led to roughly speed-up in network computation.
MAML 的显著计算开销来自:把元梯度反向传播穿过元目标中的梯度算子时使用二阶导数(见公式 (1))。在 MiniImagenet 上,我们对比省略这些二阶导的一阶近似。注意所得方法仍在更新后参数值 处计算元梯度,从而仍能有效元学习。出人意料的是,该方法性能几乎与完整二阶导数相同,表明 MAML 的大部分改进来自更新后参数处目标的梯度,而非穿过梯度更新的二阶项。先前工作观察到 ReLU 网络局部几乎线性(Goodfellow et al. 2015),暗示二阶导多数情况下接近零,部分解释了一阶近似的良好表现。该近似去掉额外反向传播中的 Hessian–向量积,我们发现网络计算大约加速 33%。
5.3 Reinforcement Learning
5.3 强化学习
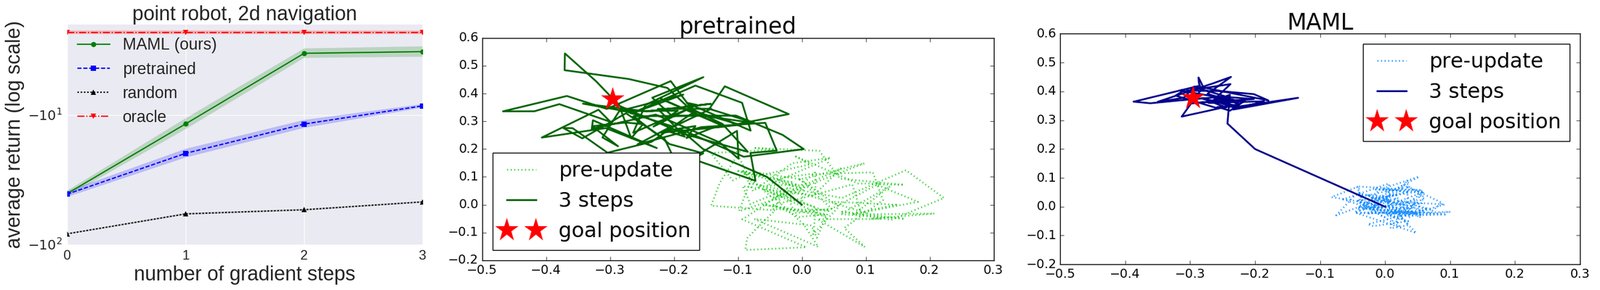
Figure 4: Top: quantitative results from 2D navigation task, Bottom: qualitative comparison between model learned with MAML and with fine-tuning from a pretrained network.
图 4:上:2D 导航任务定量结果;下:MAML 学到的模型与从预训练网络微调的定性对比。
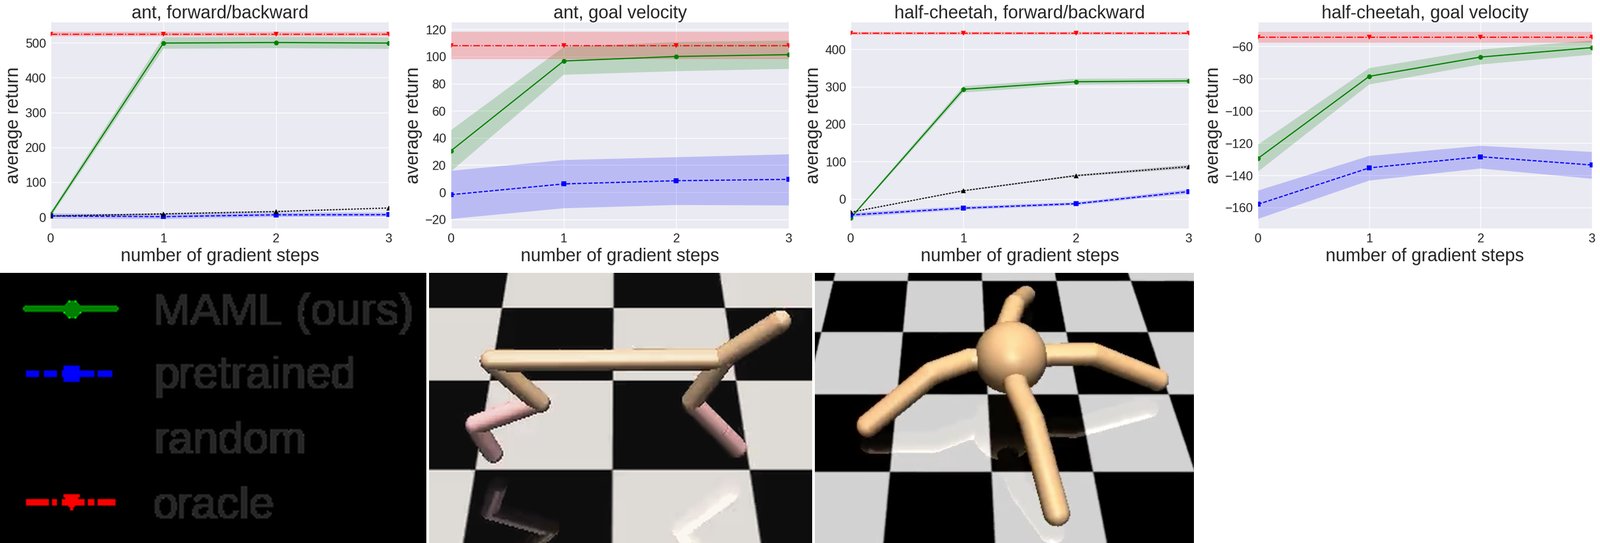
Figure 5: Reinforcement learning results for the half-cheetah and ant locomotion tasks, with the tasks shown on the far right. Each gradient step requires additional samples from the environment, unlike the supervised learning tasks. The results show that MAML can adapt to new goal velocities and directions substantially faster than conventional pretraining or random initialization, achieving good performs in just two or three gradient steps. We exclude the goal velocity, random baseline curves, since the returns are much worse ( for cheetah and for ant).
图 5:半猎豹与蚂蚁运动任务的强化学习结果,任务示于最右。与监督学习任务不同,每步梯度需要环境额外样本。结果显示 MAML 适应新目标速度与方向远快于常规预训练或随机初始化,仅两到三步梯度即可达到良好表现。我们未画出目标速度随机基线曲线,因其回报差得多(猎豹 ,蚂蚁 )。
To evaluate MAML on reinforcement learning problems, we constructed several sets of tasks based off of the simulated continuous control environments in the rllab benchmark suite (Duan et al. 2016a). We discuss the individual domains below. In all of the domains, the model trained by MAML is a neural network policy with two hidden layers of size , with ReLU nonlinearities. The gradient updates are computed using vanilla policy gradient (REINFORCE) (Williams 1992), and we use trust-region policy optimization (TRPO) as the meta-optimizer (Schulman et al. 2015). In order to avoid computing third derivatives, we use finite differences to compute the Hessian-vector products for TRPO. For both learning and meta-learning updates, we use the standard linear feature baseline proposed by Duan et al. 2016a, which is fitted separately at each iteration for each sampled task in the batch. We compare to three baseline models: (a) pretraining one policy on all of the tasks and then fine-tuning, (b) training a policy from randomly initialized weights, and (c) an oracle policy which receives the parameters of the task as input, which for the tasks below corresponds to a goal position, goal direction, or goal velocity for the agent. The baseline models of (a) and (b) are fine-tuned with gradient descent with a manually tuned step size. Videos of the learned policies can be viewed at sites.google.com/view/maml
为在强化学习问题上评估 MAML,我们基于 rllab 基准套件(Duan et al. 2016a)中的仿真连续控制环境构造若干任务集。下文分别讨论各领域。所有领域中,MAML 训练的模型均为两隐层、每层 100、ReLU 非线性的神经网络策略。梯度更新用原始策略梯度(REINFORCE)(Williams 1992),元优化器用信赖域策略优化(TRPO)(Schulman et al. 2015)。为避免计算三阶导,用有限差分计算 TRPO 的 Hessian–向量积。学习与元学习更新均使用 Duan et al. 2016a 提出的标准线性特征基线,对批中每个采样任务在每次迭代单独拟合。对比三个基线模型:(a) 在所有任务上预训练一个策略再微调;(b) 从随机初始化权重训练策略;(c) 接收任务参数作为输入的预言机策略——对下列任务即智能体的目标位置、目标方向或目标速度。基线 (a)(b) 用手动调好的步长做梯度下降微调。学到的策略视频见 sites.google.com/view/maml
2D Navigation. In our first meta-RL experiment, we study a set of tasks where a point agent must move to different goal positions in 2D, randomly chosen for each task within a unit square. The observation is the current 2D position, and actions correspond to velocity commands clipped to be in the range . The reward is the negative squared distance to the goal, and episodes terminate when the agent is within of the goal or at the horizon of . The policy was trained with MAML to maximize performance after policy gradient update using trajectories. Additional hyperparameter settings for this problem and the following RL problems are in Appendix A.2. In our evaluation, we compare adaptation to a new task with up to 4 gradient updates, each with samples. The results in Figure 4 show the adaptation performance of models that are initialized with MAML, conventional pretraining on the same set of tasks, random initialization, and an oracle policy that receives the goal position as input. The results show that MAML can learn a model that adapts much more quickly in a single gradient update, and furthermore continues to improve with additional updates.
二维导航。 第一个元 RL 实验中,点智能体须移到 2D 中不同目标位置,每个任务在单位正方形内随机选取。观测为当前 2D 位置,动作为裁剪到 的速度指令。奖励为到目标的负平方距离,智能体距目标 0.01 内或到达地平线 时终止。策略用 MAML 训练,以 20 条轨迹做 1 次策略梯度更新后的性能最大化。该问题及后续 RL 问题的更多超参见附录 A.2。评估中,我们对比最多 4 次梯度更新(每次 40 样本)对新任务的适应。图 4 显示以 MAML、同任务集常规预训练、随机初始化以及接收目标位置的预言机策略初始化的模型适应性能。结果表明 MAML 能学到在单次梯度更新中适应快得多的模型,并随额外更新继续改进。
Locomotion. To study how well MAML can scale to more complex deep RL problems, we also study adaptation on high-dimensional locomotion tasks with the MuJoCo simulator (Todorov et al. 2012). The tasks require two simulated robots – a planar cheetah and a 3D quadruped (the “ant”) – to run in a particular direction or at a particular velocity. In the goal velocity experiments, the reward is the negative absolute value between the current velocity of the agent and a goal, which is chosen uniformly at random between and for the cheetah and between and for the ant. In the goal direction experiments, the reward is the magnitude of the velocity in either the forward or backward direction, chosen at random for each task in . The horizon is , with rollouts per gradient step for all problems except the ant forward/backward task, which used rollouts per step. The results in Figure 5 show that MAML learns a model that can quickly adapt its velocity and direction with even just a single gradient update, and continues to improve with more gradient steps. The results also show that, on these challenging tasks, the MAML initialization substantially outperforms random initialization and pretraining. In fact, pretraining is in some cases worse than random initialization, a fact observed in prior RL work (Parisotto et al. 2016).
运动控制。 为研究 MAML 如何扩展到更复杂的深度 RL 问题,我们还在 MuJoCo 仿真器(Todorov et al. 2012)的高维运动任务上研究适应。任务要求两个仿真机器人——平面猎豹与三维四足(「蚂蚁」)——沿特定方向或以特定速度奔跑。目标速度实验中,奖励为智能体当前速度与目标的负绝对差,猎豹目标在 0.0 与 2.0 间均匀随机,蚂蚁在 0.0 与 3.0 间。目标方向实验中,奖励为前向或后向速度的幅度,每个任务在 中随机选取方向。地平线 ,除蚂蚁前/后任务每步用 40 条 rollout 外,其余问题每步梯度用 20 条。图 5 显示 MAML 学到的模型仅用单次梯度更新就能快速适应速度与方向,并随更多梯度步继续改进。结果还表明,在这些挑战性任务上,MAML 初始化显著优于随机初始化与预训练。事实上,预训练有时比随机初始化更差,先前 RL 工作也观察到这一点(Parisotto et al. 2016)。
6 Discussion and Future Work
6 讨论与未来工作
We introduced a meta-learning method based on learning easily adaptable model parameters through gradient descent. Our approach has a number of benefits. It is simple and does not introduce any learned parameters for meta-learning. It can be combined with any model representation that is amenable to gradient-based training, and any differentiable objective, including classification, regression, and reinforcement learning. Lastly, since our method merely produces a weight initialization, adaptation can be performed with any amount of data and any number of gradient steps, though we demonstrate state-of-the-art results on classification with only one or five examples per class. We also show that our method can adapt an RL agent using policy gradients and a very modest amount of experience.
我们提出一种基于梯度下降学习易于适应的模型参数的元学习方法。方法有若干优点:简单,不为元学习引入任何学到的参数;可与任何适于基于梯度训练的模型表示、任何可微目标结合,包括分类、回归与强化学习;最后,由于方法仅产出权重初始化,可用任意数据量与任意梯度步数做适应,尽管我们在每类仅一或五个例子的分类上已展示当时前沿结果。我们还表明方法可用策略梯度与非常有限的经验适应 RL 智能体。
Reusing knowledge from past tasks may be a crucial ingredient in making high-capacity scalable models, such as deep neural networks, amenable to fast training with small datasets. We believe that this work is one step toward a simple and general-purpose meta-learning technique that can be applied to any problem and any model. Further research in this area can make multitask initialization a standard ingredient in deep learning and reinforcement learning.
复用过去任务的知识,可能是让高容量可扩展模型(如深度神经网络)能在小数据集上快速训练的关键要素。我们认为本工作朝向一种可应用于任何问题与任何模型的简单通用元学习技术迈出一步。该领域进一步研究可使多任务初始化成为深度学习与强化学习的标准配料。
Acknowledgements
致谢
The authors would like to thank Xi Chen and Trevor Darrell for helpful discussions, Yan Duan and Alex Lee for technical advice, Nikhil Mishra, Haoran Tang, and Greg Kahn for feedback on an early draft of the paper, and the anonymous reviewers for their comments. This work was supported in part by an ONR PECASE award and an NSF GRFP award.
作者感谢 Xi Chen 与 Trevor Darrell 的有益讨论,Yan Duan 与 Alex Lee 的技术建议,Nikhil Mishra、Haoran Tang 与 Greg Kahn 对论文早期草稿的反馈,以及匿名审稿人的意见。本工作部分得到 ONR PECASE 奖与 NSF GRFP 奖支持。
References
参考文献
Abadi et al. (2016) Abadi, Martín, Agarwal, Ashish, Barham, Paul, Brevdo, Eugene, Chen, Zhifeng, Citro, Craig, Corrado, Greg S, Davis, Andy, Dean, Jeffrey, Devin, Matthieu, et al. Tensorflow: Large-scale machine learning on heterogeneous distributed systems. arXiv preprint arXiv:1603.04467 , 2016.
Andrychowicz et al. (2016) Andrychowicz, Marcin, Denil, Misha, Gomez, Sergio, Hoffman, Matthew W, Pfau, David, Schaul, Tom, and de Freitas, Nando. Learning to learn by gradient descent by gradient descent. In Neural Information Processing Systems (NIPS) , 2016.
Bengio et al. (1992) Bengio, Samy, Bengio, Yoshua, Cloutier, Jocelyn, and Gecsei, Jan. On the optimization of a synaptic learning rule. In Optimality in Artificial and Biological Neural Networks , pp. 6–8, 1992.
Bengio et al. (1990) Bengio, Yoshua, Bengio, Samy, and Cloutier, Jocelyn. Learning a synaptic learning rule . Université de Montréal, Département d’informatique et de recherche opérationnelle, 1990.
Donahue et al. (2014) Donahue, Jeff, Jia, Yangqing, Vinyals, Oriol, Hoffman, Judy, Zhang, Ning, Tzeng, Eric, and Darrell, Trevor. Decaf: A deep convolutional activation feature for generic visual recognition. In International Conference on Machine Learning (ICML) , 2014.
Duan et al. (2016a) Duan, Yan, Chen, Xi, Houthooft, Rein, Schulman, John, and Abbeel, Pieter. Benchmarking deep reinforcement learning for continuous control. In International Conference on Machine Learning (ICML) , 2016a.
Duan et al. (2016b) Duan, Yan, Schulman, John, Chen, Xi, Bartlett, Peter L, Sutskever, Ilya, and Abbeel, Pieter. Rl2: Fast reinforcement learning via slow reinforcement learning. arXiv preprint arXiv:1611.02779 , 2016b.
Edwards & Storkey (2017) Edwards, Harrison and Storkey, Amos. Towards a neural statistician. International Conference on Learning Representations (ICLR) , 2017.
Goodfellow et al. (2015) Goodfellow, Ian J, Shlens, Jonathon, and Szegedy, Christian. Explaining and harnessing adversarial examples. International Conference on Learning Representations (ICLR) , 2015.
Ha et al. (2017) Ha, David, Dai, Andrew, and Le, Quoc V. Hypernetworks. International Conference on Learning Representations (ICLR) , 2017.
Hochreiter et al. (2001) Hochreiter, Sepp, Younger, A Steven, and Conwell, Peter R. Learning to learn using gradient descent. In International Conference on Artificial Neural Networks . Springer, 2001.
Husken & Goerick (2000) Husken, Michael and Goerick, Christian. Fast learning for problem classes using knowledge based network initialization. In Neural Networks, 2000. IJCNN 2000, Proceedings of the IEEE-INNS-ENNS International Joint Conference on , volume 6, pp. 619–624. IEEE, 2000.
Ioffe & Szegedy (2015) Ioffe, Sergey and Szegedy, Christian. Batch normalization: Accelerating deep network training by reducing internal covariate shift. International Conference on Machine Learning (ICML) , 2015.
Kaiser et al. (2017) Kaiser, Lukasz, Nachum, Ofir, Roy, Aurko, and Bengio, Samy. Learning to remember rare events. International Conference on Learning Representations (ICLR) , 2017.
Kingma & Ba (2015) Kingma, Diederik and Ba, Jimmy. Adam: A method for stochastic optimization. International Conference on Learning Representations (ICLR) , 2015.
Kirkpatrick et al. (2016) Kirkpatrick, James, Pascanu, Razvan, Rabinowitz, Neil, Veness, Joel, Desjardins, Guillaume, Rusu, Andrei A, Milan, Kieran, Quan, John, Ramalho, Tiago, Grabska-Barwinska, Agnieszka, et al. Overcoming catastrophic forgetting in neural networks. arXiv preprint arXiv:1612.00796 , 2016.
Koch (2015) Koch, Gregory. Siamese neural networks for one-shot image recognition. ICML Deep Learning Workshop , 2015.
Krähenbühl et al. (2016) Krähenbühl, Philipp, Doersch, Carl, Donahue, Jeff, and Darrell, Trevor. Data-dependent initializations of convolutional neural networks. International Conference on Learning Representations (ICLR) , 2016.
Lake et al. (2011) Lake, Brenden M, Salakhutdinov, Ruslan, Gross, Jason, and Tenenbaum, Joshua B. One shot learning of simple visual concepts. In Conference of the Cognitive Science Society (CogSci) , 2011.
Li & Malik (2017) Li, Ke and Malik, Jitendra. Learning to optimize. International Conference on Learning Representations (ICLR) , 2017.
Maclaurin et al. (2015) Maclaurin, Dougal, Duvenaud, David, and Adams, Ryan. Gradient-based hyperparameter optimization through reversible learning. In International Conference on Machine Learning (ICML) , 2015.
Munkhdalai & Yu (2017) Munkhdalai, Tsendsuren and Yu, Hong. Meta networks. International Conferecence on Machine Learning (ICML) , 2017.
Naik & Mammone (1992) Naik, Devang K and Mammone, RJ. Meta-neural networks that learn by learning. In International Joint Conference on Neural Netowrks (IJCNN) , 1992.
Parisotto et al. (2016) Parisotto, Emilio, Ba, Jimmy Lei, and Salakhutdinov, Ruslan. Actor-mimic: Deep multitask and transfer reinforcement learning. International Conference on Learning Representations (ICLR) , 2016.
Ravi & Larochelle (2017) Ravi, Sachin and Larochelle, Hugo. Optimization as a model for few-shot learning. In International Conference on Learning Representations (ICLR) , 2017.
Rei (2015) Rei, Marek. Online representation learning in recurrent neural language models. arXiv preprint arXiv:1508.03854 , 2015.
Rezende et al. (2016) Rezende, Danilo Jimenez, Mohamed, Shakir, Danihelka, Ivo, Gregor, Karol, and Wierstra, Daan. One-shot generalization in deep generative models. International Conference on Machine Learning (ICML) , 2016.
Salimans & Kingma (2016) Salimans, Tim and Kingma, Diederik P. Weight normalization: A simple reparameterization to accelerate training of deep neural networks. In Neural Information Processing Systems (NIPS) , 2016.
Santoro et al. (2016) Santoro, Adam, Bartunov, Sergey, Botvinick, Matthew, Wierstra, Daan, and Lillicrap, Timothy. Meta-learning with memory-augmented neural networks. In International Conference on Machine Learning (ICML) , 2016.
Saxe et al. (2014) Saxe, Andrew, McClelland, James, and Ganguli, Surya. Exact solutions to the nonlinear dynamics of learning in deep linear neural networks. International Conference on Learning Representations (ICLR) , 2014.
Schmidhuber (1987) Schmidhuber, Jurgen. Evolutionary principles in self-referential learning. On learning how to learn: The meta-meta-… hook.) Diploma thesis, Institut f. Informatik, Tech. Univ. Munich , 1987.
Schmidhuber (1992) Schmidhuber, Jürgen. Learning to control fast-weight memories: An alternative to dynamic recurrent networks. Neural Computation , 1992.
Schulman et al. (2015) Schulman, John, Levine, Sergey, Abbeel, Pieter, Jordan, Michael I, and Moritz, Philipp. Trust region policy optimization. In International Conference on Machine Learning (ICML) , 2015.
Shyam et al. (2017) Shyam, Pranav, Gupta, Shubham, and Dukkipati, Ambedkar. Attentive recurrent comparators. International Conferecence on Machine Learning (ICML) , 2017.
Snell et al. (2017) Snell, Jake, Swersky, Kevin, and Zemel, Richard S. Prototypical networks for few-shot learning. arXiv preprint arXiv:1703.05175 , 2017.
Thrun & Pratt (1998) Thrun, Sebastian and Pratt, Lorien. Learning to learn . Springer Science & Business Media, 1998.
Todorov et al. (2012) Todorov, Emanuel, Erez, Tom, and Tassa, Yuval. Mujoco: A physics engine for model-based control. In International Conference on Intelligent Robots and Systems (IROS) , 2012.
Vinyals et al. (2016) Vinyals, Oriol, Blundell, Charles, Lillicrap, Tim, Wierstra, Daan, et al. Matching networks for one shot learning. In Neural Information Processing Systems (NIPS) , 2016.
Wang et al. (2016) Wang, Jane X, Kurth-Nelson, Zeb, Tirumala, Dhruva, Soyer, Hubert, Leibo, Joel Z, Munos, Remi, Blundell, Charles, Kumaran, Dharshan, and Botvinick, Matt. Learning to reinforcement learn. arXiv preprint arXiv:1611.05763 , 2016.
Williams (1992) Williams, Ronald J. Simple statistical gradient-following algorithms for connectionist reinforcement learning. Machine learning , 8(3-4):229–256, 1992.
Appendix A Additional Experiment Details
附录 A 额外实验细节
In this section, we provide additional details of the experimental set-up and hyperparameters.
本节提供实验设置与超参数的额外细节。
A.1 Classification
A.1 分类
For N-way, K-shot classification, each gradient is computed using a batch size of examples. For Omniglot, the 5-way convolutional and non-convolutional MAML models were each trained with gradient step with step size and a meta batch-size of tasks. The network was evaluated using gradient steps with the same step size . The 20-way convolutional MAML model was trained and evaluated with gradient steps with step size . During training, the meta batch-size was set to tasks. For MiniImagenet, both models were trained using gradient steps of size , and evaluated using gradient steps at test time. Following Ravi & Larochelle 2017, examples per class were used for evaluating the post-update meta-gradient. We used a meta batch-size of and tasks for -shot and -shot training respectively. All models were trained for iterations on a single NVIDIA Pascal Titan X GPU.
对 N-way、K-shot 分类,每次梯度用批大小 个例子计算。对 Omniglot,5-way 卷积与非卷积 MAML 模型均以步长 做 1 次梯度步训练,元批大小 32 个任务;评估时用相同步长 做 3 次梯度步。20-way 卷积 MAML 以步长 训练并评估 5 次梯度步;训练时元批大小 16 个任务。对 MiniImagenet,两模型均以 训练 5 次梯度步,测试时评估 10 次梯度步。按 Ravi & Larochelle 2017,用每类 15 个例子评估更新后元梯度。1-shot 与 5-shot 训练的元批大小分别为 4 与 2 个任务。所有模型在单块 NVIDIA Pascal Titan X GPU 上训练 60000 次迭代。
A.2 Reinforcement Learning
A.2 强化学习
In all reinforcement learning experiments, the MAML policy was trained using a single gradient step with . During evaluation, we found that halving the learning rate after the first gradient step produced superior performance. Thus, the step size during adaptation was set to for the first step, and for all future steps. The step sizes for the baseline methods were manually tuned for each domain. In the 2D navigation, we used a meta batch size of ; in the locomotion problems, we used a meta batch size of tasks. The MAML models were trained for up to meta-iterations, and the model with the best average return during training was used for evaluation. For the ant goal velocity task, we added a positive reward bonus at each timestep to prevent the ant from ending the episode.
全部强化学习实验中,MAML 策略以 的单次梯度步训练。评估时发现第一步后把学习率减半效果更好,故适应时第一步 ,之后均为 。基线方法的步长按领域手动调节。二维导航元批大小 20;运动问题元批大小 40 个任务。MAML 模型最多训练 500 次元迭代,取训练期间平均回报最好的模型评估。对蚂蚁目标速度任务,每步加入正奖励奖励,以防蚂蚁提前结束片段。
Appendix B Additional Sinusoid Results
附录 B 额外正弦结果
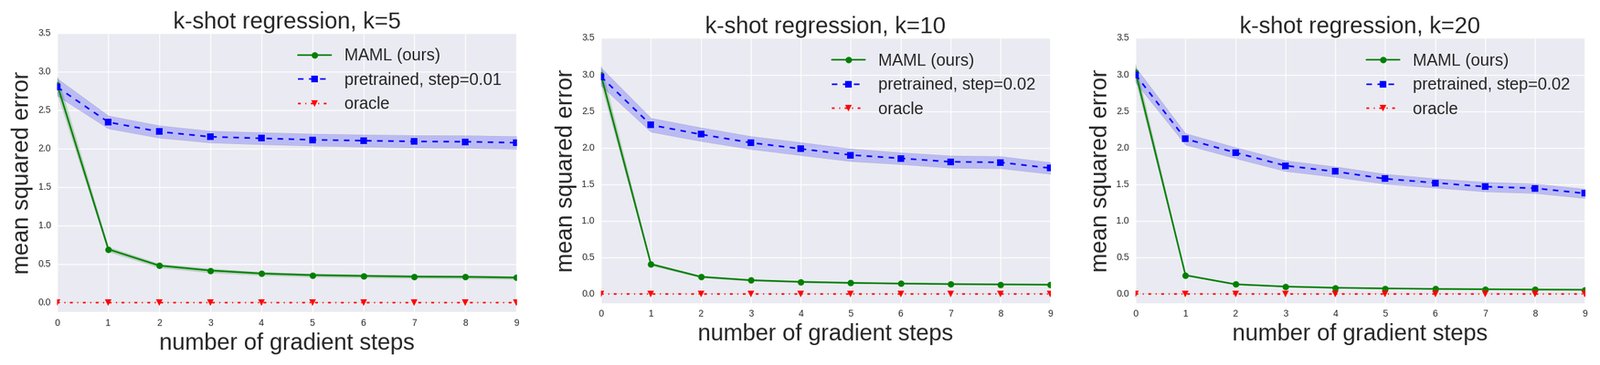
Figure 6: Quantitative sinusoid regression results showing test-time learning curves with varying numbers of test-time samples. Each gradient step is computed using the same examples. Note that MAML continues to improve with additional gradient steps without overfitting to the extremely small dataset during meta-testing, and achieves a loss that is substantially lower than the baseline fine-tuning approach.
图 6:正弦回归定量结果,展示不同数量 个测试时样本的测试时学习曲线。每步梯度用同一组 个例子计算。注意 MAML 在元测试期间用额外梯度步继续改进且不过拟合极小数据集,损失远低于基线微调方法。
In Figure 6, we show the full quantitative results of the MAML model trained on -shot learning and evaluated on -shot, -shot, and -shot. In Figure 7, we show the qualitative performance of MAML and the pretrained baseline on randomly sampled sinusoids.
图 6 给出在 10-shot 上训练、在 5-shot、10-shot、20-shot 上评估的 MAML 模型完整定量结果。图 7 给出 MAML 与预训练基线在随机采样正弦上的定性表现。
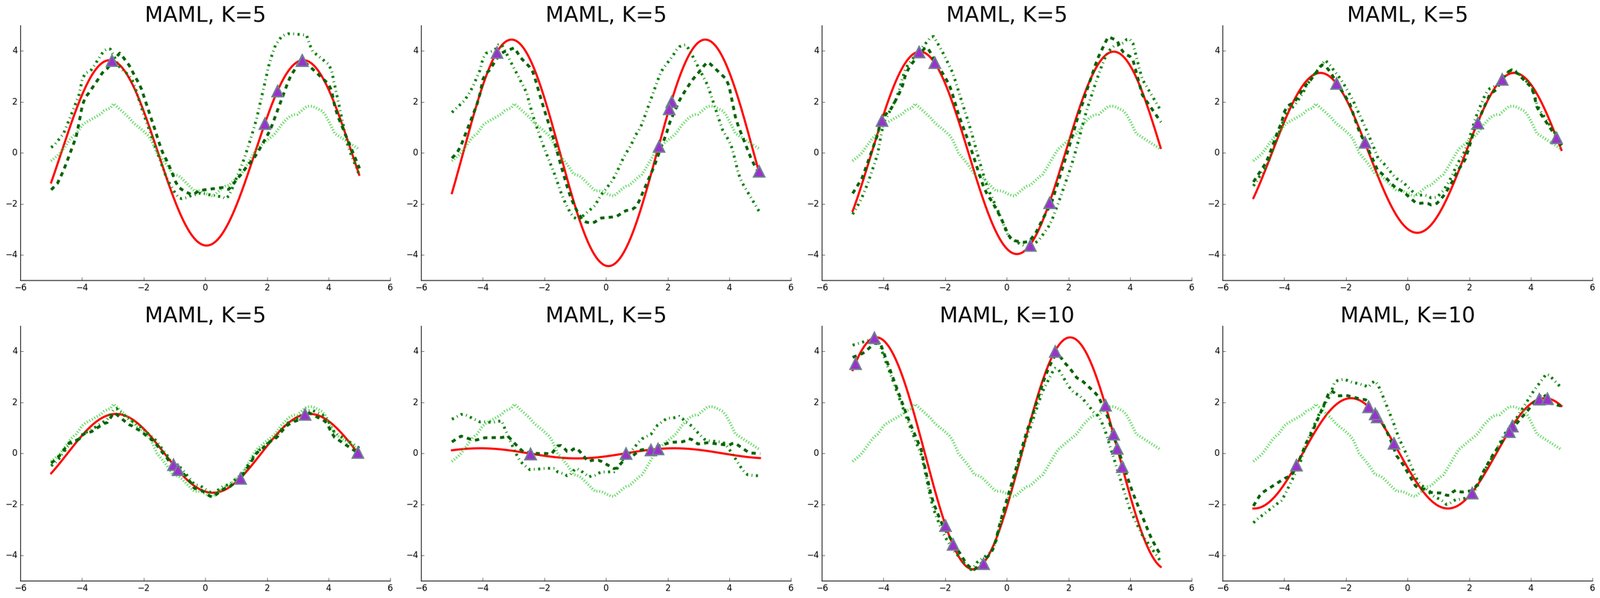
Figure 7: A random sample of qualitative results from the sinusoid regression task.
图 7:正弦回归任务定性结果的随机样本。
Appendix C Additional Comparisons
附录 C 额外对比
In this section, we include more thorough evaluations of our approach, including additional multi-task baselines and a comparison representative of the approach of Rei 2015.
本节包含对我们方法的更充分评估,包括额外多任务基线以及代表 Rei 2015 方法的对比。
C.1 Multi-task baselines
C.1 多任务基线
The pretraining baseline in the main text trained a single network on all tasks, which we referred to as “pretraining on all tasks”. To evaluate the model, as with MAML, we fine-tuned this model on each test task using examples. In the domains that we study, different tasks involve different output values for the same input. As a result, by pre-training on all tasks, the model would learn to output the average output for a particular input value. In some instances, this model may learn very little about the actual domain, and instead learn about the range of the output space.
正文中的预训练基线在所有任务上训练单个网络,我们称为「在所有任务上预训练」。评估时与 MAML 一样,用 个例子在每个测试任务上微调。在我们研究的领域中,不同任务对同一输入涉及不同输出值。因此,在所有任务上预训练会使模型学会对特定输入输出平均值。某些情形下,该模型可能对实际领域学得很少,而主要学到输出空间的范围。
We experimented with a multi-task method to provide a point of comparison, where instead of averaging in the output space, we averaged in the parameter space. To achieve averaging in parameter space, we sequentially trained separate models on tasks drawn from . Each model was initialized randomly and trained on a large amount of data from its assigned task. We then took the average parameter vector across models and fine-tuned on 5 datapoints with a tuned step size. All of our experiments for this method were on the sinusoid task because of computational requirements. The error of the individual regressors was low: less than 0.02 on their respective sine waves.
我们尝试一种多任务方法作为对照:不在输出空间平均,而在参数空间平均。为实现参数空间平均,我们顺序在从 抽出的 500 个任务上训练 500 个独立模型。每个模型随机初始化,并在其指定任务的大量数据上训练。然后取各模型参数向量的平均,再在 5 个数据点上用调好的步长微调。因算力要求,该方法全部实验在正弦任务上。各回归器在各自正弦波上误差很低:小于 0.02。
We tried three variants of this set-up. During training of the individual regressors, we tried using one of the following: no regularization, standard weight decay, and weight regularization to the mean parameter vector thus far of the trained regressors. The latter two variants encourage the individual models to find parsimonious solutions. When using regularization, we set the magnitude of the regularization to be as high as possible without significantly deterring performance. In our results, we refer to this approach as “multi-task”. As seen in the results in Table 2, we find averaging in the parameter space (multi-task) performed worse than averaging in the output space (pretraining on all tasks). This suggests that it is difficult to find parsimonious solutions to multiple tasks when training on tasks separately, and that MAML is learning a solution that is more sophisticated than the mean optimal parameter vector.
我们尝试该设置的三种变体。训练各回归器时分别使用:无正则、标准 权重衰减、以及对已训回归器迄今均值参数向量的 权重正则。后两种鼓励各模型寻找节俭解。使用正则时,把正则强度设为不显著损害性能的尽量高。结果中称该方法为「multi-task」。如表 2 所示,参数空间平均(multi-task)差于输出空间平均(在所有任务上预训练)。这表明分别训练任务时很难找到多任务的节俭解,且 MAML 学到的解比平均最优参数向量更精致。
| num. grad steps | 1 | 5 | 10 |
|---|---|---|---|
| multi-task, no reg | |||
| multi-task, l2 reg | |||
| multi-task, reg to mean | |||
| pretrain on all tasks | |||
| MAML (ours) |
Table 2: Additional multi-task baselines on the sinusoid regression domain, showing 5-shot mean squared error. The results suggest that MAML is learning a solution more sophisticated than the mean optimal parameter vector.
| 梯度步数 | 1 | 5 | 10 |
|---|---|---|---|
| multi-task, no reg | |||
| multi-task, l2 reg | |||
| multi-task, reg to mean | |||
| pretrain on all tasks | |||
| MAML(本文) |
表 2:正弦回归领域额外多任务基线,报告 5-shot 均方误差。结果表明 MAML 学到的解比平均最优参数向量更精致。
C.2 Context vector adaptation
C.2 上下文向量适应
Rei 2015 developed a method which learns a context vector that can be adapted online, with an application to recurrent language models. The parameters in this context vector are learned and adapted in the same way as the parameters in the MAML model. To provide a comparison to using such a context vector for meta-learning problems, we concatenated a set of free parameters to the input , and only allowed the gradient steps to modify , rather than modifying the model parameters , as in MAML. For image inputs, was concatenated channel-wise with the input image. We ran this method on Omniglot and two RL domains following the same experimental protocol. We report the results in Tables 3, 4, and 5. Learning an adaptable context vector performed well on the toy pointmass problem, but sub-par on more difficult problems, likely due to a less flexible meta-optimization.
Rei 2015 提出一种可在线适应上下文向量的方法,应用于循环语言模型。该上下文向量中的参数与 MAML 模型参数以相同方式学习与适应。为对比用此类上下文向量做元学习,我们把一组自由参数 拼到输入 ,并只允许梯度步修改 ,而非像 MAML 那样修改模型参数 。对图像输入, 按通道与输入图像拼接。我们按相同实验协议在 Omniglot 与两个 RL 领域运行该方法,结果见表 3、4、5。可适应上下文向量在玩具点质量问题上表现良好,但在更难问题上逊色,可能因元优化灵活性较低。
| 1-shot | 5-shot | |
|---|---|---|
| context vector | ||
| MAML |
Table 3: 5-way Omniglot Classification
| 1-shot | 5-shot | |
|---|---|---|
| context vector | ||
| MAML |
表 3:5-way Omniglot 分类
| num. grad steps | 0 | 1 | 2 | 3 |
|---|---|---|---|---|
| context vector | ||||
| MAML (ours) |
Table 4: 2D Pointmass, average return
| 梯度步数 | 0 | 1 | 2 | 3 |
|---|---|---|---|---|
| context vector | ||||
| MAML(本文) |
表 4:二维点质量,平均回报
| num. grad steps | 0 | 1 | 2 | 3 |
|---|---|---|---|---|
| context vector | ||||
| MAML (ours) |
Table 5: Half-cheetah forward/backward, average return
| 梯度步数 | 0 | 1 | 2 | 3 |
|---|---|---|---|---|
| context vector | ||||
| MAML(本文) |
表 5:半猎豹前/后,平均回报