LoRA: Low-Rank Adaptation of Large Language Models
LoRA: Low-Rank Adaptation of Large Language Models
Edward Hu Thanks: Equal contribution. Yelong ShenPhillip Wallis Zeyuan Allen-ZhuYuanzhi LiShean WangLu WangWeizhu Chen Microsoft Corporation {edwardhu, yeshe, phwallis, zeyuana,yuanzhil, swang, luw, wzchen}@microsoft.comyuanzhil@andrew.cmu.edu (Version 2)
Abstract
An important paradigm of natural language processing consists of large-scale pre-training on general domain data and adaptation to particular tasks or domains. As we pre-train larger models, full fine-tuning, which retrains all model parameters, becomes less feasible. Using GPT-3 175B as an example – deploying independent instances of fine-tuned models, each with 175B parameters, is prohibitively expensive. We propose Low-Rank Adaptation, or LoRA, which freezes the pre-trained model weights and injects trainable rank decomposition matrices into each layer of the Transformer architecture, greatly reducing the number of trainable parameters for downstream tasks. Compared to GPT-3 175B fine-tuned with Adam, LoRA can reduce the number of trainable parameters by 10,000 times and the GPU memory requirement by 3 times. LoRA performs on-par or better than fine-tuning in model quality on RoBERTa, DeBERTa, GPT-2, and GPT-3, despite having fewer trainable parameters, a higher training throughput, and, unlike adapters, no additional inference latency. We also provide an empirical investigation into rank-deficiency in language model adaptation, which sheds light on the efficacy of LoRA. We release a package that facilitates the integration of LoRA with PyTorch models and provide our implementations and model checkpoints for RoBERTa, DeBERTa, and GPT-2 at https://github.com/microsoft/LoRA.
自然语言处理的一个重要范式是:在通用领域数据上大规模预训练,再适配到特定任务或领域。随着我们预训练更大的模型,重新训练全部模型参数的全量微调变得越来越不可行。以 GPT-3 175B 为例——部署各自拥有 175B 参数的独立微调实例,代价高得难以承受。我们提出 Low-Rank Adaptation(LoRA):冻结预训练模型权重,并向 Transformer 架构的每一层注入可训练的秩分解矩阵,从而大幅减少下游任务的可训练参数数量。相对用 Adam 微调的 GPT-3 175B,LoRA 可将可训练参数数减少约 10,000 倍,GPU 内存需求减少约 3 倍。尽管可训练参数更少、训练吞吐更高,且与 adapter 不同、不引入额外推理延迟,LoRA 在 RoBERTa、DeBERTa、GPT-2 与 GPT-3 上的模型质量仍与全量微调持平或更好。我们还对语言模型适配中的秩亏缺做了实证考察,以阐明 LoRA 有效性并对未来应用给出启示。我们发布便于把 LoRA 集成到 PyTorch 模型的软件包,并在 https://github.com/microsoft/LoRA 提供 RoBERTa、DeBERTa 与 GPT-2 的实现与模型检查点。
1 Introduction
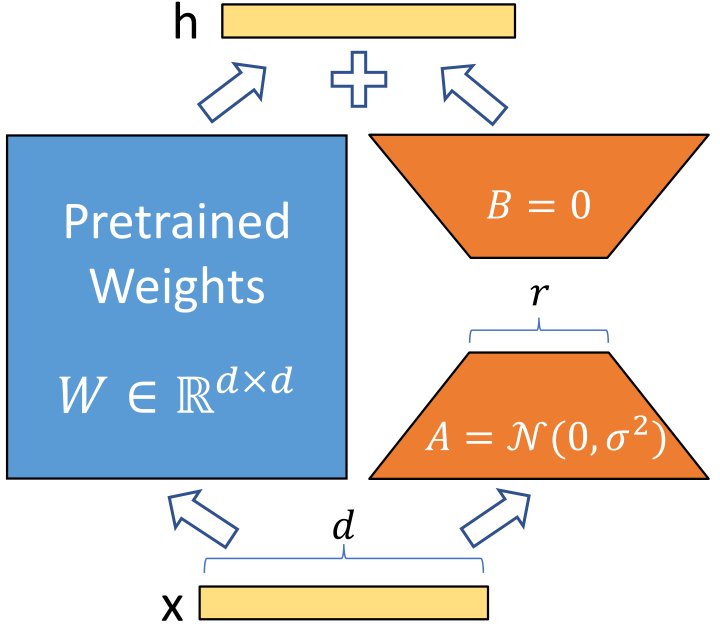
Figure 1: Our reparametrization. We only train and .
图 1:我们的重参数化。只训练 与 。
Many applications in natural language processing rely on adapting one large-scale, pre-trained language model to multiple downstream applications. Such adaptation is usually done via fine-tuning, which updates all the parameters of the pre-trained model. The major downside of fine-tuning is that the new model contains as many parameters as in the original model. As larger models are trained every few months, this changes from a mere “inconvenience” for GPT-2 (Radford et al. b) or RoBERTa large (Liu et al. 2019) to a critical deployment challenge for GPT-3 (Brown et al. 2020) with 175 billion trainable parameters.[^1]
自然语言处理的许多应用依赖把一个大规模预训练语言模型适配到多个下游应用。这种适配通常通过微调完成,即更新预训练模型的全部参数。微调的主要缺点是:新模型包含与原模型一样多的参数。随着每隔几个月就训练更大的模型,这对 GPT-2(Radford et al. b)或 RoBERTa large(Liu et al. 2019)还只是“不便”,对拥有 1750 亿可训练参数的 GPT-3(Brown et al. 2020)则变成关键部署挑战。[^1]
Many sought to mitigate this by adapting only some parameters or learning external modules for new tasks. This way, we only need to store and load a small number of task-specific parameters in addition to the pre-trained model for each task, greatly boosting the operational efficiency when deployed. However, existing techniques often introduce inference latency (Houlsby et al. 2019; Rebuffi et al. 2017) by extending model depth or reduce the model’s usable sequence length (Li & Liang 2021; Lester et al. 2021; Hambardzumyan et al. 2020; Liu et al. 2021) (Section 3). More importantly, these method often fail to match the fine-tuning baselines, posing a trade-off between efficiency and model quality.
许多人试图只适配部分参数,或为新任务学习外部模块来缓解这一问题。这样,对每个任务我们只需在预训练模型之外存储并加载少量任务特定参数,从而在部署时大幅提升运维效率。但现有技术往往通过加深模型引入推理延迟(Houlsby et al. 2019; Rebuffi et al. 2017),或缩短模型可用序列长度(Li & Liang 2021; Lester et al. 2021; Hambardzumyan et al. 2020; Liu et al. 2021)(第 3 节)。更重要的是,这些方法常常无法匹配微调基线,从而在效率与模型质量之间形成权衡。
We take inspiration from Li et al. 2018a; Aghajanyan et al. 2020 which show that the learned over-parametrized models in fact reside on a low intrinsic dimension. We hypothesize that the change in weights during model adaptation also has a low “intrinsic rank”, leading to our proposed Low-Rank Adaptation (LoRA) approach. LoRA allows us to train some dense layers in a neural network indirectly by optimizing rank decomposition matrices of the dense layers’ change during adaptation instead, while keeping the pre-trained weights frozen, as shown in Figure 1. Using GPT-3 175B as an example, we show that a very low rank (i.e., r in Figure 1 can be one or two) suffices even when the full rank (i.e., d) is as high as 12,288, making LoRA both storage- and compute-efficient.
我们受 Li et al. 2018a; Aghajanyan et al. 2020 启发:学得的过参数化模型实际上落在低本征维上。我们假设模型适配期间的权重变化也具有低“本征秩”,由此提出 Low-Rank Adaptation(LoRA)。如图 1 所示,LoRA 允许我们通过优化稠密层在适配期间变化量的秩分解矩阵,间接训练神经网络中的某些稠密层,同时保持预训练权重冻结。以 GPT-3 175B 为例,我们表明即便全秩(即 d)高达 12,288,极低的秩(即图 1 中的 r 可为 1 或 2)也已足够,从而使 LoRA 在存储与计算上都高效。
LoRA possesses several key advantages.
LoRA 具有若干关键优势。
- • A pre-trained model can be shared and used to build many small LoRA modules for different tasks. We can freeze the shared model and efficiently switch tasks by replacing the matrices and in Figure 1, reducing the storage requirement and task-switching overhead significantly.
- • 一个预训练模型可被共享,并为不同任务构建许多小型 LoRA 模块。我们可以冻结共享模型,通过替换图 1 中的矩阵 与 高效切换任务,显著降低存储需求与任务切换开销。
- • LoRA makes training more efficient and lowers the hardware barrier to entry by up to 3 times when using adaptive optimizers since we do not need to calculate the gradients or maintain the optimizer states for most parameters. Instead, we only optimize the injected, much smaller low-rank matrices.
- • LoRA 使训练更高效,并在使用自适应优化器时将硬件门槛最高降低约 3 倍:因为我们不必为大多数参数计算梯度或维护优化器状态,而只需优化注入的、小得多的低秩矩阵。
- • Our simple linear design allows us to merge the trainable matrices with the frozen weights when deployed, introducing no inference latency compared to a fully fine-tuned model, by construction.
- • 我们的简单线性设计允许在部署时把可训练矩阵与冻结权重合并,相对全量微调模型不引入推理延迟,这由构造保证。
- • LoRA is orthogonal to many prior methods and can be combined with many of them, such as prefix-tuning. We provide an example in Appendix E.
- • LoRA 与许多先前方法正交,并可与其中许多结合,例如 prefix-tuning。附录 E 给出一个例子。
Terminologies and Conventions
We make frequent references to the Transformer architecture and use the conventional terminologies for its dimensions. We call the input and output dimension size of a Transformer layer . We use , , , and to refer to the query/key/value/output projection matrices in the self-attention module. or refers to a pre-trained weight matrix and its accumulated gradient update during adaptation. We use to denote the rank of a LoRA module. We follow the conventions set out by (Vaswani et al. 2017; Brown et al. 2020) and use Adam (Loshchilov & Hutter 2019; Kingma & Ba 2017) for model optimization and use a Transformer MLP feedforward dimension .
Terminologies and Conventions
我们频繁引用 Transformer 架构,并对其维度使用常规术语。我们把 Transformer 层的输入与输出维数称为 。用 、、 与 指自注意力模块中的 query/key/value/output 投影矩阵。 或 指预训练权重矩阵, 指其在适配期间累积的梯度更新。用 表示 LoRA 模块的秩。我们遵循(Vaswani et al. 2017; Brown et al. 2020)的惯例,用 Adam(Loshchilov & Hutter 2019; Kingma & Ba 2017)做模型优化,并使用 Transformer MLP 前馈维 。
2 Problem Statement
While our proposal is agnostic to training objective, we focus on language modeling as our motivating use case. Below is a brief description of the language modeling problem and, in particular, the maximization of conditional probabilities given a task-specific prompt.
虽然我们的提议与训练目标无关,但我们以语言建模作为动机用例。以下简要描述语言建模问题,特别是给定任务特定提示时条件概率的最大化。
Suppose we are given a pre-trained autoregressive language model parametrized by . For instance, can be a generic multi-task learner such as GPT (Radford et al. b; Brown et al. 2020) based on the Transformer architecture (Vaswani et al. 2017). Consider adapting this pre-trained model to downstream conditional text generation tasks, such as summarization, machine reading comprehension (MRC), and natural language to SQL (NL2SQL). Each downstream task is represented by a training dataset of context-target pairs: , where both and are sequences of tokens. For example, in NL2SQL, is a natural language query and its corresponding SQL command; for summarization, is the content of an article and its summary.
假设给定由 参数化的预训练自回归语言模型 。例如, 可以是基于 Transformer 架构(Vaswani et al. 2017)的通用多任务学习器,如 GPT(Radford et al. b; Brown et al. 2020)。考虑把该预训练模型适配到下游条件文本生成任务,例如摘要、机器阅读理解(MRC)以及自然语言到 SQL(NL2SQL)。每个下游任务由上下文–目标对的训练数据集表示:,其中 与 都是 token 序列。例如在 NL2SQL 中, 是自然语言查询, 是对应 SQL 命令;对摘要, 是文章内容, 是其摘要。
During full fine-tuning, the model is initialized to pre-trained weights and updated to by repeatedly following the gradient to maximize the conditional language modeling objective:
在全量微调中,模型初始化为预训练权重 ,并通过反复沿梯度上升最大化条件语言建模目标,更新为 :
One of the main drawbacks for full fine-tuning is that for each downstream task, we learn a different set of parameters whose dimension equals . Thus, if the pre-trained model is large (such as GPT-3 with ), storing and deploying many independent instances of fine-tuned models can be challenging, if at all feasible.
全量微调的主要缺点之一是:对每个下游任务,我们学到一组不同的参数 ,其维数 等于 。因此,若预训练模型很大(如 GPT-3,),存储并部署许多独立微调实例即便可行也极具挑战。
In this paper, we adopt a more parameter-efficient approach, where the task-specific parameter increment is further encoded by a much smaller-sized set of parameters with . The task of finding thus becomes optimizing over :
本文采用更参数高效的方法:任务特定参数增量 进一步由规模小得多的参数集 编码,且 。于是寻找 变为对 优化:
In the subsequent sections, we propose to use a low-rank representation to encode that is both compute- and memory-efficient. When the pre-trained model is GPT-3 175B, the number of trainable parameters can be as small as of .
后续章节中,我们提出用低秩表示编码 ,使其在计算与内存上都高效。当预训练模型为 GPT-3 175B 时,可训练参数数 可小至 的 。
3 Aren’t Existing Solutions Good Enough?
The problem we set out to tackle is by no means new. Since the inception of transfer learning, dozens of works have sought to make model adaptation more parameter- and compute-efficient. See Section 6 for a survey of some of the well-known works. Using language modeling as an example, there are two prominent strategies when it comes to efficient adaptations: adding adapter layers (Houlsby et al. 2019; Rebuffi et al. 2017; Pfeiffer et al. 2021; Rücklé et al. 2020) or optimizing some forms of the input layer activations (Li & Liang 2021; Lester et al. 2021; Hambardzumyan et al. 2020; Liu et al. 2021). However, both strategies have their limitations, especially in a large-scale and latency-sensitive production scenario.
我们着手解决的问题绝非全新。自迁移学习诞生以来,已有数十项工作试图使模型适配更参数高效与计算高效。第 6 节综述其中一些知名工作。以语言建模为例,高效适配有两条突出策略:加入 adapter 层(Houlsby et al. 2019; Rebuffi et al. 2017; Pfeiffer et al. 2021; Rücklé et al. 2020),或优化输入层激活的某些形式(Li & Liang 2021; Lester et al. 2021; Hambardzumyan et al. 2020; Liu et al. 2021)。但两条策略都有局限,尤其在大规模、对延迟敏感的生产场景中。
Adapter Layers Introduce Inference Latency
There are many variants of adapters. We focus on the original design by Houlsby et al. 2019 which has two adapter layers per Transformer block and a more recent one by Lin et al. 2020 which has only one per block but with an additional LayerNorm (Ba et al. 2016). While one can reduce the overall latency by pruning layers or exploiting multi-task settings (Rücklé et al. 2020; Pfeiffer et al. 2021), there is no direct ways to bypass the extra compute in adapter layers. This seems like a non-issue since adapter layers are designed to have few parameters (sometimes 1% of the original model) by having a small bottleneck dimension, which limits the FLOPs they can add. However, large neural networks rely on hardware parallelism to keep the latency low, and adapter layers have to be processed sequentially. This makes a difference in the online inference setting where the batch size is typically as small as one. In a generic scenario without model parallelism, such as running inference on GPT-2 (Radford et al. b) medium on a single GPU, we see a noticeable increase in latency when using adapters, even with a very small bottleneck dimension (Table 1).
Adapter Layers Introduce Inference Latency
Adapter 有许多变体。我们聚焦 Houlsby et al. 2019 的原始设计(每个 Transformer 块两个 adapter 层),以及 Lin et al. 2020 更近的设计(每块仅一个,但额外有 LayerNorm(Ba et al. 2016))。虽然可通过剪枝层或利用多任务设定降低总体延迟(Rücklé et al. 2020; Pfeiffer et al. 2021),但没有直接办法绕过 adapter 层中的额外计算。这看似不是问题,因为 adapter 层通过很小的瓶颈维设计成参数很少(有时 1% 原模型),从而限制它们能增加的 FLOPs。但大型神经网络依赖硬件并行保持低延迟,而 adapter 层必须顺序处理。这在 batch size 通常小到 1 的在线推理设定中会有差别。在无模型并行的一般场景中,例如在单 GPU 上对 GPT-2(Radford et al. b)medium 做推理,即便瓶颈维很小,使用 adapter 也会带来可察觉的延迟增加。
| Batch Size | 32 | 16 | 1 |
|---|---|---|---|
| Sequence Length | 512 | 256 | 128 |
| 0.5M | 11M | 11M | |
| Fine-Tune/LoRA | 1449.40.8 | 338.00.6 | 19.82.7 |
| 1482.01.0 (+2.2%) | 354.80.5 (+5.0%) | 23.92.1 (+20.7%) | |
| 1492.21.0 (+3.0%) | 366.30.5 (+8.4%) | 25.82.2 (+30.3%) |
Table 1: Infernece latency of a single forward pass in GPT-2 medium measured in milliseconds, averaged over 100 trials. We use an NVIDIA Quadro RTX8000. “” denotes the number of trainable parameters in adapter layers. and are two variants of adapter tuning, which we describe in Section 5.1. The inference latency introduced by adapter layers can be significant in an online, short-sequence-length scenario. See the full study in Appendix B.
| Batch Size | 32 | 16 | 1 |
|---|---|---|---|
| Sequence Length | 512 | 256 | 128 |
| 0.5M | 11M | 11M | |
| Fine-Tune/LoRA | 1449.40.8 | 338.00.6 | 19.82.7 |
| 1482.01.0 (+2.2%) | 354.80.5 (+5.0%) | 23.92.1 (+20.7%) | |
| 1492.21.0 (+3.0%) | 366.30.5 (+8.4%) | 25.82.2 (+30.3%) |
表 1:GPT-2 medium 单次前向的推理延迟(毫秒),100 次试验平均。使用 NVIDIA Quadro RTX8000。“”表示 adapter 层中可训练参数数。 与 是第 5.1 节描述的两种 adapter tuning 变体。在在线、短序列场景中,adapter 层引入的推理延迟可能显著。完整研究见附录 B。
This problem gets worse when we need to shard the model as done in Shoeybi et al. 2020; Lepikhin et al. 2020, because the additional depth requires more synchronous GPU operations such as AllReduce and Broadcast, unless we store the adapter parameters redundantly many times.
当我们需要像 Shoeybi et al. 2020; Lepikhin et al. 2020 那样对模型做分片时,问题更糟:额外深度需要更多同步 GPU 操作(如 AllReduce 与 Broadcast),除非我们把 adapter 参数冗余存储许多份。
Directly Optimizing the Prompt is Hard
The other direction, as exemplified by prefix tuning (Li & Liang 2021), faces a different challenge. We observe that prefix tuning is difficult to optimize and that its performance changes non-monotonically in trainable parameters, confirming similar observations in the original paper. More fundamentally, reserving a part of the sequence length for adaptation necessarily reduces the sequence length available to process a downstream task, which we suspect makes tuning the prompt less performant compared to other methods. We defer the study on task performance to Section 5.
Directly Optimizing the Prompt is Hard
另一方向以 prefix tuning(Li & Liang 2021)为代表,面临不同挑战。我们观察到 prefix tuning 难以优化,且其表现随可训练参数非单调变化,这与原论文的类似观察一致。更根本的是,为适配预留一部分序列长度必然减少可用于处理下游任务的序列长度,我们怀疑这使得调 prompt 相对其他方法表现更弱。任务表现研究留到第 5 节。
4 Our Method
We describe the simple design of LoRA and its practical benefits. The principles outlined here apply to any dense layers in deep learning models, though we only focus on certain weights in Transformer language models in our experiments as the motivating use case.
我们描述 LoRA 的简单设计及其实际收益。这里概述的原则适用于深度学习模型中的任意稠密层,尽管实验中我们只聚焦 Transformer 语言模型中的某些权重作为动机用例。
4.1 Low-Rank-Parametrized Update Matrices
A neural network contains many dense layers which perform matrix multiplication. The weight matrices in these layers typically have full-rank. When adapting to a specific task, Aghajanyan et al. 2020 shows that the pre-trained language models have a low “instrisic dimension” and can still learn efficiently despite a random projection to a smaller subspace. Inspired by this, we hypothesize the updates to the weights also have a low “intrinsic rank” during adaptation. For a pre-trained weight matrix , we constrain its update by representing the latter with a low-rank decomposition , where , and the rank . During training, is frozen and does not receive gradient updates, while and contain trainable parameters. Note both and are multiplied with the same input, and their respective output vectors are summed coordinate-wise. For , our modified forward pass yields:
神经网络包含许多执行矩阵乘法的稠密层。这些层中的权重矩阵通常满秩。适配到特定任务时,Aghajanyan et al. 2020 表明预训练语言模型具有低“本征维”,即便随机投影到更小子空间仍能高效学习。受此启发,我们假设适配期间权重更新也具有低“本征秩”。对预训练权重矩阵 ,我们通过低秩分解约束其更新:,其中 ,,且秩 。训练时 冻结、不接收梯度更新,而 与 含可训练参数。注意 与 都与同一输入相乘,各自输出向量按坐标相加。对 ,我们修改后的前向为:
We illustrate our reparametrization in Figure 1. We use a random Gaussian initialization for and zero for , so is zero at the beginning of training. We then scale by , where is a constant in . When optimizing with Adam, tuning is roughly the same as tuning the learning rate if we scale the initialization appropriately. As a result, we simply set to the first we try and do not tune it. This scaling helps to reduce the need to retune hyperparameters when we vary (Yang & Hu 2021).
我们在图 1 中说明重参数化。对 使用随机高斯初始化,对 置零,因而训练开始时 为零。随后把 按 缩放,其中 是相对 的常数。用 Adam 优化时,若适当缩放初始化,调节 大致等同于调节学习率。因此我们简单把 设为首次尝试的 且不再调它。该缩放有助于在改变 时减少重新调节超参的需要(Yang & Hu 2021)。
A Generalization of Full Fine-tuning. A more general form of fine-tuning allows the training of a subset of the pre-trained parameters. LoRA takes a step further and does not require the accumulated gradient update to weight matrices to have full-rank during adaptation. This means that when applying LoRA to all weight matrices and training all biases[^2], we roughly recover the expressiveness of full fine-tuning by setting the LoRA rank to the rank of the pre-trained weight matrices. In other words, as we increase the number of trainable parameters [^3], training LoRA roughly converges to training the original model, while adapter-based methods converges to an MLP and prefix-based methods to a model that cannot take long input sequences.
A Generalization of Full Fine-tuning. 更一般的微调形式允许训练预训练参数的一个子集。LoRA 更进一步,不要求适配期间权重矩阵的累积梯度更新满秩。这意味着:当对所有权重矩阵应用 LoRA 并训练所有偏置[^2] 时,通过把 LoRA 秩 设为预训练权重矩阵的秩,我们大致恢复全量微调的表达能力。换言之,随着可训练参数数增加[^3],训练 LoRA 大致收敛到训练原模型;而基于 adapter 的方法收敛到一个 MLP,基于 prefix 的方法收敛到无法接受长输入序列的模型。
No Additional Inference Latency. When deployed in production, we can explicitly compute and store and perform inference as usual. Note that both and are in . When we need to switch to another downstream task, we can recover by subtracting and then adding a different , a quick operation with very little memory overhead. Critically, this guarantees that we do not introduce any additional latency during inference compared to a fine-tuned model by construction.
No Additional Inference Latency. 在生产部署时,我们可以显式计算并存储 ,并照常推理。注意 与 都在 中。需要切换到另一下游任务时,可通过减去 再加不同的 恢复 ,这是内存开销很小的快速操作。关键的是,这由构造保证:相对微调模型,我们在推理时不引入任何额外延迟。
4.2 Applying LoRA to Transformer
In principle, we can apply LoRA to any subset of weight matrices in a neural network to reduce the number of trainable parameters. In the Transformer architecture, there are four weight matrices in the self-attention module () and two in the MLP module. We treat (or , ) as a single matrix of dimension , even though the output dimension is usually sliced into attention heads. We limit our study to only adapting the attention weights for downstream tasks and freeze the MLP modules (so they are not trained in downstream tasks) both for simplicity and parameter-efficiency.We further study the effect on adapting different types of attention weight matrices in a Transformer in Section 7.1. We leave the empirical investigation of adapting the MLP layers, LayerNorm layers, and biases to a future work.
原则上,我们可对神经网络中任意权重矩阵子集应用 LoRA 以减少可训练参数数。在 Transformer 架构中,自注意力模块有四个权重矩阵(),MLP 模块有两个。即便输出维通常切成注意力头,我们仍把 (或 、)视为维数为 的单个矩阵。为简洁与参数效率,我们把研究限制为只适配注意力权重用于下游任务,并冻结 MLP 模块(因而下游任务中不训练它们)。我们在第 7.1 节进一步研究所适配的注意力权重矩阵类型的影响。把 MLP 层、LayerNorm 层与偏置也纳入适配的实证考察留待未来工作。
Practical Benefits and Limitations. The most significant benefit comes from the reduction in memory and storage usage. For a large Transformer trained with Adam, we reduce that VRAM usage by up to if as we do not need to store the optimizer states for the frozen parameters. On GPT-3 175B, we reduce the VRAM consumption during training from 1.2TB to 350GB. With and only the query and value projection matrices being adapted, the checkpoint size is reduced by roughly 10,000 (from 350GB to 35MB)[^4]. This allows us to train with significantly fewer GPUs and avoid I/O bottlenecks. Another benefit is that we can switch between tasks while deployed at a much lower cost by only swapping the LoRA weights as opposed to all the parameters. This allows for the creation of many customized models that can be swapped in and out on the fly on machines that store the pre-trained weights in VRAM. We also observe a 25% speedup during training on GPT-3 175B compared to full fine-tuning[^5] as we do not need to calculate the gradient for the vast majority of the parameters.
Practical Benefits and Limitations. 最显著收益来自内存与存储占用的降低。对用 Adam 训练的大型 Transformer,若 ,由于不必为冻结参数存储优化器状态,我们最高可将 VRAM 占用降低约 。在 GPT-3 175B 上,训练时 VRAM 消耗从 1.2TB 降到 350GB。以 且只适配 query 与 value 投影矩阵时,检查点大小约缩小 10,000(从 350GB 到 35MB)[^4]。这使我们能用显著更少的 GPU 训练并避免 I/O 瓶颈。另一收益是:部署时可仅交换 LoRA 权重而非全部参数,从而以低得多的代价在任务间切换。这允许创建许多定制模型,并在把预训练权重存于 VRAM 的机器上即时换入换出。我们还观察到:相对全量微调,在 GPT-3 175B 上训练加速约 25%[^5],因为不必为绝大多数参数计算梯度。
LoRA also has its limitations. For example, it is not straightforward to batch inputs to different tasks with different and in a single forward pass, if one chooses to absorb and into to eliminate additional inference latency. Though it is possible to not merge the weights and dynamically choose the LoRA modules to use for samples in a batch for scenarios where latency is not critical.
LoRA 也有局限。例如,若选择把 与 吸收进 以消除额外推理延迟,则不易在单次前向中把使用不同 、 的不同任务输入批在一起。不过在延迟不关键的场景中,也可以不合并权重,并为 batch 中的样本动态选择所用的 LoRA 模块。
5 Empirical Experiments
We evaluate the downstream task performance of LoRA on RoBERTa (Liu et al. 2019), DeBERTa (He et al. 2021), and GPT-2 (Radford et al. b), before scaling up to GPT-3 175B (Brown et al. 2020). Our experiments cover a wide range of tasks, from natural language understanding (NLU) to generation (NLG). Specifically, we evaluate on the GLUE (Wang et al. 2019) benchmark for RoBERTa and DeBERTa. We follow the setup of Li & Liang 2021 on GPT-2 for a direct comparison and add WikiSQL (Zhong et al. 2017) (NL to SQL queries) and SAMSum (Gliwa et al. 2019) (conversation summarization) for large-scale experiments on GPT-3. See Appendix C for more details on the datasets we use. We use NVIDIA Tesla V100 for all experiments.
我们在 RoBERTa(Liu et al. 2019)、DeBERTa(He et al. 2021)与 GPT-2(Radford et al. b)上评估 LoRA 的下游任务表现,再扩展到 GPT-3 175B(Brown et al. 2020)。实验覆盖从自然语言理解(NLU)到生成(NLG)的广泛任务。具体地,对 RoBERTa 与 DeBERTa 我们在 GLUE(Wang et al. 2019)基准上评估。对 GPT-2 我们遵循 Li & Liang 2021 的设定以便直接比较,并为 GPT-3 上的大规模实验加入 WikiSQL(Zhong et al. 2017)(自然语言到 SQL)与 SAMSum(Gliwa et al. 2019)(对话摘要)。所用数据集更多细节见附录 C。全部实验使用 NVIDIA Tesla V100。
5.1 Baselines
To compare with other baselines broadly, we replicate the setups used by prior work and reuse their reported numbers whenever possible. This, however, means that some baselines might only appear in certain experiments.
为与其他基线广泛比较,我们复现先前工作使用的设定,并尽可能复用其报告数字。但这意味着某些基线可能只出现在部分实验中。
Fine-Tuning (FT) is a common approach for adaptation. During fine-tuning, the model is initialized to the pre-trained weights and biases, and all model parameters undergo gradient updates.A simple variant is to update only some layers while freezing others. We include one such baseline reported in prior work (Li & Liang 2021) on GPT-2, which adapts just the last two layers ().
Fine-Tuning (FT) 是常见的适配方法。微调时,模型初始化为预训练权重与偏置,全部模型参数接受梯度更新。简单变体是只更新某些层、冻结其余。我们纳入先前工作(Li & Liang 2021)在 GPT-2 上报告的一种基线:只适配最后两层()。
Bias-only or BitFit is a baseline where we only train the bias vectors while freezing everything else. Contemporarily, this baseline has also been studied by BitFit (Zaken et al. 2021).
Bias-only or BitFit 是只训练偏置向量、冻结其余一切的基线。同期,该基线也被 BitFit(Zaken et al. 2021)研究。
Prefix-embedding tuning (PreEmbed) inserts special tokens among the input tokens. These special tokens have trainable word embeddings and are generally not in the model’s vocabulary. Where to place such tokens can have an impact on performance. We focus on “prefixing”, which prepends such tokens to the prompt, and “infixing”, which appends to the prompt; both are discussed in Li & Liang 2021. We use (resp. ) denote the number of prefix (resp. infix) tokens. The number of trainable parameters is .
Prefix-embedding tuning (PreEmbed) 在输入 token 之间插入特殊 token。这些特殊 token 有可训练词嵌入,一般不在模型词表中。放置位置可影响表现。我们聚焦“prefixing”(把此类 token 加在提示前)与“infixing”(加在提示后);二者均在 Li & Liang 2021 中讨论。用 (或 )表示 prefix(或 infix)token 数。可训练参数数为 。
Prefix-layer tuning (PreLayer) is an extension to prefix-embedding tuning. Instead of just learning the word embeddings (or equivalently, the activations after the embedding layer) for some special tokens, we learn the activations after every Transformer layer. The activations computed from previous layers are simply replaced by trainable ones. The resulting number of trainable parameters is , where is the number of Transformer layers.
Prefix-layer tuning (PreLayer) 是对 prefix-embedding tuning 的扩展。不只学习某些特殊 token 的词嵌入(或等价地,嵌入层后的激活),我们学习每个 Transformer 层后的激活。由前层算出的激活直接被可训练激活替换。所得可训练参数数为 ,其中 为 Transformer 层数。
Adapter tuning as proposed in Houlsby et al. 2019 inserts adapter layers between the self-attention module (and the MLP module) and the subsequent residual connection. There are two fully connected layers with biases in an adapter layer with a nonlinearity in between. We call this original design . Recently, Lin et al. 2020 proposed a more efficient design with the adapter layer applied only after the MLP module and after a LayerNorm. We call it . This is very similar to another deign proposed in Pfeiffer et al. 2021, which we call . We also include another baseline call AdapterDrop (Rücklé et al. 2020) which drops some adapter layers for greater efficiency (). We cite numbers from prior works whenever possible to maximize the number of baselines we compare with; they are in rows with an asterisk (*) in the first column. In all cases, we have where is the number of adapter layers and the number of trainable LayerNorms (e.g., in ).
Adapter tuning 如 Houlsby et al. 2019 所提,在自注意力模块(以及 MLP 模块)与随后的残差连接之间插入 adapter 层。adapter 层中有两个带偏置的全连接层,中间有非线性。我们称该原始设计为 。近来 Lin et al. 2020 提出更高效设计:adapter 层仅加在 MLP 模块之后、并在 LayerNorm 之后。我们称之为 。这与 Pfeiffer et al. 2021 提出的另一设计非常相似,我们称之为 。我们还纳入另一基线 AdapterDrop(Rücklé et al. 2020),它丢掉部分 adapter 层以换取更高效率()。为最大化比较的基线数量,我们尽可能引用先前工作数字;它们位于第一列带星号 (*) 的行。在所有情形中,,其中 为 adapter 层数, 为可训练 LayerNorm 数。
LoRA adds trainable pairs of rank decomposition matrices in parallel to existing weight matrices. As mentioned in Section 4.2, we only apply LoRA to and in most experiments for simplicity. The number of trainable parameters is determined by the rank and the shape of the original weights: , where is the number of weight matrices we apply LoRA to.
LoRA 与现有权重矩阵并行地加入可训练的秩分解矩阵对。如第 4.2 节所述,多数实验中为简洁只对 与 应用 LoRA。可训练参数数由秩 与原权重形状决定:,其中 是我们应用 LoRA 的权重矩阵数。
5.2 RoBERTa base/large
| Model & Method | # Trainable | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| Parameters | MNLI | SST-2 | MRPC | CoLA | QNLI | QQP | RTE | STS-B | Avg. | |
| (FT)* | 125.0M | 87.6 | 94.8 | 90.2 | 63.6 | 92.8 | 91.9 | 78.7 | 91.2 | 86.4 |
| (BitFit)* | 0.1M | 84.7 | 93.7 | 92.7 | 62.0 | 91.8 | 84.0 | 81.5 | 90.8 | 85.2 |
| ()* | 0.3M | 87.1.0 | 94.2.1 | 88.51.1 | 60.8.4 | 93.1.1 | 90.2.0 | 71.52.7 | 89.7.3 | 84.4 |
| ()* | 0.9M | 87.3.1 | 94.7.3 | 88.4.1 | 62.6.9 | 93.0.2 | 90.6.0 | 75.92.2 | 90.3.1 | 85.4 |
| (LoRA) | 0.3M | 87.5.3 | 95.1.2 | 89.7.7 | 63.41.2 | 93.3.3 | 90.8.1 | 86.6.7 | 91.5.2 | 87.2 |
| (FT)* | 355.0M | 90.2 | 96.4 | 90.9 | 68.0 | 94.7 | 92.2 | 86.6 | 92.4 | 88.9 |
| (LoRA) | 0.8M | 90.6.2 | 96.2.5 | 90.91.2 | 68.21.9 | 94.9.3 | 91.6.1 | 87.42.5 | 92.6.2 | 89.0 |
| () | 3.0M | 90.2.3 | 96.1.3 | 90.2.7 | 68.31.0 | 94.8.2 | 91.9.1 | 83.82.9 | 92.1.7 | 88.4 |
| () | 0.8M | 90.5.3 | 96.6.2 | 89.71.2 | 67.82.5 | 94.8.3 | 91.7.2 | 80.12.9 | 91.9.4 | 87.9 |
| () | 6.0M | 89.9.5 | 96.2.3 | 88.72.9 | 66.54.4 | 94.7.2 | 92.1.1 | 83.41.1 | 91.01.7 | 87.8 |
| () | 0.8M | 90.3.3 | 96.3.5 | 87.71.7 | 66.32.0 | 94.7.2 | 91.5.1 | 72.92.9 | 91.5.5 | 86.4 |
| (LoRA) | 0.8M | 90.6.2 | 96.2.5 | 90.21.0 | 68.21.9 | 94.8.3 | 91.6.2 | 85.21.1 | 92.3.5 | 88.6 |
| (FT)* | 1500.0M | 91.8 | 97.2 | 92.0 | 72.0 | 96.0 | 92.7 | 93.9 | 92.9 | 91.1 |
| (LoRA) | 4.7M | 91.9.2 | 96.9.2 | 92.6.6 | 72.41.1 | 96.0.1 | 92.9.1 | 94.9.4 | 93.0.2 | 91.3 |
Table 2: , , and with different adaptation methods on the GLUE benchmark. We report the overall (matched and mismatched) accuracy for MNLI, Matthew’s correlation for CoLA, Pearson correlation for STS-B, and accuracy for other tasks. Higher is better for all metrics. * indicates numbers published in prior works. indicates runs configured in a setup similar to Houlsby et al. 2019 for a fair comparison.
表 2:RoBERTa base/large 在 GLUE 上不同适配方法的结果(数字与模型名保留)。
| Model & Method | # Trainable | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| Parameters | MNLI | SST-2 | MRPC | CoLA | QNLI | QQP | RTE | STS-B | Avg. | |
| (FT)* | 125.0M | 87.6 | 94.8 | 90.2 | 63.6 | 92.8 | 91.9 | 78.7 | 91.2 | 86.4 |
| (BitFit)* | 0.1M | 84.7 | 93.7 | 92.7 | 62.0 | 91.8 | 84.0 | 81.5 | 90.8 | 85.2 |
| ()* | 0.3M | 87.1.0 | 94.2.1 | 88.51.1 | 60.8.4 | 93.1.1 | 90.2.0 | 71.52.7 | 89.7.3 | 84.4 |
| ()* | 0.9M | 87.3.1 | 94.7.3 | 88.4.1 | 62.6.9 | 93.0.2 | 90.6.0 | 75.92.2 | 90.3.1 | 85.4 |
| (LoRA) | 0.3M | 87.5.3 | 95.1.2 | 89.7.7 | 63.41.2 | 93.3.3 | 90.8.1 | 86.6.7 | 91.5.2 | 87.2 |
| (FT)* | 355.0M | 90.2 | 96.4 | 90.9 | 68.0 | 94.7 | 92.2 | 86.6 | 92.4 | 88.9 |
| (LoRA) | 0.8M | 90.6.2 | 96.2.5 | 90.91.2 | 68.21.9 | 94.9.3 | 91.6.1 | 87.42.5 | 92.6.2 | 89.0 |
| () | 3.0M | 90.2.3 | 96.1.3 | 90.2.7 | 68.31.0 | 94.8.2 | 91.9.1 | 83.82.9 | 92.1.7 | 88.4 |
| () | 0.8M | 90.5.3 | 96.6.2 | 89.71.2 | 67.82.5 | 94.8.3 | 91.7.2 | 80.12.9 | 91.9.4 | 87.9 |
| () | 6.0M | 89.9.5 | 96.2.3 | 88.72.9 | 66.54.4 | 94.7.2 | 92.1.1 | 83.41.1 | 91.01.7 | 87.8 |
| () | 0.8M | 90.3.3 | 96.3.5 | 87.71.7 | 66.32.0 | 94.7.2 | 91.5.1 | 72.92.9 | 91.5.5 | 86.4 |
| (LoRA) | 0.8M | 90.6.2 | 96.2.5 | 90.21.0 | 68.21.9 | 94.8.3 | 91.6.2 | 85.21.1 | 92.3.5 | 88.6 |
| (FT)* | 1500.0M | 91.8 | 97.2 | 92.0 | 72.0 | 96.0 | 92.7 | 93.9 | 92.9 | 91.1 |
| (LoRA) | 4.7M | 91.9.2 | 96.9.2 | 92.6.6 | 72.41.1 | 96.0.1 | 92.9.1 | 94.9.4 | 93.0.2 | 91.3 |
Table 2: , , and with different adaptation methods on the GLUE benchmark. We report the overall (matched and mismatched) accuracy for MNLI, Matthew’s correlation for CoLA, Pearson correlation for STS-B, and accuracy for other tasks. Higher is better for all metrics. * indicates numbers published in prior works. indicates runs configured in a setup similar to Houlsby et al. 2019 for a fair comparison.
RoBERTa (Liu et al. 2019) optimized the pre-training recipe originally proposed in BERT (Devlin et al. 2019a) and boosted the latter’s task performance without introducing many more trainable parameters. While RoBERTa has been overtaken by much larger models on NLP leaderboards such as the GLUE benchmark (Wang et al. 2019) in recent years, it remains a competitive and popular pre-trained model for its size among practitioners. We take the pre-trained RoBERTa base (125M) and RoBERTa large (355M) from the HuggingFace Transformers library (Wolf et al. 2020) and evaluate the performance of different efficient adaptation approaches on tasks from the GLUE benchmark. We also replicate Houlsby et al. 2019 and Pfeiffer et al. 2021 according to their setup. To ensure a fair comparison, we make two crucial changes to how we evaluate LoRA when comparing with adapters. First, we use the same batch size for all tasks and use a sequence length of 128 to match the adapter baselines. Second, we initialize the model to the pre-trained model for MRPC, RTE, and STS-B, not a model already adapted to MNLI like the fine-tuning baseline. Runs following this more restricted setup from Houlsby et al. 2019 are labeled with . The result is presented in Table 2 (Top Three Sections). See Section D.1 for details on the hyperparameters used.
RoBERTa(Liu et al. 2019)优化了 BERT(Devlin et al. 2019a)最初提出的预训练配方,在不引入许多额外可训练参数的情况下提升了后者的任务表现。尽管近年来 RoBERTa 已被更大模型在 GLUE 等 NLP 排行榜上超越,但就体量而言,它在从业者中仍是有竞争力且流行的预训练模型。我们从 HuggingFace Transformers 库(Wolf et al. 2020)取预训练 RoBERTa base(125M)与 RoBERTa large(355M),在 GLUE 基准任务上评估不同高效适配方法的表现。我们还按各自设定复现 Houlsby et al. 2019 与 Pfeiffer et al. 2021。为保证公平比较,与 adapter 比较时我们对 LoRA 评估做两处关键改动。第一,所有任务使用相同 batch size,序列长度 128,以匹配 adapter 基线。第二,对 MRPC、RTE 与 STS-B,模型初始化为预训练模型,而非像微调基线那样已适配到 MNLI 的模型。
5.3 DeBERTa XXL
DeBERTa (He et al. 2021) is a more recent variant of BERT that is trained on a much larger scale and performs very competitively on benchmarks such as GLUE (Wang et al. 2019) and SuperGLUE (Wang et al. 2020). We evaluate if LoRA can still match the performance of a fully fine-tuned DeBERTa XXL (1.5B) on GLUE. The result is presented in Table 2 (Bottom Section). See Section D.2 for details on the hyperparameters used.
DeBERTa(He et al. 2021)是 BERT 更近的变体,以更大尺度训练,并在 GLUE(Wang et al. 2019)与 SuperGLUE(Wang et al. 2020)等基准上表现极具竞争力。我们评估 LoRA 能否在 GLUE 上仍匹配全量微调 DeBERTa XXL(1.5B)的表现。结果见表 2(下段)。所用超参细节见第 D.2 节。
5.4 GPT-2 medium/large
Having shown that LoRA can be a competitive alternative to full fine-tuning on NLU, we hope to answer if LoRA still prevails on NLG models, such as GPT-2 medium and large (Radford et al. b). We keep our setup as close as possible to Li & Liang 2021 for a direct comparison. Due to space constraint, we only present our result on E2E NLG Challenge (Table 3) in this section. See Section F.1 for results on WebNLG (Gardent et al. 2017) and DART (Nan et al. 2020). We include a list of the hyperparameters used in Section D.3.
在表明 LoRA 可作为 NLU 上全量微调的有竞争力替代后,我们希望回答:LoRA 在 NLG 模型(如 GPT-2 medium 与 large(Radford et al. b))上是否仍然占优。我们尽可能保持与 Li & Liang 2021 接近的设定以便直接比较。受篇幅限制,本节只给出 E2E NLG Challenge 结果(表 3)。WebNLG 与 DART 的额外结果见第 F.1 节(表 10–11)。
| Model & Method | # Trainable | E2E NLG Challenge | ||||
|---|---|---|---|---|---|---|
| Parameters | BLEU | NIST | MET | ROUGE-L | CIDEr | |
| GPT-2 M (FT)* | 354.92M | 68.2 | 8.62 | 46.2 | 71.0 | 2.47 |
| GPT-2 M ()* | 0.37M | 66.3 | 8.41 | 45.0 | 69.8 | 2.40 |
| GPT-2 M ()* | 11.09M | 68.9 | 8.71 | 46.1 | 71.3 | 2.47 |
| GPT-2 M () | 11.09M | 67.3.6 | 8.50.07 | 46.0.2 | 70.7.2 | 2.44.01 |
| GPT-2 M ()* | 25.19M | 68.1 | 8.59 | 46.0 | 70.8 | 2.41 |
| GPT-2 M (PreLayer)* | 0.35M | 69.7 | 8.81 | 46.1 | 71.4 | 2.49 |
| GPT-2 M (LoRA) | 0.35M | 70.4.1 | 8.85.02 | 46.8.2 | 71.8.1 | 2.53.02 |
| GPT-2 L (FT)* | 774.03M | 68.5 | 8.78 | 46.0 | 69.9 | 2.45 |
| GPT-2 L () | 0.88M | 69.1.1 | 8.68.03 | 46.3.0 | 71.4.2 | 2.49.0 |
| GPT-2 L () | 23.00M | 68.9.3 | 8.70.04 | 46.1.1 | 71.3.2 | 2.45.02 |
| GPT-2 L (PreLayer)* | 0.77M | 70.3 | 8.85 | 46.2 | 71.7 | 2.47 |
| GPT-2 L (LoRA) | 0.77M | 70.4.1 | 8.89.02 | 46.8.2 | 72.0.2 | 2.47.02 |
Table 3: GPT-2 medium (M) and large (L) with different adaptation methods on the E2E NLG Challenge. For all metrics, higher is better. LoRA outperforms several baselines with comparable or fewer trainable parameters. Confidence intervals are shown for experiments we ran. * indicates numbers published in prior works.
| Model & Method | # Trainable | E2E NLG Challenge | ||||
|---|---|---|---|---|---|---|
| Parameters | BLEU | NIST | MET | ROUGE-L | CIDEr | |
| GPT-2 M (FT)* | 354.92M | 68.2 | 8.62 | 46.2 | 71.0 | 2.47 |
| GPT-2 M ()* | 0.37M | 66.3 | 8.41 | 45.0 | 69.8 | 2.40 |
| GPT-2 M ()* | 11.09M | 68.9 | 8.71 | 46.1 | 71.3 | 2.47 |
| GPT-2 M () | 11.09M | 67.3.6 | 8.50.07 | 46.0.2 | 70.7.2 | 2.44.01 |
| GPT-2 M ()* | 25.19M | 68.1 | 8.59 | 46.0 | 70.8 | 2.41 |
| GPT-2 M (PreLayer)* | 0.35M | 69.7 | 8.81 | 46.1 | 71.4 | 2.49 |
| GPT-2 M (LoRA) | 0.35M | 70.4.1 | 8.85.02 | 46.8.2 | 71.8.1 | 2.53.02 |
| GPT-2 L (FT)* | 774.03M | 68.5 | 8.78 | 46.0 | 69.9 | 2.45 |
| GPT-2 L () | 0.88M | 69.1.1 | 8.68.03 | 46.3.0 | 71.4.2 | 2.49.0 |
| GPT-2 L () | 23.00M | 68.9.3 | 8.70.04 | 46.1.1 | 71.3.2 | 2.45.02 |
| GPT-2 L (PreLayer)* | 0.77M | 70.3 | 8.85 | 46.2 | 71.7 | 2.47 |
| GPT-2 L (LoRA) | 0.77M | 70.4.1 | 8.89.02 | 46.8.2 | 72.0.2 | 2.47.02 |
表 3:GPT-2 medium (M) 与 large (L) 在 E2E NLG Challenge 上不同适配方法的结果。所有指标越高越好。LoRA 以可比或更少的可训练参数超过若干基线。置信区间对应我们运行的实验。* 表示先前工作发表的数字。
| Model&Method | # Trainable | WikiSQL | MNLI-m | SAMSum |
|---|---|---|---|---|
| Parameters | Acc. (%) | Acc. (%) | R1/R2/RL | |
| GPT-3 (FT) | 175,255.8M | 73.8 | 89.5 | 52.0/28.0/44.5 |
| GPT-3 (BitFit) | 14.2M | 71.3 | 91.0 | 51.3/27.4/43.5 |
| GPT-3 (PreEmbed) | 3.2M | 63.1 | 88.6 | 48.3/24.2/40.5 |
| GPT-3 (PreLayer) | 20.2M | 70.1 | 89.5 | 50.8/27.3/43.5 |
| GPT-3 () | 7.1M | 71.9 | 89.8 | 53.0/28.9/44.8 |
| GPT-3 () | 40.1M | 73.2 | 91.5 | 53.2/29.0/45.1 |
| GPT-3 (LoRA) | 4.7M | 73.4 | 91.7 | 53.8/29.8/45.9 |
| GPT-3 (LoRA) | 37.7M | 74.0 | 91.6 | 53.4/29.2/45.1 |
Table 4: Performance of different adaptation methods on GPT-3 175B. We report the logical form validation accuracy on WikiSQL, validation accuracy on MultiNLI-matched, and Rouge-1/2/L on SAMSum. LoRA performs better than prior approaches, including full fine-tuning. The results on WikiSQL have a fluctuation around , MNLI-m around , and SAMSum around // for the three metrics.
| Model&Method | # Trainable | WikiSQL | MNLI-m | SAMSum |
|---|---|---|---|---|
| Parameters | Acc. (%) | Acc. (%) | R1/R2/RL | |
| GPT-3 (FT) | 175,255.8M | 73.8 | 89.5 | 52.0/28.0/44.5 |
| GPT-3 (BitFit) | 14.2M | 71.3 | 91.0 | 51.3/27.4/43.5 |
| GPT-3 (PreEmbed) | 3.2M | 63.1 | 88.6 | 48.3/24.2/40.5 |
| GPT-3 (PreLayer) | 20.2M | 70.1 | 89.5 | 50.8/27.3/43.5 |
| GPT-3 () | 7.1M | 71.9 | 89.8 | 53.0/28.9/44.8 |
| GPT-3 () | 40.1M | 73.2 | 91.5 | 53.2/29.0/45.1 |
| GPT-3 (LoRA) | 4.7M | 73.4 | 91.7 | 53.8/29.8/45.9 |
| GPT-3 (LoRA) | 37.7M | 74.0 | 91.6 | 53.4/29.2/45.1 |
表 4:GPT-3 175B 上不同适配方法的表现。我们报告 WikiSQL 逻辑形式验证准确率、MultiNLI-matched 验证准确率,以及 SAMSum 上的 Rouge-1/2/L。LoRA 优于包括全量微调在内的先前方法。WikiSQL 结果波动约 ,MNLI-m 约 ,SAMSum 三项约 //。
5.5 Scaling up to GPT-3 175B
As a final stress test for LoRA, we scale up to GPT-3 with 175 billion parameters. Due to the high training cost, we only report the typical standard deviation for a given task over random seeds, as opposed to providing one for every entry. See Section D.4 for details on the hyperparameters used.
作为对 LoRA 的最终压力测试,我们扩展到 1750 亿参数的 GPT-3。由于训练成本高,我们只报告给定任务上相对随机种子的典型标准差,而非为每个条目提供。所用超参见第 D.4 节。
As shown in Table 4, LoRA matches or exceeds the fine-tuning baseline on all three datasets. Note that not all methods benefit monotonically from having more trainable parameters, as shown in Figure 2. We observe a significant performance drop when we use more than 256 special tokens for prefix-embedding tuning or more than 32 special tokens for prefix-layer tuning. This corroborates similar observations in Li & Liang 2021. While a thorough investigation into this phenomenon is out-of-scope for this work, we suspect that having more special tokens causes the input distribution to shift further away from the pre-training data distribution. Separately, we investigate the performance of different adaptation approaches in the low-data regime in Section F.3.
如表 4 所示,LoRA 在全部三个数据集上匹配或超过微调基线。注意并非所有方法都随可训练参数增多而单调受益,见图 2。当我们为 prefix-embedding tuning 使用超过 256 个特殊 token,或为 prefix-layer tuning 使用超过 32 个特殊 token 时,观察到显著性能下降。这印证了 Li & Liang 2021 中的类似观察。对该现象的彻底研究超出本文范围,但我们怀疑更多特殊 token 会使输入分布进一步偏离预训练数据分布。另外,我们在第 F.3 节考察低数据设定下不同适配方法的表现。
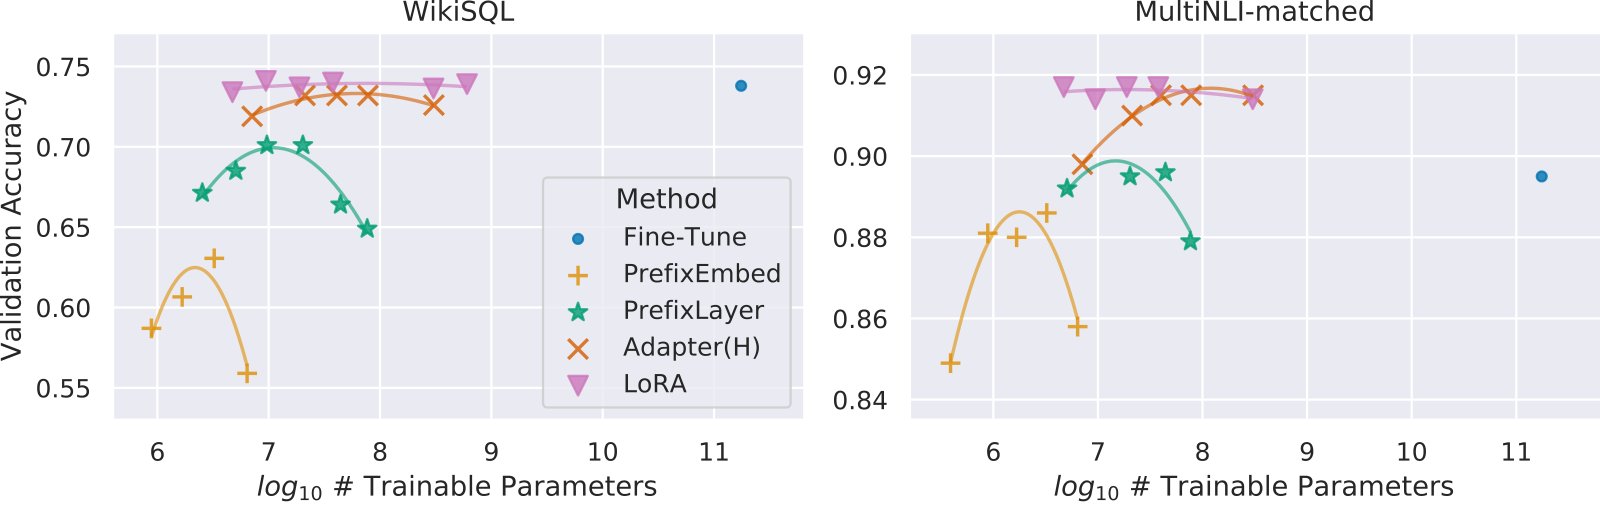
Figure 2: GPT-3 175B validation accuracy vs. number of trainable parameters of several adaptation methods on WikiSQL and MNLI-matched. LoRA exhibits better scalability and task performance. See Section F.2 for more details on the plotted data points.
图 2:GPT-3 175B 上若干适配方法在 WikiSQL 与 MNLI-matched 上的验证准确率相对可训练参数数。LoRA 展现更好的可扩展性与任务表现。所绘数据点细节见第 F.2 节。
6 Related Works
Transformer Language Models. Transformer (Vaswani et al. 2017) is a sequence-to-sequence architecture that makes heavy use of self-attention. Radford et al. a applied it to autoregressive language modeling by using a stack of Transformer decoders. Since then, Transformer-based language models have dominated NLP, achieving the state-of-the-art in many tasks. A new paradigm emerged with BERT (Devlin et al. 2019b) and GPT-2 (Radford et al. b) – both are large Transformer language models trained on a large amount of text – where fine-tuning on task-specific data after pre-training on general domain data provides a significant performance gain compared to training on task-specific data directly. Training larger Transformers generally results in better performance and remains an active research direction. GPT-3 (Brown et al. 2020) is the largest single Transformer language model trained to-date with 175B parameters.
Transformer Language Models. Transformer(Vaswani et al. 2017)是大量使用自注意力的序列到序列架构。Radford et al. a 通过堆叠 Transformer 解码器把它用于自回归语言建模。此后,基于 Transformer 的语言模型主导了 NLP,在许多任务上达到当时最好水平。BERT(Devlin et al. 2019b)与 GPT-2(Radford et al. b)——二者都是在大量文本上训练的大型 Transformer 语言模型——带来新范式:相对直接在任务数据上训练,先在通用领域预训练再在任务数据上微调能带来显著性能增益。训练更大的 Transformer 通常带来更好表现,仍是活跃研究方向。GPT-3(Brown et al. 2020)是当时训练过的最大单一 Transformer 语言模型,有 175B 参数。
Prompt Engineering and Fine-Tuning. While GPT-3 175B can adapt its behavior with just a few additional training examples, the result depends heavily on the input prompt (Brown et al. 2020). This necessitates an empirical art of composing and formatting the prompt to maximize a model’s performance on a desired task, which is known as prompt engineering or prompt hacking. Fine-tuning retrains a model pre-trained on general domains to a specific task Devlin et al. 2019b; Radford et al. a. Variants of it include learning just a subset of the parameters Devlin et al. 2019b; Collobert & Weston 2008, yet practitioners often retrain all of them to maximize the downstream performance. However, the enormity of GPT-3 175B makes it challenging to perform fine-tuning in the usual way due to the large checkpoint it produces and the high hardware barrier to entry since it has the same memory footprint as pre-training.
Prompt Engineering and Fine-Tuning. 虽然 GPT-3 175B 只需少量额外训练样本就能适配其行为,结果严重依赖输入提示(Brown et al. 2020)。这催生了组合与格式化提示以最大化模型在目标任务上表现的经验艺术,称为 prompt engineering 或 prompt hacking。微调把在通用领域预训练的模型再训练到特定任务(Devlin et al. 2019b; Radford et al. a)。其变体包括只学习参数子集(Devlin et al. 2019b; Collobert & Weston 2008),但从业者常重训全部参数以最大化下游表现。然而 GPT-3 175B 的体量使其难以按常规方式微调:它产生巨大检查点,且内存占用与预训练相同,硬件门槛很高。
Parameter-Efficient Adaptation. Many have proposed inserting adapter layers between existing layers in a neural network (Houlsby et al. 2019; Rebuffi et al. 2017; Lin et al. 2020). Our method uses a similar bottleneck structure to impose a low-rank constraint on the weight updates. The key functional difference is that our learned weights can be merged with the main weights during inference, thus not introducing any latency, which is not the case for the adapter layers (Section 3). A comtenporary extension of adapter is compacter (Mahabadi et al. 2021), which essentially parametrizes the adapter layers using Kronecker products with some predetermined weight sharing scheme. Similarly, combining LoRA with other tensor product-based methods could potentially improve its parameter efficiency, which we leave to future work. More recently, many proposed optimizing the input word embeddings in lieu of fine-tuning, akin to a continuous and differentiable generalization of prompt engineering (Li & Liang 2021; Lester et al. 2021; Hambardzumyan et al. 2020; Liu et al. 2021). We include comparisons with Li & Liang 2021 in our experiment section. However, this line of works can only scale up by using more special tokens in the prompt, which take up available sequence length for task tokens when positional embeddings are learned.
Parameter-Efficient Adaptation. 许多人提出在神经网络既有层之间插入 adapter 层(Houlsby et al. 2019; Rebuffi et al. 2017; Lin et al. 2020)。我们的方法使用类似瓶颈结构,对权重更新施加低秩约束。关键功能差别是:我们学到的权重可在推理时与主权重合并,因而不引入任何延迟,这对 adapter 层不成立(第 3 节)。同期的 adapter 扩展是 Compacter(Mahabadi et al. 2021),它本质上用带预定权重共享方案的 Kronecker 积参数化 adapter 层。类似地,把 LoRA 与其他基于张量积的方法结合有望进一步提升参数效率,我们留待未来工作。更近地,许多人提出优化输入词嵌入以代替微调,类似于 prompt engineering 的连续可微推广(Li & Liang 2021; Lester et al. 2021; Hambardzumyan et al. 2020; Liu et al. 2021)。实验部分纳入与 Li & Liang 2021 的比较。但这条工作线只能通过在提示中使用更多特殊 token 来扩展,而在学习位置嵌入时,这些 token 会占用可用于任务 token 的序列长度。
Low-Rank Structures in Deep Learning. Low-rank structure is very common in machine learning. A lot of machine learning problems have certain intrinsic low-rank structure (Li et al. 2016; Cai et al. 2010; Li et al. 2018b; Grasedyck et al. 2013). Moreover, it is known that for many deep learning tasks, especially those with a heavily over-parametrized neural network, the learned neural network will enjoy low-rank properties after training (Oymak et al. 2019). Some prior works even explicitly impose the low-rank constraint when training the original neural network (Sainath et al. 2013; Povey et al. 2018; Zhang et al. 2014; Jaderberg et al. 2014; Zhao et al. 2016; Khodak et al. 2021; Denil et al. 2014); however, to the best of our knowledge, none of these works considers low-rank update to a frozen model for adaptation to downstream tasks. In theory literature, it is known that neural networks outperform other classical learning methods, including the corresponding (finite-width) neural tangent kernels (Allen-Zhu et al. 2019; Li & Liang 2018) when the underlying concept class has certain low-rank structure (Ghorbani et al. 2020; Allen-Zhu & Li 2019; Allen-Zhu & Li 2020a). Another theoretical result in Allen-Zhu & Li 2020b suggests that low-rank adaptations can be useful for adversarial training. In sum, we believe that our proposed low-rank adaptation update is well-motivated by the literature.
Low-Rank Structures in Deep Learning. 低秩结构在机器学习中非常常见。许多机器学习问题具有某种本征低秩结构(Li et al. 2016; Cai et al. 2010; Li et al. 2018b; Grasedyck et al. 2013)。此外,已知对许多深度学习任务——尤其是严重过参数化的神经网络——训练后学得的网络会具有低秩性质(Oymak et al. 2019)。一些先前工作甚至在训练原始神经网络时显式施加低秩约束(Sainath et al. 2013; Povey et al. 2018; Zhang et al. 2014; Jaderberg et al. 2014; Zhao et al. 2016; Khodak et al. 2021; Denil et al. 2014);但据我们所知,这些工作都未考虑对冻结模型做低秩更新以适配下游任务。在理论文献中,已知当底层概念类具有某些低秩结构时,神经网络优于包括对应(有限宽)神经正切核在内的其他经典学习方法(Allen-Zhu et al. 2019; Li & Liang 2018; Ghorbani et al. 2020; Allen-Zhu & Li 2019; Allen-Zhu & Li 2020a)。Allen-Zhu & Li 2020b 的另一理论结果暗示低秩适配可对抗训练有用。总之,我们相信所提出的低秩适配更新有充分的文献动机。
7 Understanding the Low-Rank Updates
Given the empirical advantage of LoRA, we hope to further explain the properties of the low-rank adaptation learned from downstream tasks. Note that the low-rank structure not only lowers the hardware barrier to entry which allows us to run multiple experiments in parallel, but also gives better interpretability of how the update weights are correlated with the pre-trained weights. We focus our study on GPT-3 175B, where we achieved the largest reduction of trainable parameters (up to 10,000) without adversely affecting task performances.
鉴于 LoRA 的经验优势,我们希望进一步解释从下游任务学到的低秩适配的性质。注意低秩结构不仅降低硬件门槛、使我们能并行跑多个实验,还使更新权重如何与预训练权重相关更具可解释性。我们把研究聚焦于 GPT-3 175B,在此我们实现了最大的可训练参数缩减(最高约 10,000)且未损害任务表现。
We perform a sequence of empirical studies to answer the following questions: 1) Given a parameter budget constraint, which subset of weight matrices in a pre-trained Transformer should we adapt to maximize downstream performance? 2) Is the “optimal” adaptation matrix really rank-deficient? If so, what is a good rank to use in practice? 3) What is the connection between and ? Does highly correlate with ? How large is comparing to ?
我们做一系列实证研究以回答下列问题:1)给定参数预算约束,应适配预训练 Transformer 中哪一子集的权重矩阵以最大化下游表现?2)“最优”适配矩阵 是否真的秩亏?若是,实践中用多大的秩合适?3) 与 有何联系? 是否与 高度相关?相对 , 有多大?
We believe that our answers to question (2) and (3) shed light on the fundamental principles of using pre-trained language models for downstream tasks, which is a critical topic in NLP.
我们相信对问题 (2) 与 (3) 的回答,有助于阐明把预训练语言模型用于下游任务的基本原理——这是 NLP 中的关键议题。
7.1 Which Weight Matrices in Transformer Should We Apply LoRA to?
Given a limited parameter budget, which types of weights should we adapt with LoRA to obtain the best performance on downstream tasks? As mentioned in Section 4.2, we only consider weight matrices in the self-attention module. We set a parameter budget of 18M (roughly 35MB if stored in FP16) on GPT-3 175B, which corresponds to if we adapt one type of attention weights or if we adapt two types, for all 96 layers. The result is presented in Table 5.
给定有限参数预算,应把 LoRA 用在哪类权重上,才能在下游任务上取得最佳表现?如第 4.2 节所述,我们只考虑自注意力模块中的权重矩阵。我们在 GPT-3 175B 上设定 18M 参数预算(以 FP16 存储约 35MB),对应:若适配一类注意力权重则 ,若适配两类则 ,覆盖全部 96 层。结果见表 5。
| # of Trainable Parameters = 18M | |||||||
|---|---|---|---|---|---|---|---|
| Weight Type | |||||||
| Rank | 8 | 8 | 8 | 8 | 4 | 4 | 2 |
| WikiSQL (%) | 70.4 | 70.0 | 73.0 | 73.2 | 71.4 | 73.7 | 73.7 |
| MultiNLI (%) | 91.0 | 90.8 | 91.0 | 91.3 | 91.3 | 91.3 | 91.7 |
Table 5: Validation accuracy on WikiSQL and MultiNLI after applying LoRA to different types of attention weights in GPT-3, given the same number of trainable parameters. Adapting both and gives the best performance overall. We find the standard deviation across random seeds to be consistent for a given dataset, which we report in the first column.
| # of Trainable Parameters = 18M | |||||||
|---|---|---|---|---|---|---|---|
| Weight Type | |||||||
| Rank | 8 | 8 | 8 | 8 | 4 | 4 | 2 |
| WikiSQL (%) | 70.4 | 70.0 | 73.0 | 73.2 | 71.4 | 73.7 | 73.7 |
| MultiNLI (%) | 91.0 | 90.8 | 91.0 | 91.3 | 91.3 | 91.3 | 91.7 |
表 5:在可训练参数数相同的条件下,对 GPT-3 不同类型注意力权重应用 LoRA 后在 WikiSQL 与 MultiNLI 上的验证准确率。同时适配 与 总体表现最好。我们发现给定数据集上跨随机种子的标准差一致,报告于第一列。
Note that putting all the parameters in or results in significantly lower performance, while adapting both and yields the best result. This suggests that even a rank of four captures enough information in such that it is preferable to adapt more weight matrices than adapting a single type of weights with a larger rank.
注意:把全部参数放在 或 上会导致显著更低的表现,而同时适配 与 给出最佳结果。这表明即便秩为四也足以捕捉 中的足够信息,因而更宜适配更多权重矩阵,而非用更大的秩只适配单一类型权重。
7.2 What is the Optimal Rank for LoRA?
We turn our attention to the effect of rank on model performance. We adapt , , and just for a comparison.
我们转而关注秩 对模型表现的影响。我们适配 、,以及仅 以便比较。
| Weight Type | ||||||
|---|---|---|---|---|---|---|
| WikiSQL(%) | 68.8 | 69.6 | 70.5 | 70.4 | 70.0 | |
| 73.4 | 73.3 | 73.7 | 73.8 | 73.5 | ||
| 74.1 | 73.7 | 74.0 | 74.0 | 73.9 | ||
| MultiNLI (%) | 90.7 | 90.9 | 91.1 | 90.7 | 90.7 | |
| 91.3 | 91.4 | 91.3 | 91.6 | 91.4 | ||
| 91.2 | 91.7 | 91.7 | 91.5 | 91.4 |
Table 6: Validation accuracy on WikiSQL and MultiNLI with different rank . To our surprise, a rank as small as one suffices for adapting both and on these datasets while training alone needs a larger . We conduct a similar experiment on GPT-2 in Section H.2.
| Weight Type | ||||||
|---|---|---|---|---|---|---|
| WikiSQL(%) | 68.8 | 69.6 | 70.5 | 70.4 | 70.0 | |
| 73.4 | 73.3 | 73.7 | 73.8 | 73.5 | ||
| 74.1 | 73.7 | 74.0 | 74.0 | 73.9 | ||
| MultiNLI (%) | 90.7 | 90.9 | 91.1 | 90.7 | 90.7 | |
| 91.3 | 91.4 | 91.3 | 91.6 | 91.4 | ||
| 91.2 | 91.7 | 91.7 | 91.5 | 91.4 |
表 6:不同秩 在 WikiSQL 与 MultiNLI 上的验证准确率。令我们惊讶的是:在这些数据集上同时适配 与 时,小至 1 的秩已足够;而只训练 需要更大的 。我们在第 H.2 节对 GPT-2 做了类似实验。
Table 6shows that, surprisingly, LoRA already performs competitively with a very small (more so for than just ). This suggests the update matrix could have a very small ‘‘intrinsic rank”.[^6] To further support this finding, we check the overlap of the subspaces learned by different choices of and by different random seeds. We argue that increasing does not cover a more meaningful subspace, which suggests that a low-rank adaptation matrix is sufficient.
表 6 表明:令人惊讶的是,极小的 已使 LoRA 表现具有竞争力(对 尤甚于仅 )。这暗示更新矩阵 可能具有非常小的“本征秩”。[^6] 为进一步支持该发现,我们检查不同 选择以及不同随机种子所学子空间的重叠。我们主张增大 并不会覆盖更有意义的子空间,这表明低秩适配矩阵已足够。
Subspace similarity between different . Given and which are the learned adaptation matrices with rank and using the same pre-trained model, we perform singular value decomposition and obtain the right-singular unitary matrices and .[^7] We hope to answer: how much of the subspace spanned by the top singular vectors in (for ) is contained in the subspace spanned by top singular vectors of (for )? We measure this quantity with a normalized subspace similarity based on the Grassmann distance (See Appendix G for a more formal discussion)
Subspace similarity between different . 给定用同一预训练模型学到的秩 与 的适配矩阵 与 ,我们做奇异值分解并得到右奇异酉矩阵 与 。[^7] 我们希望回答: 中前 个奇异向量张成的子空间(),有多少包含在 前 个奇异向量张成的子空间中()?我们用基于 Grassmann 距离的归一化子空间相似度衡量该量(更形式化讨论见附录 G)
where represents the columns of corresponding to the top- singular vectors.
其中 表示 中对应前 个奇异向量的列。
has a range of , where represents a complete overlap of subspaces and a complete separation. See Figure 3 for how changes as we vary and . We only look at the 48th layer (out of 96) due to space constraint, but the conclusion holds for other layers as well, as shown in Section H.1.
取值范围为 ,其中 表示子空间完全重叠, 表示完全分离。见图 3 了解随 与 变化时 如何变化。受篇幅限制我们只看第 48 层(共 96 层),但结论对其余层同样成立,见第 H.1 节。
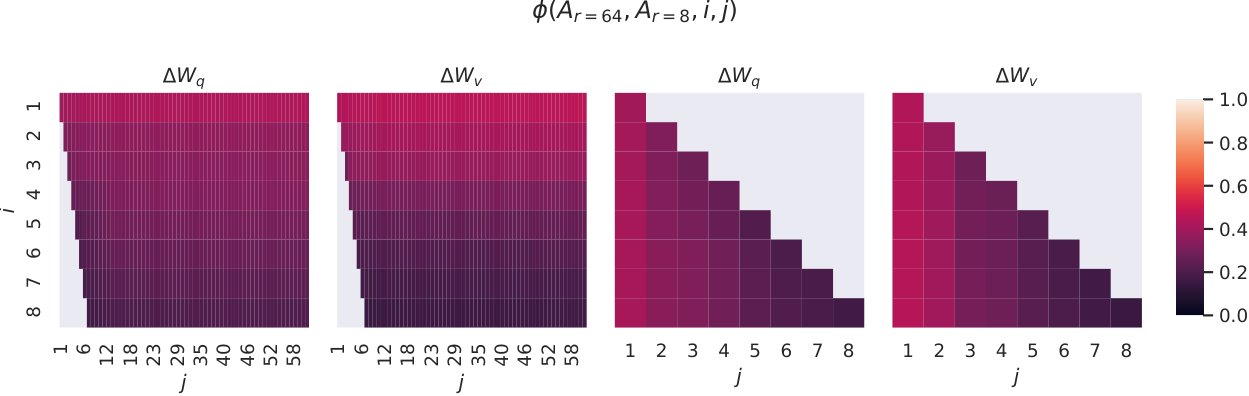
Figure 3: Subspace similarity between column vectors of and for both and . The third and the fourth figures zoom in on the lower-left triangle in the first two figures. The top directions in are included in , and vice versa.
图 3: 与 列向量之间的子空间相似度(对 与 )。第三、四图放大前两图左下三角。 的顶部方向包含在 中,反之亦然。
We make an important observation from Figure 3.
我们从图 3 得出重要观察。
Directions corresponding to the top singular vector overlap significantly between and , while others do not. Specifically, (resp. ) of and (resp. ) of share a subspace of dimension 1 with normalized similarity , providing an explanation of why performs quite well in our downstream tasks for GPT-3.
对应顶部奇异向量的方向在 与 之间显著重叠,而其他方向则不然。具体地, 的 (或 )与 的 (或 )共享归一化相似度 的一维子空间,这解释了为何 在我们 GPT-3 下游任务上已表现相当好。
Since both and are learned using the same pre-trained model, Figure 3 indicates that the top singular-vector directions of and are the most useful, while other directions potentially contain mostly random noises accumulated during training. Hence, the adaptation matrix can indeed have a very low rank.
由于 与 用同一预训练模型学得,图 3 表明二者的顶部奇异向量方向最有用,而其他方向可能主要包含训练中累积的随机噪声。因此,适配矩阵确实可以具有很低的秩。
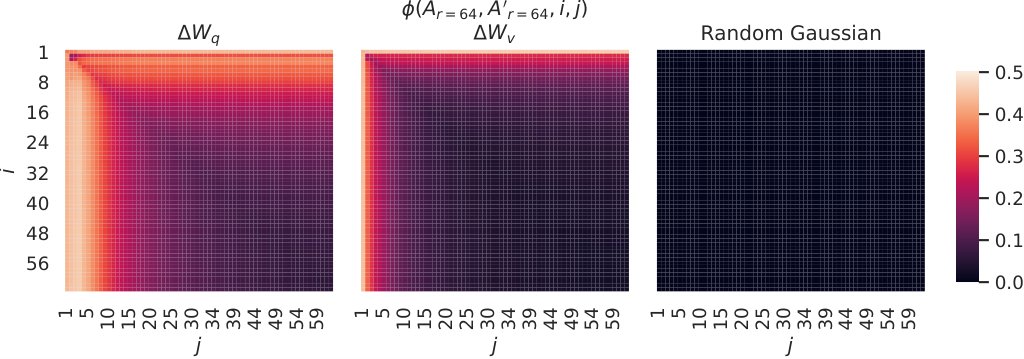
Figure 4: Left and Middle: Normalized subspace similarity between the column vectors of from two random seeds, for both and in the 48-th layer. Right: the same heat-map between the column vectors of two random Gaussian matrices. See Section H.1 for other layers.
图 4:左与中:两个随机种子得到的 列向量之间的归一化子空间相似度(第 48 层的 与 )。右:两个随机高斯矩阵列向量之间的相同热图。其他层见第 H.1 节。
Subspace similarity between different random seeds. We further confirm this by plotting the normalized subspace similarity between two randomly seeded runs with , shown in Figure 4. appears to have a higher “intrinsic rank” than , since more common singular value directions are learned by both runs for , which is in line with our empirical observation in Table 6. As a comparison, we also plot two random Gaussian matrices, which do not share any common singular value directions with each other.
Subspace similarity between different random seeds. 我们进一步通过绘制两个随机种子、 运行之间的归一化子空间相似度来确认这一点,见图 4。 似乎比 有更高的“本征秩”,因为两次运行对 学到更多共同奇异值方向,这与表 6 中的经验观察一致。作为对照,我们也绘制两个随机高斯矩阵,它们彼此不共享任何共同奇异值方向。
7.3 How Does the Adaptation Matrix Compare to ?
We further investigate the relationship between and . In particular, does highly correlate with ? (Or mathematically, is mostly contained in the top singular directions of ?) Also, how “large” is comparing to its corresponding directions in ? This can shed light on the underlying mechanism for adapting pre-trained language models.
我们进一步考察 与 的关系。特别地, 是否与 高度相关?(或在数学上, 是否主要落在 的顶部奇异方向中?)另外,相对 中对应方向, 有多“大”?这有助于阐明适配预训练语言模型的底层机制。
To answer these questions, we project onto the -dimensional subspace of by computing , with / being the left/right singular-vector matrix of . Then, we compare the Frobenius norm between and . As a comparison, we also compute by replacing with the top singular vectors of or a random matrix.
为回答这些问题,我们通过计算 把 投影到 的 维子空间上,其中 / 为 的左/右奇异向量矩阵。然后比较 与 。作为对照,我们也用 的前 个奇异向量或随机矩阵替换 来计算 。
| Random | Random | |||||
| 0.32 | 21.67 | 0.02 | 1.90 | 37.71 | 0.33 | |
Table 7: The Frobenius norm of where and are the left/right top singular vector directions of either (1) , (2) , or (3) a random matrix. The weight matrices are taken from the 48th layer of GPT-3.
| Random | Random | |||||
| 0.32 | 21.67 | 0.02 | 1.90 | 37.71 | 0.33 | |
表 7: 的 Frobenius 范数,其中 与 分别为 (1) 、(2) 或 (3) 随机矩阵的左/右前 奇异向量方向。权重矩阵取自 GPT-3 第 48 层。
We draw several conclusions from Table 7. First, has a stronger correlation with compared to a random matrix, indicating that amplifies some features that are already in . Second, instead of repeating the top singular directions of , only amplifies directions that are not emphasized in . Third, the amplification factor is rather huge: for . See Section H.4 for why has a smaller amplification factor. We also provide a visualization in Section H.3 for how the correlation changes as we include more top singular directions from . This suggests that the low-rank adaptation matrix potentially amplifies the important features for specific downstream tasks that were learned but not emphasized in the general pre-training model.
我们从表 7 得出若干结论。第一,相对随机矩阵, 与 有更强相关,表明 放大了 中已有的某些特征。第二, 并非重复 的顶部奇异方向,而只放大在 中未被强调的方向。第三,放大因子相当大:对 ,。为何 有更小放大因子见第 H.4 节。我们还在第 H.3 节提供可视化,展示随纳入更多来自 的顶部奇异方向,相关如何变化。这表明低秩适配矩阵有可能放大通用预训练模型已学到、但未强调的、对特定下游任务重要的特征。
8 Conclusion and Future Work
Fine-tuning enormous language models is prohibitively expensive in terms of the hardware required and the storage/switching cost for hosting independent instances for different tasks. We propose LoRA, an efficient adaptation strategy that neither introduces inference latency nor reduces input sequence length while retaining high model quality. Importantly, it allows for quick task-switching when deployed as a service by sharing the vast majority of the model parameters. While we focused on Transformer language models, the proposed principles are generally applicable to any neural networks with dense layers.
微调超大语言模型在硬件需求以及为不同任务托管独立实例的存储/切换成本上代价过高。我们提出 LoRA:一种既不引入推理延迟、也不缩短输入序列长度,同时保持高模型质量的高效适配策略。重要的是,它允许在作为服务部署时通过共享绝大多数模型参数实现快速任务切换。虽然我们聚焦 Transformer 语言模型,所提出的原则一般适用于任何含稠密层的神经网络。
There are many directions for future works. 1) LoRA can be combined with other efficient adaptation methods, potentially providing orthogonal improvement. 2) The mechanism behind fine-tuning or LoRA is far from clear – how are features learned during pre-training transformed to do well on downstream tasks? We believe that LoRA makes it more tractable to answer this than full fine-tuning. 3) We mostly depend on heuristics to select the weight matrices to apply LoRA to. Are there more principled ways to do it? 4) Finally, the rank-deficiency of suggests that could be rank-deficient as well, which can also be a source of inspiration for future works.
未来工作有许多方向。1)LoRA 可与其他高效适配方法结合,潜在提供正交改进。2)微调或 LoRA 背后的机制远未清楚——预训练期间学到的特征如何被转化为在下游任务上表现良好?我们相信相对全量微调,LoRA 使回答该问题更可行。3)我们多依赖启发式选择应用 LoRA 的权重矩阵。是否有更有原则的做法?4)最后, 的秩亏缺暗示 也可能秩亏,这也可成为未来工作的灵感来源。
References
Aghajanyan et al. (2020) Armen Aghajanyan, Luke Zettlemoyer, and Sonal Gupta. Intrinsic Dimensionality Explains the Effectiveness of Language Model Fine-Tuning. arXiv:2012.13255 [cs] , December 2020. URL http://arxiv.org/abs/2012.13255 .
Allen-Zhu & Li (2019) Zeyuan Allen-Zhu and Yuanzhi Li. What Can ResNet Learn Efficiently, Going Beyond Kernels? In NeurIPS , 2019. Full version available at http://arxiv.org/abs/1905.10337 .
Allen-Zhu & Li (2020a) Zeyuan Allen-Zhu and Yuanzhi Li. Backward feature correction: How deep learning performs deep learning. arXiv preprint arXiv:2001.04413 , 2020a.
Allen-Zhu & Li (2020b) Zeyuan Allen-Zhu and Yuanzhi Li. Feature purification: How adversarial training performs robust deep learning. arXiv preprint arXiv:2005.10190 , 2020b.
Allen-Zhu et al. (2019) Zeyuan Allen-Zhu, Yuanzhi Li, and Zhao Song. A convergence theory for deep learning via over-parameterization. In ICML , 2019. Full version available at http://arxiv.org/abs/1811.03962 .
Ba et al. (2016) Jimmy Lei Ba, Jamie Ryan Kiros, and Geoffrey E. Hinton. Layer normalization, 2016.
Brown et al. (2020) Tom B. Brown, Benjamin Mann, Nick Ryder, Melanie Subbiah, Jared Kaplan, Prafulla Dhariwal, Arvind Neelakantan, Pranav Shyam, Girish Sastry, Amanda Askell, Sandhini Agarwal, Ariel Herbert-Voss, Gretchen Krueger, Tom Henighan, Rewon Child, Aditya Ramesh, Daniel M. Ziegler, Jeffrey Wu, Clemens Winter, Christopher Hesse, Mark Chen, Eric Sigler, Mateusz Litwin, Scott Gray, Benjamin Chess, Jack Clark, Christopher Berner, Sam McCandlish, Alec Radford, Ilya Sutskever, and Dario Amodei. Language Models are Few-Shot Learners. arXiv:2005.14165 [cs] , July 2020. URL http://arxiv.org/abs/2005.14165 .
Cai et al. (2010) Jian-Feng Cai, Emmanuel J Candès, and Zuowei Shen. A singular value thresholding algorithm for matrix completion. SIAM Journal on optimization , 20(4):1956–1982, 2010.
Cer et al. (2017) Daniel Cer, Mona Diab, Eneko Agirre, Inigo Lopez-Gazpio, and Lucia Specia. Semeval-2017 task 1: Semantic textual similarity multilingual and crosslingual focused evaluation. Proceedings of the 11th International Workshop on Semantic Evaluation (SemEval-2017) , 2017. doi: 10.18653/v1/s17-2001 . URL http://dx.doi.org/10.18653/v1/S17-2001 .
Collobert & Weston (2008) Ronan Collobert and Jason Weston. A unified architecture for natural language processing: deep neural networks with multitask learning. In Proceedings of the 25th international conference on Machine learning , ICML ’08, pp. 160–167, New York, NY, USA, July 2008. Association for Computing Machinery. ISBN 978-1-60558-205-4. doi: 10.1145/1390156.1390177 . URL https://doi.org/10.1145/1390156.1390177 .
Denil et al. (2014) Misha Denil, Babak Shakibi, Laurent Dinh, Marc’Aurelio Ranzato, and Nando de Freitas. Predicting parameters in deep learning, 2014.
Devlin et al. (2019a) Jacob Devlin, Ming-Wei Chang, Kenton Lee, and Kristina Toutanova. Bert: Pre-training of deep bidirectional transformers for language understanding, 2019a.
Devlin et al. (2019b) Jacob Devlin, Ming-Wei Chang, Kenton Lee, and Kristina Toutanova. BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding. arXiv:1810.04805 [cs] , May 2019b. URL http://arxiv.org/abs/1810.04805 . arXiv: 1810.04805.
Dolan & Brockett (2005) William B. Dolan and Chris Brockett. Automatically constructing a corpus of sentential paraphrases. In Proceedings of the Third International Workshop on Paraphrasing (IWP2005) , 2005. URL https://aclanthology.org/I05-5002 .
Gardent et al. (2017) Claire Gardent, Anastasia Shimorina, Shashi Narayan, and Laura Perez-Beltrachini. The webnlg challenge: Generating text from rdf data. In Proceedings of the 10th International Conference on Natural Language Generation , pp. 124–133, 2017.
Ghorbani et al. (2020) Behrooz Ghorbani, Song Mei, Theodor Misiakiewicz, and Andrea Montanari. When do neural networks outperform kernel methods? arXiv preprint arXiv:2006.13409 , 2020.
Gliwa et al. (2019) Bogdan Gliwa, Iwona Mochol, Maciej Biesek, and Aleksander Wawer. Samsum corpus: A human-annotated dialogue dataset for abstractive summarization. CoRR , abs/1911.12237, 2019. URL http://arxiv.org/abs/1911.12237 .
Grasedyck et al. (2013) Lars Grasedyck, Daniel Kressner, and Christine Tobler. A literature survey of low-rank tensor approximation techniques. GAMM-Mitteilungen , 36(1):53–78, 2013.
Ham & Lee (2008) Jihun Ham and Daniel D. Lee. Grassmann discriminant analysis: a unifying view on subspace-based learning. In ICML , pp. 376–383, 2008. URL https://doi.org/10.1145/1390156.1390204 .
Hambardzumyan et al. (2020) Karen Hambardzumyan, Hrant Khachatrian, and Jonathan May. WARP: Word-level Adversarial ReProgramming. arXiv:2101.00121 [cs] , December 2020. URL http://arxiv.org/abs/2101.00121 . arXiv: 2101.00121.
He et al. (2021) Pengcheng He, Xiaodong Liu, Jianfeng Gao, and Weizhu Chen. Deberta: Decoding-enhanced bert with disentangled attention, 2021.
Houlsby et al. (2019) Neil Houlsby, Andrei Giurgiu, Stanislaw Jastrzebski, Bruna Morrone, Quentin de Laroussilhe, Andrea Gesmundo, Mona Attariyan, and Sylvain Gelly. Parameter-Efficient Transfer Learning for NLP. arXiv:1902.00751 [cs, stat] , June 2019. URL http://arxiv.org/abs/1902.00751 .
Jaderberg et al. (2014) Max Jaderberg, Andrea Vedaldi, and Andrew Zisserman. Speeding up convolutional neural networks with low rank expansions. arXiv preprint arXiv:1405.3866 , 2014.
Khodak et al. (2021) Mikhail Khodak, Neil Tenenholtz, Lester Mackey, and Nicolò Fusi. Initialization and regularization of factorized neural layers, 2021.
Kingma & Ba (2017) Diederik P. Kingma and Jimmy Ba. Adam: A method for stochastic optimization, 2017.
Lepikhin et al. (2020) Dmitry Lepikhin, HyoukJoong Lee, Yuanzhong Xu, Dehao Chen, Orhan Firat, Yanping Huang, Maxim Krikun, Noam Shazeer, and Zhifeng Chen. Gshard: Scaling giant models with conditional computation and automatic sharding, 2020.
Lester et al. (2021) Brian Lester, Rami Al-Rfou, and Noah Constant. The Power of Scale for Parameter-Efficient Prompt Tuning. arXiv:2104.08691 [cs] , April 2021. URL http://arxiv.org/abs/2104.08691 . arXiv: 2104.08691.
Li et al. (2018a) Chunyuan Li, Heerad Farkhoor, Rosanne Liu, and Jason Yosinski. Measuring the Intrinsic Dimension of Objective Landscapes. arXiv:1804.08838 [cs, stat] , April 2018a. URL http://arxiv.org/abs/1804.08838 . arXiv: 1804.08838.
Li & Liang (2021) Xiang Lisa Li and Percy Liang. Prefix-Tuning: Optimizing Continuous Prompts for Generation. arXiv:2101.00190 [cs] , January 2021. URL http://arxiv.org/abs/2101.00190 .
Li & Liang (2018) Yuanzhi Li and Yingyu Liang. Learning overparameterized neural networks via stochastic gradient descent on structured data. In Advances in Neural Information Processing Systems , 2018.
Li et al. (2016) Yuanzhi Li, Yingyu Liang, and Andrej Risteski. Recovery guarantee of weighted low-rank approximation via alternating minimization. In International Conference on Machine Learning , pp. 2358–2367. PMLR, 2016.
Li et al. (2018b) Yuanzhi Li, Tengyu Ma, and Hongyang Zhang. Algorithmic regularization in over-parameterized matrix sensing and neural networks with quadratic activations. In Conference On Learning Theory , pp. 2–47. PMLR, 2018b.
Lin et al. (2020) Zhaojiang Lin, Andrea Madotto, and Pascale Fung. Exploring versatile generative language model via parameter-efficient transfer learning. In Findings of the Association for Computational Linguistics: EMNLP 2020 , pp. 441–459, Online, November 2020. Association for Computational Linguistics. doi: 10.18653/v1/2020.findings-emnlp.41 . URL https://aclanthology.org/2020.findings-emnlp.41 .
Liu et al. (2021) Xiao Liu, Yanan Zheng, Zhengxiao Du, Ming Ding, Yujie Qian, Zhilin Yang, and Jie Tang. GPT Understands, Too. arXiv:2103.10385 [cs] , March 2021. URL http://arxiv.org/abs/2103.10385 . arXiv: 2103.10385.
Liu et al. (2019) Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, and Veselin Stoyanov. Roberta: A robustly optimized bert pretraining approach, 2019.
Loshchilov & Hutter (2017) Ilya Loshchilov and Frank Hutter. Decoupled weight decay regularization. arXiv preprint arXiv:1711.05101 , 2017.
Loshchilov & Hutter (2019) Ilya Loshchilov and Frank Hutter. Decoupled weight decay regularization, 2019.
Mahabadi et al. (2021) Rabeeh Karimi Mahabadi, James Henderson, and Sebastian Ruder. Compacter: Efficient low-rank hypercomplex adapter layers, 2021.
Nan et al. (2020) Linyong Nan, Dragomir Radev, Rui Zhang, Amrit Rau, Abhinand Sivaprasad, Chiachun Hsieh, Xiangru Tang, Aadit Vyas, Neha Verma, Pranav Krishna, et al. Dart: Open-domain structured data record to text generation. arXiv preprint arXiv:2007.02871 , 2020.
Novikova et al. (2017) Jekaterina Novikova, Ondřej Dušek, and Verena Rieser. The e2e dataset: New challenges for end-to-end generation. arXiv preprint arXiv:1706.09254 , 2017.
Oymak et al. (2019) Samet Oymak, Zalan Fabian, Mingchen Li, and Mahdi Soltanolkotabi. Generalization guarantees for neural networks via harnessing the low-rank structure of the jacobian. arXiv preprint arXiv:1906.05392 , 2019.
Pfeiffer et al. (2021) Jonas Pfeiffer, Aishwarya Kamath, Andreas Rücklé, Kyunghyun Cho, and Iryna Gurevych. Adapterfusion: Non-destructive task composition for transfer learning, 2021.
Povey et al. (2018) Daniel Povey, Gaofeng Cheng, Yiming Wang, Ke Li, Hainan Xu, Mahsa Yarmohammadi, and Sanjeev Khudanpur. Semi-orthogonal low-rank matrix factorization for deep neural networks. In Interspeech , pp. 3743–3747, 2018.
Radford et al. (a) Alec Radford, Karthik Narasimhan, Tim Salimans, and Ilya Sutskever. Improving Language Understanding by Generative Pre-Training. pp. 12, a.
Radford et al. (b) Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei, and Ilya Sutskever. Language Models are Unsupervised Multitask Learners. pp. 24, b.
Rajpurkar et al. (2018) Pranav Rajpurkar, Robin Jia, and Percy Liang. Know what you don’t know: Unanswerable questions for squad. CoRR , abs/1806.03822, 2018. URL http://arxiv.org/abs/1806.03822 .
Rebuffi et al. (2017) Sylvestre-Alvise Rebuffi, Hakan Bilen, and Andrea Vedaldi. Learning multiple visual domains with residual adapters. arXiv:1705.08045 [cs, stat] , November 2017. URL http://arxiv.org/abs/1705.08045 . arXiv: 1705.08045.
Rücklé et al. (2020) Andreas Rücklé, Gregor Geigle, Max Glockner, Tilman Beck, Jonas Pfeiffer, Nils Reimers, and Iryna Gurevych. Adapterdrop: On the efficiency of adapters in transformers, 2020.
Sainath et al. (2013) Tara N Sainath, Brian Kingsbury, Vikas Sindhwani, Ebru Arisoy, and Bhuvana Ramabhadran. Low-rank matrix factorization for deep neural network training with high-dimensional output targets. In 2013 IEEE international conference on acoustics, speech and signal processing , pp. 6655–6659. IEEE, 2013.
Shoeybi et al. (2020) Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper, and Bryan Catanzaro. Megatron-lm: Training multi-billion parameter language models using model parallelism, 2020.
Socher et al. (2013) Richard Socher, Alex Perelygin, Jean Wu, Jason Chuang, Christopher D. Manning, Andrew Ng, and Christopher Potts. Recursive deep models for semantic compositionality over a sentiment treebank. In Proceedings of the 2013 Conference on Empirical Methods in Natural Language Processing , pp. 1631–1642, Seattle, Washington, USA, October 2013. Association for Computational Linguistics. URL https://aclanthology.org/D13-1170 .
Vaswani et al. (2017) Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Łukasz Kaiser, and Illia Polosukhin. Attention is all you need. In Proceedings of the 31st International Conference on Neural Information Processing Systems , pp. 6000–6010, 2017.
Wang et al. (2019) Alex Wang, Amanpreet Singh, Julian Michael, Felix Hill, Omer Levy, and Samuel R. Bowman. Glue: A multi-task benchmark and analysis platform for natural language understanding, 2019.
Wang et al. (2020) Alex Wang, Yada Pruksachatkun, Nikita Nangia, Amanpreet Singh, Julian Michael, Felix Hill, Omer Levy, and Samuel R. Bowman. Superglue: A stickier benchmark for general-purpose language understanding systems, 2020.
Warstadt et al. (2018) Alex Warstadt, Amanpreet Singh, and Samuel R Bowman. Neural network acceptability judgments. arXiv preprint arXiv:1805.12471 , 2018.
Williams et al. (2018) Adina Williams, Nikita Nangia, and Samuel Bowman. A broad-coverage challenge corpus for sentence understanding through inference. In Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers) , pp. 1112–1122, New Orleans, Louisiana, June 2018. Association for Computational Linguistics. doi: 10.18653/v1/N18-1101 . URL https://www.aclweb.org/anthology/N18-1101 .
Wolf et al. (2020) Thomas Wolf, Lysandre Debut, Victor Sanh, Julien Chaumond, Clement Delangue, Anthony Moi, Pierric Cistac, Tim Rault, Rémi Louf, Morgan Funtowicz, Joe Davison, Sam Shleifer, Patrick von Platen, Clara Ma, Yacine Jernite, Julien Plu, Canwen Xu, Teven Le Scao, Sylvain Gugger, Mariama Drame, Quentin Lhoest, and Alexander M. Rush. Transformers: State-of-the-art natural language processing. In Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing: System Demonstrations , pp. 38–45, Online, October 2020. Association for Computational Linguistics. URL https://www.aclweb.org/anthology/2020.emnlp-demos.6 .
Yang & Hu (2021) Greg Yang and Edward J. Hu. Feature Learning in Infinite-Width Neural Networks. arXiv:2011.14522 [cond-mat] , May 2021. URL http://arxiv.org/abs/2011.14522 . arXiv: 2011.14522.
Zaken et al. (2021) Elad Ben Zaken, Shauli Ravfogel, and Yoav Goldberg. Bitfit: Simple parameter-efficient fine-tuning for transformer-based masked language-models, 2021.
Zhang et al. (2014) Yu Zhang, Ekapol Chuangsuwanich, and James Glass. Extracting deep neural network bottleneck features using low-rank matrix factorization. In 2014 IEEE international conference on acoustics, speech and signal processing (ICASSP) , pp. 185–189. IEEE, 2014.
Zhao et al. (2016) Yong Zhao, Jinyu Li, and Yifan Gong. Low-rank plus diagonal adaptation for deep neural networks. In 2016 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) , pp. 5005–5009. IEEE, 2016.
Zhong et al. (2017) Victor Zhong, Caiming Xiong, and Richard Socher. Seq2sql: Generating structured queries from natural language using reinforcement learning. CoRR , abs/1709.00103, 2017. URL http://arxiv.org/abs/1709.00103 .
Appendix A Large Language Models Still Need Parameter Updates
Few-shot learning, or prompt engineering, is very advantageous when we only have a handful of training samples. However, in practice, we can often afford to curate a few thousand or more training examples for performance-sensitive applications. As shown in Table 8, fine-tuning improves the model performance drastically compared to few-shot learning on datasets large and small. We take the GPT-3 few-shot result on RTE from the GPT-3 paper (Brown et al. 2020). For MNLI-matched, we use two demonstrations per class and six in-context examples in total.
当只有少量训练样本时,少样本学习或 prompt engineering 很有优势。但实践中,对性能敏感的应用我们往往能负担整理数千甚至更多训练样本。如表 8 所示,相对少样本学习,微调在或大或小的数据集上都大幅提升模型表现。我们取 GPT-3 论文(Brown et al. 2020)中 RTE 上的 GPT-3 少样本结果。对 MNLI-matched,我们每类用两个示范,上下文中共六个例子。
| Method | MNLI-m (Val. Acc./%) | RTE (Val. Acc./%) |
|---|---|---|
| GPT-3 Few-Shot | 40.6 | 69.0 |
| GPT-3 Fine-Tuned | 89.5 | 85.4 |
Table 8: Fine-tuning significantly outperforms few-shot learning on GPT-3 (Brown et al. 2020).
| Method | MNLI-m (Val. Acc./%) | RTE (Val. Acc./%) |
|---|---|---|
| GPT-3 Few-Shot | 40.6 | 69.0 |
| GPT-3 Fine-Tuned | 89.5 | 85.4 |
表 8:相对少样本学习,微调在 GPT-3(Brown et al. 2020)上显著更好。
Appendix B Inference Latency Introduced by Adapter Layers
Adapter layers are external modules added to a pre-trained model in a sequential manner, whereas our proposal, LoRA, can be seen as external modules added in a parallel manner. Consequently, adapter layers must be computed in addition to the base model, inevitably introducing additional latency. While as pointed out in Rücklé et al. 2020, the latency introduced by adapter layers can be mitigated when the model batch size and/or sequence length is large enough to full utilize the hardware parallelism. We confirm their observation with a similar latency study on GPT-2 medium and point out that there are scenarios, notably online inference where the batch size is small, where the added latency can be significant.
Adapter 层是以串行方式加到预训练模型上的外部模块,而我们的提议 LoRA 可视为以并行方式加入的外部模块。因此,adapter 层必须在基座模型之外额外计算,不可避免引入额外延迟。尽管如 Rücklé et al. 2020 所指出,当模型 batch size 和/或序列长度足够大以充分利用硬件并行时,adapter 层引入的延迟可被缓解。我们在 GPT-2 medium 上用类似延迟研究确认了他们的观察,并指出在某些场景——尤其是 batch size 很小的在线推理——增加的延迟可能显著。
We measure the latency of a single forward pass on an NVIDIA Quadro RTX8000 by averaging over 100 trials. We vary the input batch size, sequence length, and the adapter bottleneck dimension . We test two adapter designs: the original one by Houlsby et al. 2019, which we call , and a recent, more efficient variant by Lin et al. 2020, which we call . See Section 5.1 for more details on the designs. We plot the slow-down in percentage compared to the no-adapter baseline in Figure 5.
我们在 NVIDIA Quadro RTX8000 上对单次前向延迟做 100 次试验平均。我们改变输入 batch size、序列长度与 adapter 瓶颈维 。我们测试两种 adapter 设计:Houlsby et al. 2019 的原始设计,称为 ;以及 Lin et al. 2020 更近、更高效的变体,称为 。设计细节见第 5.1 节。我们在图 5 中绘制相对无 adapter 基线的百分比减速。
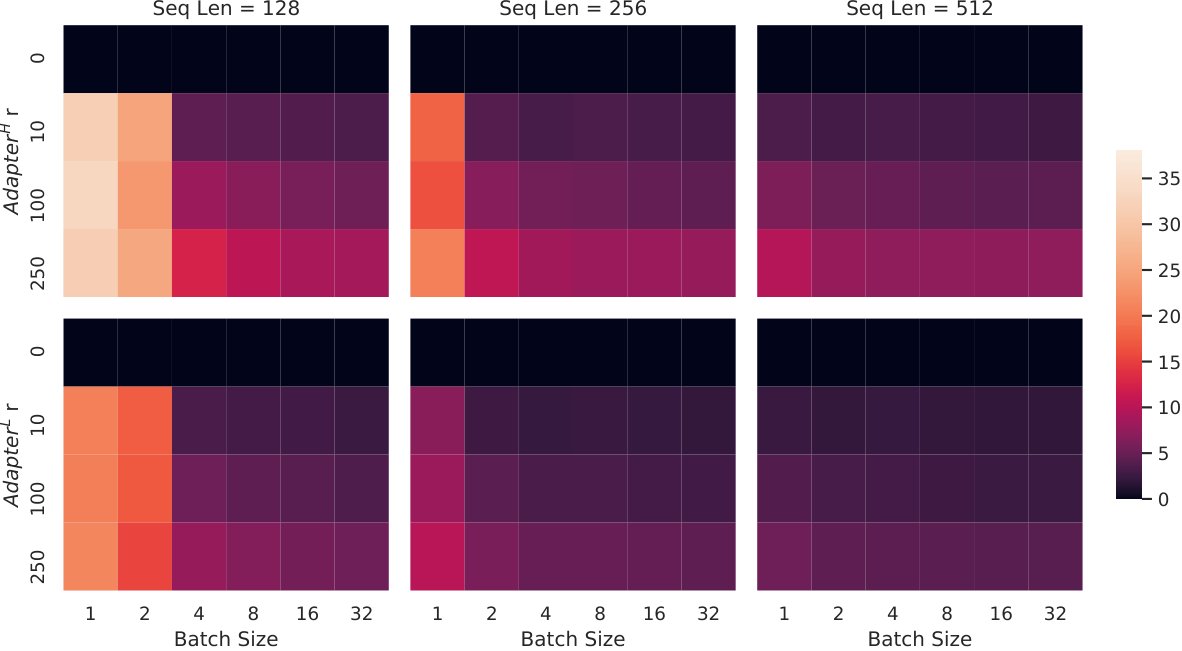
Figure 5: Percentage slow-down of inference latency compared to the no-adapter () baseline. The top row shows the result for and the bottom row . Larger batch size and sequence length help to mitigate the latency, but the slow-down can be as high as over 30% in an online, short-sequence-length scenario. We tweak the colormap for better visibility.
图 5:相对无 adapter()基线的推理延迟百分比减速。上行是 ,下行是 。更大的 batch size 与序列长度有助于缓解延迟,但在在线、短序列场景中减速可超过 30%。我们调整色图以更清晰。
Appendix C Dataset Details
GLUE Benchmark is a wide-ranging collection of natural language understanding tasks. It includes MNLI (inference, Williams et al. 2018), SST-2 (sentiment analysis, Socher et al. 2013), MRPC (paraphrase detection, Dolan & Brockett 2005), CoLA (linguistic acceptability, Warstadt et al. 2018), QNLI (inference, Rajpurkar et al. 2018), QQP[^8] (question-answering), RTE (inference), and STS-B (textual similarity, Cer et al. 2017). The broad coverage makes GLUE benchmark a standard metric to evaluate NLU models such as RoBERTa and DeBERTa. The individual datasets are released under different permissive licenses.
GLUE Benchmark 是覆盖广泛的自然语言理解任务集合。它包括 MNLI(推理,Williams et al. 2018)、SST-2(情感分析,Socher et al. 2013)、MRPC(释义检测,Dolan & Brockett 2005)、CoLA(语言可接受性,Warstadt et al. 2018)、QNLI(推理,Rajpurkar et al. 2018)、QQP[^8](问答)、RTE(推理)与 STS-B(文本相似度,Cer et al. 2017)。广泛覆盖使 GLUE 成为评估 RoBERTa、DeBERTa 等 NLU 模型的标准指标。各数据集以不同宽松许可证发布。
WikiSQL is introduced in Zhong et al. 2017 and contains / training/validation examples. The task is to generate SQL queries from natural language questions and table schemata. We encode context as and target as . The dataset is release under the BSD 3-Clause License.
WikiSQL 由 Zhong et al. 2017 引入,含 / 个训练/验证样本。任务是从自然语言问题与表模式生成 SQL 查询。我们把上下文编码为 ,目标为 。数据集以 BSD 3-Clause 许可证发布。
SAMSum is introduced in Gliwa et al. 2019 and contains / training/test examples. It consists of staged chat conversations between two people and corresponding abstractive summaries written by linguists. We encode context as ”\n” concatenated utterances followed by a ”\n\n”, and target as . The dataset is released under the non-commercial licence: Creative Commons BY-NC-ND 4.0.
SAMSum 由 Gliwa et al. 2019 引入,含 / 个训练/测试样本。它由两个人之间的编排聊天对话,以及语言学家撰写的对应抽象摘要组成。我们把上下文编码为用 ”\n” 拼接的话语后接 ”\n\n”,目标为 。数据集以非商业许可证 Creative Commons BY-NC-ND 4.0 发布。
E2E NLG Challenge was first introduced in Novikova et al. 2017 as a dataset for training end-to-end, data-driven natural language generation systems and is commonly used for data-to-text evaluation. The E2E dataset consists of roughly training, validation, and test examples from the restaurant domain. Each source table used as input can have multiple references. Each sample input consists of a sequence of slot-value pairs, along with a corresponding natural language reference text. The dataset is released under Creative Commons BY-NC-SA 4.0.
E2E NLG Challenge 最早由 Novikova et al. 2017 引入,用作训练端到端、数据驱动自然语言生成系统的数据集,并常用于 data-to-text 评估。E2E 数据集约有 训练、 验证与 测试样本,来自餐厅领域。用作输入的每个源表可有多个参考。每个样本输入 由一串槽–值对以及对应的自然语言参考文本组成。数据集以 Creative Commons BY-NC-SA 4.0 发布。
DART is an open-domain data-to-text dataset described in Nan et al. 2020. DART inputs are structured as sequences of ENTITY — RELATION — ENTITY triples. With examples in total, DART is a significantly larger and more complex data-to-text task compared to E2E. The dataset is released under the MIT license.
DART 是 Nan et al. 2020 描述的开放域 data-to-text 数据集。DART 输入被组织为 ENTITY — RELATION — ENTITY 三元组序列。总计约 样本,相对 E2E,DART 是显著更大且更复杂的 data-to-text 任务。数据集以 MIT 许可证发布。
WebNLG is another commonly used dataset for data-to-text evaluation (Gardent et al. 2017). With examples in total WebNLG comprises 14 distinct categories, nine of which are seen during training. Since five of the 14 total categories are not seen during training, but are represented in the test set, evaluation is typically broken out by “seen” categories (S), “unseen” categories (U) and “all” (A). Each input example is represented by a sequence of SUBJECT — PROPERTY — OBJECT triples. The dataset is released under Creative Commons BY-NC-SA 4.0.
WebNLG 是另一常用的 data-to-text 评估数据集(Gardent et al. 2017)。总计约 样本,涵盖 14 个不同类别,其中 9 个在训练中见过。由于 14 类中有 5 类训练未见但出现在测试集,评估通常按“已见”类别(S)、“未见”类别(U)与“全部”(A)分别报告。每个输入样本表示为 SUBJECT — PROPERTY — OBJECT 三元组序列。数据集以 Creative Commons BY-NC-SA 4.0 发布。
Appendix D Hyperparameters Used in Experiments
D.1 RoBERTa
We train using AdamW with a linear learning rate decay schedule. We sweep learning rate, number of training epochs, and batch size for LoRA. Following Liu et al. 2019, we initialize the LoRA modules to our best MNLI checkpoint when adapting to MRPC, RTE, and STS-B, instead of the usual initialization; the pre-trained model stays frozen for all tasks. We report the median over 5 random seeds; the result for each run is taken from the best epoch. For a fair comparison with the setup in Houlsby et al. 2019 and Pfeiffer et al. 2021, we restrict the model sequence length to 128 and used a fixed batch size for all tasks. Importantly, we start with the pre-trained RoBERTa large model when adapting to MRPC, RTE, and STS-B, instead of a model already adapted to MNLI. The runs with this restricted setup are marked with . See the hyperparameters used in our runs in Table 9.
我们用 AdamW 与线性学习率衰减日程训练。对 LoRA 扫描学习率、训练 epoch 数与 batch size。遵循 Liu et al. 2019,适配 MRPC、RTE 与 STS-B 时把 LoRA 模块初始化为我们最好的 MNLI 检查点,而非通常初始化;预训练模型对所有任务保持冻结。我们报告 5 个随机种子的中位数;每次运行取最佳 epoch 的结果。为与 Houlsby et al. 2019 与 Pfeiffer et al. 2021 的设定公平比较,我们把模型序列长度限制为 128,并对所有任务使用固定 batch size。重要的是,适配 MRPC、RTE 与 STS-B 时从预训练 RoBERTa large 起步,而非已适配到 MNLI 的模型。该受限设定下的运行标以 。所用超参见表 9。
| Method | Dataset | MNLI | SST-2 | MRPC | CoLA | QNLI | QQP | RTE | STS-B |
|---|---|---|---|---|---|---|---|---|---|
| Optimizer | AdamW | ||||||||
| Warmup Ratio | 0.06 | ||||||||
| LR Schedule | Linear | ||||||||
| RoBERTa base LoRA | Batch Size | 16 | 16 | 16 | 32 | 32 | 16 | 32 | 16 |
| # Epochs | 30 | 60 | 30 | 80 | 25 | 25 | 80 | 40 | |
| Learning Rate | 5E-04 | 5E-04 | 4E-04 | 4E-04 | 4E-04 | 5E-04 | 5E-04 | 4E-04 | |
| LoRA Config. | |||||||||
| LoRA | 8 | ||||||||
| Max Seq. Len. | 512 | ||||||||
| RoBERTa large LoRA | Batch Size | 4 | 4 | 4 | 4 | 4 | 4 | 8 | 8 |
| # Epochs | 10 | 10 | 20 | 20 | 10 | 20 | 20 | 30 | |
| Learning Rate | 3E-04 | 4E-04 | 3E-04 | 2E-04 | 2E-04 | 3E-04 | 4E-04 | 2E-04 | |
| LoRA Config. | |||||||||
| LoRA | 16 | ||||||||
| Max Seq. Len. | 128 | 128 | 512 | 128 | 512 | 512 | 512 | 512 | |
| RoBERTa large LoRA | Batch Size | 4 | |||||||
| # Epochs | 10 | 10 | 20 | 20 | 10 | 20 | 20 | 10 | |
| Learning Rate | 3E-04 | 4E-04 | 3E-04 | 2E-04 | 2E-04 | 3E-04 | 4E-04 | 2E-04 | |
| LoRA Config. | |||||||||
| LoRA | 16 | ||||||||
| Max Seq. Len. | 128 | ||||||||
| RoBERTa large (3M) | Batch Size | 32 | |||||||
| # Epochs | 10 | 20 | 20 | 20 | 10 | 20 | 20 | 20 | |
| Learning Rate | 3E-05 | 3E-05 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | |
| Bottleneck | 64 | ||||||||
| Max Seq. Len. | 128 | ||||||||
| RoBERTa large (0.8M) | Batch Size | 32 | |||||||
| # Epochs | 5 | 20 | 20 | 20 | 10 | 20 | 20 | 20 | |
| Learning Rate | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | |
| Bottleneck | 16 | ||||||||
| Max Seq. Len. | 128 | ||||||||
| RoBERTa large (6M) | Batch Size | 32 | |||||||
| # Epochs | 10 | 5 | 10 | 10 | 5 | 20 | 20 | 10 | |
| Learning Rate | 3E-05 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | |
| Bottleneck | 64 | ||||||||
| Max Seq. Len. | 128 | ||||||||
| RoBERTa large (0.8M) | Batch Size | 32 | |||||||
| # Epochs | 10 | 5 | 10 | 10 | 5 | 20 | 20 | 10 | |
| Learning Rate | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | |
| Bottleneck | 8 | ||||||||
| Max Seq. Len. | 128 |
Table 9: The hyperparameters we used for RoBERTa on the GLUE benchmark.
| Method | Dataset | MNLI | SST-2 | MRPC | CoLA | QNLI | QQP | RTE | STS-B |
|---|---|---|---|---|---|---|---|---|---|
| Optimizer | AdamW | ||||||||
| Warmup Ratio | 0.06 | ||||||||
| LR Schedule | Linear | ||||||||
| RoBERTa base LoRA | Batch Size | 16 | 16 | 16 | 32 | 32 | 16 | 32 | 16 |
| # Epochs | 30 | 60 | 30 | 80 | 25 | 25 | 80 | 40 | |
| Learning Rate | 5E-04 | 5E-04 | 4E-04 | 4E-04 | 4E-04 | 5E-04 | 5E-04 | 4E-04 | |
| LoRA Config. | |||||||||
| LoRA | 8 | ||||||||
| Max Seq. Len. | 512 | ||||||||
| RoBERTa large LoRA | Batch Size | 4 | 4 | 4 | 4 | 4 | 4 | 8 | 8 |
| # Epochs | 10 | 10 | 20 | 20 | 10 | 20 | 20 | 30 | |
| Learning Rate | 3E-04 | 4E-04 | 3E-04 | 2E-04 | 2E-04 | 3E-04 | 4E-04 | 2E-04 | |
| LoRA Config. | |||||||||
| LoRA | 16 | ||||||||
| Max Seq. Len. | 128 | 128 | 512 | 128 | 512 | 512 | 512 | 512 | |
| RoBERTa large LoRA | Batch Size | 4 | |||||||
| # Epochs | 10 | 10 | 20 | 20 | 10 | 20 | 20 | 10 | |
| Learning Rate | 3E-04 | 4E-04 | 3E-04 | 2E-04 | 2E-04 | 3E-04 | 4E-04 | 2E-04 | |
| LoRA Config. | |||||||||
| LoRA | 16 | ||||||||
| Max Seq. Len. | 128 | ||||||||
| RoBERTa large (3M) | Batch Size | 32 | |||||||
| # Epochs | 10 | 20 | 20 | 20 | 10 | 20 | 20 | 20 | |
| Learning Rate | 3E-05 | 3E-05 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | |
| Bottleneck | 64 | ||||||||
| Max Seq. Len. | 128 | ||||||||
| RoBERTa large (0.8M) | Batch Size | 32 | |||||||
| # Epochs | 5 | 20 | 20 | 20 | 10 | 20 | 20 | 20 | |
| Learning Rate | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | |
| Bottleneck | 16 | ||||||||
| Max Seq. Len. | 128 | ||||||||
| RoBERTa large (6M) | Batch Size | 32 | |||||||
| # Epochs | 10 | 5 | 10 | 10 | 5 | 20 | 20 | 10 | |
| Learning Rate | 3E-05 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | |
| Bottleneck | 64 | ||||||||
| Max Seq. Len. | 128 | ||||||||
| RoBERTa large (0.8M) | Batch Size | 32 | |||||||
| # Epochs | 10 | 5 | 10 | 10 | 5 | 20 | 20 | 10 | |
| Learning Rate | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | 3E-04 | |
| Bottleneck | 8 | ||||||||
| Max Seq. Len. | 128 |
表 9: The hyperparameters we used for RoBERTa on the GLUE benchmark.
D.2 DeBERTa
We again train using AdamW with a linear learning rate decay schedule. Following He et al. 2021, we tune learning rate, dropout probability, warm-up steps, and batch size. We use the same model sequence length used by (He et al. 2021) to keep our comparison fair. Following He et al. 2021, we initialize the LoRA modules to our best MNLI checkpoint when adapting to MRPC, RTE, and STS-B, instead of the usual initialization; the pre-trained model stays frozen for all tasks. We report the median over 5 random seeds; the result for each run is taken from the best epoch. See the hyperparameters used in our runs in Table 10.
我们再次用 AdamW 与线性学习率衰减日程训练。遵循 He et al. 2021,调节学习率、dropout 概率、warm-up 步数与 batch size。使用与(He et al. 2021)相同的模型序列长度以保持比较公平。遵循 He et al. 2021,适配 MRPC、RTE 与 STS-B 时把 LoRA 模块初始化为我们最好的 MNLI 检查点,而非通常初始化;预训练模型对所有任务保持冻结。我们报告 5 个随机种子的中位数;每次运行取最佳 epoch 的结果。所用超参见表 10。
| Method | Dataset | MNLI | SST-2 | MRPC | CoLA | QNLI | QQP | RTE | STS-B |
|---|---|---|---|---|---|---|---|---|---|
| Optimizer | AdamW | ||||||||
| Warmup Ratio | 0.1 | ||||||||
| LR Schedule | Linear | ||||||||
| DeBERTa XXL LoRA | Batch Size | 8 | 8 | 32 | 4 | 6 | 8 | 4 | 4 |
| # Epochs | 5 | 16 | 30 | 10 | 8 | 11 | 11 | 10 | |
| Learning Rate | 1E-04 | 6E-05 | 2E-04 | 1E-04 | 1E-04 | 1E-04 | 2E-04 | 2E-04 | |
| Weight Decay | 0 | 0.01 | 0.01 | 0 | 0.01 | 0.01 | 0.01 | 0.1 | |
| CLS Dropout | 0.15 | 0 | 0 | 0.1 | 0.1 | 0.2 | 0.2 | 0.2 | |
| LoRA Config. | |||||||||
| LoRA | 8 | ||||||||
| Max Seq. Len. | 256 | 128 | 128 | 64 | 512 | 320 | 320 | 128 |
Table 10: The hyperparameters for DeBERTa XXL on tasks included in the GLUE benchmark.
| Method | Dataset | MNLI | SST-2 | MRPC | CoLA | QNLI | QQP | RTE | STS-B |
|---|---|---|---|---|---|---|---|---|---|
| Optimizer | AdamW | ||||||||
| Warmup Ratio | 0.1 | ||||||||
| LR Schedule | Linear | ||||||||
| DeBERTa XXL LoRA | Batch Size | 8 | 8 | 32 | 4 | 6 | 8 | 4 | 4 |
| # Epochs | 5 | 16 | 30 | 10 | 8 | 11 | 11 | 10 | |
| Learning Rate | 1E-04 | 6E-05 | 2E-04 | 1E-04 | 1E-04 | 1E-04 | 2E-04 | 2E-04 | |
| Weight Decay | 0 | 0.01 | 0.01 | 0 | 0.01 | 0.01 | 0.01 | 0.1 | |
| CLS Dropout | 0.15 | 0 | 0 | 0.1 | 0.1 | 0.2 | 0.2 | 0.2 | |
| LoRA Config. | |||||||||
| LoRA | 8 | ||||||||
| Max Seq. Len. | 256 | 128 | 128 | 64 | 512 | 320 | 320 | 128 |
表 10:DeBERTa XXL 在 GLUE 基准所含任务上的超参。
D.3 GPT-2
We train all of our GPT-2 models using AdamW (Loshchilov & Hutter 2017) with a linear learning rate schedule for 5 epochs. We use the batch size, learning rate, and beam search beam size described in Li & Liang 2021. Accordingly, we also tune the above hyperparameters for LoRA. We report the mean over 3 random seeds; the result for each run is taken from the best epoch. The hyperparameters used for LoRA in GPT-2 are listed in Table 11. For those used for other baselines, see Li & Liang 2021.
我们用 AdamW(Loshchilov & Hutter 2017)与线性学习率日程训练全部 GPT-2 模型,共 5 个 epoch。使用 Li & Liang 2021 所述的 batch size、学习率与束搜索束宽。相应地,我们也为 LoRA 调节上述超参。报告 3 个随机种子的均值;每次运行取最佳 epoch。GPT-2 上 LoRA 所用超参见表 11。其他基线所用超参见 Li & Liang 2021。
| Dataset | E2E | WebNLG | DART |
|---|---|---|---|
| Training | |||
| Optimizer | AdamW | ||
| Weight Decay | 0.01 | 0.01 | 0.0 |
| Dropout Prob | 0.1 | 0.1 | 0.0 |
| Batch Size | 8 | ||
| # Epoch | 5 | ||
| Warmup Steps | 500 | ||
| Learning Rate Schedule | Linear | ||
| Label Smooth | 0.1 | 0.1 | 0.0 |
| Learning Rate | 0.0002 | ||
| Adaptation | |||
| LoRA | 32 | ||
| Inference | |||
| Beam Size | 10 | ||
| Length Penalty | 0.9 | 0.8 | 0.8 |
| no repeat ngram size | 4 |
Table 11: The hyperparameters for GPT-2 LoRA on E2E, WebNLG and DART.
| Dataset | E2E | WebNLG | DART |
|---|---|---|---|
| Training | |||
| Optimizer | AdamW | ||
| Weight Decay | 0.01 | 0.01 | 0.0 |
| Dropout Prob | 0.1 | 0.1 | 0.0 |
| Batch Size | 8 | ||
| # Epoch | 5 | ||
| Warmup Steps | 500 | ||
| Learning Rate Schedule | Linear | ||
| Label Smooth | 0.1 | 0.1 | 0.0 |
| Learning Rate | 0.0002 | ||
| Adaptation | |||
| LoRA | 32 | ||
| Inference | |||
| Beam Size | 10 | ||
| Length Penalty | 0.9 | 0.8 | 0.8 |
| no repeat ngram size | 4 |
表 11:GPT-2 LoRA 在 E2E、WebNLG 与 DART 上的超参。
D.4 GPT-3
For all GPT-3 experiments, we train using AdamW (Loshchilov & Hutter 2017) for 2 epochs with a batch size of 128 samples and a weight decay factor of 0.1. We use a sequence length of 384 for WikiSQL (Zhong et al. 2017), 768 for MNLI (Williams et al. 2018), and 2048 for SAMSum (Gliwa et al. 2019). We tune learning rate for all method-dataset combinations. See Section D.4 for more details on the hyperparameters used. For prefix-embedding tuning, we find the optimal and to be 256 and 8, respectively, totalling trainable parameters. We use and for prefix-layer tuning with trainable parameters to obtain the overall best performance. We present two parameter budgets for LoRA: 4.7M ( or ) and 37.7M ( or ). We report the best validation performance from each run. The training hyperparameters used in our GPT-3 experiments are listed in Table 12.
对所有 GPT-3 实验,我们用 AdamW(Loshchilov & Hutter 2017)训练 2 个 epoch,batch size 为 128 样本,权重衰减因子为 0.1。WikiSQL(Zhong et al. 2017)序列长度 384,MNLI(Williams et al. 2018)为 768,SAMSum(Gliwa et al. 2019)为 2048。我们对所有方法–数据集组合调节学习率。对 prefix-embedding tuning,我们发现最优 与 分别为 256 与 8,合计 可训练参数。对 prefix-layer tuning 我们用 与 ,共 可训练参数以获得总体最佳表现。我们为 LoRA 给出两个参数预算:4.7M( 或 )与 37.7M( 或 )。我们报告每次运行的最佳验证表现。
| Hyperparameters | Fine-Tune | PreEmbed | PreLayer | BitFit | LoRA | |
|---|---|---|---|---|---|---|
| Optimizer | AdamW | |||||
| Batch Size | 128 | |||||
| # Epoch | 2 | |||||
| Warmup Tokens | 250,000 | |||||
| LR Schedule | Linear | |||||
| Learning Rate | 5.00E-06 | 5.00E-04 | 1.00E-04 | 1.6E-03 | 1.00E-04 | 2.00E-04 |
Table 12: The training hyperparameters used for different GPT-3 adaption methods. We use the same hyperparameters for all datasets after tuning learning rate.
| Hyperparameters | Fine-Tune | PreEmbed | PreLayer | BitFit | LoRA | |
|---|---|---|---|---|---|---|
| Optimizer | AdamW | |||||
| Batch Size | 128 | |||||
| # Epoch | 2 | |||||
| Warmup Tokens | 250,000 | |||||
| LR Schedule | Linear | |||||
| Learning Rate | 5.00E-06 | 5.00E-04 | 1.00E-04 | 1.6E-03 | 1.00E-04 | 2.00E-04 |
表 12:不同 GPT-3 适配方法所用训练超参。调节学习率后,所有数据集使用相同超参。
Appendix E Combining LoRA with Prefix Tuning
LoRA can be naturally combined with existing prefix-based approaches. In this section, we evaluate two combinations of LoRA and variants of prefix-tuning on WikiSQL and MNLI.
LoRA 可自然与现有基于 prefix 的方法结合。本节我们在 WikiSQL 与 MNLI 上评估 LoRA 与 prefix-tuning 变体的两种组合。
LoRA+PrefixEmbed (LoRA+PE) combines LoRA with prefix-embedding tuning, where we insert special tokens whose embeddings are treated as trainable parameters. For more on prefix-embedding tuning, see Section 5.1.
LoRA+PrefixEmbed (LoRA+PE) 把 LoRA 与 prefix-embedding tuning 结合:插入 个特殊 token,其嵌入视为可训练参数。关于 prefix-embedding tuning 见第 5.1 节。
LoRA+PrefixLayer (LoRA+PL) combines LoRA with prefix-layer tuning. We also insert special tokens; however, instead of letting the hidden representations of these tokens evolve naturally, we replace them after every Transformer block with an input agnostic vector. Thus, both the embeddings and subsequent Transformer block activations are treated as trainable parameters. For more on prefix-layer tuning, see Section 5.1.
LoRA+PrefixLayer (LoRA+PL) 把 LoRA 与 prefix-layer tuning 结合。同样插入 个特殊 token;但不是让这些 token 的隐表示自然演化,而是在每个 Transformer 块之后用与输入无关的向量替换它们。因此,嵌入以及后续 Transformer 块激活都被视为可训练参数。关于 prefix-layer tuning 见第 5.1 节。
In Table 15, we show the evaluation results of LoRA+PE and LoRA+PL on WikiSQL and MultiNLI. First of all, LoRA+PE significantly outperforms both LoRA and prefix-embedding tuning on WikiSQL, which indicates that LoRA is somewhat orthogonal to prefix-embedding tuning. On MultiNLI, the combination of LoRA+PE doesn’t perform better than LoRA, possibly because LoRA on its own already achieves performance comparable to the human baseline. Secondly, we notice that LoRA+PL performs slightly worse than LoRA even with more trainable parameters. We attribute this to the fact that prefix-layer tuning is very sensitive to the choice of learning rate and thus makes the optimization of LoRA weights more difficult in LoRA+PL.
表 15 给出 LoRA+PE 与 LoRA+PL 在 WikiSQL 与 MultiNLI 上的评估结果。首先,LoRA+PE 在 WikiSQL 上显著超过 LoRA 与 prefix-embedding tuning,表明 LoRA 与 prefix-embedding tuning 在一定程度上正交。在 MultiNLI 上,LoRA+PE 组合未超过 LoRA,可能因为单独 LoRA 已达到与人类基线可比的表现。其次,我们注意到即便可训练参数更多,LoRA+PL 仍略差于 LoRA。我们将其归因于:prefix-layer tuning 对学习率选择非常敏感,从而使 LoRA+PL 中 LoRA 权重的优化更困难。
Appendix F Additional Empirical Experiments
F.1 Additional Experiments on GPT-2
We also repeat our experiment on DART (Nan et al. 2020) and WebNLG (Gardent et al. 2017) following the setup of Li & Liang 2021. The result is shown in Table 13. Similar to our result on E2E NLG Challenge, reported in Section 5, LoRA performs better than or at least on-par with prefix-based approaches given the same number of trainable parameters.
我们还按 Li & Liang 2021 的设定在 DART(Nan et al. 2020)与 WebNLG(Gardent et al. 2017)上重复实验。结果见表 13。与第 5 节报告的 E2E NLG Challenge 结果类似,在可训练参数数相同的条件下,LoRA 表现优于或至少持平基于 prefix 的方法。
| Method | # Trainable | DART | ||
|---|---|---|---|---|
| Parameters | BLEU | MET | TER | |
| GPT-2 Medium | ||||
| Fine-Tune | 354M | 46.2 | 0.39 | 0.46 |
| 0.37M | 42.4 | 0.36 | 0.48 | |
| 11M | 45.2 | 0.38 | 0.46 | |
| 24M | 41.0 | 0.34 | 0.56 | |
| PrefLayer | 0.35M | 46.4 | 0.38 | 0.46 |
| LoRA | 0.35M | 47.1.2 | 0.39 | 0.46 |
| GPT-2 Large | ||||
| Fine-Tune | 774M | 47.0 | 0.39 | 0.46 |
| 0.88M | 45.7.1 | 0.38 | 0.46 | |
| 23M | 47.1.1 | 0.39 | 0.45 | |
| PrefLayer | 0.77M | 46.7 | 0.38 | 0.45 |
| LoRA | 0.77M | 47.5.1 | 0.39 | 0.45 |
Table 13: GPT-2 with different adaptation methods on DART. The variances of MET and TER are less than for all adaption approaches.
| Method | # Trainable | DART | ||
|---|---|---|---|---|
| Parameters | BLEU | MET | TER | |
| GPT-2 Medium | ||||
| Fine-Tune | 354M | 46.2 | 0.39 | 0.46 |
| 0.37M | 42.4 | 0.36 | 0.48 | |
| 11M | 45.2 | 0.38 | 0.46 | |
| 24M | 41.0 | 0.34 | 0.56 | |
| PrefLayer | 0.35M | 46.4 | 0.38 | 0.46 |
| LoRA | 0.35M | 47.1.2 | 0.39 | 0.46 |
| GPT-2 Large | ||||
| Fine-Tune | 774M | 47.0 | 0.39 | 0.46 |
| 0.88M | 45.7.1 | 0.38 | 0.46 | |
| 23M | 47.1.1 | 0.39 | 0.45 | |
| PrefLayer | 0.77M | 46.7 | 0.38 | 0.45 |
| LoRA | 0.77M | 47.5.1 | 0.39 | 0.45 |
表 13:GPT-2 在 DART 上不同适配方法的结果。
| Method | WebNLG | ||||||||
|---|---|---|---|---|---|---|---|---|---|
| BLEU | MET | TER | |||||||
| U | S | A | U | S | A | U | S | A | |
| GPT-2 Medium | |||||||||
| Fine-Tune (354M) | 27.7 | 64.2 | 46.5 | .30 | .45 | .38 | .76 | .33 | .53 |
| (0.37M) | 45.1 | 54.5 | 50.2 | .36 | .39 | .38 | .46 | .40 | .43 |
| (11M) | 48.3 | 60.4 | 54.9 | .38 | .43 | .41 | .45 | .35 | .39 |
| (24M) | 18.9 | 53.6 | 36.0 | .23 | .38 | .31 | .99 | .49 | .72 |
| Prefix (0.35M) | 45.6 | 62.9 | 55.1 | .38 | .44 | .41 | .49 | .35 | .40 |
| LoRA (0.35M) | 46.7.4 | 62.1.2 | 55.3.2 | .38 | .44 | .41 | .46 | .33 | .39 |
| GPT-2 Large | |||||||||
| Fine-Tune (774M) | 43.1 | 65.3 | 55.5 | .38 | .46 | .42 | .53 | .33 | .42 |
| (0.88M) | 49.8.0 | 61.1.0 | 56.0.0 | .38 | .43 | .41 | .44 | .35 | .39 |
| (23M) | 49.2.1 | 64.7.2 | 57.7.1 | .39 | .46 | .43 | .46 | .33 | .39 |
| Prefix (0.77M) | 47.7 | 63.4 | 56.3 | .39 | .45 | .42 | .48 | .34 | .40 |
| LoRA (0.77M) | 48.4.3 | 64.0.3 | 57.0.1 | .39 | .45 | .42 | .45 | .32 | .38 |
Table 14: GPT-2 with different adaptation methods on WebNLG. The variances of MET and TER are less than for all the experiments we ran. “U” indicates unseen categories, “S” indicates seen categories, and “A” indicates all categories in the test set of WebNLG.
| Method | WebNLG | ||||||||
|---|---|---|---|---|---|---|---|---|---|
| BLEU | MET | TER | |||||||
| U | S | A | U | S | A | U | S | A | |
| GPT-2 Medium | |||||||||
| Fine-Tune (354M) | 27.7 | 64.2 | 46.5 | .30 | .45 | .38 | .76 | .33 | .53 |
| (0.37M) | 45.1 | 54.5 | 50.2 | .36 | .39 | .38 | .46 | .40 | .43 |
| (11M) | 48.3 | 60.4 | 54.9 | .38 | .43 | .41 | .45 | .35 | .39 |
| (24M) | 18.9 | 53.6 | 36.0 | .23 | .38 | .31 | .99 | .49 | .72 |
| Prefix (0.35M) | 45.6 | 62.9 | 55.1 | .38 | .44 | .41 | .49 | .35 | .40 |
| LoRA (0.35M) | 46.7.4 | 62.1.2 | 55.3.2 | .38 | .44 | .41 | .46 | .33 | .39 |
| GPT-2 Large | |||||||||
| Fine-Tune (774M) | 43.1 | 65.3 | 55.5 | .38 | .46 | .42 | .53 | .33 | .42 |
| (0.88M) | 49.8.0 | 61.1.0 | 56.0.0 | .38 | .43 | .41 | .44 | .35 | .39 |
| (23M) | 49.2.1 | 64.7.2 | 57.7.1 | .39 | .46 | .43 | .46 | .33 | .39 |
| Prefix (0.77M) | 47.7 | 63.4 | 56.3 | .39 | .45 | .42 | .48 | .34 | .40 |
| LoRA (0.77M) | 48.4.3 | 64.0.3 | 57.0.1 | .39 | .45 | .42 | .45 | .32 | .38 |
表 14:GPT-2 在 WebNLG 上不同适配方法的结果(U/S/A 分别为未见/已见/全部)。
F.2 Additional Experiments on GPT-3
We present additional runs on GPT-3 with different adaptation methods in Table 15. The focus is on identifying the trade-off between performance and the number of trainable parameters.
我们在表 15 中给出 GPT-3 上不同适配方法的额外运行。重点在于识别表现与可训练参数数之间的权衡。
| Method | Hyperparameters | # Trainable Parameters | WikiSQL | MNLI-m |
|---|---|---|---|---|
| Fine-Tune | - | 175B | 73.8 | 89.5 |
| PrefixEmbed | 0.4 M | 55.9 | 84.9 | |
| 0.9 M | 58.7 | 88.1 | ||
| 1.7 M | 60.6 | 88.0 | ||
| 3.2 M | 63.1 | 88.6 | ||
| 6.4 M | 55.9 | 85.8 | ||
| PrefixLayer | 5.1 M | 68.5 | 89.2 | |
| 10.1 M | 69.8 | 88.2 | ||
| 20.2 M | 70.1 | 89.5 | ||
| 44.1 M | 66.4 | 89.6 | ||
| 76.1 M | 64.9 | 87.9 | ||
| 7.1 M | 71.9 | 89.8 | ||
| 21.2 M | 73.2 | 91.0 | ||
| 40.1 M | 73.2 | 91.5 | ||
| 77.9 M | 73.2 | 91.5 | ||
| 304.4 M | 72.6 | 91.5 | ||
| LoRA | 4.7 M | 73.4 | 91.7 | |
| 4.7 M | 73.4 | 91.3 | ||
| 9.4 M | 73.3 | 91.4 | ||
| 9.4 M | 74.1 | 91.2 | ||
| 18.8 M | 73.7 | 91.3 | ||
| 18.8 M | 73.7 | 91.7 | ||
| 37.7 M | 73.8 | 91.6 | ||
| 37.7 M | 74.0 | 91.7 | ||
| 301.9 M | 73.6 | 91.4 | ||
| 603.8 M | 73.9 | 91.4 | ||
| LoRA+PE | 37.8 M | 75.0 | 91.4 | |
| 151.1 M | 75.9 | 91.1 | ||
| 302.1 M | 76.2 | 91.3 | ||
| LoRA+PL | 52.8 M | 72.9 | 90.2 |
Table 15: Hyperparameter analysis of different adaptation approaches on WikiSQL and MNLI. Both prefix-embedding tuning (PrefixEmbed) and prefix-layer tuning (PrefixLayer) perform worse as we increase the number of trainable parameters, while LoRA’s performance stabilizes. Performance is measured in validation accuracy.
| Method | Hyperparameters | # Trainable Parameters | WikiSQL | MNLI-m |
|---|---|---|---|---|
| Fine-Tune | - | 175B | 73.8 | 89.5 |
| PrefixEmbed | 0.4 M | 55.9 | 84.9 | |
| 0.9 M | 58.7 | 88.1 | ||
| 1.7 M | 60.6 | 88.0 | ||
| 3.2 M | 63.1 | 88.6 | ||
| 6.4 M | 55.9 | 85.8 | ||
| PrefixLayer | 5.1 M | 68.5 | 89.2 | |
| 10.1 M | 69.8 | 88.2 | ||
| 20.2 M | 70.1 | 89.5 | ||
| 44.1 M | 66.4 | 89.6 | ||
| 76.1 M | 64.9 | 87.9 | ||
| 7.1 M | 71.9 | 89.8 | ||
| 21.2 M | 73.2 | 91.0 | ||
| 40.1 M | 73.2 | 91.5 | ||
| 77.9 M | 73.2 | 91.5 | ||
| 304.4 M | 72.6 | 91.5 | ||
| LoRA | 4.7 M | 73.4 | 91.7 | |
| 4.7 M | 73.4 | 91.3 | ||
| 9.4 M | 73.3 | 91.4 | ||
| 9.4 M | 74.1 | 91.2 | ||
| 18.8 M | 73.7 | 91.3 | ||
| 18.8 M | 73.7 | 91.7 | ||
| 37.7 M | 73.8 | 91.6 | ||
| 37.7 M | 74.0 | 91.7 | ||
| 301.9 M | 73.6 | 91.4 | ||
| 603.8 M | 73.9 | 91.4 | ||
| LoRA+PE | 37.8 M | 75.0 | 91.4 | |
| 151.1 M | 75.9 | 91.1 | ||
| 302.1 M | 76.2 | 91.3 | ||
| LoRA+PL | 52.8 M | 72.9 | 90.2 |
表 15:GPT-3 上不同适配方法在 WikiSQL 与 MNLI-m 上相对可训练参数数的额外结果。
F.3 Low-Data Regime
To evaluate the performance of different adaptation approaches in the low-data regime. we randomly sample 100, 1k and 10k training examples from the full training set of MNLI to form the low-data MNLI- tasks. In Table 16, we show the performance of different adaptation approaches on MNLI-. To our surprise, PrefixEmbed and PrefixLayer performs very poorly on MNLI-100 dataset, with PrefixEmbed performing only slightly better than random chance (37.6% vs. 33.3%). PrefixLayer performs better than PrefixEmbed but is still significantly worse than Fine-Tune or LoRA on MNLI-100. The gap between prefix-based approaches and LoRA/Fine-tuning becomes smaller as we increase the number of training examples, which might suggest that prefix-based approaches are not suitable for low-data tasks in GPT-3. LoRA achieves better performance than fine-tuning on both MNLI-100 and MNLI-Full, and comparable results on MNLI-1k and MNLI-10K considering the () variance due to random seeds.
为评估低数据设定下不同适配方法的表现,我们从 MNLI 完整训练集随机采样 100、1k 与 10k 个训练样本,构成低数据 MNLI- 任务。表 16 给出不同适配方法在 MNLI- 上的表现。令我们惊讶的是,PrefixEmbed 与 PrefixLayer 在 MNLI-100 上表现很差,PrefixEmbed 仅略好于随机猜测(37.6% vs. 33.3%)。PrefixLayer 好于 PrefixEmbed,但在 MNLI-100 上仍显著差于 Fine-Tune 或 LoRA。随着训练样本增多,基于 prefix 的方法与 LoRA/微调之间的差距缩小。
| Method | MNLI(m)-100 | MNLI(m)-1k | MNLI(m)-10k | MNLI(m)-392K |
|---|---|---|---|---|
| GPT-3 (Fine-Tune) | 60.2 | 85.8 | 88.9 | 89.5 |
| GPT-3 (PrefixEmbed) | 37.6 | 75.2 | 79.5 | 88.6 |
| GPT-3 (PrefixLayer) | 48.3 | 82.5 | 85.9 | 89.6 |
| GPT-3 (LoRA) | 63.8 | 85.6 | 89.2 | 91.7 |
Table 16: Validation accuracy of different methods on subsets of MNLI using GPT-3 175B. MNLI- describes a subset with training examples. We evaluate with the full validation set. LoRA performs exhibits favorable sample-efficiency compared to other methods, including fine-tuning.
| Method | MNLI(m)-100 | MNLI(m)-1k | MNLI(m)-10k | MNLI(m)-392K |
|---|---|---|---|---|
| GPT-3 (Fine-Tune) | 60.2 | 85.8 | 88.9 | 89.5 |
| GPT-3 (PrefixEmbed) | 37.6 | 75.2 | 79.5 | 88.6 |
| GPT-3 (PrefixLayer) | 48.3 | 82.5 | 85.9 | 89.6 |
| GPT-3 (LoRA) | 63.8 | 85.6 | 89.2 | 91.7 |
表 16:用 GPT-3 175B 在 MNLI 子集上不同方法的验证准确率。MNLI- 表示含 个训练样本的子集。我们用完整验证集评估。相对其他方法(含微调),LoRA 展现有利的样本效率。
The training hyperparameters of different adaptation approaches on MNLI-n are reported in Table 17. We use a smaller learning rate for PrefixLayer on the MNLI-100 set, as the training loss does not decrease with a larger learning rate.
不同适配方法在 MNLI-n 上的训练超参见表 17。对 MNLI-100 上的 PrefixLayer 我们使用更小学习率,因为更大的学习率下训练损失不下降。
| Hyperparameters | Adaptation | MNLI-100 | MNLI-1k | MNLI-10K | MNLI-392K |
|---|---|---|---|---|---|
| Optimizer | - | AdamW | |||
| Warmup Tokens | - | 250,000 | |||
| LR Schedule | - | Linear | |||
| Batch Size | - | 20 | 20 | 100 | 128 |
| # Epoch | - | 40 | 40 | 4 | 2 |
| Learning Rate | FineTune | 5.00E-6 | |||
| PrefixEmbed | 2.00E-04 | 2.00E-04 | 4.00E-04 | 5.00E-04 | |
| PrefixLayer | 5.00E-05 | 5.00E-05 | 5.00E-05 | 1.00E-04 | |
| LoRA | 2.00E-4 | ||||
| PrefixEmbed | 16 | 32 | 64 | 256 | |
| Adaptation- | PrefixEmbed | 8 | |||
| Specific | PrefixTune | ||||
| LoRA |
Table 17: The hyperparameters used for different GPT-3 adaptation methods on MNLI(m)-.
| Hyperparameters | Adaptation | MNLI-100 | MNLI-1k | MNLI-10K | MNLI-392K |
|---|---|---|---|---|---|
| Optimizer | - | AdamW | |||
| Warmup Tokens | - | 250,000 | |||
| LR Schedule | - | Linear | |||
| Batch Size | - | 20 | 20 | 100 | 128 |
| # Epoch | - | 40 | 40 | 4 | 2 |
| Learning Rate | FineTune | 5.00E-6 | |||
| PrefixEmbed | 2.00E-04 | 2.00E-04 | 4.00E-04 | 5.00E-04 | |
| PrefixLayer | 5.00E-05 | 5.00E-05 | 5.00E-05 | 1.00E-04 | |
| LoRA | 2.00E-4 | ||||
| PrefixEmbed | 16 | 32 | 64 | 256 | |
| Adaptation- | PrefixEmbed | 8 | |||
| Specific | PrefixTune | ||||
| LoRA |
表 17:MNLI- 上不同适配方法的训练超参。
Appendix G Measuring Similarity Between Subspaces
In this paper we use the measure to measure the subspace similarity between two column orthonormal matrices and , obtained by taking columns of the left singular matrices of and . We point out that this similarity is simply a reverse of the standard Projection Metric that measures distance between subspaces Ham & Lee 2008.
本文使用度量 来衡量两个列正交矩阵 与 之间的子空间相似度;二者分别取自 与 左奇异矩阵的列。我们指出:该相似度只是衡量子空间距离的标准投影度量(Projection Metric,Ham & Lee 2008)的反转。
To be concrete, let the singular values of to be where . We know that the Projection Metric Ham & Lee 2008 is defined as:
具体地,设 的奇异值为 ,其中 。我们知道投影度量(Ham & Lee 2008)定义为:
where our similarity is defined as:
而我们的相似度定义为:
This similarity satisfies that if and share the same column span, then . If they are completely orthogonal, then . Otherwise, .
该相似度满足:若 与 共享相同列空间,则 ;若完全正交,则 ;否则 。
Appendix H Additional Experiments on Low-Rank Matrices
We present additional results from our investigation into the low-rank update matrices.
我们给出对低秩更新矩阵调查的额外结果。
H.1 Correlation between LoRA Modules
See Figure 6 and Figure 7 for how the results presented in Figure 3 and Figure 4 generalize to other layers.
见图 6 与图 7:图 3 与图 4 所示结果如何推广到其他层。
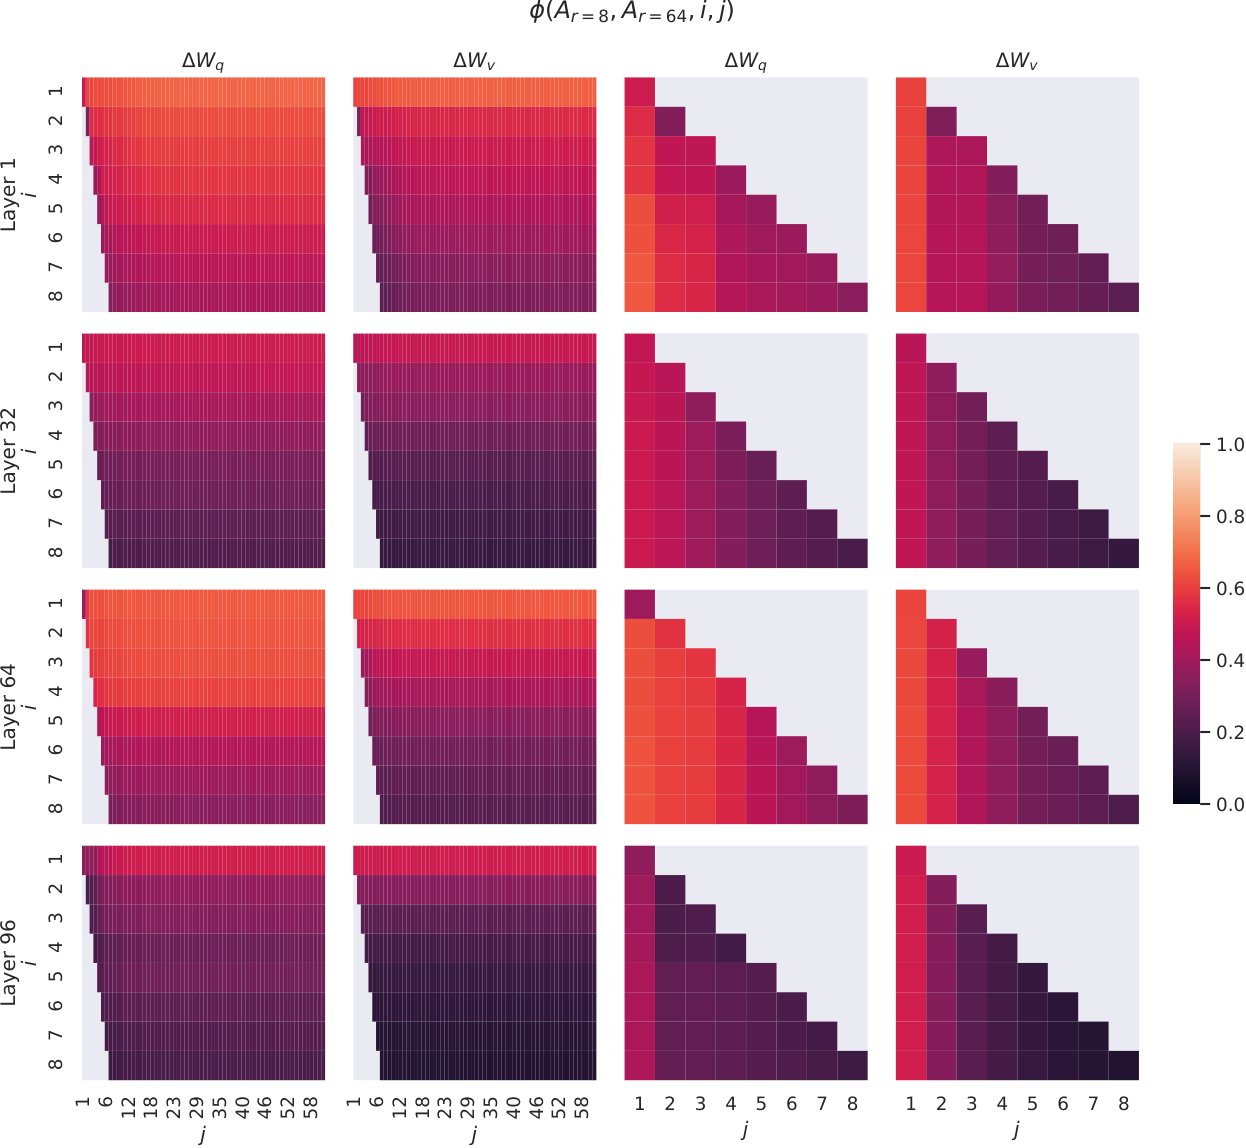
Figure 6: Normalized subspace similarity between the column vectors of and for both and from the 1st, 32nd, 64th, and 96th layers in a 96-layer Transformer.
图 6:96 层 Transformer 中第 1、32、64、96 层上, 与 列向量之间的归一化子空间相似度(对 与 )。
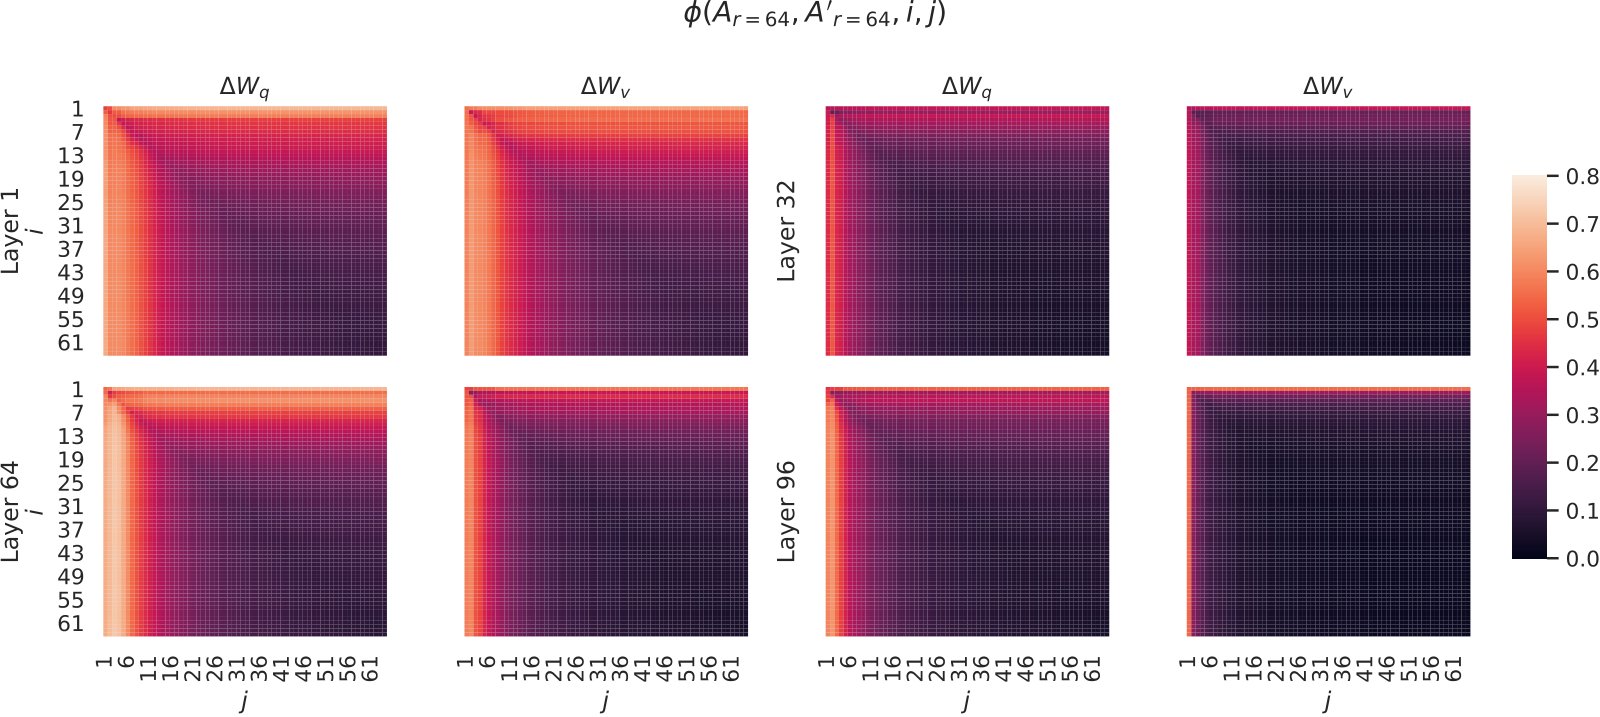
Figure 7: Normalized subspace similarity between the column vectors of from two randomly seeded runs, for both and from the 1st, 32nd, 64th, and 96th layers in a 96-layer Transformer.
图 7:96 层 Transformer 中第 1、32、64、96 层上,两个随机种子运行得到的 列向量之间的归一化子空间相似度(对 与 )。
H.2 Effect of on GPT-2
We repeat our experiment on the effect of (Section 7.2) in GPT-2. Using the E2E NLG Challenge dataset as an example, we report the validation loss and test metrics achieved by different choices of after training for 26,000 steps. We present our result in Table 18. The optimal rank for GPT-2 Medium is between 4 and 16 depending on the metric used, which is similar to that for GPT-3 175B. Note that the relationship between model size and the optimal rank for adaptation is still an open question.
我们在 GPT-2 上重复关于 影响的实验(第 7.2 节)。以 E2E NLG Challenge 数据集为例,我们报告训练 26,000 步后不同 选择达到的验证损失与测试指标。结果见表 18。GPT-2 Medium 的最优秩依所用指标约在 4 到 16 之间,与 GPT-3 175B 相近。注意模型规模与适配最优秩之间的关系仍是开放问题。
| Rank | val_loss | BLEU | NIST | METEOR | ROUGE_L | CIDEr |
|---|---|---|---|---|---|---|
| 1 | 1.23 | 68.72 | 8.7215 | 0.4565 | 0.7052 | 2.4329 |
| 2 | 1.21 | 69.17 | 8.7413 | 0.4590 | 0.7052 | 2.4639 |
| 4 | 1.18 | 70.38 | 8.8439 | 0.4689 | 0.7186 | 2.5349 |
| 8 | 1.17 | 69.57 | 8.7457 | 0.4636 | 0.7196 | 2.5196 |
| 16 | 1.16 | 69.61 | 8.7483 | 0.4629 | 0.7177 | 2.4985 |
| 32 | 1.16 | 69.33 | 8.7736 | 0.4642 | 0.7105 | 2.5255 |
| 64 | 1.16 | 69.24 | 8.7174 | 0.4651 | 0.7180 | 2.5070 |
| 128 | 1.16 | 68.73 | 8.6718 | 0.4628 | 0.7127 | 2.5030 |
| 256 | 1.16 | 68.92 | 8.6982 | 0.4629 | 0.7128 | 2.5012 |
| 512 | 1.16 | 68.78 | 8.6857 | 0.4637 | 0.7128 | 2.5025 |
| 1024 | 1.17 | 69.37 | 8.7495 | 0.4659 | 0.7149 | 2.5090 |
Table 18: Validation loss and test set metrics on E2E NLG Challenge achieved by LoRA with different rank using GPT-2 Medium. Unlike on GPT-3 where suffices for many tasks, here the performance peaks at for validation loss and for BLEU, suggesting the GPT-2 Medium has a similar intrinsic rank for adaptation compared to GPT-3 175B. Note that some of our hyperparameters are tuned on , which matches the parameter count of another baseline, and thus might not be optimal for other choices of .
| Rank | val_loss | BLEU | NIST | METEOR | ROUGE_L | CIDEr |
|---|---|---|---|---|---|---|
| 1 | 1.23 | 68.72 | 8.7215 | 0.4565 | 0.7052 | 2.4329 |
| 2 | 1.21 | 69.17 | 8.7413 | 0.4590 | 0.7052 | 2.4639 |
| 4 | 1.18 | 70.38 | 8.8439 | 0.4689 | 0.7186 | 2.5349 |
| 8 | 1.17 | 69.57 | 8.7457 | 0.4636 | 0.7196 | 2.5196 |
| 16 | 1.16 | 69.61 | 8.7483 | 0.4629 | 0.7177 | 2.4985 |
| 32 | 1.16 | 69.33 | 8.7736 | 0.4642 | 0.7105 | 2.5255 |
| 64 | 1.16 | 69.24 | 8.7174 | 0.4651 | 0.7180 | 2.5070 |
| 128 | 1.16 | 68.73 | 8.6718 | 0.4628 | 0.7127 | 2.5030 |
| 256 | 1.16 | 68.92 | 8.6982 | 0.4629 | 0.7128 | 2.5012 |
| 512 | 1.16 | 68.78 | 8.6857 | 0.4637 | 0.7128 | 2.5025 |
| 1024 | 1.17 | 69.37 | 8.7495 | 0.4659 | 0.7149 | 2.5090 |
表 18:GPT-2 Medium 上不同秩 在 E2E 上的验证损失与测试指标。
H.3 Correlation between and
See Figure 8 for the normalized subspace similarity between and with varying .
见图 8: 与 在不同 下的归一化子空间相似度。
Note again that does not contain the top singular directions of , since the similarity between the top 4 directions in and the top-10% of those in barely exceeds 0.2. This gives evidence that contains those “task-specific” directions that are otherwise not emphasized in .
再次注意: 并不包含 的顶部奇异方向,因为 前 4 个方向与 前 10% 方向之间的相似度几乎不超过 0.2。这给出证据: 包含那些在 中未被强调的“任务特定”方向。
An interesting next question to answer, is how “strong” do we need to amplify those task-specific directions, in order for the model adaptation to work well?
下一个有趣的问题是:为使模型适配表现良好,我们需要把这些任务特定方向放大到多“强”?
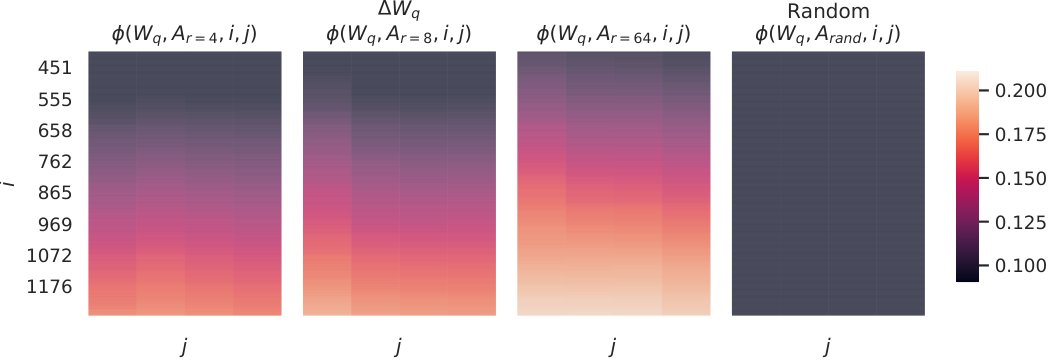
Figure 8: Normalized subspace similarity between the singular directions of and those of with varying and a random baseline. amplifies directions that are important but not emphasized in . with a larger tends to pick up more directions that are already emphasized in .
图 8: 与 奇异方向之间的归一化子空间相似度(随 变化,并含随机基线)。 放大在 中重要但未被强调的方向。更大 的 倾向于拾取更多已在 中被强调的方向。
H.4 Amplification Factor
One can naturally consider a feature amplification factor as the ratio , where and are the left- and right-singular matrices of the SVD decomposition of . (Recall gives the “projection” of onto the subspace spanned by .)
人们可自然考虑特征放大因子为比值 ,其中 与 为 的 SVD 分解的左、右奇异矩阵。(回想 给出 到 张成子空间上的“投影”。)
Intuitively, when mostly contains task-specific directions, this quantity measures how much of them are amplified by . As shown in Section 7.3, for , this amplification factor is as large as 20. In other words, there are (generally speaking) four feature directions in each layer (out of the entire feature space from the pre-trained model ), that need to be amplified by a very large factor 20, in order to achieve our reported accuracy for the downstream specific task. And, one should expect a very different set of feature directions to be amplified for each different downstream task.
直观上,当 主要包含任务特定方向时,该量衡量它们被 放大了多少。如第 7.3 节所示,对 ,该放大因子可高达 20。换言之,(一般而言)每层有四个特征方向(来自预训练模型 的整个特征空间),需要被放大约 20 倍的很大因子,才能达到我们报告的下游特定任务准确率。并且,对每个不同下游任务,应预期被放大的特征方向集合非常不同。
One may notice, however, for , this amplification factor is only around 2, meaning that most directions learned in with are not being amplified by much. This should not be surprising, and in fact gives evidence (once again) that the intrinsic rank needed to represent the “task-specific directions” (thus for model adaptation) is low. In contrast, those directions in the rank-4 version of (corresponding to ) are amplified by a much larger factor 20.
然而人们可能注意到:对 ,该放大因子仅约 2,意味着用 在 中学到的大多数方向并未被大幅放大。这并不令人惊讶,事实上再次给出证据:表示“任务特定方向”(从而用于模型适配)所需的本征秩是低的。相比之下, 的秩-4 版本(对应 )中的那些方向被放大了大得多的因子 20。