Learning Dynamics of LLM Finetuning
Learning Dynamics of LLM Finetuning
大语言模型微调的学习动力学
Yi Ren Affiliation: University of British Columbia Email: renyi.joshua@gmail.com Danica J. Sutherland Affiliation: University of British Columbia & Amii Email: dsuth@cs.ubc.ca
Abstract
摘要
Learning dynamics, which describes how the learning of specific training examples influences the model’s predictions on other examples, gives us a powerful tool for understanding the behavior of deep learning systems. We study the learning dynamics of large language models during different types of finetuning, by analyzing the step-wise decomposition of how influence accumulates among different potential responses. Our framework allows a uniform interpretation of many interesting observations about the training of popular algorithms for both instruction tuning and preference tuning. In particular, we propose a hypothetical explanation of why specific types of hallucination are strengthened after finetuning, e.g., the model might use phrases or facts in the response for question B to answer question A, or the model might keep repeating similar simple phrases when generating responses. We also extend our framework and highlight a unique “squeezing effect” to explain a previously observed phenomenon in off-policy direct preference optimization (DPO), where running DPO for too long makes even the desired outputs less likely. This framework also provides insights into where the benefits of on-policy DPO and other variants come from. The analysis not only provides a novel perspective of understanding LLM’s finetuning but also inspires a simple, effective method to improve alignment performance. Code for experiments is available at https://github.com/Joshua-Ren/Learning_dynamics_LLM.
学习动力学刻画特定训练样本的学习如何影响模型对其它样本的预测,是理解深度学习系统行为的有力工具。我们分析大语言模型在各类微调中的学习动力学,逐步分解不同潜在回复之间影响力的累积。该框架可对指令微调与偏好微调中许多常见算法的训练现象给出统一解释。尤其是,我们提出一种假说,解释为何某些幻觉在微调后反而加重:例如模型会用问题 B 的回复中的措辞或事实去回答问题 A,或在生成时反复使用相似的简单短语。我们还扩展该框架,强调一种独特的「挤压效应」,用以解释 off-policy 直接偏好优化(DPO)中先前观察到的现象——DPO 跑得过久,连期望输出的概率也会下降。该框架亦有助于理解 on-policy DPO 及其变体收益来自何处。分析不仅为 LLM 微调提供新视角,还启发了一种简单有效、可提升对齐表现的方法。实验代码见 https://github.com/Joshua-Ren/Learning_dynamics_LLM。
1 Introduction
1 引言
Deep neural networks usually acquire new knowledge by updating their parameters via gradient descent (GD). This procedure can be described by learning dynamics, which links changes in the model’s predictions to the gradients generated by learning specific examples. With the help of learning dynamics, researchers have not only explained many interesting phenomena during training, e.g., the “zig-zag” learning path (Ren et al. 2022a) and the formation of compositional concept space (Park et al. 2024a), but used these insights to propose novel, improved algorithms in different problems (e.g. Ren et al. 2023b; Pruthi et al. 2020a; Xia et al. 2024a).
深度神经网络通常通过梯度下降(GD)更新参数来获取新知识。该过程可用学习动力学描述:它把模型预测的变化与学习特定样本所产生的梯度联系起来。借助学习动力学,研究者不仅解释了训练中的诸多现象,例如「之」字形学习路径(Ren et al. 2022a)以及组合概念空间的形成(Park et al. 2024a),还据此提出了面向不同问题的新算法(如 Ren et al. 2023b;Pruthi et al. 2020a;Xia et al. 2024a)。
The study of large language models (LLM) is gaining popularity due to their surprising capabilities on various tasks. To ensure the LLMs follow human instructions and align well with human preferences, finetuning has attracted much recent attention. Practitioners often start with instruction tuning, where the model learns extra knowledge necessary for the downstream task, and then preference tuning, where the model aligns its outputs to human preference (Ouyang et al. 2022a). Various finetuning algorithms have been proposed to fit into this pipeline, with differing explanations as to why they improve the model’s performance.
大语言模型(LLM)因在多种任务上的出色能力而受到广泛关注。为使其遵循人类指令并与人类偏好对齐,微调成为近期热点。实践中通常先做指令微调,让模型学习下游任务所需的额外知识,再做偏好微调,使输出与人类偏好对齐(Ouyang et al. 2022a)。围绕该流程已有多种微调算法,对其有效性的解释也不尽相同。
Contrary to most existing analyses of LLM finetuning, which use the perspective of their training targets, their status at the end of training, or their relationships to reinforcement learning (e.g. Ji et al. 2024a; Rafailov et al. 2024a; Tajwar et al. 2024a), this paper tries to understand LLMs’ evolution from a dynamical perspective. Specifically, we formalize the learning dynamics of LLM finetuning by decomposing the change of the model’s prediction into three terms which play different roles. This framework can be easily adapted to various finetuning algorithms with different goals, including supervised finetuning (SFT, Wei et al. 2022a), direct preference optimization (DPO, Rafailov et al. 2023a, and its variants) and even reinforcement learning based methods (e.g., PPO, Schulman et al. 2017a). This framework helps explain several interesting and counter-intuitive observations during training – including the “repeater” phenomenon after preference tuning (Holtzman et al. 2020a), hallucination (Huang et al. 2023a), the decay in confidence of all responses during off-policy DPO (Rafailov et al. 2024a), and more.
与多数从训练目标、训练终点状态或与强化学习关系出发分析 LLM 微调的工作不同(如 Ji et al. 2024a;Rafailov et al. 2024a;Tajwar et al. 2024a),本文试图从动力学视角理解 LLM 的演化。具体而言,我们将 LLM 微调的学习动力学形式化,把模型预测的变化分解为起不同作用的三项。该框架可轻松适配目标各异的多种微调算法,包括监督微调(SFT,Wei et al. 2022a)、直接偏好优化(DPO,Rafailov et al. 2023a 及其变体),乃至基于强化学习的方法(如 PPO,Schulman et al. 2017a)。它有助于解释训练中若干有趣且反直觉的现象——包括偏好微调后的「复读机」现象(Holtzman et al. 2020a)、幻觉(Huang et al. 2023a)、off-policy DPO 中所有回复置信度下降(Rafailov et al. 2024a)等。
Moreover, we also provide a new perspective on understanding why off-policy DPO and other variants underperform their on-policy counterparts (Guo et al. 2024c). Our explanation starts by observing an interesting “squeezing effect,” which we demonstrate is a consequence of gradient ascent (as in DPO and similar algorithms) on models with cross-entropy loss following a softmax layer. In short, for each token’s prediction, the negative gradient will push down the model’s predictions on (almost) all possible output labels, moving this probability mass to the most-likely labels. This can be detrimental to the alignment we are trying to achieve. This effect is most serious when the negative gradient is imposed on an already-unlikely label, which is why the confidence of almost all responses decreases during off-policy DPO. Inspired by this, we propose a simple, counter-intuitive, but very effective method to further improve alignment performance.
此外,我们还给出理解为何 off-policy DPO 及其变体逊于 on-policy 对照的新视角(Guo et al. 2024c)。解释始于一种有趣的「挤压效应」:我们证明,它是带 Softmax 层的交叉熵模型在做梯度上升(如 DPO 及同类算法)时的必然后果。简言之,对每个 token 的预测,负梯度会压低模型在(几乎)所有可能输出标签上的预测,并把概率质量推向当前最可能的标签。这对我们试图达成的对齐可能有害。当负梯度作用在本已不太可能的标签上时,该效应尤为严重,这也解释了为何 off-policy DPO 中几乎所有回复的置信度都会下降。受此启发,我们提出一种简单、看似反直觉却非常有效的方法,以进一步提升对齐表现。
2 Definition of Learning Dynamics and an MNIST Example
2 学习动力学的定义与一个 MNIST 例子
Learning dynamics is usually an umbrella term describing how the change of a specific factor influences the model’s prediction. In this paper, we narrow down it to describe “how the change in model’s parameter influences the corresponding change in ”, i.e., the relationship between and . When the model updates its parameters using gradient descent (GD), we have
学习动力学通常是一个统称,描述某个因素的变化如何影响模型预测。本文将范围收窄为「参数 的变化如何引起 的变化」,即 与 的关系。当模型用梯度下降(GD)更新参数时,有
\quad\Delta\theta\triangleq\theta^{t+1}-\theta^{t}=-\eta\cdot\nabla\mathcal{L}\left(f_{\theta}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}}),{\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}}\right);\quad\Delta f({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})\triangleq f_{\theta^{t+1}}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})-f_{\theta^{t}}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}}), \tag{1}
where the update of during step is given by one gradient update on the sample pair ({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}},{\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}}) with learning rate . In short, the learning dynamics in this paper address the question:
其中 在步 的更新由对样本对 ({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}},{\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}})、学习率 的一次梯度更新给出。简言之,本文的学习动力学要回答的问题是:
After an GD update on {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}}, how does the model’s prediction on {\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}} change?
在 {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} 上做一次 GD 更新后,模型对 {\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}} 的预测如何变化?
Studying the learning dynamics can shed light on many important problems in deep learning and also help to understand various counter-intuitive phenomena. Appendix A further discusses related work.
研究学习动力学可以澄清深度学习中许多重要问题,也有助于理解各种反直觉现象。附录 A 进一步讨论相关工作。
As a warm-up, we first consider a standard supervised learning problem, where the model learns to map to predictions , where is the vocabulary of size . The model usually outputs a probability distribution by first generating a matrix of logits and then takes the of each column. We can track the change in the model’s confidence by observing .
作为热身,先考虑标准监督学习:模型学习把 映射到预测 ,其中 为大小 的词表。模型通常先生成 logits 矩阵 ,再对每列做 Softmax 得到概率分布。我们可通过观察 来跟踪模型置信度的变化。
Per-step influence decomposition.
The learning dynamics of (1) become,
逐步影响力分解。
式 (1) 的学习动力学变为
\displaystyle\Delta\log\pi^{t}(\bm{\mathsf{y}}\mid{\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})\triangleq\log\pi_{\theta^{t+1}}(\bm{\mathsf{y}}\mid{\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})-\log\pi_{\theta^{t}}(\bm{\mathsf{y}}\mid{\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}}),. \tag{2}
For simplicity, we start from the scenario, where the and can be linked by the following result, a version of a result of Ren et al. 2022a proved and further discussed in Appendix B. For multi-label classification (), the updates separate; we can calculate different and stack them together.
为简单起见,先从 情形出发: 与 可由下述结果联系起来,这是 Ren et al. 2022a 结果的一个版本,证明与进一步讨论见附录 B。对多标签分类(),更新可分离;我们可计算 个不同的 再堆叠。
Proposition 1.
Let and . The one-step learning dynamics decompose as
命题 1。
设 且 。一步学习动力学可分解为
\underbrace{\Delta\log\pi^{t}(\bm{\mathsf{y}}\mid{\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})}_{V\times 1}=-\eta\underbrace{\mathcal{A}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})}_{V\times V}\underbrace{\mathcal{K}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}},{\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}})}_{V\times V}\underbrace{\mathcal{G}^{t}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}},{\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}})}_{V\times 1}{}+\bigO(\eta^{2}\|\nabla_{\theta}\bm{\mathsf{z}}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}})\|^{2}_{\mathrm{op}}), \tag{3}
where \mathcal{A}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})=\nabla_{\bm{\mathsf{z}}}\log\pi_{\theta^{t}}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})=I-\bm{\mathsf{1}}\pi_{\theta^{t}}^{\top}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}}), \mathcal{K}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}},{\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}})=(\nabla_{\theta}\bm{\mathsf{z}}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})|_{\theta^{t}})(\nabla_{\theta}\bm{\mathsf{z}}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}})|_{\theta^{t}})^{\top} is the empirical neural tangent kernel of the logit network , and \mathcal{G}^{t}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}},{\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}})=\nabla_{\bm{\mathsf{z}}}\mathcal{L}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}},{\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}})|_{\bm{\mathsf{z}}^{t}}.
其中 \mathcal{A}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})=\nabla_{\bm{\mathsf{z}}}\log\pi_{\theta^{t}}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})=I-\bm{\mathsf{1}}\pi_{\theta^{t}}^{\top}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}}),\mathcal{K}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}},{\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}})=(\nabla_{\theta}\bm{\mathsf{z}}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})|_{\theta^{t}})(\nabla_{\theta}\bm{\mathsf{z}}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}})|_{\theta^{t}})^{\top} 是 logits 网络 的经验神经正切核,\mathcal{G}^{t}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}},{\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}})=\nabla_{\bm{\mathsf{z}}}\mathcal{L}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}},{\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}})|_{\bm{\mathsf{z}}^{t}}。
\mathcal{A}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})=I-\bm{\mathsf{1}}\pi_{\theta^{t}}^{\top}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}}) only depends on the model’s current predicted probability. The matrix is the empirical neural tangent kernel (eNTK, Jacot et al. 2018a) of the model, the product of the model’s gradients with respect to {\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}} and {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}}. The analysis in this paper relies on the following assumption:
\mathcal{A}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})=I-\bm{\mathsf{1}}\pi_{\theta^{t}}^{\top}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}}) 只取决于模型当前预测概率。矩阵 是模型的经验神经正切核(eNTK,Jacot et al. 2018a),即模型分别对 {\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}} 与 {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} 的梯度之积。本文分析依赖下述假设:
During the training, the relative influence of learning on all other different is relatively stable.
训练过程中,学习 对其它各个 的相对影响力保持相对稳定。
The common “lazy eNTK” assumption discussed in Arora et al. 2019a is a sufficient but not necessary condition for this paper. Appendix C provides a more detailed discussion and experimental verification for both MNIST and LLM settings. We can then think of as a model-specific similarity measurement between different input samples: larger means the update of likely influences the model’s prediction on more. Finally, is determined by the loss function , which provides the energy and direction for the model’s adaptation. For example, for cross-entropy loss , we have , a length- vector that points from the model’s current predictive distribution to the desired supervisory distribution. For typical “hard” labels, is a one-hot vector .
Arora et al. 2019a 讨论的常见「惰性 eNTK」假设是本文的充分非必要条件。附录 C 对 MNIST 与 LLM 设定给出更细讨论与实验验证。于是可将 视为模型特异的样本相似度度量: 越大,更新 越可能更强地影响模型对 的预测。最后, 由损失函数 决定,为模型适应提供能量与方向。例如对交叉熵损失 ,有 ,这是从当前预测分布指向期望监督分布的长度为 的向量。对典型「硬」标签, 是 one-hot 向量 。
Accumulated influence and a demonstration on MNIST.
Proposition 1 describes how the update of {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} changes the model’s prediction on {\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}} for each learning step. Since a real model updates its parameters for many steps, it is important to ask about accumulation of these per-step influences over time. We start by analyzing a simple example of training a LeNet on the MNIST dataset (LeCun et al. 1998a).
累积影响力与 MNIST 上的演示。
命题 1 描述每一步学习中更新 {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} 如何改变模型对 {\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}} 的预测。真实模型会更新许多步,因此需要关心这些逐步影响力如何随时间累积。我们先分析在 MNIST 上训练 LeNet 的简单例子(LeCun et al. 1998a)。
See Figure 1-(a), where the network is updating its parameters using the loss calculated on one training example ({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}},{\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}}=\bm{\mathsf{e}}_{\texttt{4}}). The residual term \mathcal{G}^{t}_{\text{CE}}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}},{\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}}) is then represented by the red arrows, which all start from \pi_{\theta^{t}}(\bm{\mathsf{y}}\mid{\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}}) and point to . We can then ask how the model’s predictions on different {\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}} change after this update. As in Figure 1-(b), for an {\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}} in the same class with {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} (i.e., the identical case), the predicted probability of this correct label is “pulled up” by this update, as expected. On the other hand, if this {\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}} is similar to {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} (i.e., is reasonably large) but comes from another class, then the predicted probability on {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}}’s class (not the correct label of {\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}}) would be “pulled up,” as in the second panel of Figure 1-(b). Last, for examples that look dissimilar to {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} (small ), this update will not change the model’s prediction on {\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}} much, as in the bottom panel in Figure 1-(b).
见图 1-(a):网络 用单个训练样本 ({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}},{\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}}=\bm{\mathsf{e}}_{\texttt{4}}) 上的损失更新参数。残差项 \mathcal{G}^{t}_{\text{CE}}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}},{\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}}) 用红色箭头表示,均从 \pi_{\theta^{t}}(\bm{\mathsf{y}}\mid{\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}}) 指向 。接着可问:这次更新后,模型对不同 {\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}} 的预测如何变化。如图 1-(b),若 {\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}} 与 {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} 同类(即相同类情形),正确标签的预测概率会如预期被「拉高」。另一方面,若该 {\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}} 与 {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} 相似(即 足够大)却来自另一类,则 {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} 所在类(而非 {\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}} 的正确标签)的预测概率会被「拉高」,见图 1-(b) 第二幅。最后,对与 {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} 外观不相似的样本( 小),这次更新几乎不改变模型对 {\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}} 的预测,见图 1-(b) 底幅。
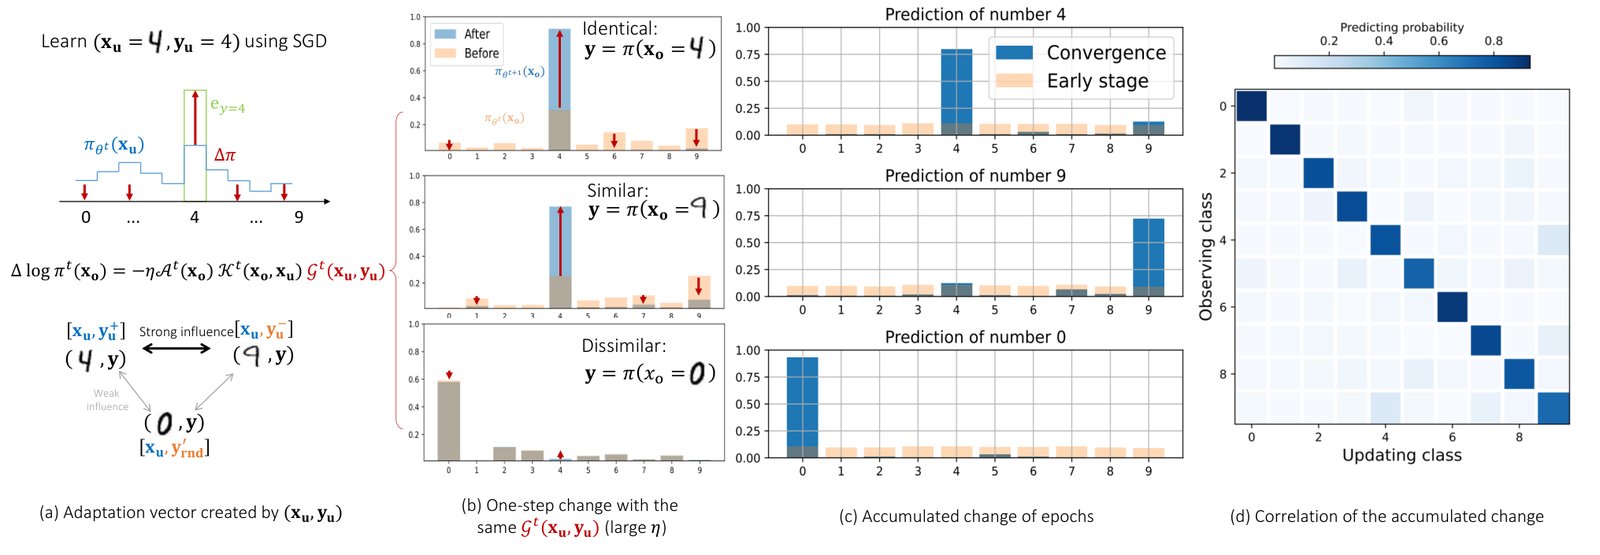
Figure 1: The per-step learning dynamics and the accumulated influence in an MNIST experiment.
图 1:MNIST 实验中的逐步学习动力学与累积影响力。
The interactions among the updates of different inputs then form an interesting pattern for the learned predictions. As illustrated in Figure 1-(c), when making predictions on images coming from class 4, the model tends to assign higher confidence on class 9. That is because the examples in class 9 on average look more similar to class 4 than examples in other classes. Hence the update of examples in classes 4 and 9 will reinforce their mutual influence and lead to a bump in their predictions. To verify this, we plot the average of for from each of the classes in Figure 1-(d). The values of some off-diagonal patches are significantly higher than others, which means the examples in those classes look more similar, like 4 and 9, 5 and 3, 8 and 5, etc.
不同输入更新之间的相互作用,会在学到的预测上形成有趣图案。如图 1-(c) 所示,对来自类别 4 的图像做预测时,模型往往对类别 9 给出更高置信度。因为类别 9 的样本平均而言比其它类更像类别 4,于是类别 4 与 9 样本的更新会相互强化影响力,在彼此预测上形成鼓包。为验证这一点,我们在图 1-(d) 画出各类 上 的平均。部分非对角块的值显著高于其它,说明这些类的样本更相似,例如 4 与 9、5 与 3、8 与 5 等。
3 Learning Dynamics of LLM’s Finetuning
3 LLM 微调的学习动力学
Although learning dynamics have been applied to many deep learning systems, extending this framework to LLM finetuning is non-trivial. The first problem is the high dimensionality and the sequence nature of both the input and output signals. The high-dimensional property makes it hard to observe the model’s output, and the sequential nature makes the distributions on different tokens mutually dependent, which is more complicated than a standard multi-label classification problem considered by most previous work. Furthermore, as there are many different algorithms for LLM finetuning – SFT (Wei et al. 2022a), RLHF (Ouyang et al. 2022a), DPO (Rafailov et al. 2023a), etc. – analyzing them under a uniform framework is challenging. Finally, compared with the training-from-scratch scenario, where a roughly uniform distribution over all possible outputs is usually assumed, LLMs’ finetuning dynamics heavily rely on the pretrained base model, which could make the analysis harder. For example, the pretrained model usually assigns little probability mass to unlikely tokens, which is good for most applications but leads to risk of the “squeezing effect” we show later. We now tackle these problems and propose a unified framework for different finetuning methods.
尽管学习动力学已用于许多深度学习系统,将其扩展到 LLM 微调并非易事。首要问题是输入与输出信号都具有高维性与序列性。高维使观察模型输出困难,序列性又使不同 token 上的分布彼此依赖,比多数先前工作考虑的标准多标签分类更复杂。此外,LLM 微调算法众多——SFT(Wei et al. 2022a)、RLHF(Ouyang et al. 2022a)、DPO(Rafailov et al. 2023a)等——要在统一框架下分析它们颇具挑战。最后,与通常假设输出近似均匀的从零训练不同,LLM 微调动力学严重依赖预训练基座,分析更难。例如,预训练模型通常把很少概率质量分给不太可能的 token,这对多数应用有利,却会带来后文所示「挤压效应」的风险。下文我们着手解决这些问题,并提出面向不同微调方法的统一框架。
3.1 Per-step Decomposition of the SFT Loss
3.1 SFT 损失的逐步分解
The typical loss function used during supervised finetuning is the negative log-likelihood (NLL) of a given completion , conditioned on the prompt :
监督微调中常用的损失是给定补全 、以提示 为条件的负对数似然(NLL):
Note that compared with the multi-label classification problem discussed before, where the joint distribution of all labels can be factorized as , the sequential nature of language modeling makes the analysis more complicated, because we must have . To solve this problem, we can merge this factorization into the definition of the backbone while keeping the format of Proposition 1. Specifically, letting be the concatenation of and , the prediction of all tokens of is
注意,与前文多标签分类中联合分布可分解为 不同,语言建模的序列性使分析更复杂,因为必须有 。为处理这一点,可将该分解并入骨干 的定义,同时保持命题 1 的形式。具体地,令 为 与 的拼接,则 全部 token 的预测为
Here is a matrix where each column contains the logits of the prediction of the th token. Our , even though it takes the entire sequence as its input, will force the model not to refer to the future tokens when making predictions on the -th token, commonly implemented via “causal masking” (proposed in Vaswani et al. 2017a, details in Figure 10(a) of Appendix D). Then, we can calculate on each column of and stack them to form a tensor . The calculation of and also follows a similar procedure. Thanks to the causal mask implemented in , the resulting decomposition is almost identical to that in a multi-label classification problem. Assuming have a response of length associated with , stacked into , and of length associated with , stacked into . The change of the model’s prediction on the -th token of can be represented as, when gradients have bounded norm,
这里 是 矩阵,每列含第 个 token 预测的 logits。我们的 虽以整段序列 为输入,但会强制模型在预测第 个 token 时不参考未来 token ,通常由「因果掩码」实现(Vaswani et al. 2017a 提出,细节见附录 D 图 10(a))。于是可对 的每列计算 ,再堆成 张量 。 与 的计算类似。得益于 中的因果掩码,所得分解几乎与多标签分类相同。假设与 关联的回复 长度为 ,拼成 ;与 关联的 长度为 ,拼成 。在 梯度范数有界时, 第 个 token 上模型预测的变化可表示为
where . Compared with Proposition 1, the main difference is that the eNTK term also depends on the responses and , which allows us to answer questions like
其中 。与命题 1 相比,主要差别是 eNTK 项也依赖于回复 与 ,从而可回答如下问题
For a prompt , how does learning the response {\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}^{+}} influence the model’s belief about a response {\color[rgb]{1,0.5,0}\bm{\mathsf{y}}_{u}^{\prime}}?
对提示 ,学习回复 {\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}^{+}} 如何影响模型对回复 {\color[rgb]{1,0.5,0}\bm{\mathsf{y}}_{u}^{\prime}} 的信念?
When tracking the model’s confidence on different responses given the question , learning from will impose a strong “upwards” pressure on , as illustrated in the first panel of Figure 2. At the same time, the confidence of “similar responses” will also be slightly pulled up, like how learning a 4 influences the prediction on 9 in the MNIST example. We will discuss how to understand the “similarity” between two sequences of responses in the next section.
在跟踪给定问题 下模型对不同回复的置信度时,从 学习会对 施加强烈「向上」压力,如图 2 第一幅所示。与此同时,「相似回复」的置信度也会被略微拉高,类似 MNIST 中学习 4 会影响对 9 的预测。下一节讨论如何理解两段回复之间的「相似性」。
3.2 Per-step Decomposition of the DPO Loss
3.2 DPO 损失的逐步分解
Preference finetuning, which teaches the model to provide responses that align better with human preferences, is also an important phase in LLM finetuning pipelines. Different from the SFT stage above, where the training tells the model “what to do”, many preference finetuning methods also teach the model “what not to do,” which makes the learning dynamics more complex. For intuition, we start by analyzing a typical method, i.e., DPO (direct preference optimization, an RL-free method), under a similar framework. Following Rafailov et al. 2023a, the loss function of off-policy DPO is
偏好微调教模型给出更符合人类偏好的回复,同样是 LLM 微调流程中的重要阶段。与上文 SFT「告诉模型该做什么」不同,许多偏好微调方法还会教模型「不该做什么」,学习动力学因此更复杂。为建立直觉,我们先在相似框架下分析典型方法 DPO(直接偏好优化,一种免 RL 方法)。按 Rafailov et al. 2023a,off-policy DPO 的损失函数为
where and are pre-generated responses, and is the reference model, typically the result of SFT. In the loss function, the terms are also calculated using teacher forcing. Hence we can decompose the learning dynamics for DPO similarly to Equation 5,
其中 与 是预先生成的回复, 为参考模型,通常是 SFT 结果。损失中的 项同样用 teacher forcing 计算,故可将 DPO 的学习动力学按与式 5 类似的方式分解:
where is the margin (i.e., the value) for the -th token, which represents how well the current policy separates and compared with the reference policy. Due to the monotonicity of , a larger margin leads to larger , which in turn restrains the strength of . In other words, automatically provides less energy on the examples that are already well separated. We then check the role of , which controls the regularizing effect on the KL distance between and in the original RL loss (Rafailov et al. 2023a). When the margin is negative, larger leads to a smaller and hence provides stronger for the model to “catch up” the separating ability of the reference model faster. But when the model is better and has a positive margin, increasing will increase and hence create a negative influence on , which makes the model update less. This aligns well with the claims of Rafailov et al. 2023a: the stronger regularizing effect tends to “drag back towards ” when its predictions deviate from too much. The derivation and the functions for other RL-free methods are given in Section B.2.2.
其中 是第 个 token 的间隔(即 的值),表示当前策略相对参考策略区分 与 的好坏。由于 单调,间隔越大则 越大,从而抑制 的强度。换言之,对已分得很开的样本, 会自动提供更少能量。再看 的作用:它在原始 RL 损失中控制 与 之间 KL 距离的正则强度(Rafailov et al. 2023a)。当间隔为负时,更大的 使 更小,从而给出更强的 ,让模型更快「追上」参考模型的区分能力。但当模型更好、间隔为正时,增大 会增大 ,进而对 产生负向影响,使更新变弱。这与 Rafailov et al. 2023a 的论断一致:更强的正则倾向于在预测偏离 过多时「把 拉回 」。推导及其它免 RL 方法的 见第 B.2.2 节。
These analyses make no assumptions on where and come from. Hence our framework can be directly extended to on-policy RL-free methods, which often perform better than their off-policy counterparts (Tajwar et al. 2024a; Guo et al. 2024c). The main difference between these algorithms is how the supervisory responses are generated. Off-policy methods typically use a fixed pre-collected dataset, with and are generated by another LLM or humans. In other words, it is likely that both the chosen and rejected responses come from the “less likely” region of the model’s prediction. On-policy responses, though, are more likely to have higher predicted probabilities under this model, as they were sampled from it. We will show next that imposing large negative pressure on an unlikely prediction will lead to unexpected behavior, giving a new explanation for why on-policy sampling is important for algorithms with large negative gradients.
上述分析不对 与 的来源做假设,因此框架可直接扩展到往往优于 off-policy 对照的 on-policy 免 RL 方法(Tajwar et al. 2024a;Guo et al. 2024c)。算法间的主要差别在于监督回复如何生成。Off-policy 方法通常使用固定预采集数据集, 与 由另一 LLM 或人类生成;换言之,偏好与拒绝回复都可能落在模型预测的「不太可能」区域。On-policy 回复则更可能在该模型下具有更高预测概率,因为它们是从该模型采样得到的。下一节将表明:对不太可能的预测施加很大的负压会导致意外行为,从而为「为何带大负梯度的算法需要 on-policy 采样」提供新解释。
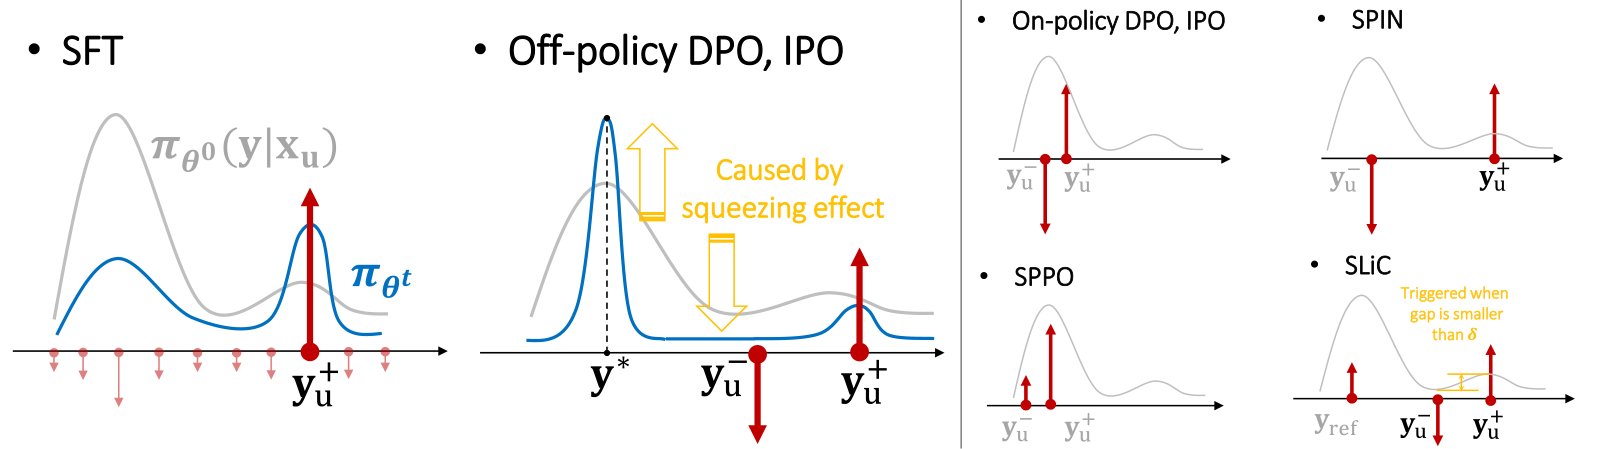
Figure 2: The updating vector provided by the residual term of different algorithms. The gray are responses sampled from in an on-policy way. In the second panel, we demonstrate the “squeezing effect” caused by imposing a big negative gradient on a “valley” region of a distribution. For more details about this counter-intuitive effect, please refer to Section 3.3 and Appendix E. Other panels demonstrate on-policy DPO (and IPO), SPIN (Chen et al. 2024a), SPPO (Wu et al. 2024a), and SLiC (Zhao et al. 2023a).
图 2:不同算法残差项 提供的更新向量。灰色 是以 on-policy 方式从 采样的回复。第二幅展示在分布的「谷底」区域施加大负梯度引起的「挤压效应」。该反直觉效应的更多细节见第 3.3 节与附录 E。其余各幅展示 on-policy DPO(及 IPO)、SPIN(Chen et al. 2024a)、SPPO(Wu et al. 2024a)与 SLiC(Zhao et al. 2023a)。
3.3 The Squeezing Effect Caused by Negative Gradient
3.3 负梯度引起的挤压效应
As demonstrated by the first two panels in Figure 2, the use of large negative gradients is the main difference between the learning dynamics of SFT and DPO. We will show later that this difference is the key to understanding why the learning curves of SFT and DPO behave so differently. For example, Rafailov et al. 2024a; Tajwar et al. 2024a; Pal et al. 2024a (and our Figure 4) reported that the confidence of both and gradually decreases when conducting DPO, while the confidence of rarely drops during SFT. This trend becomes more serious if is finetuned for longer before conducting DPO (reported in Figure 3 of Rafailov et al. 2024a and verified by our Figure 17). Furthermore, we also find that for all the we track (various responses similar to or ; details in the next section), none of them increase during the DPO phase. This is different from SFT and quite counter-intuitive:
如图 2 前两幅所示,使用大负梯度是 SFT 与 DPO 学习动力学的主要差别。后文将表明,正是这一差别是理解为何 SFT 与 DPO 学习曲线表现如此不同的关键。例如,Rafailov et al. 2024a、Tajwar et al. 2024a、Pal et al. 2024a(以及我们的图 4)报告:做 DPO 时 与 的置信度都会逐渐下降,而 SFT 中 的置信度很少下降。若在做 DPO 前对 微调更久,该趋势更严重(见 Rafailov et al. 2024a 图 3,并由我们的图 17 验证)。此外我们还发现,所跟踪的所有 (与 或 相似的各类回复;细节见下节)在 DPO 阶段无一上升。这与 SFT 不同,且相当反直觉:
If everything we observe is becoming less confident, where has the probability mass gone?
若我们观察到的一切都变得更不自信,概率质量去哪了?
To answer this question, we first identify a phenomenon we call the squeezing effect, which occurs when using negative gradients from any model outputting a distribution with output heads, even in a simple multi-class logistic regression task. Specifically, in the case when we impose a negative gradient on label , we can describe the changing of model’s predictive distribution as follows:
为回答该问题,我们先指出一种称为挤压效应的现象:只要模型用 Softmax 输出头给出分布,即便在简单的多类逻辑回归任务中,使用负梯度也会出现该现象。具体地,在 情形对标签 施加负梯度时,可将预测分布 的变化描述如下:
- • Guarantee: the confidence of , i.e., will decrease.
- • Guarantee: the decreased probability mass is largely “squeezed” into the output which was most confident before the update: if , then will increase.
- • Trend: the rich get richer and the poor get poorer: generally, dimensions with high tend to increase, and those with low tend to decrease.
- • Trend: peakier squeezes more. If the probability mass concentrates on few dimensions in , which is common for a pretrained model, all decrease (only is “rich”).
- • Trend: smaller exacerbate the squeezing effect: if is unlikely under , the probability mass of all other will be more seriously decreased, and the increases more.
- • 保证: 的置信度,即 会下降。
- • 保证:下降的概率质量很大程度上被「挤压」到更新前最自信的输出上:若 ,则 会上升。
- • 趋势:富者愈富、贫者愈贫:一般地, 高的维倾向于上升,低的维倾向于下降。
- • 趋势:更尖峰的 挤压更强。若 的概率质量集中在少数维上(预训练模型常见),则所有 都下降(只有 「富」)。
- • 趋势:更小的 会加剧挤压:若 在 下不太可能,则其它所有 下降更严重,且 上升更多。
Appendix E illustrates the squeezing effect and analytically proves its existence for logistic regression models, by directly computing in different situations. Section 4.2 also experimentally verifies the analysis above in real LLM experiments. Note that in practical settings, where both positive and negative pressures and the auto-regressive nature are strictly considered, the squeezing effect can become more complicated. The differences between the two eNTK terms in Equation 7 also influence the relative strength and direction of these two pressures. Razin et al. 2025a analyze a similar problem in a token-level setting, and their conclusions align with ours well. We left a more detailed analysis to our future work.
附录 E 说明挤压效应,并通过直接计算不同情形下的 ,对逻辑回归模型给出存在性的解析证明。第 4.2 节亦在真实 LLM 实验中验证上述分析。注意在同时严格考虑正负压力与自回归特性的实际设定中,挤压效应会更复杂。式 7 中两个 eNTK 项的差异也会影响这两种压力的相对强度与方向。Razin et al. 2025a 在 token 级设定下分析了类似问题,结论与我们一致。更细致的分析留待未来工作。
We can now get a high-level overview of the learning dynamics of a typical off-policy DPO algorithm. Since both and are not sampled from the model’s distribution, sometimes can be dissimilar to , and the are likely located in a valley region of the model’s prediction. Then its learning dynamics would look like the sketch in the second panel of Figure 2: the confidence on almost all are pushed down. At the same time, all the decreased probability mass is squeezed to , which might make the model keep generating repeated phrases, as reported by Holtzman et al. 2020a. Variants of DPO algorithms often unintentionally mitigate this squeezing effect by constraining the strength of the negative gradient or the positions of , which partially explains their benefits. The last four panels in Figure 2 and Section B.2.2 have more details.
至此可对典型 off-policy DPO 算法的学习动力学有一高层概览。由于 与 都不是从模型分布采样, 有时会与 不相似,而 很可能落在模型预测的谷底区域。于是其学习动力学会如图 2 第二幅草图:几乎所有 上的置信度都被压低;同时下降的概率质量被挤压到 ,可能使模型不断生成重复短语,正如 Holtzman et al. 2020a 所报告。各类 DPO 变体往往通过约束负梯度强度或 的位置无意中缓解挤压效应,这部分解释了它们的收益。图 2 后四幅与第 B.2.2 节有更多细节。
4 Experimental Verifications
4 实验验证
We now verify our analysis in practical settings. We first create the training set by randomly selecting 5000 examples from the training split of the dataset. We consider two common datasets, Antropic-HH (Bai et al. 2022a) and UltraFeedback (Cui et al. 2023a), in all experiments. Each example in contains three components: the prompt (or question) , the preferred response , and the less preferred response . SFT finetunes with and , while DPO uses all three (subscripts of and are removed for conciseness). We repeat the experiments on two series of models: pythia-410M/1B/1.4B/2.8B (Biderman et al. 2023a) and Qwen1.5-0.5B/1.8B (Bai et al. 2023a).
我们现在在实际设定中验证分析。首先从数据集训练划分随机选取 5000 条构成训练集 。全部实验考虑两个常用数据集:Antropic-HH(Bai et al. 2022a)与 UltraFeedback(Cui et al. 2023a)。 中每条含三部分:提示(或问题)、偏好回复 、较不偏好回复 。SFT 用 与 微调,DPO 三者皆用(为简洁省略 、 下标)。实验在两系列模型上重复:pythia-410M/1B/1.4B/2.8B(Biderman et al. 2023a)与 Qwen1.5-0.5B/1.8B(Bai et al. 2023a)。
To get a more detailed observation of the learning dynamics, we further create a probing dataset by randomly selecting 500 examples from , and generate several typical responses based on the corresponding , , or . (We also study another probing dataset where all come from the test set in an ablation study in the appendix.) Then for each in , we can observe how gradually changes on different types of . For example, one extended response type can be a rephrase of , an irrelevant response answering another question , or just a randomly generated English sentence with the same number of words with . We explain why we need these extended responses and how they are generated in detail in Section D.1. In short, helps us to get a more fine-grind inspection of the learning dynamics, which can not only support our analysis above, but also shed more light on how the model’s prediction evolves on the entire , a very sparse and huge space.
为更细致观察学习动力学,我们再从 随机选 500 条构成探测集 ,并基于对应的 、 或 生成若干典型回复。(附录消融中还研究了另一探测集,其中所有 来自测试集。)于是对 中每个 ,可观察 在不同类型 上如何逐渐变化。例如,扩展回复类型可以是 的改写、回答另一问题 的无关回复,或与 词数相同的随机英文句。第 D.1 节详细说明为何需要这些扩展回复以及如何生成。简言之, 有助于更细粒度检视学习动力学,既支撑上文分析,也揭示模型预测在整个 (极其稀疏且巨大的空间)上如何演化。
4.1 Learning dynamics of SFT
4.1 SFT 的学习动力学
The main lesson we learn from the analysis in Section 3.1 is that learning from not only increases the model’s confidence on , but also indirectly “pulls up” responses similar to with a smaller strength (scaled roughly by ), similar to how learning a “4” influences the prediction of a “9” in the MNIST example. At the same time, the increase of naturally “pushes down” all , because the model’s predicted probability to all responses in -space must sum to one. The model’s behavior on different is mostly a trade-off among these pressures. To verify this claim, we finetune the model for several epochs and evaluate the model’s prediction on all responses in every 25 updates (with a training batch size of 4, the probing occurs every 100 examples). For each type of response, we average the model’s confidence on all 500 examples and report the mean value of their log-likelihood.
第 3.1 节分析的主要启示是:从 学习不仅提高模型对 的置信度,还会以较小强度(大致按 缩放)间接「拉高」与 相似的回复,类似 MNIST 中学习「4」会影响对「9」的预测。同时, 的上升自然会「压低」所有 ,因为 空间中所有回复的预测概率之和为 1。模型在不同 上的行为主要是这些压力之间的权衡。为验证该论断,我们微调若干 epoch,每 25 次更新评估模型在 全部回复上的预测(训练批大小为 4,即每 100 条样本探测一次)。对每类回复,在全部 500 例上平均模型置信度,并报告对数似然均值。
As demonstrated in the first panel of Figure 3, the model’s confidence on keeps increasing throughout the whole learning process, which is straightforward because the main “pull-up” pressure is imposed directly on . However, the behavior of some responses similar to is non-trivial. For example, we draw the following types of responses in the same panel, i.e., the less preferred response for the same question (), two types of rephrases of generated by ChatGPT ( and ), another preferred response randomly selected from the test set (), or even a randomly generated English sentence (). The model’s confidence in these responses are all slightly increased at the beginning of training, and then gradually decrease as the training goes on, even though the model never sees them during SFT. This counter-intuitive behavior can be well explained by the learning dynamics we discussed before. Since all these examples are “similar” to to some extent (at least, they are all common “standard English” sentences), their are reasonably large. Then learning will indirectly increase the model’s confidence of these similar . That is why the corresponding are slightly increased at the beginning of training. However, as the training goes on, the model’s confidence on keeps increasing and the update energy, the norm of in Equation 5, gradually decreases. That means the indirect “pull-up” pressures are also diminished accordingly. Then, the “push-down” pressure on all becomes dominant and all the related curves start going down.
如图 3 第一幅所示,模型对 的置信度在整个学习过程中持续上升,这很直接,因为主要「拉高」压力直接作用在 上。但一些与 相似的回复行为并不平凡。同幅中我们画出:同一问题的较不偏好回复()、由 ChatGPT 生成的两类 改写( 与 )、从测试集随机选取的另一偏好回复(),乃至随机生成的英文句()。这些回复上的置信度在训练初期都略有上升,随后随训练逐渐下降,尽管 SFT 中从未见过它们。该反直觉行为可由前述学习动力学很好解释。这些样本在某种程度上都与 「相似」(至少都是常见「标准英文」句子),其 足够大,于是学习 会间接提高这些相似 的置信度,故训练初期对应 略升。但随训练推进,对 的置信度持续上升,式 5 中更新能量 逐渐减小,间接「拉高」压力随之减弱,于是对所有 的「压低」压力占主导,相关曲线开始下降。
To verify the existence of this global “push-down” pressure, we observe two types of responses; both have the same number of words as their . One is a purely random English word sequence . Another is a random permutation of all the words in , which is called . Since both are not natural language, we expect the between them and to be very small, which means learning from imposes almost no “pull-up” pressure on them; thus the “push-down” pressure will dominate through the whole training procedure. These analyses are well supported by the second panel in Figure 3, in which we see these all start from a very small value, and keep decreasing throughout the training.
为验证这种全局「压低」压力的存在,我们观察两类与各自 词数相同的回复:一是纯随机英文词序列 ;二是 全部词的随机置换,记为 。二者都不是自然语言,我们预期它们与 之间的 很小,即从 学习几乎不对它们施加「拉高」压力,因而「压低」压力会贯穿整个训练。图 3 第二幅很好支持这些分析:这些 均从很小的值起步,并在训练全程持续下降。
Another interesting type of responses is , a preferred response for another question in the training set. For these responses, the model’s prediction on will be kept influenced by two “pull-up” pressures: one is from learning , another is from learning , where the latter might be even stronger as the gradient is directly calculated by observing . That explains why we see the confidence on keeps increasing with a smaller rate compared with in the third panel. Because the “pull-up” pressure is always strong enough to counter the “push-down” one. These observations provide us with a unique explanation of why specific types of hallucinations are amplified after SFT. Specifically, the increase of means if we ask the model to answer a question , it might provide a response from (or partially from) another unrelated question in the training set.
另一类有趣的回复是 ,即训练集中另一问题 的偏好回复。对这些回复,模型对 的预测会持续受到两股「拉高」压力影响:一来自学习 ,二来自学习 ,后者可能更强,因为梯度是通过直接观察 算得的。这解释了为何第三幅中对 的置信度以小于 的速率持续上升——「拉高」压力始终足以对抗「压低」。这些观察为「为何某些幻觉在 SFT 后被放大」提供了独特解释:具体地, 上升意味着若问模型 ,它可能给出(或部分给出)训练集中另一无关问题 的回复。
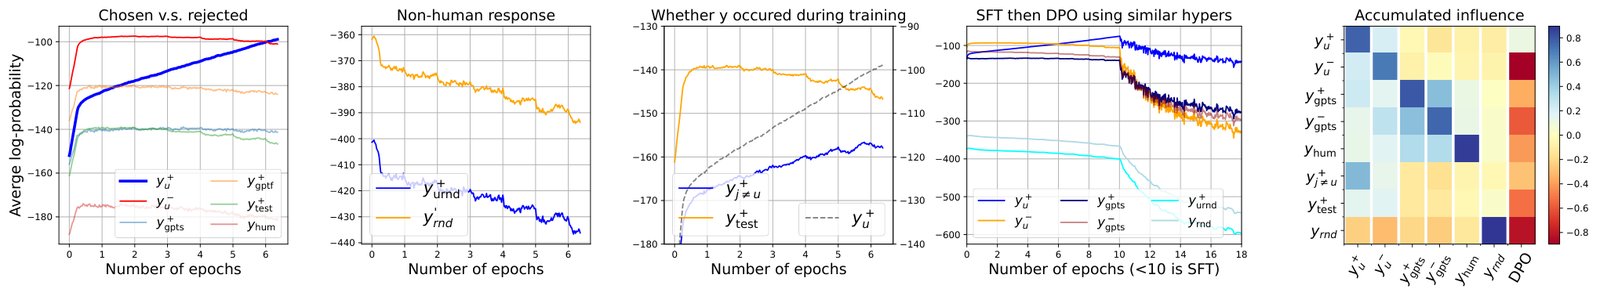
Figure 3: First three: learning dynamics of SFT on different response types. Fourth: SFT 10 epochs then DPO. Last: the accumulated influence when SFT using different (full results in Appendix C and D).
图 3:前三幅:SFT 在不同回复类型上的学习动力学。第四幅:SFT 10 个 epoch 再做 DPO。末幅:用不同 做 SFT 时的累积影响力(完整结果见附录 C 与 D)。
Last, to further explore the “similarity” between different responses from the model’s perspective. we SFT the model using more types of responses and observe how changes accordingly. The results are demonstrated in Figure 3, where the blue and orange colors represent the positive and negative influence respectively. The x-axis is the updating response while the y-axis denotes the observing response. Hence the first column resembles how different changes when we SFT the model using . One interesting finding is that all responses generated by ChatGPT are considered very similar to each other, regardless of how semantically different they are. Probably, LLM has its preferred idioms or phrases, which could be considered as a type of “fingerprint”. We left this interesting problem for our future work.
最后,为进一步从模型视角探索不同回复之间的「相似性」,我们用更多类型的回复做 SFT,并观察 如何相应变化。结果见图 3,蓝、橙分别表示正向与负向影响。横轴为更新所用回复,纵轴为观察回复。因此第一列类似:用 做 SFT 时,不同 如何变化。一个有趣发现是:ChatGPT 生成的所有回复彼此都被视为非常相似,无论语义差别多大。或许 LLM 有其偏好的惯用表达或短语,可视为一种「指纹」。该有趣问题留待未来工作。
4.2 Learning dynamics of off-policy DPO
4.2 Off-policy DPO 的学习动力学
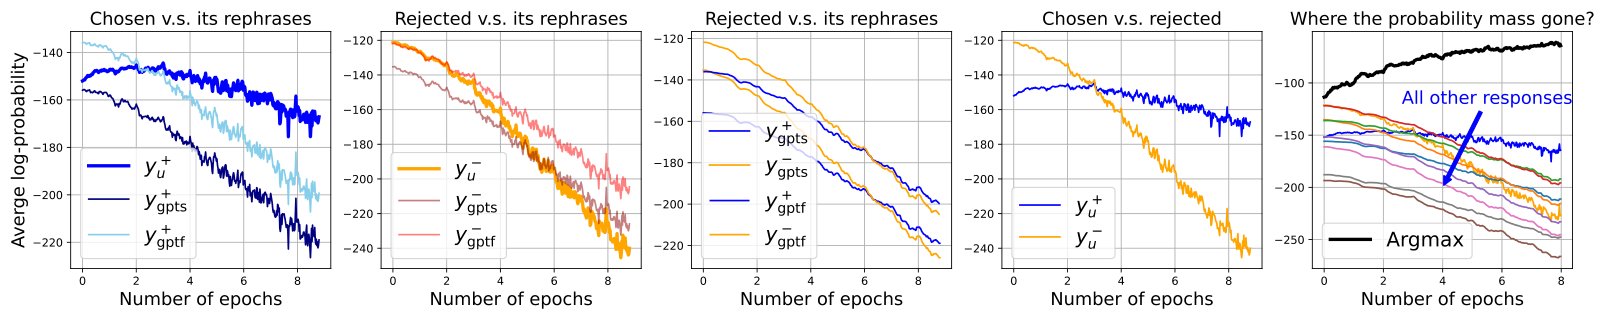
Figure 4: Learning dynamics of off-policy DPO. The last panel verifies the existence of the squeezing effect.
图 4:Off-policy DPO 的学习动力学。末幅验证挤压效应的存在。
To verify our framework also explains the model’s behavior in preference tuning, we conduct similar experiments for DPO. Recall the residual term introduces a pair of arrows on both and , with different directions. To show how these two pressures influence the model, we check two types of rephrases of or (, , , and , used in the previous experiment). See the three curves in the first panel in Figure 4, where the two rephrases decrease at a similar speed, faster than the decay of . That is because the upward pressure is directly imposed on rather than these rephrases. Similarly, in the second panel, we observe that decays faster than its rephrases, because directly imposes a negative pressure on . Then in the third panel, we find the rephrases of consistently decay slower than those of , although none of them ever occur during training. That is because these responses are close to or in , which means their is relatively large. Hence the pressures imposed on and also introduce a non-negligible influence on them. Last, in the fourth panel, the margin keeps increasing, which means the model is gaining the ability to separate and as the training goes on.
为验证框架同样能解释偏好微调中的模型行为,我们对 DPO 做类似实验。回忆 残差项在 与 上引入方向不同的一对箭头。为展示这两种压力如何影响模型,我们检查 或 的两类改写(前一实验用过的 、、、)。见图 4 第一幅三条曲线:两类改写以相近速度下降,快于 的衰减——因为向上压力直接作用在 而非这些改写上。类似地,第二幅中 比其改写衰减更快,因为 直接对 施加负压。第三幅中, 的改写始终比 的改写衰减更慢,尽管训练中从未出现它们——因为这些回复在 中靠近 或 ,即 相对较大,故作用在 、 上的压力也会对它们产生不可忽视的影响。最后,第四幅中间隔 持续增大,说明随训练推进模型区分 与 的能力在增强。
Although directly imposes a “pull-up” pressure on , the value of does not increase a lot as it does in SFT. The downward arrow on indeed introduces a “push-down” pressure on responses that are similar to , but the influence is unlikely to be that strong (it will be weakened by ) to make the confidence on almost every observing responses decrease so fast, as demonstrated in the last panel of Figure 3 where we use similar for both SFT and DPO. Then, where has the probability mass gone during DPO? The key to answering this question is the squeezing effect discussed in Section 3.3: since the big negative gradient is imposed on , which is at this point probably in a region of low , the confidence of most will be decreased and will increase very fast.
尽管 直接对 施加「拉高」压力, 并未像 SFT 中那样大幅上升。 上的向下箭头确实会对与 相似的回复引入「压低」压力,但该影响不太可能强到(会被 削弱)使几乎所有观测回复的置信度下降如此之快——见图 3 末幅,我们对 SFT 与 DPO 使用相近的 。那么,DPO 期间概率质量去哪了? 回答关键是第 3.3 节的挤压效应:大负梯度作用在此时很可能处于低 区域的 上,于是多数 的置信度下降,而 快速上升。
To verify this, we report the log-likelihood of chosen by greedy decoding: each token is chosen by maximizing the conditional probability given in real-time, where is a sub-sequence of . As illustrated by the last panel of Figure 4, the confidence of this “teacher forcing” greedy increases very fast (from -113 to -63), which is even faster than the increase of during SFT (from -130 to -90), within 8 epochs. However, the tokens with the highest confidence do not necessarily form a preferred response: it will reinforce the prior bias in . This could be a reasonable explanation of the “degeneration” reported in recent work (e.g. Holtzman et al. 2020a): as becomes more peaky at its most confident predictions, it is easier to sample sequences with repeated phrases. Note that such behavior could also be understood as a special type of self-bias amplifying (Ren et al. 2024a), which would bring more serious consequences if it is combined with a multiple-generation self-improving algorithm, e.g., self-reward (Yuan et al. 2024a), iterative DPO (Xiong et al. 2024a), etc.
为验证这一点,我们报告贪心解码所选 的对数似然:每个 token 在给定 时实时最大化条件概率,其中 是 的子序列。如图 4 末幅,这种「teacher forcing」贪心 的置信度上升极快(从 -113 到 -63),甚至快于 SFT 中 的上升(从 -130 到 -90),且仅用 8 个 epoch。然而,置信度最高的 token 未必构成偏好回复:它会强化 中的先验偏差。这可合理解释近期工作报告的「退化」(如 Holtzman et al. 2020a):当 在最自信预测上变得更尖峰时,更容易采样出含重复短语的序列。注意,此类行为也可理解为一种特殊的自我偏差放大(Ren et al. 2024a);若再与多轮生成式自我改进算法结合,例如 self-reward(Yuan et al. 2024a)、迭代 DPO(Xiong et al. 2024a)等,后果会更严重。
In summary, the behaviors of different types of responses all match our analyses well. More subtle trends of different responses support our story well (both for SFT and DPO).Due to space constraints, we explain these (and the full results on other models and datasets) in Appendix D.
总之,各类回复的行为都与我们的分析吻合。不同回复更细微的趋势也支持上述故事(对 SFT 与 DPO 皆然)。篇幅所限,这些内容以及其它模型与数据集上的完整结果放在附录 D。
4.3 Mitigating the squeezing effect by augmenting the training set for SFT
4.3 通过扩充 SFT 训练集缓解挤压效应
Since the “squeezing effect” caused by the big negative gradient on unlikely predictions can damage the model’s performance during DPO, we can first train the model on both and during the SFT stage (making the negative response more likely), and then run the usual DPO. Following the analysis above, we can expect during this new SFT stage, the region of those responses similar to or will be “pulled up” simultaneously. This is what we want because in many cases, both and are reasonably good responses for the question ; the new SFT design hence helps to pull up a larger region that contains more suitable responses compared with the baseline SFT. After that, the “push-down” pressure imposed during DPO can efficiently decrease the model’s confidence on and its similar responses. Since is no longer so unlikely before DPO, the squeezing effect should not be as strong as in the baseline procedure.
由于对不太可能预测施加大负梯度引起的「挤压效应」会损害 DPO 中的模型表现,我们可以先在 SFT 阶段同时在 与 上训练(使负回复更可能),再按常規跑 DPO。按上文分析,可预期在这个新的 SFT 阶段,与 或 相似的回复区域会被同时「拉高」。这正是我们想要的:许多情形下 与 都是对问题 相当不错的回复;新的 SFT 设计因此有助于拉高比基线 SFT 更大、含更多合适回复的区域。之后,DPO 中施加的「压低」压力可有效降低模型对 及其相似回复的置信度。由于 DPO 前 不再那么不可能,挤压效应应不如基线流程严重。
| DPO Ep. | ChatGPT | Claude |
|---|---|---|
| 0 | 0.4729 | 0.4679 |
| 2 | 0.6518 | 0.5151 |
| 4 | 0.6928 | 0.6045 |
| 6 | 0.6667 | 0.5432 |
Table 1: Win-rate against baseline.
| DPO Ep. | ChatGPT | Claude |
|---|---|---|
| 0 | 0.4729 | 0.4679 |
| 2 | 0.6518 | 0.5151 |
| 4 | 0.6928 | 0.6045 |
| 6 | 0.6667 | 0.5432 |
表 1:相对基线的胜率。
We call our training pipeline “extend” and compare its learning dynamics with the baseline setting in Figure 5. It is clear that the squeezing effect is mitigated, because the confidence of other responses all decays slower during DPO, and we also observe a big drop in the greedy-decoding response when DPO starts. To further show that mitigating the squeezing effect indeed brings benefits, we compare the responses generated by models trained using different methods by feeding them to ChatGPT and Claude3. Specifically, we first SFT the model for two epochs using two methods discussed above and call the resulting policy network and . Then, we conduct identical DPO training on both and for several epochs. The win rate of the proposed method against the baseline one is provided in Table 1. It is clear that before DPO, is better, because is explicitly trained on those . However, the performs better after DPO several epochs since the squeezing effect is efficiently mitigated. Please refer to Appendix F for more details. In the future, this simple method inspired by our analysis could be further improved by introducing more responses, e.g., rephrases of , etc., during both stages, and also by combining with many existing RL-free methods we mentioned before.
我们将该训练流程称为「extend」,并在图 5 中与基线设定比较学习动力学。显然挤压效应得到缓解:其它回复在 DPO 中衰减更慢,且 DPO 开始时贪心解码回复出现明显下降。为进一步表明缓解挤压确实带来收益,我们将不同方法训得模型生成的回复送入 ChatGPT 与 Claude3 比较。具体地,先用上述两种方法各 SFT 两个 epoch,得到策略网络 与 ;再对二者做相同的若干 epoch DPO。所提方法相对基线的胜率见表 1。显然,DPO 前 更好,因为 显式在那些 上训练过;但 DPO 若干 epoch 后 表现更好,因挤压效应被有效缓解。更多细节见附录 F。未来,这一由分析启发的简单方法还可通过在两阶段引入更多回复(如 的改写等),并与前述多种免 RL 方法结合而进一步改进。
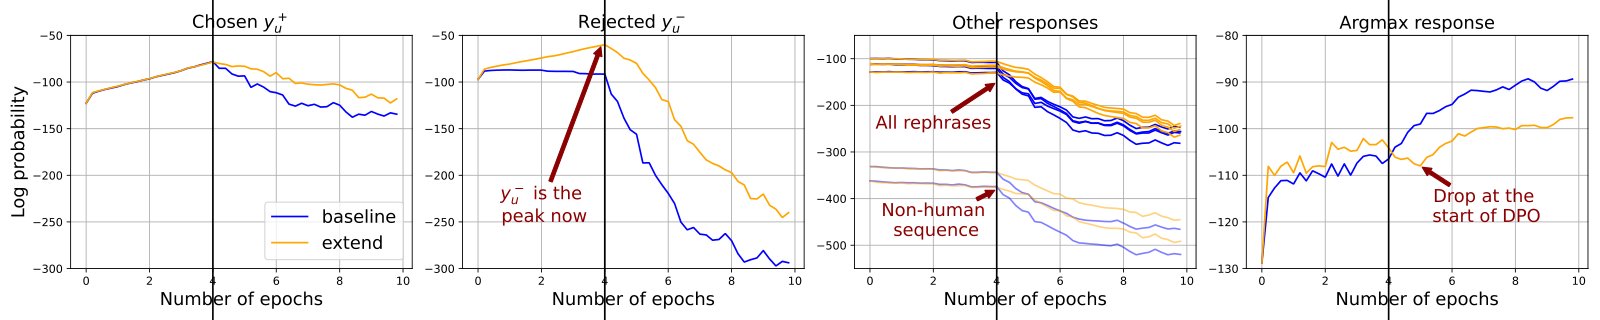
Figure 5: Learning dynamics of the baseline and the proposed method with training data extension. Key trends to observe: 1.) Baseline and the extend method have similar behavior on during SFT; 2.) The extend method considerably increase during SFT; 3.) The squeezing effect of the extend method is weaker (all other responses decay slower and the confidence on the “greedy-decoding” response increases slower).
图 5:基线与所提训练数据扩充方法的学习动力学。需关注的关键趋势:1)基线与 extend 在 SFT 阶段对 行为相似;2)extend 在 SFT 中显著提高 ;3)extend 的挤压效应更弱(其它回复衰减更慢,「贪心解码」回复置信度上升更慢)。
5 Conclusion
5 结论
Learning dynamics, which depict how the model’s prediction changes when it learns new examples, provide a powerful tool to analyze the behavior of models trained with gradient descent. To better utilize this tool in the context of LLM finetuning, we first derive the step-wise decomposition of LLM finetuning for various common algorithms. Then, we propose a unified framework for understanding LLM predictions’ behaviors across different finetuning methods. The proposed analysis successfully explains various phenomena during LLM’s instruction tuning and preference tuning, some of them are quite counter-intuitive. We also shed light on how specific hallucinations are introduced in the SFT stage, as previously observed (Gekhman et al. 2024a), and where the improvements of some new RL-free algorithms come from compared with the vanilla off-policy DPO. The analysis of the squeezing effect also has the potential to be applied to other deep learning systems which apply big negative gradients to already-unlikely outcomes. Finally, inspired by this analysis, we propose a simple (but counter-intuitive) method that is effective in improving the alignment of models.
学习动力学刻画模型在学习新样本时预测如何变化,是分析梯度下降训练模型行为的有力工具。为在 LLM 微调场景更好利用该工具,我们首先导出多种常见算法的逐步分解,再提出统一框架,理解不同微调方法下 LLM 预测行为。所提分析成功解释了指令微调与偏好微调中的多种现象,其中一些相当反直觉。我们还阐明了 SFT 阶段如何引入特定类型幻觉(此前由 Gekhman et al. 2024a 观察到),以及一些新的免 RL 算法相对朴素 off-policy DPO 的改进从何而来。对挤压效应的分析也有望推广到其它对已不太可能结果施加大负梯度的深度学习系统。最后,受该分析启发,我们提出一种简单(但反直觉)且能有效提升模型对齐的方法。
Acknowledgements
致谢
This research was enabled in part by support provided by the Canada CIFAR AI Chairs program, WestGrid, and Compute Canada. We thank Shangmin Guo, Noam Razin, Wonho Bae, and Hamed Shirzad for their valuable discussions and feedback. We also appreciate the constructive comments from the anonymous reviewers, which helped improve this work.
本研究部分得益于 Canada CIFAR AI Chairs 项目、WestGrid 与 Compute Canada 的支持。感谢 Shangmin Guo、Noam Razin、Wonho Bae 与 Hamed Shirzad 的宝贵讨论与反馈。亦感谢匿名审稿人的建设性意见,帮助改进本文。
References
参考文献
Arora et al. (2019) Sanjeev Arora, Simon. Du, Wei Hu, Zhiyuan Li, Ruslan Salakhutdinov and Ruosong Wang “On Exact Computation with an Infinitely Wide Neural Net” In NeurIPS , 2019 arXiv: 1904.11955
Azar et al. (2024) Mohammad Azar, Zhaohan Guo, Bilal Piot, Remi Munos, Mark Rowland, Michal Valko and Daniele Calandriello “A general theoretical paradigm to understand learning from human preferences” In International Conference on Artificial Intelligence and Statistics , 2024, pp. 4447–4455 PMLR
Bai et al. (2023) Jinze Bai, Shuai Bai and et.al “Qwen Technical Report”, 2023 arXiv: 2309.16609
Bai et al. (2022) Yuntao Bai, Andy Jones, Kamal Ndousse, Amanda Askell, Anna Chen, Nova DasSarma, Dawn Drain, Stanislav Fort, Deep Ganguli and Tom Henighan “Training a helpful and harmless assistant with reinforcement learning from human feedback”, 2022 arXiv: 2204.05862
Biderman et al. (2023) Stella Biderman, Hailey Schoelkopf, Quentin Anthony, Herbie Bradley, Kyle O’Brien, Eric Hallahan, Mohammad Khan, Shivanshu Purohit, USVSN Prashanth and Edward Raff “Pythia: A suite for analyzing large language models across training and scaling” In ICML , 2023, pp. 2397–2430 PMLR
Caccia et al. (2020) Massimo Caccia, Lucas Caccia, William Fedus, Hugo Larochelle, Joelle Pineau and Laurent Charlin “Language GANs Falling Short” In International Conference on Learning Representations , 2020
Chen et al. (2024) Zixiang Chen, Yihe Deng, Huizhuo Yuan, Kaixuan Ji and Quanquan Gu “Self-play fine-tuning converts weak language models to strong language models”, 2024 arXiv: 2401.01335
Choshen et al. (2020) Leshem Choshen, Lior Fox, Zohar Aizenbud and Omri Abend “On the Weaknesses of Reinforcement Learning for Neural Machine Translation” In International Conference on Learning Representations , 2020
Christiano et al. (2017) Paul Christiano, Jan Leike, Tom Brown, Miljan Martic, Shane Legg and Dario Amodei “Deep reinforcement learning from human preferences” In NeurIPS , 2017
Cui et al. (2023) Ganqu Cui, Lifan Yuan, Ning Ding, Guanming Yao, Wei Zhu, Yuan Ni, Guotong Xie, Zhiyuan Liu and Maosong Sun “UltraFeedback: Boosting Language Models with High-quality Feedback”, 2023 arXiv: 2310.01377 [cs.CL]
Feldman (2020) Dan Feldman “Introduction to core-sets: an updated survey”, 2020 arXiv: 2011.09384
Gekhman et al. (2024) Zorik Gekhman, Gal Yona, Roee Aharoni, Matan Eyal, Amir Feder, Roi Reichart and Jonathan Herzig “Does Fine-Tuning LLMs on New Knowledge Encourage Hallucinations?”, 2024 arXiv: 2405.05904
Guo et al. (2025) Daya Guo, Dejian Yang, Haowei Zhang, Junxiao Song, Ruoyu Zhang, Runxin Xu, Qihao Zhu, Shirong Ma, Peiyi Wang and Xiao Bi “Deepseek-r1: Incentivizing reasoning capability in llms via reinforcement learning” In arXiv preprint arXiv:2501.12948 , 2025
Guo et al. (2024) Shangmin Guo, Yi Ren, Stefano Albrecht and Kenny Smith “lpNTK: Better Generalisation with Less Data via Sample Interaction During Learning” In ICLR , 2024
Guo et al. (2024a) Shangmin Guo, Biao Zhang, Tianlin Liu, Tianqi Liu, Misha Khalman, Felipe Llinares, Alexandre Rame, Thomas Mesnard, Yao Zhao and Bilal Piot “Direct language model alignment from online AI feedback”, 2024 arXiv: 2402.04792
Hinton et al. (2015) Geoffrey Hinton, Oriol Vinyals and Jeff Dean “Distilling the knowledge in a neural network”, 2015 arXiv: 1503.02531
Holtzman et al. (2020) Ari Holtzman, Jan Buys, Li Du, Maxwell Forbes and Yejin Choi “The Curious Case of Neural Text Degeneration” In ICLR , 2020
Huang et al. (2023) Lei Huang, Weijiang Yu, Weitao Ma, Weihong Zhong, Zhangyin Feng, Haotian Wang, Qianglong Chen, Weihua Peng, Xiaocheng Feng and Bing Qin “A survey on hallucination in large language models: Principles, taxonomy, challenges, and open questions”, 2023 arXiv: 2311.05232
Jacot et al. (2018) Arthur Jacot, Franck Gabriel and Clément Hongler “Neural tangent kernel: Convergence and generalization in neural networks” In NeurIPS , 2018
Ji et al. (2024) Haozhe Ji, Cheng Lu, Yilin Niu, Pei Ke, Hongning Wang, Jun Zhu, Jie Tang and Minlie Huang “Towards Efficient and Exact Optimization of Language Model Alignment”, 2024 arXiv: 2402.00856
Kumar et al. (2022) Ananya Kumar, Aditi Raghunathan, Robbie Jones, Tengyu Ma and Percy Liang “Fine-Tuning can Distort Pretrained Features and Underperform Out-of-Distribution” In ICLR , 2022
LeCun et al. (1998) Yann LeCun, Léon Bottou, Yoshua Bengio and Patrick Haffner “Gradient-based learning applied to document recognition” In Proceedings of the IEEE 86.11 Ieee, 1998, pp. 2278–2324
Liu et al. (2020) Sheng Liu, Jonathan Niles-Weed, Narges Razavian and Carlos Fernandez-Granda “Early-learning regularization prevents memorization of noisy labels” In NeurIPS , 2020
Mohamadi et al. (2022) Mohamad Mohamadi, Wonho Bae and Danica. Sutherland “Making Look-Ahead Active Learning Strategies Feasible with Neural Tangent Kernels” In NeurIPS , 2022 arXiv: 2206.12569
Ouyang et al. (2022) Long Ouyang, Jeffrey Wu, Xu Jiang, Diogo Almeida, Carroll Wainwright, Pamela Mishkin, Chong Zhang, Sandhini Agarwal, Katarina Slama and Alex Ray “Training language models to follow instructions with human feedback” In NeurIPS , 2022, pp. 27730–27744
Pal et al. (2024) Arka Pal, Deep Karkhanis, Samuel Dooley, Manley Roberts, Siddartha Naidu and Colin White “Smaug: Fixing Failure Modes of Preference Optimisation with DPO-Positive”, 2024 arXiv: 2402.13228
Park et al. (2024) Core Park, Maya Okawa, Andrew Lee, Ekdeep Lubana and Hidenori Tanaka “Emergence of Hidden Capabilities: Exploring Learning Dynamics in Concept Space” In The Thirty-eighth Annual Conference on Neural Information Processing Systems , 2024
Pruthi et al. (2020) Garima Pruthi, Frederick Liu, Satyen Kale and Mukund Sundararajan “Estimating training data influence by tracing gradient descent” In NeurIPS , 2020
Rafailov et al. (2024) Rafael Rafailov, Joey Hejna, Ryan Park and Chelsea Finn “From r r to Q ∗ Q^{*} : Your Language Model is Secretly a Q-Function”, 2024 arXiv: 2404.12358
Rafailov et al. (2023) Rafael Rafailov, Archit Sharma, Eric Mitchell, Christopher Manning, Stefano Ermon and Chelsea Finn “Direct preference optimization: Your language model is secretly a reward model” In NeurIPS , 2023
Razin et al. (2025) Noam Razin, Sadhika Malladi, Adithya Bhaskar, Danqi Chen, Sanjeev Arora and Boris Hanin “Unintentional Unalignment: Likelihood Displacement in Direct Preference Optimization” In The Thirteenth International Conference on Learning Representations , 2025
Ren et al. (2023) Yi Ren, Shangmin Guo, Wonho Bae and Danica. Sutherland “How to prepare your task head for finetuning” In ICLR , 2023
Ren et al. (2020) Yi Ren, Shangmin Guo, Matthieu Labeau, Shay. Cohen and Simon Kirby “Compositional languages emerge in a neural iterated learning model” In ICLR , 2020
Ren et al. (2024) Yi Ren, Shangmin Guo, Linlu Qiu, Bailin Wang and Danica Sutherland “Bias Amplification in Language Model Evolution: An Iterated Learning Perspective” In NeurIPS , 2024
Ren et al. (2022) Yi Ren, Shangmin Guo and Danica. Sutherland “Better Supervisory Signals by Observing Learning Paths” In ICLR , 2022
Ren et al. (2023a) Yi Ren, Samuel Lavoie, Michael Galkin, Danica Sutherland and Aaron Courville “Improving compositional generalization using iterated learning and simplicial embeddings” In NeurIPS , 2023
Ren & Sutherland (2024) Yi Ren and Danica. Sutherland “Understanding Simplicity Bias towards Compositional Mappings via Learning Dynamics” In NeurIPS 2024 Workshop on Compositional Learning: Perspectives, Methods, and Paths Forward , 2024
Schaeffer et al. (2024) Rylan Schaeffer, Brando Miranda and Sanmi Koyejo “Are emergent abilities of large language models a mirage?” In Advances in Neural Information Processing Systems 36 , 2024
Schulman et al. (2017) John Schulman, Filip Wolski, Prafulla Dhariwal, Alec Radford and Oleg Klimov “Proximal policy optimization algorithms” In arXiv preprint arXiv:1707.06347 , 2017
Settles (2009) Burr Settles “Active learning literature survey” University of Wisconsin-Madison Department of Computer Sciences, 2009
Tajwar et al. (2024) Fahim Tajwar, Anikait Singh, Archit Sharma, Rafael Rafailov, Jeff Schneider, Tengyang Xie, Stefano Ermon, Chelsea Finn and Aviral Kumar “Preference Fine-Tuning of LLMs Should Leverage Suboptimal, On-Policy Data”, 2024 arXiv: 2404.14367 [cs.LG]
Tang et al. (2024) Yunhao Tang, Daniel Guo, Zeyu Zheng, Daniele Calandriello, Yuan Cao, Eugene Tarassov, Rémi Munos, BernardoÁvila Pires, Michal Valko and Yong Cheng “Understanding the performance gap between online and offline alignment algorithms” In arXiv preprint arXiv:2405.08448 , 2024
Vaswani et al. (2017) Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan. Gomez, Lukasz Kaiser and Illia Polosukhin “Attention Is All You Need” In NeurIPS , 2017 arXiv: 1706.03762
Wang et al. (2018) Tongzhou Wang, Jun-Yan Zhu, Antonio Torralba and Alexei Efros “Dataset distillation”, 2018 arXiv: 1811.10959
Wei et al. (2022) Jason Wei, Maarten Bosma, Vincent Zhao, Kelvin Guu, Adams Yu, Brian Lester, Nan Du, Andrew. Dai and Quoc Le “Finetuned Language Models are Zero-Shot Learners” In ICLR , 2022
Wu et al. (2024) Yue Wu, Zhiqing Sun, Huizhuo Yuan, Kaixuan Ji, Yiming Yang and Quanquan Gu “Self-play preference optimization for language model alignment”, 2024 arXiv: 2405.00675
Xia et al. (2024) Mengzhou Xia, Sadhika Malladi, Suchin Gururangan, Sanjeev Arora and Danqi Chen “Less: Selecting influential data for targeted instruction tuning”, 2024 arXiv: 2402.04333
Xiong et al. (2024) Wei Xiong, Hanze Dong, Chenlu Ye, Ziqi Wang, Han Zhong, Heng Ji, Nan Jiang and Tong Zhang “Iterative Preference Learning from Human Feedback: Bridging Theory and Practice for RLHF under KL-constraint” In ICML , 2024
Yang et al. (2024) Zhaorui Yang, Qian Liu, Tianyu Pang, Han Wang, Haozhe Feng, Minfeng Zhu and Wei Chen “Self-Distillation Bridges Distribution Gap in Language Model Fine-Tuning”, 2024 arXiv: 2402.13669
Yuan et al. (2024) Weizhe Yuan, Richard Pang, Kyunghyun Cho, Sainbayar Sukhbaatar, Jing Xu and Jason Weston “Self-rewarding language models”, 2024 arXiv: 2401.10020
Zhang et al. (2024) Ruiqi Zhang, Licong Lin, Yu Bai and Song Mei “Negative preference optimization: From catastrophic collapse to effective unlearning” In arXiv preprint arXiv:2404.05868 , 2024
Zhang et al. (2023) Yue Zhang, Yafu Li, Leyang Cui, Deng Cai, Lemao Liu, Tingchen Fu, Xinting Huang, Enbo Zhao, Yu Zhang and Yulong Chen “Siren’s song in the AI ocean: a survey on hallucination in large language models” In arXiv preprint arXiv:2309.01219 , 2023
Zhao et al. (2023) Yao Zhao, Rishabh Joshi, Tianqi Liu, Misha Khalman, Mohammad Saleh and Peter Liu “Slic-hf: Sequence likelihood calibration with human feedback”, 2023 arXiv: 2305.10425
References
参考文献
LeCun et al. (1998a) Yann LeCun, Léon Bottou, Yoshua Bengio and Patrick Haffner “Gradient-based learning applied to document recognition” In Proceedings of the IEEE 86.11 Ieee, 1998, pp. 2278–2324
Settles (2009a) Burr Settles “Active learning literature survey” University of Wisconsin-Madison Department of Computer Sciences, 2009
Hinton et al. (2015a) Geoffrey Hinton, Oriol Vinyals and Jeff Dean “Distilling the knowledge in a neural network”, 2015 arXiv: 1503.02531
Christiano et al. (2017a) Paul Christiano, Jan Leike, Tom Brown, Miljan Martic, Shane Legg and Dario Amodei “Deep reinforcement learning from human preferences” In NeurIPS , 2017
Schulman et al. (2017a) John Schulman, Filip Wolski, Prafulla Dhariwal, Alec Radford and Oleg Klimov “Proximal policy optimization algorithms” In arXiv preprint arXiv:1707.06347 , 2017
Vaswani et al. (2017a) Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan. Gomez, Lukasz Kaiser and Illia Polosukhin “Attention Is All You Need” In NeurIPS , 2017 arXiv: 1706.03762
Jacot et al. (2018a) Arthur Jacot, Franck Gabriel and Clément Hongler “Neural tangent kernel: Convergence and generalization in neural networks” In NeurIPS , 2018
Wang et al. (2018a) Tongzhou Wang, Jun-Yan Zhu, Antonio Torralba and Alexei Efros “Dataset distillation”, 2018 arXiv: 1811.10959
Arora et al. (2019a) Sanjeev Arora, Simon. Du, Wei Hu, Zhiyuan Li, Ruslan Salakhutdinov and Ruosong Wang “On Exact Computation with an Infinitely Wide Neural Net” In NeurIPS , 2019 arXiv: 1904.11955
Caccia et al. (2020a) Massimo Caccia, Lucas Caccia, William Fedus, Hugo Larochelle, Joelle Pineau and Laurent Charlin “Language GANs Falling Short” In International Conference on Learning Representations , 2020
Choshen et al. (2020a) Leshem Choshen, Lior Fox, Zohar Aizenbud and Omri Abend “On the Weaknesses of Reinforcement Learning for Neural Machine Translation” In International Conference on Learning Representations , 2020
Feldman (2020a) Dan Feldman “Introduction to core-sets: an updated survey”, 2020 arXiv: 2011.09384
Holtzman et al. (2020a) Ari Holtzman, Jan Buys, Li Du, Maxwell Forbes and Yejin Choi “The Curious Case of Neural Text Degeneration” In ICLR , 2020
Liu et al. (2020a) Sheng Liu, Jonathan Niles-Weed, Narges Razavian and Carlos Fernandez-Granda “Early-learning regularization prevents memorization of noisy labels” In NeurIPS , 2020
Pruthi et al. (2020a) Garima Pruthi, Frederick Liu, Satyen Kale and Mukund Sundararajan “Estimating training data influence by tracing gradient descent” In NeurIPS , 2020
Ren et al. (2020a) Yi Ren, Shangmin Guo, Matthieu Labeau, Shay. Cohen and Simon Kirby “Compositional languages emerge in a neural iterated learning model” In ICLR , 2020
Bai et al. (2022a) Yuntao Bai, Andy Jones, Kamal Ndousse, Amanda Askell, Anna Chen, Nova DasSarma, Dawn Drain, Stanislav Fort, Deep Ganguli and Tom Henighan “Training a helpful and harmless assistant with reinforcement learning from human feedback”, 2022 arXiv: 2204.05862
Kumar et al. (2022a) Ananya Kumar, Aditi Raghunathan, Robbie Jones, Tengyu Ma and Percy Liang “Fine-Tuning can Distort Pretrained Features and Underperform Out-of-Distribution” In ICLR , 2022
Mohamadi et al. (2022a) Mohamad Mohamadi, Wonho Bae and Danica. Sutherland “Making Look-Ahead Active Learning Strategies Feasible with Neural Tangent Kernels” In NeurIPS , 2022 arXiv: 2206.12569
Ouyang et al. (2022a) Long Ouyang, Jeffrey Wu, Xu Jiang, Diogo Almeida, Carroll Wainwright, Pamela Mishkin, Chong Zhang, Sandhini Agarwal, Katarina Slama and Alex Ray “Training language models to follow instructions with human feedback” In NeurIPS , 2022, pp. 27730–27744
Ren et al. (2022a) Yi Ren, Shangmin Guo and Danica. Sutherland “Better Supervisory Signals by Observing Learning Paths” In ICLR , 2022
Wei et al. (2022a) Jason Wei, Maarten Bosma, Vincent Zhao, Kelvin Guu, Adams Yu, Brian Lester, Nan Du, Andrew. Dai and Quoc Le “Finetuned Language Models are Zero-Shot Learners” In ICLR , 2022
Bai et al. (2023a) Jinze Bai, Shuai Bai and et.al “Qwen Technical Report”, 2023 arXiv: 2309.16609
Biderman et al. (2023a) Stella Biderman, Hailey Schoelkopf, Quentin Anthony, Herbie Bradley, Kyle O’Brien, Eric Hallahan, Mohammad Khan, Shivanshu Purohit, USVSN Prashanth and Edward Raff “Pythia: A suite for analyzing large language models across training and scaling” In ICML , 2023, pp. 2397–2430 PMLR
Cui et al. (2023a) Ganqu Cui, Lifan Yuan, Ning Ding, Guanming Yao, Wei Zhu, Yuan Ni, Guotong Xie, Zhiyuan Liu and Maosong Sun “UltraFeedback: Boosting Language Models with High-quality Feedback”, 2023 arXiv: 2310.01377 [cs.CL]
Huang et al. (2023a) Lei Huang, Weijiang Yu, Weitao Ma, Weihong Zhong, Zhangyin Feng, Haotian Wang, Qianglong Chen, Weihua Peng, Xiaocheng Feng and Bing Qin “A survey on hallucination in large language models: Principles, taxonomy, challenges, and open questions”, 2023 arXiv: 2311.05232
Rafailov et al. (2023a) Rafael Rafailov, Archit Sharma, Eric Mitchell, Christopher Manning, Stefano Ermon and Chelsea Finn “Direct preference optimization: Your language model is secretly a reward model” In NeurIPS , 2023
Ren et al. (2023b) Yi Ren, Shangmin Guo, Wonho Bae and Danica. Sutherland “How to prepare your task head for finetuning” In ICLR , 2023
Ren et al. (2023c) Yi Ren, Samuel Lavoie, Michael Galkin, Danica Sutherland and Aaron Courville “Improving compositional generalization using iterated learning and simplicial embeddings” In NeurIPS , 2023
Zhang et al. (2023a) Yue Zhang, Yafu Li, Leyang Cui, Deng Cai, Lemao Liu, Tingchen Fu, Xinting Huang, Enbo Zhao, Yu Zhang and Yulong Chen “Siren’s song in the AI ocean: a survey on hallucination in large language models” In arXiv preprint arXiv:2309.01219 , 2023
Zhao et al. (2023a) Yao Zhao, Rishabh Joshi, Tianqi Liu, Misha Khalman, Mohammad Saleh and Peter Liu “Slic-hf: Sequence likelihood calibration with human feedback”, 2023 arXiv: 2305.10425
Azar et al. (2024a) Mohammad Azar, Zhaohan Guo, Bilal Piot, Remi Munos, Mark Rowland, Michal Valko and Daniele Calandriello “A general theoretical paradigm to understand learning from human preferences” In International Conference on Artificial Intelligence and Statistics , 2024, pp. 4447–4455 PMLR
Chen et al. (2024a) Zixiang Chen, Yihe Deng, Huizhuo Yuan, Kaixuan Ji and Quanquan Gu “Self-play fine-tuning converts weak language models to strong language models”, 2024 arXiv: 2401.01335
Gekhman et al. (2024a) Zorik Gekhman, Gal Yona, Roee Aharoni, Matan Eyal, Amir Feder, Roi Reichart and Jonathan Herzig “Does Fine-Tuning LLMs on New Knowledge Encourage Hallucinations?”, 2024 arXiv: 2405.05904
Guo et al. (2024b) Shangmin Guo, Yi Ren, Stefano Albrecht and Kenny Smith “lpNTK: Better Generalisation with Less Data via Sample Interaction During Learning” In ICLR , 2024
Guo et al. (2024c) Shangmin Guo, Biao Zhang, Tianlin Liu, Tianqi Liu, Misha Khalman, Felipe Llinares, Alexandre Rame, Thomas Mesnard, Yao Zhao and Bilal Piot “Direct language model alignment from online AI feedback”, 2024 arXiv: 2402.04792
Ji et al. (2024a) Haozhe Ji, Cheng Lu, Yilin Niu, Pei Ke, Hongning Wang, Jun Zhu, Jie Tang and Minlie Huang “Towards Efficient and Exact Optimization of Language Model Alignment”, 2024 arXiv: 2402.00856
Pal et al. (2024a) Arka Pal, Deep Karkhanis, Samuel Dooley, Manley Roberts, Siddartha Naidu and Colin White “Smaug: Fixing Failure Modes of Preference Optimisation with DPO-Positive”, 2024 arXiv: 2402.13228
Park et al. (2024a) Core Park, Maya Okawa, Andrew Lee, Ekdeep Lubana and Hidenori Tanaka “Emergence of Hidden Capabilities: Exploring Learning Dynamics in Concept Space” In The Thirty-eighth Annual Conference on Neural Information Processing Systems , 2024
Rafailov et al. (2024a) Rafael Rafailov, Joey Hejna, Ryan Park and Chelsea Finn “From r r to Q ∗ Q^{*} : Your Language Model is Secretly a Q-Function”, 2024 arXiv: 2404.12358
Ren et al. (2024a) Yi Ren, Shangmin Guo, Linlu Qiu, Bailin Wang and Danica Sutherland “Bias Amplification in Language Model Evolution: An Iterated Learning Perspective” In NeurIPS , 2024
Ren & Sutherland (2024a) Yi Ren and Danica. Sutherland “Understanding Simplicity Bias towards Compositional Mappings via Learning Dynamics” In NeurIPS 2024 Workshop on Compositional Learning: Perspectives, Methods, and Paths Forward , 2024
Schaeffer et al. (2024a) Rylan Schaeffer, Brando Miranda and Sanmi Koyejo “Are emergent abilities of large language models a mirage?” In Advances in Neural Information Processing Systems 36 , 2024
Tajwar et al. (2024a) Fahim Tajwar, Anikait Singh, Archit Sharma, Rafael Rafailov, Jeff Schneider, Tengyang Xie, Stefano Ermon, Chelsea Finn and Aviral Kumar “Preference Fine-Tuning of LLMs Should Leverage Suboptimal, On-Policy Data”, 2024 arXiv: 2404.14367 [cs.LG]
Tang et al. (2024a) Yunhao Tang, Daniel Guo, Zeyu Zheng, Daniele Calandriello, Yuan Cao, Eugene Tarassov, Rémi Munos, BernardoÁvila Pires, Michal Valko and Yong Cheng “Understanding the performance gap between online and offline alignment algorithms” In arXiv preprint arXiv:2405.08448 , 2024
Wu et al. (2024a) Yue Wu, Zhiqing Sun, Huizhuo Yuan, Kaixuan Ji, Yiming Yang and Quanquan Gu “Self-play preference optimization for language model alignment”, 2024 arXiv: 2405.00675
Xia et al. (2024a) Mengzhou Xia, Sadhika Malladi, Suchin Gururangan, Sanjeev Arora and Danqi Chen “Less: Selecting influential data for targeted instruction tuning”, 2024 arXiv: 2402.04333
Xiong et al. (2024a) Wei Xiong, Hanze Dong, Chenlu Ye, Ziqi Wang, Han Zhong, Heng Ji, Nan Jiang and Tong Zhang “Iterative Preference Learning from Human Feedback: Bridging Theory and Practice for RLHF under KL-constraint” In ICML , 2024
Yang et al. (2024a) Zhaorui Yang, Qian Liu, Tianyu Pang, Han Wang, Haozhe Feng, Minfeng Zhu and Wei Chen “Self-Distillation Bridges Distribution Gap in Language Model Fine-Tuning”, 2024 arXiv: 2402.13669
Yuan et al. (2024a) Weizhe Yuan, Richard Pang, Kyunghyun Cho, Sainbayar Sukhbaatar, Jing Xu and Jason Weston “Self-rewarding language models”, 2024 arXiv: 2401.10020
Zhang et al. (2024a) Ruiqi Zhang, Licong Lin, Yu Bai and Song Mei “Negative preference optimization: From catastrophic collapse to effective unlearning” In arXiv preprint arXiv:2404.05868 , 2024
Guo et al. (2025a) Daya Guo, Dejian Yang, Haowei Zhang, Junxiao Song, Ruoyu Zhang, Runxin Xu, Qihao Zhu, Shirong Ma, Peiyi Wang and Xiao Bi “Deepseek-r1: Incentivizing reasoning capability in llms via reinforcement learning” In arXiv preprint arXiv:2501.12948 , 2025
Razin et al. (2025a) Noam Razin, Sadhika Malladi, Adithya Bhaskar, Danqi Chen, Sanjeev Arora and Boris Hanin “Unintentional Unalignment: Likelihood Displacement in Direct Preference Optimization” In The Thirteenth International Conference on Learning Representations , 2025
Appendix A More Related Works
附录 A 更多相关工作
A.1 More about learning dynamics
A.1 关于学习动力学的更多讨论
Instead of emphasizing the model’s convergence status and guarantees, learning dynamics focus more on its relative behavior during training. Since many LLMs exhibit “emergent ability” during training in terms of the amount of training data or inference time (Schaeffer et al. 2024a), like the “aha moment” mentioned in Guo et al. 2025a, we hence believe the analysis of learning dynamics can provide a novel perspective on understanding the LLM system.
学习动力学不强调模型的收敛状态与保证,而更关注训练过程中的相对行为。由于许多 LLM 在训练数据量或推理时间维度上会表现出「涌现能力」(Schaeffer et al. 2024a),例如 Guo et al. 2025a 提到的「aha moment」,我们相信学习动力学分析可为理解 LLM 系统提供新视角。
Beyond their application to LLMs, learning dynamics are widely utilized in analyzing various machine learning problems. For example, if we consider {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} from the training set, and {\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}} from the test set, this form of learning dynamics provides a new perspective on generalization: the model generalizes better if the loss of f_{\theta}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}}) keeps decreasing when it learns from {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}}. By studying the influence of different {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} at different stages during supervised learning, Ren et al. 2022a explain a “zigzag” pattern of the learning path, which sheds light on why the model can spontaneously pursue better supervisory signals and correct noisy labels in the early stage of training (see also Liu et al. 2020a). Kumar et al. 2022a; Ren et al. 2023b apply learning dynamics to explain why directly finetuning a well-trained backbone with a randomly initialized task head might harm the out-of-distribution generalization ability. Ren et al. 2020a; Ren et al. 2023c; Ren & Sutherland 2024a also explains where the simplicity bias favoring compositional representations comes from during knowledge distillation (Hinton et al. 2015a), providing a new perspective of understanding why successive knowledge transferring can improve the model’s systematic generalization ability.
除应用于 LLM 外,学习动力学也广泛用于分析各类机器学习问题。例如,若 {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} 来自训练集、{\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}} 来自测试集,这种形式的学习动力学为泛化提供新视角:当模型从 {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} 学习时,若 f_{\theta}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}}) 的损失持续下降,则泛化更好。通过研究监督学习不同阶段不同 {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} 的影响,Ren et al. 2022a 解释了学习路径的「之」字形图案,从而说明为何模型能自发追求更好的监督信号并在训练早期纠正噪声标签(亦见 Liu et al. 2020a)。Kumar et al. 2022a、Ren et al. 2023b 用学习动力学解释:为何用随机初始化的任务头直接微调训好的骨干可能损害分布外泛化。Ren et al. 2020a、Ren et al. 2023c、Ren & Sutherland 2024a 亦解释了知识蒸馏(Hinton et al. 2015a)中偏好组合表示的简单性偏置从何而来,为理解连续知识迁移为何能提升系统化泛化能力提供新视角。
Besides explaining the model’s behavior, learning dynamics is also helpful for evaluating the quality or the effectiveness of different training samples. For example, Pruthi et al. 2020a propose a quantitative metric called TracIn to compute the influence of a training example on the predictions made by the model. This metric is then applied by Xia et al. 2024a to search for the most influential examples in LLM instruction finetuning. By expanding Equation 1 in the neural tangent kernel (NTK) regime, Guo et al. 2024b propose a metric called lpNTK to measure the relative difficulty among different training samples. These metrics and analyses inspired by learning dynamics are expected to be helpful in many related fields, like coreset selection (Feldman 2020a), active learning (Settles 2009a) (see, e.g., Mohamadi et al. 2022a), and dataset distillation (Wang et al. 2018a).
除解释模型行为外,学习动力学也有助于评估不同训练样本的质量或有效性。例如,Pruthi et al. 2020a 提出定量指标 TracIn,计算训练样本对模型预测的影响;Xia et al. 2024a 再用该指标在 LLM 指令微调中搜索最具影响力的样本。通过在神经正切核(NTK)机制下展开式 1,Guo et al. 2024b 提出 lpNTK 指标,度量不同训练样本的相对难度。这些由学习动力学启发的指标与分析有望惠及许多相关领域,如核心集选择(Feldman 2020a)、主动学习(Settles 2009a;亦见 Mohamadi et al. 2022a)以及数据集蒸馏(Wang et al. 2018a)。
A.2 More about LLM’s finetuning
A.2 关于 LLM 微调的更多讨论
In this paper, we broadly define finetuning as any in-weight learning on top of a pretrained base model, including supervised finetuning (SFT), direct policy optimization (DPO, Rafailov et al. 2023a) and its variants, etc. Since the analysis throughout this paper relies on the “teacher forcing” mechanism and the relatively stable eNTK assumption, our framework cannot be directly applied to algorithms with token-wise supervision like reinforcement learning with human feedback (RLHF, Ouyang et al. 2022a) and proximal policy optimization (PPO, Schulman et al. 2017a)[^1]. We leave the study of the token-wise learning dynamics, which aligns better with the “squeezing effect” in real settings, to future work.
本文广义地将微调定义为在预训练基座之上的任何权重内学习,包括监督微调(SFT)、直接偏好优化(DPO,Rafailov et al. 2023a)及其变体等。由于全文分析依赖「teacher forcing」机制与相对稳定的 eNTK 假设,我们的框架不能直接应用于带 token 级监督的算法,如基于人类反馈的强化学习(RLHF,Ouyang et al. 2022a)与近端策略优化(PPO,Schulman et al. 2017a)[^1]。与真实设定中「挤压效应」更吻合的 token 级学习动力学,留待未来工作。
We also identify several related works that report similar observations on the phenomena discussed in this paper. For example, Zhang et al. 2023a; Gekhman et al. 2024a mentioned that learning new facts during SFT tends to make the model hallucinate more, which aligns with our finding that the model tends to use when answering question . Holtzman et al. 2020a related the peakiness of the model’s distribution to LLM’s “repeater phenomena”, which also indirectly supports our claims well: more DPO leads to a more serious squeezing effect, hence the model’s prediction becomes peakier on most tokens, which makes the aforementioned phenomena more common.
我们亦指出若干相关工作报告了与本文现象类似的观察。例如,Zhang et al. 2023a、Gekhman et al. 2024a 提到:SFT 中学习新事实往往使模型幻觉更严重,这与我们发现模型回答问题 时倾向于使用 一致。Holtzman et al. 2020a 将模型分布的尖峰性与 LLM「复读机」现象联系起来,也间接支持我们的论断:更多 DPO 导致更严重的挤压效应,于是模型在多数 token 上的预测更尖峰,上述现象更常见。
Furthermore, the “confidence decaying on ” attracts more attention in the community, because it is quite counter-intuitive and the vanilla off-policy DPO algorithm works reasonably well in most cases. Many related works study this phenomenon by analyzing the major discrepancy between off-policy DPO and PPO, i.e., where the samples used to train the model comes from, e.g., Rafailov et al. 2024a; Tang et al. 2024a; Guo et al. 2024c. They showed that when the responses are off-policy sampled, the learning process may fail to benefit from the contrastive information in the data. In other words, we should be more careful when working on the “valley” region of the model’s distribution. Other works try to analyze this problem by inspecting the token-level influence between responses. For example, Pal et al. 2024a assumes and are identical expect one token. Under this assumption, the model’s confidence of after the identical token is guaranteed to decrease. They propose a solution by significantly enhancing the learning rate (roughly x50 larger when their ) of the positive part when detecting located in a low-confidence region. Razin et al. 2025a takes the similarity between the hidden embeddings and the geometry of the readout layer of different responses into account. Most of the conclusions of their paper align with ours well. The main discrepancy lies in the squeezing effect part, which we will discuss in our future work (they do not contradict each other, but need a more detailed analysis to understand the whole story).
此外,「 上置信度衰减」更受社区关注,因为它相当反直觉,而朴素 off-policy DPO 在多数情形下仍表现尚可。许多相关工作通过分析 off-policy DPO 与 PPO 的主要差异——即训练所用样本来自何处——来研究该现象,例如 Rafailov et al. 2024a、Tang et al. 2024a、Guo et al. 2024c。他们表明,当回复为 off-policy 采样时,学习过程可能无法从数据中的对比信息获益;换言之,处理模型分布的「谷底」区域时需更谨慎。另一些工作试图通过检视回复间的 token 级影响来分析该问题。例如,Pal et al. 2024a 假设 与 除一个 token 外完全相同;在该假设下,相同 token 之后模型对 的置信度保证下降。他们提出:当检测到 位于低置信区域时,显著增大正项学习率(其 时大约大 50 倍)。Razin et al. 2025a 将不同回复隐嵌入相似度与读出层几何纳入考虑,多数结论与我们一致。主要差别在挤压效应部分,我们将在未来工作中讨论(二者并不矛盾,但需更细致分析才能理解全貌)。
A.3 Benign and harmful negative gradient
A.3 良性与有害的负梯度
The “squeezing effect” can negatively impact our analysis when it is strongly imposed in a valley region of the model. However, a well-regulated negative gradient is both beneficial and commonly observed in many deep-learning systems. For example, it is common in many “machine unlearning” algorithms, e.g., in Zhang et al. 2024a. Moreover, even in the field of LLM finetuning, we can find many mechanisms in different popular algorithms that can mitigate this effect. For example, the typical learning rate of DPO is usually smaller than that used in SFT, which unintentionally mitigates the harmful squeezing effect. The on-policy counterpart of the DPO-like algorithms is shown to perform better than their off-policy counterparts, which also supports our claims. Furthermore, we find the PPO loss automatically avoids imposing a big negative gradient (when its is negative) on the valley region (when its is small).
当「挤压效应」在模型谷底区域被强烈施加时,可能对我们的分析产生负面影响。但受良好调控的负梯度在许多深度学习系统中既有益又常见。例如,它常见于多种「机器遗忘」算法(如 Zhang et al. 2024a)。即便在 LLM 微调领域,也可在多种流行算法中找到缓解该效应的机制。例如,DPO 典型学习率通常小于 SFT,这无意中缓解了有害挤压效应。类 DPO 算法的 on-policy 对照被证明优于 off-policy,亦支持我们的论断。此外,我们发现 PPO 损失会自动避免在谷底区域(当 较小时)对大负梯度(当其 为负时)的施加。
On the other hand, the effect that negative gradients make the model’s distribution peakier is independently reported in many related works. For example, Equation 1 in Caccia et al. 2020a shows that we are minimizing a negative thing in a standard GAN loss, which might explain why peakiness occurs. Furthermore, in Table 1 and Table 2 of Choshen et al. 2020a, we see the peakiness (measured by ) of the “PG-average” method is stronger than the standard PG method. Note that the “PG-average” method will map a reward ranging from 0 to 1 to a centered one ranging from -0.5 to 0.5. Since the negative reward can introduce a negative gradient, the peakiness increases.
另一方面,负梯度使模型分布更尖峰的效应在许多相关工作中被独立报告。例如,Caccia et al. 2020a 式 1 表明标准 GAN 损失中我们在最小化一个负项,这或可解释尖峰为何出现。此外,在 Choshen et al. 2020a 的表 1、表 2 中,「PG-average」方法的尖峰性(由 、 度量)强于标准 PG。注意「PG-average」会把 0 到 1 的奖励映射为 -0.5 到 0.5 的居中奖励;负奖励可引入负梯度,尖峰性随之增加。
Appendix B Proof of Propositions and Residual Term for Different Losses
附录 B 命题证明与不同损失的残差项
B.1 Proof of Proposition 1
B.1 命题 1 的证明
See 1
见命题 1。
Proof.
Suppose we want to observe the model’s prediction on an “observing example” {\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}}. Starting from Equation 2, we first approximate \log\pi^{t+1}(\bm{\mathsf{y}}\mid{\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}}) using first-order Taylor expansion (we use to represent interchangeably for notation conciseness):
证明。
假设我们要观察模型在「观察样本」{\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}} 上的预测。从式 2 出发,先用一阶 Taylor 展开近似 \log\pi^{t+1}(\bm{\mathsf{y}}\mid{\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})(为简洁起见,用 互换表示 ):
\log\pi^{t+1}(\bm{\mathsf{y}}\mid{\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})=\log\pi^{t}(\bm{\mathsf{y}}\mid{\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})+\ \langle\nabla\log\pi^{t}(\bm{\mathsf{y}}\mid{\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}}),\ \theta^{t+1}-\theta^{t}\rangle+O(\|\theta^{t+1}-\theta^{t}\|^{2}).
Then, assuming the model updates its parameters using SGD calculated by an “updating example” ({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}},{\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}}), we can rearrange the terms in the above equation to get the following expression:
接着,假设模型用「更新样本」({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}},{\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}}) 上算出的 SGD 更新参数,可重排上式各项得到:
\Delta\log\pi^{t}(\bm{\mathsf{y}}\mid{\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})=\underbrace{\log\pi^{t+1}(\bm{\mathsf{y}}\mid{\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})}_{V\times 1}-\underbrace{\log\pi^{t}(\bm{\mathsf{y}}\mid{\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})}_{V\times 1}=\underbrace{\nabla_{\theta}\log\pi^{t}(\bm{\mathsf{y}}\mid{\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})|_{\theta^{t}}}_{V\times d}\underbrace{\big(\theta^{t+1}-\theta^{t}\big)}_{d\times 1}{}+O\big(\lVert\theta^{t+1}-\theta^{t}\rVert^{2}\big),
where is the number of parameters of the model. To evaluate the leading term, we plug in the definition of SGD and repeatedly use the chain rule:
其中 为模型参数个数。为估计主导项,代入 SGD 定义并反复使用链式法则:
\displaystyle\underbrace{\nabla_{\theta}\log\pi^{t}(\bm{\mathsf{y}}\mid{\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})|_{\theta^{t}}}_{V\times d}\underbrace{\big(\theta^{t+1}-\theta^{t}\big)}_{d\times 1} \\ \displaystyle=\big(\underbrace{\nabla_{\bm{\mathsf{z}}}\log\pi^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})|_{\bm{\mathsf{z}}^{t}}}_{V\times V}\underbrace{\nabla_{\theta}\bm{\mathsf{z}}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})|_{\theta^{t}}}_{V\times d}\big)\big(-\eta\underbrace{\nabla_{\theta}\mathcal{L}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}})|_{\theta^{t}}}_{1\times d}\big)^{\mathsf{T}} \\ \displaystyle=\underbrace{\nabla_{\bm{\mathsf{z}}}\log\pi^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})|_{\bm{\mathsf{z}}^{t}}}_{V\times V}\underbrace{\nabla_{\theta}\bm{\mathsf{z}}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})|_{\theta^{t}}}_{V\times d}\big(\underbrace{-\eta\nabla_{\bm{\mathsf{z}}}\mathcal{L}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}})|_{\bm{\mathsf{z}}^{t}}}_{1\times V}\underbrace{\nabla_{\theta}\bm{\mathsf{z}}^{t}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}})|_{\theta^{t}}}_{V\times d}\big)^{\mathsf{T}} \\ \displaystyle=-\eta\underbrace{\nabla_{\bm{\mathsf{z}}}\log\pi^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})|_{\bm{\mathsf{z}}^{t}}}_{V\times V}\big[\underbrace{\nabla_{\theta}\bm{\mathsf{z}}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})|_{\theta^{t}}}_{V\times d}\underbrace{\left(\nabla_{\theta}\bm{\mathsf{z}}^{t}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}})|_{\theta^{t}}\right)^{\mathsf{T}}}_{d\times V}\big]\underbrace{\big(\nabla_{\bm{\mathsf{z}}}\mathcal{L}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}})|_{\bm{\mathsf{z}}^{t}}\big)^{\mathsf{T}}}_{V\times 1} \\ \displaystyle=-\eta\mathcal{A}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})\mathcal{K}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}},{\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}})\mathcal{G}^{t}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}},{\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}}) \tag{8}
For the higher-order term, using as above that
对高阶项,同上利用
\theta^{t+1}-\theta^{t}=-\eta\nabla_{\theta}\bm{\mathsf{z}}^{t}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}})|_{\theta^{t}}^{\mathsf{T}}\mathcal{G}^{t}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}},\hat{\bm{\mathsf{y}}})
and noting that, since the residual term is usually bounded (and the practical algorithms will also use gradient clip to avoid too large gradient), we have that
并注意到:由于残差项 通常有界(实际算法也会用梯度裁剪避免过大梯度),我们有
O\big(\lVert\theta^{t+1}-\theta^{t}\rVert^{2}\big)=O\big(\eta^{2}\,\lVert\left(\nabla_{\theta}\bm{\mathsf{z}}^{t}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}})|_{\theta^{t}}\right)^{\mathsf{T}}\rVert_{\mathrm{op}}^{2}\,\lVert\mathcal{G}^{t}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}},\hat{\bm{\mathsf{y}}})\rVert_{\mathrm{op}}^{2}\big)=O\big(\eta^{2}\lVert\nabla_{\theta}\bm{\mathsf{z}}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}})\rVert_{\mathrm{op}}^{2}\big).\qed
In the decomposition, using to represent the model’s prediction on different dimensions, we can write our as:
在分解中,用 表示模型在不同维上的预测,可将 写为:
$$\mathcal{A}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}{o}})=I-\bm{\mathsf{1}}(\pi^{t})^{\top}=\left[\begin{matrix}1-\pi{1}&-\pi_{1}&\cdots&-\pi_{1}\
-\pi_{2}&1-\pi_{2}&\cdots&-\pi_{2}\
\dots&\dots&\ddots&\dots\
-\pi_{V}&-\pi_{V}&\cdots&1-\pi_{V}\end{matrix}\right], \tag{9}$$
The second term in this decomposition, \mathcal{K}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}},{\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}}), is the product of gradients at {\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}} and {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}}. Intuitively, if their gradients have similar directions, the Frobenius norm of this matrix is large, and vice versa. This matrix is known as the empirical neural tangent kernel, and it can change through the course of training as the network’s notion of “similarity” evolves. For appropriately initialized very wide networks trained with very small learning rates, remains almost constant during the course of training, the kernel it converges to is known as the neural tangent kernel (Jacot et al. 2018a; Arora et al. 2019a). Note that the assumption that \mathcal{K}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}},{\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}}) is unchanged (usually used in theoretical analysis) might be too strong in the LLM’s finetuning. Hence as stated in the main context, our qualitative analysis only assumes that “during the training, the relative influence of learning on all other different is relatively stable”. We will validate this assumption using experiments in Appendix C.
分解中的第二项 \mathcal{K}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}},{\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}}) 是 {\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}} 与 {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} 处梯度之积。直观上,若二者梯度方向相近,该矩阵的 Frobenius 范数就大,反之亦然。该矩阵即经验神经正切核,可随训练推进、网络「相似度」观念演化而变化。对适当初始化、极宽且学习率极小的网络, 在训练过程中几乎不变,其收敛核即神经正切核(Jacot et al. 2018a;Arora et al. 2019a)。注意,\mathcal{K}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}},{\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}}) 不变的假设(理论分析中常用)在 LLM 微调中可能过强。因此如正文所述,我们的定性分析只假设「训练中,学习 对其它各个 的相对影响力保持相对稳定」。附录 C 用实验验证该假设。
B.2 Residual Term for Different LLM Finetuning Algorithms
B.2 不同 LLM 微调算法的残差项
As stated in Section 3, one of the conundrums of decomposing the learning dynamics of LLM is its auto-regression nature of the output sequence. Different from the multi-label classification problem, where for different is independently generated as long as the shared network is fixed, the for the LLM’s output depends on , which is usually sampled from the model’s prediction iteratively. However, in most of the finetuning cases where the supervisory signal {\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}} is given, the model will apply the so-called “teacher forcing” mechanism when calculating the predicting probabilities. In other words, when generating the output of each , the is given rather than sampled on-policy. This mechanism makes it possible for us to define and hence merge the auto-regressive nature of the sequence prediction into the shared \mathcal{K}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{\chi}}_{o}},{\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}}). After this step, the decomposition of LLM’s finetuning learning dynamics then becomes similar to a multi-label classification task.
如第 3 节所述,分解 LLM 学习动力学的难点之一是输出序列的自回归性质。与多标签分类不同——其中只要共享网络固定,不同 的 独立生成——LLM 输出的 依赖于 ,通常由模型预测迭代采样。但在多数给定监督信号 {\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}} 的微调情形中,计算预测概率时模型会采用「teacher forcing」:生成每个 时 是给定的而非 on-policy 采样。该机制使我们得以定义 ,从而把序列预测的自回归性质并入共享的 \mathcal{K}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{\chi}}_{o}},{\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}})。此后,LLM 微调学习动力学的分解便与多标签分类任务类似。
B.2.1 Instruction finetuning using auto-regression loss (SFT)
Here we derive the residual term, i.e., for different algorithms in LLM’s finetuning. We first rewrite Equation 5 here:
B.2.1 使用自回归损失的指令微调(SFT)
这里推导 LLM 微调中不同算法的残差项,即 。先重写式 5:
[\underbrace{\Delta\log\pi^{t}(\bm{\mathsf{y}}\mid{\color[rgb]{1,0.5,0}\bm{\mathsf{\chi}}_{o}})}_{V\times M}]_{m}=-\sum_{l=1}^{L}\eta[\underbrace{\mathcal{A}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{\chi}}_{o}})}_{V\times V\times M}]_{m}[\underbrace{\mathcal{K}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{\chi}}_{o}},{\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}})}_{V\times V\times L}]_{l}[\underbrace{\mathcal{G}^{t}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}})}_{V\times L}]_{l}+O(\eta^{2}),
where , , and \mathcal{G}^{t}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}})=\nabla_{\bm{\mathsf{z}}}\mathcal{L}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}})|_{\bm{\mathsf{z}}^{t}} is a matrix. As the auto-regression nature of the SFT loss is already encoded in the causal mask used in , as demonstrated in Figure 10(a). the columns in \mathcal{G}^{t}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}}) are independent of each other, which can be separately calculated. Plus, the summation over can also be achieved by left-multiplying a length- all-one vector . Specifically, the SFT loss for each is:
其中 ,,且 \mathcal{G}^{t}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}})=\nabla_{\bm{\mathsf{z}}}\mathcal{L}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}})|_{\bm{\mathsf{z}}^{t}} 是 矩阵。如图 10(a) 所示,SFT 损失的自回归性质已编码在 所用因果掩码中,\mathcal{G}^{t}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}}) 各列彼此独立,可分别计算。此外,对 的求和也可通过对长度为 的全一向量 左乘实现。具体地,每个 的 SFT 损失为:
[\mathcal{L}_{\text{SFT}}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}})]_{l}=-\log\pi(y_{l}=y_{u}^{+}\mid{\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}})=-\bm{\mathsf{e}}_{y_{u}^{+}}^{\top}\log\pi(y_{l}\mid{\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}})=-\bm{\mathsf{e}}_{y_{u}^{+}}^{\top}\log\left(\texttt{Softmax}(\bm{\mathsf{z}}_{l})\right),
where is for the -th dimension of . The gradient of on can be then calculated as:
其中 对应 的第 维。 对 的梯度可算为:
\displaystyle[\mathcal{G}_{\text{SFT}}^{t}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}})]_{l} \\ \displaystyle=\underbrace{\nabla_{\bm{\mathsf{z}}_{l}}[\mathcal{L}_{\text{SFT}}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}})]_{l}}_{1\times V}=\left(\underbrace{\nabla_{\pi}[\mathcal{L}_{\text{SFT}}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}})]_{l}}_{V\times 1}\right)^{\top}\underbrace{\nabla_{\bm{\mathsf{z}}_{l}}\pi}_{V\times V} \\ \displaystyle=-\left(\bm{\mathsf{e}}_{y_{u}^{+}}\oslash\pi\right)^{\top}{\nabla_{\bm{\mathsf{z}}_{l}}\pi}=\pi(y_{l}\mid{\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}})-\bm{\mathsf{e}}_{y_{u}^{+}}, \tag{10}
where is element-wise division.
其中 为逐元素除法。
To calculate the equation above, we first recall the NLL loss of the -th token is , where . Then, . For each dimension of , we have if and if . By writing it in vector form, we have . For , we have:
为计算上式,先回忆第 个 token 的 NLL 损失为 ,其中 。于是 。对 的每一维:若 则 ,若 则 。写成向量形式有 。对 ,有:
$$\nabla_{\bm{\mathsf{z}}}\pi=\left[\begin{matrix}\pi_{1}(1-\pi_{1})&-\pi_{2}\pi_{1}&\cdots&-\pi_{V}\pi_{1}\
-\pi_{1}\pi_{2}&1-\pi_{2}\pi_{2}&\cdots&-\pi_{V}\pi_{2}\
\dots&\dots&\ddots&\dots\
-\pi_{1}\pi_{V}&-\pi_{2}\pi_{V}&\cdots&1-\pi_{V}\pi_{V}\end{matrix}\right].$$
Combining this matrix and the vector , where the only non-zero term is at the position. So, left multiplying by this vector is actually first selecting the -th row of , and then multiplying to it. In summary, we have:
将该矩阵与 向量 结合:后者唯一非零项是在 位置的 。因此左乘该向量实际是先选取 的第 行,再乘以 。总结有:
By stacking the terms with different , we can get
将不同 的项堆叠,可得
\mathcal{G}^{t}_{\text{SFT}}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}})=\nabla_{\bm{\mathsf{z}}}\mathcal{L}_{\text{SFT}}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}})|_{\bm{\mathsf{z}}^{t}}=\pi_{\theta^{t}}(\bm{\mathsf{y}}\mid{\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}})-\bm{\mathsf{y}}_{u}^{+} \tag{11}
B.2.2 Different preference finetuning algorithms
Direct Preference Optimization (DPO, Rafailov et al. 2023a) is usually considered the first RL-free alignment algorithm for preference finetuning. Different from the standard RLHF (reinforcement learning with human feedback (Christiano et al. 2017a)), the training of off-policy DPO is more similar to SFT, where the model keeps learning from a pre-generated preference dataset. Hence, we start from DPO to analyze the learning dynamics of different preference finetuning algorithms (the on-policy versions of these algorithms could also be explained using the proposed framework).
B.2.2 不同偏好微调算法
直接偏好优化(DPO,Rafailov et al. 2023a)通常被视为偏好微调中首个免 RL 对齐算法。与标准 RLHF(基于人类反馈的强化学习,Christiano et al. 2017a)不同,off-policy DPO 的训练更接近 SFT:模型持续从预先生成的偏好数据集学习。因此我们从 DPO 入手,分析不同偏好微调算法的学习动力学(这些算法的 on-policy 版本亦可由所提框架解释)。
Following Rafailov et al. 2023a, the training loss of DPO is:
按 Rafailov et al. 2023a,DPO 的训练损失为:
Before calculating the residual term , we need to re-calculate the learning dynamics decomposition, because the loss term now depends on both and , which involves two different terms. Specifically, we define and , where and respectively (\bm{\mathsf{\chi}}_{u}^{+}=[{\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}};\bm{\mathsf{y}}_{u}^{+}] and \bm{\mathsf{\chi}}_{u}^{-}=[{\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}};\bm{\mathsf{y}}_{u}^{-}]). Then, starting from , the decomposition for the DPO loss (similar to Equation 8 for SFT) could be written as:
在计算残差项 之前,需重新计算学习动力学分解,因为损失项现在同时依赖 与 ,涉及两个不同的 项。具体地,定义 、,其中 、(\bm{\mathsf{\chi}}_{u}^{+}=[{\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}};\bm{\mathsf{y}}_{u}^{+}],\bm{\mathsf{\chi}}_{u}^{-}=[{\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}};\bm{\mathsf{y}}_{u}^{-}])。从 出发,DPO 损失的分解(类似 SFT 的式 8)可写为:
\displaystyle\underbrace{\nabla_{\theta}\log\pi^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{\chi}}_{o}})|_{\theta^{t}}}_{V\times d}\underbrace{\Delta\theta^{t}}_{d\times 1} \\ \displaystyle=\big(\underbrace{\nabla_{\bm{\mathsf{z}}}\log\pi^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{\chi}}_{o}})|_{\bm{\mathsf{z}}^{t}}}_{V\times V}\underbrace{\nabla_{\theta}\bm{\mathsf{z}}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{\chi}}_{o}})|_{\theta^{t}}}_{V\times d}\big)\big(-\eta\underbrace{\nabla_{\theta}\mathcal{L}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}},\bm{\mathsf{y}}_{u}^{+},\bm{\mathsf{y}}_{u}^{-})|_{\theta^{t}}}_{1\times d}\big)^{\mathsf{T}} \\ \displaystyle=\underbrace{\nabla_{\bm{\mathsf{z}}}\log\pi^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{\chi}}_{o}})|_{\bm{\mathsf{z}}^{t}}}_{V\times V}\underbrace{\nabla_{\theta}\bm{\mathsf{z}}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{\chi}}_{o}})|_{\theta^{t}}}_{V\times d}\big(\underbrace{-\eta\nabla_{[\bm{\mathsf{z}}^{+};\bm{\mathsf{z}}^{-}]}\mathcal{L}|_{\bm{\mathsf{z}}^{t}}}_{1\times 2V}\underbrace{\left[\nabla_{\theta}\bm{\mathsf{z}}^{+}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}^{+}});\nabla_{\theta}\bm{\mathsf{z}}^{-}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}^{-}})\right]|_{\theta^{t}}}_{2V\times d}\big)^{\mathsf{T}} \\ \displaystyle=-\eta\underbrace{\nabla_{\bm{\mathsf{z}}}\log\pi^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})|_{\bm{\mathsf{z}}^{t}}}_{V\times V}\Big[\underbrace{\nabla_{\theta}\bm{\mathsf{z}}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{o}})|_{\theta^{t}}}_{V\times d}\underbrace{\left(\left[\nabla_{\theta}\bm{\mathsf{z}}^{+}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}^{+}});\nabla_{\theta}\bm{\mathsf{z}}^{-}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}^{-}})\right]|_{\theta^{t}}\right)^{\mathsf{T}}}_{d\times 2V}\Big]\underbrace{\big(\nabla_{[\bm{\mathsf{z}}^{+};\bm{\mathsf{z}}^{-}]}\mathcal{L}|_{\bm{\mathsf{z}}^{t}}\big)^{\mathsf{T}}}_{2V\times 1} \\ \displaystyle=-\eta\mathcal{A}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{\chi}}_{o}})\big[\mathcal{K}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{\chi}}_{o}},{\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}^{+}});\mathcal{K}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{\chi}}_{o}},{\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}^{-}})\big]\big(\nabla_{[\bm{\mathsf{z}}^{+};\bm{\mathsf{z}}^{-}]}\mathcal{L}|_{\bm{\mathsf{z}}^{t}}\big)^{\mathsf{T}} \\ \displaystyle\triangleq-\eta\mathcal{A}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{\chi}}_{o}})\left(\mathcal{K}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{\chi}}_{o}},{\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}^{+}})\mathcal{G}^{t}_{\text{DPO+}}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}^{+}})-\mathcal{K}^{t}({\color[rgb]{1,0.5,0}\bm{\mathsf{\chi}}_{o}},{\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}^{-}})\mathcal{G}^{t}_{\text{DPO-}}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}^{-}})\right) \tag{13}
where are concatenation of two vectors or matrices, \mathcal{G}^{t}_{\text{DPO+}}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}^{+}})\triangleq\nabla_{\bm{\mathsf{z}}^{+}}\mathcal{L}_{\text{DPO}}, and \mathcal{G}^{t}_{\text{DPO-}}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}^{-}})\triangleq\nabla_{\bm{\mathsf{z}}^{-}}\mathcal{L}_{\text{DPO}}. To calculate the residual terms, we decompose the loss into:
其中 为两向量或矩阵的拼接,\mathcal{G}^{t}_{\text{DPO+}}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}^{+}})\triangleq\nabla_{\bm{\mathsf{z}}^{+}}\mathcal{L}_{\text{DPO}},\mathcal{G}^{t}_{\text{DPO-}}({\color[rgb]{0,1,1}\bm{\mathsf{\chi}}_{u}^{-}})\triangleq\nabla_{\bm{\mathsf{z}}^{-}}\mathcal{L}_{\text{DPO}}。为计算残差项,将损失分解为:
\displaystyle\mathcal{L}_{\text{DPO}}({\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}},\bm{\mathsf{y}}_{u}^{+},\bm{\mathsf{y}}_{u}^{-}\mid\theta) \\ \displaystyle=-\log(a) \\ \displaystyle a \\ \displaystyle\triangleq\sigma(b) \\ \displaystyle b \\ \displaystyle\triangleq\beta\left(\log\pi_{\theta^{t}}(\bm{\mathsf{y}}_{u}^{+}\mid\bm{\mathsf{\chi}}_{u}^{+})-\log\pi_{\theta^{t}}(\bm{\mathsf{y}}_{u}^{-}\mid\bm{\mathsf{\chi}}_{u}^{-})\right)-c \\ \displaystyle=-\beta\left(\mathcal{L}_{\text{SFT}}(\bm{\mathsf{\chi}}_{u}^{+})-\mathcal{L}_{\text{SFT}}(\bm{\mathsf{\chi}}_{u}^{-})\right)-c \\ \displaystyle c \\ \displaystyle\triangleq\beta\left(\log\pi_{\text{ref}}(\bm{\mathsf{y}}_{u}^{+}\mid\bm{\mathsf{\chi}}_{u}^{+})-\log\pi_{\text{ref}}(\bm{\mathsf{y}}_{u}^{-}\mid\bm{\mathsf{\chi}}_{u}^{-}\right), \tag{14}
where is not a function of . Using the chain rule, the -th column of the residual term can be calculated as (the calculate of is similar):
其中 不是 的函数。用链式法则,残差项 的第 列可算为( 类似):
By stacking values with different , we can get the residual term of DPO as
将不同 的值堆叠,可得 DPO 的残差项为
Similarly, we can calculate the residual terms for other off-policy preference optimization methods, like Identity-preference Optimization (IPO (Azar et al. 2024a)):
类似地,可计算其它 off-policy 偏好优化方法的残差项,例如恒等偏好优化(IPO,Azar et al. 2024a):
For the Sequence Likelihood Calibration (SLiC (Zhao et al. 2023a)), we have:
对序列似然校准(SLiC,Zhao et al. 2023a),有:
In summary, these RL-free algorithms all relate to the SFT loss to some extent. For the DPO and IPO loss, the directions of the updating signals are identical. A scalar controls the strength of this update, which usually correlated with the confidence gap between the model’s current confidence on and , i.e., . Generally, larger this value leads to a bigger , making the norm of smaller. In other words, we see a “regularizing” effect in this term, where the model should not make too large. The SLiC loss can be considered as a combination of SFT adaptation and preference adaptation. Similarly, we can also see a hard version of the regularization effect mentioned above. If , the indicator function will become zero, and the model stops pushing and away when it already separates and well.
总之,这些免 RL 算法都在某种程度上与 SFT 损失相关。对 DPO 与 IPO 损失,更新信号方向相同。一个标量控制该更新强度,通常与模型当前对 、 的置信度间隙相关,即 。一般地,该值越大则 越大,使 越小。换言之,该项呈现「正则」效应:模型不应使 过大。SLiC 损失可视为 SFT 适应与偏好适应的组合;类似地,也可看到上述正则效应的硬版本:若 ,指示函数变为零,模型在已能很好区分 与 时停止把 与 推远。
Recently, authors of (Wu et al. 2024a) propose another interesting self-play alignment algorithm called SPPO, which further improves the alignment performance on top of many on-policy DPO methods. Our framework could also give an interesting explanation of why this method works so well. Specifically, the loss function of SPPO can be written as:
最近,Wu et al. 2024a 提出另一种有趣的自我对弈对齐算法 SPPO,在许多 on-policy DPO 方法之上进一步提升对齐表现。我们的框架亦可对其为何如此有效给出有趣解释。具体地,SPPO 损失函数可写为:
This loss looks similar to the IPO one, but the main difference between SPPO and other methods (e.g., DPO, KTO, IPO, SPIN, etc.) is that there is no negative sign in front of or . From its residual term , it is more convenient to understand this algorithm as imposing two positive vectors on both and , but the former has a longer norm, as illustrated in Figure 2. By doing so, the big negative gradient no longer exists, and so does the squeezing effect. That is partly why this method is more stable and performs better.
该损失看似类似 IPO,但 SPPO 与其它方法(如 DPO、KTO、IPO、SPIN 等)的主要差别在于: 或 前面没有负号。从其残差项 看,更便于将该算法理解为在 与 上各施加一个正向量,但前者范数更长,如图 2 所示。如此一来,大负梯度不再存在,挤压效应亦不复存在。这是该方法更稳定、表现更好的部分原因。
Appendix C The “Relative Stable” eNTK Assumption
附录 C「相对稳定」eNTK 假设
We use this appendix to verify the core assumption of our analysis – during the training, the relative influence of learning on all other different is relatively stable – on both MNIST and LLM finetuning settings. To make the notation concise, we use to reprsent , and other related variants.
本附录在 MNIST 与 LLM 微调设定下验证分析的核心假设——训练中,学习 对其它各个 的相对影响力保持相对稳定。为简洁起见,用 表示 、 及其它相关变体。
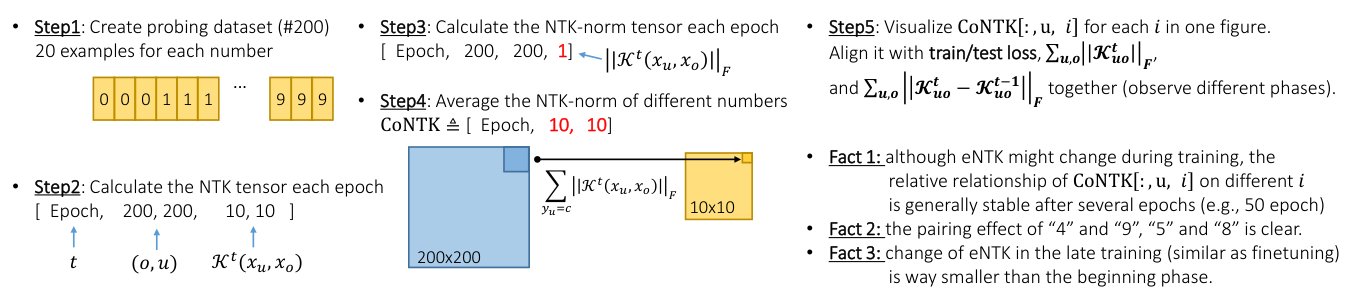
Figure 6: Experimental design of verifying the relative stability of for fixed on different .
图 6:验证固定 下不同 上 相对稳定性 的实验设计。
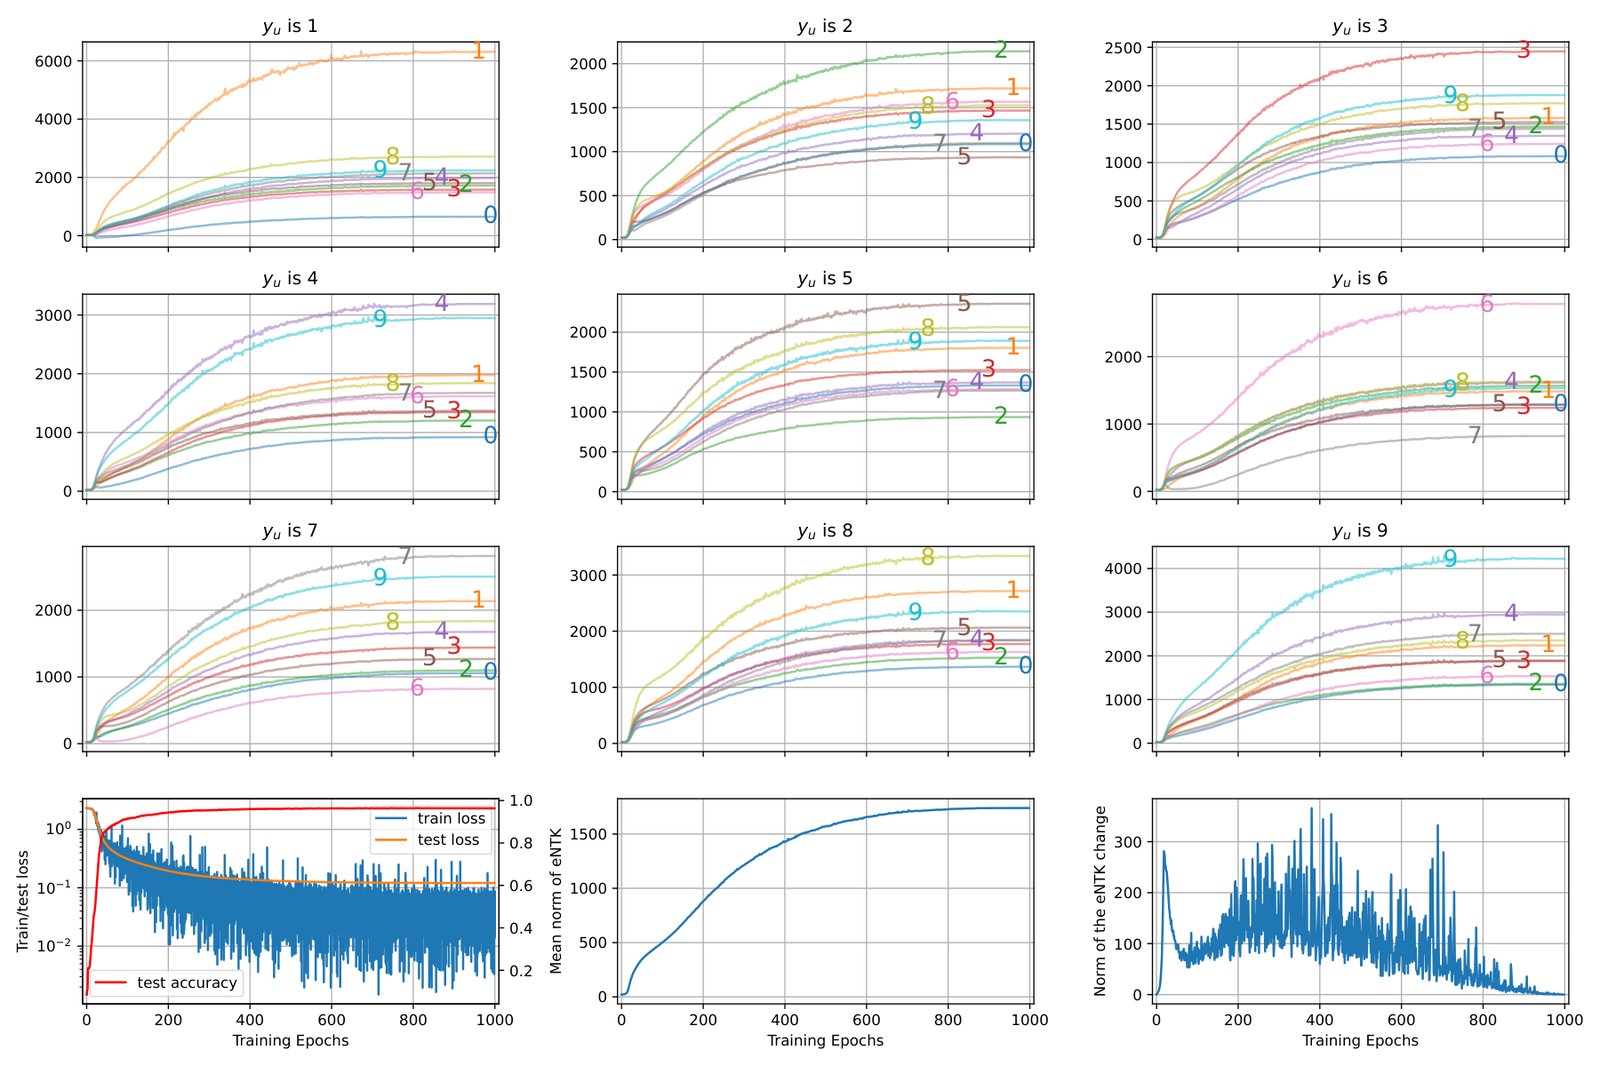
Figure 7: Results showing the relative stability of for fixed on different (labeled by the colorful digits near the lines).
图 7:固定 下不同 (曲线旁彩色数字标注)上 相对稳定性的结果。
C.1 Relative Stable eNTK Assumption - MNIST Experiments
C.1 相对稳定 eNTK 假设——MNIST 实验
For the MNIST example, we directly calculate the eNTK term using a pipeline demonstrated in Figure 6. The results are showed in Figure 7, where the key findings are:
对 MNIST 例子,我们按图 6 所示流程直接计算 eNTK 项。结果见图 7,关键发现是:
- The last three panels roughly indicate different phases throughout the training, where the first several epochs () are a bit messy, and the last several epochs () behave similarly to the finetuning stage;
- Although the norm of eNTK () and the norm of eNTK’s adaptation () changes a lot after 30 epochs, the ranking between on different are relatively stable, as demonstrated by the upper 9 panels;
- The pairing effect between the “similar” inputs is clear, e.g., “4” and “9”, “5” and “8”, etc;
- The pairing effect between the “dis-similar” inputs are also clear, e.g., “6” and “7”, “2” and “5”, etc.
- The pairing effect mentioned previously is not strictly symmetry, which is because the inconsistent and terms;
- The accumulated influence demonstrated in the third panel of Figure 1 is strongly correlated to the integral of all these curves.
- 后三幅大致对应训练不同阶段:前若干 epoch()较乱,后若干 epoch()行为类似微调阶段;
- 尽管 eNTK 范数()及其适应范数()在 30 epoch 后变化很大,不同 上 的排序相对稳定,见上 9 幅;
- 「相似」输入之间的配对效应清晰,例如「4」与「9」、「5」与「8」等;
- 「不相似」输入之间的配对效应亦清晰,例如「6」与「7」、「2」与「5」等;
- 前述配对效应并非严格对称,因 与 项不一致;
- 图 1 第三幅所示累积影响力与所有这些曲线的积分强相关。
C.2 Relative Stable eNTK Assumption - LLM Experiments
C.2 相对稳定 eNTK 假设——LLM 实验
Directly calculating for the LLM experiment requires huge amount of computation, because for each token in each example, we need to multiply a matrix to a one, where is the number of parameters of the LLM. However, since we only care about the relative relationship between on different , where is fixed, based on the basic decomposition in Proposition 1, we can get a lower-bound as follows (ignoring superscript for conciseness, ignoring the influence of ):
对 LLM 实验直接计算 需要巨大算力:对每个样本的每个 token,需将 矩阵乘以 矩阵,其中 为 LLM 参数个数。但我们只关心固定 时不同 上 的相对关系,故基于命题 1 的基本分解,可得如下下界(为简洁省略上标 ,并忽略 影响):
We hence define two quantitive measurements to have a better understanding of , they are:
于是我们定义两个定量度量以更好理解 ,分别为:
where the subscript here represent the -th token and -th dimension for the prediction. In later experiments, we will observe both and to have a better understanding of the strength (norm) and the direction (sign) of the relative influence imposed via .
其中下标 表示预测的第 个 token 与第 维。后续实验中,我们将同时观察 与 ,以更好理解经 施加的相对影响的强度(范数)与方向(符号)。
(a)
Regarding the calculation of , is easy to track because, in the main context, we already showed for different responses. , where is defined as a stacking of one-hot vectors. The is a bit complex. Recall the definition that , we can have:
关于 的计算: 易于跟踪,因为正文中已展示不同回复的 。,其中 定义为 个 one-hot 向量的堆叠。 稍复杂。回忆定义 ,可得:
which is also trackable in our setting. Note that intuitively, the value of is inversely correlated to the Shannon entropy of the distribution : if is one-hot; if is uniform. Hence we can also interoperate as the peakiness of . In the following experiment, we track the value of for different types of responses during SFT and DPO to show that the relative influence between different response types is relatively stable. We show the experimental results in Figure 8, in which the key findings are:
在我们的设定中亦可跟踪。直观上, 与分布 的 Shannon 熵负相关: 为 one-hot 时 ; 均匀时 。故亦可将 解读为 的尖峰程度。下述实验中,我们在 SFT 与 DPO 期间跟踪不同类型回复的 ,以表明不同回复类型之间的相对影响相对稳定。结果见图 8,关键发现是:
- In both SFT and DPO under different supervisory signals, the change of these two metrics are relatively stable, similar to those in Figure 7;
- The clear pairing effect between (blue curve) and (red curve) exist;
- In , learning any natural language sequences (i.e., ) influence the non-language sequence () a lot, especially at the end of finetuning. However, from we know such an influence is negative, which is caused by the pushing down pressure;
- An interesting “similarity pattern” occurs: by observing , we see SFT using or imposes more influence on the sequence generated using ChatGPT other than their original response (i.e., or ), which might be an interesting phenomenon to explore further;
- By observing the last row, where the model is trained using DPO, it is clear that the push-down pressure is dominant. Because almost all terms have big negative values, and the only positive one is (roughly 0.5, much smaller than other positive values in the SFT cases).
- 在不同监督信号下的 SFT 与 DPO 中,这两个指标的变化都相对稳定,类似图 7;
- (蓝曲线)与 (红曲线)之间存在清晰配对效应;
- 在 中,学习任何自然语言序列(即 、、、)对非语言序列(、)影响很大,尤其在微调末期。但从 可知该影响为负,由压低压力造成;
- 出现有趣的「相似模式」:观察 ,可见用 或 做 SFT 对用 ChatGPT 生成的序列影响,比对原始回复(即 或 )更大,值得进一步探索;
- 观察末行(模型用 DPO 训练)可清楚看到压低压力占主导:几乎所有 项都有很大负值,唯一正值是 (约 0.5,远小于 SFT 情形中其它正值)。
We also provide some intermediate quantities in Figure 9 to further validate our analysis. The key trends are provided in its caption for ease of reading.
我们还在图 9 提供若干中间量以进一步验证分析。关键趋势见其图注,便于阅读。
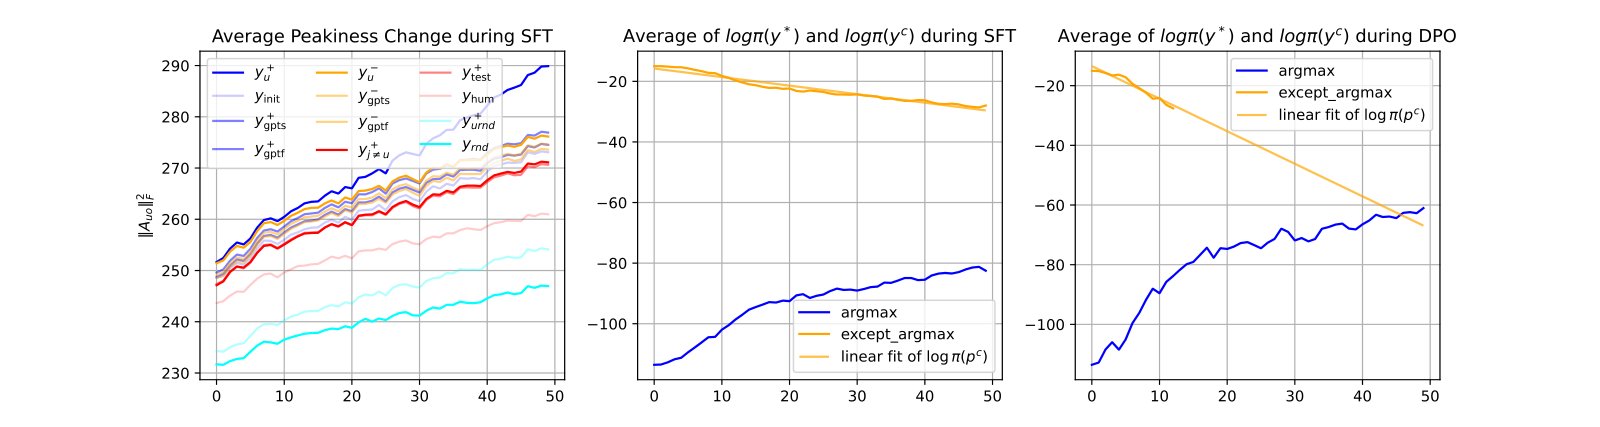
Figure 9: Other metrics related to LLM’s learning dynamics. The first panel demonstrates how changes during SFT (higher means peakier ). It is clear that the peakiness of , i.e., the supervisory signal, increases fastest. The last two panels demonstrate the average and its complementary (denoted by , which measures how many probability masses are left for other possible tokens). The second one is for SFT and the third one is for DPO. It is clear that and changes faster in the DPO case, which matches our observations in the fourth panel of Figure 3 well. The linear fit extrapolates the values because we suffer an underflow issue when estimating this term. We will fix them in the next version. However, the trend of their changing speed is consistent across different settings.
图 9:与 LLM 学习动力学相关的其它指标。第一幅展示 SFT 中 如何变化(越高表示 越尖峰)。可见监督信号 的尖峰上升最快。后两幅展示平均 及其补(记为 ,度量留给其它可能 token 的概率质量)。第二幅为 SFT,第三幅为 DPO。显然 DPO 中 与 变化更快,与图 3 第四幅观察吻合。因估计该项时出现下溢,线性拟合外推了 值;下一版本将修复。但其变化速度趋势在不同设定下一致。
Appendix D More About Experiments
附录 D 关于实验的更多内容
This section provides more experimental details and results about the learning dynamics to support our claim. We will first discuss how different types of responses are selected in our probing dataset . These responses can fit into a 2-D space where one dimension is semantical relevance of the response to . We then provide more results and discussions on different models and settings. The subtle differences between the responses all support our story well.
本节提供更多关于学习动力学的实验细节与结果以支撑论断。我们先讨论探测集 中如何选取不同类型回复。这些回复可放入二维空间,其中一维是回复相对 的语义相关性。随后给出不同模型与设定下的更多结果与讨论。回复之间的细微差别都很好支持我们的故事。
(a)
D.1 The Selection of Response Types for the Probing Dataset
D.1 探测集回复类型的选取
Besides the sequential nature of the loss function, another conundrum in analyzing LLM learning dynamics is the huge response space : the number of possible is , but the vast majority of possible sequences look nothing like natural language, and we expect the model to generate only a subset of natural language-like responses. These properties prevent us from observing the changes of all possible like what we did for MNIST. Instead, we define several interesting regions of , and select corresponding typical responses to observe. Intuitively, we can use the semantic relevance between and {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} as a heuristic. Such a measurement can be understood as “how suitable this is as a response to {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}}, compared to .” Then, starting from the structure of common preference optimization datasets such as Antropic-HH (Bai et al. 2022a) and UltraFeedback (Cui et al. 2023a), we can divide into three sub-spaces and evaluate the following types of responses (as in Figure 10(b)). The prompt templates used to generate them are illustrated in Figure 11. We also provide examples of all 14 types of responses in Figure 12.
除损失函数的序列性外,分析 LLM 学习动力学的另一难点是巨大的回复空间 :可能的 数量为 ,但绝大多数可能序列完全不像自然语言,我们期望模型只生成自然语言样回复的一个子集。这些性质使我们无法像 MNIST 那样观察所有可能 的变化。于是我们定义 的若干有趣区域,并选取对应典型回复来观察。直观上可用 与 {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} 的语义相关性作启发;该度量可理解为「相对 ,该 作为 {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} 回复有多合适」。从 Antropic-HH(Bai et al. 2022a)、UltraFeedback(Cui et al. 2023a)等常见偏好优化数据集结构出发,可将 划为三个子空间并评估下列回复类型(见图 10(b))。生成所用提示模板见图 11。图 12 亦给出全部 14 类回复的例子。
- • : reasonable responses following the instruction {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}}: 0. , the initial response generated by feeding {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} to LLM before finetuning; 1. , the chosen (i.e., the preferred) response to {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}}. 1.1 , rephrase using , algorithm from Yang et al. 2024a; 1.2 , rephrase using ChatGPT, keep the semantics while changing the format; 1.3 , rephrase using ChatGPT, keep the format while changing the semantics; 2. , the rejected (i.e., the less preferred, but still reasonable) response to {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}}. 2.1 , rephrase using , algorithm from Yang et al. 2024a; 2.2 , rephrase using ChatGPT, keep the semantics while changing the format; 2.3 , rephrase using ChatGPT, keep the format while changing the semantics;
- • : irrelevant responses to {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} that are still recognizably human language (in these datasets, roughly “internet-standard” English): 3. , the chosen response for a different question selected from the training set. 4. , the chosen response of a question selected from the test set. 5. , a “random” English sentence generated by ChatGPT with as many words as .
- • : token sequences that do not form meaningful human language: 6. , a random permutation of the words (space-separated strings) of . 7. , a random permutation of the words of a generated sentence as in .
- • :遵循指令 {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} 的合理回复:0. ,微调前将 {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} 输入 LLM 得到的初始回复;1. ,对 {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} 的所选(即偏好)回复。1.1 ,用 改写 ,算法来自 Yang et al. 2024a;1.2 ,用 ChatGPT 改写 ,保持语义改格式;1.3 ,用 ChatGPT 改写 ,保持格式改语义;2. ,对 {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} 的拒绝(即较不偏好但仍合理)回复。2.1 ,用 改写 ;2.2 ,用 ChatGPT 改写 ,保持语义改格式;2.3 ,用 ChatGPT 改写 ,保持格式改语义;
- • :对 {\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}} 无关但仍可辨认为人类语言的回复(在这些数据集中大致为「互联网标准」英文):3. ,训练集中另一问题 的所选回复。4. ,测试集中问题 的所选回复。5. ,由 ChatGPT 生成、与 词数相当的「随机」英文句。
- • :不构成有意义人类语言的 token 序列:6. , 各词(空格分隔字符串)的随机置换。7. ,类似 生成句各词的随机置换。
Furthermore, we also create another probing dataset (named ) where all comes from the test set. Compared with that we used in the main context, all the prompts and responses in are never exposed to the model during finetuning. By comparing the learning curves of these two probing datasets, we can figure out the difference between the model’s prediction of those directly influenced responses ( appears during training) and the indirectly influenced ones ( that the model never sees during training). Finally, we believe the level of the “on-policy” property (which is very important for the preference finetuning, as discussed in Tajwar et al. 2024a) could also be introduced as the second axis in our 2-D plane. We left the exploration of this interesting direction in our future work.
此外我们还创建另一探测集(记为 ),其中所有 来自测试集。与正文所用 相比, 中的提示与回复在微调中从未暴露给模型。比较两探测集的学习曲线,可弄清模型对直接受影响回复(训练中出现的 )与间接受影响回复(训练中从未见过的 )预测的差别。最后,我们认为「on-policy」性质的程度(对偏好微调很重要,见 Tajwar et al. 2024a)也可作为二维平面的第二轴引入。该有趣方向留待未来探索。
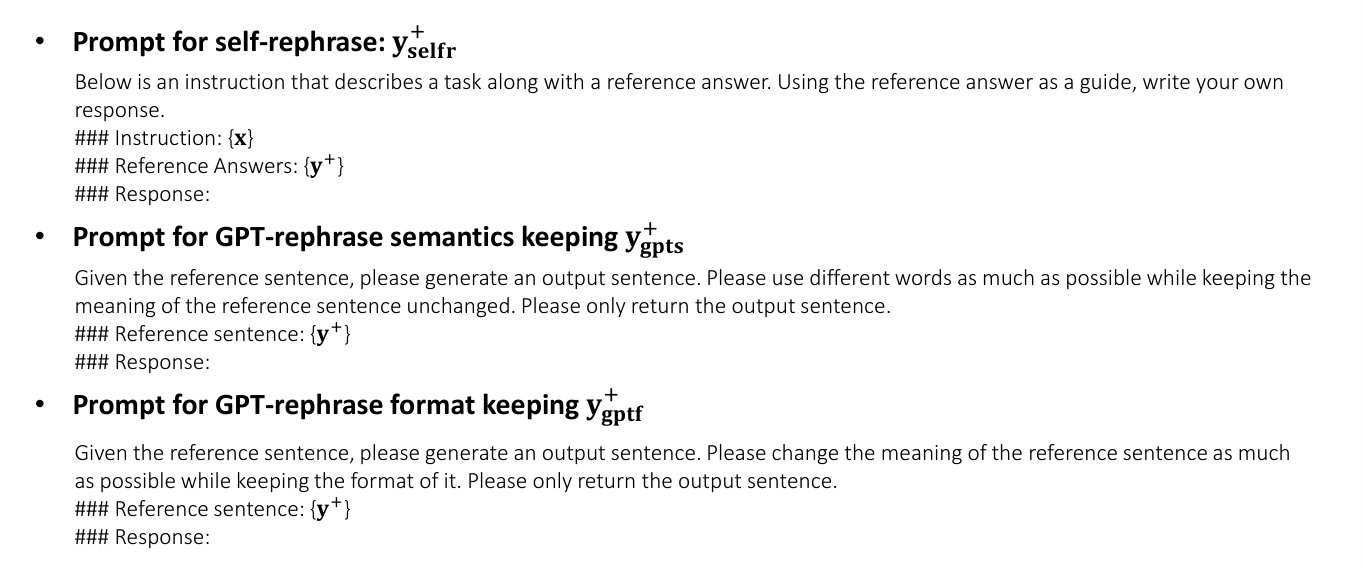
Figure 11: The prompts used to generate , , and . The rephrases of rejected samples are generated similarly. The self-rephrase template comes from Yang et al. 2024a.
图 11:生成 、 与 所用提示。拒绝样本的改写类似生成。自我改写模板来自 Yang et al. 2024a。
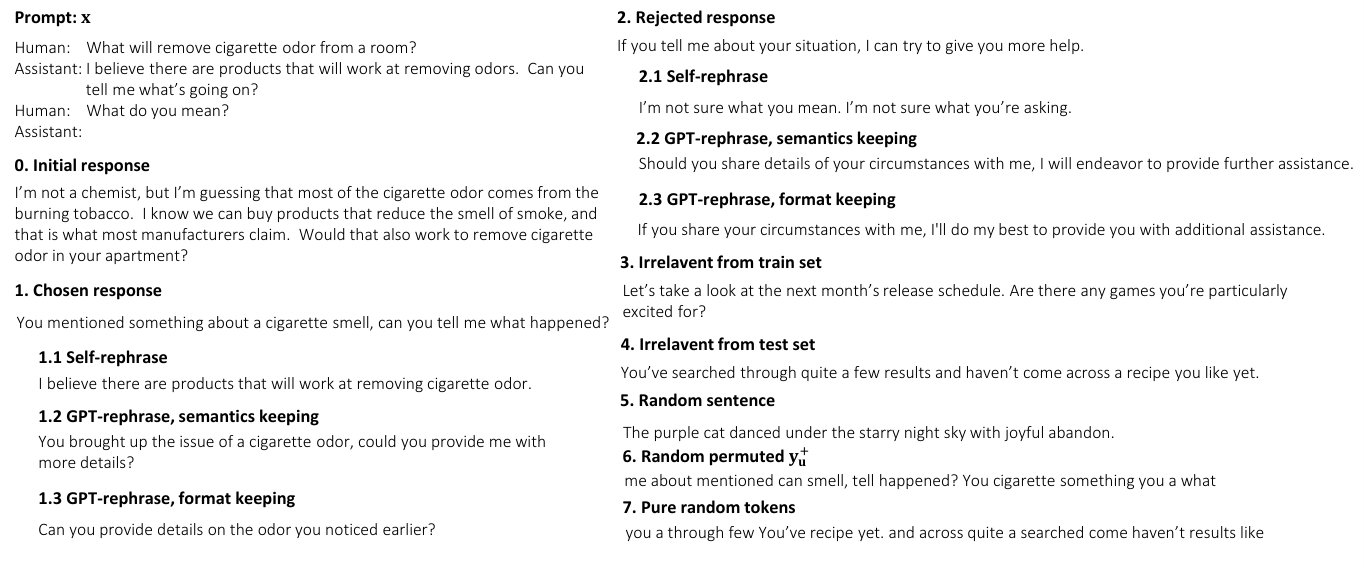
Figure 12: Example of all possible responses for one in our probing dataset. Note that the pure random token is generated by first creating a random sentence, then randomly permuting its tokens.
图 12:探测集中某一 全部可能回复的例子。注意纯随机 token 先生成随机句,再随机置换其 token。
D.2 More results on different settings: SFT case
D.2 不同设定下的更多结果:SFT 情形
Consistent learning dynamics for different models. In this subsection, we provide more results to support our analysis on SFT in Section 4.1. The first thing to verify is the consistency of the trends of learning dynamics across different settings. As illustrated in Figure 14, we conduct SFT on five models with different sizes pretrained using different recipes. Note that Pythia-410M/1B/1.4B/2.8B are pretrained using exactly the same dataset and pipeline (Biderman et al. 2023a), while Qwen1.5-0.5B are pretrained differently. Hence we can observe a slight difference between the curves from Pythia series and Qwen series, e.g., those in . However, the trends demonstrated in Figure 3 consistently hold for all models.
不同模型上一致的学习动力学。 本小节提供更多结果以支撑第 4.1 节对 SFT 的分析。首先验证学习动力学趋势在不同设定下的一致性。如图 14,我们在五种不同规模、不同预训练配方的模型上做 SFT。注意 Pythia-410M/1B/1.4B/2.8B 用完全相同的数据集与流程预训练(Biderman et al. 2023a),而 Qwen1.5-0.5B 预训练不同。因此可观察到 Pythia 系列与 Qwen 系列曲线的轻微差别,例如 上的曲线。但图 3 所示趋势对所有模型一致成立。
Compare the rephrases of and . See Figure 15, where we put the rephrases of the same response into the same figure. We can treat the red curve, i.e., the one of generated by , as a baseline, whose decaying suggests the policy model is deviating from the initial point. The first observation is that after several updates, is the only one that keeps increasing fast, which means the “pull up” pressure generated by [{\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}};{\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}^{+}}] do not have that strong influence on these rephrases compared to [{\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{u}};{\color[rgb]{1,0.5,0}\bm{\mathsf{y}}_{j\neq u}^{+}}], even though these {\color[rgb]{1,0.5,0}\bm{\mathsf{y}}} are good rephrases of {\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}^{+}} (recall the curve always increase in Figure 14). Furthermore, by carefully comparing the decreasing speed of and other curves, we find those rephrases decays slower than in the chosen case, but not the case for the rejected responses. This phenomenon also supports our analysis well: because we train the model using , their rephrases are “pulled up” more than the rephrases of . Such a claim is also verified by the experiment in the last column of this figure, where we train the model using [{\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}};{\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}^{-}}] rather than . In these two panels, we see the decaying speed of rephrases of is now identical to that of while the decaying speed of rephrases for is slightly slower. Last, compare the green and orange curves (i.e., the format-keeping and semantics-keeping GPT rephrases), we find the predicting probabilities of those format-keeping curves are usually larger than their semantic-keeping counterparts. This is a sign that the model during SFT might care more about the format rather than the semantics of one sentence. We will delve into this interesting phenomenon in our future work.
比较 与 的改写。 见图 15,我们将同一回复的改写放在同一图中。可将红曲线,即由 生成的 ,视为基线,其衰减表明策略模型正偏离初始点。首要观察是:若干更新后,只有 持续快速上升,说明 [{\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}};{\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}^{+}}] 产生的「拉高」压力对这些改写的影响,弱于 [{\color[rgb]{1,0.5,0}\bm{\mathsf{x}}_{u}};{\color[rgb]{1,0.5,0}\bm{\mathsf{y}}_{j\neq u}^{+}}],即便这些 {\color[rgb]{1,0.5,0}\bm{\mathsf{y}} 是 {\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}^{+}} 的良好改写(回忆图 14 中 曲线总在上升)。再仔细比较 与其它曲线的下降速度,发现所选情形中这些改写比 衰减更慢,但对拒绝回复并非如此。该现象也很好支持分析:因为我们用 训练模型,其改写比 的改写被「拉高」更多。图末列实验亦验证该论断——我们改用 [{\color[rgb]{0,1,1}\bm{\mathsf{x}}_{u}};{\color[rgb]{0,1,1}\bm{\mathsf{y}}_{u}^{-}}] 而非 训练。这两幅中, 改写的衰减速度现与 相同,而 改写的衰减略慢。最后,比较绿、橙曲线(即保格式与保语义的 GPT 改写),发现保格式曲线的预测概率通常大于保语义对照。这提示 SFT 中模型可能更关心句子格式而非语义。该有趣现象留待未来深入。
Compare and . To isolate the influence of the “pull up” pressure introduced by the training updates, we also create another probing dataset using the same pipeline as . The only difference between them is that all in comes from the test set, and hence neither the prompts nor the responses ever occur during training. See Figure 16, where the solid curves and dotted curves represent the learning dynamics of responses in and respectively. The color of the curves represents the model we are finetuning. By qualitatively comparing the trend difference between curves coming from and , we roughly observe that trend_diff > trend_diff() > trend_diff() > trend_diff(), which aligns well with our hypothesis about how strong the “pull up” pressure influence different responses.
比较 与 。 为隔离训练更新引入的「拉高」压力影响,我们用与 相同的流程另建探测集 。唯一差别是 中所有 来自测试集,故提示与回复在训练中均未出现。见图 16,实线与虚线分别表示 与 中回复的学习动力学;曲线颜色表示正在微调的模型。定性比较来自两探测集曲线的趋势差异,大致观察到 trend_diff > trend_diff() > trend_diff() > trend_diff(),与我们对「拉高」压力如何强弱影响不同回复的假设吻合。
(a) Result of SFT on Antropic-HH.
(a) Antropic-HH 上的 SFT 结果。
(a) Result of SFT on Antropic-HH.
(a) Antropic-HH 上的 SFT 结果。
(a) Result of SFT on Antropic-HH.
(a) Antropic-HH 上的 SFT 结果。
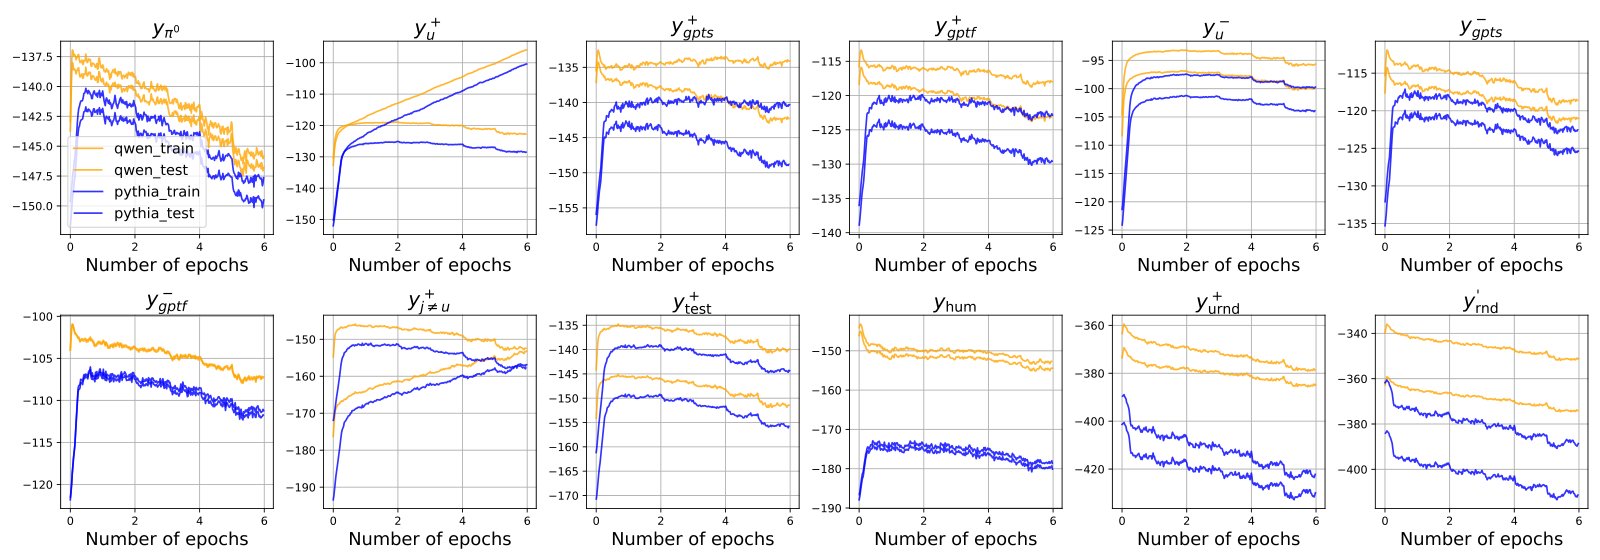
Figure 16: Compare the learning dynamics of examples from and . Key trend to observe: for , since many responses and prompts ever occur during training, the pull-up pressure is generally stronger. Curves of , , and shows a clear trend. (Antropic-HH, SFT)
图 16:比较 与 样本的学习动力学。需关注的关键趋势:对 ,因许多回复与提示在训练中出现过,拉高压力一般更强。、、 与 曲线呈现清晰趋势。(Antropic-HH,SFT)
D.3 More results on different settings: off-policy DPO case
D.3 不同设定下的更多结果:off-policy DPO 情形
Similar to Section D.2, we also provide extra experiments for DPO in this part using the same probing dataset. Note that as the responses of on-policy DPO change generation-by-generation, it is hard to observe the dynamics of a pre-collected probing dataset. We left the exploration of how to effectively probe other DPO variants in our future work.
与第 D.2 节类似,本部分用同一探测集为 DPO 提供额外实验。注意 on-policy DPO 的回复逐代变化,难以观察预采集探测集的动力学。如何有效探测其它 DPO 变体留待未来工作。
Consistent learning dynamics for different models. Compare Figure 4 in the main context and Figure 18, where we provide the results on many different models (Pythia-410M/1B/2.8B and Qwen1.5-0.5B). Their trends on different are quite consistent:
不同模型上一致的学习动力学。 比较正文图 4 与图 18(给出 Pythia-410M/1B/2.8B 与 Qwen1.5-0.5B 等多种模型结果)。它们在不同 上的趋势相当一致:
- 1.) in the first column, the margin keeps increasing. The first increase and then decrease, always with a smaller decay speed than that of ;
- 2.) in the second column, decreases slower than the other rephrases, verifying the “pull up” pressure and the influence on other responses via ;
- 3.) in the third column, decreases faster than the other rephrases, verifying the “push down” pressure and the influence on other ;
- 4.) in the fourth column, the rephrases of decay slower than those of , supporting the claims that the rephrases near the chosen responses are influenced by the “pull up” pressure while the rephrases of the rejected ones are influenced by the “push down” pressure.
- 1.) 第一列中,间隔 持续增大。 先升后降,衰减速度始终小于 ;
- 2.) 第二列中, 比其它改写下降更慢,验证「拉高」压力及经 对其它回复的影响;
- 3.) 第三列中, 比其它改写下降更快,验证「压低」压力及对其它 的影响;
- 4.) 第四列中, 的改写比 的改写衰减更慢,支持「靠近所选回复的改写受拉高压力影响、拒绝回复的改写受压低压力影响」的论断。
Learning dynamics of conducting SFT first, then DPO. As stated in (Ouyang et al. 2022a), conducting SFT before DPO is a common pipeline for alignment. Using as the SFT dataset is also a common practice in many existing works. Hence in this part, we plot the curves of different in both two stages to demonstrate their differences. See Figure 17, where the difference between the experiments in these three rows is how long the model is trained using SFT before DPO. The learning rate of both SFT and DPO are controlled to be the same (i.e., , the default value in (Tajwar et al. 2024a)). All the curves are aligned by the 10th epoch on the x-axis (i.e., the starting time for the DPO training) for the convenience of comparing the trends across different settings.
先 SFT 再 DPO 的学习动力学。 如 Ouyang et al. 2022a 所述,DPO 前做 SFT 是对齐的常见流程;用 作 SFT 数据亦是许多工作的惯例。故本部分绘制两阶段中不同 的曲线以展示差别。见图 17,三行实验的差别在于 DPO 前用 SFT 训练多久。SFT 与 DPO 学习率控制相同(即 ,Tajwar et al. 2024a 默认值)。所有曲线按横轴第 10 个 epoch(即 DPO 训练起点)对齐,便于跨设定比较趋势。
We first check the curves of SFT and DPO parts separately and find that all the above relative trends still hold in these experiments. We then compare the model’s behavior in these two phases respectively. In the last two rows of Figure 17, where the epoch for SFT is non-zero, it is clear that the decaying speed of most observing is much larger in DPO than those in SFT. The main reason for this is the existence of a big negative gradient introduced in DPO. This gradient, especially conducted on a “valley” region of the model’s prediction, will “push down” the whole curve significantly, except the one with the highest confidence before updating. This non-trivial trend is named “squeezing effect”, which is elaborated on in Appendix E. Furthermore, a more peaky and a smaller will lead to a stronger “squeezing effect”, which can be verified by comparing the curves of the last two panels: longer SFT makes the model’s prediction peakier when DPO is conducted, which leads to a larger decay on all during DPO.
我们先分别检查 SFT 与 DPO 部分的曲线,发现上述相对趋势在这些实验中仍成立。再分别比较两阶段中的模型行为。图 17 后两行中 SFT epoch 非零,可见多数观测 在 DPO 中的衰减速度远大于 SFT。主因是 DPO 引入的大负梯度。该梯度尤其作用于模型预测的「谷底」区域时,会显著「压低」整条曲线,除更新前置信度最高者外。这一非平凡趋势称为「挤压效应」,附录 E 详述。此外,更尖峰的 与更小的 会导致更强挤压效应,比较后两幅曲线可验证:更长 SFT 使做 DPO 时模型预测更尖峰,从而 DPO 中所有 衰减更大。
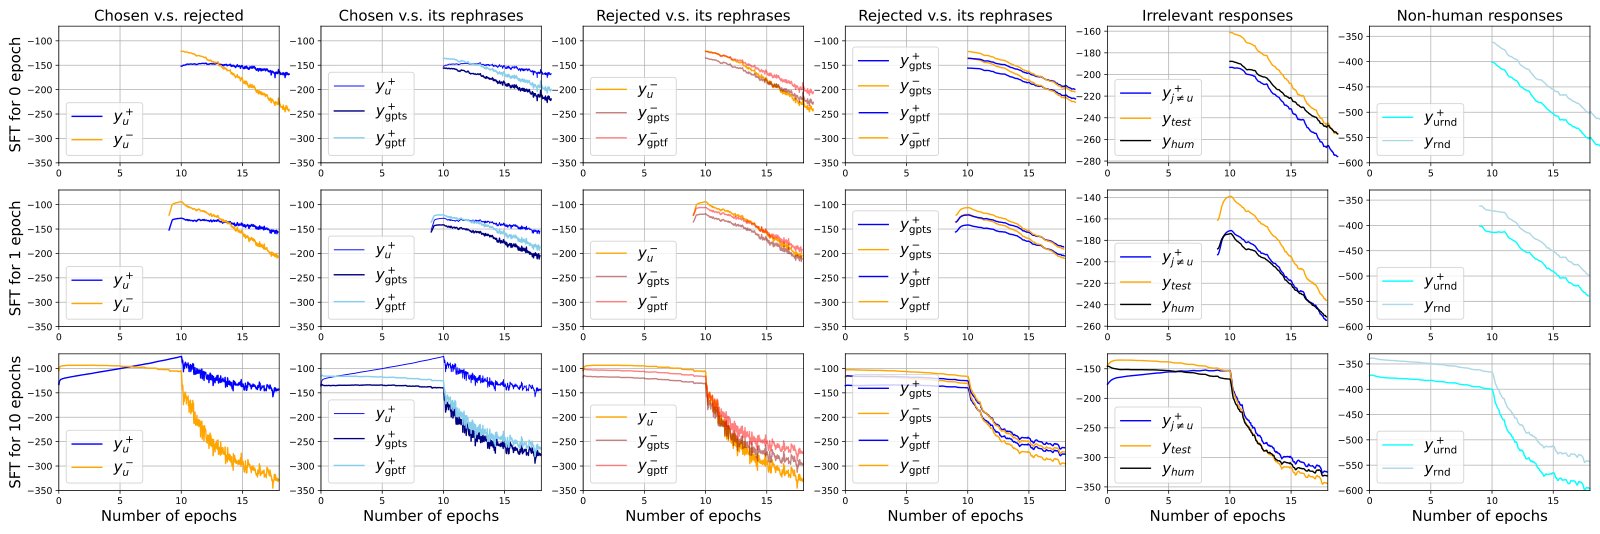
Figure 17: The learning dynamics of conducting DPO after SFT the model for several epochs. We align the starting point of DPO (i.e., the 10th epoch from the x-axis) to better compare the curves. Key trend to observe: 1.) Confidence of all responses decays way faster when DPO starts, which is caused by the squeezing effect introduced via a big negative gradient; 2.) The more epochs we SFT the model, the more serious the squeezing effect is (confidence decays faster). (Antropic-HH, SFT DPO)
图 17:先 SFT 若干 epoch 再做 DPO 的学习动力学。将 DPO 起点(横轴第 10 个 epoch)对齐以便比较曲线。需关注的关键趋势:1)DPO 开始后所有回复置信度衰减远更快,由大负梯度引入的挤压效应造成;2)SFT 越久,挤压效应越严重(置信度衰减更快)。(Antropic-HH,SFT → DPO)
(a) Result on Antropic-HH.
(a) Antropic-HH 上的结果。
Appendix E The Squeezing Effect Introduced by Big Negative Gradient
附录 E 大负梯度引入的挤压效应
In DPO, the model gradually learns how to separate the chosen and rejected responses by imposing one positive and one negative adaptation vector centered at and respectively, as illustrated in the second panel in Figure 2. These two opposite pressures ensure the margin reward keep increasing, which makes the model align better with human preferences. However, if we go deeper and consider and separately (actually we should, because their are usually different), a very interesting phenomenon occurs. See the first column of Figure 18, we find although DPO also contains a strong positive adaptation vector, the curve of all goes down after several updates, which is very different from in the SFT case. Such an observation is also reported in many related works (Rafailov et al. 2024a; Tajwar et al. 2024a; Pal et al. 2024a; Razin et al. 2025a), but a clear-cut explanation of it is still missing. Furthermore, although the relative behaviors of various rephrases matches our analysis of learning dynamics well, merely the two pressures on and cannot explain why all these observed keeps decreasing during training. So, it is natural to ask:
在 DPO 中,模型通过对分别以 、 为中心的一正一负适应向量,逐渐学会区分所选与拒绝回复,如图 2 第二幅所示。这两种相反压力保证间隔奖励 持续增大,使模型与人类偏好更好对齐。但若深入并分别考虑 与 (实际上应该如此,因为它们的 通常不同),会出现很有趣的现象。见图 18 第一列:尽管 DPO 也含强正适应向量, 的曲线在若干更新后全部下降,与 SFT 情形中的 很不同。许多相关工作亦报告该观察(Rafailov et al. 2024a;Tajwar et al. 2024a;Pal et al. 2024a;Razin et al. 2025a),但仍缺少清晰解释。此外,尽管各类改写的相对行为与学习动力学分析吻合,仅凭 、 上的两股压力无法解释为何训练中所有观测到的 持续下降。于是自然要问:
Where has the probability mass gone?
概率质量去哪了?
E.1 The Squeezing Effect and Why it Exists
E.1 挤压效应及其为何存在
To answer the above question, we can start from the properties of the basic function by analyzing a simple multi-class logistic regression problem. Because no matter how complex the LLM is, its predictions are made by converting the logits into probabilities using heads. Note that the analysis here only considers the negative gradient, i.e., the one imposed by in LLM’s finetuning. As also pointed by Razin et al. 2025a, the pull up pressure imposed by will cancel the influence imposed by when their are identical. However, when and are dissimilar, the squeezing effect discussed in this paper still dominates. We left analyzing this intricate interaction between these two pressures is left to our future work.
为回答上述问题,可从基本 Softmax 函数的性质出发,分析简单的多类逻辑回归问题。因为无论 LLM 多复杂,其预测都是用 Softmax 头把 logits 转成概率。注意此处分析只考虑负梯度,即 LLM 微调中由 施加的那一项。如 Razin et al. 2025a 亦指出,当 相同时, 施加的拉高压力会抵消 的影响。但当 与 不相似时,本文讨论的挤压效应仍占主导。这两种压力之间的复杂相互作用留待未来分析。
Consider a simple -class logistic regression problem where each high-dimensional input data is converted to a length- feature vector via a deep neural network . In other words, we have . The model uses a linear read-out layer to convert the feature vector to logits and then generate the probability prediction vector using a head. We consider a common cross-entropy loss function for each input pair . In summary, we have:
考虑简单的 类逻辑回归问题:每个高维输入 经深度网络 转为长度为 的特征向量,即 。模型用线性读出层 将特征转为 logits ,再用 Softmax 头生成概率预测向量 。对每个输入对 考虑常见交叉熵损失。总结有:
where is the index of the step during training and is a length- one-hot vector determined by the ground truth label . To simplify our analysis, we assume a fixed and only update the parameters of the read-out layer using stochastic gradient descent:
其中 为训练步下标, 为由真实标签 决定的长度为 的 one-hot 向量。为简化分析,假设 固定,仅用随机梯度下降更新读出层 的参数:
where is the learning rate which can be negative if we consider a negative gradient during training. With Equation 32 and (33), we can write down each dimension of and after some calculations. To quantitatively analyze how the model’s confidence in each class changes, we define a ratio and use the following lemma to describe its behavior:
其中 为学习率;若训练中考虑负梯度,可为负。由式 32 与 (33),经若干计算可写出 与 的每一维。为定量分析模型对各类置信度如何变化,定义比率 ,并用下述引理描述其行为:
Lemma 1.
The ratio of confidence change for each can be represented as:
引理 1。
每一维置信度变化比率可表示为:
Note that the values of also depends on whether equals , hence for Case 1 () and Case 2 (), we have ( is the equivalent learning rate):
注意 的值也依赖于 是否等于 ,故对情形 1()与情形 2(),有( 为等效学习率):
$$\text{Case 1: }\beta_{j}=\left{\begin{aligned} &e^{-\eta^{\prime}(1+p_{j}^{t}-p_{i}^{t})}&\text{if }j\neq y\
&\quad\quad\quad 1&\text{if }j=y\end{aligned}\right.;\quad\text{Case 2: }\beta_{j}=\left{\begin{aligned} &e^{-\eta^{\prime}(p_{j}^{t}-p_{i}^{t})}&\text{if }j\neq y\
&e^{-\eta^{\prime}(p_{j}^{t}-p_{i}^{t}-1)}&\text{if }j=y\end{aligned}\right. \tag{35}$$
Proof.
To derive Equation 34, we need to have the analytical expression of each and . As , we need to link and first. With Equation 32 and (33), can be recursively written down as:
证明。
为导出式 34,需有各 与 的解析表达式。因 ,需先联系 与 。由式 32 与 (33), 可递归写为:
where is the equivalent learning rate that depends on the norm of feature representation. Note that , and are all length- vectors and is an integer ranging from 1 to . Then we can write down each as:
其中 是依赖特征表示范数的等效学习率。注意 、 与 均为长度 的向量, 为 1 到 的整数。于是可将每个 写为:
$$z_{i}^{t+1}=\left{\begin{aligned} &z_{i}^{t}-\eta^{\prime}p_{i}^{t}+\eta^{\prime},\quad&\text{if }i=y\
&z_{i}^{t}-\eta^{\prime}p_{i}^{t},\quad&\text{if }i\neq y\end{aligned}\right. \tag{37}$$
Then, we can combine the definition of function and write down different case-by-case. For Case 1 where , we have:
接着结合 Softmax 定义,分情形写出不同 。对情形 1(),有:
p_{i=y}^{t+1}=\frac{e^{z_{i}^{t+1}}}{\sum^{V}_{j=1}e^{z_{j}^{t+1}}}=\frac{e^{z_{i}^{t}-\eta^{\prime}p_{i}^{t}+\eta^{\prime}}}{\sum_{j\neq y}e^{z_{j}^{t}-\eta^{\prime}p_{j}^{t}}+e^{z_{y}^{t}-\eta^{\prime}p_{y}^{t}+\eta^{\prime}}}=\frac{e^{z_{i}^{t}}}{\sum_{j\neq y}e^{z_{j}^{t}{\color[rgb]{1,0.5,0}-\eta^{\prime}(1+p_{j}^{t}-p_{i}^{t})}}+e^{z_{y}^{t}{\color[rgb]{1,0.5,0}-0}}}, \tag{38}
combining the fact that , we can derive and as the left part of Equation 35. Similarly, when , we have:
结合 ,可导出 与 如式 35 左部。类似地,当 时,有:
p_{i\neq y}^{t+1}=\frac{e^{z_{i}^{t+1}}}{\sum^{V}_{j=1}e^{z_{j}^{t+1}}}=\frac{e^{z_{i}^{t}-\eta^{\prime}p_{i}^{t}}}{\sum_{j\neq y}e^{z_{j}^{t}-\eta^{\prime}p_{j}^{t}}+e^{z_{y}^{t}-\eta^{\prime}p_{y}^{t}+\eta^{\prime}}}=\frac{e^{z_{i}^{t}}}{\sum_{j\neq y}e^{z_{j}^{t}{\color[rgb]{1,0.5,0}-\eta^{\prime}(p_{j}^{t}-p_{i}^{t})}}+e^{z_{y}^{t}{\color[rgb]{1,0.5,0}-\eta^{\prime}(p_{y}^{t}-p_{i}^{t}-1)}}}, \tag{39}
which leads to the right part of Equation 35.
由此得到式 35 右部。
∎
We can now better understand how each changes after this update. Specifically, if , the corresponding increases, and vice versa. To determine the value of , we can treat any as contributing to the conclusion that while any against it. The value of the corresponding and controls how strong the contribution is. With the preparations above, we derive the following observations on how the confidence evolves when a gradient ascent (i.e., ) is imposed on class .
现在可更好理解更新后每个 如何变化。具体地,若 ,对应 上升,反之亦然。为确定 的值,可将任何 视为支持「」的结论,任何 视为反对;对应 与 控制贡献强弱。有了上述准备,我们导出对类别 施加梯度上升(即 )时置信度如何演化的下列观察。
Claim 1: The value of is guaranteed to decrease, i.e., .
We start from the value of in Case 1 as illustrated in Equation 35. It is clear that for any , we have , because . Combining with , it is straightforward to have Claim 1.
论断 1: 保证下降,即 。
从式 35 情形 1 中 的值出发。显然对任意 有 ,因为 。再结合 ,立得论断 1。
Claim 2: The value of where is guaranteed to increase, i.e., .
We now use the value of in Case 2, since cannot equal by definition. When , we have for all possible , because is the largest among all of . Hence all must be smaller than one. Combining with the fact that (because must be negative), we can prove that .
论断 2:对 , 保证上升,即 。
现用情形 2 中 的值,因按定义 不能等于 。当 时,对所有可能 有 ,因为 是所有 中最大的。故所有 必小于 1。再结合 (因为 必为负),可证 。
The two claims above demonstrate that the parameter update can be imagined as taking the probability mass from and redistributing that to other dimensions. From Claim 2, we know some of the mass is guaranteed to be “squeezed” into the dimension with the highest (if is the highest value, then is the second highest in ). But how other changes is still not clear yet. Will the probability mass from is also split into other (i.e., other increases)? Or will absorb the mass not only from but also from other dimensions (i.e., other decreases)? To get a clearer picture, we need to track the adaptations of each . To achieve this, we now must scrutinize the distribution of , because it controls the value of for different . We chose three typical scenarios where is strictly uniform, slightly non-uniform, and extremely peaky, and leads to the following claims.
上述两论断表明:参数更新可想象为从 取走概率质量并再分配到其它维。由论断 2,部分质量保证被「挤压」到 最高的维(若 最高,则 为 中次高)。但其它 如何变化仍不清楚: 的概率质量是否也会分到其它 (即其它 上升)?抑或 不仅吸收来自 的质量、还吸收来自其它维的质量(即其它 下降)?为更清晰,需跟踪每个 的适应。为此必须审视 的分布,因为它控制不同 的 。我们选取三种典型情形: 严格均匀、略非均匀、极端尖峰,并导出下列论断。
Claim 3A: When is a uniform distribution, the probability mass decreased from class is uniformly distributed to all other , i.e., all increase the same value.
With the uniform assumption, Equation 34 can be simplified to . Note that the first two claims hold for any distribution , hence we only check the values of here to verify the “uniformly distributed mass” hypothesis. Substituting the values of to this new leads to for all . Since and , we must have . Combined with the fact that all are the same, this claim can be proved.
论断 3A:当 为均匀分布时,从类别 减少的概率质量均匀分配到所有其它 ,即所有 增加相同值。
在均匀 假设下,式 34 可简化为 。注意前两论断对任意分布 成立,故此处只检查 以验证「质量均匀分配」假说。将 代入新 ,对所有 得 。因 且 ,必有 。再结合所有 相同,可证该论断。
Claim 3B: When is slightly non-uniform, with smaller tend to decrease, and vice versa.
This claim is a general trend and might not have any guarantees. However, analyzing such a scenario helps us to understand the influence of better. Assume we are observing where is not nor . We consider two subsets of , i.e., , which contains all with and that contains all with . Now consider Case 2 in Equation 35, we have:
论断 3B:当 略非均匀时, 较小的 倾向于下降,反之亦然。
这是一般趋势,未必有严格保证。但分析该情形有助于更好理解 的影响。假设观察既非 也非 的 。考虑 的两个子集: 含所有满足 的 , 含所有满足 的 。现看式 35 情形 2,有:
Note that we misuse the notation to highlight the fact that would be much smaller than , because there is a negative one term in the exponential. With the above expression, we can imagine that if is relatively small, the size of would be large, which means there will be more contributing to the conclusion that . If the influence of is strong enough to override the influence of other (especially which is way smaller than other ), would be smaller than one and hence decreases. On the contrary, for those with relatively large , the terms becomes dominant and hence lead to , i.e., increases.
注意我们借用 记号强调: 会远小于 ,因为指数里有负的一项。由上式可想象:若 相对较小, 规模会较大,意味着有更多 支持「」的结论。若 的影响强到压过其它 (尤其远小于其它 的 ),则 会小于 1,从而 下降。反之,对那些 相对较大的 , 的项占主导,导致 ,即 上升。
In the analysis above, we assume is only slightly non-uniform (i.e., not so peaky), which means the values of different are relatively comparable. However, in practical machine learning systems like LLM’s finetuning, the distribution would be very non-uniform, which means most of the probability mass is obtained by a few dimensions. That is because the LLM’s vocabulary size is usually very large and the reasonable choice of the next word is only a small portion of the whole vocabulary. Thus we have the following claim to describe this practical scenario.
上文分析假设 仅略非均匀(即不太尖峰),意味着不同 的值相对可比。但在 LLM 微调等实际机器学习系统中, 会非常不均匀,即多数概率质量由少数维获得。因为 LLM 词表通常很大,而下一词的合理选择只占整个词表的一小部分。故有下列论断描述这一实际情形。
Claim 3C: When is very peaky, which means most of the probability mass is obtained by , then all other will decrease. In other words, the probability mass of all other is squeezed to .
We continue the analysis in Claim 3B but consider a more extreme influence on . For this peaky , we might have an very large that dominates . In other words, . Then for any we want to observe, the . In other words, the model’s predictions on all dimensions other than the one with the highest confidence in will decrease.
论断 3C:当 非常尖峰,即多数概率质量由 获得时,所有其它 都会下降。换言之,所有其它 的概率质量被挤压到 。
我们延续论断 3B 的分析,但考虑对 更极端的影响。对这种尖峰 ,可能有非常大的 主导 。换言之,。于是对任意想观察的 ,有 。换言之,模型在 中置信度最高维以外的所有维上的预测都会下降。
Last, we analyze the influence of to explain why “imposing a large negative gradient on the valley region” makes the squeezing effect more serious.
最后,我们分析 的影响,以解释为何「对谷底区域施加大负梯度」会使挤压效应更严重。
Claim 4: Smaller makes those non-max easier to decay, i.e., a stronger squeezing effect.
This is also a general trend that is observed in the experiments in Figure 20. Intuitively, since the model is already confident that cannot be the correct label (i.e., is very small), letting the model further decrease the prediction on does not make sense. We can also use the analysis above to understand how it happens. As illustrated in Equation 40, where the value of is decomposed into three subgroups. Recall the definition of , we know all contribute to the hypothesis that increases after this update, where the strength of this contribution is controlled by . Since a small means a small , the influence of is significantly weakened under this scenario. In other words, is more likely to occur for all possible , which means the squeezing effect (all decreases) becomes more serious.
论断 4:更小的 使那些非最大的 更容易衰减,即挤压效应更强。
这也是图 20 实验中观察到的一般趋势。直观上,模型已很确信 不可能是正确标签(即 很小),再让模型进一步降低对 的预测没有意义。亦可用上文分析理解其发生机制。如式 40 所示, 的值被分解为三个子组。回忆 的定义,可知所有 都支持「更新后 上升」的假说,贡献强度由 控制。由于 小意味着 小,此情形下 的影响被显著削弱。换言之,对所有可能 更可能出现 ,即挤压效应(所有 下降)更严重。
Claim 5: The learning rate with a larger absolute value and a larger feature norm will amplify all the trends, maybe more serious than our expectation.
Throughout our analysis, the equivalent learning rate is a shared scalar in all . Hence larger can amplify all the trends aforementioned. Furthermore, recall the shape of an exponential function , where a small change of (especially when ) will make changes a lot. Then the terms in Case 1 and in Case 2 will play a stronger role if we use a larger learning rate or the norm of features is larger.
论断 5:绝对值更大的学习率 与更大的特征范数 会放大所有趋势,或许比预期更严重。
贯穿分析,等效学习率 是所有 中的共享标量。故更大的 可放大前述所有趋势。此外,回忆指数函数 的形状:即便 小幅变化(尤其 时)也会使 变化很大。于是若使用更大学习率 或特征范数更大,情形 1 中的 与情形 2 中的 将扮演更强角色。
E.2 Verify the Squeezing Effect using a Simple Experiment
E.2 用简单实验验证挤压效应
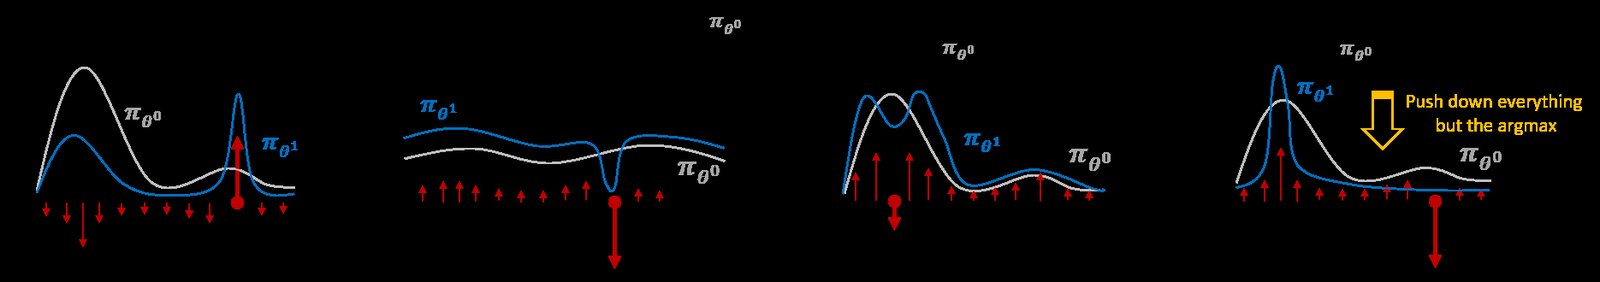
Figure 19: Illustration of how big positive and negative gradients influence the model’s prediction.
图 19:大的正、负梯度如何影响模型预测的示意。
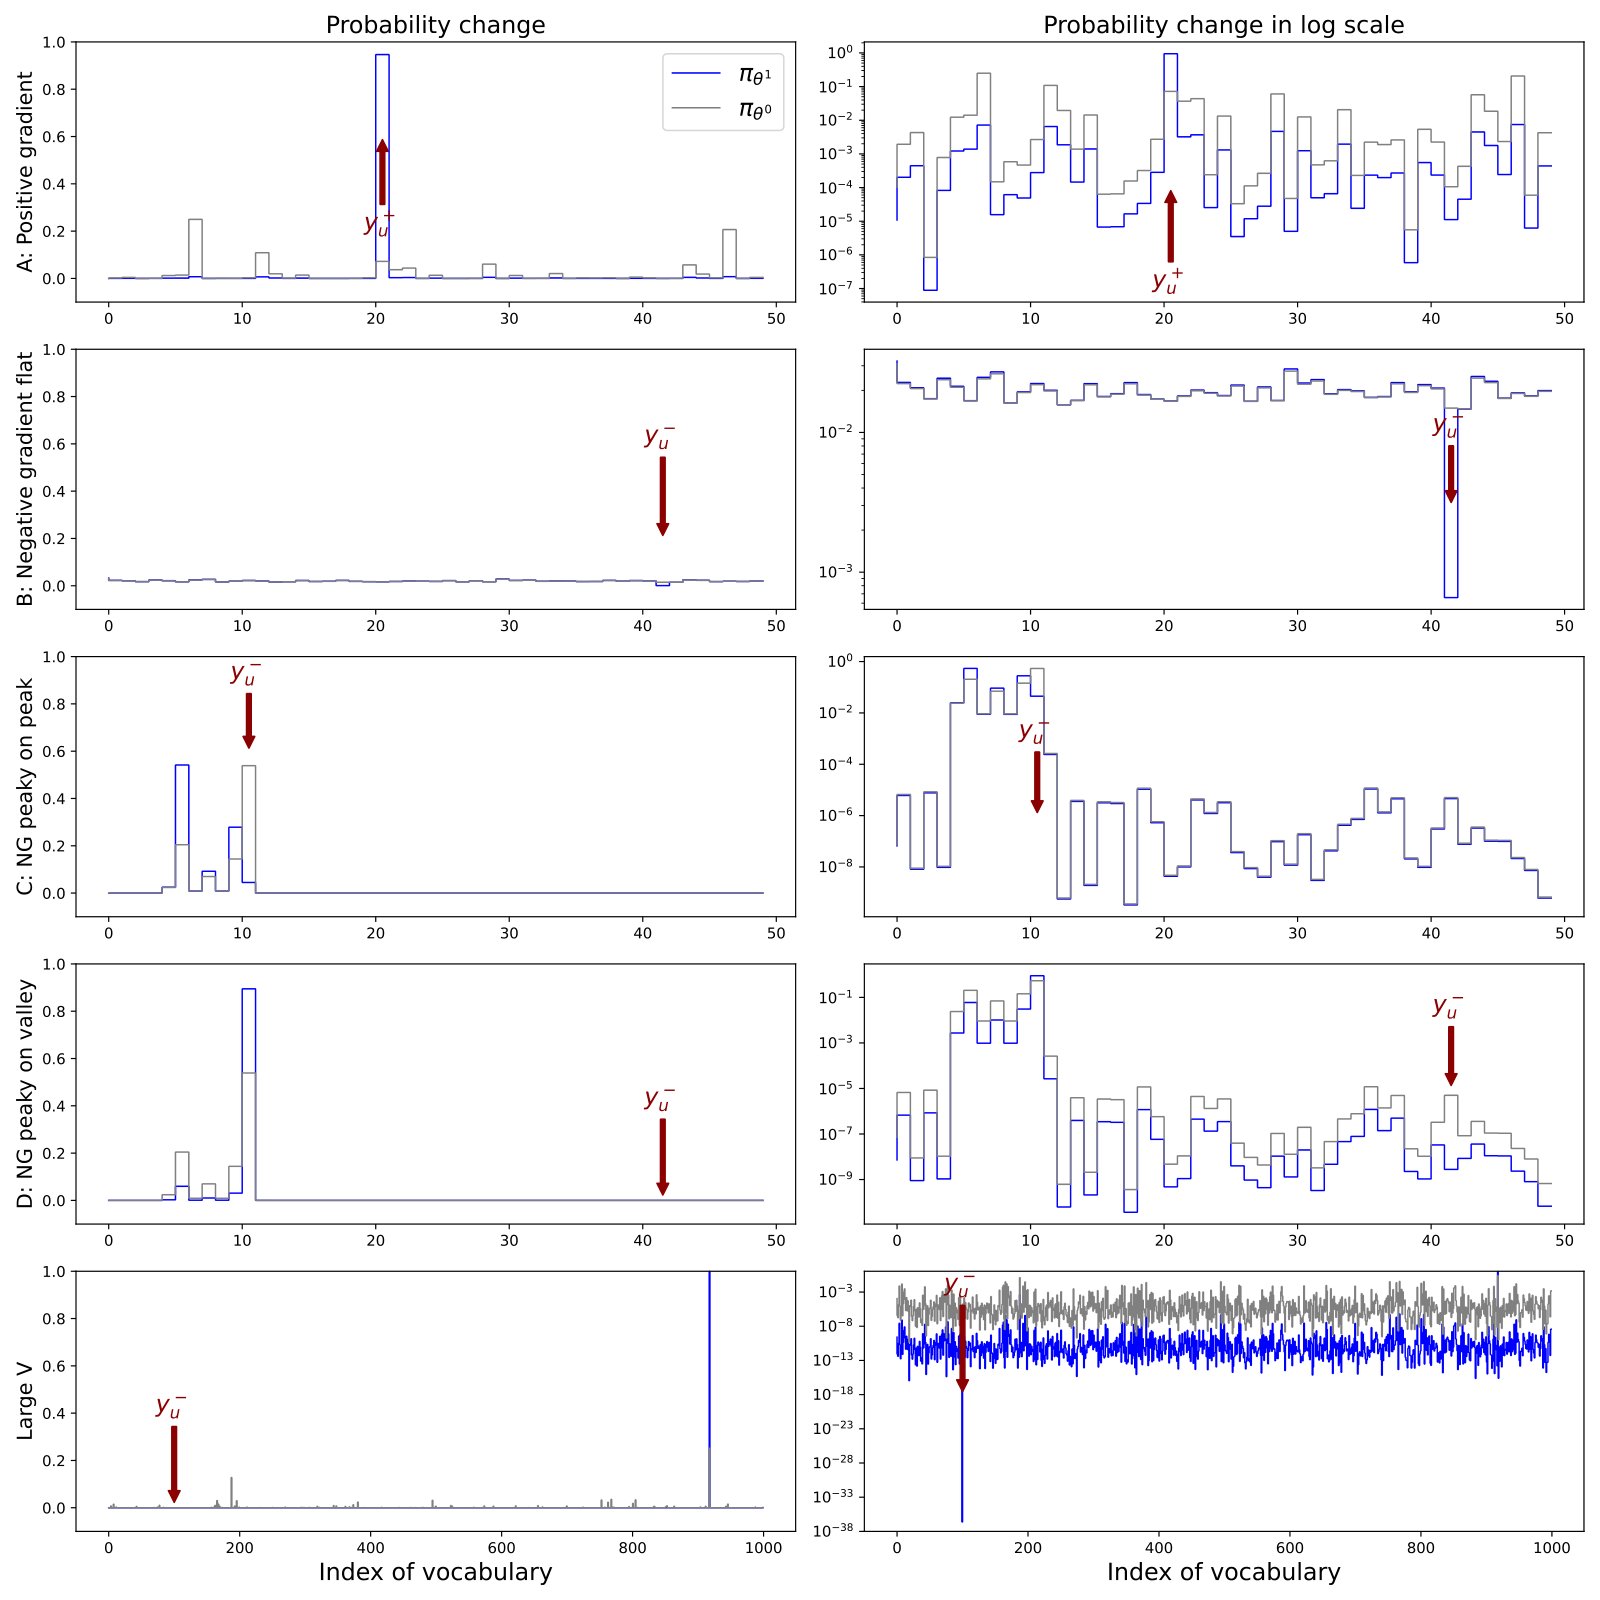
Figure 20: Experimental verification of the “squeezing effect” illustrated in Figure 19 using a simple multi-class logistic regression task.
图 20:用简单多类逻辑回归任务实验验证图 19 所示「挤压效应」。
Let us analyze a simple example to get an intuition. We set , , , and a randomly generated . In the first row of Figure 20, we consider the model updates its parameters using standard SGD assuming the label of this is 21. Specifically, we randomly generate by sampling each parameter from a standard Gaussian distribution and calculate using Equation 33. The two curves in each panel demonstrate the model’s predicted distribution before and after this update. As we expected, the positive vector on the 21st class “pull up” and “push down” all other at the same time. This trend is quite consistent under different settings (i.e., different choices of , etc.), which can be depicted by the first panel in Figure 19.
先分析一个简单例子以建立直觉。设 、、,并随机生成 。图 20 第一行中,假设该 的标签为 21,模型用标准 SGD 更新参数。具体地,从标准高斯分布采样各参数随机生成 ,并用式 33 计算 。每幅中两条曲线展示更新前后模型的预测分布。如预期,第 21 类上的正向量「拉高」,同时「压低」所有其它 。该趋势在不同设定下(即不同选择的 、、、、 等)相当一致,可由图 19 第一幅刻画。
We then set to simulate the negative gradient in DPO and consider three different settings. First, we assume the model’s prediction on is relatively flat, as demonstrated in the second row of Figure 20, where the predicting probability of every class is around 0.02. The negative gradient is imposed on , a randomly selected number. We see the negative adaptation vector “push down” heavily and re-assign those decreased probability mass evenly to all other classes, as illustrated in the second panel in Figure 19.
接着设 以模拟 DPO 中的负梯度,并考虑三种不同设定。首先假设模型对 的预测相对平坦,如图 20 第二行,每类预测概率约 0.02。负梯度施加在随机选取的 上。可见负适应向量大幅「压低」,并把下降的概率质量均匀再分配到所有其它类,如图 19 第二幅。
Although the behavior described above follows our intuitions well, a flat is not common in LLM’s finetuning. Because finetuning usually starts from a pre-trained , where the model’s prediction would likely be non-uniform. So in the third row of Figure 20, we consider a more practical that leads to a multi-mode . In this example, the model has relatively high confidence in classes 5 to 11 and low confidence in all other dimensions. We set the target label as 11 (i.e., the one in the model has the highest confidence) and use to “push down” the model’s prediction on this class. As demonstrated by the blue curve, decreases a lot as we expected. However, different from the flat case, where the model evenly assigns the reduced probability mass to all other , the model in this example “squeezes” the mass to those confident predictions, i.e., classes 6, 9, and 10, leaving the confidence of other classes almost unchanged. Such a trend is consistent when the negative gradient is imposed on the “peaky” region of a non-uniform distribution, as illustrated in the third panel in Figure 19.
尽管上述行为很符合直觉,平坦的 在 LLM 微调中并不常见——微调通常从预训练的 起步,模型预测很可能不均匀。故图 20 第三行考虑更实际的 ,导致多峰 。本例中模型对类别 5 到 11 置信度较高,对其它维较低。将目标标签设为 11(即模型置信度最高者),用 「压低」该类预测。如蓝曲线所示, 如预期大幅下降。但与平坦 情形中模型把减少的概率质量均匀分给所有其它 不同,本例中模型把质量「挤压」到那些自信预测上,即类别 6、9、10,其它类置信度几乎不变。只要负梯度施加在非均匀分布的「尖峰」区域,该趋势一致,如图 19 第三幅。
The previous setting simulates the on-policy DPO well, where the rejected examples are sampled from the high confidence region of the model’s predictions. Then, what will happen if we conduct off-policy DPO and impose a big negative gradient on those classes that already have very low confidence? See the fourth row of Figure 20, where we use the same and as in the previous case. The only difference is that we change the label of to 42, where is very small (roughly ) before training. The behavior in this setting is quite interesting: we first observe a big increase on , which means the model “squeezes” the probability mass to the most confident one in , similar to the previous setting. More interesting, the predictions on all other are heavily “pushed down”, even including classes 6, 9, and 10, whose confidence is relatively high before training. In the last two panels of Figure 20, we set and find this trend is more obvious (that might be because the absolute value of the efficient learning rate, which depends on , becomes larger). Since the vocabulary size of a common LLM is usually more than 50k, the squeezing effect in real systems would be non-negligible even if the learning rate is small. Such a trend is also quite consistent as long as we impose a big negative gradient on the “valley” region of the model’s prediction, as illustrated in the last panel in Figure 19. Now we can answer the question of why all observing decreases and where the probability mass has gone:
上一设定很好模拟了 on-policy DPO:拒绝样本 从模型预测的高置信区域采样。那么,若做 off-policy DPO,对那些本已置信度很低的类施加大负梯度,会发生什么?见图 20 第四行,使用与上一情形相同的 与 ,唯一差别是把 的标签改为 42,训练前 很小(约 )。该设定下的行为相当有趣:首先观察到 大幅上升,意味着模型把概率质量「挤压」到 中最自信的那一类,类似上一设定。更有趣的是,所有其它 上的预测都被大幅「压低」,甚至包括训练前置信度相对较高的类别 6、9、10。图 20 后两幅设 ,发现该趋势更明显(或许因为依赖 的有效学习率绝对值变大)。由于常见 LLM 词表通常超过 5 万,即便学习率很小,真实系统中的挤压效应也不可忽视。只要对模型预测的「谷底」区域施加大负梯度,该趋势就相当一致,如图 19 末幅。现在可以回答为何所有观测到的 都下降、以及概率质量去哪了:
For each token, the probability mass is squeezed to the one with the highest confidence.
对每个 token,概率质量被挤压到置信度最高的那一个上。
Note that the tokens with the highest confidence do not necessarily form a preferred response: it just reinforces the prior knowledge contained in , which could be a drawback for off-policy DPO.
注意,置信度最高的 token 未必构成偏好回复:它只是强化 中的先验知识,这可能是 off-policy DPO 的一个缺陷。
The hypothesis above is not only supported by this simple logistic regression problem but also by many consistent trends in LLM’s finetuning experiments. First, by comparing the average decaying speed of the when the model SFT different epochs before DPO (in Figure 17), we notice that longer SFT leads to a more peaky and hence leads to a faster decaying speed of all non-argmax responses. That is because the longer SFT stage will eventually push down more. Hence in the DPO stage, the big negative gradient is imposed on a deeper valley region, which makes the squeezing effect stronger. Second, to directly verify this hypothesis, we track the sum of the log-likelihood of the tokens with the largest confidence and call it “argmax confidence”, i.e., . As illustrated in the last panel in Figure 4, the argmax confidence keeps increasing while all other decreases: the missing probability mass is found! Last, in the dataset-extension method we proposed in Section 4.3 and Appendix F, we train the model using both and during SFT to also “pull up” the region before conducting DPO. Then, we observe compared with the standard training flow, i.e., SFT using first and then DPO, the proposed flow has a lower “argmax confidence” during DPO. That is because we pulled up during the modified SFT stage, the big negative gradient is then imposed on the peaky region rather than the valley region of the model’s prediction. Such a change in turn weakens the squeezing effect, as illustrated in Figure 5.
上述假说不仅由这一简单逻辑回归问题支持,也被 LLM 微调实验中许多一致趋势支持。首先,比较 DPO 前模型 SFT 不同 epoch 时 的平均衰减速度(图 17),注意到更长 SFT 导致更尖峰的 ,从而所有非 argmax 回复衰减更快——因为更长 SFT 最终会把 压得更低,于是 DPO 阶段大负梯度施加在更深的谷底区域,挤压效应更强。其次,为直接验证该假说,我们跟踪置信度最大的那些 token 的对数似然之和,称为「argmax 置信度」,即 。如图 4 末幅,argmax 置信度持续上升,而所有其它 下降:失踪的概率质量找到了!最后,在第 4.3 节与附录 F 所提的数据集扩充方法中,我们在 SFT 期间同时用 与 训练,以便在做 DPO 前也「拉高」 区域。随后观察到:相对标准训练流程(先用 做 SFT 再 DPO),所提流程在 DPO 中有更低的「argmax 置信度」。因为我们在修改后的 SFT 阶段拉高了 ,大负梯度便施加在模型预测的尖峰区域而非谷底区域;这一变化反过来削弱了挤压效应,如图 5 所示。
Appendix F A Simple Method to Improve Alignment
附录 F 一种改进对齐的简单方法
F.1 Pinpointing the drawback of off-policy DPO
F.1 定位 off-policy DPO 的缺陷
Based on our observations and analysis above, we speculate that “imposing big negative gradients on the valley region” is one of the bottlenecks of off-policy RL-free methods. Starting from this hypothesis, we believe introducing on-policy sampling has the potential to mitigate this problem, as demonstrated in SPIN (Chen et al. 2024a) and other online algorithms (Guo et al. 2024c). However, we also speculate that these methods improve the model’s performance not only by mitigating the squeezing effect. Hence to figure out to what extent the squeezing effect can harm the model’s performance, we propose a simple yet effective method to isolate its influence. As this method can directly mitigate this effect, it can also be considered as an ablation study of this interesting phenomenon.
基于上述观察与分析,我们推测「对谷底区域施加大负梯度」是 off-policy 免 RL 方法的瓶颈之一。从该假说出发,我们相信引入 on-policy 采样有望缓解该问题,如 SPIN(Chen et al. 2024a)及其它在线算法(Guo et al. 2024c)所示。但我们也推测这些方法提升模型表现不仅靠缓解挤压效应。为弄清挤压效应能在多大程度上损害模型表现,我们提出一种简单有效的方法以隔离其影响。由于该方法可直接缓解该效应,亦可视为对该有趣现象的消融研究。
Figure 21: Illustration of the proposed method and baseline. “E” is short for the “dataset extension”.
图 21:所提方法与基线的示意。「E」为「数据集扩充」(dataset extension)的缩写。
F.2 A simple method inspired by learning dynamics
F.2 由学习动力学启发的简单方法
As illustrated in Figure 21, where the baseline method is a standard SFT-then-DPO pipeline. The proposed method is very simple. We only need to augment the dataset used in SFT by adding pairs for each sample into it. All other settings are unchanged. The motivation for this method is also quite simple: as SFT can pull up the region of supervised and we don’t want the model to impose big negative gradients on a valley region, we can just pull up those before DPO. Furthermore, as demonstrated in the third panel in Figure 19 and Equation 15, the negative gradient in DPO would be strong enough to push down , because the gradient will be large if the model cannot separate and well. In other words, under DPO’s loss, there is no need to worry about the model overfitting those during SFT.
如图 21,基线方法是标准的先 SFT 再 DPO 流程。所提方法非常简单:只需把每个样本的 对加入 SFT 所用数据集加以扩充,其它设定不变。动机也很简单:既然 SFT 能拉高被监督的 \hat{\bm{\mathsf{y}} 区域,而我们不希望模型对谷底区域施加大负梯度,就可以在 DPO 前先拉高那些 。此外,如图 19 第三幅与式 15 所示,DPO 中的负梯度会强到足以压低 ,因为若模型不能很好区分 与 ,梯度会很大。换言之,在 DPO 损失下,不必担心模型在 SFT 中过拟合那些 。
(a) Result on Antropic-HH.
(a) Antropic-HH 上的结果。
F.3 Experimental verification
F.3 实验验证
To verify our analysis, we conduct experiments by finetuning a pretrained Qwen1.5-1.8B (Bai et al. 2023a) model using Antropic-HH dataset (Bai et al. 2022a) (we use a subset containing 5000 random examples from the training split). The pipelines of different methods are demonstrated in Figure 21. In this experiment, we call the pretrained model (and , which is identical to ), which is an official checkpoint pretrained by Bai et al. 2023a. Model and are the ones after SFT, which are different for these two methods. Model and are the models finetuned using DPO for 2/4/6 epochs. All the settings (except the starting model) of the DPO stage are the same for these two methods.
为验证分析,我们在 Antropic-HH 数据集(Bai et al. 2022a)上微调预训练的 Qwen1.5-1.8B(Bai et al. 2023a)(使用训练划分中 5000 条随机样本的子集)。不同方法的流程见图 21。本实验中,称预训练模型为 (与 相同,即 Bai et al. 2023a 官方检查点)。 与 为 SFT 后的模型,两种方法不同。 与 为再用 DPO 微调 2/4/6 个 epoch 的模型。除起点模型外,两方法 DPO 阶段全部设定相同。
We first observe the learning dynamics of these two methods in Figure 5, where all the trends support our analysis quite well. See the first two panels that compare and respectively. It is clear that these two methods have an almost identical curve on in the SFT stage but behave quite differently on : because we directly train the model using in the proposed method. Then, after the SFT stage, we conduct DPO using identical settings for these two methods. From the first three panels, we can observe the decay speed of all curves of the proposed method is smaller than its counterpart in the baseline. That is the benefit introduced by “pulling up” the region before conducting DPO. With this specific design, the big negative gradients in DPO are imposed on the peaky region (the behavior is like the third panel in Figure 19) rather than the valley region (see the fourth panel), hence the squeezing effect is successfully restrained. The results in the last panel of Figure 5 are also a strong verification of the whole picture. During the SFT stage, the observed “argmax-probability” of the proposed method is higher than the baseline, because we impose twice “pull up” pressure, i.e., those for , compared with the baseline. However, at the beginning of DPO, we observe a clear drop in the orange curve. That is because the negative gradients are exactly imposed on those (in the second panel of Figure 5, is already very high). Furthermore, at the end of DPO, we see the “argmax-probability” of the proposed method is significantly lower than the baseline setting, which implies that the squeezing effect is restrained in our setting.
我们首先在图 5 观察两方法的学习动力学,所有趋势都很好支持分析。见比较 与 的前两幅:两方法在 SFT 阶段对 几乎有相同曲线,但对 行为很不同——因为所提方法直接用 训练模型。SFT 之后,两方法用相同设定做 DPO。从前三幅可见,所提方法所有曲线的衰减速度都小于基线对照。这正是在做 DPO 前「拉高」 区域带来的收益。有了这一特定设计,DPO 中的大负梯度施加在尖峰区域(行为如图 19 第三幅)而非谷底区域(见第四幅),从而成功抑制挤压效应。图 5 末幅结果也是对全貌的有力验证。SFT 阶段,所提方法观测到的「argmax 概率」高于基线,因为我们施加了两倍「拉高」压力,即那些针对 的压力。但在 DPO 开始时,橙曲线出现明显下降——因为负梯度正好施加在那些 上(图 5 第二幅中 已经很高)。此外,DPO 结束时,所提方法的「argmax 概率」显著低于基线设定,意味着我们的设定中挤压效应被抑制。
In order to figure out whether the model trained using the proposed flow, which successfully restrains the squeezing effect, indeed does alignment better, we conduct pair-wise comparisons of these models’ responses and report their win rate as in (Rafailov et al. 2023a). Specifically, we first randomly select 1000 test questions from the test split of Antropic-HH and generate 1000 responses by feeding the prompts to each of these models (we use the default sampling setting provided in (Rafailov et al. 2023a)). Then, with the prompt template provided in Figure 23, we evaluate the win rate of the responses pairs using GPT3.5-Turbo and Claude3-Haiku. Here we report the average win rate of different comparisons (the degenerated responses are not compared, so the number of compared examples is slightly smaller than 1000). Note that a win rate greater than 0.5 means the method that comes first is preferred by the evaluator.
为弄清用成功抑制挤压效应的所提流程训练的模型是否确实对齐更好,我们对这些模型的回复做成对比较,并按 Rafailov et al. 2023a 报告胜率。具体地,先从 Antropic-HH 测试划分随机选 1000 个测试问题,将提示输入各模型生成 1000 条回复(使用 Rafailov et al. 2023a 提供的默认采样设定)。然后用图 23 提供的提示模板,以 GPT3.5-Turbo 与 Claude3-Haiku 评估回复对的胜率。此处报告不同比较的平均胜率(退化回复不参与比较,故比较例数略少于 1000)。注意胜率大于 0.5 表示排在前面的方法更受评估者偏好。
- Compare models after SFT: v.s. , win rate is 0.4729 and 0.4679;
- Demonstrate benefits of DPO: a. v.s. , win rate is 0.6727 and 0.6411; b. v.s. , win rate is 0.6898 and 0.7321;
- Compare the proposed method and baseline after DPO for different epochs: a. v.s. , win rate is 0.6518 and 0.5151; b. v.s. , win rate is 0.6928 and 0.6045; c. v.s. , win rate is 0.6667 and 0.5432;
- Compare the best with other 2 checkpoints: a. v.s. , win rate is 0.6853 and 0.5517; b. v.s. , win rate is 0.6324 and 0.5316;
- 比较 SFT 后模型: 对 ,胜率分别为 0.4729 与 0.4679;
- 展示 DPO 收益:a. 对 ,胜率 0.6727 与 0.6411;b. 对 ,胜率 0.6898 与 0.7321;
- 比较不同 epoch DPO 后所提方法与基线:a. 对 ,胜率 0.6518 与 0.5151;b. 对 ,胜率 0.6928 与 0.6045;c. 对 ,胜率 0.6667 与 0.5432;
- 比较最佳 与其它两个检查点:a. 对 ,胜率 0.6853 与 0.5517;b. 对 ,胜率 0.6324 与 0.5316;
In the first comparison, we find the model trained using both and loses more (win rate is smaller than 0.5), which makes sense because assigns higher probabilities on those less preferred responses. In the second comparison, the model fine-tuned using DPO indeed aligns with human value better. The win rate of the proposed method is slightly higher, which might also be explained as leaving more space for improvement. Hence we then directly compare the models after DPO in these two methods in the third group. In this group, all models in the proposed method win the baseline counterparts by a large margin, which demonstrates the effectiveness of our proposed method. Furthermore, we find the evaluation made by Claude is more reserved compared with GPT (the numbers are smaller). However, the trends among the comparisons in this group are consistent: brings the largest improvement, which is potentially the best model. This fact is verified in the fourth group comparison, where we evaluate against and . The results demonstrate that both a too-long or too-short finetuning stage using DPO is not the best choice.
第一组比较中,发现同时用 与 训练的模型输得更多(胜率小于 0.5),这说得通,因为 在那些较不偏好回复上分配了更高概率。第二组比较中,用 DPO 微调的模型确实与人类价值对齐更好。所提方法胜率略高,或也可解释为 留下了更多改进空间。于是第三组直接比较两方法 DPO 后的模型。该组中,所提方法的所有模型都以大幅优势胜过基线对照,说明所提方法有效。此外,发现 Claude 的评估相对 GPT 更保守(数值更小)。但该组比较中的趋势一致: 带来最大提升,可能是最佳模型。第四组比较验证了这一点:我们评估 对 与 。结果表明,用 DPO 微调过久或过短都不是最佳选择。
Figure 23: Prompt used for evaluating model’s response (from (Rafailov et al. 2023a)), an example feedback from GPT3.5-turbo, and two examples of the “degenerate” effect described in Holtzman et al. 2020a. Although both and inevitably generate such degenerate responses, we find this phenomenon is less common in the proposed method.
图 23:评估模型回复所用提示(来自 Rafailov et al. 2023a)、GPT3.5-turbo 的反馈示例,以及 Holtzman et al. 2020a 所述「退化」效应的两个例子。尽管 与 都不可避免地生成此类退化回复,我们发现该现象在所提方法中较少见。