Layer Normalization
Layer Normalization
Jimmy Lei Ba Affiliation: University of Toronto Email: jimmy@psi.toronto.edu Jamie Ryan Kiros Affiliation: University of Toronto Email: rkiros@cs.toronto.edu Geoffrey E. Hinton Affiliation: University of Toronto Affiliation: and Google Inc. Email: hinton@cs.toronto.edu
Abstract
摘要
Training state-of-the-art, deep neural networks is computationally expensive. One way to reduce the training time is to normalize the activities of the neurons. A recently introduced technique called batch normalization uses the distribution of the summed input to a neuron over a mini-batch of training cases to compute a mean and variance which are then used to normalize the summed input to that neuron on each training case. This significantly reduces the training time in feed-forward neural networks. However, the effect of batch normalization is dependent on the mini-batch size and it is not obvious how to apply it to recurrent neural networks. In this paper, we transpose batch normalization into layer normalization by computing the mean and variance used for normalization from all of the summed inputs to the neurons in a layer on a single training case. Like batch normalization, we also give each neuron its own adaptive bias and gain which are applied after the normalization but before the non-linearity. Unlike batch normalization, layer normalization performs exactly the same computation at training and test times. It is also straightforward to apply to recurrent neural networks by computing the normalization statistics separately at each time step. Layer normalization is very effective at stabilizing the hidden state dynamics in recurrent networks. Empirically, we show that layer normalization can substantially reduce the training time compared with previously published techniques.
训练前沿深度神经网络在计算上代价很高。缩短训练时间的途径之一是对神经元活动做归一化。近期提出的批归一化(batch normalization)利用一个 mini-batch 训练样本上、某个神经元加总输入的分布来计算均值与方差,再用它们对该神经元在每条训练样本上的加总输入做归一化。这在前馈网络中显著缩短了训练时间。然而,批归一化的效果依赖 mini-batch 大小,且如何施加到循环神经网络并不显然。本文将批归一化改写为层归一化(layer normalization):用于归一化的均值与方差,来自单条训练样本上某一层全部神经元的加总输入。与批归一化一样,我们也为每个神经元配备自适应的偏置与增益,在归一化之后、非线性之前施加。与批归一化不同,层归一化在训练与测试时执行完全相同的计算;把它用到循环网络也很直接——在每个时间步单独计算归一化统计量。层归一化对稳定循环网络中的隐状态动态非常有效。经验上,我们表明相对此前发表的技术,层归一化能大幅缩短训练时间。
1 Introduction
1 引言
Deep neural networks trained with some version of Stochastic Gradient Descent have been shown to substantially outperform previous approaches on various supervised learning tasks in computer vision [Krizhevsky et al. 2012] and speech processing [Hinton et al. 2012]. But state-of-the-art deep neural networks often require many days of training. It is possible to speed-up the learning by computing gradients for different subsets of the training cases on different machines or splitting the neural network itself over many machines [Dean et al. 2012], but this can require a lot of communication and complex software. It also tends to lead to rapidly diminishing returns as the degree of parallelization increases. An orthogonal approach is to modify the computations performed in the forward pass of the neural net to make learning easier. Recently, batch normalization [Ioffe and Szegedy 2015] has been proposed to reduce training time by including additional normalization stages in deep neural networks. The normalization standardizes each summed input using its mean and its standard deviation across the training data. Feedforward neural networks trained using batch normalization converge faster even with simple SGD. In addition to training time improvement, the stochasticity from the batch statistics serves as a regularizer during training.
用某种随机梯度下降训练的深度神经网络,已在计算机视觉 [Krizhevsky et al. 2012] 与语音处理 [Hinton et al. 2012] 等多种监督学习任务上大幅超越先前方法。但前沿深度网络常常需要许多天才能训完。可以在不同机器上为不同训练子集算梯度,或把网络本身拆到多台机器上 [Dean et al. 2012] 来加速,但这往往需要大量通信与复杂软件,且并行度提高后收益迅速递减。另一条正交思路是改前向计算,让学习更容易。近期,批归一化 [Ioffe and Szegedy 2015] 通过在深度网络中加入额外归一化阶段来缩短训练时间:用训练数据上的均值与标准差标准化每个加总输入。即使用简单 SGD,带批归一化的前馈网也收敛更快;此外,来自 batch 统计量的随机性在训练中还起到正则作用。
Despite its simplicity, batch normalization requires running averages of the summed input statistics. In feed-forward networks with fixed depth, it is straightforward to store the statistics separately for each hidden layer. However, the summed inputs to the recurrent neurons in a recurrent neural network (RNN) often vary with the length of the sequence so applying batch normalization to RNNs appears to require different statistics for different time-steps. Furthermore, batch normalization cannot be applied to online learning tasks or to extremely large distributed models where the minibatches have to be small.
尽管形式简单,批归一化需要加总输入统计量的跑动平均。在深度固定的前馈网中,为每个隐层分别存统计量很直接。然而 RNN 中循环神经元的加总输入常随序列长度变化,把批归一化用到 RNN 上似乎需要为不同时间步准备不同统计量。此外,批归一化无法用于在线学习,或 mini-batch 必须很小的超大规模分布式模型。
This paper introduces layer normalization, a simple normalization method to improve the training speed for various neural network models. Unlike batch normalization, the proposed method directly estimates the normalization statistics from the summed inputs to the neurons within a hidden layer so the normalization does not introduce any new dependencies between training cases. We show that layer normalization works well for RNNs and improves both the training time and the generalization performance of several existing RNN models.
本文提出层归一化,一种提升多种神经网络模型训练速度的简单归一化方法。与批归一化不同,该方法直接从同一隐层内各神经元的加总输入估计归一化统计量,因而不会在训练样本之间引入新的依赖。我们表明层归一化对 RNN 效果很好,并能同时改善若干现有 RNN 模型的训练时间与泛化表现。
2 Background
2 背景
A feed-forward neural network is a non-linear mapping from a input pattern to an output vector . Consider the hidden layer in a deep feed-forward, neural network, and let be the vector representation of the summed inputs to the neurons in that layer. The summed inputs are computed through a linear projection with the weight matrix and the bottom-up inputs given as follows:
前馈神经网络是从输入模式 到输出向量 的非线性映射。考虑深度前馈网络中的第 个隐层,令 为该层神经元加总输入的向量表示。加总输入由权重矩阵 与自下而上的输入 经线性投影得到:
where is an element-wise non-linear function and is the incoming weights to the hidden units and is the scalar bias parameter. The parameters in the neural network are learnt using gradient-based optimization algorithms with the gradients being computed by back-propagation.
其中 是逐元素非线性, 是第 个隐单元的入边权重, 是标量偏置。网络参数用基于梯度的优化算法学习,梯度由反向传播计算。
One of the challenges of deep learning is that the gradients with respect to the weights in one layer are highly dependent on the outputs of the neurons in the previous layer especially if these outputs change in a highly correlated way. Batch normalization [Ioffe and Szegedy 2015] was proposed to reduce such undesirable “covariate shift”. The method normalizes the summed inputs to each hidden unit over the training cases. Specifically, for the summed input in the layer, the batch normalization method rescales the summed inputs according to their variances under the distribution of the data
深度学习的挑战之一是:某一层权重的梯度高度依赖前一层神经元的输出,尤其当这些输出高度相关地变化时。批归一化 [Ioffe and Szegedy 2015] 被提出以减轻这种不良的“协变量偏移”。该方法在训练样本上对每个隐单元的加总输入做归一化。具体地,对第 层第 个加总输入,批归一化按其在数据分布下的方差重新缩放加总输入:
where is normalized summed inputs to the hidden unit in the layer and is a gain parameter scaling the normalized activation before the non-linear activation function. Note the expectation is under the whole training data distribution. It is typically impractical to compute the expectations in Eq. (2) exactly, since it would require forward passes through the whole training dataset with the current set of weights. Instead, and are estimated using the empirical samples from the current mini-batch. This puts constraints on the size of a mini-batch and it is hard to apply to recurrent neural networks.
其中 是第 层第 个隐单元归一化后的加总输入, 是在非线性激活之前缩放归一化激活的增益参数。注意期望是在整个训练数据分布下取的。精确计算式 (2) 中的期望通常不现实,因为需要用当前权重对整个训练集做前向。实践中用当前 mini-batch 的经验样本估计 与 。这对 mini-batch 大小构成约束,也难以用于循环神经网络。
3 Layer normalization
3 层归一化
We now consider the layer normalization method which is designed to overcome the drawbacks of batch normalization.
我们现在讨论旨在克服批归一化缺陷的层归一化方法。
Notice that changes in the output of one layer will tend to cause highly correlated changes in the summed inputs to the next layer, especially with ReLU units whose outputs can change by a lot. This suggests the “covariate shift” problem can be reduced by fixing the mean and the variance of the summed inputs within each layer. We, thus, compute the layer normalization statistics over all the hidden units in the same layer as follows:
注意,一层输出的变化往往会引起下一层加总输入高度相关的变化,尤其是输出可大幅跳动的 ReLU 单元。这表明,通过固定每层内加总输入的均值与方差,可以减轻“协变量偏移”。因此,我们在同一层全部隐单元上计算层归一化统计量如下:
where denotes the number of hidden units in a layer. The difference between Eq. (2) and Eq. (3) is that under layer normalization, all the hidden units in a layer share the same normalization terms and , but different training cases have different normalization terms. Unlike batch normalization, layer normaliztion does not impose any constraint on the size of a mini-batch and it can be used in the pure online regime with batch size 1.
其中 表示一层中的隐单元数。式 (2) 与式 (3) 的差别在于:层归一化下,同一层所有隐单元共享同一组归一化项 与 ,但不同训练样本有不同的归一化项。与批归一化不同,层归一化不对 mini-batch 大小施加任何约束,并可在 batch size 为 1 的纯在线设定下使用。
3.1 Layer normalized recurrent neural networks
3.1 层归一化的循环神经网络
The recent sequence to sequence models [Sutskever et al. 2014] utilize compact recurrent neural networks to solve sequential prediction problems in natural language processing. It is common among the NLP tasks to have different sentence lengths for different training cases. This is easy to deal with in an RNN because the same weights are used at every time-step. But when we apply batch normalization to an RNN in the obvious way, we need to to compute and store separate statistics for each time step in a sequence. This is problematic if a test sequence is longer than any of the training sequences. Layer normalization does not have such problem because its normalization terms depend only on the summed inputs to a layer at the current time-step. It also has only one set of gain and bias parameters shared over all time-steps.
近期的序列到序列模型 [Sutskever et al. 2014] 用紧凑的循环神经网络解决自然语言处理中的序列预测问题。NLP 任务中不同训练样本的句子长度往往不同。在 RNN 里这容易处理,因为每个时间步共用同一套权重。但若按显而易见的方式把批归一化用到 RNN 上,就需要为序列中每个时间步分别计算并存储统计量;若测试序列比任何训练序列都长,就会出问题。层归一化没有这一问题,因为它的归一化项只依赖当前时间步该层的加总输入;并且增益与偏置参数只有一套,在所有时间步共享。
In a standard RNN, the summed inputs in the recurrent layer are computed from the current input and previous vector of hidden states which are computed as . The layer normalized recurrent layer re-centers and re-scales its activations using the extra normalization terms similar to Eq. (3):
在标准 RNN 中,循环层的加总输入由当前输入 与上一隐状态向量 计算:。层归一化循环层用与式 (3) 类似的额外归一化项对其激活重新居中与重新缩放:
where is the recurrent hidden to hidden weights and are the bottom up input to hidden weights. is the element-wise multiplication between two vectors. and are defined as the bias and gain parameters of the same dimension as .
其中 是隐到隐的循环权重, 是自下而上的输入到隐权重。 表示两向量的逐元素乘。 与 定义为与 同维的偏置与增益参数。
In a standard RNN, there is a tendency for the average magnitude of the summed inputs to the recurrent units to either grow or shrink at every time-step, leading to exploding or vanishing gradients. In a layer normalized RNN, the normalization terms make it invariant to re-scaling all of the summed inputs to a layer, which results in much more stable hidden-to-hidden dynamics.
在标准 RNN 中,循环单元加总输入的平均幅度往往每步增长或缩小,导致梯度爆炸或消失。在层归一化 RNN 中,归一化项使模型对整层加总输入的整体缩放不变,从而得到稳定得多的隐到隐动态。
4 Related work
4 相关工作
Batch normalization has been previously extended to recurrent neural networks [Laurent et al. 2015, Amodei et al. 2015, Cooijmans et al. 2016]. The previous work [Cooijmans et al. 2016] suggests the best performance of recurrent batch normalization is obtained by keeping independent normalization statistics for each time-step. The authors show that initializing the gain parameter in the recurrent batch normalization layer to 0.1 makes significant difference in the final performance of the model. Our work is also related to weight normalization [Salimans and Kingma 2016]. In weight normalization, instead of the variance, the L2 norm of the incoming weights is used to normalize the summed inputs to a neuron. Applying either weight normalization or batch normalization using expected statistics is equivalent to have a different parameterization of the original feed-forward neural network. Re-parameterization in the ReLU network was studied in the Path-normalized SGD [Neyshabur et al. 2015]. Our proposed layer normalization method, however, is not a re-parameterization of the original neural network. The layer normalized model, thus, has different invariance properties than the other methods, that we will study in the following section.
批归一化此前已被扩展到循环神经网络 [Laurent et al. 2015, Amodei et al. 2015, Cooijmans et al. 2016]。先前工作 [Cooijmans et al. 2016] 指出,循环批归一化的最佳表现来自为每个时间步保留独立的归一化统计量;作者还表明把循环批归一化层的增益参数初始化为 0.1 对最终表现影响显著。我们的工作也与权重归一化 [Salimans and Kingma 2016] 相关:权重归一化不用方差,而用入边权重的 L2 范数来归一化神经元的加总输入。用期望统计量施加权重归一化或批归一化,等价于对原始前馈网络的一种不同参数化。ReLU 网络中的再参数化曾在 Path-normalized SGD [Neyshabur et al. 2015] 中研究。我们提出的层归一化方法则不是原始网络的再参数化,因而具有与其他方法不同的不变性,下一节将加以研究。
5 Analysis
5 分析
In this section, we investigate the invariance properties of different normalization schemes.
本节考察不同归一化方案的不变性。
5.1 Invariance under weights and data transformations
5.1 权重与数据变换下的不变性
The proposed layer normalization is related to batch normalization and weight normalization. Although, their normalization scalars are computed differently, these methods can be summarized as normalizing the summed inputs to a neuron through the two scalars and . They also learn an adaptive bias and gain for each neuron after the normalization.
所提出的层归一化与批归一化、权重归一化相关。尽管归一化标量的计算方式不同,这些方法都可概括为:用两个标量 与 归一化神经元的加总输入 ,并在归一化后为每个神经元学习自适应偏置 与增益 。
Note that for layer normalization and batch normalization, and is computed according to Eq. 2 and 3. In weight normalization, is 0, and .
注意对层归一化与批归一化, 与 分别按式 2 与 3 计算。在权重归一化中, 为 0,。
Table 1 highlights the following invariance results for three normalization methods.
表 1 汇总了三种归一化方法的下列不变性结果。
| Weight matrix | Weight matrix | Weight vector | Dataset | Dataset | Single training case | |
|---|---|---|---|---|---|---|
| re-scaling | re-centering | re-scaling | re-scaling | re-centering | re-scaling | |
| Batch norm | Invariant | No | Invariant | Invariant | Invariant | No |
| Weight norm | Invariant | No | Invariant | No | No | No |
| Layer norm | Invariant | Invariant | No | Invariant | No | Invariant |
Table 1: Invariance properties under the normalization methods.
| 权重矩阵 | 权重矩阵 | 权重向量 | 数据集 | 数据集 | 单条训练样本 | |
|---|---|---|---|---|---|---|
| 缩放 | 居中 | 缩放 | 缩放 | 居中 | 缩放 | |
| Batch norm | 不变 | 否 | 不变 | 不变 | 不变 | 否 |
| Weight norm | 不变 | 否 | 不变 | 否 | 否 | 否 |
| Layer norm | 不变 | 不变 | 否 | 不变 | 否 | 不变 |
表 1:各归一化方法下的不变性。
Weight re-scaling and re-centering: First, observe that under batch normalization and weight normalization, any re-scaling to the incoming weights of a single neuron has no effect on the normalized summed inputs to a neuron. To be precise, under batch and weight normalization, if the weight vector is scaled by , the two scalar and will also be scaled by . The normalized summed inputs stays the same before and after scaling. So the batch and weight normalization are invariant to the re-scaling of the weights. Layer normalization, on the other hand, is not invariant to the individual scaling of the single weight vectors. Instead, layer normalization is invariant to scaling of the entire weight matrix and invariant to a shift to all of the incoming weights in the weight matrix. Let there be two sets of model parameters , whose weight matrices and differ by a scaling factor and all of the incoming weights in are also shifted by a constant vector , that is . Under layer normalization, the two models effectively compute the same output:
权重重新缩放与重新居中: 首先,在批归一化与权重归一化下,对单个神经元入边权重 的任何重新缩放都不影响归一化后的加总输入。精确地说,若权重向量被缩放 ,则 与 这两个标量也会被缩放 ,归一化后的加总输入在缩放前后保持不变。因此批归一化与权重归一化对权重的重新缩放不变。层归一化则不对单个权重向量的单独缩放不变;相反,它对整个权重矩阵的缩放不变,也对权重矩阵中全部入边权重的平移不变。设两组模型参数 、 的权重矩阵 与 相差缩放因子 ,且 中全部入边权重还平移了常向量 ,即 。在层归一化下,两模型有效计算相同输出:
Notice that if normalization is only applied to the input before the weights, the model will not be invariant to re-scaling and re-centering of the weights.
注意,若归一化只施加在权重之前的输入上,模型将对权重的重新缩放与重新居中不再不变。
Data re-scaling and re-centering: We can show that all the normalization methods are invariant to re-scaling the dataset by verifying that the summed inputs of neurons stays constant under the changes. Furthermore, layer normalization is invariant to re-scaling of individual training cases, because the normalization scalars and in Eq. (3) only depend on the current input data. Let be a new data point obtained by re-scaling by . Then we have,
数据重新缩放与重新居中: 可通过验证神经元加总输入在变化下保持不变,证明所有归一化方法对数据集的重新缩放不变。此外,层归一化对单条训练样本的重新缩放不变,因为式 (3) 中的归一化标量 与 只依赖当前输入。令 为将 缩放 得到的新数据点,则有:
It is easy to see re-scaling individual data points does not change the model’s prediction under layer normalization. Similar to the re-centering of the weight matrix in layer normalization, we can also show that batch normalization is invariant to re-centering of the dataset.
容易看出,在层归一化下重新缩放单条数据点不改变模型预测。类似于层归一化对权重矩阵的重新居中,我们也可证明批归一化对数据集的重新居中不变。
5.2 Geometry of parameter space during learning
5.2 学习过程中参数空间的几何
We have investigated the invariance of the model’s prediction under re-centering and re-scaling of the parameters. Learning, however, can behave very differently under different parameterizations, even though the models express the same underlying function. In this section, we analyze learning behavior through the geometry and the manifold of the parameter space. We show that the normalization scalar can implicitly reduce learning rate and makes learning more stable.
我们已考察模型预测在参数重新居中与重新缩放下的不变性。然而,即便模型表达同一底层函数,在不同参数化下学习行为可以截然不同。本节通过参数空间的几何与流形分析学习行为,并表明归一化标量 能隐式降低学习率,使学习更稳定。
5.2.1 Riemannian metric
The learnable parameters in a statistical model form a smooth manifold that consists of all possible input-output relations of the model. For models whose output is a probability distribution, a natural way to measure the separation of two points on this manifold is the Kullback-Leibler divergence between their model output distributions. Under the KL divergence metric, the parameter space is a Riemannian manifold.
5.2.1 黎曼度量
统计模型中的可学习参数构成光滑流形,包含模型所有可能的输入–输出关系。对输出为概率分布的模型,衡量该流形上两点分离程度的自然方式是其模型输出分布之间的 Kullback-Leibler 散度。在 KL 散度度量下,参数空间是黎曼流形。
The curvature of a Riemannian manifold is entirely captured by its Riemannian metric, whose quadratic form is denoted as . That is the infinitesimal distance in the tangent space at a point in the parameter space. Intuitively, it measures the changes in the model output from the parameter space along a tangent direction. The Riemannian metric under KL was previously studied [Amari 1998] and was shown to be well approximated under second order Taylor expansion using the Fisher information matrix:
黎曼流形的曲率完全由其黎曼度量刻画,其二次型记为 ,即参数空间某点切空间中的无穷小距离。直观上,它衡量沿切方向从参数空间引起的模型输出变化。KL 下的黎曼度量此前已有研究 [Amari 1998],并表明可用 Fisher 信息矩阵在二阶泰勒展开下很好近似:
where, is a small change to the parameters. The Riemannian metric above presents a geometric view of parameter spaces. The following analysis of the Riemannian metric provides some insight into how normalization methods could help in training neural networks.
其中 是对参数的小扰动。上述黎曼度量为参数空间提供几何视角。下文对黎曼度量的分析有助于理解归一化方法如何帮助训练神经网络。
5.2.2 The geometry of normalized generalized linear models
We focus our geometric analysis on the generalized linear model. The results from the following analysis can be easily applied to understand deep neural networks with block-diagonal approximation to the Fisher information matrix, where each block corresponds to the parameters for a single neuron.
5.2.2 归一化广义线性模型的几何
我们把几何分析集中在广义线性模型上。下列结果可借助对 Fisher 信息矩阵的块对角近似方便地推广到深度网络,其中每一块对应单个神经元的参数。
A generalized linear model (GLM) can be regarded as parameterizing an output distribution from the exponential family using a weight vector and bias scalar . To be consistent with the previous sections, the log likelihood of the GLM can be written using the summed inputs as the following:
广义线性模型(GLM)可看作用权重向量 与偏置标量 参数化指数族中的输出分布。为与前几节一致,GLM 的对数似然可用加总输入 写成:
where, is the transfer function that is the analog of the non-linearity in neural networks, is the derivative of the transfer function, is a real valued function and is the log partition function. is a constant that scales the output variance. Assume a -dimensional output vector is modeled using independent GLMs and . Let be the weight matrix whose rows are the weight vectors of the individual GLMs, denote the bias vector of length and denote the Kronecker vector operator. The Fisher information matrix for the multi-dimensional GLM with respect to its parameters is simply the expected Kronecker product of the data features and the output covariance matrix:
其中 是对应于神经网络非线性的转移函数, 是其导数, 是实值函数, 是对数配分函数。 是缩放输出方差的常数。设 维输出向量 由 个独立 GLM 建模,且 。令 为各行是各 GLM 权重向量的权重矩阵, 为长度 的偏置向量, 为 Kronecker 向量化算子。多维 GLM 相对参数 的 Fisher 信息矩阵,恰是数据特征与输出协方差矩阵的期望 Kronecker 积:
$$\displaystyle{F}(\theta) \ \displaystyle=\mathop{\mathbb{E}}_{{\mathbb{x}}\sim P({\mathbb{x}})}\left[\frac{\text{Cov}[{\mathbb{y}},|,{\mathbb{x}}]}{\phi^{2}}\otimes\begin{bmatrix}{\mathbb{x}}{\mathbb{x}}^{\top}&{\mathbb{x}}\
{\mathbb{x}}^{\top}&1\end{bmatrix}\right]. \tag{12}$$
We obtain normalized GLMs by applying the normalization methods to the summed inputs in the original model through and . Without loss of generality, we denote as the Fisher information matrix under the normalized multi-dimensional GLM with the additional gain parameters :
通过对原模型中的加总输入 用 与 施加归一化,得到归一化 GLM。不失一般性,记 为带额外增益参数 的归一化多维 GLM 下的 Fisher 信息矩阵:
$$\displaystyle\bar{{F}}(\theta)=\begin{bmatrix}[1.5]\bar{{F}}{11}&\cdots&\bar{{F}}{1H}\
\vdots&\ddots&\vdots\
\bar{{F}}{H1}&\cdots&\bar{{F}}{HH}\end{bmatrix},\quad\bar{{F}}{ij} \ \displaystyle=\mathop{\mathbb{E}}{{\mathbb{x}}\sim P({\mathbb{x}})}\left[\frac{\text{Cov}[y_{i},\ y_{j}\ ,|,{\mathbb{x}}]}{\phi^{2}}\begin{bmatrix}[1.5]\frac{{g}{i}{g}{j}}{\sigma_{i}\sigma_{j}}{\chi}{i}{\chi}{j}^{\top}&{\chi}{i}\frac{{g}{i}}{\sigma_{i}}&{\chi}{i}\frac{{g}{i}({a}{j}-\mu{j})}{\sigma_{i}\sigma_{j}}\
{\chi}{j}^{\top}\frac{{g}{j}}{\sigma_{j}}&1&\frac{{a}{j}-\mu{j}}{\sigma_{j}}\
{\chi}{j}^{\top}\frac{{g}{j}({a}{i}-\mu{i})}{\sigma_{i}\sigma_{j}}&\frac{{a}{i}-\mu{i}}{\sigma_{i}}&\frac{({a}{i}-\mu{i})({a}{j}-\mu{j})}{\sigma_{i}\sigma_{j}}\end{bmatrix}\right] \ \displaystyle{\chi}{i} \ \displaystyle={\mathbb{x}}-\frac{\partial{\mu{i}}}{\partial{{w}{i}}}-\frac{{a}{i}-\mu_{i}}{\sigma_{i}}\frac{\partial{\sigma_{i}}}{\partial{{w}_{i}}}. \tag{13}$$
Implicit learning rate reduction through the growth of the weight vector: Notice that, comparing to standard GLM, the block along the weight vector direction is scaled by the gain parameters and the normalization scalar . If the norm of the weight vector grows twice as large, even though the model’s output remains the same, the Fisher information matrix will be different. The curvature along the direction will change by a factor of because the will also be twice as large. As a result, for the same parameter update in the normalized model, the norm of the weight vector effectively controls the learning rate for the weight vector. During learning, it is harder to change the orientation of the weight vector with large norm. The normalization methods, therefore, have an implicit “early stopping” effect on the weight vectors and help to stabilize learning towards convergence.
通过权重向量增长实现的隐式学习率降低: 注意,相对标准 GLM,沿权重向量 方向的块 被增益参数与归一化标量 缩放。若 的范数增大一倍,即便模型输出不变,Fisher 信息矩阵也会不同:沿 方向的曲率会因 同样增大一倍而变为原来的 。因此,对归一化模型中同样的参数更新,权重向量的范数有效地控制着该向量的学习率。学习过程中,范数大的权重向量更难改变方向。归一化方法因而对权重向量具有隐式的“早停”效应,有助于学习在收敛阶段保持稳定。
Learning the magnitude of incoming weights: In normalized models, the magnitude of the incoming weights is explicitly parameterized by the gain parameters. We compare how the model output changes between updating the gain parameters in the normalized GLM and updating the magnitude of the equivalent weights under original parameterization during learning. The direction along the gain parameters in captures the geometry for the magnitude of the incoming weights. We show that Riemannian metric along the magnitude of the incoming weights for the standard GLM is scaled by the norm of its input, whereas learning the gain parameters for the batch normalized and layer normalized models depends only on the magnitude of the prediction error. Learning the magnitude of incoming weights in the normalized model is therefore, more robust to the scaling of the input and its parameters than in the standard model. See Appendix for detailed derivations.
学习入边权重的幅度: 在归一化模型中,入边权重的幅度由增益参数显式参数化。我们比较:在归一化 GLM 中更新增益参数,与在原始参数化下更新等价权重的幅度,两者如何改变模型输出。 中沿增益参数的方向刻画了入边权重幅度的几何。我们表明,标准 GLM 中沿入边权重幅度方向的黎曼度量被其输入范数缩放;而批归一化与层归一化模型学习增益参数时,只依赖预测误差的幅度。因此,归一化模型中学习入边权重幅度,相对标准模型对输入及其参数的缩放更为稳健。详细推导见附录。
6 Experimental results
6 实验结果
We perform experiments with layer normalization on 6 tasks, with a focus on recurrent neural networks: image-sentence ranking, question-answering, contextual language modelling, generative modelling, handwriting sequence generation and MNIST classification. Unless otherwise noted, the default initialization of layer normalization is to set the adaptive gains to and the biases to in the experiments.
我们在 6 项任务上做层归一化实验,重点放在循环神经网络:图像–句子排序、问答、上下文语言建模、生成建模、手写序列生成与 MNIST 分类。除非另有说明,实验中层归一化的默认初始化是把自适应增益设为 、偏置设为 。
6.1 Order embeddings of images and language
6.1 图像与语言的顺序嵌入
(a) Recall@1
(a)Recall@1
| MSCOCO | ||||||||
|---|---|---|---|---|---|---|---|---|
| Caption Retrieval | Image Retrieval | |||||||
| Model | R@1 | R@5 | R@10 | Mean r | R@1 | R@5 | R@10 | Mean r |
| Sym [Vendrov et al. 2016] | 45.4 | 88.7 | 5.8 | 36.3 | 85.8 | 9.0 | ||
| OE [Vendrov et al. 2016] | 46.7 | 88.9 | 5.7 | 37.9 | 85.9 | 8.1 | ||
| OE (ours) | 46.6 | 79.3 | 89.1 | 5.2 | 37.8 | 73.6 | 85.7 | 7.9 |
| OE + LN | 48.5 | 80.6 | 89.8 | 5.1 | 38.9 | 74.3 | 86.3 | 7.6 |
Table 2: Average results across 5 test splits for caption and image retrieval. R@K is Recall@K (high is good). Mean r is the mean rank (low is good). Sym corresponds to the symmetric baseline while OE indicates order-embeddings.
| MSCOCO | ||||||||
|---|---|---|---|---|---|---|---|---|
| 标题检索 | 图像检索 | |||||||
| 模型 | R@1 | R@5 | R@10 | Mean r | R@1 | R@5 | R@10 | Mean r |
| Sym [Vendrov et al. 2016] | 45.4 | 88.7 | 5.8 | 36.3 | 85.8 | 9.0 | ||
| OE [Vendrov et al. 2016] | 46.7 | 88.9 | 5.7 | 37.9 | 85.9 | 8.1 | ||
| OE (ours) | 46.6 | 79.3 | 89.1 | 5.2 | 37.8 | 73.6 | 85.7 | 7.9 |
| OE + LN | 48.5 | 80.6 | 89.8 | 5.1 | 38.9 | 74.3 | 86.3 | 7.6 |
表 2:标题与图像检索在 5 个测试划分上的平均结果。R@K 为 Recall@K(越高越好)。Mean r 为平均排名(越低越好)。Sym 对应对称基线,OE 表示顺序嵌入。
In this experiment, we apply layer normalization to the recently proposed order-embeddings model of Vendrov et al. 2016 for learning a joint embedding space of images and sentences. We follow the same experimental protocol as Vendrov et al. 2016 and modify their publicly available code to incorporate layer normalization [^1] which utilizes Theano [Team et al. 2016]. Images and sentences from the Microsoft COCO dataset [Lin et al. 2014] are embedded into a common vector space, where a GRU [Cho et al. 2014] is used to encode sentences and the outputs of a pre-trained VGG ConvNet [Simonyan and Zisserman 2015] (10-crop) are used to encode images. The order-embedding model represents images and sentences as a 2-level partial ordering and replaces the cosine similarity scoring function used in Kiros et al. 2014 with an asymmetric one.
本实验把层归一化施加到 Vendrov et al. 2016 最近提出的、用于学习图像与句子联合嵌入空间的顺序嵌入(order-embeddings)模型上。我们遵循与 Vendrov et al. 2016 相同的实验协议,并修改其公开代码以加入层归一化[^1](基于 Theano [Team et al. 2016])。来自 Microsoft COCO [Lin et al. 2014] 的图像与句子被嵌入到同一向量空间:句子用 GRU [Cho et al. 2014] 编码,图像用预训练 VGG ConvNet [Simonyan and Zisserman 2015](10-crop)的输出编码。顺序嵌入模型把图像与句子表示为两级偏序,并用非对称打分函数替换 Kiros et al. 2014 中使用的余弦相似度。
We trained two models: the baseline order-embedding model as well as the same model with layer normalization applied to the GRU. After every 300 iterations, we compute Recall@K (R@K) values on a held out validation set and save the model whenever R@K improves. The best performing models are then evaluated on 5 separate test sets, each containing 1000 images and 5000 captions, for which the mean results are reported. Both models use Adam [Kingma and Ba 2014] with the same initial hyperparameters and both models are trained using the same architectural choices as used in Vendrov et al. 2016. We refer the reader to the appendix for a description of how layer normalization is applied to GRU.
我们训练了两个模型:基线顺序嵌入模型,以及在 GRU 上施加层归一化的同一模型。每 300 次迭代在留出验证集上计算 Recall@K(R@K),并在 R@K 提升时保存模型。表现最好的模型再在 5 个独立测试集上评估(每个含 1000 张图像与 5000 条标题),报告均值结果。两模型都用 Adam [Kingma and Ba 2014] 与相同初始超参,架构选择与 Vendrov et al. 2016 一致。层归一化如何施加到 GRU 的说明见附录。
Figure 1 illustrates the validation curves of the models, with and without layer normalization. We plot R@1, R@5 and R@10 for the image retrieval task. We observe that layer normalization offers a per-iteration speedup across all metrics and converges to its best validation model in 60% of the time it takes the baseline model to do so. In Table 2, the test set results are reported from which we observe that layer normalization also results in improved generalization over the original model. The results we report are state-of-the-art for RNN embedding models, with only the structure-preserving model of Wang et al. 2016 reporting better results on this task. However, they evaluate under different conditions (1 test set instead of the mean over 5) and are thus not directly comparable.
图 1 给出有无层归一化时模型的验证曲线。我们绘制图像检索任务的 R@1、R@5 与 R@10。观察到层归一化在所有指标上都能按迭代加速,并在基线模型所用时间的约 60% 内收敛到其最佳验证模型。表 2 报告测试集结果:层归一化相对原模型也带来更好的泛化。我们所报告的结果是 RNN 嵌入模型中的当时最好水平;仅 Wang et al. 2016 的结构保持模型在该任务上报告了更好数字,但他们的评估条件不同(1 个测试集而非 5 个平均),因而不可直接比较。
6.2 Teaching machines to read and comprehend
6.2 教机器阅读与理解
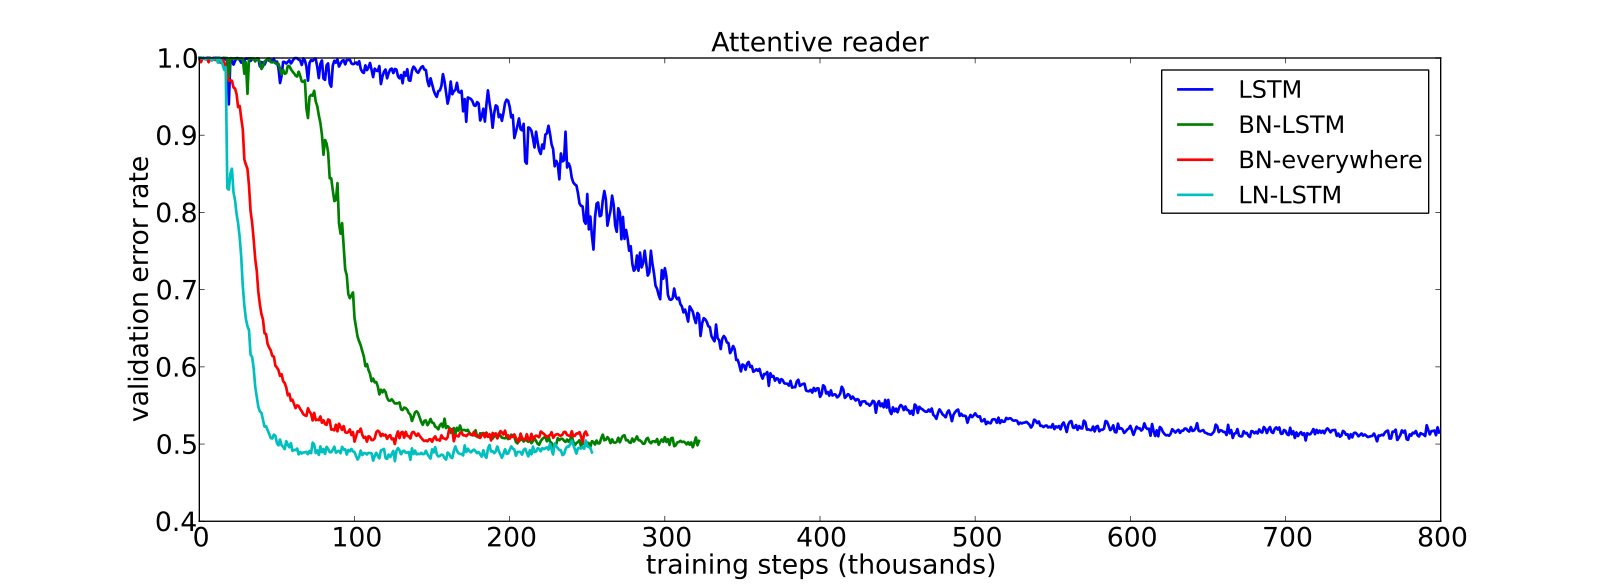
Figure 2: Validation curves for the attentive reader model. BN results are taken from [Cooijmans et al. 2016].
图 2:attentive reader 模型的验证曲线。BN 结果取自 [Cooijmans et al. 2016]。
In order to compare layer normalization to the recently proposed recurrent batch normalization [Cooijmans et al. 2016], we train an unidirectional attentive reader model on the CNN corpus both introduced by Hermann et al. 2015. This is a question-answering task where a query description about a passage must be answered by filling in a blank. The data is anonymized such that entities are given randomized tokens to prevent degenerate solutions, which are consistently permuted during training and evaluation. We follow the same experimental protocol as Cooijmans et al. 2016 and modify their public code to incorporate layer normalization [^2] which uses Theano [Team et al. 2016]. We obtained the pre-processed dataset used by Cooijmans et al. 2016 which differs from the original experiments of Hermann et al. 2015 in that each passage is limited to 4 sentences. In Cooijmans et al. 2016, two variants of recurrent batch normalization are used: one where BN is only applied to the LSTM while the other applies BN everywhere throughout the model. In our experiment, we only apply layer normalization within the LSTM.
为把层归一化与近期提出的循环批归一化 [Cooijmans et al. 2016] 比较,我们在 Hermann et al. 2015 提出的 CNN 语料上训练单向 attentive reader 模型。这是一项问答任务:关于某篇短文的查询描述须通过填空作答。数据经匿名化,实体被赋予随机化记号以防退化解,训练与评估时这些记号一致地置换。我们遵循与 Cooijmans et al. 2016 相同的实验协议,并修改其公开代码以加入层归一化[^2](基于 Theano [Team et al. 2016])。所用预处理数据与 Cooijmans et al. 2016 一致,与 Hermann et al. 2015 原始实验的差别在于每篇短文限为 4 句。Cooijmans et al. 2016 使用两种循环批归一化变体:一种只对 LSTM 施加 BN,另一种在模型各处施加 BN。我们的实验中,层归一化只施加在 LSTM 内部。
The results of this experiment are shown in Figure 2. We observe that layer normalization not only trains faster but converges to a better validation result over both the baseline and BN variants. In Cooijmans et al. 2016, it is argued that the scale parameter in BN must be carefully chosen and is set to 0.1 in their experiments. We experimented with layer normalization for both 1.0 and 0.1 scale initialization and found that the former model performed significantly better. This demonstrates that layer normalization is not sensitive to the initial scale in the same way that recurrent BN is. [^3]
本实验结果见图 2。我们观察到,层归一化不仅训练更快,最终验证结果也优于基线与两种 BN 变体。Cooijmans et al. 2016 认为 BN 中的尺度参数必须仔细选择,并在实验中设为 0.1。我们对层归一化分别尝试了 1.0 与 0.1 的尺度初始化,发现前者显著更好。这说明层归一化对初始尺度的敏感程度不像循环 BN 那样高。[^3]
6.3 Skip-thought vectors
6.3 Skip-thought 向量
(a) SICK()
(a)SICK()
Skip-thoughts [Kiros et al. 2015] is a generalization of the skip-gram model [Mikolov et al. 2013] for learning unsupervised distributed sentence representations. Given contiguous text, a sentence is encoded with a encoder RNN and decoder RNNs are used to predict the surrounding sentences. Kiros et al. 2015 showed that this model could produce generic sentence representations that perform well on several tasks without being fine-tuned. However, training this model is time-consuming, requiring several days of training in order to produce meaningful results.
Skip-thoughts [Kiros et al. 2015] 是 skip-gram 模型 [Mikolov et al. 2013] 的推广,用于学习无监督的分布式句子表示。给定连续文本,用编码器 RNN 编码一个句子,再用解码器 RNN 预测其前后句子。Kiros et al. 2015 表明该模型可产生通用句子表示,在多项任务上无需微调即表现良好。但训练耗时,往往需要数天才能得到有意义的结果。
| Method | SICK() | SICK() | SICK(MSE) | MR | CR | SUBJ | MPQA |
|---|---|---|---|---|---|---|---|
| Original [Kiros et al. 2015] | 0.848 | 0.778 | 0.287 | 75.5 | 79.3 | 92.1 | 86.9 |
| Ours | 0.842 | 0.767 | 0.298 | 77.3 | 81.8 | 92.6 | 87.9 |
| Ours + LN | 0.854 | 0.785 | 0.277 | 79.5 | 82.6 | 93.4 | 89.0 |
| Ours + LN | 0.858 | 0.788 | 0.270 | 79.4 | 83.1 | 93.7 | 89.3 |
Table 3: Skip-thoughts results. The first two evaluation columns indicate Pearson and Spearman correlation, the third is mean squared error and the remaining indicate classification accuracy. Higher is better for all evaluations except MSE. Our models were trained for 1M iterations with the exception of () which was trained for 1 month (approximately 1.7M iterations)
| 方法 | SICK() | SICK() | SICK(MSE) | MR | CR | SUBJ | MPQA |
|---|---|---|---|---|---|---|---|
| Original [Kiros et al. 2015] | 0.848 | 0.778 | 0.287 | 75.5 | 79.3 | 92.1 | 86.9 |
| Ours | 0.842 | 0.767 | 0.298 | 77.3 | 81.8 | 92.6 | 87.9 |
| Ours + LN | 0.854 | 0.785 | 0.277 | 79.5 | 82.6 | 93.4 | 89.0 |
| Ours + LN | 0.858 | 0.788 | 0.270 | 79.4 | 83.1 | 93.7 | 89.3 |
表 3:Skip-thoughts 结果。前两列评估为 Pearson 与 Spearman 相关,第三列为均方误差,其余为分类精度。除 MSE 外越高越好。我们的模型训练 100 万次迭代,例外是()训练了 1 个月(约 170 万次迭代)。
In this experiment we determine to what effect layer normalization can speed up training. Using the publicly available code of Kiros et al. 2015 [^4], we train two models on the BookCorpus dataset [Zhu et al. 2015]: one with and one without layer normalization. These experiments are performed with Theano [Team et al. 2016]. We adhere to the experimental setup used in Kiros et al. 2015, training a 2400-dimensional sentence encoder with the same hyperparameters. Given the size of the states used, it is conceivable layer normalization would produce slower per-iteration updates than without. However, we found that provided CNMeM [^5] is used, there was no significant difference between the two models. We checkpoint both models after every 50,000 iterations and evaluate their performance on five tasks: semantic-relatedness (SICK) [Marelli et al. 2014], movie review sentiment (MR) [Pang and Lee 2005], customer product reviews (CR) [Hu and Liu 2004], subjectivity/objectivity classification (SUBJ) [Pang and Lee 2004] and opinion polarity (MPQA) [Wiebe et al. 2005]. We plot the performance of both models for each checkpoint on all tasks to determine whether the performance rate can be improved with LN.
本实验考察层归一化能在多大程度上加速训练。使用 Kiros et al. 2015 的公开代码[^4],我们在 BookCorpus [Zhu et al. 2015] 上训练两个模型:一个带层归一化,一个不带。实验基于 Theano [Team et al. 2016],并遵循 Kiros et al. 2015 的设定,训练 2400 维句子编码器、超参相同。鉴于状态维度很大,层归一化有可能使每次迭代比基线更慢;但我们发现只要使用 CNMeM[^5],两模型之间没有显著差异。每 5 万次迭代做一次检查点,并在五项任务上评估:语义相关(SICK)[Marelli et al. 2014]、影评情感(MR)[Pang and Lee 2005]、客户产品评论(CR)[Hu and Liu 2004]、主观/客观分类(SUBJ)[Pang and Lee 2004] 与意见极性(MPQA)[Wiebe et al. 2005]。我们绘制各检查点在全部任务上的表现,以判断 LN 能否提升性能爬升速度。
The experimental results are illustrated in Figure 3. We observe that applying layer normalization results both in speedup over the baseline as well as better final results after 1M iterations are performed as shown in Table 3. We also let the model with layer normalization train for a total of a month, resulting in further performance gains across all but one task. We note that the performance differences between the original reported results and ours are likely due to the fact that the publicly available code does not condition at each timestep of the decoder, where the original model does.
实验结果见图 3。我们观察到施加层归一化既能相对基线加速,也能在完成 100 万次迭代后得到更好的最终结果,见表 3。我们还让带层归一化的模型一共训练一个月,除一项任务外其余都继续提升。我们与原文报告结果之间的差异,很可能是因为公开代码未在解码器每个时间步做条件化,而原模型做了。
6.4 Modeling binarized MNIST using DRAW
6.4 用 DRAW 建模二值化 MNIST
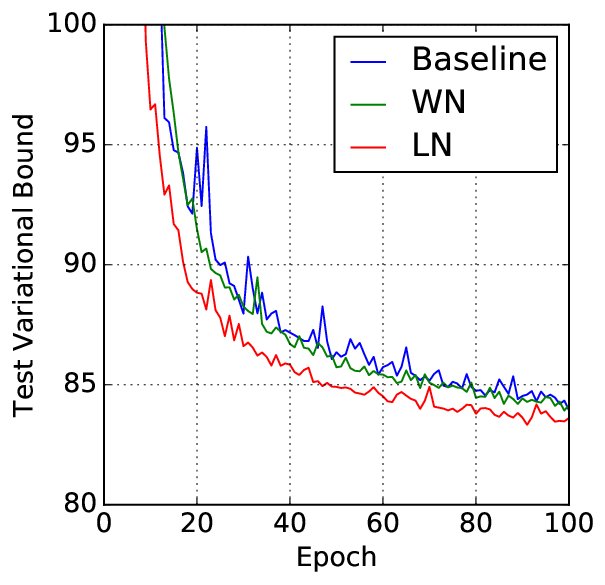
Figure 4: DRAW model test negative log likelihood with and without layer normalization.
图 4:有无层归一化时 DRAW 模型的测试负对数似然。
We also experimented with the generative modeling on the MNIST dataset. Deep Recurrent Attention Writer (DRAW) [Gregor et al. 2015] has previously achieved the state-of-the-art performance on modeling the distribution of MNIST digits. The model uses a differential attention mechanism and a recurrent neural network to sequentially generate pieces of an image. We evaluate the effect of layer normalization on a DRAW model using 64 glimpses and 256 LSTM hidden units. The model is trained with the default setting of Adam [Kingma and Ba 2014] optimizer and the minibatch size of 128. Previous publications on binarized MNIST have used various training protocols to generate their datasets. In this experiment, we used the fixed binarization from Larochelle and Murray 2011. The dataset has been split into 50,000 training, 10,000 validation and 10,000 test images.
我们还在 MNIST 数据集上做了生成建模实验。Deep Recurrent Attention Writer(DRAW)[Gregor et al. 2015] 此前在建模 MNIST 数字分布上取得了当时最好表现。该模型用可微注意力机制与循环神经网络顺序生成图像片段。我们评估层归一化对使用 64 次 glimpse、256 个 LSTM 隐单元的 DRAW 模型的影响。模型用 Adam [Kingma and Ba 2014] 默认设定训练,mini-batch 大小为 128。先前关于二值化 MNIST 的工作用过多种训练协议生成数据集;本实验使用 Larochelle and Murray 2011 的固定二值化。数据划分为 50000 训练、10000 验证与 10000 测试图像。
Figure 4 shows the test variational bound for the first 100 epoch. It highlights the speedup benefit of applying layer normalization that the layer normalized DRAW converges almost twice as fast than the baseline model. After 200 epoches, the baseline model converges to a variational log likelihood of 82.36 nats on the test data and the layer normalization model obtains 82.09 nats.
图 4 给出前 100 个 epoch 的测试变分界。它突出了施加层归一化的加速收益:层归一化 DRAW 收敛速度几乎是基线模型的两倍。200 个 epoch 后,基线模型在测试数据上收敛到变分对数似然 82.36 nats,层归一化模型得到 82.09 nats。
6.5 Handwriting sequence generation
6.5 手写序列生成
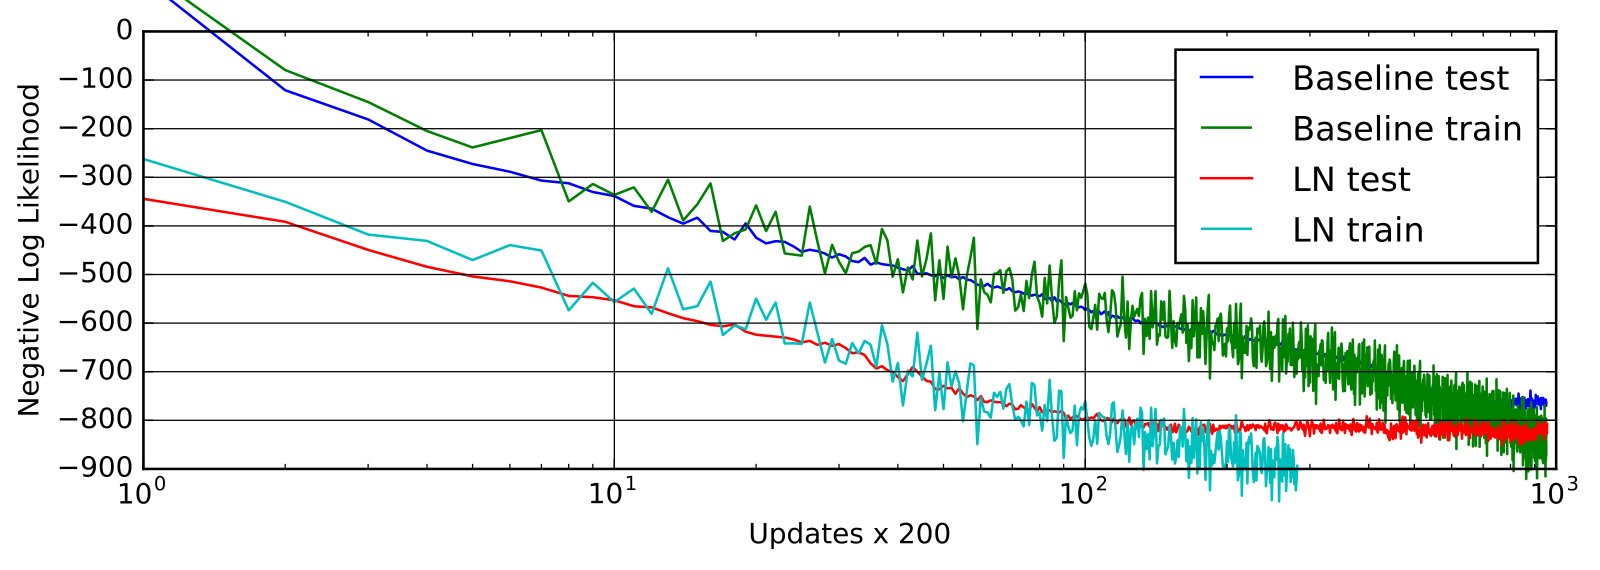
Figure 5: Handwriting sequence generation model negative log likelihood with and without layer normalization. The models are trained with mini-batch size of 8 and sequence length of 500,
图 5:有无层归一化时手写序列生成模型的负对数似然。模型以 mini-batch 大小 8、序列长度 500 训练。
The previous experiments mostly examine RNNs on NLP tasks whose lengths are in the range of 10 to 40. To show the effectiveness of layer normalization on longer sequences, we performed handwriting generation tasks using the IAM Online Handwriting Database [Liwicki and Bunke 2005]. IAM-OnDB consists of handwritten lines collected from 221 different writers. When given the input character string, the goal is to predict a sequence of x and y pen co-ordinates of the corresponding handwriting line on the whiteboard. There are, in total, 12179 handwriting line sequences. The input string is typically more than 25 characters and the average handwriting line has a length around 700.
先前实验大多考察长度约在 10 到 40 的 NLP 任务上的 RNN。为展示层归一化在更长序列上的效果,我们在 IAM Online Handwriting Database [Liwicki and Bunke 2005] 上做手写生成。IAM-OnDB 由来自 221 位书写者的手写行组成。给定输入字符串,目标是预测白板上对应手写行的 x、y 笔坐标序列。共有 12179 条手写行序列。输入串通常超过 25 个字符,平均手写行长度约 700。
We used the same model architecture as in Section (5.2) of Graves 2013. The model architecture consists of three hidden layers of 400 LSTM cells, which produce 20 bivariate Gaussian mixture components at the output layer, and a size 3 input layer. The character sequence was encoded with one-hot vectors, and hence the window vectors were size 57. A mixture of 10 Gaussian functions was used for the window parameters, requiring a size 30 parameter vector. The total number of weights was increased to approximately 3.7M. The model is trained using mini-batches of size 8 and the Adam [Kingma and Ba 2014] optimizer.
我们使用与 Graves 2013 第 (5.2) 节相同的模型架构:三个隐层各 400 个 LSTM 单元,输出层产生 20 个二元高斯混合成分,输入层大小为 3。字符序列用 one-hot 编码,因而窗口向量大小为 57。窗口参数使用 10 个高斯函数的混合,需要大小为 30 的参数向量。权重大约增至 370 万。模型用大小为 8 的 mini-batch 与 Adam [Kingma and Ba 2014] 优化器训练。
The combination of small mini-batch size and very long sequences makes it important to have very stable hidden dynamics. Figure 5 shows that layer normalization converges to a comparable log likelihood as the baseline model but is much faster.
小 mini-batch 与很长序列的组合,使得隐动态必须非常稳定。图 5 显示,层归一化收敛到与基线模型可比的对数似然,但更快得多。
6.6 Permutation invariant MNIST
6.6 置换不变 MNIST
In addition to RNNs, we investigated layer normalization in feed-forward networks. We show how layer normalization compares with batch normalization on the well-studied permutation invariant MNIST classification problem. From the previous analysis, layer normalization is invariant to input re-scaling which is desirable for the internal hidden layers. But this is unnecessary for the logit outputs where the prediction confidence is determined by the scale of the logits. We only apply layer normalization to the fully-connected hidden layers that excludes the last softmax layer.
除 RNN 外,我们也在前馈网络中考察层归一化,并在研究充分的置换不变 MNIST 分类问题上与批归一化比较。由先前分析,层归一化对输入重新缩放不变,这对应内部隐层是可取的;但对由 logits 尺度决定预测置信度的 logit 输出并不必要。我们只对全连接隐层施加层归一化,最后一层 Softmax 除外。
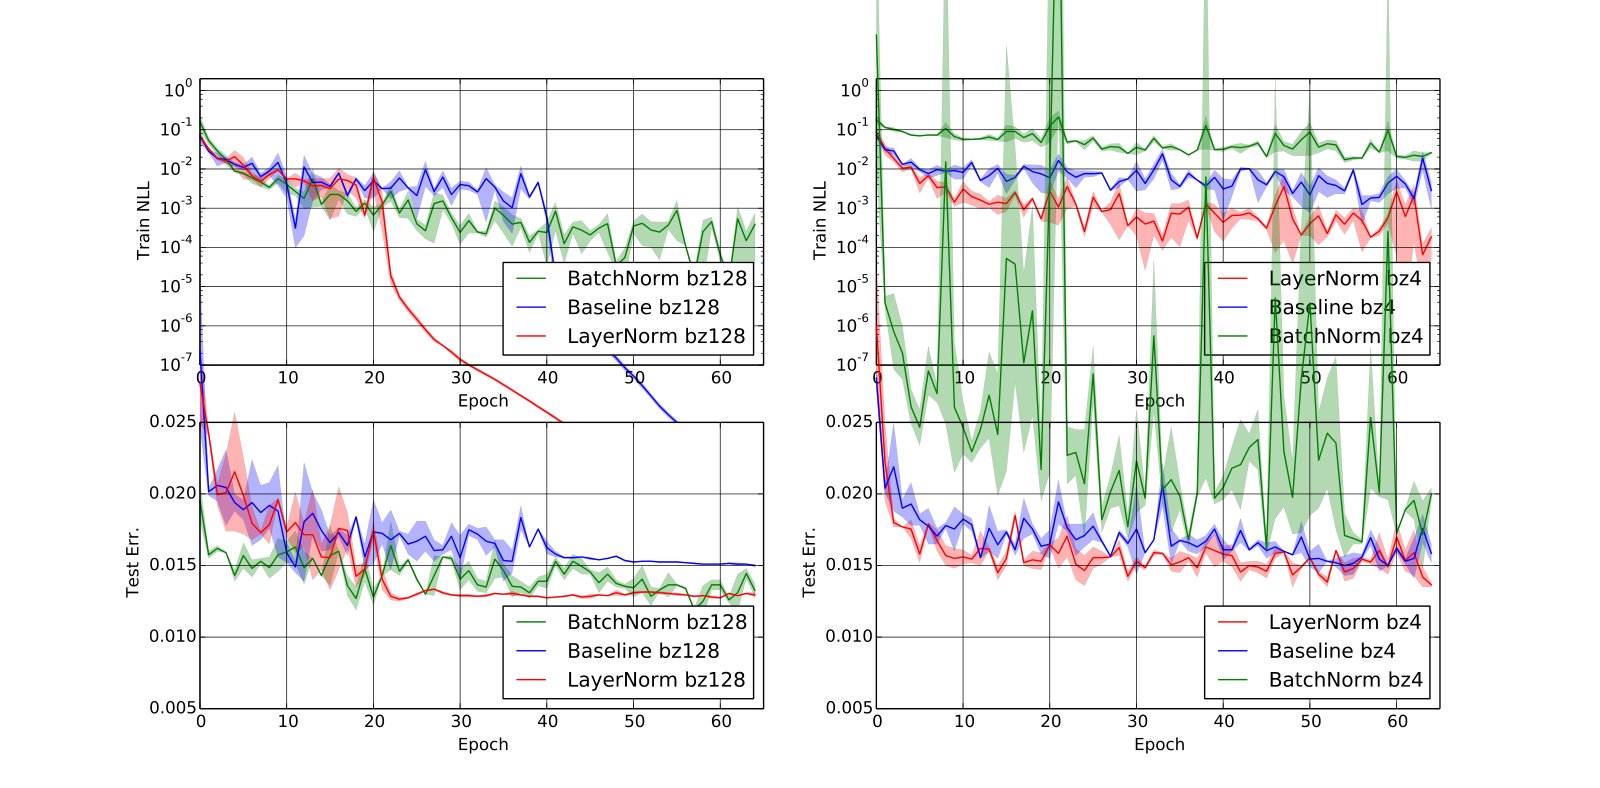
Figure 6: Permutation invariant MNIST 784-1000-1000-10 model negative log likelihood and test error with layer normalization and batch normalization. (Left) The models are trained with batch-size of 128. (Right) The models are trained with batch-size of 4.
图 6:置换不变 MNIST 784-1000-1000-10 模型在层归一化与批归一化下的负对数似然与测试误差。(左)batch-size 为 128。(右)batch-size 为 4。
All the models were trained using 55000 training data points and the Adam [Kingma and Ba 2014] optimizer. For the smaller batch-size, the variance term for batch normalization is computed using the unbiased estimator. The experimental results from Figure 6 highlight that layer normalization is robust to the batch-sizes and exhibits a faster training convergence comparing to batch normalization that is applied to all layers.
所有模型用 55000 个训练点与 Adam [Kingma and Ba 2014] 优化器训练。较小 batch-size 时,批归一化的方差项用无偏估计计算。图 6 的实验结果表明,层归一化对 batch-size 稳健,并相对施加于所有层的批归一化展现更快的训练收敛。
6.7 Convolutional Networks
6.7 卷积网络
We have also experimented with convolutional neural networks. In our preliminary experiments, we observed that layer normalization offers a speedup over the baseline model without normalization, but batch normalization outperforms the other methods. With fully connected layers, all the hidden units in a layer tend to make similar contributions to the final prediction and re-centering and re-scaling the summed inputs to a layer works well. However, the assumption of similar contributions is no longer true for convolutional neural networks. The large number of the hidden units whose receptive fields lie near the boundary of the image are rarely turned on and thus have very different statistics from the rest of the hidden units within the same layer. We think further research is needed to make layer normalization work well in ConvNets.
我们也在卷积神经网络上做了实验。初步实验中观察到,层归一化相对无归一化基线有加速,但批归一化优于其他方法。在全连接层中,一层内所有隐单元往往对最终预测贡献相近,对一层加总输入重新居中与重新缩放效果良好。然而对卷积网络,这一“贡献相近”的假设不再成立:感受野靠近图像边界的大量隐单元很少被激活,因而与同层其余隐单元有很不同的统计量。我们认为还需要进一步研究,才能让层归一化在 ConvNet 上表现良好。
7 Conclusion
7 结论
In this paper, we introduced layer normalization to speed-up the training of neural networks. We provided a theoretical analysis that compared the invariance properties of layer normalization with batch normalization and weight normalization. We showed that layer normalization is invariant to per training-case feature shifting and scaling.
本文引入层归一化以加速神经网络训练。我们给出理论分析,比较了层归一化与批归一化、权重归一化的不变性,并表明层归一化对每条训练样本的特征平移与缩放不变。
Empirically, we showed that recurrent neural networks benefit the most from the proposed method especially for long sequences and small mini-batches.
经验上,我们表明循环神经网络从该方法获益最大,尤其是在长序列与小 mini-batch 设定下。
Acknowledgments
致谢
This research was funded by grants from NSERC, CFI, and Google.
本研究由 NSERC、CFI 与 Google 的资助支持。
References
参考文献
Krizhevsky et al. [2012] Alex Krizhevsky, Ilya Sutskever, and Geoffrey E Hinton. Imagenet classification with deep convolutional neural networks. In NIPS , 2012.
Hinton et al. [2012] Geoffrey Hinton, Li Deng, Dong Yu, George E Dahl, Abdel-rahman Mohamed, Navdeep Jaitly, Andrew Senior, Vincent Vanhoucke, Patrick Nguyen, Tara N Sainath, et al. Deep neural networks for acoustic modeling in speech recognition: The shared views of four research groups. IEEE , 2012.
Dean et al. [2012] Jeffrey Dean, Greg Corrado, Rajat Monga, Kai Chen, Matthieu Devin, Mark Mao, Andrew Senior, Paul Tucker, Ke Yang, Quoc V Le, et al. Large scale distributed deep networks. In NIPS , 2012.
Ioffe and Szegedy [2015] Sergey Ioffe and Christian Szegedy. Batch normalization: Accelerating deep network training by reducing internal covariate shift. ICML , 2015.
Sutskever et al. [2014] Ilya Sutskever, Oriol Vinyals, and Quoc V Le. Sequence to sequence learning with neural networks. In Advances in neural information processing systems , pages 3104–3112, 2014.
Laurent et al. [2015] César Laurent, Gabriel Pereyra, Philémon Brakel, Ying Zhang, and Yoshua Bengio. Batch normalized recurrent neural networks. arXiv preprint arXiv:1510.01378 , 2015.
Amodei et al. [2015] Dario Amodei, Rishita Anubhai, Eric Battenberg, Carl Case, Jared Casper, Bryan Catanzaro, Jingdong Chen, Mike Chrzanowski, Adam Coates, Greg Diamos, et al. Deep speech 2: End-to-end speech recognition in english and mandarin. arXiv preprint arXiv:1512.02595 , 2015.
Cooijmans et al. [2016] Tim Cooijmans, Nicolas Ballas, César Laurent, and Aaron Courville. Recurrent batch normalization. arXiv preprint arXiv:1603.09025 , 2016.
Salimans and Kingma [2016] Tim Salimans and Diederik P Kingma. Weight normalization: A simple reparameterization to accelerate training of deep neural networks. arXiv preprint arXiv:1602.07868 , 2016.
Neyshabur et al. [2015] Behnam Neyshabur, Ruslan R Salakhutdinov, and Nati Srebro. Path-sgd: Path-normalized optimization in deep neural networks. In Advances in Neural Information Processing Systems , pages 2413–2421, 2015.
Amari [1998] Shun-Ichi Amari. Natural gradient works efficiently in learning. Neural computation , 1998.
Vendrov et al. [2016] Ivan Vendrov, Ryan Kiros, Sanja Fidler, and Raquel Urtasun. Order-embeddings of images and language. ICLR , 2016.
Team et al. [2016] The Theano Development Team, Rami Al-Rfou, Guillaume Alain, Amjad Almahairi, Christof Angermueller, Dzmitry Bahdanau, Nicolas Ballas, Frédéric Bastien, Justin Bayer, Anatoly Belikov, et al. Theano: A python framework for fast computation of mathematical expressions. arXiv preprint arXiv:1605.02688 , 2016.
Lin et al. [2014] Tsung-Yi Lin, Michael Maire, Serge Belongie, James Hays, Pietro Perona, Deva Ramanan, Piotr Dollár, and C Lawrence Zitnick. Microsoft coco: Common objects in context. ECCV , 2014.
Cho et al. [2014] Kyunghyun Cho, Bart Van Merriënboer, Caglar Gulcehre, Dzmitry Bahdanau, Fethi Bougares, Holger Schwenk, and Yoshua Bengio. Learning phrase representations using rnn encoder-decoder for statistical machine translation. EMNLP , 2014.
Simonyan and Zisserman [2015] Karen Simonyan and Andrew Zisserman. Very deep convolutional networks for large-scale image recognition. ICLR , 2015.
Kiros et al. [2014] Ryan Kiros, Ruslan Salakhutdinov, and Richard S Zemel. Unifying visual-semantic embeddings with multimodal neural language models. arXiv preprint arXiv:1411.2539 , 2014.
Kingma and Ba [2014] D. Kingma and J. L. Ba. Adam: a method for stochastic optimization. ICLR , 2014. arXiv:1412.6980.
Wang et al. [2016] Liwei Wang, Yin Li, and Svetlana Lazebnik. Learning deep structure-preserving image-text embeddings. CVPR , 2016.
Hermann et al. [2015] Karl Moritz Hermann, Tomas Kocisky, Edward Grefenstette, Lasse Espeholt, Will Kay, Mustafa Suleyman, and Phil Blunsom. Teaching machines to read and comprehend. In NIPS , 2015.
Kiros et al. [2015] Ryan Kiros, Yukun Zhu, Ruslan R Salakhutdinov, Richard Zemel, Raquel Urtasun, Antonio Torralba, and Sanja Fidler. Skip-thought vectors. In NIPS , 2015.
Mikolov et al. [2013] Tomas Mikolov, Kai Chen, Greg Corrado, and Jeffrey Dean. Efficient estimation of word representations in vector space. arXiv preprint arXiv:1301.3781 , 2013.
Zhu et al. [2015] Yukun Zhu, Ryan Kiros, Rich Zemel, Ruslan Salakhutdinov, Raquel Urtasun, Antonio Torralba, and Sanja Fidler. Aligning books and movies: Towards story-like visual explanations by watching movies and reading books. In ICCV , 2015.
Marelli et al. [2014] Marco Marelli, Luisa Bentivogli, Marco Baroni, Raffaella Bernardi, Stefano Menini, and Roberto Zamparelli. Semeval-2014 task 1: Evaluation of compositional distributional semantic models on full sentences through semantic relatedness and textual entailment. SemEval-2014 , 2014.
Pang and Lee [2005] Bo Pang and Lillian Lee. Seeing stars: Exploiting class relationships for sentiment categorization with respect to rating scales. In ACL , pages 115–124, 2005.
Hu and Liu [2004] Minqing Hu and Bing Liu. Mining and summarizing customer reviews. In Proceedings of the tenth ACM SIGKDD international conference on Knowledge discovery and data mining , 2004.
Pang and Lee [2004] Bo Pang and Lillian Lee. A sentimental education: Sentiment analysis using subjectivity summarization based on minimum cuts. In ACL , 2004.
Wiebe et al. [2005] Janyce Wiebe, Theresa Wilson, and Claire Cardie. Annotating expressions of opinions and emotions in language. Language resources and evaluation , 2005.
Gregor et al. [2015] K. Gregor, I. Danihelka, A. Graves, and D. Wierstra. DRAW: a recurrent neural network for image generation. arXiv:1502.04623, 2015.
Larochelle and Murray [2011] Hugo Larochelle and Iain Murray. The neural autoregressive distribution estimator. In AISTATS , volume 6, page 622, 2011.
Liwicki and Bunke [2005] Marcus Liwicki and Horst Bunke. Iam-ondb-an on-line english sentence database acquired from handwritten text on a whiteboard. In ICDAR , 2005.
Graves [2013] Alex Graves. Generating sequences with recurrent neural networks. arXiv preprint arXiv:1308.0850 , 2013.
Supplementary Material
补充材料
Application of layer normalization to each experiment
各实验中层归一化的施加方式
This section describes how layer normalization is applied to each of the papers’ experiments. For notation convenience, we define layer normalization as a function mapping with two set of adaptive parameters, gains and biases :
本节说明层归一化如何施加到论文各实验。为记号方便,把层归一化定义为带两组自适应参数——增益 与偏置 ——的函数映射 :
where, is the element of the vector .
其中 是向量 的第 个元素。
Teaching machines to read and comprehend and handwriting sequence generation
The basic LSTM equations used for these experiment are given by:
教机器阅读与理解及手写序列生成
这些实验使用的基本 LSTM 方程为:
$$\displaystyle\begin{pmatrix}{\bf f}{t}\
{\bf i}{t}\
{\bf o}{t}\
{\bf g}{t}\end{pmatrix} \ \displaystyle= \ \displaystyle{\bf W}{h}{\bf h}{t-1}+{\bf W}{x}{\bf x}{t}+b \ \displaystyle{\bf c}{t} \ \displaystyle= \ \displaystyle\sigma({\bf f}{t})\odot{\bf c}{t-1}+\sigma({\bf i}{t})\odot\text{tanh}({\bf g}{t}) \ \displaystyle{\bf h}{t} \ \displaystyle= \ \displaystyle\sigma({\bf o}{t})\odot\text{tanh}({\bf c}{t}) \tag{17}$$
The version that incorporates layer normalization is modified as follows:
加入层归一化后的版本修改如下:
$$\displaystyle\begin{pmatrix}{\bf f}{t}\
{\bf i}{t}\
{\bf o}{t}\
{\bf g}{t}\end{pmatrix} \ \displaystyle= \ \displaystyle LN({\bf W}{h}{\bf h}{t-1};\bm{\alpha}{1},\bm{\beta}{1})+LN({\bf W}{x}{\bf x}{t};\bm{\alpha}{2},\bm{\beta}{2})+b \ \displaystyle{\bf c}{t} \ \displaystyle= \ \displaystyle\sigma({\bf f}{t})\odot{\bf c}{t-1}+\sigma({\bf i}{t})\odot\text{tanh}({\bf g}{t}) \ \displaystyle{\bf h}{t} \ \displaystyle= \ \displaystyle\sigma({\bf o}{t})\odot\text{tanh}(LN({\bf c}{t};\bm{\alpha}{3},\bm{\beta}{3})) \tag{20}$$
where are the additive and multiplicative parameters, respectively. Each is initialized to a vector of zeros and each is initialized to a vector of ones.
其中 分别为加性与乘性参数。每个 初始化为零向量,每个 初始化为全 1 向量。
Order embeddings and skip-thoughts
These experiments utilize a variant of gated recurrent unit which is defined as follows:
顺序嵌入与 skip-thoughts
这些实验使用如下定义的门控循环单元变体:
$$\displaystyle\begin{pmatrix}{\bf z}{t}\
{\bf r}{t}\end{pmatrix} \ \displaystyle= \ \displaystyle{\bf W}{h}{\bf h}{t-1}+{\bf W}{x}{\bf x}{t} \ \displaystyle\hat{{\bf h}}{t} \ \displaystyle= \ \displaystyle\text{tanh}({\bf W}{\bf x}{t}+\sigma({\bf r}{t})\odot({\bf U}{\bf h}{t-1})) \ \displaystyle{\bf h}{t} \ \displaystyle= \ \displaystyle(1-\sigma({\bf z}{t})){\bf h}{t-1}+\sigma({\bf z}{t})\hat{{\bf h}}_{t} \tag{23}$$
Layer normalization is applied as follows:
层归一化施加如下:
$$\displaystyle\begin{pmatrix}{\bf z}{t}\
{\bf r}{t}\end{pmatrix} \ \displaystyle= \ \displaystyle LN({\bf W}{h}{\bf h}{t-1};\bm{\alpha}{1},\bm{\beta}{1})+LN({\bf W}{x}{\bf x}{t};\bm{\alpha}{2},\bm{\beta}{2}) \ \displaystyle\hat{{\bf h}}{t} \ \displaystyle= \ \displaystyle\text{tanh}(LN({\bf W}{\bf x}{t};\bm{\alpha}{3},\bm{\beta}{3})+\sigma({\bf r}{t})\odot LN({\bf U}{\bf h}{t-1};\bm{\alpha}{4},\bm{\beta}{4})) \ \displaystyle{\bf h}{t} \ \displaystyle= \ \displaystyle(1-\sigma({\bf z}{t})){\bf h}{t-1}+\sigma({\bf z}{t})\hat{{\bf h}}_{t} \tag{26}$$
just as before, is initialized to a vector of zeros and each is initialized to a vector of ones.
与前面一样, 初始化为零向量,每个 初始化为全 1 向量。
Modeling binarized MNIST using DRAW
The layer norm is only applied to the output of the LSTM hidden states in this experiment:
用 DRAW 建模二值化 MNIST
本实验中层归一化只施加于 LSTM 隐状态的输出:
The version that incorporates layer normalization is modified as follows:
加入层归一化后的版本修改如下:
$$\displaystyle\begin{pmatrix}{\bf f}{t}\
{\bf i}{t}\
{\bf o}{t}\
{\bf g}{t}\end{pmatrix} \ \displaystyle= \ \displaystyle{\bf W}{h}{\bf h}{t-1}+{\bf W}{x}{\bf x}{t}+b \ \displaystyle{\bf c}{t} \ \displaystyle= \ \displaystyle\sigma({\bf f}{t})\odot{\bf c}{t-1}+\sigma({\bf i}{t})\odot\text{tanh}({\bf g}{t}) \ \displaystyle{\bf h}{t} \ \displaystyle= \ \displaystyle\sigma({\bf o}{t})\odot\text{tanh}(LN({\bf c}{t};\bm{\alpha},\bm{\beta})) \tag{29}$$
where are the additive and multiplicative parameters, respectively. is initialized to a vector of zeros and is initialized to a vector of ones.
其中 分别为加性与乘性参数。 初始化为零向量, 初始化为全 1 向量。
Learning the magnitude of incoming weights
We now compare how gradient descent updates changing magnitude of the equivalent weights between the normalized GLM and original parameterization. The magnitude of the weights are explicitly parameterized using the gain parameter in the normalized model. Assume there is a gradient update that changes norm of the weight vectors by . We can project the gradient updates to the weight vector for the normal GLM. The KL metric, ie how much the gradient update changes the model prediction, for the normalized model depends only on the magnitude of the prediction error. Specifically,
学习入边权重的幅度
我们现在比较:在归一化 GLM 与原始参数化之间,梯度下降更新如何改变等价权重的幅度。归一化模型中权重幅度由增益参数显式参数化。假设有一次梯度更新使权重向量范数改变 。我们可以把梯度更新投影到普通 GLM 的权重向量上。归一化模型的 KL 度量(即梯度更新使模型预测改变多少)只依赖预测误差的幅度。具体地,
under batch normalization:
在批归一化下:
Under layer normalization:
在层归一化下:
$$\displaystyle ds^{2}= \ \displaystyle\frac{1}{2}\vecop([0,0,\delta_{g}]^{\top})^{\top}\bar{F}(\vecop([W,{\mathbb{b}},{\mathbb{g}}]^{\top})\vecop([0,0,\delta_{g}]^{\top}) \ \displaystyle= \ \displaystyle\frac{1}{2}\delta_{g}^{\top}\frac{1}{{\phi^{2}}}\mathop{\mathbb{E}}{{\mathbb{x}}\sim P({\mathbb{x}})}\begin{bmatrix}[1.5]{\text{Cov}(y{1},y_{1},|,{\mathbb{x}})}\frac{(a_{1}-\mu)^{2}}{\sigma^{2}}&\cdots&{\text{Cov}(y_{1},y_{H},|,{\mathbb{x}})}\frac{(a_{1}-\mu)(a_{H}-\mu)}{\sigma^{2}}\
\vdots&\ddots&\vdots\
\text{Cov}(y_{H},y_{1},|,{\mathbb{x}})\frac{(a_{H}-\mu)(a_{1}-\mu)}{\sigma^{2}}&\cdots&\text{Cov}(y_{H},y_{H},|,{\mathbb{x}})\frac{(a_{H}-\mu)^{2}}{\sigma^{2}}\end{bmatrix}\delta_{g} \tag{33}$$
Under weight normalization:
在权重归一化下:
$$\displaystyle ds^{2}= \ \displaystyle\frac{1}{2}\vecop([0,0,\delta_{g}]^{\top})^{\top}\bar{F}(\vecop([W,{\mathbb{b}},{\mathbb{g}}]^{\top})\vecop([0,0,\delta_{g}]^{\top}) \ \displaystyle= \ \displaystyle\frac{1}{2}\delta_{g}^{\top}\frac{1}{{\phi^{2}}}\mathop{\mathbb{E}}{{\mathbb{x}}\sim P({\mathbb{x}})}\begin{bmatrix}[1.5]{\text{Cov}(y{1},y_{1},|,{\mathbb{x}})}\frac{a_{1}^{2}}{|w_{1}|{2}^{2}}&\cdots&{\text{Cov}(y{1},y_{H},|,{\mathbb{x}})}\frac{a_{1}a_{H}}{|w_{1}|{2}|w{H}|{2}}\
\vdots&\ddots&\vdots\
\text{Cov}(y{H},y_{1},|,{\mathbb{x}})\frac{a_{H}a_{1}}{|w_{H}|{2}|w{1}|{2}}&\cdots&\text{Cov}(y{H},y_{H},|,{\mathbb{x}})\frac{a_{H}^{2}}{|w_{H}|^{2}{2}}\end{bmatrix}\delta{g}. \tag{34}$$
Whereas, the KL metric in the standard GLM is related to its activities , that is depended on both its current weights and input data. We project the gradient updates to the gain parameter of the neuron to its weight vector as in the standard GLM model:
而标准 GLM 中的 KL 度量与其活动 相关,同时依赖当前权重与输入数据。我们把第 个神经元增益参数上的梯度更新 投影到其权重向量为 (在标准 GLM 模型中):
The batch normalized and layer normalized models are therefore more robust to the scaling of the input and its parameters than the standard model.
因此,批归一化与层归一化模型相对标准模型对输入及其参数的缩放更为稳健。