Intriguing properties of neural networks
Intriguing properties of neural networks
Abstract
摘要
Deep neural networks are highly expressive models that have recently achieved state of the art performance on speech and visual recognition tasks. While their expressiveness is the reason they succeed, it also causes them to learn uninterpretable solutions that could have counter-intuitive properties. In this paper we report two such properties.
深度神经网络是表达能力很强的模型,近来在语音和视觉识别任务上达到了当时最好的成绩。表达能力强是它们成功的原因,但这也使它们学到难以解释、并可能带有反直觉性质的解。本文报告其中的两个性质。
First, we find that there is no distinction between individual high level units and random linear combinations of high level units, according to various methods of unit analysis. It suggests that it is the space, rather than the individual units, that contains the semantic information in the high layers of neural networks.
第一,按多种单元分析方法来看,个别高层单元与高层单元的随机线性组合之间并无区别。这说明,在神经网络的高层里,承载语义信息的是整个空间,而不是单个单元。
Second, we find that deep neural networks learn input-output mappings that are fairly discontinuous to a significant extent. We can cause the network to misclassify an image by applying a certain hardly perceptible perturbation, which is found by maximizing the network's prediction error. In addition, the specific nature of these perturbations is not a random artifact of learning: the same perturbation can cause a different network, that was trained on a different subset of the dataset, to misclassify the same input.
第二,我们发现深度神经网络学到的输入输出映射在相当程度上是不连续的。只需加上某种几乎难以察觉的扰动,就可以让网络把一张图分错;这种扰动是通过最大化网络的预测误差找到的。而且,这些扰动的具体形态并不是学习过程中的随机产物:同一种扰动也可以让另一个在数据集的不同子集上训练出来的网络,把同一输入分错。
1 Introduction
1 引言
Deep neural networks are powerful learning models that achieve excellent performance on visual and speech recognition problems [9, 8]. Neural networks achieve high performance because they can express arbitrary computation that consists of a modest number of massively parallel nonlinear steps. But as the resulting computation is automatically discovered by backpropagation via supervised learning, it can be difficult to interpret and can have counter-intuitive properties. In this paper, we discuss two counter-intuitive properties of deep neural networks.
深度神经网络是强大的学习模型,在视觉和语音识别问题上表现优异 [9, 8]。它们之所以能达到很高的性能,是因为可以表达由数量不算多、但高度并行的非线性步骤组成的任意计算。不过,得到的计算是通过有监督学习和反向传播自动发现的,因而可能难以解释,也可能带有反直觉的性质。本文讨论深度神经网络的两个反直觉性质。
The first property is concerned with the semantic meaning of individual units. Previous works [6, 13, 7] analyzed the semantic meaning of various units by finding the set of inputs that maximally activate a given unit. The inspection of individual units makes the implicit assumption that the units of the last feature layer form a distinguished basis which is particularly useful for extracting semantic information. Instead, we show in section 3 that random projections of are semantically indistinguishable from the coordinates of . This puts into question the conjecture that neural networks disentangle variation factors across coordinates. Generally, it seems that it is the entire space of activations, rather than the individual units, that contains the bulk of the semantic information. A similar, but even stronger conclusion was reached recently by Mikolov et al. [12] for word representations, where the various directions in the vector space representing the words are shown to give rise to a surprisingly rich semantic encoding of relations and analogies. At the same time, the vector representations are stable up to a rotation of the space, so the individual units of the vector representations are unlikely to contain semantic information.
第一个性质涉及单个单元的语义。先前的工作 [6, 13, 7] 通过找出最能激活某一单元的输入集合,来分析各个单元的语义。这种对单个单元的检查,隐含地假定最后一层特征的各个单元构成了一组特别适合提取语义信息的基底。相反,我们在第 3 节表明, 的随机投影在语义上与 的各个坐标难以区分。这使“神经网络把各变化因素分解到不同坐标上”这一猜想变得可疑。总的来看,承载大部分语义信息的,似乎是整个激活空间,而不是单个单元。Mikolov 等人 [12] 最近对词表示得出了类似、甚至更强的结论:表示词语的向量空间中,各个方向可以给出关系与类比的丰富语义编码。与此同时,这些向量表示在空间旋转下仍然稳定,因而向量表示的单个单元不大可能单独承载语义信息。
The second property is concerned with the stability of neural networks with respect to small perturbations to their inputs. Consider a state-of-the-art deep neural network that generalizes well on an object recognition task. We expect such network to be robust to small perturbations of its input, because small perturbation cannot change the object category of an image. However, we find that applying an imperceptible non-random perturbation to a test image, it is possible to arbitrarily change the network's prediction (see figure 5). These perturbations are found by optimizing the input to maximize the prediction error. We term the so perturbed examples "adversarial examples".
第二个性质涉及神经网络对输入上小扰动的稳定性。考虑一个在物体识别任务上泛化良好的先进深度神经网络。我们会期望这样的网络对输入的小扰动是稳健的,因为小扰动并不能改变图像的物体类别。然而我们发现,给一张测试图像加上几乎难以察觉的非随机扰动,就可以任意改变网络的预测(见图 5)。这些扰动是通过优化输入、最大化预测误差找到的。我们把这样得到的样本称为“对抗样本”(adversarial examples)。
It is natural to expect that the precise configuration of the minimal necessary perturbations is a random artifact of the normal variability that arises in different runs of backpropagation learning. Yet, we found that adversarial examples are relatively robust, and are shared by neural networks with varied number of layers, activations or trained on different subsets of the training data. That is, if we use one neural net to generate a set of adversarial examples, we find that these examples are still statistically hard for another neural network even when it was trained with different hyperparameters or, most surprisingly, when it was trained on a different set of examples.
人们很自然会以为,最小必要扰动的精确形态,不过是不同次反向传播学习中正常波动带来的随机产物。可是我们发现,对抗样本相当稳固,并且为层数、激活函数不同,或在训练数据的不同子集上训练出来的神经网络所共享。也就是说,如果用一个网络生成一组对抗样本,这些样本对另一个网络在统计上仍然困难,即使后者用了不同的超参数,甚至更令人惊讶的是,即使它是在另一组样本上训练的。
These results suggest that the deep neural networks that are learned by backpropagation have nonintuitive characteristics and intrinsic blind spots, whose structure is connected to the data distribution in a non-obvious way.
这些结果说明,用反向传播学到的深度神经网络具有反直觉的特征和内在盲区,其结构与数据分布之间的关系并不显然。
2 Framework
2 框架
Notation We denote by an input image, and activation values of some layer. We first examine properties of the image of , and then we search for its blind spots.
记号 我们用 表示一张输入图像,用 表示某一层的激活值。我们先考察 的像所具有的性质,然后再寻找它的盲区。
We perform a number of experiments on a few different networks and three datasets:
我们在若干不同网络和三个数据集上做了一系列实验:
- For the MNIST dataset, we used the following architectures [11]
- 对于 MNIST 数据集,我们使用了以下结构 [11]
- A simple fully connected network with one or more hidden layers and a Softmax classifier. We refer to this network as "FC".
- 一个带有一层或多层隐层以及 Softmax 分类器的简单全连接网络。我们称之为 “FC”。
- A classifier trained on top of an autoencoder. We refer to this network as "AE".
- 一个训练在自动编码器之上的分类器。我们称之为 “AE”。
- The ImageNet dataset [3].
- ImageNet 数据集 [3]。
- Krizhevsky et. al architecture [9]. We refer to it as "AlexNet".
- Krizhevsky 等人的结构 [9]。我们称之为 “AlexNet”。
- 10M image samples from Youtube (see [10])
- 来自 YouTube 的约 1000 万张图像样本(见 [10])
- Unsupervised trained network with 1 billion learnable parameters. We refer to it as "QuocNet".
- 一个无监督训练、约有 10 亿个可学习参数的网络。我们称之为 “QuocNet”。
For the MNIST experiments, we use regularization with a weight decay of . Moreover, in some experiments we split the MNIST training dataset into two disjoint datasets , and , each with 30000 training cases.
在 MNIST 实验中,我们使用权重衰减系数为 的正则化。此外,在部分实验里,我们把 MNIST 训练集分成两个不相交的数据集 和 ,各有 30000 个训练样本。
3 Units of
3 的单元
Traditional computer vision systems rely on feature extraction: often a single feature is easily interpretable, e.g. a histogram of colors, or quantized local derivatives. This allows one to inspect the individual coordinates of the feature space, and link them back to meaningful variations in the input domain. Similar reasoning was used in previous work that attempted to analyze neural networks that were applied to computer vision problems. These works interpret an activation of a hidden unit as a meaningful feature. They look for input images which maximize the activation value of this single feature [6, 13, 7, 4].
传统计算机视觉系统依赖特征提取:单个特征往往容易解释,例如颜色直方图,或量化后的局部导数。这样就可以检查特征空间的各个坐标,并把它们与输入域中有意义的变化对应起来。此前分析用于计算机视觉问题的神经网络的工作,也采用了类似思路。这些工作把隐单元的激活解释成有意义的特征,并寻找使这一单个特征的激活值最大的输入图像 [6, 13, 7, 4]。
The aforementioned technique can be formally stated as visual inspection of images , which satisfy (or are close to maximum attainable value):
上述技术可以形式化地表述为:对满足下式(或接近可达到的最大值)的图像 做视觉检查:
where is a held-out set of images from the data distribution that the network was not trained on and is the natural basis vector associated with the -th hidden unit. Our experiments show that any random direction gives rise to similarly interpretable semantic properties. More formally, we find that images are semantically related to each other, for many such that
其中 是来自数据分布、且网络未曾在其上训练的留出图像集合, 是与第 个隐单元对应的自然基底向量。我们的实验表明,任意随机方向 都会产生同样可解释的语义性质。更形式地说,我们发现,对于许多满足下式的 ,这些图像 在语义上彼此相关:
This suggests that the natural basis is not better than a random basis for inspecting the properties of . This puts into question the notion that neural networks disentangle variation factors across coordinates.
这说明,在考察 的性质时,自然基底并不比随机基底更好。这使“神经网络把各变化因素分解到不同坐标上”这一看法变得可疑。
First, we evaluated the above claim using a convolutional neural network trained on MNIST. We used the MNIST test set for . Figure 1 shows images that maximize the activations in the natural basis, and Figure 2 shows images that maximize the activation in random directions. In both cases the resulting images share many high-level similarities.
我们首先用一个在 MNIST 上训练的卷积神经网络来评估上述论断。 取 MNIST 测试集。图 1 展示了在自然基底上使激活最大的图像,图 2 展示了在随机方向上使激活最大的图像。两种情形下,得到的图像都共享许多高层相似性。
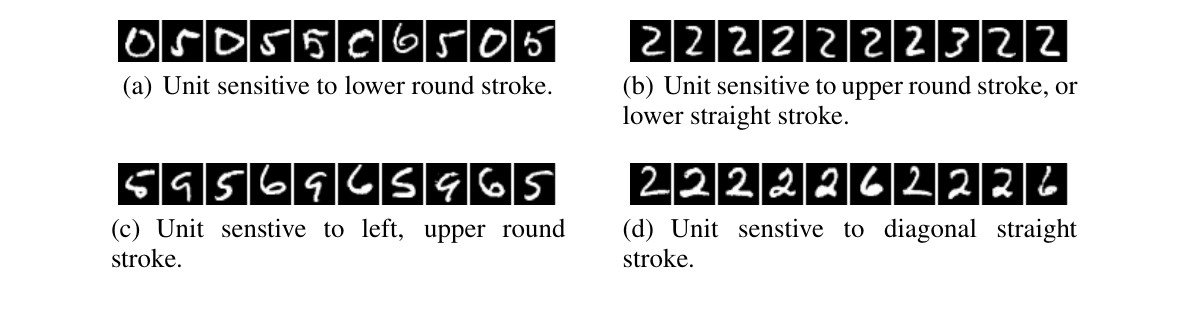
Figure 1: An MNIST experiment. The figure shows images that maximize the activation of various units (maximum stimulation in the natural basis direction). Images within each row share semantic properties.
图 1:一项 MNIST 实验。图中展示的是使各个单元激活最大的图像(在自然基底方向上的最大刺激)。同一行内的图像共享语义性质。
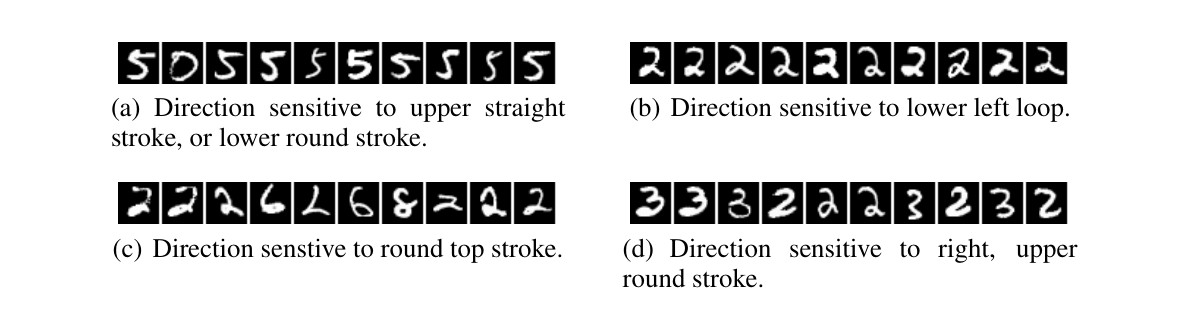
Figure 2: An MNIST experiment. The figure shows images that maximize the activations in a random direction (maximum stimulation in a random basis). Images within each row share semantic properties.
图 2:一项 MNIST 实验。图中展示的是使随机方向上激活最大的图像(在随机基底上的最大刺激)。同一行内的图像共享语义性质。
Next, we repeated our experiment on an AlexNet, where we used the validation set as . Figures 3 and 4 compare the natural basis to the random basis on the trained network. The rows appear to be semantically meaningful for both the single unit and the combination of units.
接着,我们在一个 AlexNet 上重复了这一实验,并把验证集作为 。图 3 和图 4 在该训练好的网络上比较了自然基底与随机基底。无论是单个单元还是单元组合,各行看起来都具有语义。
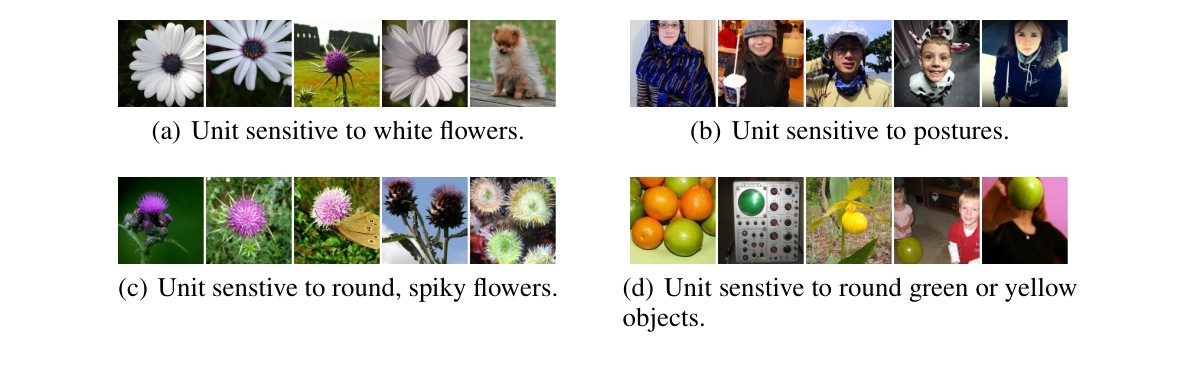
Figure 3: Experiment performed on ImageNet. Images stimulating single unit most (maximum stimulation in natural basis direction). Images within each row share many semantic properties.
图 3:在 ImageNet 上做的实验。使单个单元受到最大刺激的图像(在自然基底方向上的最大刺激)。同一行内的图像共享许多语义性质。
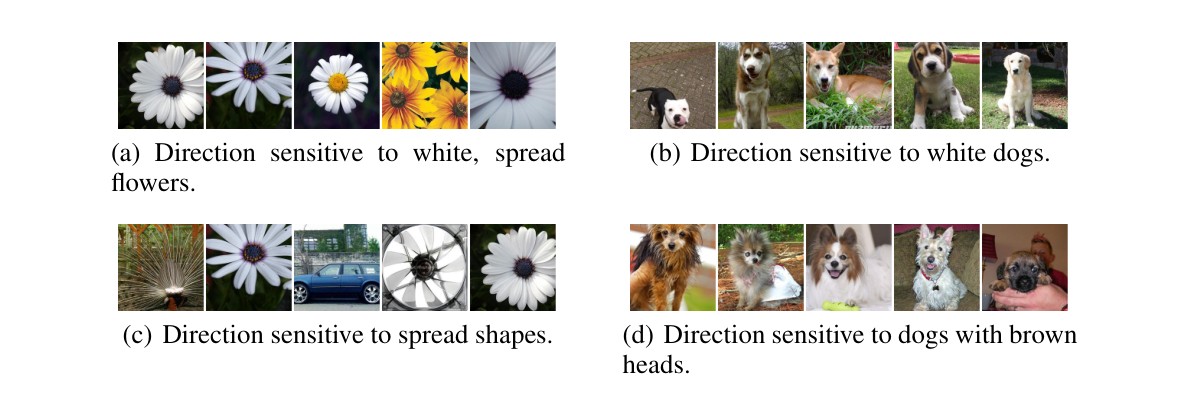
Figure 4: Experiment performed on ImageNet. Images giving rise to maximum activations in a random direction (maximum stimulation in a random basis). Images within each row share many semantic properties.
图 4:在 ImageNet 上做的实验。在随机方向上产生最大激活的图像(在随机基底上的最大刺激)。同一行内的图像共享许多语义性质。
Although such analysis gives insight on the capacity of to generate invariance on a particular subset of the input distribution, it does not explain the behavior on the rest of its domain. We shall see in the next section that has counterintuitive properties in the neighbourhood of almost every point form data distribution.
尽管这类分析有助于理解 在输入分布的某个特定子集上产生不变性的能力,它并不能解释 在其定义域其余部分上的行为。下一节将会看到, 在数据分布中几乎每个点的邻域里都具有反直觉的性质。
4 Blind Spots in Neural Networks
4 神经网络中的盲区
So far, unit-level inspection methods had relatively little utility beyond confirming certain intuitions regarding the complexity of the representations learned by a deep neural network [6, 13, 7, 4]. Global, network level inspection methods can be useful in the context of explaining classification decisions made by a model [1] and can be used to, for instance, identify the parts of the input which led to a correct classification of a given visual input instance (in other words, one can use a trained model for weakly-supervised localization). Such global analyses are useful in that they can make us understand better the input-to-output mapping represented by the trained network.
到目前为止,单元级检查方法除了用来确认关于深度网络所学表示复杂性的某些直觉之外,用处相对有限 [6, 13, 7, 4]。全局的、网络级检查方法可以用来解释模型做出的分类决定 [1],例如找出输入中哪些部分导致对某个视觉实例的正确分类(换言之,可以用训练好的模型做弱监督定位)。这类全局分析有助于更好地理解训练网络所表示的输入到输出映射。
Generally speaking, the output layer unit of a neural network is a highly nonlinear function of its input. When it is trained with the cross-entropy loss (using the Softmax activation function), it represents a conditional distribution of the label given the input (and the training set presented so far). It has been argued [2] that the deep stack of non-linear layers in between the input and the output unit of a neural network are a way for the model to encode a non-local generalization prior over the input space. In other words, it is assumed that is possible for the output unit to assign nonsignificant (and, presumably, non-epsilon) probabilities to regions of the input space that contain no training examples in their vicinity. Such regions can represent, for instance, the same objects from different viewpoints, which are relatively far (in pixel space), but which share nonetheless both the label and the statistical structure of the original inputs.
一般而言,神经网络输出层单元是其输入的高度非线性函数。当用交叉熵损失(并使用 Softmax 激活)训练时,它表示给定输入(以及至此所见的训练集)时标签的条件分布。有论点认为 [2],输入与输出单元之间那一叠深层非线性层,是模型在输入空间上编码一种非局部泛化先验的方式。换句话说,人们假定输出单元能够给附近没有任何训练样本的输入区域赋予不可忽略的(并且大概也不是无穷小的)概率。这类区域可以表示,例如同一物体的不同视角:它们在像素空间中相距较远,却仍然共享原来输入的标签和统计结构。
It is implicit in such arguments that local generalization—in the very proximity of the training examples—works as expected. And that in particular, for a small enough radius in the vicinity of a given training input , an satisfying will get assigned a high probability of the correct class by the model. This kind of smoothness prior is typically valid for computer vision problems. In general, imperceptibly tiny perturbations of a given image do not normally change the underlying class.
这类论点暗含着一个前提:在训练样本的紧邻范围内,局部泛化会按预期工作。特别是,对给定训练输入 的邻域,只要半径 足够小,满足 的 会被模型赋予正确类别的高概率。这种平滑先验在计算机视觉问题里通常是成立的。一般而言,对给定图像做几乎看不出的微小扰动,通常并不会改变其真实类别。
Our main result is that for deep neural networks, the smoothness assumption that underlies many kernel methods does not hold. Specifically, we show that by using a simple optimization procedure, we are able to find adversarial examples, which are obtained by imperceptibly small perturbations to a correctly classified input image, so that it is no longer classified correctly.
我们的主要结果是:对深度神经网络而言,许多核方法所依赖的平滑性假设并不成立。具体来说,我们表明,用一个简单的优化过程就能找到对抗样本:它们是对一张原本分类正确的输入图像做几乎看不出的小扰动后得到的,扰动之后就不再被正确分类。
In some sense, what we describe is a way to traverse the manifold represented by the network in an efficient way (by optimization) and finding adversarial examples in the input space. The adversarial examples represent low-probability (high-dimensional) "pockets" in the manifold, which are hard to efficiently find by simply randomly sampling the input around a given example. Already, a variety of recent state of the art computer vision models employ input deformations during training for increasing the robustness and convergence speed of the models [9, 13]. These deformations are, however, statistically inefficient, for a given example: they are highly correlated and are drawn from the same distribution throughout the entire training of the model. We propose a scheme to make this process adaptive in a way that exploits the model and its deficiencies in modeling the local space around the training data.
从某种意义上说,我们描述的是一种有效遍历网络所表示流形的方法(通过优化),并在输入空间中找出对抗样本。对抗样本对应流形上低概率(高维)的“口袋”,只是在给定样本周围随机采样输入,很难有效找到它们。近来已有不少先进的计算机视觉模型在训练时对输入做变形,以提高稳健性和收敛速度 [9, 13]。但对给定样本而言,这些变形在统计上是低效的:它们高度相关,并且在整个训练过程中都来自同一分布。我们提出一种方案,让这一过程变得自适应,从而利用模型及其在训练数据局部空间建模上的不足。
We make the connection with hard-negative mining explicitly, as it is close in spirit: hard-negative mining, in computer vision, consists of identifying training set examples (or portions thereof) which are given low probabilities by the model, but which should be high probability instead, cf. [5]. The training set distribution is then changed to emphasize such hard negatives and a further round of model training is performed. As shall be described, the optimization problem proposed in this work can also be used in a constructive way, similar to the hard-negative mining principle.
我们明确把它与难负例挖掘联系起来,因为两者在思路上接近:在计算机视觉中,难负例挖掘是找出那些被模型赋予低概率、但本应是高概率的训练样本(或其一部分),参见 [5]。然后改变训练集分布以强调这些难负例,再进行新一轮训练。如下所述,本文提出的优化问题也可以建设性地使用,类似于难负例挖掘的原则。
4.1 Formal description
4.1 形式描述
We denote by a classifier mapping image pixel value vectors to a discrete label set. We also assume that has an associated continuous loss function denoted by . For a given image and target label , we aim to solve the following box-constrained optimization problem:
我们用 表示一个把图像像素值向量映射到离散标签集的分类器。我们还假定 有一个与之相伴的连续损失函数,记为 。对给定图像 和目标标签 ,我们希望求解如下盒约束优化问题:
- Minimize subject to:
- 最小化 ,约束为:
The minimizer might not be unique, but we denote one such for an arbitrarily chosen minimizer by . Informally, is the closest image to classified as by . Obviously, , so this task is non-trivial only if . In general, the exact computation of is a hard problem, so we approximate it by using a box-constrained L-BFGS. Concretely, we find an approximation of by performing line-search to find the minimum for which the minimizer of the following problem satisfies .
最小化子 未必唯一,但对任意选定的一个最小化子,我们把相应的 记为 。非正式地说, 是在 看来距离 最近、且被分为 的图像。显然 ,因此只有当 时这一任务才是非平凡的。一般而言,精确计算 是困难的,我们用盒约束 L-BFGS 来近似。具体做法是做线搜索,找出使下列问题的最小化子 满足 的最小 ,从而得到 的一个近似。
- Minimize subject to
- 最小化 ,约束为
This penalty function method would yield the exact solution for in the case of convex losses, however neural networks are non-convex in general, so we end up with an approximation in this case.
若损失是凸的,这种罚函数方法会给出 的精确解;但神经网络一般是非凸的,因此在这种情形下我们得到的是近似。
4.2 Experimental results
4.2 实验结果
Our "minimimum distortion" function has the following intriguing properties which we will support by informal evidence and quantitative experiments in this section:
我们的“最小失真”(原文作 minimimum distortion)函数 具有下列引人注意的性质,本节将用非正式证据和定量实验来支持它们:
- For all the networks we studied (MNIST, QuocNet [10], AlexNet [9]), for each sample, we have always managed to generate very close, visually hard to distinguish, adversarial examples that are misclassified by the original network (see figure 5 and http://goo.gl/huaGPb for examples).
- 对所有我们研究过的网络(MNIST、QuocNet [10]、AlexNet [9]),对每一个样本,我们总能生成非常接近、视觉上难以分辨、且会被原网络分错的对抗样本(见图 5 以及 http://goo.gl/huaGPb 中的例子)。
- Cross model generalization: a relatively large fraction of examples will be misclassified by networks trained from scratch with different hyper-parameters (number of layers, regularization or initial weights).
- 跨模型泛化:用不同超参数(层数、正则化或初始权重)从头训练的网络,仍会把相当大一部分样本分错。
- Cross training-set generalization a relatively large fraction of examples will be misclassified by networks trained from scratch on a disjoint training set.
- 跨训练集泛化:在不相交的训练集上从头训练的网络,仍会把相当大一部分样本分错。
The above observations suggest that adversarial examples are somewhat universal and not just the results of overfitting to a particular model or to the specific selection of the training set. They also suggest that back-feeding adversarial examples to training might improve generalization of the resulting models. Our preliminary experiments have yielded positive evidence on MNIST to support this hypothesis as well: We have successfully trained a two layer 100-100-10 non-convolutional neural network with a test error below 1.2% by keeping a pool of adversarial examples a random subset of which is continuously replaced by newly generated adversarial examples and which is mixed into the original training set all the time. We used weight decay, but no dropout for this network. For comparison, a network of this size gets to 1.6% errors when regularized by weight decay alone and can be improved to around 1.3% by using carefully applied dropout. A subtle, but essential detail is that we only got improvements by generating adversarial examples for each layer outputs which were used to train all the layers above. The network was trained in an alternating fashion, maintaining and updating a pool of adversarial examples for each layer separately in addition to the original training set. According to our initial observations, adversarial examples for the higher layers seemed to be significantly more useful than those on the input or lower layers. In our future work, we plan to compare these effects in a systematic manner.
上述观察表明,对抗样本在某种程度上是普遍的,而不仅仅是对某一模型或某一特定训练集选择过拟合的结果。它们也提示,把对抗样本回馈到训练中,可能会改善所得模型的泛化。我们在 MNIST 上的初步实验也为这一假设提供了正面证据:我们成功地训练了一个两隐层的 100-100-10 非卷积网络,测试错误率低于 1.2%。做法是维护一个对抗样本池,其中随机一部分不断被新生成的对抗样本替换,并始终混合进原始训练集。该网络使用了权重衰减,但没有使用 dropout。作为对照,同样大小的网络若只用权重衰减正则化,错误率约为 1.6%;仔细使用 dropout 可改善到约 1.3%。一个细微但关键的细节是:只有为每一层的输出生成对抗样本、并用来训练其上的所有层时,我们才得到了改进。网络以交替方式训练,除原始训练集外,还为每一层分别维护和更新一个对抗样本池。按我们最初的观察,较高层的对抗样本似乎比输入层或较低层的对抗样本有用得多。在未来工作中,我们计划系统地比较这些效应。
For space considerations, we just present results for a representative subset (see Table 1) of the MNIST experiments we performed. The results presented here are consistent with those on a larger variety of non-convolutional models. For MNIST, we do not have results for convolutional models yet, but our first qualitative experiments with AlexNet gives us reason to believe that convolutional networks may behave similarly as well. Each of our models were trained with L-BFGS until convergence. The first three models are linear classifiers that work on the pixel level with various weight decay parameters . All our examples use quadratic weight decay on the connection weights: added to the total loss, where is the number of units in the layer. Three of our models are simple linear (softmax) classifier without hidden units (FC10()). One of them, FC10(1), is trained with extremely high in order to test whether it is still possible to generate adversarial examples in this extreme setting as well. Two other models are a simple sigmoidal neural network with two hidden layers and a classifier. The last model, AE400-10, consists of a single layer sparse autoencoder with sigmoid activations and 400 nodes with a Softmax classifier. This network has been trained until it got very high quality first layer filters and this layer was not fine-tuned. The last column measures the minimum average pixel level distortion necessary to reach 0% accuracy on the training set. The distortion is measured by between the original and distorted images, where is the number of image pixels. The pixel intensities are scaled to be in the range .
出于篇幅考虑,我们只给出所做 MNIST 实验中一个有代表性的子集(见表 1)。这里给出的结果,与更多种类非卷积模型上的结果是一致的。在 MNIST 上,我们还没有卷积模型的结果,但对 AlexNet 的初步定性实验让我们有理由相信,卷积网络的行为也可能类似。我们的每个模型都用 L-BFGS 训练到收敛。前三个模型是在像素层面工作的线性分类器,权重衰减参数 各不相同。我们的全部例子都对连接权重使用二次权重衰减:在总损失上加上 ,其中 是该层的单元数。其中三个模型是没有隐单元的简单线性(softmax)分类器(FC10())。其中一个 FC10(1) 用了极高的 来训练,以测试在这种极端设定下是否仍能生成对抗样本。另外两个模型是带两个隐层和分类器的简单 sigmoid 网络。最后一个模型 AE400-10 由一个带 sigmoid 激活、400 个节点的单层稀疏自动编码器加上 Softmax 分类器组成。该网络被训练到第一层滤波器质量很高,并且这一层没有再微调。最后一列度量的是,要使训练集准确率降到 0% 所需的最小平均像素级失真。失真用原始图像 与失真图像 之间的 来衡量,其中 是图像像素数。像素强度被缩放到 范围。
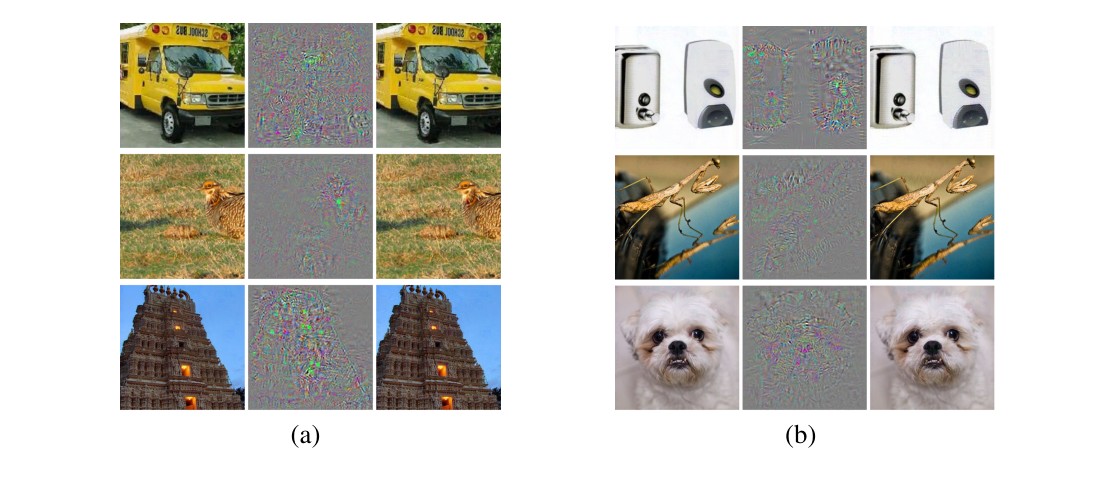
Figure 5: Adversarial examples generated for AlexNet [9].(Left) is a correctly predicted sample, (center) difference between correct image, and image predicted incorrectly magnified by 10x (values shifted by 128 and clamped), (right) adversarial example. All images in the right column are predicted to be an "ostrich, Struthio camelus". Average distortion based on 64 examples is 0.006508. Plase refer to http://goo.gl/huaGPb for full resolution images. The examples are strictly randomly chosen. There is not any postselection involved.
图 5:为 AlexNet [9] 生成的对抗样本。(左)是预测正确的样本,(中)是正确图像与被错误预测的图像之差,放大 10 倍(数值平移 128 并截断),(右)是对抗样本。右列所有图像都被预测为 “ostrich, Struthio camelus”。基于 64 个例子的平均失真为 0.006508。完整分辨率图像请参见 http://goo.gl/huaGPb(原文作 Plase)。这些例子是严格随机选取的,没有做任何事后筛选。
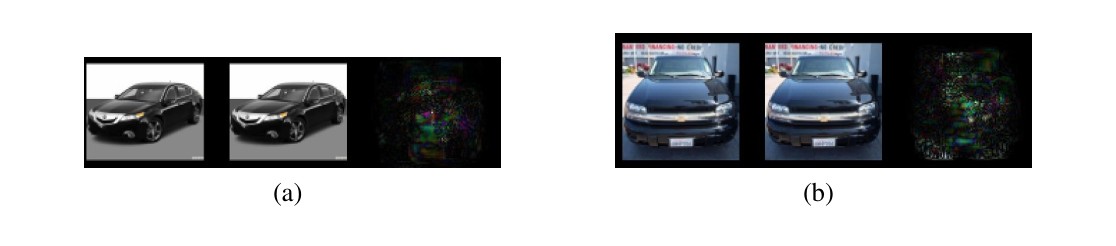
Figure 6: Adversarial examples for QuocNet [10]. A binary car classifier was trained on top of the last layer features without fine-tuning. The randomly chosen examples on the left are recognized correctly as cars, while the images in the middle are not recognized. The rightmost column is the magnified absolute value of the difference between the two images.
图 6:QuocNet [10] 上的对抗样本。在最后一层特征之上训练了一个二分类汽车分类器,没有做微调。左侧随机选取的例子被正确识别为汽车,中间的图像则未被识别。最右列是两张图像之差的放大绝对值。
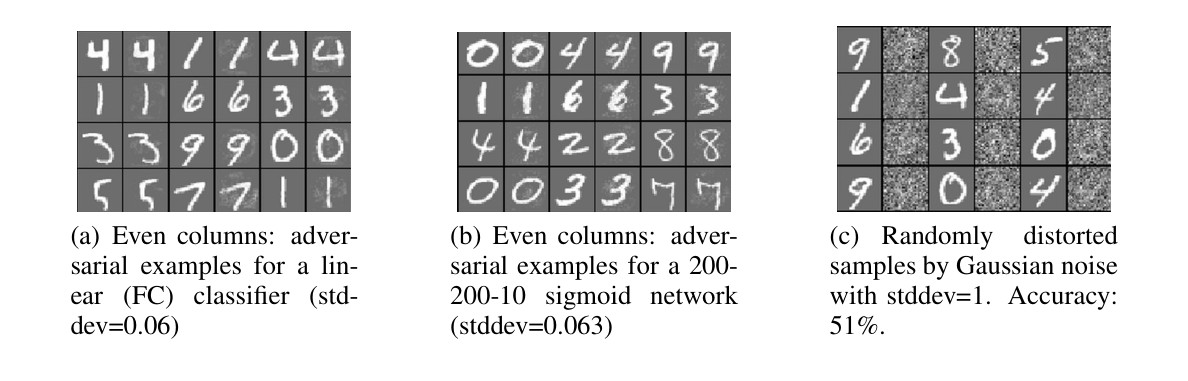
Figure 7: Adversarial examples for a randomly chosen subset of MNIST compared with randomly distorted examples. Odd columns correspond to original images, and even columns correspond to distorted counterparts. The adversarial examples generated for the specific model have accuracy 0% for the respective model. Note that while the randomly distorted examples are hardly readable, still they are classified correctly in half of the cases, while the adversarial examples are never classified correctly.
图 7:在随机选取的 MNIST 子集上,对抗样本与随机失真样本的比较。奇数列对应原始图像,偶数列对应失真后的对应图像。为特定模型生成的对抗样本,在相应模型上的准确率为 0%。注意,随机失真的例子几乎难以辨认,却仍有一半被正确分类,而对抗样本则从未被正确分类。
| Model Name | Description | Training error | Test error | Av. min. distortion |
|---|---|---|---|---|
| FC10() | Softmax with | 6.7% | 7.4% | 0.062 |
| FC10() | Softmax with | 10% | 9.4% | 0.1 |
| FC10(1) | Softmax with | 21.2% | 20% | 0.14 |
| FC100-100-10 | Sigmoid network | 0% | 1.64% | 0.058 |
| FC200-200-10 | Sigmoid network | 0% | 1.54% | 0.065 |
| AE400-10 | Autoencoder with Softmax | 0.57% | 1.9% | 0.086 |
Table 1: Tests of the generalization of adversarial instances on MNIST.
| Model Name | Description | Training error | Test error | Av. min. distortion |
|---|---|---|---|---|
| FC10() | Softmax with | 6.7% | 7.4% | 0.062 |
| FC10() | Softmax with | 10% | 9.4% | 0.1 |
| FC10(1) | Softmax with | 21.2% | 20% | 0.14 |
| FC100-100-10 | Sigmoid network | 0% | 1.64% | 0.058 |
| FC200-200-10 | Sigmoid network | 0% | 1.54% | 0.065 |
| AE400-10 | Autoencoder with Softmax | 0.57% | 1.9% | 0.086 |
表 1:在 MNIST 上对对抗实例泛化的测试。
| FC10() | FC10() | FC10(1) | FC100-100-10 | FC200-200-10 | AE400-10 | Av. distortion | |
|---|---|---|---|---|---|---|---|
| FC10() | 100% | 11.7% | 22.7% | 2% | 3.9% | 2.7% | 0.062 |
| FC10() | 87.1% | 100% | 35.2% | 35.9% | 27.3% | 9.8% | 0.1 |
| FC10(1) | 71.9% | 76.2% | 100% | 48.1% | 47% | 34.4% | 0.14 |
| FC100-100-10 | 28.9% | 13.7% | 21.1% | 100% | 6.6% | 2% | 0.058 |
| FC200-200-10 | 38.2% | 14% | 23.8% | 20.3% | 100% | 2.7% | 0.065 |
| AE400-10 | 23.4% | 16% | 24.8% | 9.4% | 6.6% | 100% | 0.086 |
| Gaussian noise, stddev=0.1 | 5.0% | 10.1% | 18.3% | 0% | 0% | 0.8% | 0.1 |
| Gaussian noise, stddev=0.3 | 15.6% | 11.3% | 22.7% | 5% | 4.3% | 3.1% | 0.3 |
Table 2: Cross-model generalization of adversarial examples. The columns of the Tables show the error induced by distorted examples fed to the given model. The last column shows average distortion wrt. original training set.
| FC10() | FC10() | FC10(1) | FC100-100-10 | FC200-200-10 | AE400-10 | Av. distortion | |
|---|---|---|---|---|---|---|---|
| FC10() | 100% | 11.7% | 22.7% | 2% | 3.9% | 2.7% | 0.062 |
| FC10() | 87.1% | 100% | 35.2% | 35.9% | 27.3% | 9.8% | 0.1 |
| FC10(1) | 71.9% | 76.2% | 100% | 48.1% | 47% | 34.4% | 0.14 |
| FC100-100-10 | 28.9% | 13.7% | 21.1% | 100% | 6.6% | 2% | 0.058 |
| FC200-200-10 | 38.2% | 14% | 23.8% | 20.3% | 100% | 2.7% | 0.065 |
| AE400-10 | 23.4% | 16% | 24.8% | 9.4% | 6.6% | 100% | 0.086 |
| Gaussian noise, stddev=0.1 | 5.0% | 10.1% | 18.3% | 0% | 0% | 0.8% | 0.1 |
| Gaussian noise, stddev=0.3 | 15.6% | 11.3% | 22.7% | 5% | 4.3% | 3.1% | 0.3 |
表 2:对抗样本的跨模型泛化。表中各列给出把失真样本送入给定模型所造成的错误率。最后一列给出相对于原始训练集的平均失真。
In our first experiment, we generated a set of adversarial instances for a given network and fed these examples for each other network to measure the proportion of misclassified instances. The last column shows the average minimum distortion that was necessary to reach 0% accuracy on the whole training set. The experimental results are presented in Table 2. The columns of Table 2 show the error (proportion of misclassified instances) on the so distorted training sets. The last two rows are given for reference showing the error induced when distorting by the given amounts of Gaussian noise. Note that even the noise with stddev 0.1 is greater than the stddev of our adversarial noise for all but one of the models. Figure 7 shows a visualization of the generated adversarial instances for two of the networks used in this experiment. The general conclusion is that adversarial examples tend to stay hard even for models trained with different hyperparameters. Although the autoencoder based version seems most resilient to adversarial examples, it is not fully immune either.
在第一个实验中,我们为给定网络生成一组对抗实例,再把这些例子送到其他各个网络上,以度量被分错的比例。最后一列给出使整个训练集准确率降到 0% 所需的平均最小失真。实验结果见表 2。表 2 的各列给出在如此失真的训练集上的错误率(被分错实例的比例)。最后两行作为参照,给出按指定幅度施加高斯噪声时所造成的错误率。注意,即使标准差为 0.1 的噪声,也已经大于除一个模型外所有模型上我们对抗噪声的标准差。图 7 展示了本实验中两个网络所生成对抗实例的可视化。总的结论是:即使对用不同超参数训练的模型,对抗样本往往仍然困难。基于自动编码器的版本看起来对对抗样本最有抵抗力,但也并非完全免疫。
Still, this experiment leaves open the question of dependence over the training set. Does the hardness of the generated examples rely solely on the particular choice of our training set as a sample or does this effect generalize even to models trained on completely different training sets?
不过,这一实验仍未回答对训练集的依赖问题。所生成例子的困难,是否仅仅依赖于我们把训练集当作样本的这一特定选择,还是这一效应甚至可以推广到在完全不同的训练集上训练出来的模型?
| Model | Error on | Error on | Error on Test | Min Av. Distortion |
|---|---|---|---|---|
| FC100-100-10: 100-100-10 trained on | 0% | 2.4% | 2% | 0.062 |
| FC123-456-10: 123-456-10 trained on | 0% | 2.5% | 2.1% | 0.059 |
| FC100-100-10' trained on | 2.3% | 0% | 2.1% | 0.058 |
Table 3: Models trained to study cross-training-set generalization of the generated adversarial examples. Errors presented in Table correpond to original not-distorted data, to provide a baseline.
| Model | Error on | Error on | Error on Test | Min Av. Distortion |
|---|---|---|---|---|
| FC100-100-10: 100-100-10 trained on | 0% | 2.4% | 2% | 0.062 |
| FC123-456-10: 123-456-10 trained on | 0% | 2.5% | 2.1% | 0.059 |
| FC100-100-10' trained on | 2.3% | 0% | 2.1% | 0.058 |
表 3:为研究所生成对抗样本的跨训练集泛化而训练的模型。表中给出的错误率对应于未被失真的原始数据,用作基线(原文作 correpond)。
| FC100-100-10 | FC123-456-10 | FC100-100-10' | |
|---|---|---|---|
| Distorted for FC100-100-10 (av. stddev=0.062) | 100% | 26.2% | 5.9% |
| Distorted for FC123-456-10 (av. stddev=0.059) | 6.25% | 100% | 5.1% |
| Distorted for FC100-100-10' (av. stddev=0.058) | 8.2% | 8.2% | 100% |
| Gaussian noise with stddev=0.06 | 2.2% | 2.6% | 2.4% |
| Distorted for FC100-100-10 amplified to stddev=0.1 | 100% | 98% | 43% |
| Distorted for FC123-456-10 amplified to stddev=0.1 | 96% | 100% | 22% |
| Distorted for FC100-100-10' amplified to stddev=0.1 | 27% | 50% | 100% |
| Gaussian noise with stddev=0.1 | 2.6% | 2.8% | 2.7% |
Table 4: Cross-training-set generalization error rate for the set of adversarial examples generated for different models. The error induced by a random distortion to the same examples is displayed in the last row.
| FC100-100-10 | FC123-456-10 | FC100-100-10' | |
|---|---|---|---|
| Distorted for FC100-100-10 (av. stddev=0.062) | 100% | 26.2% | 5.9% |
| Distorted for FC123-456-10 (av. stddev=0.059) | 6.25% | 100% | 5.1% |
| Distorted for FC100-100-10' (av. stddev=0.058) | 8.2% | 8.2% | 100% |
| Gaussian noise with stddev=0.06 | 2.2% | 2.6% | 2.4% |
| Distorted for FC100-100-10 amplified to stddev=0.1 | 100% | 98% | 43% |
| Distorted for FC123-456-10 amplified to stddev=0.1 | 96% | 100% | 22% |
| Distorted for FC100-100-10' amplified to stddev=0.1 | 27% | 50% | 100% |
| Gaussian noise with stddev=0.1 | 2.6% | 2.8% | 2.7% |
表 4:为不同模型生成的对抗样本集合上的跨训练集泛化错误率。对同样这些例子施加随机失真所造成的错误率列在最后一行。
To study cross-training-set generalization, we have partitioned the 60000 MNIST training images into two parts and of size 30000 each and trained three non-convolutional networks with sigmoid activations on them: Two, FC100-100-10 and FC123-456-10, on and FC100-100-10 on . The reason we trained two networks for is to study the cumulative effect of changing the hypermarameters and the training sets at the same time. Models FC100-100-10 and FC100-100-10' share the same hyperparameters: both of them are 100-100-10 networks, while FC123-456-10 has different number of hidden units. In this experiment, we were distorting the elements of the test set rather than the training set. Table 3 summarizes the basic facts about these models. After we generate adversarial examples with 100% error rates with minimum distortion for the test set, we feed these examples to the each of the models. The error for each model is displayed in the corresponding column of the upper part of Table 4. In the last experiment, we magnify the effect of our distortion by using the examples rather than . This magnifies the distortion on average by 40%, from stddev 0.06 to 0.1. The so distorted examples are fed back to each of the models and the error rates are displayed in the lower part of Table 4. The intriguing conclusion is that the adversarial examples remain hard for models trained even on a disjoint training set, although their effectiveness decreases considerably.
为研究跨训练集泛化,我们把 60000 张 MNIST 训练图像分成大小各为 30000 的两部分 和 ,并在其上训练了三个带 sigmoid 激活的非卷积网络:两个在 上训练,分别是 FC100-100-10 和 FC123-456-10;一个在 上训练,是 FC100-100-10。我们在 上训练两个网络,是为了同时改变超参数(原文作 hypermarameters)和训练集时的累积效应。模型 FC100-100-10 与 FC100-100-10' 共享同一组超参数:二者都是 100-100-10 网络,而 FC123-456-10 的隐单元数不同。在这一实验中,我们失真的是测试集中的元素,而不是训练集。表 3 汇总了这些模型的基本事实。我们在测试集上以最小失真生成错误率为 100% 的对抗样本后,再把这些例子送到各个模型上。每个模型的错误率列在表 4 上半部分的相应列中。在最后一个实验里,我们改用 而不是 ,以放大失真的效果。这平均把失真放大了 40%,标准差从 0.06 增到 0.1。如此失真的例子再送回各个模型,错误率列在表 4 的下半部分。一个引人注意的结论是:即使对在不相交训练集上训练出来的模型,对抗样本仍然困难,只是有效程度明显下降。
4.3 Spectral Analysis of Unstability
4.3 不稳定性的谱分析
The previous section showed examples of deep networks resulting from purely supervised training which are unstable with respect to a peculiar form of small perturbations. Independently of their generalisation properties across networks and training sets, the adversarial examples show that there exist small additive perturbations of the input (in Euclidean sense) that produce large perturbations at the output of the last layer. This section describes a simple procedure to measure and control the additive stability of the network by measuring the spectrum of each rectified layer.
上一节给出了一些纯有监督训练得到的深度网络的例子,它们对一种特殊形式的小扰动是不稳定的。且不论它们在不同网络和训练集之间的泛化性质,这些对抗样本表明:存在(欧氏意义下)很小的输入加性扰动,却会在最后一层的输出上产生很大的扰动。本节描述一个简单步骤,通过度量每一层整流层的谱,来测量并控制网络的加性稳定性。
Mathematically, if denotes the output of a network of layers corresponding to input and trained parameters , we write
在数学上,若 表示一个 层网络在输入 和训练参数 下的输出,我们写成
where denotes the operator mapping layer to layer . The unstability of can be explained by inspecting the upper Lipschitz constant of each layer , defined as the constant such that . The resulting network thus satsifies , with .
其中 表示把第 层映射到第 层的算子。 的不稳定性可以通过考察每一层 的 Lipschitz 上界常数来解释,该常数定义为满足 的 。于是整个网络满足 ,其中 (原文作 satsifies)。
A half-rectified layer (both convolutional or fully connected) is defined by the mapping . Let denote the operator norm of (i.e., its largest singular value). Since the non-linearity is contractive, i.e. satisfies for all ; it follows that
半整流层(无论是卷积还是全连接)由映射 定义。设 表示 的算子范数(即其最大奇异值)。由于非线性 是收缩的,即对所有 满足 ,于是有
and hence . On the other hand, a max-pooling layer is contractive: , since its Jacobian is a projection onto a subset of the input coordinates and hence does not expand the gradients. Finally, if is a contrast-normalization layer , one can verify that for , which corresponds to most common operating regimes.
从而 。另一方面,最大池化层 是收缩的:,因为它的雅可比是到输入坐标某个子集上的投影,因而不会放大梯度。最后,若 是对比度归一化层 ,可以验证当 时,,而这正对应大多数常见的工作区间。
It results that a conservative measure of the unstability of the network can be obtained by simply computing the operator norm of each fully connected and convolutional layer. The fully connected case is trivial since the norm is directly given by the largest singular value of the fully connected matrix. Let us describe the convolutional case. If denotes a generic 4-tensor, implementing a convolutional layer with input features, output features, support and spatial stride ,
由此,只需计算每个全连接层和卷积层的算子范数,就可以得到网络不稳定性的一个保守度量。全连接情形是平凡的,因为范数直接由全连接矩阵的最大奇异值给出。下面描述卷积情形。设 表示一个一般的 4 阶张量,实现一个具有 个输入特征、 个输出特征、支撑为 、空间步幅为 的卷积层,
where denotes the -th input feature image, and is the spatial kernel corresponding to input feature and output feature , by applying Parseval's formula we obtain that its operator norm is given by
其中 表示第 个输入特征图像, 是与输入特征 、输出特征 对应的空间核。应用 Parseval 公式,得到其算子范数为
where is a matrix whose rows are
其中 是一个 矩阵,其各行为
and is the 2-D Fourier transform of :
而 是 的二维傅里叶变换:
| Layer | Size | Stride | Upper bound |
|---|---|---|---|
| Conv. 1 | 4 | 2.75 | |
| Conv. 2 | 1 | 10 | |
| Conv. 3 | 1 | 7 | |
| Conv. 4 | 1 | 7.5 | |
| Conv. 5 | 1 | 11 | |
| FC. 1 | N/A | 3.12 | |
| FC. 2 | N/A | 4 | |
| FC. 3 | N/A | 4 |
Table 5: Frame Bounds of each rectified layer of the network from [9].
| Layer | Size | Stride | Upper bound |
|---|---|---|---|
| Conv. 1 | 4 | 2.75 | |
| Conv. 2 | 1 | 10 | |
| Conv. 3 | 1 | 7 | |
| Conv. 4 | 1 | 7.5 | |
| Conv. 5 | 1 | 11 | |
| FC. 1 | N/A | 3.12 | |
| FC. 2 | N/A | 4 | |
| FC. 3 | N/A | 4 |
表 5:来自 [9] 的网络中各整流层的框架界。
Table 5 shows the upper Lipschitz bounds computed from the ImageNet deep convolutional network of [9], using (1). It shows that instabilities can appear as soon as in the first convolutional layer.
表 5 给出了用 (1) 式、从 [9] 的 ImageNet 深度卷积网络算出的 Lipschitz 上界。它表明,不稳定性最早在第一层卷积层就可能出现。
These results are consistent with the exsitence of blind spots constructed in the previous section, but they don't attempt to explain why these examples generalize across different hyperparameters or training sets. We emphasize that we compute upper bounds: large bounds do not automatically translate into existence of adversarial examples; however, small bounds guarantee that no such examples can appear. This suggests a simple regularization of the parameters, consisting in penalizing each upper Lipschitz bound, which might help improve the generalisation error of the networks.
这些结果与上一节构造出盲区的存在(原文作 exsitence)是一致的,但它们并不试图解释这些例子为何能在不同超参数或训练集之间泛化。我们强调,我们计算的是上界:大的上界并不自动意味着对抗样本存在;然而,小的上界可以保证不会出现这类例子。这提示了一种简单的参数正则化:对每一个 Lipschitz 上界加以惩罚,这可能有助于改善网络的泛化误差。
5 Discussion
5 讨论
We demonstrated that deep neural networks have counter-intuitive properties both with respect to the semantic meaning of individual units and with respect to their discontinuities. The existence of the adversarial negatives appears to be in contradiction with the network's ability to achieve high generalization performance. Indeed, if the network can generalize well, how can it be confused by these adversarial negatives, which are indistinguishable from the regular examples? Possible explanation is that the set of adversarial negatives is of extremely low probability, and thus is never (or rarely) observed in the test set, yet it is dense (much like the rational numbers), and so it is found near every virtually every test case. However, we don't have a deep understanding of how often adversarial negatives appears, and thus this issue should be addressed in a future research.
我们表明,深度神经网络无论是在单个单元的语义上,还是在其不连续性上,都具有反直觉的性质。对抗性负例的存在,看起来与网络能够达到很高泛化性能这一点相矛盾。的确,如果网络能够很好地泛化,又怎么会被这些与常规例子无法分辨的对抗性负例所迷惑?一种可能的解释是:对抗性负例的集合概率极低,因而在测试集中从未(或很少)被观察到,但它又是稠密的(很像有理数),因此几乎在每一个测试样本附近都能找到。不过,我们还没有深入理解对抗性负例出现的频率,因此这一问题应在未来研究中加以讨论。
References
参考文献
[1] David Baehrens, Timon Schroeter, Stefan Harmeling, Motoaki Kawanabe, Katja Hansen, and Klaus-Robert Müller. How to explain individual classification decisions. The Journal of Machine Learning Research, 99:1803–1831, 2010.
[2] Yoshua Bengio. Learning deep architectures for ai. Foundations and trends® in Machine Learning, 2(1):1–127, 2009.
[3] Jia Deng, Wei Dong, Richard Socher, Li-Jia Li, Kai Li, and Li Fei-Fei. Imagenet: A large-scale hierarchical image database. In Computer Vision and Pattern Recognition, 2009. CVPR 2009. IEEE Conference on, pages 248–255. IEEE, 2009.
[4] Dumitru Erhan, Yoshua Bengio, Aaron Courville, and Pascal Vincent. Visualizing higher-layer features of a deep network. Technical Report 1341, University of Montreal, June 2009. Also presented at the ICML 2009 Workshop on Learning Feature Hierarchies, Montréal, Canada.
[5] Pedro Felzenszwalb, David McAllester, and Deva Ramanan. A discriminatively trained, multiscale, deformable part model. In Computer Vision and Pattern Recognition, 2008. CVPR 2008. IEEE Conference on, pages 1–8. IEEE, 2008.
[6] Ross Girshick, Jeff Donahue, Trevor Darrell, and Jitendra Malik. Rich feature hierarchies for accurate object detection and semantic segmentation. arXiv preprint arXiv:1311.2524, 2013.
[7] Ian Goodfellow, Quoc Le, Andrew Saxe, Honglak Lee, and Andrew Y Ng. Measuring invariances in deep networks. Advances in neural information processing systems, 22:646–654, 2009.
[8] Geoffrey E. Hinton, Li Deng, Dong Yu, George E. Dahl, Abdel rahman Mohamed, Navdeep Jaitly, Andrew Senior, Vincent Vanhoucke, Patrick Nguyen, Tara N. Sainath, and Brian Kingsbury. Deep neural networks for acoustic modeling in speech recognition: The shared views of four research groups. IEEE Signal Process. Mag., 29(6):82–97, 2012.
[9] Alex Krizhevsky, Ilya Sutskever, and Geoff Hinton. Imagenet classification with deep convolutional neural networks. In Advances in Neural Information Processing Systems 25, pages 1106–1114, 2012.
[10] Quoc V Le, Marc’Aurelio Ranzato, Rajat Monga, Matthieu Devin, Kai Chen, Greg S Corrado, Jeff Dean, and Andrew Y Ng. Building high-level features using large scale unsupervised learning. arXiv preprint arXiv:1112.6209, 2011.
[11] Yann LeCun and Corinna Cortes. The mnist database of handwritten digits, 1998.
[12] Tomas Mikolov, Kai Chen, Greg Corrado, and Jeffrey Dean. Efficient estimation of word representations in vector space. arXiv preprint arXiv:1301.3781, 2013.
[13] Matthew D Zeiler and Rob Fergus. Visualizing and understanding convolutional neural networks. arXiv preprint arXiv:1311.2901, 2013.