Going deeper with convolutions
Going deeper with convolutions
走向更深的卷积
Christian Szegedy Affiliation: Google Inc. Wei Liu Affiliation: University of North Carolina, Chapel Hill Yangqing Jia Affiliation: Google Inc. Pierre Sermanet Affiliation: Google Inc. Scott Reed Affiliation: University of Michigan Dragomir Anguelov Affiliation: Google Inc. Dumitru Erhan Affiliation: Google Inc. Vincent Vanhoucke Affiliation: Google Inc. Andrew Rabinovich Affiliation: Google Inc.
Abstract
摘要
We propose a deep convolutional neural network architecture codenamed “Inception”, which was responsible for setting the new state of the art for classification and detection in the ImageNet Large-Scale Visual Recognition Challenge 2014 (ILSVRC’14). The main hallmark of this architecture is the improved utilization of the computing resources inside the network. This was achieved by a carefully crafted design that allows for increasing the depth and width of the network while keeping the computational budget constant. To optimize quality, the architectural decisions were based on the Hebbian principle and the intuition of multi-scale processing. One particular incarnation used in our submission for ILSVRC’14 is called GoogLeNet, a 22 layers deep network, the quality of which is assessed in the context of classification and detection.
我们提出一种代号为「Inception」的深度卷积神经网络结构,它在 ImageNet 大规模视觉识别挑战赛 2014(ILSVRC’14)上刷新了分类与检测的当时最优。该结构的主要特征是更充分地利用网络内部的计算资源:通过精心设计,在计算预算保持不变的前提下同时加深、加宽网络。为优化质量,结构决策依据 Hebb 原则与多尺度处理直觉。我们在 ILSVRC’14 提交中使用的具体实现称为 GoogLeNet,是一个 22 层深的网络;本文在分类与检测情境下评估其质量。
1 Introduction
1 引言
In the last three years, mainly due to the advances of deep learning, more concretely convolutional networks [10], the quality of image recognition and object detection has been progressing at a dramatic pace. One encouraging news is that most of this progress is not just the result of more powerful hardware, larger datasets and bigger models, but mainly a consequence of new ideas, algorithms and improved network architectures. No new data sources were used, for example, by the top entries in the ILSVRC 2014 competition besides the classification dataset of the same competition for detection purposes. Our GoogLeNet submission to ILSVRC 2014 actually uses fewer parameters than the winning architecture of Krizhevsky et al [9] from two years ago, while being significantly more accurate. The biggest gains in object-detection have not come from the utilization of deep networks alone or bigger models, but from the synergy of deep architectures and classical computer vision, like the R-CNN algorithm by Girshick et al [6].
过去三年,主要由于深度学习——更具体地说是卷积网络 [10]——的进展,图像识别与目标检测质量以惊人速度提升。令人鼓舞的是,多数进步并不只来自更强硬件、更大数据与更大模型,而主要来自新想法、新算法与更好的网络结构。例如 ILSVRC 2014 检测赛道的顶尖条目并未使用新的数据源,分类数据之外也未另找检测专用库。我们提交的 GoogLeNet 参数量约为两年前 Krizhevsky 等 [9] 夺冠结构的 ,精度却明显更高。目标检测上的最大收益,也并非单靠更深网络或更大模型,而是深度结构与经典视觉方法的协同,例如 Girshick 等 [6] 的 R-CNN。
Another notable factor is that with the ongoing traction of mobile and embedded computing, the efficiency of our algorithms – especially their power and memory use – gains importance. It is noteworthy that the considerations leading to the design of the deep architecture presented in this paper included this factor rather than having a sheer fixation on accuracy numbers. For most of the experiments, the models were designed to keep a computational budget of billion multiply-adds at inference time, so that the they do not end up to be a purely academic curiosity, but could be put to real world use, even on large datasets, at a reasonable cost.
另一值得注意的因素是:随着移动与嵌入式计算持续升温,算法效率——尤其是功耗与内存——愈发重要。本文深度结构的设计考量包含这一因素,而非只盯着精度数字。多数实验中,模型被设计为推理时约 亿次乘加的计算预算,从而不致沦为纯学术好奇,而能以合理成本用于真实场景乃至大规模数据。
In this paper, we will focus on an efficient deep neural network architecture for computer vision, codenamed “Inception”, which derives its name from the “Network in network” paper by Lin et al [12] in conjunction with the famous “we need to go deeper” internet meme [1]. In our case, the word “deep” is used in two different meanings: first of all, in the sense that we introduce a new level of organization in the form of the “Inception module” and also in the more direct sense of increased network depth. In general, one can view the Inception model as a logical culmination of [12] while taking inspiration and guidance from the theoretical work by Arora et al [2]. The benefits of the architecture are experimentally verified on the ILSVRC 2014 classification and detection challenges, on which it significantly outperforms the current state of the art.
本文将聚焦一种面向计算机视觉的高效深度网络结构,代号「Inception」:名称来自 Lin 等 [12] 的「Network in network」论文,并呼应著名的「we need to go deeper」网络梗 [1]。此处「深」有两层含义:一是引入「Inception 模块」这一新的组织层级;二是网络深度本身增加。总体而言,可把 Inception 模型看作 [12] 的逻辑延伸,同时汲取 Arora 等 [2] 理论工作的启发与指引。其收益在 ILSVRC 2014 分类与检测挑战上得到实验验证,并显著超过当时最优。
2 Related Work
2 相关工作
Starting with LeNet-5 [10], convolutional neural networks (CNN) have typically had a standard structure – stacked convolutional layers (optionally followed by contrast normalization and max-pooling) are followed by one or more fully-connected layers. Variants of this basic design are prevalent in the image classification literature and have yielded the best results to-date on MNIST, CIFAR and most notably on the ImageNet classification challenge [9, 21]. For larger datasets such as Imagenet, the recent trend has been to increase the number of layers [12] and layer size [21, 14], while using dropout [7] to address the problem of overfitting.
自 LeNet-5 [10] 起,卷积神经网络(CNN)通常呈标准结构——堆叠的卷积层(可选地接对比度归一化与最大池化),再接一个或多个全连接层。这一基本设计的变体遍布图像分类文献,并在 MNIST、CIFAR 以及尤其是 ImageNet 分类挑战上取得当时最佳结果 [9, 21]。对 ImageNet 这类更大数据集,近期趋势是增加层数 [12] 与层宽 [21, 14],并用 dropout [7] 应对过拟合。
Despite concerns that max-pooling layers result in loss of accurate spatial information, the same convolutional network architecture as [9] has also been successfully employed for localization [9, 14], object detection [6, 14, 18, 5] and human pose estimation [19]. Inspired by a neuroscience model of the primate visual cortex, Serre et al. [15] use a series of fixed Gabor filters of different sizes in order to handle multiple scales, similarly to the Inception model. However, contrary to the fixed 2-layer deep model of [15], all filters in the Inception model are learned. Furthermore, Inception layers are repeated many times, leading to a 22-layer deep model in the case of the GoogLeNet model.
尽管有人担心最大池化会损失精确空间信息,与 [9] 相同的卷积网络结构仍成功用于定位 [9, 14]、目标检测 [6, 14, 18, 5] 与人体姿态估计 [19]。受灵长类视觉皮层神经科学模型启发,Serre 等 [15] 使用一系列不同尺寸的固定 Gabor 滤波器以处理多尺度,思路与 Inception 相近。但与 [15] 那两层固定模型不同,Inception 中所有滤波器均学习得到;并且 Inception 层被多次重复,GoogLeNet 达到 22 层深。
Network-in-Network is an approach proposed by Lin et al. [12] in order to increase the representational power of neural networks. When applied to convolutional layers, the method could be viewed as additional convolutional layers followed typically by the rectified linear activation [9]. This enables it to be easily integrated in the current CNN pipelines. We use this approach heavily in our architecture. However, in our setting, convolutions have dual purpose: most critically, they are used mainly as dimension reduction modules to remove computational bottlenecks, that would otherwise limit the size of our networks. This allows for not just increasing the depth, but also the width of our networks without significant performance penalty.
Network-in-Network 由 Lin 等 [12] 提出,用以提升神经网络的表示能力。用到卷积层时,该方法可看作额外的 卷积,通常再接整流线性激活 [9],因而易于嵌入现有 CNN 管线。我们在结构中大量使用这一做法。但在我们的设定里, 卷积身兼二职:最关键的是作为降维模块,去掉本会限制网络规模的计算瓶颈。如此一来,网络深度与宽度都可显著增加,而不致付出过大性能代价。
The current leading approach for object detection is the Regions with Convolutional Neural Networks (R-CNN) proposed by Girshick et al. [6]. R-CNN decomposes the overall detection problem into two subproblems: to first utilize low-level cues such as color and superpixel consistency for potential object proposals in a category-agnostic fashion, and to then use CNN classifiers to identify object categories at those locations. Such a two stage approach leverages the accuracy of bounding box segmentation with low-level cues, as well as the highly powerful classification power of state-of-the-art CNNs. We adopted a similar pipeline in our detection submissions, but have explored enhancements in both stages, such as multi-box [5] prediction for higher object bounding box recall, and ensemble approaches for better categorization of bounding box proposals.
当前领先的目标检测路径是 Girshick 等 [6] 提出的 Regions with Convolutional Neural Networks(R-CNN)。R-CNN 把检测拆成两步:先用颜色、超像素一致性等低层线索,以类别无关方式提出潜在目标;再用 CNN 分类器在这些位置识别类别。两阶段路径同时利用低层线索的框分割精度与当代 CNN 的强分类力。我们的检测提交采用类似管线,但在两阶段都做了增强,例如用 multi-box [5] 预测提高框召回,并用集成改善对提议框的分类。
3 Motivation and High Level Considerations
3 动机与高层考量
The most straightforward way of improving the performance of deep neural networks is by increasing their size. This includes both increasing the depth – the number of levels – of the network and its width: the number of units at each level. This is as an easy and safe way of training higher quality models, especially given the availability of a large amount of labeled training data. However this simple solution comes with two major drawbacks.
提升深度网络性能最直接的办法是加大规模:既加深——增加层级数——也加宽——增加每层单元数。在有大量标注训练数据时,这是训练更高质量模型的简便且稳妥途径。但这一简单方案有两大缺点。
Bigger size typically means a larger number of parameters, which makes the enlarged network more prone to overfitting, especially if the number of labeled examples in the training set is limited. This can become a major bottleneck, since the creation of high quality training sets can be tricky and expensive, especially if expert human raters are necessary to distinguish between fine-grained visual categories like those in ImageNet (even in the 1000-class ILSVRC subset) as demonstrated by Figure 1.
更大通常意味着更多参数,从而更容易过拟合,尤其当训练集标注样本有限时。高质量训练集的构建可能棘手且昂贵,特别是在需要专家区分细粒度视觉类别时(即便是 ImageNet 的 1000 类 ILSVRC 子集),如图 1 所示,这会成为主要瓶颈。
(a) Siberian husky
(a)西伯利亚哈士奇
Another drawback of uniformly increased network size is the dramatically increased use of computational resources. For example, in a deep vision network, if two convolutional layers are chained, any uniform increase in the number of their filters results in a quadratic increase of computation. If the added capacity is used inefficiently (for example, if most weights end up to be close to zero), then a lot of computation is wasted. Since in practice the computational budget is always finite, an efficient distribution of computing resources is preferred to an indiscriminate increase of size, even when the main objective is to increase the quality of results.
均匀加大网络规模的另一缺点是计算资源消耗急剧上升。例如在深度视觉网络中,若两层卷积串联,滤波器数的任何均匀增加都会使计算量近似二次增长。若新增容量利用低效(例如多数权重接近零),大量计算就被浪费。实践中计算预算总是有限的,因此即便目标是提高结果质量,也更宜高效分配计算资源,而非不加分辨地加大规模。
The fundamental way of solving both issues would be by ultimately moving from fully connected to sparsely connected architectures, even inside the convolutions. Besides mimicking biological systems, this would also have the advantage of firmer theoretical underpinnings due to the groundbreaking work of Arora et al. [2]. Their main result states that if the probability distribution of the data-set is representable by a large, very sparse deep neural network, then the optimal network topology can be constructed layer by layer by analyzing the correlation statistics of the activations of the last layer and clustering neurons with highly correlated outputs. Although the strict mathematical proof requires very strong conditions, the fact that this statement resonates with the well known Hebbian principle – neurons that fire together, wire together – suggests that the underlying idea is applicable even under less strict conditions, in practice.
同时解决这两个问题的根本途径,终究是从全连接到稀疏连接结构——即便在卷积内部亦然。这既模仿生物系统,也因 Arora 等 [2] 的开创性工作而有更坚实的理论支撑。其主要结论是:若数据集的概率分布可由一个很大、非常稀疏的深度网络表示,则可逐层分析上一层激活的相关统计,并把输出高度相关的神经元聚类,从而构造最优网络拓扑。严格数学证明需要很强条件,但该陈述与著名的 Hebb 原则——一起放电的神经元连在一起——相呼应,暗示其思想在实践中、在较弱条件下仍可适用。
On the downside, today’s computing infrastructures are very inefficient when it comes to numerical calculation on non-uniform sparse data structures. Even if the number of arithmetic operations is reduced by , the overhead of lookups and cache misses is so dominant that switching to sparse matrices would not pay off. The gap is widened even further by the use of steadily improving, highly tuned, numerical libraries that allow for extremely fast dense matrix multiplication, exploiting the minute details of the underlying CPU or GPU hardware [16, 9]. Also, non-uniform sparse models require more sophisticated engineering and computing infrastructure. Most current vision oriented machine learning systems utilize sparsity in the spatial domain just by the virtue of employing convolutions. However, convolutions are implemented as collections of dense connections to the patches in the earlier layer. ConvNets have traditionally used random and sparse connection tables in the feature dimensions since [11] in order to break the symmetry and improve learning, the trend changed back to full connections with [9] in order to better optimize parallel computing. The uniformity of the structure and a large number of filters and greater batch size allow for utilizing efficient dense computation.
不利的一面是:当今计算基础设施在非均匀稀疏数据结构上的数值计算非常低效。即便算术运算减少 ,查找与缓存未命中的开销仍常占主导,切换到稀疏矩阵往往不划算。高度调优、可极快做稠密矩阵乘的数值库进一步拉大差距,它们吃透了底层 CPU/GPU 硬件细节 [16, 9]。非均匀稀疏模型还需要更复杂的工程与计算基础设施。多数面向视觉的机器学习系统只是凭卷积在空间域利用了稀疏性;卷积对前一层的图块却仍以稠密连接集合来实现。自 [11] 以来,ConvNet 传统上在特征维使用随机稀疏连接表以打破对称、改善学习;到 [9] 又回到全连接,以便更好优化并行计算。结构的均匀性、大量滤波器与更大 batch,才使高效稠密计算成为可能。
This raises the question whether there is any hope for a next, intermediate step: an architecture that makes use of the extra sparsity, even at filter level, as suggested by the theory, but exploits our current hardware by utilizing computations on dense matrices. The vast literature on sparse matrix computations (e.g. [3]) suggests that clustering sparse matrices into relatively dense submatrices tends to give state of the art practical performance for sparse matrix multiplication. It does not seem far-fetched to think that similar methods would be utilized for the automated construction of non-uniform deep-learning architectures in the near future.
这就引出问题:是否存在一个中间步骤——按理论在滤波器层面利用额外稀疏性,却仍用稠密矩阵计算以适配现有硬件?稀疏矩阵计算的大量文献(如 [3])表明:把稀疏矩阵聚成相对稠密的子矩阵,往往能给出稀疏矩阵乘的实用最优。不难设想,不久的将来自动化构造非均匀深度学习结构时也会用到类似方法。
The Inception architecture started out as a case study of the first author for assessing the hypothetical output of a sophisticated network topology construction algorithm that tries to approximate a sparse structure implied by [2] for vision networks and covering the hypothesized outcome by dense, readily available components. Despite being a highly speculative undertaking, only after two iterations on the exact choice of topology, we could already see modest gains against the reference architecture based on [12]. After further tuning of learning rate, hyperparameters and improved training methodology, we established that the resulting Inception architecture was especially useful in the context of localization and object detection as the base network for [6] and [5]. Interestingly, while most of the original architectural choices have been questioned and tested thoroughly, they turned out to be at least locally optimal.
Inception 结构起初是第一作者的案例研究:评估一种试图逼近 [2] 所蕴含的视觉网络稀疏结构、再用现成稠密组件覆盖的「精巧拓扑构造算法」的假想输出。尽管高度投机,在精确拓扑只迭代两轮后,相对基于 [12] 的参考结构已可见温和收益。再经学习率、超参与训练方法调优,我们确认所得 Inception 结构在定位与目标检测中作为 [6] 与 [5] 的基干网络尤其有用。有趣的是,尽管原始结构选择多数被反复质疑与检验,它们至少在局部是最优的。
One must be cautious though: although the proposed architecture has become a success for computer vision, it is still questionable whether its quality can be attributed to the guiding principles that have lead to its construction. Making sure would require much more thorough analysis and verification: for example, if automated tools based on the principles described below would find similar, but better topology for the vision networks. The most convincing proof would be if an automated system would create network topologies resulting in similar gains in other domains using the same algorithm but with very differently looking global architecture. At very least, the initial success of the Inception architecture yields firm motivation for exciting future work in this direction.
仍须谨慎:尽管该结构在计算机视觉上已获成功,其质量能否归因于引导其构造的原则仍存疑。要确认需要更彻底的分析与验证:例如,基于下述原则的自动化工具是否会为视觉网络找到相似但更好的拓扑。最有说服力的证明是:同一算法在其他领域生成外观很不相同的全局结构,却带来类似收益。至少,Inception 的初步成功为这一方向的未来工作提供了坚实动机。
4 Architectural Details
4 结构细节
The main idea of the Inception architecture is based on finding out how an optimal local sparse structure in a convolutional vision network can be approximated and covered by readily available dense components. Note that assuming translation invariance means that our network will be built from convolutional building blocks. All we need is to find the optimal local construction and to repeat it spatially. Arora et al. [2] suggests a layer-by layer construction in which one should analyze the correlation statistics of the last layer and cluster them into groups of units with high correlation. These clusters form the units of the next layer and are connected to the units in the previous layer. We assume that each unit from the earlier layer corresponds to some region of the input image and these units are grouped into filter banks. In the lower layers (the ones close to the input) correlated units would concentrate in local regions. This means, we would end up with a lot of clusters concentrated in a single region and they can be covered by a layer of convolutions in the next layer, as suggested in [12]. However, one can also expect that there will be a smaller number of more spatially spread out clusters that can be covered by convolutions over larger patches, and there will be a decreasing number of patches over larger and larger regions. In order to avoid patch-alignment issues, current incarnations of the Inception architecture are restricted to filter sizes , and , however this decision was based more on convenience rather than necessity. It also means that the suggested architecture is a combination of all those layers with their output filter banks concatenated into a single output vector forming the input of the next stage. Additionally, since pooling operations have been essential for the success in current state of the art convolutional networks, it suggests that adding an alternative parallel pooling path in each such stage should have additional beneficial effect, too (see Figure 2(a)).
Inception 结构的核心思想是:弄清如何用现成稠密组件去逼近并覆盖卷积视觉网络中的最优局部稀疏结构。平移不变性意味着网络由卷积积木构成;我们只需找到最优局部构造并在空间上重复。Arora 等 [2] 建议逐层构造:分析上一层相关统计,把高相关单元聚成组;这些簇构成下一层单元并连回上一层。我们假定更早层的每个单元对应输入图像某区域,并被组成滤波器组。在靠近输入的较低层,相关单元会集中在局部区域,因而会出现大量集中于单一区域的簇,下一层可用一层 卷积覆盖,如 [12] 所建议。同时也可预期存在数量较少、空间上更分散的簇,需用更大图块上的卷积覆盖,且更大区域上的图块数递减。为避免图块对齐问题,当前 Inception 实现把滤波器尺寸限制为 、 与 ,这一决定更多出于方便而非必然。也就是说,建议结构是把上述各层输出滤波器组拼接成单一输出向量,作为下一阶段输入。此外,池化对当代卷积网络的成功至关重要,因此在每个阶段加入并行池化路径也应有额外益处(见图 2(a))。
(a) Inception module, naïve version
(a)Inception 模块,朴素版
As these “Inception modules” are stacked on top of each other, their output correlation statistics are bound to vary: as features of higher abstraction are captured by higher layers, their spatial concentration is expected to decrease suggesting that the ratio of and convolutions should increase as we move to higher layers.
随着这些「Inception 模块」层层堆叠,其输出相关统计势必变化:更高层捕获更高抽象特征,空间集中度预期下降,因而上移时 与 卷积的比例应增加。
One big problem with the above modules, at least in this naïve form, is that even a modest number of convolutions can be prohibitively expensive on top of a convolutional layer with a large number of filters. This problem becomes even more pronounced once pooling units are added to the mix: their number of output filters equals to the number of filters in the previous stage. The merging of the output of the pooling layer with the outputs of convolutional layers would lead to an inevitable increase in the number of outputs from stage to stage. Even while this architecture might cover the optimal sparse structure, it would do it very inefficiently, leading to a computational blow up within a few stages.
上述模块至少在此朴素形式上有一大问题:即便适度数量的 卷积,叠在滤波器很多的卷积层之上也可能贵得难以承受。一旦再加入池化单元,问题更尖锐:池化输出通道数等于上一阶段滤波器数。把池化输出与卷积输出合并,将使各阶段输出数不可避免地逐级膨胀。即便该结构能覆盖最优稀疏结构,也会非常低效,几级之内就会计算爆炸。
This leads to the second idea of the proposed architecture: judiciously applying dimension reductions and projections wherever the computational requirements would increase too much otherwise. This is based on the success of embeddings: even low dimensional embeddings might contain a lot of information about a relatively large image patch. However, embeddings represent information in a dense, compressed form and compressed information is harder to model. We would like to keep our representation sparse at most places (as required by the conditions of [2]) and compress the signals only whenever they have to be aggregated en masse. That is, convolutions are used to compute reductions before the expensive and convolutions. Besides being used as reductions, they also include the use of rectified linear activation which makes them dual-purpose. The final result is depicted in Figure 2(b).
于是引出所提结构的第二个想法:在计算需求本会暴涨之处审慎做降维与投影。这基于嵌入的成功:即便低维嵌入也可能包含较大图像块的大量信息。但嵌入以稠密压缩形式表示信息,压缩信息更难建模。我们希望多数位置保持稀疏表示(以满足 [2] 的条件),只在必须大规模聚合时才压缩信号。也就是说,用 卷积在昂贵的 与 卷积之前做降维。它们除作降维外还带整流线性激活,因而一身二用。最终结果见图 2(b)。
In general, an Inception network is a network consisting of modules of the above type stacked upon each other, with occasional max-pooling layers with stride 2 to halve the resolution of the grid. For technical reasons (memory efficiency during training), it seemed beneficial to start using Inception modules only at higher layers while keeping the lower layers in traditional convolutional fashion. This is not strictly necessary, simply reflecting some infrastructural inefficiencies in our current implementation.
一般而言,Inception 网络由上述类型的模块堆叠而成,偶尔插入步长为 2 的最大池化以减半网格分辨率。出于技术原因(训练时内存效率),似乎有益的做法是:仅在较高层开始使用 Inception 模块,较低层仍保持传统卷积。这并非严格必要,只是反映当前实现中的一些基础设施低效。
One of the main beneficial aspects of this architecture is that it allows for increasing the number of units at each stage significantly without an uncontrolled blow-up in computational complexity. The ubiquitous use of dimension reduction allows for shielding the large number of input filters of the last stage to the next layer, first reducing their dimension before convolving over them with a large patch size. Another practically useful aspect of this design is that it aligns with the intuition that visual information should be processed at various scales and then aggregated so that the next stage can abstract features from different scales simultaneously.
该结构的一个主要好处是:可显著增加每阶段单元数,而不致让计算复杂度失控膨胀。无处不在的降维把上一阶段大量输入滤波器先降维,再以大图块卷积,从而「护住」下一层。另一实用方面是契合直觉:视觉信息应在多种尺度处理再聚合,使下一阶段能同时从不同尺度抽象特征。
The improved use of computational resources allows for increasing both the width of each stage as well as the number of stages without getting into computational difficulties. Another way to utilize the inception architecture is to create slightly inferior, but computationally cheaper versions of it. We have found that all the included the knobs and levers allow for a controlled balancing of computational resources that can result in networks that are faster than similarly performing networks with non-Inception architecture, however this requires careful manual design at this point.
计算资源利用改善后,既可加宽每阶段,也可增加阶段数,而不陷入计算困境。利用 Inception 的另一方式是构造略逊一筹但更省算力的版本。我们发现,其中的旋钮使计算资源可控平衡,可得到比相近性能的非 Inception 网络快 – 的网络,但目前仍需仔细手工设计。
5 GoogLeNet
We chose GoogLeNet as our team-name in the ILSVRC14 competition. This name is an homage to Yann LeCun’s pioneering LeNet 5 network [10]. We also use GoogLeNet to refer to the particular incarnation of the Inception architecture used in our submission for the competition. We have also used a deeper and wider Inception network, the quality of which was slightly inferior, but adding it to the ensemble seemed to improve the results marginally. We omit the details of that network, since our experiments have shown that the influence of the exact architectural parameters is relatively minor. Here, the most successful particular instance (named GoogLeNet) is described in Table 1 for demonstrational purposes. The exact same topology (trained with different sampling methods) was used for 6 out of the 7 models in our ensemble.
我们在 ILSVRC14 竞赛中以 GoogLeNet 作为队名,向 Yann LeCun 开创性的 LeNet 5 网络 [10] 致敬。我们也用 GoogLeNet 指代竞赛提交所用的那一版 Inception 具体实现。我们还训练过更深更宽、质量略逊的 Inception 网络,把它加入集成似乎能边际提升结果。该网络细节从略,因实验表明精确结构参数影响相对较小。这里出于演示目的,在表 1 描述最成功的实例(名为 GoogLeNet)。集成中 7 个模型有 6 个使用完全相同的拓扑(训练采样方法不同)。
| type | patch size/ stride | output size | depth | reduce | reduce | pool proj | params | ops | |||
|---|---|---|---|---|---|---|---|---|---|---|---|
| convolution | 1 | 2.7K | 34M | ||||||||
| max pool | 0 | ||||||||||
| convolution | 2 | 64 | 192 | 112K | 360M | ||||||
| max pool | 0 | ||||||||||
| inception (3a) | 2 | 64 | 96 | 128 | 16 | 32 | 32 | 159K | 128M | ||
| inception (3b) | 2 | 128 | 128 | 192 | 32 | 96 | 64 | 380K | 304M | ||
| max pool | 0 | ||||||||||
| inception (4a) | 2 | 192 | 96 | 208 | 16 | 48 | 64 | 364K | 73M | ||
| inception (4b) | 2 | 160 | 112 | 224 | 24 | 64 | 64 | 437K | 88M | ||
| inception (4c) | 2 | 128 | 128 | 256 | 24 | 64 | 64 | 463K | 100M | ||
| inception (4d) | 2 | 112 | 144 | 288 | 32 | 64 | 64 | 580K | 119M | ||
| inception (4e) | 2 | 256 | 160 | 320 | 32 | 128 | 128 | 840K | 170M | ||
| max pool | 0 | ||||||||||
| inception (5a) | 2 | 256 | 160 | 320 | 32 | 128 | 128 | 1072K | 54M | ||
| inception (5b) | 2 | 384 | 192 | 384 | 48 | 128 | 128 | 1388K | 71M | ||
| avg pool | 0 | ||||||||||
| dropout (40%) | 0 | ||||||||||
| linear | 1 | 1000K | 1M | ||||||||
| softmax | 0 |
Table 1: GoogLeNet incarnation of the Inception architecture
| type | patch size/ stride | output size | depth | reduce | reduce | pool proj | params | ops | |||
|---|---|---|---|---|---|---|---|---|---|---|---|
| convolution | 1 | 2.7K | 34M | ||||||||
| max pool | 0 | ||||||||||
| convolution | 2 | 64 | 192 | 112K | 360M | ||||||
| max pool | 0 | ||||||||||
| inception (3a) | 2 | 64 | 96 | 128 | 16 | 32 | 32 | 159K | 128M | ||
| inception (3b) | 2 | 128 | 128 | 192 | 32 | 96 | 64 | 380K | 304M | ||
| max pool | 0 | ||||||||||
| inception (4a) | 2 | 192 | 96 | 208 | 16 | 48 | 64 | 364K | 73M | ||
| inception (4b) | 2 | 160 | 112 | 224 | 24 | 64 | 64 | 437K | 88M | ||
| inception (4c) | 2 | 128 | 128 | 256 | 24 | 64 | 64 | 463K | 100M | ||
| inception (4d) | 2 | 112 | 144 | 288 | 32 | 64 | 64 | 580K | 119M | ||
| inception (4e) | 2 | 256 | 160 | 320 | 32 | 128 | 128 | 840K | 170M | ||
| max pool | 0 | ||||||||||
| inception (5a) | 2 | 256 | 160 | 320 | 32 | 128 | 128 | 1072K | 54M | ||
| inception (5b) | 2 | 384 | 192 | 384 | 48 | 128 | 128 | 1388K | 71M | ||
| avg pool | 0 | ||||||||||
| dropout (40%) | 0 | ||||||||||
| linear | 1 | 1000K | 1M | ||||||||
| softmax | 0 |
表 1:Inception 结构的 GoogLeNet 实例
All the convolutions, including those inside the Inception modules, use rectified linear activation. The size of the receptive field in our network is taking RGB color channels with mean subtraction. “ reduce” and “ reduce” stands for the number of filters in the reduction layer used before the and convolutions. One can see the number of filters in the projection layer after the built-in max-pooling in the “pool proj” column. All these reduction/projection layers use rectified linear activation as well.
所有卷积(含 Inception 模块内部)均使用整流线性激活。网络感受野尺寸为 ,输入为做均值减法的 RGB。「 reduce」与「 reduce」表示 与 卷积之前降维层中 滤波器的数量。「pool proj」列是内置最大池化之后投影层中 滤波器数。所有这些降维/投影层同样使用整流线性激活。
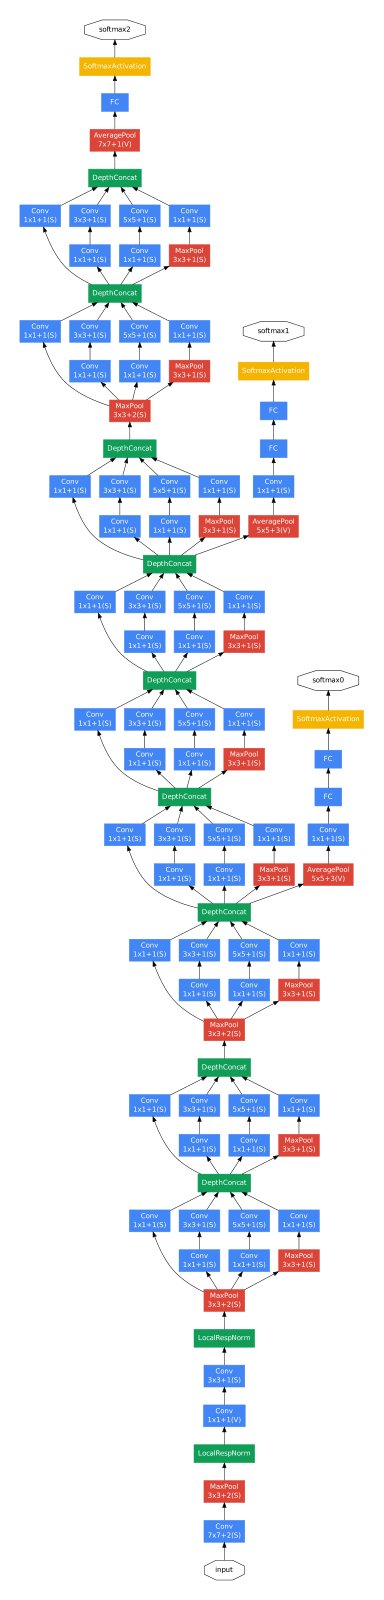
Figure 3: GoogLeNet network with all the bells and whistles
图 3:配备全部细节的 GoogLeNet 网络
The network was designed with computational efficiency and practicality in mind, so that inference can be run on individual devices including even those with limited computational resources, especially with low-memory footprint. The network is 22 layers deep when counting only layers with parameters (or 27 layers if we also count pooling). The overall number of “layers” (independent building blocks) used for the construction of the network is about 100. However this number depends on the machine learning infrastructure system used. The use of average pooling before the classifier is based on [12], although our implementation differs in that we use an extra linear layer. This enables adapting and fine-tuning our networks for other label sets easily, but it is mostly convenience and we do not expect it to have a major effect. It was found that a move from fully connected layers to average pooling improved the top-1 accuracy by about 0.6%, however the use of dropout remained essential even after removing the fully connected layers.
网络设计兼顾计算效率与实用性,使推理可在单设备上运行,包括计算资源有限、尤其内存紧张的设备。仅计含参数层时深度为 22 层(若计池化则为 27 层)。用于构造网络的独立积木约 100 个「层」,具体数目取决于所用机器学习基础设施。分类器前的平均池化基于 [12],但我们的实现多加一层线性层。这便于把网络适配、微调到其他标签集,主要是方便,我们不预期有重大影响。发现从全连接改为平均池化可提升 top-1 约 0.6%,但去掉全连接后 dropout 仍不可或缺。
Given the relatively large depth of the network, the ability to propagate gradients back through all the layers in an effective manner was a concern. One interesting insight is that the strong performance of relatively shallower networks on this task suggests that the features produced by the layers in the middle of the network should be very discriminative. By adding auxiliary classifiers connected to these intermediate layers, we would expect to encourage discrimination in the lower stages in the classifier, increase the gradient signal that gets propagated back, and provide additional regularization. These classifiers take the form of smaller convolutional networks put on top of the output of the Inception (4a) and (4d) modules. During training, their loss gets added to the total loss of the network with a discount weight (the losses of the auxiliary classifiers were weighted by 0.3). At inference time, these auxiliary networks are discarded.
鉴于网络相对较深,能否有效把梯度回传到所有层曾令人担忧。一个有趣的观察是:相对较浅的网络在该任务上表现已很强,说明网络中部层产生的特征应已很有判别力。在这些中间层接上辅助分类器,可望鼓励较低阶段更具判别力、增强回传梯度信号,并提供额外正则。这些分类器是接在 Inception (4a) 与 (4d) 模块输出上的较小卷积网络。训练时其损失以折扣权重加入总损失(辅助分类器损失权重为 0.3)。推理时丢弃这些辅助网络。
The exact structure of the extra network on the side, including the auxiliary classifier, is as follows:
侧枝额外网络(含辅助分类器)的精确结构如下:
- • An average pooling layer with filter size and stride , resulting in an output for the (4a), and for the (4d) stage.
- • 平均池化层,滤波器 、步长 3,对 (4a) 得到 输出,对 (4d) 得到 ;
- • A convolution with 128 filters for dimension reduction and rectified linear activation.
- • 卷积,128 个滤波器,用于降维并接整流线性激活;
- • A fully connected layer with 1024 units and rectified linear activation.
- • 全连接层,1024 单元,整流线性激活;
- • A dropout layer with 70% ratio of dropped outputs.
- • dropout 层,丢弃比例 70%;
- • A linear layer with softmax loss as the classifier (predicting the same 1000 classes as the main classifier, but removed at inference time).
- • 带 softmax 损失的线性层作为分类器(预测与主分类器相同的 1000 类,推理时移除)。
A schematic view of the resulting network is depicted in Figure 3.
所得网络的示意见图 3。
6 Training Methodology
6 训练方法
Our networks were trained using the DistBelief [4] distributed machine learning system using modest amount of model and data-parallelism. Although we used CPU based implementation only, a rough estimate suggests that the GoogLeNet network could be trained to convergence using few high-end GPUs within a week, the main limitation being the memory usage. Our training used asynchronous stochastic gradient descent with 0.9 momentum [17], fixed learning rate schedule (decreasing the learning rate by 4% every 8 epochs). Polyak averaging [13] was used to create the final model used at inference time.
网络用 DistBelief [4] 分布式机器学习系统训练,采用适度的模型并行与数据并行。虽仅用基于 CPU 的实现,粗略估计用少量高端 GPU 约一周可使 GoogLeNet 收敛,主要限制是内存。训练使用动量 0.9 的异步随机梯度下降 [17],固定学习率日程(每 8 个 epoch 学习率降 4%)。推理用最终模型由 Polyak 平均 [13] 得到。
Our image sampling methods have changed substantially over the months leading to the competition, and already converged models were trained on with other options, sometimes in conjunction with changed hyperparameters, like dropout and learning rate, so it is hard to give a definitive guidance to the most effective single way to train these networks. To complicate matters further, some of the models were mainly trained on smaller relative crops, others on larger ones, inspired by [8]. Still, one prescription that was verified to work very well after the competition includes sampling of various sized patches of the image whose size is distributed evenly between 8% and 100% of the image area and whose aspect ratio is chosen randomly between and . Also, we found that the photometric distortions by Andrew Howard [8] were useful to combat overfitting to some extent. In addition, we started to use random interpolation methods (bilinear, area, nearest neighbor and cubic, with equal probability) for resizing relatively late and in conjunction with other hyperparameter changes, so we could not tell definitely whether the final results were affected positively by their use.
竞赛前数月图像采样方法大幅变化,已收敛模型还会用其他选项继续训,有时同时改 dropout、学习率等超参,因而很难给出「单一最有效」的明确处方。更复杂的是,有的模型主要在较小相对裁剪上训练,有的在较大裁剪上,灵感来自 [8]。不过竞赛后验证效果很好的一条处方是:采样图像面积在 8% 到 100% 之间均匀分布的各种尺寸图块,宽高比在 与 间随机选取。我们还发现 Andrew Howard [8] 的光度畸变在一定程度上有助于对抗过拟合。此外,较晚才开始以相等概率使用多种插值(双线性、区域、最近邻、三次)做缩放,且与其他超参改动同时进行,因此无法断定最终结果是否因其而正向受益。
7 ILSVRC 2014 Classification Challenge Setup and Results
7 ILSVRC 2014 分类挑战设置与结果
The ILSVRC 2014 classification challenge involves the task of classifying the image into one of 1000 leaf-node categories in the Imagenet hierarchy. There are about 1.2 million images for training, 50,000 for validation and 100,000 images for testing. Each image is associated with one ground truth category, and performance is measured based on the highest scoring classifier predictions. Two numbers are usually reported: the top-1 accuracy rate, which compares the ground truth against the first predicted class, and the top-5 error rate, which compares the ground truth against the first 5 predicted classes: an image is deemed correctly classified if the ground truth is among the top-5, regardless of its rank in them. The challenge uses the top-5 error rate for ranking purposes.
ILSVRC 2014 分类挑战要求把图像分到 ImageNet 层次中 1000 个叶节点类别之一。训练集约 120 万张,验证 5 万,测试 10 万。每张图对应一个真值类别,性能按最高分分类器预测衡量。通常报告两个数:top-1 准确率(真值对第一预测类),以及 top-5 错误率(真值对前 5 预测:只要真值落在前 5 即算正确,不论名次)。挑战以 top-5 错误率排名。
We participated in the challenge with no external data used for training. In addition to the training techniques aforementioned in this paper, we adopted a set of techniques during testing to obtain a higher performance, which we elaborate below.
我们参赛时未使用外部训练数据。除本文前述训练技巧外,测试阶段还采用一组技术以获得更高性能,详述如下。
- We independently trained 7 versions of the same GoogLeNet model (including one wider version), and performed ensemble prediction with them. These models were trained with the same initialization (even with the same initial weights, mainly because of an oversight) and learning rate policies, and they only differ in sampling methodologies and the random order in which they see input images.
- 我们独立训练了 7 个同一 GoogLeNet 模型版本(含一个更宽版本),并做集成预测。这些模型初始化相同(甚至初始权重相同,主要是疏忽),学习率策略也相同,仅在采样方法与看到输入图像的随机次序上不同。
- During testing, we adopted a more aggressive cropping approach than that of Krizhevsky et al. [9]. Specifically, we resize the image to 4 scales where the shorter dimension (height or width) is 256, 288, 320 and 352 respectively, take the left, center and right square of these resized images (in the case of portrait images, we take the top, center and bottom squares). For each square, we then take the 4 corners and the center crop as well as the square resized to , and their mirrored versions. This results in crops per image. A similar approach was used by Andrew Howard [8] in the previous year’s entry, which we empirically verified to perform slightly worse than the proposed scheme. We note that such aggressive cropping may not be necessary in real applications, as the benefit of more crops becomes marginal after a reasonable number of crops are present (as we will show later on).
- 测试时采用比 Krizhevsky 等 [9] 更激进的裁剪。具体地,把图像缩放到短边分别为 256、288、320、352 的 4 个尺度,再取左、中、右三个正方形(竖图则取上、中、下)。对每个正方形再取四角与中心的 裁剪,以及缩放到 的整方块,再加上镜像,共 个裁剪。Andrew Howard [8] 上年条目用过类似做法,我们经验证其略逊于本方案。需指出:实际应用未必需要如此激进裁剪,裁剪数到一定程度后收益会边际递减(后文将展示)。
- The softmax probabilities are averaged over multiple crops and over all the individual classifiers to obtain the final prediction. In our experiments we analyzed alternative approaches on the validation data, such as max pooling over crops and averaging over classifiers, but they lead to inferior performance than the simple averaging.
- 最终预测由多裁剪与各分类器的 softmax 概率平均得到。我们在验证集上分析了替代方案,如对裁剪做最大池化、对分类器做平均等,均不如简单平均。
In the remainder of this paper, we analyze the multiple factors that contribute to the overall performance of the final submission.
后文分析促成最终提交整体性能的多种因素。
| Team | Year | Place | Error (top-5) | Uses external data |
|---|---|---|---|---|
| SuperVision | 2012 | 1st | no | |
| SuperVision | 2012 | 1st | Imagenet k | |
| Clarifai | 2013 | 1st | no | |
| Clarifai | 2013 | 1st | Imagenet k | |
| MSRA | 2014 | 3rd | no | |
| VGG | 2014 | 2nd | no | |
| GoogLeNet | 2014 | 1st | no |
Table 2: Classification performance
| Team | Year | Place | Error (top-5) | Uses external data |
|---|---|---|---|---|
| SuperVision | 2012 | 1st | no | |
| SuperVision | 2012 | 1st | Imagenet k | |
| Clarifai | 2013 | 1st | no | |
| Clarifai | 2013 | 1st | Imagenet k | |
| MSRA | 2014 | 3rd | no | |
| VGG | 2014 | 2nd | no | |
| GoogLeNet | 2014 | 1st | no |
表 2:分类性能
Our final submission in the challenge obtains a top-5 error of 6.67% on both the validation and testing data, ranking the first among other participants. This is a 56.5% relative reduction compared to the SuperVision approach in 2012, and about 40% relative reduction compared to the previous year’s best approach (Clarifai), both of which used external data for training the classifiers. The following table shows the statistics of some of the top-performing approaches.
最终提交在验证与测试上 top-5 错误率均为 6.67%,在参赛者中排名第一。相对 2012 年 SuperVision 相对下降 56.5%,相对上年最佳 Clarifai 约下降 40%;后两者训练分类器时都用了外部数据。下表给出若干顶尖方法的统计。
| Number of models | Number of Crops | Cost | Top-5 error | compared to base |
|---|---|---|---|---|
| 1 | 1 | 1 | base | |
| 1 | 10 | 10 | -0.92% | |
| 1 | 144 | 144 | -2.18% | |
| 7 | 1 | 7 | -1.98% | |
| 7 | 10 | 70 | -2.45% | |
| 7 | 144 | 1008 | -3.45% |
Table 3: GoogLeNet classification performance break down
| Number of models | Number of Crops | Cost | Top-5 error | compared to base |
|---|---|---|---|---|
| 1 | 1 | 1 | base | |
| 1 | 10 | 10 | -0.92% | |
| 1 | 144 | 144 | -2.18% | |
| 7 | 1 | 7 | -1.98% | |
| 7 | 10 | 70 | -2.45% | |
| 7 | 144 | 1008 | -3.45% |
表 3:GoogLeNet 分类性能分解
We also analyze and report the performance of multiple testing choices, by varying the number of models and the number of crops used when predicting an image in the following table. When we use one model, we chose the one with the lowest top-1 error rate on the validation data. All numbers are reported on the validation dataset in order to not overfit to the testing data statistics.
我们还通过改变预测时使用的模型数与裁剪数,分析并报告多种测试选择的性能,见下表。单模型时选取验证集 top-1 错误最低者。所有数字均在验证集上报告,以免过拟合测试统计。
8 ILSVRC 2014 Detection Challenge Setup and Results
8 ILSVRC 2014 检测挑战设置与结果
The ILSVRC detection task is to produce bounding boxes around objects in images among 200 possible classes. Detected objects count as correct if they match the class of the groundtruth and their bounding boxes overlap by at least 50% (using the Jaccard index). Extraneous detections count as false positives and are penalized. Contrary to the classification task, each image may contain many objects or none, and their scale may vary from large to tiny. Results are reported using the mean average precision (mAP).
ILSVRC 检测任务要求在图像中为 200 个可能类别的目标生成边界框。检测算正确需类别与真值一致,且边界框重叠至少 50%(Jaccard 指数)。多余检测计为假阳性并受罚。与分类不同,每张图可含多个或零个目标,尺度可从很大到很小。结果以平均精度均值(mAP)报告。
The approach taken by GoogLeNet for detection is similar to the R-CNN by [6], but is augmented with the Inception model as the region classifier. Additionally, the region proposal step is improved by combining the Selective Search [20] approach with multi-box [5] predictions for higher object bounding box recall. In order to cut down the number of false positives, the superpixel size was increased by . This halves the proposals coming from the selective search algorithm. We added back 200 region proposals coming from multi-box [5] resulting, in total, in about 60% of the proposals used by [6], while increasing the coverage from 92% to 93%. The overall effect of cutting the number of proposals with increased coverage is a 1% improvement of the mean average precision for the single model case. Finally, we use an ensemble of 6 ConvNets when classifying each region which improves results from 40% to 43.9% accuracy. Note that contrary to R-CNN, we did not use bounding box regression due to lack of time.
GoogLeNet 的检测路径类似 [6] 的 R-CNN,但用 Inception 模型作区域分类器。区域提议阶段把 Selective Search [20] 与 multi-box [5] 预测结合以提高框召回。为减少假阳性,超像素尺寸增大 ,使 selective search 提议减半;再补回 multi-box [5] 的 200 个区域提议,总计约为 [6] 所用提议的 60%,覆盖率却从 92% 提到 93%。在单模型情形,削减提议且提高覆盖使 mAP 提升约 1%。最后对每个区域用 6 个 ConvNet 集成分类,准确率从约 40% 提到 43.9%。注意与 R-CNN 不同,因时间不足我们未做边界框回归。
| Team | Year | Place | mAP | external data | ensemble | approach |
|---|---|---|---|---|---|---|
| UvA-Euvision | 2013 | 1st | none | ? | Fisher vectors | |
| Deep Insight | 2014 | 3rd | ImageNet k | 3 | CNN | |
| CUHK DeepID-Net | 2014 | 2nd | ImageNet k | ? | CNN | |
| GoogLeNet | 2014 | 1st | ImageNet k | 6 | CNN |
Table 4: Detection performance
| Team | Year | Place | mAP | external data | ensemble | approach |
|---|---|---|---|---|---|---|
| UvA-Euvision | 2013 | 1st | none | ? | Fisher vectors | |
| Deep Insight | 2014 | 3rd | ImageNet k | 3 | CNN | |
| CUHK DeepID-Net | 2014 | 2nd | ImageNet k | ? | CNN | |
| GoogLeNet | 2014 | 1st | ImageNet k | 6 | CNN |
表 4:检测性能
We first report the top detection results and show the progress since the first edition of the detection task. Compared to the 2013 result, the accuracy has almost doubled. The top performing teams all use Convolutional Networks. We report the official scores in Table 4 and common strategies for each team: the use of external data, ensemble models or contextual models. The external data is typically the ILSVRC12 classification data for pre-training a model that is later refined on the detection data. Some teams also mention the use of the localization data. Since a good portion of the localization task bounding boxes are not included in the detection dataset, one can pre-train a general bounding box regressor with this data the same way classification is used for pre-training. The GoogLeNet entry did not use the localization data for pretraining.
我们先报告顶尖检测结果,并展示自检测任务首届以来的进展。相较 2013,精度几乎翻倍。顶尖队伍均使用卷积网络。表 4 给出官方分数及各队常见策略:外部数据、集成或上下文模型。外部数据通常是 ILSVRC12 分类数据,用于预训练后再在检测数据上精调。有队伍也提到使用定位数据。由于定位任务的不少边界框未纳入检测集,可用该数据像分类预训练那样预训练通用边界框回归器。GoogLeNet 条目未用定位数据做预训练。
| Team | mAP | Contextual model | Bounding box regression |
|---|---|---|---|
| Trimps-Soushen | no | ? | |
| Berkeley Vision | no | yes | |
| UvA-Euvision | ? | ? | |
| CUHK DeepID-Net2 | no | ? | |
| GoogLeNet | no | no | |
| Deep Insight | yes | yes |
Table 5: Single model performance for detection
| Team | mAP | Contextual model | Bounding box regression |
|---|---|---|---|
| Trimps-Soushen | no | ? | |
| Berkeley Vision | no | yes | |
| UvA-Euvision | ? | ? | |
| CUHK DeepID-Net2 | no | ? | |
| GoogLeNet | no | no | |
| Deep Insight | yes | yes |
表 5:检测单模型性能
In Table 5, we compare results using a single model only. The top performing model is by Deep Insight and surprisingly only improves by 0.3 points with an ensemble of 3 models while the GoogLeNet obtains significantly stronger results with the ensemble.
表 5 比较仅用单模型的结果。表现最好的是 Deep Insight;有趣的是其 3 模型集成仅再提升 0.3 分,而 GoogLeNet 用集成获得明显更强结果。
9 Conclusions
9 结论
Our results seem to yield a solid evidence that approximating the expected optimal sparse structure by readily available dense building blocks is a viable method for improving neural networks for computer vision. The main advantage of this method is a significant quality gain at a modest increase of computational requirements compared to shallower and less wide networks. Also note that our detection work was competitive despite of neither utilizing context nor performing bounding box regression and this fact provides further evidence of the strength of the Inception architecture. Although it is expected that similar quality of result can be achieved by much more expensive networks of similar depth and width, our approach yields solid evidence that moving to sparser architectures is feasible and useful idea in general. This suggest promising future work towards creating sparser and more refined structures in automated ways on the basis of [2].
我们的结果似乎提供了坚实证据:用现成稠密积木逼近期望的最优稀疏结构,是改进计算机视觉神经网络的可行方法。相对更浅更窄的网络,该方法在计算需求仅适度增加时带来显著质量提升。还需指出:我们的检测工作在既未用上下文、也未做边界框回归的情况下仍具竞争力,这进一步证明 Inception 结构的实力。尽管可以预期深度与宽度相近、但代价高得多的网络也能达到类似质量,我们的路径仍证明走向更稀疏结构总体可行且有用。这提示基于 [2] 以自动化方式创造更稀疏、更精细结构的未来工作很有前景。
10 Acknowledgements
10 致谢
We would like to thank Sanjeev Arora and Aditya Bhaskara for fruitful discussions on [2]. Also we are indebted to the DistBelief [4] team for their support especially to Rajat Monga, Jon Shlens, Alex Krizhevsky, Jeff Dean, Ilya Sutskever and Andrea Frome. We would also like to thank to Tom Duerig and Ning Ye for their help on photometric distortions. Also our work would not have been possible without the support of Chuck Rosenberg and Hartwig Adam.
感谢 Sanjeev Arora 与 Aditya Bhaskara 就 [2] 的富有成果讨论。亦感谢 DistBelief [4] 团队的支持,尤其是 Rajat Monga、Jon Shlens、Alex Krizhevsky、Jeff Dean、Ilya Sutskever 与 Andrea Frome。还要感谢 Tom Duerig 与 Ning Ye 在光度畸变上的帮助。没有 Chuck Rosenberg 与 Hartwig Adam 的支持,本工作亦不可能完成。
References
参考文献
[1] Know your meme: We need to go deeper. http://knowyourmeme.com/memes/we-need-to-go-deeper . Accessed: 2014-09-15.
[2] Sanjeev Arora, Aditya Bhaskara, Rong Ge, and Tengyu Ma. Provable bounds for learning some deep representations. CoRR , abs/1310.6343, 2013.
[3] Ümit V. Çatalyürek, Cevdet Aykanat, and Bora Uçar. On two-dimensional sparse matrix partitioning: Models, methods, and a recipe. SIAM J. Sci. Comput. , 32(2):656–683, February 2010.
[4] Jeffrey Dean, Greg Corrado, Rajat Monga, Kai Chen, Matthieu Devin, Mark Mao, Marc’aurelio Ranzato, Andrew Senior, Paul Tucker, Ke Yang, Quoc V. Le, and Andrew Y. Ng. Large scale distributed deep networks. In P. Bartlett, F.c.n. Pereira, C.j.c. Burges, L. Bottou, and K.q. Weinberger, editors, Advances in Neural Information Processing Systems 25 , pages 1232–1240. 2012.
[5] Dumitru Erhan, Christian Szegedy, Alexander Toshev, and Dragomir Anguelov. Scalable object detection using deep neural networks. In Computer Vision and Pattern Recognition, 2014. CVPR 2014. IEEE Conference on , 2014.
[6] Ross B. Girshick, Jeff Donahue, Trevor Darrell, and Jitendra Malik. Rich feature hierarchies for accurate object detection and semantic segmentation. In Computer Vision and Pattern Recognition, 2014. CVPR 2014. IEEE Conference on , 2014.
[7] Geoffrey E. Hinton, Nitish Srivastava, Alex Krizhevsky, Ilya Sutskever, and Ruslan Salakhutdinov. Improving neural networks by preventing co-adaptation of feature detectors. CoRR , abs/1207.0580, 2012.
[8] Andrew G. Howard. Some improvements on deep convolutional neural network based image classification. CoRR , abs/1312.5402, 2013.
[9] Alex Krizhevsky, Ilya Sutskever, and Geoff Hinton. Imagenet classification with deep convolutional neural networks. In Advances in Neural Information Processing Systems 25 , pages 1106–1114, 2012.
[10] Y. LeCun, B. Boser, J. S. Denker, D. Henderson, R. E. Howard, W. Hubbard, and L. D. Jackel. Backpropagation applied to handwritten zip code recognition. Neural Comput. , 1(4):541–551, December 1989.
[11] Yann LeCun, Léon Bottou, Yoshua Bengio, and Patrick Haffner. Gradient-based learning applied to document recognition. Proceedings of the IEEE , 86(11):2278–2324, 1998.
[12] Min Lin, Qiang Chen, and Shuicheng Yan. Network in network. CoRR , abs/1312.4400, 2013.
[13] B. T. Polyak and A. B. Juditsky. Acceleration of stochastic approximation by averaging. SIAM J. Control Optim. , 30(4):838–855, July 1992.
[14] Pierre Sermanet, David Eigen, Xiang Zhang, Michaël Mathieu, Rob Fergus, and Yann LeCun. Overfeat: Integrated recognition, localization and detection using convolutional networks. CoRR , abs/1312.6229, 2013.
[15] Thomas Serre, Lior Wolf, Stanley M. Bileschi, Maximilian Riesenhuber, and Tomaso Poggio. Robust object recognition with cortex-like mechanisms. IEEE Trans. Pattern Anal. Mach. Intell. , 29(3):411–426, 2007.
[16] Fengguang Song and Jack Dongarra. Scaling up matrix computations on shared-memory manycore systems with 1000 cpu cores. In Proceedings of the 28th ACM International Conference on Supercomputing , ICS ’14, pages 333–342, New York, NY, USA, 2014. ACM.
[17] Ilya Sutskever, James Martens, George E. Dahl, and Geoffrey E. Hinton. On the importance of initialization and momentum in deep learning. In Proceedings of the 30th International Conference on Machine Learning, ICML 2013, Atlanta, GA, USA, 16-21 June 2013 , volume 28 of JMLR Proceedings , pages 1139–1147. JMLR.org, 2013.
[18] Christian Szegedy, Alexander Toshev, and Dumitru Erhan. Deep neural networks for object detection. In Christopher J. C. Burges, Léon Bottou, Zoubin Ghahramani, and Kilian Q. Weinberger, editors, Advances in Neural Information Processing Systems 26: 27th Annual Conference on Neural Information Processing Systems 2013. Proceedings of a meeting held December 5-8, 2013, Lake Tahoe, Nevada, United States. , pages 2553–2561, 2013.
[19] Alexander Toshev and Christian Szegedy. Deeppose: Human pose estimation via deep neural networks. CoRR , abs/1312.4659, 2013.
[20] Koen E. A. van de Sande, Jasper R. R. Uijlings, Theo Gevers, and Arnold W. M. Smeulders. Segmentation as selective search for object recognition. In Proceedings of the 2011 International Conference on Computer Vision , ICCV ’11, pages 1879–1886, Washington, DC, USA, 2011. IEEE Computer Society.
[21] Matthew D. Zeiler and Rob Fergus. Visualizing and understanding convolutional networks. In David J. Fleet, Tomás Pajdla, Bernt Schiele, and Tinne Tuytelaars, editors, Computer Vision - ECCV 2014 - 13th European Conference, Zurich, Switzerland, September 6-12, 2014, Proceedings, Part I , volume 8689 of Lecture Notes in Computer Science , pages 818–833. Springer, 2014.