IMPALA: Scalable Distributed Deep-RL with Importance Weighted Actor-Learner Architectures
Supplementary Material
补充材料
Lasse Espeholt Affiliation: DeepMind Technologies, London, United Kingdom Correspondence to: lespeholt@google.com Hubert Soyer Affiliation: DeepMind Technologies, London, United Kingdom Remi Munos Affiliation: DeepMind Technologies, London, United Kingdom Karen Simonyan Affiliation: DeepMind Technologies, London, United Kingdom Volodymyr Mnih Affiliation: DeepMind Technologies, London, United Kingdom Tom Ward Affiliation: DeepMind Technologies, London, United Kingdom Yotam Doron Affiliation: DeepMind Technologies, London, United Kingdom Vlad Firoiu Affiliation: DeepMind Technologies, London, United Kingdom Tim Harley Affiliation: DeepMind Technologies, London, United Kingdom Iain Dunning Affiliation: DeepMind Technologies, London, United Kingdom Shane Legg Affiliation: DeepMind Technologies, London, United Kingdom Koray Kavukcuoglu Affiliation: DeepMind Technologies, London, United Kingdom
Abstract
摘要
In this work we aim to solve a large collection of tasks using a single reinforcement learning agent with a single set of parameters. A key challenge is to handle the increased amount of data and extended training time. We have developed a new distributed agent IMPALA (Importance Weighted Actor-Learner Architecture) that not only uses resources more efficiently in single-machine training but also scales to thousands of machines without sacrificing data efficiency or resource utilisation. We achieve stable learning at high throughput by combining decoupled acting and learning with a novel off-policy correction method called V-trace. We demonstrate the effectiveness of IMPALA for multi-task reinforcement learning on DMLab-30 (a set of 30 tasks from the DeepMind Lab environment (Beattie et al., 2016)) and Atari-57 (all available Atari games in Arcade Learning Environment (Bellemare et al., 2013a)). Our results show that IMPALA is able to achieve better performance than previous agents with less data, and crucially exhibits positive transfer between tasks as a result of its multi-task approach. The source code is publicly available at github.com/deepmind/scalable_agent.
本文旨在用单个强化学习智能体、同一套参数,解决一大批任务。关键挑战是数据量更大、训练时间更长。我们提出新的分布式智能体 IMPALA(Importance Weighted Actor-Learner Architecture):不仅在单机训练里更高效地用资源,还能扩到数千台机器而不牺牲数据效率或资源利用率。通过把行动与学习解耦,并结合名为 V-trace 的新型离策略校正,我们在高吞吐下仍能稳定学习。我们在 DMLab-30(DeepMind Lab 环境中的 30 项任务 (Beattie et al., 2016))以及 Atari-57(Arcade Learning Environment 中全部可用 Atari 游戏 (Bellemare et al., 2013a))上验证多任务强化学习效果。结果表明:IMPALA 能以更少数据取得优于先前智能体的表现,并且由于多任务训练而出现任务间的正向迁移。源代码公开于 github.com/deepmind/scalable_agent。
1 Introduction
1 引言
Keywords:
Deep reinforcement learning methods have recently mastered a wide variety of domains through trial and error learning (Mnih et al., 2015; Silver et al., 2017; Silver et al., 2016; Zoph et al., 2017; Lillicrap et al., 2015; Barth-Maron et al., 2018). While the improvements on tasks like the game of Go (Silver et al., 2017) and Atari games (Horgan et al., 2018) have been dramatic, the progress has been primarily in single task performance, where an agent is trained on each task separately. We are interested in developing new methods capable of mastering a diverse set of tasks simultaneously as well as environments suitable for evaluating such methods.
关键词:
深度强化学习方法近来通过试错学习掌握了广泛领域 (Mnih et al., 2015; Silver et al., 2017; Silver et al., 2016; Zoph et al., 2017; Lillicrap et al., 2015; Barth-Maron et al., 2018)。尽管在围棋 (Silver et al., 2017) 与 Atari (Horgan et al., 2018) 等任务上的进步显著,进展主要仍落在单任务表现——每个任务单独训练一个智能体。我们希望发展能同时掌握多样化任务集合的新方法,并配套适合评估这类方法的环境。
One of the main challenges in training a single agent on many tasks at once is scalability. Since the current state-of-the-art methods like A3C (Mnih et al., 2016) or UNREAL (Jaderberg et al., 2017b) can require as much as a billion frames and multiple days to master a single domain, training them on tens of domains at once is too slow to be practical.
一次训练单个智能体覆盖许多任务时,可扩展性是主要挑战之一。像 A3C (Mnih et al., 2016) 或 UNREAL (Jaderberg et al., 2017b) 这类当前最强方法,掌握单一领域可能就要十亿帧、多日训练;同时训几十个领域会慢到不实用。
We propose the Importance Weighted Actor-Learner Architecture (IMPALA) shown in Figure 1. IMPALA is capable of scaling to thousands of machines without sacrificing training stability or data efficiency. Unlike the popular A3C-based agents, in which workers communicate gradients with respect to the parameters of the policy to a central parameter server, IMPALA actors communicate trajectories of experience (sequences of states, actions, and rewards) to a centralised learner. Since the learner in IMPALA has access to full trajectories of experience we use a GPU to perform updates on mini-batches of trajectories while aggressively parallelising all time independent operations. This type of decoupled architecture can achieve very high throughput. However, because the policy used to generate a trajectory can lag behind the policy on the learner by several updates at the time of gradient calculation, learning becomes off-policy. Therefore, we introduce the V-trace off-policy actor-critic algorithm to correct for this harmful discrepancy.
我们提出图 1 所示的 Importance Weighted Actor-Learner Architecture(IMPALA)。IMPALA 能扩到数千台机器,同时保持训练稳定与数据效率。与常见的基于 A3C 的智能体不同——工作者向中心参数服务器传递相对策略参数的梯度——IMPALA 的 actor 向中心化 learner 传递经验轨迹(状态、动作与奖励序列)。由于 learner 能看到完整轨迹,我们用 GPU 在轨迹小批量上做更新,并积极并行化所有与时间无关的运算。这类解耦架构可达到很高吞吐;但生成轨迹时所用策略,在计算梯度时可能已落后 learner 上策略若干次更新,学习因此变成离策略。为此我们引入 V-trace 离策略 actor-critic 算法,校正这一有害偏差。
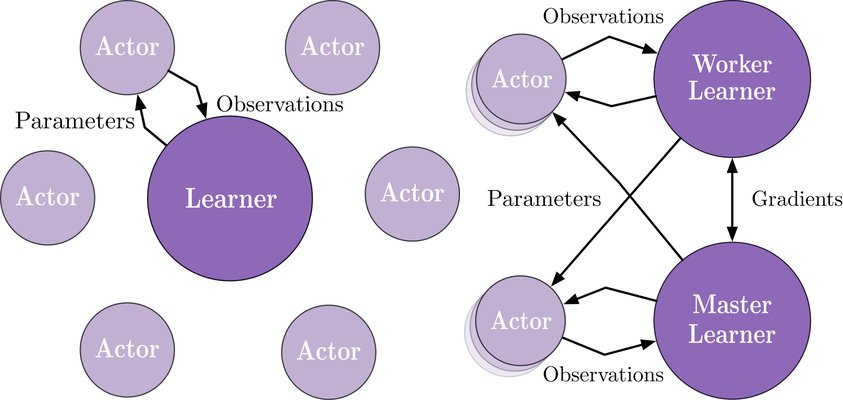
Figure 1: Left: Single Learner. Each actor generates trajectories and sends them via a queue to the learner. Before starting the next trajectory, actor retrieves the latest policy parameters from learner. Right: Multiple Synchronous Learners. Policy parameters are distributed across multiple learners that work synchronously.
图 1:左:单 learner。每个 actor 生成轨迹,经队列送给 learner;开始下一条轨迹前,actor 从 learner 取回最新策略参数。右:多个同步 learner。策略参数分布在多个同步工作的 learner 上。
With the scalable architecture and V-trace combined, IMPALA achieves exceptionally high data throughput rates of 250,000 frames per second, making it over 30 times faster than single-machine A3C. Crucially, IMPALA is also more data efficient than A3C based agents and more robust to hyperparameter values and network architectures, allowing it to make better use of deeper neural networks. We demonstrate the effectiveness of IMPALA by training a single agent on multi-task problems using DMLab-30, a new challenge set which consists of 30 diverse cognitive tasks in the 3D DeepMind Lab (Beattie et al., 2016) environment and by training a single agent on all games in the Atari-57 set of tasks.
可扩展架构与 V-trace 结合后,IMPALA 达到每秒 250,000 帧的极高数据吞吐,比单机 A3C 快 30 倍以上。关键的是,IMPALA 也比基于 A3C 的智能体更省数据,并对超参与网络结构更鲁棒,从而更好利用更深网络。我们用 DMLab-30(DeepMind Lab (Beattie et al., 2016) 中 30 项多样认知任务的新挑战集)以及 Atari-57 全部游戏上的单智能体多任务训练,展示了 IMPALA 的有效性。
2 Related Work
2 相关工作
The earliest attempts to scale up deep reinforcement learning relied on distributed asynchronous SGD (Dean et al., 2012) with multiple workers. Examples include distributed A3C (Mnih et al., 2016) and Gorila (Nair et al., 2015), a distributed version of Deep Q-Networks (Mnih et al., 2015). Recent alternatives to asynchronous SGD for RL include using evolutionary processes (Salimans et al., 2017), distributed BA3C (Adamski et al., 2018) and Ape-X (Horgan et al., 2018) which has a distributed replay but a synchronous learner.
最早放大深度强化学习的尝试依赖多工作者分布式异步 SGD (Dean et al., 2012)。例子包括分布式 A3C (Mnih et al., 2016) 以及 Deep Q-Networks 的分布式版本 Gorila (Nair et al., 2015; Mnih et al., 2015)。近期替代异步 SGD 的 RL 方案包括演化过程 (Salimans et al., 2017)、分布式 BA3C (Adamski et al., 2018),以及带分布式回放、同步 learner 的 Ape-X (Horgan et al., 2018)。
There have also been multiple efforts that scale up reinforcement learning by utilising GPUs. One of the simplest of such methods is batched A2C (Clemente et al., 2017). At every step, batched A2C produces a batch of actions and applies them to a batch of environments. Therefore, the slowest environment in each batch determines the time it takes to perform the entire batch step (see Figure 2(a) and 2(b)). In other words, high variance in environment speed can severely limit performance. Batched A2C works particularly well on Atari environments, because rendering and game logic are computationally very cheap in comparison to the expensive tensor operations performed by reinforcement learning agents. However, more visually or physically complex environments can be slower to simulate and can have high variance in the time required for each step. Environments may also have variable length (sub)episodes causing a slowdown when initialising an episode.
也有多项工作用 GPU 放大强化学习。最简单的一类是批处理 A2C (Clemente et al., 2017):每步产生一批动作并施加到一批环境,因此每批中最慢的环境决定整批步进耗时(见图 2(a)(b))。换言之,环境速度方差大会严重限制性能。批处理 A2C 在 Atari 上特别好用,因为渲染与游戏逻辑相对智能体昂贵的张量运算非常便宜。但视觉或物理更复杂的环境仿真更慢,且每步耗时方差更大;环境还可能有可变长度(子)回合,初始化时也会拖慢。
The most similar architecture to IMPALA is GA3C (Babaeizadeh et al., 2016), which also uses asynchronous data collection to more effectively utilise GPUs. It decouples the acting/forward pass from the gradient calculation/backward pass by using dynamic batching. The actor/learner asynchrony in GA3C leads to instabilities during learning, which (Babaeizadeh et al., 2016) only partially mitigates by adding a small constant to action probabilities during the estimation of the policy gradient. In contrast, IMPALA uses the more principled V-trace algorithm.
与 IMPALA 最相似的结构是 GA3C (Babaeizadeh et al., 2016):同样用异步数据采集更有效利用 GPU,并通过动态批处理把行动/前向与梯度/反向解耦。GA3C 中 actor/learner 不同步会带来学习不稳定,原文仅靠在估计策略梯度时给动作概率加一小常数部分缓解。相比之下,IMPALA 使用更有原则的 V-trace 算法。
Related previous work on off-policy RL include (Precup et al., 2000; Precup et al., 2001; Wawrzynski, 2009; Geist & Scherrer, 2014; O’Donoghue et al., 2017) and (Harutyunyan et al., 2016). The closest work to ours is the Retrace algorithm (Munos et al., 2016) which introduced an off-policy correction for multi-step RL, and has been used in several agent architectures (Wang et al., 2017; Gruslys et al., 2018). Retrace requires learning state-action-value functions in order to make the off-policy correction. However, many actor-critic methods such as A3C learn a state-value function instead of a state-action-value function . V-trace is based on the state-value function.
离策略 RL 的相关工作包括 (Precup et al., 2000; Precup et al., 2001; Wawrzynski, 2009; Geist & Scherrer, 2014; O’Donoghue et al., 2017) 与 (Harutyunyan et al., 2016)。与我们最接近的是 Retrace (Munos et al., 2016):为多步 RL 引入离策略校正,并被多种智能体结构采用 (Wang et al., 2017; Gruslys et al., 2018)。Retrace 需要学习状态–动作价值 才能做离策略校正;而许多 actor-critic 方法(如 A3C)学的是状态价值 而非 。V-trace 基于状态价值函数。
3 IMPALA
(a) Batched A2C (sync step.)
(a) 批处理 A2C(逐步同步)
IMPALA (Figure 1) uses an actor-critic setup to learn a policy and a baseline function . The process of generating experiences is decoupled from learning the parameters of and . The architecture consists of a set of actors, repeatedly generating trajectories of experience, and one or more learners that use the experiences sent from actors to learn off-policy.
IMPALA(图 1)用 actor-critic 设定学习策略 与基线函数 。生成经验的过程与学习 、 的参数解耦。架构由一组反复生成经验轨迹的 actor,以及一个或多个用 actor 送来的经验离策略学习 的 learner 组成。
At the beginning of each trajectory, an actor updates its own local policy to the latest learner policy and runs it for steps in its environment. After steps, the actor sends the trajectory of states, actions and rewards together with the corresponding policy distributions and initial LSTM state to the learner through a queue. The learner then continuously updates its policy on batches of trajectories, each collected from many actors. This simple architecture enables the learner(s) to be accelerated using GPUs and actors to be easily distributed across many machines. However, the learner policy is potentially several updates ahead of the actor’s policy at the time of update, therefore there is a policy-lag between the actors and learner(s). V-trace corrects for this lag to achieve extremely high data throughput while maintaining data efficiency. Using an actor-learner architecture, provides fault tolerance like distributed A3C but often has lower communication overhead since the actors send observations rather than parameters/gradients.
每条轨迹开始时,actor 把本地策略 更新为最新的 learner 策略 ,并在环境中跑 步。 步之后,actor 把状态、动作与奖励轨迹 ,连同对应策略分布 与初始 LSTM 状态,经队列送给 learner。learner 则持续在来自众多 actor 的轨迹批次上更新 。这一简单架构使 learner 可用 GPU 加速,actor 也易于分布到多机。但更新时 learner 策略 可能已领先 actor 策略 若干次更新,因而存在 策略滞后。V-trace 校正该滞后,从而在极高数据吞吐下仍保持数据效率。actor-learner 架构像分布式 A3C 一样具备容错,但通信开销往往更低,因为 actor 发送的是观测而非参数/梯度。
With the introduction of very deep model architectures, the speed of a single GPU is often the limiting factor during training. IMPALA can be used with distributed set of learners to train large neural networks efficiently as shown in Figure 1. Parameters are distributed across the learners and actors retrieve the parameters from all the learners in parallel while only sending observations to a single learner. IMPALA use synchronised parameter update which is vital to maintain data efficiency when scaling to many machines (Chen et al., 2016).
随着模型结构变深,单块 GPU 的速度常成训练瓶颈。如图 1 所示,IMPALA 可用分布式 learner 高效训练大型神经网络:参数分布在各 learner 上,actor 并行从所有 learner 取参,但只向其中一个 learner 发送观测。IMPALA 使用同步参数更新,这对扩到多机时保持数据效率至关重要 (Chen et al., 2016)。
3.1 Efficiency Optimisations
3.1 效率优化
GPUs and many-core CPUs benefit greatly from running few large, parallelisable operations instead of many small operations. Since the learner in IMPALA performs updates on entire batches of trajectories, it is able to parallelise more of its computations than an online agent like A3C. As an example, a typical deep RL agent features a convolutional network followed by a Long Short-Term Memory (LSTM) (Hochreiter & Schmidhuber, 1997) and a fully connected output layer after the LSTM. An IMPALA learner applies the convolutional network to all inputs in parallel by folding the time dimension into the batch dimension. Similarly, it also applies the output layer to all time steps in parallel once all LSTM states are computed. This optimisation increases the effective batch size to thousands. LSTM-based agents also obtain significant speedups on the learner by exploiting the network structure dependencies and operation fusion (Appleyard et al., 2016).
GPU 与众核 CPU 更适合跑少量大型可并行运算,而非大量细碎运算。IMPALA 的 learner 在整批轨迹上更新,因此比 A3C 一类在线智能体能并行化更多计算。例如,典型深度 RL 智能体是卷积网络,后接 LSTM (Hochreiter & Schmidhuber, 1997),再接全连接输出层。IMPALA learner 把时间维折进批维,从而并行对所有输入施加卷积;同样,算完全部 LSTM 状态后,也可并行对所有时间步施加输出层。该优化把有效批大小提到数千。基于 LSTM 的智能体还可通过利用网络结构依赖与算子融合,在 learner 上获得显著加速 (Appleyard et al., 2016)。
Finally, we also make use of several off the shelf optimisations available in TensorFlow (Abadi et al., 2017) such as preparing the next batch of data for the learner while still performing computation, compiling parts of the computational graph with XLA (a TensorFlow Just-In-Time compiler) and optimising the data format to get the maximum performance from the cuDNN framework (Chetlur et al., 2014).
我们还用了 TensorFlow (Abadi et al., 2017) 中若干现成优化:在仍做计算时预取下一批数据、用 XLA(TensorFlow 即时编译器)编译部分计算图,以及优化数据格式以尽量吃满 cuDNN (Chetlur et al., 2014)。
4 V-trace
Off-policy learning is important in the decoupled distributed actor-learner architecture because of the lag between when actions are generated by the actors and when the learner estimates the gradient. To this end, we introduce a novel off-policy actor-critic algorithm for the learner, called V-trace.
在解耦的分布式 actor-learner 架构中,离策略学习很重要,因为 actor 生成动作与 learner 估计梯度之间存在滞后。为此,我们为 learner 引入新型离策略 actor-critic 算法 V-trace。
First, let us introduce some notations. We consider the problem of discounted infinite-horizon RL in Markov Decision Processes (MDP), see (Puterman, 1994; Sutton & Barto, 1998) where the goal is to find a policy that maximises the expected sum of future discounted rewards: , where is the discount factor, is the reward at time , is the state at time (initialised in ) and is the action generated by following some policy .
先引入记号。我们考虑马尔可夫决策过程(MDP)中的折扣无限时域 RL,见 (Puterman, 1994; Sutton & Barto, 1998),目标是找策略 最大化期望折扣回报和:,其中 为折扣因子, 为 时刻奖励, 为 时刻状态(初始化 ), 为按策略 生成的动作。
The goal of an off-policy RL algorithm is to use trajectories generated by some policy , called the behaviour policy, to learn the value function of another policy (possibly different from ), called the target policy.
离策略 RL 算法的目标是:用行为策略 生成的轨迹,学习另一策略 (可与 不同)的价值函数 ,称 为目标策略。
4.1 V-trace target
4.1 V-trace 目标
Consider a trajectory generated by the actor following some policy . We define the -steps V-trace target for , our value approximation at state , as:
考虑 actor 按某策略 生成的轨迹 。我们把状态 处价值近似 的 步 V-trace 目标定义为:
where is a temporal difference for , and and are truncated importance sampling (IS) weights (we make use of the notation for ). In addition we assume that the truncation levels are such that .
其中 是 的时序差分, 与 是截断重要性采样(IS)权重(并约定 时 )。此外假设截断水平满足 。
Notice that in the on-policy case (when ), and assuming that , then all and , thus (1) rewrites
注意在同策略情形()且假定 时,所有 、,于是 (1) 改写为
which is the on-policy -steps Bellman target. Thus in the on-policy case, V-trace reduces to the on-policy -steps Bellman update. This property (which Retrace (Munos et al., 2016) does not have) allows one to use the same algorithm for off- and on-policy data.
亦即同策略 步 Bellman 目标。因此同策略时 V-trace 退化为同策略 步 Bellman 更新。这一性质(Retrace (Munos et al., 2016) 不具备)使人能对离策略与同策略数据使用同一算法。
Notice that the (truncated) IS weights and play different roles. The weight appears in the definition of the temporal difference and defines the fixed point of this update rule. In a tabular case, where functions can be perfectly represented, the fixed point of this update (i.e., when for all states), characterised by being equal to zero in expectation (under ), is the value function of some policy , defined by
还要注意(截断)IS 权重 与 角色不同。 出现在时序差分 的定义中,并决定该更新规则的不动点。在表格情形、函数可完美表示时,该更新的不动点(即对所有状态 )由期望意义下 为零刻画(在 下),对应某策略 的价值函数 ,其中
(see the analysis in Appendix A ). So when is infinite (i.e. no truncation of ), then this is the value function of the target policy. However if we choose a truncation level , our fixed point is the value function of a policy which is somewhere between and . At the limit when is close to zero, we obtain the value function of the behaviour policy . In Appendix A we prove the contraction of a related V-trace operator and the convergence of the corresponding online V-trace algorithm.
(分析见附录 A)。因此当 为无穷(即不截断 )时,不动点就是目标策略的价值 。若取有限截断 ,不动点则是介于 与 之间某策略 的价值 ;当 接近零时,得到行为策略价值 。附录 A 证明了相关 V-trace 算子的压缩性,以及对应在线 V-trace 算法的收敛。
The weights are similar to the “trace cutting” coefficients in Retrace. Their product measures how much a temporal difference observed at time impacts the update of the value function at a previous time . The more dissimilar and are (the more off-policy we are), the larger the variance of this product. We use the truncation level as a variance reduction technique. However notice that this truncation does not impact the solution to which we converge (which is characterised by only).
权重 类似 Retrace 中的「轨迹截断」系数。乘积 衡量时刻 观察到的时序差分 对更早时刻 价值更新的影响有多大。 与 越不像(离策略程度越高),该乘积方差越大。我们用截断水平 做方差削减;但注意该截断不影响收敛到的解(解只由 刻画)。
Thus we see that the truncation levels and represent different features of the algorithm: impacts the nature of the value function we converge to, whereas impacts the speed at which we converge to this function.
由此可见,截断水平 与 代表算法的不同侧面: 影响我们收敛到的价值函数性质,而 影响收敛到该函数的速度。
Remark 1.
V-trace targets can be computed recursively:
注 1。
V-trace 目标可递归计算:
Remark 2.
Like in Retrace(), we can also consider an additional discounting parameter in the definition of V-trace by setting . In the on-policy case, when , V-trace then reduces to TD().
注 2。
像 Retrace() 一样,也可在 V-trace 定义中引入额外折扣参数 ,令 。同策略且 时,V-trace 退化为 TD()。
4.2 Actor-Critic algorithm
4.2 Actor-Critic 算法
Policy gradient
In the on-policy case, the gradient of the value function with respect to some parameter of the policy is
策略梯度
同策略情形下,价值函数 相对策略 某参数的梯度为
where is the state-action value of policy at . This is usually implemented by a stochastic gradient ascent that updates the policy parameters in the direction of , where is an estimate of , and averaged over the set of states that are visited under some behaviour policy .
其中 是策略 在 的状态–动作价值。实现上通常用随机梯度上升,沿 方向更新策略参数,其中 是 的估计,并在行为策略 访问到的状态集合 上平均。
Now in the off-policy setting that we consider, we can use an IS weight between the policy being evaluated and the behaviour policy , to update our policy parameter in the direction of
在我们所考虑的离策略设定下,可用被评估策略 与行为策略 之间的 IS 权重,沿下式方向更新策略参数:
where is an estimate of built from the V-trace estimate at the next state . The reason why we use instead of as the target for our Q-value is that, assuming our value estimate is correct at all states, i.e. , then we have (whereas we do not have this property if we choose ). See Appendix A for analysis and Appendix E.3 for a comparison of different ways to estimate .
其中 是用下一状态 处 V-trace 估计 构造的 估计。之所以用 而非 作为 的目标,是因为:若价值估计在所有状态都正确,即 ,则 (若取 则无此性质)。分析见附录 A,不同 估计方式的对比见附录 E.3。
In order to reduce the variance of the policy gradient estimate (4), we usually subtract from a state-dependent baseline, such as the current value approximation .
为降低策略梯度估计 (4) 的方差,通常从 减去状态相关基线,例如当前价值近似 。
Finally notice that (4) estimates the policy gradient for which is the policy evaluated by the V-trace algorithm when using a truncation level . However assuming the bias is small (e.g. if is large enough) then we can expect to provide us with a good estimate of . Taking into account these remarks, we derive the following canonical V-trace actor-critic algorithm.
最后注意,(4) 估计的是 的策略梯度,而 正是使用截断水平 时 V-trace 所评估的策略。但若偏差 较小(例如 足够大),则可期望 对 给出良好估计。综合这些备注,我们导出如下标准 V-trace actor-critic 算法。
V-trace actor-critic algorithm
Consider a parametric representation of the value function and the current policy . Trajectories have been generated by actors following some behaviour policy . The V-trace targets are defined by (1). At training time , the value parameters are updated by gradient descent on the loss to the target , i.e., in the direction of
V-trace actor-critic 算法
考虑价值函数的参数化表示 与当前策略 。轨迹由 actor 按某行为策略 生成。V-trace 目标 由 (1) 定义。训练时刻 ,价值参数 沿相对目标 的 损失做梯度下降,即沿方向
and the policy parameters in the direction of the policy gradient:
策略参数 则沿策略梯度方向:
In order to prevent premature convergence we may add an entropy bonus, like in A3C, along the direction
为防止过早收敛,可像 A3C 一样加入熵奖励,沿方向
The overall update is obtained by summing these three gradients rescaled by appropriate coefficients, which are hyperparameters of the algorithm.
总更新由这三项梯度按适当系数缩放后相加得到,系数是算法超参数。
5 Experiments
5 实验
We investigate the performance of IMPALA under multiple settings. For data efficiency, computational performance and effectiveness of the off-policy correction we look at the learning behaviour of IMPALA agents trained on individual tasks. For multi-task learning we train agents—each with one set of weights for all tasks—on a newly introduced collection of 30 DeepMind Lab tasks and on all 57 games of the Atari Learning Environment (Bellemare et al., 2013a).
我们在多种设定下考察 IMPALA 表现。为看数据效率、计算性能与离策略校正效果,观察在单项任务上训练的 IMPALA 智能体学习行为;多任务方面,则用同一套权重在一个新引入的 30 项 DeepMind Lab 任务集,以及 Arcade Learning Environment (Bellemare et al., 2013a) 全部 57 款 Atari 游戏上训练智能体。
For all the experiments we have used two different model architectures: a shallow model similar to (Mnih et al., 2016) with an LSTM before the policy and value (shown in Figure 3 (left)) and a deeper residual model (He et al., 2016) (shown in Figure 3 (right)). For tasks with a language channel we used an LSTM with text embeddings as input.
所有实验使用两种模型结构:与 (Mnih et al., 2016) 类似的浅层模型,在策略与价值前接 LSTM(图 3 左);以及更深的残差模型 (He et al., 2016)(图 3 右)。对带语言通道的任务,用文本嵌入作为输入的 LSTM。
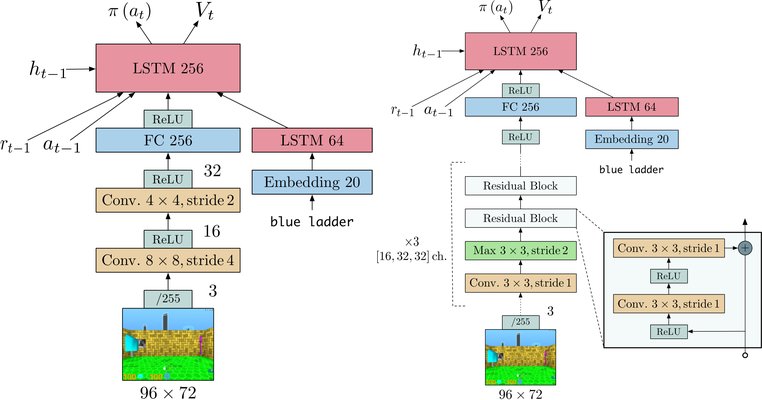
Figure 3: Model Architectures. Left: Small architecture, convolutional layers and million parameters. Right: Large architecture, convolutional layers and million parameters.
图 3:模型结构。左: 小结构,2 个卷积层,约 120 万参数。右: 大结构,15 个卷积层,约 160 万参数。
5.1 Computational Performance
5.1 计算性能
| Architecture | CPUs | GPUs1 | FPS2 | |
|---|---|---|---|---|
| Single-Machine | Task 1 | Task 2 | ||
| A3C 32 workers | 64 | 0 | 6.5K | 9K |
| Batched A2C (sync step) | 48 | 0 | 9K | 5K |
| Batched A2C (sync step) | 48 | 1 | 13K | 5.5K |
| Batched A2C (sync traj.) | 48 | 0 | 16K | 17.5K |
| Batched A2C (dyn. batch) | 48 | 1 | 16K | 13K |
| IMPALA 48 actors | 48 | 0 | 17K | 20.5K |
| IMPALA (dyn. batch) 48 actors3 | 48 | 1 | 21K | 24K |
| Distributed | ||||
| A3C | 200 | 0 | 46K | 50K |
| IMPALA | 150 | 1 | 80K | |
| IMPALA (optimised) | 375 | 1 | 200K | |
| IMPALA (optimised) batch 128 | 500 | 1 | 250K |
Table 1: Throughput on seekavoid_arena_01 (task 1) and rooms_keys_doors_puzzle (task 2) with the shallow model in Figure 3. The latter has variable length episodes and slow restarts. Batched A2C and IMPALA use batch size 32 if not otherwise mentioned.
| Architecture | CPUs | GPUs1 | FPS2 | |
|---|---|---|---|---|
| Single-Machine | Task 1 | Task 2 | ||
| A3C 32 workers | 64 | 0 | 6.5K | 9K |
| Batched A2C (sync step) | 48 | 0 | 9K | 5K |
| Batched A2C (sync step) | 48 | 1 | 13K | 5.5K |
| Batched A2C (sync traj.) | 48 | 0 | 16K | 17.5K |
| Batched A2C (dyn. batch) | 48 | 1 | 16K | 13K |
| IMPALA 48 actors | 48 | 0 | 17K | 20.5K |
| IMPALA (dyn. batch) 48 actors3 | 48 | 1 | 21K | 24K |
| Distributed | ||||
| A3C | 200 | 0 | 46K | 50K |
| IMPALA | 150 | 1 | 80K | |
| IMPALA (optimised) | 375 | 1 | 200K | |
| IMPALA (optimised) batch 128 | 500 | 1 | 250K |
表 1:在 seekavoid_arena_01(任务 1)与 rooms_keys_doors_puzzle(任务 2)上用图 3 浅层模型的吞吐。后者回合长度可变且重启较慢。批处理 A2C 与 IMPALA 若无另说明则批大小为 32。
High throughput, computational efficiency and scalability are among the main design goals of IMPALA. To demonstrate that IMPALA outperforms current algorithms in these metrics we compare A3C (Mnih et al., 2016), batched A2C variations and IMPALA variants with various optimisations. For single-machine experiments using GPUs, we use dynamic batching in the forward pass to avoid several batch size 1 forward passes. Our dynamic batching module is implemented by specialised TensorFlow operations but is conceptually similar to the queues used in GA3C. Table 1 details the results for single-machine and multi-machine versions with the shallow model from Figure 3. In the single-machine case, IMPALA achieves the highest performance on both tasks, ahead of all batched A2C variants and ahead of A3C. However, the distributed, multi-machine setup is where IMPALA can really demonstrate its scalability. With the optimisations from Section 3.1 to speed up the GPU-based learner, the IMPALA agent achieves a throughput rate of 250,000 frames/sec or billion frames/day. Note, to reduce the number of actors needed per learner, one can use auxiliary losses, data from experience replay or other expensive learner-only computation.
高吞吐、计算效率与可扩展性是 IMPALA 的主要设计目标。为说明它在这些指标上优于现有算法,我们比较 A3C (Mnih et al., 2016)、批处理 A2C 变体,以及带多种优化的 IMPALA 变体。单机 GPU 实验中,我们在前向中使用动态批处理,以避免多次批大小为 1 的前向。动态批处理模块由专用 TensorFlow 算子实现,概念上类似 GA3C 所用队列。表 1 给出图 3 浅层模型下单机与多机版本结果。单机情形下,IMPALA 在两项任务上都取得最高性能,超过所有批处理 A2C 变体与 A3C。但真正展现可扩展性的是分布式多机设定:借助第 3.1 节加速 GPU learner 的优化,IMPALA 智能体达到 250,000 帧/秒或每天 210 亿帧。注意,若要减少每个 learner 所需 actor 数,可用辅助损失、经验回放数据或其他昂贵的仅 learner 侧计算。
5.2 Single-Task Training
5.2 单任务训练
To investigate IMPALA’s learning dynamics, we employ the single-task scenario where we train agents individually on 5 different DeepMind Lab tasks. The task set consists of a planning task, two maze navigation tasks, a laser tag task with scripted bots and a simple fruit collection task.
为考察 IMPALA 的学习动态,我们采用单任务场景:在 5 项不同的 DeepMind Lab 任务上分别训练智能体。任务集包含一项规划任务、两项迷宫导航、一项带脚本机器人的激光标签,以及一项简单水果收集。
We perform hyperparameter sweeps over the weighting of entropy regularisation, the learning rate and the RMSProp epsilon. For each experiment we use an identical set of 24 pre-sampled hyperparameter combinations from the ranges in Appendix D.1 . The other hyperparameters were fixed to values specified in Appendix D.3 .
我们对 熵正则 权重、学习率 与 RMSProp epsilon 做超参扫描。每次实验使用附录 D.1 范围内预先采样的同一组 24 组超参组合;其余超参固定为附录 D.3 所列取值。
5.2.1 Convergence and Stability
Figure 4 shows a comparison between IMPALA, A3C and batched A2C with the shallow model in Figure 3. In all of the 5 tasks, either batched A2C or IMPALA reach the best final average return and in all tasks but seekavoid_arena_01 they are ahead of A3C throughout the entire course of training. IMPALA outperforms the synchronous batched A2C on 2 out of 5 tasks while achieving much higher throughput (see Table 1). We hypothesise that this behaviour could stem from the V-trace off-policy correction acting similarly to generalised advantage estimation (Schulman et al., 2016) and asynchronous data collection yielding more diverse batches of experience.
5.2.1 收敛与稳定性
图 4 比较了 IMPALA、A3C 与批处理 A2C(均用图 3 浅层模型)。五项任务中,最终平均回报最佳者总是批处理 A2C 或 IMPALA;除 seekavoid_arena_01 外,全程也领先 A3C。IMPALA 在 5 项中的 2 项上超过同步批处理 A2C,同时吞吐高得多(见表 1)。我们猜测:这可能因为 V-trace 离策略校正的作用类似广义优势估计 (Schulman et al., 2016),且异步采集使经验批次更多样。

Figure 4: Top Row: Single task training on 5 DeepMind Lab tasks. Each curve is the mean of the best 3 runs based on final return. IMPALA achieves better performance than A3C. Bottom Row: Stability across hyperparameter combinations sorted by the final performance across different hyperparameter combinations. IMPALA is consistently more stable than A3C.
图 4:上行:5 项 DeepMind Lab 任务上的单任务训练。每条曲线为按最终回报取最佳 3 次运行的均值。IMPALA 表现优于 A3C。下行:按最终表现排序的不同超参组合稳定性。IMPALA 一贯比 A3C 更稳。
In addition to reaching better final performance, IMPALA is also more robust to the choice of hyperparameters than A3C. Figure 4 compares the final performance of the aforementioned methods across different hyperparameter combinations, sorted by average final return from high to low. Note that IMPALA achieves higher scores over a larger number of combinations than A3C.
除最终表现更好外,IMPALA 对超参选择也比 A3C 更鲁棒。图 4 比较了上述方法在不同超参组合下的最终表现,按平均最终回报从高到低排序。可见 IMPALA 在更多组合上取得更高分数。
5.2.2 V-trace Analysis
| Task 1 | Task 2 | Task 3 | Task 4 | Task 5 | |
|---|---|---|---|---|---|
| Without Replay | |||||
| V-trace | 46.8 | 32.9 | 31.3 | 229.2 | 43.8 |
| 1-Step | 51.8 | 35.9 | 25.4 | 215.8 | 43.7 |
| -correction | 44.2 | 27.3 | 4.3 | 107.7 | 41.5 |
| No-correction | 40.3 | 29.1 | 5.0 | 94.9 | 16.1 |
| With Replay | |||||
| V-trace | 47.1 | 35.8 | 34.5 | 250.8 | 46.9 |
| 1-Step | 54.7 | 34.4 | 26.4 | 204.8 | 41.6 |
| -correction | 30.4 | 30.2 | 3.9 | 101.5 | 37.6 |
| No-correction | 35.0 | 21.1 | 2.8 | 85.0 | 11.2 |
Table 2: Average final return over 3 best hyperparameters for different off-policy correction methods on 5 DeepMind Lab tasks. When the lag in policy is negligible both V-trace and 1-step importance sampling perform similarly well and better than -correction/No-correction. However, when the lag increases due to use of experience replay, V-trace performs better than all other methods in out tasks.
5.2.2 V-trace 分析
To analyse V-trace we investigate four different algorithms: 1. No-correction - No off-policy correction. 2. -correction - Add a small value () during gradient calculation to prevent from becoming very small and leading to numerical instabilities, similar to (Babaeizadeh et al., 2016). 3. 1-step importance sampling - No off-policy correction when optimising . For the policy gradient, multiply the advantage at each time step by the corresponding importance weight. This variant is similar to V-trace without “traces” and is included to investigate the importance of “traces” in V-trace. 4. V-trace as described in Section 4.
| Task 1 | Task 2 | Task 3 | Task 4 | Task 5 | |
|---|---|---|---|---|---|
| Without Replay | |||||
| V-trace | 46.8 | 32.9 | 31.3 | 229.2 | 43.8 |
| 1-Step | 51.8 | 35.9 | 25.4 | 215.8 | 43.7 |
| -correction | 44.2 | 27.3 | 4.3 | 107.7 | 41.5 |
| No-correction | 40.3 | 29.1 | 5.0 | 94.9 | 16.1 |
| With Replay | |||||
| V-trace | 47.1 | 35.8 | 34.5 | 250.8 | 46.9 |
| 1-Step | 54.7 | 34.4 | 26.4 | 204.8 | 41.6 |
| -correction | 30.4 | 30.2 | 3.9 | 101.5 | 37.6 |
| No-correction | 35.0 | 21.1 | 2.8 | 85.0 | 11.2 |
表 2:5 项 DeepMind Lab 任务上,不同离策略校正方法在最佳 3 组超参上的平均最终回报。策略滞后可忽略时,V-trace 与 1 步重要性采样表现相近,且优于 -校正/无校正。但使用经验回放使滞后增大时,V-trace 在 5 项中的 4 项上优于其余方法。
For V-trace and 1-step importance sampling we clip each importance weight and at (i.e. . This reduces the variance of the gradient estimate but introduces a bias. Out of we found that worked best.
为分析 V-trace,我们考察四种算法:1. 无校正——不做离策略校正。2. -校正——梯度计算时加小常数(),防止 过小导致数值不稳,类似 (Babaeizadeh et al., 2016)。3. 1 步重要性采样——优化 时不做离策略校正;对策略梯度,在每步优势上乘对应重要性权重。该变体类似去掉「轨迹」的 V-trace,用于考察「轨迹」的重要性。4. V-trace,见第 4 节。
We evaluate all algorithms on the set of 5 DeepMind Lab tasks from the previous section. We also add an experience replay buffer on the learner to increase the off-policy gap between and . In the experience replay experiments we draw 50% of the items in each batch uniformly at random from the replay buffer. Table 2 shows the final performance for each algorithm with and without replay respectively. In the no replay setting, V-trace performs best on 3 out of 5 tasks, followed by 1-step importance sampling, -correction and No-correction. Although 1-step importance sampling performs similarly to V-trace in the no-replay setting, the gap widens on 4 out 5 tasks when using experience replay. This suggests that the cruder 1-step importance sampling approximation becomes insufficient as the target and behaviour policies deviate from each other more strongly. Also note that V-trace is the only variant that consistently benefits from adding experience replay. -correction improves significantly over No-correction on two tasks but lies far behind the importance-sampling based methods, particularly in the more off-policy setting with experience replay. Figure E.1 shows results of a more detailed analysis. Figure E.2 shows that the importance-sampling based methods also perform better across all hyperparameters and are typically more robust.
对 V-trace 与 1 步重要性采样,我们将每个重要性权重 、 截断于 1(即 )。这降低梯度估计方差,但引入偏差。在 中, 效果最好。
5.3 Multi-Task Training
5.3 多任务训练
IMPALA’s high data throughput and data efficiency allow us to train not only on one task but on multiple tasks in parallel with only a minimal change to the training setup. Instead of running the same task on all actors, we allocate a fixed number of actors to each task in the multi-task suite. Note, the model does not know which task it is being trained or evaluated on.
IMPALA 的高吞吐与数据效率使我们不仅能训单任务,还能几乎不改训练设定地并行训多任务:不再让所有 actor 跑同一任务,而是给多任务套件中每个任务分配固定数量的 actor。注意,模型并不知道自己正在训练或评估的是哪项任务。
5.3.1 DMLab-30
| Model | Test score |
|---|---|
| A3C, deep | 23.8% |
| IMPALA, shallow | 37.1% |
| IMPALA-Experts, deep | 44.5% |
| IMPALA, deep | 46.5% |
| IMPALA, deep, PBT | 49.4% |
| IMPALA, deep, PBT, 8 learners | 49.1% |
Table 3: Mean capped human normalised scores on DMLab-30. All models were evaluated on the test tasks with 500 episodes per task. The table shows the best score for each architecture.
5.3.1 DMLab-30
To test IMPALA’s performance in a multi-task setting we use DMLab-30, a set of 30 diverse tasks built on DeepMind Lab. Among the many task types in the suite are visually complex environments with natural-looking terrain, instruction-based tasks with grounded language (Hermann et al., 2017), navigation tasks, cognitive (Leibo et al., 2018) and first-person tagging tasks featuring scripted bots as opponents. A detailed description of DMLab-30 and the tasks are available at github.com/deepmind/lab and deepmind.com/dm-lab-30.
| Model | Test score |
|---|---|
| A3C, deep | 23.8% |
| IMPALA, shallow | 37.1% |
| IMPALA-Experts, deep | 44.5% |
| IMPALA, deep | 46.5% |
| IMPALA, deep, PBT | 49.4% |
| IMPALA, deep, PBT, 8 learners | 49.1% |
表 3:DMLab-30 上的均值截断人类归一化分数。所有模型在测试任务上每任务评估 500 个回合。表中为各结构的最佳分数。
We compare multiple variants of IMPALA with a distributed A3C implementation. Except for agents using population-based training (PBT) (Jaderberg et al., 2017), all agents are trained with hyperparameter sweeps across the same range given in Appendix D.1 . We report mean capped human normalised score where the score for each task is capped at 100% (see Appendix B ). Using mean capped human normalised score emphasises the need to solve multiple tasks instead of focusing on becoming super human on a single task. For PBT we use the mean capped human normalised score as fitness function and tune entropy cost, learning rate and RMSProp . See Appendix F for the specifics of the PBT setup.
为检验多任务设定下的 IMPALA,我们使用 DMLab-30:基于 DeepMind Lab 的 30 项多样任务。套件中任务类型包括视觉复杂、地形自然的环境,带有接地语言的指令任务 (Hermann et al., 2017),导航任务,认知任务 (Leibo et al., 2018),以及带脚本机器人对手的第一人称标签任务。DMLab-30 与各任务详情见 github.com/deepmind/lab 与 deepmind.com/dm-lab-30。
In particular, we compare the following agent variants. A3C, deep, a distributed implementation with 210 workers (7 per task) featuring the deep residual network architecture (Figure 3 (Right)). IMPALA, shallow with 210 actors and IMPALA, deep with 150 actors both with a single learner. IMPALA, deep, PBT, the same as IMPALA, deep, but additionally using the PBT (Jaderberg et al., 2017) for hyperparameter optimisation. Finally IMPALA, deep, PBT, 8 learners, which utilises 8 learner GPUs to maximise learning speed. We also train IMPALA agents in an expert setting, IMPALA-Experts, deep, where a separate agent is trained per task. In this case we did not optimise hyperparameters for each task separately but instead across all tasks on which the 30 expert agents were trained.
我们比较多种 IMPALA 变体与分布式 A3C 实现。除使用基于种群训练(PBT)(Jaderberg et al., 2017) 的智能体外,其余均在附录 D.1 同一范围内做超参扫描。我们报告均值截断人类归一化分数:每项任务分数截断于 100%(见附录 B)。该指标强调需要解决多项任务,而非只在单任务上超人类。对 PBT,以适应度函数取均值截断人类归一化分数,并调节熵代价、学习率与 RMSProp 。PBT 设定见附录 F。
Table 3 and Figure 6 show all variants of IMPALA performing much better than the deep distributed A3C. Moreover, the deep variant of IMPALA performs better than the shallow network version not only in terms of final performance but throughout the entire training. Note in Table 3 that IMPALA, deep, PBT, 8 learners, although providing much higher throughput, reaches the same final performance as the 1 GPU IMPALA, deep, PBT in the same number of steps. Of particular importance is the gap between the IMPALA-Experts which were trained on each task individually and IMPALA, deep, PBT which was trained on all tasks at once. As Figure 6 shows, the multi-task version is outperforms IMPALA-Experts throughout training and the breakdown into individual scores in Appendix B shows positive transfer on tasks such as language tasks and laser tag tasks.
具体比较以下变体。A3C, deep:210 个工作者(每任务 7 个)的分布式实现,使用深度残差网络(图 3 右)。IMPALA, shallow:210 个 actor;IMPALA, deep:150 个 actor,均配单个 learner。IMPALA, deep, PBT:同 IMPALA, deep,另用 PBT (Jaderberg et al., 2017) 做超参优化。最后 IMPALA, deep, PBT, 8 learners 使用 8 块 learner GPU 以最大化学习速度。我们还在专家设定下训练 IMPALA:IMPALA-Experts, deep,每任务单独一个智能体;此时并未为每任务单独调超参,而是在 30 个专家智能体所训全部任务上统一搜索。
Comparing A3C to IMPALA with respect to wall clock time (Figure 6) further highlights the scalability gap between the two approaches. IMPALA with 1 learner takes only around 10 hours to reach the same performance that A3C approaches after 7.5 days. Using 8 learner GPUs instead of 1 further speeds up training of the deep model by a factor of 7 to 210K frames/sec, up from 30K frames/sec.
表 3 与图 6 显示,所有 IMPALA 变体都远好于深度分布式 A3C。而且 IMPALA 的深度变体不仅最终表现优于浅层网络版,全程训练也更好。表 3 中 IMPALA, deep, PBT, 8 learners 尽管吞吐高得多,却以相同步数达到与 1 GPU 的 IMPALA, deep, PBT 相同的最终表现。尤其重要的是:逐任务训练的 IMPALA-Experts 与同时训全部任务的 IMPALA, deep, PBT 之间的差距。如图 6 所示,多任务版全程优于 IMPALA-Experts;附录 B 的分项分数还显示,在语言任务与激光标签等任务上存在正向迁移。
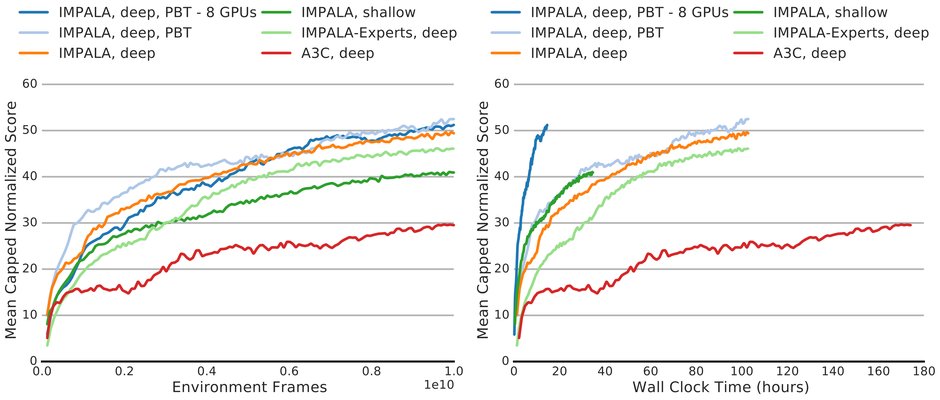
Figure 5: Performance of best agent in each sweep/population during training on the DMLab-30 task-set wrt. data consumed across all environments. IMPALA with multi-task training is not only faster, it also converges at higher accuracy with better data efficiency across all 30 tasks. The x-axis is data consumed by one agent out of a hyperparameter sweep/PBT population of 24 agents, total data consumed across the whole population/sweep can be obtained by multiplying with the population/sweep size.
按墙钟时间比较 A3C 与 IMPALA(图 6)进一步凸显两者可扩展性差距。1 个 learner 的 IMPALA 约 10 小时即可达到 A3C 跑 7.5 天后接近的表现。用 8 块 learner GPU 替代 1 块,还把深度模型训练再加速约 7 倍,从 30K 帧/秒提到 210K 帧/秒。
5.3.2 Atari
The Atari Learning Environment (ALE) (Bellemare et al., 2013b) has been the testing ground of most recent deep reinforcement agents. Its 57 tasks pose challenging reinforcement learning problems including exploration, planning, reactive play and complex visual input. Most games feature very different visuals and game mechanics which makes this domain particularly challenging for multi-task learning.
图 5:在 DMLab-30 任务集上,各扫描/种群中最佳智能体相对跨环境总数据消耗的训练表现。多任务训练的 IMPALA 不仅更快,还在全部 30 项任务上以更好的数据效率收敛到更高精度。横轴是超参扫描/PBT 种群(24 个智能体)中单个智能体的数据消耗;整个人群/扫描的总数据消耗需再乘以种群/扫描规模。
We train IMPALA and A3C agents on each game individually and compare their performance using the deep network (without the LSTM) introduced in Section 5. We also provide results using a shallow network that is equivalent to the feed forward network used in (Mnih et al., 2016) which features three convolutional layers. The network is provided with a short term history by stacking the 4 most recent observations at each step. For details on pre-processing and hyperparameter setup please refer to Appendix G .
5.3.2 Atari
Atari Learning Environment(ALE)(Bellemare et al., 2013b) 是多数近期深度强化学习智能体的试验场。其 57 项任务构成具挑战性的 RL 问题,涵盖探索、规划、反应式游玩与复杂视觉输入。多数游戏视觉与机制差异很大,使该领域对多任务学习尤其困难。
In addition to individual per-game experts, trained for 200 million frames with a fixed set of hyperparameters, we train an IMPALA Atari-57 agent—one agent, one set of weights—on all 57 Atari games at once for 200 million frames per game or a total of 11.4 billion frames. For the Atari-57 agent, we use population based training with a population size of 24 to adapt entropy regularisation, learning rate, RMSProp and the global gradient norm clipping threshold throughout training.
我们在每款游戏上分别训练 IMPALA 与 A3C,并用第 5 节引入的深度网络(不含 LSTM)比较表现。还给出与 (Mnih et al., 2016) 所用前馈网络等价的浅层网络结果,该网络含三个卷积层。网络通过堆叠最近 4 帧观测获得短期历史。预处理与超参设定见附录 G。
| Human Normalised Return | Median | Mean |
|---|---|---|
| A3C, shallow, experts | 54.9% | 285.9% |
| A3C, deep, experts | 117.9% | 503.6% |
| Reactor, experts | 187% | N/A |
| IMPALA, shallow, experts | 93.2% | 466.4% |
| IMPALA, deep, experts | 191.8% | 957.6% |
| IMPALA, deep, multi-task | 59.7% | 176.9% |
Table 4: Human normalised scores on Atari-57. Up to 30 no-ops at the beginning of each episode. For a level-by-level comparison to ACKTR (Wu et al., 2017) and Reactor see Appendix C.1 .
除按游戏训练的专家外,我们还训练 IMPALA Atari-57 智能体——一个智能体、一套权重——同时覆盖全部 57 款 Atari,每游戏 2 亿帧,合计 114 亿帧。对该 Atari-57 智能体,我们用规模 24 的种群训练,在训练过程中调节熵正则、学习率、RMSProp 与全局梯度范数裁剪阈值。
We compare all algorithms in terms of median human normalised score across all 57 Atari games. Evaluation follows a standard protocol, each game-score is the mean over 200 evaluation episodes, each episode was started with a random number of no-op actions (uniformly chosen from [1, 30]) to combat the determinism of the ALE environment.
| Human Normalised Return | Median | Mean |
|---|---|---|
| A3C, shallow, experts | 54.9% | 285.9% |
| A3C, deep, experts | 117.9% | 503.6% |
| Reactor, experts | 187% | N/A |
| IMPALA, shallow, experts | 93.2% | 466.4% |
| IMPALA, deep, experts | 191.8% | 957.6% |
| IMPALA, deep, multi-task | 59.7% | 176.9% |
表 4:Atari-57 上的人类归一化分数。每回合开始最多 30 次空操作。逐关对比 ACKTR (Wu et al., 2017) 与 Reactor 见附录 C.1。
As table 4 shows, IMPALA experts provide both better final performance and data efficiency than their A3C counterparts in the deep and the shallow configuration. As in our DeepMind Lab experiments, the deep residual network leads to higher scores than the shallow network, irrespective of the reinforcement learning algorithm used. Note that the shallow IMPALA experiment completes training over 200 million frames in less than one hour.
我们按全部 57 款 Atari 的人类归一化分数中位数比较各算法。评估遵循标准协议:每游戏分数为 200 个评估回合均值,每回合以随机次数的空操作开局(在 [1, 30] 上均匀采样),以缓解 ALE 环境的确定性。
We want to particularly emphasise that IMPALA, deep, multi-task, a single agent trained on all 57 ALE games at once, reaches 59.7% median human normalised score. Despite the high diversity in visual appearance and game mechanics within the ALE suite, IMPALA multi-task still manages to stay competitive to A3C, shallow, experts, commonly used as a baseline in related work. ALE is typically considered a hard multi-task environment, often accompanied by negative transfer between tasks (Rusu et al., 2016). To our knowledge, IMPALA is the first agent to be trained in a multi-task setting on all 57 games of ALE that is competitive with a standard expert baseline.
如表 4 所示,在深度与浅层配置下,IMPALA 专家都比对应 A3C 有更好最终表现与数据效率。与 DeepMind Lab 实验一样,无论用哪种强化学习算法,深度残差网络分数都高于浅层网络。注意浅层 IMPALA 实验在不到一小时内完成 2 亿帧训练。
6 Conclusion
6 结论
We have introduced a new highly scalable distributed agent, IMPALA, and a new off-policy learning algorithm, V-trace. With its simple but scalable distributed architecture, IMPALA can make efficient use of available compute at small and large scale. This directly translates to very quick turnaround for investigating new ideas and opens up unexplored opportunities.
我们提出了高度可扩展的分布式智能体 IMPALA,以及新的离策略学习算法 V-trace。凭借简单却可扩展的分布式架构,IMPALA 能在小规模与大规模上高效利用可用算力。这直接转化为验证新想法的更快迭代,并打开了尚未探索的机会。
V-trace is a general off-policy learning algorithm that is more stable and robust compared to other off-policy correction methods for actor critic agents. We have demonstrated that IMPALA achieves better performance compared to A3C variants in terms of data efficiency, stability and final performance. We have further evaluated IMPALA on the new DMLab-30 set and the Atari-57 set. To the best of our knowledge, IMPALA is the first Deep-RL agent that has been successfully tested in such large-scale multi-task settings and it has shown superior performance compared to A3C based agents (49.4% vs. 23.8% human normalised score on DMLab-30). Most importantly, our experiments on DMLab-30 show that, in the multi-task setting, positive transfer between individual tasks lead IMPALA to achieve better performance compared to the expert training setting. We believe that IMPALA provides a simple yet scalable and robust framework for building better Deep-RL agents and has the potential to enable research on new challenges.
V-trace 是通用离策略学习算法,相对其他面向 actor-critic 智能体的离策略校正更稳定、更鲁棒。我们展示 IMPALA 在数据效率、稳定性与最终表现上优于 A3C 变体;并在新的 DMLab-30 与 Atari-57 上进一步评估。据我们所知,IMPALA 是首个在如此大规模多任务设定中成功验证的深度 RL 智能体,相对基于 A3C 的智能体表现更优(DMLab-30 上人类归一化分数 49.4% 对 23.8%)。最重要的是,DMLab-30 实验表明:多任务设定下任务间正向迁移使 IMPALA 优于专家训练设定。我们相信 IMPALA 提供了简单却可扩展、鲁棒的框架,用于构建更好的深度 RL 智能体,并有潜力支撑新挑战上的研究。
Acknowledgements
致谢
We would like to thank Denis Teplyashin, Ricardo Barreira, Manuel Sanchez for their work improving the performance on DMLab-30 environments and Matteo Hessel, Jony Hudson, Igor Babuschkin, Max Jaderberg, Ivo Danihelka, Jacob Menick and David Silver for their comments and insightful discussions.
感谢 Denis Teplyashin、Ricardo Barreira、Manuel Sanchez 改进 DMLab-30 环境性能,以及 Matteo Hessel、Jony Hudson、Igor Babuschkin、Max Jaderberg、Ivo Danihelka、Jacob Menick 与 David Silver 的评论与深入讨论。
References
参考文献
Abadi et al. (2017) Abadi, M., Isard, M., and Murray, D. G. A computational model for tensorflow: An introduction. In Proceedings of the 1st ACM SIGPLAN International Workshop on Machine Learning and Programming Languages , MAPL 2017, 2017. ISBN 978-1-4503-5071-6.
Adamski et al. (2018) Adamski, I., Adamski, R., Grel, T., Jedrych, A., Kaczmarek, K., and Michalewski, H. Distributed deep reinforcement learning: Learn how to play atari games in 21 minutes. CoRR , abs/1801.02852, 2018.
Appleyard et al. (2016) Appleyard, J., Kociský, T., and Blunsom, P. Optimizing performance of recurrent neural networks on gpus. CoRR , abs/1604.01946, 2016.
Babaeizadeh et al. (2016) Babaeizadeh, M., Frosio, I., Tyree, S., Clemons, J., and Kautz, J. GA3C: GPU-based A3C for deep reinforcement learning. NIPS Workshop , 2016.
Barth-Maron et al. (2018) Barth-Maron, G., Hoffman, M. W., Budden, D., Dabney, W., Horgan, D., Tirumala, D., Muldal, A., Heess, N., and Lillicrap, T. Distributional policy gradients. ICLR , 2018.
Beattie et al. (2016) Beattie, C., Leibo, J. Z., Teplyashin, D., Ward, T., Wainwright, M., Kuttler, H., Lefrancq, A., Green, S., Valdes, V., Sadik, A., Schrittwieser, J., Anderson, K., York, S., Cant, M., Cain, A., Bolton, A., Gaffney, S., King, H., Hassabis, D., Legg, S., and Petersen, S. Deepmind lab. CoRR , abs/1612.03801, 2016.
Bellemare et al. (2013a) Bellemare, M. G., Naddaf, Y., Veness, J., and Bowling, M. The Arcade Learning Environment: An evaluation platform for general agents. Journal of Artificial Intelligence Research , 47:253–279, June 2013a.
Bellemare et al. (2013b) Bellemare, M. G., Naddaf, Y., Veness, J., and Bowling, M. The arcade learning environment: An evaluation platform for general agents. J. Artif. Intell. Res.(JAIR) , 47:253–279, 2013b.
Chen et al. (2016) Chen, J., Monga, R., Bengio, S., and Józefowicz, R. Revisiting distributed synchronous SGD. CoRR , abs/1604.00981, 2016.
Chetlur et al. (2014) Chetlur, S., Woolley, C., Vandermersch, P., Cohen, J., Tran, J., Catanzaro, B., and Shelhamer, E. cudnn: Efficient primitives for deep learning. CoRR , abs/1410.0759, 2014.
Clemente et al. (2017) Clemente, A. V., Martínez, H. N. C., and Chandra, A. Efficient parallel methods for deep reinforcement learning. CoRR , abs/1705.04862, 2017.
Dean et al. (2012) Dean, J., Corrado, G., Monga, R., Chen, K., Devin, M., Mao, M., Ranzato, M., Senior, A., Tucker, P., Yang, K., Le, Q. V., and Ng, A. Y. Large scale distributed deep networks. In Advances in Neural Information Processing Systems 25 , pp. 1223–1231, 2012.
Geist & Scherrer (2014) Geist, M. and Scherrer, B. Off-policy learning with eligibility traces: A survey. The Journal of Machine Learning Research , 15(1):289–333, 2014.
Gruslys et al. (2018) Gruslys, A., Dabney, W., Azar, M. G., Piot, B., Bellemare, M. G., and Munos, R. The Reactor: A fast and sample-efficient actor-critic agent for reinforcement learning. ICLR , 2018.
Harutyunyan et al. (2016) Harutyunyan, A., Bellemare, M. G., Stepleton, T., and Munos, R. Q( λ \lambda ) with Off-Policy Corrections , pp. 305–320. Springer International Publishing, Cham, 2016.
He et al. (2016) He, K., Zhang, X., Ren, S., and Sun, J. Identity mappings in deep residual networks. In European Conference on Computer Vision , pp. 630–645. Springer, 2016.
Hermann et al. (2017) Hermann, K. M., Hill, F., Green, S., Wang, F., Faulkner, R., Soyer, H., Szepesvari, D., Czarnecki, W., Jaderberg, M., Teplyashin, D., et al. Grounded language learning in a simulated 3d world. arXiv preprint arXiv:1706.06551 , 2017.
Hochreiter & Schmidhuber (1997) Hochreiter, S. and Schmidhuber, J. Long short-term memory. Neural computation , 9(8):1735–1780, 1997.
Horgan et al. (2018) Horgan, D., Quan, J., Budden, D., Barth-Maron, G., Hessel, M., van Hasselt, H., and Silver, D. Distributed prioritized experience replay. ICLR , 2018.
Jaderberg et al. (2017a) Jaderberg, M., Dalibard, V., Osindero, S., Czarnecki, W. M., Donahue, J., Razavi, A., Vinyals, O., Green, T., Dunning, I., Simonyan, K., Fernando, C., and Kavukcuoglu, K. Population based training of neural networks. CoRR , abs/1711.09846, 2017a.
Jaderberg et al. (2017b) Jaderberg, M., Mnih, V., Czarnecki, W. M., Schaul, T., Leibo, J. Z., Silver, D., and Kavukcuoglu, K. Reinforcement learning with unsupervised auxiliary tasks. ICLR , 2017b.
Leibo et al. (2018) Leibo, J. Z., d’Autume, C. d. M., Zoran, D., Amos, D., Beattie, C., Anderson, K., Castañeda, A. G., Sanchez, M., Green, S., Gruslys, A., et al. Psychlab: A psychology laboratory for deep reinforcement learning agents. arXiv preprint arXiv:1801.08116 , 2018.
Lillicrap et al. (2015) Lillicrap, T. P., Hunt, J. J., Pritzel, A., Heess, N., Erez, T., Tassa, Y., Silver, D., and Wierstra, D. Continuous control with deep reinforcement learning. arXiv preprint arXiv:1509.02971 , 2015.
Mnih et al. (2015) Mnih, V., Kavukcuoglu, K., Silver, D., Rusu, A. A., Veness, J., Bellemare, M. G., Graves, A., Riedmiller, M., Fidjeland, A. K., Ostrovski, G., et al. Human-level control through deep reinforcement learning. Nature , 518(7540):529–533, 2015.
Mnih et al. (2016) Mnih, V., Badia, A. P., Mirza, M., Graves, A., Lillicrap, T. P., Harley, T., Silver, D., and Kavukcuoglu, K. Asynchronous methods for deep reinforcement learning. ICML , 2016.
Munos et al. (2016) Munos, R., Stepleton, T., Harutyunyan, A., and Bellemare, M. Safe and efficient off-policy reinforcement learning. In Advances in Neural Information Processing Systems , pp. 1046–1054, 2016.
Nair et al. (2015) Nair, A., Srinivasan, P., Blackwell, S., Alcicek, C., Fearon, R., Maria, A. D., Panneershelvam, V., Suleyman, M., Beattie, C., Petersen, S., Legg, S., Mnih, V., Kavukcuoglu, K., and Silver, D. Massively parallel methods for deep reinforcement learning. CoRR , abs/1507.04296, 2015.
O’Donoghue et al. (2017) O’Donoghue, B., Munos, R., Kavukcuoglu, K., and Mnih, V. Combining policy gradient and Q-learning. In ICLR , 2017.
Precup et al. (2000) Precup, D., Sutton, R. S., and Singh, S. Eligibility traces for off-policy policy evaluation. In Proceedings of the Seventeenth International Conference on Machine Learning , 2000.
Precup et al. (2001) Precup, D., Sutton, R. S., and Dasgupta, S. Off-policy temporal-difference learning with function approximation. In Proceedings of the 18th International Conference on Machine Laerning , pp. 417–424, 2001.
Puterman (1994) Puterman, M. L. Markov Decision Processes: Discrete Stochastic Dynamic Programming . John Wiley & Sons, Inc., New York, NY, USA, 1st edition, 1994. ISBN 0471619779.
Rusu et al. (2016) Rusu, A. A., Rabinowitz, N. C., Desjardins, G., Soyer, H., Kirkpatrick, J., Kavukcuoglu, K., Pascanu, R., and Hadsell, R. Progressive neural networks. arXiv preprint arXiv:1606.04671 , 2016.
Salimans et al. (2017) Salimans, T., Ho, J., Chen, X., and Sutskever, I. Evolution strategies as a scalable alternative to reinforcement learning. arXiv preprint arXiv:1703.03864 , 2017.
Schulman et al. (2016) Schulman, J., Moritz, P., Levine, S., Jordan, M., and Abbeel, P. High-dimensional continuous control using generalized advantage estimation. In ICLR , 2016.
Silver et al. (2016) Silver, D., Huang, A., Maddison, C. J., Guez, A., Sifre, L., van den Driessche, G., Schrittwieser, J., Antonoglou, I., Panneershelvam, V., Lanctot, M., Dieleman, S., Grewe, D., Nham, J., Kalchbrenner, N., Sutskever, I., Lillicrap, T., Leach, M., Kavukcuoglu, K., Graepel, T., and Hassabis, D. Mastering the game of go with deep neural networks and tree search. Nature , 529:484–503, 2016.
Silver et al. (2017) Silver, D., Schrittwieser, J., Simonyan, K., Antonoglou, I., Huang, A., Guez, A., Hubert, T., Baker, L., Lai, M., Bolton, A., Chen, Y., Lillicrap, T., Hui, F., Sifre, L., Driessche, G. v. d., Graepel, T., and Hassabis, D. Mastering the game of go without human knowledge. Nature , 550(7676):354–359, 10 2017. ISSN 0028-0836. doi: 10.1038/nature24270 .
Sutton & Barto (1998) Sutton, R. and Barto, A. Reinforcement learning: An introduction , volume 116. Cambridge Univ Press, 1998.
Wang et al. (2017) Wang, Z., Bapst, V., Heess, N., Mnih, V., Munos, R., Kavukcuoglu, K., and de Freitas, N. Sample efficient actor-critic with experience replay. In ICLR , 2017.
Wawrzynski (2009) Wawrzynski, P. Real-time reinforcement learning by sequential actor-critics and experience replay. Neural Networks , 22(10):1484–1497, 2009.
Wu et al. (2017) Wu, Y., Mansimov, E., Liao, S., Grosse, R. B., and Ba, J. Scalable trust-region method for deep reinforcement learning using kronecker-factored approximation. CoRR , abs/1708.05144, 2017.
Zoph et al. (2017) Zoph, B., Vasudevan, V., Shlens, J., and Le, Q. V. Learning transferable architectures for scalable image recognition. arXiv preprint arXiv:1707.07012 , 2017.
Appendix A Analysis of V-trace
附录 A V-trace 分析
A.1 V-trace operator
A.1 V-trace 算子
Define the V-trace operator :
定义 V-trace 算子 :
where the expectation is with respect to the policy which has generated the trajectory , i.e., , , . Here we consider the infinite-horizon operator but very similar results hold for the -step truncated operator.
其中期望 相对生成轨迹 的策略 取值,即 ,,。这里考虑无限时域算子,但对 步截断算子有非常类似的结果。
Theorem 1.
Let and be truncated importance sampling weights, with . Assume that there exists such that . Then the operator defined by (5) has a unique fixed point , which is the value function of the policy defined by
定理 1。
令 、 为截断重要性采样权重,且 。假设存在 使 。则由 (5) 定义的算子 有唯一不动点 ,即由下式定义的策略 的价值函数
Furthermore, is a -contraction mapping in sup-norm, with
此外, 在上确界范数下是 -压缩映射,其中
Remark 3.
The truncation levels and play different roles in this operator:
注 3。
截断水平 与 在该算子中扮演不同角色:
- • impacts the fixed-point of the operator, thus the policywhich is evaluated. For(untruncated) we get the value function of the target policy, whereas for finite, we evaluate a policy which is in betweenand(and whenis close to, then we evaluate). So the largerthe smaller the bias in off-policy learning. The variance naturally grows with. However notice that we do not take the product of thosecoefficients (in contrast to thecoefficients) so the variance does not explode with the time horizon.
- • impacts the contraction modulusof(thus the speed at which an online-algorithm like V-trace will converge to its fixed point). In terms of variance reduction, here is it really important to truncate the importance sampling ratios inbecause we take the product of those. Fortunately, our result says that for any level of truncation, the fixed point (the value functionwe converge to) is the same: it does not depend onbut ononly.
- • 影响算子的不动点,亦即被评估的策略。对(不截断)我们得到目标策略价值;对有限,则评估介于与之间的策略(当接近时评估)。因此越大,离策略学习偏差越小;方差自然随增大。但注意我们并不把这些系数相乘(与不同),故方差不会随时域爆炸。
- • 影响的压缩模量(从而影响像 V-trace 这样的在线算法收敛到不动点的速度)。就方差削减而言,截断中的重要性采样比尤为重要,因为我们要对它们取乘积。幸运的是,结果表明:对任意截断水平,不动点(收敛到的价值)相同——它不依赖,只依赖。
Proof.
First notice that we can rewrite as
证明。
首先注意到可以把 改写为
Thus
因此
with the notation that and for and . Now the coefficients are non-negative in expectation. Indeed, since , we have E_μαt = E[ ρt-1 - c_t-1 ρt] ≥Eμ[ c_t-1( 1- ρt)] ≥0, since $\mathbb{E}{\mu}\rho{t}\leq\mathbb{E}{\mu}\big[\frac{\pi(a_{t}|x_{t})}{\mu(a_{t}|x_{t})}\big]=1V_{1}(x)-V_{2}(x)V_{1}-V_{2}$ at other states, weighted by non-negative coefficients whose sum is
并约定 ,且对 与 有 。现在系数 在期望下非负。的确,由于 ,有 ,因为 。于是 是其他状态上 取值的线性组合,权重非负,其和为
We deduce that , with , so is a contraction mapping. Thus possesses a unique fixed point. Let us now prove that this fixed point is . We have:
由此得到 ,其中 ,故 是压缩映射,因而有唯一不动点。下面证明该不动点是 。我们有:
since this is the Bellman equation for . We deduce that , thus is the unique fixed point of . ∎
因为这正是 的 Bellman 方程。于是 ,故 是 的唯一不动点。∎
A.2 Online learning
A.2 在线学习
Theorem 2.
Assume a tabular representation, i.e. the state and action spaces are finite. Consider a set of trajectories, with the trajectory generated by following : . For each state along this trajectory, update
定理 2。
假定表格表示,即状态与动作空间有限。考虑一组轨迹,第 条轨迹 由跟随 生成:。对该轨迹上每个状态 ,更新
with , , . Assume that (1) all states are visited infinitely often, and (2) the stepsizes obey the usual Robbins-Munro conditions: for each state , , . Then almost surely.
其中 ,,。假定 (1) 所有状态被无限次访问,(2) 步长满足通常的 Robbins-Munro 条件:对每个状态 ,,。则 几乎必然成立。
The proof is a straightforward application of the convergence result for stochastic approximation algorithms to the fixed point of a contraction operator, see e.g. (Dayan & Sejnowski, 1994; Bertsekas & Tsitsiklis, 1996; Kushner & Yin, 2003).
证明是随机逼近算法收敛到压缩算子不动点这一结果的直接应用,参见例如 (Dayan & Sejnowski, 1994; Bertsekas & Tsitsiklis, 1996; Kushner & Yin, 2003)。
A.3 On the choice of in policy gradient
A.3 策略梯度中 的选择
The policy gradient update rule (4) makes use of the coefficient as an estimate of built from the V-trace estimate at the next state . The reason why we use instead of as target for our Q-value is to make sure our estimate of the Q-value is as unbiased as possible, and the first requirement is that it is entirely unbiased in the case of perfect representation of the V-values. Indeed, assuming our value function is correctly estimated at all states, i.e. , then we have (whereas we do not have this property for ). Indeed,
策略梯度更新规则 (4) 使用系数 ,作为由下一状态 处 V-trace 估计 构造的 估计。之所以用 而非 作为 的目标,是为了尽量减少 Q 价值估计的偏差,首要要求是:在 V 价值被完美表示时,估计完全无偏。的确,若价值函数在所有状态估计正确,即 ,则 (对 则无此性质)。具体地,
whereas
而
which is different from when .
当 时,它不同于 。
Appendix B Reference Scores
附录 B 参考分数
Table B.1: DMLab-30 test scores.
表 B.1:DMLab-30 测试分数。
B.1 Final training scores on DMLab-30
B.1 DMLab-30 最终训练分数
Figure B.1: Human normalised scores across all DMLab-30 tasks.
图 B.1:全部 DMLab-30 任务上的人类归一化分数。
Appendix C Atari Scores
附录 C Atari 分数
Table C.1: Atari scores after 200M steps environment steps of training. Up to 30 no-ops at the beginning of each episode.
表 C.1:训练 2 亿环境步后的 Atari 分数。每回合开始最多 30 次空操作。
Appendix D Parameters
附录 D 参数
In this section, the specific parameter settings that are used throughout our experiments are given in detail.
本节详细给出实验中使用的具体参数设定。
Table D.1: The ranges used in sampling hyperparameters across all experiments that used a sweep and for the initial hyperparameters for PBT. Sweep size and population size are 24. Note, the loss is summed across the batch and time dimensions.
表 D.1:所有使用扫描的实验,以及 PBT 初始超参的采样范围。扫描规模与种群规模均为 24。注意,损失在批与时间维上求和。
Table D.2: Action set used in all tasks from the DeepMind Lab environment, including the DMLab-30 experiments.
表 D.2:DeepMind Lab 环境全部任务(含 DMLab-30 实验)所用的动作集。
D.1 Fixed Model Hyperparameters
D.1 固定模型超参数
In this section, we list all the hyperparameters that were kept fixed across all experiments in the paper which are mostly concerned with observations specifications and optimisation. We first show below the reward pre-processing function that is used across all experiments using DeepMind Lab, followed by all fixed numerical values.
本节列出全文实验中保持固定的超参数,多与观测规格和优化有关。先给出 DeepMind Lab 全部实验使用的奖励预处理函数,再列出所有固定数值。
Figure D.1: Optimistic Asymmetric Clipping -
图 D.1:乐观非对称裁剪 —
Table D.3: Fixed model hyperparameters across all DeepMind Lab experiments.
表 D.3:全部 DeepMind Lab 实验的固定模型超参数。
Appendix E V-trace Analysis
附录 E V-trace 分析
E.1 Controlled Updates
E.1 受控更新
Here we show how different algorithms (On-Policy, No-correction, -correction, V-trace) behave under varying levels of policy-lag between the actors and the learner.
这里展示不同算法(同策略、无校正、-校正、V-trace)在 actor 与 learner 之间不同程度策略滞后下的行为。
Figure E.1: As the policy-lag (the number of update steps the actor policy is behind learner policy) increases, learning with V-trace is more robust compared to -correction and pure on-policy learning.
图 E.1:随着策略滞后(actor 策略落后 learner 策略的更新步数)增大,相对 -校正与纯同策略学习,带 V-trace 的学习更鲁棒。
E.2 V-trace Stability Analysis
E.2 V-trace 稳定性分析
Figure E.2: Stability across hyper parameter combinations for different off-policy correction variants using replay. V-trace is much more stable across a wide range of parameter combinations compared to -correction and pure on-policy learning.
图 E.2:带回放时,不同离策略校正变体跨超参组合的稳定性。相对 -校正与纯同策略学习,V-trace 在宽范围参数组合上稳定得多。
E.3 Estimating the State Action Value for Policy Gradient
E.3 策略梯度的状态–动作价值估计
We investigated different ways of estimating the state action value function used to estimate advantages for the policy gradient calculation. The variant presented in the main section of the paper uses the V-trace corrected value function to estimate . Another possibility is to use the actor-critic baseline to estimate . Note that the latter variant does not use any information from the current policy rollout to estimate the policy gradient and relies on an accurate estimate of the value function. We found the latter variant to perform worse both when comparing the top 3 runs and an average over all runs of the hyperparameter sweep as can be see in figures E.3 and E.4.
我们考察了多种估计状态–动作价值函数的方式,用于策略梯度中的优势估计。正文采用的变体用 V-trace 校正后的价值 估计 。另一种可能是用 actor-critic 基线 估计 。注意后一变体估计策略梯度时完全不使用当前策略 rollout 的信息,而依赖价值函数的准确估计。我们发现后一变体无论看最佳 3 次运行还是超参扫描全部运行的平均,表现都更差,见图 E.3 与 E.4。
Figure E.3: Variants for estimation of state action value function - average over top 3 runs.
图 E.3:状态–动作价值函数估计变体——最佳 3 次运行平均。
Figure E.4: Variants for estimation of state action value function - average over all runs.
图 E.4:状态–动作价值函数估计变体——全部运行平均。
Appendix F Population Based Training
附录 F 基于种群的训练
For Population Based Training we used a “burn-in” period of 20 million frames where no evolution is done. This is to stabilise the process and to avoid very rapid initial adaptation which hinders diversity. After collecting 5,000 episode rewards in total, the mean capped human normalised score is calculated and a random instance in the population is selected. If the score of the selected instance is more than an absolute 5% higher, then the selected instance weights and parameters are copied.
对基于种群的训练,我们使用 2000 万帧的「预热」期不做演化,以稳定过程并避免过快的初始适应损害多样性。累计收集 5000 个回合奖励后,计算均值截断人类归一化分数,并随机选中种群中一个实例。若被选实例分数绝对高出超过 5%,则复制其权重与参数。
No matter if a copy happened or not, each parameter (RMSProp epsilon, learning rate and entropy cost) is permuted with 33% probability by multiplying with either or . This is different from (Jaderberg et al., 2017) in that our multiplication is unbiased where they use a multiplication of or . We found that diversity is increased when the parameters are permuted even if no copy happened.
无论是否发生复制,每个参数(RMSProp epsilon、学习率与熵代价)都以 33% 概率乘以 或 做扰动。这与 (Jaderberg et al., 2017) 不同:我们的乘法无偏,而他们用 或 。我们发现即使未发生复制也对参数扰动,多样性会增加。
We reconstruct the learning curves of the PBT runs in Figure 6 by backtracking through the ancestry of copied checkpoints for selected instances.
我们通过回溯所选实例的检查点复制谱系,重建图 6 中 PBT 运行的学习曲线。
Figure F.1: Learning rate schedule that is discovered by the PBT (Jaderberg et al., 2017) method compared against the linear annealing schedule of the best run from the parameter sweep (red line).
图 F.1:PBT (Jaderberg et al., 2017) 发现的学习率日程,对比参数扫描最佳运行的线性退火日程(红线)。
Appendix G Atari Experiments
附录 G Atari 实验
All agents trained on Atari are equipped only with a feed forward network and pre-process frames in the same way as described in (Mnih et al., 2016). When training experts agents, we use the same hyperparameters for each game for both IMPALA and A3C. These hyperparameters are the result of tuning A3C with a shallow network on the following games: breakout, pong, space_invaders, seaquest, beam_rider, qbert. Following related work, experts use game-specific action sets.
所有在 Atari 上训练的智能体仅配备前馈网络,并按 (Mnih et al., 2016) 所述方式预处理帧。训练专家智能体时,IMPALA 与 A3C 对每款游戏使用相同超参。这些超参来自在下列游戏上用浅层网络调 A3C:breakout、pong、space_invaders、seaquest、beam_rider、qbert。沿用相关工作,专家使用游戏特定动作集。
The multi-task agent was equipped with a feed forward residual network (see Figure 3 ). The learning rate, entropy regularisation, RMSProp and gradient clipping threshold were adapted through population based training. To be able to use the same policy layer on all Atari games in the multi-task setting we train the multi-task agent on the full Atari action set consisting of 18 actions.
多任务智能体配备前馈残差网络(见图 3)。学习率、熵正则、RMSProp 与梯度裁剪阈值通过基于种群的训练调节。为在多任务设定下对全部 Atari 游戏使用同一策略层,我们在包含 18 个动作的完整 Atari 动作集上训练多任务智能体。
Agents were trained using the following set of hyperparameters:
智能体使用以下超参数训练:
| Parameter | Value |
|---|---|
| Image Width | 84 |
| Image Height | 84 |
| Grayscaling | Yes |
| Action Repetitions | 4 |
| Max-pool over last N action repeat frames | 2 |
| Frame Stacking | 4 |
| End of episode when life lost | Yes |
| Reward Clipping | [-1, 1] |
| Unroll Length () | 20 |
| Batch size | 32 |
| Discount () | 0.99 |
| Baseline loss scaling | 0.5 |
| Entropy Regularizer | 0.01 |
| RMSProp momentum | 0.0 |
| RMSProp | 0.01 |
| Learning rate | 0.0006 |
| Clip global gradient norm | 40.0 |
| Learning rate schedule | Anneal linearly to 0 |
| From beginning to end of training. | |
| Population based training (only multi-task agent) | |
| - Population size | 24 |
| - Start parameters | Same as DMLab-30 sweep |
| - Fitness | Mean capped human normalised scores |
| - Adapted parameters | Gradient clipping threshold |
| Entropy regularisation | |
| Learning rate | |
| RMSProp |
Table G.1: Hyperparameters for Atari experiments.
| Parameter | Value |
|---|---|
| Image Width | 84 |
| Image Height | 84 |
| Grayscaling | Yes |
| Action Repetitions | 4 |
| Max-pool over last N action repeat frames | 2 |
| Frame Stacking | 4 |
| End of episode when life lost | Yes |
| Reward Clipping | [-1, 1] |
| Unroll Length () | 20 |
| Batch size | 32 |
| Discount () | 0.99 |
| Baseline loss scaling | 0.5 |
| Entropy Regularizer | 0.01 |
| RMSProp momentum | 0.0 |
| RMSProp | 0.01 |
| Learning rate | 0.0006 |
| Clip global gradient norm | 40.0 |
| Learning rate schedule | Anneal linearly to 0 |
| From beginning to end of training. | |
| Population based training (only multi-task agent) | |
| - Population size | 24 |
| - Start parameters | Same as DMLab-30 sweep |
| - Fitness | Mean capped human normalised scores |
| - Adapted parameters | Gradient clipping threshold |
| Entropy regularisation | |
| Learning rate | |
| RMSProp |
表 G.1:Atari 实验超参数。
References
参考文献
Bertsekas & Tsitsiklis (1996) Bertsekas, D. P. and Tsitsiklis, J. N. Neuro-Dynamic Programming . Athena Scientific, 1996.
Dayan & Sejnowski (1994) Dayan, P. and Sejnowski, T. J. TD( λ \lambda ) converges with probability 1. Machine Learning , 14(1):295–301, 1994. doi: 10.1023/A:1022657612745 .
Jaderberg et al. (2017) Jaderberg, M., Dalibard, V., Osindero, S., Czarnecki, W. M., Donahue, J., Razavi, A., Vinyals, O., Green, T., Dunning, I., Simonyan, K., Fernando, C., and Kavukcuoglu, K. Population based training of neural networks. CoRR , abs/1711.09846, 2017.
Kushner & Yin (2003) Kushner, H. and Yin, G. Stochastic Approximation and Recursive Algorithms and Applications . Stochastic Modelling and Applied Probability. Springer New York, 2003. ISBN 9780387008943.
Mnih et al. (2016) Mnih, V., Badia, A. P., Mirza, M., Graves, A., Lillicrap, T. P., Harley, T., Silver, D., and Kavukcuoglu, K. Asynchronous methods for deep reinforcement learning. ICML , 2016.