Identity Mappings in Deep Residual Networks
Identity Mappings in Deep Residual Networks
深度残差网络中的恒等映射
Kaiming He Xiangyu Zhang Shaoqing Ren Jian Sun Affiliation: Microsoft Research
Abstract
摘要
Deep residual networks [1] have emerged as a family of extremely deep architectures showing compelling accuracy and nice convergence behaviors. In this paper, we analyze the propagation formulations behind the residual building blocks, which suggest that the forward and backward signals can be directly propagated from one block to any other block, when using identity mappings as the skip connections and after-addition activation. A series of ablation experiments support the importance of these identity mappings. This motivates us to propose a new residual unit, which makes training easier and improves generalization. We report improved results using a 1001-layer ResNet on CIFAR-10 (4.62% error) and CIFAR-100, and a 200-layer ResNet on ImageNet. Code is available at: https://github.com/KaimingHe/resnet-1k-layers.
深度残差网络[1]已成为一类极深的结构,既有很强的精度,收敛表现也好。本文分析残差构建模块背后的传播公式,结果表明:当捷径连接和加法后的激活都取恒等映射时,前向和反向信号都可以从一个模块直接传播到任意其他模块。一系列消融实验支持这些恒等映射的重要性。由此我们提出一种新的残差单元,使训练更容易,也改善了泛化。我们报告了 1001 层 ResNet 在 CIFAR-10(误差 4.62%)和 CIFAR-100 上的更好结果,以及 200 层 ResNet 在 ImageNet 上的更好结果。代码见:https://github.com/KaimingHe/resnet-1k-layers。
1 Introduction
1 引言
Deep residual networks (ResNets) [1] consist of many stacked “Residual Units”. Each unit (Fig. 1 (a)) can be expressed in a general form:
深度残差网络(ResNets)[1]由许多堆叠的“残差单元”组成。每个单元(图 1(a))可以写成一般形式:
where and are input and output of the -th unit, and is a residual function. In [1], is an identity mapping and is a ReLU [2] function.
其中 和 是第 个单元的输入和输出, 是残差函数。在[1]中, 是恒等映射, 是 ReLU[2]函数。
ResNets that are over 100-layer deep have shown state-of-the-art accuracy for several challenging recognition tasks on ImageNet [3] and MS COCO [4] competitions. The central idea of ResNets is to learn the additive residual function with respect to , with a key choice of using an identity mapping . This is realized by attaching an identity skip connection (“shortcut”).
深度超过 100 层的 ResNet,已在 ImageNet[3] 和 MS COCO[4] 竞赛的多项困难识别任务上达到当时最好的精度。ResNet 的核心想法,是相对于 去学习可加的残差函数 ,关键选择是采用恒等映射 。这通过接上一条恒等捷径连接(shortcut)来实现。
In this paper, we analyze deep residual networks by focusing on creating a “direct” path for propagating information — not only within a residual unit, but through the entire network. Our derivations reveal that if both and are identity mappings, the signal could be directly propagated from one unit to any other units, in both forward and backward passes. Our experiments empirically show that training in general becomes easier when the architecture is closer to the above two conditions.
本文分析深度残差网络,重点是开辟一条“直接”的信息传播路径——不仅在一个残差单元内部,而且贯穿整个网络。推导表明,如果 和 都是恒等映射,信号就可以在前向和反向过程中,从一个单元直接传播到任意其他单元。实验也表明,当结构更接近上述两个条件时,训练通常会更容易。
To understand the role of skip connections, we analyze and compare various types of . We find that the identity mapping chosen in [1] achieves the fastest error reduction and lowest training loss among all variants we investigated, whereas skip connections of scaling, gating [5, 6, 7], and 11 convolutions all lead to higher training loss and error. These experiments suggest that keeping a “clean” information path (indicated by the grey arrows in Fig. 1, 2, and 4) is helpful for easing optimization.
为了理解捷径连接的作用,我们分析并比较了各种形式的 。我们发现,[1]中选用的恒等映射 ,在我们考察的所有变体里误差下降最快、训练损失也最低;而缩放、门控[5, 6, 7]以及 卷积形式的捷径,都会带来更高的训练损失和误差。这些实验表明,保持一条“干净”的信息通路(如图 1、2 和 4 中灰色箭头所示)有助于减轻优化困难。
To construct an identity mapping , we view the activation functions (ReLU and BN [8]) as “pre-activation” of the weight layers, in contrast to conventional wisdom of “post-activation”. This point of view leads to a new residual unit design, shown in (Fig. 1(b)). Based on this unit, we present competitive results on CIFAR-10/100 with a 1001-layer ResNet, which is much easier to train and generalizes better than the original ResNet in [1]. We further report improved results on ImageNet using a 200-layer ResNet, for which the counterpart of [1] starts to overfit. These results suggest that there is much room to exploit the dimension of network depth, a key to the success of modern deep learning.
为了构造恒等映射 ,我们把激活函数(ReLU 和 BN[8])看成权重层的“预激活”,而不是通常所想的“后激活”。这一看法带来了一种新的残差单元设计,见图 1(b)。基于该单元,我们用 1001 层 ResNet 在 CIFAR-10/100 上给出了有竞争力的结果;它比[1]中原来的 ResNet 更容易训练,泛化也更好。我们还用 200 层 ResNet 在 ImageNet 上得到了更好的结果,而[1]中的对应模型已经开始过拟合。这些结果说明,网络深度这一维度还有很大空间可以挖掘,而深度正是现代深度学习成功的关键之一。
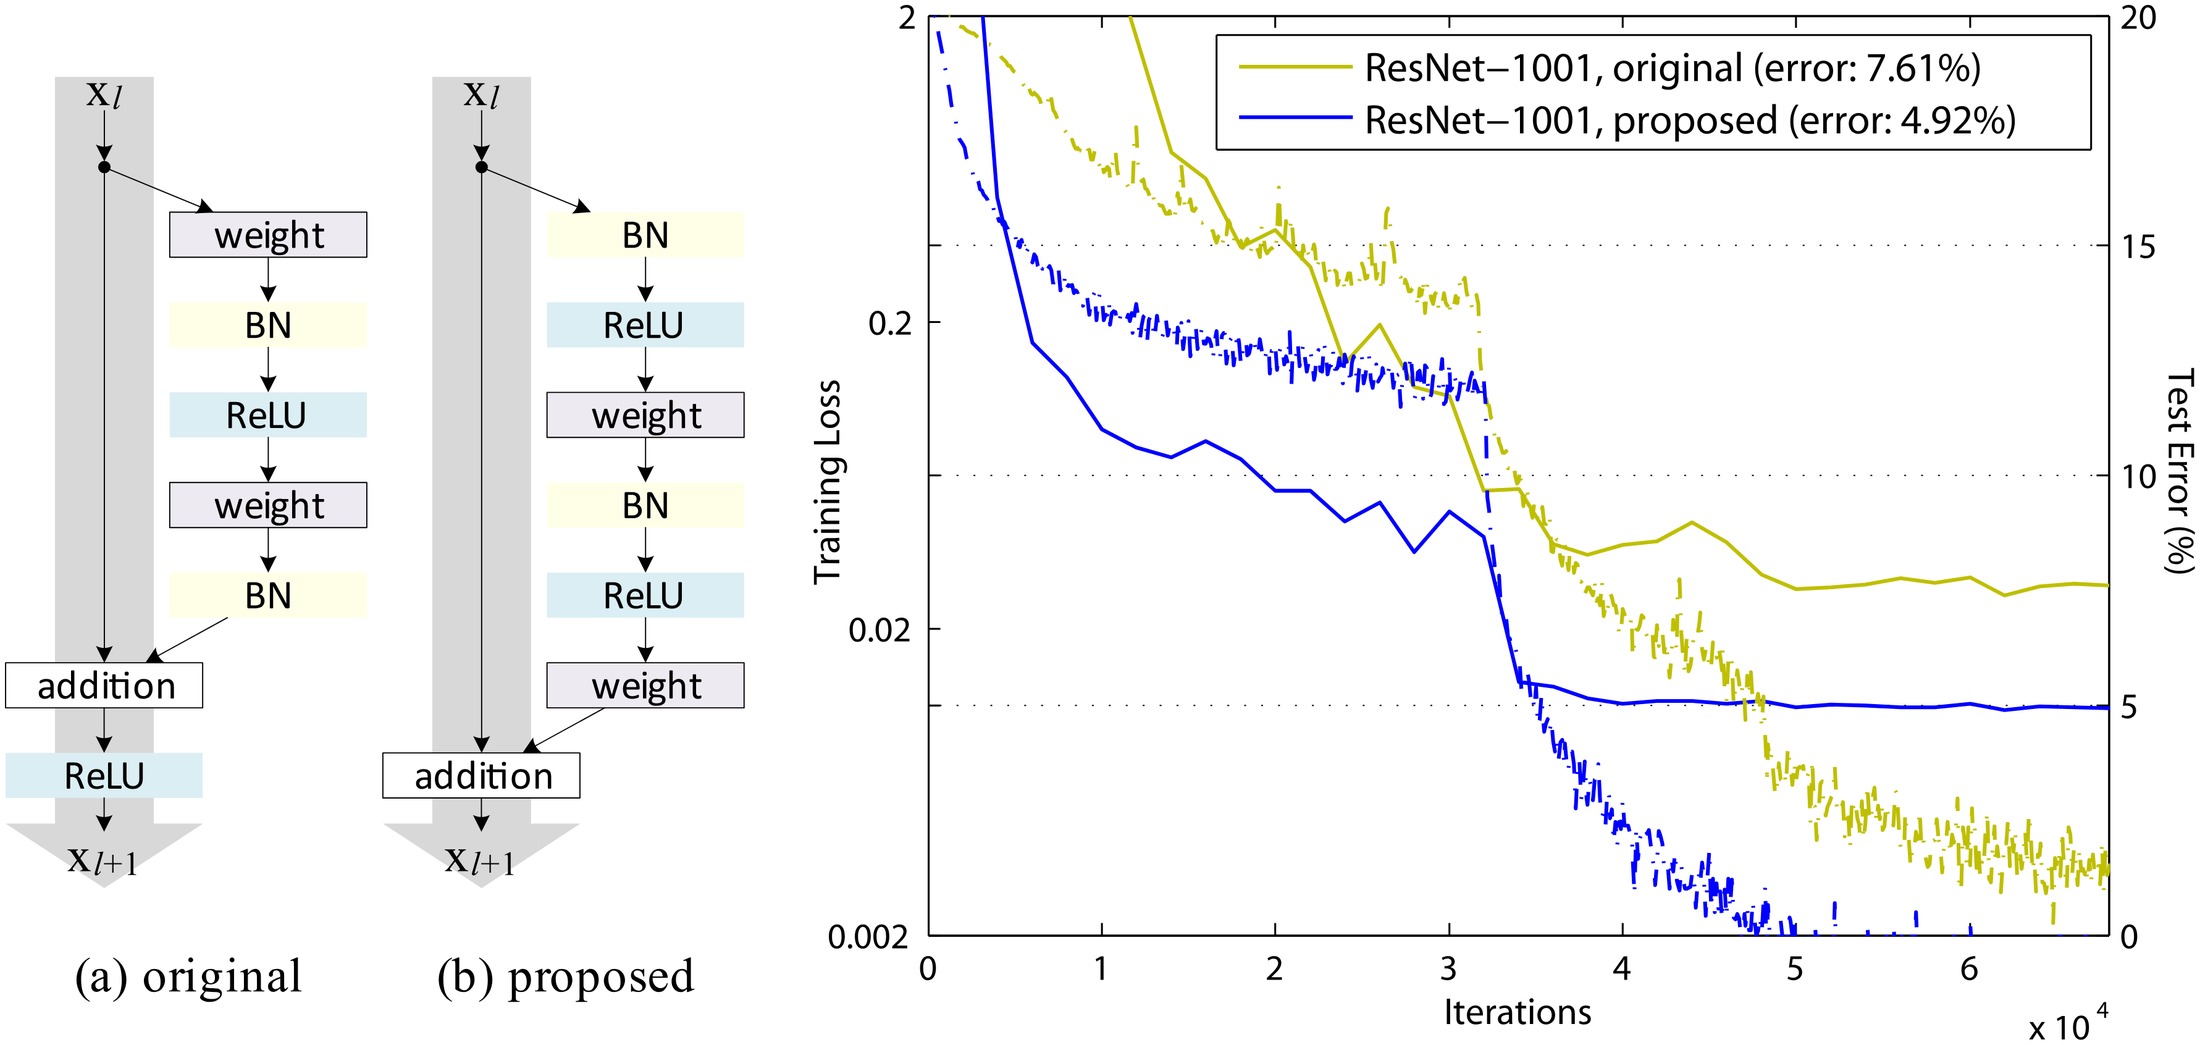
Figure 1: Left: (a) original Residual Unit in [1]; (b) proposed Residual Unit. The grey arrows indicate the easiest paths for the information to propagate, corresponding to the additive term “” in Eqn.(4) (forward propagation) and the additive term “1” in Eqn.(5) (backward propagation). Right: training curves on CIFAR-10 of 1001-layer ResNets. Solid lines denote test error (y-axis on the right), and dashed lines denote training loss (y-axis on the left). The proposed unit makes ResNet-1001 easier to train.
图 1:左:(a) [1]中原来的残差单元;(b) 本文提出的残差单元。灰色箭头标出信息最容易传播的路径,分别对应式(4)中的加性项“”(前向传播)和式(5)中的加性项“1”(反向传播)。右:1001 层 ResNet 在 CIFAR-10 上的训练曲线。实线是测试误差(右纵轴),虚线是训练损失(左纵轴)。提出的单元使 ResNet-1001 更容易训练。
2 Analysis of Deep Residual Networks
2 深度残差网络的分析
The ResNets developed in [1] are modularized architectures that stack building blocks of the same connecting shape. In this paper we call these blocks “Residual Units”. The original Residual Unit in [1] performs the following computation:
[1]中提出的 ResNet 是模块化结构,由连接形状相同的构建块堆叠而成。本文称这些块为“残差单元”。[1]中原来的残差单元进行如下计算:
Here is the input feature to the -th Residual Unit. is a set of weights (and biases) associated with the -th Residual Unit, and is the number of layers in a Residual Unit ( is 2 or 3 in [1]). denotes the residual function, e.g., a stack of two 33 convolutional layers in [1]. The function is the operation after element-wise addition, and in [1] is ReLU. The function is set as an identity mapping: .[^1]
这里 是第 个残差单元的输入特征。 是与第 个残差单元相关的一组权重(以及偏置), 是一个残差单元中的层数(在[1]中 为 2 或 3)。 表示残差函数,例如[1]中两层 卷积的堆叠。函数 是逐元素加法之后的运算,在[1]中 是 ReLU。函数 取为恒等映射:。[^1]
If is also an identity mapping: , we can put Eqn.(2) into Eqn.(1) and obtain:
如果 也是恒等映射:,把式(2)代入式(1)可得:
Recursively (, etc.) we will have:
递归地写下去(,依此类推)就有:
for any deeper unit and any shallower unit . Eqn.(4) exhibits some nice properties. (i) The feature of any deeper unit can be represented as the feature of any shallower unit plus a residual function in a form of , indicating that the model is in a residual fashion between any units and . (ii) The feature , of any deep unit , is the summation of the outputs of all preceding residual functions (plus ). This is in contrast to a “plain network” where a feature is a series of matrix-vector products, say, (ignoring BN and ReLU).
这对任意较深的单元 和任意较浅的单元 都成立。式(4)有一些很好的性质。(i) 任意较深单元 的特征 ,都可以写成任意较浅单元 的特征 加上形式为 的残差函数,说明模型在任意两个单元 和 之间都呈残差形式。(ii) 任意深层单元 的特征 ,是此前所有残差函数输出的求和(再加上 )。这与“普通网络”不同:在普通网络里,特征 是一连串矩阵–向量乘积,例如 (忽略 BN 和 ReLU)。
Eqn.(4) also leads to nice backward propagation properties. Denoting the loss function as , from the chain rule of backpropagation [9] we have:
式(4)也带来很好的反向传播性质。把损失函数记为 ,由反向传播的链式法则[9]得到:
Eqn.(5) indicates that the gradient can be decomposed into two additive terms: a term of that propagates information directly without concerning any weight layers, and another term of that propagates through the weight layers. The additive term of ensures that information is directly propagated back to any shallower unit . Eqn.(5) also suggests that it is unlikely for the gradient to be canceled out for a mini-batch, because in general the term cannot be always -1 for all samples in a mini-batch. This implies that the gradient of a layer does not vanish even when the weights are arbitrarily small.
式(5)表明,梯度 可以分解为两个加性项:一项是 ,它不经过任何权重层,直接传播信息;另一项是 ,它经过权重层传播。加性项 保证信息被直接传回任意较浅的单元 。式(5)还表明,对一个 mini-batch 而言,梯度 不太可能被抵消掉,因为一般说来, 不可能对 mini-batch 中的所有样本都恰好等于 。这意味着,即使权重任意小,某一层的梯度也不会消失。
Discussions
讨论
Eqn.(4) and Eqn.(5) suggest that the signal can be directly propagated from any unit to another, both forward and backward. The foundation of Eqn.(4) is two identity mappings: (i) the identity skip connection , and (ii) the condition that is an identity mapping.
式(4)和式(5)表明,信号可以在任意两个单元之间直接传播,前向和反向都是如此。式(4)的基础是两个恒等映射:(i) 恒等捷径连接 ,以及 (ii) 为恒等映射这一条件。
These directly propagated information flows are represented by the grey arrows in Fig. 1, 2, and 4. And the above two conditions are true when these grey arrows cover no operations (expect addition) and thus are “clean”. In the following two sections we separately investigate the impacts of the two conditions.
这些直接传播的信息流,由图 1、2 和 4 中的灰色箭头表示。当这些灰色箭头上没有运算(加法除外),因而是“干净”的时候,上述两个条件成立。下面两节我们分别考察这两个条件的影响。
3 On the Importance of Identity Skip Connections
3 恒等捷径连接的重要性
Let’s consider a simple modification, , to break the identity shortcut:
我们考虑一个简单的改动 ,以打破恒等捷径:
where is a modulating scalar (for simplicity we still assume is identity). Recursively applying this formulation we obtain an equation similar to Eqn. (4): , or simply:
其中 是一个调制标量(为简单起见,我们仍假定 是恒等映射)。递归套用这一公式,会得到与式(4)类似的方程:,或者简写成:
where the notation absorbs the scalars into the residual functions. Similar to Eqn.(5), we have backpropagation of the following form:
其中记号 把这些标量吸收进了残差函数。与式(5)类似,反向传播取如下形式:
Unlike Eqn.(5), in Eqn.(8) the first additive term is modulated by a factor . For an extremely deep network ( is large), if for all , this factor can be exponentially large; if for all , this factor can be exponentially small and vanish, which blocks the backpropagated signal from the shortcut and forces it to flow through the weight layers. This results in optimization difficulties as we show by experiments.
与式(5)不同,式(8)中的第一个加性项被因子 调制。对极深的网络( 很大),若所有 都有 ,这个因子会指数级变大;若所有 都有 ,这个因子会指数级变小以至消失,从而阻断来自捷径的反向信号,迫使它流过权重层。如下面实验所示,这会带来优化困难。
In the above analysis, the original identity skip connection in Eqn.(3) is replaced with a simple scaling . If the skip connection represents more complicated transforms (such as gating and 11 convolutions), in Eqn.(8) the first term becomes where is the derivative of . This product may also impede information propagation and hamper the training procedure as witnessed in the following experiments.
在上面的分析里,式(3)中原来的恒等捷径被简单的缩放 取代。如果捷径连接 表示更复杂的变换(例如门控和 卷积),式(8)中的第一项就变成 ,其中 是 的导数。这个乘积同样可能阻碍信息传播、妨碍训练,如下面实验所见。
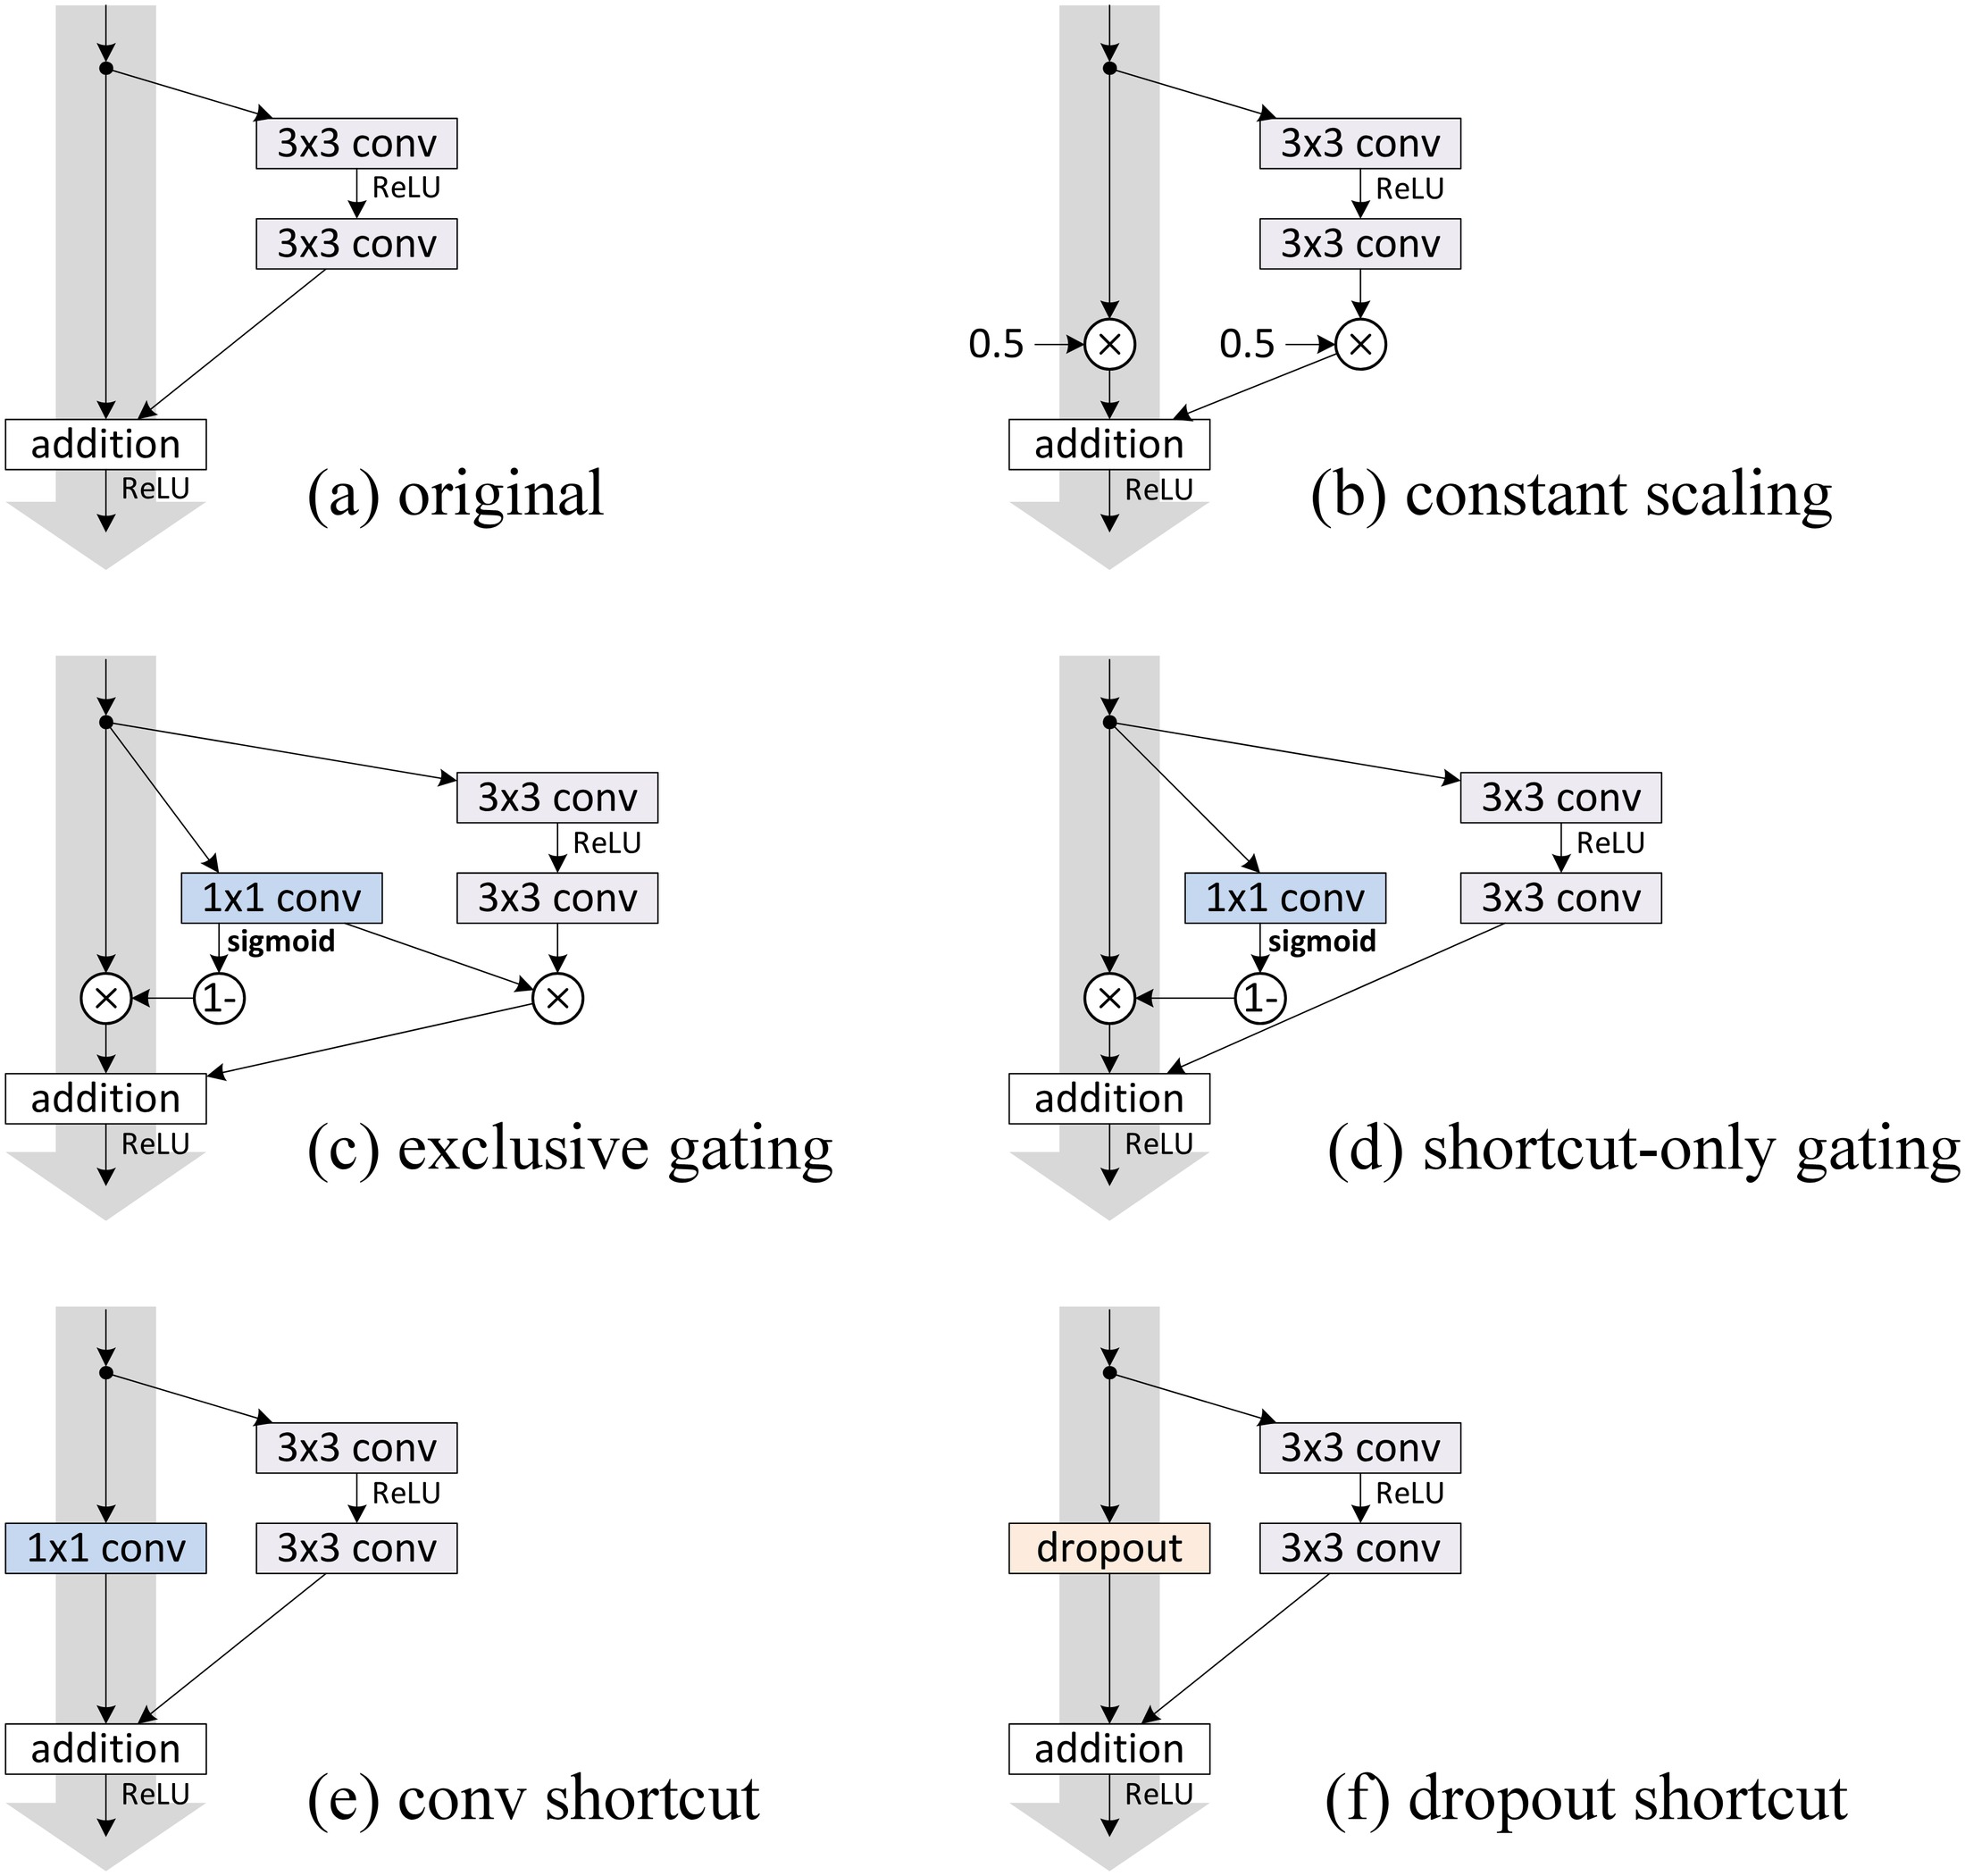
Figure 2: Various types of shortcut connections used in Table 1. The grey arrows indicate the easiest paths for the information to propagate. The shortcut connections in (b-f) are impeded by different components. For simplifying illustrations we do not display the BN layers, which are adopted right after the weight layers for all units here.
图 2:表 1 中用到的各类捷径连接。灰色箭头标出信息最容易传播的路径。(b–f) 中的捷径被不同的组件挡住。为简化图示,这里没有画出 BN 层;对本节所有单元,BN 都接在权重层之后。
| case | Fig. | on shortcut | on | error (%) | remark |
|---|---|---|---|---|---|
| original [1] | Fig. 2(a) | 1 | 1 | 6.61 | |
| constant scaling | Fig. 2(b) | 0 | 1 | fail | This is a plain net |
| 0.5 | 1 | fail | |||
| 0.5 | 0.5 | 12.35 | frozen gating | ||
| exclusive gating | Fig. 2(c) | fail | init =0 to | ||
| 8.70 | init =-6 | ||||
| 9.81 | init =-7 | ||||
| shortcut-only gating | Fig. 2(d) | 1 | 12.86 | init =0 | |
| 1 | 6.91 | init =-6 | |||
| 11 conv shortcut | Fig. 2(e) | 11 conv | 1 | 12.22 | |
| dropout shortcut | Fig. 2(f) | dropout 0.5 | 1 | fail |
Table 1: Classification error on the CIFAR-10 test set using ResNet-110 [1], with different types of shortcut connections applied to all Residual Units. We report “fail” when the test error is higher than 20%.
| 情形 | 图 | 作用于捷径 | 作用于 | 误差 (%) | 说明 |
|---|---|---|---|---|---|
| 原来的做法 [1] | 图 2(a) | 1 | 1 | 6.61 | |
| 常数缩放 | 图 2(b) | 0 | 1 | 失败 | 这是普通网络 |
| 0.5 | 1 | 失败 | |||
| 0.5 | 0.5 | 12.35 | 冻结的门控 | ||
| 互斥门控 | 图 2(c) | 失败 | 初始化 =0 到 | ||
| 8.70 | 初始化 =-6 | ||||
| 9.81 | 初始化 =-7 | ||||
| 仅捷径门控 | 图 2(d) | 1 | 12.86 | 初始化 =0 | |
| 1 | 6.91 | 初始化 =-6 | |||
| 卷积捷径 | 图 2(e) | 卷积 | 1 | 12.22 | |
| dropout 捷径 | 图 2(f) | dropout 0.5 | 1 | 失败 |
表 1:在 CIFAR-10 测试集上,用 ResNet-110[1] 并把不同类型的捷径连接加到所有残差单元时的分类误差。测试误差高于 20% 时记为“失败”。
3.1 Experiments on Skip Connections
3.1 关于捷径连接的实验
We experiment with the 110-layer ResNet as presented in [1] on CIFAR-10 [10]. This extremely deep ResNet-110 has 54 two-layer Residual Units (consisting of 33 convolutional layers) and is challenging for optimization. Our implementation details (see appendix) are the same as [1]. Throughout this paper we report the median accuracy of 5 runs for each architecture on CIFAR, reducing the impacts of random variations.
我们在 CIFAR-10[10] 上,用[1]中给出的 110 层 ResNet 做实验。这个极深的 ResNet-110 有 54 个两层残差单元(由 卷积层组成),对优化很有挑战。实现细节(见附录)与[1]相同。本文在 CIFAR 上报告每种结构 5 次运行 的中位数精度,以减小随机波动的影响。
Though our above analysis is driven by identity , the experiments in this section are all based on ReLU as in [1]; we address identity in the next section. Our baseline ResNet-110 has 6.61% error on the test set. The comparisons of other variants (Fig. 2 and Table 1) are summarized as follows:
尽管上面的分析是在恒等的 下展开的,本节实验全部基于与[1]一样的 ReLU;恒等的 放到下一节再讨论。作为基线的 ResNet-110 在测试集上误差为 6.61%。其他变体(图 2 和表 1)的对比总结如下:
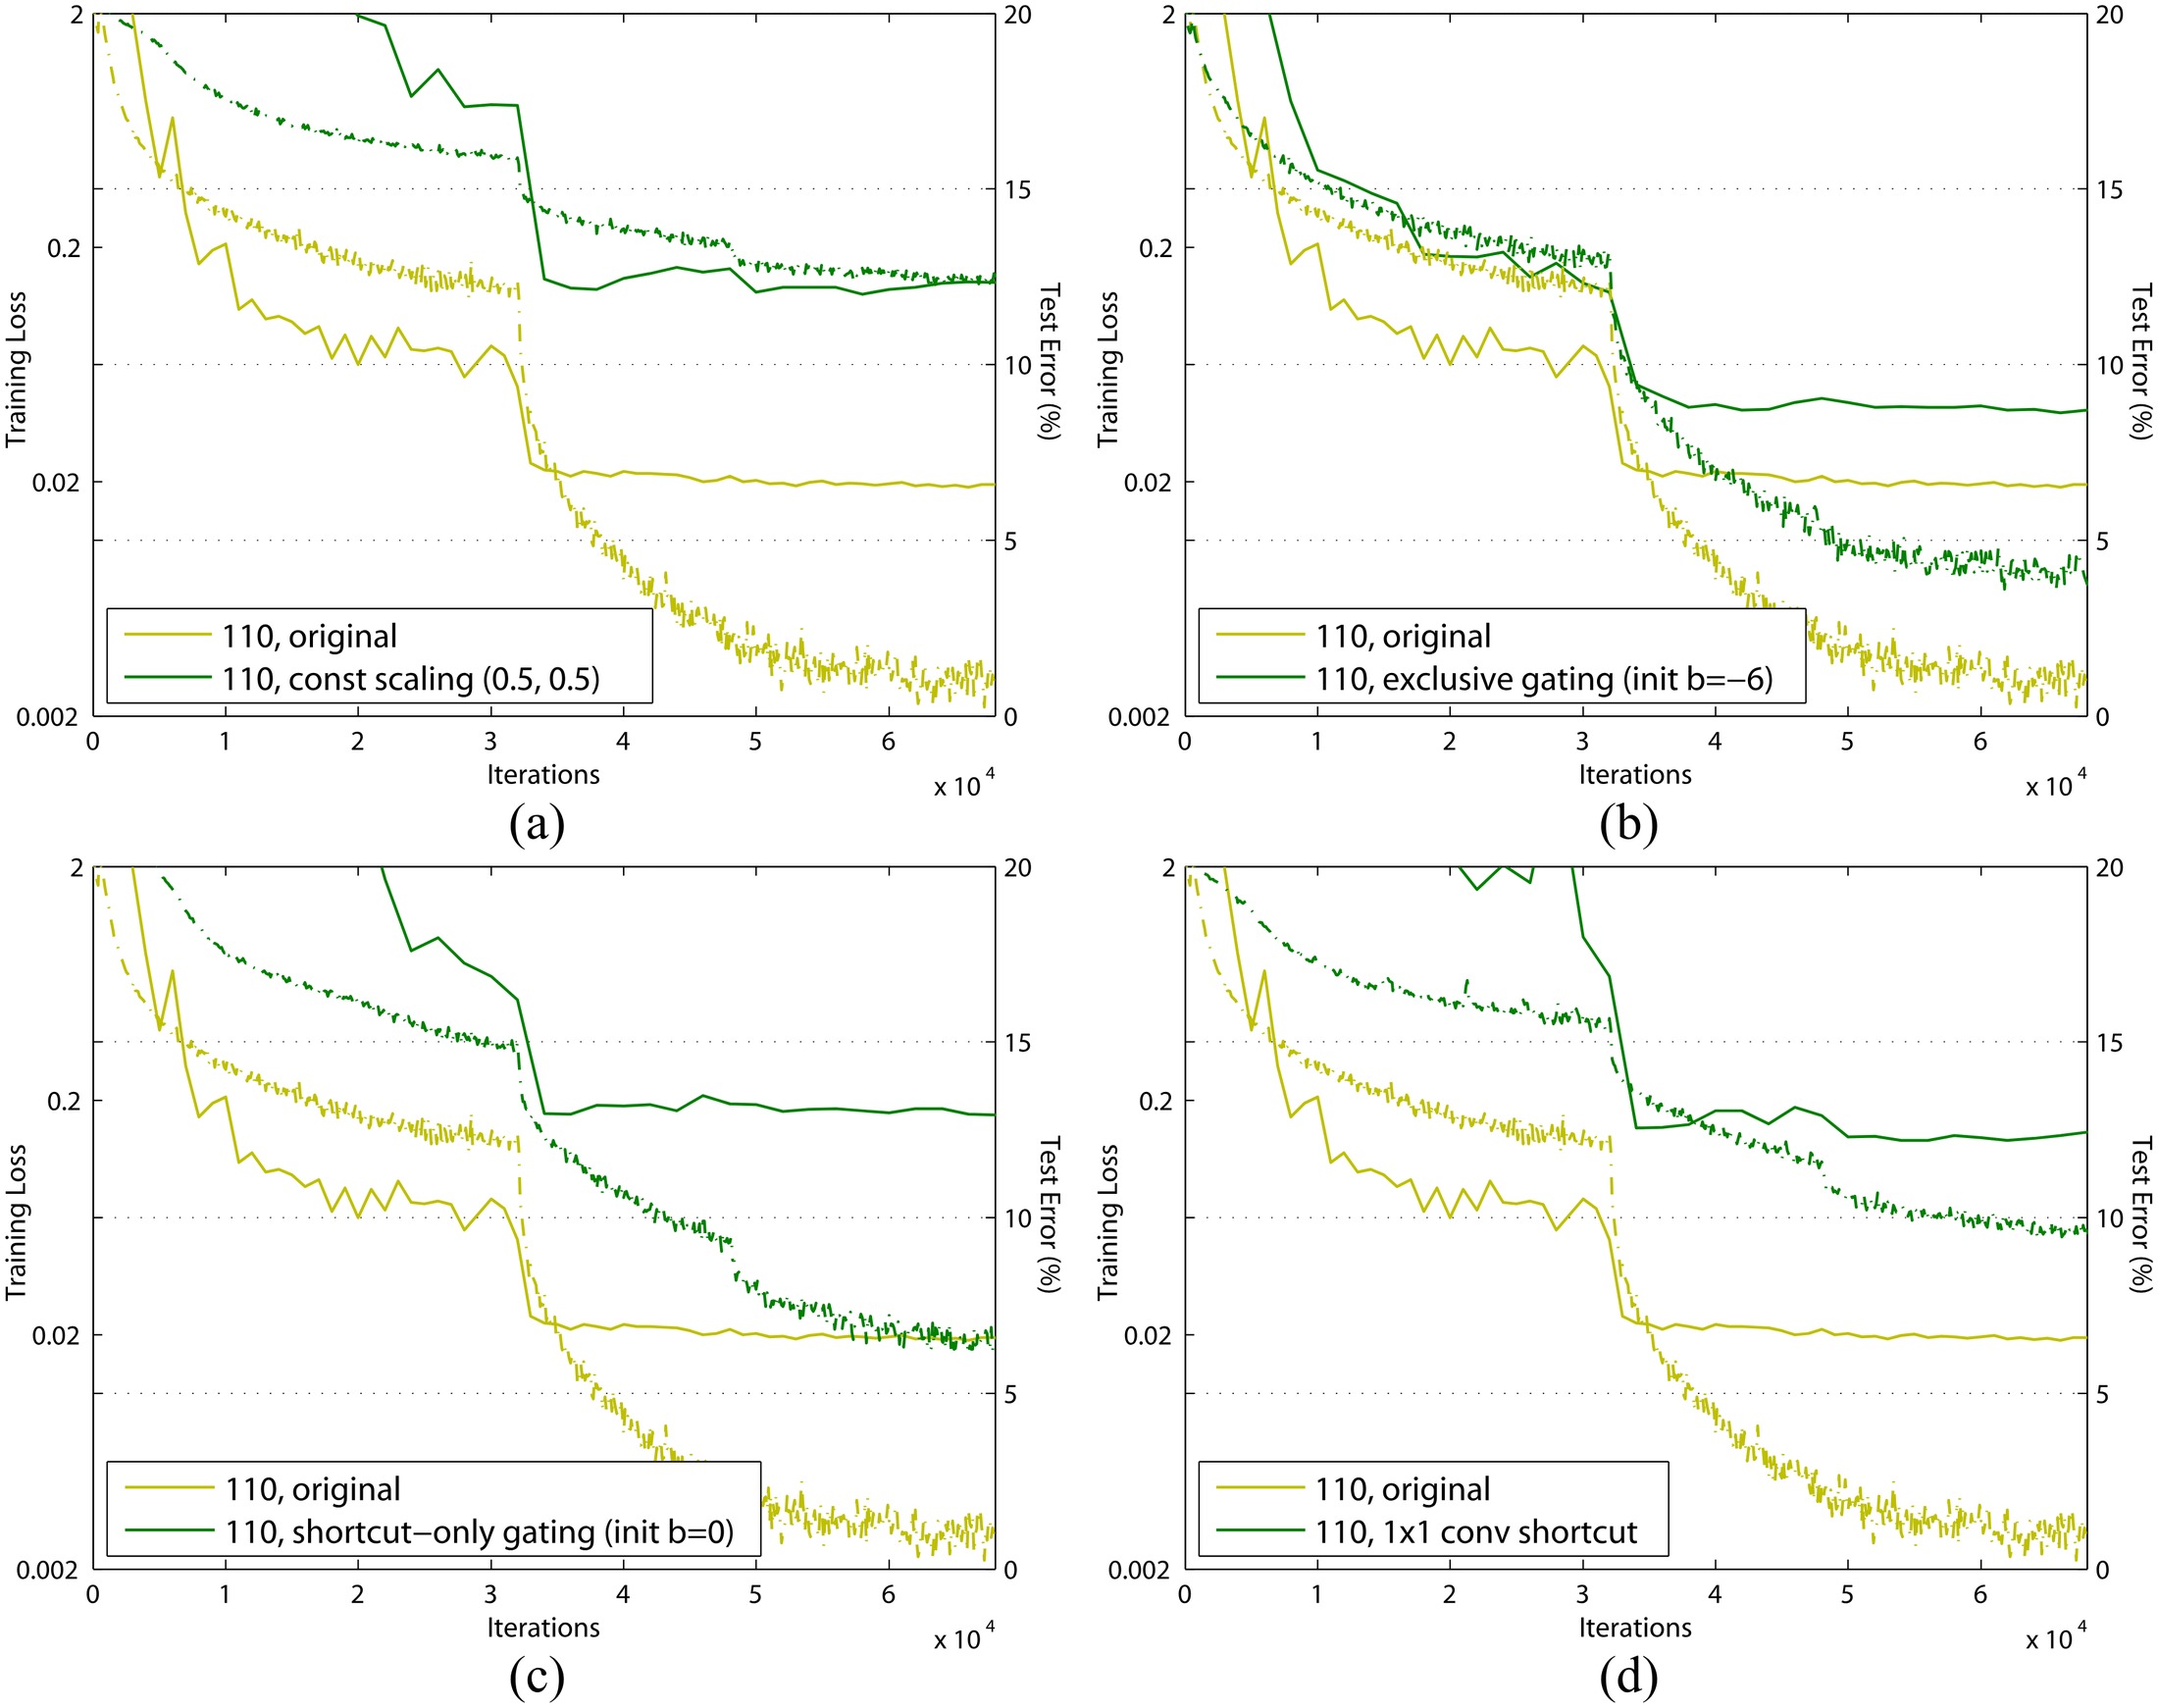
Figure 3: Training curves on CIFAR-10 of various shortcuts. Solid lines denote test error (y-axis on the right), and dashed lines denote training loss (y-axis on the left).
图 3:各类捷径在 CIFAR-10 上的训练曲线。实线是测试误差(右纵轴),虚线是训练损失(左纵轴)。
Constant scaling. We set for all shortcuts (Fig. 2(b)). We further study two cases of scaling : (i) is not scaled; or (ii) is scaled by a constant scalar of , which is similar to the highway gating [6, 7] but with frozen gates. The former case does not converge well; the latter is able to converge, but the test error (Table 1, 12.35%) is substantially higher than the original ResNet-110. Fig 3(a) shows that the training error is higher than that of the original ResNet-110, suggesting that the optimization has difficulties when the shortcut signal is scaled down.
常数缩放。我们把所有捷径的 设为 0.5(图 2(b))。进一步考察两种缩放 的情形:(i) 不缩放 ;或 (ii) 用常数 缩放 ,这类似于 Highway 的门控[6, 7],但门是冻结的。前一种情形收敛不好;后一种能够收敛,但测试误差(表 1,12.35%)明显高于原来的 ResNet-110。图 3(a) 显示训练误差也高于原来的 ResNet-110,说明捷径信号被缩小后,优化会出现困难。
Exclusive gating. Following the Highway Networks [6, 7] that adopt a gating mechanism [5], we consider a gating function where a transform is represented by weights and biases followed by the sigmoid function . In a convolutional network is realized by a 11 convolutional layer. The gating function modulates the signal by element-wise multiplication.
互斥门控。沿用采用门控机制[5]的 Highway 网络[6, 7],我们考虑门控函数 ,其中变换由权重 和偏置 表示,再接 sigmoid 函数 。在卷积网络里, 由一层 卷积实现。门控函数通过逐元素乘法调制信号。
We investigate the “exclusive” gates as used in [6, 7] — the path is scaled by and the shortcut path is scaled by . See Fig 2(c). We find that the initialization of the biases is critical for training gated models, and following the guidelines[^2] in [6, 7], we conduct hyper-parameter search on the initial value of in the range of 0 to -10 with a decrement step of -1 on the training set by cross-validation. The best value ( here) is then used for training on the training set, leading to a test result of 8.70% (Table 1), which still lags far behind the ResNet-110 baseline. Fig 3(b) shows the training curves. Table 1 also reports the results of using other initialized values, noting that the exclusive gating network does not converge to a good solution when is not appropriately initialized.
我们考察[6, 7]中使用的“互斥”门—— 路径乘以 ,捷径路径乘以 。见图 2(c)。我们发现,偏置 的初始化对训练有门控的模型至关重要;按照[6, 7]中的指导[^2],我们在训练集上用交叉验证,在 0 到 -10 的范围内以 -1 为步长搜索 的初始值。最好的取值(这里是 )再用于在训练集上训练,得到测试结果 8.70%(表 1),仍然远落后于 ResNet-110 基线。图 3(b) 给出训练曲线。表 1 也报告了其他初始值的结果,需要指出的是,当 初始化不当时,互斥门控网络不能收敛到好的解。
The impact of the exclusive gating mechanism is two-fold. When approaches 1, the gated shortcut connections are closer to identity which helps information propagation; but in this case approaches 0 and suppresses the function . To isolate the effects of the gating functions on the shortcut path alone, we investigate a non-exclusive gating mechanism in the next.
互斥门控机制的影响是两方面的。当 接近 1 时,被门控的捷径更接近恒等,有助于信息传播;但这时 接近 0,会抑制函数 。为了单独观察门控函数对捷径路径的影响,下面我们考察一种非互斥的门控机制。
Shortcut-only gating. In this case the function is not scaled; only the shortcut path is gated by . See Fig 2(d). The initialized value of is still essential in this case. When the initialized is 0 (so initially the expectation of is 0.5), the network converges to a poor result of 12.86% (Table 1). This is also caused by higher training error (Fig 3(c)).
仅捷径门控。这种情形下不缩放函数 ,只对捷径路径用 做门控。见图 2(d)。 的初始值在这里仍然关键。当初始 为 0 时(因而一开始 的期望是 0.5),网络收敛到较差的 12.86%(表 1)。这也是由更高的训练误差造成的(图 3(c))。
When the initialized is very negatively biased (e.g., ), the value of is closer to 1 and the shortcut connection is nearly an identity mapping. Therefore, the result (6.91%, Table 1) is much closer to the ResNet-110 baseline.
当初始 有很强的负偏置(例如 )时, 更接近 1,捷径连接几乎就是恒等映射。因此结果(6.91%,表 1)更接近 ResNet-110 基线。
11 convolutional shortcut. Next we experiment with 11 convolutional shortcut connections that replace the identity. This option has been investigated in [1] (known as option C) on a 34-layer ResNet (16 Residual Units) and shows good results, suggesting that 11 shortcut connections could be useful. But we find that this is not the case when there are many Residual Units. The 110-layer ResNet has a poorer result (12.22%, Table 1) when using 11 convolutional shortcuts. Again, the training error becomes higher (Fig 3(d)). When stacking so many Residual Units (54 for ResNet-110), even the shortest path may still impede signal propagation. We witnessed similar phenomena on ImageNet with ResNet-101 when using 11 convolutional shortcuts.
卷积捷径。接下来我们用 卷积捷径连接替换恒等连接。这一选项已在[1]中(称为选项 C)在 34 层 ResNet(16 个残差单元)上考察过,并显示出好的结果,暗示 捷径可能有用。但我们发现,当残差单元很多时情况并非如此。使用 卷积捷径时,110 层 ResNet 的结果较差(12.22%,表 1)。训练误差同样更高(图 3(d))。堆叠这么多残差单元时(ResNet-110 有 54 个),即便是最短的路径仍可能阻碍信号传播。我们在 ImageNet 上对 ResNet-101 使用 卷积捷径时,也观察到类似现象。
Dropout shortcut. Last we experiment with dropout [11] (at a ratio of 0.5) which we adopt on the output of the identity shortcut (Fig. 2(f)). The network fails to converge to a good solution. Dropout statistically imposes a scale of with an expectation of 0.5 on the shortcut, and similar to constant scaling by 0.5, it impedes signal propagation.
Dropout 捷径。最后我们实验 dropout[11](比率为 0.5),把它加在恒等捷径的输出上(图 2(f))。网络未能收敛到好的解。Dropout 在统计上给捷径加上期望为 0.5 的尺度 ,类似于用 0.5 做常数缩放,会阻碍信号传播。
3.2 Discussions
3.2 讨论
As indicated by the grey arrows in Fig. 2, the shortcut connections are the most direct paths for the information to propagate. Multiplicative manipulations (scaling, gating, 11 convolutions, and dropout) on the shortcuts can hamper information propagation and lead to optimization problems.
如图 2 中灰色箭头所示,捷径连接是信息传播最直接的路径。在捷径上做乘法操作(缩放、门控、 卷积以及 dropout)会妨碍信息传播,并带来优化问题。
It is noteworthy that the gating and 11 convolutional shortcuts introduce more parameters, and should have stronger representational abilities than identity shortcuts. In fact, the shortcut-only gating and 11 convolution cover the solution space of identity shortcuts (i.e., they could be optimized as identity shortcuts). However, their training error is higher than that of identity shortcuts, indicating that the degradation of these models is caused by optimization issues, instead of representational abilities.
应当指出,门控和 卷积捷径引入了更多参数,按理应比恒等捷径有更强的表达能力。事实上,仅捷径门控和 卷积覆盖了恒等捷径的解空间(也就是说,它们可以被优化成恒等捷径)。然而它们的训练误差高于恒等捷径,说明这些模型变差是由优化问题造成的,而不是表达能力不足。
4 On the Usage of Activation Functions
4 关于激活函数的用法
| case | Fig. | ResNet-110 | ResNet-164 |
|---|---|---|---|
| original Residual Unit [1] | Fig. 4(a) | 6.61 | 5.93 |
| BN after addition | Fig. 4(b) | 8.17 | 6.50 |
| ReLU before addition | Fig. 4(c) | 7.84 | 6.14 |
| ReLU-only pre-activation | Fig. 4(d) | 6.71 | 5.91 |
| full pre-activation | Fig. 4(e) | 6.37 | 5.46 |
Table 2: Classification error (%) on the CIFAR-10 test set using different activation functions.
| 情形 | 图 | ResNet-110 | ResNet-164 |
|---|---|---|---|
| 原来的残差单元 [1] | 图 4(a) | 6.61 | 5.93 |
| 加法后做 BN | 图 4(b) | 8.17 | 6.50 |
| 加法前做 ReLU | 图 4(c) | 7.84 | 6.14 |
| 仅 ReLU 预激活 | 图 4(d) | 6.71 | 5.91 |
| 完全预激活 | 图 4(e) | 6.37 | 5.46 |
表 2:在 CIFAR-10 测试集上,使用不同激活函数时的分类误差(%)。
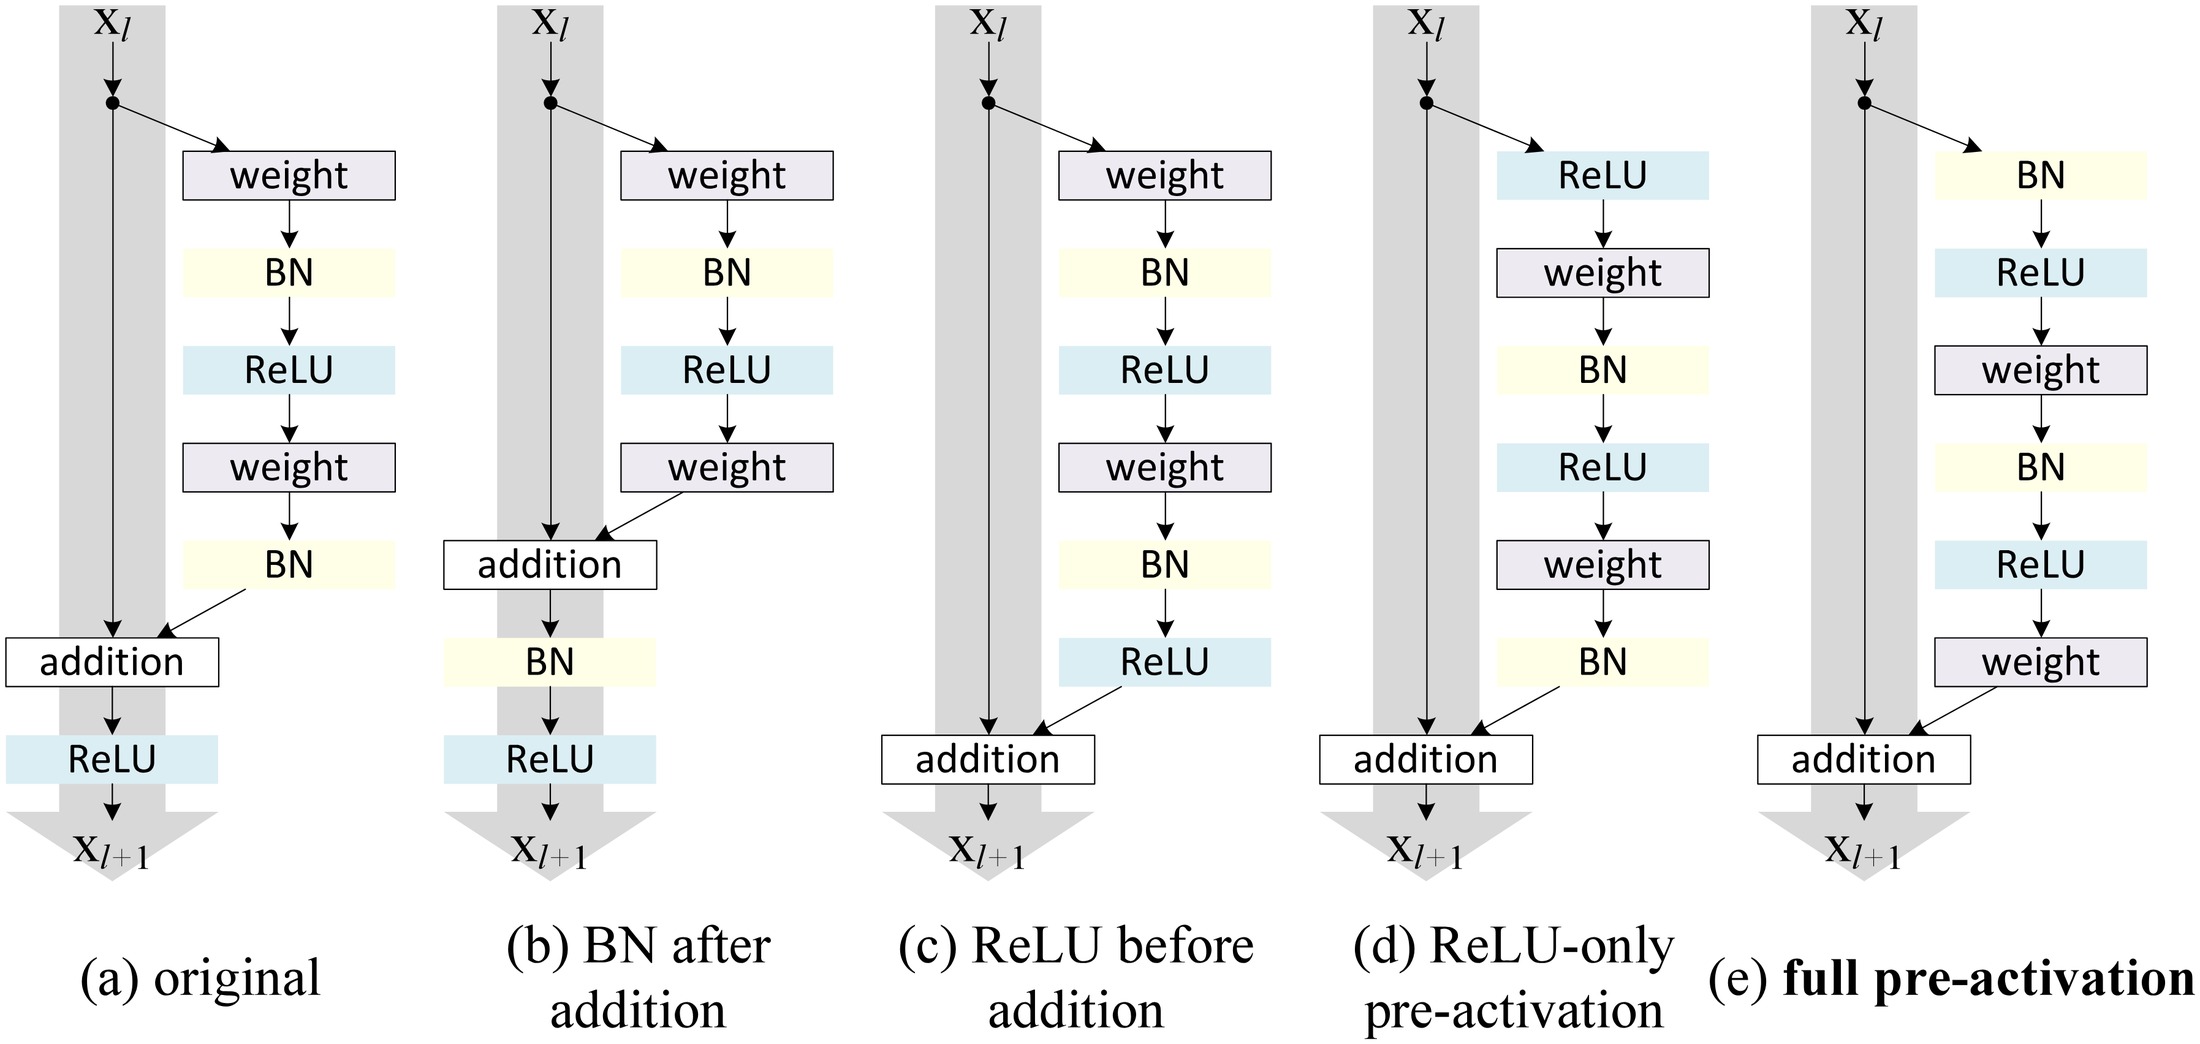
Figure 4: Various usages of activation in Table 2. All these units consist of the same components — only the orders are different.
图 4:表 2 中激活函数的各种用法。这些单元的组件完全相同,只是顺序不同。
Experiments in the above section support the analysis in Eqn.(5) and Eqn.(8), both being derived under the assumption that the after-addition activation is the identity mapping. But in the above experiments is ReLU as designed in [1], so Eqn.(5) and (8) are approximate in the above experiments. Next we investigate the impact of .
上一节的实验支持对式(5)和式(8)的分析,这两式都是在加法后的激活 为恒等映射的假定下推导的。但在上面的实验里, 仍是[1]中设计的 ReLU,因此式(5)和(8)在那些实验中只是近似成立。接下来我们考察 的影响。
We want to make an identity mapping, which is done by re-arranging the activation functions (ReLU and/or BN). The original Residual Unit in [1] has a shape in Fig. 4(a) — BN is used after each weight layer, and ReLU is adopted after BN except that the last ReLU in a Residual Unit is after element-wise addition ( ReLU). Fig. 4(b-e) show the alternatives we investigated, explained as following.
我们希望让 成为恒等映射,做法是重新排布激活函数(ReLU 和/或 BN)。[1]中原来的残差单元形状如图 4(a)——BN 用在每个权重层之后,ReLU 接在 BN 之后,只是一个残差单元里的最后一个 ReLU 放在逐元素加法之后( ReLU)。图 4(b–e) 给出我们考察的替代方案,说明如下。
4.1 Experiments on Activation
4.1 关于激活的实验
In this section we experiment with ResNet-110 and a 164-layer Bottleneck [1] architecture (denoted as ResNet-164). A bottleneck Residual Unit consist of a 11 layer for reducing dimension, a 33 layer, and a 11 layer for restoring dimension. As designed in [1], its computational complexity is similar to the two-33 Residual Unit. More details are in the appendix. The baseline ResNet-164 has a competitive result of 5.93% on CIFAR-10 (Table 2).
本节我们用 ResNet-110 以及一种 164 层的瓶颈[1]结构(记为 ResNet-164)做实验。瓶颈残差单元由一层用于降维的 、一层 ,以及一层用于恢复维度的 组成。按[1]的设计,它的计算复杂度与两层 的残差单元相近。更多细节见附录。作为基线的 ResNet-164 在 CIFAR-10 上取得了有竞争力的 5.93%(表 2)。
BN after addition. Before turning into an identity mapping, we go the opposite way by adopting BN after addition (Fig. 4(b)). In this case involves BN and ReLU. The results become considerably worse than the baseline (Table 2). Unlike the original design, now the BN layer alters the signal that passes through the shortcut and impedes information propagation, as reflected by the difficulties on reducing training loss at the beginning of training (Fib. 6 left).
加法后做 BN。在把 变成恒等映射之前,我们先走相反的方向,把 BN 放在加法之后(图 4(b))。这时 包含 BN 和 ReLU。结果比基线差了不少(表 2)。与原设计不同,现在 BN 层会改写经过捷径的信号,从而阻碍信息传播,这体现在训练初期降低训练损失的困难上(图 6 左)。
ReLU before addition. A naïve choice of making into an identity mapping is to move the ReLU before addition (Fig. 4(c)). However, this leads to a non-negative output from the transform , while intuitively a “residual” function should take values in . As a result, the forward propagated signal is monotonically increasing. This may impact the representational ability, and the result is worse (7.84%, Table 2) than the baseline. We expect to have a residual function taking values in . This condition is satisfied by other Residual Units including the following ones.
加法前做 ReLU。要把 做成恒等映射,一种直接的选择是把 ReLU 移到加法之前(图 4(c))。但这会使变换 的输出非负,而直观上“残差”函数的取值应在 上。结果是前向传播的信号单调递增。这可能影响表达能力,结果(7.84%,表 2)比基线更差。我们希望残差函数的取值在 上。包括下面几种在内的其他残差单元都满足这一条件。
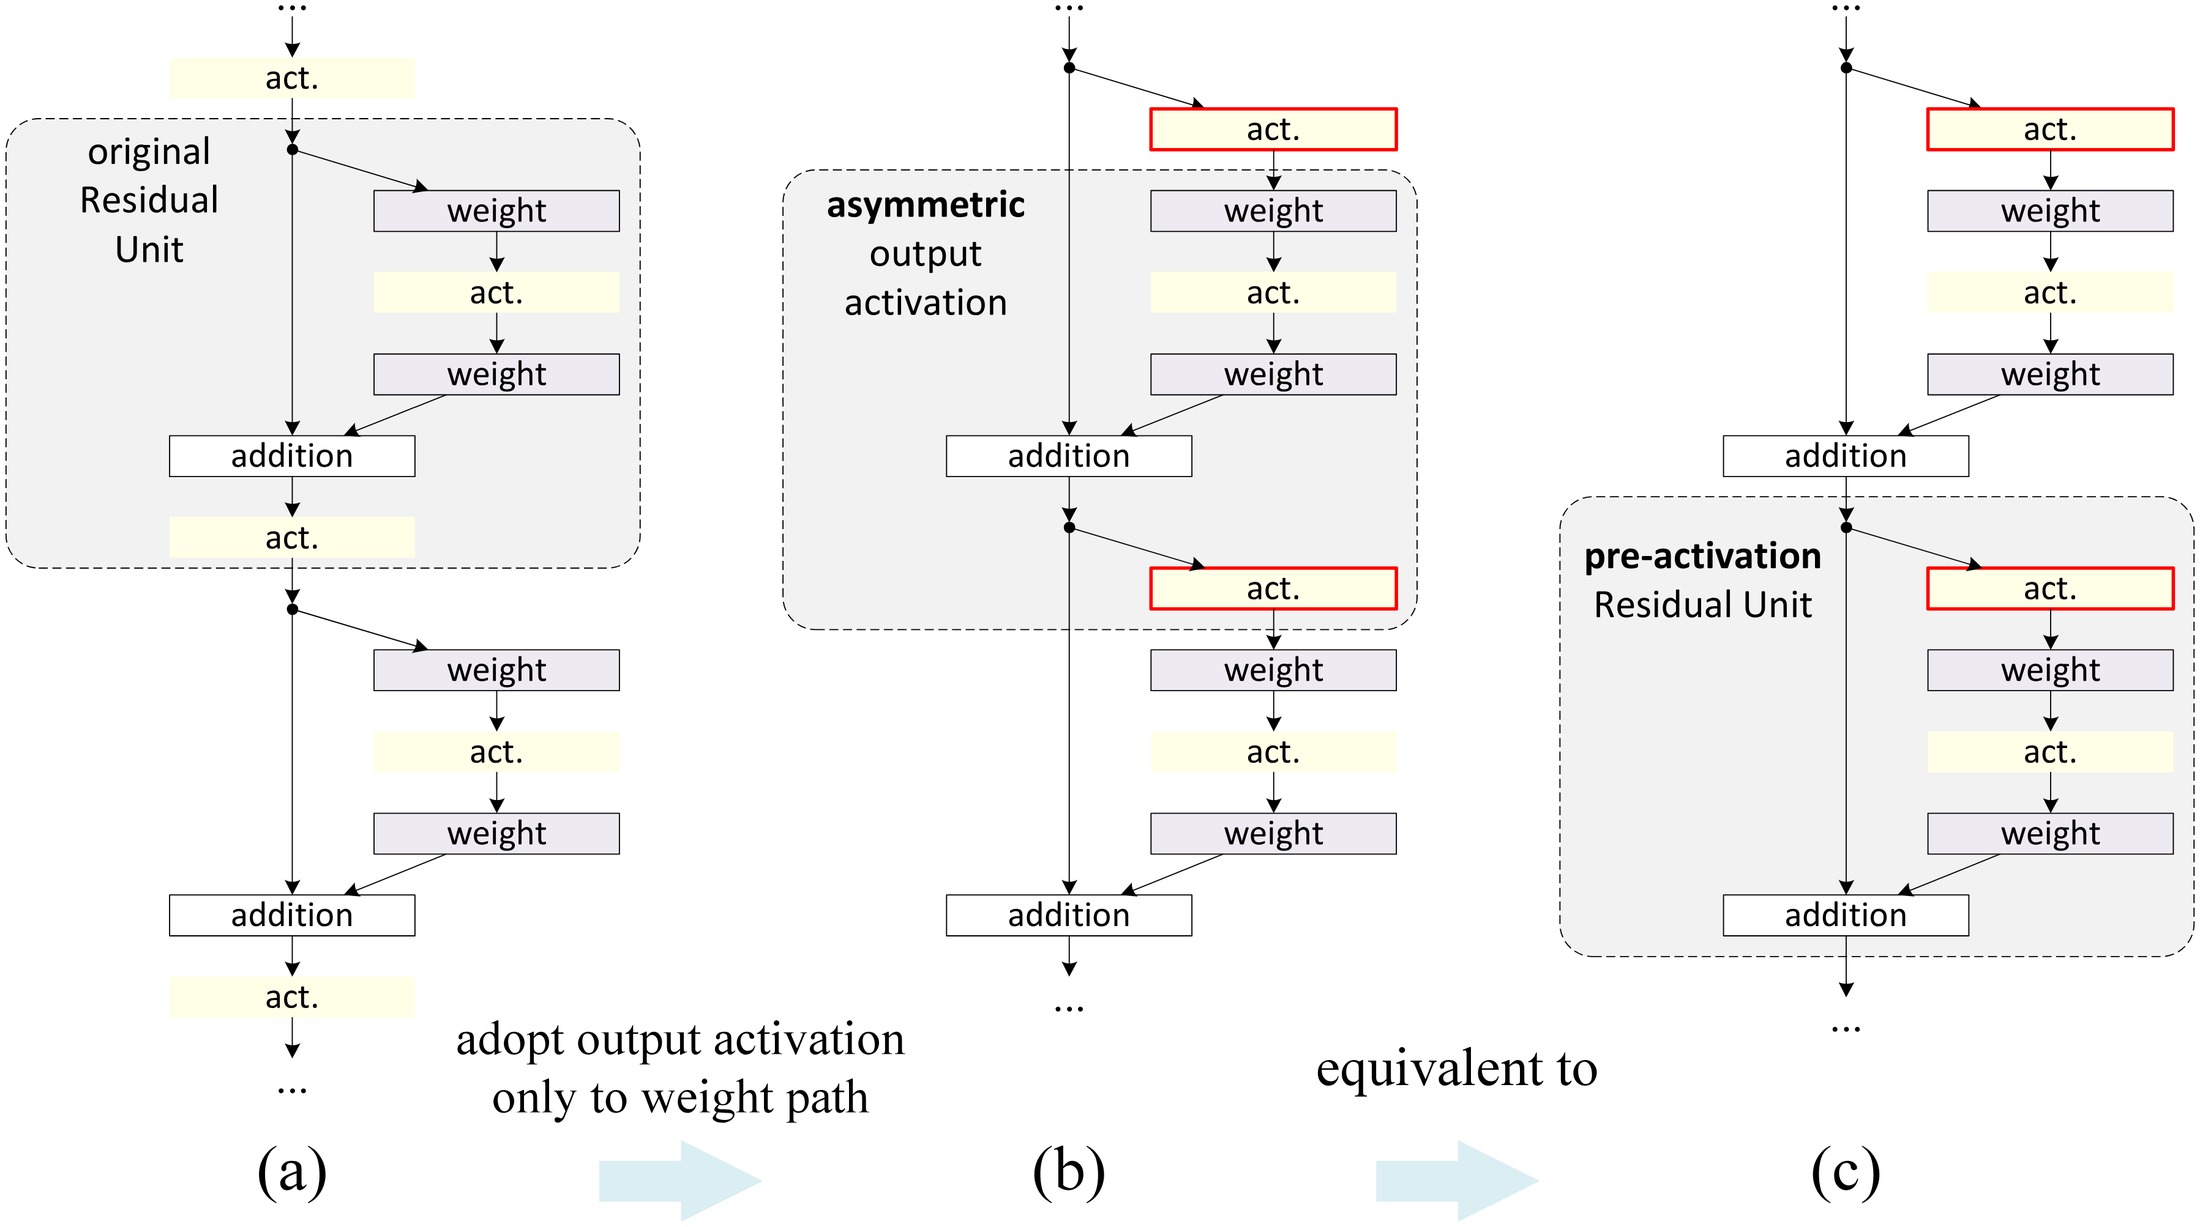
Figure 5: Using asymmetric after-addition activation is equivalent to constructing a pre-activation Residual Unit.
图 5:使用不对称的加法后激活,等价于构造一个预激活残差单元。
Post-activation or pre-activation? In the original design (Eqn.(1) and Eqn.(2)), the activation affects both paths in the next Residual Unit: . Next we develop an asymmetric form where an activation only affects the path: , for any (Fig. 5 (a) to (b)). By renaming the notations, we have the following form:
后激活还是预激活? 在原来的设计(式(1)和式(2))中,激活 会影响下一个残差单元中的两条路径:。接下来我们给出一种不对称形式,使激活 只影响 路径:对任意 ,有 (图 5(a) 到 (b))。重新命名记号后,我们得到如下形式:
It is easy to see that Eqn.(9) is similar to Eqn.(4), and can enable a backward formulation similar to Eqn.(5). For this new Residual Unit as in Eqn.(9), the new after-addition activation becomes an identity mapping. This design means that if a new after-addition activation is asymmetrically adopted, it is equivalent to recasting as the pre-activation of the next Residual Unit. This is illustrated in Fig. 5.
容易看出,式(9)与式(4)类似,并且可以导出与式(5)类似的反向形式。对式(9)这种新的残差单元,新的加法后激活变成了恒等映射。这一设计意味着:如果新的加法后激活 被不对称地采用,就等价于把 改写为下一个残差单元的预激活。图 5 说明了这一点。
The distinction between post-activation/pre-activation is caused by the presence of the element-wise addition. For a plain network that has layers, there are activations (BN/ReLU), and it does not matter whether we think of them as post- or pre-activations. But for branched layers merged by addition, the position of activation matters.
后激活与预激活的区别,来自逐元素加法的存在。对一个有 层的普通网络,有 个激活(BN/ReLU),把它们看成后激活还是预激活并无区别。但对由加法合并的分支层,激活的位置就有关系了。
We experiment with two such designs: (i) ReLU-only pre-activation (Fig. 4(d)), and (ii) full pre-activation (Fig. 4(e)) where BN and ReLU are both adopted before weight layers. Table 2 shows that the ReLU-only pre-activation performs very similar to the baseline on ResNet-110/164. This ReLU layer is not used in conjunction with a BN layer, and may not enjoy the benefits of BN [8].
我们实验了两种这样的设计:(i) 仅 ReLU 预激活(图 4(d)),以及 (ii) 完全预激活(图 4(e)),即 BN 和 ReLU 都放在权重层之前。表 2 显示,仅 ReLU 预激活在 ResNet-110/164 上的表现与基线非常接近。这一 ReLU 层没有与 BN 层一起使用,可能无法享受 BN 的好处[8]。
| dataset | network | baseline unit | pre-activation unit |
|---|---|---|---|
| CIFAR-10 | ResNet-110 (1layer skip) | 9.90 | 8.91 |
| ResNet-110 | 6.61 | 6.37 | |
| ResNet-164 | 5.93 | 5.46 | |
| ResNet-1001 | 7.61 | 4.92 | |
| CIFAR-100 | ResNet-164 | 25.16 | 24.33 |
| ResNet-1001 | 27.82 | 22.71 |
Table 3: Classification error (%) on the CIFAR-10/100 test set using the original Residual Units and our pre-activation Residual Units.
| 数据集 | 网络 | 基线单元 | 预激活单元 |
|---|---|---|---|
| CIFAR-10 | ResNet-110(1 层跳跃) | 9.90 | 8.91 |
| ResNet-110 | 6.61 | 6.37 | |
| ResNet-164 | 5.93 | 5.46 | |
| ResNet-1001 | 7.61 | 4.92 | |
| CIFAR-100 | ResNet-164 | 25.16 | 24.33 |
| ResNet-1001 | 27.82 | 22.71 |
表 3:在 CIFAR-10/100 测试集上,使用原来的残差单元与我们的预激活残差单元时的分类误差(%)。
Somehow surprisingly, when BN and ReLU are both used as pre-activation, the results are improved by healthy margins (Table 2 and Table 3). In Table 3 we report results using various architectures: (i) ResNet-110, (ii) ResNet-164, (iii) a 110-layer ResNet architecture in which each shortcut skips only 1 layer (i.e., a Residual Unit has only 1 layer), denoted as “ResNet-110(1layer)”, and (iv) a 1001-layer bottleneck architecture that has 333 Residual Units (111 on each feature map size), denoted as “ResNet-1001”. We also experiment on CIFAR-100. Table 3 shows that our “pre-activation” models are consistently better than the baseline counterparts. We analyze these results in the following.
有些出人意料的是,当 BN 和 ReLU 都用作预激活时,结果有了相当可观的提升(表 2 和表 3)。在表 3 中,我们报告了多种结构的结果:(i) ResNet-110,(ii) ResNet-164,(iii) 一种 110 层 ResNet 结构,其中每条捷径只跳过 1 层(也就是说,一个残差单元只有 1 层),记为“ResNet-110(1layer)”,以及 (iv) 一种 1001 层瓶颈结构,有 333 个残差单元(每种特征图尺寸上 111 个),记为“ResNet-1001”。我们也在 CIFAR-100 上做了实验。表 3 显示,我们的“预激活”模型始终优于对应的基线。下面分析这些结果。
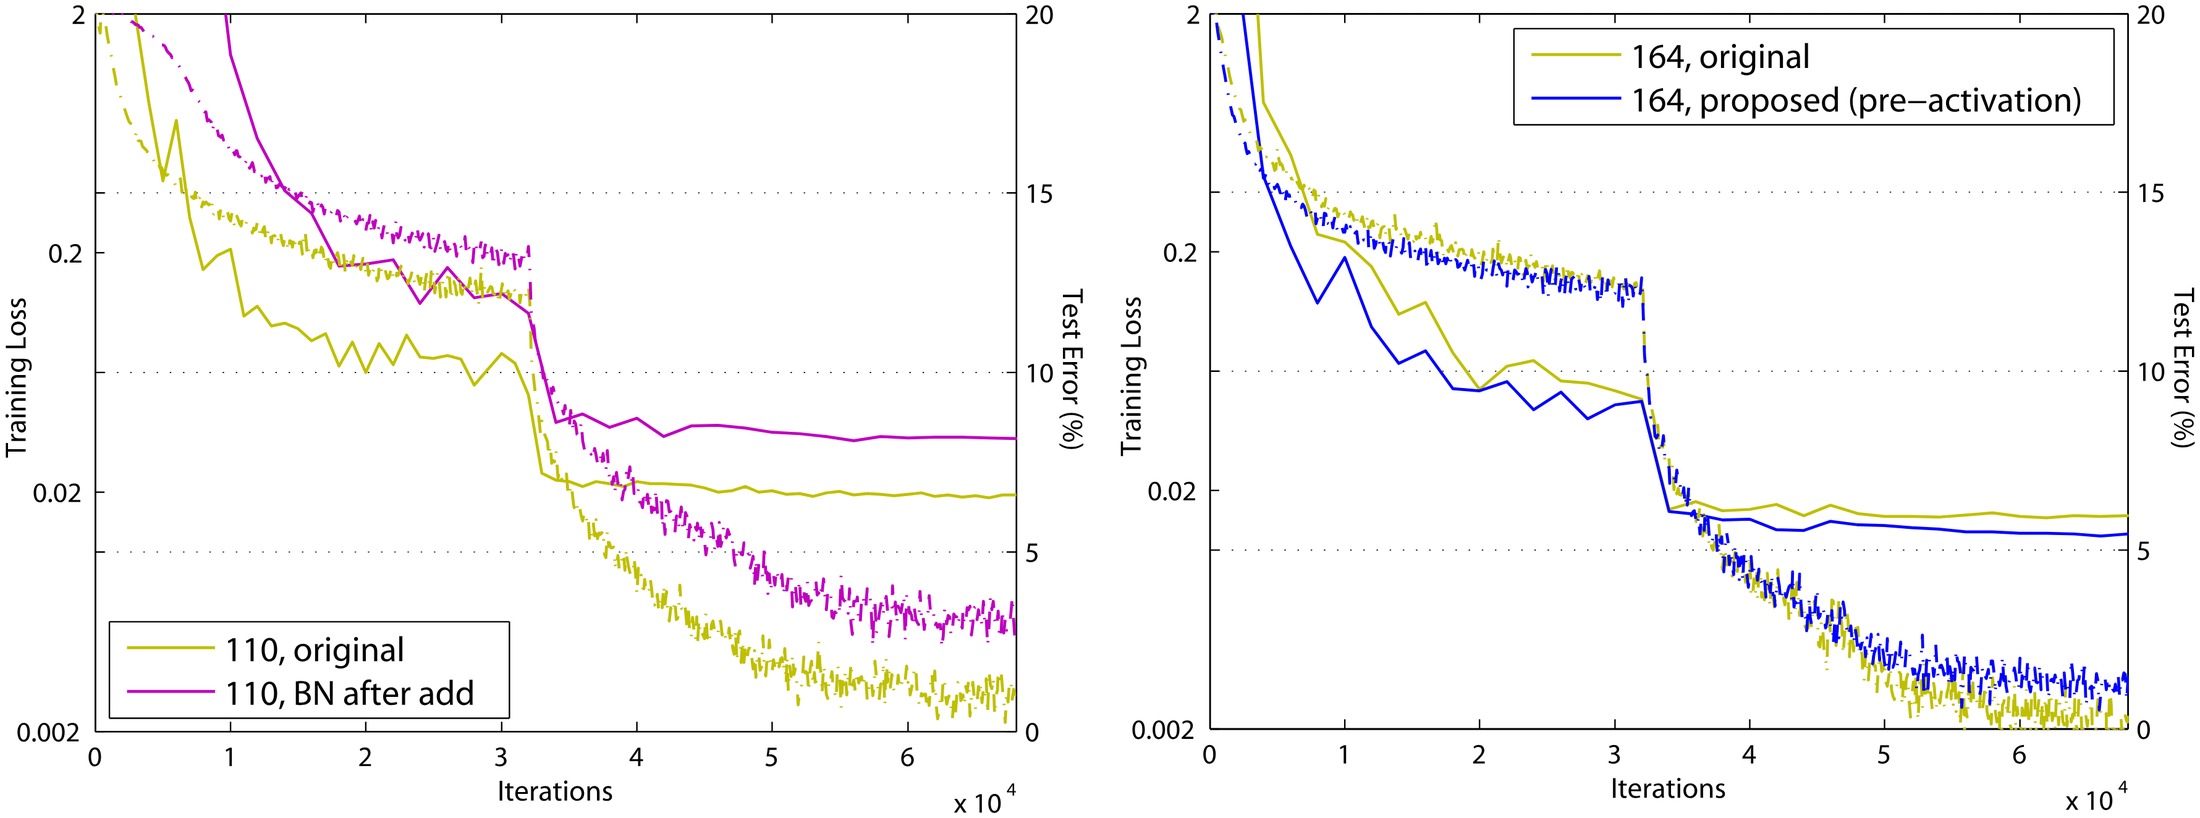
Figure 6: Training curves on CIFAR-10. Left: BN after addition (Fig. 4(b)) using ResNet-110. Right: pre-activation unit (Fig. 4(e)) on ResNet-164. Solid lines denote test error, and dashed lines denote training loss.
图 6:CIFAR-10 上的训练曲线。左:加法后做 BN(图 4(b)),使用 ResNet-110。右:预激活单元(图 4(e))用在 ResNet-164 上。实线是测试误差,虚线是训练损失。
4.2 Analysis
4.2 分析
We find the impact of pre-activation is twofold. First, the optimization is further eased (comparing with the baseline ResNet) because is an identity mapping. Second, using BN as pre-activation improves regularization of the models.
我们发现预激活的影响是两方面的。第一,优化被进一步简化(与基线 ResNet 相比),因为 是恒等映射。第二,把 BN 用作预激活改善了模型的正则化。
Ease of optimization. This effect is particularly obvious when training the 1001-layer ResNet. Fig. 1 shows the curves. Using the original design in [1], the training error is reduced very slowly at the beginning of training. For ReLU, the signal is impacted if it is negative, and when there are many Residual Units, this effect becomes prominent and Eqn.(3) (so Eqn.(5)) is not a good approximation. On the other hand, when is an identity mapping, the signal can be propagated directly between any two units. Our 1001-layer network reduces the training loss very quickly (Fig. 1). It also achieves the lowest loss among all models we investigated, suggesting the success of optimization.
优化更容易。这一效果在训练 1001 层 ResNet 时尤为明显。图 1 给出了曲线。使用[1]中的原设计,训练误差在训练初期下降得很慢。当 ReLU 时,若信号为负就会受到影响;残差单元很多时,这一效应变得突出,式(3)(从而式(5))不再是好的近似。另一方面,当 是恒等映射时,信号可以在任意两个单元之间直接传播。我们的 1001 层网络很快就把训练损失降了下去(图 1)。它也在我们考察的所有模型中达到了最低的损失,说明优化是成功的。
We also find that the impact of ReLU is not severe when the ResNet has fewer layers (e.g., 164 in Fig. 6(right)). The training curve seems to suffer a little bit at the beginning of training, but goes into a healthy status soon. By monitoring the responses we observe that this is because after some training, the weights are adjusted into a status such that in Eqn.(1) is more frequently above zero and does not truncate it ( is always non-negative due to the previous ReLU, so is below zero only when the magnitude of is very negative). The truncation, however, is more frequent when there are 1000 layers.
我们也发现,当 ResNet 层数较少时(例如图 6 右中的 164 层), ReLU 的影响并不严重。训练曲线在训练初期似乎会差一点,但很快进入正常状态。通过监测响应,我们观察到这是因为经过一段时间训练后,权重被调整到这样一种状态:式(1)中的 更经常大于零, 不会截断它(由于前面的 ReLU, 总是非负的,因此只有当 的幅度非常负时, 才会低于零)。而这种截断在有 1000 层时会更频繁。
Reducing overfitting. Another impact of using the proposed pre-activation unit is on regularization, as shown in Fig. 6 (right). The pre-activation version reaches slightly higher training loss at convergence, but produces lower test error. This phenomenon is observed on ResNet-110, ResNet-110(1-layer), and ResNet-164 on both CIFAR-10 and 100. This is presumably caused by BN’s regularization effect [8]. In the original Residual Unit (Fig. 4(a)), although the BN normalizes the signal, this is soon added to the shortcut and thus the merged signal is not normalized. This unnormalized signal is then used as the input of the next weight layer. On the contrary, in our pre-activation version, the inputs to all weight layers have been normalized.
减轻过拟合。使用所提出的预激活单元的另一重影响是正则化,如图 6(右)所示。预激活版本在收敛时训练损失略高,但测试误差更低。这一现象在 ResNet-110、ResNet-110(1 层)和 ResNet-164 上,在 CIFAR-10 和 CIFAR-100 上都观察得到。这大概是由 BN 的正则作用造成的[8]。在原来的残差单元(图 4(a))中,尽管 BN 对信号做了归一化,这一信号很快就加到捷径上,因而合并后的信号并未被归一化。这个未归一化的信号随后作为下一权重层的输入。相反,在我们的预激活版本中,所有权重层的输入都已经归一化。
5 Results
5 结果
Comparisons on CIFAR-10/100. Table 4 compares the state-of-the-art methods on CIFAR-10/100, where we achieve competitive results. We note that we do not specially tailor the network width or filter sizes, nor use regularization techniques (such as dropout) which are very effective for these small datasets. We obtain these results via a simple but essential concept — going deeper. These results demonstrate the potential of pushing the limits of depth.
在 CIFAR-10/100 上的比较。 表 4 把本文方法与当时最好的方法在 CIFAR-10/100 上做了比较,我们取得了有竞争力的结果。需要说明的是,我们没有专门调整网络宽度或滤波器尺寸,也没有使用对这些小数据集非常有效的正则技术(例如 dropout)。这些结果是通过一个简单但关键的想法得到的——把网络做深。它们展示了把深度推到极限的潜力。
| CIFAR-10 | error (%) |
|---|---|
| NIN [15] | 8.81 |
| DSN [16] | 8.22 |
| FitNet [17] | 8.39 |
| Highway [7] | 7.72 |
| All-CNN [14] | 7.25 |
| ELU [12] | 6.55 |
| FitResNet, LSUV [18] | 5.84 |
| ResNet-110 [1] (1.7M) | 6.61 |
| ResNet-1202 [1] (19.4M) | 7.93 |
| ResNet-164 [ours] (1.7M) | 5.46 |
| ResNet-1001 [ours] (10.2M) | 4.92 (4.890.14) |
| ResNet-1001 [ours] (10.2M)† | 4.62 (4.690.20) |
| CIFAR-100 | error (%) |
|---|---|
| NIN [15] | 35.68 |
| DSN [16] | 34.57 |
| FitNet [17] | 35.04 |
| Highway [7] | 32.39 |
| All-CNN [14] | 33.71 |
| ELU [12] | 24.28 |
| FitNet, LSUV [18] | 27.66 |
| ResNet-164 [1] (1.7M) | 25.16 |
| ResNet-1001 [1] (10.2M) | 27.82 |
| ResNet-164 [ours] (1.7M) | 24.33 |
| ResNet-1001 [ours] (10.2M) | 22.71 (22.680.22) |
Table 4: Comparisons with state-of-the-art methods on CIFAR-10 and CIFAR-100 using “moderate data augmentation” (flip/translation), except for ELU [12] with no augmentation. Better results of [13, 14] have been reported using stronger data augmentation and ensembling. For the ResNets we also report the number of parameters. Our results are the median of 5 runs with meanstd in the brackets. All ResNets results are obtained with a mini-batch size of 128 except † with a mini-batch size of 64 (code available at https://github.com/KaimingHe/resnet-1k-layers).
| CIFAR-10 | 误差 (%) |
|---|---|
| NIN [15] | 8.81 |
| DSN [16] | 8.22 |
| FitNet [17] | 8.39 |
| Highway [7] | 7.72 |
| All-CNN [14] | 7.25 |
| ELU [12] | 6.55 |
| FitResNet, LSUV [18] | 5.84 |
| ResNet-110 [1] (1.7M) | 6.61 |
| ResNet-1202 [1] (19.4M) | 7.93 |
| ResNet-164 [ours] (1.7M) | 5.46 |
| ResNet-1001 [ours] (10.2M) | 4.92 (4.890.14) |
| ResNet-1001 [ours] (10.2M)† | 4.62 (4.690.20) |
| CIFAR-100 | 误差 (%) |
|---|---|
| NIN [15] | 35.68 |
| DSN [16] | 34.57 |
| FitNet [17] | 35.04 |
| Highway [7] | 32.39 |
| All-CNN [14] | 33.71 |
| ELU [12] | 24.28 |
| FitNet, LSUV [18] | 27.66 |
| ResNet-164 [1] (1.7M) | 25.16 |
| ResNet-1001 [1] (10.2M) | 27.82 |
| ResNet-164 [ours] (1.7M) | 24.33 |
| ResNet-1001 [ours] (10.2M) | 22.71 (22.680.22) |
表 4:在 CIFAR-10 和 CIFAR-100 上,使用“中等强度数据增强”(翻转/平移)与当时最好方法的比较,惟 ELU[12] 未使用增强。[13, 14] 在更强的数据增强和集成下报告过更好的结果。对 ResNet,我们还报告了参数量。我们的结果是 5 次运行的中位数,括号内为均值标准差。除 † 的 mini-batch 大小为 64 外,所有 ResNet 结果的 mini-batch 大小均为 128(代码见 https://github.com/KaimingHe/resnet-1k-layers)。
Comparisons on ImageNet. Next we report experimental results on the 1000-class ImageNet dataset [3]. We have done preliminary experiments using the skip connections studied in Fig. 2 & 3 on ImageNet with ResNet-101 [1], and observed similar optimization difficulties. The training error of these non-identity shortcut networks is obviously higher than the original ResNet at the first learning rate (similar to Fig. 3), and we decided to halt training due to limited resources. But we did finish a “BN after addition” version (Fig. 4(b)) of ResNet-101 on ImageNet and observed higher training loss and validation error. This model’s single-crop (224224) validation error is 24.6%/7.5%, *vs.*the original ResNet-101’s 23.6%/7.1%. This is in line with the results on CIFAR in Fig. 6 (left).
在 ImageNet 上的比较。 接下来我们报告在 1000 类 ImageNet 数据集[3]上的实验结果。我们曾用图 2 和图 3 中研究的捷径连接,在 ImageNet 上对 ResNet-101[1] 做了初步实验,并观察到类似的优化困难。这些非恒等捷径网络在第一段学习率下的训练误差明显高于原来的 ResNet(类似于图 3),由于资源有限,我们决定停止训练。但我们确实在 ImageNet 上完成了 ResNet-101 的“加法后做 BN”版本(图 4(b)),并观察到更高的训练损失和验证误差。该模型单裁剪(224224)的验证误差为 24.6%/7.5%,而原来的 ResNet-101 为 23.6%/7.1%。这与图 6(左)中 CIFAR 上的结果一致。
Table 5 shows the results of ResNet-152 [1] and ResNet-200[^3], all trained from scratch. We notice that the original ResNet paper [1] trained the models using scale jittering with shorter side , and so the test of a 224224 crop on (as did in [1]) is negatively biased. Instead, we test a single 320320 crop from , for all original and our ResNets. Even though the ResNets are trained on smaller crops, they can be easily tested on larger crops because the ResNets are fully convolutional by design. This size is also close to 299299 used by Inception v3 [19], allowing a fairer comparison.
表 5 给出了 ResNet-152[1] 和 ResNet-200[^3] 的结果,全部从零开始训练。我们注意到,原来的 ResNet 论文[1]用短边 的尺度抖动来训练模型,因此在 上测试 224224 裁剪(如[1]所做)会带有负向偏差。取而代之,我们对原来的和我们的所有 ResNet,都从 测试单个 320320 裁剪。尽管这些 ResNet 是在较小的裁剪上训练的,但由于设计上是全卷积的,它们可以很容易地在更大的裁剪上测试。这一尺寸也接近 Inception v3[19] 使用的 299299,便于更公平地比较。
The original ResNet-152 [1] has top-1 error of 21.3% on a 320320 crop, and our pre-activation counterpart has 21.1%. The gain is not big on ResNet-152 because this model has not shown severe generalization difficulties. However, the original ResNet-200 has an error rate of 21.8%, higher than the baseline ResNet-152. But we find that the original ResNet-200 has lower training error than ResNet-152, suggesting that it suffers from overfitting.
原来的 ResNet-152[1] 在 320320 裁剪上的 top-1 误差为 21.3%,我们的预激活对应模型为 21.1%。在 ResNet-152 上增益不大,因为这个模型还没有表现出严重的泛化困难。然而,原来的 ResNet-200 误差率为 21.8%,高于基线 ResNet-152。但我们发现,原来的 ResNet-200 的训练误差低于 ResNet-152,说明它受到了过拟合的影响。
Our pre-activation ResNet-200 has an error rate of 20.7%, which is 1.1% lower than the baseline ResNet-200 and also lower than the two versions of ResNet-152. When using the scale and aspect ratio augmentation of [20, 19], our ResNet-200 has a result better than Inception v3 [19] (Table 5). Concurrent with our work, an Inception-ResNet-v2 model [21] achieves a single-crop result of 19.9%/4.9%. We expect our observations and the proposed Residual Unit will help this type and generally other types of ResNets.
我们的预激活 ResNet-200 误差率为 20.7%,比基线 ResNet-200 低 1.1%,也低于两个版本的 ResNet-152。当使用[20, 19]中的尺度和长宽比增强时,我们的 ResNet-200 得到了优于 Inception v3[19] 的结果(表 5)。与本文同时,Inception-ResNet-v2 模型[21]取得了 19.9%/4.9% 的单裁剪结果。我们期望本文的观察和所提出的残差单元,会有助于这类以及其他类型的 ResNet。
| method | augmentation | train crop | test crop | top-1 | top-5 |
|---|---|---|---|---|---|
| ResNet-152, original Residual Unit [1] | scale | 224224 | 224224 | 23.0 | 6.7 |
| ResNet-152, original Residual Unit [1] | scale | 224224 | 320320 | 21.3 | 5.5 |
| ResNet-152, pre-act Residual Unit | scale | 224224 | 320320 | 21.1 | 5.5 |
| ResNet-200, original Residual Unit [1] | scale | 224224 | 320320 | 21.8 | 6.0 |
| ResNet-200, pre-act Residual Unit | scale | 224224 | 320320 | 20.7 | 5.3 |
| ResNet-200, pre-act Residual Unit | scale+asp ratio | 224224 | 320320 | 20.1†** | 4.8†** |
| Inception v3 [19] | scale+asp ratio | 299299 | 299299 | 21.2 | 5.6 |
Table 5: Comparisons of single-crop error on the ILSVRC 2012 validation set. All ResNets are trained using the same hyper-parameters and implementations as [1]). Our Residual Units are the full pre-activation version (Fig. 4(e)). †: code/model available at https://github.com/facebook/fb.resnet.torch/tree/master/pretrained, using scale and aspect ratio augmentation in [20].
| 方法 | 数据增强 | 训练裁剪 | 测试裁剪 | top-1 | top-5 |
|---|---|---|---|---|---|
| ResNet-152,原来的残差单元 [1] | 尺度 | 224224 | 224224 | 23.0 | 6.7 |
| ResNet-152,原来的残差单元 [1] | 尺度 | 224224 | 320320 | 21.3 | 5.5 |
| ResNet-152,预激活残差单元 | 尺度 | 224224 | 320320 | 21.1 | 5.5 |
| ResNet-200,原来的残差单元 [1] | 尺度 | 224224 | 320320 | 21.8 | 6.0 |
| ResNet-200,预激活残差单元 | 尺度 | 224224 | 320320 | 20.7 | 5.3 |
| ResNet-200,预激活残差单元 | 尺度+长宽比 | 224224 | 320320 | 20.1†** | 4.8†** |
| Inception v3 [19] | 尺度+长宽比 | 299299 | 299299 | 21.2 | 5.6 |
表 5:在 ILSVRC 2012 验证集上的单裁剪误差比较。所有 ResNet 都使用与[1]相同的超参数和实现。我们的残差单元是完全预激活版本(图 4(e))。†:代码/模型见 https://github.com/facebook/fb.resnet.torch/tree/master/pretrained,使用了[20]中的尺度和长宽比增强。
Computational Cost. Our models’ computational complexity is linear on depth (so a 1001-layer net is 10 complex of a 100-layer net). On CIFAR, ResNet-1001 takes about 27 hours to train on 2 GPUs; on ImageNet, ResNet-200 takes about 3 weeks to train on 8 GPUs (on par with VGG nets [22]).
计算代价。 我们模型的计算复杂度对深度是线性的(因此 1001 层网络的复杂度大约是 100 层网络的 倍)。在 CIFAR 上,ResNet-1001 在 2 块 GPU 上大约要训练 27 小时;在 ImageNet 上,ResNet-200 在 8 块 GPU 上大约要训练 3 周(与 VGG 网络[22]相当)。
6 Conclusions
6 结论
This paper investigates the propagation formulations behind the connection mechanisms of deep residual networks. Our derivations imply that identity shortcut connections and identity after-addition activation are essential for making information propagation smooth. Ablation experiments demonstrate phenomena that are consistent with our derivations. We also present 1000-layer deep networks that can be easily trained and achieve improved accuracy.
本文研究了深度残差网络连接机制背后的传播公式。推导表明,恒等捷径连接和加法后的恒等激活,对于信息传播的顺畅是必要的。消融实验展示了与推导一致的现象。我们还给出了可以轻松训练、并取得更高精度的 1000 层深度网络。
Appendix: Implementation Details
The implementation details and hyper-parameters are the same as those in [1]. On CIFAR we use only the translation and flipping augmentation in [1] for training. The learning rate starts from 0.1, and is divided by 10 at 32k and 48k iterations. Following [1], for all CIFAR experiments we warm up the training by using a smaller learning rate of 0.01 at the beginning 400 iterations and go back to 0.1 after that, although we remark that this is not necessary for our proposed Residual Unit. The mini-batch size is 128 on 2 GPUs (64 each), the weight decay is 0.0001, the momentum is 0.9, and the weights are initialized as in [23].
附录:实现细节
实现细节和超参数与[1]中相同。在 CIFAR 上,训练时只使用[1]中的平移和翻转增强。学习率从 0.1 开始,在 32k 和 48k 次迭代时除以 10。沿用[1],对所有 CIFAR 实验,我们在开始的 400 次迭代用较小的学习率 0.01 做预热,之后再回到 0.1,尽管我们要说明,对我们提出的残差单元来说这并非必要。mini-batch 大小在 2 块 GPU 上为 128(每块 64),权重衰减为 0.0001,动量为 0.9,权重按[23]初始化。
On ImageNet, we train the models using the same data augmentation as in [1]. The learning rate starts from 0.1 (no warming up), and is divided by 10 at 30 and 60 epochs. The mini-batch size is 256 on 8 GPUs (32 each). The weight decay, momentum, and weight initialization are the same as above.
在 ImageNet 上,我们使用与[1]相同的数据增强来训练模型。学习率从 0.1 开始(不做预热),在第 30 和 60 个 epoch 除以 10。mini-batch 大小在 8 块 GPU 上为 256(每块 32)。权重衰减、动量和权重初始化与上面相同。
When using the pre-activation Residual Units (Fig. 4(d)(e) and Fig. 5), we pay special attention to the first and the last Residual Units of the entire network. For the first Residual Unit (that follows a stand-alone convolutional layer, conv1), we adopt the first activation right after conv1 and before splitting into two paths; for the last Residual Unit (followed by average pooling and a fully-connected classifier), we adopt an extra activation right after its element-wise addition. These two special cases are the natural outcome when we obtain the pre-activation network via the modification procedure as shown in Fig. 5.
使用预激活残差单元时(图 4(d)(e) 和图 5),我们对整个网络的第一个和最后一个残差单元做了特别处理。对第一个残差单元(它跟在一个独立的卷积层 conv1 之后),我们把第一次激活放在 conv1 之后、分成两条路径之前;对最后一个残差单元(后面接着平均池化和全连接分类器),我们在其逐元素加法之后额外再加一次激活。这两个特例,是我们按图 5 所示的改写步骤得到预激活网络时的自然结果。
The bottleneck Residual Units (for ResNet-164/1001 on CIFAR) are constructed following [1]. For example, a \left[\begin{array}[]{c}\text{3\times3, 16}\\ \text{3\times3, 16}\end{array}\right] unit in ResNet-110 is replaced with a \left[\begin{array}[]{c}\text{1\times1, 16}\\[-0.73616pt] \text{3\times3, 16}\\[-0.73616pt] \text{1\times1, 64}\end{array}\right] unit in ResNet-164, both of which have roughly the same number of parameters. For the bottleneck ResNets, when reducing the feature map size we use projection shortcuts [1] for increasing dimensions, and when pre-activation is used, these projection shortcuts are also with pre-activation.
瓶颈残差单元(用于 CIFAR 上的 ResNet-164/1001)按[1]构造。例如,ResNet-110 中的 \left[\begin{array}[]{c}\text{3\times3, 16}\\ \text{3\times3, 16}\end{array}\right] 单元,在 ResNet-164 中被替换为 \left[\begin{array}[]{c}\text{1\times1, 16}\\[-0.73616pt] \text{3\times3, 16}\\[-0.73616pt] \text{1\times1, 64}\end{array}\right] 单元,二者的参数量大致相同。对瓶颈 ResNet,当缩小特征图尺寸时,我们用投影捷径[1]来增加维度;在使用预激活时,这些投影捷径也带预激活。
[^1] It is noteworthy that there are Residual Units for increasing dimensions and reducing feature map sizes [1] in which is not identity. In this case the following derivations do not hold strictly. But as there are only a very few such units (two on CIFAR and three on ImageNet, depending on image sizes [1]), we expect that they do not have the exponential impact as we present in Sec. 3. One may also think of our derivations as applied to all Residual Units within the same feature map size.
[^1] 需要说明的是,存在一些用于增加维度和缩小特征图尺寸的残差单元[1],其中 不是恒等映射。在这种情况下,后面的推导并不严格成立。但由于这样的单元很少(在 CIFAR 上有两个,在 ImageNet 上有三个,取决于图像尺寸[1]),我们预期它们不会产生第 3 节中讨论的那种指数级影响。也可以把我们的推导,理解为应用在同一特征图尺寸内的所有残差单元上。
[^2] See also: people.idsia.ch/~rupesh/very_deep_learning/ by [6, 7].
[^2] 另见:[6, 7] 的 people.idsia.ch/~rupesh/very_deep_learning/。
[^3] The ResNet-200 has 16 more 3-layer bottleneck Residual Units than ResNet-152, which are added on the feature map of 2828.
[^3] ResNet-200 比 ResNet-152 多 16 个 3 层瓶颈残差单元,加在 的特征图上。
References
参考文献
[1] He, K., Zhang, X., Ren, S., Sun, J.: Deep residual learning for image recognition. In: CVPR. (2016)
[2] Nair, V., Hinton, G.E.: Rectified linear units improve restricted boltzmann machines. In: ICML. (2010)
[3] Russakovsky, O., Deng, J., Su, H., Krause, J., Satheesh, S., Ma, S., Huang, Z., Karpathy, A., Khosla, A., Bernstein, M., Berg, A.C., Fei-Fei, L.: ImageNet Large Scale Visual Recognition Challenge. IJCV (2015)
[4] Lin, T.Y., Maire, M., Belongie, S., Hays, J., Perona, P., Ramanan, D., Dollár, P., Zitnick, C.L.: Microsoft COCO: Common objects in context. In: ECCV. (2014)
[5] Hochreiter, S., Schmidhuber, J.: Long short-term memory. Neural computation (1997)
[6] Srivastava, R.K., Greff, K., Schmidhuber, J.: Highway networks. In: ICML workshop. (2015)
[7] Srivastava, R.K., Greff, K., Schmidhuber, J.: Training very deep networks. In: NIPS. (2015)
[8] Ioffe, S., Szegedy, C.: Batch normalization: Accelerating deep network training by reducing internal covariate shift. In: ICML. (2015)
[9] LeCun, Y., Boser, B., Denker, J.S., Henderson, D., Howard, R.E., Hubbard, W., Jackel, L.D.: Backpropagation applied to handwritten zip code recognition. Neural computation (1989)
[10] Krizhevsky, A.: Learning multiple layers of features from tiny images. Tech Report (2009)
[11] Hinton, G.E., Srivastava, N., Krizhevsky, A., Sutskever, I., Salakhutdinov, R.R.: Improving neural networks by preventing co-adaptation of feature detectors. arXiv:1207.0580 (2012)
[12] Clevert, D.A., Unterthiner, T., Hochreiter, S.: Fast and accurate deep network learning by exponential linear units (ELUs). In: ICLR. (2016)
[13] Graham, B.: Fractional max-pooling. arXiv:1412.6071 (2014)
[14] Springenberg, J.T., Dosovitskiy, A., Brox, T., Riedmiller, M.: Striving for simplicity: The all convolutional net. arXiv:1412.6806 (2014)
[15] Lin, M., Chen, Q., Yan, S.: Network in network. In: ICLR. (2014)
[16] Lee, C.Y., Xie, S., Gallagher, P., Zhang, Z., Tu, Z.: Deeply-supervised nets. In: AISTATS. (2015)
[17] Romero, A., Ballas, N., Kahou, S.E., Chassang, A., Gatta, C., Bengio, Y.: Fitnets: Hints for thin deep nets. In: ICLR. (2015)
[18] Mishkin, D., Matas, J.: All you need is a good init. In: ICLR. (2016)
[19] Szegedy, C., Vanhoucke, V., Ioffe, S., Shlens, J., Wojna, Z.: Rethinking the inception architecture for computer vision. In: CVPR. (2016)
[20] Szegedy, C., Liu, W., Jia, Y., Sermanet, P., Reed, S., Anguelov, D., Erhan, D., Vanhoucke, V., Rabinovich, A.: Going deeper with convolutions. In: CVPR. (2015)
[21] Szegedy, C., Ioffe, S., Vanhoucke, V.: Inception-v4, inception-resnet and the impact of residual connections on learning. arXiv:1602.07261 (2016)
[22] Simonyan, K., Zisserman, A.: Very deep convolutional networks for large-scale image recognition. In: ICLR. (2015)
[23] He, K., Zhang, X., Ren, S., Sun, J.: Delving deep into rectifiers: Surpassing human-level performance on imagenet classification. In: ICCV. (2015)