Hindsight Experience Replay
Hindsight Experience Replay
事后经验回放
Marcin Andrychowicz * Filip Wolski Alex Ray Jonas Schneider Rachel Fong Affiliation: Peter Welinder, Bob McGrew, Josh Tobin, Pieter Abbeel † , Wojciech Zaremba † Affiliation: OpenAI
Abstract
摘要
Dealing with sparse rewards is one of the biggest challenges in Reinforcement Learning (RL). We present a novel technique called Hindsight Experience Replay which allows sample-efficient learning from rewards which are sparse and binary and therefore avoid the need for complicated reward engineering. It can be combined with an arbitrary off-policy RL algorithm and may be seen as a form of implicit curriculum.
处理稀疏奖励是强化学习(RL)最大的挑战之一。我们提出名为 事后经验回放(Hindsight Experience Replay)的新技术,使智能体能从稀疏且二值的奖励中做样本高效的学习,从而避免复杂的奖励工程。它可与任意离策略 RL 算法结合,并可看作一种隐式课程。
We demonstrate our approach on the task of manipulating objects with a robotic arm. In particular, we run experiments on three different tasks: pushing, sliding, and pick-and-place, in each case using only binary rewards indicating whether or not the task is completed. Our ablation studies show that Hindsight Experience Replay is a crucial ingredient which makes training possible in these challenging environments. We show that our policies trained on a physics simulation can be deployed on a physical robot and successfully complete the task. The video presenting our experiments is available at https://goo.gl/SMrQnI.
我们在机械臂操作物体的任务上验证该方法。具体地,在推动、滑动与抓取放置三项任务上实验,每项都只用指示任务是否完成的二值奖励。消融表明,事后经验回放是使这些困难环境可训练的关键成分。我们还展示:在物理仿真中训练的策略可部署到真实机器人并成功完成任务。实验视频见 https://goo.gl/SMrQnI。
1 Introduction
1 引言
Reinforcement learning (RL) combined with neural networks has recently led to a wide range of successes in learning policies for sequential decision-making problems. This includes simulated environments, such as playing Atari games (Mnih et al.,, 2015), and defeating the best human player at the game of Go (Silver et al.,, 2016), as well as robotic tasks such as helicopter control (Ng et al.,, 2006), hitting a baseball (Peters and Schaal,, 2008), screwing a cap onto a bottle (Levine et al.,, 2015), or door opening (Chebotar et al.,, 2016).
强化学习(RL)与神经网络结合,近来在序列决策问题上取得广泛成功。这包括仿真环境中的 Atari 游戏(Mnih et al., 2015)、围棋战胜顶尖人类棋手(Silver et al., 2016),以及直升机控制(Ng et al., 2006)、击棒球(Peters and Schaal, 2008)、拧瓶盖(Levine et al., 2015)或开门(Chebotar et al., 2016)等机器人任务。
However, a common challenge, especially for robotics, is the need to engineer a reward function that not only reflects the task at hand but is also carefully shaped (Ng et al.,, 1999) to guide the policy optimization. For example, Popov et al., (2017) use a cost function consisting of five relatively complicated terms which need to be carefully weighted in order to train a policy for stacking a brick on top of another one. The necessity of cost engineering limits the applicability of RL in the real world because it requires both RL expertise and domain-specific knowledge. Moreover, it is not applicable in situations where we do not know what admissible behaviour may look like. It is therefore of great practical relevance to develop algorithms which can learn from unshaped reward signals, e.g. a binary signal indicating successful task completion.
然而一个常见挑战——尤其在机器人中——是必须工程化奖励函数:它既要反映手头任务,又要精心塑形(Ng et al., 1999)以引导策略优化。例如 Popov et al. (2017) 用由五项相当复杂、需仔细加权的项组成的代价函数,才能训练把砖叠到另一块上的策略。代价工程限制了 RL 在真实世界的适用性,因为它同时需要 RL 专长与领域知识;在我们不清楚何为可接受行为时更不适用。因此,开发能从未塑形奖励信号(例如指示任务成功完成的二值信号)学习的算法,具有重要实践意义。
One ability humans have, unlike the current generation of model-free RL algorithms, is to learn almost as much from achieving an undesired outcome as from the desired one. Imagine that you are learning how to play hockey and are trying to shoot a puck into a net. You hit the puck but it misses the net on the right side. The conclusion drawn by a standard RL algorithm in such a situation would be that the performed sequence of actions does not lead to a successful shot, and little (if anything) would be learned. It is however possible to draw another conclusion, namely that this sequence of actions would be successful if the net had been placed further to the right.
人类具备、而当代无模型 RL 算法尚不具备的一种能力,是从非期望结果中几乎与从期望结果学到同样多。设想你在学打冰球、试图把冰球射入球门。你击中冰球,但偏右打偏。标准 RL 算法在此情境下的结论是:所执行的动作序列不会导致成功射门,因而几乎学不到什么。但也可以得出另一结论:若球门放得更靠右,这一动作序列本会成功。
In this paper we introduce a technique called Hindsight Experience Replay (HER) which allows the algorithm to perform exactly this kind of reasoning and can be combined with any off-policy RL algorithm. It is applicable whenever there are multiple goals which can be achieved, e.g. achieving each state of the system may be treated as a separate goal. Not only does HER improve the sample efficiency in this setting, but more importantly, it makes learning possible even if the reward signal is sparse and binary. Our approach is based on training universal policies (Schaul et al., 2015a, ) which take as input not only the current state, but also a goal state. The pivotal idea behind HER is to replay each episode with a different goal than the one the agent was trying to achieve, e.g. one of the goals which was achieved in the episode.
本文提出名为 事后经验回放(Hindsight Experience Replay, HER)的技术,使算法恰好能做这类推理,并可与任意离策略 RL 算法结合。只要存在多个可达成的 目标——例如把系统的每个状态都当作单独目标——它就适用。HER 不仅提升该设定下的样本效率,更重要的是,即便奖励信号稀疏且二值,也能使学习成为可能。我们的方法基于训练通用策略(Schaul et al., 2015a):输入不仅是当前状态,还有目标状态。HER 的核心思想是用不同于智能体当时试图达成的目标回放每个回合,例如回合中实际达成的某个目标。
2 Background
2 背景
In this section we introduce reinforcement learning formalism used in the paper as well as RL algorithms we use in our experiments.
本节介绍文中使用的强化学习形式体系,以及实验所用的 RL 算法。
2.1 Reinforcement Learning
2.1 强化学习
We consider the standard reinforcement learning formalism consisting of an agent interacting with an environment. To simplify the exposition we assume that the environment is fully observable. An environment is described by a set of states , a set of actions , a distribution of initial states , a reward function , transition probabilities , and a discount factor .
我们考虑智能体与环境交互的标准强化学习形式体系。为简化叙述,假定环境完全可观测。环境由状态集 、动作集 、初始状态分布 、奖励函数 、转移概率 以及折扣因子 描述。
A deterministic policy is a mapping from states to actions: . Every episode starts with sampling an initial state . At every timestep the agent produces an action based on the current state: . Then it gets the reward and the environment’s new state is sampled from the distribution . A discounted sum of future rewards is called a return: . The agent’s goal is to maximize its expected return . The Q-function or action-value function is defined as .
确定性策略是从状态到动作的映射:。每个回合从采样初始状态 开始。在每个时间步 ,智能体基于当前状态产生动作:。随后得到奖励 ,环境新状态从分布 采样。未来奖励的折扣和称为 回报:。智能体目标是最大化期望回报 。Q 函数或动作价值函数定义为 。
Let denote an optimal policy i.e. any policy s.t. for every and any policy . All optimal policies have the same Q-function which is called optimal Q-function and denoted . It is easy to show that it satisfies the following equation called the Bellman equation:
令 表示 最优策略,即任意满足:对每个 、 及任意策略 ,都有 的策略 。所有最优策略共享同一 Q 函数,称为 最优 Q 函数,记为 。易于证明它满足如下称为 Bellman 方程的关系:
2.2 Deep Q-Networks (DQN)
2.2 深度 Q 网络(DQN)
Deep Q-Networks (DQN) (Mnih et al.,, 2015) is a model-free RL algorithm for discrete action spaces. Here we sketch it only informally, see Mnih et al., (2015) for more details. In DQN we maintain a neural network which approximates . A greedy policy w.r.t. is defined as . An -greedy policy w.r.t. is a policy which with probability takes a random action (sampled uniformly from ) and takes the action with probability .
深度 Q 网络(DQN)(Mnih et al., 2015)是面向离散动作空间的无模型 RL 算法。这里仅非正式勾勒,细节见 Mnih et al. (2015)。DQN 中我们维护逼近 的神经网络 。相对 的 贪心 策略定义为 。相对 的 -贪心策略以概率 取随机动作(从 均匀采样),以概率 取动作 。
During training we generate episodes using -greedy policy w.r.t. the current approximation of the action-value function . The transition tuples encountered during training are stored in the so-called replay buffer. The generation of new episodes is interleaved with neural network training. The network is trained using mini-batch gradient descent on the loss which encourages the approximated Q-function to satisfy the Bellman equation: , where and the tuples are sampled from the replay buffer[^1].
训练期间用相对当前动作价值函数逼近 的 -贪心策略生成回合。训练中遇到的转移元组 存入所谓 回放缓冲。新回合生成与神经网络训练交错进行。网络在损失 上用小批量梯度下降训练,该损失促使逼近的 Q 函数满足 Bellman 方程:,其中 ,元组 从回放缓冲采样。[^1]
In order to make this optimization procedure more stable the targets are usually computed using a separate target network which changes at a slower pace than the main network. A common practice is to periodically set the weights of the target network to the current weights of the main network (e.g. Mnih et al., (2015)) or to use a polyak-averaged[^2] (Polyak and Juditsky,, 1992) version of the main network instead (Lillicrap et al.,, 2015).
为使该优化更稳定,目标 通常用单独的 目标网络 计算,其变化慢于主网络。常见做法是周期性把目标网络权重设为主网络当前权重(如 Mnih et al., 2015),或使用主网络的 polyak 平均[^2](Polyak and Juditsky, 1992)版本(Lillicrap et al., 2015)。
2.3 Deep Deterministic Policy Gradients (DDPG)
2.3 深度确定性策略梯度(DDPG)
Deep Deterministic Policy Gradients (DDPG) (Lillicrap et al.,, 2015) is a model-free RL algorithm for continuous action spaces. Here we sketch it only informally, see Lillicrap et al., (2015) for more details. In DDPG we maintain two neural networks: a target policy (also called an actor) and an action-value function approximator (called the critic) . The critic’s job is to approximate the actor’s action-value function .
深度确定性策略梯度(DDPG)(Lillicrap et al., 2015)是面向连续动作空间的无模型 RL 算法。这里仅非正式勾勒,细节见 Lillicrap et al. (2015)。DDPG 中我们维护两个神经网络:目标策略(亦称 演员),以及动作价值函数逼近器(称 评论家)。评论家的任务是逼近演员的动作价值函数 。
Episodes are generated using a behavioral policy which is a noisy version of the target policy, e.g. . The critic is trained in a similar way as the Q-function in DQN but the targets are computed using actions outputted by the actor, i.e. . The actor is trained with mini-batch gradient descent on the loss , where is sampled from the replay buffer. The gradient of w.r.t. actor parameters can be computed by backpropagation through the combined critic and actor networks.
回合由 行为策略 生成,它是目标策略的带噪版本,例如 。评论家的训练方式类似 DQN 中的 Q 函数,但目标 用演员输出的动作计算,即 。演员在损失 上用小批量梯度下降训练,其中 从回放缓冲采样。 对演员参数的梯度可通过组合评论家与演员网络反向传播计算。
2.4 Universal Value Function Approximators (UVFA)
2.4 通用价值函数逼近器(UVFA)
Universal Value Function Approximators (UVFA) (Schaul et al., 2015a, ) is an extension of DQN to the setup where there is more than one goal we may try to achieve. Let be the space of possible goals. Every goal corresponds to some reward function . Every episode starts with sampling a state-goal pair from some distribution . The goal stays fixed for the whole episode. At every timestep the agent gets as input not only the current state but also the current goal and gets the reward . The Q-function now depends not only on a state-action pair but also on a goal . Schaul et al., 2015a () show that in this setup it is possible to train an approximator to the Q-function using direct bootstrapping from the Bellman equation (just like in case of DQN) and that a greedy policy derived from it can generalize to previously unseen state-action pairs. The extension of this approach to DDPG is straightforward.
通用价值函数逼近器(UVFA)(Schaul et al., 2015a)是 DQN 在可能有多个目标时的扩展。令 为可能目标空间。每个目标 对应某个奖励函数 。每个回合从某分布 采样状态—目标对。目标在整个回合内固定。每个时间步智能体输入不仅是当前状态还有当前目标 ,并得到奖励 。Q 函数现在不仅依赖状态—动作对,还依赖目标:。Schaul et al. (2015a) 表明,在此设定下可直接从 Bellman 方程自举训练 Q 函数逼近器(与 DQN 类似),且由其导出的贪心策略可泛化到先前未见的状态—动作对。将该思路扩展到 DDPG 是直接的。
3 Hindsight Experience Replay
3 事后经验回放
3.1 A motivating example
3.1 一个启发性例子
Consider a bit-flipping environment with the state space and the action space for some integer in which executing the -th action flips the -th bit of the state. For every episode we sample uniformly an initial state as well as a target state and the policy gets a reward of as long as it is not in the target state, i.e. .
考虑比特翻转环境:状态空间 ,动作空间 ( 为某整数),执行第 个动作会翻转状态的第 位。每个回合均匀采样初始状态与目标状态;只要不在目标状态,策略就得到奖励 ,即 。
Figure 1: Bit-flipping experiment.
图 1:比特翻转实验。
Standard RL algorithms are bound to fail in this environment for because they will never experience any reward other than . Notice that using techniques for improving exploration (e.g. VIME (Houthooft et al.,, 2016), count-based exploration (Ostrovski et al.,, 2017) or bootstrapped DQN (Osband et al.,, 2016)) does not help here because the real problem is not in lack of diversity of states being visited, rather it is simply impractical to explore such a large state space. The standard solution to this problem would be to use a shaped reward function which is more informative and guides the agent towards the goal, e.g. . While using a shaped reward solves the problem in our toy environment, it may be difficult to apply to more complicated problems. We investigate the results of reward shaping experimentally in Sec. 4.4.
在该环境中,对 ,标准 RL 算法注定失败,因为它们永远遇不到除 以外的奖励。注意,用于改善探索的技术(如 VIME(Houthooft et al., 2016)、基于计数的探索(Ostrovski et al., 2017)或 bootstrapped DQN(Osband et al., 2016))在此并无帮助,因为真正的问题 并非 访问状态缺乏多样性,而是如此大的状态空间根本不切实际去穷尽探索。该问题的标准解法是使用信息更丰富、能引导智能体朝目标前进的塑形奖励,例如 。塑形奖励能解决我们的玩具环境,但可能难以用于更复杂问题。我们在第 4.4 节实验考察奖励塑形的结果。
Instead of shaping the reward we propose a different solution which does not require any domain knowledge. Consider an episode with a state sequence and a goal which implies that the agent received a reward of at every timestep. The pivotal idea behind our approach is to re-examine this trajectory with a different goal — while this trajectory may not help us learn how to achieve the state , it definitely tells us something about how to achieve the state . This information can be harvested by using an off-policy RL algorithm and experience replay where we replace in the replay buffer by . In addition we can still replay with the original goal left intact in the replay buffer. With this modification at least half of the replayed trajectories contain rewards different from and learning becomes much simpler. Fig. 1 compares the final performance of DQN with and without this additional replay technique which we call Hindsight Experience Replay (HER). DQN without HER can only solve the task for while DQN with HER easily solves the task for up to . See Appendix A for the details of the experimental setup. Note that this approach combined with powerful function approximators (e.g., deep neural networks) allows the agent to learn how to achieve the goal even if it has never observed it during training.
我们不塑形奖励,而提出一种不需任何领域知识的不同解法。考虑状态序列为 、目标 的回合,这意味着智能体每步都收到 。我们方法的核心思想是用不同目标重新审视这条轨迹——尽管它可能无助于学习如何达成状态 ,但它确实告诉我们如何达成状态 。信息可通过离策略 RL 算法与经验回放收获:在回放缓冲中把 替换为 。此外仍可用原目标 原样回放。经此修改,至少一半回放轨迹含有异于 的奖励,学习变得容易得多。图 1 比较了有无这项额外回放技术——我们称之为 事后经验回放(HER)——时 DQN 的最终表现。无 HER 的 DQN 只能在 时解题,有 HER 的 DQN 轻松解到 达 50。实验设置细节见附录 A。注意,该方法与强力函数逼近器(如深度神经网络)结合时,即使训练中从未观察到目标 ,智能体也能学会如何达成它。
We more formally describe our approach in the following sections.
后续各节更形式地描述我们的方法。
3.2 Multi-goal RL
3.2 多目标 RL
We are interested in training agents which learn to achieve multiple different goals. We follow the approach from Universal Value Function Approximators (Schaul et al., 2015a, ), i.e. we train policies and value functions which take as input not only a state but also a goal . Moreover, we show that training an agent to perform multiple tasks can be easier than training it to perform only one task (see Sec. 4.3 for details) and therefore our approach may be applicable even if there is only one task we would like the agent to perform (a similar situation was recently observed by Pinto and Gupta, (2016)).
我们关心训练能达成多个不同目标的智能体。我们沿用 通用价值函数逼近器(Schaul et al., 2015a)的思路,即训练以状态 与目标 为输入的策略与价值函数。此外我们表明,训练智能体执行多项任务可以比只训一项更容易(细节见第 4.3 节),因此即便我们只关心一项任务,该方法也可能适用(Pinto and Gupta (2016) 最近也观察到类似情形)。
We assume that every goal corresponds to some predicate and that the agent’s goal is to achieve any state that satisfies . In the case when we want to exactly specify the desired state of the system we may use and . The goals can also specify only some properties of the state, e.g. suppose that and we want to be able to achieve an arbitrary state with the given value of coordinate. In this case and .
我们假定每个目标 对应某个谓词 ,智能体目标是达成任意满足 的状态 。当我们想精确指定系统期望状态时,可用 且 。目标也可只指定状态的某些性质,例如设 ,我们希望能达成 坐标给定的任意状态。此时 ,。
Moreover, we assume that given a state we can easily find a goal which is satisfied in this state. More formally, we assume that there is given a mapping s.t. . Notice that this assumption is not very restrictive and can usually be satisfied. In the case where each goal corresponds to a state we want to achieve, i.e. and , the mapping is just an identity. For the case of 2-dimensional state and 1-dimensional goals from the previous paragraph this mapping is also very simple .
此外假定给定状态 ,我们能容易找到在该状态下被满足的目标 。更形式地,假定存在映射 使得 。注意该假定并不很苛刻,通常可以满足。当每个目标对应想达成的状态,即 且 时,映射 就是恒等。对上一段二维状态、一维目标的情形,该映射也很简单:。
A universal policy can be trained using an arbitrary RL algorithm by sampling goals and initial states from some distributions, running the agent for some number of timesteps and giving it a negative reward at every timestep when the goal is not achieved, i.e. . This does not however work very well in practice because this reward function is sparse and not very informative.
可通过任意 RL 算法训练通用策略:从某些分布采样目标与初始状态,运行智能体若干时间步,并在未达成目标的每步给负奖励,即 。但这在实践中效果不佳,因为该奖励函数稀疏且信息量不大。
In order to solve this problem we introduce the technique of Hindsight Experience Replay which is the crux of our approach.
为解决该问题,我们引入作为方法核心的事后经验回放技术。
3.3 Algorithm
3.3 算法
The idea behind Hindsight Experience Replay (HER) is very simple: after experiencing some episode we store in the replay buffer every transition not only with the original goal used for this episode but also with a subset of other goals. Notice that the goal being pursued influences the agent’s actions but not the environment dynamics and therefore we can replay each trajectory with an arbitrary goal assuming that we use an off-policy RL algorithm like DQN (Mnih et al.,, 2015), DDPG (Lillicrap et al.,, 2015), NAF (Gu et al.,, 2016) or SDQN (Metz et al.,, 2017).
事后经验回放(HER)背后的想法很简单:在经历某回合 后,我们把每个转移 存入回放缓冲时,不仅使用该回合原先的目标,还使用其他目标的一个子集。注意,所追求的目标影响智能体动作但不影响环境动力学,因此若使用 DQN(Mnih et al., 2015)、DDPG(Lillicrap et al., 2015)、NAF(Gu et al., 2016)或 SDQN(Metz et al., 2017)等离策略 RL 算法,就可用任意目标回放每条轨迹。
One choice which has to be made in order to use HER is the set of additional goals used for replay. In the simplest version of our algorithm we replay each trajectory with the goal , i.e. the goal which is achieved in the final state of the episode. We experimentally compare different types and quantities of additional goals for replay in Sec. 4.5. In all cases we also replay each trajectory with the original goal pursued in the episode. See Alg. 1 for a more formal description of the algorithm.
使用 HER 时必须做出的一个选择,是用于回放的额外目标集合。在算法最简版本中,我们用目标 ——即回合最终状态所达成的目标——回放每条轨迹。第 4.5 节实验比较不同类型与数量的额外回放目标。所有情形下我们也用回合中原先追求的目标回放每条轨迹。更形式的描述见算法 1。
Given: • an off-policy RL algorithm , e.g. DQN, DDPG, NAF, SDQN • a strategy for sampling goals for replay, e.g. • a reward function . e.g.
Initialize e.g. initialize neural networks
Initialize replay buffer
for episode = , do
Sample a goal and an initial state .
for do
Sample an action using the behavioral policy from :
denotes concatenation
Execute the action and observe a new state
end for
for do
Store the transition in standard experience replay
Sample a set of additional goals for replay
for do
Store the transition in HER
end for
end for
for do
Sample a minibatch from the replay buffer
Perform one step of optimization using and minibatch
end for
end for
Algorithm 1 Hindsight Experience Replay (HER)
给定: • 离策略 RL 算法 , 例如 DQN、DDPG、NAF、SDQN • 为回放采样目标的策略 , 例如 • 奖励函数 。 例如
初始化 例如初始化神经网络
初始化回放缓冲
for episode = , do
采样目标 与初始状态 。
for do
用 的行为策略采样动作 :
表示拼接
执行动作 并观测新状态
end for
for do
把转移 存入 标准经验回放
采样额外回放目标集合
for do
把转移 存入 HER
end for
end for
for do
从回放缓冲 采样小批量
用 与小批量 执行一步优化
end for
end for
算法 1 事后经验回放(HER)
HER may be seen as a form of implicit curriculum as the goals used for replay naturally shift from ones which are simple to achieve even by a random agent to more difficult ones. However, in contrast to explicit curriculum, HER does not require having any control over the distribution of initial environment states. Not only does HER learn with extremely sparse rewards, in our experiments it also performs better with sparse rewards than with shaped ones (See Sec. 4.4). These results are indicative of the practical challenges with reward shaping, and that shaped rewards would often constitute a compromise on the metric we truly care about (such as binary success/failure).
HER 可看作一种隐式课程:用于回放的目标自然地从随机智能体也能轻易达成的目标,转向更困难的目标。但与显式课程不同,HER 不要求能控制初始环境状态的分布。HER 不仅能在极度稀疏奖励下学习,在我们的实验中它用稀疏奖励甚至优于塑形奖励(见第 4.4 节)。这些结果提示奖励塑形的实践难题:塑形奖励往往是对我们真正关心的指标(如二值成功/失败)的折中。
4 Experiments
4 实验
The video presenting our experiments is available at https://goo.gl/SMrQnI.
展示实验的视频见 https://goo.gl/SMrQnI。
This section is organized as follows. In Sec. 4.1 we introduce multi-goal RL environments we use for the experiments as well as our training procedure. In Sec. 4.2 we compare the performance of DDPG with and without HER. In Sec. 4.3 we check if HER improves performance in the single-goal setup. In Sec. 4.4 we analyze the effects of using shaped reward functions. In Sec. 4.5 we compare different strategies for sampling additional goals for HER. In Sec. 4.6 we show the results of the experiments on the physical robot.
本节组织如下。第 4.1 节介绍实验所用的多目标 RL 环境与训练流程。第 4.2 节比较有无 HER 的 DDPG 表现。第 4.3 节检查 HER 在单目标设定下是否仍提升表现。第 4.4 节分析使用塑形奖励函数的效应。第 4.5 节比较为 HER 采样额外目标的不同策略。第 4.6 节给出真实机器人上的实验结果。
4.1 Environments
4.1 环境
The are no standard environments for multi-goal RL and therefore we created our own environments. We decided to use manipulation environments based on an existing hardware robot to ensure that the challenges we face correspond as closely as possible to the real world. In all experiments we use a -DOF Fetch Robotics arm which has a two-fingered parallel gripper. The robot is simulated using the MuJoCo (Todorov et al.,, 2012) physics engine. The whole training procedure is performed in the simulation but we show in Sec. 4.6 that the trained policies perform well on the physical robot without any finetuning.
多目标 RL 尚无标准环境,因此我们自建。我们决定基于现有硬件机器人使用操作环境,以确保面对的挑战尽量贴近真实世界。所有实验使用带两指平行夹爪的 7 自由度 Fetch Robotics 机械臂。机器人用 MuJoCo(Todorov et al., 2012)物理引擎仿真。整个训练在仿真中进行,但我们在第 4.6 节表明,训练好的策略无需微调即可在真实机器人上表现良好。
Policies are represented as Multi-Layer Perceptrons (MLPs) with Rectified Linear Unit (ReLU) activation functions. Training is performed using the DDPG algorithm (Lillicrap et al.,, 2015) with Adam (Kingma and Ba,, 2014) as the optimizer. For improved efficiency we use workers which average the parameters after every update. See Appendix A for more details and the values of all hyperparameters.
策略表示为带修正线性单元(ReLU)激活的多层感知机(MLP)。训练使用 DDPG 算法(Lillicrap et al., 2015),优化器为 Adam(Kingma and Ba, 2014)。为提升效率,我们使用 8 个 worker,每次更新后平均参数。更多细节与全部超参见附录 A。
We consider different tasks:
我们考虑 3 项不同任务:
- Pushing. In this task a box is placed on a table in front of the robot and the task is to move it to the target location on the table. The robot fingers are locked to prevent grasping. The learned behaviour is a mixture of pushing and rolling.
- Sliding. In this task a puck is placed on a long slippery table and the target position is outside of the robot’s reach so that it has to hit the puck with such a force that it slides and then stops in the appropriate place due to friction.
- Pick-and-place. This task is similar to pushing but the target position is in the air and the fingers are not locked. To make exploration in this task easier we recorded a single state in which the box is grasped and start half of the training episodes from this state.
- 推动。桌上机器人前方放置一盒,任务是把它移到桌上目标位置。机器人手指锁定以防抓取。学到的行为是推动与滚动的混合。
- 滑动。长而光滑的桌上放置冰球,目标位置在机器人触及范围之外,因此必须以合适力度击球,使其滑动后靠摩擦停在适当位置。
- 抓取放置。类似推动,但目标位置在空中,且手指不锁定。为使该任务探索更容易,我们记录了盒子被抓住的 单个 状态,并用半数训练回合从该状态起步。
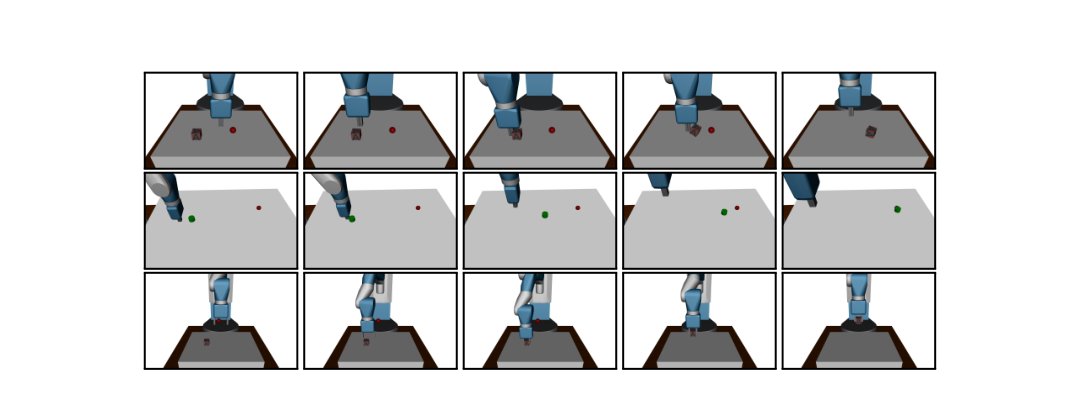
Figure 2: Different tasks: pushing (top row), sliding (middle row) and pick-and-place (bottom row). The red ball denotes the goal position.
图 2:不同任务:推动(上行)、滑动(中行)与 抓取放置(下行)。红球表示目标位置。
States:
The state of the system is represented in the MuJoCo physics engine and consists of angles and velocities of all robot joints as well as positions, rotations and velocities (linear and angular) of all objects.
状态:
系统状态在 MuJoCo 物理引擎中表示,包含所有机器人关节的角度与速度,以及所有物体的位置、旋转与速度(线速度与角速度)。
Goals:
Goals describe the desired position of the object (a box or a puck depending on the task) with some fixed tolerance of i.e. and , where is the position of the object in the state . The mapping from states to goals used in HER is simply .
目标:
目标描述物体(按任务为盒子或冰球)的期望位置,带固定容差 ,即 ,,其中 是状态 中物体的位置。HER 中使用的从状态到目标的映射即为 。
Rewards:
Unless stated otherwise we use binary and sparse rewards where if the state after the execution of the action in the state . We compare sparse and shaped reward functions in Sec. 4.4.
奖励:
除非另有说明,我们使用二值稀疏奖励 ,其中 是在状态 执行动作 之后 的状态。第 4.4 节比较稀疏与塑形奖励函数。
State-goal distributions:
For all tasks the initial position of the gripper is fixed, while the initial position of the object and the target are randomized. See Appendix A for details.
状态—目标分布:
对所有任务,夹爪初始位置固定,而物体初始位置与目标随机化。细节见附录 A。
Observations:
In this paragraph relative means relative to the current gripper position. The policy is given as input the absolute position of the gripper, the relative position of the object and the target[^3], as well as the distance between the fingers. The Q-function is additionally given the linear velocity of the gripper and fingers as well as relative linear and angular velocity of the object. We decided to restrict the input to the policy in order to make deployment on the physical robot easier.
观测:
本段中 相对 指相对 当前 夹爪位置。策略输入为夹爪绝对位置、物体与目标的相对位置[^3],以及手指间距。Q 函数额外获得夹爪与手指的线速度,以及物体的相对线速度与角速度。我们限制策略输入,以便更易在真实机器人上部署。
Actions:
None of the problems we consider require gripper rotation and therefore we keep it fixed. Action space is -dimensional. Three dimensions specify the desired relative gripper position at the next timestep. We use MuJoCo constraints to move the gripper towards the desired position but Jacobian-based control could be used instead[^4]. The last dimension specify the desired distance between the fingers which are position controlled.
动作:
所考虑问题都不需要夹爪旋转,因此保持固定。动作空间为 4 维。三维指定下一时间步期望的相对夹爪位置。我们用 MuJoCo 约束把夹爪移向期望位置,也可用基于雅可比的控制替代。[^4] 最后一维指定两指之间的期望距离,手指为位置控制。
Strategy for sampling goals for replay:
Unless stated otherwise HER uses replay with the goal corresponding to the final state in each episode, i.e. . We compare different strategies for choosing which goals to replay with in Sec. 4.5.
为回放采样目标的策略 :
除非另有说明,HER 用对应每个回合最终状态的目标回放,即 。第 4.5 节比较选择回放目标的不同策略。
4.2 Does HER improve performance?
4.2 HER 是否提升表现?
In order to verify if HER improves performance we evaluate DDPG with and without HER on all tasks. Moreover, we compare against DDPG with count-based exploration[^5] (Strehl and Littman,, 2005; Kolter and Ng,, 2009; Tang et al.,, 2016; Bellemare et al.,, 2016; Ostrovski et al.,, 2017). For HER we store each transition in the replay buffer twice: once with the goal used for the generation of the episode and once with the goal corresponding to the final state from the episode (we call this strategy final). In Sec. 4.5 we perform ablation studies of different strategies for choosing goals for replay, here we include the best version from Sec. 4.5 in the plot for comparison.
为验证 HER 是否提升表现,我们在全部 3 项任务上评估有无 HER 的 DDPG。此外与带基于计数的探索[^5] 的 DDPG 比较(Strehl and Littman, 2005;Kolter and Ng, 2009;Tang et al., 2016;Bellemare et al., 2016;Ostrovski et al., 2017)。对 HER,每个转移在回放缓冲中存两次:一次用生成该回合时的目标,一次用对应回合最终状态的目标(称该策略为 final)。第 4.5 节对不同选择回放目标的策略 做消融;此处把第 4.5 节最佳版本画入图中以供比较。
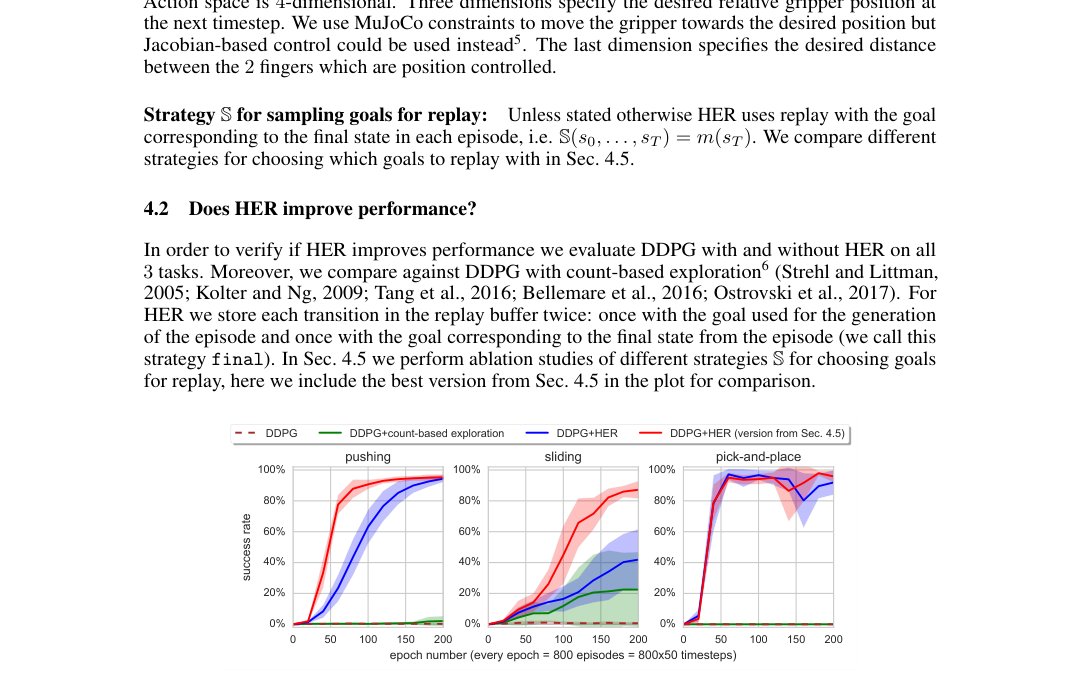
Figure 3: Learning curves for multi-goal setup. An episode is considered successful if the distance between the object and the goal at the end of the episode is less than 7cm for pushing and pick-and-place and less than 20cm for sliding. The results are averaged across random seeds and shaded areas represent one standard deviation. The red curves correspond to the future strategy with from Sec. 4.5 while the blue one corresponds to the final strategy.
图 3:多目标设定下的学习曲线。若回合结束时物体与目标距离小于 7cm(推动与抓取放置)或小于 20cm(滑动),则该回合视为成功。结果对 5 个随机种子平均,阴影区域表示一个标准差。红线对应第 4.5 节 的 future 策略,蓝线对应 final 策略。
From Fig. 3 it is clear that DDPG without HER is unable to solve any of the tasks[^6] and DDPG with count-based exploration is only able to make some progress on the sliding task. On the other hand, DDPG with HER solves all tasks almost perfectly. It confirms that HER is a crucial element which makes learning from sparse, binary rewards possible.
由图 3 清楚可见:无 HER 的 DDPG 无法解决任何任务[^6],带基于计数探索的 DDPG 仅在滑动任务上有些进展。另一方面,带 HER 的 DDPG 几乎完美解决全部任务。这证实 HER 是使从稀疏二值奖励学习成为可能的关键要素。
4.3 Does HER improve performance even if there is only one goal we care about?
4.3 即便只关心一个目标,HER 是否仍提升表现?
In this section we evaluate whether HER improves performance in the case where there is only one goal we care about. To this end, we repeat the experiments from the previous section but the goal state is identical in all episodes.
本节评估当只关心一个目标时 HER 是否仍提升表现。为此我们重复上节实验,但所有回合的目标状态相同。
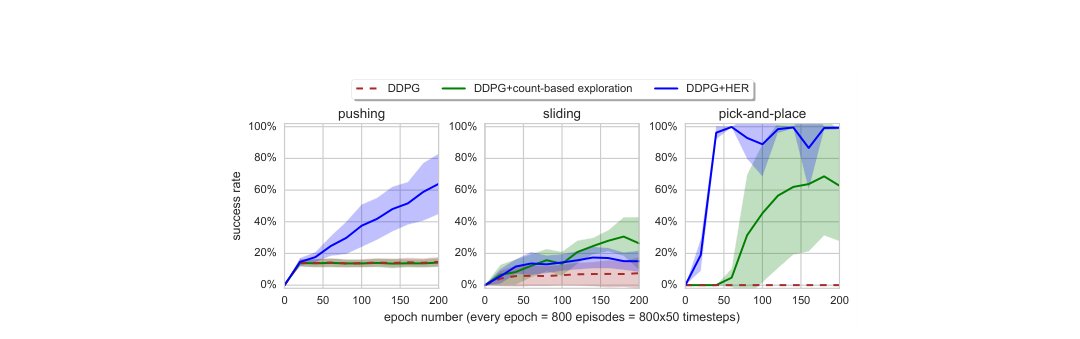
Figure 4: Learning curves for the single-goal case.
图 4:单目标情形下的学习曲线。
From Fig. 4 it is clear that DDPG+HER performs much better than pure DDPG even if the goal state is identical in all episodes. More importantly, comparing Fig. 3 and Fig. 4 we can also notice that HER learns faster if training episodes contain multiple goals, so in practice it is advisable to train on multiple goals even if we care only about one of them.
由图 4 清楚可见:即便所有回合目标状态相同,DDPG+HER 仍远好于纯 DDPG。更重要的是,比较图 3 与图 4 还可注意到:训练回合含多个目标时 HER 学得更快,因此实践中即便我们只关心其中一个目标,也宜在多目标上训练。
4.4 How does HER interact with reward shaping?
4.4 HER 如何与奖励塑形交互?
So far we only considered binary rewards of the form . In this section we check how the performance of DDPG with and without HER changes if we replace this reward with one which is shaped. We considered reward functions of the form , where is the state of the environment after the execution of the action in the state and are hyperparameters.
此前我们只考虑形如 的二值奖励。本节检查若将其替换为塑形奖励,有无 HER 的 DDPG 表现如何变化。我们考虑形如 的奖励函数,其中 是在状态 执行动作 后的环境状态,、 为超参。
Fig. 5 shows the results. Surprisingly neither DDPG, nor DDPG+HER was able to successfully solve any of the tasks with any of these reward functions[^7].Our results are consistent with the fact that successful applications of RL to difficult manipulation tasks which does not use demonstrations usually have more complicated reward functions than the ones we tried (e.g. Popov et al., (2017)).
图 5 给出结果。出人意料的是,无论 DDPG 还是 DDPG+HER,在这些奖励函数的任意一种下都未能成功解决任何任务。[^7] 我们的结果与如下事实一致:不使用演示、却成功应用于困难操作任务的 RL,通常有比我们尝试的更复杂的奖励函数(如 Popov et al., 2017)。
The following two reasons can cause shaped rewards to perform so poorly: (1) There is a huge discrepancy between what we optimize (i.e. a shaped reward function) and the success condition (i.e.: is the object within some radius from the goal at the end of the episode); (2) Shaped rewards penalize for inappropriate behaviour (e.g. moving the box in a wrong direction) which may hinder exploration. It can cause the agent to learn not to touch the box at all if it can not manipulate it precisely and we noticed such behaviour in some of our experiments.
塑形奖励表现如此之差可能有两个原因:(1) 我们优化的对象(塑形奖励函数)与成功条件(回合结束时物体是否在目标某半径内)之间存在巨大落差;(2) 塑形奖励惩罚不当行为(如把盒子移错方向),可能阻碍探索。若智能体无法精确操作盒子,可能学会根本不碰它;我们在部分实验中观察到此类行为。
Our results suggest that domain-agnostic reward shaping does not work well (at least in the simple forms we have tried). Of course for every problem there exists a reward which makes it easy (Ng et al.,, 1999) but designing such shaped rewards requires a lot of domain knowledge and may in some cases not be much easier than directly scripting the policy. This strengthens our belief that learning from sparse, binary rewards is an important problem.
我们的结果表明,与领域无关的奖励塑形效果不佳(至少在我们尝试的简单形式下)。当然对每个问题都存在使它变容易的奖励(Ng et al., 1999),但设计此类塑形奖励需要大量领域知识,有时并不比直接脚本化策略容易多少。这加强了我们的信念:从稀疏二值奖励学习是重要问题。
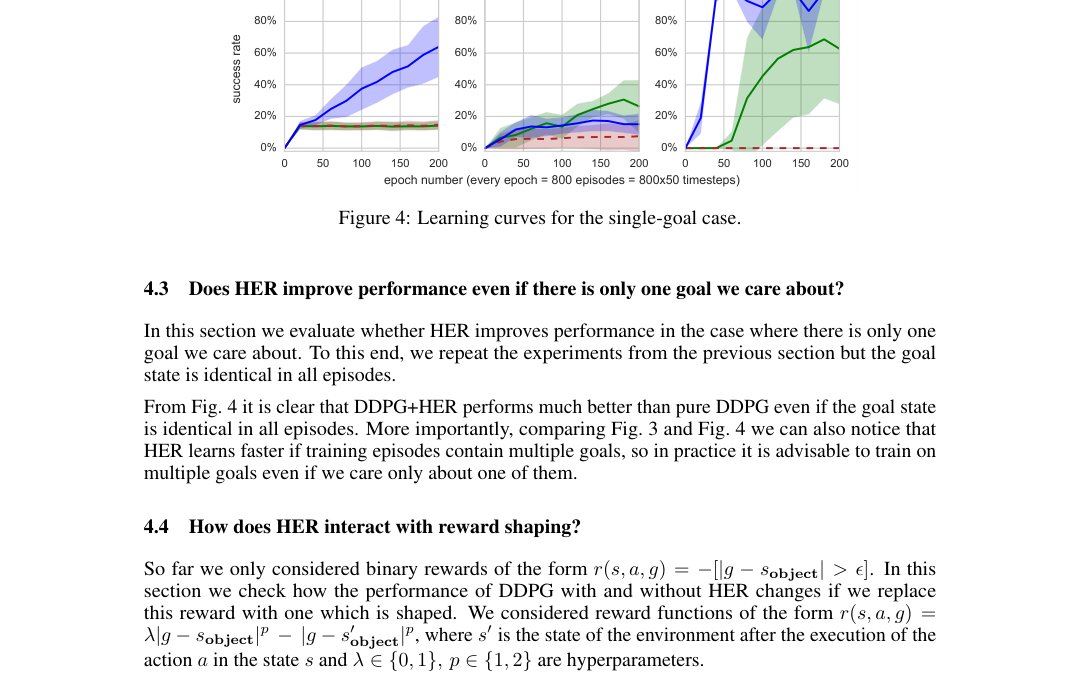
Figure 5: Learning curves for the shaped reward (it performed best among the shaped rewards we have tried). Both algorithms fail on all tasks.
图 5:塑形奖励 下的学习曲线(在我们尝试的塑形奖励中表现最好)。两种算法在全部任务上都失败。
4.5 How many goals should we replay each trajectory with and how to choose them?
4.5 每条轨迹该用多少目标回放、如何选择?
In this section we experimentally evaluate different strategies (i.e. in Alg. 1) for choosing goals to use with HER. So far the only additional goals we used for replay were the ones corresponding to the final state of the environment and we will call this strategy final. Apart from it we consider the following strategies:
本节实验评估为 HER 选择目标的不同策略(即算法 1 中的 )。此前用于回放的唯一额外目标是对应环境最终状态的目标,我们称该策略为 final。除此之外我们考虑如下策略:
- • future — replay with random states which come from the same episode as the transition being replayed and were observed after it,
- • episode — replay with random states coming from the same episode as the transition being replayed,
- • random — replay with random states encountered so far in the whole training procedure.
- • future — 用与正被回放的转移来自同一回合、且在其 之后 观测到的 个随机状态回放,
- • episode — 用与正被回放的转移来自同一回合的 个随机状态回放,
- • random — 用整个训练过程中迄今遇到的 个随机状态回放。
All of these strategies have a hyperparameter which controls the ratio of HER data to data coming from normal experience replay in the replay buffer.
这些策略都有超参 ,控制回放缓冲中 HER 数据与普通经验回放数据的比例。
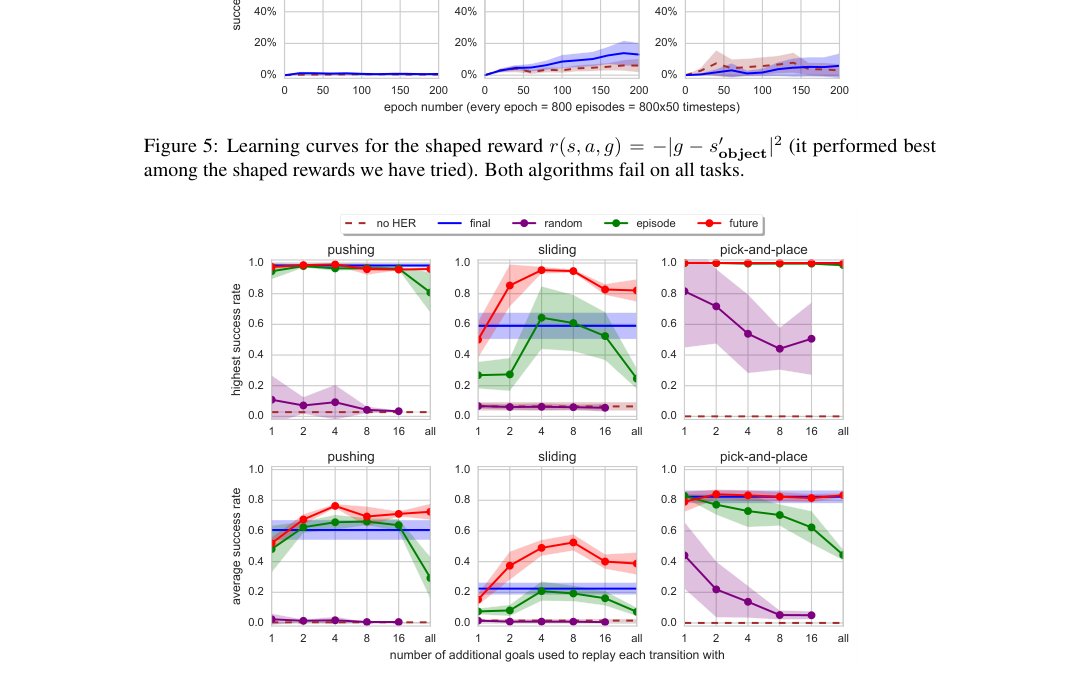
Figure 6: Ablation study of different strategies for choosing additional goals for replay. The top row shows the highest (across the training epochs) test performance and the bottom row shows the average test performance across all training epochs. On the right top plot the curves for final, episode and future coincide as all these strategies achieve perfect performance on this task.
图 6:选择额外回放目标的不同策略的消融。上行给出训练各轮中最高测试表现,下行给出全部训练轮次的平均测试表现。右上图中 final、episode 与 future 曲线重合,因为这些策略在该任务上都达到完美表现。
The plots comparing different strategies and different values of can be found in Fig. 6. We can see from the plots that all strategies apart from random solve pushing and pick-and-place almost perfectly regardless of the values of . In all cases future with equal or performs best and it is the only strategy which is able to solve the sliding task almost perfectly. The learning curves for future with can be found in Fig. 3. It confirms that the the most valuable goals for replay are the ones which are going to be achieved in the near future. Notice that increasing the values of above degrades performance because the fraction of normal replay data in the buffer becomes very low.
比较不同策略与不同 的图见 图 6。可见除 random 外,所有策略无论 取值如何几乎都能完美解决推动与抓取放置。所有情形下 为 4 或 8 的 future 表现最好,且是唯一几乎完美解决滑动任务的策略。 的 future 学习曲线见图 3。这证实对回放最有价值的目标,是即将在不久将来达成的那些。注意 增至超过 8 会损害表现,因为缓冲中普通回放数据占比变得很低。
4.6 Deployment on a physical robot
4.6 在真实机器人上部署
We took a policy for the pick-and-place task trained in the simulator (version with the future strategy and from Sec. 4.5) and deployed it on a physical fetch robot without any finetuning. The box position was predicted using a separately trained CNN using raw fetch head camera images. See Appendix B for details.
我们取仿真中训练的抓取放置策略(第 4.5 节 future 策略且 的版本),不经任何微调部署到真实 Fetch 机器人。盒子位置由单独训练的 CNN 用 Fetch 头部相机原始图像预测。细节见附录 B。
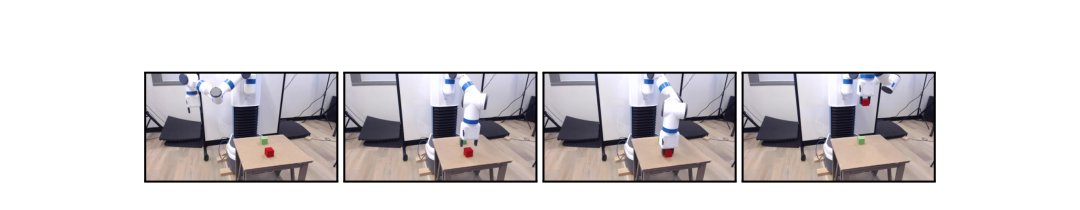
Figure 7: The pick-and-place policy deployed on the physical robot.
图 7:部署到真实机器人上的抓取放置策略。
Initially the policy succeeded in out of trials. It was not robust to small errors in the box position estimation because it was trained on perfect state coming from the simulation. After retraining the policy with gaussian noise (std=1cm) added to observations[^8] the success rate increased to . The video showing some of the trials is available at https://goo.gl/SMrQnI.
起初策略在 5 次试验中成功 2 次。它对盒子位置估计的小误差不够稳健,因为训练时用的是仿真给出的完美状态。在观测上加入高斯噪声(标准差=1cm)后重新训练策略[^8],成功率升至 5/5。部分试验视频见 https://goo.gl/SMrQnI。
5 Related work
5 相关工作
The technique of experience replay has been introduced in Lin, (1992) and became very popular after it was used in the DQN agent playing Atari (Mnih et al.,, 2015). Prioritized experience replay (Schaul et al., 2015b, ) is an improvement to experience replay which prioritizes transitions in the replay buffer in order to speed up training. It it orthogonal to our work and both approaches can be easily combined.
经验回放技术由 Lin (1992) 引入,并在 DQN 智能体玩 Atari(Mnih et al., 2015)后广为流行。优先级 经验回放(Schaul et al., 2015b)是对经验回放的改进,通过对回放缓冲中的转移排序以加速训练。它与我们的工作正交,两者可轻易结合。
Learning simultaneously policies for multiple tasks have been heavily explored in the context of policy search, e.g. Caruana, (1998); Da Silva et al., (2012); Kober et al., (2012); Devin et al., (2016); Pinto and Gupta, (2016). Learning off-policy value functions for multiple tasks was investigated by Foster and Dayan, (2002) and Sutton et al., (2011). Our work is most heavily based on Schaul et al., 2015a () who considers training a single neural network approximating multiple value functions. Learning simultaneously to perform multiple tasks has been also investigated for a long time in the context of Hierarchical Reinforcement Learning, e.g. Bakker and Schmidhuber, (2004); Vezhnevets et al., (2017).
在策略搜索语境下,同时为多项任务学习策略已被大量探索,例如 Caruana (1998);Da Silva et al. (2012);Kober et al. (2012);Devin et al. (2016);Pinto and Gupta (2016)。为多项任务学习离策略价值函数由 Foster and Dayan (2002) 与 Sutton et al. (2011) 研究。我们的工作最主要基于 Schaul et al. (2015a),他们考虑训练逼近多个价值函数的 单个 神经网络。在分层强化学习语境下,同时学习执行多项任务也已被长期研究,例如 Bakker and Schmidhuber (2004);Vezhnevets et al. (2017)。
Our approach may be seen as a form of implicit curriculum learning (Elman,, 1993; Bengio et al.,, 2009). While curriculum is now often used for training neural networks (e.g. Zaremba and Sutskever, (2014); Graves et al., (2016)), the curriculum is almost always hand-crafted. The problem of automatic curriculum generation has been approached only recently. Graves et al., (2017) consider a setup where there is a fixed discrete set of tasks and empirically evaluate different strategies for automatic curriculum generation in this settings. Another approach investigated by Sukhbaatar et al., (2017) and Held et al., (2017) uses self-play between the policy and a task-setter in order to automatically generate goal states which are on the border of what the current policy can achieve. Our approach is orthogonal to these techniques and can be combined with them.
我们的方法可看作一种隐式课程学习(Elman, 1993;Bengio et al., 2009)。虽然课程现常用于训练神经网络(如 Zaremba and Sutskever, 2014;Graves et al., 2016),但课程几乎总是手工制定。自动生成课程的问题直到最近才被触及。Graves et al. (2017) 考虑存在固定离散任务集的设定,并经验评估该设定下自动生成课程的不同策略。Sukhbaatar et al. (2017) 与 Held et al. (2017) 研究的另一思路,用策略与任务设定者之间的自对弈,自动生成处于当前策略能力边界的目标状态。我们的方法与这些技术正交,可以结合。
6 Conclusions
6 结论
We introduced a novel technique called Hindsight Experience Replay which makes possible applying RL algorithms to problems with sparse and binary rewards. Our technique can be combined with an arbitrary off-policy RL algorithm and we experimentally demonstrated that with DQN and DDPG.
我们提出名为事后经验回放的新技术,使 RL 算法可应用于稀疏二值奖励问题。该技术可与任意离策略 RL 算法结合,我们用 DQN 与 DDPG 实验验证。
We showed that HER allows training policies which push, slide and pick-and-place objects with a robotic arm to the specified positions while the vanilla RL algorithm fails to solve these tasks. We also showed that the policy for the pick-and-place task performs well on the physical robot without any finetuning. As far as we know, it is the first time so complicated behaviours were learned using only sparse, binary rewards.
我们表明 HER 能训练出用机械臂把物体推动、滑动与抓取放置到指定位置的策略,而原版 RL 算法无法解决这些任务。我们还表明抓取放置策略无需微调即可在真实机器人上表现良好。据我们所知,这是首次仅用稀疏二值奖励就学到如此复杂的行为。
Acknowledgments
We would like to thank Ankur Handa, Jonathan Ho, John Schulman, Matthias Plappert, Tim Salimans, and Vikash Kumar for providing feedback on the previous versions of this manuscript. We would also like to thank Rein Houthooft and the whole OpenAI team for fruitful discussions.
致谢
感谢 Ankur Handa、Jonathan Ho、John Schulman、Matthias Plappert、Tim Salimans 与 Vikash Kumar 对本文先前版本给出反馈。也感谢 Rein Houthooft 与整个 OpenAI 团队的富有成效的讨论。
References
参考文献
Abadi et al., (2016) Abadi, M., Agarwal, A., Barham, P., Brevdo, E., Chen, Z., Citro, C., Corrado, G. S., Davis, A., Dean, J., Devin, M., et al. (2016). Tensorflow: Large-scale machine learning on heterogeneous distributed systems. arXiv preprint arXiv:1603.04467 .
Bakker and Schmidhuber, (2004) Bakker, B. and Schmidhuber, J. (2004). Hierarchical reinforcement learning based on subgoal discovery and subpolicy specialization. In Proc. of the 8-th Conf. on Intelligent Autonomous Systems , pages 438–445.
Bellemare et al., (2016) Bellemare, M., Srinivasan, S., Ostrovski, G., Schaul, T., Saxton, D., and Munos, R. (2016). Unifying count-based exploration and intrinsic motivation. In Advances in Neural Information Processing Systems , pages 1471–1479.
Bengio et al., (2009) Bengio, Y., Louradour, J., Collobert, R., and Weston, J. (2009). Curriculum learning. In Proceedings of the 26th annual international conference on machine learning , pages 41–48. ACM.
Caruana, (1998) Caruana, R. (1998). Multitask learning. In Learning to learn , pages 95–133. Springer.
Chebotar et al., (2016) Chebotar, Y., Kalakrishnan, M., Yahya, A., Li, A., Schaal, S., and Levine, S. (2016). Path integral guided policy search. arXiv preprint arXiv:1610.00529 .
Da Silva et al., (2012) Da Silva, B., Konidaris, G., and Barto, A. (2012). Learning parameterized skills. arXiv preprint arXiv:1206.6398 .
Devin et al., (2016) Devin, C., Gupta, A., Darrell, T., Abbeel, P., and Levine, S. (2016). Learning modular neural network policies for multi-task and multi-robot transfer. arXiv preprint arXiv:1609.07088 .
Elman, (1993) Elman, J. L. (1993). Learning and development in neural networks: The importance of starting small. Cognition , 48(1):71–99.
Foster and Dayan, (2002) Foster, D. and Dayan, P. (2002). Structure in the space of value functions. Machine Learning , 49(2):325–346.
Graves et al., (2017) Graves, A., Bellemare, M. G., Menick, J., Munos, R., and Kavukcuoglu, K. (2017). Automated curriculum learning for neural networks. arXiv preprint arXiv:1704.03003 .
Graves et al., (2016) Graves, A., Wayne, G., Reynolds, M., Harley, T., Danihelka, I., Grabska-Barwińska, A., Colmenarejo, S. G., Grefenstette, E., Ramalho, T., Agapiou, J., et al. (2016). Hybrid computing using a neural network with dynamic external memory. Nature , 538(7626):471–476.
Gu et al., (2016) Gu, S., Lillicrap, T., Sutskever, I., and Levine, S. (2016). Continuous deep q-learning with model-based acceleration. arXiv preprint arXiv:1603.00748 .
Held et al., (2017) Held, D., Geng, X., Florensa, C., and Abbeel, P. (2017). Automatic goal generation for reinforcement learning agents. arXiv preprint arXiv:1705.06366 .
Houthooft et al., (2016) Houthooft, R., Chen, X., Duan, Y., Schulman, J., De Turck, F., and Abbeel, P. (2016). Vime: Variational information maximizing exploration. In Advances in Neural Information Processing Systems , pages 1109–1117.
Kingma and Ba, (2014) Kingma, D. and Ba, J. (2014). Adam: A method for stochastic optimization. arXiv preprint arXiv:1412.6980 .
Kober et al., (2012) Kober, J., Wilhelm, A., Oztop, E., and Peters, J. (2012). Reinforcement learning to adjust parametrized motor primitives to new situations. Autonomous Robots , 33(4):361–379.
Kolter and Ng, (2009) Kolter, J. Z. and Ng, A. Y. (2009). Near-bayesian exploration in polynomial time. In Proceedings of the 26th Annual International Conference on Machine Learning , pages 513–520. ACM.
Levine et al., (2015) Levine, S., Finn, C., Darrell, T., and Abbeel, P. (2015). End-to-end training of deep visuomotor policies. arXiv preprint arXiv:1504.00702 .
Lillicrap et al., (2015) Lillicrap, T. P., Hunt, J. J., Pritzel, A., Heess, N., Erez, T., Tassa, Y., Silver, D., and Wierstra, D. (2015). Continuous control with deep reinforcement learning. arXiv preprint arXiv:1509.02971 .
Lin, (1992) Lin, L.-J. (1992). Self-improving reactive agents based on reinforcement learning, planning and teaching. Machine learning , 8(3-4):293–321.
Metz et al., (2017) Metz, L., Ibarz, J., Jaitly, N., and Davidson, J. (2017). Discrete sequential prediction of continuous actions for deep rl. arXiv preprint arXiv:1705.05035 .
Mnih et al., (2015) Mnih, V., Kavukcuoglu, K., Silver, D., Rusu, A. A., Veness, J., Bellemare, M. G., Graves, A., Riedmiller, M., Fidjeland, A. K., Ostrovski, G., et al. (2015). Human-level control through deep reinforcement learning. Nature , 518(7540):529–533.
Ng et al., (2006) Ng, A., Coates, A., Diel, M., Ganapathi, V., Schulte, J., Tse, B., Berger, E., and Liang, E. (2006). Autonomous inverted helicopter flight via reinforcement learning. Experimental Robotics IX , pages 363–372.
Ng et al., (1999) Ng, A. Y., Harada, D., and Russell, S. (1999). Policy invariance under reward transformations: Theory and application to reward shaping. In ICML , volume 99, pages 278–287.
Osband et al., (2016) Osband, I., Blundell, C., Pritzel, A., and Van Roy, B. (2016). Deep exploration via bootstrapped dqn. In Advances In Neural Information Processing Systems , pages 4026–4034.
Ostrovski et al., (2017) Ostrovski, G., Bellemare, M. G., Oord, A. v. d., and Munos, R. (2017). Count-based exploration with neural density models. arXiv preprint arXiv:1703.01310 .
Peters and Schaal, (2008) Peters, J. and Schaal, S. (2008). Reinforcement learning of motor skills with policy gradients. Neural networks , 21(4):682–697.
Pinto and Gupta, (2016) Pinto, L. and Gupta, A. (2016). Learning to push by grasping: Using multiple tasks for effective learning. arXiv preprint arXiv:1609.09025 .
Polyak and Juditsky, (1992) Polyak, B. T. and Juditsky, A. B. (1992). Acceleration of stochastic approximation by averaging. SIAM Journal on Control and Optimization , 30(4):838–855.
Popov et al., (2017) Popov, I., Heess, N., Lillicrap, T., Hafner, R., Barth-Maron, G., Vecerik, M., Lampe, T., Tassa, Y., Erez, T., and Riedmiller, M. (2017). Data-efficient deep reinforcement learning for dexterous manipulation. arXiv preprint arXiv:1704.03073 .
(32) Schaul, T., Horgan, D., Gregor, K., and Silver, D. (2015a). Universal value function approximators. In Proceedings of the 32nd International Conference on Machine Learning (ICML-15) , pages 1312–1320.
(33) Schaul, T., Quan, J., Antonoglou, I., and Silver, D. (2015b). Prioritized experience replay. arXiv preprint arXiv:1511.05952 .
Silver et al., (2016) Silver, D., Huang, A., Maddison, C. J., Guez, A., Sifre, L., Van Den Driessche, G., Schrittwieser, J., Antonoglou, I., Panneershelvam, V., Lanctot, M., et al. (2016). Mastering the game of go with deep neural networks and tree search. Nature , 529(7587):484–489.
Strehl and Littman, (2005) Strehl, A. L. and Littman, M. L. (2005). A theoretical analysis of model-based interval estimation. In Proceedings of the 22nd international conference on Machine learning , pages 856–863. ACM.
Sukhbaatar et al., (2017) Sukhbaatar, S., Kostrikov, I., Szlam, A., and Fergus, R. (2017). Intrinsic motivation and automatic curricula via asymmetric self-play. arXiv preprint arXiv:1703.05407 .
Sutton et al., (2011) Sutton, R. S., Modayil, J., Delp, M., Degris, T., Pilarski, P. M., White, A., and Precup, D. (2011). Horde: A scalable real-time architecture for learning knowledge from unsupervised sensorimotor interaction. In The 10th International Conference on Autonomous Agents and Multiagent Systems-Volume 2 , pages 761–768. International Foundation for Autonomous Agents and Multiagent Systems.
Tang et al., (2016) Tang, H., Houthooft, R., Foote, D., Stooke, A., Chen, X., Duan, Y., Schulman, J., De Turck, F., and Abbeel, P. (2016). # exploration: A study of count-based exploration for deep reinforcement learning. arXiv preprint arXiv:1611.04717 .
Tobin et al., (2017) Tobin, J., Fong, R., Ray, A., Schneider, J., Zaremba, W., and Abbeel, P. (2017). Domain randomization for transferring deep neural networks from simulation to the real world. arXiv preprint arXiv:1703.06907 .
Todorov et al., (2012) Todorov, E., Erez, T., and Tassa, Y. (2012). Mujoco: A physics engine for model-based control. In Intelligent Robots and Systems (IROS), 2012 IEEE/RSJ International Conference on , pages 5026–5033. IEEE.
Vezhnevets et al., (2017) Vezhnevets, A. S., Osindero, S., Schaul, T., Heess, N., Jaderberg, M., Silver, D., and Kavukcuoglu, K. (2017). Feudal networks for hierarchical reinforcement learning. arXiv preprint arXiv:1703.01161 .
Zaremba and Sutskever, (2014) Zaremba, W. and Sutskever, I. (2014). Learning to execute. arXiv preprint arXiv:1410.4615 .
Appendix A Experiment details
附录 A 实验细节
In this section we provide more details on our experimental setup and hyperparameters used.
本节提供实验设置与所用超参的更多细节。
Bit-flipping experiment:
We used a network with hidden layer with neurons. The length of each episode was equal to the number of bits and the episode was considered successful if the goal state was achieved at an arbitrary timestep during the episode. All other hyperparameters used were the same as in the case of DDPG experiments.
比特翻转实验:
我们使用含 1 个隐层、256 个神经元的网络。每个回合长度等于比特数;若回合中任意时间步达成目标状态,则视为成功。其余超参与 DDPG 实验相同。
State-goal distributions:
For all tasks the initial position of the gripper is fixed, for the pushing and sliding tasks it is located just above the table surface and for pushing it is located 20cm above the table. The object is placed randomly on the table in the 30cm x 30cm (20c x 20cm for sliding) square with the center directly under the gripper (both objects are 5cm wide). For pushing, the goal state is sampled uniformly from the same square as the box position. In the pick-and-place task the target is located in the air in order to force the robot to grasp (and not just push). The and coordinates of the goal position are sampled uniformly from the mentioned square and the height is sampled uniformly between 10cm and 45cm. For sliding the goal position is sampled from a 60cm x 60cm square centered 40cm away from the initial gripper position. For all tasks we discard initial state-goal pairs in which the goal is already satisfied.
状态—目标分布:
对所有任务夹爪初始位置固定:推动与滑动任务中位于桌面正上方,推动任务中位于桌面上方 20cm。物体随机放在以夹爪正下方为中心的 30cm×30cm(滑动为 20cm×20cm)正方形桌面上(两物体宽 5cm)。推动任务中,目标状态从与盒子位置相同的正方形中均匀采样。抓取放置任务中目标在空中,以迫使机器人抓取(而非仅推动)。目标位置的 、 从上述正方形均匀采样,高度在 10cm 与 45cm 间均匀采样。滑动任务中目标从以初始夹爪位置外 40cm 为中心的 60cm×60cm 正方形采样。对所有任务,若目标已被满足,则丢弃该初始状态—目标对。
Network architecture:
Both actor and critic networks have hidden layers with hidden units in each layer. Hidden layers use ReLu activation function and the actor output layer uses tanh. The output of the tanh is then rescaled so that it lies in the range . In order to prevent tanh saturation and vanishing gradients we add the square of the their preactivations to the actor’s cost function.
网络结构:
演员与评论家网络均有 3 个隐层,每层 64 个隐单元。隐层使用 ReLU 激活,演员输出层使用 tanh。tanh 输出再缩放,使其落在 。为防止 tanh 饱和与梯度消失,我们把其预激活的平方加入演员代价函数。
Training procedure:
We train for epochs. Each epoch consists of cycles where each cycle consists of running the policy for episodes and then performing optimization steps on minibatches of size sampled uniformly from a replay buffer consisting of transitions. We update the target networks after every cycle using the decay coefficient of . Apart from using the target network for computing Q-targets for the critic we also use it in testing episodes as it is more stable than the main network. The whole training procedure is distributed over threads. For the Adam optimization algorithm we use the learning rate of and the default values from Tensorflow framework (Abadi et al.,, 2016) for the other hyperparameters. We use the discount factor of for all transitions including the ones ending an episode. Moreover, we clip the targets used to train the critic to the range of possible values, i.e. .
训练流程:
训练 200 个 epoch。每个 epoch 含 50 个 cycle;每个 cycle 先用策略跑 16 个回合,再在从含 转移的回放缓冲中均匀采样、大小为 128 的小批量上做 40 步优化。每个 cycle 后用衰减系数 0.95 更新目标网络。除用目标网络计算评论家的 Q 目标外,测试回合也使用它,因其比主网络更稳定。整个训练分布在 8 个线程上。Adam 优化学习率 0.001,其余超参用 Tensorflow 框架(Abadi et al., 2016)默认值。对包括结束回合的转移在内的所有转移,折扣因子 。此外把训练评论家所用目标裁剪到可能取值范围,即 。
Input scaling:
Neural networks have problems dealing with inputs of different magnitudes and therefore it is crucial to scale them properly. To this end, we rescale inputs to neural networks so that they have mean zero and standard deviation equal to one and then clip them to the range . Means and standard deviations used for rescaling are computed using all the observations encountered so far in the training.
输入缩放:
神经网络难以处理量级不同的输入,因此恰当缩放至关重要。为此我们把神经网络输入缩放到均值零、标准差一,再裁剪到 。缩放所用均值与标准差用训练中迄今遇到的全部观测计算。
Exploration:
The behavioral policy we use for exploration works as follows. With probability we sample (uniformly) a random action from the hypercube of valid actions. Otherwise, we take the output of the policy network and add independently to every coordinate normal noise with standard deviation equal to of the total range of allowed values on this coordinate.
探索:
用于探索的行为策略如下。以 20% 概率从有效动作超立方体中(均匀)采样随机动作。否则取策略网络输出,并独立地向每一坐标加入标准差等于该坐标允许取值总范围 5% 的正态噪声。
Simulation:
Every episode consists of environment timesteps, each of which consists of MuJoCo steps with . MuJoCo uses soft constraints for contacts and therefore object penetration is possible. It can be minimized by using a small timestep and more constraint solver epochs but it would slow down the simulation. We encountered some penetration in the pushing task (the agent learnt to push the box into the table in a way that it is pushed out by contact forces onto the target). In order to void this behaviour we added to the reward a term penalizing the squared depth of penetration for every contact pair.
仿真:
每个回合含 50 个环境时间步,每步含 10 个 的 MuJoCo 步。MuJoCo 对接触使用软约束,因此物体穿透可能发生。用更小时间步与更多约束求解轮次可减小穿透,但会拖慢仿真。我们在推动任务中遇到一些穿透(智能体学会把盒子推进桌面,再由接触力推出到目标上)。为避免该行为,我们在奖励中加入对每个接触对穿透深度平方的惩罚项。
Training time:
Training for epochs took us approximately 2.5h for pushing and the pick-and-place tasks and 6h for kicking (because physics simulation was slower for this task) using cpu cores.
训练时间:
用 8 个 CPU 核训练 200 个 epoch,推动与抓取放置约 2.5 小时,踢球约 6 小时(因该任务物理仿真更慢)。
Appendix B Deployment on the physical robot
附录 B 在真实机器人上部署
We have trained a convolutional neural network (CNN) which predicts the box position given the raw image from the fetch head camera. The CNN was trained using only images coming from the Mujoco renderer. Despite the fact that training images were not photorealistic, the trained network performs well on real world data thanks to a high degree of randomization of textures, lightning and other visual parameters in training. This approach called domain randomization is described in more detail in Tobin et al., (2017).
我们训练了一个卷积神经网络(CNN),根据 Fetch 头部相机原始图像预测盒子位置。CNN 仅用 MuJoCo 渲染器生成的图像训练。尽管训练图像并非照片级真实,由于训练中对纹理、光照及其他视觉参数高度随机化,训练好的网络在真实世界数据上表现良好。该方法称为 域随机化,细节见 Tobin et al. (2017)。
At the beginning of each episode we initialize a simulated environment using the box position predicted by the CNN and robot state coming from the physical robot. From this point we run the policy in the simulator. After each timestep we send the simulated robot joint angles to the real one which is position-controlled and uses the simulated data as targets.
每个回合开始时,我们用 CNN 预测的盒子位置与来自真实机器人的机器人状态初始化仿真环境。此后在仿真器中运行策略。每个时间步后,把仿真机器人的关节角发给真实机器人;真实机器人为位置控制,以仿真数据为目标。