Group Normalization
Group Normalization
组归一化
Yuxin Wu Kaiming He Affiliation: Facebook AI Research (FAIR) Affiliation: {yuxinwu,kaiminghe}@fb.com
Abstract
摘要
Batch Normalization (BN) is a milestone technique in the development of deep learning, enabling various networks to train. However, normalizing along the batch dimension introduces problems --- BN’s error increases rapidly when the batch size becomes smaller, caused by inaccurate batch statistics estimation. This limits BN’s usage for training larger models and transferring features to computer vision tasks including detection, segmentation, and video, which require small batches constrained by memory consumption. In this paper, we present Group Normalization (GN) as a simple alternative to BN. GN divides the channels into groups and computes within each group the mean and variance for normalization. GN’s computation is independent of batch sizes, and its accuracy is stable in a wide range of batch sizes. On ResNet-50 trained in ImageNet, GN has 10.6% lower error than its BN counterpart when using a batch size of 2; when using typical batch sizes, GN is comparably good with BN and outperforms other normalization variants. Moreover, GN can be naturally transferred from pre-training to fine-tuning. GN can outperform its BN-based counterparts for object detection and segmentation in COCO,[^1] and for video classification in Kinetics, showing that GN can effectively replace the powerful BN in a variety of tasks. GN can be easily implemented by a few lines of code in modern libraries.
批量归一化(Batch Normalization,BN)是深度学习发展中的里程碑技术,让各类网络得以顺利训练。然而,沿着 batch 维做归一化也带来问题——当 batch 变小时,批量统计估计不准,BN 的误差会迅速升高。这限制了 BN 用于训练更大模型,以及把特征迁移到检测、分割、视频等受显存约束、只能用小 batch 的视觉任务。本文提出组归一化(Group Normalization,GN)作为 BN 的简单替代:把通道分成若干组,在组内计算均值与方差做归一化。GN 的计算与 batch 大小无关,在很宽的 batch 范围内精度都稳定。在 ImageNet 上训练的 ResNet-50 中,batch 大小为 2 时 GN 比对应 BN 低 10.6% 误差;在常用 batch 大小下 GN 与 BN 相当,并优于其他归一化变体。此外,GN 能自然地从预训练迁移到微调:在 COCO 目标检测与分割、以及 Kinetics 视频分类上,GN 都能超过基于 BN 的对应模型,表明 GN 可以在多种任务上有效替代强势的 BN。GN 用现代库里几行代码即可实现。
1 Introduction
1 引言
Batch Normalization (Batch Norm or BN) [26] has been established as a very effective component in deep learning, largely helping push the frontier in computer vision [59, 20] and beyond [54]. BN normalizes the features by the mean and variance computed within a (mini-)batch. This has been shown by many practices to ease optimization and enable very deep networks to converge. The stochastic uncertainty of the batch statistics also acts as a regularizer that can benefit generalization. BN has been a foundation of many state-of-the-art computer vision algorithms.
批量归一化(Batch Norm,简称 BN)[26] 已成为深度学习中非常有效的组件,大幅推动了计算机视觉 [59, 20] 及其他领域 [54] 的前沿。BN 用(小)batch 内计算的均值与方差对特征做归一化。大量实践表明,这能减轻优化难度,使很深的网络收敛;batch 统计量的随机不确定性也起到正则作用,有利于泛化。BN 已是许多顶尖视觉算法的基础。
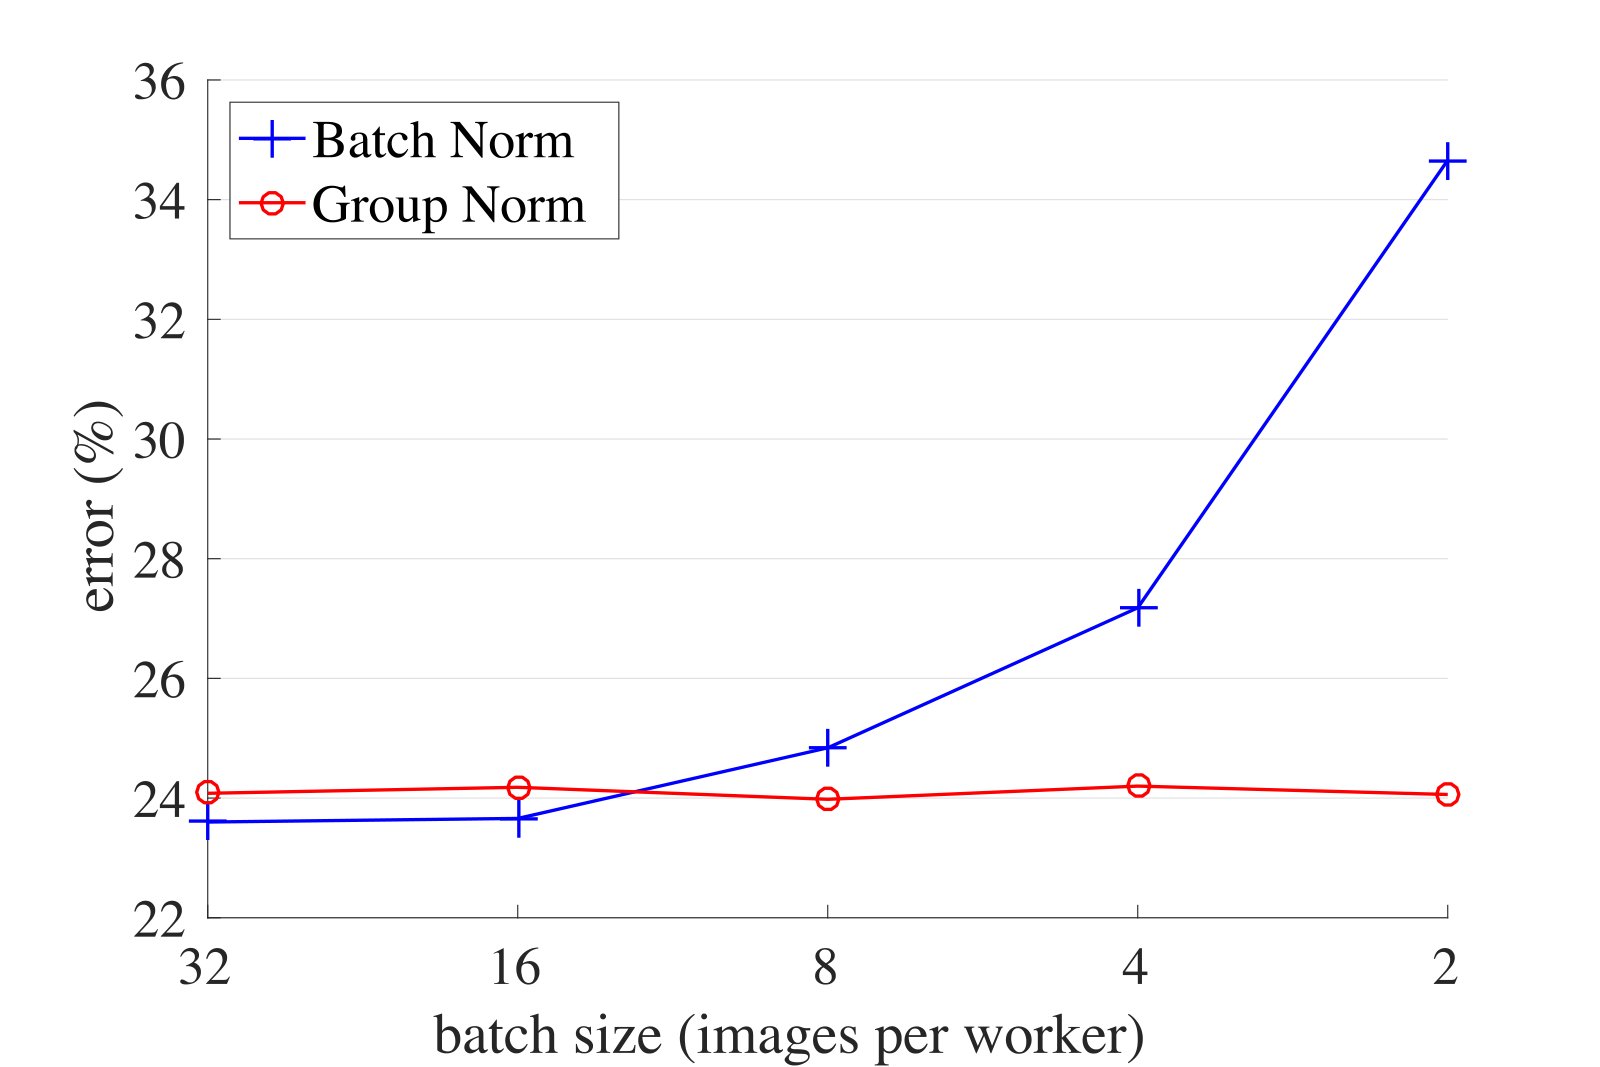
Figure 1: ImageNet classification error vs. batch sizes. This is a ResNet-50 model trained in the ImageNet training set using 8 workers (GPUs), evaluated in the validation set.
图 1:ImageNet 分类误差随 batch 大小变化。这是在 ImageNet 训练集上用 8 个 worker(GPU)训练、在验证集上评估的 ResNet-50。
Despite its great success, BN exhibits drawbacks that are also caused by its distinct behavior of normalizing along the batch dimension. In particular, it is required for BN to work with a sufficiently large batch size (e.g., 32 per worker[^2] [26, 59, 20]). A small batch leads to inaccurate estimation of the batch statistics, and reducing BN’s batch size increases the model error dramatically (Figure 1). As a result, many recent models [59, 20, 57, 24, 63] are trained with non-trivial batch sizes that are memory-consuming. The heavy reliance on BN’s effectiveness to train models in turn prohibits people from exploring higher-capacity models that would be limited by memory.
尽管极为成功,BN 的缺陷也正来自它沿 batch 维归一化这一独特行为。具体而言,BN 需要足够大的 batch(例如每个 worker 32 个样本[^2] [26, 59, 20])才能正常工作。小 batch 会导致批量统计估计不准,减小 BN 的 batch 会急剧抬高模型误差(图 1)。因此,许多近期模型 [59, 20, 57, 24, 63] 都用占用大量显存的非平凡 batch 训练。对 BN 有效性的重度依赖反过来又阻碍人们探索更高容量、却会被显存卡住的模型。
The restriction on batch sizes is more demanding in computer vision tasks including detection [12, 47, 18], segmentation [38, 18], video recognition [60, 6], and other high-level systems built on them. For example, the Fast/er and Mask R-CNN frameworks [12, 47, 18] use a batch size of 1 or 2 images because of higher resolution, where BN is “frozen” by transforming to a linear layer [20]; in video classification with 3D convolutions [60, 6], the presence of spatial-temporal features introduces a trade-off between the temporal length and batch size. The usage of BN often requires these systems to compromise between the model design and batch sizes.
在检测 [12, 47, 18]、分割 [38, 18]、视频识别 [60, 6] 以及建立在其上的高层系统里,对 batch 大小的限制更苛刻。例如 Fast/er 与 Mask R-CNN [12, 47, 18] 因分辨率高而用每批 1 或 2 张图,此时 BN 被“冻结”并改写成线性层 [20];在带 3D 卷积的视频分类 [60, 6] 中,时空特征又迫使在时间长度与 batch 大小之间权衡。使用 BN 常常迫使这些系统在模型设计与 batch 大小之间妥协。
This paper presents Group Normalization (GN) as a simple alternative to BN. We notice that many classical features like SIFT [39] and HOG [9] are group-wise features and involve group-wise normalization. For example, a HOG vector is the outcome of several spatial cells where each cell is represented by a normalized orientation histogram. Analogously, we propose GN as a layer that divides channels into groups and normalizes the features within each group (Figure 2). GN does not exploit the batch dimension, and its computation is independent of batch sizes.
本文提出组归一化(Group Normalization,GN)作为 BN 的简单替代。我们注意到,许多经典特征如 SIFT [39] 与 HOG [9] 本身就是分组特征,并涉及组内归一化。例如 HOG 向量来自若干空间单元,每个单元是一个归一化后的方向直方图。类似地,我们提出 GN:把通道分成组,并在每组内归一化特征(图 2)。GN 不利用 batch 维,其计算与 batch 大小无关。
GN behaves very stably over a wide range of batch sizes (Figure 1). With a batch size of 2 samples, GN has 10.6% lower error than its BN counterpart for ResNet-50 [20] in ImageNet [50]. With a regular batch size, GN is comparably good as BN (with a gap of 0.5%) and outperforms other normalization variants [3, 61, 51]. Moreover, although the batch size may change, GN can naturally transfer from pre-training to fine-tuning. GN shows improved results vs. its BN counterpart on Mask R-CNN for COCO object detection and segmentation [37], and on 3D convolutional networks for Kinetics video classification [30]. The effectiveness of GN in ImageNet, COCO, and Kinetics demonstrates that GN is a competitive alternative to BN that has been dominant in these tasks.
GN 在很宽的 batch 范围内表现都很稳定(图 1)。在 ImageNet 上 batch 为 2 时,GN 比对应 BN 的 ResNet-50 [20] 低 10.6% 误差。在常规 batch 下,GN 与 BN 相当(差距约 0.5%),并优于其他归一化变体 [3, 61, 51]。而且,即便微调时 batch 变了,GN 也能自然地从预训练迁到微调。在 Mask R-CNN 的 COCO 检测与分割 [37]、以及 Kinetics 视频分类的 3D 卷积网络 [30] 上,GN 相对 BN 对应模型都有提升。ImageNet、COCO 与 Kinetics 上的结果说明,GN 是这些任务上长期主导的 BN 的有力替代。
There have been existing methods, such as Layer Normalization (LN) [3] and Instance Normalization (IN) [61] (Figure 2), that also avoid normalizing along the batch dimension. These methods are effective for training sequential models (RNN/LSTM [49, 22]) or generative models (GANs [15, 27]). But as we will show by experiments, both LN and IN have limited success in visual recognition, for which GN presents better results. Conversely, GN could be used in place of LN and IN and thus is applicable for sequential or generative models. This is beyond the focus of this paper, but it is suggestive for future research.
已有方法如层归一化(Layer Normalization,LN)[3] 与实例归一化(Instance Normalization,IN)[61](图 2)也避免沿 batch 维归一化。它们对训练序列模型(RNN/LSTM [49, 22])或生成模型(GAN [15, 27])很有效。但实验会表明,LN 与 IN 在视觉识别上的成功有限,而 GN 给出更好结果。反过来,GN 也可替代 LN 与 IN,从而用于序列或生成模型。这超出本文范围,但提示了未来研究方向。
2 Related Work
2 相关工作
Normalization.
It is well-known that normalizing the input data makes training faster [33]. To normalize hidden features, initialization methods [33, 14, 19] have been derived based on strong assumptions of feature distributions, which can become invalid when training evolves.
归一化。
众所周知,对输入数据做归一化能加快训练 [33]。要对隐层特征归一化,人们曾基于对特征分布的强假设推导初始化方法 [33, 14, 19],而这些假设在训练推进后往往不再成立。
Normalization layers in deep networks had been widely used before the development of BN. Local Response Normalization (LRN) [40, 28, 32] was a component in AlexNet [32] and following models [64, 53, 58]. Unlike recent methods [26, 3, 61], LRN computes the statistics in a small neighborhood for each pixel.
在 BN 出现之前,深度网络里就广泛使用归一化层。局部响应归一化(Local Response Normalization,LRN)[40, 28, 32] 是 AlexNet [32] 及后续模型 [64, 53, 58] 的组件。与近期方法 [26, 3, 61] 不同,LRN 在每个像素的小邻域内统计。
Batch Normalization [26] performs more global normalization along the batch dimension (and as importantly, it suggests to do this for all layers). But the concept of “batch” is not always present, or it may change from time to time. For example, batch-wise normalization is not legitimate at inference time, so the mean and variance are pre-computed from the training set [26], often by running average; consequently, there is no normalization performed when testing. The pre-computed statistics may also change when the target data distribution changes [45]. These issues lead to inconsistency at training, transferring, and testing time. In addition, as aforementioned, reducing the batch size can have dramatic impact on the estimated batch statistics.
批量归一化 [26] 沿 batch 维做更全局的归一化(同样重要的是,它建议对所有层都这样做)。但“batch”概念并不总是存在,也可能随时间变化。例如推理时不能合法地做 batch 内归一化,于是均值与方差常从训练集预计算 [26],多用运行平均;测试时实际上不再做归一化。目标数据分布变化时,预计算统计量也会漂移 [45]。这些问题导致训练、迁移与测试之间不一致。此外如前所述,减小 batch 会对估计出的批量统计造成剧烈影响。
Several normalization methods [3, 61, 51, 2, 46] have been proposed to avoid exploiting the batch dimension. Layer Normalization (LN) [3] operates along the channel dimension, and Instance Normalization (IN) [61] performs BN-like computation but only for each sample (Figure 2). Instead of operating on features, Weight Normalization (WN) [51] proposes to normalize the filter weights. These methods do not suffer from the issues caused by the batch dimension, but they have not been able to approach BN’s accuracy in many visual recognition tasks. We provide comparisons with these methods in context of the remaining sections.
若干归一化方法 [3, 61, 51, 2, 46] 被提出以避免利用 batch 维。层归一化(LN)[3] 沿通道维操作;实例归一化(IN)[61] 做类似 BN 的计算,但只针对每个样本(图 2)。权重归一化(Weight Normalization,WN)[51] 则归一化滤波器权重而非特征。这些方法不受 batch 维问题困扰,但在许多视觉识别任务上仍难以接近 BN 的精度。下文会在具体语境中与它们比较。
Addressing small batches.
Ioffe [25] proposes Batch Renormalization (BR) that alleviates BN’s issue involving small batches. BR introduces two extra parameters that constrain the estimated mean and variance of BN within a certain range, reducing their drift when the batch size is small. BR has better accuracy than BN in the small-batch regime. But BR is also batch-dependent, and when the batch size decreases its accuracy still degrades [25].
应对小 batch。
Ioffe [25] 提出批量重归一化(Batch Renormalization,BR)以缓解 BN 在小 batch 上的问题。BR 引入两个额外参数,把 BN 估计的均值与方差约束在一定范围内,减小小 batch 时的漂移。小 batch 设定下 BR 精度优于 BN,但它仍依赖 batch,batch 继续减小时精度仍会下降 [25]。
There are also attempts to avoid using small batches. The object detector in [43] performs synchronized BN whose mean and variance are computed across multiple GPUs. However, this method does not solve the problem of small batches; instead, it migrates the algorithm problem to engineering and hardware demands, using a number of GPUs proportional to BN’s requirements. Moreover, the synchronized BN computation prevents using asynchronous solvers (ASGD [10]), a practical solution to large-scale training widely used in industry. These issues can limit the scope of using synchronized BN.
也有人试图避免使用小 batch。[43] 中的目标检测器用同步 BN,跨多个 GPU 汇总均值与方差。但这并未解决小 batch 问题,只是把算法问题转成工程与硬件需求——GPU 数量要与 BN 的需求成正比。而且同步 BN 妨碍使用异步求解器(ASGD [10]),而这正是工业界大规模训练的常用方案。这些因素会限制同步 BN 的适用范围。
Instead of addressing the batch statistics computation (e.g., [25, 43]), our normalization method inherently avoids this computation.
我们的归一化方法不是去修补批量统计计算(例如 [25, 43]),而是从根上避免这一计算。
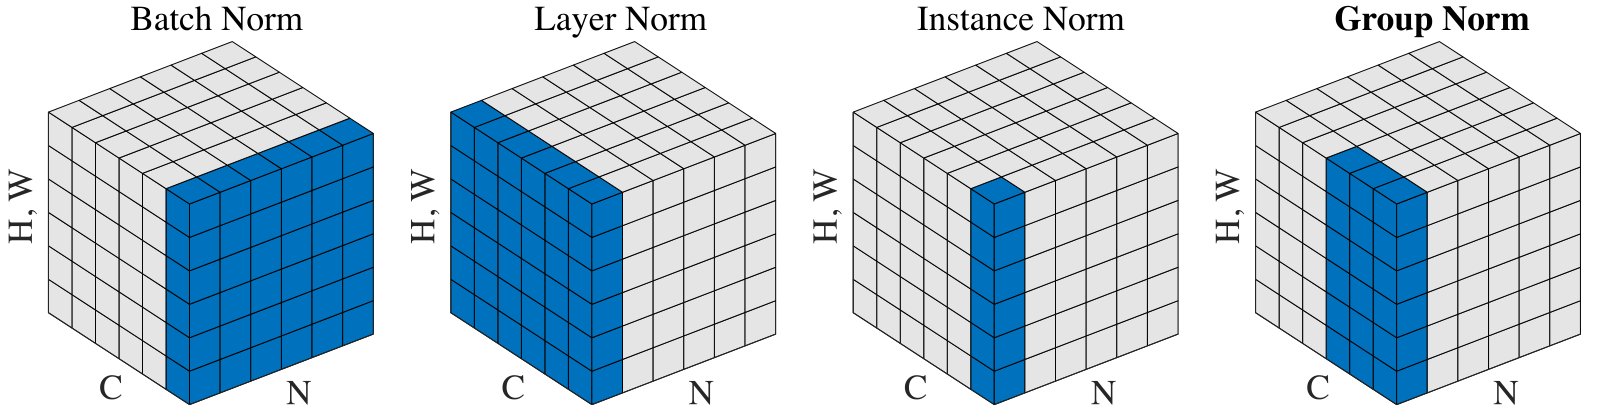
Figure 2: Normalization methods. Each subplot shows a feature map tensor, with as the batch axis, as the channel axis, and as the spatial axes. The pixels in blue are normalized by the same mean and variance, computed by aggregating the values of these pixels.
图 2:归一化方法。每个子图展示一个特征张量, 为 batch 轴, 为通道轴, 为空间轴。蓝色像素用同一组均值与方差归一化,该统计由这些像素的值聚合得到。
Group-wise computation.
Group convolutions have been presented by AlexNet [32] for distributing a model into two GPUs. The concept of groups as a dimension for model design has been more widely studied recently. The work of ResNeXt [63] investigates the trade-off between depth, width, and groups, and it suggests that a larger number of groups can improve accuracy under similar computational cost. MobileNet [23] and Xception [7] exploit channel-wise (also called “depth-wise”) convolutions, which are group convolutions with a group number equal to the channel number. ShuffleNet [65] proposes a channel shuffle operation that permutes the axes of grouped features. These methods all involve dividing the channel dimension into groups. Despite the relation to these methods, GN does not require group convolutions. GN is a generic layer, as we evaluate in standard ResNets [20].
分组计算。
分组卷积由 AlexNet [32] 提出,用于把模型分到两块 GPU。近年来,组作为模型设计维度得到更广泛研究。ResNeXt [63] 考察深度、宽度与组数的权衡,指出在相近计算量下更大组数可提升精度。MobileNet [23] 与 Xception [7] 利用按通道(也称“深度可分”)卷积,即组数等于通道数的分组卷积。ShuffleNet [65] 提出通道混洗,置换分组特征的轴。这些方法都把通道维分成组。尽管与它们相关,GN 并不要求分组卷积。GN 是通用层,我们在标准 ResNet [20] 上评估。
3 Group Normalization
3 组归一化
The channels of visual representations are not entirely independent. Classical features of SIFT [39], HOG [9], and GIST [41] are group-wise representations by design, where each group of channels is constructed by some kind of histogram. These features are often processed by group-wise normalization over each histogram or each orientation. Higher-level features such as VLAD [29] and Fisher Vectors (FV) [44] are also group-wise features where a group can be thought of as the sub-vector computed with respect to a cluster.
视觉表示的通道并非完全独立。SIFT [39]、HOG [9]、GIST [41] 等经典特征在设计上就是分组表示,每组通道由某种直方图构成。这些特征常对每个直方图或每个方向做组内归一化。更高层的 VLAD [29] 与 Fisher 向量(FV)[44] 也是分组特征,一组可视为相对某个聚类算出的子向量。
Analogously, it is not necessary to think of deep neural network features as unstructured vectors. For example, for conv1 (the first convolutional layer) of a network, it is reasonable to expect a filter and its horizontal flipping to exhibit similar distributions of filter responses on natural images. If conv1 happens to approximately learn this pair of filters, or if the horizontal flipping (or other transformations) is made into the architectures by design [11, 8], then the corresponding channels of these filters can be normalized together.
类似地,不必把深度网络特征看成无结构向量。例如对网络的 conv1(第一层卷积),可以合理期望某个滤波器与其水平翻转,在自然图像上的响应分布相近。若 conv1 恰好近似学到这样一对滤波器,或水平翻转(及其他变换)被设计进架构 [11, 8],则这些滤波器对应的通道可以一起归一化。
The higher-level layers are more abstract and their behaviors are not as intuitive. However, in addition to orientations (SIFT [39], HOG [9], or [11, 8]), there are many factors that could lead to grouping, e.g., frequency, shapes, illumination, textures. Their coefficients can be interdependent. In fact, a well-accepted computational model in neuroscience is to normalize across the cell responses [21, 52, 55, 5], “with various receptive-field centers (covering the visual field) and with various spatiotemporal frequency tunings” (p183, [21]); this can happen not only in the primary visual cortex, but also “throughout the visual system” [5]. Motivated by these works, we propose new generic group-wise normalization for deep neural networks.
更高层更抽象,行为不那么直观。但除方向(SIFT [39]、HOG [9],或 [11, 8])外,频率、形状、光照、纹理等因素也可能导致分组,其系数可以相互依赖。事实上,神经科学中广为接受的计算模型是对细胞响应做归一化 [21, 52, 55, 5],“具有不同感受野中心(覆盖视野)以及不同时空频率调谐”(p183,[21]);这不仅发生在初级视皮层,也发生在“整个视觉系统” [5]。受此启发,我们为深度网络提出新的通用组归一化。
3.1 Formulation
3.1 形式化
We first describe a general formulation of feature normalization, and then present GN in this formulation. A family of feature normalization methods, including BN, LN, IN, and GN, perform the following computation:
我们先给出特征归一化的一般形式,再在该形式下给出 GN。包括 BN、LN、IN 与 GN 在内的一类方法做如下计算:
Here is the feature computed by a layer, and is an index. In the case of 2D images, is a 4D vector indexing the features in order, where is the batch axis, is the channel axis, and and are the spatial height and width axes.
这里 是某层算出的特征, 是索引。对二维图像, 是按 顺序索引特征的四维向量,其中 为 batch 轴, 为通道轴, 与 为空间高与宽。
and in (1) are the mean and standard deviation (std) computed by:
(1) 中的 与 是均值与标准差,由下式计算:
with as a small constant. is the set of pixels in which the mean and std are computed, and is the size of this set. Many types of feature normalization methods mainly differ in how the set is defined (Figure 2), discussed as follows.
其中 为小常数。 是计算均值与标准差所用的像素集合, 为该集合大小。多种特征归一化方法的主要差别在于如何定义 (图 2),分述如下。
In Batch Norm [26], the set is defined as:
在批量归一化 [26] 中, 定义为:
where (and ) denotes the sub-index of (and ) along the axis. This means that the pixels sharing the same channel index are normalized together, i.e., for each channel, BN computes and along the axes. In Layer Norm [3], the set is:
其中 (以及 )表示 (以及 )沿 轴的子索引。这意味着共享同一通道索引的像素一起归一化,即对每个通道,BN 沿 轴计算 与 。在层归一化 [3] 中,集合为:
meaning that LN computes and along the axes for each sample. In Instance Norm [61], the set is:
即 LN 对每个样本沿 轴计算 与 。在实例归一化 [61] 中,集合为:
meaning that IN computes and along the axes for each sample and each channel. The relations among BN, LN, and IN are in Figure 2.
即 IN 对每个样本、每个通道沿 轴计算 与 。BN、LN、IN 的关系见图 2。
As in [26], all methods of BN, LN, and IN learn a per-channel linear transform to compensate for the possible lost of representational ability:
与 [26] 一样,BN、LN、IN 都学习按通道的线性变换,以补偿可能损失的表示能力:
where and are trainable scale and shift (indexed by in all case, which we omit for simplifying notations).
其中 与 是可训练的尺度与平移(所有情形下都按 索引,记号上从略)。
Group Norm.
Formally, a Group Norm layer computes and in a set defined as:
组归一化。
形式化地,组归一化层在集合 上计算 与 ,该集合定义为:
Here is the number of groups, which is a pre-defined hyper-parameter ( by default). is the number of channels per group. is the floor operation, and “” means that the indexes and are in the same group of channels, assuming each group of channels are stored in a sequential order along the axis. GN computes and along the axes and along a group of channels. The computation of GN is illustrated in Figure 2 (rightmost), which is a simple case of 2 groups () each having 3 channels.
这里 是组数,为预定义超参(默认 )。 是每组通道数。 为下取整,而“”表示索引 与 属于同一通道组(假设各组通道沿 轴顺序存放)。GN 沿 轴以及一组 个通道计算 与 。图 2(最右)示意了 GN:简单情形为 2 组(),每组 3 个通道。
Given in Eqn.(7), a GN layer is defined by Eqn.(1), (2), and (6). Specifically, the pixels in the same group are normalized together by the same and . GN also learns the per-channel and .
给定式 (7) 中的 ,GN 层由式 (1)、(2)、(6) 定义。具体地,同一组内的像素用同一组 与 归一化。GN 也学习按通道的 与 。
Relation to Prior Work.
LN, IN, and GN all perform independent computations along the batch axis. The two extreme cases of GN are equivalent to LN and IN (Figure 2).
与先前工作的关系。
LN、IN 与 GN 都沿 batch 轴独立计算。GN 的两个极端情形分别等价于 LN 与 IN(图 2)。
Relation to Layer Normalization [3]. GN becomes LN if we set the group number as . LN assumes all channels in a layer make “similar contributions” [3]. Unlike the case of fully-connected layers studied in [3], this assumption can be less valid with the presence of convolutions, as discussed in [3]. GN is less restricted than LN, because each group of channels (instead of all of them) are assumed to subject to the shared mean and variance; the model still has flexibility of learning a different distribution for each group. This leads to improved representational power of GN over LN, as shown by the lower training and validation error in experiments (Figure 4).
与层归一化的关系 [3]。若设组数 ,GN 退化为 LN。LN 假定一层中所有通道作出“相似贡献” [3]。与 [3] 研究的全连接层不同,有卷积时这一假定更不稳妥,[3] 中也有讨论。GN 比 LN 限制更少:假定共享均值与方差的是每组通道(而非全部),模型仍可为各组学习不同分布。这带来相对 LN 更强的表示能力,实验中训练与验证误差都更低(图 4)。
Relation to Instance Normalization [61]. GN becomes IN if we set the group number as (i.e., one channel per group). But IN can only rely on the spatial dimension for computing the mean and variance and it misses the opportunity of exploiting the channel dependence.
与实例归一化的关系 [61]。若设组数 (即每组一个通道),GN 退化为 IN。但 IN 只能依赖空间维计算均值与方差,错过了利用通道依赖的机会。
def GroupNorm(x, gamma, beta, G, eps=1e-5):
x: input features with shape [N,C,H,W]
gamma, beta: scale and offset, with shape [1,C,1,1]
G: number of groups for GN
N, C, H, W = x.shape
x = tf.reshape(x, [N, G, C // G, H, W])
mean, var = tf.nn.moments(x, [2, 3, 4], keep_dims=True)
x = (x - mean) / tf.sqrt(var + eps)
x = tf.reshape(x, [N, C, H, W])
return x * gamma + beta
Figure 3: Python code of Group Norm based on TensorFlow.
def GroupNorm(x, gamma, beta, G, eps=1e-5):
x: input features with shape [N,C,H,W]
gamma, beta: scale and offset, with shape [1,C,1,1]
G: number of groups for GN
N, C, H, W = x.shape
x = tf.reshape(x, [N, G, C // G, H, W])
mean, var = tf.nn.moments(x, [2, 3, 4], keep_dims=True)
x = (x - mean) / tf.sqrt(var + eps)
x = tf.reshape(x, [N, C, H, W])
return x * gamma + beta
图 3:基于 TensorFlow 的组归一化 Python 代码。
3.2 Implementation
3.2 实现
GN can be easily implemented by a few lines of code in PyTorch [42] and TensorFlow [1] where automatic differentiation is supported. Figure 3 shows the code based on TensorFlow. In fact, we only need to specify how the mean and variance (“moments”) are computed, along the appropriate axes as defined by the normalization method.
在支持自动微分的 PyTorch [42] 与 TensorFlow [1] 中,GN 用几行代码即可实现。图 3 给出基于 TensorFlow 的代码。实际上只需按归一化方法定义的轴,指定如何计算均值与方差(“moments”)。
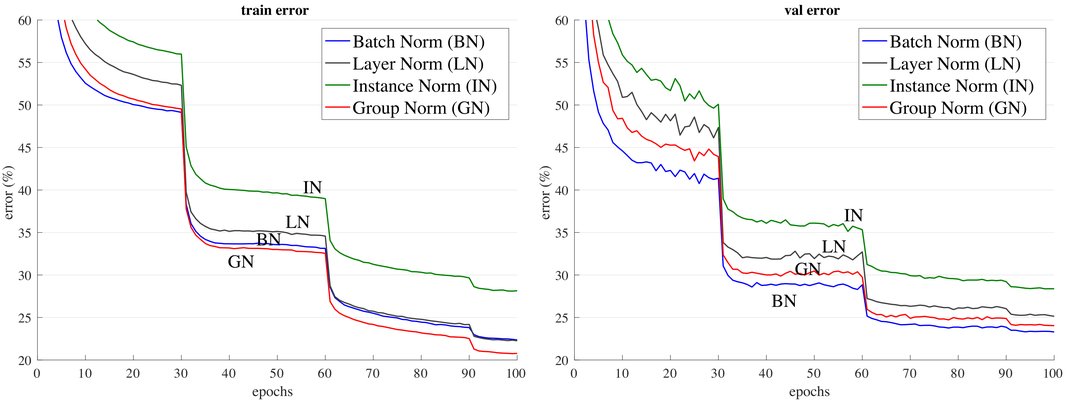
Figure 4: Comparison of error curves with a batch size of 32 images/GPU. We show the ImageNet training error (left) and validation error (right) vs. numbers of training epochs. The model is ResNet-50.
图 4:误差曲线对比,每 GPU 32 张图的 batch。展示 ImageNet 训练误差(左)与验证误差(右)随训练 epoch 数的变化。模型为 ResNet-50。
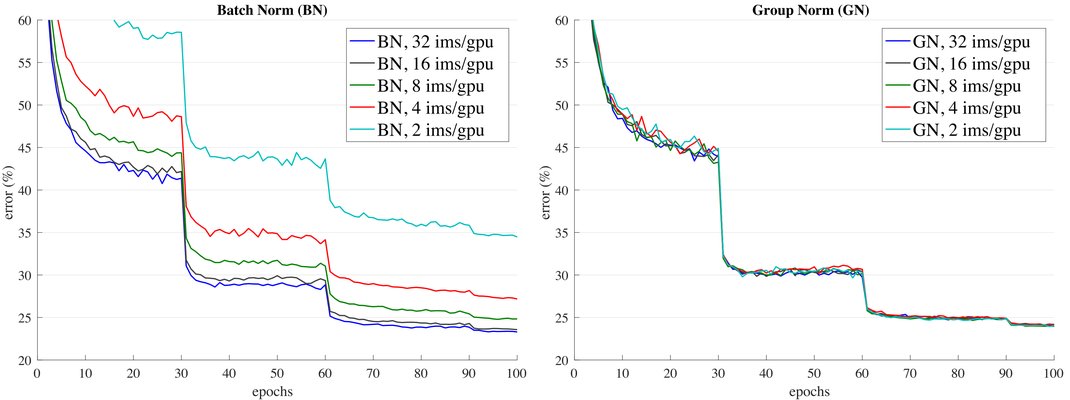
Figure 5: Sensitivity to batch sizes: ResNet-50’s validation error of BN (left) and GN (right) trained with 32, 16, 8, 4, and 2 images/GPU.
图 5:对 batch 大小的敏感性:ResNet-50 在每 GPU 32、16、8、4、2 张图训练时,BN(左)与 GN(右)的验证误差。
4 Experiments
4 实验
4.1 Image Classification in ImageNet
4.1 ImageNet 图像分类
We experiment in the ImageNet classification dataset [50] with 1000 classes. We train on the 1.28M training images and evaluate on the 50,000 validation images, using the ResNet models [20].
我们在含 1000 类的 ImageNet 分类数据集 [50] 上实验:约 128 万张训练图、5 万张验证图,使用 ResNet 模型 [20]。
Implementation details.
As standard practice [20, 17], we use 8 GPUs to train all models, and the batch mean and variance of BN are computed within each GPU. We use the method of [19] to initialize all convolutions for all models. We use 1 to initialize all parameters, except for each residual block’s last normalization layer where we initialize by 0 following [16] (such that the initial state of a residual block is identity). We use a weight decay of 0.0001 for all weight layers, including and (following [17] but unlike [20, 16]). We train 100 epochs for all models, and decrease the learning rate by 10 at 30, 60, and 90 epochs. During training, we adopt the data augmentation of [58] as implemented by [17]. We evaluate the top-1 classification error on the center crops of 224224 pixels in the validation set. To reduce random variations, we report the median error rate of the final 5 epochs [16]. Other implementation details follow [17].
实现细节。
按常规做法 [20, 17],所有模型用 8 块 GPU 训练,BN 的 batch 均值与方差在每块 GPU 内计算。所有模型的卷积用 [19] 的方法初始化。所有 参数初始化为 1,但每个残差块最后一个归一化层的 按 [16] 初始化为 0(使残差块初始状态为恒等)。所有权重层(含 与 )权重衰减为 0.0001(跟随 [17],而非 [20, 16])。所有模型训练 100 个 epoch,在第 30、60、90 个 epoch 把学习率降 10。训练期数据增强采用 [58],实现来自 [17]。验证集上对 224224 中心裁剪报告 top-1 分类误差。为减小随机波动,报告最后 5 个 epoch 的中位误差率 [16]。其余实现细节跟随 [17]。
Our baseline is the ResNet trained with BN [20]. To compare with LN, IN, and GN, we replace BN with the specific variant. We use the same hyper-parameters for all models. We set for GN by default.
基线是带 BN 训练的 ResNet [20]。与 LN、IN、GN 比较时,用对应变体替换 BN。所有模型用相同超参。GN 默认设 。
Comparison of feature normalization methods.
We first experiment with a regular batch size of 32 images (per GPU) [26, 20]. BN works successfully in this regime, so this is a strong baseline to compare with. Figure 4 shows the error curves, and Table 1 shows the final results.
特征归一化方法比较。
我们首先在常规 batch 大小——每 GPU 32 张图 [26, 20]——下实验。该设定下 BN 工作良好,因而是强基线。图 4 给出误差曲线,表 1 给出最终结果。
| BN | LN | IN | GN | |
|---|---|---|---|---|
| val error | 23.6 | 25.3 | 28.4 | 24.1 |
| (vs. BN) | - | 1.7 | 4.8 | 0.5 |
Table 1: Comparison of error rates (%) of ResNet-50 in the ImageNet validation set, trained with a batch size of 32 images/GPU. The error curves are in Figure 4.
| BN | LN | IN | GN | |
|---|---|---|---|---|
| 验证误差 | 23.6 | 25.3 | 28.4 | 24.1 |
| (相对 BN) | - | 1.7 | 4.8 | 0.5 |
表 1:ImageNet 验证集上 ResNet-50 的误差率比较(%),每 GPU 32 张图训练。误差曲线见图 4。
Figure 4 shows that all of these normalization methods are able to converge. LN has a small degradation of 1.7% comparing with BN. This is an encouraging result, as it suggests that normalizing along all channels (as done by LN) of a convolutional network is reasonably good. IN also makes the model converge, but is 4.8% worse than BN.[^3]
图 4 显示,所有这些归一化方法都能收敛。LN 相对 BN 略差 1.7%。这令人鼓舞:说明在卷积网络上沿全部通道归一化(如 LN)已经相当不错。IN 也能让模型收敛,但比 BN 差 4.8%。[^3]
In this regime where BN works well, GN is able to approach BN’s accuracy, with a decent degradation of 0.5% in the validation set. Actually, Figure 4 (left) shows that GN has lower training error than BN, indicating that GN is effective for easing optimization. The slightly higher validation error of GN implies that GN loses some regularization ability of BN. This is understandable, because BN’s mean and variance computation introduces uncertainty caused by the stochastic batch sampling, which helps regularization [26]. This uncertainty is missing in GN (and LN/IN). But it is possible that GN combined with a suitable regularizer will improve results. This can be a future research topic.
在 BN 表现良好的这一设定下,GN 能接近 BN 的精度,验证集上仅差 0.5%。实际上图 4(左)显示 GN 的训练误差更低,说明 GN 有助于减轻优化难度。GN 略高的验证误差意味着它损失了 BN 的一部分正则能力。这可以理解:BN 的均值与方差计算引入了随机采样 batch 带来的不确定性,有助于正则 [26]。GN(以及 LN/IN)没有这一不确定性。但 GN 若配合合适的正则器,结果仍可能提升,可作为未来课题。
| batch size | 32 | 16 | 8 | 4 | 2 |
|---|---|---|---|---|---|
| BN | 23.6 | 23.7 | 24.8 | 27.3 | 34.7 |
| GN | 24.1 | 24.2 | 24.0 | 24.2 | 24.1 |
| 0.5 | 0.5 | -0.8 | -3.1 | -10.6 |
Table 2: Sensitivity to batch sizes. We show ResNet-50’s validation error (%) in ImageNet. The last row shows the differences between BN and GN. The error curves are in Figure 5. This table is visualized in Figure 1.
| batch 大小 | 32 | 16 | 8 | 4 | 2 |
|---|---|---|---|---|---|
| BN | 23.6 | 23.7 | 24.8 | 27.3 | 34.7 |
| GN | 24.1 | 24.2 | 24.0 | 24.2 | 24.1 |
| 0.5 | 0.5 | -0.8 | -3.1 | -10.6 |
表 2:对 batch 大小的敏感性。给出 ImageNet 上 ResNet-50 的验证误差(%)。末行是 BN 与 GN 的差。误差曲线见图 5。本表可视化为图 1。
| error | |
|---|---|
| none | 29.2 |
| BN | 28.0 |
| GN | 27.6 |
Figure 6: Evolution of feature distributions of conv5_3’s output (before normalization and ReLU) from VGG-16, shown as the {1, 20, 80, 99} percentile of responses. The table on the right shows the ImageNet validation error (%). Models are trained with 32 images/GPU.
| 误差 | |
|---|---|
| 无归一化 | 29.2 |
| BN | 28.0 |
| GN | 27.6 |
图 6:VGG-16 中 conv5_3 输出(归一化与 ReLU 之前)的特征分布演化,展示响应的 {1, 20, 80, 99} 百分位。右侧表格为 ImageNet 验证误差(%)。模型以每 GPU 32 张图训练。
Small batch sizes.
Although BN benefits from the stochasticity under some situations, its error increases when the batch size becomes smaller and the uncertainty gets bigger. We show this in Figure 1, Figure 5, and Table 2.
小 batch。
尽管 BN 在某些情形下受益于随机性,但当 batch 变小、不确定性变大时,其误差会升高。我们在图 1、图 5 与表 2 中展示这一点。
We evaluate batch sizes of 32, 16, 8, 4, 2 images per GPU. In all cases, the BN mean and variance are computed within each GPU and not synchronized. All models are trained in 8 GPUs. In this set of experiments, we adopt the linear learning rate scaling rule [31, 4, 16] to adapt to batch size changes — we use a learning rate of 0.1 [20] for the batch size of 32, and 0.132 for a batch size of . This linear scaling rule works well for BN if the total batch size changes (by changing the number of GPUs) but the per-GPU batch size does not change [16]. We keep the same number of training epochs for all cases (Figure 5, x-axis). All other hyper-parameters are unchanged.
我们评估每 GPU 32、16、8、4、2 张图。所有情形下 BN 均值与方差在每块 GPU 内计算、不同步。所有模型用 8 块 GPU。本实验采用线性学习率缩放规则 [31, 4, 16] 以适应 batch 变化——batch 为 32 时学习率 0.1 [20],batch 为 时为 0.132。若总 batch 因 GPU 数变化而变、但每 GPU batch 不变,该线性规则对 BN 效果良好 [16]。所有情形保持相同训练 epoch 数(图 5,横轴)。其余超参不变。
Figure 5 (left) shows that BN’s error becomes considerably higher with small batch sizes. GN’s behavior is more stable and insensitive to the batch size. Actually, Figure 5 (right) shows that GN has very similar curves (subject to random variations) across a wide range of batch sizes from 32 to 2. In the case of a batch size of 2, GN has 10.6% lower error rate than its BN counterpart (24.1% vs. 34.7%).
图 5(左)显示,小 batch 时 BN 误差明显升高。GN 的行为更稳定,对 batch 大小不敏感。实际上图 5(右)显示,从 32 到 2 的宽范围内,GN 曲线非常接近(仅有随机波动)。batch 为 2 时,GN 比对应 BN 低 10.6% 误差率(24.1% 对 34.7%)。
These results indicate that the batch mean and variance estimation can be overly stochastic and inaccurate, especially when they are computed over 4 or 2 images. However, this stochasticity disappears if the statistics are computed from 1 image, in which case BN becomes similar to IN at training time. We see that IN has a better result (28.4%) than BN with a batch size of 2 (34.7%).
这些结果表明,批量均值与方差估计可能过于随机且不准,尤其在只用 4 或 2 张图计算时。不过,若统计来自 1 张图,这种随机性消失,训练时 BN 变得类似 IN。可见 IN(28.4%)优于 batch 为 2 的 BN(34.7%)。
The robust results of GN in Table 2 demonstrate GN’s strength. It allows to remove the batch size constraint imposed by BN, which can give considerably more memory (e.g., 16 or more). This will make it possible to train higher-capacity models that would be otherwise bottlenecked by memory limitation. We hope this will create new opportunities in architecture design.
表 2 中 GN 的稳健结果展示了其优势:可以去掉 BN 施加的 batch 大小约束,从而腾出可观显存(例如 16 或更多)。这将使训练原本被显存卡住的更高容量模型成为可能。我们希望这为架构设计开辟新机会。
| # groups () | ||||||
|---|---|---|---|---|---|---|
| 64 | 32 | 16 | 8 | 4 | 2 | 1 (=LN) |
| 24.6 | 24.1 | 24.6 | 24.4 | 24.6 | 24.7 | 25.3 |
| 0.5 | - | 0.5 | 0.3 | 0.5 | 0.6 | 1.2 |
| # channels per group | ||||||
|---|---|---|---|---|---|---|
| 64 | 32 | 16 | 8 | 4 | 2 | 1 (=IN) |
| 24.4 | 24.5 | 24.2 | 24.3 | 24.8 | 25.6 | 28.4 |
| 0.2 | 0.3 | - | 0.1 | 0.6 | 1.4 | 4.2 |
Table 3: Group division. We show ResNet-50’s validation error (%) in ImageNet, trained with 32 images/GPU. (Top): a given number of groups. (Bottom): a given number of channels per group. The last rows show the differences with the best number.
| 组数 () | ||||||
|---|---|---|---|---|---|---|
| 64 | 32 | 16 | 8 | 4 | 2 | 1(=LN) |
| 24.6 | 24.1 | 24.6 | 24.4 | 24.6 | 24.7 | 25.3 |
| 0.5 | - | 0.5 | 0.3 | 0.5 | 0.6 | 1.2 |
| 每组通道数 | ||||||
|---|---|---|---|---|---|---|
| 64 | 32 | 16 | 8 | 4 | 2 | 1(=IN) |
| 24.4 | 24.5 | 24.2 | 24.3 | 24.8 | 25.6 | 28.4 |
| 0.2 | 0.3 | - | 0.1 | 0.6 | 1.4 | 4.2 |
表 3:分组方式。给出每 GPU 32 张图训练时 ImageNet 上 ResNet-50 的验证误差(%)。(上)给定组数。(下)给定每组通道数。末行是相对最优取值的差。
Comparison with Batch Renorm (BR).
BR [25] introduces two extra parameters ( and in [25]) that constrain the estimated mean and variance of BN. Their values are controlled by and . To apply BR to ResNet-50, we have carefully chosen these hyper-parameters, and found that and work best for ResNet-50. With a batch size of 4, ResNet-50 trained with BR has an error rate of 26.3%. This is better than BN’s 27.3%, but still 2.1% higher than GN’s 24.2%.
与批量重归一化(BR)的比较。
BR [25] 引入两个额外参数([25] 中的 与 )约束 BN 估计的均值与方差,其取值由 与 控制。把 BR 用到 ResNet-50 时,我们仔细选择这些超参,发现 、 效果最好。batch 为 4 时,BR 训练的 ResNet-50 误差率为 26.3%,优于 BN 的 27.3%,但仍比 GN 的 24.2% 高 2.1%。
Group division.
Thus far all presented GN models are trained with a group number of . Next we evaluate different ways of dividing into groups. With a given fixed group number, GN performs reasonably well for all values of we studied (Table 3, top panel). In the extreme case of , GN is equivalent to LN, and its error rate is higher than all cases of studied.
分组方式。
此前给出的 GN 模型均以组数 训练。接下来评估不同分组方式。固定组数时,我们所研究的所有 上 GN 都表现合理(表 3,上半)。极端情形 时 GN 等价于 LN,误差高于所有 的情形。
We also evaluate fixing the number of channels per group (Table 3, bottom panel). Note that because the layers can have different channel numbers, the group number can change across layers in this setting. In the extreme case of 1 channel per group, GN is equivalent to IN. Even if using as few as 2 channels per group, GN has substantially lower error than IN (25.6% vs. 28.4%). This result shows the effect of grouping channels when performing normalization.
我们也评估固定每组通道数(表 3,下半)。注意各层通道数可能不同,此时组数 可随层变化。极端情形每组 1 个通道时 GN 等价于 IN。即便每组仅 2 个通道,GN 仍明显优于 IN(25.6% 对 28.4%)。这说明在归一化时对通道分组是有效的。
Deeper models.
We have also compared GN with BN on ResNet-101 [20]. With a batch size of 32, our BN baseline of ResNet-101 has 22.0% validation error, and the GN counterpart has 22.4%, slightly worse by 0.4%. With a batch size of 2, GN ResNet-101’s error is 23.0%. This is still a decently stable result considering the very small batch size, and it is 8.9% better than the BN counterpart’s 31.9%.
更深模型。
我们也在 ResNet-101 [20] 上比较了 GN 与 BN。batch 为 32 时,ResNet-101 的 BN 基线验证误差 22.0%,GN 对应为 22.4%,略差 0.4%。batch 为 2 时,GN ResNet-101 误差 23.0%。考虑到 batch 极小,这仍相当稳定,并比 BN 对应的 31.9% 好 8.9%。
Results and analysis of VGG models.
To study GN/BN compared to no normalization, we consider VGG-16 [56] that can be healthily trained without normalization layers. We apply BN or GN right after each convolutional layer. Figure 6 shows the evolution of the feature distributions of conv5_3 (the last convolutional layer). GN and BN behave qualitatively similar, while being substantially different with the variant that uses no normalization; this phenomenon is also observed for all other convolutional layers. This comparison suggests that performing normalization is essential for controlling the distribution of features.
VGG 模型的结果与分析。
为研究 GN/BN 相对无归一化的差异,我们考虑可以在没有归一化层时健康训练的 VGG-16 [56]。在每个卷积层后立即施加 BN 或 GN。图 6 展示 conv5_3(最后一层卷积)特征分布的演化。GN 与 BN 行为定性相似,而与无归一化变体明显不同;这一现象在其他卷积层也观察到。该比较说明,做归一化对控制特征分布至关重要。
For VGG-16, GN is better than BN by 0.4% (Figure 6, right). This possibly implies that VGG-16 benefits less from BN’s regularization effect, and GN (that leads to lower training error) is superior to BN in this case.
对 VGG-16,GN 比 BN 好 0.4%(图 6,右)。这可能意味着 VGG-16 较少受益于 BN 的正则效应,而(带来更低训练误差的)GN 在此情形下优于 BN。
4.2 Object Detection and Segmentation in COCO
4.2 COCO 目标检测与分割
Next we evaluate fine-tuning the models for transferring to object detection and segmentation. These computer vision tasks in general benefit from higher-resolution input, so the batch size tends to be small in common practice (1 or 2 images/GPU [12, 47, 18, 36]). As a result, BN is turned into a linear layer where and are pre-computed from the pre-trained model and frozen [20]. We denote this as BN, which in fact performs no normalization during fine-tuning. We have also tried a variant that fine-tunes BN (normalization is performed and not frozen) and found it works poorly (reducing 6 AP with a batch size of 2), so we ignore this variant.
接下来评估把模型微调迁移到目标检测与分割。这些视觉任务通常受益于更高分辨率输入,因而实践中 batch 往往较小(每 GPU 1 或 2 张图 [12, 47, 18, 36])。于是 BN 被改写成线性层 ,其中 与 来自预训练模型并冻结 [20]。我们记为 BN,微调时实际上不做归一化。我们也试过微调 BN(仍做归一化、不冻结),发现效果很差(batch 为 2 时约掉 6 AP),故忽略该变体。
We experiment on the Mask R-CNN baselines [18], implemented in the publicly available codebase of Detectron [13]. We use the end-to-end variant with the same hyper-parameters as in [13]. We replace BN with GN during fine-tuning, using the corresponding models pre-trained from ImageNet.[^4] During fine-tuning, we use a weight decay of 0 for the and parameters, which is important for good detection results when and are being tuned. We fine-tune with a batch size of 1 image/GPU and 8 GPUs.
我们在 Mask R-CNN 基线 [18] 上实验,实现基于公开代码库 Detectron [13],采用端到端变体及与 [13] 相同的超参。微调时用对应 ImageNet 预训练模型,把 BN 换成 GN。[^4] 微调时对 与 使用权重衰减 0——在调它们时这对检测结果很重要。微调 batch 为每 GPU 1 张图、共 8 块 GPU。
The models are trained in the COCO train2017 set and evaluated in the COCO val2017 set (a.k.a minival). We report the standard COCO metrics of Average Precision (AP), AP, and AP, for bounding box detection (AP) and instance segmentation (AP).
模型在 COCO train2017 上训练、在 COCO val2017(也称 minival)上评估。报告标准 COCO 指标:平均精度(AP)、AP、AP,分别针对边界框检测(AP)与实例分割(AP)。
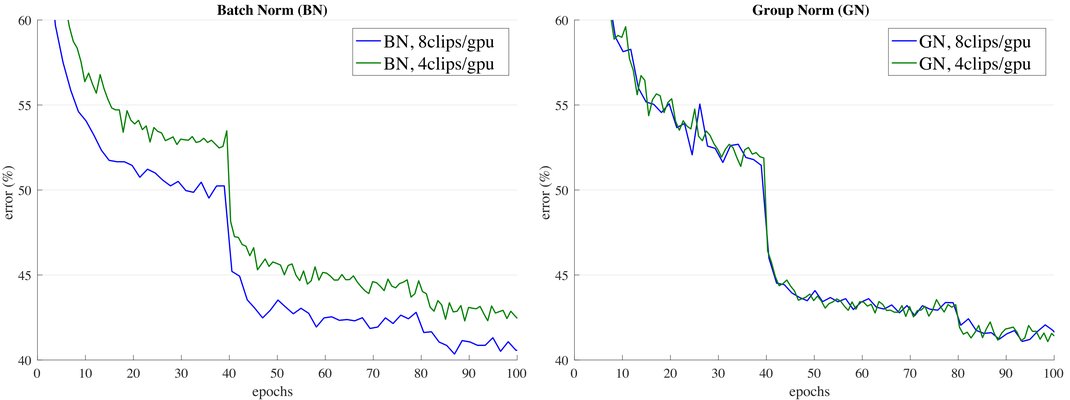
Figure 7: Error curves in Kinetics with an input length of 32 frames. We show ResNet-50 I3D’s validation error of BN (left) and GN (right) using a batch size of 8 and 4 clips/GPU. The monitored validation error is the 1-clip error under the same data augmentation as the training set, while the final validation accuracy in Table 8 is 10-clip testing without data augmentation.
图 7:Kinetics 上输入长度 32 帧的误差曲线。展示 ResNet-50 I3D 在每 GPU 8 与 4 个 clip 时 BN(左)与 GN(右)的验证误差。监控的验证误差是与训练集相同数据增强下的 1-clip 误差,而表 8 中的最终验证精度是无数据增强的 10-clip 测试。
Results of C4 backbone.
Table 4 shows the comparison of GN vs. BN on Mask R-CNN using a conv4 backbone (“C4” [18]). This C4 variant uses ResNet’s layers of up to conv4 to extract feature maps, and ResNet’s conv5 layers as the Region-of-Interest (RoI) heads for classification and regression. As they are inherited from the pre-trained model, the backbone and head both involve normalization layers.
C4 骨干结果。
表 4 比较 Mask R-CNN 使用 conv4 骨干(“C4” [18])时 GN 与 BN。该 C4 变体用 ResNet 到 conv4 的层提取特征图,用 ResNet 的 conv5 层作为分类与回归的 RoI 头。二者均继承自预训练模型,骨干与头都含归一化层。
On this baseline, GN improves over BN by 1.1 box AP and 0.8 mask AP. We note that the pre-trained GN model is slightly worse than BN in ImageNet (24.1% vs. 23.6%), but GN still outperforms BN for fine-tuning. BN creates inconsistency between pre-training and fine-tuning (frozen), which may explain the degradation.
在该基线上,GN 相对 BN 提升 1.1 box AP 与 0.8 mask AP。注意预训练 GN 模型在 ImageNet 上略逊于 BN(24.1% 对 23.6%),但微调时 GN 仍超过 BN。BN 造成预训练与微调(冻结)之间的不一致,或可解释这一退化。
We have also experimented with the LN variant, and found it is 1.9 box AP worse than GN and 0.8 worse than BN. Although LN is also independent of batch sizes, its representational power is weaker than GN.
我们也试过 LN 变体,发现比 GN 差 1.9 box AP,比 BN 差 0.8。尽管 LN 同样与 batch 无关,其表示能力弱于 GN。
| backbone | AP | AP | AP | AP | AP | AP |
|---|---|---|---|---|---|---|
| BN | 37.7 | 57.9 | 40.9 | 32.8 | 54.3 | 34.7 |
| GN | 38.8 | 59.2 | 42.2 | 33.6 | 55.9 | 35.4 |
Table 4: Detection and segmentation ablation results in COCO, using Mask R-CNN with ResNet-50 C4. BN means BN is frozen.
| 骨干 | AP | AP | AP | AP | AP | AP |
|---|---|---|---|---|---|---|
| BN | 37.7 | 57.9 | 40.9 | 32.8 | 54.3 | 34.7 |
| GN | 38.8 | 59.2 | 42.2 | 33.6 | 55.9 | 35.4 |
表 4:COCO 上检测与分割的消融结果,Mask R-CNN + ResNet-50 C4。BN 表示 BN 被冻结。
| backbone | box head | AP | AP | AP | AP | AP | AP |
|---|---|---|---|---|---|---|---|
| BN | - | 38.6 | 59.5 | 41.9 | 34.2 | 56.2 | 36.1 |
| BN | GN | 39.5 | 60.0 | 43.2 | 34.4 | 56.4 | 36.3 |
| GN | GN | 40.0 | 61.0 | 43.3 | 34.8 | 57.3 | 36.3 |
Table 5: Detection and segmentation ablation results in COCO, using Mask R-CNN with ResNet-50 FPN and a 4conv1fc bounding box head. BN means BN is frozen.
| 骨干 | box 头 | AP | AP | AP | AP | AP | AP |
|---|---|---|---|---|---|---|---|
| BN | - | 38.6 | 59.5 | 41.9 | 34.2 | 56.2 | 36.1 |
| BN | GN | 39.5 | 60.0 | 43.2 | 34.4 | 56.4 | 36.3 |
| GN | GN | 40.0 | 61.0 | 43.3 | 34.8 | 57.3 | 36.3 |
表 5:COCO 上检测与分割的消融结果,Mask R-CNN + ResNet-50 FPN 与 4conv1fc 边界框头。BN 表示 BN 被冻结。
| AP | AP | AP | AP | AP | AP | |
|---|---|---|---|---|---|---|
| R50 BN | 38.6 | 59.8 | 42.1 | 34.5 | 56.4 | 36.3 |
| R50 GN | 40.3 | 61.0 | 44.0 | 35.7 | 57.9 | 37.7 |
| R50 GN, long | 40.8 | 61.6 | 44.4 | 36.1 | 58.5 | 38.2 |
| R101 BN | 40.9 | 61.9 | 44.8 | 36.4 | 58.5 | 38.7 |
| R101 GN | 41.8 | 62.5 | 45.4 | 36.8 | 59.2 | 39.0 |
| R101 GN, long | 42.3 | 62.8 | 46.2 | 37.2 | 59.7 | 39.5 |
Table 6: Detection and segmentation results in COCO using Mask R-CNN and FPN. Here BN is the default Detectron baseline [13], and GN is applied to the backbone, box head, and mask head. “long” means training with more iterations. Code of these results are in https://github.com/facebookresearch/Detectron/blob/master/projects/GN.
| AP | AP | AP | AP | AP | AP | |
|---|---|---|---|---|---|---|
| R50 BN | 38.6 | 59.8 | 42.1 | 34.5 | 56.4 | 36.3 |
| R50 GN | 40.3 | 61.0 | 44.0 | 35.7 | 57.9 | 37.7 |
| R50 GN,长训 | 40.8 | 61.6 | 44.4 | 36.1 | 58.5 | 38.2 |
| R101 BN | 40.9 | 61.9 | 44.8 | 36.4 | 58.5 | 38.7 |
| R101 GN | 41.8 | 62.5 | 45.4 | 36.8 | 59.2 | 39.0 |
| R101 GN,长训 | 42.3 | 62.8 | 46.2 | 37.2 | 59.7 | 39.5 |
表 6:COCO 上 Mask R-CNN + FPN 的检测与分割结果。此处 BN 为默认 Detectron 基线 [13],GN 施加于骨干、box 头与 mask 头。“长训”表示更多迭代。结果代码见 https://github.com/facebookresearch/Detectron/blob/master/projects/GN。
Results of FPN backbone.
Next we compare GN and BN on Mask R-CNN using a Feature Pyramid Network (FPN) backbone [35], the currently state-of-the-art framework in COCO. Unlike the C4 variant, FPN exploits all pre-trained layers to construct a pyramid, and appends randomly initialized layers as the head. In [35], the box head consists of two hidden fully-connected layers (2fc). We find that replacing the 2fc box head with 4conv1fc (similar to [48]) can better leverage GN. The resulting comparisons are in Table 5.
FPN 骨干结果。
接下来在当前 COCO 上最先进的特征金字塔网络(FPN)骨干 [35] 的 Mask R-CNN 上比较 GN 与 BN。与 C4 不同,FPN 用全部预训练层构造金字塔,并附加随机初始化的头。[35] 中 box 头是两个隐层全连接(2fc)。我们发现把 2fc box 头换成 4conv1fc(类似 [48])能更好发挥 GN。结果见表 5。
As a baseline, BN has 38.6 box AP using the 4conv1fc head, on par with its 2fc counterpart using the same pre-trained model (38.5 AP). By adding GN to all convolutional layers of the box head (but still using the BN backbone), we increase the box AP by 0.9 to 39.5 (2nd row, Table 5). This ablation shows that a substantial portion of GN’s improvement for detection is from normalization in the head (which is also done by the C4 variant). On the contrary, applying BN to the box head (that has 512 RoIs per image) does not provide satisfactory result and is 9 AP worse — in detection, the batch of RoIs are sampled from the same image and their distribution is not i.i.d., and the non-i.i.d. distribution is also an issue that degrades BN’s batch statistics estimation [25]. GN does not suffer from this problem.
作为基线,BN 用 4conv1fc 头得到 38.6 box AP,与同一预训练模型上的 2fc 对应(38.5 AP)相当。仅在 box 头的所有卷积层加 GN(骨干仍为 BN),box AP 提升 0.9 到 39.5(表 5 第 2 行)。这一消融说明,GN 对检测的相当一部分改进来自头内的归一化(C4 变体也这样做)。相反,对 box 头(每图 512 个 RoI)施加 BN 结果不佳,约差 9 AP——检测中 RoI 的 batch 来自同一张图,分布非 i.i.d.,这种非独立同分布也会损害 BN 的批量统计估计 [25]。GN 不受此问题影响。
Next we replace the FPN backbone with the GN-based counterpart, i.e., the GN pre-trained model is used during fine-tuning (3rd row, Table 5). Applying GN to the backbone alone contributes a 0.5 AP gain (from 39.5 to 40.0), suggesting that GN helps when transferring features.
接下来把 FPN 骨干换成基于 GN 的对应模型,即微调时使用 GN 预训练模型(表 5 第 3 行)。仅对骨干施加 GN 就贡献 0.5 AP(从 39.5 到 40.0),说明 GN 有助于特征迁移。
Table 6 shows the full results of GN (applied to the backbone, box head, and mask head), compared with the standard Detectron baseline [13] based on BN. Using the same hyper-parameters as [13], GN increases over BN by a healthy margin. Moreover, we found that GN is not fully trained with the default schedule in [13], so we also tried increasing the iterations from 180k to 270k (BN does not benefit from longer training). Our final ResNet-50 GN model (“long”, Table 6) is 2.2 points box AP and 1.6 points mask AP better than its BN variant.
表 6 给出 GN(施加于骨干、box 头与 mask 头)的完整结果,并与基于 BN 的标准 Detectron 基线 [13] 比较。使用与 [13] 相同的超参时,GN 相对 BN 有稳健提升。此外我们发现默认日程 [13] 下 GN 尚未充分训练,于是把迭代从 180k 增到 270k(BN 并不受益于更长训练)。最终 ResNet-50 GN 模型(表 6 “长训”)比 BN 变体高 2.2 点 box AP 与 1.6 点 mask AP。
| from scratch | AP | AP | AP | AP | AP | AP |
|---|---|---|---|---|---|---|
| R50 BN [34] | 34.5 | 55.2 | 37.7 | - | - | - |
| R50 GN | 39.5 | 59.8 | 43.6 | 35.2 | 56.9 | 37.6 |
| R101 GN | 41.0 | 61.1 | 44.9 | 36.4 | 58.2 | 38.7 |
Table 7: Detection and segmentation results trained from scratch in COCO using Mask R-CNN and FPN. Here the BN results are from [34], and BN is synced across GPUs [43] and is not frozen. Code of these results are in https://github.com/facebookresearch/Detectron/blob/master/projects/GN.
| 从零训练 | AP | AP | AP | AP | AP | AP |
|---|---|---|---|---|---|---|
| R50 BN [34] | 34.5 | 55.2 | 37.7 | - | - | - |
| R50 GN | 39.5 | 59.8 | 43.6 | 35.2 | 56.9 | 37.6 |
| R101 GN | 41.0 | 61.1 | 44.9 | 36.4 | 58.2 | 38.7 |
表 7:COCO 上 Mask R-CNN + FPN 从零训练的检测与分割结果。此处 BN 结果来自 [34],BN 跨 GPU 同步 [43] 且不冻结。结果代码见 https://github.com/facebookresearch/Detectron/blob/master/projects/GN。
Training Mask R-CNN from scratch.
GN allows us to easily investigate training object detectors from scratch (without any pre-training). We show the results in Table 7, where the GN models are trained for 270k iterations.[^5] To our knowledge, our numbers (41.0 box AP and 36.4 mask AP) are the best from-scratch results in COCO reported to date; they can even compete with the ImageNet-pretrained results in Table 6. As a reference, with synchronous BN [43], a concurrent work [34] achieves a from-scratch result of 34.5 box AP using R50 (Table 7), and 36.3 using a specialized backbone.
从零训练 Mask R-CNN。
GN 使我们能方便地研究从零训练目标检测器(无任何预训练)。结果见表 7,GN 模型训练 270k 次迭代。[^5] 据我们所知,我们的数字(41.0 box AP 与 36.4 mask AP)是迄今 COCO 上报告的最佳从零训练结果;甚至可与表 6 中 ImageNet 预训练结果媲美。作为参照,同期工作 [34] 用同步 BN [43] 在 R50 上得到从零训练 34.5 box AP(表 7),专用骨干为 36.3。
4.3 Video Classification in Kinetics
4.3 Kinetics 视频分类
Lastly we evaluate video classification in the Kinetics dataset [30]. Many video classification models [60, 6] extend the features to 3D spatial-temporal dimensions. This is memory-demanding and imposes constraints on the batch sizes and model designs.
最后在 Kinetics 数据集 [30] 上评估视频分类。许多视频分类模型 [60, 6] 把特征扩展到三维时空,显存需求大,从而约束 batch 大小与模型设计。
We experiment with Inflated 3D (I3D) convolutional networks [6]. We use the ResNet-50 I3D baseline as described in [62]. The models are pre-trained from ImageNet. For both BN and GN, we extend the normalization from over to over , where is the temporal axis. We train in the 400-class Kinetics training set and evaluate in the validation set. We report the top-1 and top-5 classification accuracy, using standard 10-clip testing that averages softmax scores from 10 clips regularly sampled.
我们实验 Inflated 3D(I3D)卷积网络 [6],采用 [62] 描述的 ResNet-50 I3D 基线。模型从 ImageNet 预训练。对 BN 与 GN,我们都把归一化从 扩展到 ,其中 为时间轴。在 400 类 Kinetics 训练集上训练、在验证集上评估。报告 top-1 与 top-5 分类精度,采用标准 10-clip 测试:对规则采样的 10 个 clip 的 softmax 分数取平均。
We study two different temporal lengths: 32-frame and 64-frame input clips. The 32-frame clip is regularly sampled with a frame interval of 2 from the raw video, and the 64-frame clip is sampled continuously. The model is fully convolutional in spacetime, so the 64-frame variant consumes about 2 more memory. We study a batch size of 8 or 4 clips/GPU for the 32-frame variant, and 4 clips/GPU for the 64-frame variant due to memory limitation.
我们研究两种时间长度:32 帧与 64 帧输入 clip。32 帧 clip 从原始视频以帧间隔 2 规则采样,64 帧 clip 连续采样。模型在时空上全卷积,故 64 帧变体约多消耗 2 显存。32 帧变体研究每 GPU 8 或 4 个 clip;64 帧变体因显存限制为每 GPU 4 个 clip。
| clip length | 32 | 32 | 64 |
|---|---|---|---|
| batch size | 8 | 4 | 4 |
| BN | 73.3 / 90.7 | 72.1 / 90.0 | 73.3 / 90.8 |
| GN | 73.0 / 90.6 | 72.8 / 90.6 | 74.5 / 91.7 |
Table 8: Video classification results in Kinetics: ResNet-50 I3D baseline’s top-1 / top-5 accuracy (%).
| clip 长度 | 32 | 32 | 64 |
|---|---|---|---|
| batch 大小 | 8 | 4 | 4 |
| BN | 73.3 / 90.7 | 72.1 / 90.0 | 73.3 / 90.8 |
| GN | 73.0 / 90.6 | 72.8 / 90.6 | 74.5 / 91.7 |
表 8:Kinetics 视频分类结果:ResNet-50 I3D 基线的 top-1 / top-5 精度(%)。
Results of 32-frame inputs.
Table 8 (col. 1, 2) shows the video classification accuracy in Kinetics using 32-frame clips. For the batch size of 8, GN is slightly worse than BN by 0.3% top-1 accuracy and 0.1% top-5. This shows that GN is competitive with BN when BN works well. For the smaller batch size of 4, GN’s accuracy is kept similar (72.8 / 90.6 vs. 73.0 / 90.6), but is better than BN’s 72.1 / 90.0. BN’s accuracy is decreased by 1.2% when the batch size decreases from 8 to 4.
32 帧输入结果。
表 8(第 1、2 列)给出 Kinetics 上用 32 帧 clip 的视频分类精度。batch 为 8 时,GN 略逊于 BN:top-1 差 0.3%,top-5 差 0.1%。说明 BN 工作良好时 GN 仍有竞争力。更小的 batch 4 时,GN 精度基本保持(72.8 / 90.6 对 73.0 / 90.6),但优于 BN 的 72.1 / 90.0。BN 在 batch 从 8 降到 4 时精度下降 1.2%。
Figure 7 shows the error curves. BN’s error curves (left) have a noticeable gap when the batch size decreases from 8 to 4, while GN’s error curves (right) are very similar.
图 7 给出误差曲线。BN 的误差曲线(左)在 batch 从 8 降到 4 时有明显差距,而 GN 的误差曲线(右)非常接近。
Results of 64-frame inputs.
Table 8 (col. 3) shows the results of using 64-frame clips. In this case, BN has a result of 73.3 / 90.8. These appear to be acceptable numbers (vs. 73.3 / 90.7 of 32-frame, batch size 8), but the trade-off between the temporal length (64 vs. 32) and batch size (4 vs. 8) could have been overlooked. Comparing col. 3 and col. 2 in Table 8, we find that the temporal length actually has positive impact (+1.2%), but it is veiled by BN’s negative effect of the smaller batch size.
64 帧输入结果。
表 8(第 3 列)给出 64 帧 clip 的结果。此时 BN 为 73.3 / 90.8。这些数字看似可接受(相对 32 帧、batch 8 的 73.3 / 90.7),但时间长度(64 对 32)与 batch 大小(4 对 8)之间的权衡可能被忽视。比较表 8 第 3 列与第 2 列可见,时间长度实际有正面影响(+1.2%),却被 BN 在更小 batch 上的负面影响掩盖。
GN does not suffer from this trade-off. The 64-frame variant of GN has 74.5 / 91.7 accuracy, showing healthy gains over its BN counterpart and all BN variants. GN helps the model benefit from temporal length, and the longer clip boosts the top-1 accuracy by 1.7% (top-5 1.1%) with the same batch size.
GN 不受这一权衡困扰。64 帧 GN 变体达到 74.5 / 91.7,相对其 BN 对应以及所有 BN 变体都有稳健提升。GN 帮助模型从时间长度中获益:相同 batch 下更长 clip 把 top-1 抬高 1.7%(top-5 1.1%)。
The improvement of GN on detection, segmentation, and video classification demonstrates that GN is a strong alternative to the powerful and currently dominant BN technique in these tasks.
GN 在检测、分割与视频分类上的提升表明,它是这些任务上强势且当前占主导的 BN 技术的有力替代。
5 Discussion and Future Work
5 讨论与未来工作
We have presented GN as an effective normalization layer without exploiting the batch dimension. We have evaluated GN’s behaviors in a variety of applications. We note, however, that BN has been so influential that many state-of-the-art systems and their hyper-parameters have been designed for it, which may not be optimal for GN-based models. It is possible that re-designing the systems or searching new hyper-parameters for GN will give better results.
我们提出了不利用 batch 维的有效归一化层 GN,并在多种应用中评估其行为。但需指出,BN 影响如此之大,许多顶尖系统及其超参都围绕它设计,对基于 GN 的模型未必最优。重新设计系统或为 GN 搜索新超参,有可能给出更好结果。
In addition, we have shown that GN is related to LN and IN, two normalization methods that are particularly successful in training recurrent (RNN/LSTM) or generative (GAN) models. This suggests us to study GN in those areas in the future. We will also investigate GN’s performance on learning representations for reinforcement learning (RL) tasks, e.g., [54], where BN is playing an important role for training very deep models [20].
此外我们表明 GN 与 LN、IN 相关——后两者在训练循环(RNN/LSTM)或生成(GAN)模型上特别成功。这提示未来在这些领域研究 GN。我们也将考察 GN 在强化学习(RL)任务表示学习上的表现,例如 [54],其中 BN 对训练很深模型起着重要作用 [20]。
Acknowledgement.
We would like to thank Piotr Dollár and Ross Girshick for helpful discussions.
致谢。
感谢 Piotr Dollár 与 Ross Girshick 的有益讨论。
References
参考文献
[1] M. Abadi, P. Barham, J. Chen, Z. Chen, A. Davis, J. Dean, M. Devin, S. Ghemawat, G. Irving, M. Isard, et al. Tensorflow: A system for large-scale machine learning. In Operating Systems Design and Implementation (OSDI) , 2016.
[2] D. Arpit, Y. Zhou, B. Kota, and V. Govindaraju. Normalization propagation: A parametric technique for removing internal covariate shift in deep networks. In ICML , 2016.
[3] J. L. Ba, J. R. Kiros, and G. E. Hinton. Layer normalization. arXiv:1607.06450 , 2016.
[4] L. Bottou, F. E. Curtis, and J. Nocedal. Optimization methods for large-scale machine learning. arXiv:1606.04838 , 2016.
[5] M. Carandini and D. J. Heeger. Normalization as a canonical neural computation. Nature Reviews Neuroscience , 2012.
[6] J. Carreira and A. Zisserman. Quo vadis, action recognition? a new model and the kinetics dataset. In CVPR , 2017.
[7] F. Chollet. Xception: Deep learning with depthwise separable convolutions. In CVPR , 2017.
[8] T. Cohen and M. Welling. Group equivariant convolutional networks. In ICML , 2016.
[9] N. Dalal and B. Triggs. Histograms of oriented gradients for human detection. In CVPR , 2005.
[10] J. Dean, G. Corrado, R. Monga, K. Chen, M. Devin, M. Mao, A. Senior, P. Tucker, K. Yang, Q. V. Le, et al. Large scale distributed deep networks. In NIPS , 2012.
[11] S. Dieleman, J. De Fauw, and K. Kavukcuoglu. Exploiting cyclic symmetry in convolutional neural networks. In ICML , 2016.
[12] R. Girshick. Fast R-CNN. In ICCV , 2015.
[13] R. Girshick, I. Radosavovic, G. Gkioxari, P. Dollár, and K. He. Detectron. https://github.com/facebookresearch/detectron , 2018.
[14] X. Glorot and Y. Bengio. Understanding the difficulty of training deep feedforward neural networks. In International Conference on Artificial Intelligence and Statistics (AISTATS) , 2010.
[15] I. Goodfellow, J. Pouget-Abadie, M. Mirza, B. Xu, D. Warde-Farley, S. Ozair, A. Courville, and Y. Bengio. Generative adversarial nets. In NIPS , 2014.
[16] P. Goyal, P. Dollár, R. Girshick, P. Noordhuis, L. Wesolowski, A. Kyrola, A. Tulloch, Y. Jia, and K. He. Accurate, large minibatch SGD: Training ImageNet in 1 hour. arXiv:1706.02677 , 2017.
[17] S. Gross and M. Wilber. Training and investigating Residual Nets. https://github.com/facebook/fb.resnet.torch , 2016.
[18] K. He, G. Gkioxari, P. Dollár, and R. Girshick. Mask R-CNN. In ICCV , 2017.
[19] K. He, X. Zhang, S. Ren, and J. Sun. Delving deep into rectifiers: Surpassing human-level performance on imagenet classification. In ICCV , 2015.
[20] K. He, X. Zhang, S. Ren, and J. Sun. Deep residual learning for image recognition. In CVPR , 2016.
[21] D. J. Heeger. Normalization of cell responses in cat striate cortex. Visual neuroscience , 1992.
[22] S. Hochreiter and J. Schmidhuber. Long short-term memory. Neural computation , 1997.
[23] A. G. Howard, M. Zhu, B. Chen, D. Kalenichenko, W. Wang, T. Weyand, M. Andreetto, and H. Adam. MobileNets: Efficient convolutional neural networks for mobile vision applications. arXiv:1704.04861 , 2017.
[24] G. Huang, Z. Liu, L. van der Maaten, and K. Q. Weinberger. Densely connected convolutional networks. In CVPR , 2017.
[25] S. Ioffe. Batch renormalization: Towards reducing minibatch dependence in batch-normalized models. In NIPS , 2017.
[26] S. Ioffe and C. Szegedy. Batch normalization: Accelerating deep network training by reducing internal covariate shift. In ICML , 2015.
[27] P. Isola, J.-Y. Zhu, T. Zhou, and A. A. Efros. Image-to-image translation with conditional adversarial networks. In CVPR , 2017.
[28] K. Jarrett, K. Kavukcuoglu, Y. LeCun, et al. What is the best multi-stage architecture for object recognition? In ICCV , 2009.
[29] H. Jegou, M. Douze, C. Schmid, and P. Perez. Aggregating local descriptors into a compact image representation. In CVPR , 2010.
[30] W. Kay, J. Carreira, K. Simonyan, B. Zhang, C. Hillier, S. Vijayanarasimhan, F. Viola, T. Green, T. Back, P. Natsev, et al. The Kinetics human action video dataset. arXiv:1705.06950 , 2017.
[31] A. Krizhevsky. One weird trick for parallelizing convolutional neural networks. arXiv:1404.5997 , 2014.
[32] A. Krizhevsky, I. Sutskever, and G. Hinton. Imagenet classification with deep convolutional neural networks. In NIPS , 2012.
[33] Y. LeCun, L. Bottou, G. B. Orr, and K.-R. Müller. Efficient backprop. In Neural Networks: Tricks of the Trade . 1998.
[34] Z. Li, C. Peng, G. Yu, X. Zhang, Y. Deng, and J. Sun. DetNet: A backbone network for object detection. arXiv:1804.06215 , 2018.
[35] T.-Y. Lin, P. Dollár, R. Girshick, K. He, B. Hariharan, and S. Belongie. Feature pyramid networks for object detection. In CVPR , 2017.
[36] T.-Y. Lin, P. Goyal, R. Girshick, K. He, and P. Dollár. Focal loss for dense object detection. In ICCV , 2017.
[37] T.-Y. Lin, M. Maire, S. Belongie, J. Hays, P. Perona, D. Ramanan, P. Dollár, and C. L. Zitnick. Microsoft COCO: Common objects in context. In ECCV . 2014.
[38] J. Long, E. Shelhamer, and T. Darrell. Fully convolutional networks for semantic segmentation. In CVPR , 2015.
[39] D. G. Lowe. Distinctive image features from scale-invariant keypoints. IJCV , 2004.
[40] S. Lyu and E. P. Simoncelli. Nonlinear image representation using divisive normalization. In CVPR , 2008.
[41] A. Oliva and A. Torralba. Modeling the shape of the scene: A holistic representation of the spatial envelope. IJCV , 2001.
[42] A. Paszke, S. Gross, S. Chintala, G. Chanan, E. Yang, Z. DeVito, Z. Lin, A. Desmaison, L. Antiga, and A. Lerer. Automatic differentiation in pytorch. 2017.
[43] C. Peng, T. Xiao, Z. Li, Y. Jiang, X. Zhang, K. Jia, G. Yu, and J. Sun. MegDet: A large mini-batch object detector. In CVPR , 2018.
[44] F. Perronnin and C. Dance. Fisher kernels on visual vocabularies for image categorization. In CVPR , 2007.
[45] S.-A. Rebuffi, H. Bilen, and A. Vedaldi. Learning multiple visual domains with residual adapters. In NIPS , 2017.
[46] M. Ren, R. Liao, R. Urtasun, F. H. Sinz, and R. S. Zemel. Normalizing the normalizers: Comparing and extending network normalization schemes. In ICLR , 2017.
[47] S. Ren, K. He, R. Girshick, and J. Sun. Faster R-CNN: Towards real-time object detection with region proposal networks. In NIPS , 2015.
[48] S. Ren, K. He, R. Girshick, X. Zhang, and J. Sun. Object detection networks on convolutional feature maps. TPAMI , 2017.
[49] D. E. Rumelhart, G. E. Hinton, and R. J. Williams. Learning representations by back-propagating errors. Nature , 1986.
[50] O. Russakovsky, J. Deng, H. Su, J. Krause, S. Satheesh, S. Ma, Z. Huang, A. Karpathy, A. Khosla, M. Bernstein, A. C. Berg, and L. Fei-Fei. ImageNet Large Scale Visual Recognition Challenge. IJCV , 2015.
[51] T. Salimans and D. P. Kingma. Weight normalization: A simple reparameterization to accelerate training of deep neural networks. In NIPS , 2016.
[52] O. Schwartz and E. P. Simoncelli. Natural signal statistics and sensory gain control. Nature neuroscience , 2001.
[53] P. Sermanet, D. Eigen, X. Zhang, M. Mathieu, R. Fergus, and Y. LeCun. Overfeat: Integrated recognition, localization and detection using convolutional networks. In ICLR , 2014.
[54] D. Silver, J. Schrittwieser, K. Simonyan, I. Antonoglou, A. Huang, A. Guez, T. Hubert, L. Baker, M. Lai, A. Bolton, Y. Chen, T. Lillicrap, F. Hui, L. Sifre, G. van den Driessche, T. Graepel, and D. Hassabis. Mastering the game of go without human knowledge. Nature , 2017.
[55] E. P. Simoncelli and B. A. Olshausen. Natural image statistics and neural representation. Annual review of neuroscience , 2001.
[56] K. Simonyan and A. Zisserman. Very deep convolutional networks for large-scale image recognition. In ICLR , 2015.
[57] C. Szegedy, S. Ioffe, and V. Vanhoucke. Inception-v4, inception-resnet and the impact of residual connections on learning. In ICLR Workshop , 2016.
[58] C. Szegedy, W. Liu, Y. Jia, P. Sermanet, S. Reed, D. Anguelov, D. Erhan, V. Vanhoucke, and A. Rabinovich. Going deeper with convolutions. In CVPR , 2015.
[59] C. Szegedy, V. Vanhoucke, S. Ioffe, J. Shlens, and Z. Wojna. Rethinking the inception architecture for computer vision. In CVPR , 2016.
[60] D. Tran, L. Bourdev, R. Fergus, L. Torresani, and M. Paluri. Learning spatiotemporal features with 3D convolutional networks. In ICCV , 2015.
[61] D. Ulyanov, A. Vedaldi, and V. Lempitsky. Instance normalization: The missing ingredient for fast stylization. arXiv:1607.08022 , 2016.
[62] X. Wang, R. Girshick, A. Gupta, and K. He. Non-local neural networks. In CVPR , 2018.
[63] S. Xie, R. Girshick, P. Dollár, Z. Tu, and K. He. Aggregated residual transformations for deep neural networks. In CVPR , 2017.
[64] M. D. Zeiler and R. Fergus. Visualizing and understanding convolutional neural networks. In ECCV , 2014.
[65] X. Zhang, X. Zhou, M. Lin, and J. Sun. ShuffleNet: An extremely efficient convolutional neural network for mobile devices. In CVPR , 2018.